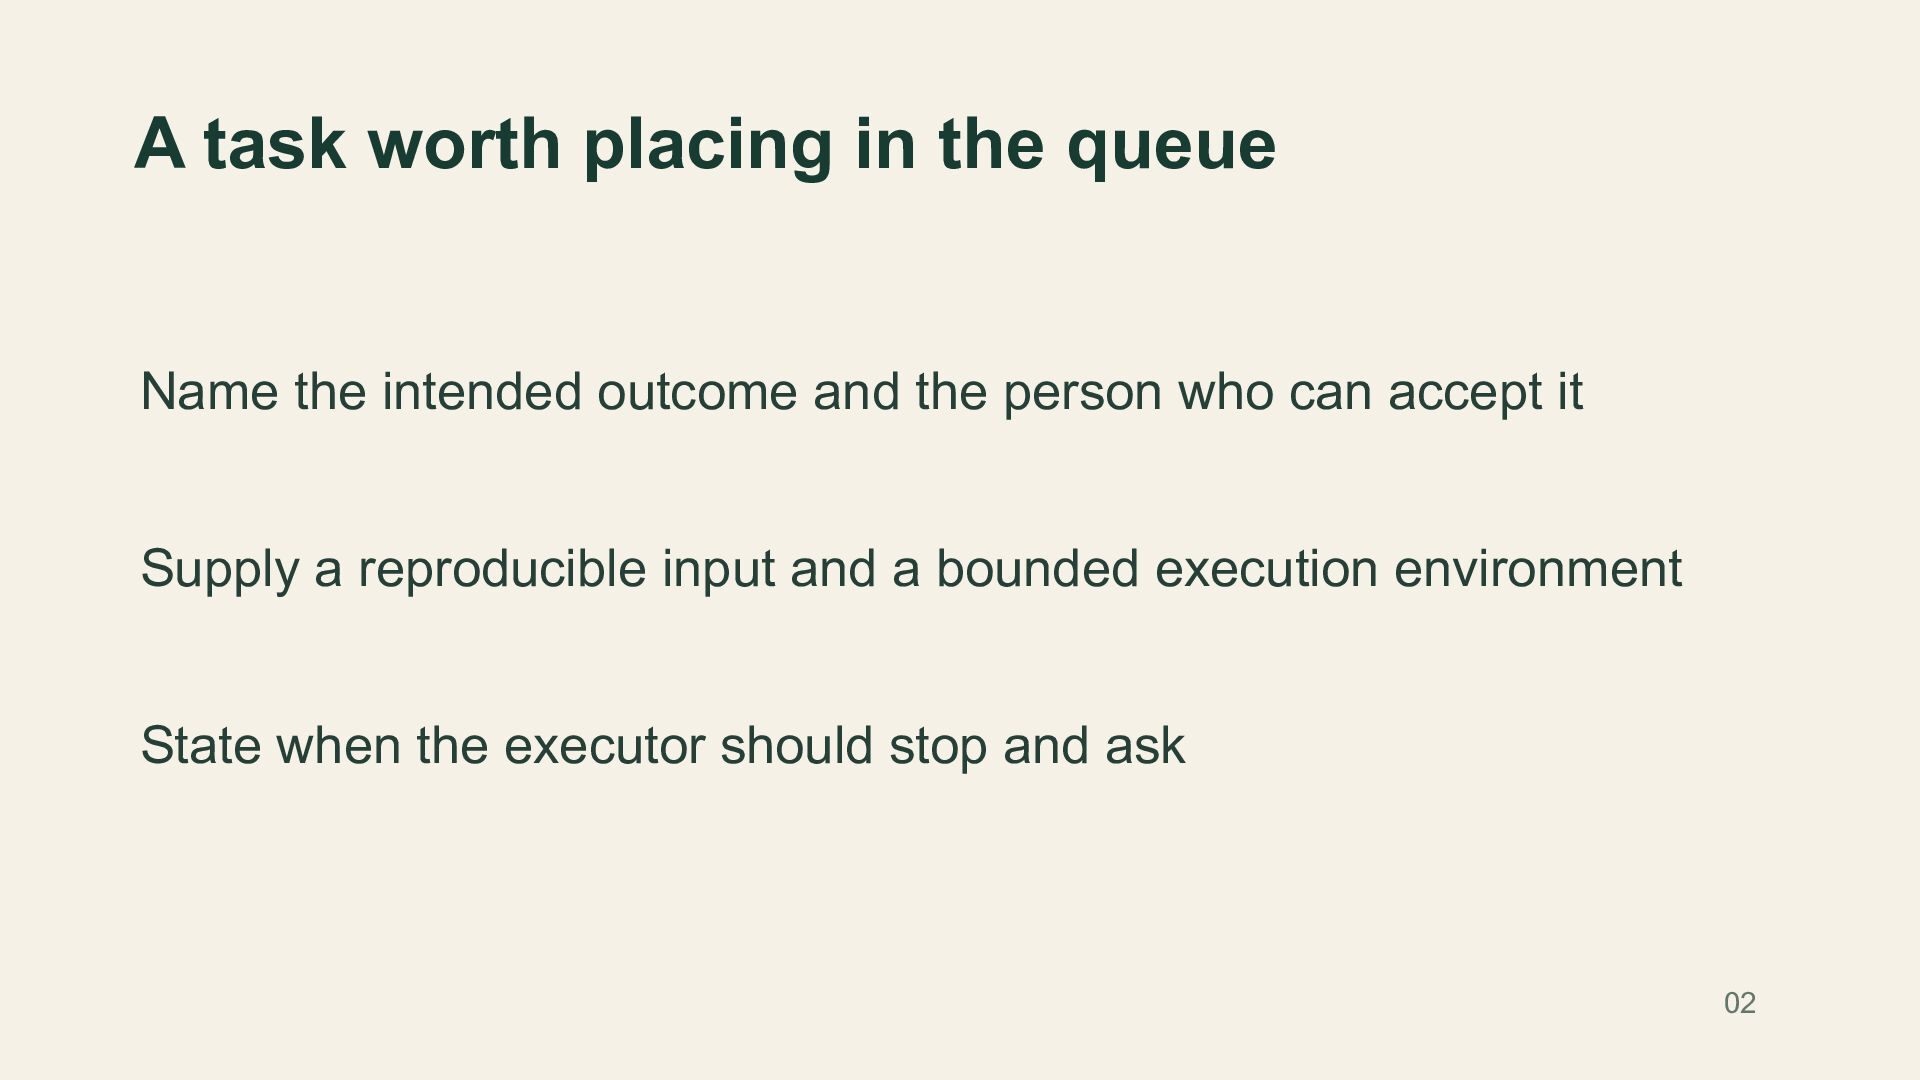
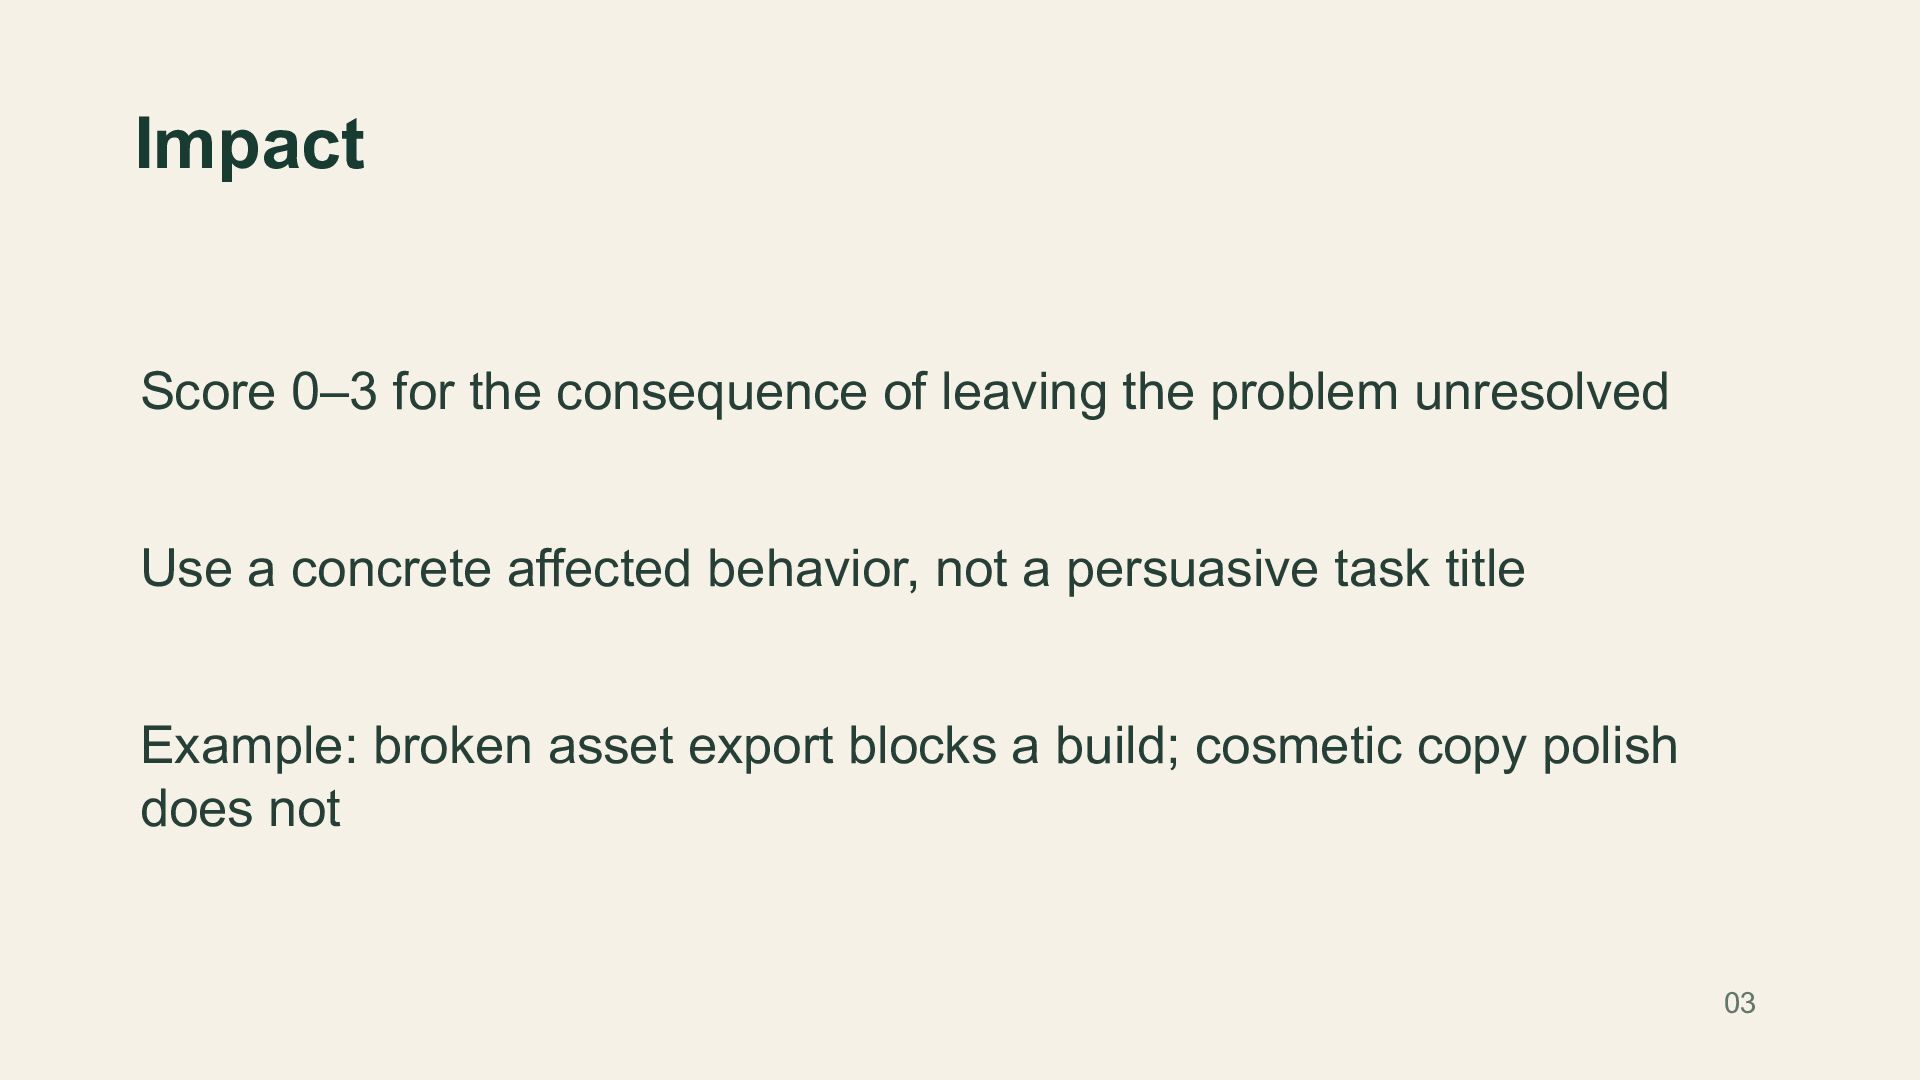
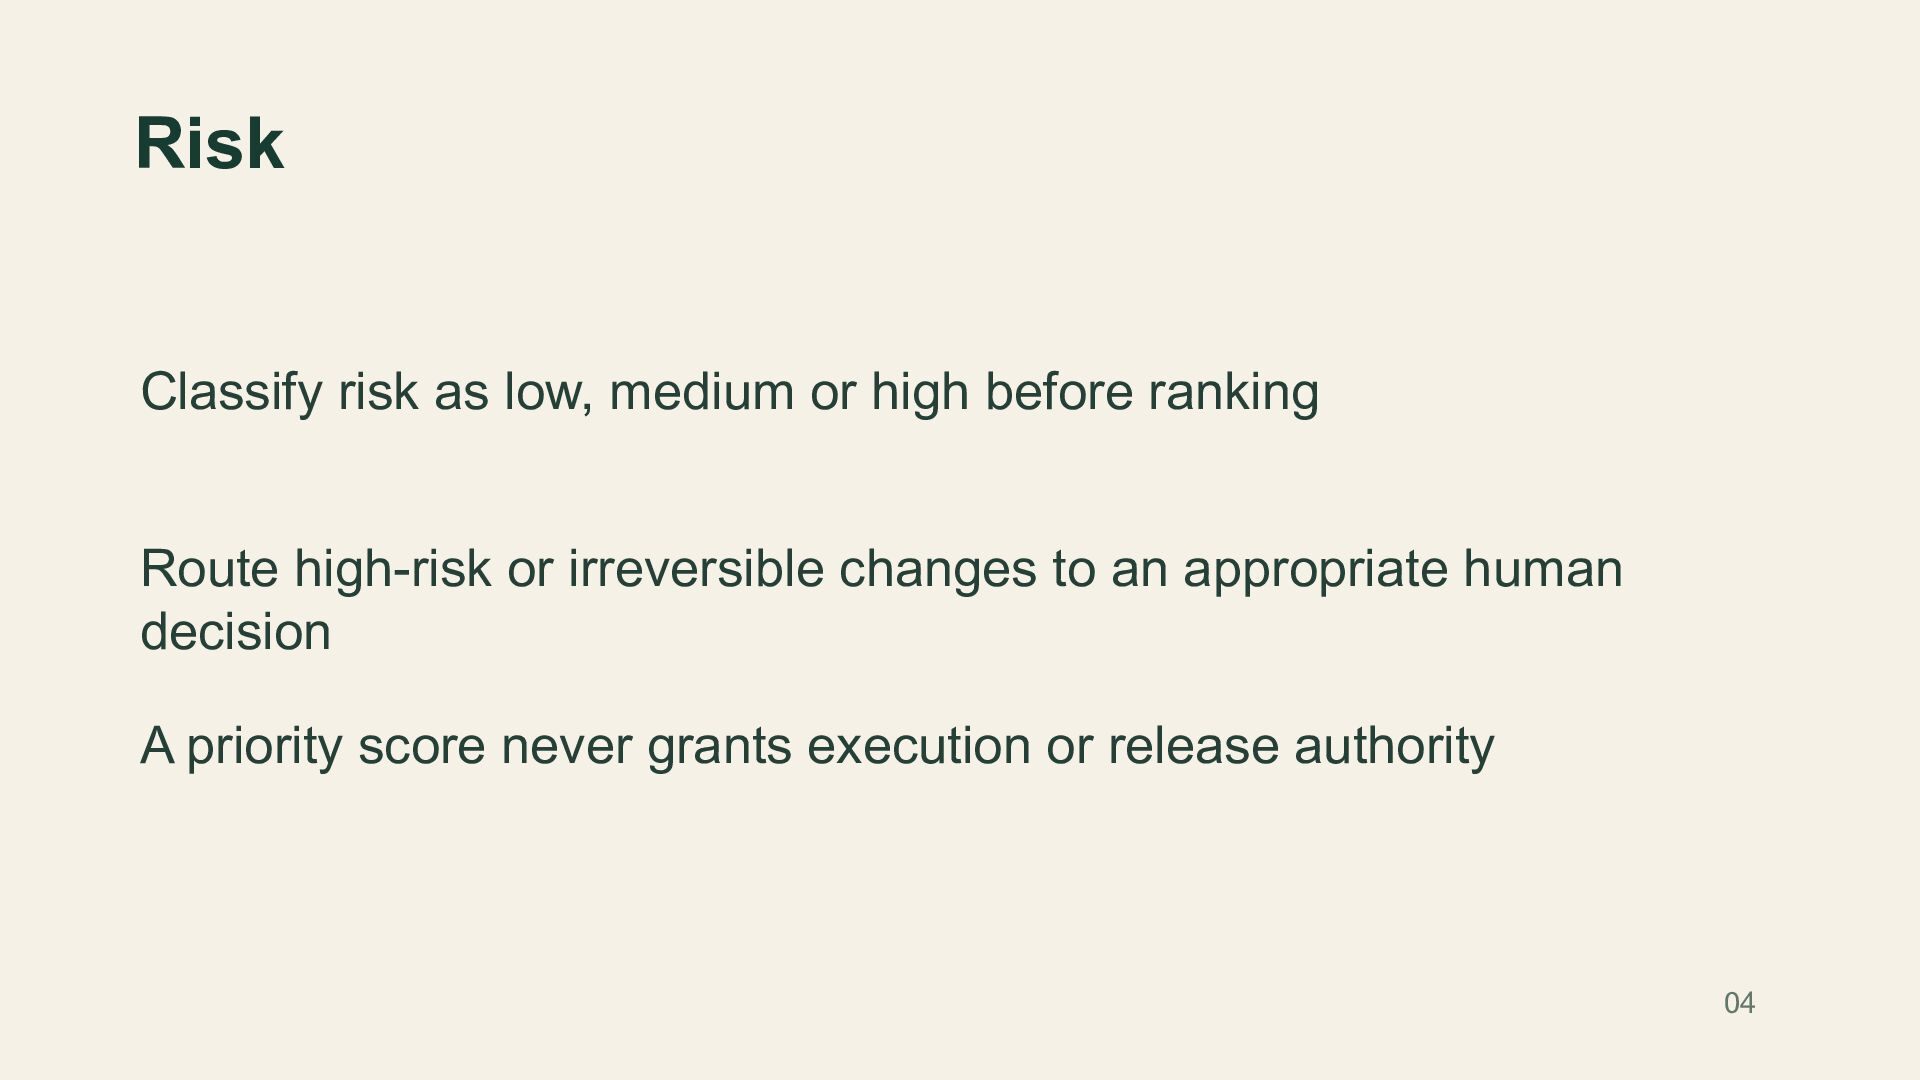
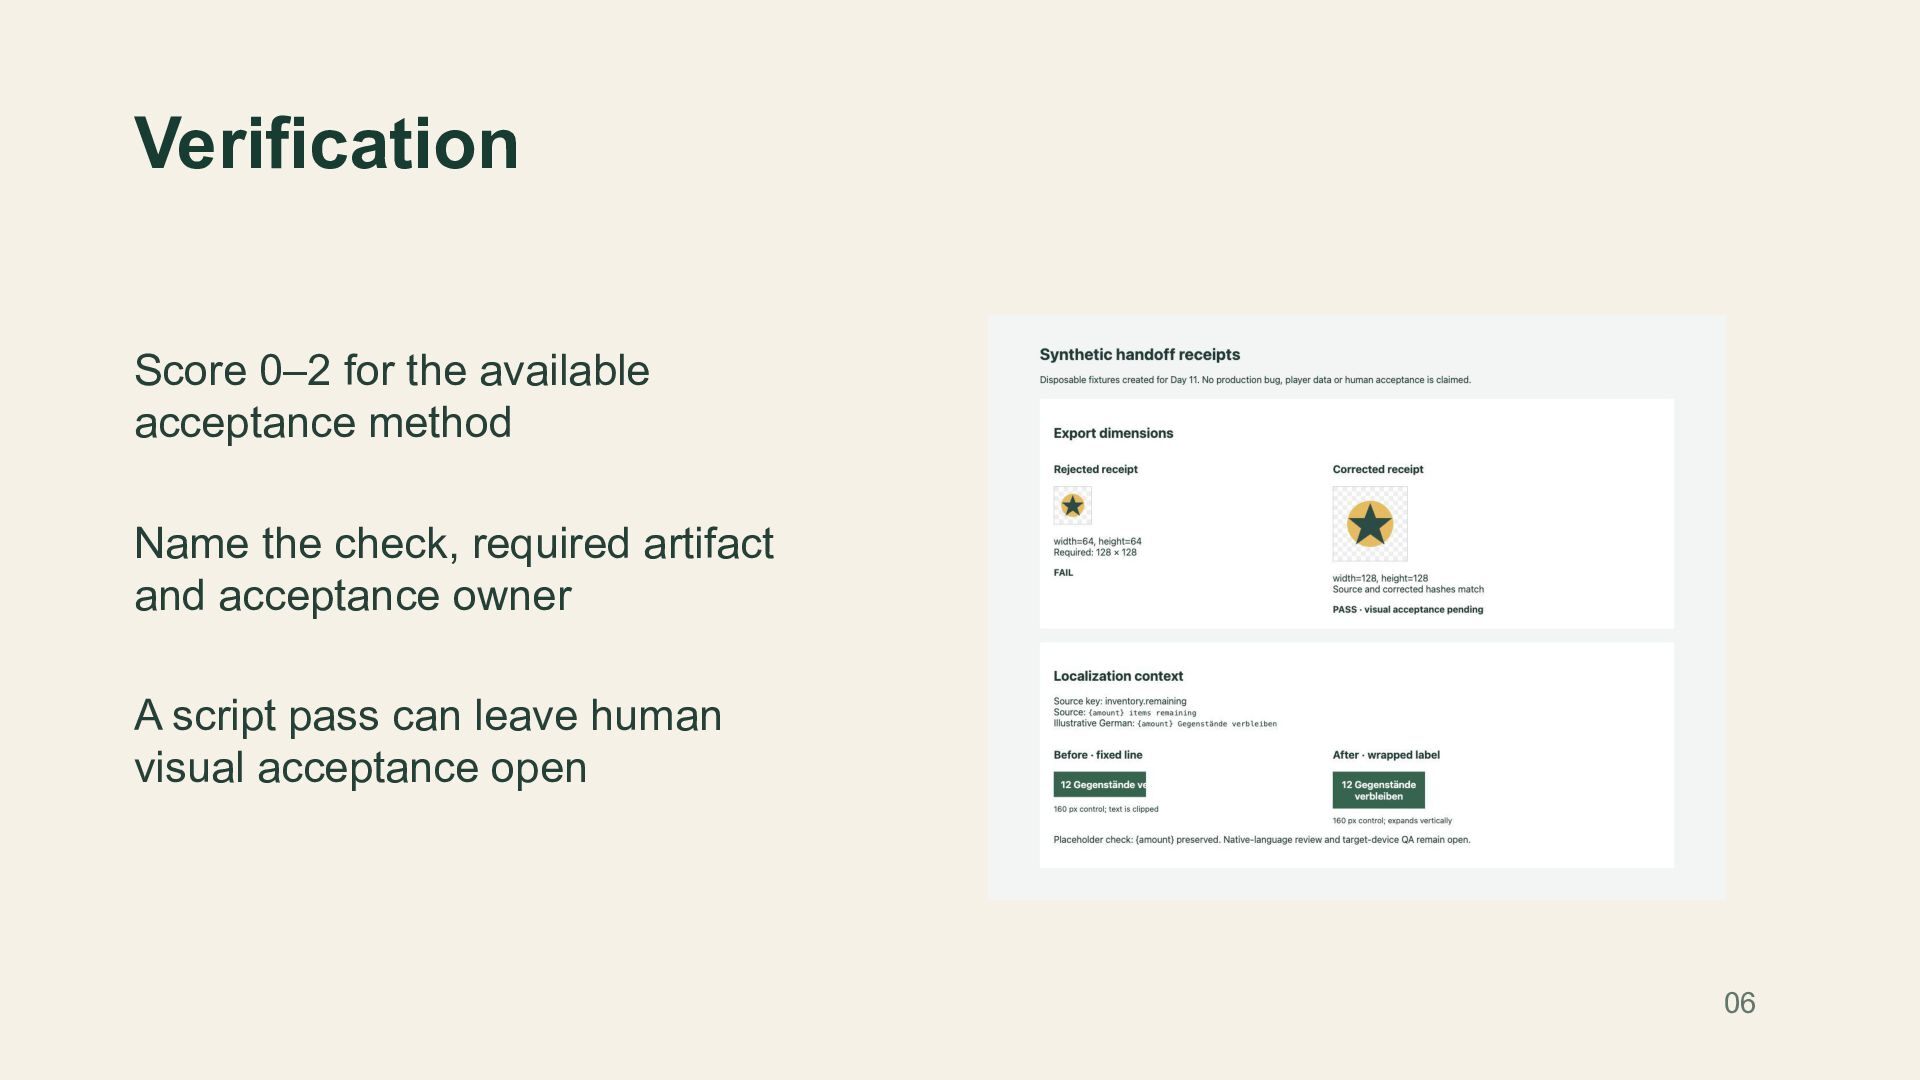
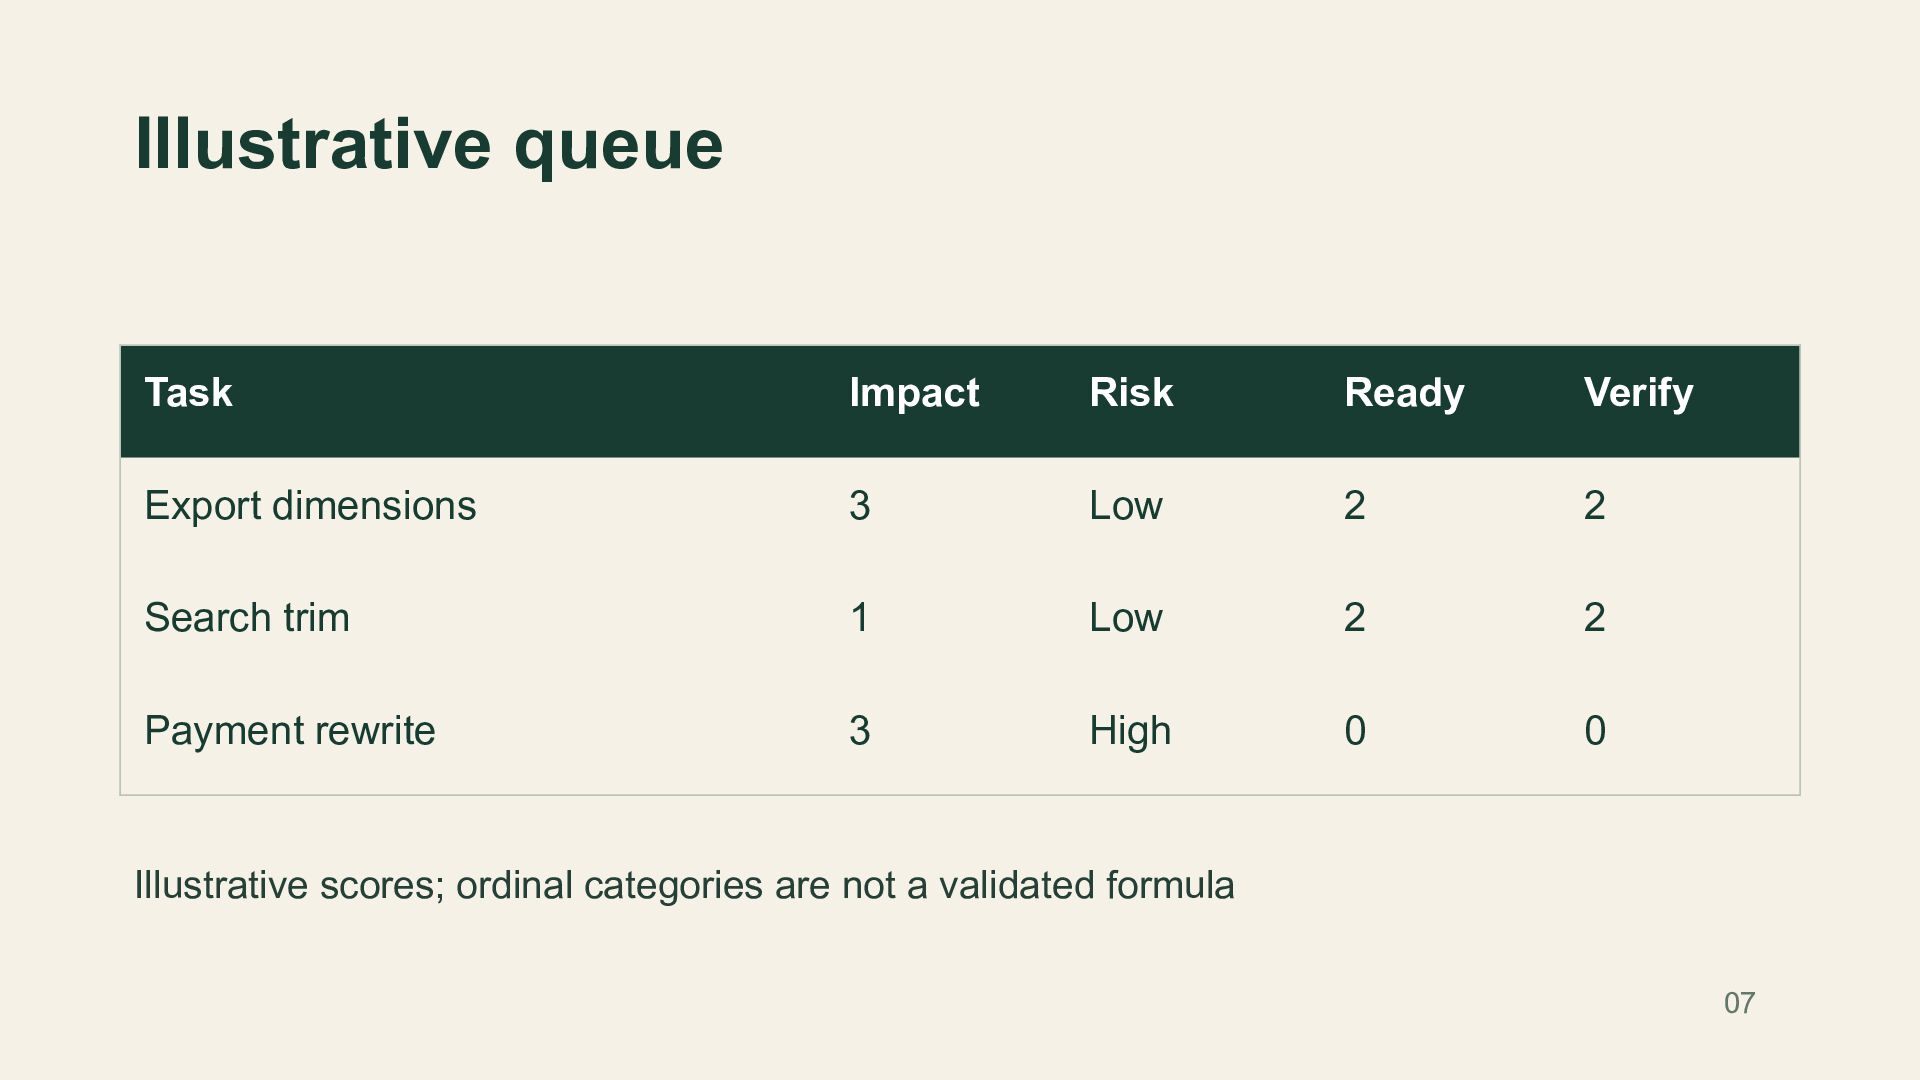
This deck offers a small queue rubric for human supervised AI execution. It separates impact, risk, readiness and verification so that a high-impact task cannot bypass missing context or an appropriate human decision. Three fictional technical tasks show how a reproducible export issue and a bounded search change can be ready for execution while a payment rewrite remains in preparation. The examples use ordinal scores to support discussion, rather than claiming a validated productivity formula. The preparer defines the outcome, an authorized executor uses their own tools, and a named reviewer judges acceptance. Token consumption remains an operating cost, not evidence that useful work was completed. The Wagglet discussion of work rewards provides context for keeping the reward tied to the result. AI prepared the outline; human organizational review and any real-world outcome evaluation remain open.


 asamiiiiiii
 takuroabe
 nttcom
 teamlab
 kenichiodo
 yu23ki14
 endonanana
 kairim0
 keeg
 satomasahiro2005
 shugo
 kworkdev
 akhino
 smashingmag
 erikaheidi
 skipperchong
 retrage
 thekraken
 yeseniaperezcruz
 iamctodd
 tammyeverts
 lara
 mfonobong
 sarafernandez
 ryanjones