Share
Modern Data Pipelines using Kafka Streaming and Kubernetes
Recursion Pharmaceuticals is turning drug discovery into a data science problem which entails generating petabytes of microscopy images from carefully designed biological experiments. In early 2017 the data generation effort scaled to a point where the existing batch processing system was not sufficient. New use cases required that the batch system be replaced with a streaming system. After evaluating the typical contenders in this space, e.g. Spark and Storm, we settled on using Kafka Streaming and Kubernetes instead. By building on top of Kafka and Kubernetes we were able to build a flexible, highly available, and robust pipeline with container support built in. This presentation will walk you through our thought process and explain the tradeoffs between all of these systems in light of our specific use case. We will give a high level introduction to Kafka Streaming and the workflow layer we were able to easily add on top of it that orchestrated our existing microservices. We'll also explain how we leverage Kubernetes Jobs with a custom in-memory task queue system, TaskStore, that we wrote. We've been operating at scale with these two systems for a year now with success, albeit with some war stories. In the end we find this solution much easier to work with than behemoth frameworks and, due to the robustness of these two systems, are able to operate it at much lower costs using preemptible Goolge Cloud instances.
Ben Mabey
Transcript
191 slides
-
Ben Mabey VP of Engineering Modern Data Pipelines using Kafka
Streaming and Kubernetes Scott Nielsen Director of Data Engineering Utah Data Engineering Meetup, October 2018 -
0.00001 0.0001 0.001 0.01 0.1 1 10 100 1000 1971
1972 1973 1974 1975 1976 1977 1978 1979 1980 1981 1982 1983 1984 1985 1986 1987 1988 1989 1990 1991 1992 1993 1994 1995 1996 1997 1998 1999 2000 2001 2002 2003 2004 2005 2006 2007 2008 2009 2010 2011 2012 2013 2014 2015 Transistor Area (% of 1970 values) Moore’s Law -
0.00001 0.0001 0.001 0.01 0.1 1 10 100 1000 1971
1972 1973 1974 1975 1976 1977 1978 1979 1980 1981 1982 1983 1984 1985 1986 1987 1988 1989 1990 1991 1992 1993 1994 1995 1996 1997 1998 1999 2000 2001 2002 2003 2004 2005 2006 2007 2008 2009 2010 2011 2012 2013 2014 2015 Transistor Area (% of 1970 values) Moore’s Law Eroom’s Law -
0.00001 0.0001 0.001 0.01 0.1 1 10 100 1000 1971
1972 1973 1974 1975 1976 1977 1978 1979 1980 1981 1982 1983 1984 1985 1986 1987 1988 1989 1990 1991 1992 1993 1994 1995 1996 1997 1998 1999 2000 2001 2002 2003 2004 2005 2006 2007 2008 2009 2010 2011 2012 2013 2014 2015 Transistor Area (% of 1970 values) 1 10 100 1971 1972 1973 1974 1975 1976 1977 1978 1979 1980 1981 1982 1983 1984 1985 1986 1987 1988 1989 1990 1991 1992 1993 1994 1995 1996 1997 1998 1999 2000 2001 2002 2003 2004 2005 2006 2007 2008 2009 2010 R&D Spend / Drug (% of 2007 values) Moore’s Law Eroom’s Law -
Healthy child Healthy cells Child with rare genetic disease (Cornelia
de Lange Syndrome) Genetic disease model cells (Cornelia de Lange Syndrome) -
86mm 2mm 86mm 2mm 86mm 2mm 86mm 2mm 6 channels
(images)/site 7,392 images per plate 4 sites/well 308 wells/plate -
86mm 2mm 86mm 2mm 86mm 2mm 86mm 2mm 6 channels
(images)/site 7,392 images per plate 4 sites/well 308 wells/plate ~69GB per plate -
Images / channel level site (all channels/images) thumbnails site level
features image level metrics -
Images / channel level site (all channels/images) thumbnails site level
features image level metrics -
Images / channel level site (all channels/images) thumbnails site level
features image level metrics site metrics -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features image level metrics site metrics -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features image level metrics site metrics metrics -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features image level metrics site metrics metrics plate level features metrics -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc -
100 6.9TB 300 20TB 700 48TB 1,300 90TB 1,700 118TB
1,900 132 TB -
100 6.9TB 300 20TB 700 48TB 1,300 90TB 1,700 118TB
1,900 132 TB 3,600 250 TB -
Systems early 2017 •Microservices written in Python and Go. Some
were AWS lambdas while others were containerized, running on kubernetes. -
Systems early 2017 •Microservices written in Python and Go. Some
were AWS lambdas while others were containerized, running on kubernetes. •Main job queue ran on Google pub/sub with autoscaling feature. Experimenting with Kubernetes jobs for other use cases. -
Systems early 2017 •Microservices written in Python and Go. Some
were AWS lambdas while others were containerized, running on kubernetes. •Main job queue ran on Google pub/sub with autoscaling feature. Experimenting with Kubernetes jobs for other use cases. -
Systems early 2017 •Experiments processed in batch once an experiment
was complete. •Microservices written in Python and Go. Some were AWS lambdas while others were containerized, running on kubernetes. •Main job queue ran on Google pub/sub with autoscaling feature. Experimenting with Kubernetes jobs for other use cases. -
Experiment A Experiment B Experiment C Experiment D Plates are
not imaged in order -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) site_metrics = site_features.map(compute_site_metrics) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) site_metrics = site_features.map(compute_site_metrics) well_site_features = site_features.groupBy(lambda s: s['well']) well_features = well_site_features.map(aggregate_site_to_well) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) site_metrics = site_features.map(compute_site_metrics) well_site_features = site_features.groupBy(lambda s: s['well']) well_features = well_site_features.map(aggregate_site_to_well) plate_features = well_site_features.groupBy(lambda w: w['plate']) plate_metrics = plate_features.map(calc_plate_features) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) site_metrics = site_features.map(compute_site_metrics) well_site_features = site_features.groupBy(lambda s: s['well']) well_features = well_site_features.map(aggregate_site_to_well) plate_features = well_site_features.groupBy(lambda w: w['plate']) plate_metrics = plate_features.map(calc_plate_features) experiment_features = plate_features.groupBy(lambda p: p['experiment']) experiment_metrics = (experiment_features .map(lambda e: e[‘experiment']).map(calc_exp_metrics)) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc (pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) site_metrics = site_features.map(compute_site_metrics) well_site_features = site_features.groupBy(lambda s: s['well']) well_features = well_site_features.map(aggregate_site_to_well) plate_features = well_site_features.groupBy(lambda w: w['plate']) plate_metrics = plate_features.map(calc_plate_features) experiment_features = plate_features.groupBy(lambda p: p['experiment']) experiment_metrics = (experiment_features .map(lambda e: e[‘experiment']).map(calc_exp_metrics)) reports = experiment_features.map(lambda e: e['experiment']).map(run_report) -
(pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda
i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) site_metrics = site_features.map(compute_site_metrics) well_site_features = site_features.groupBy(lambda s: s['well']) well_features = well_site_features.map(aggregate_site_to_well) plate_features = well_site_features.groupBy(lambda w: w['plate']) plate_metrics = plate_features.map(calc_plate_features) experiment_features = plate_features.groupBy(lambda p: p['experiment']) experiment_metrics = (experiment_features .map(lambda e: e[‘experiment']).map(calc_exp_metrics)) reports = experiment_features.map(lambda e: e['experiment']).map(run_report) -
(pseudocode) images = get_images_rdd_for_experiment('foo') image_metrics = images.map(compute_image_metrics) sites = images.groupBy(lambda
i: (i['plate'], i['site'])) site_features = sites.map(lambda i: extract_features(i['data'])) site_metrics = site_features.map(compute_site_metrics) well_site_features = site_features.groupBy(lambda s: s['well']) well_features = well_site_features.map(aggregate_site_to_well) plate_features = well_site_features.groupBy(lambda w: w['plate']) plate_metrics = plate_features.map(calc_plate_features) experiment_features = plate_features.groupBy(lambda p: p['experiment']) experiment_metrics = (experiment_features .map(lambda e: e[‘experiment']).map(calc_exp_metrics)) reports = experiment_features.map(lambda e: e['experiment']).map(run_report) ? -
Why not ? •Spark Streaming in 2017 with the mini
batch model would not allow us to express the workflow naturally. -
Why not ? •Spark Streaming in 2017 with the mini
batch model would not allow us to express the workflow naturally. •We didn’t want to rewrite any of the microservices. -
Why not ? •Spark Streaming in 2017 with the mini
batch model would not allow us to express the workflow naturally. •We didn’t want to rewrite any of the microservices. •Some of our “map” operations are dependency heavy and have high variation in memory usage which requires fine tuning of workers for that particular function/task. -
Why not ? •Spark Streaming in 2017 with the mini
batch model would not allow us to express the workflow naturally. •We didn’t want to rewrite any of the microservices. •Some of our “map” operations are dependency heavy and have high variation in memory usage which requires fine tuning of workers for that particular function/task. •Cloud providers didn’t have container support. No Kubernetes support then either. (now in beta) -
Why not ? •Spark Streaming in 2017 with the mini
batch model would not allow us to express the workflow naturally. •We didn’t want to rewrite any of the microservices. •Some of our “map” operations are dependency heavy and have high variation in memory usage which requires fine tuning of workers for that particular function/task. •Cloud providers didn’t have container support. No Kubernetes support then either. (now in beta) -
Why not ? •Spark Streaming in 2017 with the mini
batch model would not allow us to express the workflow naturally. •We didn’t want to rewrite any of the microservices. •Some of our “map” operations are dependency heavy and have high variation in memory usage which requires fine tuning of workers for that particular function/task. •Cloud providers didn’t have container support. No Kubernetes support then either. (now in beta) -
What about ? •Probably the closest to what we wanted/needed.
But… •The migration path was still unclear with all of our microservices. -
What about ? •Probably the closest to what we wanted/needed.
But… •The migration path was still unclear with all of our microservices. •Lots of operational complexity around running a Storm cluster. No Kubernetes support. -
What about ? •Probably the closest to what we wanted/needed.
But… •The migration path was still unclear with all of our microservices. •Lots of operational complexity around running a Storm cluster. No Kubernetes support. •Popularity seemed to be fading. -
What about ? •Probably the closest to what we wanted/needed.
But… •The migration path was still unclear with all of our microservices. •Lots of operational complexity around running a Storm cluster. No Kubernetes support. •Popularity seemed to be fading. •The real reason… it was 2017. Better cluster and streaming primitives existed. -
What about ? •Probably the closest to what we wanted/needed.
But… •The migration path was still unclear with all of our microservices. •Lots of operational complexity around running a Storm cluster. No Kubernetes support. •Popularity seemed to be fading. •The real reason… it was 2017. Better cluster and streaming primitives existed. -
With all of these stream processors you still needed to
provide a stream (queue)… -
ANATOMY OF A KAFKA TOPIC Partition 0 Partition 0 Partition
0 Partition 1 Partition 1 Partition 1 Partition 2 Partition 2 Partition 2 A partitioned and replicated structured commit log -
KAFKA STREAMS Obligatory Word Count Example final Serde<String> stringSerde =
Serdes.String(); final Serde<Long> longSerde = Serdes.Long(); -
KAFKA STREAMS Obligatory Word Count Example final Serde<String> stringSerde =
Serdes.String(); final Serde<Long> longSerde = Serdes.Long(); KStream<String, String> textLines = builder.stream("streams-plaintext-input", Consumed.with(stringSerde, stringSerde); -
KAFKA STREAMS Obligatory Word Count Example final Serde<String> stringSerde =
Serdes.String(); final Serde<Long> longSerde = Serdes.Long(); KStream<String, String> textLines = builder.stream("streams-plaintext-input", Consumed.with(stringSerde, stringSerde); KTable<String, Long> wordCounts = textLines .flatMapValues(value -> Arrays.asList(value.toLowerCase().split("\\W+"))) -
KAFKA STREAMS Obligatory Word Count Example final Serde<String> stringSerde =
Serdes.String(); final Serde<Long> longSerde = Serdes.Long(); KStream<String, String> textLines = builder.stream("streams-plaintext-input", Consumed.with(stringSerde, stringSerde); KTable<String, Long> wordCounts = textLines .flatMapValues(value -> Arrays.asList(value.toLowerCase().split("\\W+"))) .groupBy((key, value) -> value) -
KAFKA STREAMS Obligatory Word Count Example final Serde<String> stringSerde =
Serdes.String(); final Serde<Long> longSerde = Serdes.Long(); KStream<String, String> textLines = builder.stream("streams-plaintext-input", Consumed.with(stringSerde, stringSerde); KTable<String, Long> wordCounts = textLines .flatMapValues(value -> Arrays.asList(value.toLowerCase().split("\\W+"))) .groupBy((key, value) -> value) .count() -
KAFKA STREAMS Obligatory Word Count Example final Serde<String> stringSerde =
Serdes.String(); final Serde<Long> longSerde = Serdes.Long(); KStream<String, String> textLines = builder.stream("streams-plaintext-input", Consumed.with(stringSerde, stringSerde); KTable<String, Long> wordCounts = textLines .flatMapValues(value -> Arrays.asList(value.toLowerCase().split("\\W+"))) .groupBy((key, value) -> value) .count() wordCounts.toStream().to("streams-wordcount-output", Produced.with(Serdes.String(), Serdes.Long())); -
dagger workflow library written on top of Kafka Streams that
orchestrates microservices -
dagger workflow library written on top of Kafka Streams that
orchestrates microservices Dagger, ya know, because it is all about the workflows represented as directed acyclic graphs, i.e. DAGs. -
dagger workflow library written on top of Kafka Streams that
orchestrates microservices -
core logic ~2700 LOC All of our our DAGs, including
schema, task, and workflow definition ~1700 LOC How big is it? -
core logic ~2700 LOC All of our our DAGs, including
schema, task, and workflow definition ~1700 LOC How big is it? -
DAGGER CONCEPTUAL OVERVIEW Schemas - What does my data look
like Topics - Where is my data coming from / going to -
DAGGER CONCEPTUAL OVERVIEW Schemas - What does my data look
like Topics - Where is my data coming from / going to External Tasks - Triggers actions outside of the streams application -
DAGGER CONCEPTUAL OVERVIEW Schemas - What does my data look
like Topics - Where is my data coming from / going to External Tasks - Triggers actions outside of the streams application DAGs - Combines schemas, topics, and tasks into a complete workflow -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc -
images_channel (d/register-schema! system (d/record "channel_level" ["experiment_id" "string"] ["cell_type" "string"] ["plate_number"
"int"] ["plate_barcode" "string"] ["well" "string"] ["site" "int"] ["channel" "int"] ["location" "string"])) Kafka topic, images_channel, a message for each image -
images_channel (d/register-schema! system (d/record "channel_level" ["experiment_id" "string"] ["cell_type" "string"] ["plate_number"
"int"] ["plate_barcode" "string"] ["well" "string"] ["site" "int"] ["channel" "int"] ["location" "string"])) Everything is serialized to Avro Kafka topic, images_channel, a message for each image -
images_channel (d/register-schema! system (d/record "channel_level" ["experiment_id" "string"] ["cell_type" "string"] ["plate_number"
"int"] ["plate_barcode" "string"] ["well" "string"] ["site" "int"] ["channel" "int"] ["location" "string"])) Everything is serialized to Avro In the future will use the Confluent Schema Registry Kafka topic, images_channel, a message for each image -
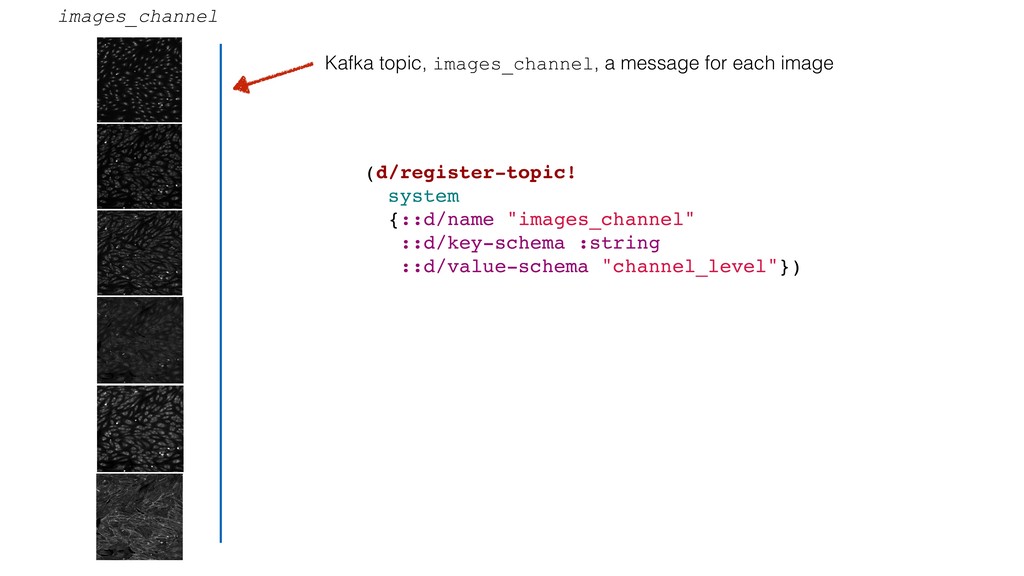
images_channel Kafka topic, images_channel, a message for each image (d/register-topic!
system {::d/name "images_channel" ::d/key-schema :string ::d/value-schema "channel_level"}) -
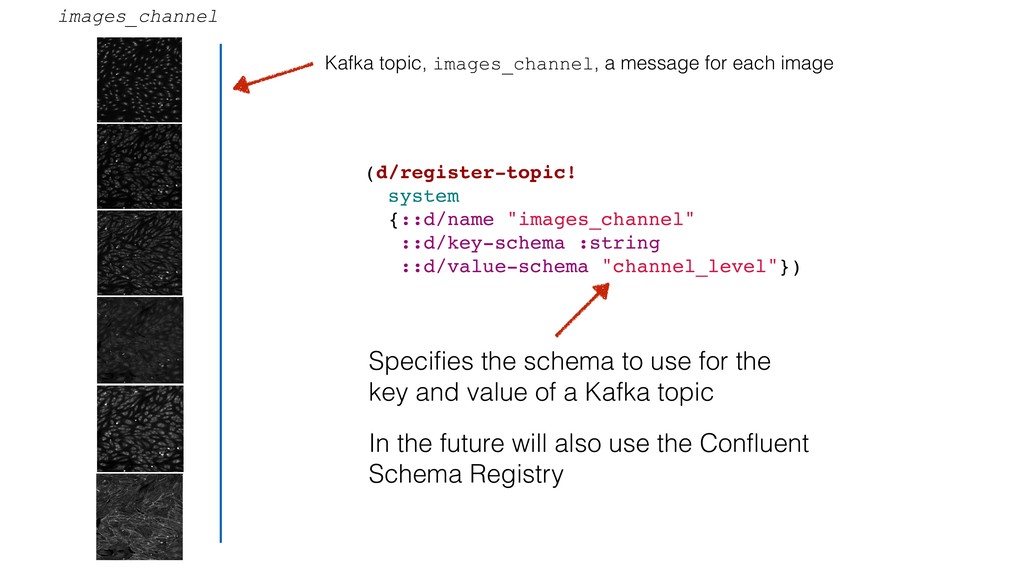
images_channel Kafka topic, images_channel, a message for each image (d/register-topic!
system {::d/name "images_channel" ::d/key-schema :string ::d/value-schema "channel_level"}) Specifies the schema to use for the key and value of a Kafka topic -
images_channel Kafka topic, images_channel, a message for each image (d/register-topic!
system {::d/name "images_channel" ::d/key-schema :string ::d/value-schema "channel_level"}) Specifies the schema to use for the key and value of a Kafka topic In the future will also use the Confluent Schema Registry -
images_channel image level metrics (d/register-task! system metrics-registry {::d/name “image-level-metrics“ ::d/doc
“Extracts descriptive pixel stats from images" ::d/input {::d/schema “channel_level"} ::d/output {::d/name “image_stats_results" ::d/schema “image_stats_results"}}) ::d/input {::d/schema “channel_level"} -
images_channel image level metrics (d/register-task! system metrics-registry {::d/name “image-level-metrics“ ::d/doc
“Extracts descriptive pixel stats from images" ::d/input {::d/schema “channel_level"} ::d/output {::d/name “image_stats_results" ::d/schema “image_stats_results"}}) Creates a task input topic to be consumed by an external service Dagger DAG (Kafka Streams App) Kafka Dagger Task (External Service) task input topic ::d/input {::d/schema “channel_level"} -
images_channel image level metrics (d/register-task! system metrics-registry {::d/name “image-level-metrics“ ::d/doc
“Extracts descriptive pixel stats from images" ::d/input {::d/schema “channel_level"} ::d/output {::d/name “image_stats_results" ::d/schema “image_stats_results"}}) Optionally creates a task output topic where the external service will publish results Creates a task input topic to be consumed by an external service Dagger DAG (Kafka Streams App) Kafka Dagger Task (External Service) task input topic task output topic ::d/output {::d/name “image_stats_results" ::d/schema “image_stats_results"}}) -
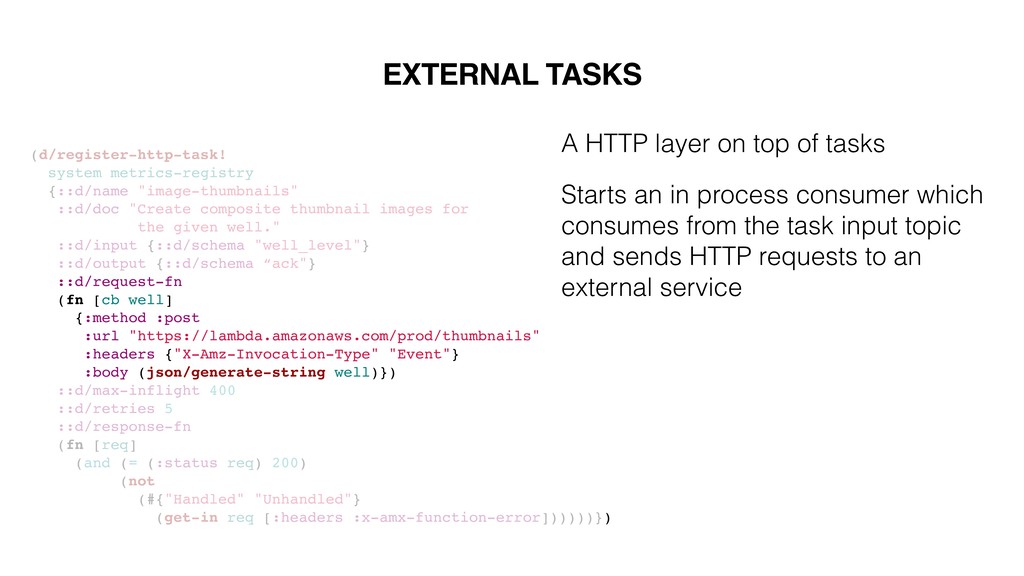
(d/register-http-task! system metrics-registry {::d/name "image-thumbnails" ::d/doc "Create composite thumbnail images
for the given well." ::d/input {::d/schema "well_level"} ::d/output {::d/schema “ack"} ::d/request-fn (fn [cb well] {:method :post :url "https://lambda.amazonaws.com/prod/thumbnails" :headers {"X-Amz-Invocation-Type" "Event"} :body (json/generate-string well)}) ::d/max-inflight 400 ::d/retries 5 ::d/response-fn (fn [req] (and (= (:status req) 200) (not (#{"Handled" "Unhandled"} (get-in req [:headers :x-amx-function-error])))))}) EXTERNAL TASKS -
(d/register-http-task! system metrics-registry {::d/name "image-thumbnails" ::d/doc "Create composite thumbnail images
for the given well." ::d/input {::d/schema "well_level"} ::d/output {::d/schema “ack"} ::d/request-fn (fn [cb well] {:method :post :url "https://lambda.amazonaws.com/prod/thumbnails" :headers {"X-Amz-Invocation-Type" "Event"} :body (json/generate-string well)}) ::d/max-inflight 400 ::d/retries 5 ::d/response-fn (fn [req] (and (= (:status req) 200) (not (#{"Handled" "Unhandled"} (get-in req [:headers :x-amx-function-error])))))}) EXTERNAL TASKS A HTTP layer on top of tasks -
(d/register-http-task! system metrics-registry {::d/name "image-thumbnails" ::d/doc "Create composite thumbnail images
for the given well." ::d/input {::d/schema "well_level"} ::d/output {::d/schema “ack"} ::d/request-fn (fn [cb well] {:method :post :url "https://lambda.amazonaws.com/prod/thumbnails" :headers {"X-Amz-Invocation-Type" "Event"} :body (json/generate-string well)}) ::d/max-inflight 400 ::d/retries 5 ::d/response-fn (fn [req] (and (= (:status req) 200) (not (#{"Handled" "Unhandled"} (get-in req [:headers :x-amx-function-error])))))}) EXTERNAL TASKS A HTTP layer on top of tasks Starts an in process consumer which consumes from the task input topic and sends HTTP requests to an external service -
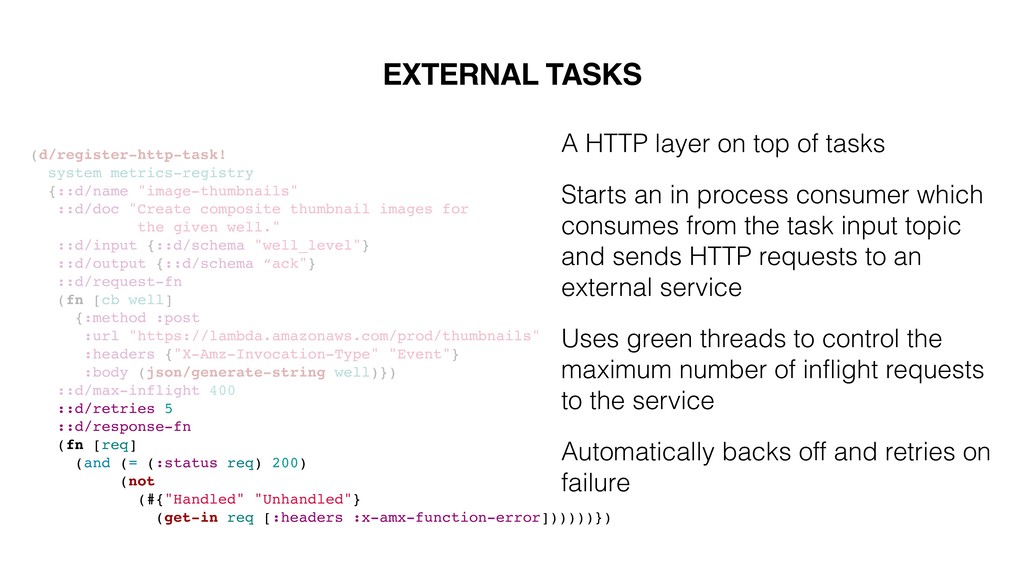
(d/register-http-task! system metrics-registry {::d/name "image-thumbnails" ::d/doc "Create composite thumbnail images
for the given well." ::d/input {::d/schema "well_level"} ::d/output {::d/schema “ack"} ::d/request-fn (fn [cb well] {:method :post :url "https://lambda.amazonaws.com/prod/thumbnails" :headers {"X-Amz-Invocation-Type" "Event"} :body (json/generate-string well)}) ::d/max-inflight 400 ::d/retries 5 ::d/response-fn (fn [req] (and (= (:status req) 200) (not (#{"Handled" "Unhandled"} (get-in req [:headers :x-amx-function-error])))))}) EXTERNAL TASKS A HTTP layer on top of tasks Starts an in process consumer which consumes from the task input topic and sends HTTP requests to an external service Uses green threads to control the maximum number of inflight requests to the service -
(d/register-http-task! system metrics-registry {::d/name "image-thumbnails" ::d/doc "Create composite thumbnail images
for the given well." ::d/input {::d/schema "well_level"} ::d/output {::d/schema “ack"} ::d/request-fn (fn [cb well] {:method :post :url "https://lambda.amazonaws.com/prod/thumbnails" :headers {"X-Amz-Invocation-Type" "Event"} :body (json/generate-string well)}) ::d/max-inflight 400 ::d/retries 5 ::d/response-fn (fn [req] (and (= (:status req) 200) (not (#{"Handled" "Unhandled"} (get-in req [:headers :x-amx-function-error])))))}) EXTERNAL TASKS A HTTP layer on top of tasks Starts an in process consumer which consumes from the task input topic and sends HTTP requests to an external service Uses green threads to control the maximum number of inflight requests to the service Automatically backs off and retries on failure -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc -
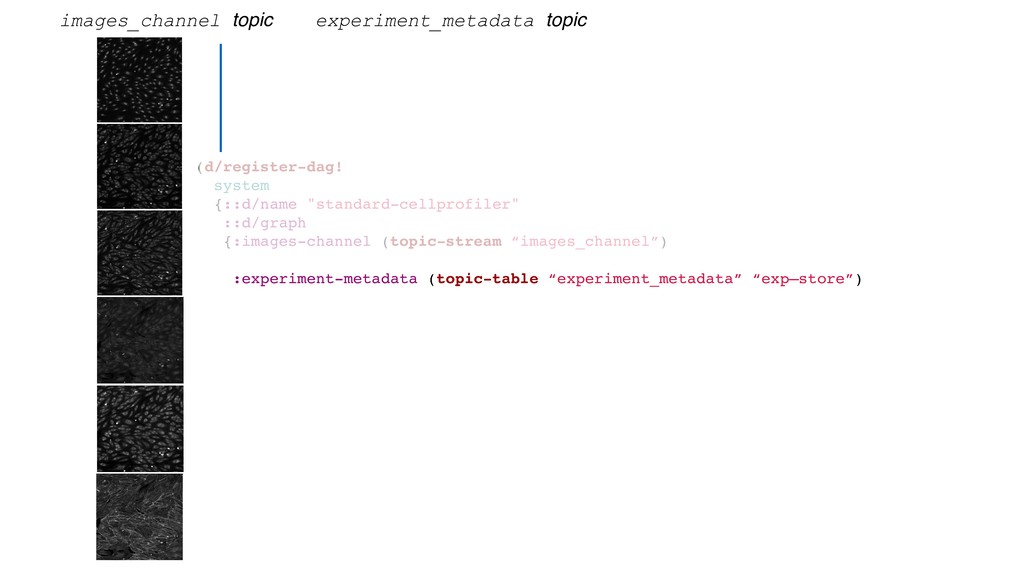
images_channel topic experiment_metadata topic (d/register-dag! system {::d/name "standard-cellprofiler" ::d/graph {:images-channel
(topic-stream “images_channel”) :experiment-metadata (topic-table “experiment_metadata” “exp—store”) -
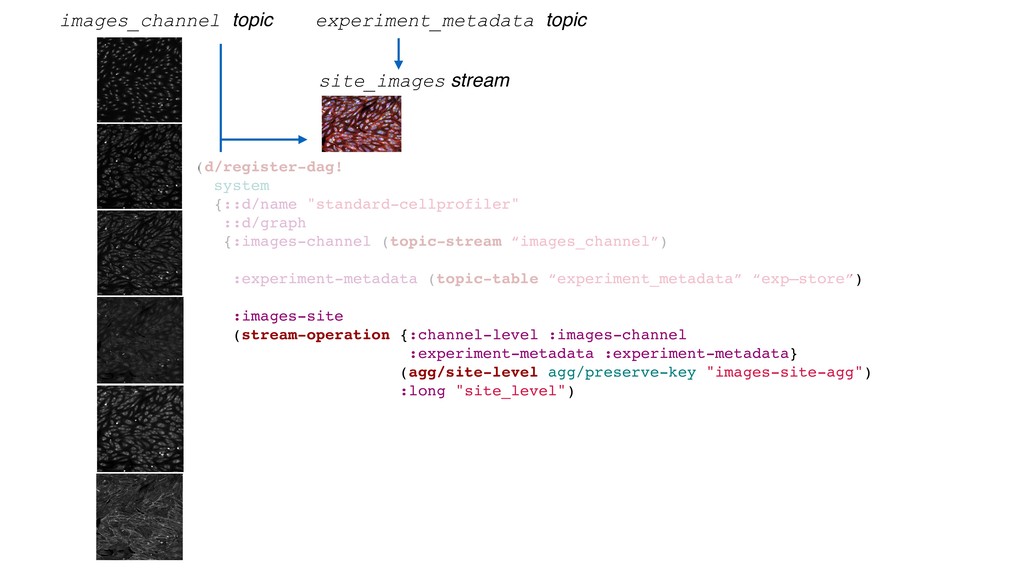
site_images stream images_channel topic experiment_metadata topic (d/register-dag! system {::d/name "standard-cellprofiler"
::d/graph {:images-channel (topic-stream “images_channel”) :experiment-metadata (topic-table “experiment_metadata” “exp—store”) :images-site (stream-operation {:channel-level :images-channel :experiment-metadata :experiment-metadata} (agg/site-level agg/preserve-key "images-site-agg") :long "site_level") -
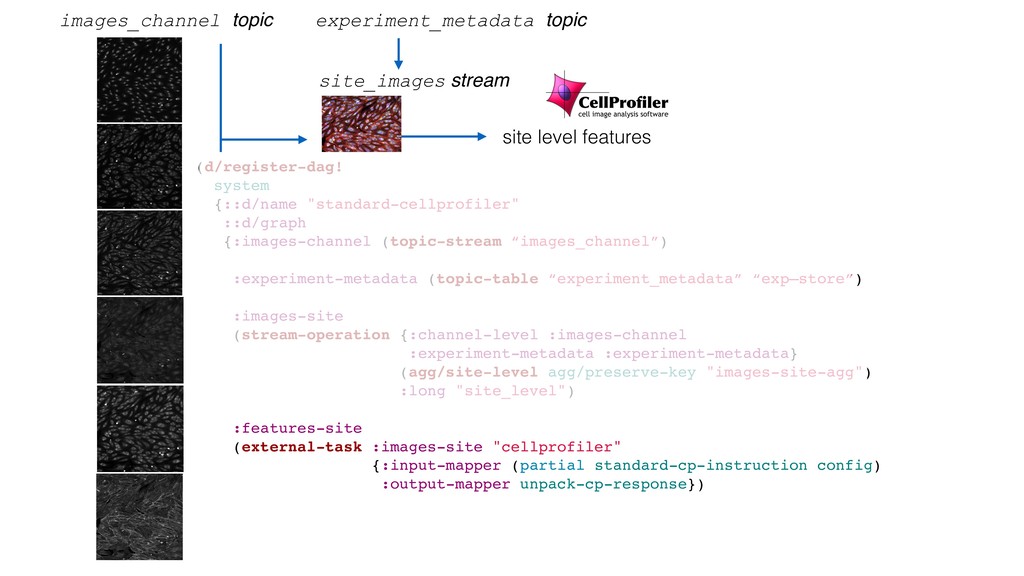
site level features site_images stream images_channel topic experiment_metadata topic (d/register-dag!
system {::d/name "standard-cellprofiler" ::d/graph {:images-channel (topic-stream “images_channel”) :experiment-metadata (topic-table “experiment_metadata” “exp—store”) :images-site (stream-operation {:channel-level :images-channel :experiment-metadata :experiment-metadata} (agg/site-level agg/preserve-key "images-site-agg") :long "site_level") :features-site (external-task :images-site "cellprofiler" {:input-mapper (partial standard-cp-instruction config) :output-mapper unpack-cp-response}) -
site level features site_images stream images_channel topic experiment_metadata topic cellprofiler_features
topic (d/register-dag! system {::d/name "standard-cellprofiler" ::d/graph {:images-channel (topic-stream “images_channel”) :experiment-metadata (topic-table “experiment_metadata” “exp—store”) :images-site (stream-operation {:channel-level :images-channel :experiment-metadata :experiment-metadata} (agg/site-level agg/preserve-key "images-site-agg") :long "site_level") :features-site (external-task :images-site "cellprofiler" {:input-mapper (partial standard-cp-instruction config) :output-mapper unpack-cp-response}) :features-output (publish :features-site "cellprofiler_features")}}) -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc -
86mm 2mm well level features Images / channel level site
(all channels/images) thumbnails site level features experiment features image level metrics site metrics metrics plate level features metrics metrics, models, reports, etc -
Systems early 2017 •Experiments processed in batch once an experiment
was complete. •Microservices written in Python and Go. Some were AWS lambdas while others were containerized, running on kubernetes. •Main job queue ran on Google pub/sub with autoscaling feature. Experimenting with Kubernetes jobs for other use cases. -
Job queue desiderata •Language agnostic •Container support, ideally on top
of Kubernetes •Autoscaling -
Job queue desiderata •Language agnostic •Container support, ideally on top
of Kubernetes •Autoscaling •Sane retry and backoff semantics to handle common failure modes -
So, we built one. We call it taskstore. server ~2300
LOC worker ~800 LOC -
Kubernetes Master Node API Scheduler Controller Manager Node Pod Pod
Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod KUBERNETES: AN OS FOR THE CLUSTER -
CONTROLLER RESOURCES Manage pods with higher level semantics Replication Controller
- runs N copies of a pod across the cluster -
CONTROLLER RESOURCES Manage pods with higher level semantics Replication Controller
- runs N copies of a pod across the cluster Deployment - uses multiple replication controllers to provide rolling deployments -
CONTROLLER RESOURCES Manage pods with higher level semantics Replication Controller
- runs N copies of a pod across the cluster Deployment - uses multiple replication controllers to provide rolling deployments DaemonSet - runs one copy of a pod on each node in the cluster -
CONTROLLER RESOURCES Manage pods with higher level semantics Replication Controller
- runs N copies of a pod across the cluster Deployment - uses multiple replication controllers to provide rolling deployments DaemonSet - runs one copy of a pod on each node in the cluster Job - runs M copies of a pod until it has completed N times -
KUBERNETES: AN OS FOR THE CLUSTER Kubernetes Master Node API
Scheduler Controller Manager Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod -
KUBERNETES: AN OS FOR THE CLUSTER Node Pool (n1-standard-4, min:
2, max: 100) Autoscaler Node Pool (n1-standard-64, min: 0, max: 300) Kubernetes Master Node API Scheduler Controller Manager Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod Node Pod Pod Pod Pod Pod -
Server Client Group A Group X POST /groups A Group
is an ordered queue of tasks to be executed. -
Server Client Group A Group X POST /groups A Group
is an ordered queue of tasks to be executed. Max time before a task is presumed hanging and execution is halted -
Server Client Group A Group X POST /groups A Group
is an ordered queue of tasks to be executed. Autoscaling settings dictate how many workers per tasks should be spun up. Max time before a task is presumed hanging and execution is halted -
Server Client Group A Group X POST /groups A Group
is an ordered queue of tasks to be executed. Autoscaling settings dictate how many workers per tasks should be spun up. Max time before a task is presumed hanging and execution is halted Retry settings handle common failure modes. More on this later. -
Server Client Group A Group X POST /tasks { "cmd":
["my-program.py", "url-to-data", "settings"], "group": "Group A", "labels": {"my-label": "is-good", "this-label": "is-helpful"} } -
Server Group A Group X Worker A Worker X POST
/tasks/claim { "groups": ["Group A"], "client-id": "client-123", "duration": 30000 } Request A Worker claims a task to work on for a period of time. -
Server Group A Group X Worker A Worker X POST
/tasks/claim { "groups": ["Group A"], "client-id": "client-123", "duration": 30000 } Request Response { "cmd": [“my-program.py","url-to-data", "settings"], "group": "Group A", "labels": {"my-label": "is-good", "this-label": "is-helpful"} "version": 1, "id": "5292d800-cdda-11e8-87d7-9d45611d "status": "available" } A Worker claims a task to work on for a period of time. -
Server Group A Group X Worker A Worker X POST
/tasks/claim Request A Worker claims a task to work on for a period of time. POST /tasks/extend-claim It must extend the lease of the task or else it will become available for another worker to claim it. { "client-id": "client-123", "duration": 30000, "id": "5292d800-cdda-11e8-87d7-9d45611de99b", "version": 1 } -
Server Group A Group X Worker A Worker X POST
/tasks/claim Request Response { … "version": 2, "id": "5292d800-cdda-11e8-87d7-9d45611de99b", } A Worker claims a task to work on for a period of time. POST /tasks/extend-claim It must extend the lease of the task or else it will become available for another worker to claim it. { "client-id": "client-123", "duration": 30000, "id": "5292d800-cdda-11e8-87d7-9d45611de99b", "version": 1 } -
Server Group A Group X Worker A Worker X POST
/tasks/success or POST /tasks/failure A Worker reports back when a task is finished executing. { "client-id": "client-123", “elapsed-time": 300232000, "id": "5292d800-cdda-11e8-87d7-9d45611de99b", "version": 43 } -
•The public cloud tide is rising •Crushing storage costs •Faster,
better, and cheaper cloud databases (e.g. BigQuery) -
•The public cloud tide is rising •Crushing storage costs •Faster,
better, and cheaper cloud databases (e.g. BigQuery) •Python and R data science running on containers and Kubernetes -
•The public cloud tide is rising •Crushing storage costs •Faster,
better, and cheaper cloud databases (e.g. BigQuery) •Python and R data science running on containers and Kubernetes As recently as this week, the big Hadoop vendors’ advice has been “translate Python/R code into Scala/Java,” which sounds like King Hadoop commanding the Python/R machine learning tide to go back out again. Containers and Kubernetes work just as well with Python and R as they do with Java and Scala, and provide a far more flexible and powerful framework for distributed computation. And it’s where software development teams are heading anyway – they’re not looking to distribute new microservice applications on top of Hadoop/Spark. Too complicated and limiting.