Share
Embed
Google's Cloud Datastore
This talk will provide an overview over the core concepts, discuss limitations enforced by the underlying distributed storage system, and how the Datastore performs in combination with Google App Engine. A special focus is on the entity group concept, which is important to guarantee good scalability and to keep performance high.
The Datastore is a fully managed schemaless database and part of the Google Cloud Platform. It’s available in many of Google’s cloud services, or can be used as standalone data backend. At the moment Philipp is working on his master’s thesis which includes an extensive analysis of Google App Engine in combination with the Datastore as data storage backend.
Philipp Naderer
April 27, 2015
Transcript
42 slides
-
My Background • @botic on Twitter / Github / …
• Working at ORF.at since 2001 ◦ Web Frontend Dev & Accessibility ◦ RingoJS Maintainer – ringojs.org • Student @ Vienna University of Technology ◦ Software Engineering, writing my master’s thesis • Coworking Seestern Aspern ◦ Cohousing Project in Vienna ◦ coworking.seestern-aspern.at -
My Master’s Thesis Find methods and tools to test cloud
platforms like Google App Engine for • fast response times • elasticity and scalability and spot potential bottlenecks for Java applications. A special focus is on migrating JVM- based applications into App Engine. -
Google App Engine (GAE) • Google’s PaaS offering ◦ fully-managed
services ◦ support Python and Java (PHP and Go in beta) • Specialized on web applications ◦ requests form the basic lifecycle of code execution ◦ optimized web stack (Caching, TLS, SPDY, QUIC, IPv6) • Runs and manages application instances ◦ autoscales individual instances based on containers ◦ instances are lightweight and non-persistent -
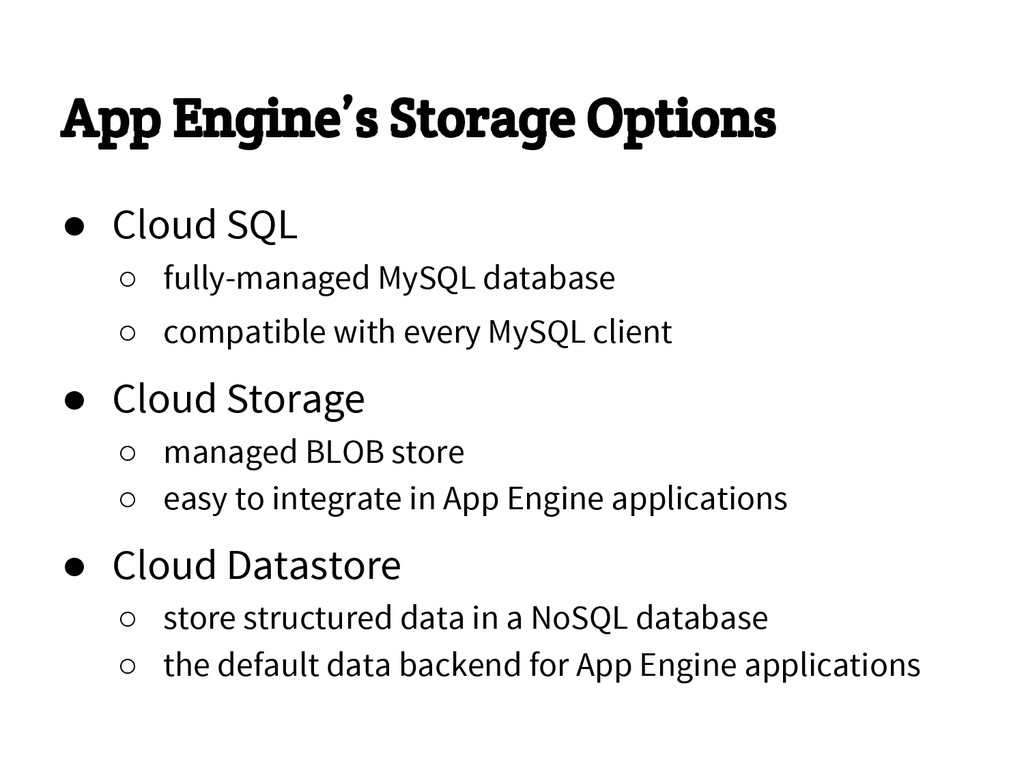
App Engine’s Storage Options • Cloud SQL ◦ fully-managed MySQL
database ◦ compatible with every MySQL client • Cloud Storage ◦ managed BLOB store ◦ easy to integrate in App Engine applications • Cloud Datastore ◦ store structured data in a NoSQL database ◦ the default data backend for App Engine applications -
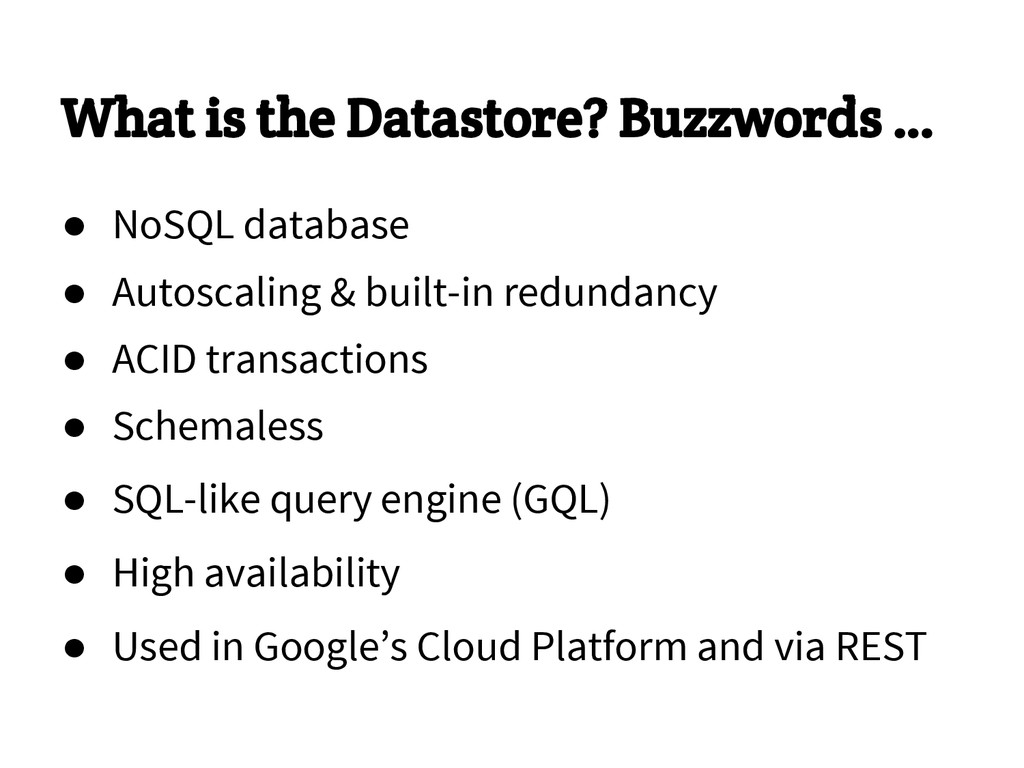
What is the Datastore? Buzzwords … • NoSQL database •
Autoscaling & built-in redundancy • ACID transactions • Schemaless • SQL-like query engine (GQL) • High availability • Used in Google’s Cloud Platform and via REST -
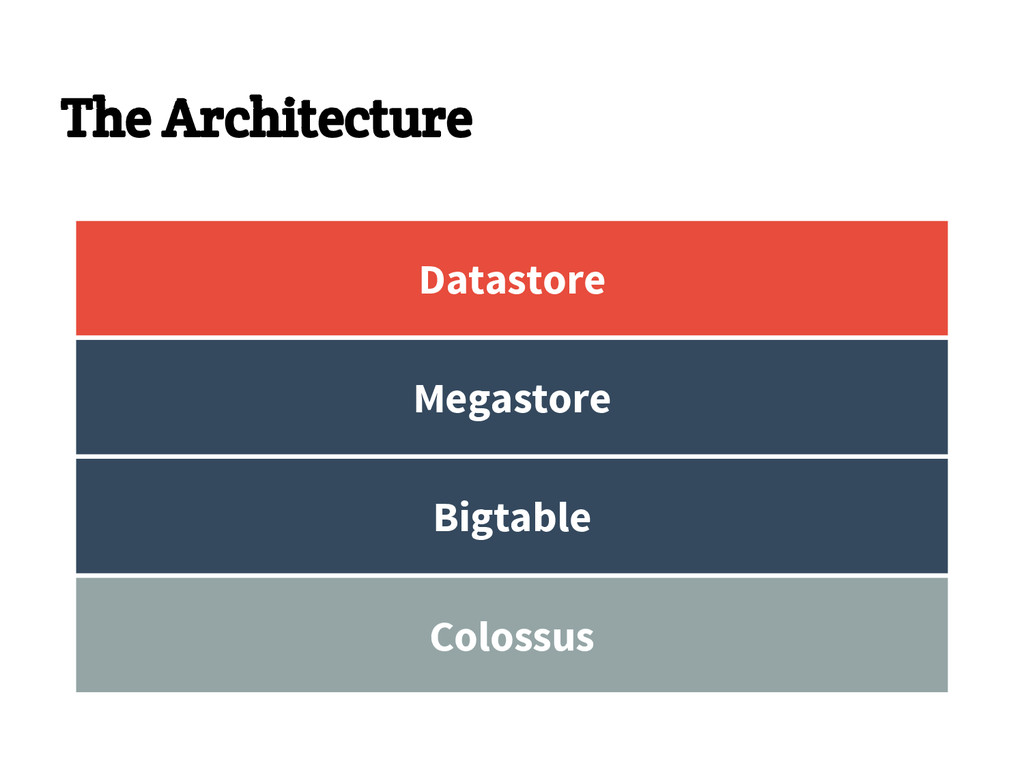
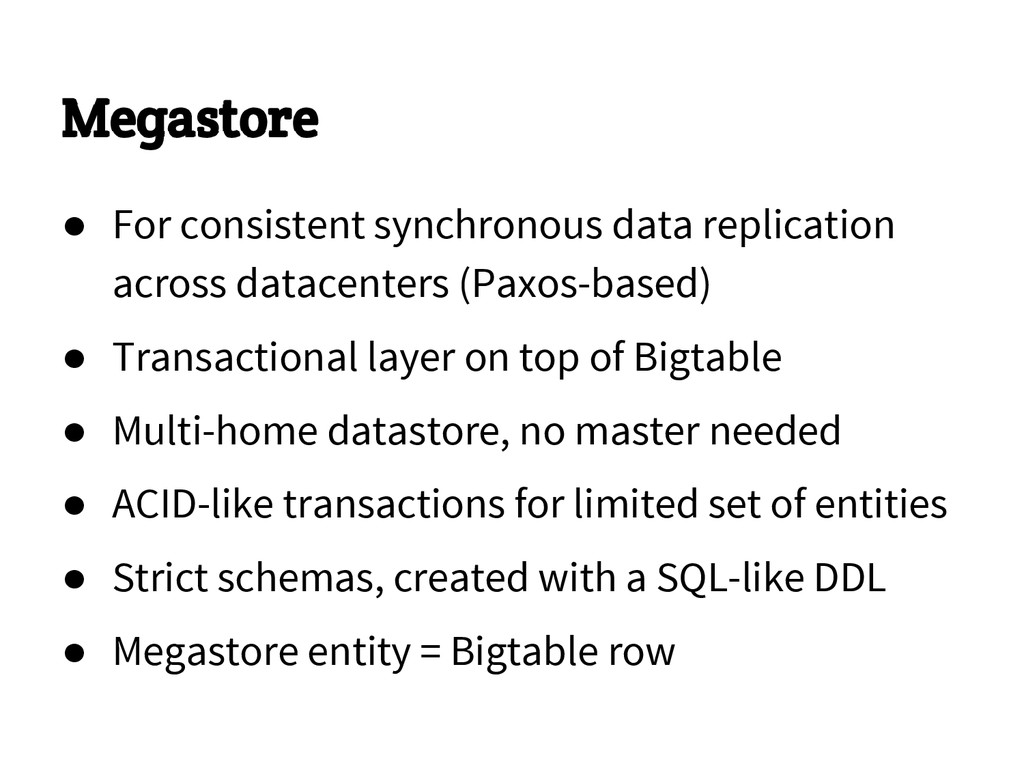
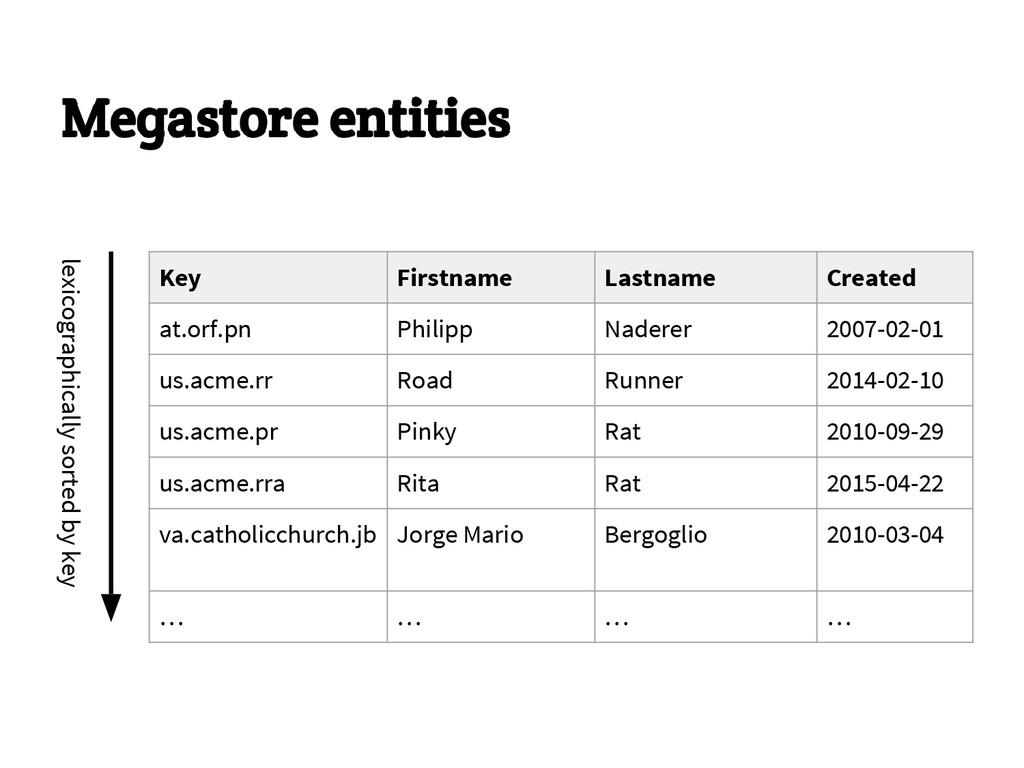
Megastore • For consistent synchronous data replication across datacenters (Paxos-based)
• Transactional layer on top of Bigtable • Multi-home datastore, no master needed • ACID-like transactions for limited set of entities • Strict schemas, created with a SQL-like DDL • Megastore entity = Bigtable row -
Megastore entities Key Firstname Lastname Created at.orf.pn Philipp Naderer 2007-02-01
us.acme.rr Road Runner 2014-02-10 us.acme.pr Pinky Rat 2010-09-29 us.acme.rra Rita Rat 2015-04-22 va.catholicchurch.jb Jorge Mario Bergoglio 2010-03-04 … … … … lexicographically sorted by key -
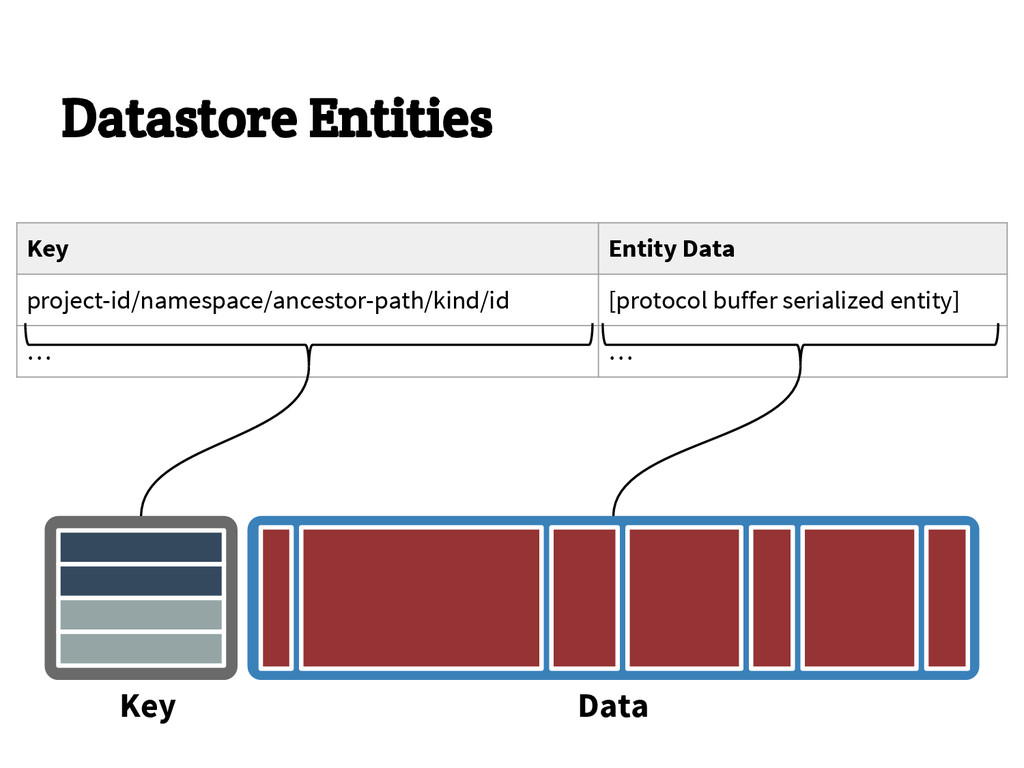
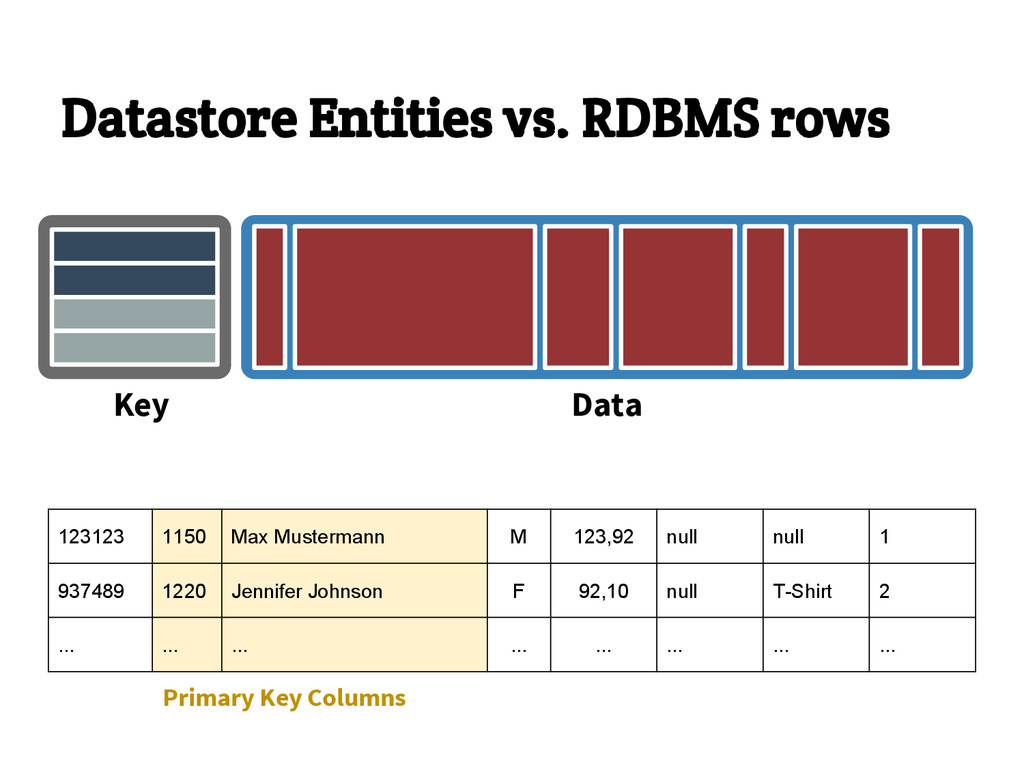
Datastore Entities vs. RDBMS rows Key Data 123123 1150 Max
Mustermann M 123,92 null null 1 937489 1220 Jennifer Johnson F 92,10 null T-Shirt 2 ... ... ... ... ... ... ... ... Primary Key Columns -
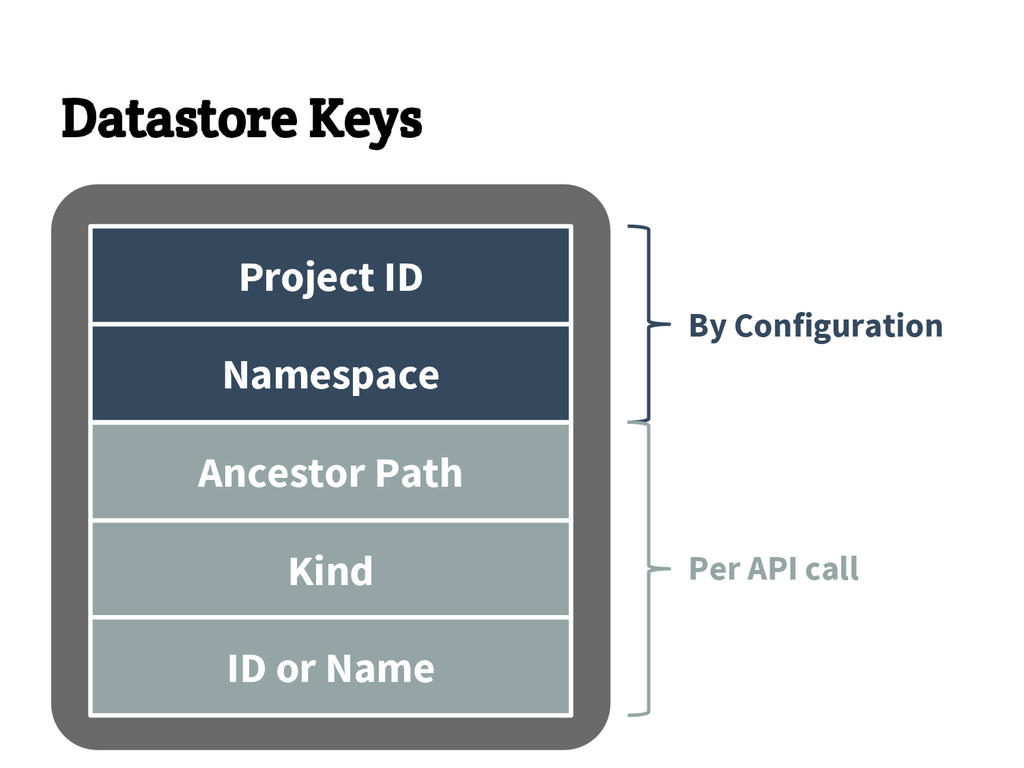
Datastore Keys Project ID Namespace By Configuration Per API call
Ancestor Path Kind ID or Name -
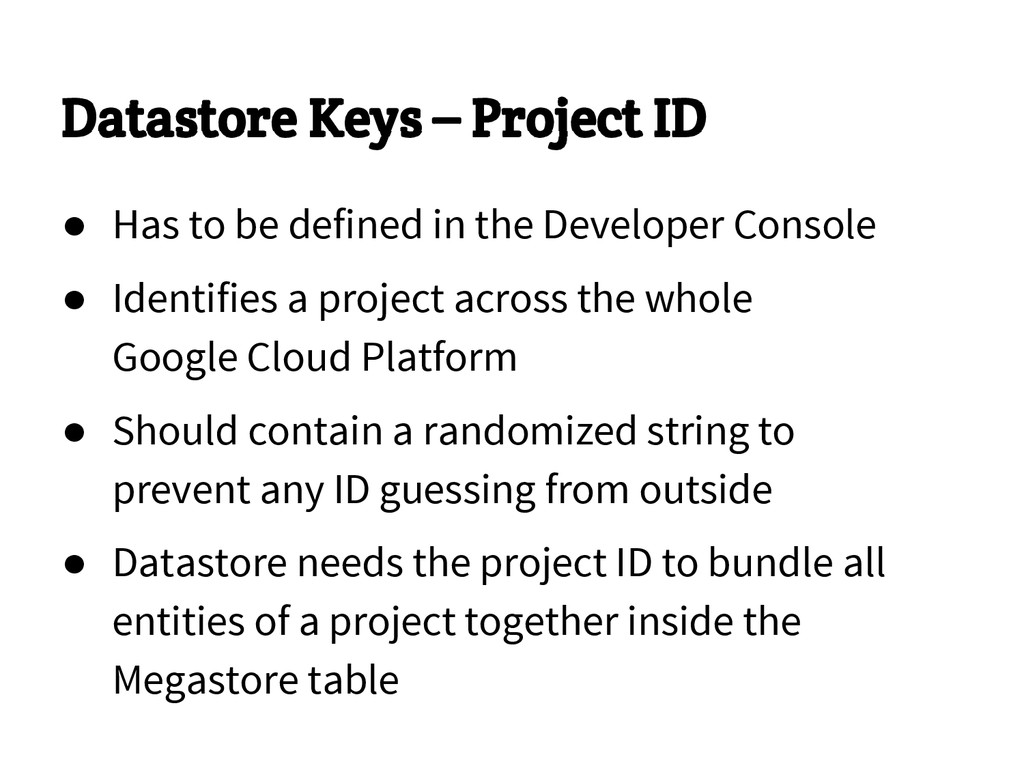
Datastore Keys – Project ID • Has to be defined
in the Developer Console • Identifies a project across the whole Google Cloud Platform • Should contain a randomized string to prevent any ID guessing from outside • Datastore needs the project ID to bundle all entities of a project together inside the Megastore table -
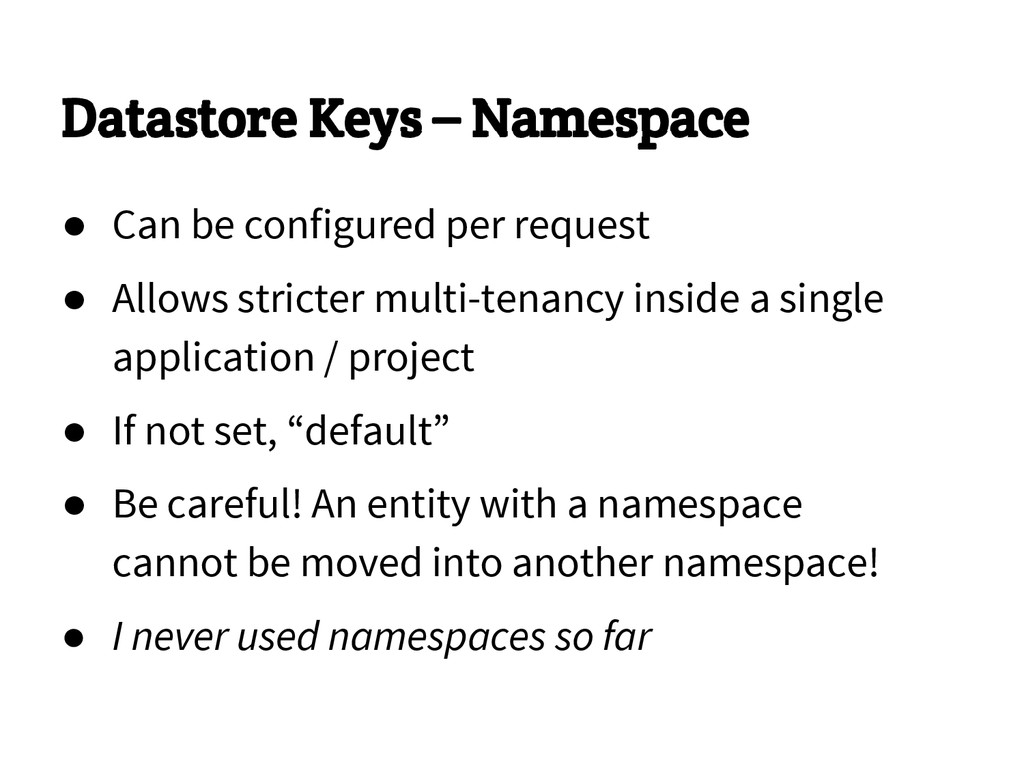
Datastore Keys – Namespace • Can be configured per request
• Allows stricter multi-tenancy inside a single application / project • If not set, “default” • Be careful! An entity with a namespace cannot be moved into another namespace! • I never used namespaces so far -
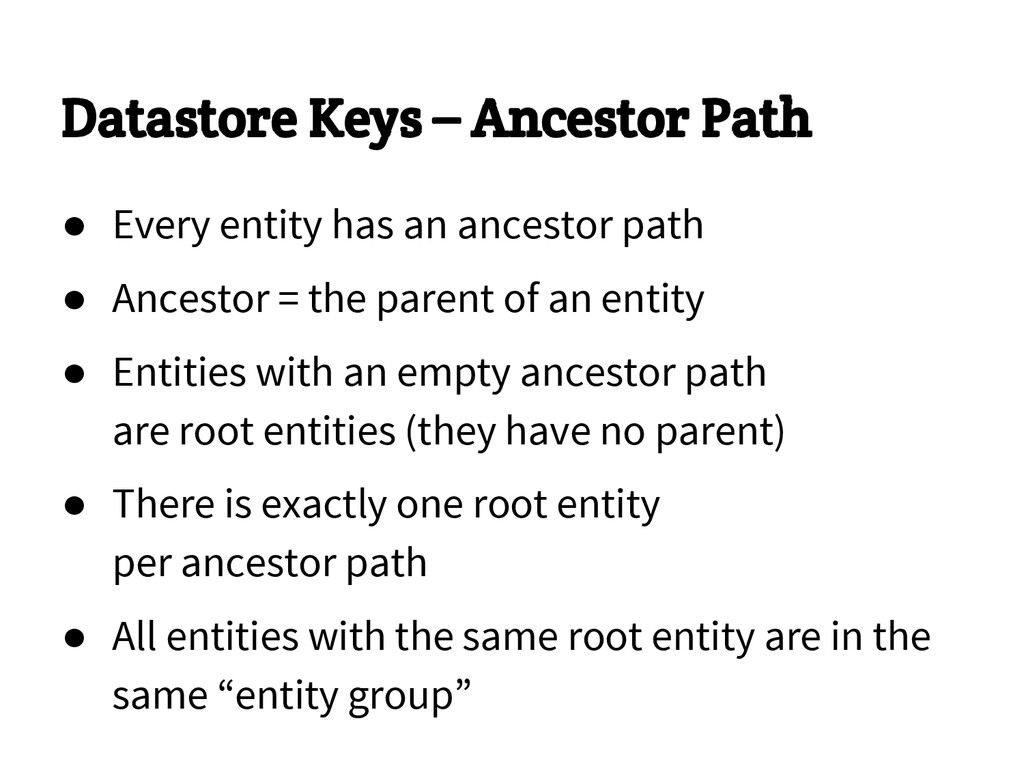
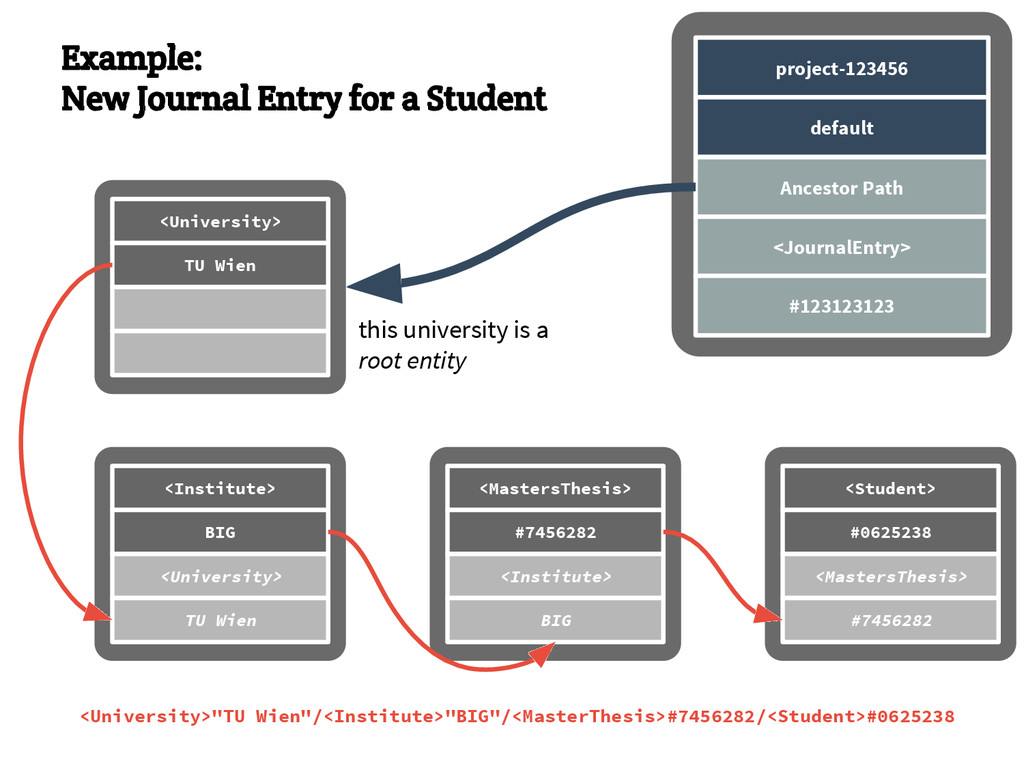
Datastore Keys – Ancestor Path • Every entity has an
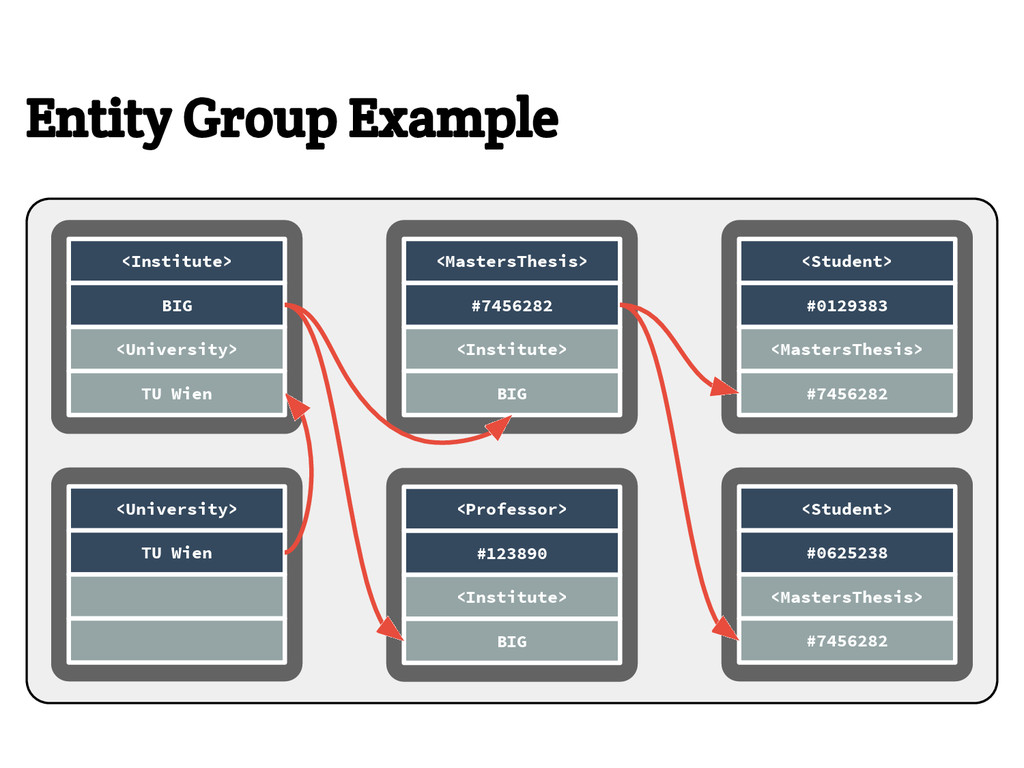
ancestor path • Ancestor = the parent of an entity • Entities with an empty ancestor path are root entities (they have no parent) • There is exactly one root entity per ancestor path • All entities with the same root entity are in the same “entity group” -
Example: New Journal Entry for a Student <Institute> BIG <University>
TU Wien <University> TU Wien <MastersThesis> #7456282 <Institute> BIG <Student> #0625238 <MastersThesis> #7456282 <University>"TU Wien"/<Institute>"BIG"/<MasterThesis>#7456282/<Student>#0625238 this university is a root entity project-123456 default Ancestor Path <JournalEntry> #123123123 -
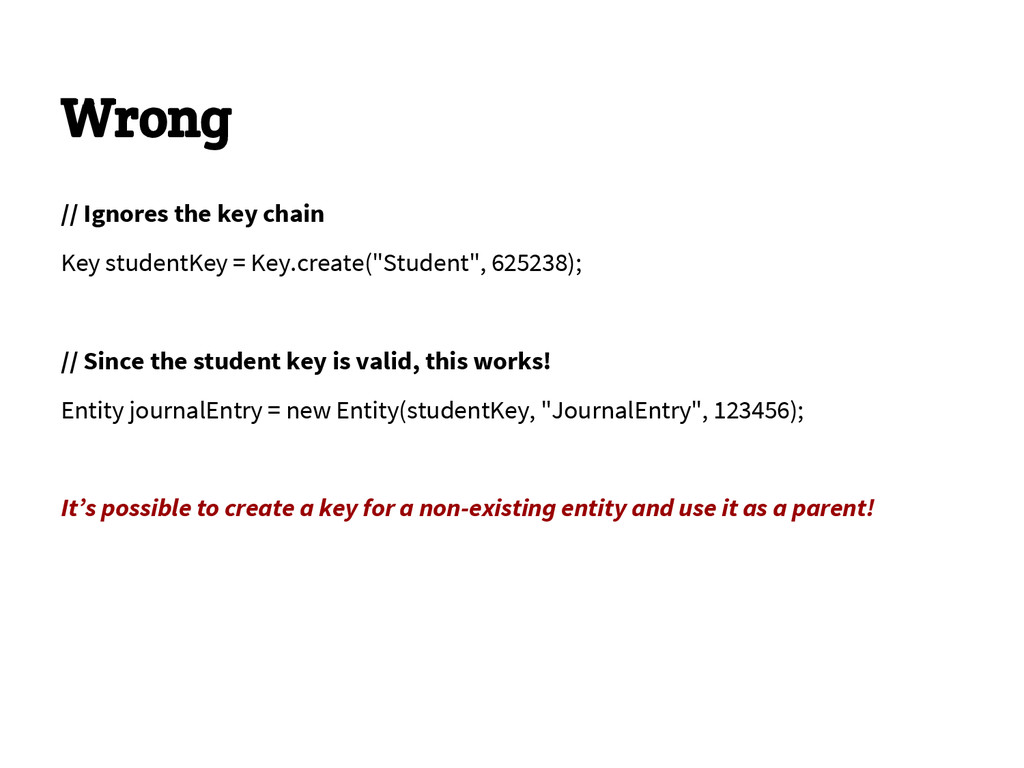
Wrong // Ignores the key chain Key studentKey = Key.create("Student",
625238); // Since the student key is valid, this works! Entity journalEntry = new Entity(studentKey, "JournalEntry", 123456); It’s possible to create a key for a non-existing entity and use it as a parent! -
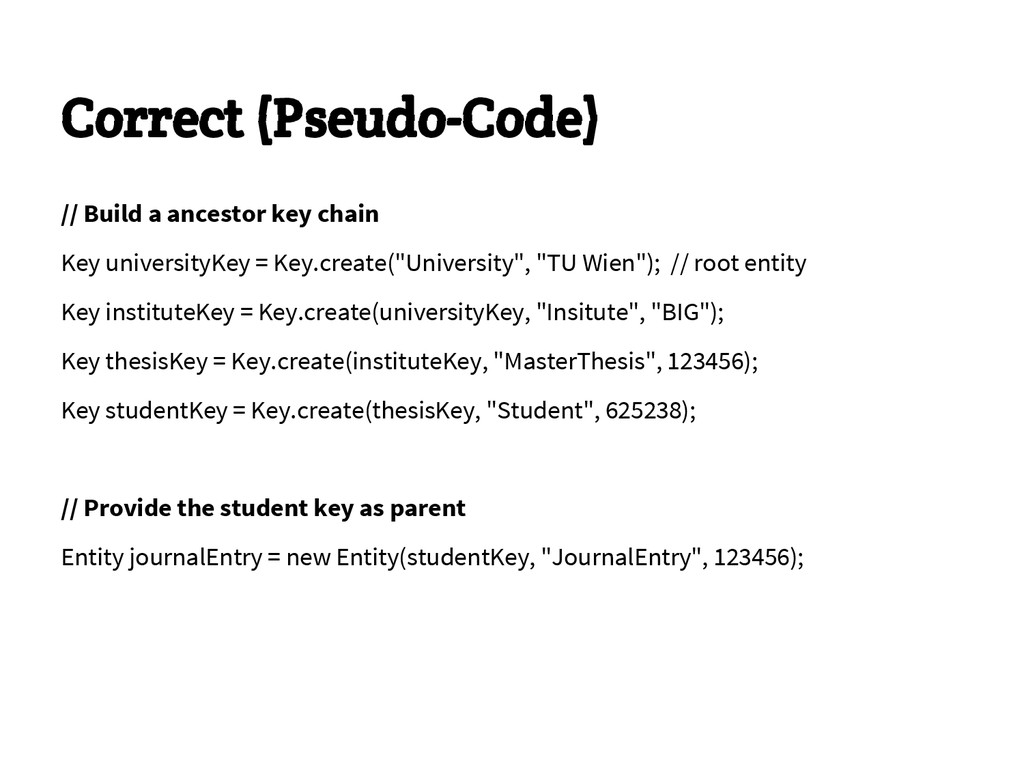
Correct (Pseudo-Code) // Build a ancestor key chain Key universityKey
= Key.create("University", "TU Wien"); // root entity Key instituteKey = Key.create(universityKey, "Insitute", "BIG"); Key thesisKey = Key.create(instituteKey, "MasterThesis", 123456); Key studentKey = Key.create(thesisKey, "Student", 625238); // Provide the student key as parent Entity journalEntry = new Entity(studentKey, "JournalEntry", 123456); -
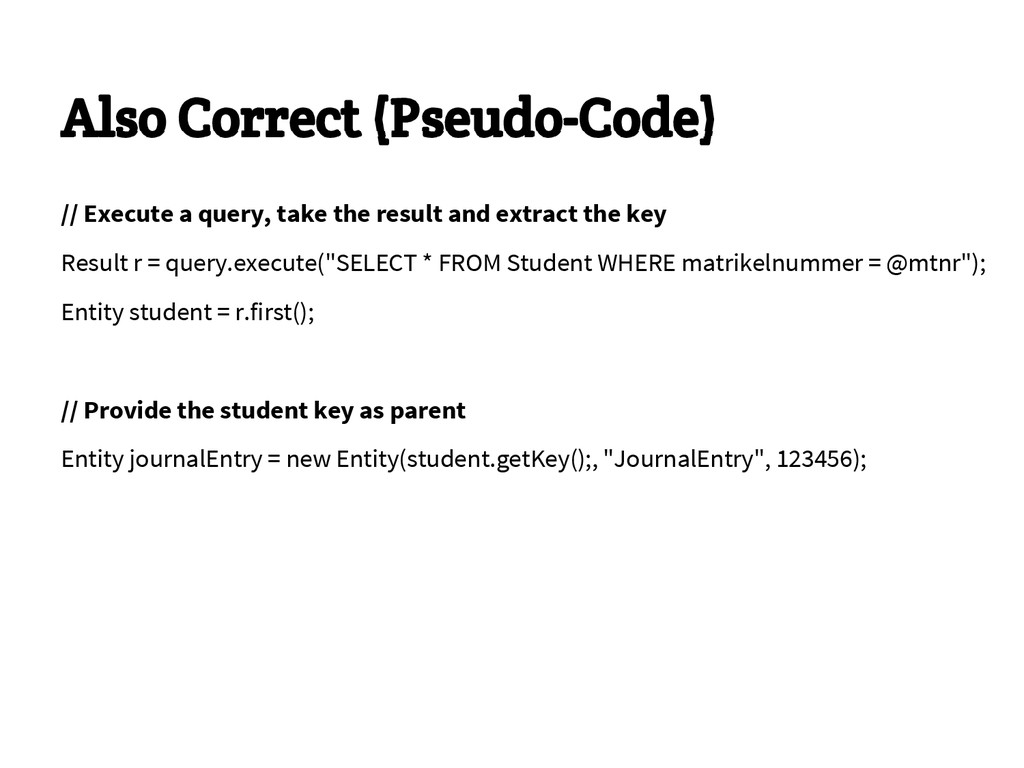
Also Correct (Pseudo-Code) // Execute a query, take the result
and extract the key Result r = query.execute("SELECT * FROM Student WHERE matrikelnummer = @mtnr"); Entity student = r.first(); // Provide the student key as parent Entity journalEntry = new Entity(student.getKey();, "JournalEntry", 123456); -
Entity Group Example <Institute> BIG <University> TU Wien <University> TU
Wien <MastersThesis> #7456282 <Institute> BIG <Student> #0129383 <MastersThesis> #7456282 <Student> #0625238 <MastersThesis> #7456282 <Professor> #123890 <Institute> BIG -
Entity Group Example Key Data <>/University:"TU Wien" [pbuff] <University:TUWien>/Intitute:"BIG" [pbuff]
<University:TUWien>/Intitute:"IFS" [pbuff] <University:TUWien><Intitute:"BIG">/Professor:123890 [pbuff] <University:TUWien><Intitute:"BIG">/Thesis:123890 [pbuff] <University:TUWien><Intitute:"BIG"><Thesis:123890>/Student:0625238 [pbuff] <University:TUWien><Intitute:"BIG"><Thesis:123890><Student:0625238> /JournalEntry:123456 [pbuff] … … -
Transactions • Provide ACID-like transactions per entity group • Datastore
uses optimistic locking • Two transactions cannot manipulate the same entity group in parallel – both will throw a ConcurrentModificationException • A maximum of 5 entity groups can participate a single transaction -
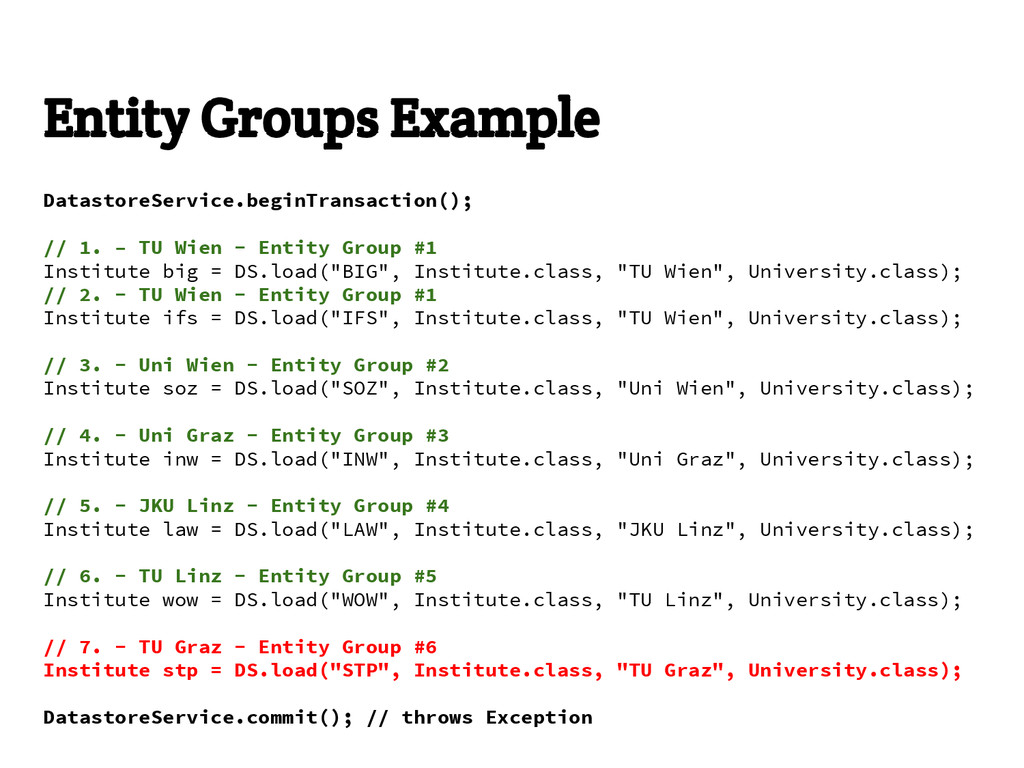
Entity Groups Example DatastoreService.beginTransaction(); // 1. – TU Wien -
Entity Group #1 Institute big = DS.load("BIG", Institute.class, "TU Wien", University.class); // 2. - TU Wien - Entity Group #1 Institute ifs = DS.load("IFS", Institute.class, "TU Wien", University.class); // 3. - Uni Wien - Entity Group #2 Institute soz = DS.load("SOZ", Institute.class, "Uni Wien", University.class); // 4. - Uni Graz - Entity Group #3 Institute inw = DS.load("INW", Institute.class, "Uni Graz", University.class); // 5. - JKU Linz - Entity Group #4 Institute law = DS.load("LAW", Institute.class, "JKU Linz", University.class); // 6. - TU Linz - Entity Group #5 Institute wow = DS.load("WOW", Institute.class, "TU Linz", University.class); // 7. - TU Graz - Entity Group #6 Institute stp = DS.load("STP", Institute.class, "TU Graz", University.class); DatastoreService.commit(); // throws Exception -
Best Practice • Design applications for 1 write per entity
group per second • Keep entity groups small • Keep ancestor paths short • Ancestor path defines scope of a transaction • Don’t use the ancestor path to form a relationship between two entities -
Kinds and IDs • Kinds categorizes entities like classes ◦
the “__” prefix is reserved for internal use • IDs can be strings or long numbers ◦ if string, it has to be unique per kind ◦ if numeric, it’s recommended to use the ID generator ▪ numbers have to be > 0 ▪ unique per kind ◦ ID generator enhances the performance since it allocates IDs in a batch -
Queries • Datastore uses Megastore tables for indexes • Every
query is translated into a table scan • Every property involved in a query has to be part of an index • The number of indexes is limited to 200 • Ancestor queries are always strong consistent • There is no fulltext search available -
Queries and Sorting • Every sorting is implemented as index
scan • So you need an index for every sort direction • This can lead to a very high number of indexes • Every manipulation on an indexed property will cost you a write operation ◦ Write operations are expensive! ◦ Indexes can be much larger than the actual data -
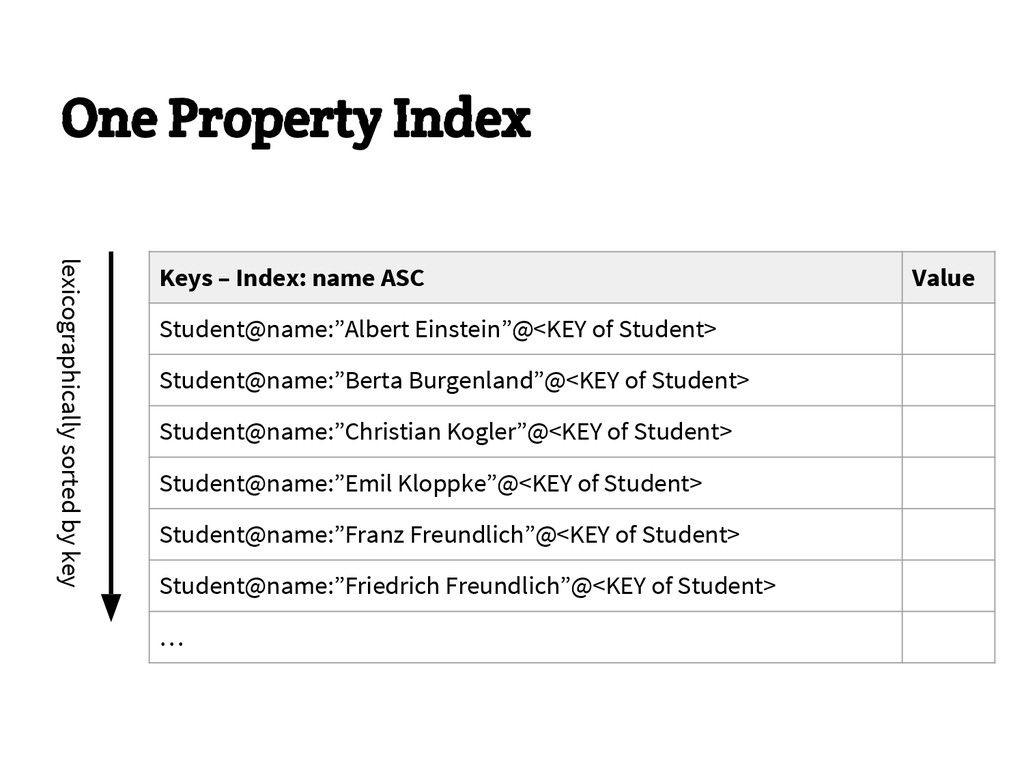
One Property Index Keys – Index: name ASC Value Student@name:”Albert
Einstein”@<KEY of Student> Student@name:”Berta Burgenland”@<KEY of Student> Student@name:”Christian Kogler”@<KEY of Student> Student@name:”Emil Kloppke”@<KEY of Student> Student@name:”Franz Freundlich”@<KEY of Student> Student@name:”Friedrich Freundlich”@<KEY of Student> … lexicographically sorted by key -
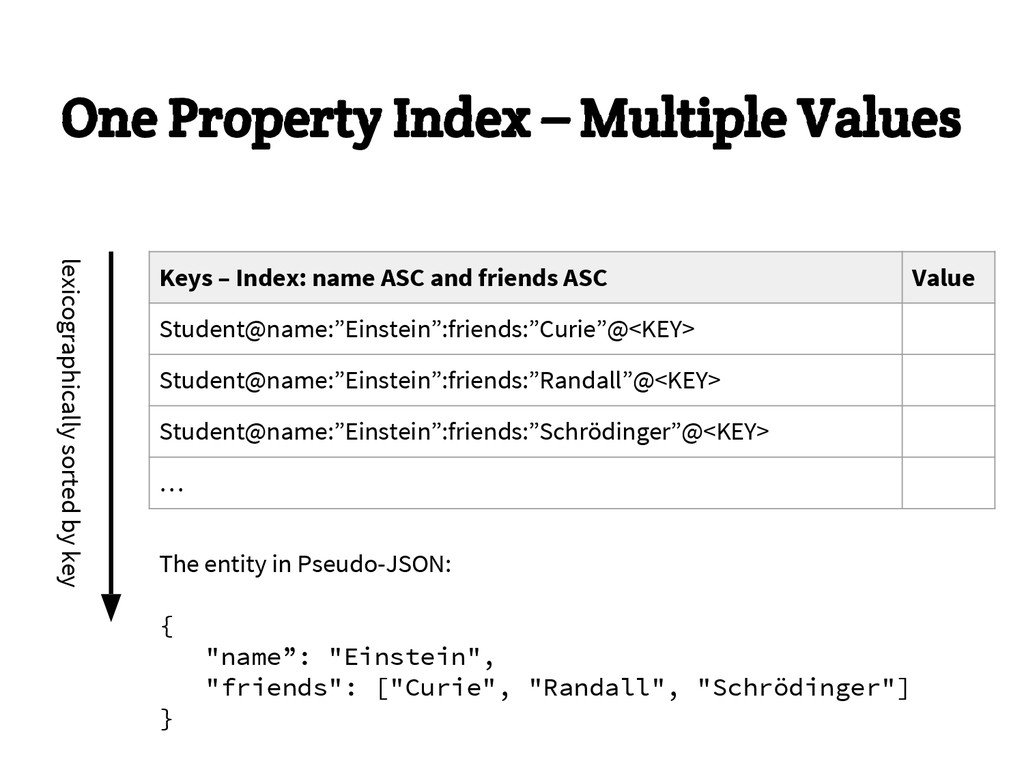
One Property Index – Multiple Values Keys – Index: name
ASC and friends ASC Value Student@name:”Einstein”:friends:”Curie”@<KEY> Student@name:”Einstein”:friends:”Randall”@<KEY> Student@name:”Einstein”:friends:”Schrödinger”@<KEY> … lexicographically sorted by key The entity in Pseudo-JSON: { "name”: "Einstein", "friends": ["Curie", "Randall", "Schrödinger"] } -
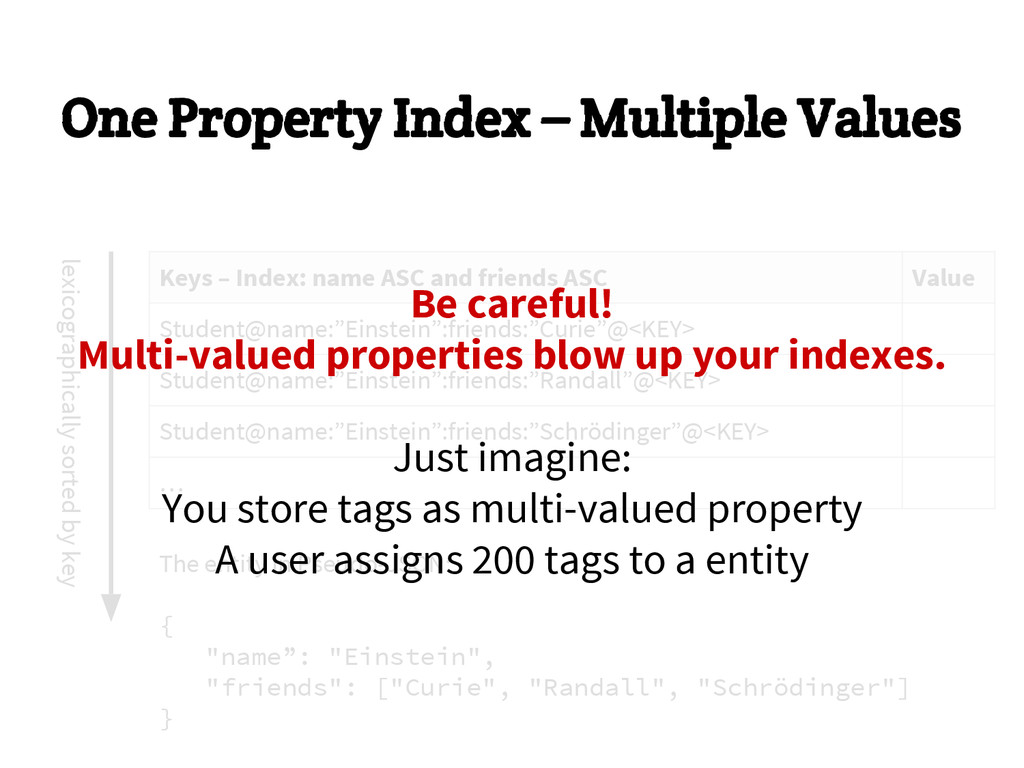
One Property Index – Multiple Values Keys – Index: name
ASC and friends ASC Value Student@name:”Einstein”:friends:”Curie”@<KEY> Student@name:”Einstein”:friends:”Randall”@<KEY> Student@name:”Einstein”:friends:”Schrödinger”@<KEY> … lexicographically sorted by key The entity in Pseudo-JSON: { "name”: "Einstein", "friends": ["Curie", "Randall", "Schrödinger"] } Be careful! Multi-valued properties blow up your indexes. Just imagine: You store tags as multi-valued property A user assigns 200 tags to a entity -
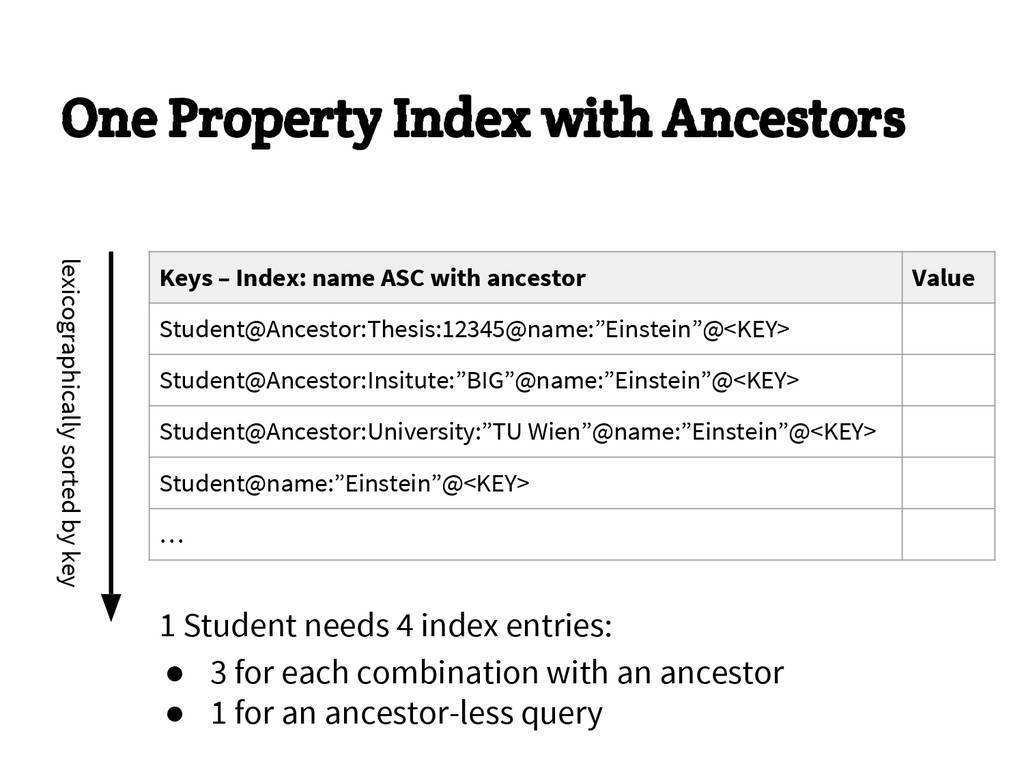
One Property Index with Ancestors Keys – Index: name ASC
with ancestor Value Student@Ancestor:Thesis:12345@name:”Einstein”@<KEY> Student@Ancestor:Insitute:”BIG”@name:”Einstein”@<KEY> Student@Ancestor:University:”TU Wien”@name:”Einstein”@<KEY> Student@name:”Einstein”@<KEY> … lexicographically sorted by key 1 Student needs 4 index entries: • 3 for each combination with an ancestor • 1 for an ancestor-less query -
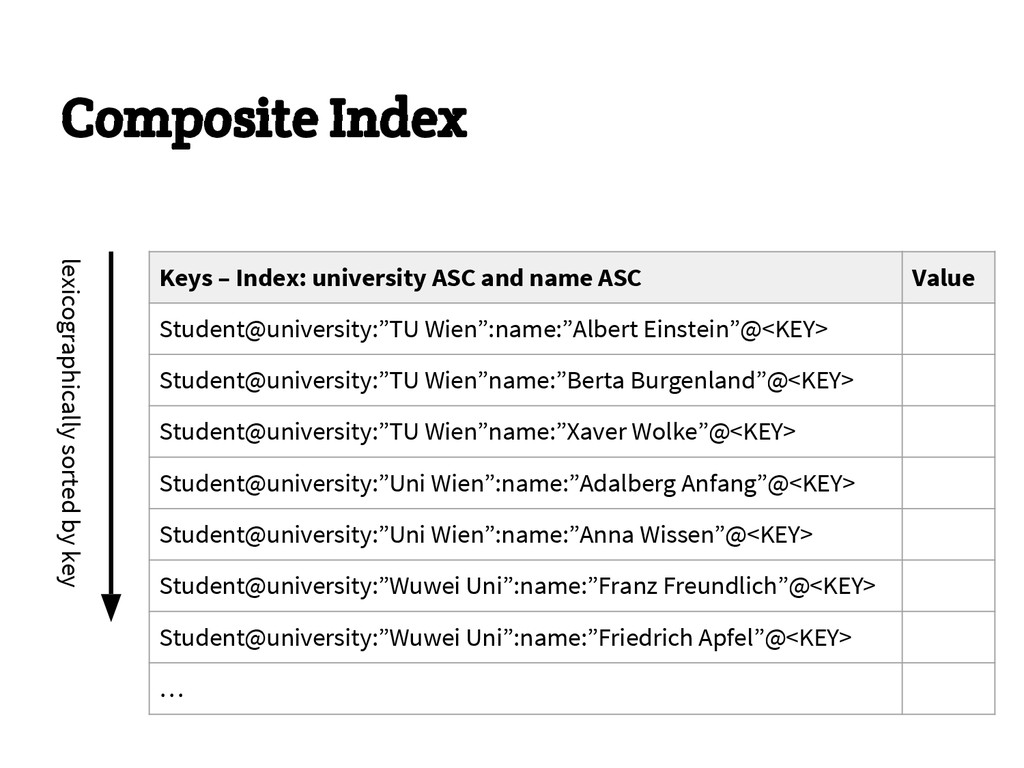
Composite Index Keys – Index: university ASC and name ASC
Value Student@university:”TU Wien”:name:”Albert Einstein”@<KEY> Student@university:”TU Wien”name:”Berta Burgenland”@<KEY> Student@university:”TU Wien”name:”Xaver Wolke”@<KEY> Student@university:”Uni Wien”:name:”Adalberg Anfang”@<KEY> Student@university:”Uni Wien”:name:”Anna Wissen”@<KEY> Student@university:”Wuwei Uni”:name:”Franz Freundlich”@<KEY> Student@university:”Wuwei Uni”:name:”Friedrich Apfel”@<KEY> … lexicographically sorted by key -
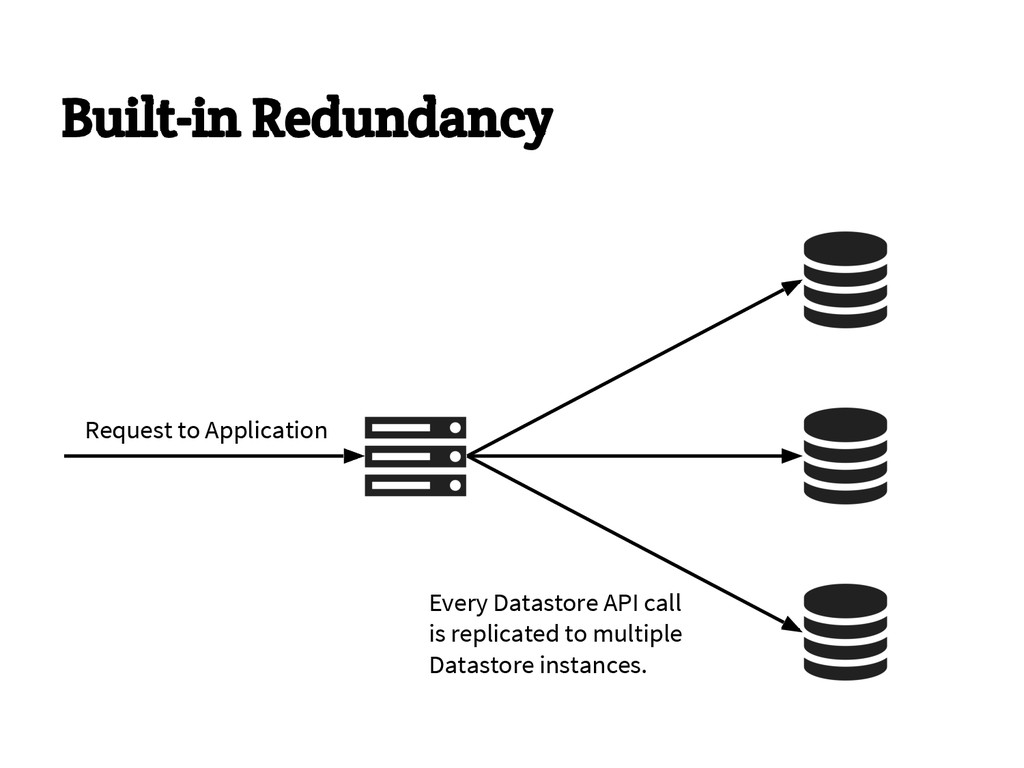
Request to Application Built-in Redundancy Every Datastore API call is
replicated to multiple Datastore instances. -
Java Persistence Frameworks • JDO / Datanucleus ◦ I never
used it • JPA / Datanucleus ◦ evaluated for my master’s thesis ◦ hard to bring an ORM to the NoSQL world ◦ feels buggy and old • Objectify ◦ App Engine specific framework ◦ has built-in caching (instance- and memcache) ◦ my personal recommendation -
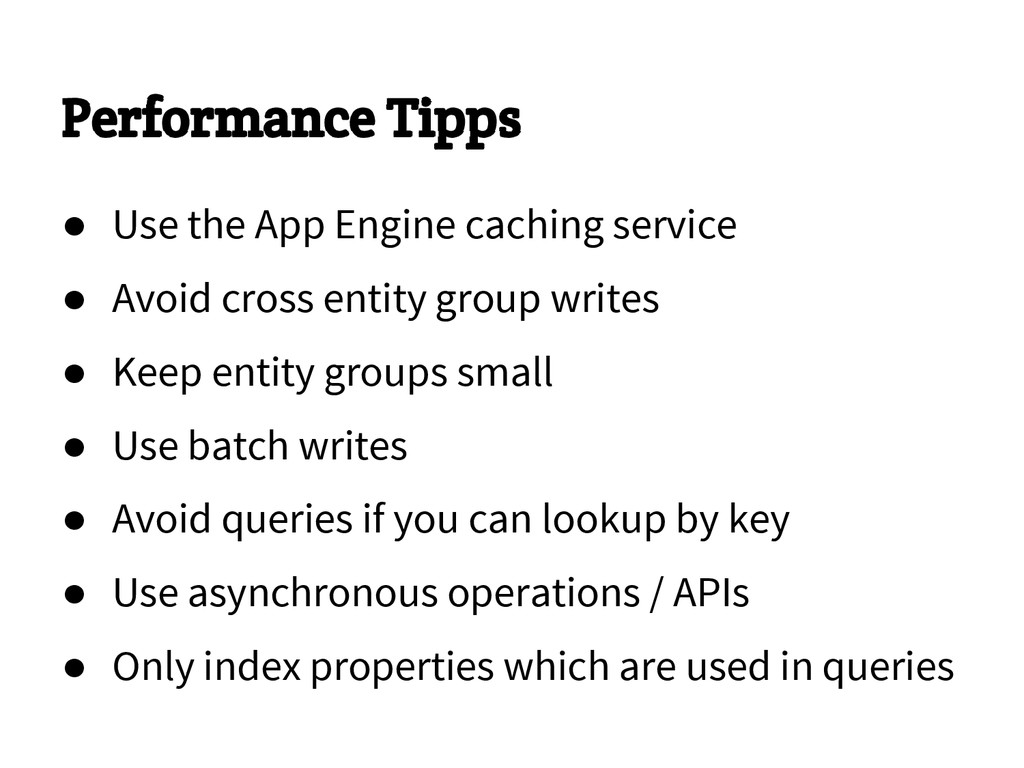
Performance Tipps • Use the App Engine caching service •
Avoid cross entity group writes • Keep entity groups small • Use batch writes • Avoid queries if you can lookup by key • Use asynchronous operations / APIs • Only index properties which are used in queries -
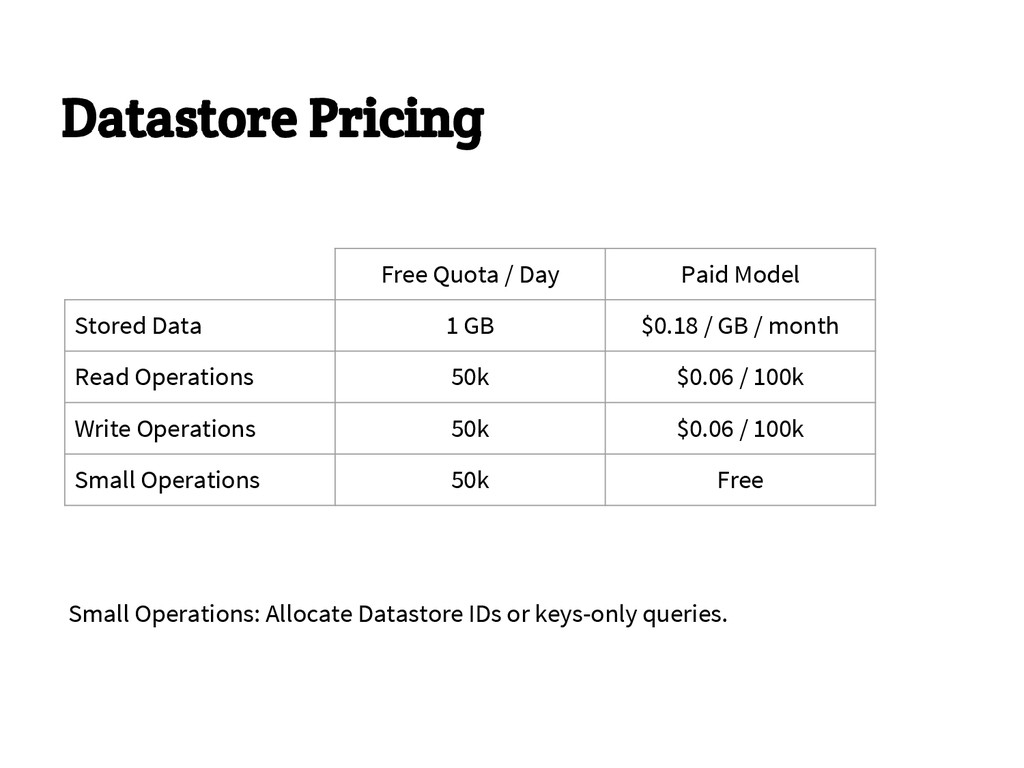
Datastore Pricing Free Quota / Day Paid Model Stored Data
1 GB $0.18 / GB / month Read Operations 50k $0.06 / 100k Write Operations 50k $0.06 / 100k Small Operations 50k Free Small Operations: Allocate Datastore IDs or keys-only queries.