Share
Embed
Transcript
72 slides
-
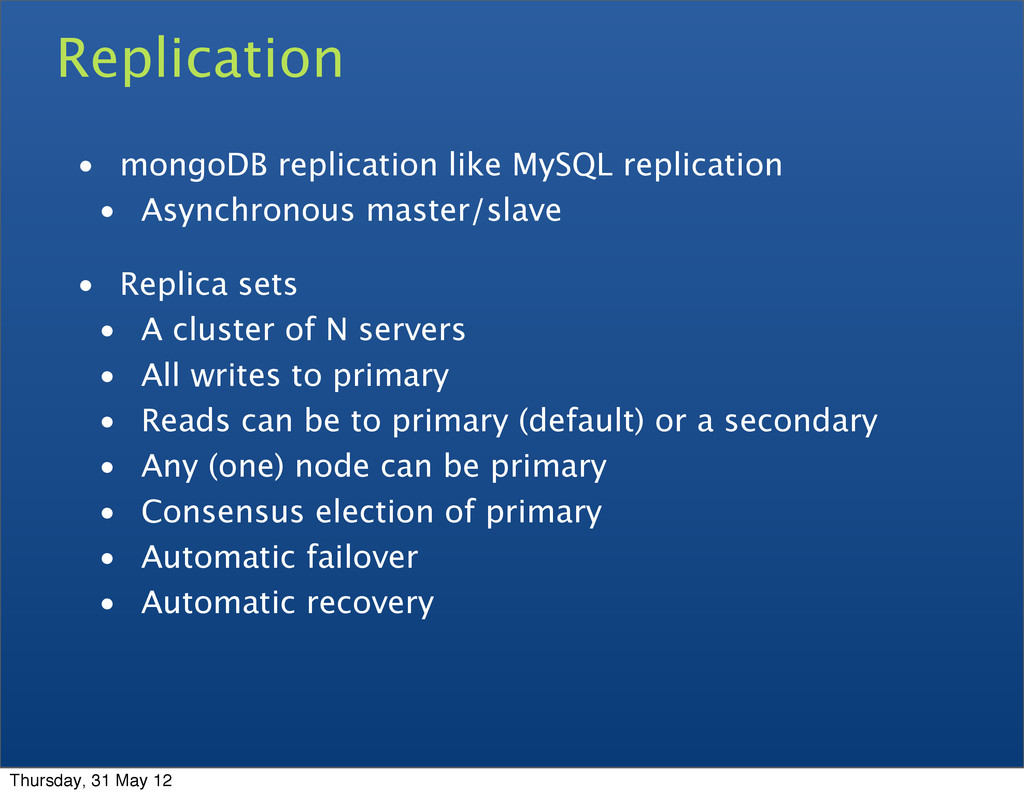
Replication • mongoDB replication like MySQL replication • Asynchronous master/slave
• Replica sets • A cluster of N servers • All writes to primary • Reads can be to primary (default) or a secondary • Any (one) node can be primary • Consensus election of primary • Automatic failover • Automatic recovery Thursday, 31 May 12 -
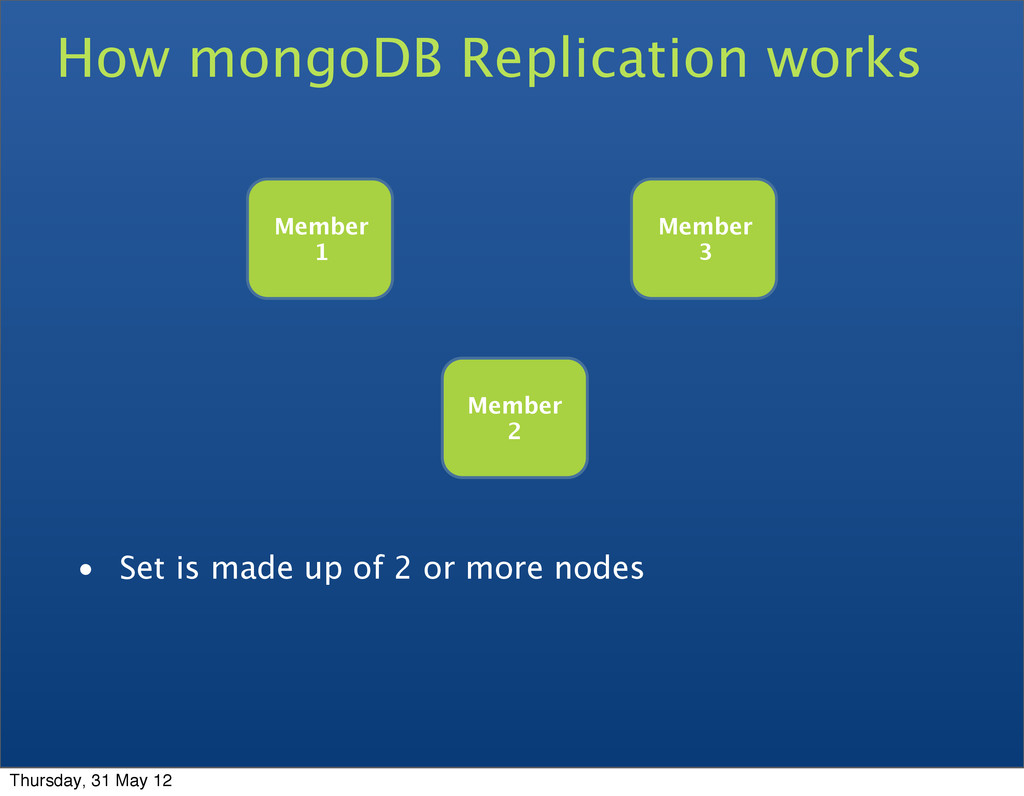
How mongoDB Replication works Member 1 Member 2 Member 3
• Set is made up of 2 or more nodes Thursday, 31 May 12 -
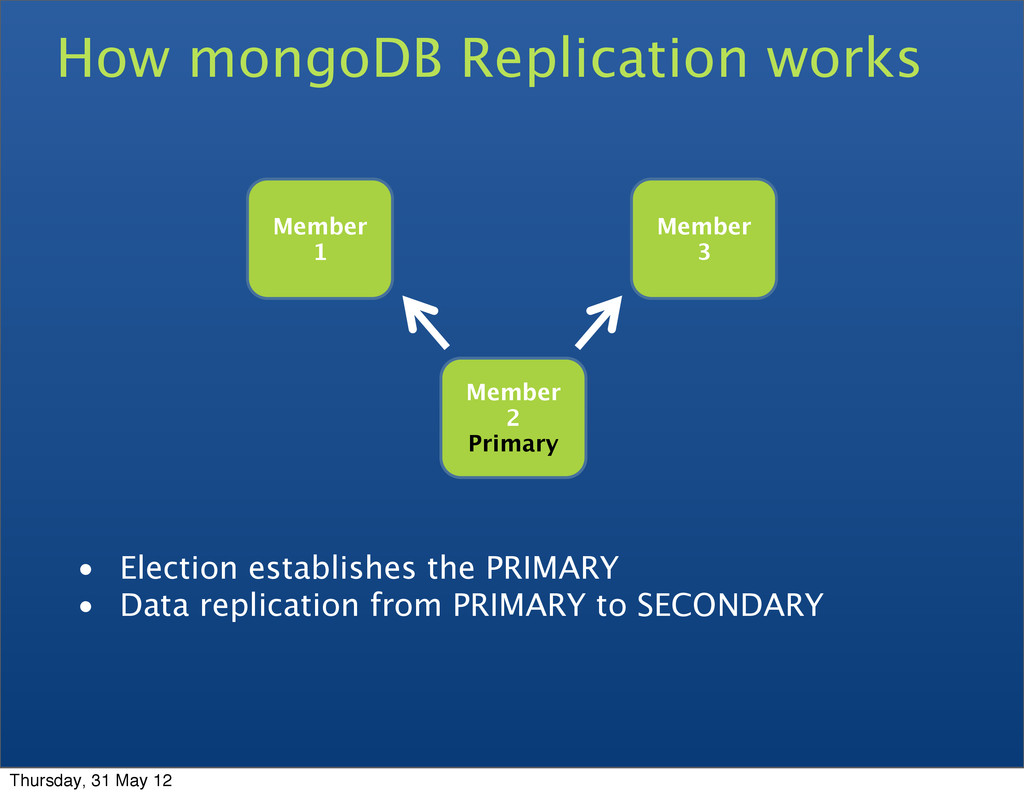
How mongoDB Replication works • Election establishes the PRIMARY •
Data replication from PRIMARY to SECONDARY Member 1 Member 2 Primary Member 3 Thursday, 31 May 12 -
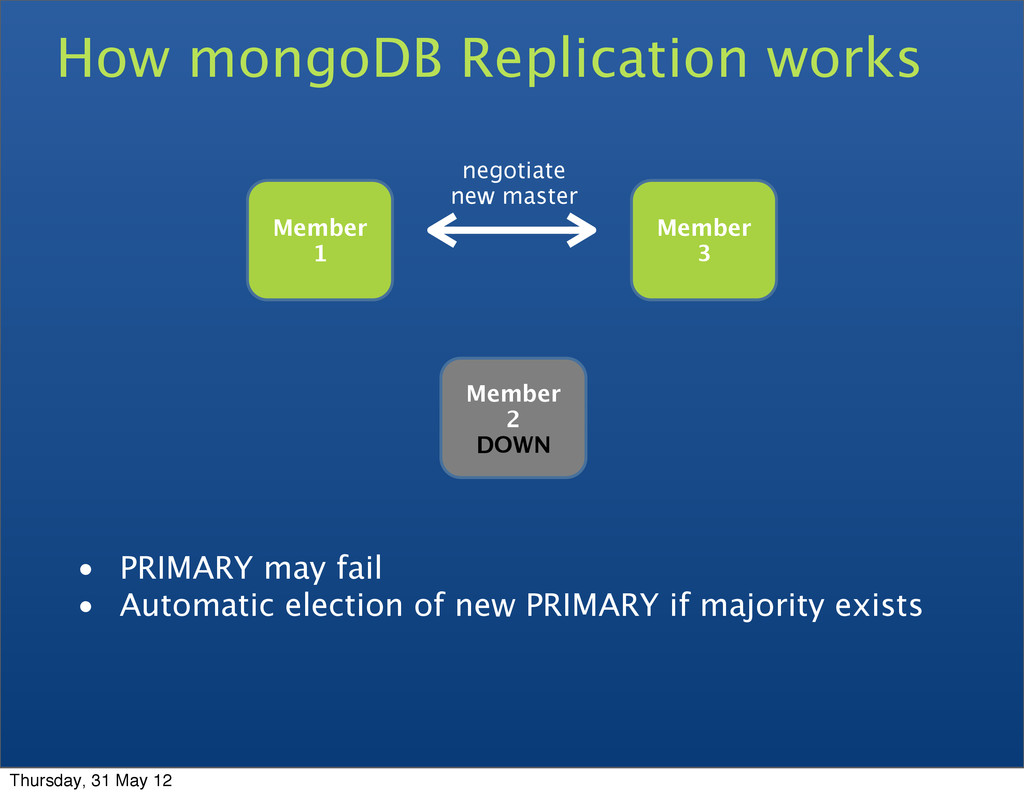
How mongoDB Replication works • PRIMARY may fail • Automatic
election of new PRIMARY if majority exists Member 1 Member 2 DOWN Member 3 negotiate new master Thursday, 31 May 12 -
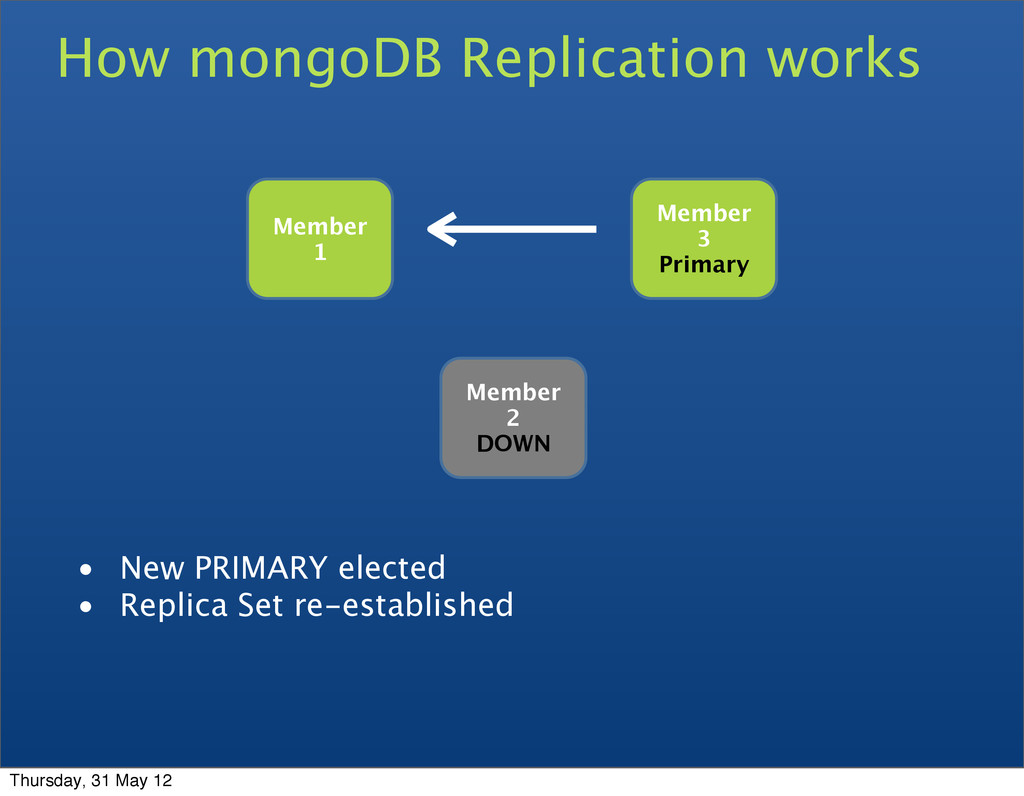
How mongoDB Replication works • New PRIMARY elected • Replica
Set re-established Member 1 Member 2 DOWN Member 3 Primary Thursday, 31 May 12 -
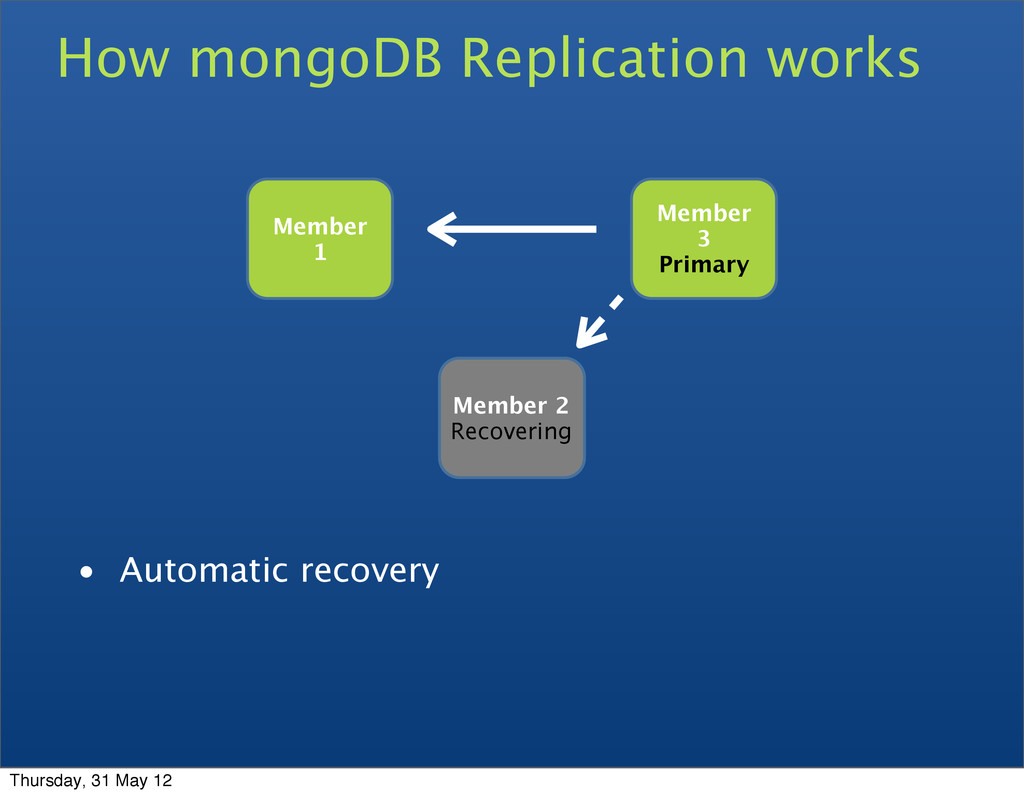
How mongoDB Replication works • Automatic recovery Member 1 Member
3 Primary Member 2 Recovering Thursday, 31 May 12 -
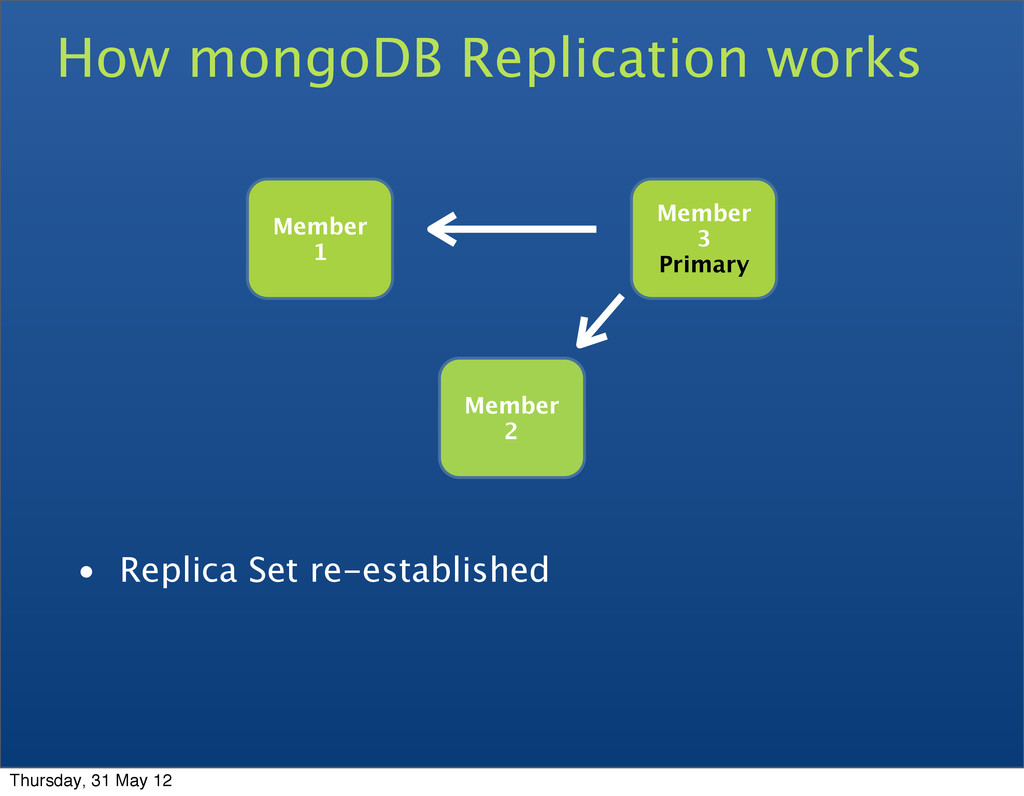
How mongoDB Replication works • Replica Set re-established Member 1
Member 3 Primary Member 2 Thursday, 31 May 12 -
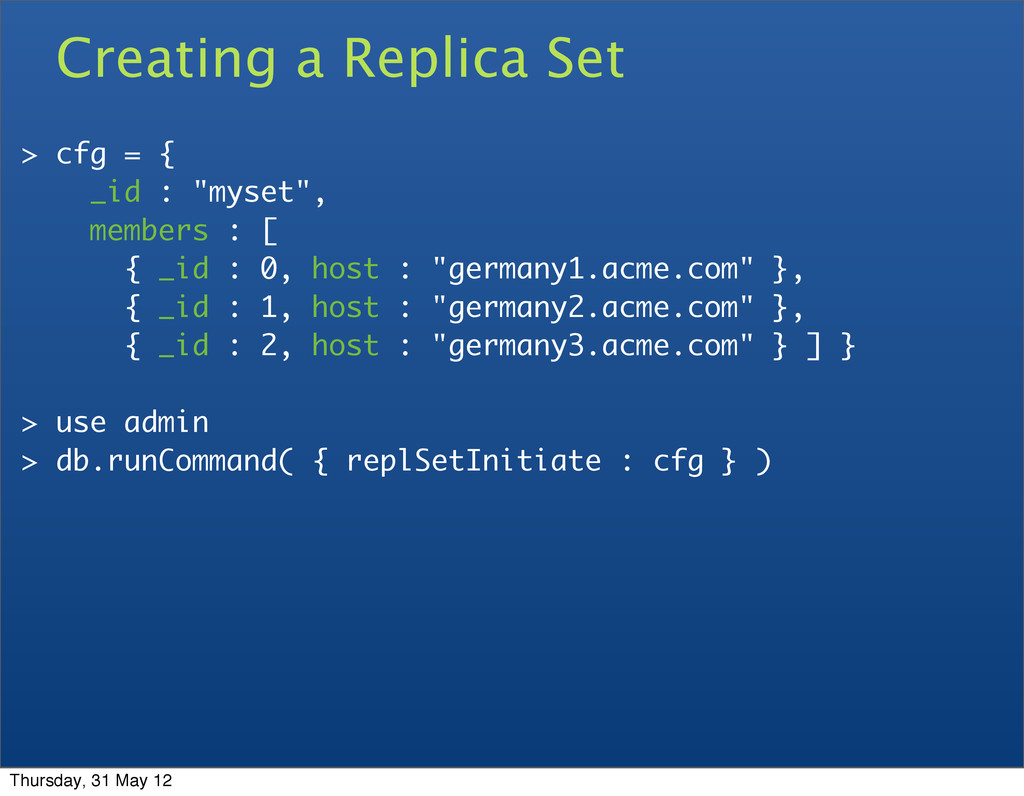
> cfg = { _id : "myset", members : [
{ _id : 0, host : "germany1.acme.com" }, { _id : 1, host : "germany2.acme.com" }, { _id : 2, host : "germany3.acme.com" } ] } > use admin > db.runCommand( { replSetInitiate : cfg } ) Creating a Replica Set Thursday, 31 May 12 -
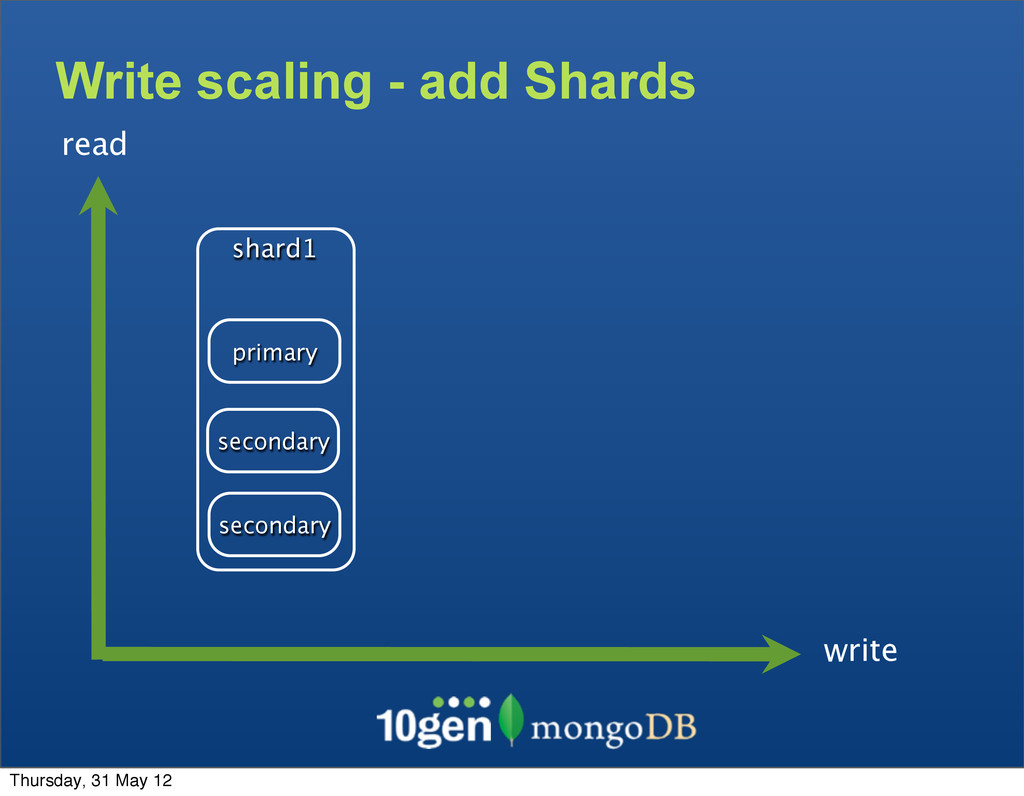
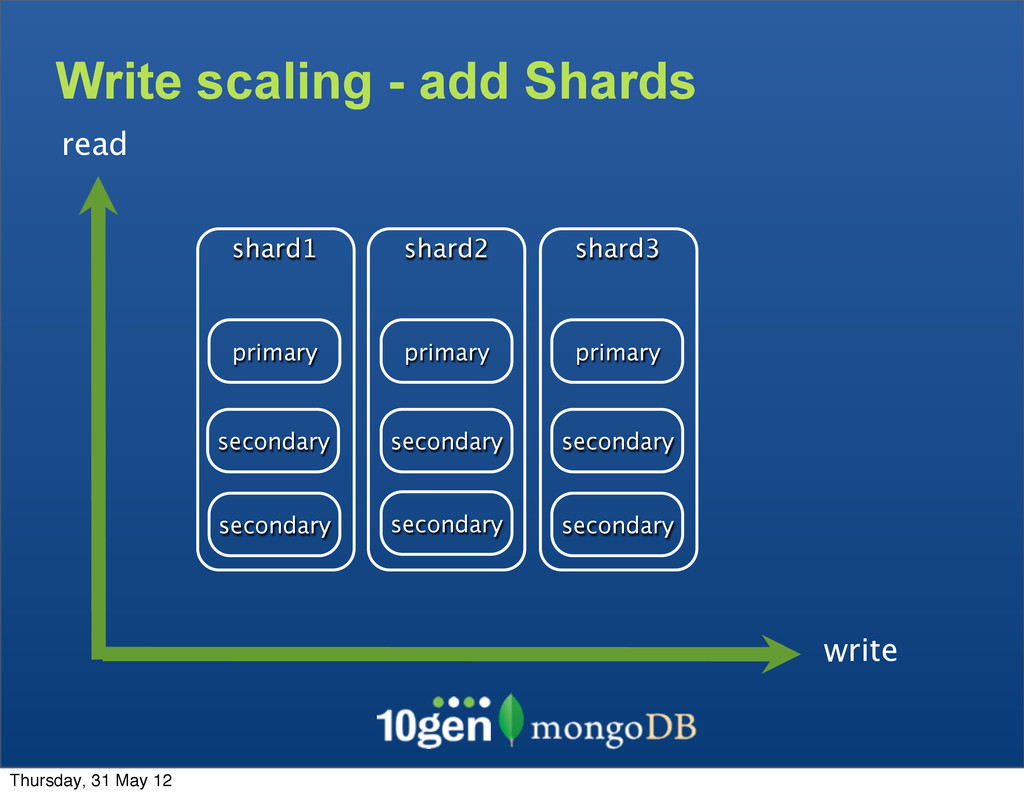
Write scaling - add Shards write read shard1 primary secondary
secondary Thursday, 31 May 12 -
Write scaling - add Shards write read shard1 primary secondary
secondary shard2 primary secondary secondary shard3 primary secondary secondary Thursday, 31 May 12 -
Big Data at a Glance Large Dataset Primary Key as
“username” a b c d e f g h s t u v w x y z ... Thursday, 31 May 12 -
Big Data at a Glance • Systems like Google File
System (which inspired Hadoop’s HDFS) and MongoDB’s Sharding handle the scale problem by chunking Large Dataset Primary Key as “username” a b c d e f g h s t u v w x y z ... Thursday, 31 May 12 -
Big Data at a Glance • Systems like Google File
System (which inspired Hadoop’s HDFS) and MongoDB’s Sharding handle the scale problem by chunking • Break up pieces of data into smaller chunks, spread across many data nodes Large Dataset Primary Key as “username” a b c d e f g h s t u v w x y z ... Thursday, 31 May 12 -
Big Data at a Glance • Systems like Google File
System (which inspired Hadoop’s HDFS) and MongoDB’s Sharding handle the scale problem by chunking • Break up pieces of data into smaller chunks, spread across many data nodes • Each data node contains many chunks Large Dataset Primary Key as “username” a b c d e f g h s t u v w x y z ... Thursday, 31 May 12 -
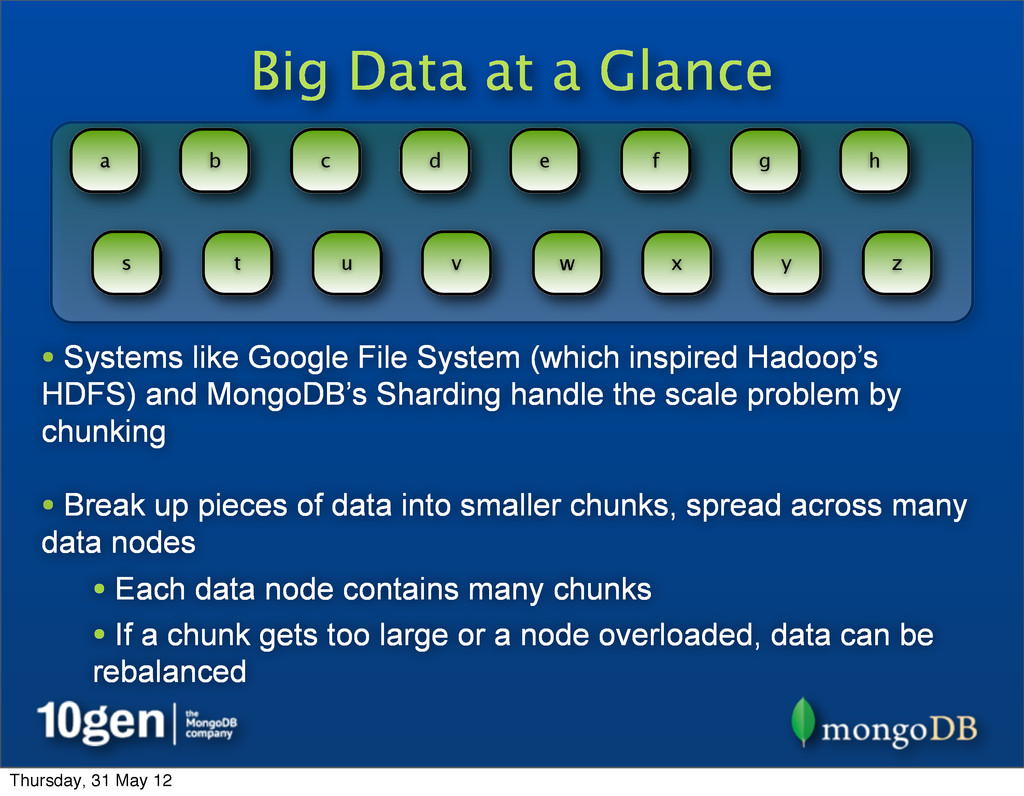
Big Data at a Glance • Systems like Google File
System (which inspired Hadoop’s HDFS) and MongoDB’s Sharding handle the scale problem by chunking • Break up pieces of data into smaller chunks, spread across many data nodes • Each data node contains many chunks • If a chunk gets too large or a node overloaded, data can be rebalanced Large Dataset Primary Key as “username” a b c d e f g h s t u v w x y z ... Thursday, 31 May 12 -
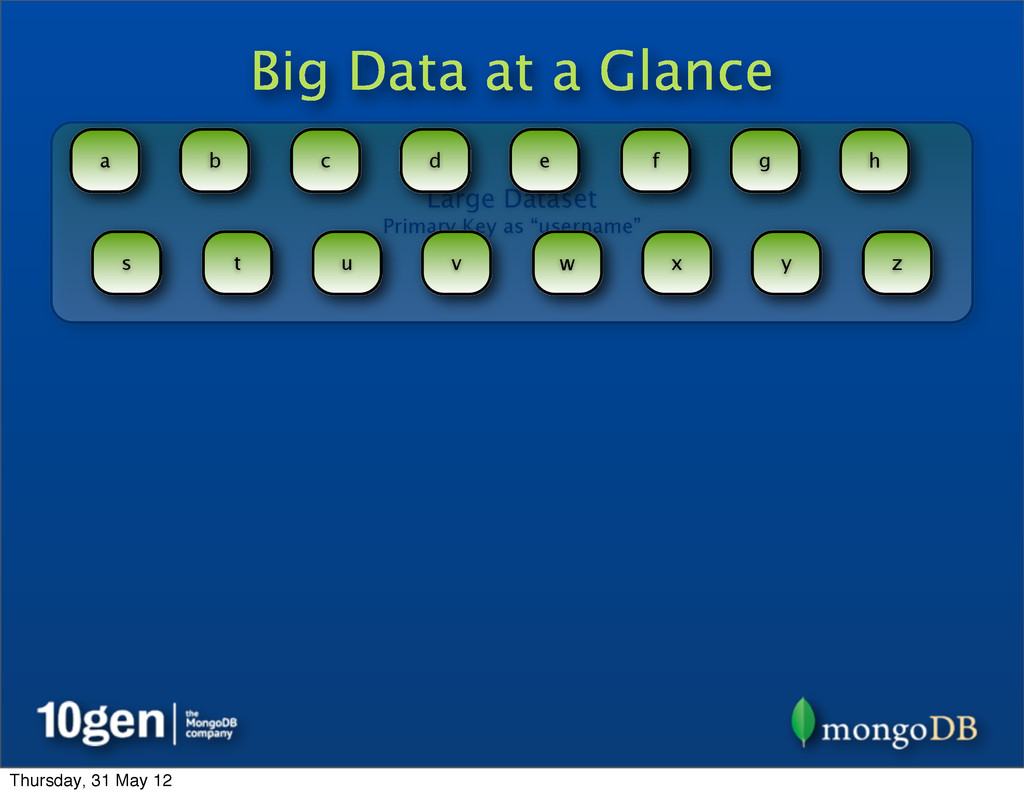
Big Data at a Glance Large Dataset Primary Key as
“username” a b c d e f g h s t u v w x y z Thursday, 31 May 12 -
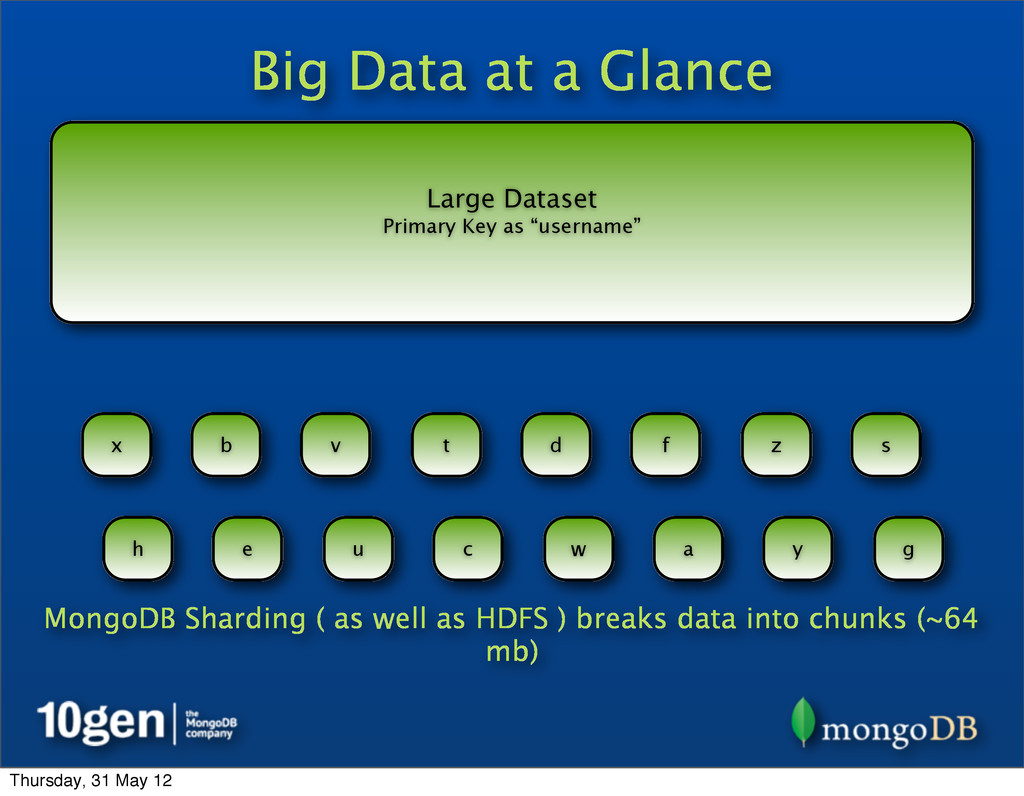
Big Data at a Glance Large Dataset Primary Key as
“username” a b c d e f g h s t u v w x y z MongoDB Sharding ( as well as HDFS ) breaks data into chunks (~64 mb) Thursday, 31 May 12 -
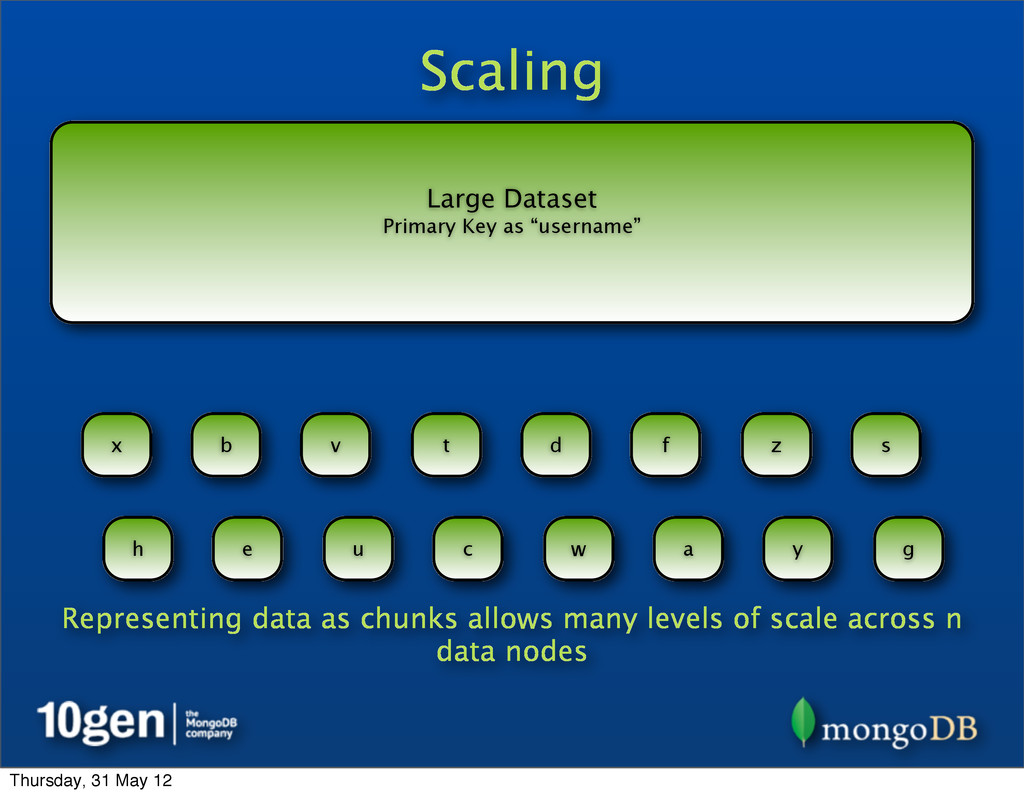
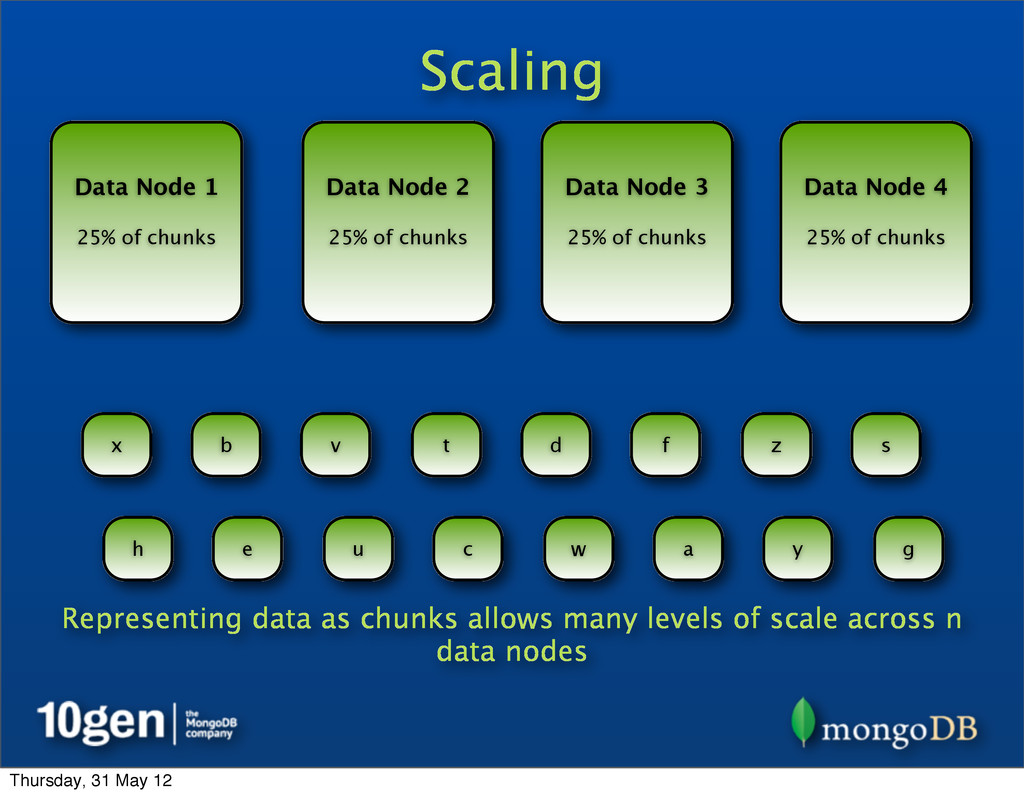
Large Dataset Primary Key as “username” Scaling Data Node 1
25% of chunks Data Node 2 25% of chunks Data Node 3 25% of chunks Data Node 4 25% of chunks a b c d e f g h s t u v w x y z Representing data as chunks allows many levels of scale across n data nodes Thursday, 31 May 12 -
Large Dataset Primary Key as “username” Scaling Data Node 1
25% of chunks Data Node 2 25% of chunks Data Node 3 25% of chunks Data Node 4 25% of chunks a b c d e f g h s t u v w x y z Representing data as chunks allows many levels of scale across n data nodes Thursday, 31 May 12 -
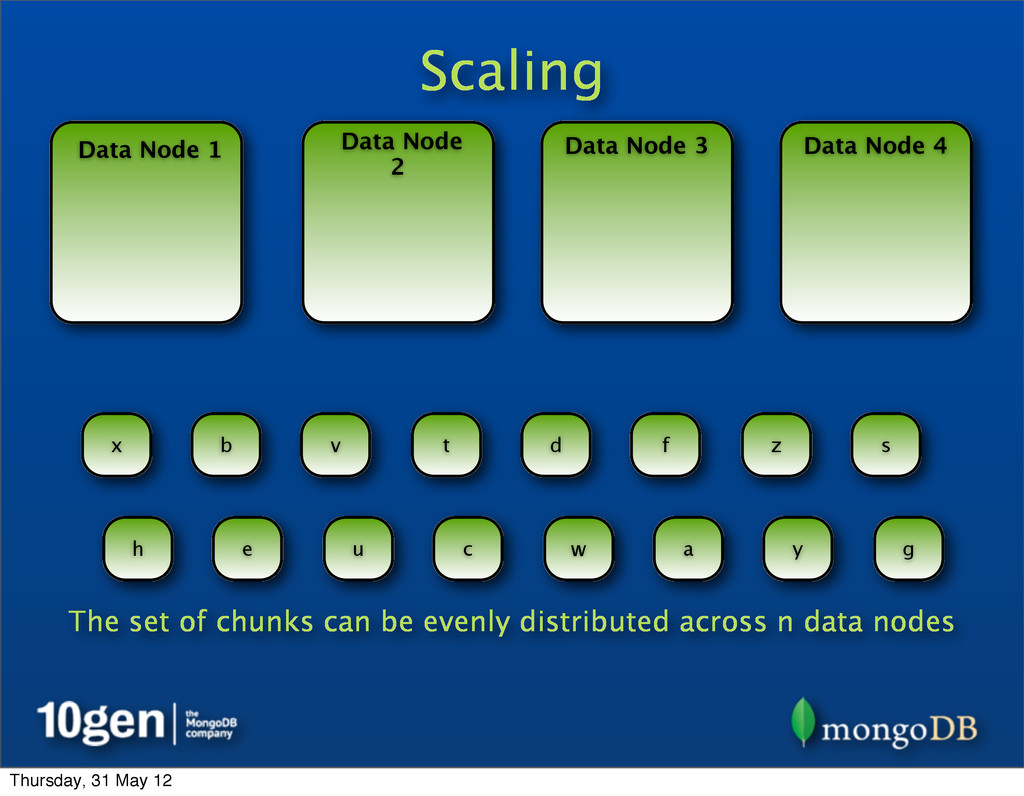
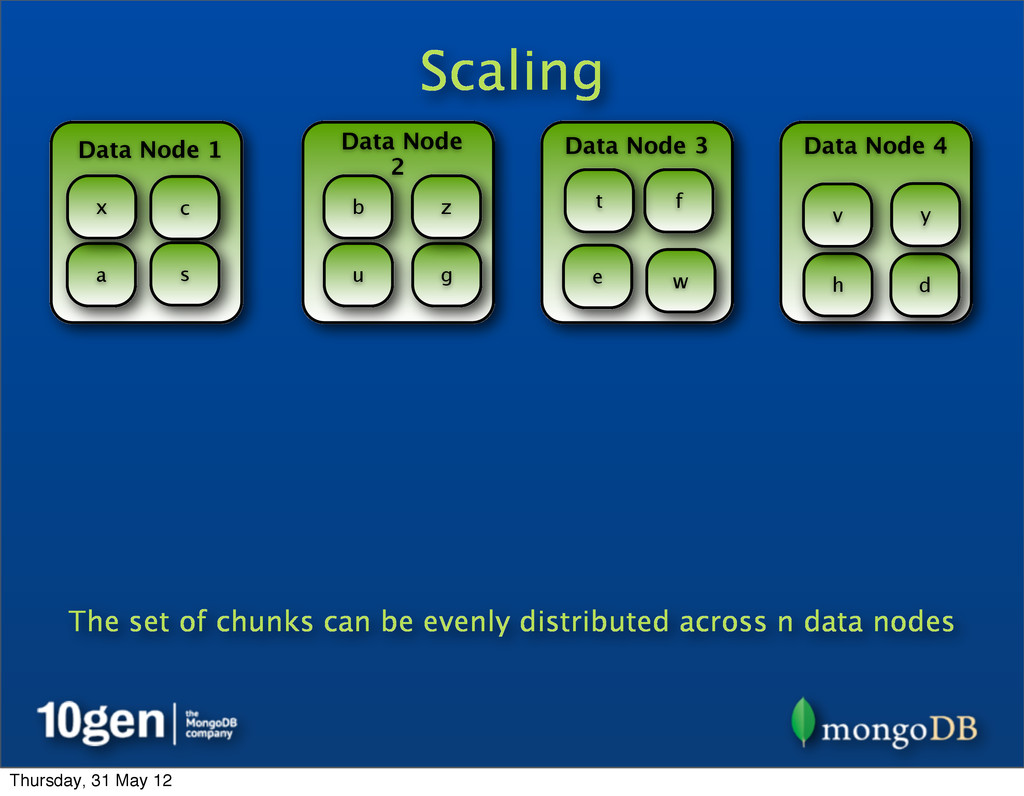
Scaling Data Node 1 Data Node 2 Data Node 3
Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z The set of chunks can be evenly distributed across n data nodes Thursday, 31 May 12 -
Scaling Data Node 1 Data Node 2 Data Node 3
Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z The set of chunks can be evenly distributed across n data nodes Thursday, 31 May 12 -
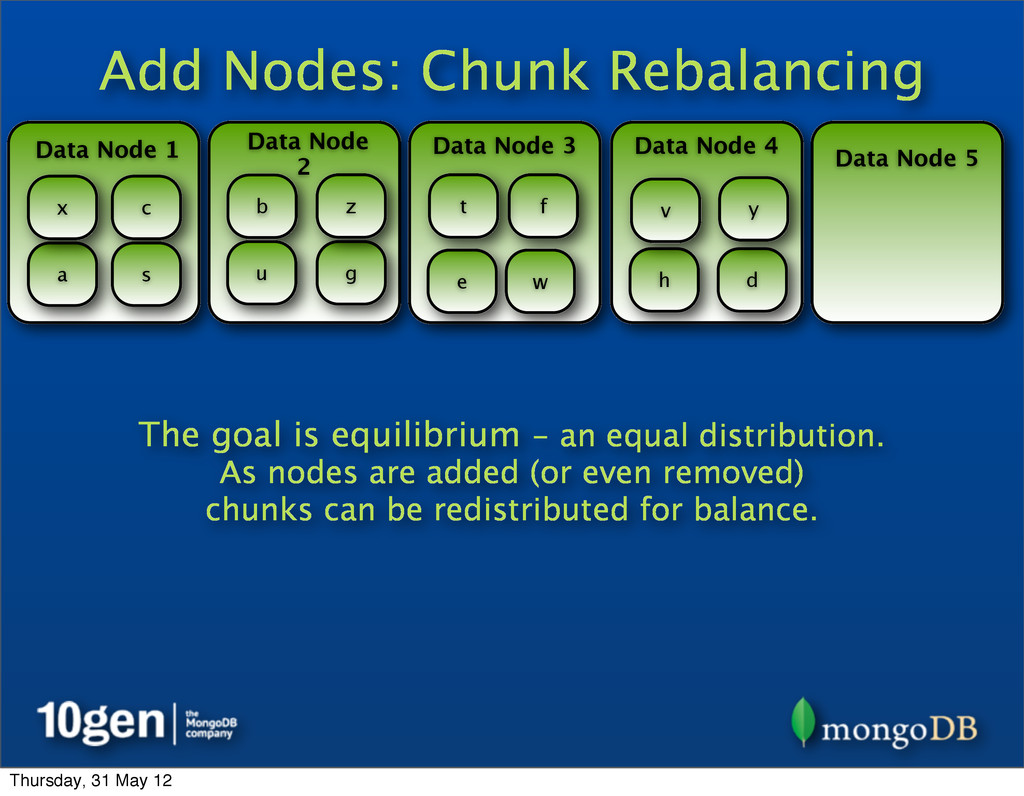
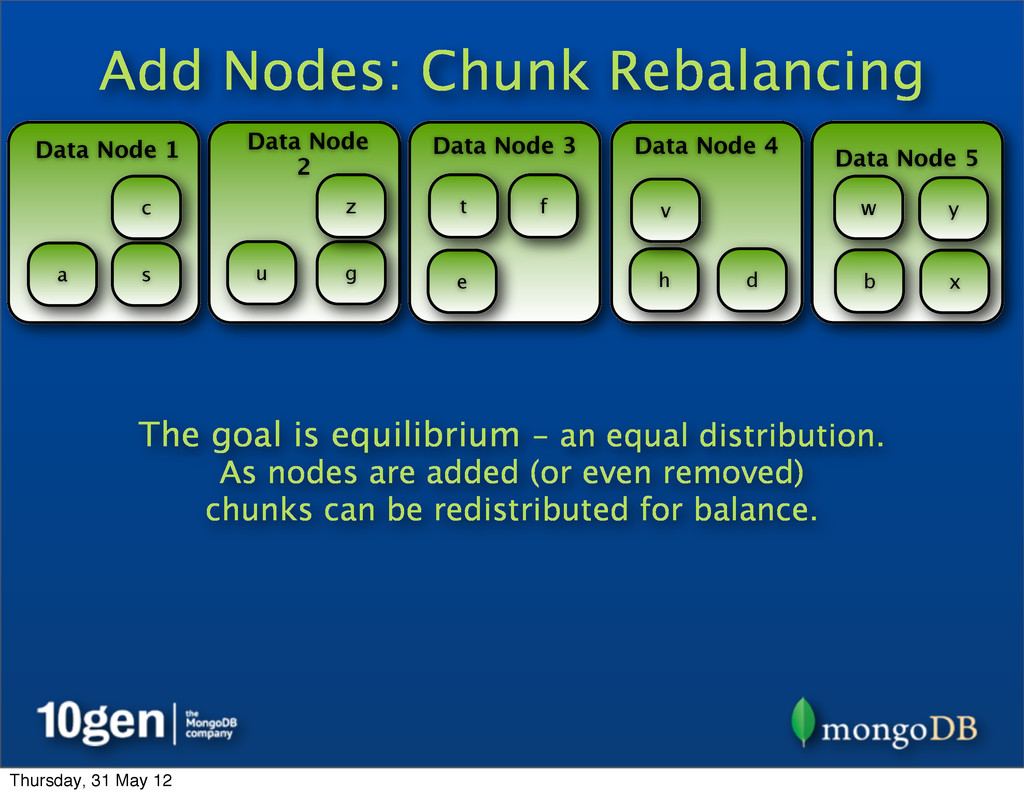
Add Nodes: Chunk Rebalancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z The goal is equilibrium - an equal distribution. As nodes are added (or even removed) chunks can be redistributed for balance. Thursday, 31 May 12 -
Add Nodes: Chunk Rebalancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z The goal is equilibrium - an equal distribution. As nodes are added (or even removed) chunks can be redistributed for balance. Thursday, 31 May 12 -
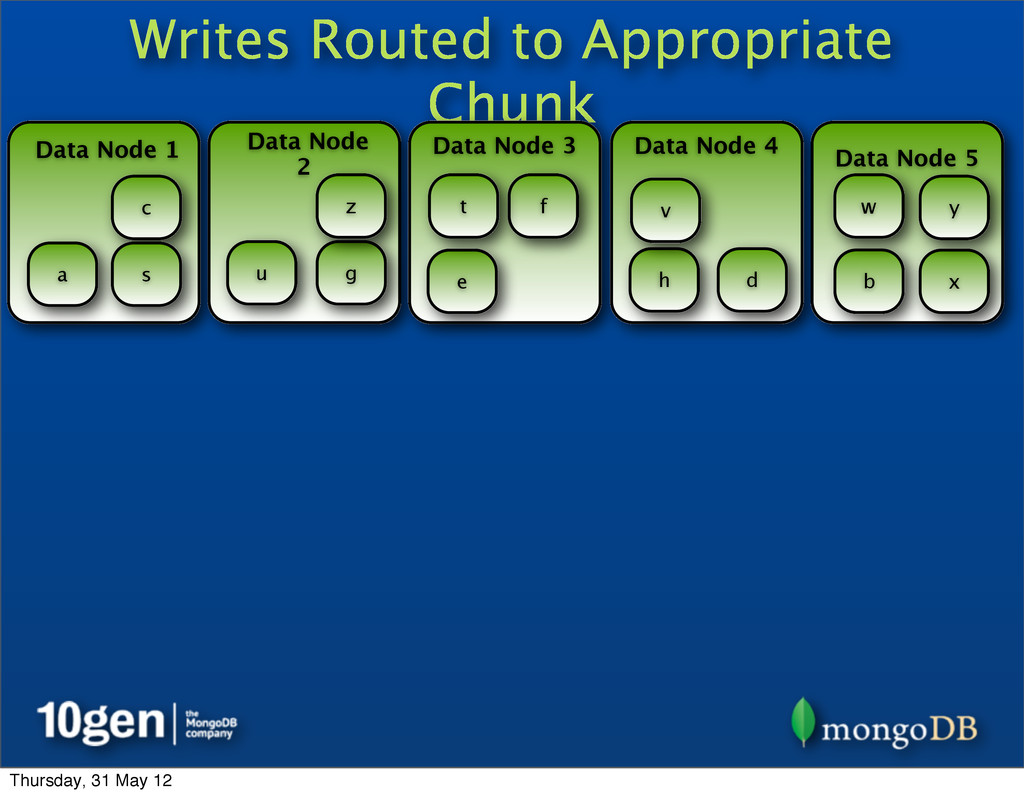
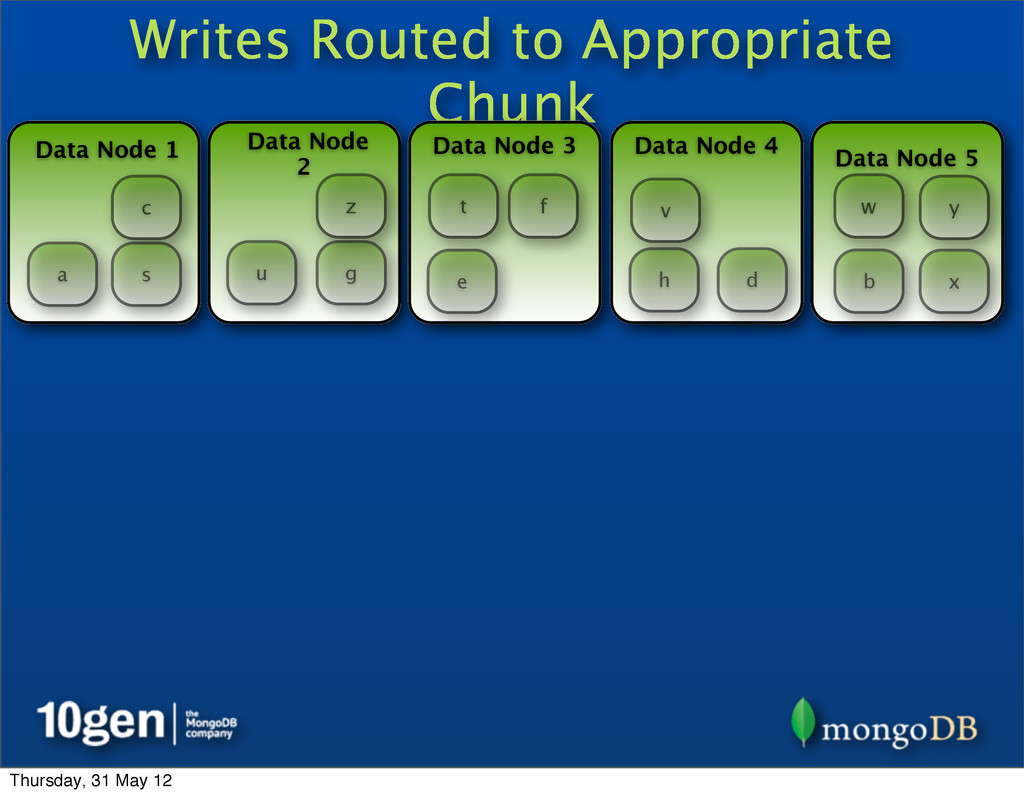
Writes Routed to Appropriate Chunk Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z Thursday, 31 May 12 -
Writes Routed to Appropriate Chunk Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z Thursday, 31 May 12 -
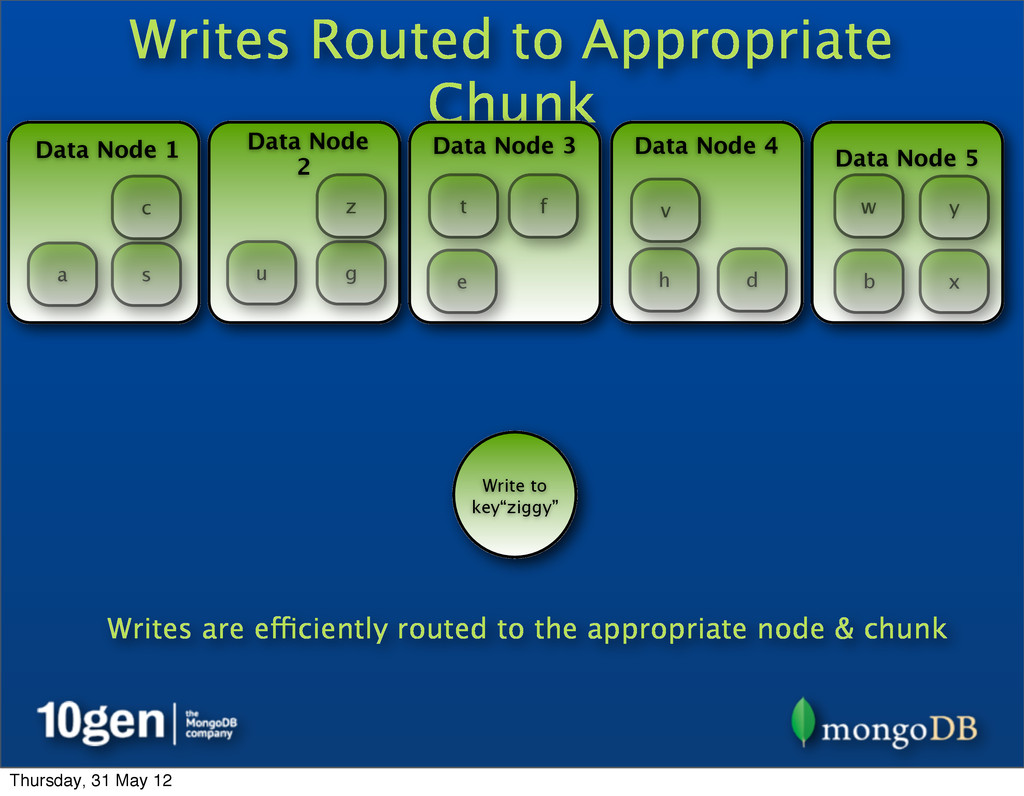
Writes Routed to Appropriate Chunk Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z Write to key“ziggy” z Writes are efficiently routed to the appropriate node & chunk Thursday, 31 May 12 -
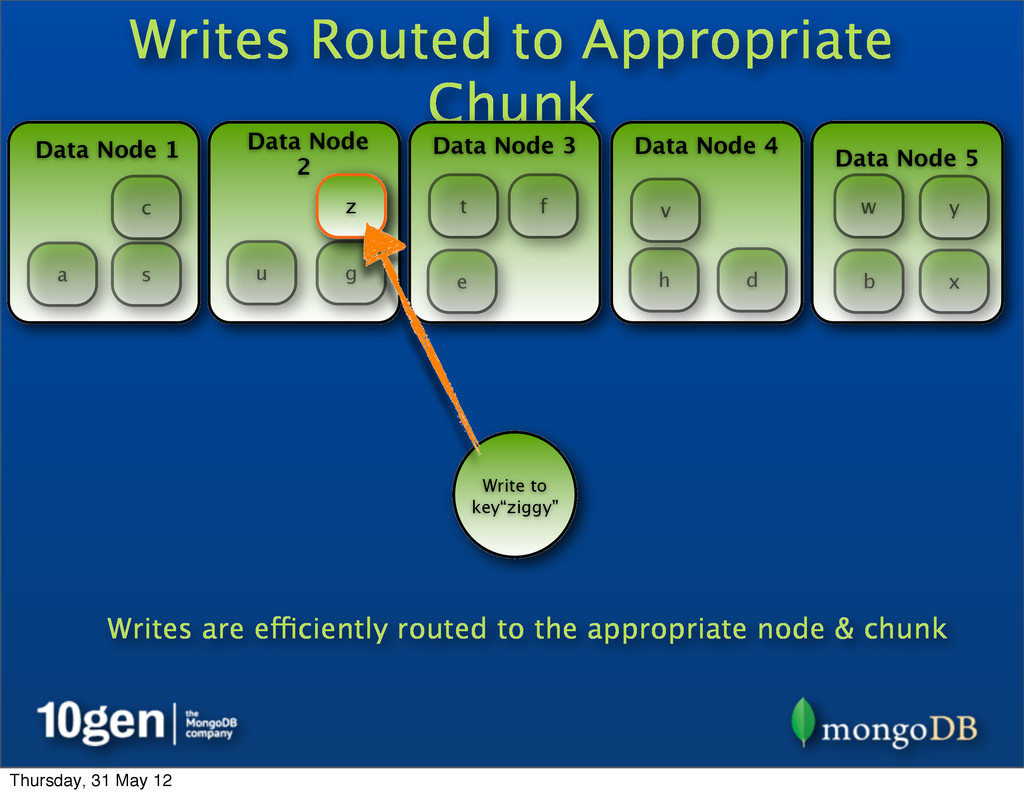
Writes Routed to Appropriate Chunk Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z Write to key“ziggy” z Writes are efficiently routed to the appropriate node & chunk Thursday, 31 May 12 -
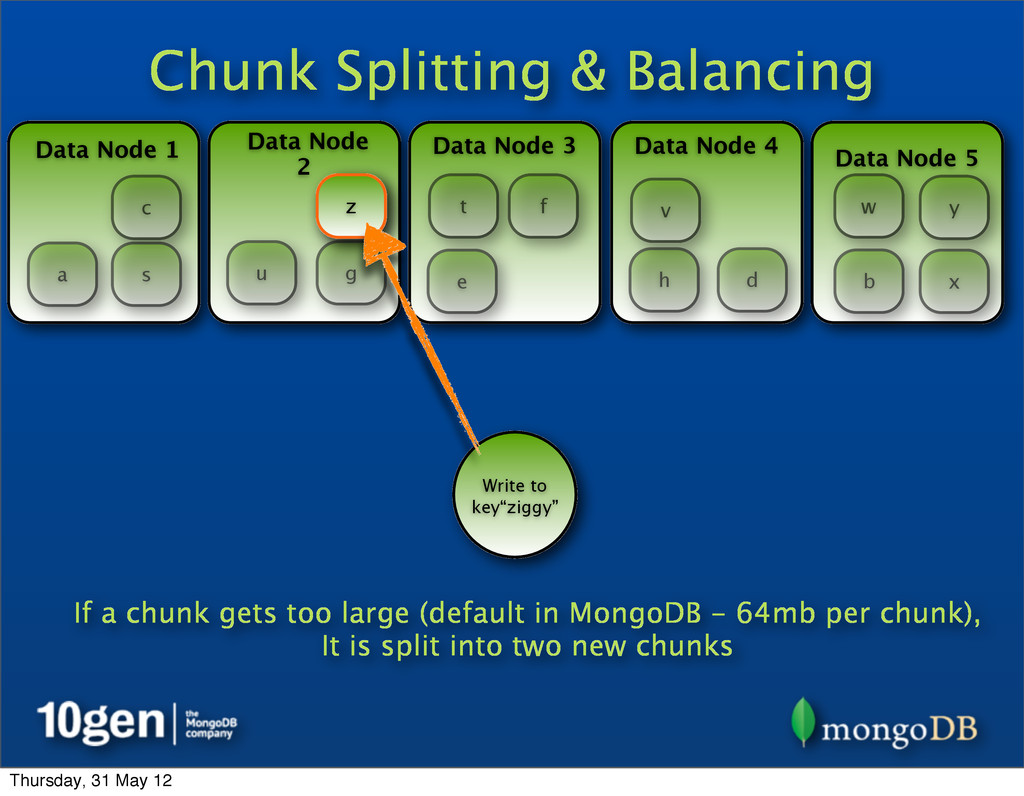
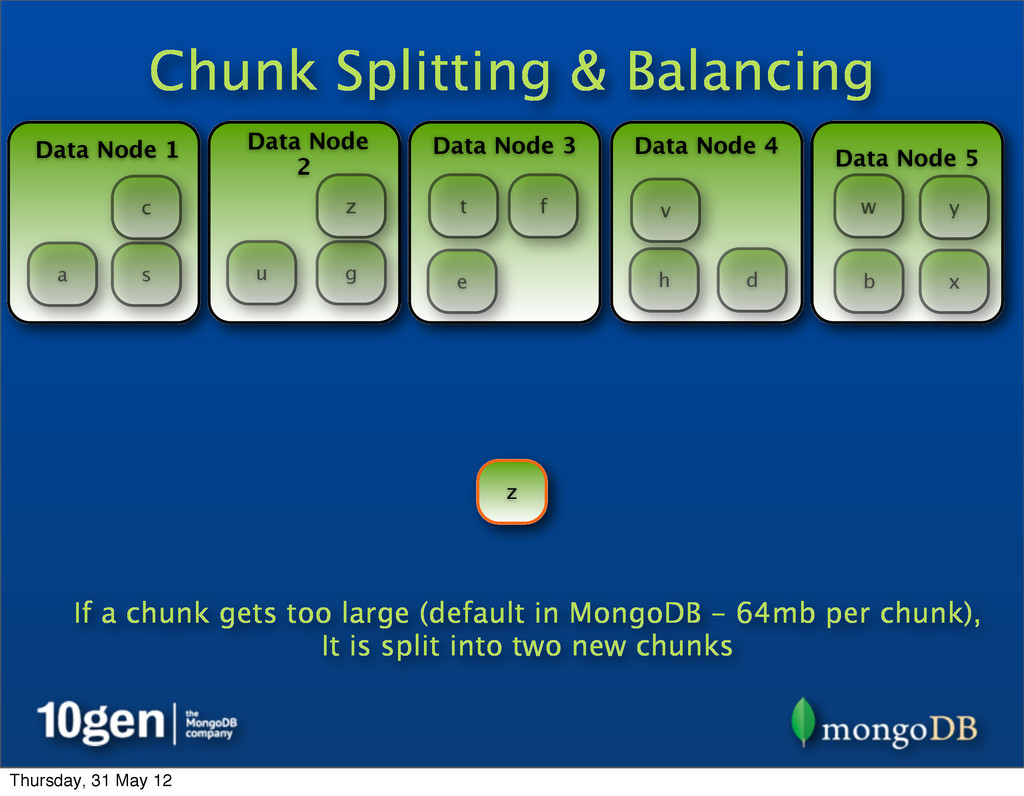
Chunk Splitting & Balancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z Write to key“ziggy” z If a chunk gets too large (default in MongoDB - 64mb per chunk), It is split into two new chunks Thursday, 31 May 12 -
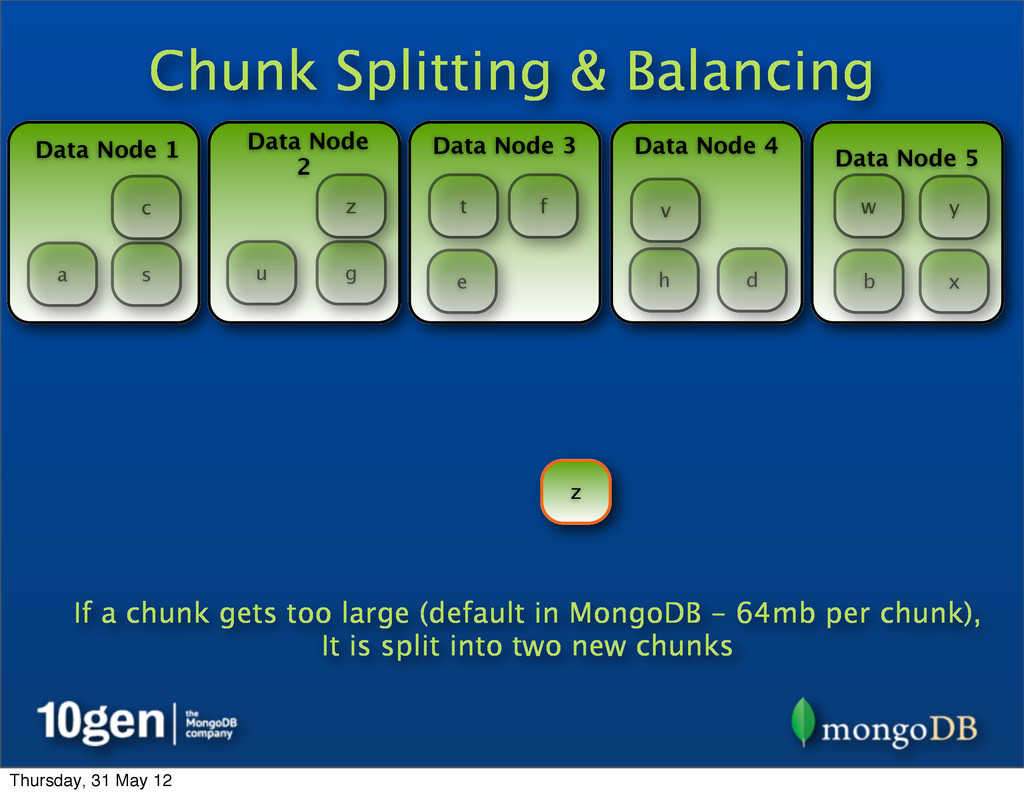
Chunk Splitting & Balancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z z If a chunk gets too large (default in MongoDB - 64mb per chunk), It is split into two new chunks Thursday, 31 May 12 -
Chunk Splitting & Balancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z z If a chunk gets too large (default in MongoDB - 64mb per chunk), It is split into two new chunks Thursday, 31 May 12 -
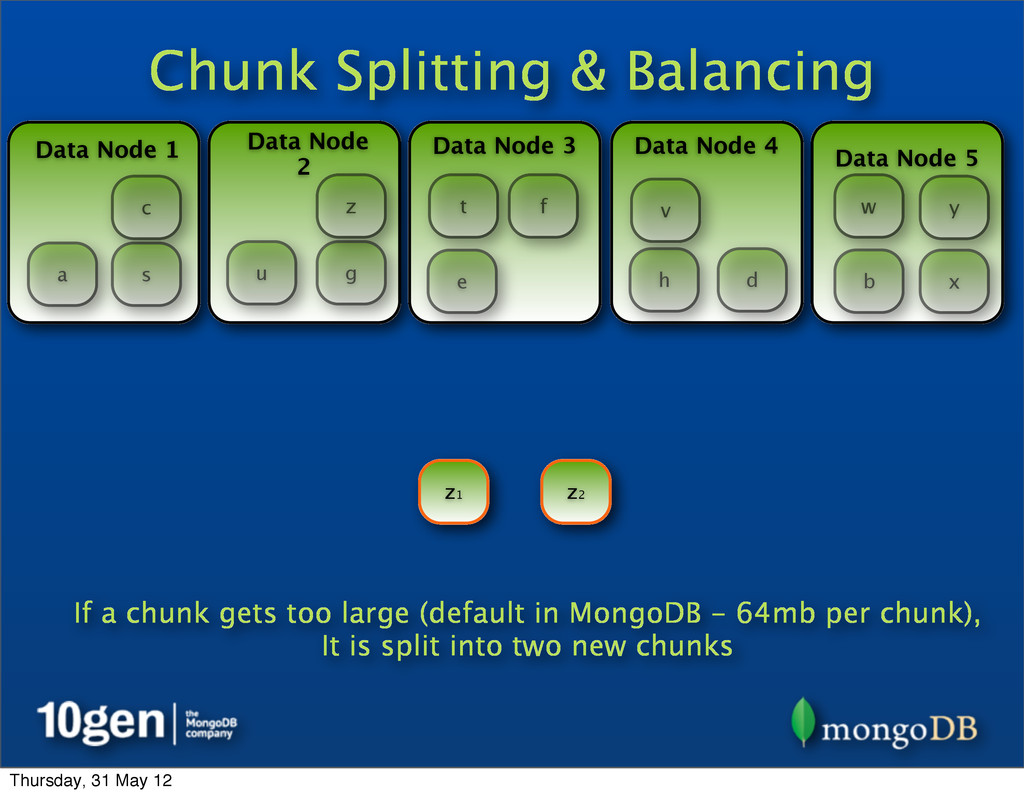
Chunk Splitting & Balancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z z2 If a chunk gets too large (default in MongoDB - 64mb per chunk), It is split into two new chunks z1 Thursday, 31 May 12 -
Chunk Splitting & Balancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z z2 If a chunk gets too large (default in MongoDB - 64mb per chunk), It is split into two new chunks z1 Thursday, 31 May 12 -
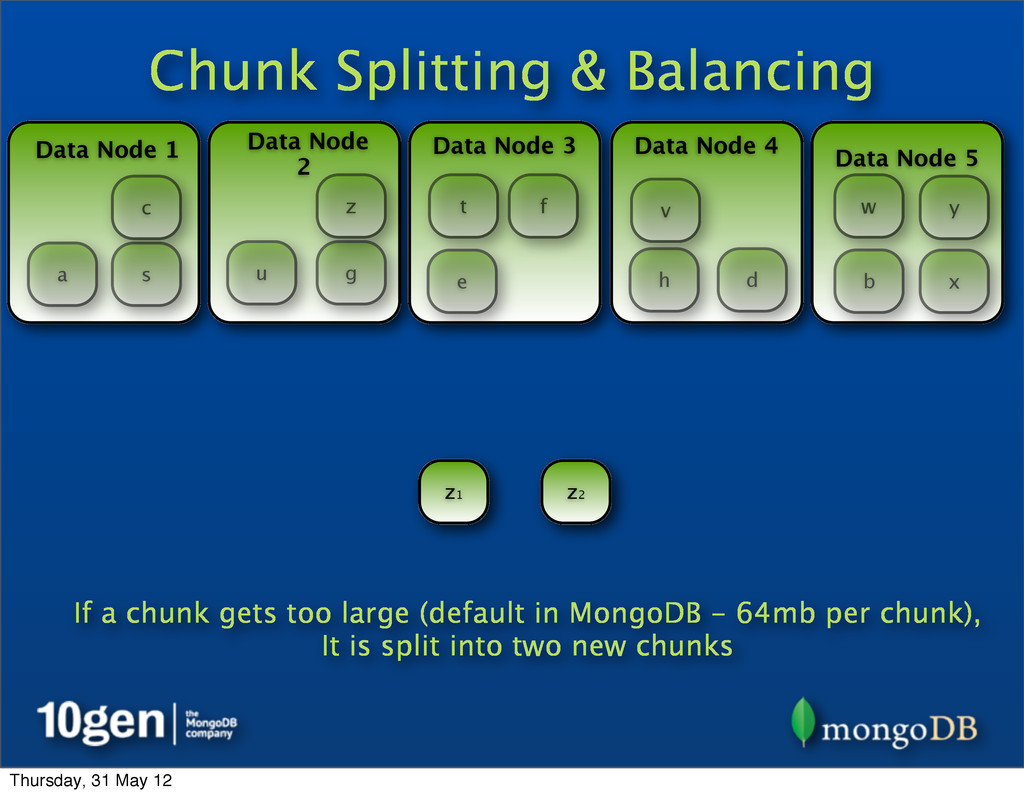
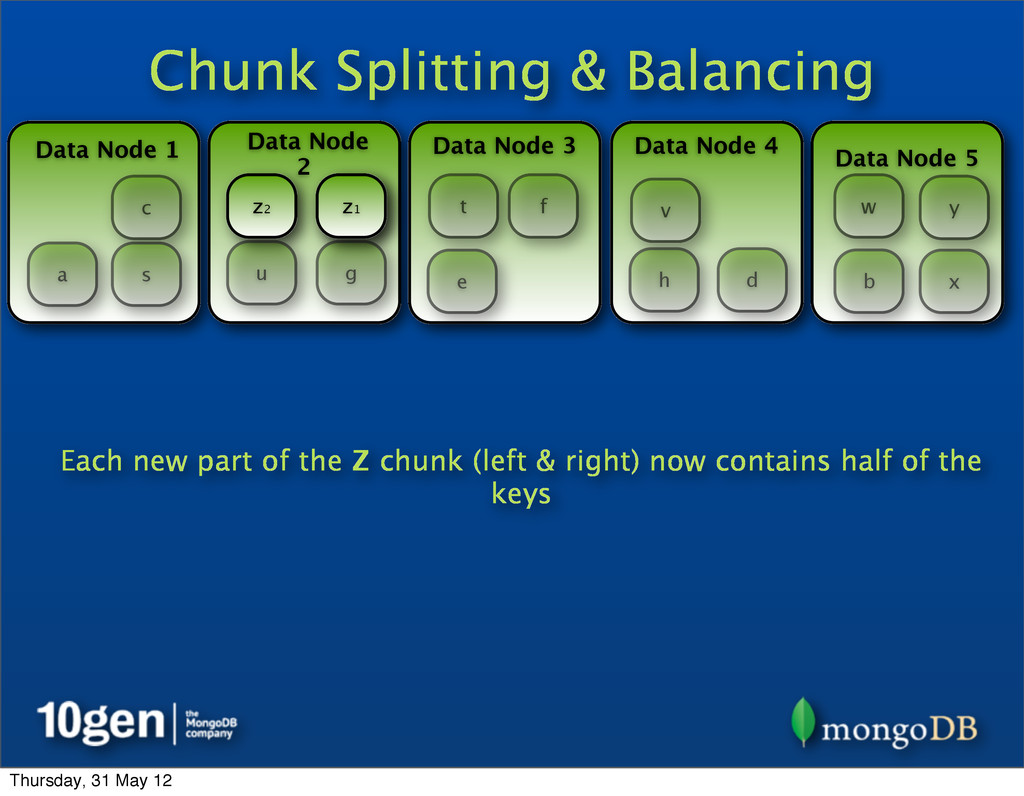
Chunk Splitting & Balancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z z2 z1 Each new part of the Z chunk (left & right) now contains half of the keys Thursday, 31 May 12 -
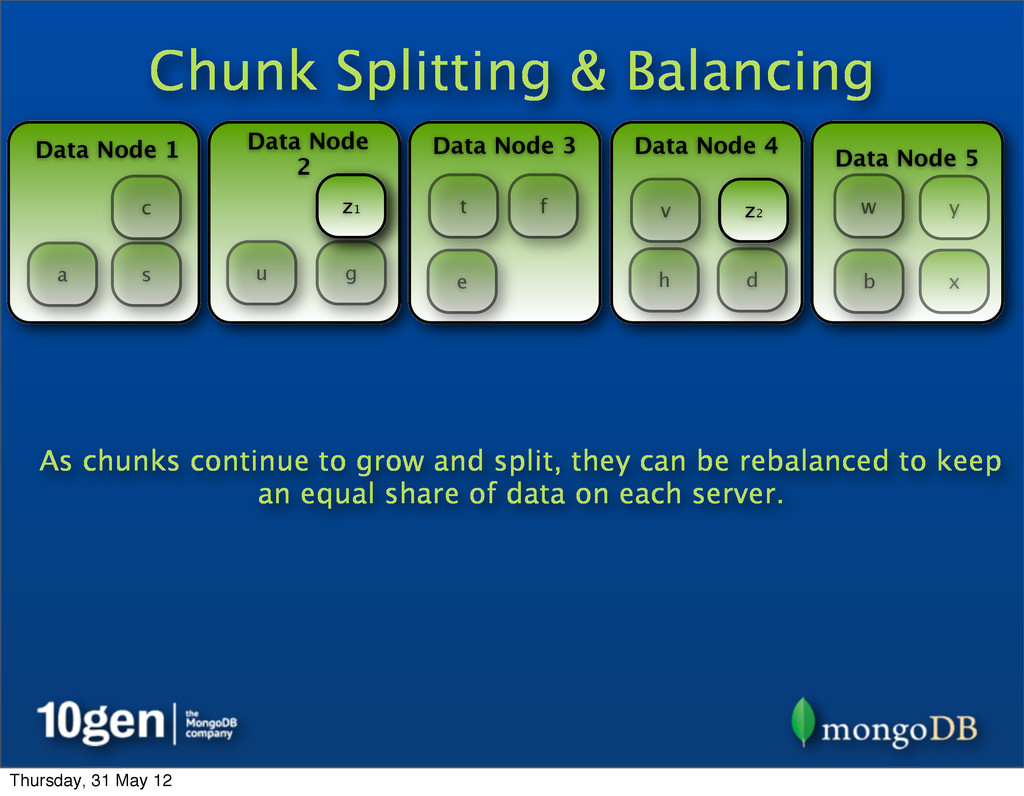
Chunk Splitting & Balancing Data Node 1 Data Node 2
Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z z2 z1 As chunks continue to grow and split, they can be rebalanced to keep an equal share of data on each server. Thursday, 31 May 12 -
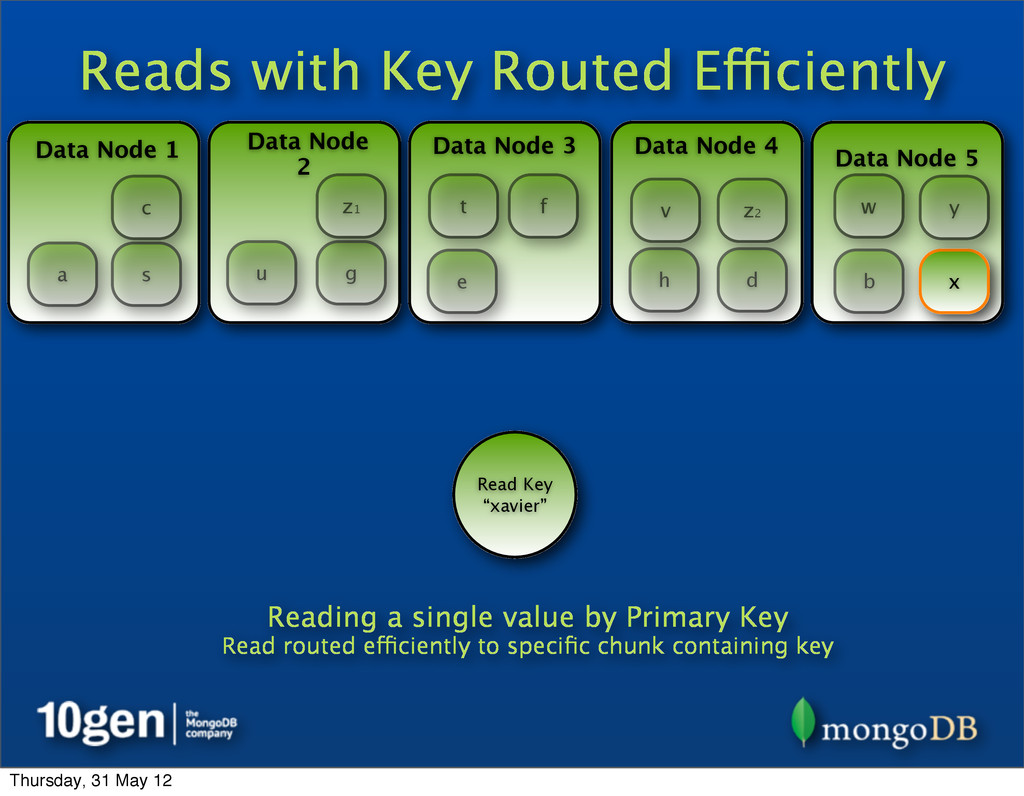
Reads with Key Routed Efficiently Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y z1 Read Key “xavier” Reading a single value by Primary Key Read routed efficiently to specific chunk containing key z2 Thursday, 31 May 12 -
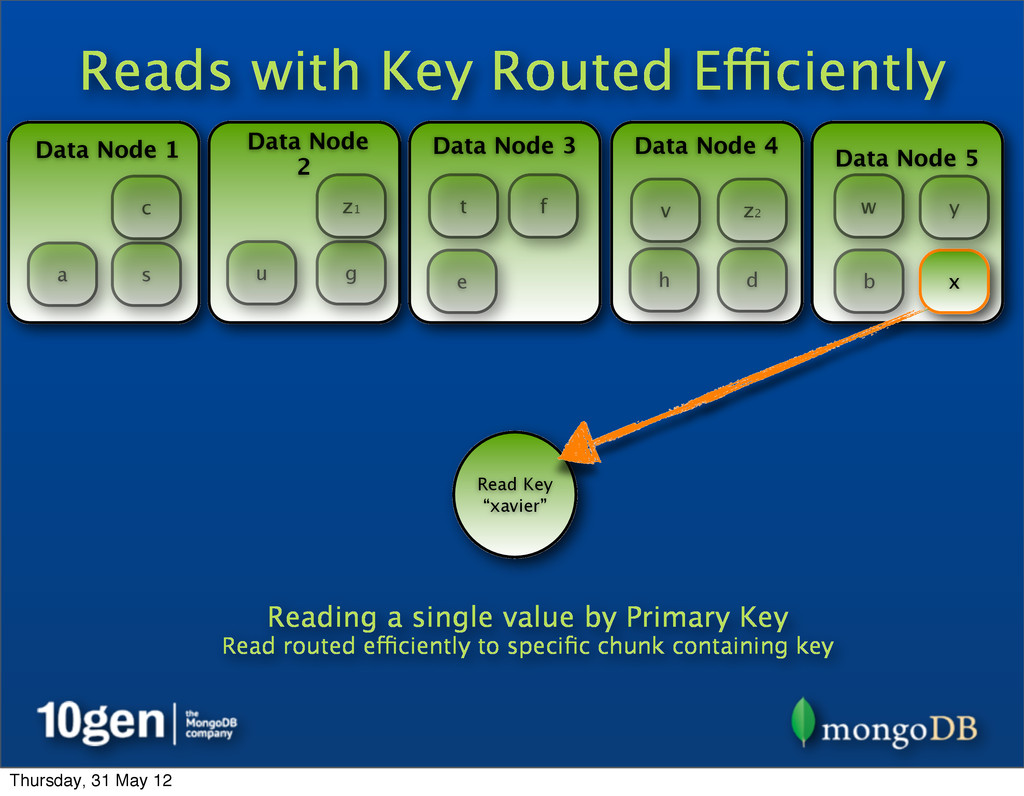
Reads with Key Routed Efficiently Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y Read Key “xavier” Reading a single value by Primary Key Read routed efficiently to specific chunk containing key z1 z2 Thursday, 31 May 12 -
Reads with Key Routed Efficiently Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y Read Key “xavier” Reading a single value by Primary Key Read routed efficiently to specific chunk containing key z1 z2 Thursday, 31 May 12 -
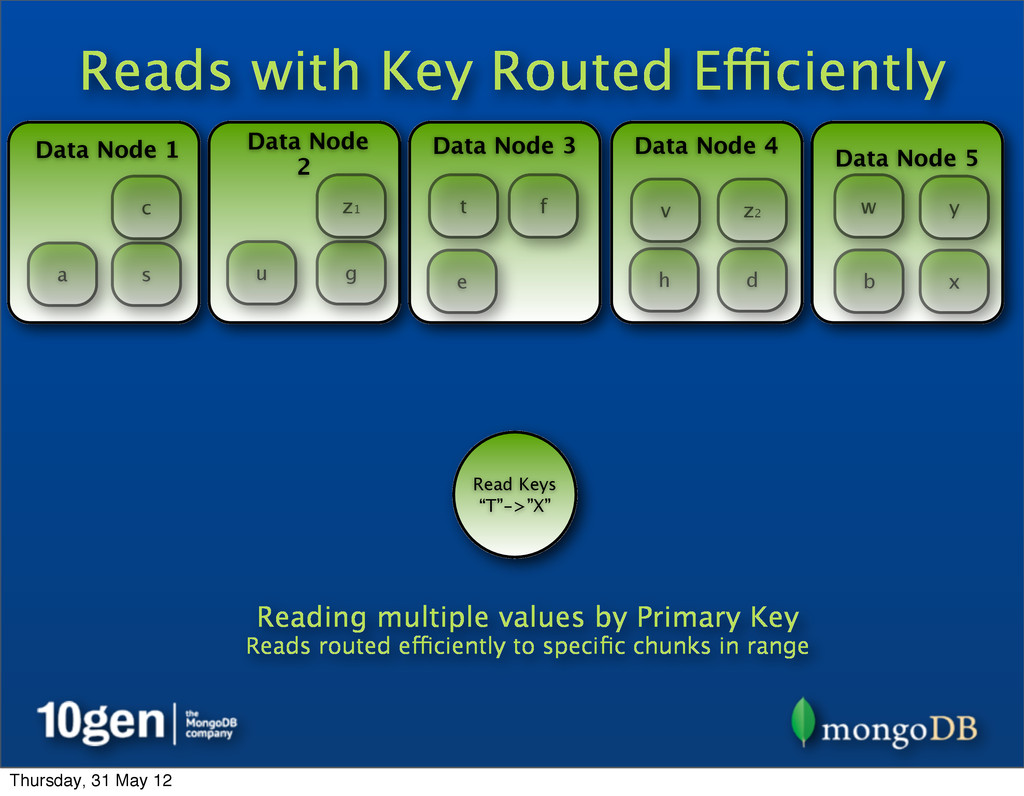
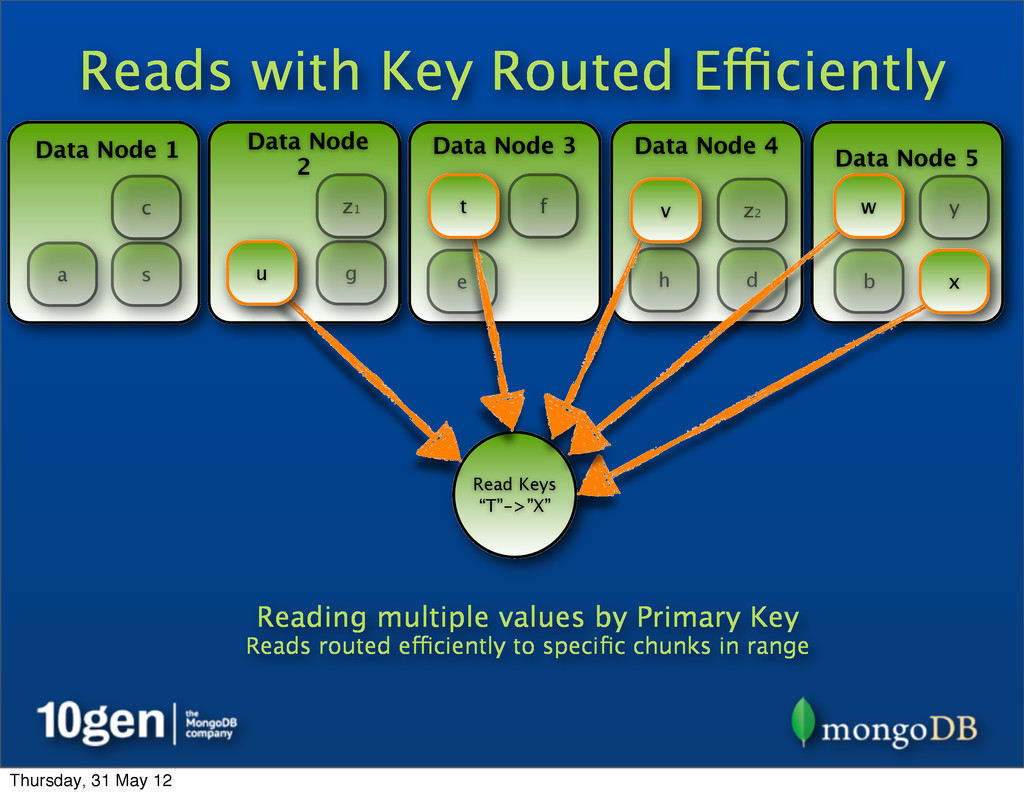
Reads with Key Routed Efficiently Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y Read Keys “T”->”X” Reading multiple values by Primary Key Reads routed efficiently to specific chunks in range t u v w x z1 z2 Thursday, 31 May 12 -
Reads with Key Routed Efficiently Data Node 1 Data Node
2 Data Node 3 Data Node 4 Data Node 5 a b c d e f g h s t u v w x y Read Keys “T”->”X” Reading multiple values by Primary Key Reads routed efficiently to specific chunks in range t u v w x z1 z2 Thursday, 31 May 12 -
MongoDB Sharding • Automatic partitioning and management • Range based
• Convert to sharded system with no downtime • Fully consistent Thursday, 31 May 12 -
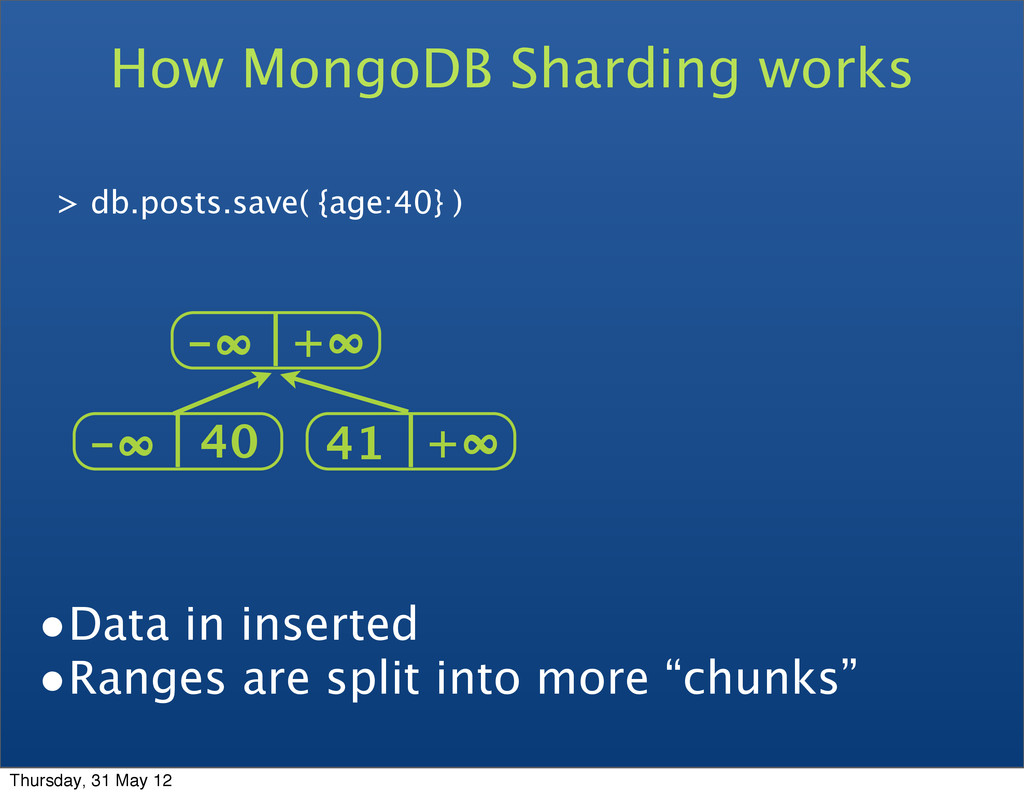
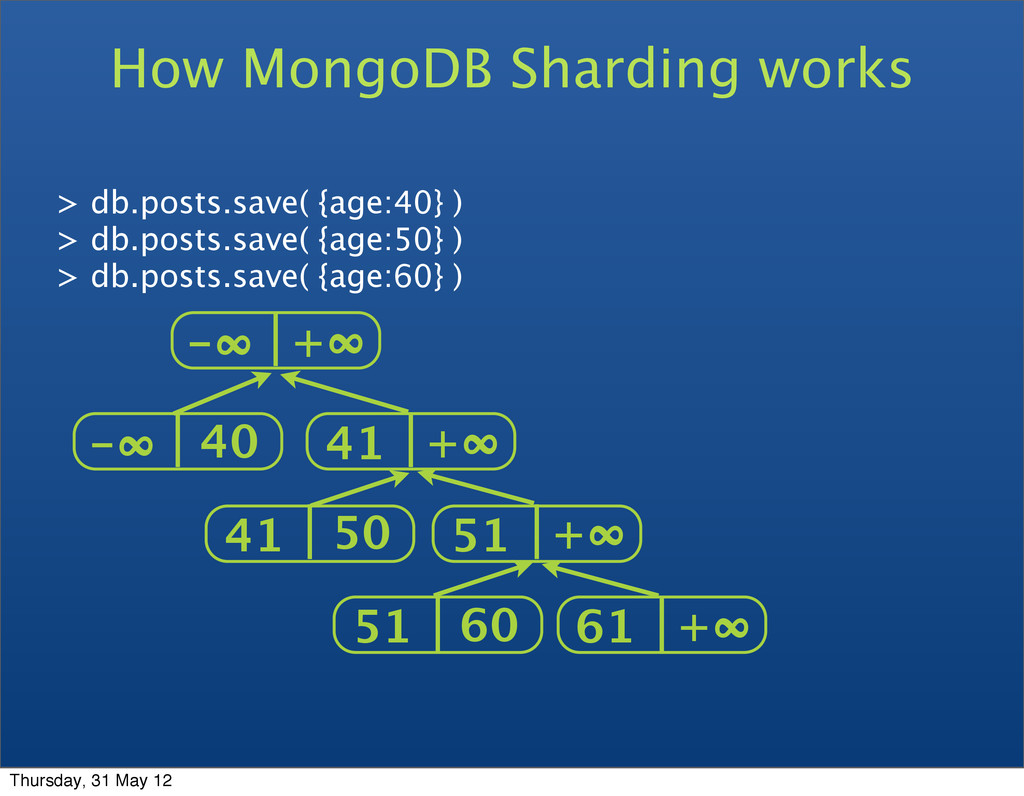
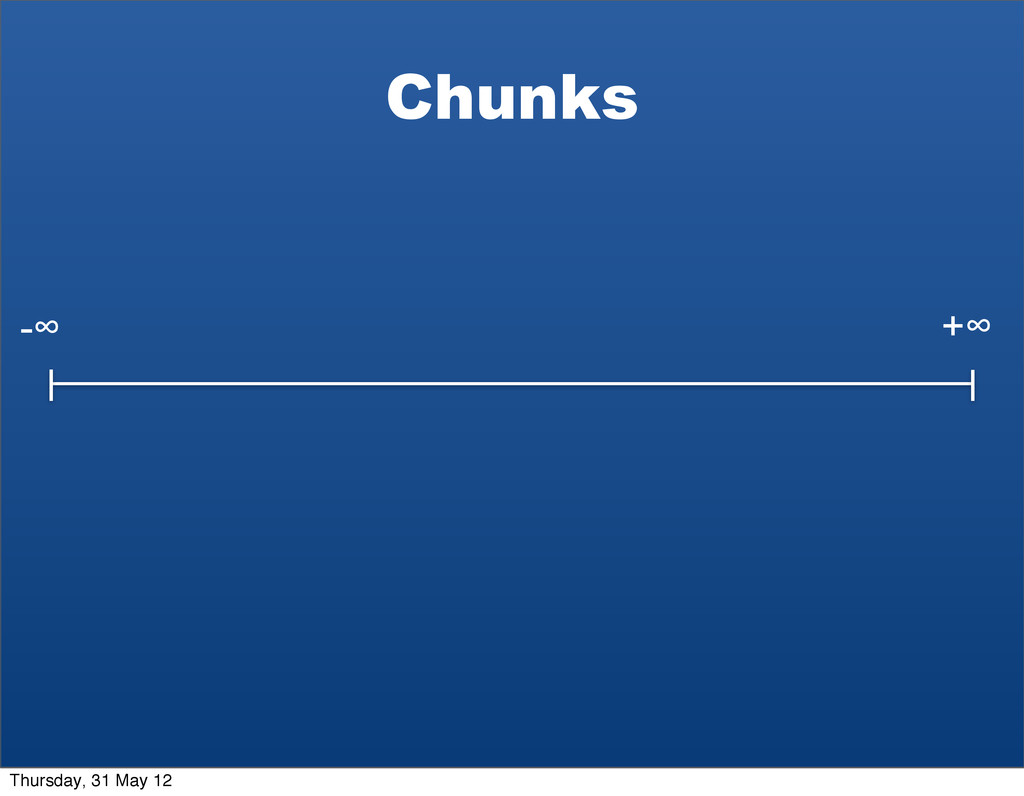
How MongoDB Sharding works > db.posts.save( {age:40} ) -∞ +∞
-∞ 40 41 +∞ •Data in inserted •Ranges are split into more “chunks” Thursday, 31 May 12 -
How MongoDB Sharding works > db.posts.save( {age:40} ) > db.posts.save(
{age:50} ) > db.posts.save( {age:60} ) -∞ +∞ -∞ 40 41 +∞ 41 50 51 +∞ 61 +∞ 51 60 Thursday, 31 May 12 -
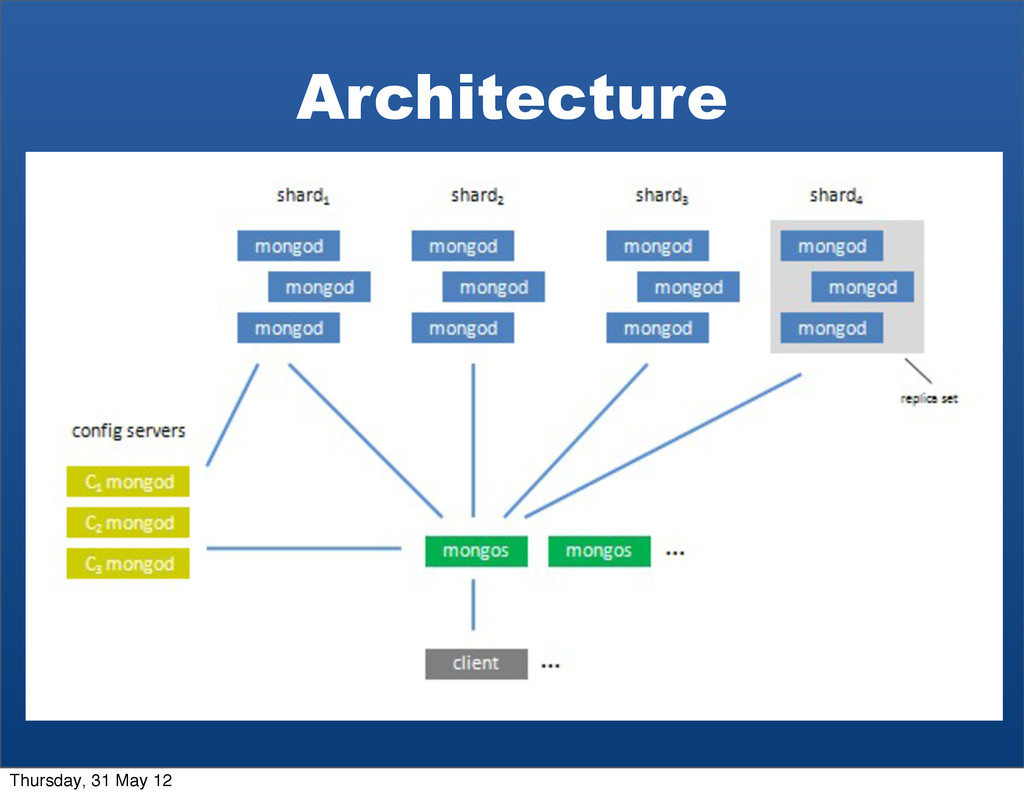
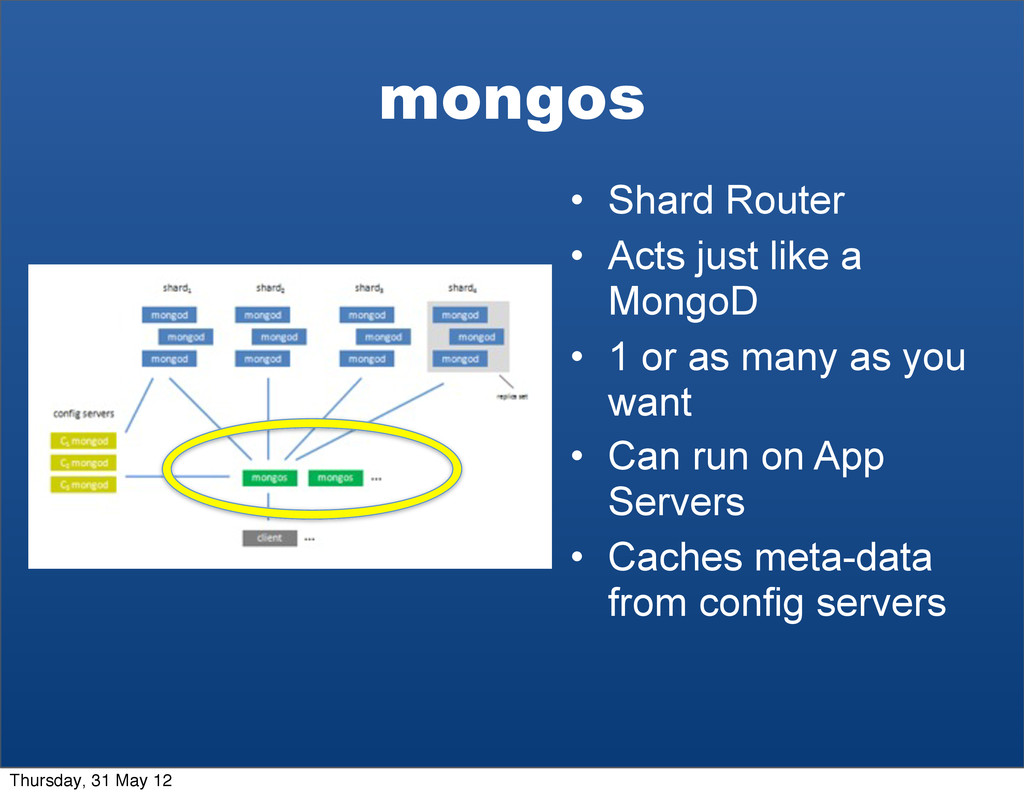
mongos • Shard Router • Acts just like a MongoD
• 1 or as many as you want • Can run on App Servers • Caches meta-data from config servers Thursday, 31 May 12 -
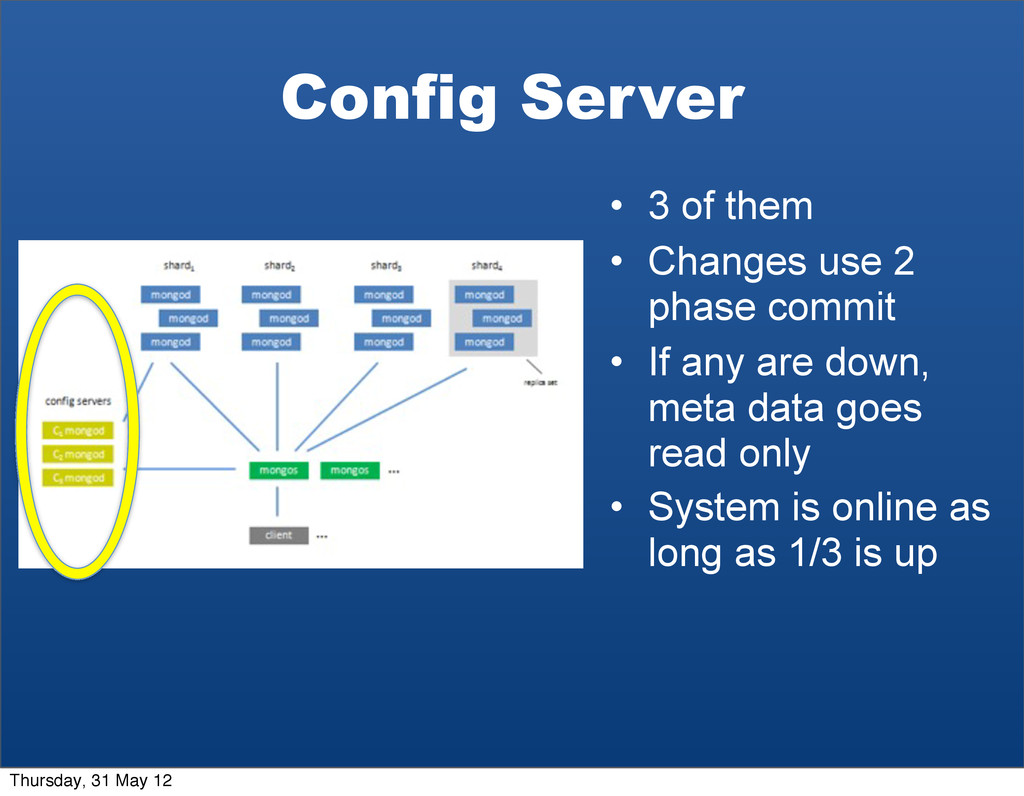
Config Server • 3 of them • Changes use 2
phase commit • If any are down, meta data goes read only • System is online as long as 1/3 is up Thursday, 31 May 12 -
Keys { name: “Jared”, email: “[email protected]”, } { name: “Scott”,
email: “[email protected]”, } { name: “Dan”, email: “[email protected]”, } > db.runCommand( { shardcollection: “test.users”, key: { email: 1 }} ) Thursday, 31 May 12 -
Chunks -∞ +∞ [email protected] [email protected] [email protected] Split! This is a
chunk This is a chunk Thursday, 31 May 12 -
Chunks Min Key Max Key Shard -∞ [email protected] 1 [email protected]
[email protected] 1 [email protected] [email protected] 1 [email protected] +∞ 1 • Stored in the config servers • Cached in MongoS • Used to route requests and keep cluster balanced Thursday, 31 May 12 -
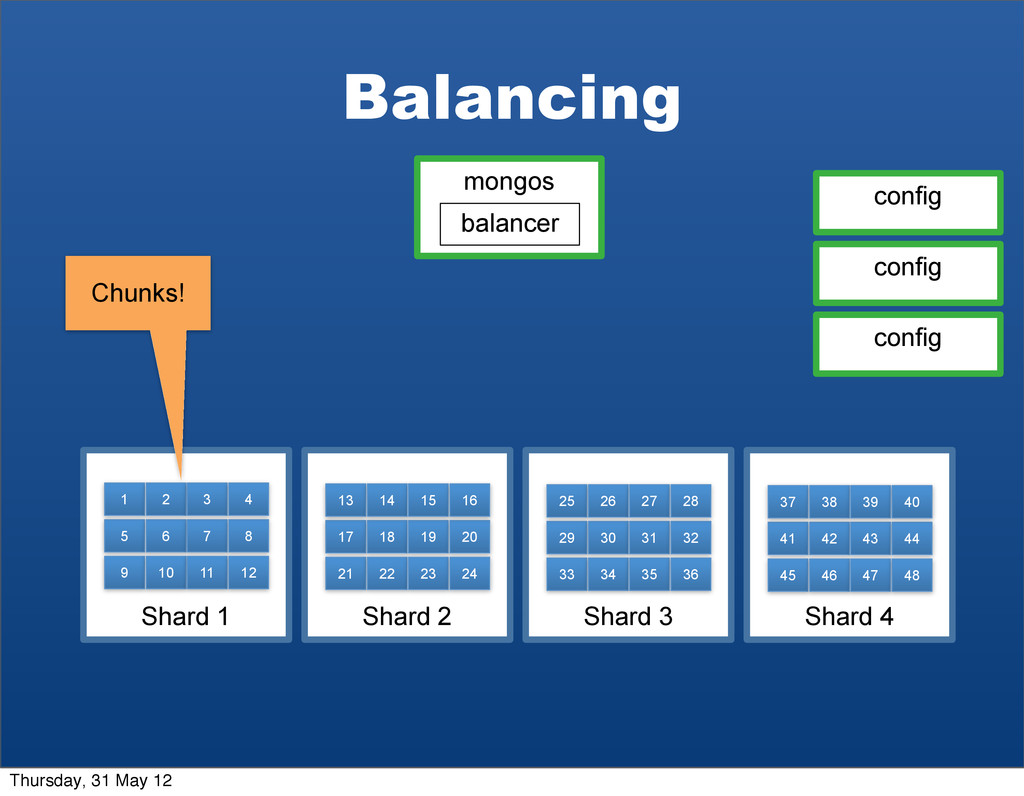
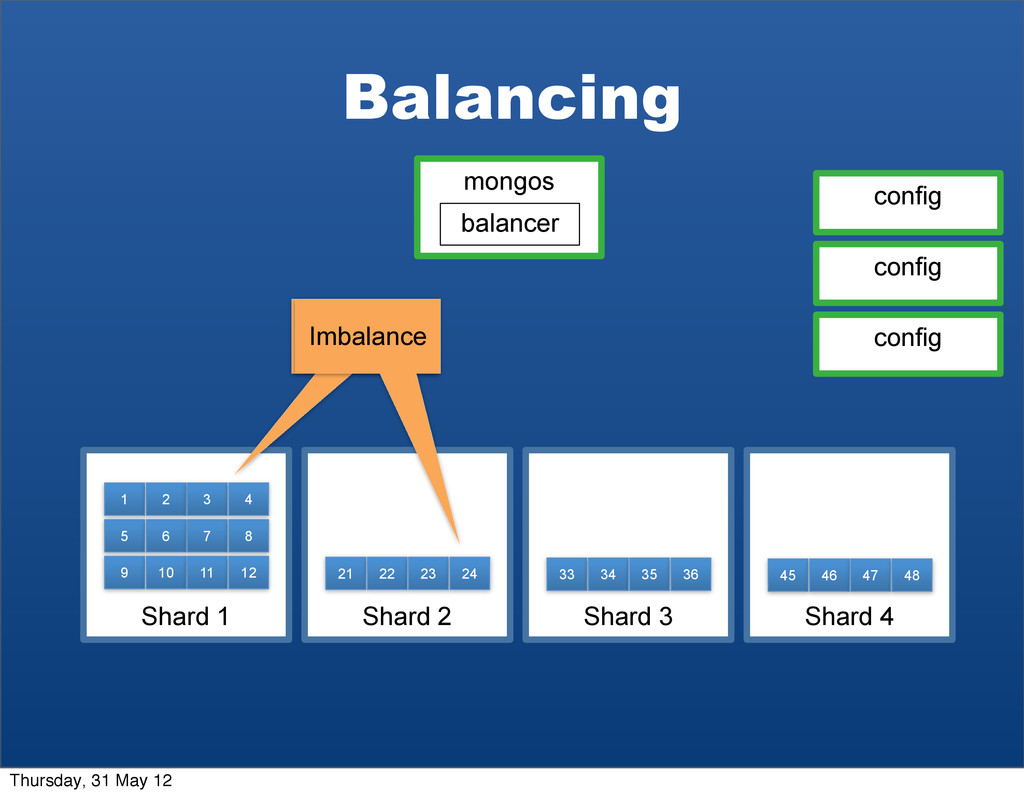
Balancing Shard 1 Shard 2 Shard 3 Shard 4 5
9 1 6 10 2 7 11 3 8 12 4 17 21 13 18 22 14 19 23 15 20 24 16 29 33 25 30 34 26 31 35 27 32 36 28 41 45 37 42 46 38 43 47 39 44 48 40 mongos balancer config config config Chunks! Thursday, 31 May 12 -
Balancing mongos balancer config config config Shard 1 Shard 2
Shard 3 Shard 4 5 9 1 6 10 2 7 11 3 8 12 4 21 22 23 24 33 34 35 36 45 46 47 48 Imbalance Imbalance Thursday, 31 May 12 -
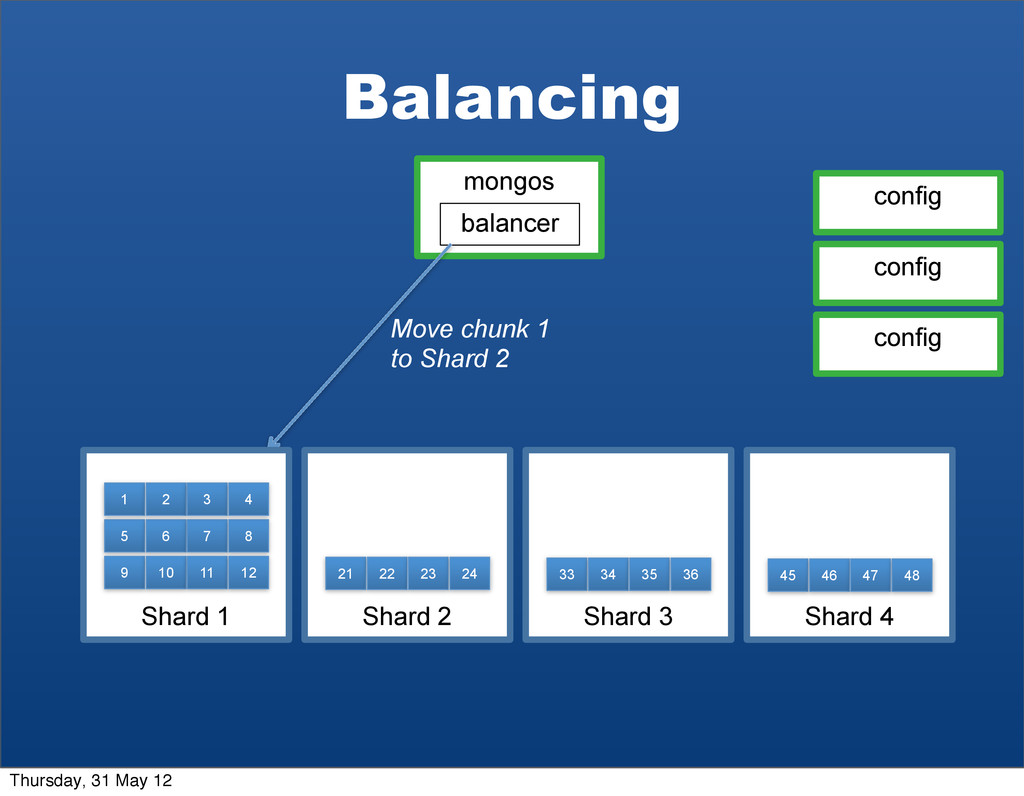
Balancing mongos balancer Move chunk 1 to Shard 2 config
config config Shard 1 Shard 2 Shard 3 Shard 4 5 9 1 6 10 2 7 11 3 8 12 4 21 22 23 24 33 34 35 36 45 46 47 48 Thursday, 31 May 12 -
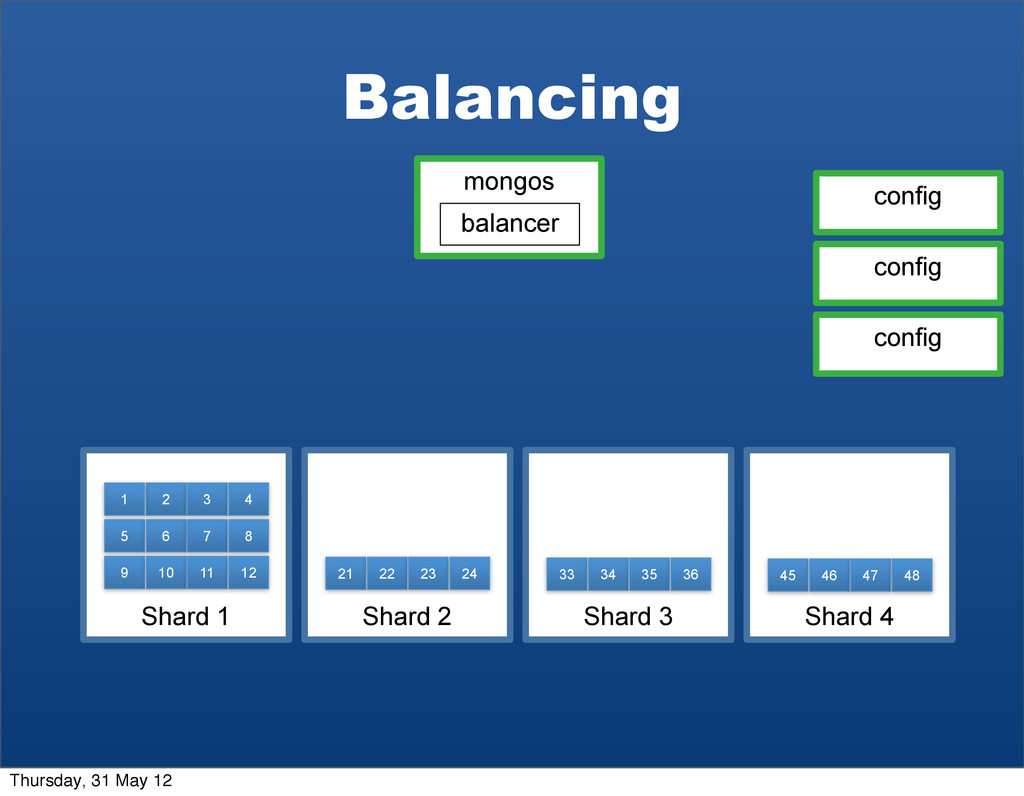
Balancing mongos balancer config config config Shard 1 Shard 2
Shard 3 Shard 4 5 9 6 10 2 7 11 3 8 12 4 21 22 23 24 33 34 35 36 45 46 47 48 1 Thursday, 31 May 12 -
Balancing mongos balancer config config config Shard 1 Shard 2
Shard 3 Shard 4 5 9 6 10 2 7 11 3 8 12 4 21 22 23 24 33 34 35 36 45 46 47 48 1 Thursday, 31 May 12 -
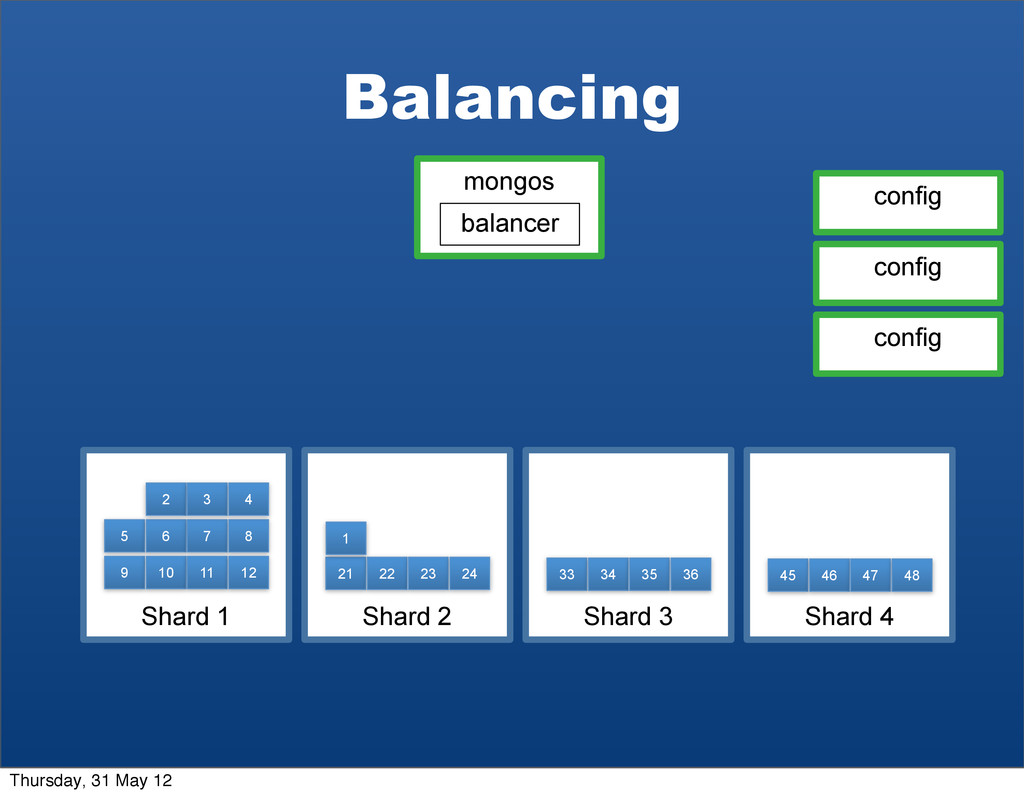
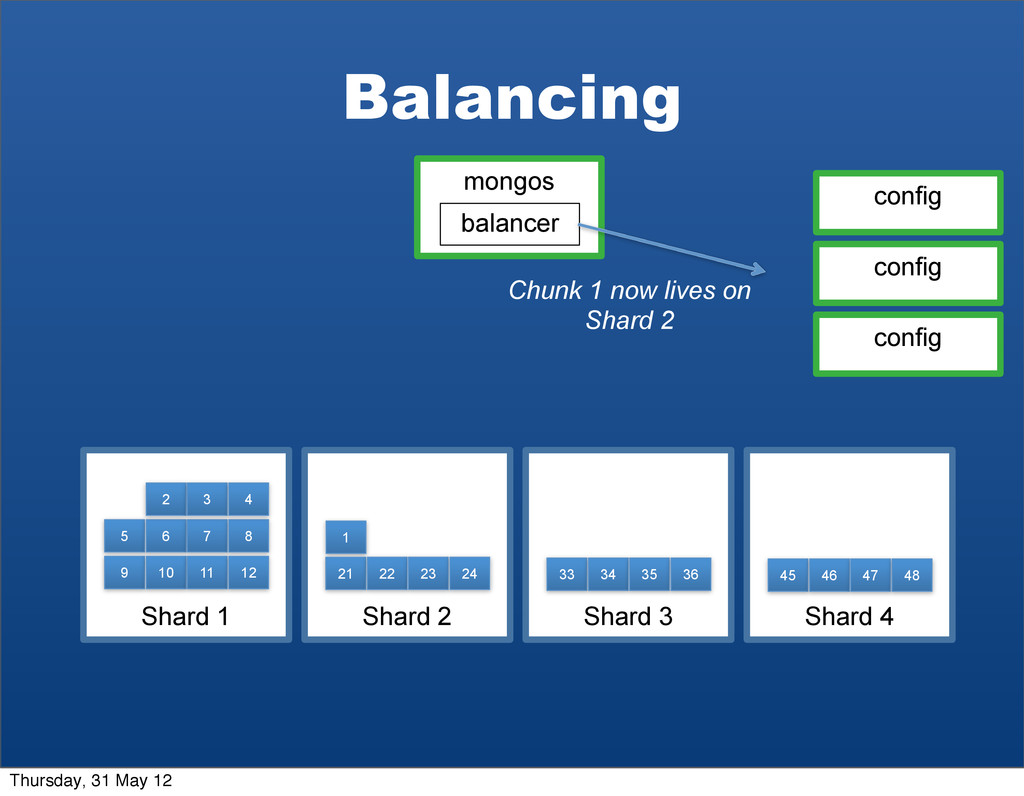
Balancing mongos balancer Chunk 1 now lives on Shard 2
config config config Shard 1 Shard 2 Shard 3 Shard 4 5 9 1 6 10 2 7 11 3 8 12 4 21 22 23 24 33 34 35 36 45 46 47 48 Thursday, 31 May 12 -
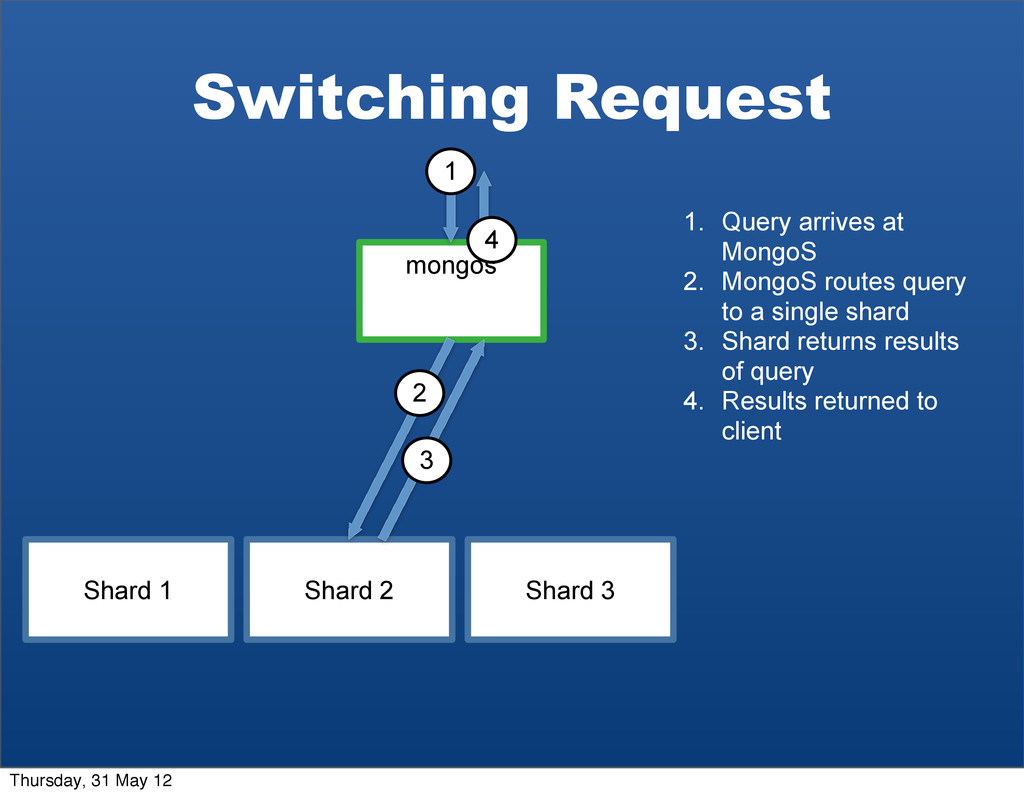
Switching Request mongos Shard 1 Shard 2 Shard 3 1
2 3 4 1. Query arrives at MongoS 2. MongoS routes query to a single shard 3. Shard returns results of query 4. Results returned to client Thursday, 31 May 12 -
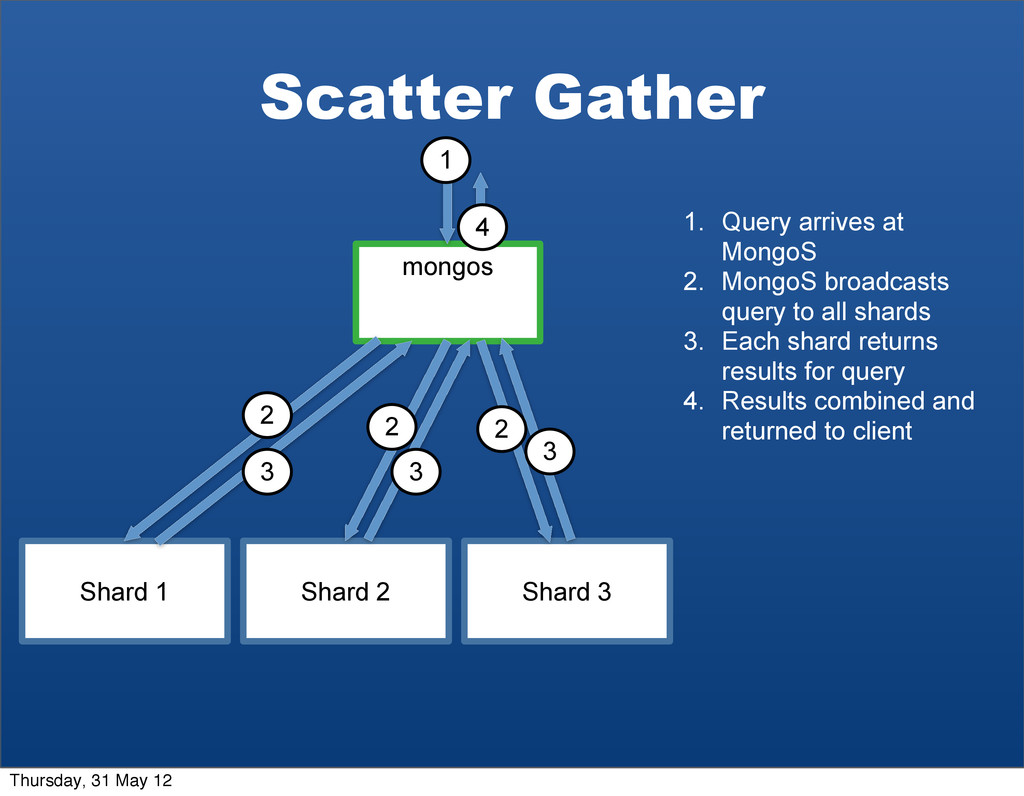
Scatter Gather mongos Shard 1 Shard 2 Shard 3 1
4 1. Query arrives at MongoS 2. MongoS broadcasts query to all shards 3. Each shard returns results for query 4. Results combined and returned to client 2 2 3 3 2 3 Thursday, 31 May 12 -
Writes Inserts Requires shard key db.users.insert({ name: “Jared”, email: “[email protected]”})
Removes Routed db.users.delete({ email: “[email protected]”}) Removes Scattered db.users.delete({name: “Jared”}) Updates Routed db.users.update( {email: “[email protected]”}, {$set: { state: “CA”}}) Updates Scattered db.users.update( {state: “FZ”}, {$set:{ state: “CA”}} ) Thursday, 31 May 12 -
Queries By Shard Key Routed db.users.find( {email: “[email protected]”}) Sorted by
shard key Routed in order db.users.find().sort({email:-1}) Find by non shard key Scatter Gather db.users.find({state:”CA”}) Sorted by non shard key Distributed merge sort db.users.find().sort({state:1}) Thursday, 31 May 12 -
conferences, appearances http://www.10gen.com/events download at mongodb.org We’re Hiring ! Chris
Harris Email : [email protected] Twitter : cj_harris5 Thursday, 31 May 12