Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Introduction to Big Data Engineering

Sponsored · SiteGround - Reliable hosting with speed, security, and support you can count on. →

Introduction to Big Data Engineering

How to construct algorithms that can scale

Felix Chern

March 11, 2015

Transcript

28 slides
  1. About me • Felix Chern • 2 years of Hadoop

    Experience • MapReduce and Hive • Started hadoop using 8 nodes cluster • Later joined OpenX to manage and develop on 600+ nodes cluster • 100+TB/day data volume • http://idryman.org
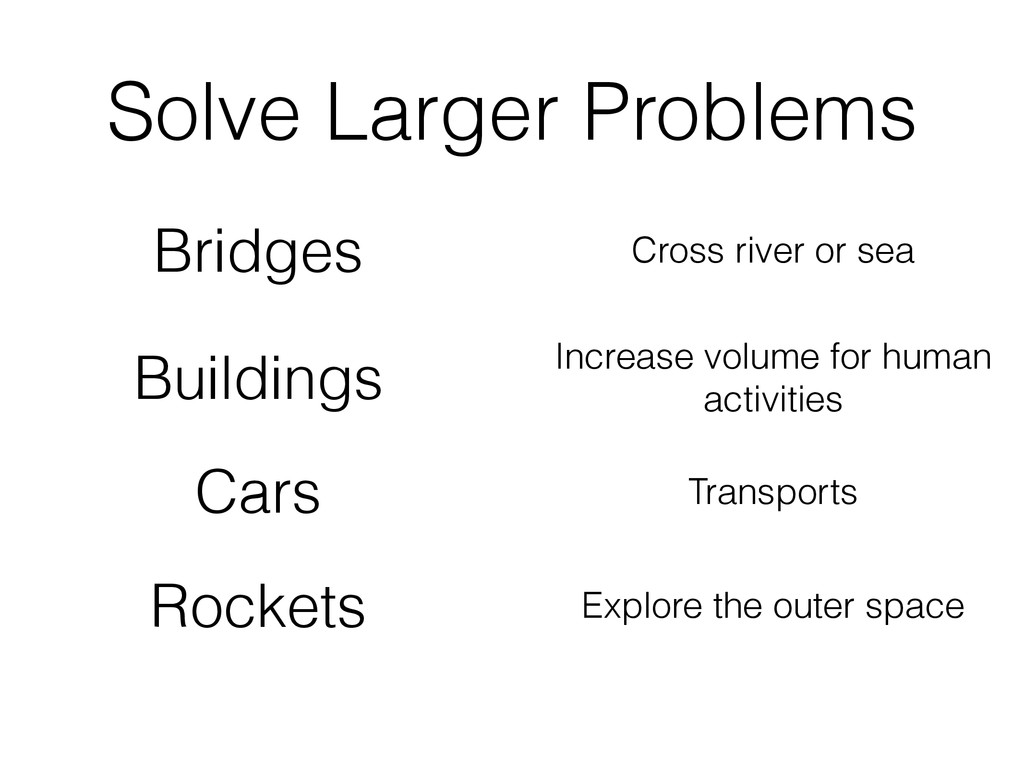
  2. Bridges Buildings Cars Rockets Solve Larger Problems Cross river or

    sea Increase volume for human activities Transports Explore the outer space
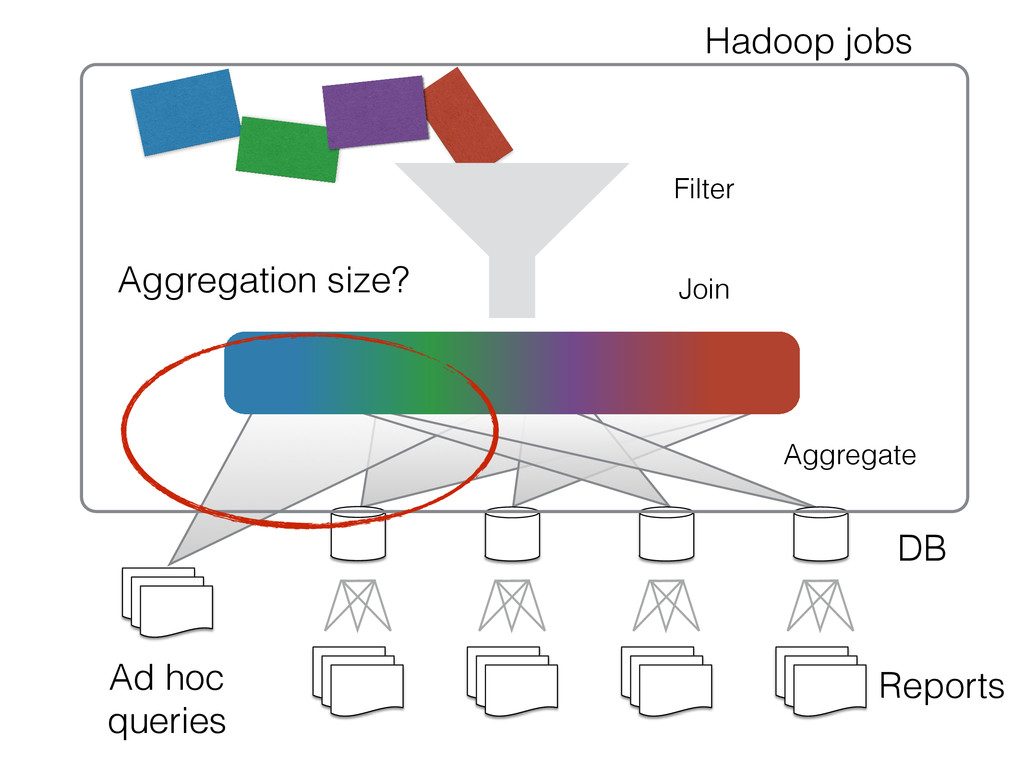
  3. Data Engineering Problems • Maintain the data flow • Extract

    Transform Load (ETL) • Downstream consumer: reporting and analytics • Data correctness • System stability
  4. Extract Transform Load • De-duplicate (remove unwanted data) • Join

    relevant data • Aggregations in different perspective • select … from large_table group by buyers; • select … from large_table group by publishers;
  5. Estimate instead of actual run • Estimate the properties of

    an aggregation (or any other data operations) • Cardinality • Frequency distribution (is data skewed?) • Top-k elements • Don’t need to be precise, but be fast and stable
  6. Probabilistic Data Structure/Algorithms • Cardinality -> hyperloglog • Frequency distribution

    -> count-min-sketch • Top-k elements -> lossy count Runtime: ! O(log(N)) Data size: ! several kbs
  7. Cardinality test • Goal: find out the distinct element count

    of a given query • Naive approach 1: Put into a hash set! • not enough memory! • Approach 2: Hash the input to a BitSet (allow collisions) • Linear counting [ACM’90] • Estimate collision impacts • Still require 1/10 size of the input (too large!)
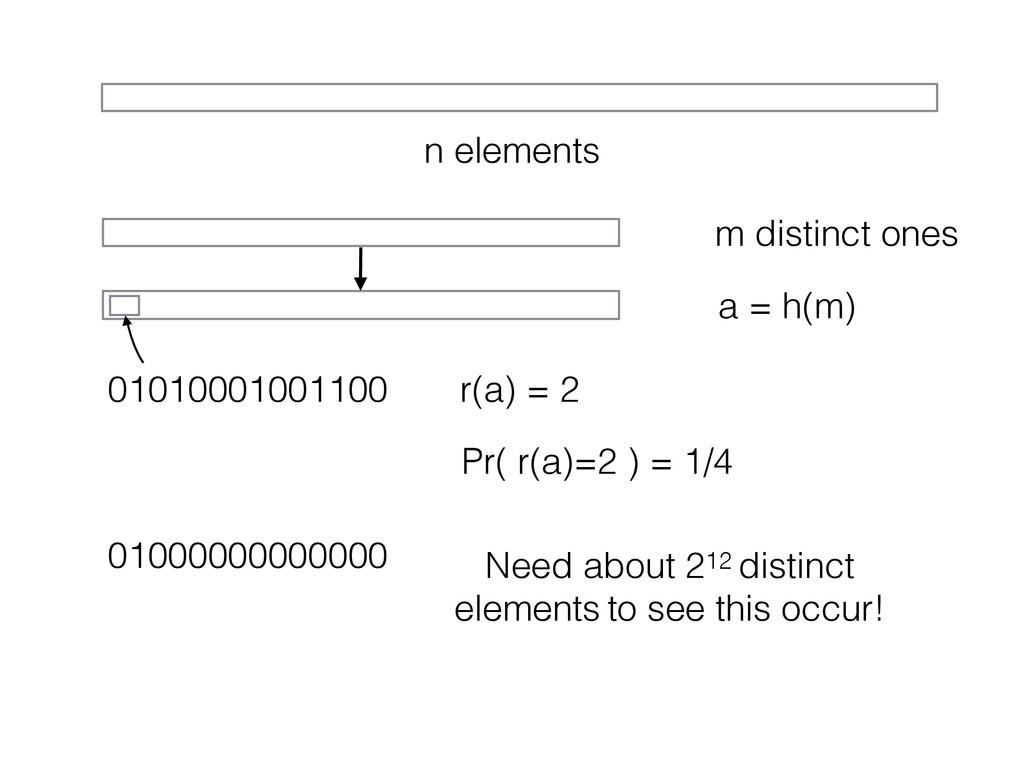
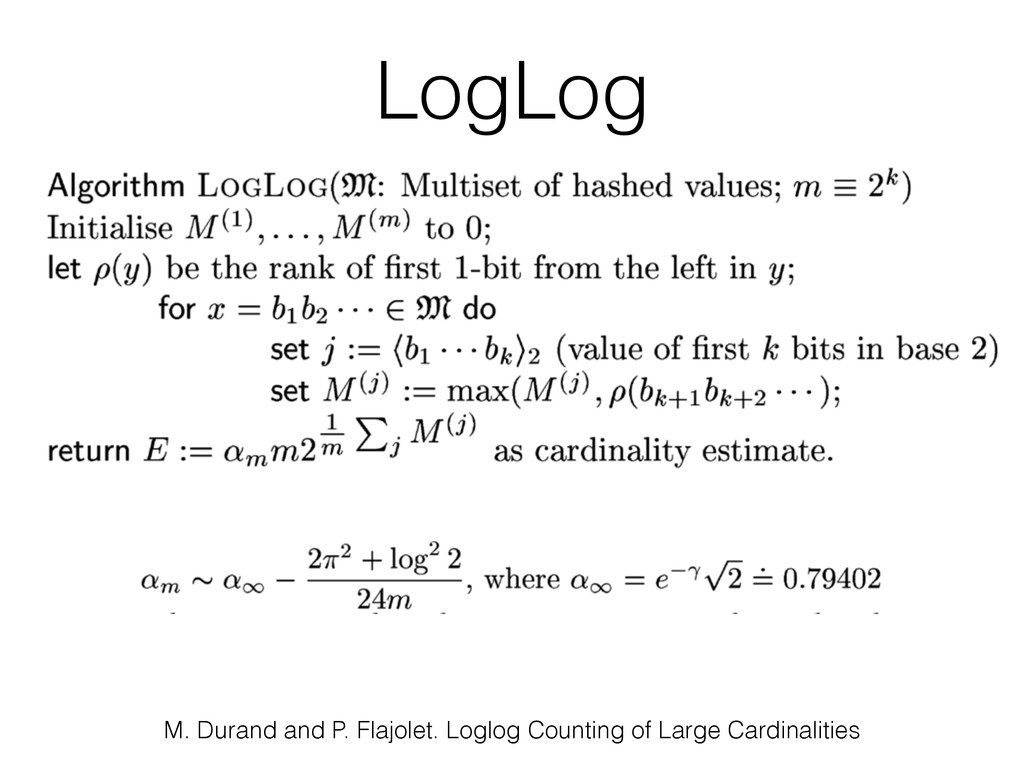
  8. LogLog (basic idea) • Pick a hash function h that

    maps each of the n elements to at least log(n) bits • For each a = h(x), let r(a) be the number of trailing zeros • Record R = maximum r(a) seen • Cardinality estimate = 2R • Data size (R): 4 bytes or 8 byes
  9. n elements m distinct ones a = h(m) 01010001001100 r(a)

    = 2 Pr( r(a)=2 ) = 1/4 01000000000000 Need about 212 distinct elements to see this occur!
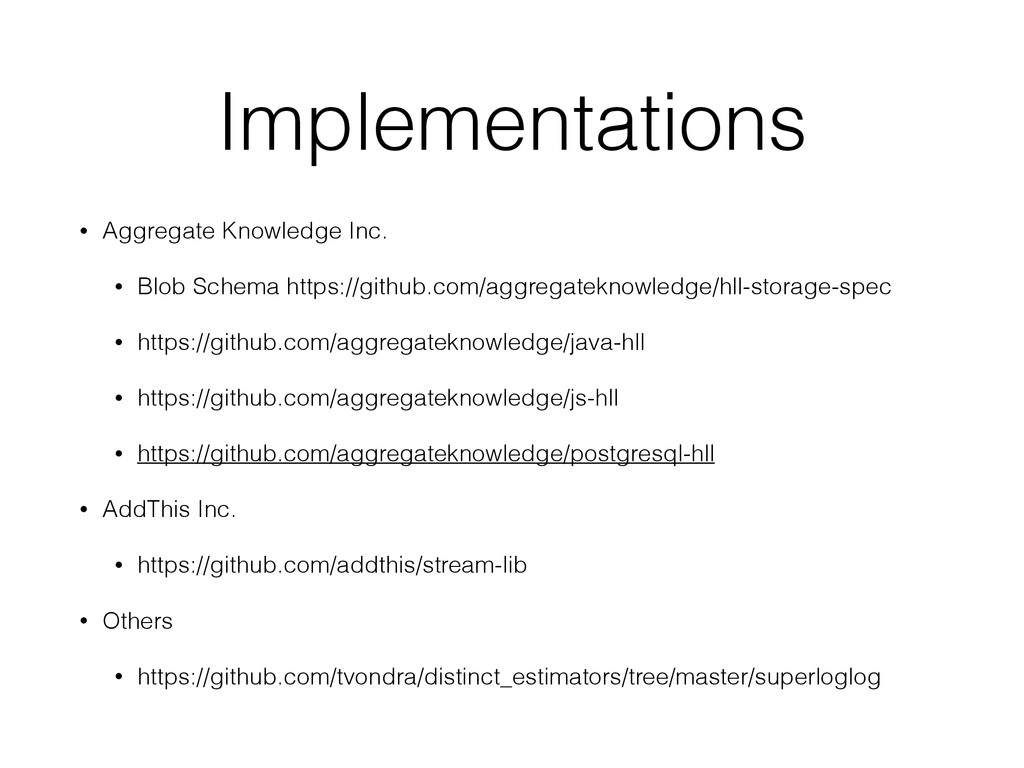
  10. Implementations • Aggregate Knowledge Inc. • Blob Schema https://github.com/aggregateknowledge/hll-storage-spec •

    https://github.com/aggregateknowledge/java-hll • https://github.com/aggregateknowledge/js-hll • https://github.com/aggregateknowledge/postgresql-hll • AddThis Inc. • https://github.com/addthis/stream-lib • Others • https://github.com/tvondra/distinct_estimators/tree/master/superloglog
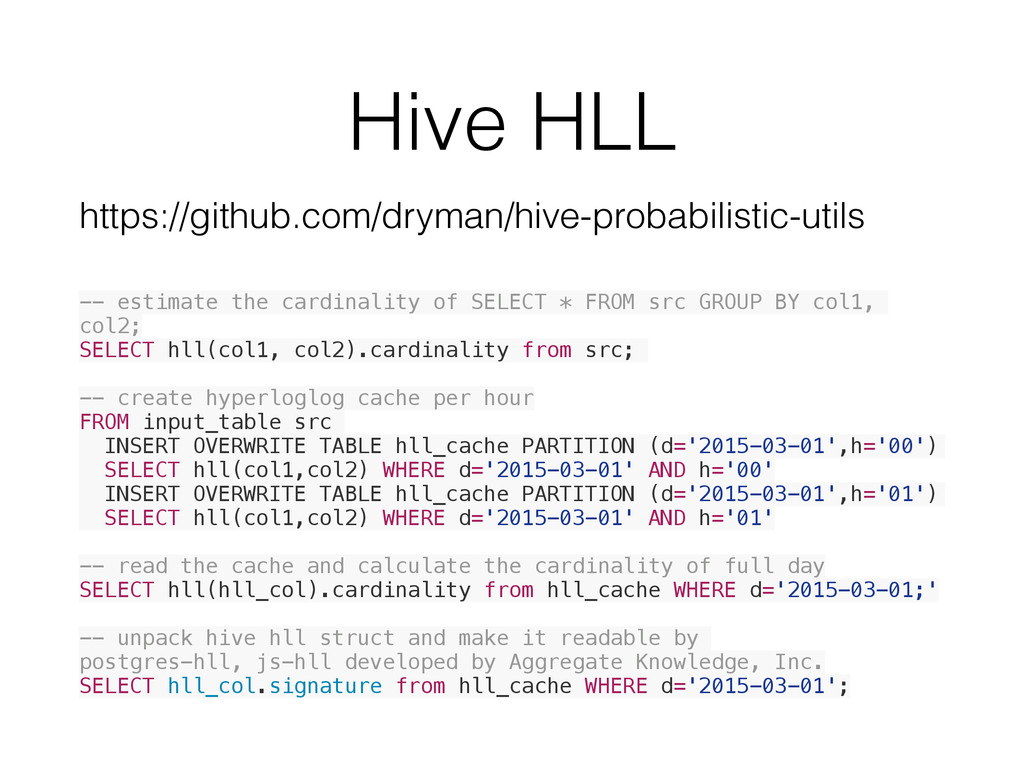
  11. Hive HLL -- estimate the cardinality of SELECT * FROM

    src GROUP BY col1, col2; SELECT hll(col1, col2).cardinality from src; ! -- create hyperloglog cache per hour FROM input_table src INSERT OVERWRITE TABLE hll_cache PARTITION (d='2015-03-01',h='00') SELECT hll(col1,col2) WHERE d='2015-03-01' AND h='00' INSERT OVERWRITE TABLE hll_cache PARTITION (d='2015-03-01',h='01') SELECT hll(col1,col2) WHERE d='2015-03-01' AND h='01' ! -- read the cache and calculate the cardinality of full day SELECT hll(hll_col).cardinality from hll_cache WHERE d='2015-03-01;' ! -- unpack hive hll struct and make it readable by postgres-hll, js-hll developed by Aggregate Knowledge, Inc. SELECT hll_col.signature from hll_cache WHERE d='2015-03-01'; https://github.com/dryman/hive-probabilistic-utils
  12. Business Values <3 • Distinct count on user (cookie, User

    Agent, etc.) every hour/minute. • How many unique users do we have every day/ week/month? • What is the churn rate? • It can even be visualized in browser! (js-hll)
  13. Similar algorithms to HyperLogLog • Count-min-sketch (frequency estimation) • Bloom

    filter (probabilistic set) • Lossy count (top-k elements) • ASM (2nd order moment estimation)
  14. Algorithms that extend our problem sets • Locality Sensitive Hashing

    (finding similar items) • ECLAT (frequent item set) • BigCLAM (graph clustering) • Many more

More Decks by Felix Chern

Other Decks in Technology