Share
Embed
Installing the Flux Capacitor: Search at the Internet Archive
The Internet Archive’s Wayback Machine has collections that range in size from billions of archived web pages, to millions of scanned books, down to 10,000 quite-popular Grateful Dead concert recordings. See how Elasticsearch glues everything together and hear some lessons learned along the way.
Elastic Co
February 18, 2016
Transcript
20 slides
-
1 Greg Lindahl / Aaron Ximm Feb 18, 2016 @glindahl
Search at the Internet Archive -
2 • Non-profit Digital Library & Archive founded in 1996
• Dedicated to free, public, open access to collections -
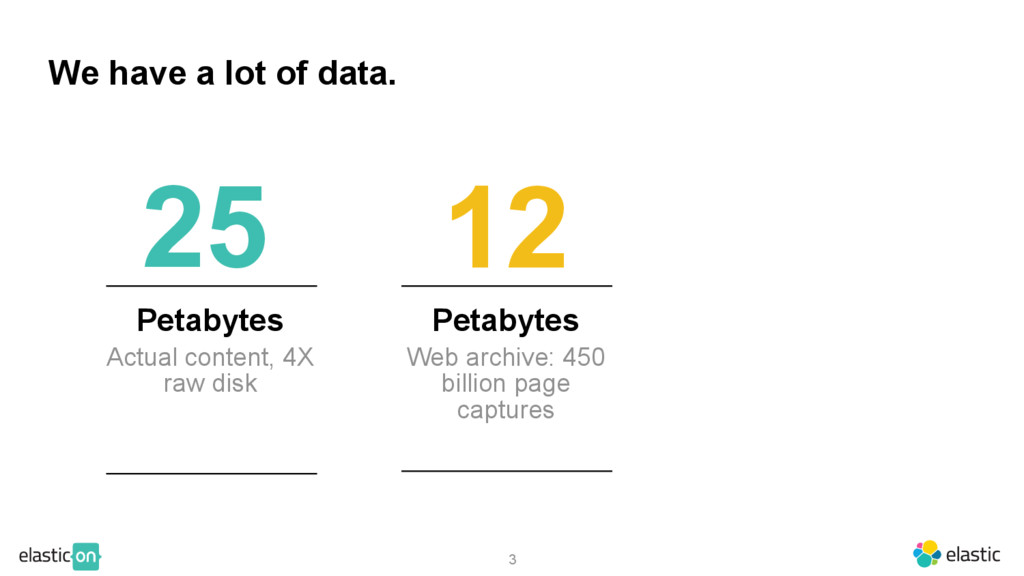
3 Petabytes Actual content, 4X raw disk 25 12 We
have a lot of data. Petabytes Web archive: 450 billion page captures -
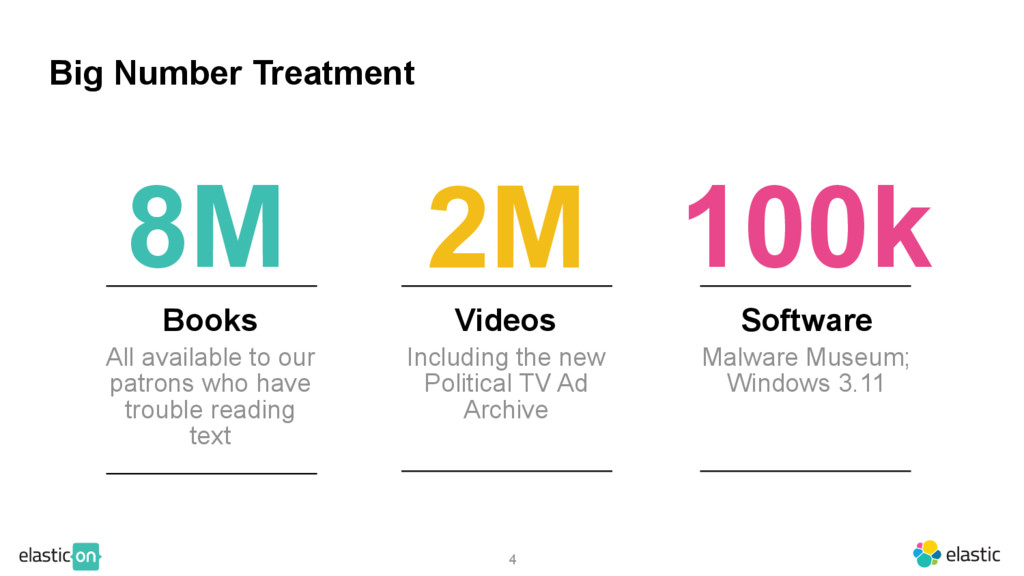
4 Books All available to our patrons who have trouble
reading text 8M 2M 100k Big Number Treatment Videos Including the new Political TV Ad Archive Software Malware Museum; Windows 3.11 -
5 The largest publicly available web archive in existence. Ø
465 Billion URLs (1996-current) Ø 1 billion URLs added per week Ø No search, today -
6 Search makes our world go ‘round • Almost every
webpage on archive.org involves a search • Many of our “collections” are actually search results • We show accurate counts and “downloads” for every item • Frequently we have a flurry of visitors because of a viral tweet or major news story ‒ Malware Museum ‒ Political TV Ad Archive ‒ Windows 3.11 -
7 Challenges • 20 year old organization with very diverse
data • A year ago, we had 5 separate search indices (Lucene etc) • We are under-using search; need to be able to 10x … 100x ... 1,000x our search infrastructure -
8 Search @ IA, today • 18 million documents ‒
1 per book, 1 per video, 1 per music album • Churn: 2-3 million documents per night • Even our front page is driven by ES – usage counts ‒ “We wish” – ES could handle caching without us having to have a Redis instance • 100 gigabyte index (not counting replicas) – Toy-sized -
9 The Near Future • Expand search from items to
files: 5X index • Expand search document size: 5X index ‒ We do TV closed captions already ‒ Books: algorithmic metadata, e.g. list of most important 10,000 things in the book • More items: 5X index ‒ 87 million research papers… • 0.1 terabyte x 125 = large • Harder to scale the engineering/devops effort than it is to buy more hardware! -
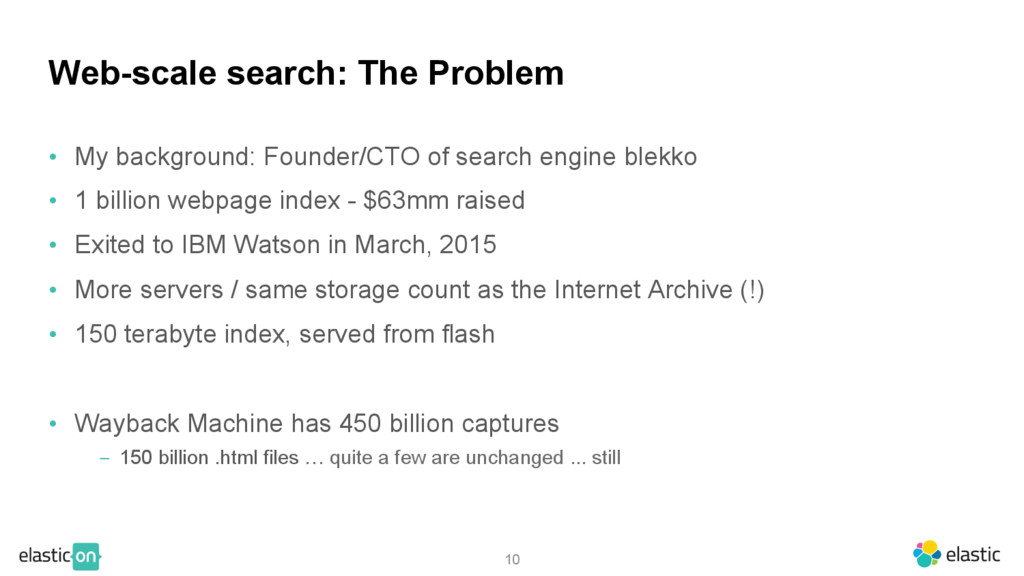
10 Web-scale search: The Problem • My background: Founder/CTO of
search engine blekko • 1 billion webpage index - $63mm raised • Exited to IBM Watson in March, 2015 • More servers / same storage count as the Internet Archive (!) • 150 terabyte index, served from flash • Wayback Machine has 450 billion captures ‒ 150 billion .html files … quite a few are unchanged ... still -
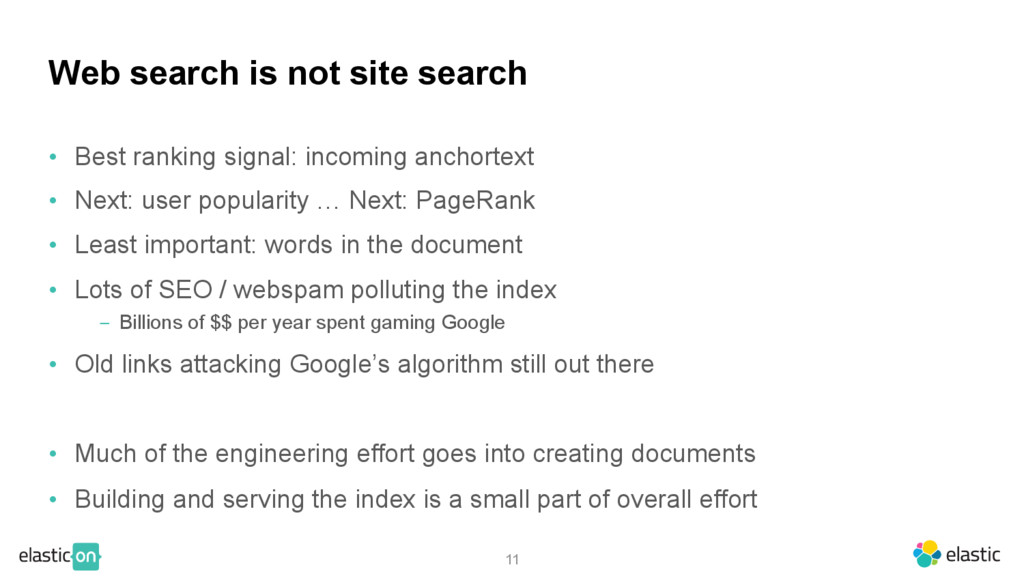
11 Web search is not site search • Best ranking
signal: incoming anchortext • Next: user popularity … Next: PageRank • Least important: words in the document • Lots of SEO / webspam polluting the index ‒ Billions of $$ per year spent gaming Google • Old links attacking Google’s algorithm still out there • Much of the engineering effort goes into creating documents • Building and serving the index is a small part of overall effort -
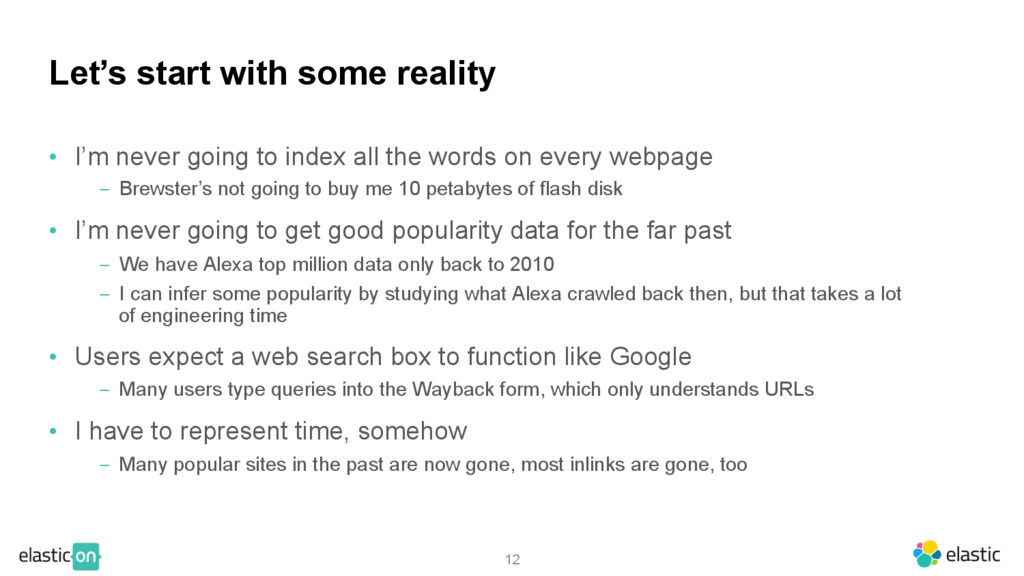
12 Let’s start with some reality • I’m never going
to index all the words on every webpage ‒ Brewster’s not going to buy me 10 petabytes of flash disk • I’m never going to get good popularity data for the far past ‒ We have Alexa top million data only back to 2010 ‒ I can infer some popularity by studying what Alexa crawled back then, but that takes a lot of engineering time • Users expect a web search box to function like Google ‒ Many users type queries into the Wayback form, which only understands URLs • I have to represent time, somehow ‒ Many popular sites in the past are now gone, most inlinks are gone, too -
13 OMG. I am sooo screwed. Greg Lindahl (day 2
of working for the Internet Archive) -
14 Let’s sneak up on the problem • Let’s start
with 3 months of data – 10 billion pages • Let’s index only the ‘/’ page of every website – 300 million of these? • Let’s pick a recent time period ‒ Popularity data from Alexa top million ‒ Search engine ranking from blekko’s 2013 metadata release • Let’s only aggregate the most important incoming links, not all • How big is it? 300mm documents, 10 terms max… 200 gigabytes? -
15 What searches could this answer? • “The Rocky” >>
Rocky Mountain News >> rockymountainnews.com • “Man United” >> manutd.com • White House >> not the porn site • “Candidate Name” >> omg they all have parody & anti-Candidate sites :/ -
16 Federate our way into a time dimension • Let’s
build an index for each year going back to 1996 • Early years are small, later years are 200 gigabytes … 2 TB total, OK • Run 20 queries for each query • ... OMG where’s my UX person? • Traditional “ten blue links” SERP won’t work for this interface • Early website with similar nickname to modern site might be drowned out • If I boost early sites, I’ll boost spam, too. -
17 Searching within a site • I’m not going to
1,000X a 2 TB index • We have easy access to the list of all URLs in a website • SEO-friendly URLs are OK for faking search • No anchortext available, but I do know which pages are “landing pages” ‒ These are pages with incoming links from external sites • Which words in the search box describe the site, vs the page within the site? Oh oh. -
19 • Web-scale anything is hard, this is harder •
Site search is a very different beast from web search • Resource constraints drive this entire project • Keep in touch! @glindahl or wumpus zat archive zot org -
20 Except where otherwise noted, this work is licensed under
http://creativecommons.org/licenses/by-nd/4.0/ Creative Commons and the double C in a circle are registered trademarks of Creative Commons in the United States and other countries. Third party marks and brands are the property of their respective holders.