Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Postgresql

Eloy Coto
January 25, 2017

 Postgresql

Eloy Coto

January 25, 2017

Transcript

53 slides
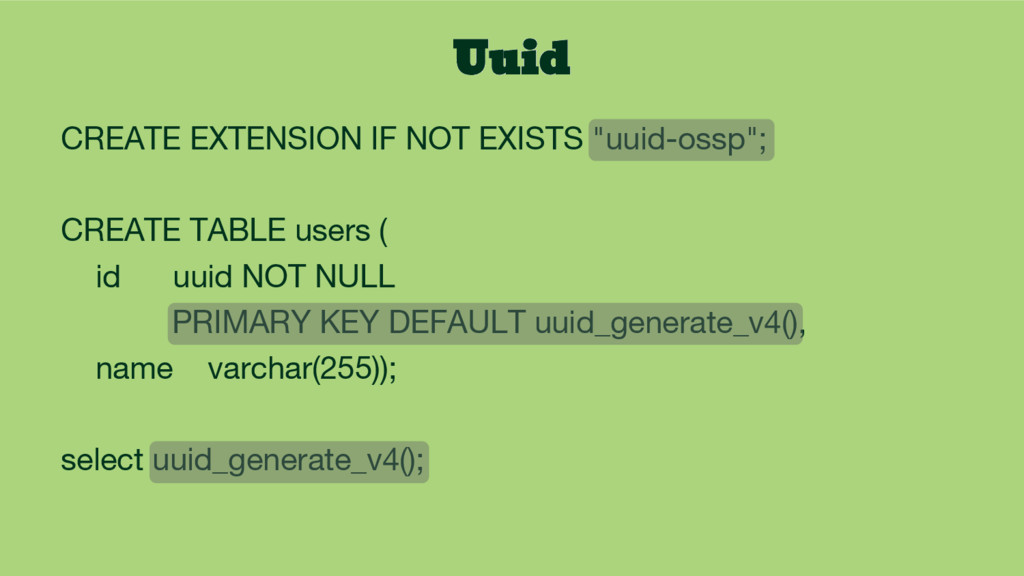
  1. Uuid CREATE EXTENSION IF NOT EXISTS "uuid-ossp"; CREATE TABLE users

    ( id uuid NOT NULL PRIMARY KEY DEFAULT uuid_generate_v4(), name varchar(255)); select uuid_generate_v4();
  2. Arrays CREATE TABLE restaurants ( name text, typical_dishes varchar(255)[] );

    insert into restaurants values ('Alice', '{lobsters, barnacles}'), ('Bob', '{scallop, spider crab}'), ('Daniel', '{lobsters, prawn}');
  3. Filter options select * from restaurants where .. typical_dishes[1] ==

    '{barnacles}' typical_dishes @> '{lobsters}' typical_dishes && '{lobsters}' 'lobsters' = ANY(typical_dishes); 'lobsters' = ALL(typical_dishes); 'lobsters' = SOME(typical_dishes);
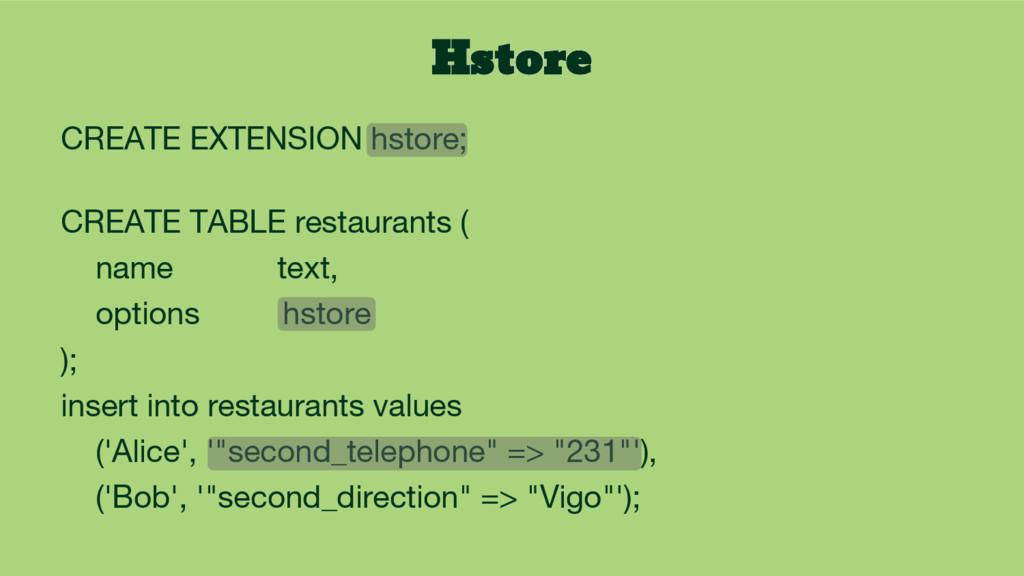
  4. Hstore CREATE EXTENSION hstore; CREATE TABLE restaurants ( name text,

    options hstore ); insert into restaurants values ('Alice', '"second_telephone" => "231"'), ('Bob', '"second_direction" => "Vigo"');
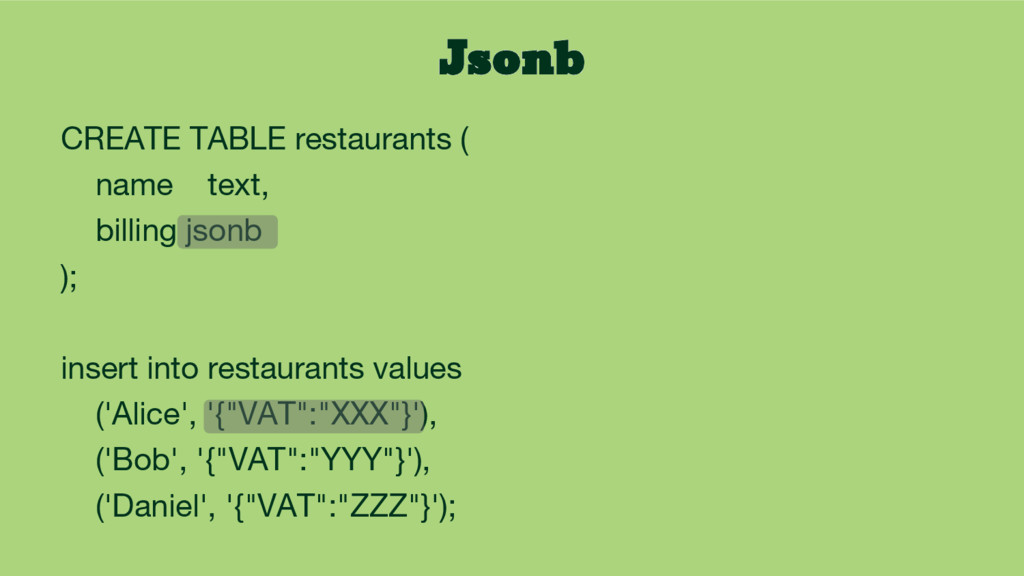
  5. Jsonb CREATE TABLE restaurants ( name text, billing jsonb );

    insert into restaurants values ('Alice', '{"VAT":"XXX"}'), ('Bob', '{"VAT":"YYY"}'), ('Daniel', '{"VAT":"ZZZ"}');
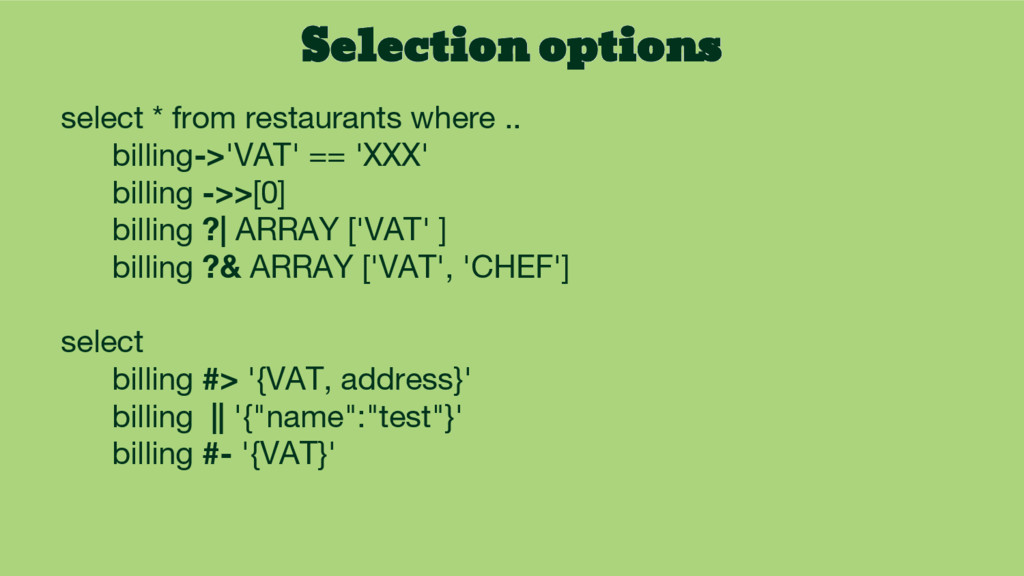
  6. Selection options select * from restaurants where .. billing->'VAT' ==

    'XXX' billing ->>[0] billing ?| ARRAY ['VAT' ] billing ?& ARRAY ['VAT', 'CHEF'] select billing #> '{VAT, address}' billing || '{"name":"test"}' billing #- '{VAT}'
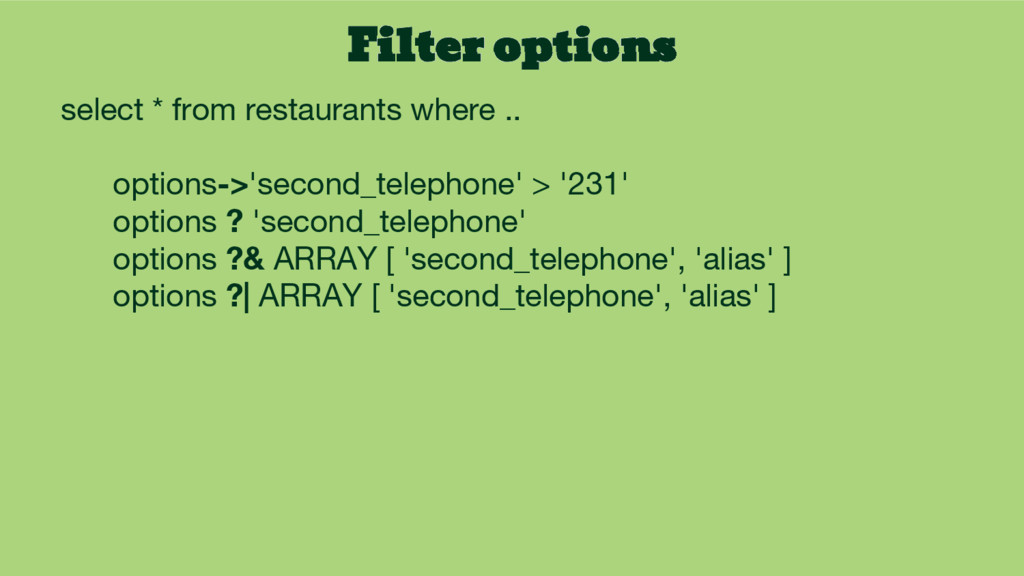
  7. Filter options select * from restaurants where .. options->'second_telephone' >

    '231' options ? 'second_telephone' options ?& ARRAY [ 'second_telephone', 'alias' ] options ?| ARRAY [ 'second_telephone', 'alias' ]
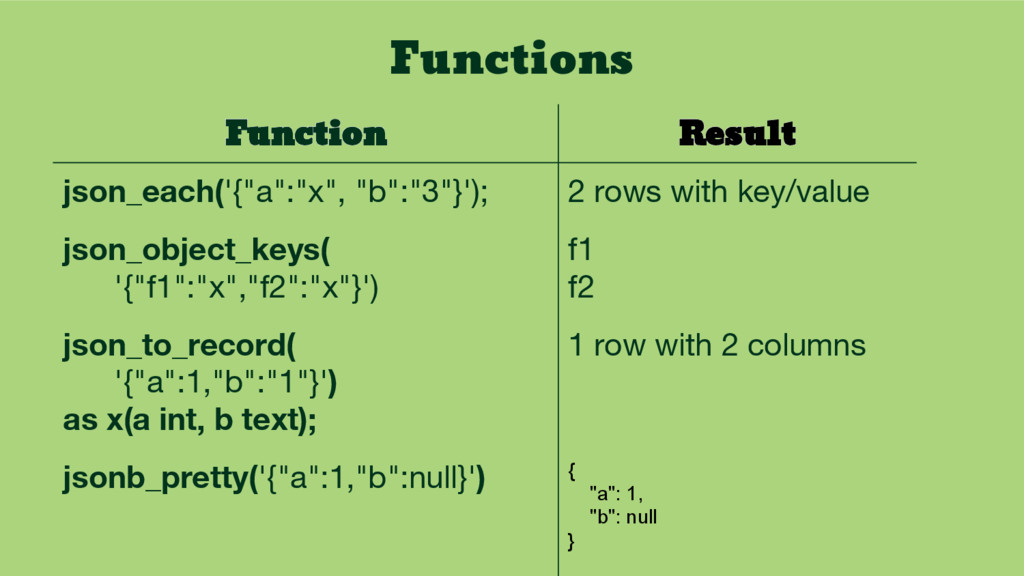
  8. Functions Function Result json_each('{"a":"x", "b":"3"}'); 2 rows with key/value json_object_keys(

    '{"f1":"x","f2":"x"}') f1 f2 json_to_record( '{"a":1,"b":"1"}') as x(a int, b text); 1 row with 2 columns jsonb_pretty('{"a":1,"b":null}') { "a": 1, "b": null }
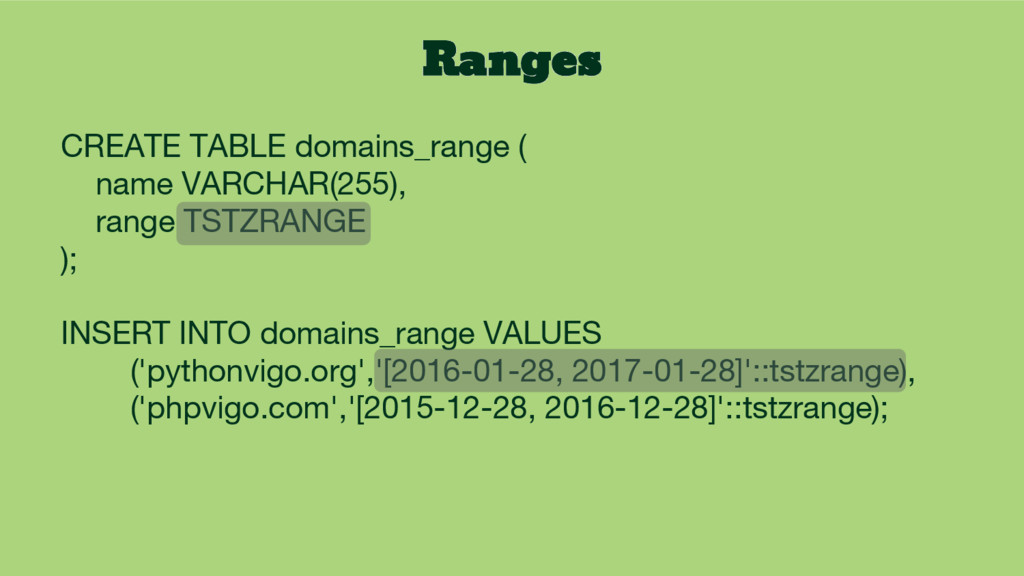
  9. Ranges CREATE TABLE domains_range ( name VARCHAR(255), range TSTZRANGE );

    INSERT INTO domains_range VALUES ('pythonvigo.org','[2016-01-28, 2017-01-28]'::tstzrange), ('phpvigo.com','[2015-12-28, 2016-12-28]'::tstzrange);
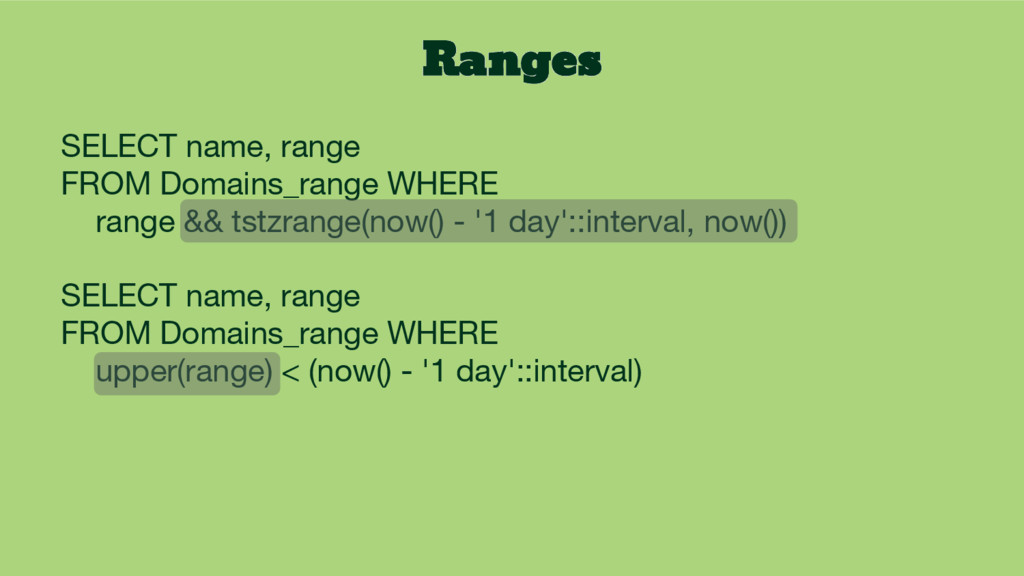
  10. Ranges SELECT name, range FROM Domains_range WHERE range && tstzrange(now()

    - '1 day'::interval, now()) SELECT name, range FROM Domains_range WHERE upper(range) < (now() - '1 day'::interval)
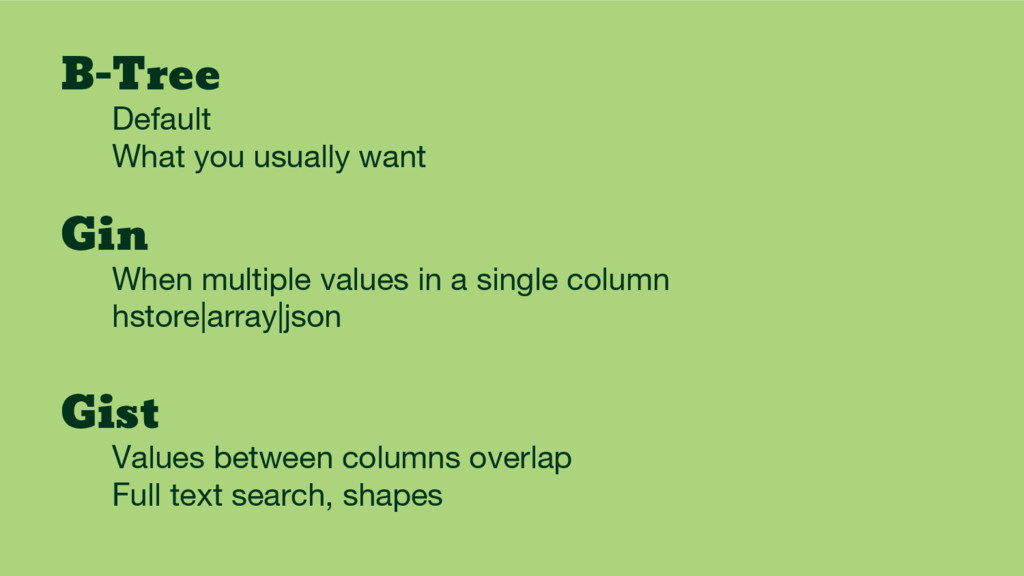
  11. B-Tree Default What you usually want Gin When multiple values

    in a single column hstore|array|json Gist Values between columns overlap Full text search, shapes
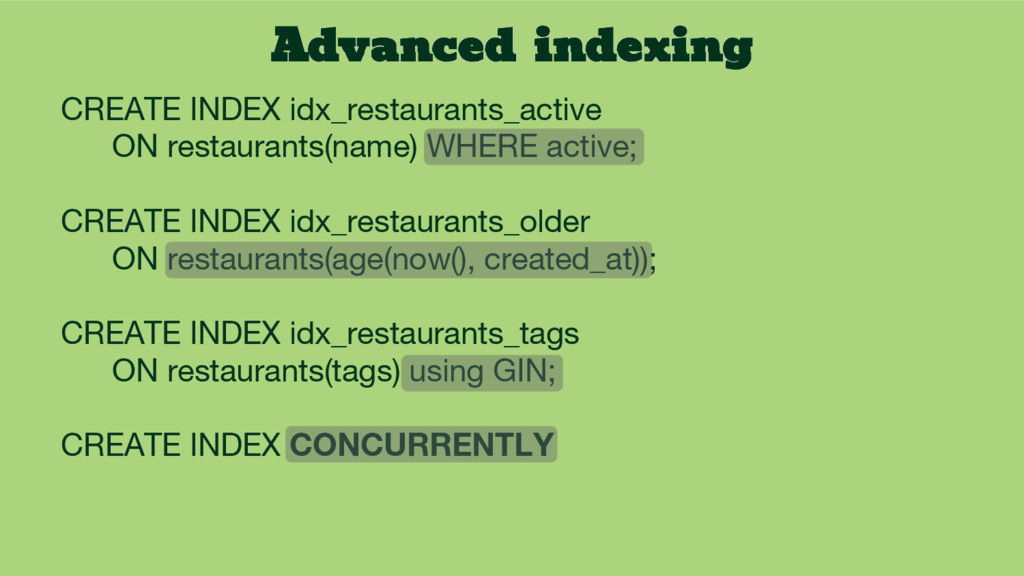
  12. Advanced indexing CREATE INDEX idx_restaurants_active ON restaurants(name) WHERE active; CREATE

    INDEX idx_restaurants_older ON restaurants(age(now(), created_at)); CREATE INDEX idx_restaurants_tags ON restaurants(tags) using GIN; CREATE INDEX CONCURRENTLY
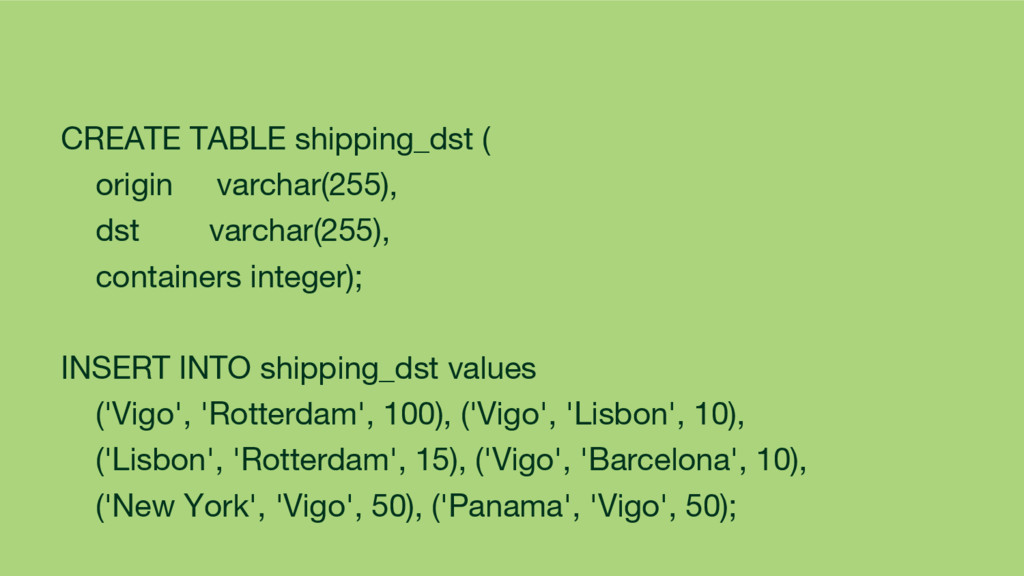
  13. CREATE TABLE shipping_dst ( origin varchar(255), dst varchar(255), containers integer);

    INSERT INTO shipping_dst values ('Vigo', 'Rotterdam', 100), ('Vigo', 'Lisbon', 10), ('Lisbon', 'Rotterdam', 15), ('Vigo', 'Barcelona', 10), ('New York', 'Vigo', 50), ('Panama', 'Vigo', 50);
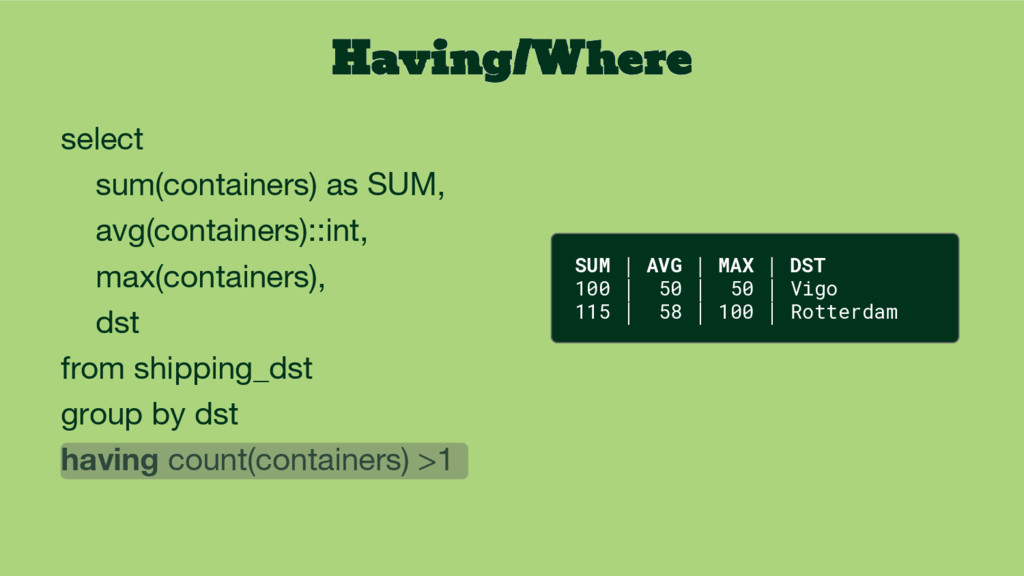
  14. Having/Where select sum(containers) as SUM, avg(containers)::int, max(containers), dst from shipping_dst

    group by dst having count(containers) >1 SUM │ AVG │ MAX │ DST 100 │ 50 │ 50 │ Vigo 115 │ 58 │ 100 │ Rotterdam
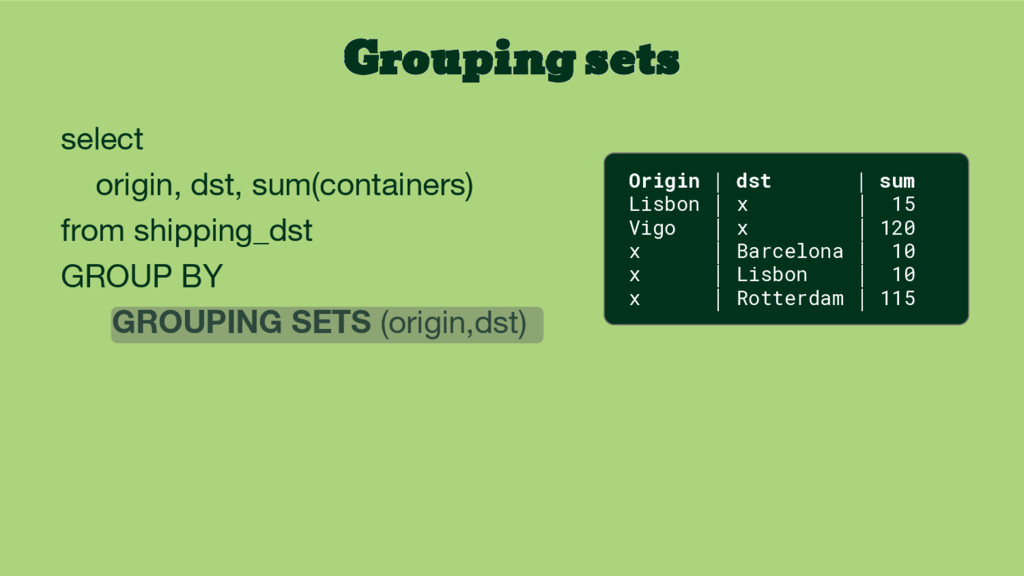
  15. Grouping sets select origin, dst, sum(containers) from shipping_dst GROUP BY

    GROUPING SETS (origin,dst) Origin │ dst │ sum Lisbon │ x │ 15 Vigo │ x │ 120 x │ Barcelona │ 10 x │ Lisbon │ 10 x │ Rotterdam │ 115
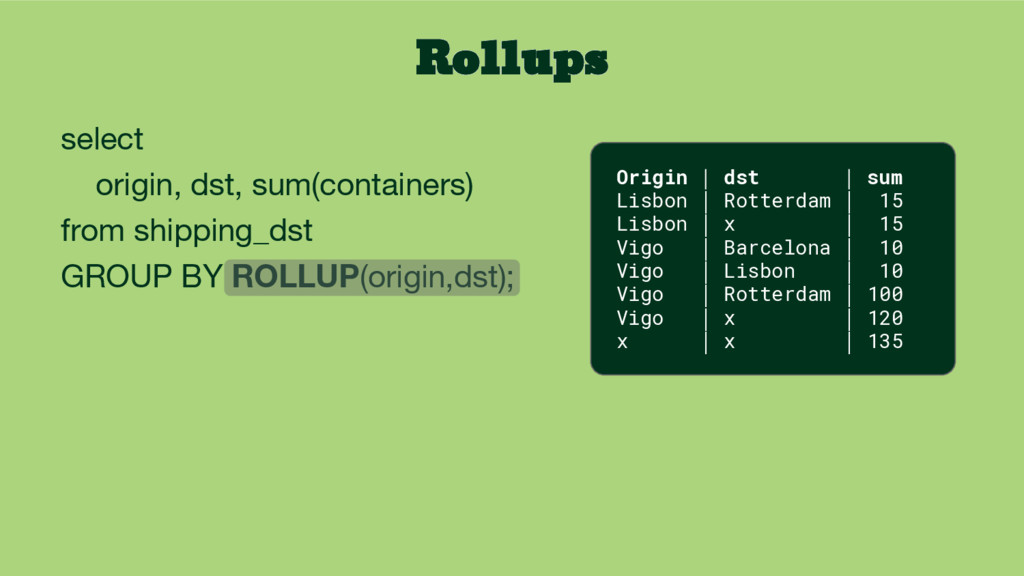
  16. Rollups select origin, dst, sum(containers) from shipping_dst GROUP BY ROLLUP(origin,dst);

    Origin │ dst │ sum Lisbon │ Rotterdam │ 15 Lisbon │ x │ 15 Vigo │ Barcelona │ 10 Vigo │ Lisbon │ 10 Vigo │ Rotterdam │ 100 Vigo │ x │ 120 x │ x │ 135
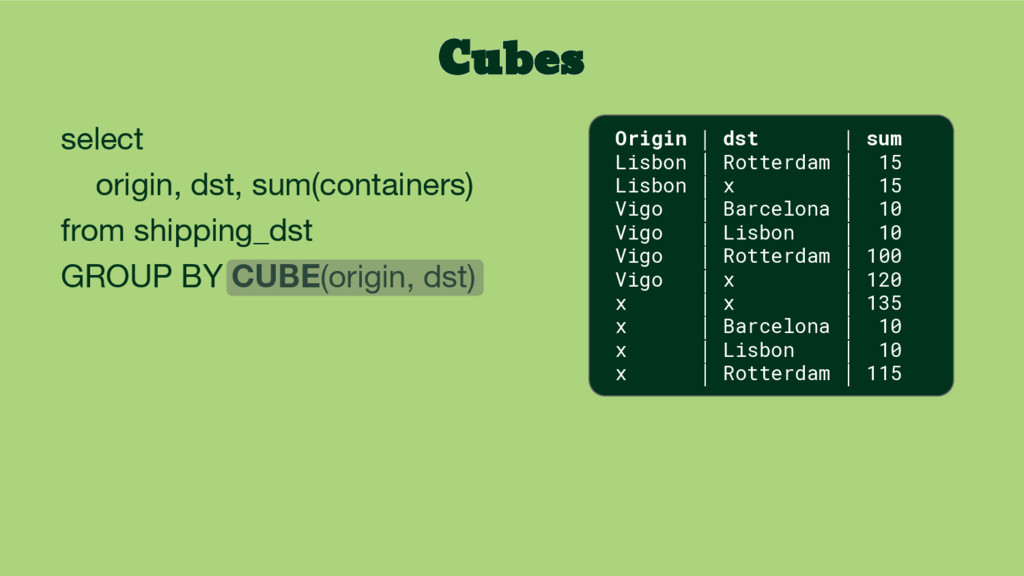
  17. Cubes select origin, dst, sum(containers) from shipping_dst GROUP BY CUBE(origin,

    dst) Origin │ dst │ sum Lisbon │ Rotterdam │ 15 Lisbon │ x │ 15 Vigo │ Barcelona │ 10 Vigo │ Lisbon │ 10 Vigo │ Rotterdam │ 100 Vigo │ x │ 120 x │ x │ 135 x │ Barcelona │ 10 x │ Lisbon │ 10 x │ Rotterdam │ 115
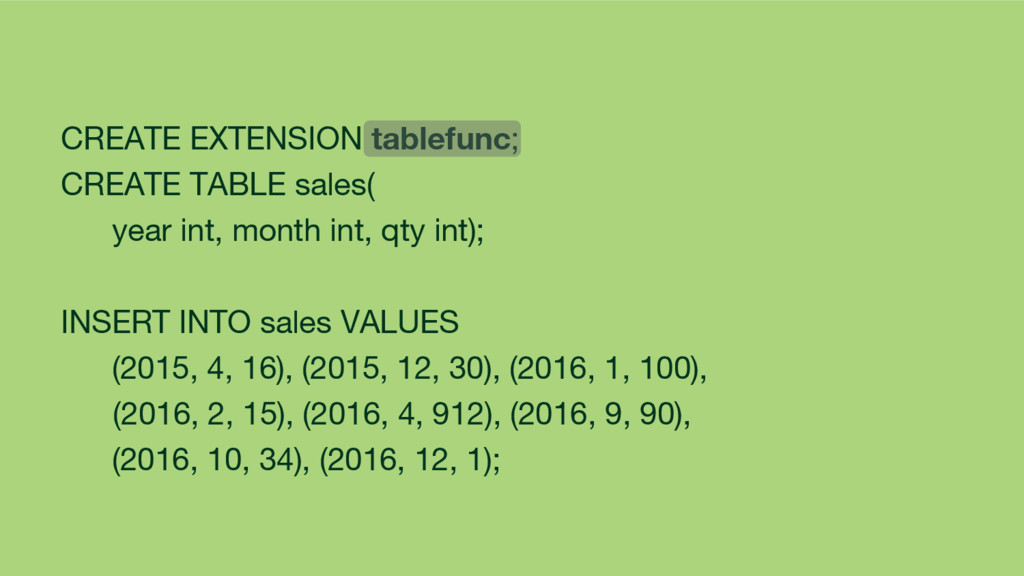
  18. CREATE EXTENSION tablefunc; CREATE TABLE sales( year int, month int,

    qty int); INSERT INTO sales VALUES (2015, 4, 16), (2015, 12, 30), (2016, 1, 100), (2016, 2, 15), (2016, 4, 912), (2016, 9, 90), (2016, 10, 34), (2016, 12, 1);
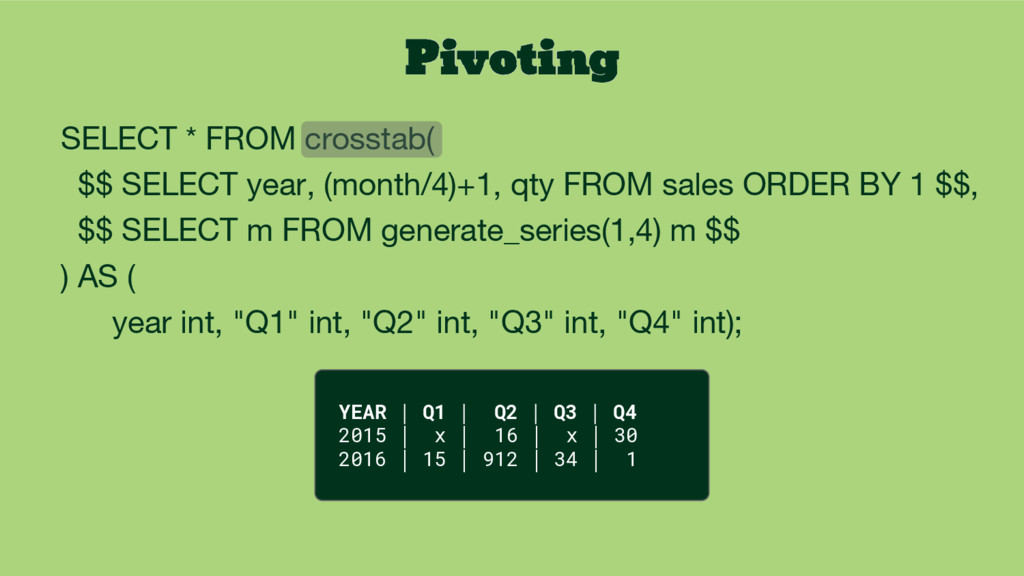
  19. Pivoting SELECT * FROM crosstab( $$ SELECT year, (month/4)+1, qty

    FROM sales ORDER BY 1 $$, $$ SELECT m FROM generate_series(1,4) m $$ ) AS ( year int, "Q1" int, "Q2" int, "Q3" int, "Q4" int); YEAR │ Q1 │ Q2 │ Q3 │ Q4 2015 │ x │ 16 │ x │ 30 2016 │ 15 │ 912 │ 34 │ 1
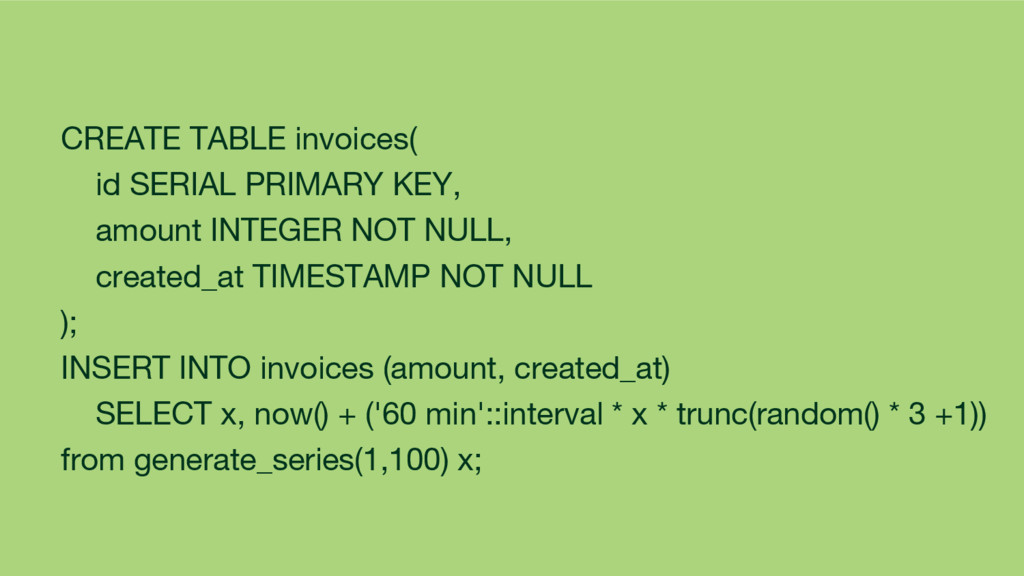
  20. CREATE TABLE invoices( id SERIAL PRIMARY KEY, amount INTEGER NOT

    NULL, created_at TIMESTAMP NOT NULL ); INSERT INTO invoices (amount, created_at) SELECT x, now() + ('60 min'::interval * x * trunc(random() * 3 +1)) from generate_series(1,100) x;
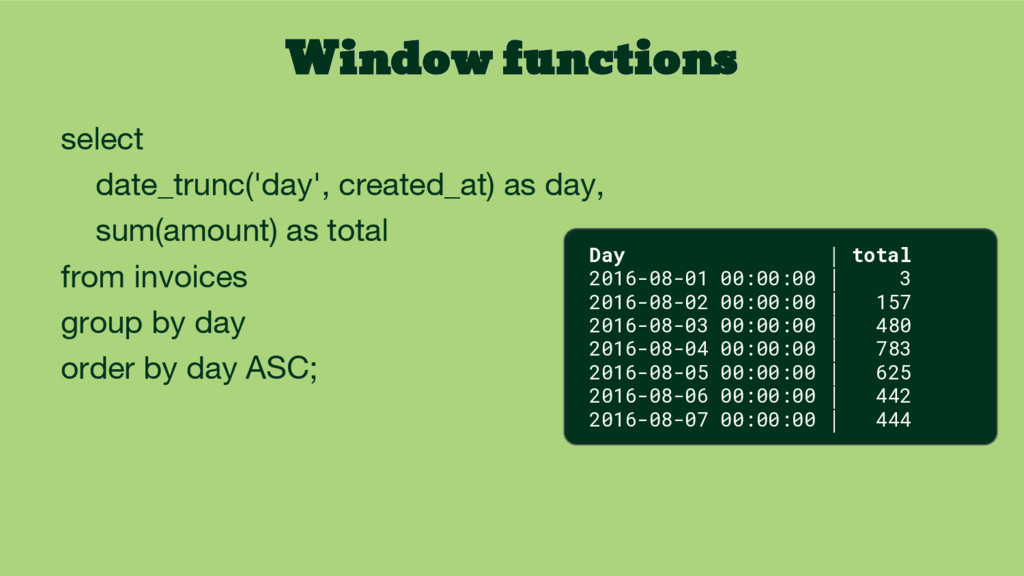
  21. Window functions select date_trunc('day', created_at) as day, sum(amount) as total

    from invoices group by day order by day ASC; Day │ total 2016-08-01 00:00:00 │ 3 2016-08-02 00:00:00 │ 157 2016-08-03 00:00:00 │ 480 2016-08-04 00:00:00 │ 783 2016-08-05 00:00:00 │ 625 2016-08-06 00:00:00 │ 442 2016-08-07 00:00:00 │ 444
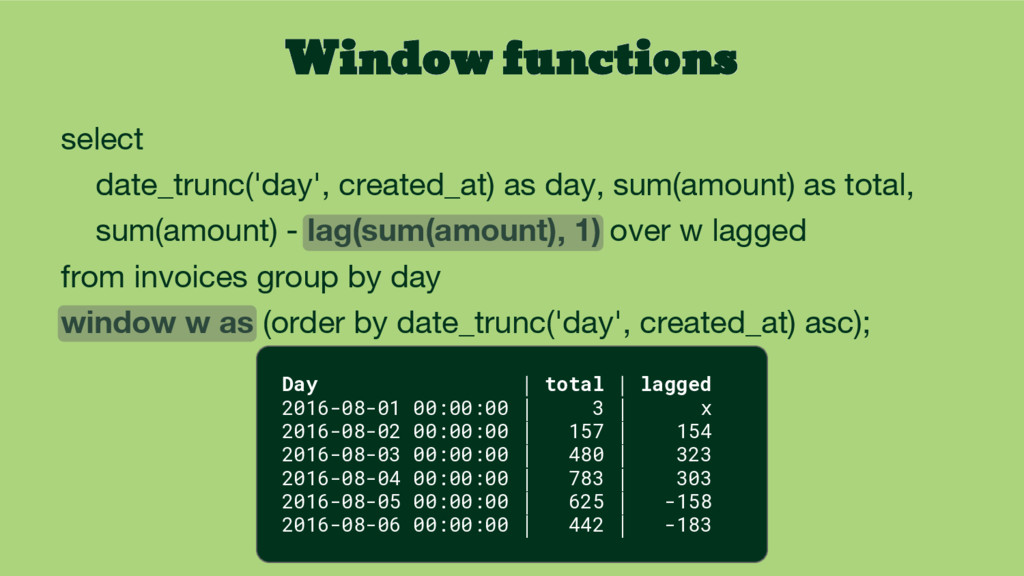
  22. Window functions select date_trunc('day', created_at) as day, sum(amount) as total,

    sum(amount) - lag(sum(amount), 1) over w lagged from invoices group by day window w as (order by date_trunc('day', created_at) asc); Day │ total │ lagged 2016-08-01 00:00:00 │ 3 │ x 2016-08-02 00:00:00 │ 157 │ 154 2016-08-03 00:00:00 │ 480 │ 323 2016-08-04 00:00:00 │ 783 │ 303 2016-08-05 00:00:00 │ 625 │ -158 2016-08-06 00:00:00 │ 442 │ -183
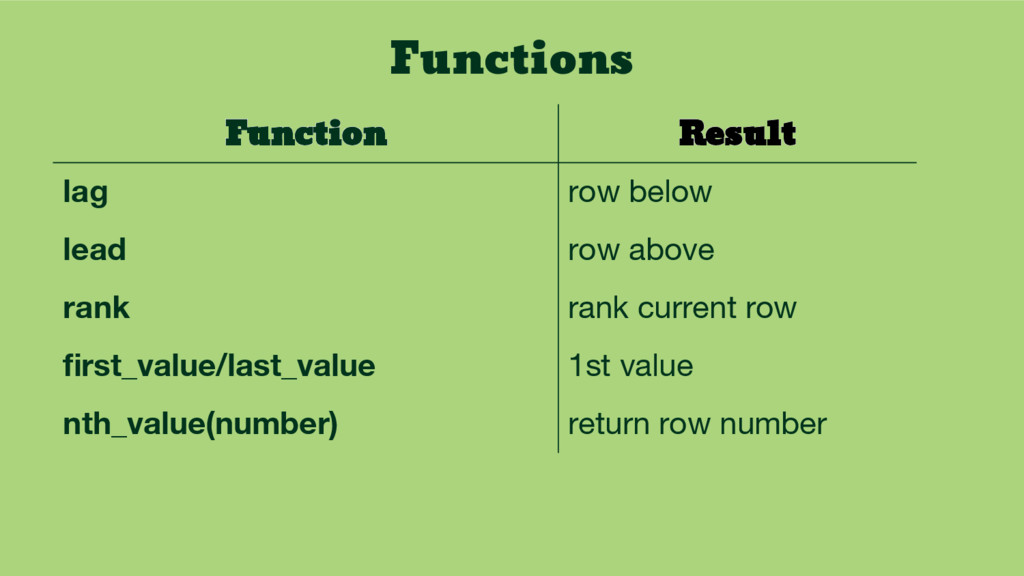
  23. Functions Function Result lag row below lead row above rank

    rank current row first_value/last_value 1st value nth_value(number) return row number
  24. Materialized views create materialized view active_posts AS select id, to_tsvector(title)

    as title, to_tsvector(body) as body, created_at from post where active=True; create index on active_posts using gist(title, body); refresh materialized view active_posts;
  25. Full text search SELECT to_tsvector('Try not to become a man

    of success, but rather try to become a man of value'); select to_tsvector('It''s kind of fun to do the impossible') @@ to_tsquery('impossible'); More info on rachbelaid.com blog 'becom':4,13 'man':6,15 'rather':10 'success':8 'tri':1,11 'valu':17
  26. create table tasks ( name varchar(100), username varchar(100), project varchar(100));

    insert into tasks values ('a', 'Alice', 'XX'), ('b', 'Alice', 'XX'), ('c', 'Bob', 'XX'), ('d', 'Paul', 'XX'), ('e', 'Paul', 'YY'), ('f', 'Paul', 'ZZ');
  27. CTE WITH users_tasks AS ( SELECT username, project, count(*) as

    tasks, array_agg(name) as task_list FROM tasks GROUP BY username,project), top_projects_tasks AS ( SELECT project, count(*) as tasks FROM tasks GROUP BY project ORDER by tasks DESC)
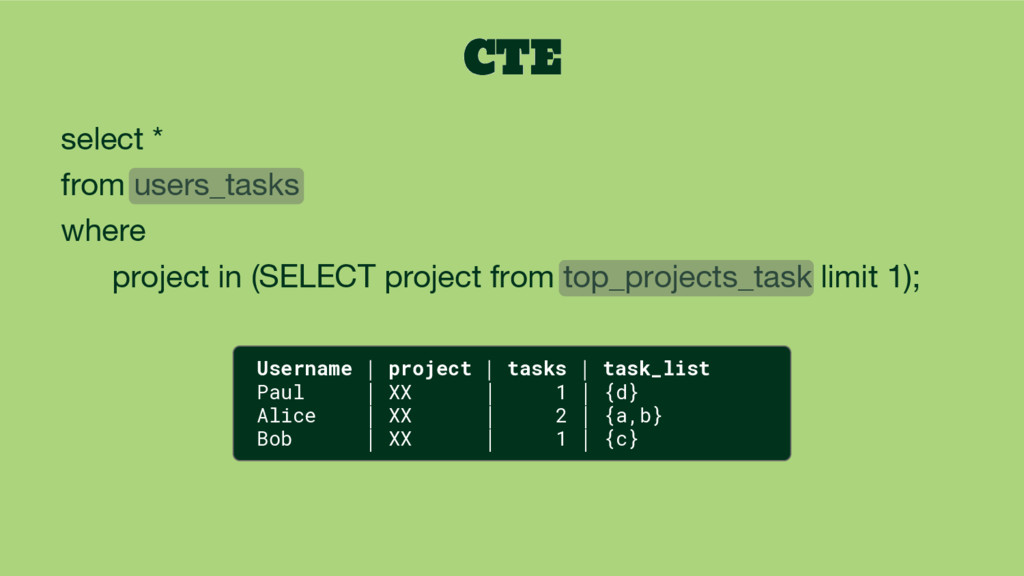
  28. CTE select * from users_tasks where project in (SELECT project

    from top_projects_task limit 1); Username │ project │ tasks │ task_list Paul │ XX │ 1 │ {d} Alice │ XX │ 2 │ {a,b} Bob │ XX │ 1 │ {c}
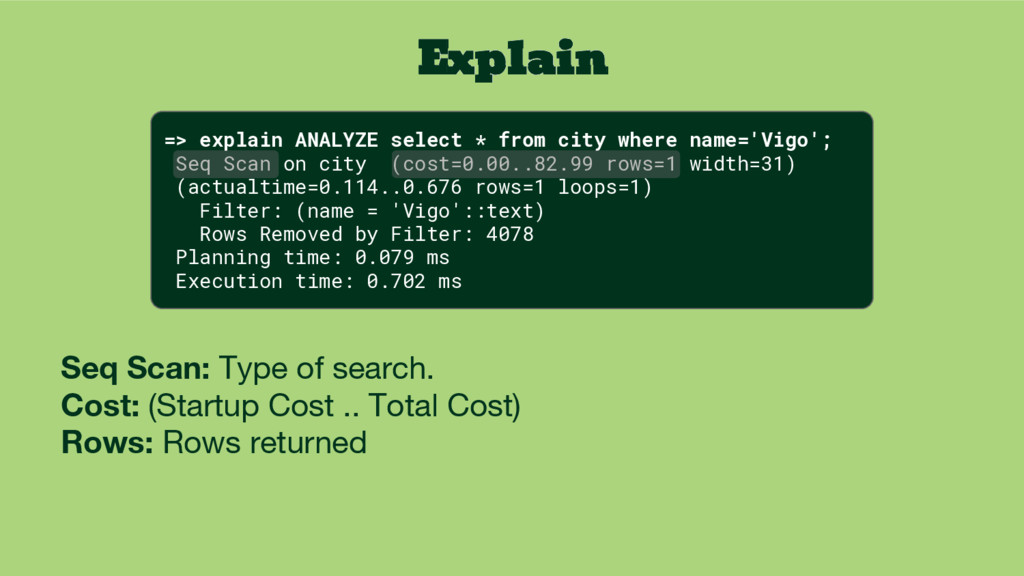
  29. Explain Seq Scan: Type of search. Cost: (Startup Cost ..

    Total Cost) Rows: Rows returned => explain ANALYZE select * from city where name='Vigo'; Seq Scan on city (cost=0.00..82.99 rows=1 width=31) (actualtime=0.114..0.676 rows=1 loops=1) Filter: (name = 'Vigo'::text) Rows Removed by Filter: 4078 Planning time: 0.079 ms Execution time: 0.702 ms
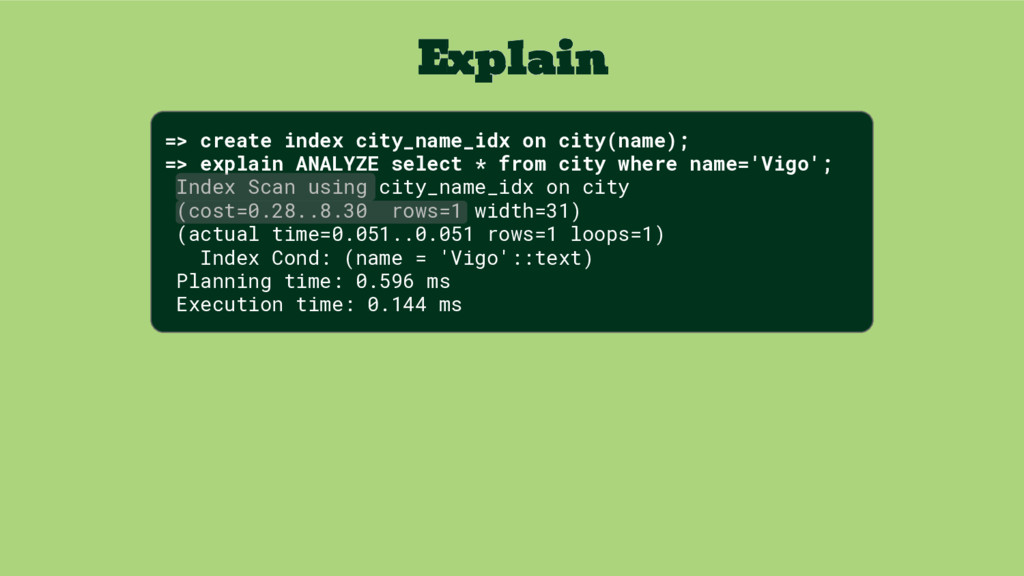
  30. Explain => create index city_name_idx on city(name); => explain ANALYZE

    select * from city where name='Vigo'; Index Scan using city_name_idx on city (cost=0.28..8.30 rows=1 width=31) (actual time=0.051..0.051 rows=1 loops=1) Index Cond: (name = 'Vigo'::text) Planning time: 0.596 ms Execution time: 0.144 ms
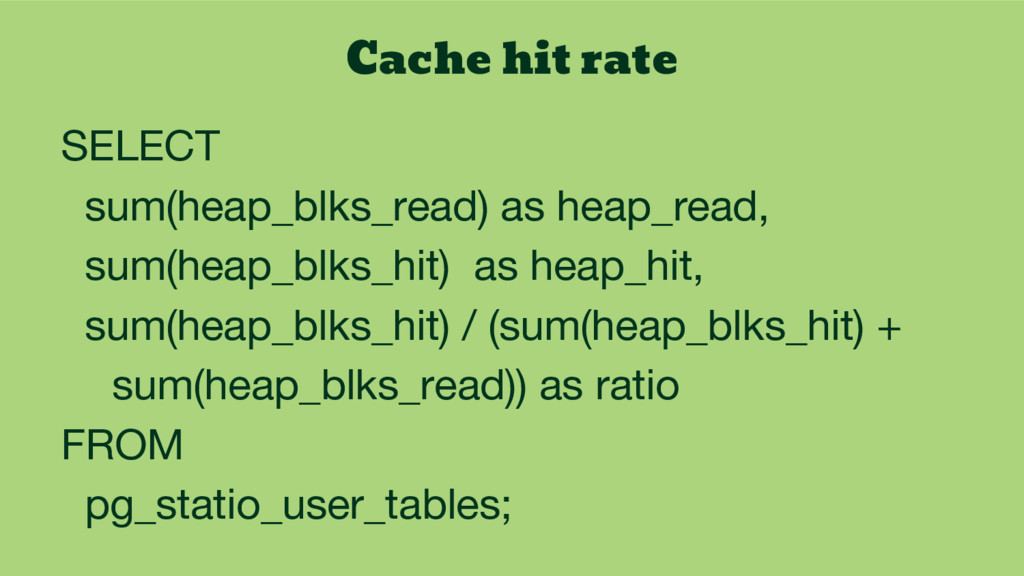
  31. Cache hit rate SELECT sum(heap_blks_read) as heap_read, sum(heap_blks_hit) as heap_hit,

    sum(heap_blks_hit) / (sum(heap_blks_hit) + sum(heap_blks_read)) as ratio FROM pg_statio_user_tables;
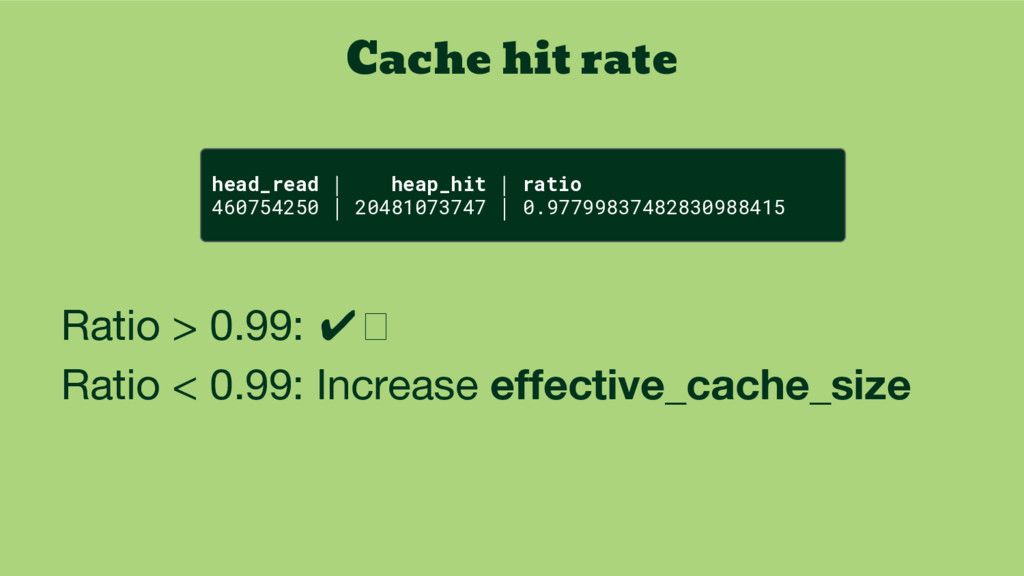
  32. Cache hit rate Ratio > 0.99: ✔ Ratio < 0.99:

    Increase effective_cache_size head_read │ heap_hit │ ratio 460754250 │ 20481073747 │ 0.97799837482830988415
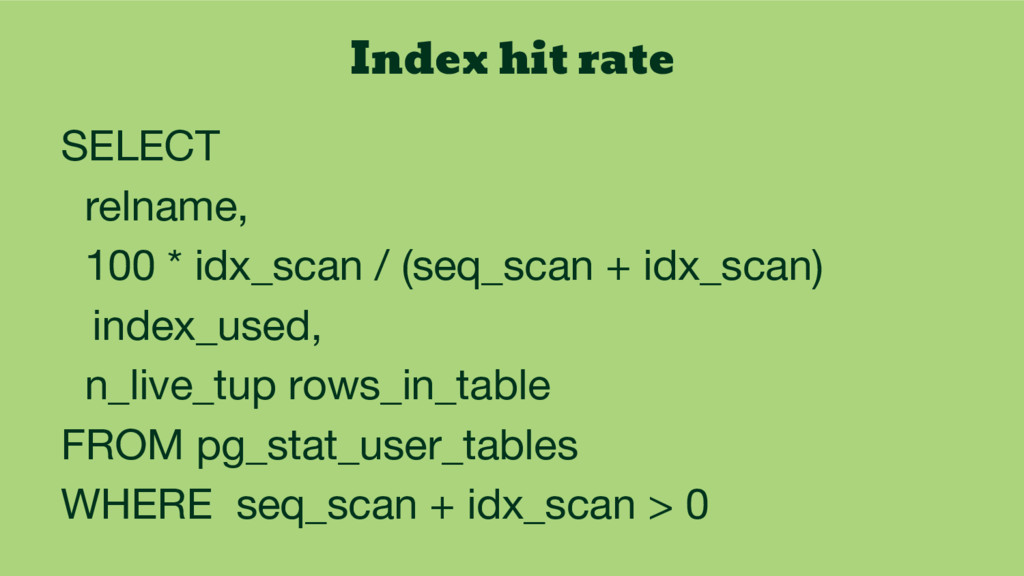
  33. Index hit rate SELECT relname, 100 * idx_scan / (seq_scan

    + idx_scan) index_used, n_live_tup rows_in_table FROM pg_stat_user_tables WHERE seq_scan + idx_scan > 0
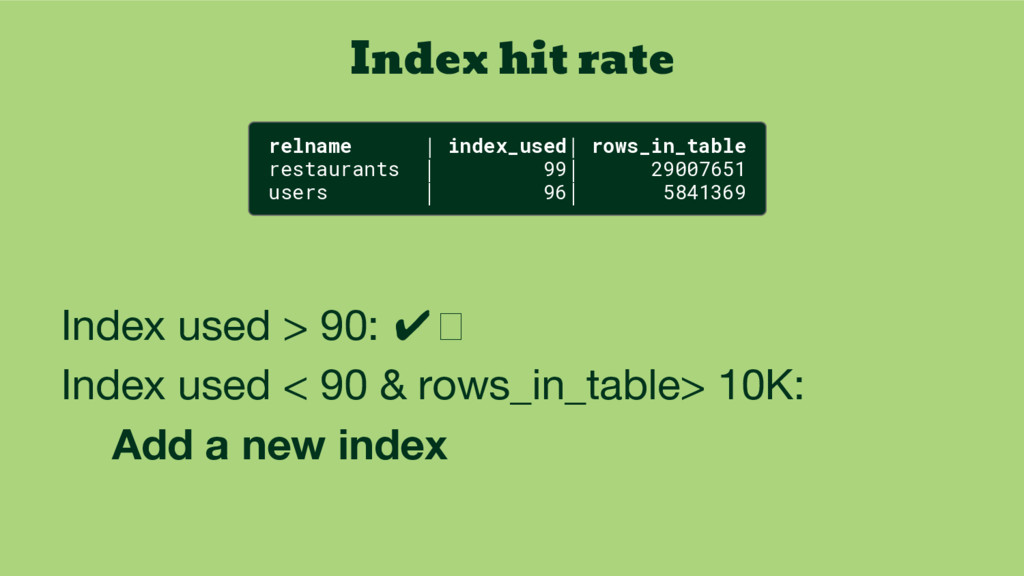
  34. Index hit rate Index used > 90: ✔ Index used

    < 90 & rows_in_table> 10K: Add a new index relname │ index_used│ rows_in_table restaurants │ 99│ 29007651 users │ 96│ 5841369
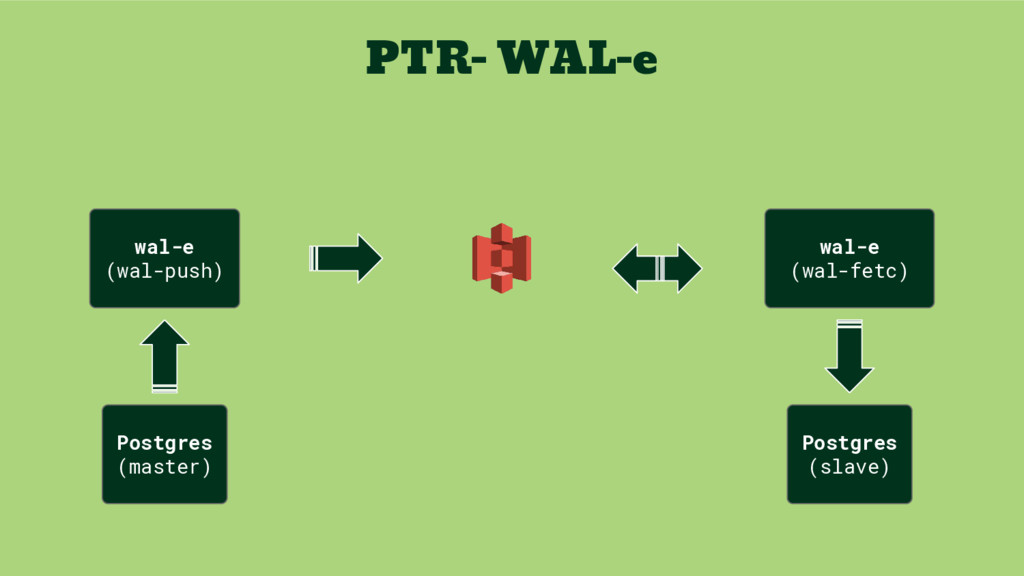
  35. PTR- WAL-e Use WAL(Write-Ahead Log) files Continuous archive to external

    storage Four simple commands: - wal-push - wal-fetch - backup-push - backup-fetch
  36. PTR- WAL-e Use WAL(Write-Ahead Log) files Continuous archive to external

    storage Four simple commands: - wal-push - wal-fetch - backup-push - backup-fetch
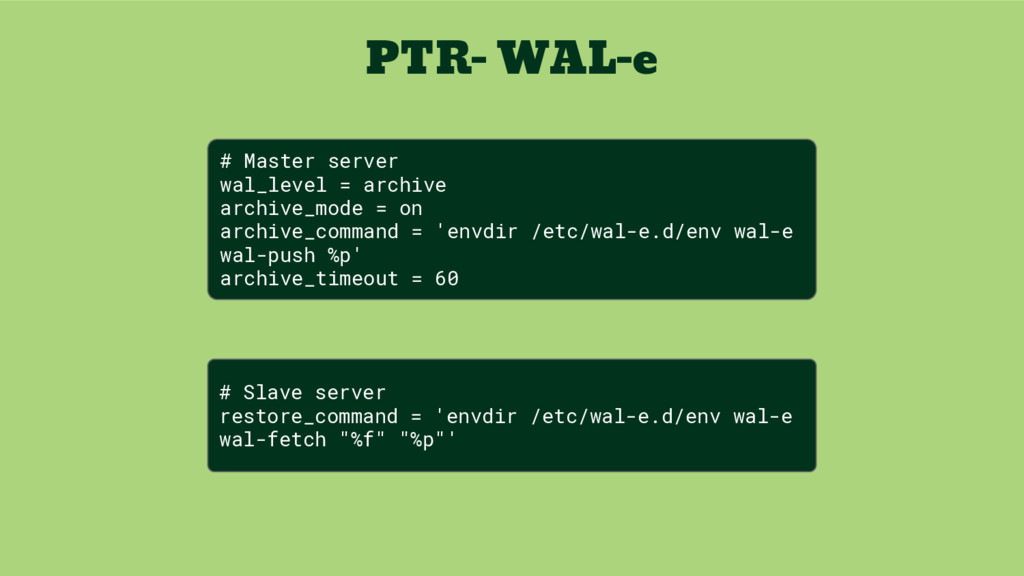
  37. PTR- WAL-e # Slave server restore_command = 'envdir /etc/wal-e.d/env wal-e

    wal-fetch "%f" "%p"' # Master server wal_level = archive archive_mode = on archive_command = 'envdir /etc/wal-e.d/env wal-e wal-push %p' archive_timeout = 60
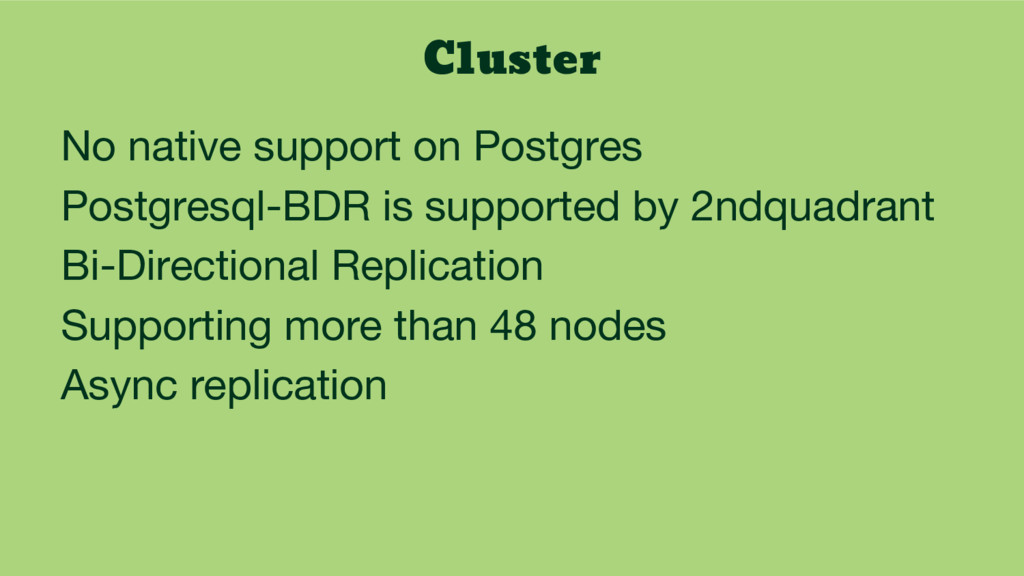
  38. Cluster No native support on Postgres Postgresql-BDR is supported by

    2ndquadrant Bi-Directional Replication Supporting more than 48 nodes Async replication

More Decks by Eloy Coto

Other Decks in Programming