Share
Embed

Transcript
102 slides
-
KDD 2020 Tutorial: Advances in Recommender Systems Part A: Recommendations
in a Marketplace [Multi-objective Methods] Rishabh Mehrotra Ben Carterette Senior Research Scientist, Senior Research Manager, Spotify, London Spotify, New York [email protected] [email protected] 23rd August 2020 @erishabh @BenCarterette https://sites.google.com/view/kdd20-marketplace-autorecsys/ -
KDD 2020 Tutorial: Advances in Recommender Systems Part A: Recommendations
in a Marketplace Rishabh Mehrotra Ben Carterette Senior Research Scientist, Senior Research Manager, Spotify, London Spotify, New York [email protected] [email protected] 23rd August 2020 @erishabh @BenCarterette https://sites.google.com/view/kdd20-marketplace-autorecsys/ Break: back at 10:10 AM PST -
Summary: Part I Introduction to Marketplaces - Traditional RecSys ML
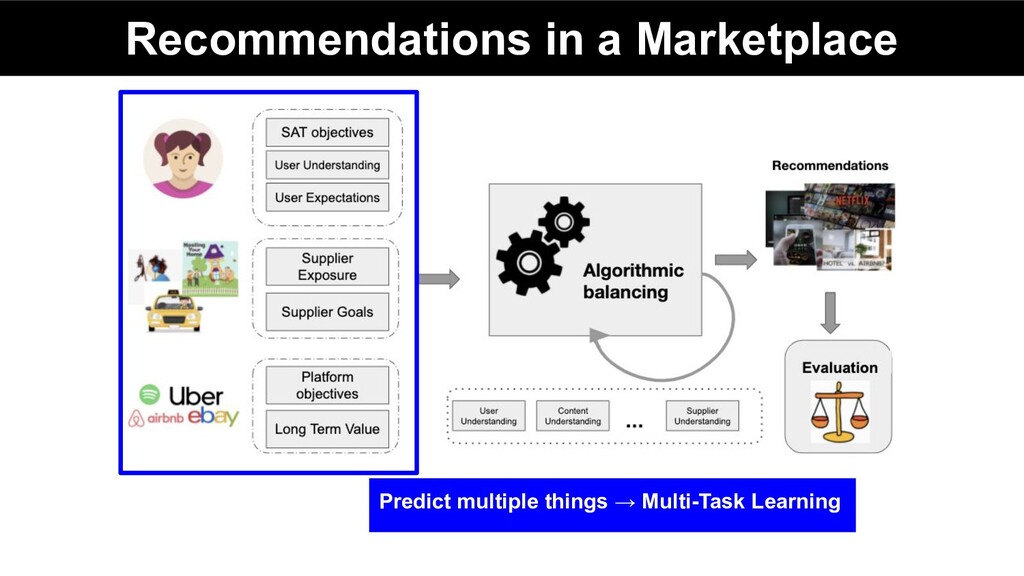
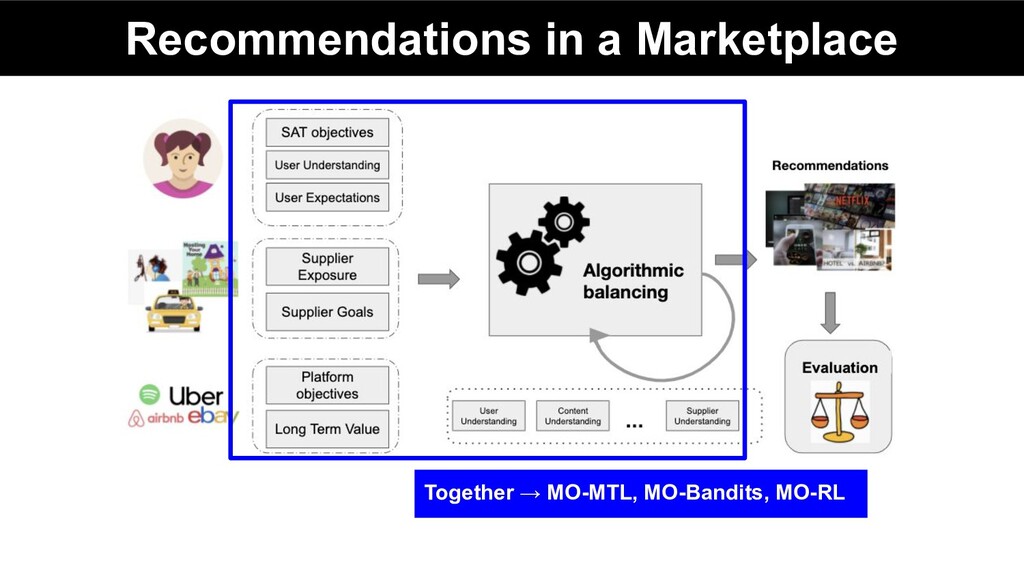
catered towards user-centric modeling - Multiple stakeholders in online marketplaces - Need to consider multiple objectives + ML models to optimize those objectives -
Summary: Part II Stakeholders & Objectives - Multiple stakeholders in
online marketplaces - different industrial case-studies - UberEats, Postmates, Etsy, AirBnb, Music, P2P lending, Crowdfunding - Multiple, often conflicting objectives - +vely correlated, neutral, -vely correlated - ML methods needed to model the interplay between objectives - Important to carefully decide what a system optimizes for -
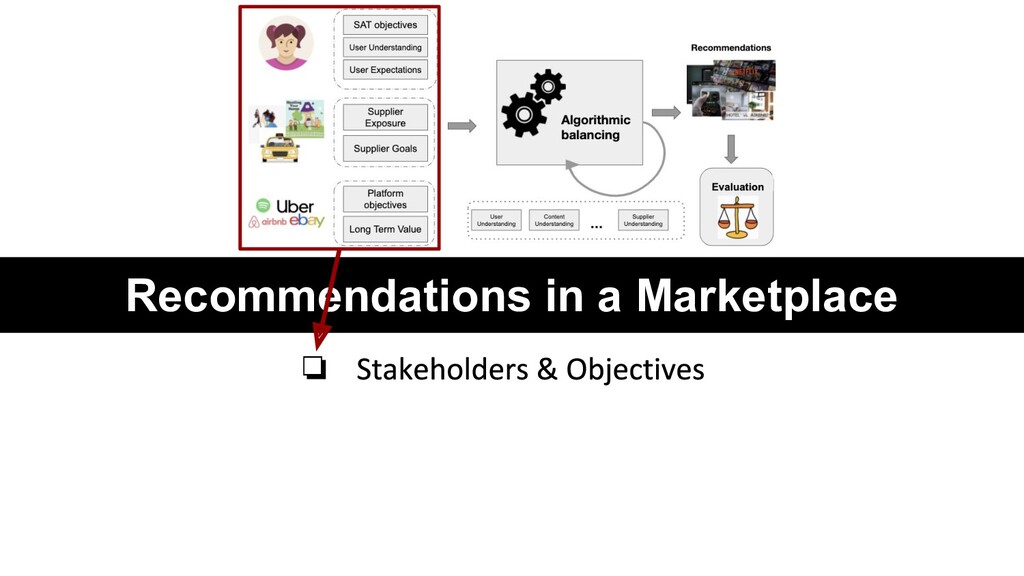
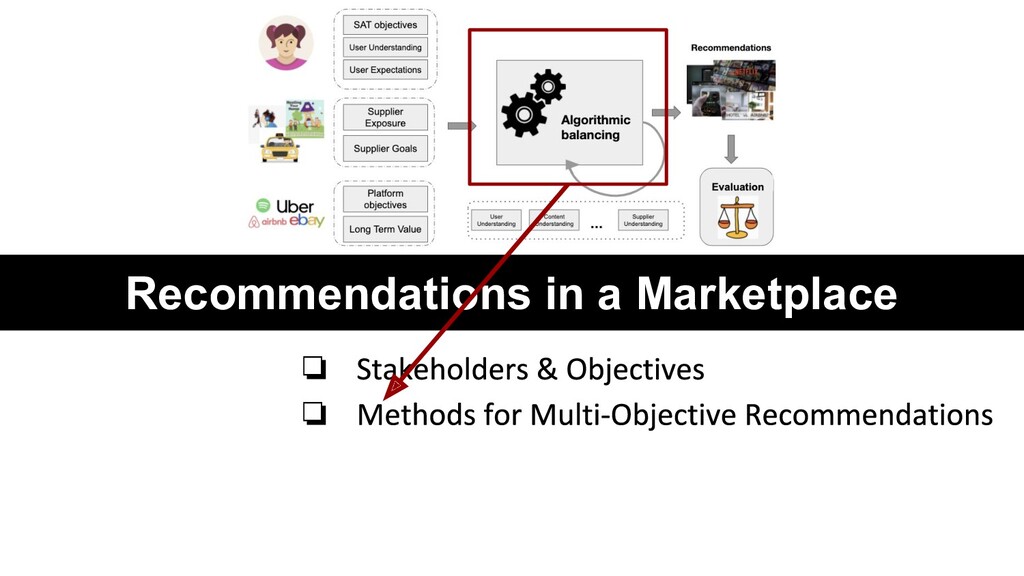
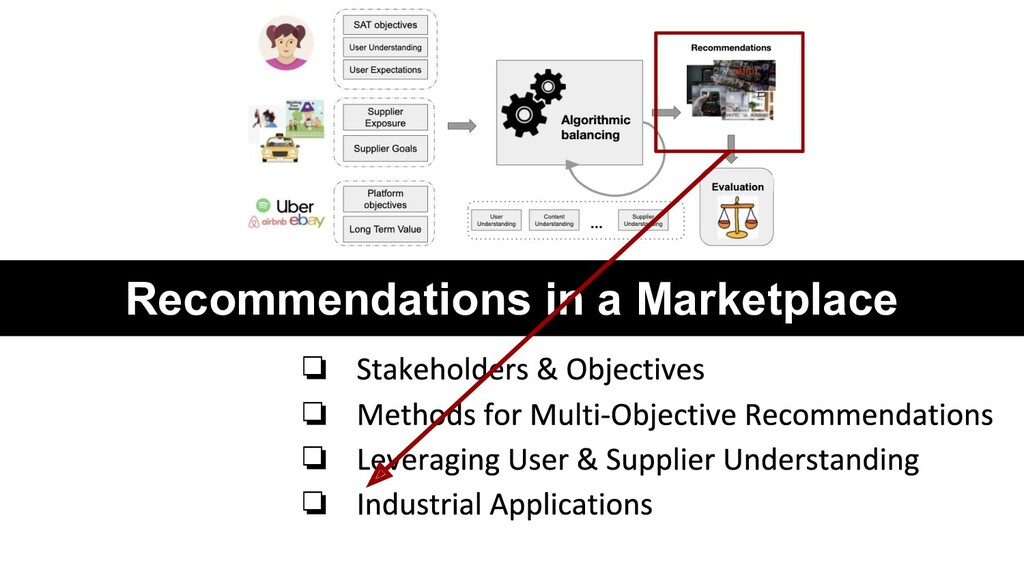
Outline 1. Introduction to Marketplaces 2. Optimization Objectives in a
Marketplace 3. Methods for Multi-Objective Ranking & Recommendations a. Pareto optimality b. Multi-objective models i. Multi-task Learning ii. Scalarization iii. Multi-objective bandits iv. Multi-objective RL 4. Leveraging Consumer, Supplier & Content Understanding 5. Industrial Applications -
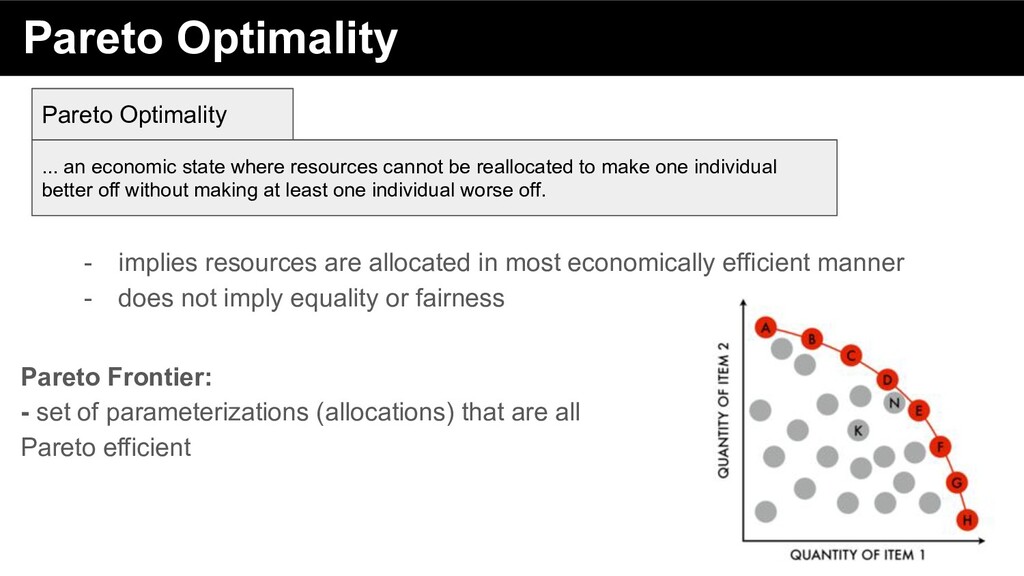
Pareto Optimality ... an economic state where resources cannot be
reallocated to make one individual better off without making at least one individual worse off. Pareto Optimality -
Pareto Optimality - implies resources are allocated in most economically
efficient manner - does not imply equality or fairness ... an economic state where resources cannot be reallocated to make one individual better off without making at least one individual worse off. Pareto Optimality Pareto Frontier: - set of parameterizations (allocations) that are all Pareto efficient -
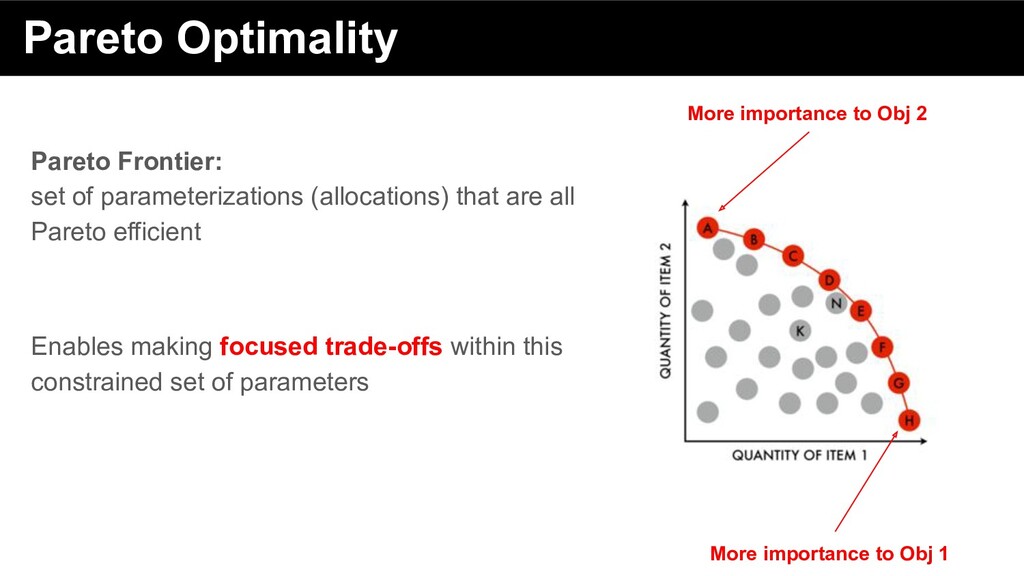
Pareto Optimality Pareto Frontier: set of parameterizations (allocations) that are
all Pareto efficient Enables making focused trade-offs within this constrained set of parameters More importance to Obj 2 More importance to Obj 1 -
Outline 1. Introduction to Marketplaces 2. Optimization Objectives in a
Marketplace 3. Methods for Multi-Objective Ranking & Recommendations a. Pareto optimality b. Multi-objective models i. Multi-task Learning ii. Scalarization iii. Multi-objective bandits iv. Multi-objective RL 4. Leveraging Consumer, Supplier & Content Understanding 5. Industrial Applications -
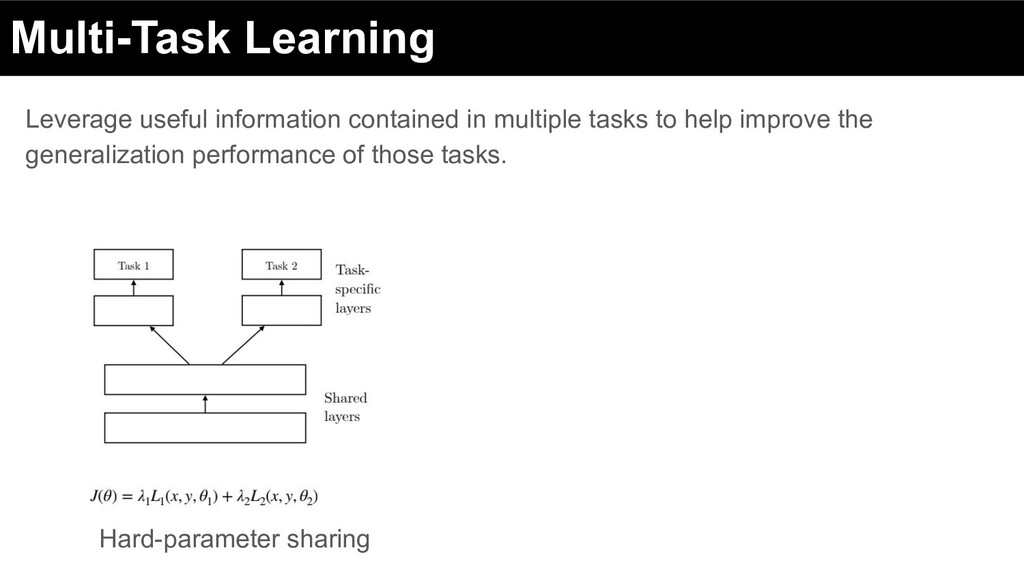
Multi-Task Learning Leverage useful information contained in multiple tasks to
help improve the generalization performance of those tasks. Hard-parameter sharing -
Multi-Task Learning Hard-parameter sharing Soft parameter training Leverage useful information
contained in multiple tasks to help improve the generalization performance of those tasks. -
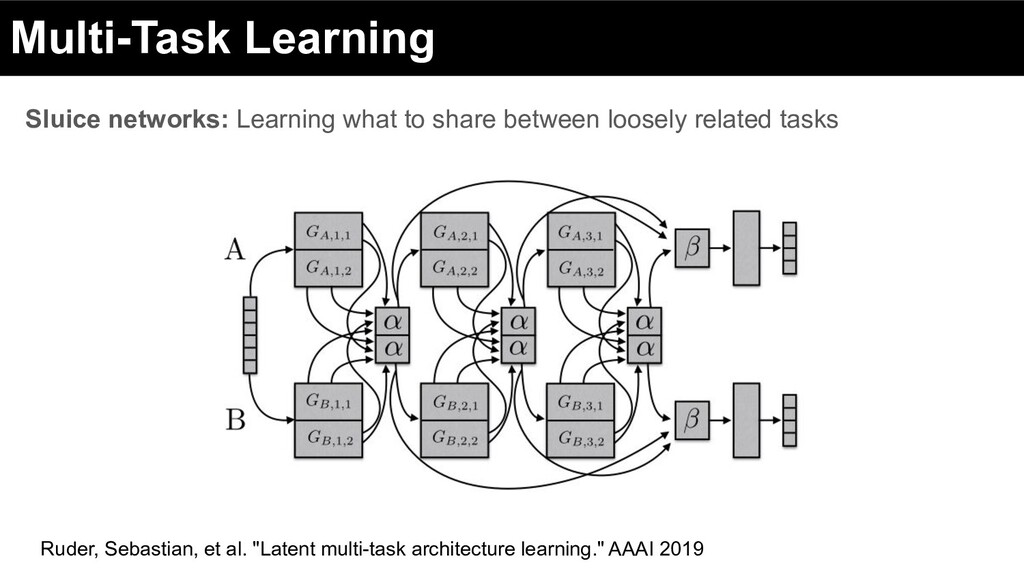
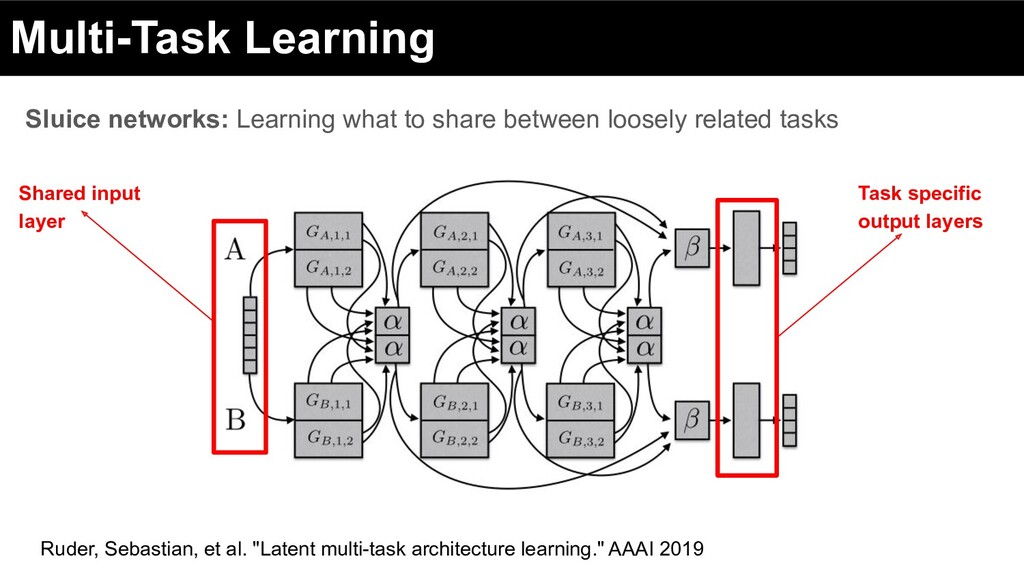
Multi-Task Learning Sluice networks: Learning what to share between loosely
related tasks Ruder, Sebastian, et al. "Latent multi-task architecture learning." AAAI 2019 -
Multi-Task Learning Sluice networks: Learning what to share between loosely
related tasks Ruder, Sebastian, et al. "Latent multi-task architecture learning." AAAI 2019 Shared input layer Task specific output layers -
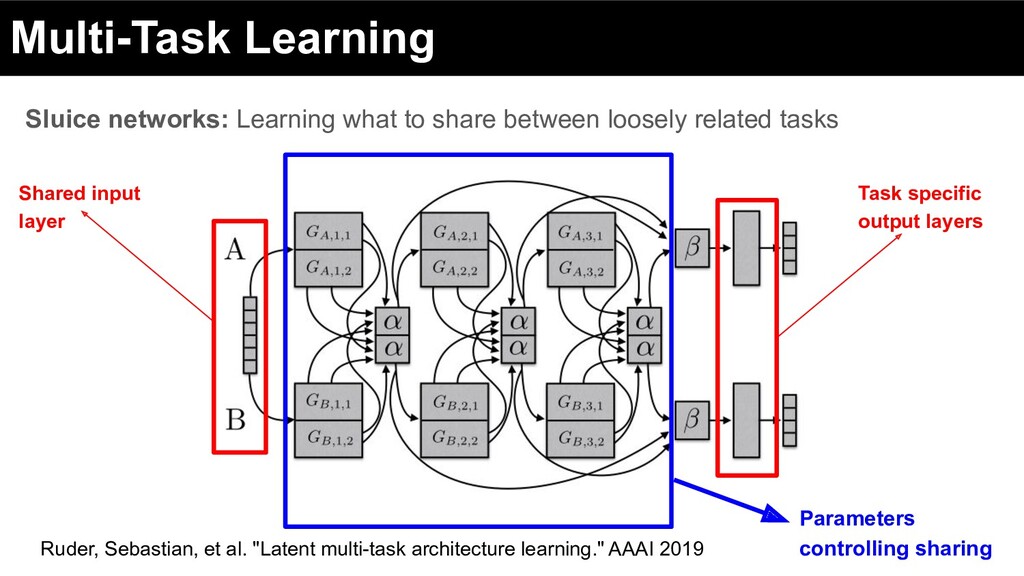
Multi-Task Learning Sluice networks: Learning what to share between loosely
related tasks Ruder, Sebastian, et al. "Latent multi-task architecture learning." AAAI 2019 Shared input layer Task specific output layers Parameters controlling sharing -
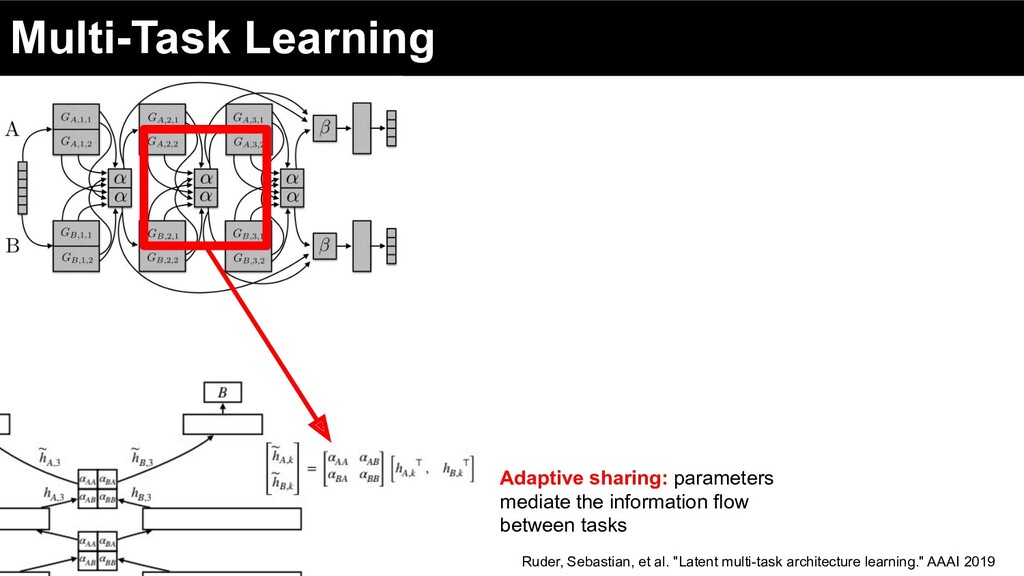
Multi-Task Learning Adaptive sharing: parameters mediate the information flow between
tasks Ruder, Sebastian, et al. "Latent multi-task architecture learning." AAAI 2019 -
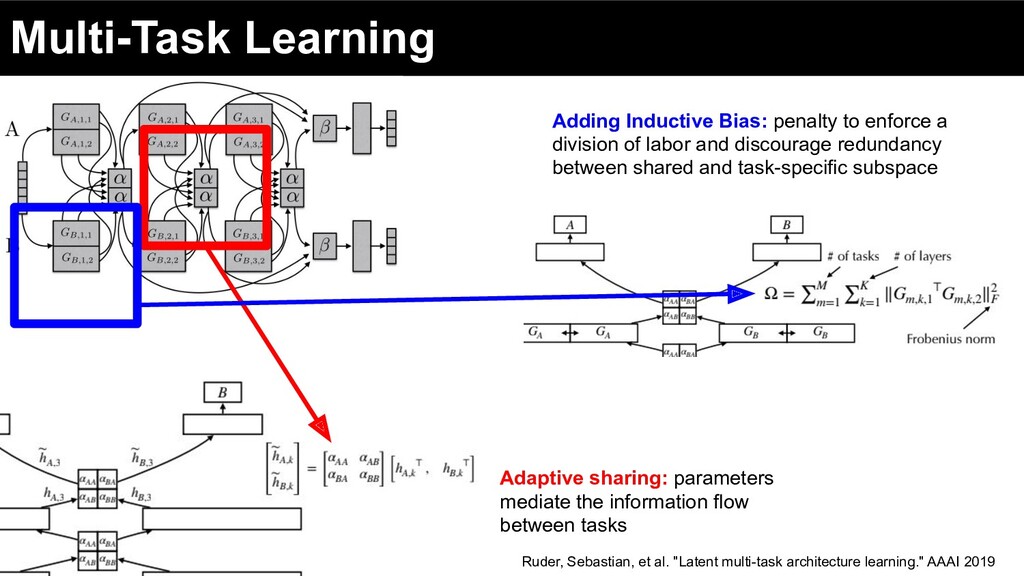
Multi-Task Learning Adding Inductive Bias: penalty to enforce a division
of labor and discourage redundancy between shared and task-specific subspace Adaptive sharing: parameters mediate the information flow between tasks Ruder, Sebastian, et al. "Latent multi-task architecture learning." AAAI 2019 -
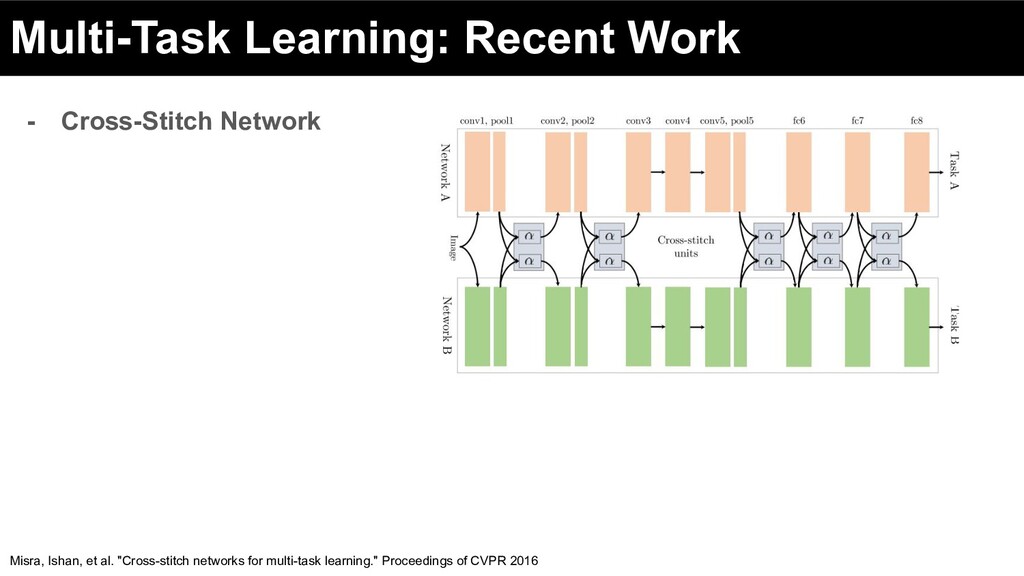
Multi-Task Learning: Recent Work - Cross-Stitch Network Misra, Ishan, et
al. "Cross-stitch networks for multi-task learning." Proceedings of CVPR 2016 -
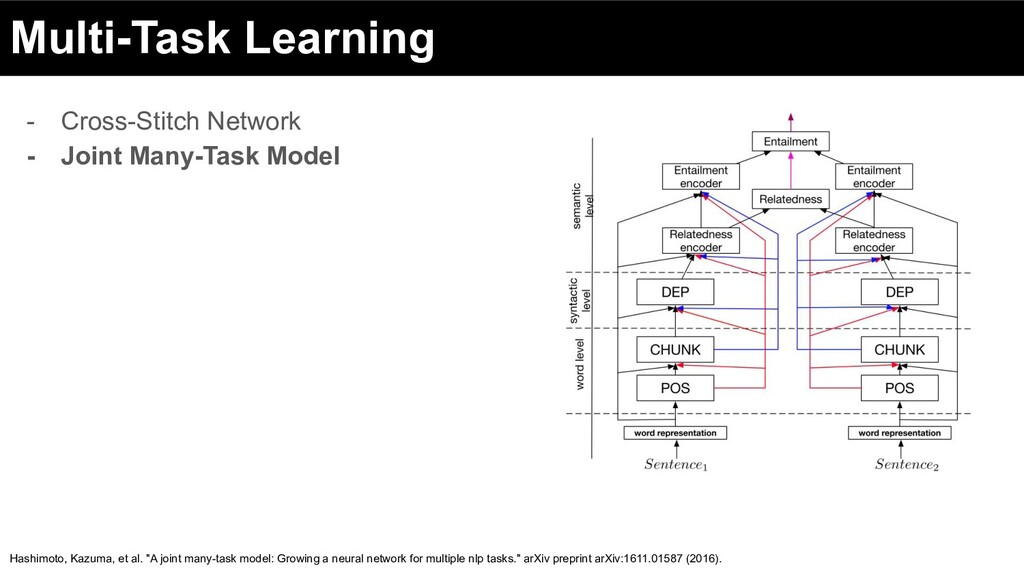
Multi-Task Learning - Cross-Stitch Network - Joint Many-Task Model Hashimoto,
Kazuma, et al. "A joint many-task model: Growing a neural network for multiple nlp tasks." arXiv preprint arXiv:1611.01587 (2016). -
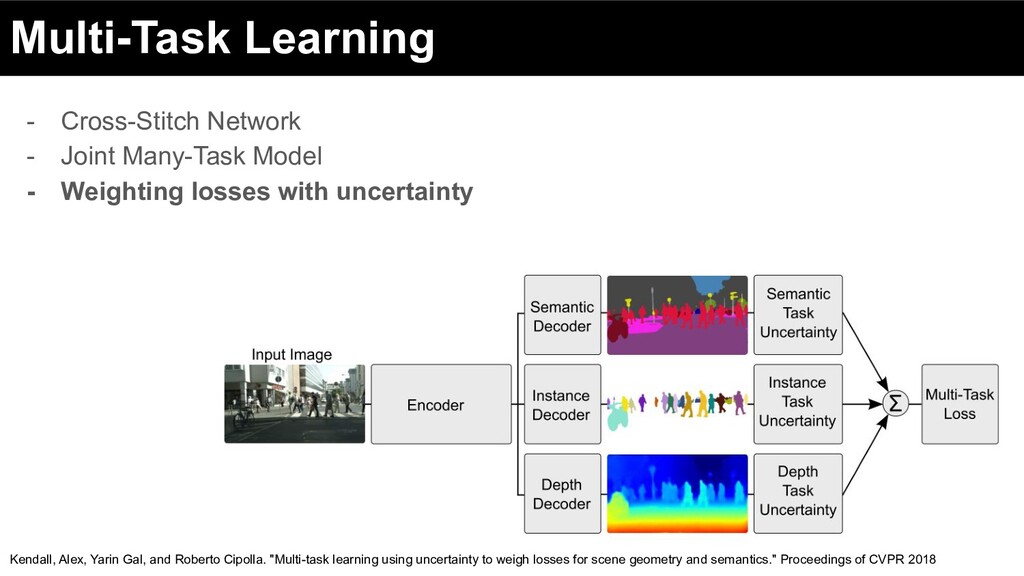
Multi-Task Learning - Cross-Stitch Network - Joint Many-Task Model -
Weighting losses with uncertainty Kendall, Alex, Yarin Gal, and Roberto Cipolla. "Multi-task learning using uncertainty to weigh losses for scene geometry and semantics." Proceedings of CVPR 2018 -
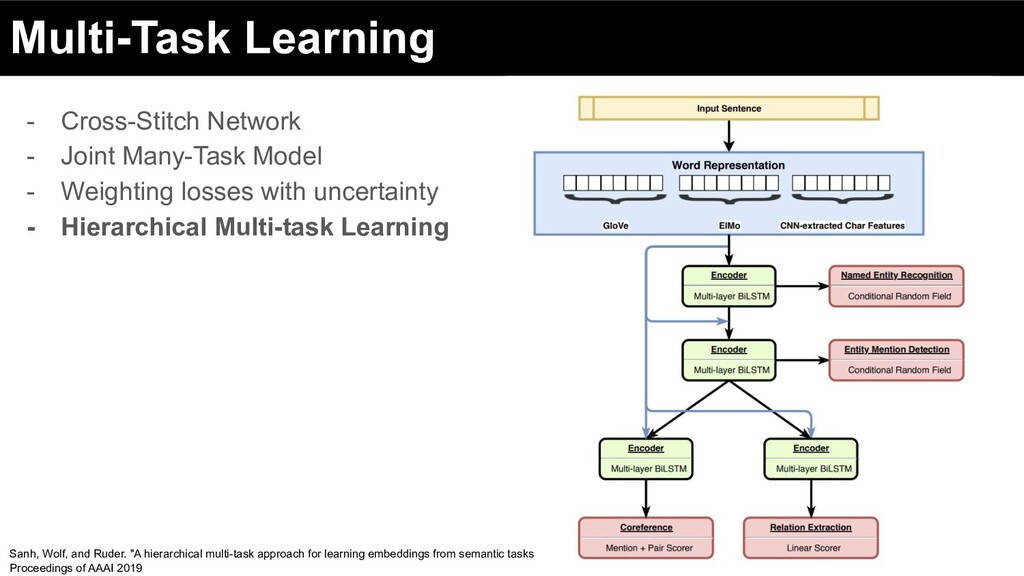
Multi-Task Learning - Cross-Stitch Network - Joint Many-Task Model -
Weighting losses with uncertainty - Hierarchical Multi-task Learning Sanh, Wolf, and Ruder. "A hierarchical multi-task approach for learning embeddings from semantic tasks Proceedings of AAAI 2019 -
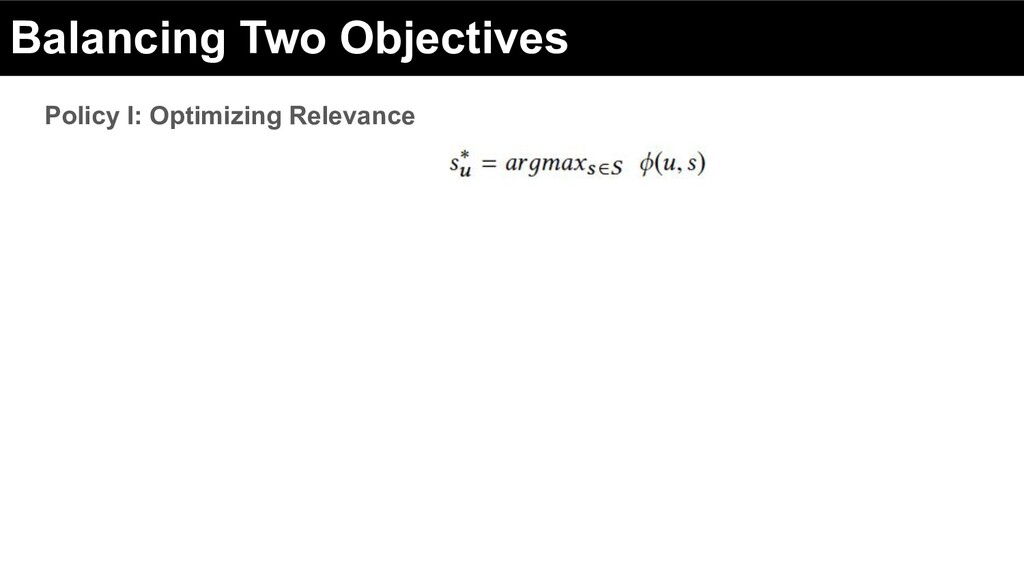
Balancing Two Objectives user-centric fairness Select an arm (i.e. card)
Let’s consider 2 objectives: 1. Relevance (user-centric) 2. Fairness (supplier-centric) -
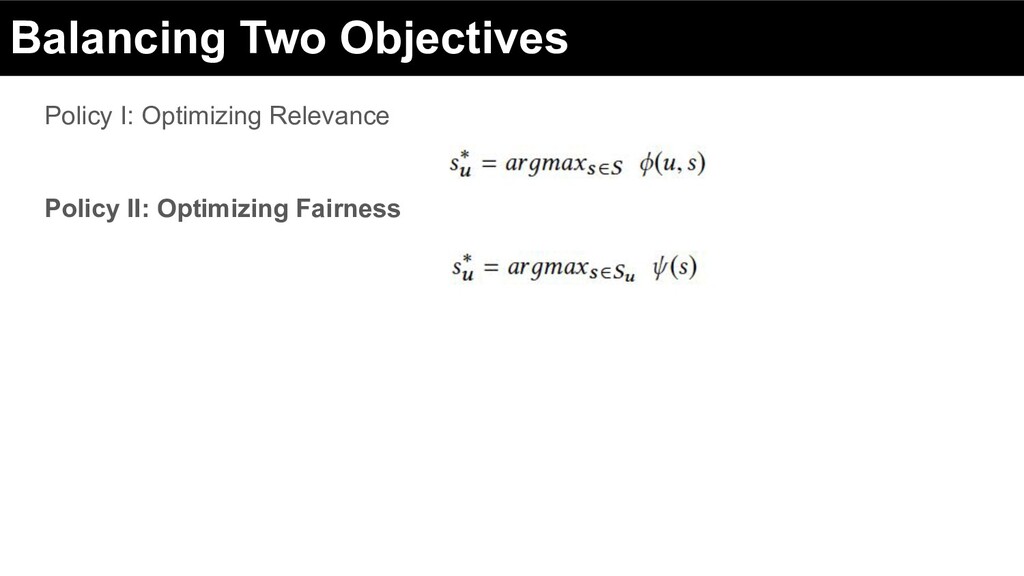
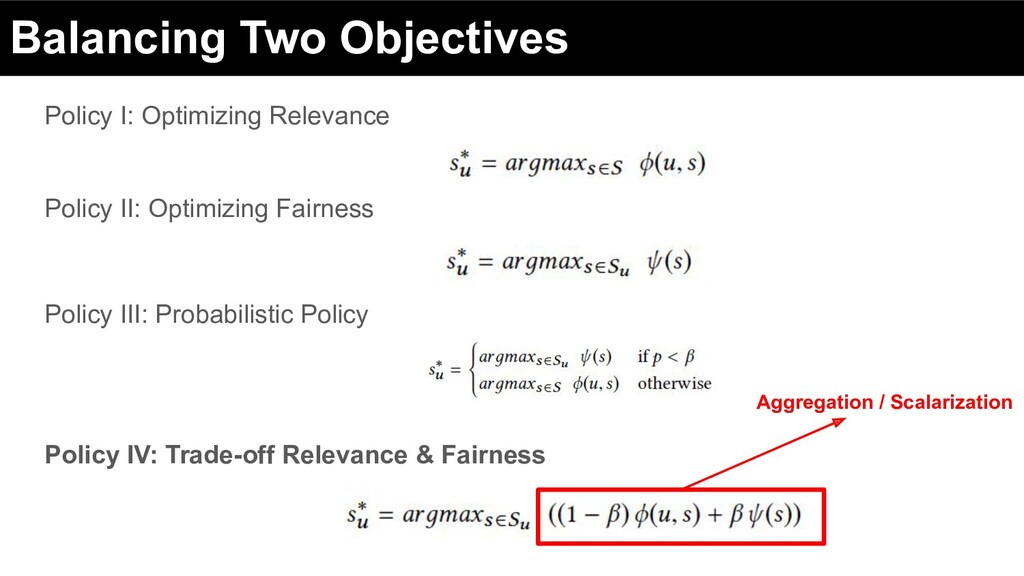
Balancing Two Objectives Policy I: Optimizing Relevance Policy II: Optimizing
Fairness Policy III: Probabilistic Policy -
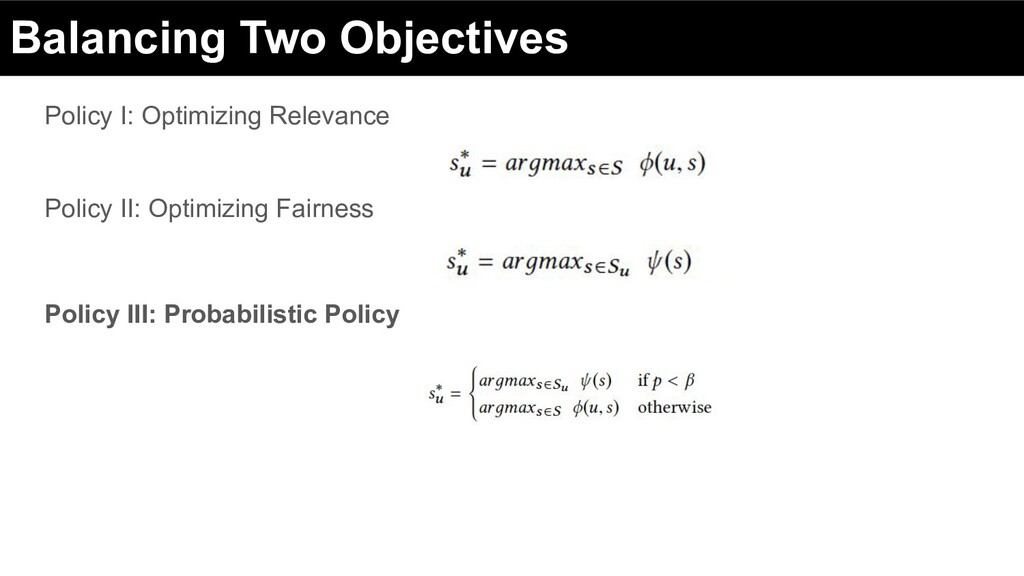
Balancing Two Objectives Policy I: Optimizing Relevance Policy II: Optimizing
Fairness Policy III: Probabilistic Policy Policy IV: Trade-off Relevance & Fairness -
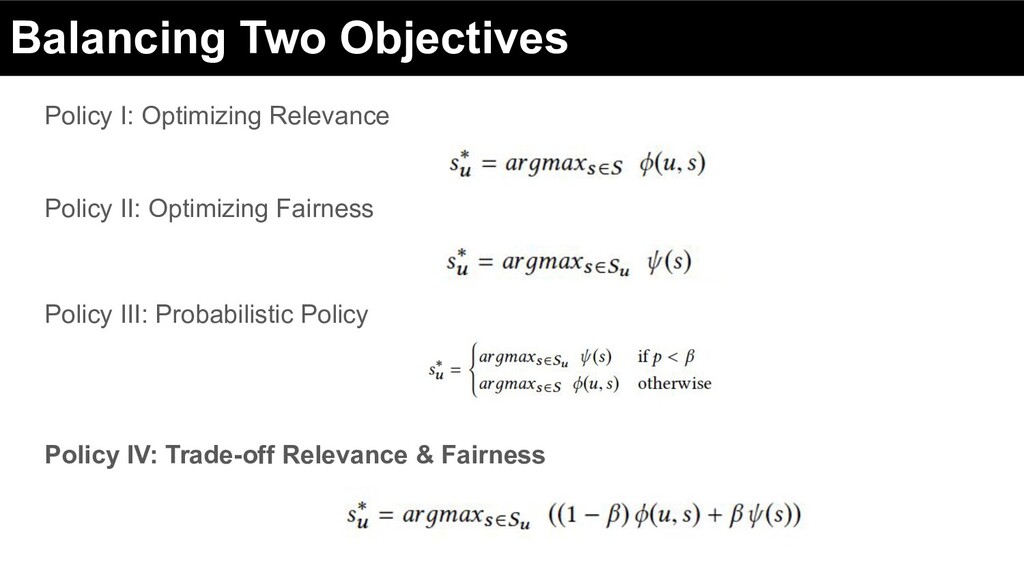
Balancing Two Objectives Policy I: Optimizing Relevance Policy II: Optimizing
Fairness Policy III: Probabilistic Policy Policy IV: Trade-off Relevance & Fairness Aggregation / Scalarization -
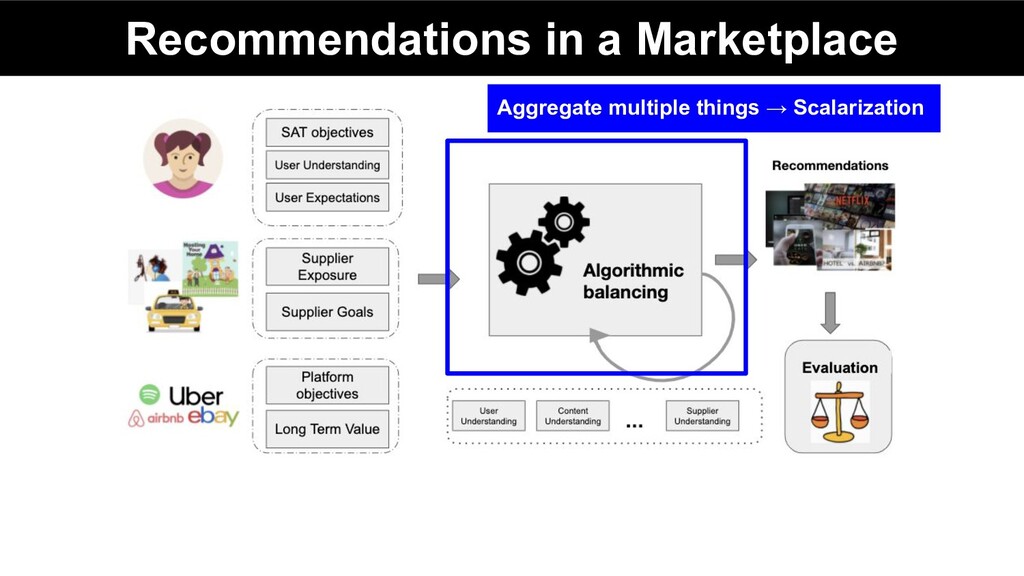
Scalarization An aggregation (or scalarizing) function, which is a non-decreasing
function, allows every vector to receive a scalar value to be optimized -
Scalarization An aggregation (or scalarizing) function, which is a non-decreasing
function, allows every vector to receive a scalar value to be optimized Different aggregation function can be used depending on the problem at hand: • Sum • Weighted sum • Min, Max • (augmented) weighted Chebyshev norm (Steuer & Choo, 1983) • Ordered Weighted Averages (OWA) (Yager, 1988) • Ordered Weighted Regret (OWR) (Ogryczak et al., 2011) -
Outline 1. Introduction to Marketplaces 2. Optimization Objectives in a
Marketplace 3. Methods for Multi-Objective Ranking & Recommendations a. Pareto optimality b. Multi-objective models i. Multi-task Learning ii. Scalarization iii. Multi-objective Multi-Task Learning iv. Multi-objective bandits v. Multi-objective RL 4. Leveraging Consumer, Supplier & Content Understanding 5. Industrial Applications -
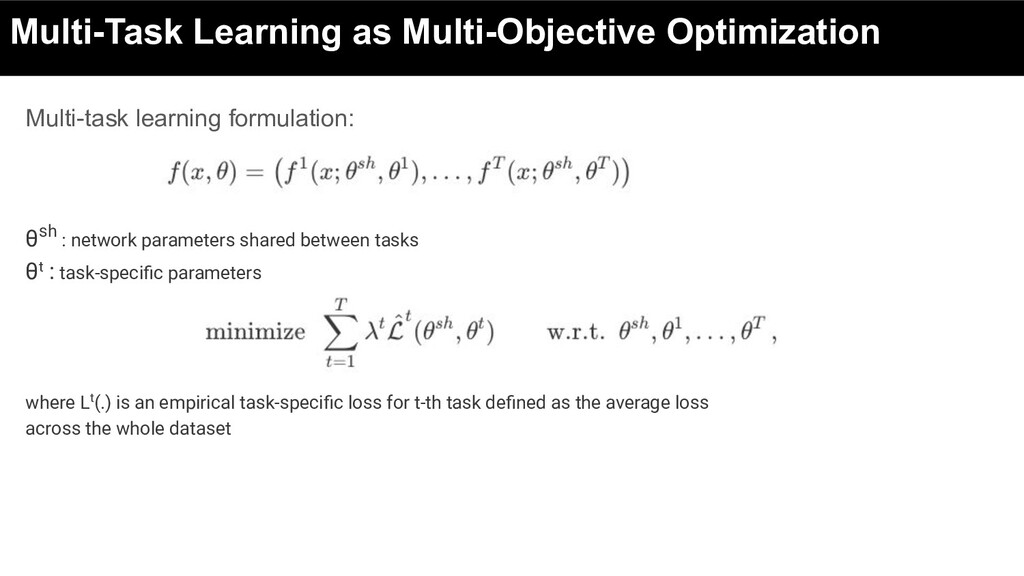
Multi-Task Learning as Multi-Objective Optimization Multi-task learning formulation: θsh :
network parameters shared between tasks θt : task-specific parameters where Lt(.) is an empirical task-specific loss for t-th task defined as the average loss across the whole dataset -
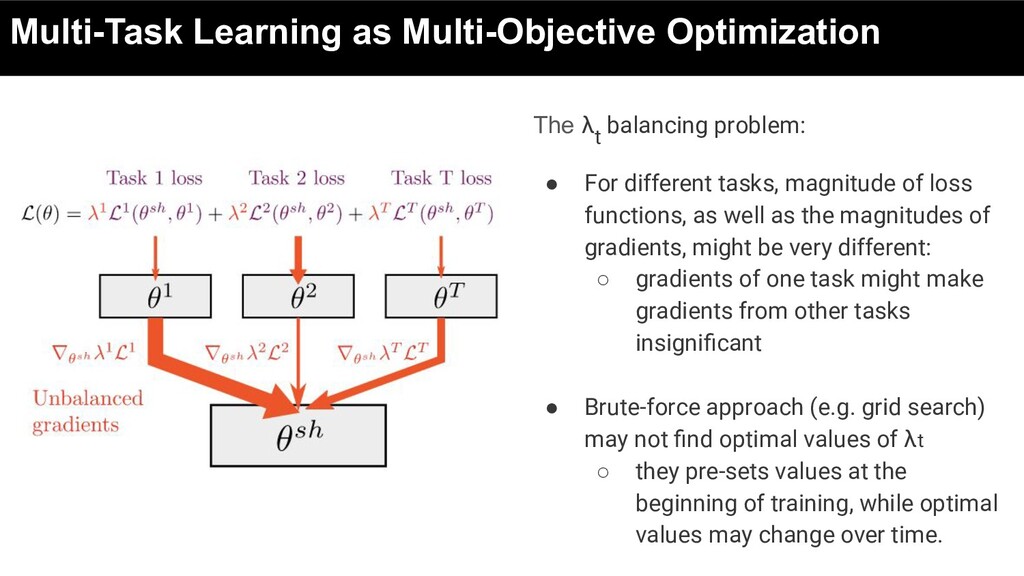
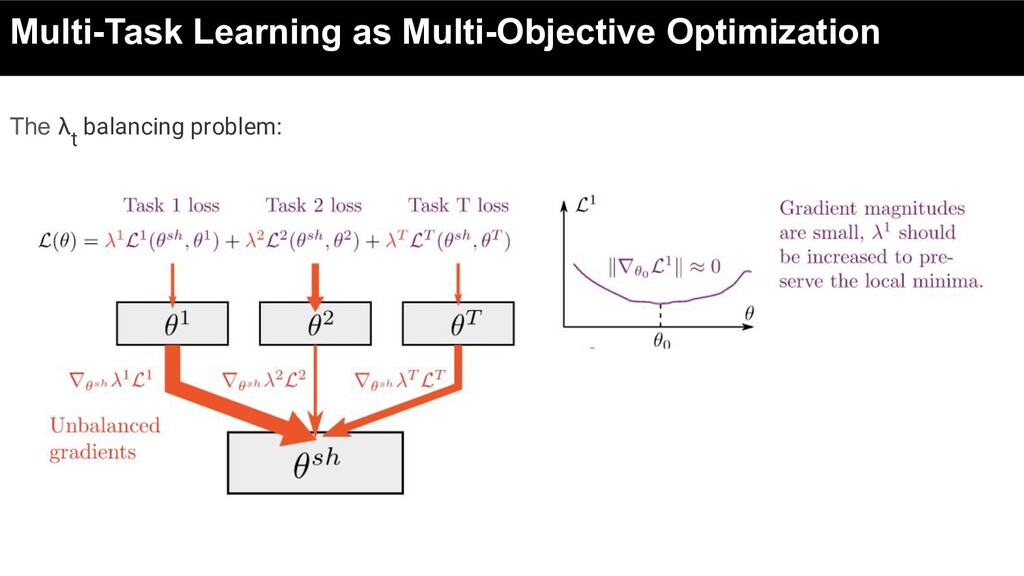
Multi-Task Learning as Multi-Objective Optimization The λ t balancing problem:
• For different tasks, magnitude of loss functions, as well as the magnitudes of gradients, might be very different: ◦ gradients of one task might make gradients from other tasks insignificant • Brute-force approach (e.g. grid search) may not find optimal values of λt ◦ they pre-sets values at the beginning of training, while optimal values may change over time. -
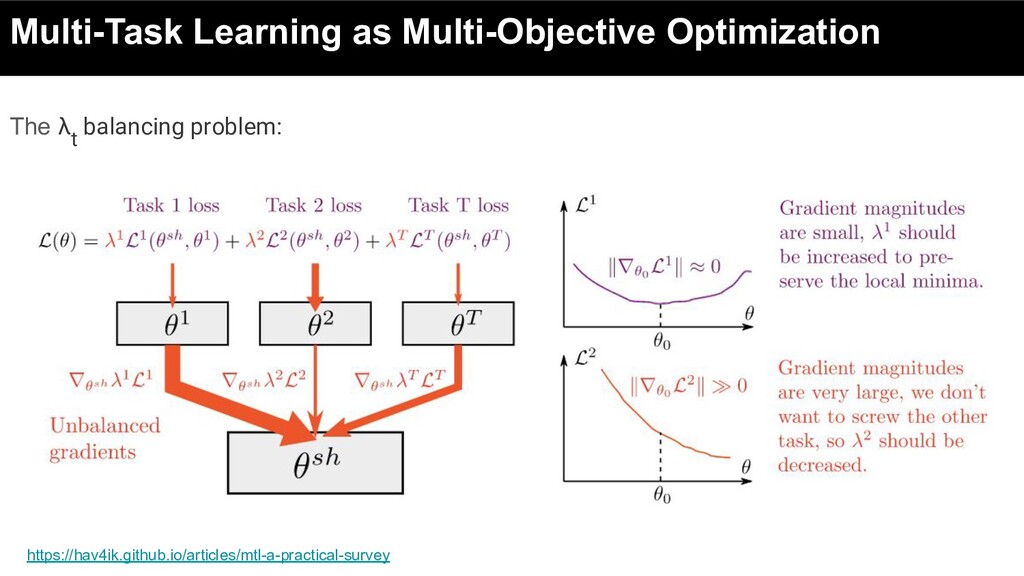
Multi-Task Learning as Multi-Objective Optimization The λ t balancing problem:
https://hav4ik.github.io/articles/mtl-a-practical-survey -
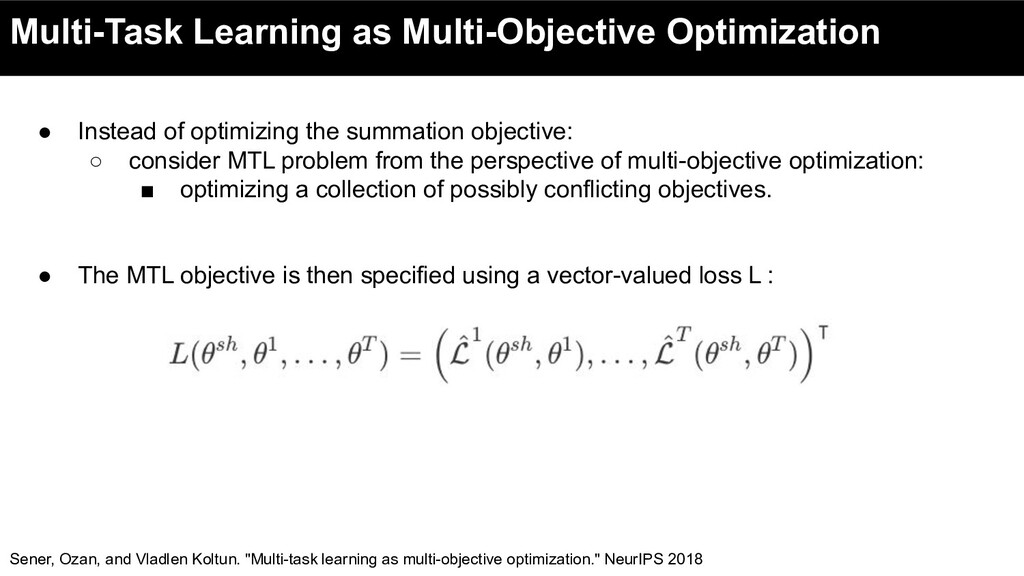
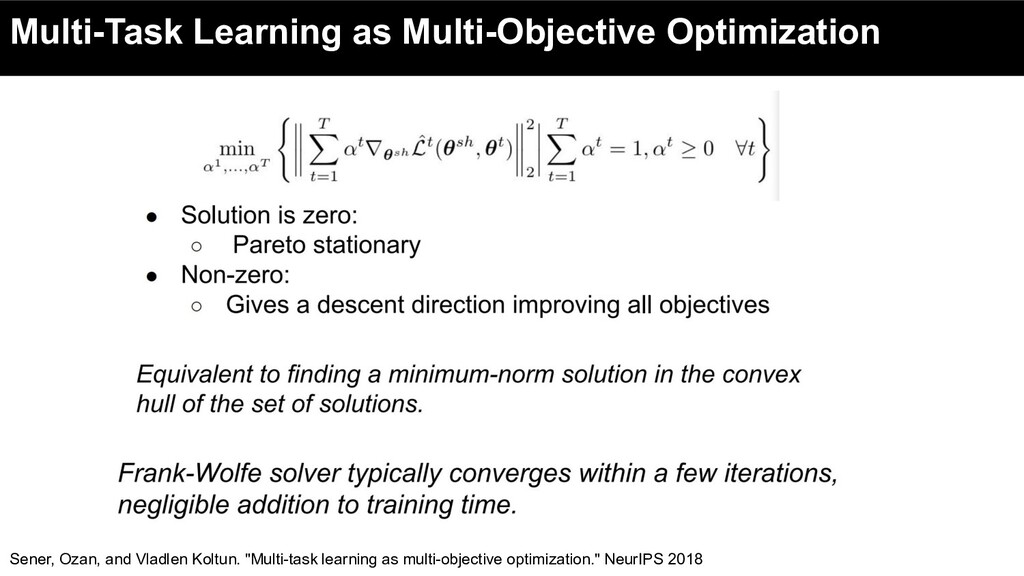
Multi-Task Learning as Multi-Objective Optimization • Instead of optimizing the
summation objective: ◦ consider MTL problem from the perspective of multi-objective optimization: ▪ optimizing a collection of possibly conflicting objectives. Sener, Ozan, and Vladlen Koltun. "Multi-task learning as multi-objective optimization." NeurIPS 2018 -
Multi-Task Learning as Multi-Objective Optimization • Instead of optimizing the
summation objective: ◦ consider MTL problem from the perspective of multi-objective optimization: ▪ optimizing a collection of possibly conflicting objectives. • The MTL objective is then specified using a vector-valued loss L : Sener, Ozan, and Vladlen Koltun. "Multi-task learning as multi-objective optimization." NeurIPS 2018 -
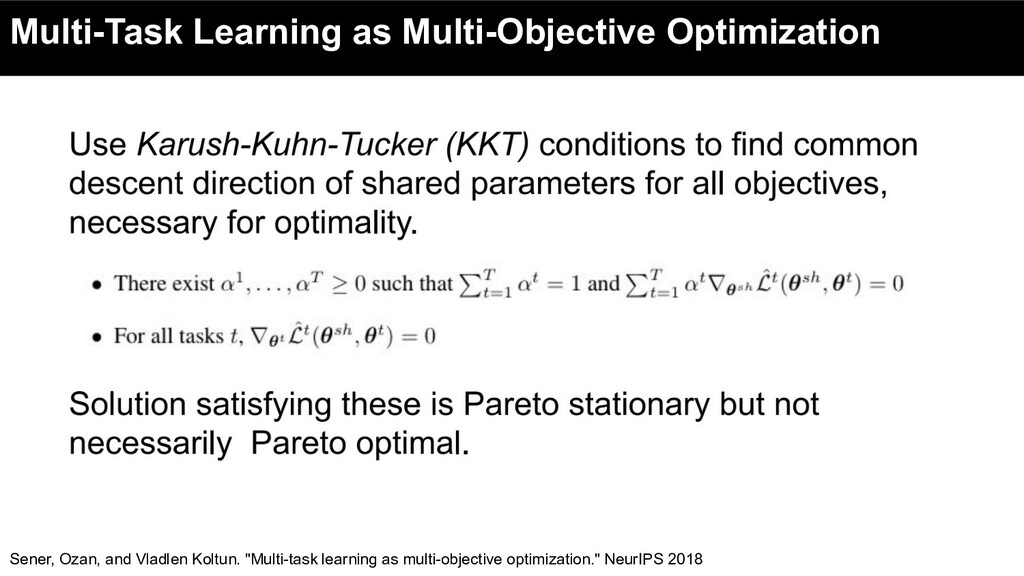
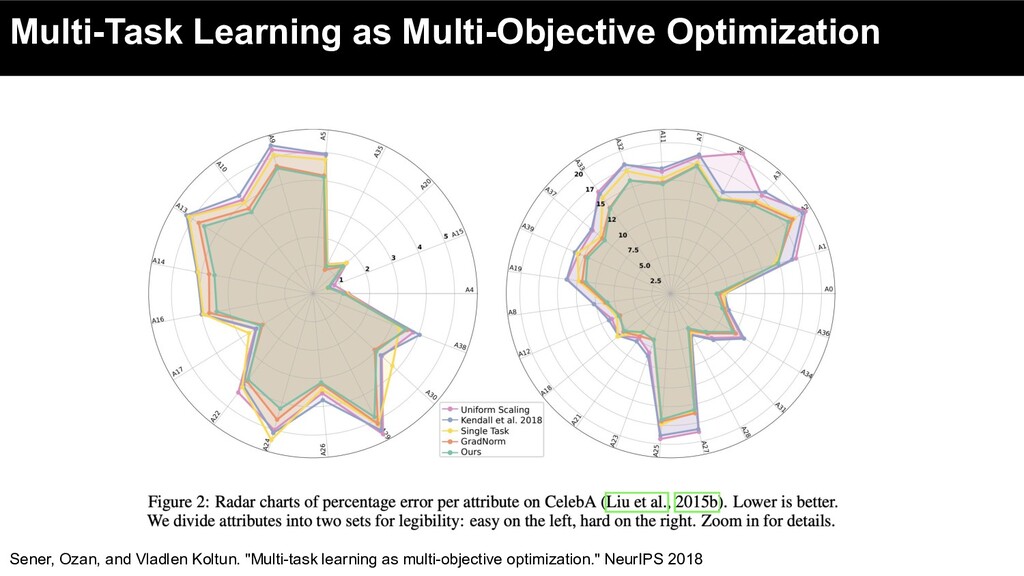
Multi-Task Learning as Multi-Objective Optimization Sener, Ozan, and Vladlen Koltun.
"Multi-task learning as multi-objective optimization." NeurIPS 2018 -
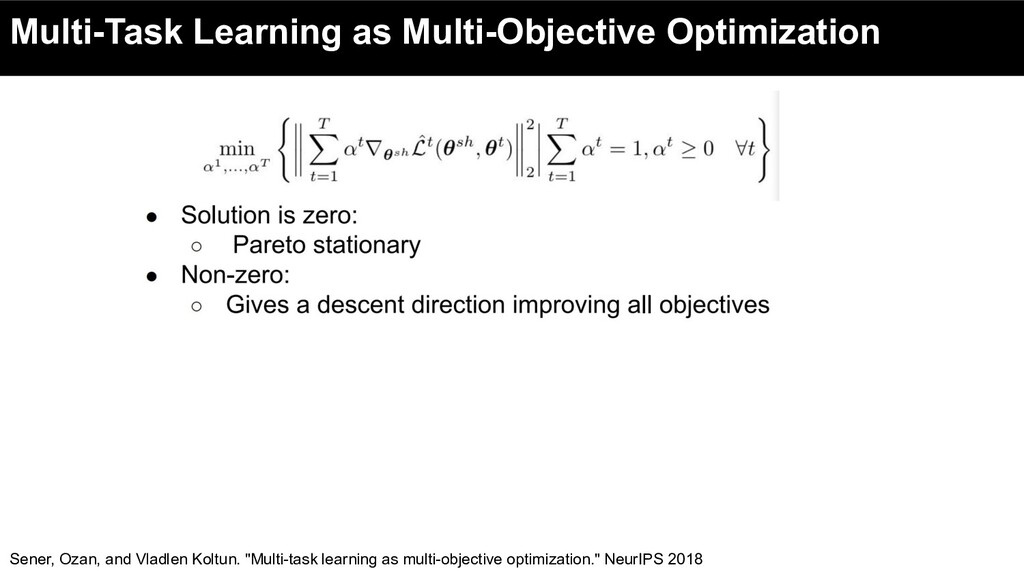
Multi-Task Learning as Multi-Objective Optimization Sener, Ozan, and Vladlen Koltun.
"Multi-task learning as multi-objective optimization." NeurIPS 2018 -
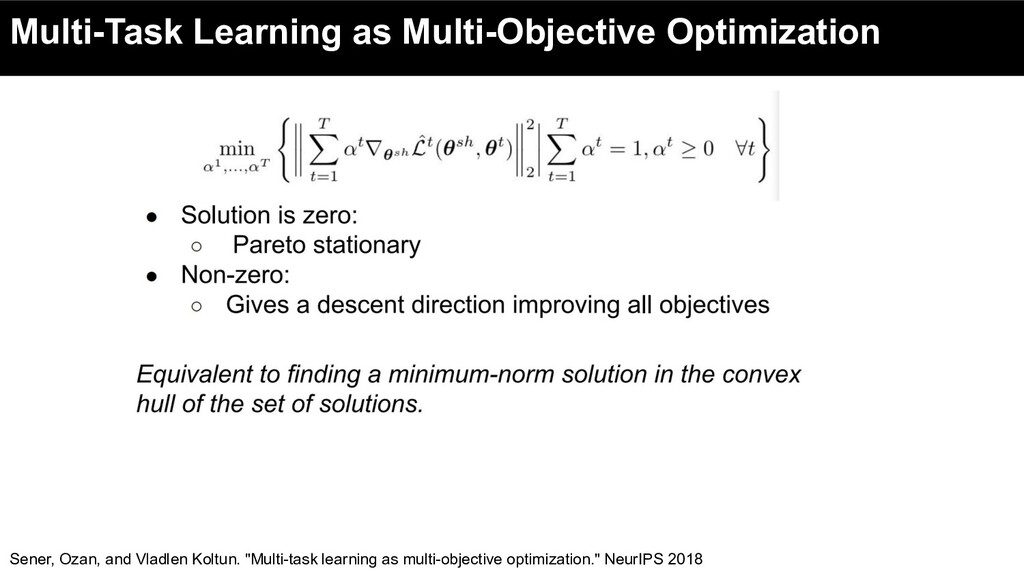
Multi-Task Learning as Multi-Objective Optimization Sener, Ozan, and Vladlen Koltun.
"Multi-task learning as multi-objective optimization." NeurIPS 2018 -
Multi-Task Learning as Multi-Objective Optimization Sener, Ozan, and Vladlen Koltun.
"Multi-task learning as multi-objective optimization." NeurIPS 2018 -
Multi-Task Learning as Multi-Objective Optimization Sener, Ozan, and Vladlen Koltun.
"Multi-task learning as multi-objective optimization." NeurIPS 2018 -
Outline 1. Introduction to Marketplaces 2. Optimization Objectives in a
Marketplace 3. Methods for Multi-Objective Ranking & Recommendations a. Pareto optimality b. Multi-objective models i. Multi-task Learning ii. Scalarization iii. Multi-objective Multi-Task Learning iv. Multi-objective bandits v. Multi-objective RL 4. Leveraging Consumer, Supplier & Content Understanding 5. Industrial Applications -
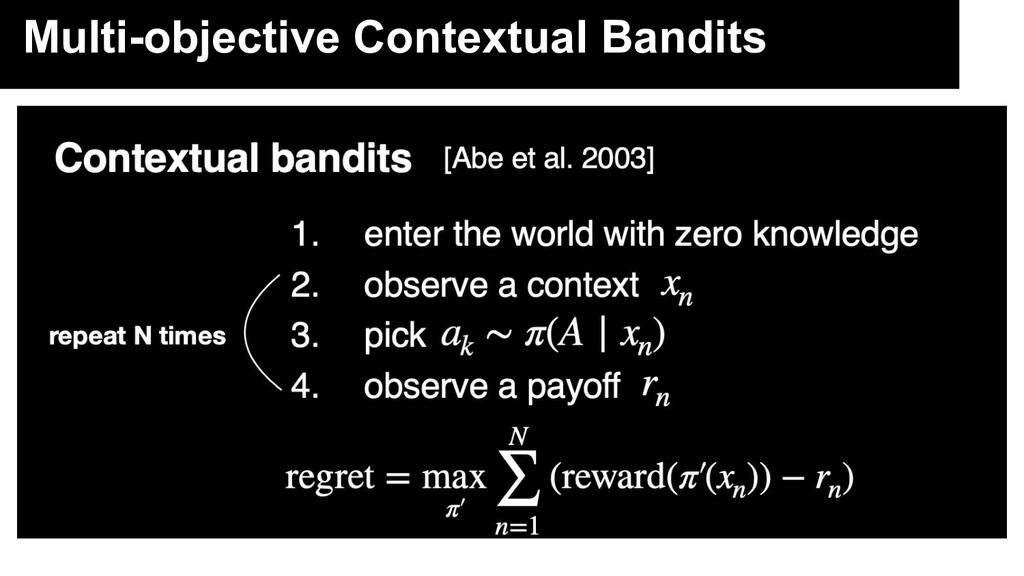
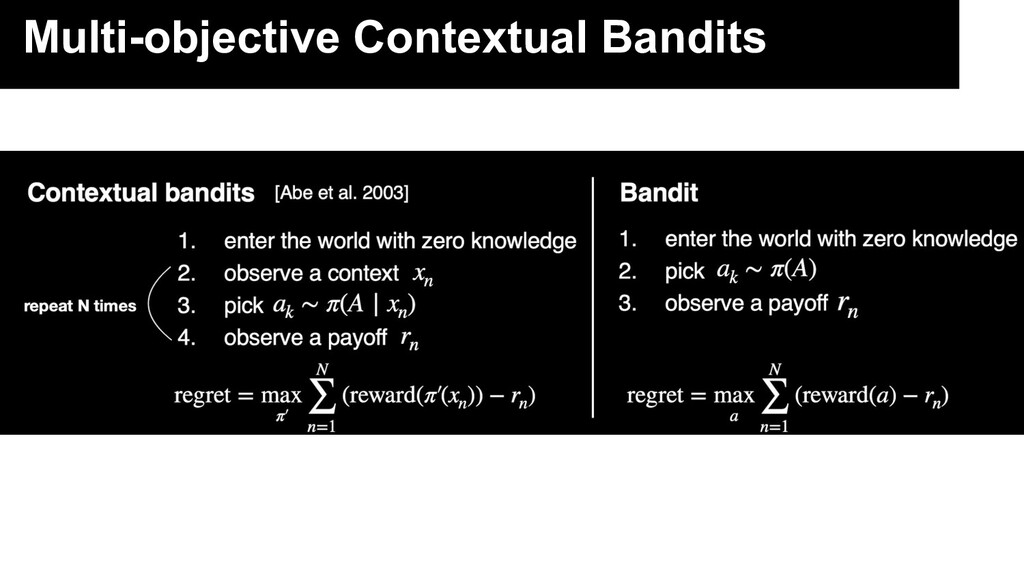
Multi-objective Contextual Bandits Recent work on Multi-Objective Bandits: I. Busa-Fekete,
Szörényi, Weng, and Mannor. Multiobjective Bandits: Optimizing the Generalized Gini Index. In ICML 2017 II. Tekin and Turğay. Multi-objective contextual multi-armed bandit with a dominant objective. IEEE Transactions on Signal Processing (2018) III. Turğay, Öner, and Tekin. Multi-objective contextual bandit problem with similarity information. AISTATS 2018 IV. Mehrotra, Xue, and Lalmas. Multi-objective Linear Contextual Bandits via Generalised Gini Function. KDD 2020 -
Multi-objective Contextual Bandits Recent work on Multi-Objective Bandits: I. Busa-Fekete,
Szörényi, Weng, and Mannor. Multiobjective Bandits: Optimizing the Generalized Gini Index. In ICML 2017 II. Tekin and Turğay. Multi-objective contextual multi-armed bandit with a dominant objective. IEEE Transactions on Signal Processing (2018) III. Turğay, Öner, and Tekin. Multi-objective contextual bandit problem with similarity information. AISTATS 2018 IV. Mehrotra, Xue, and Lalmas. Multi-objective Linear Contextual Bandits via Generalised Gini Function. KDD 2020 -
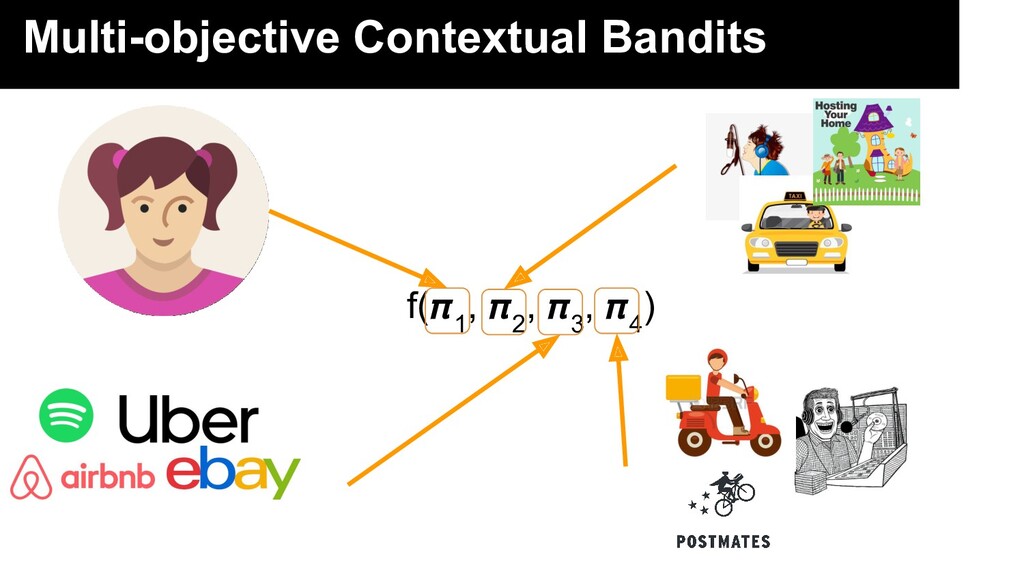
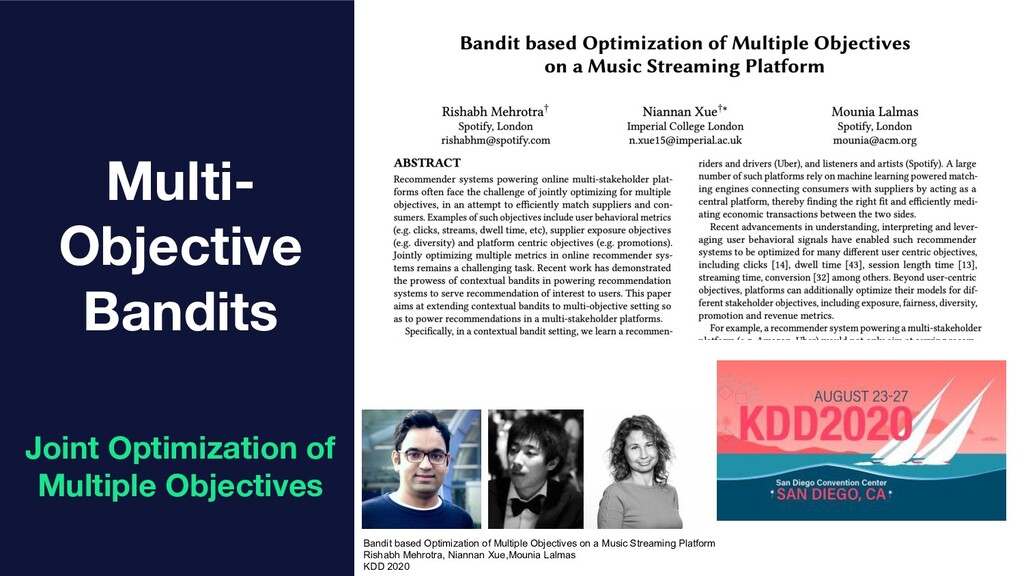
Multi- Objective Bandits Joint Optimization of Multiple Objectives Bandit based
Optimization of Multiple Objectives on a Music Streaming Platform Rishabh Mehrotra, Niannan Xue,Mounia Lalmas KDD 2020 -
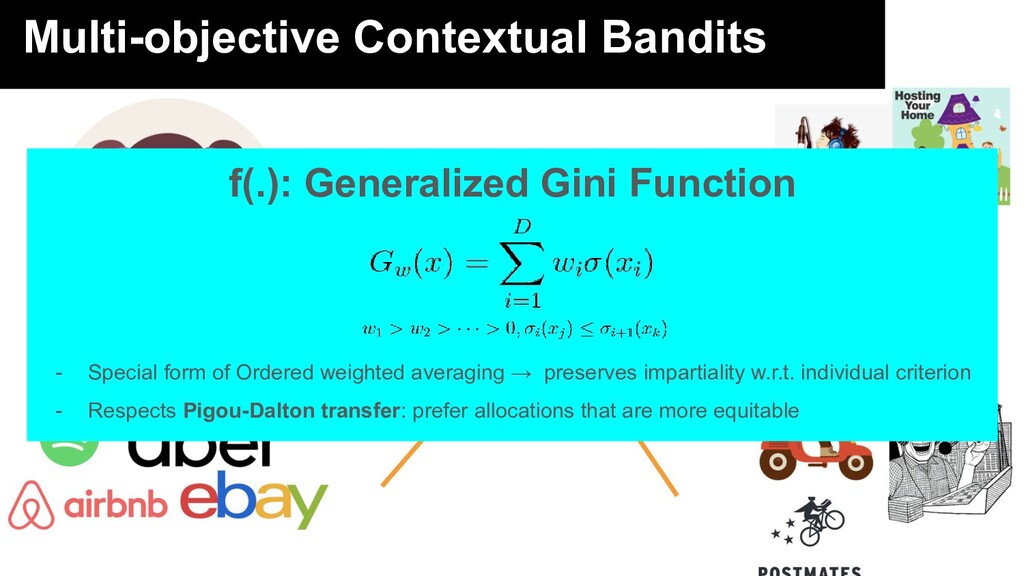
Multi-objective Contextual Bandits f(.): Generalized Gini Function - Special form
of Ordered weighted averaging → preserves impartiality w.r.t. individual criterion - Respects Pigou-Dalton transfer: prefer allocations that are more equitable -
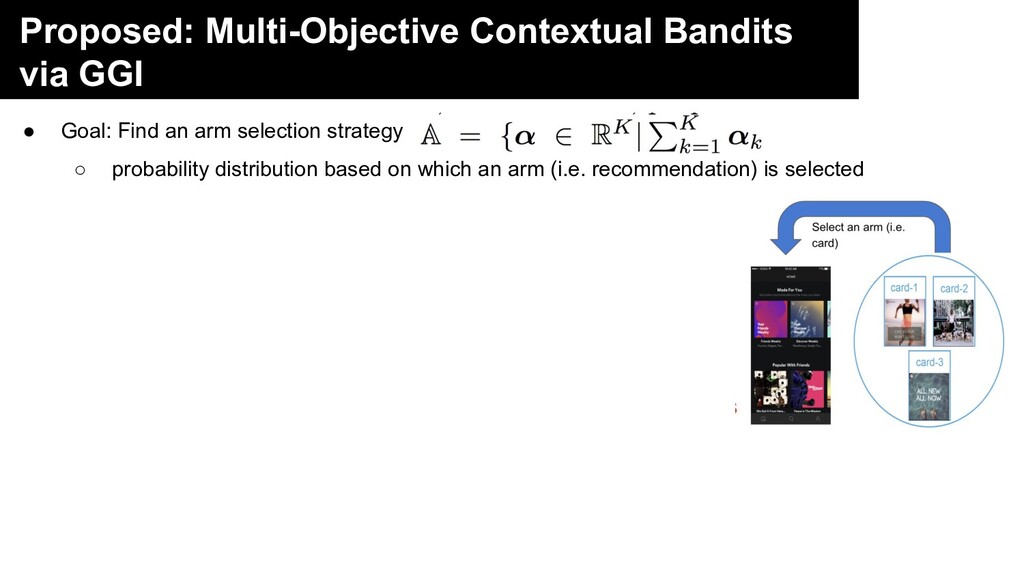
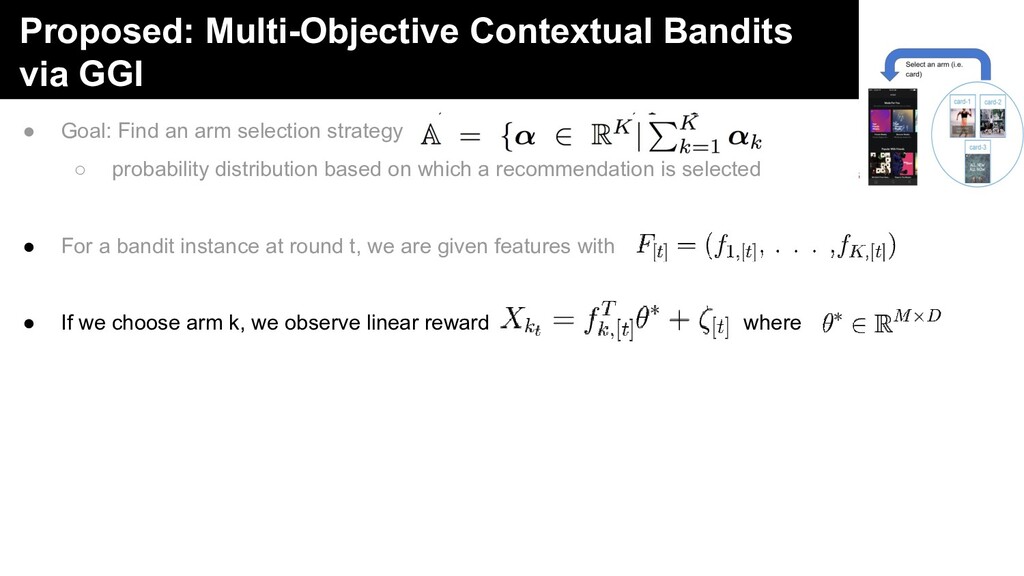
Proposed: Multi-Objective Contextual Bandits via GGI • Goal: Find an
arm selection strategy ◦ probability distribution based on which an arm (i.e. recommendation) is selected -
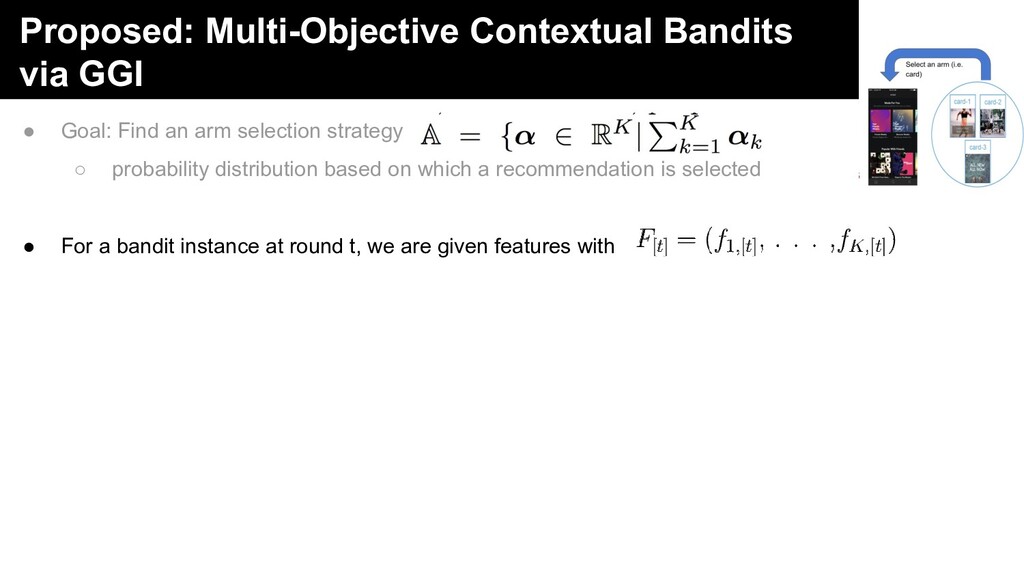
Proposed: Multi-Objective Contextual Bandits via GGI • Goal: Find an
arm selection strategy ◦ probability distribution based on which a recommendation is selected • For a bandit instance at round t, we are given features with -
Proposed: Multi-Objective Contextual Bandits via GGI • Goal: Find an
arm selection strategy ◦ probability distribution based on which a recommendation is selected • For a bandit instance at round t, we are given features with • If we choose arm k, we observe linear reward where -
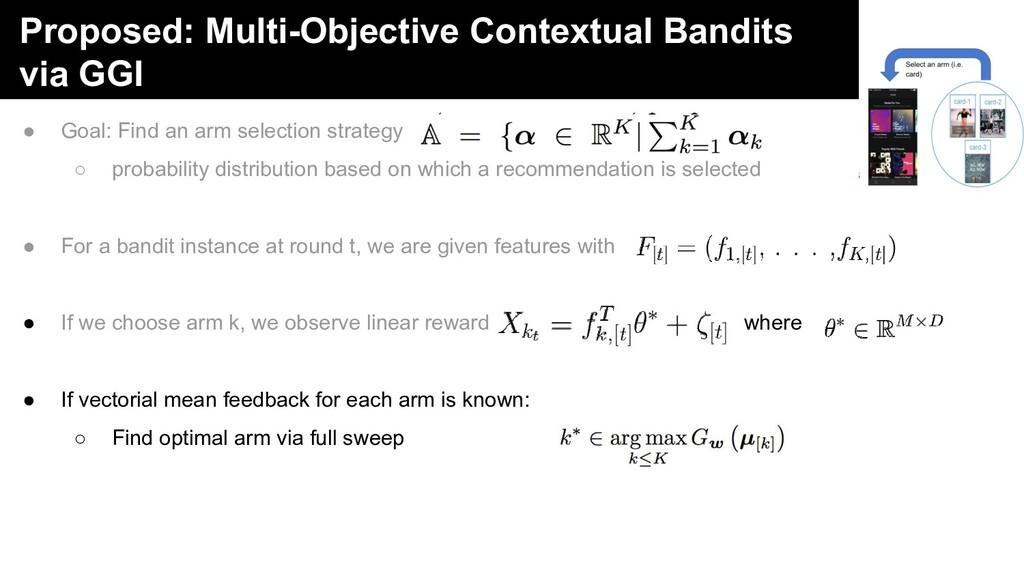
Proposed: Multi-Objective Contextual Bandits via GGI • Goal: Find an
arm selection strategy ◦ probability distribution based on which a recommendation is selected • For a bandit instance at round t, we are given features with • If we choose arm k, we observe linear reward where • If vectorial mean feedback for each arm is known: ◦ Find optimal arm via full sweep -
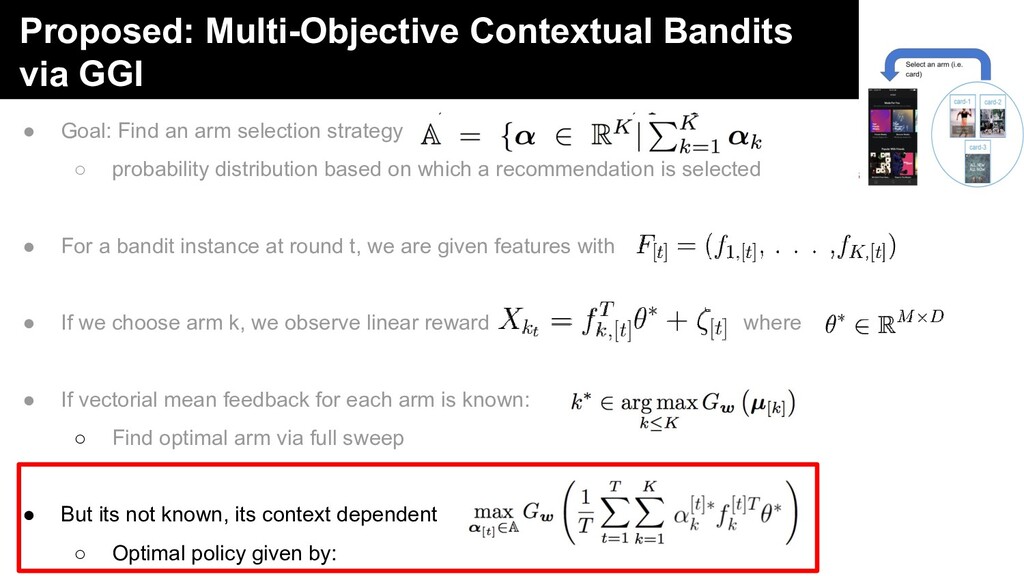
Proposed: Multi-Objective Contextual Bandits via GGI • Goal: Find an
arm selection strategy ◦ probability distribution based on which a recommendation is selected • For a bandit instance at round t, we are given features with • If we choose arm k, we observe linear reward where • If vectorial mean feedback for each arm is known: ◦ Find optimal arm via full sweep • But its not known, its context dependent ◦ Optimal policy given by: -
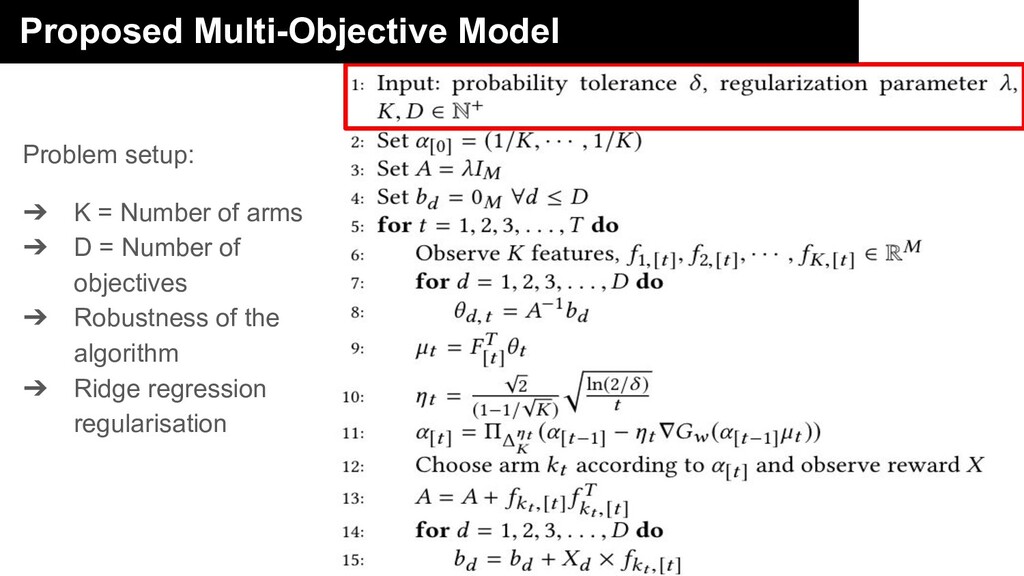
Problem setup: ➔ K = Number of arms ➔ D
= Number of objectives ➔ Robustness of the algorithm ➔ Ridge regression regularisation Proposed Multi-Objective Model -
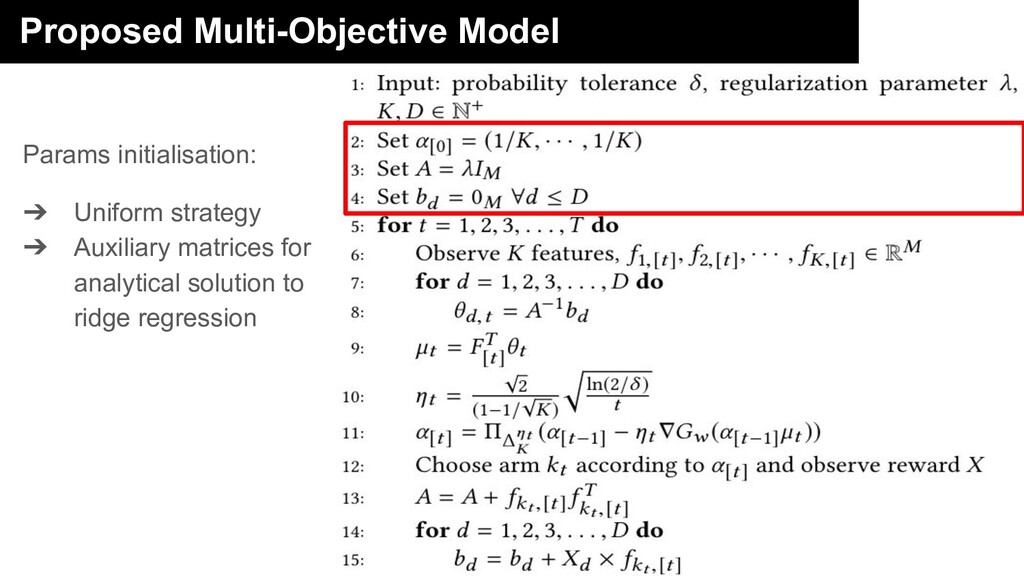
Params initialisation: ➔ Uniform strategy ➔ Auxiliary matrices for analytical
solution to ridge regression Proposed Multi-Objective Model -
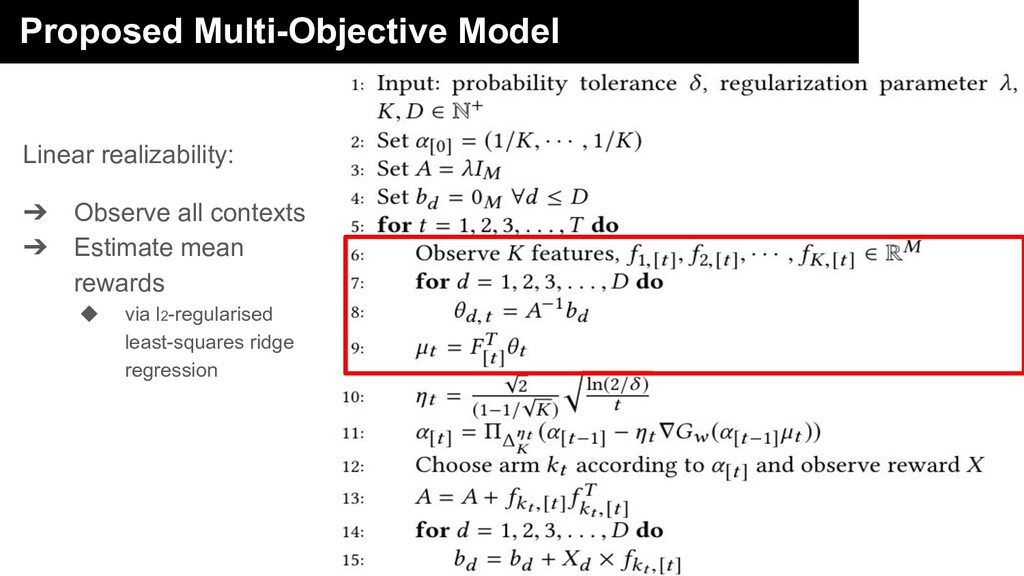
Linear realizability: ➔ Observe all contexts ➔ Estimate mean rewards
◆ via l2-regularised least-squares ridge regression Proposed Multi-Objective Model -
Online Gradient Descent: ➔ Non-vanishing step size ➔ Project a[t]
back onto A Proposed Multi-Objective Model -
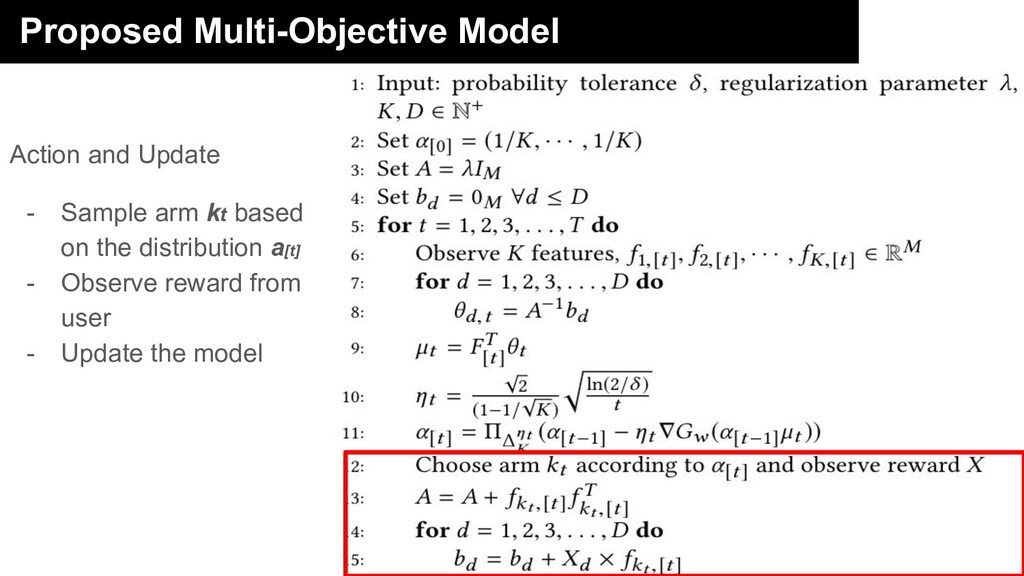
Action and Update - Sample arm kt based on the
distribution a[t] - Observe reward from user - Update the model Proposed Multi-Objective Model -
Multi-Objective RL Two primary strategies: • Scalarized approach: Find a
single policy that optimises a combinations of the rewards ◦ Which reward combination is preferable at which state? • Pareto approach: ◦ Find multiple policies that cover the Pareto front: Sampling in a high-dimensional case -
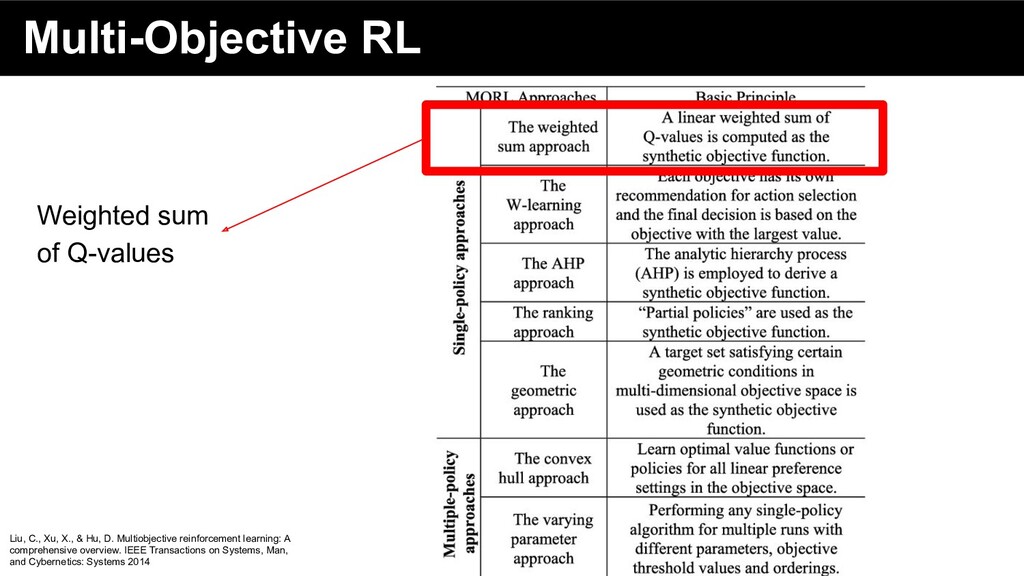
Multi-Objective RL Liu, C., Xu, X., & Hu, D. Multiobjective
reinforcement learning: A comprehensive overview. IEEE Transactions on Systems, Man, and Cybernetics: Systems 2014 Single Policy approach Multiple Policy approach -
Multi-Objective RL Liu, C., Xu, X., & Hu, D. Multiobjective
reinforcement learning: A comprehensive overview. IEEE Transactions on Systems, Man, and Cybernetics: Systems 2014 Weighted sum of Q-values -
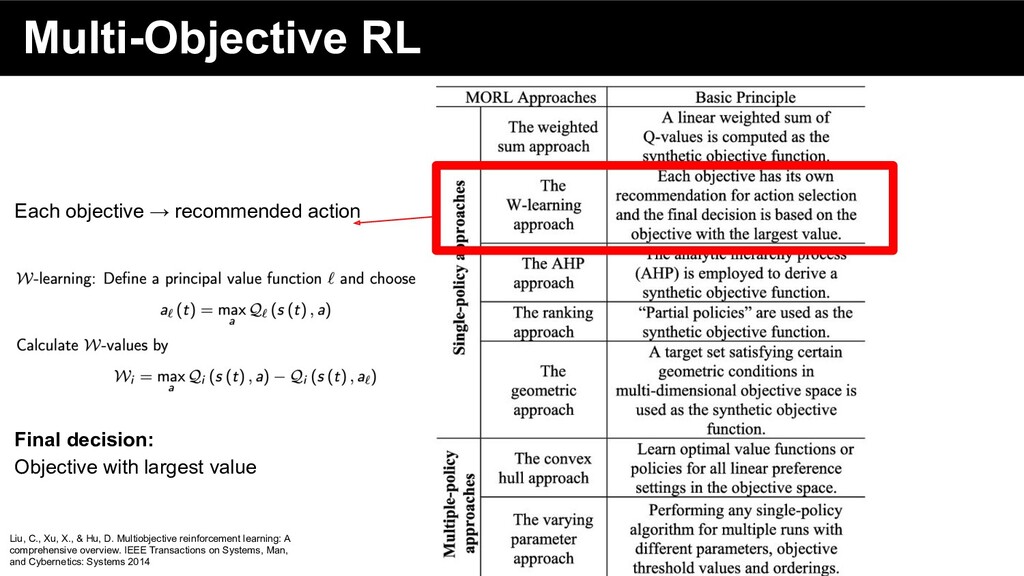
Multi-Objective RL Liu, C., Xu, X., & Hu, D. Multiobjective
reinforcement learning: A comprehensive overview. IEEE Transactions on Systems, Man, and Cybernetics: Systems 2014 Each objective → recommended action Final decision: Objective with largest value -
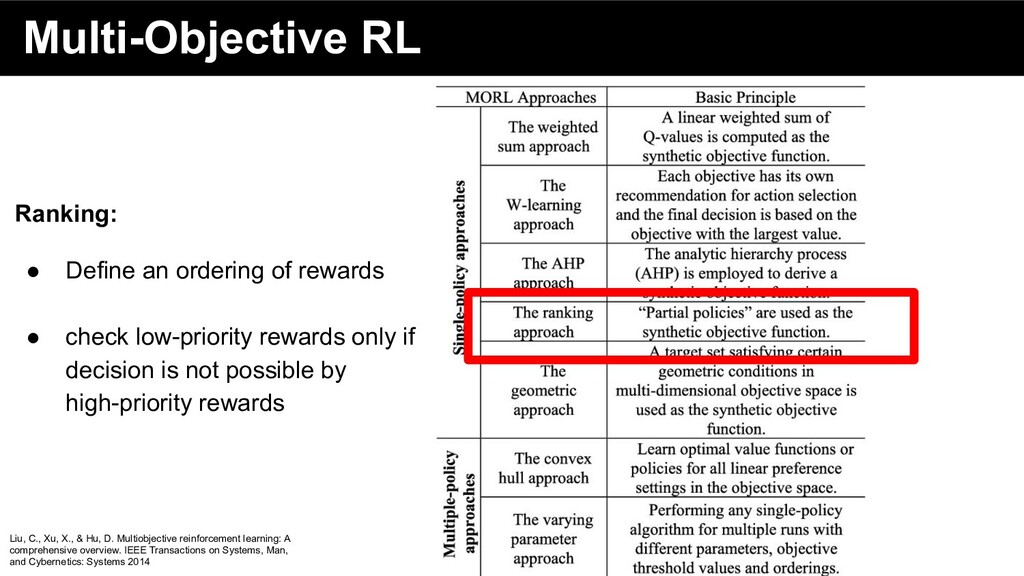
Multi-Objective RL Liu, C., Xu, X., & Hu, D. Multiobjective
reinforcement learning: A comprehensive overview. IEEE Transactions on Systems, Man, and Cybernetics: Systems 2014 Ranking: • Define an ordering of rewards • check low-priority rewards only if decision is not possible by high-priority rewards -
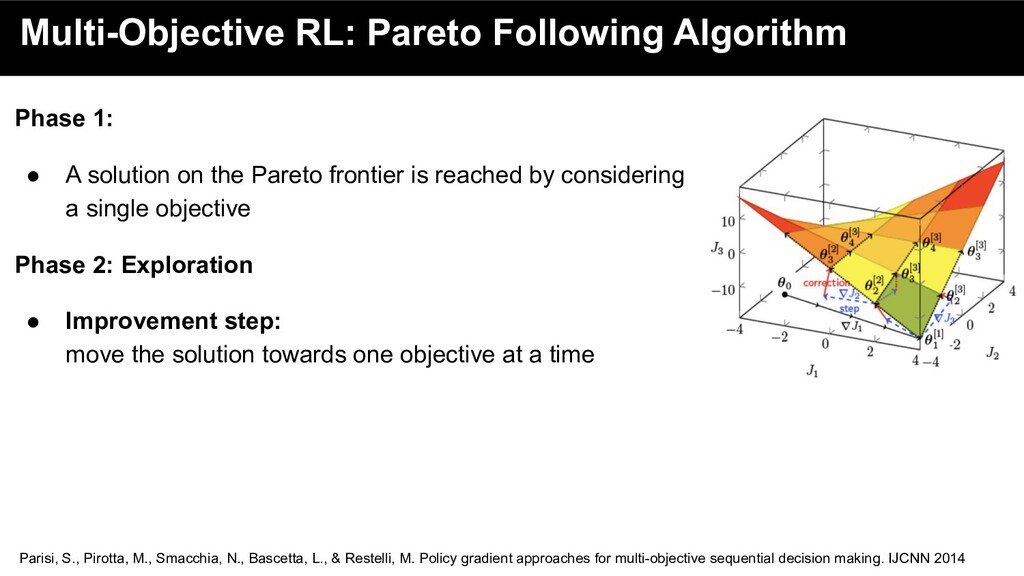
Multi-Objective RL: Pareto Following Algorithm Phase 1: • A solution
on the Pareto frontier is reached by considering a single objective Parisi, S., Pirotta, M., Smacchia, N., Bascetta, L., & Restelli, M. Policy gradient approaches for multi-objective sequential decision making. IJCNN 2014 -
Multi-Objective RL: Pareto Following Algorithm Phase 1: • A solution
on the Pareto frontier is reached by considering a single objective Phase 2: Exploration • Improvement step: move the solution towards one objective at a time Parisi, S., Pirotta, M., Smacchia, N., Bascetta, L., & Restelli, M. Policy gradient approaches for multi-objective sequential decision making. IJCNN 2014 -
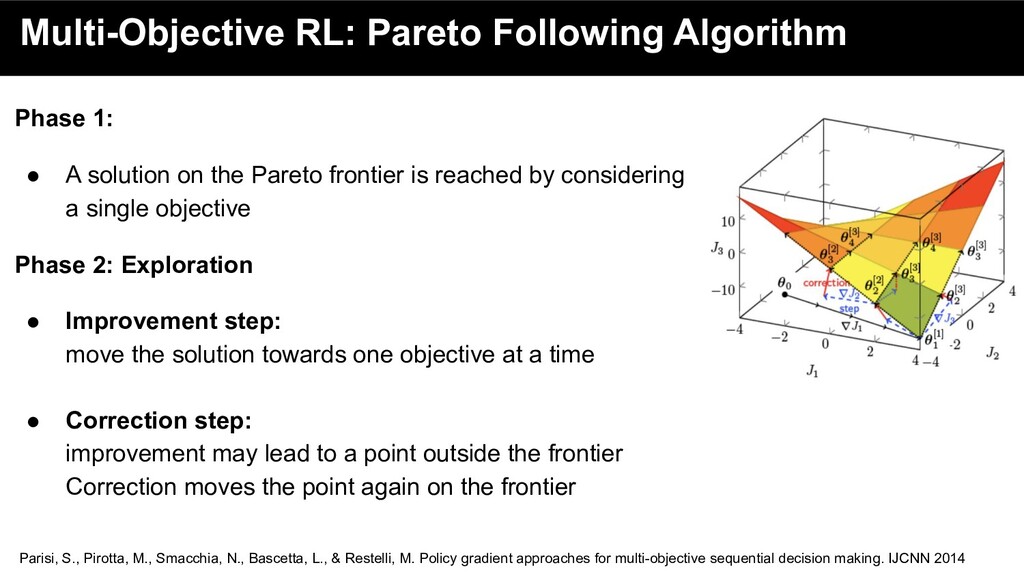
Multi-Objective RL: Pareto Following Algorithm Phase 1: • A solution
on the Pareto frontier is reached by considering a single objective Phase 2: Exploration • Improvement step: move the solution towards one objective at a time • Correction step: improvement may lead to a point outside the frontier Correction moves the point again on the frontier Parisi, S., Pirotta, M., Smacchia, N., Bascetta, L., & Restelli, M. Policy gradient approaches for multi-objective sequential decision making. IJCNN 2014 -
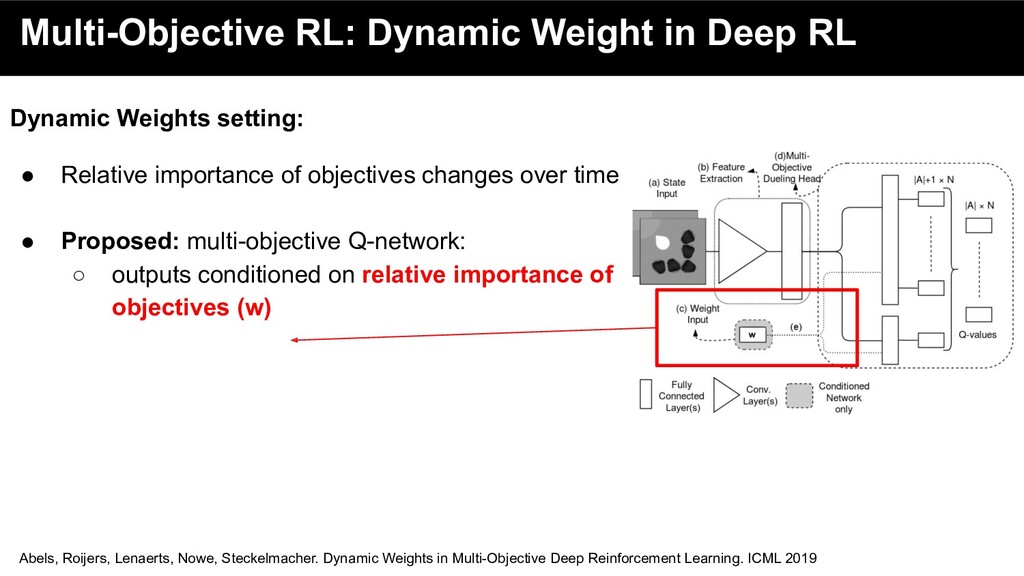
Multi-Objective RL: Dynamic Weight in Deep RL Dynamic Weights setting:
• Relative importance of objectives changes over time Abels, Roijers, Lenaerts, Nowe, Steckelmacher. Dynamic Weights in Multi-Objective Deep Reinforcement Learning. ICML 2019 -
Multi-Objective RL: Dynamic Weight in Deep RL Dynamic Weights setting:
• Relative importance of objectives changes over time Abels, Roijers, Lenaerts, Nowe, Steckelmacher. Dynamic Weights in Multi-Objective Deep Reinforcement Learning. ICML 2019 ICML 2019 -
Multi-Objective RL: Dynamic Weight in Deep RL Dynamic Weights setting:
• Relative importance of objectives changes over time • Proposed: multi-objective Q-network: ◦ outputs conditioned on relative importance of objectives (w) Abels, Roijers, Lenaerts, Nowe, Steckelmacher. Dynamic Weights in Multi-Objective Deep Reinforcement Learning. ICML 2019 -
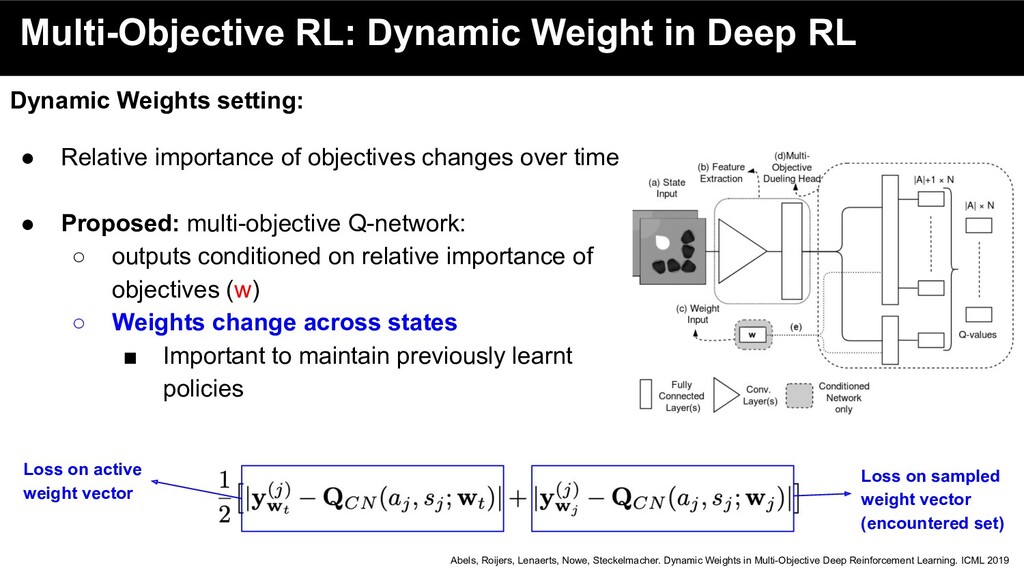
Multi-Objective RL: Dynamic Weight in Deep RL Dynamic Weights setting:
• Relative importance of objectives changes over time • Proposed: multi-objective Q-network: ◦ outputs conditioned on relative importance of objectives (w) ◦ Weights change across states ▪ Important to maintain previously learnt policies Abels, Roijers, Lenaerts, Nowe, Steckelmacher. Dynamic Weights in Multi-Objective Deep Reinforcement Learning. ICML 2019 -
Multi-Objective RL: Dynamic Weight in Deep RL Dynamic Weights setting:
• Relative importance of objectives changes over time • Proposed: multi-objective Q-network: ◦ outputs conditioned on relative importance of objectives (w) ◦ Weights change across states ▪ Important to maintain previously learnt policies Abels, Roijers, Lenaerts, Nowe, Steckelmacher. Dynamic Weights in Multi-Objective Deep Reinforcement Learning. ICML 2019 Loss on active weight vector Loss on sampled weight vector (encountered set) -
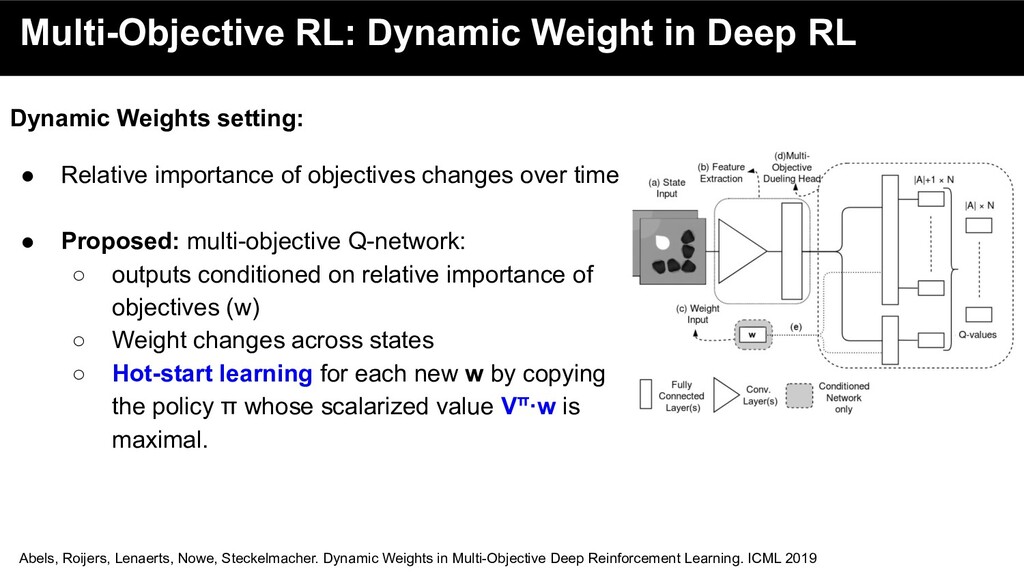
Multi-Objective RL: Dynamic Weight in Deep RL Dynamic Weights setting:
• Relative importance of objectives changes over time • Proposed: multi-objective Q-network: ◦ outputs conditioned on relative importance of objectives (w) ◦ Weight changes across states ◦ Hot-start learning for each new w by copying the policy π whose scalarized value Vπ·w is maximal. Abels, Roijers, Lenaerts, Nowe, Steckelmacher. Dynamic Weights in Multi-Objective Deep Reinforcement Learning. ICML 2019 -
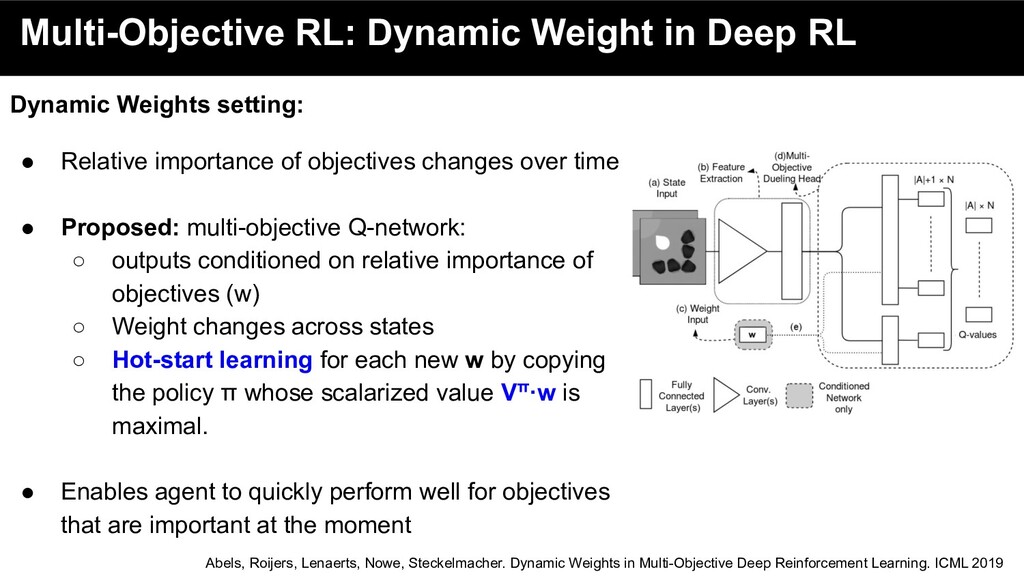
Multi-Objective RL: Dynamic Weight in Deep RL Dynamic Weights setting:
• Relative importance of objectives changes over time • Proposed: multi-objective Q-network: ◦ outputs conditioned on relative importance of objectives (w) ◦ Weight changes across states ◦ Hot-start learning for each new w by copying the policy π whose scalarized value Vπ·w is maximal. • Enables agent to quickly perform well for objectives that are important at the moment Abels, Roijers, Lenaerts, Nowe, Steckelmacher. Dynamic Weights in Multi-Objective Deep Reinforcement Learning. ICML 2019 -
Multi-Objective RL: Useful Resources Multi-Objective Planning & Learning AAMAS 2018
tutorial http://roijers.info/pub/slides_faim.pdf Multi-Objective Reinforcement Learning MORL Lecture Slide - RL course at Univ of Edinburgh http://www.inf.ed.ac.uk/teaching/courses/rl/slides16/rl16.pdf A Survey of Multi-Objective Sequential Decision-Making Journal of AI Research, 2013 https://arxiv.org/pdf/1402.0590.pdf Multiobjective Reinforcement Learning: A Comprehensive Overview. IEEE Transactions on Systems, Man, and Cybernetics, 2015 https://ieeexplore.ieee.org/abstract/document/6918520 -
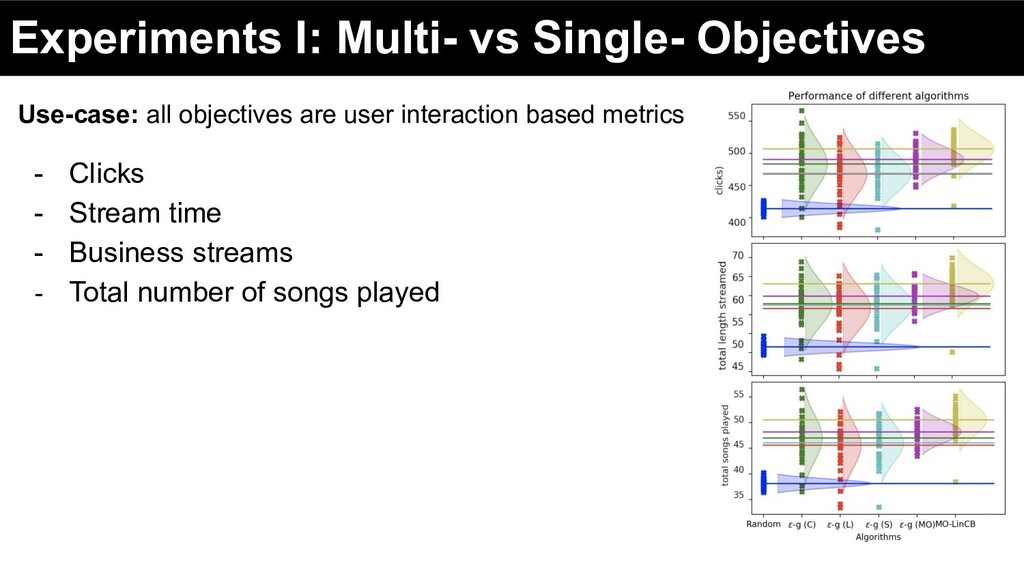
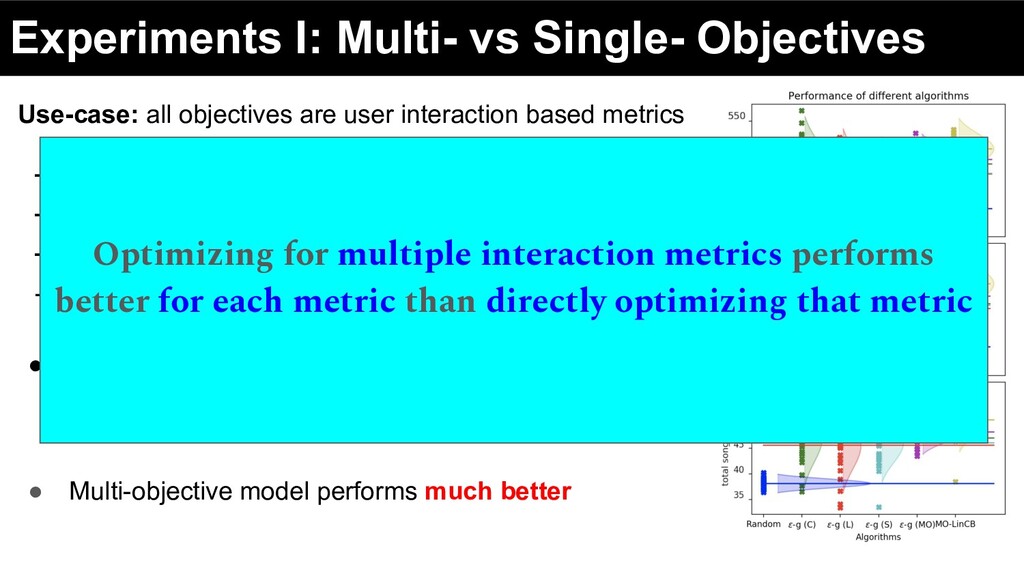
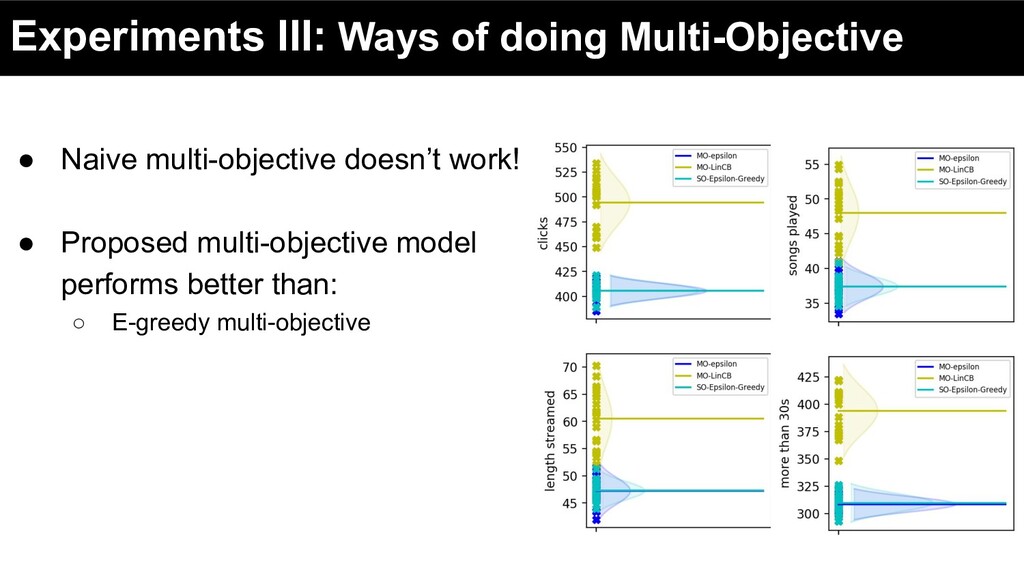
Experiments I: Multi- vs Single- Objectives Use-case: all objectives are
user interaction based metrics - Clicks - Stream time - Business streams - Total number of songs played -
Experiments I: Multi- vs Single- Objectives Use-case: all objectives are
user interaction based metrics - Clicks - Stream time - Business streams - Total number of songs played • Optimizing for different objectives impacts other objectives ◦ If you want more clicks, optimize for clicks -
Experiments I: Multi- vs Single- Objectives Use-case: all objectives are
user interaction based metrics - Clicks - Stream time - Business streams - Total number of songs played • Optimizing for different objectives impacts other objectives ◦ If you want more clicks, optimize for clicks • Multi-objective model performs much better -
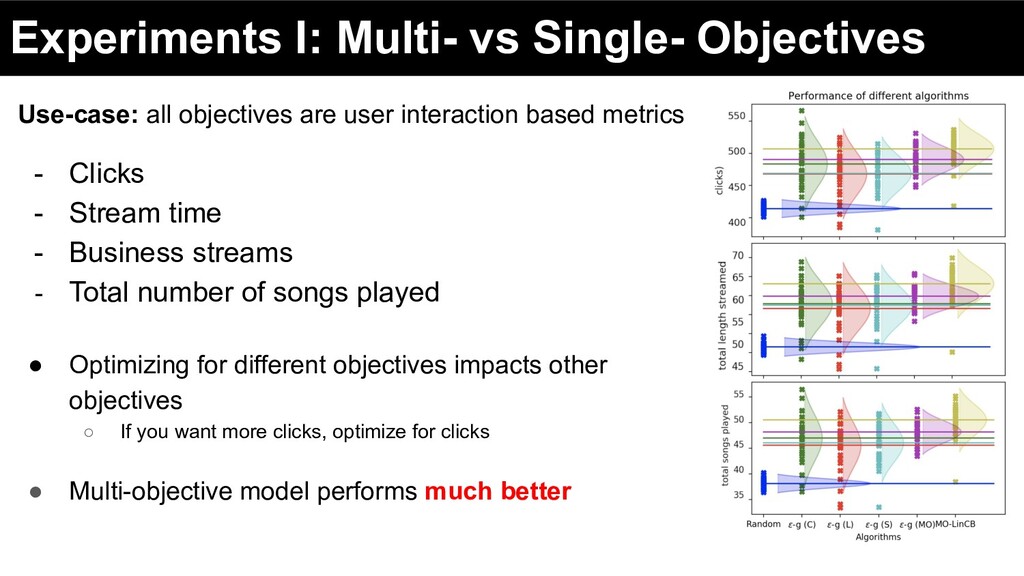
Experiments I: Multi- vs Single- Objectives Use-case: all objectives are
user interaction based metrics - Clicks - Stream time - Business streams - Total number of songs played • Optimizing for different objectives impacts other objectives ◦ If you want more clicks, optimize for clicks • Multi-objective model performs much better Optimizing for multiple interaction metrics performs better for each metric than directly optimizing that metric -
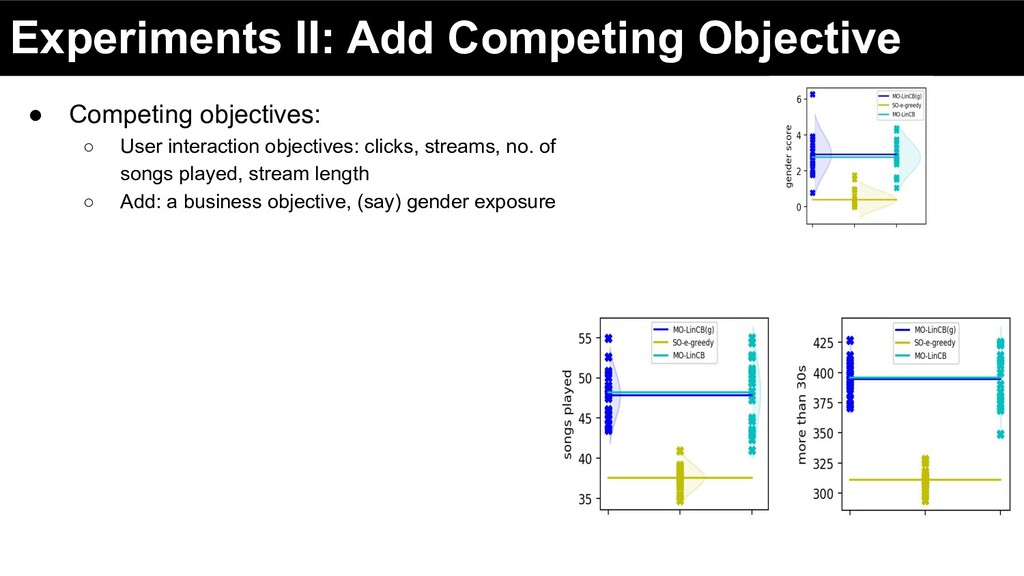
Experiments II: Add Competing Objective • Competing objectives: ◦ User
interaction objectives: clicks, streams, no. of songs played, stream length ◦ Add: a business objective, (say) gender exposure -
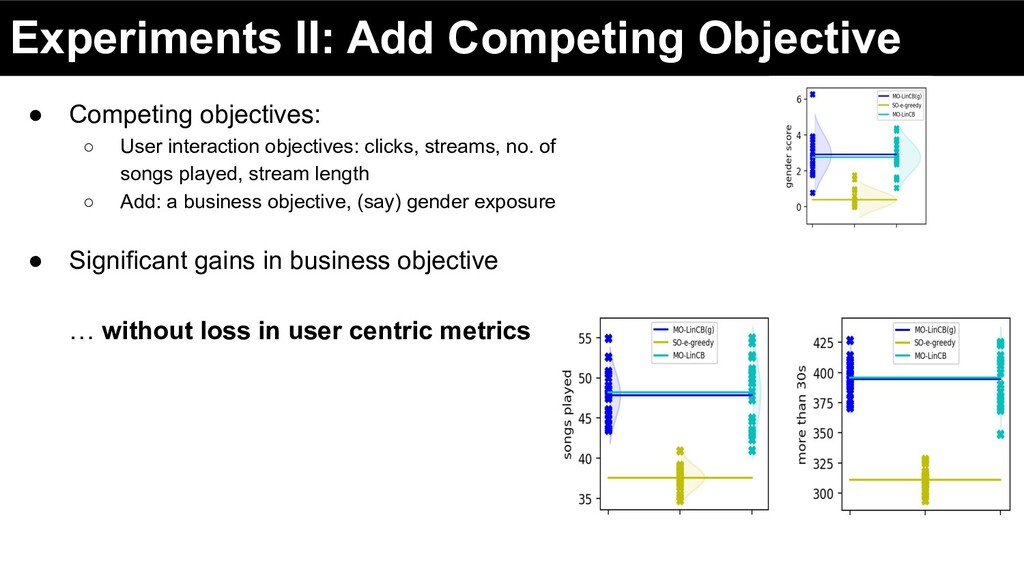
Experiments II: Add Competing Objective • Competing objectives: ◦ User
interaction objectives: clicks, streams, no. of songs played, stream length ◦ Add: a business objective, (say) gender exposure • Significant gains in business objective … without loss in user centric metrics -
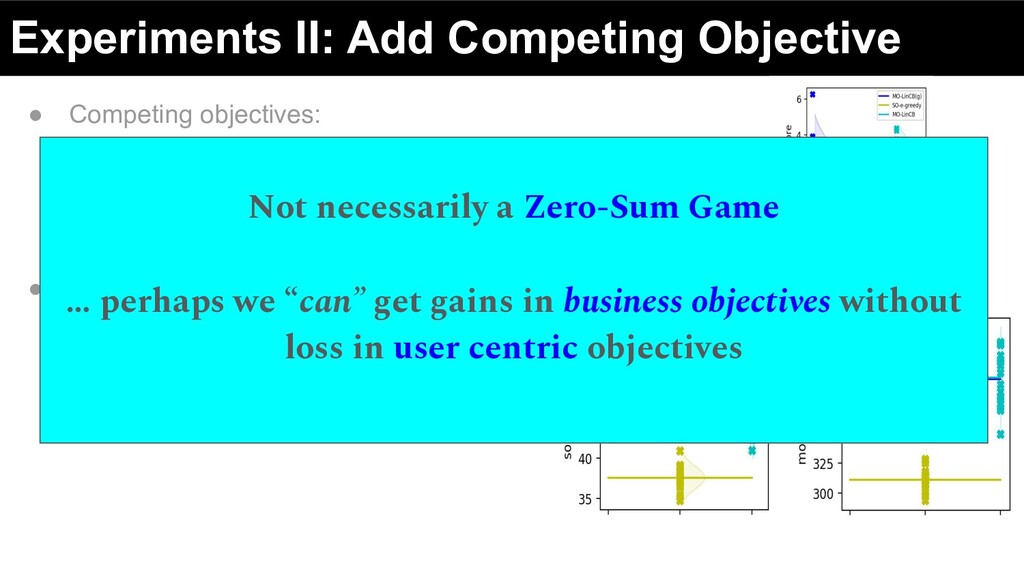
Experiments II: Add Competing Objective • Competing objectives: ◦ User
interaction objectives: clicks, streams, no. of songs played, stream length ◦ Add: a business objective, (say) gender exposure • Significant gains in business objective … without loss in user centric metrics Not necessarily a Zero-Sum Game … perhaps we “can” get gains in business objectives without loss in user centric objectives -
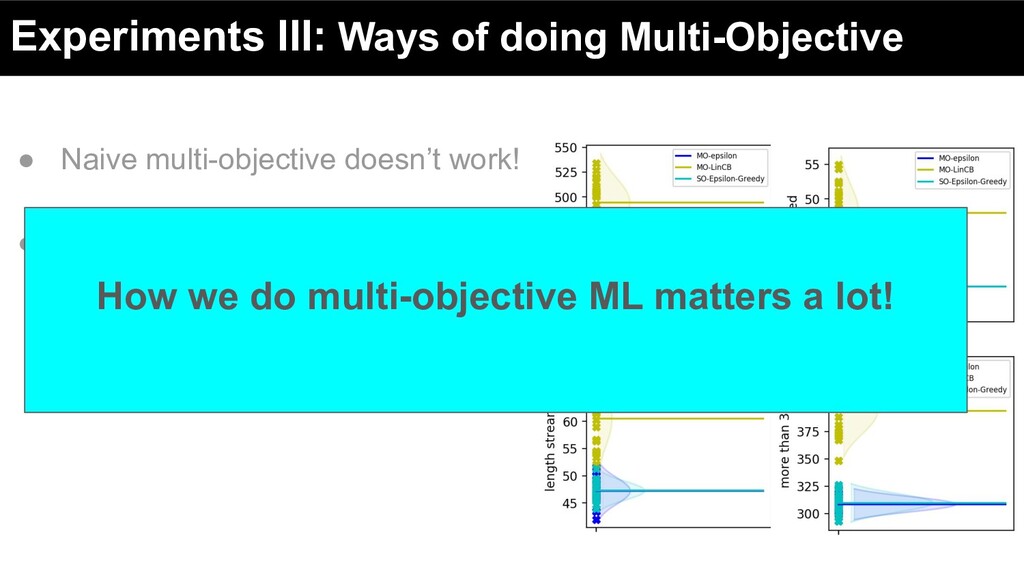
Experiments III: Ways of doing Multi-Objective • Naive multi-objective doesn’t
work! • Proposed multi-objective model performs better than: ◦ Ε-greedy multi-objective -
Experiments III: Ways of doing Multi-Objective • Naive multi-objective doesn’t
work! • Proposed multi-objective model performs better than: ◦ Ε-greedy multi-objective How we do multi-objective ML matters a lot! -
Part III: Methods for Multi-Objective Recommendation What is a task
& why are they important? Characterizing Tasks across interfaces: desktop search digital assistants voice-only assistants Understanding User Tasks in Web Search Extracting Query Intents Queries → Sessions → Tasks Search Task Understanding Task extraction Subtask extraction Hierarchies of tasks & subtasks Evaluating task extraction algorithms Recommendation Systems Case study: Pinterest Case study: Spotify • – – – – • • -
Schedule 08:00 - 08:10: Welcome + Introduction 08:10 - 08:30:
Part I: Introduction to Marketplaces 08:30 - 09:00: Part II: Optimization Objectives in a Marketplace 09:00 - 09:30: Part III: Methods for Multi-Objective Recommendations 09:40 - 10:10: Break 10:00 - 10:30: Part III: Methods for Multi-Objective Recommendations 10:30 - 11:10: Part IV: Leveraging Consumer, Supplier & Content Understanding 11:10 - 11:40: Part V: Industrial Applications 11:40 - 11:50: Questions & Discussions
 erishabh
 visional_engineering_and_design
 ssakita
 itosoft
 inariku
 iwamot
 tsukuboshi
 sioncojp
 kamadamakoto
 yuutosi
 tkito
 jnunemaker
 cassininazir
 techseoconnect
 tmiket
 reverentgeek
 rkendrick25
 hatefulcrawdad
 mfonobong
 inesmontani
 jonyablonski
 nmsamuel
 caitiem20