Upgrade to Pro — share decks privately, control downloads, hide ads and more …

How to find content opportunities beyond keywor...

How to find content opportunities beyond keyword research

Most SEOs rely on tools like Ahrefs for content gap analysis, but keyword research misses crucial context. In this talk, Frank walks through use cases using gap analysis to reveal missed organic opportunities. Frank will show how to leverage audience intent data and entity relationships to uncover content gaps traditional tools overlook, leaving the audience with a practical, step-by-step framework to take home.

Avatar for Frank van Dijk

Frank van Dijk

October 05, 2026

More Decks by Frank van Dijk

Other Decks in Marketing & SEO

Transcript

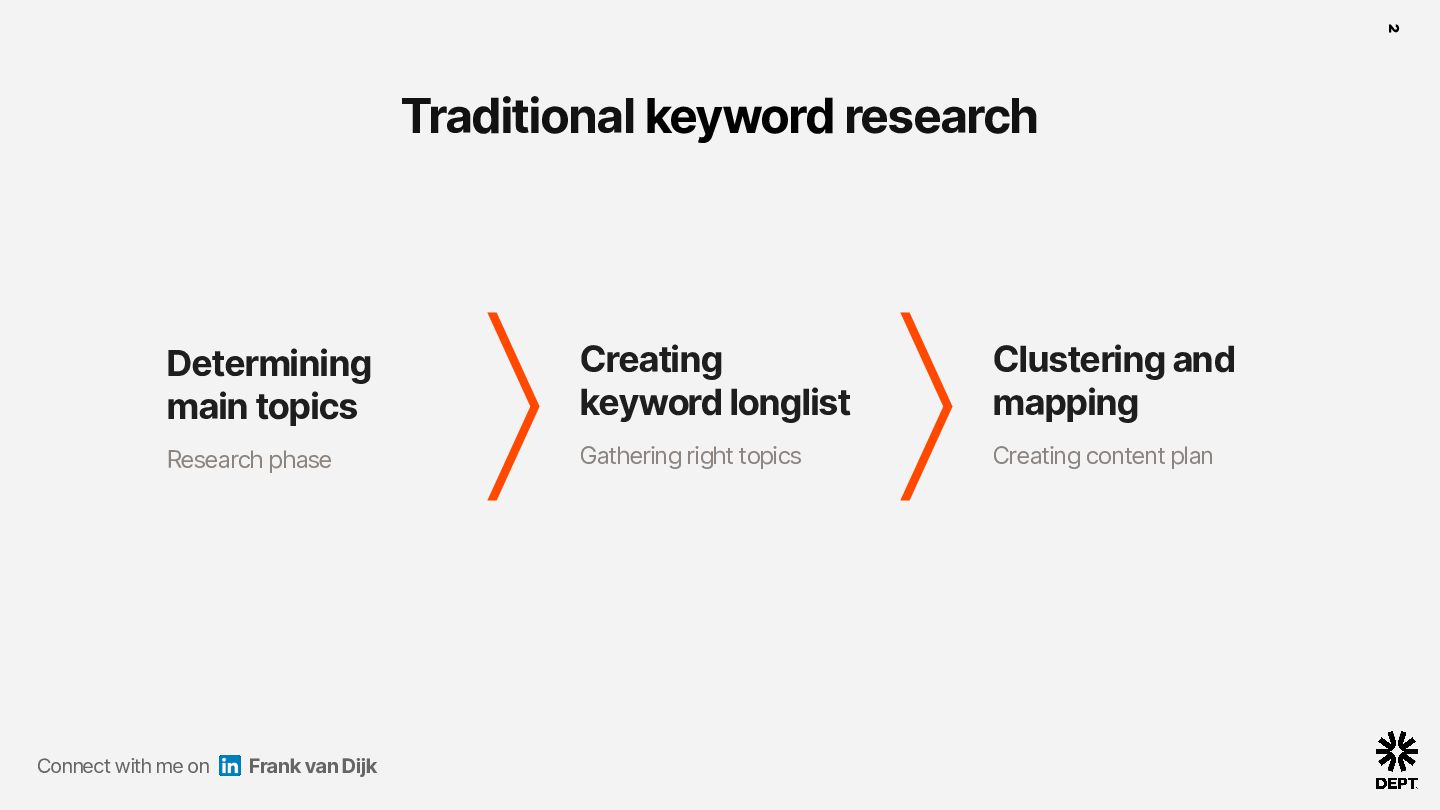
  1. 2 Traditional keyword research Determining main topics Creating keyword longlist

    Clustering and mapping Research phase Gathering right topics Creating content plan Connect with me on Frank van Dijk
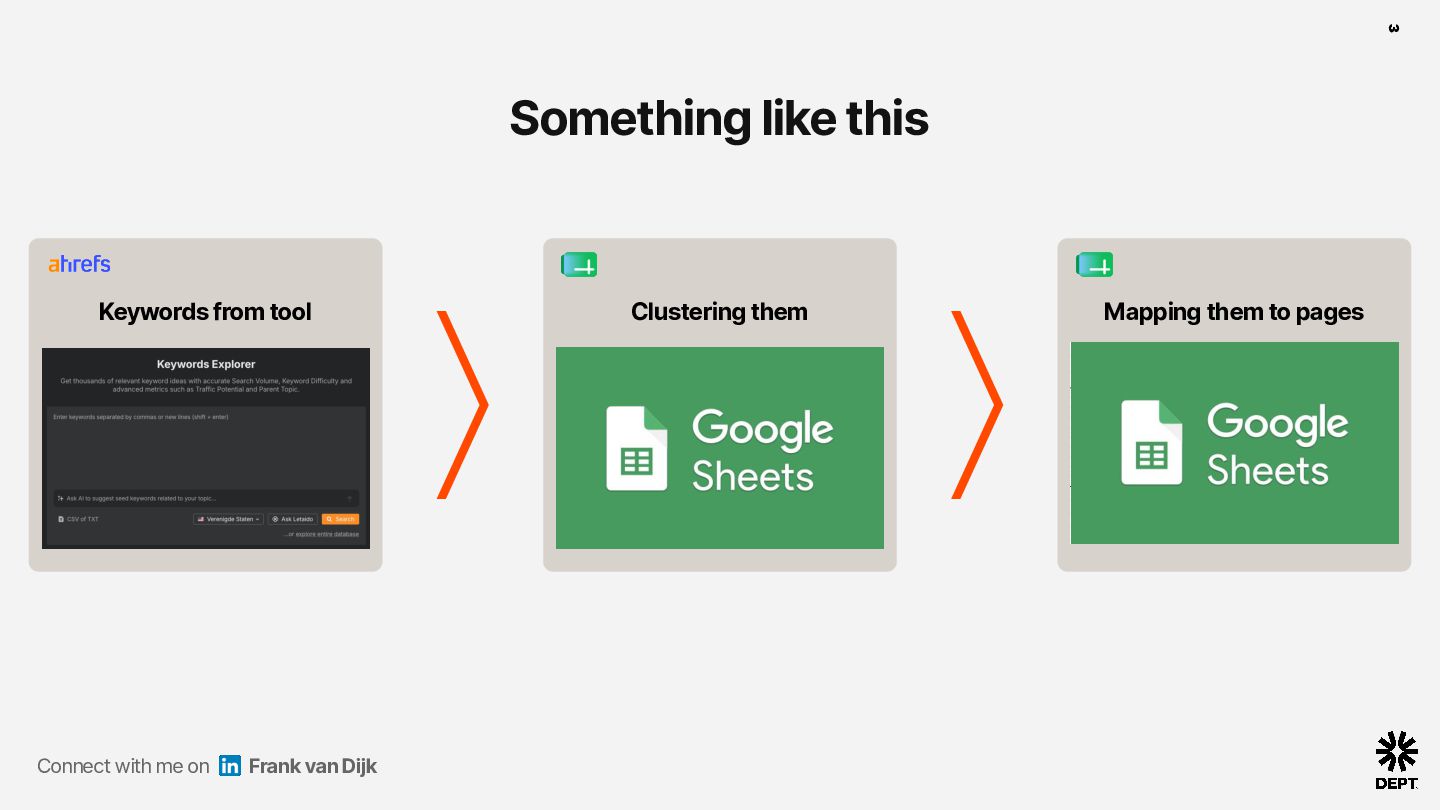
  2. 3 Something like this Keywords from tool Connect with me

    on Frank van Dijk Clustering them Mapping them to pages
  3. 4 The problem is, weʼre all looking at the same

    data Connect with me on Frank van Dijk
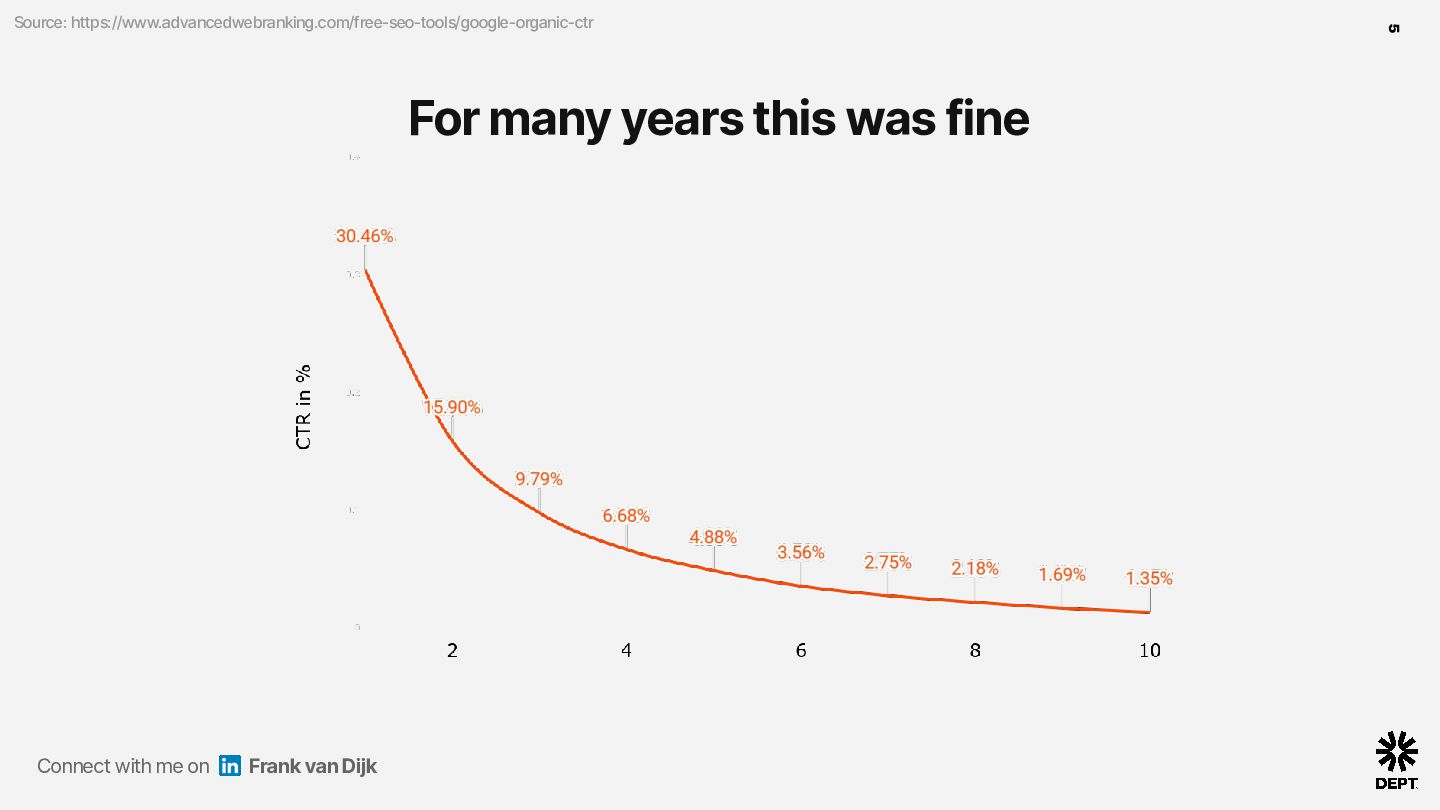
  4. For many years this was fine Connect with me on

    Frank van Dijk 5 Source: https://www.advancedwebranking.com/free-seo-tools/google-organic-ctr
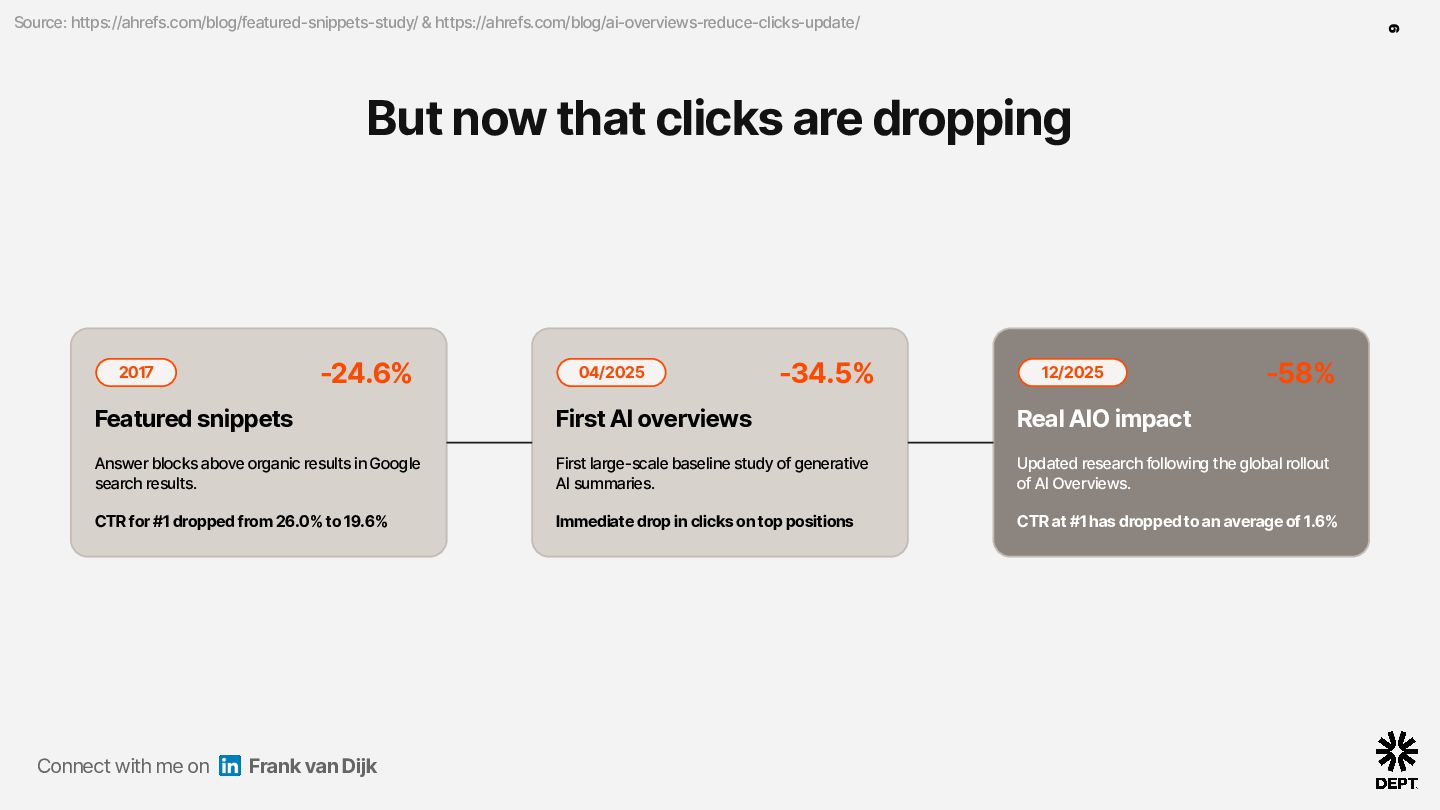
  5. 6 Source: https://ahrefs.com/blog/featured-snippets-study/ & https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/ But now that clicks are

    dropping -24.6% 2017 04/2025 -34.5% 12/2025 -58% Featured snippets First AI overviews Real AIO impact Answer blocks above organic results in Google search results. First large-scale baseline study of generative AI summaries. Updated research following the global rollout of AI Overviews. CTR for #1 dropped from 26.0% to 19.6% Immediate drop in clicks on top positions CTR at #1 has dropped to an average of 1.6% Connect with me on Frank van Dijk
  6. 8 These tools are just the tip of the iceberg

    Connect with me on Frank van Dijk
  7. 9 Iʼm gonna show you how to find those alternative

    content opportunities to beat your competition Connect with me on Frank van Dijk
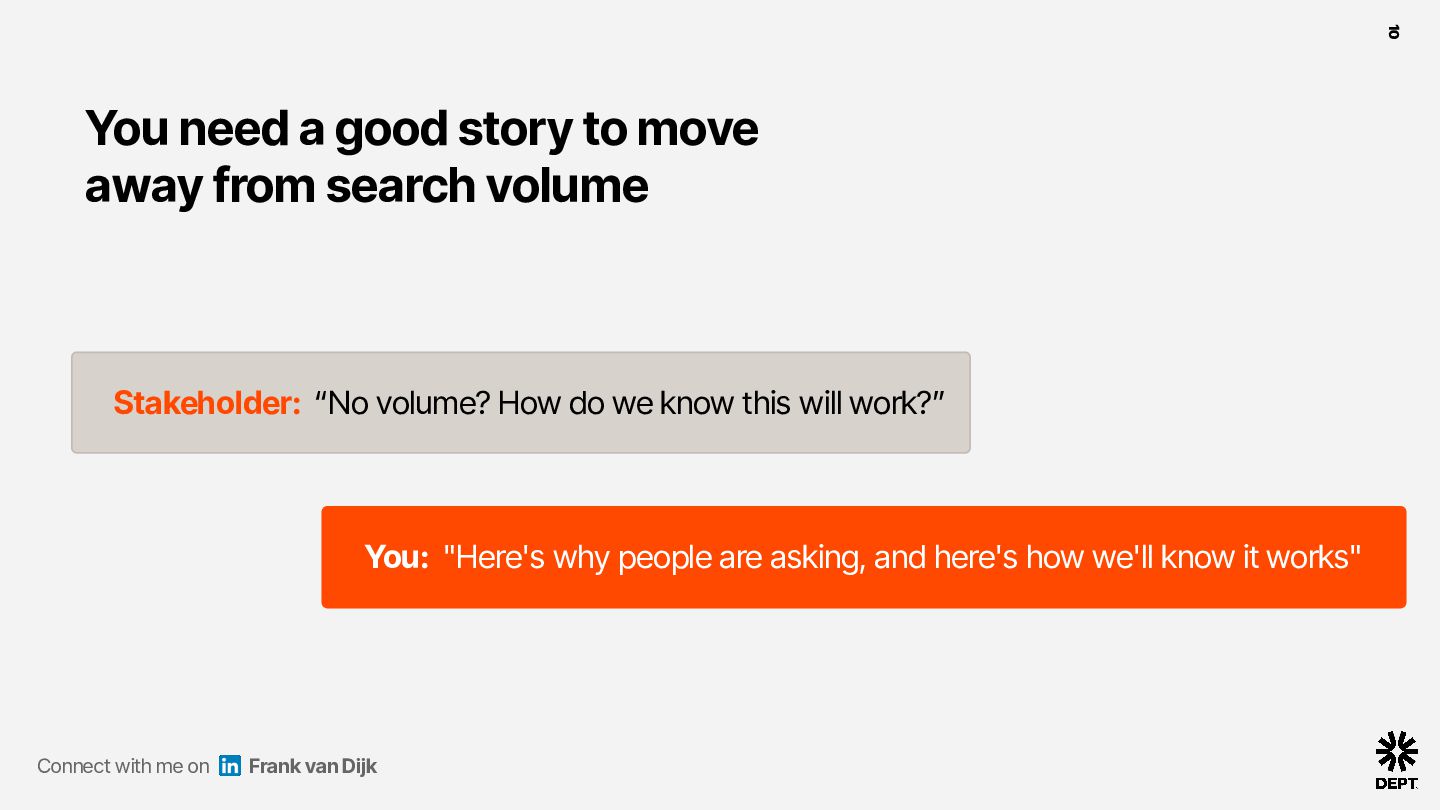
  8. 10 You need a good story to move away from

    search volume Stakeholder: “No volume? How do we know this will work?” You: "Here's why people are asking, and here's how we'll know it works" Connect with me on Frank van Dijk
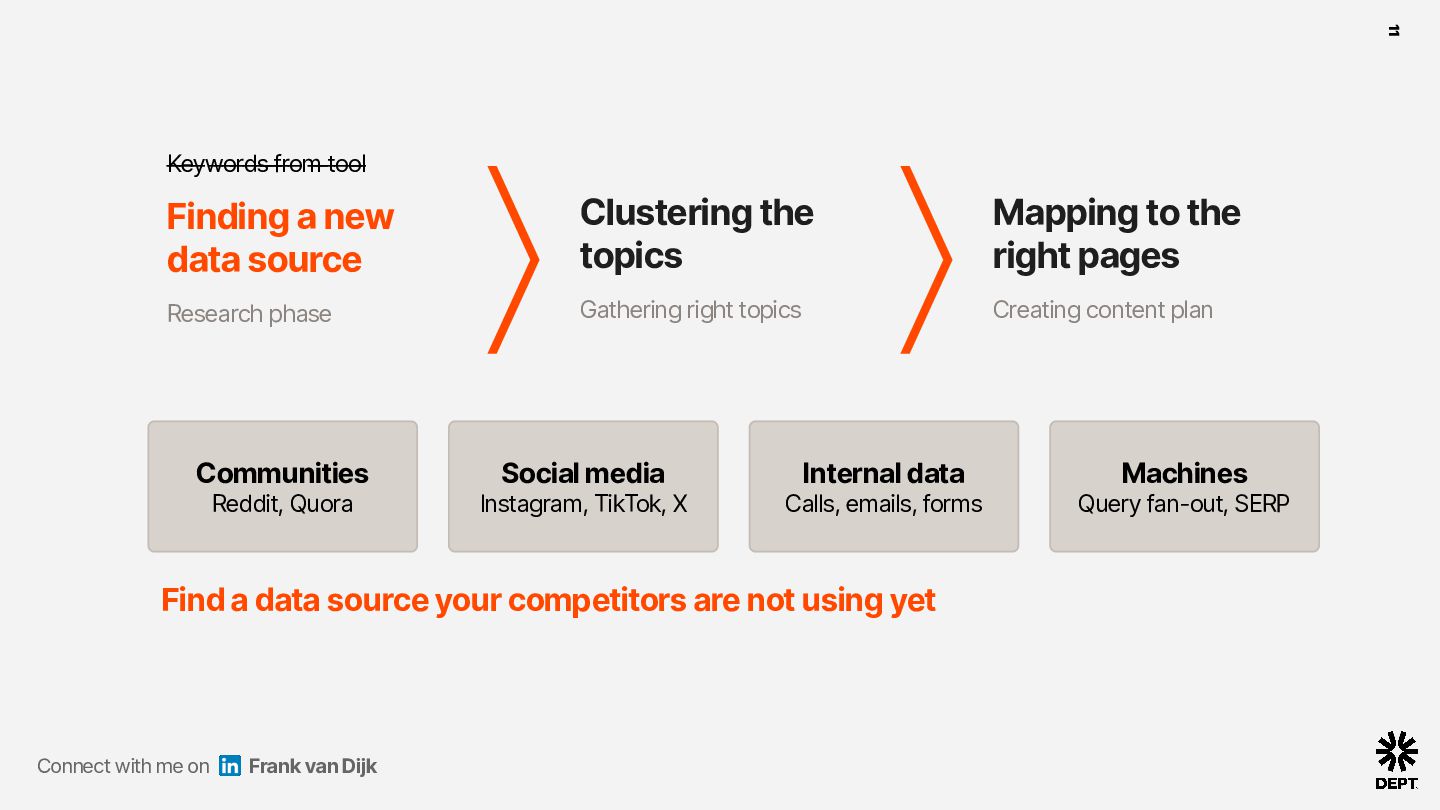
  9. 11 K̶e̶y̶w̶o̶r̶d̶s̶ ̶f̶r̶o̶m̶ ̶t̶o̶o̶l̶ Finding a new data source Clustering

    the topics Mapping to the right pages Research phase Gathering right topics Creating content plan Communities Reddit, Quora Social media Instagram, TikTok, X Internal data Calls, emails, forms Find a data source your competitors are not using yet Connect with me on Frank van Dijk Machines Query fan-out, SERP
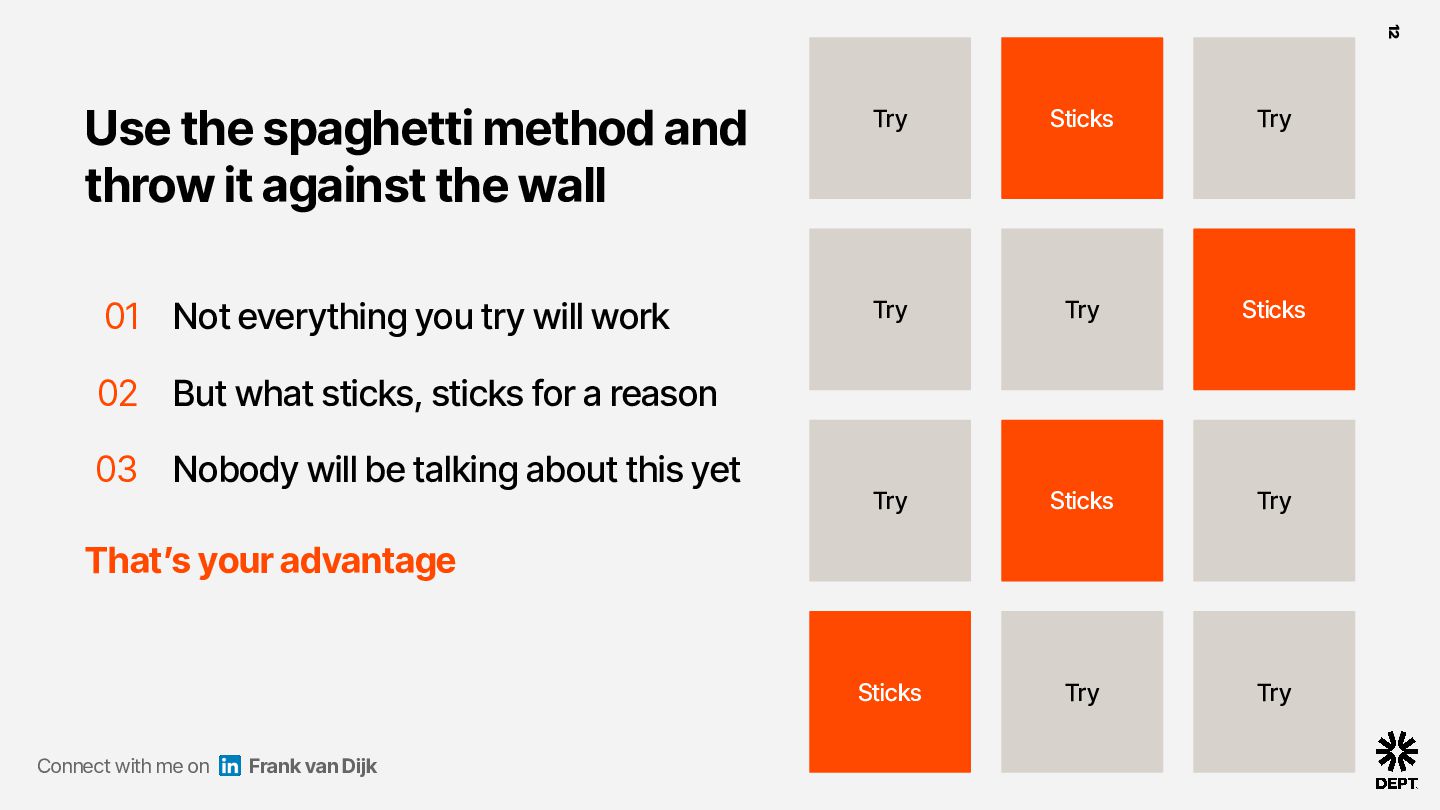
  10. 12 Use the spaghetti method and throw it against the

    wall 01 Not everything you try will work Try Sticks Try Try Try Sticks Try Sticks Try Sticks Try Try 02 But what sticks, sticks for a reason 03 Nobody will be talking about this yet Thatʼs your advantage Connect with me on Frank van Dijk
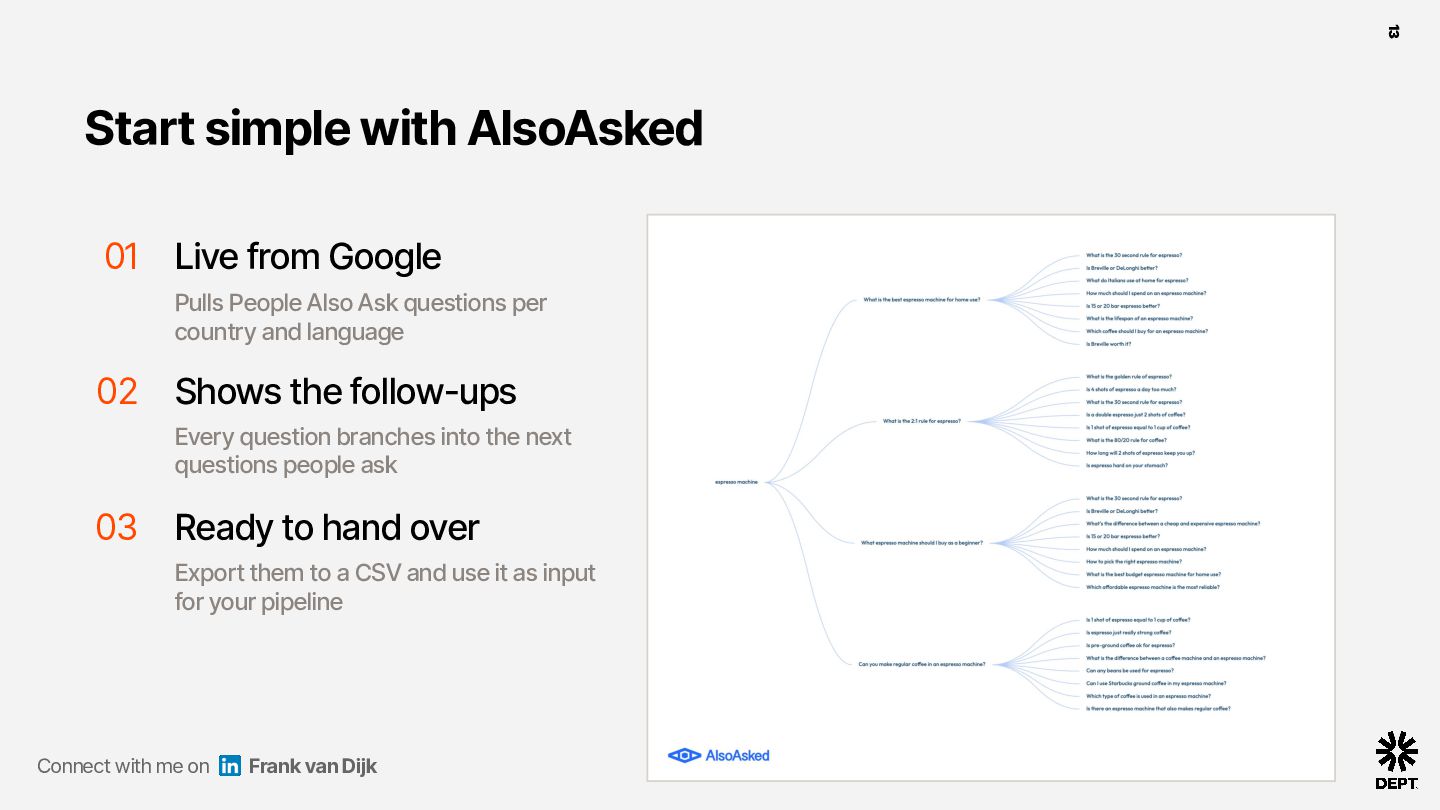
  11. 13 Start simple with AlsoAsked 01 Live from Google Pulls

    People Also Ask questions per country and language 02 Shows the follow-ups Every question branches into the next questions people ask 03 Ready to hand over Export them to a CSV and use it as input for your pipeline Connect with me on Frank van Dijk
  12. 14 We should love Reddit Reddit is a pure form

    of user-generated content 01 Reddit is very accessible for people 02 People discuss anything and everything 03 And theyʼre brutally honest about it Connect with me on Frank van Dijk
  13. 15 Meanwhile on Reddit: “is it normal that my €600

    espresso machine makes me anxious every single morning?” r/espresso - 847 upvotes - 212 comments Connect with me on Frank van Dijk
  14. 16 People type keywords into Google, but theyʼll tell the

    truth on Reddit “Espresso machine problem” “why does mine taste sour and am I an idiot for buying it” Clean, composed Doubt, emotion, the actual need Connect with me on Frank van Dijk
  15. 17 You choose where to listen, not what you wanna

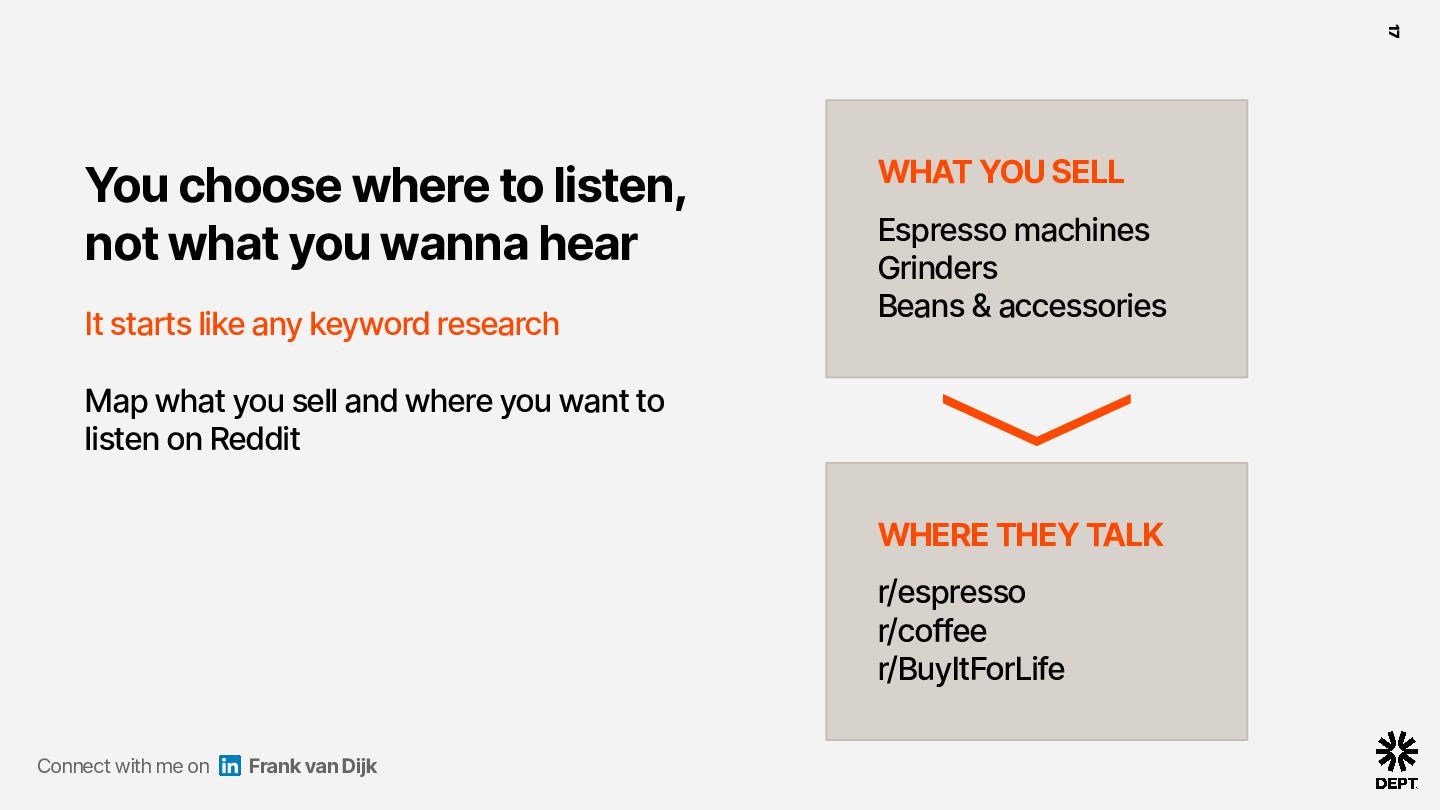
    hear It starts like any keyword research WHAT YOU SELL Espresso machines Grinders Beans & accessories Map what you sell and where you want to listen on Reddit WHERE THEY TALK r/espresso r/coffee r/BuyItForLife Connect with me on Frank van Dijk
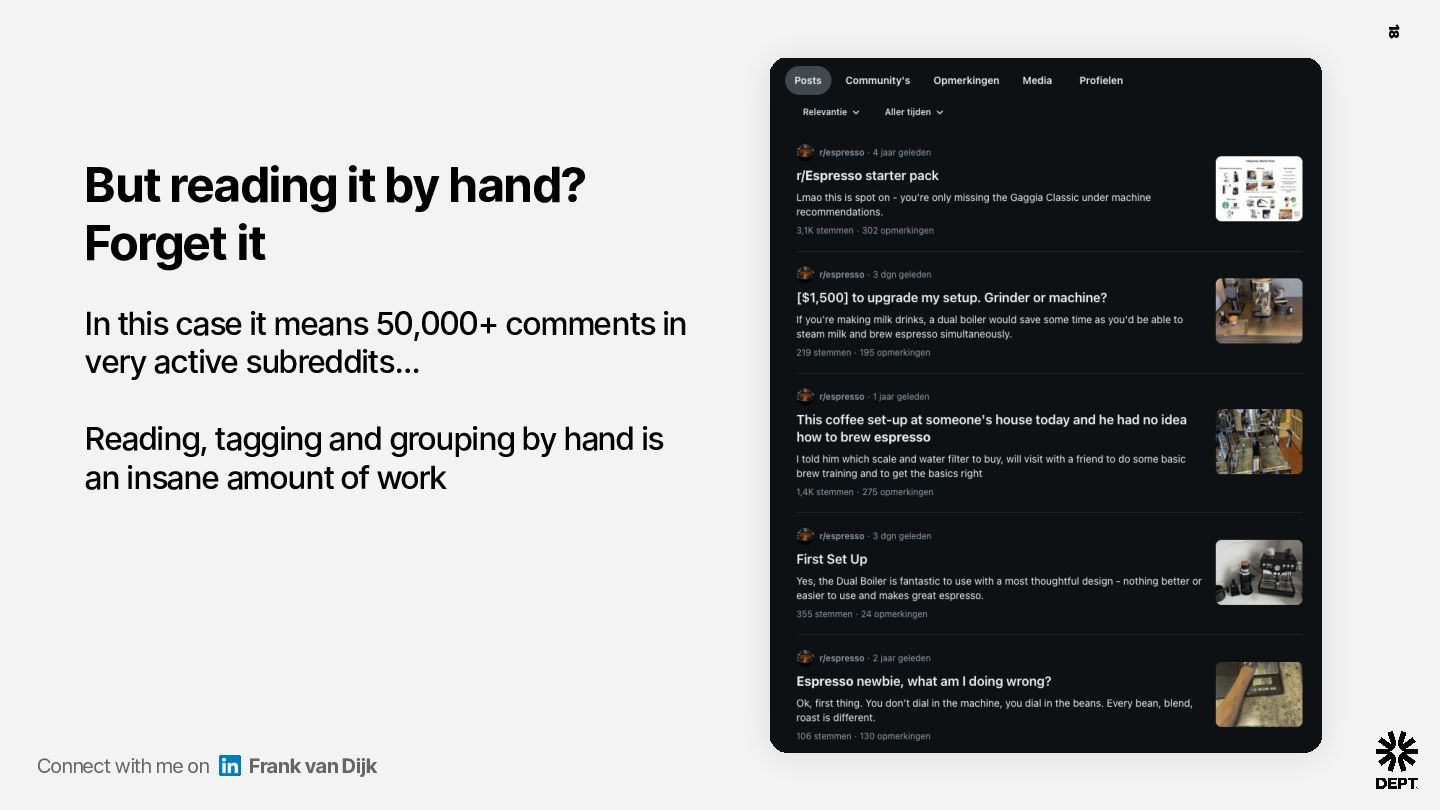
  16. 18 But reading it by hand? Forget it In this

    case it means 50,000+ comments in very active subreddits… Reading, tagging and grouping by hand is an insane amount of work Connect with me on Frank van Dijk
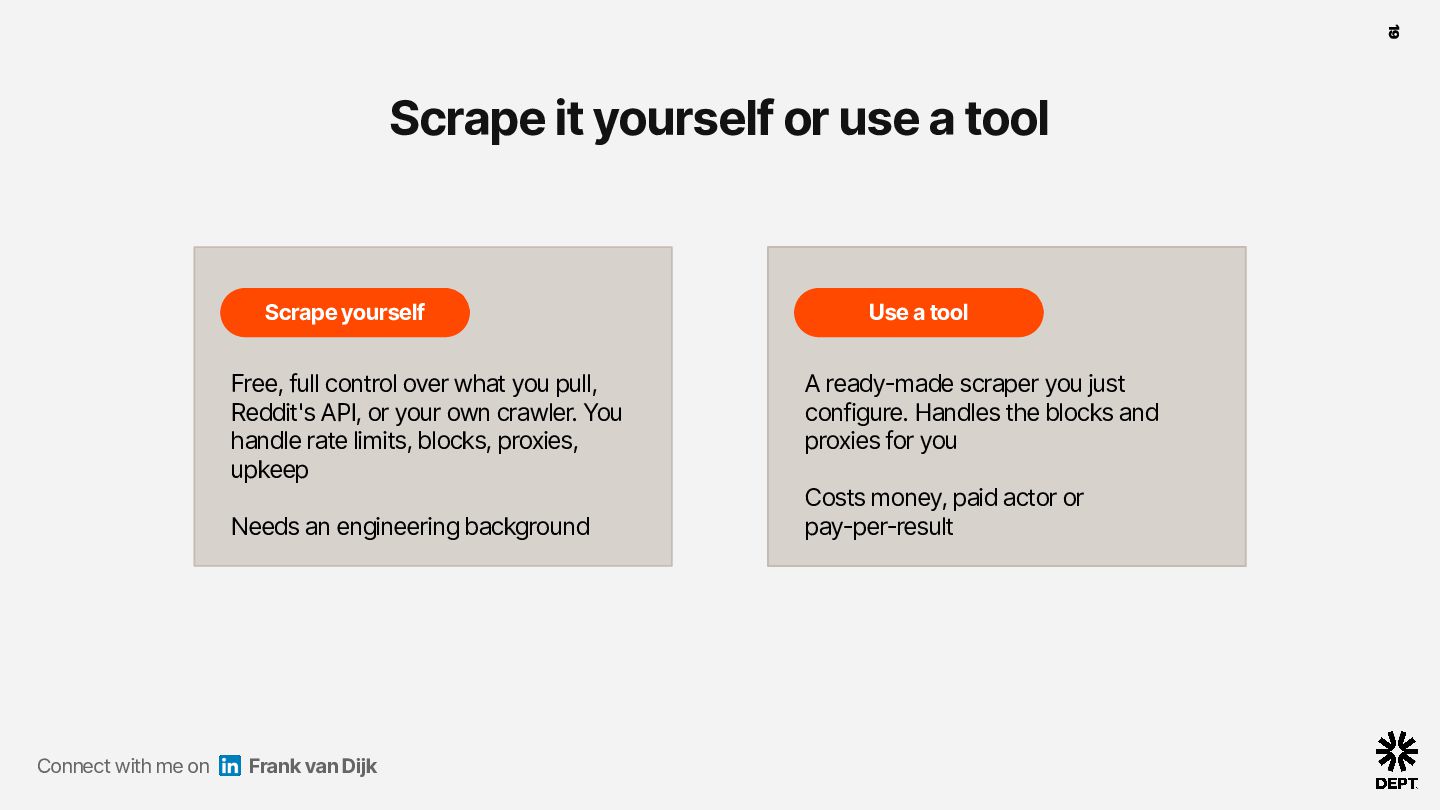
  17. 19 Scrape it yourself or use a tool Scrape yourself

    Free, full control over what you pull, Reddit's API, or your own crawler. You handle rate limits, blocks, proxies, upkeep Needs an engineering background Connect with me on Frank van Dijk Use a tool A ready-made scraper you just configure. Handles the blocks and proxies for you Costs money, paid actor or pay-per-result
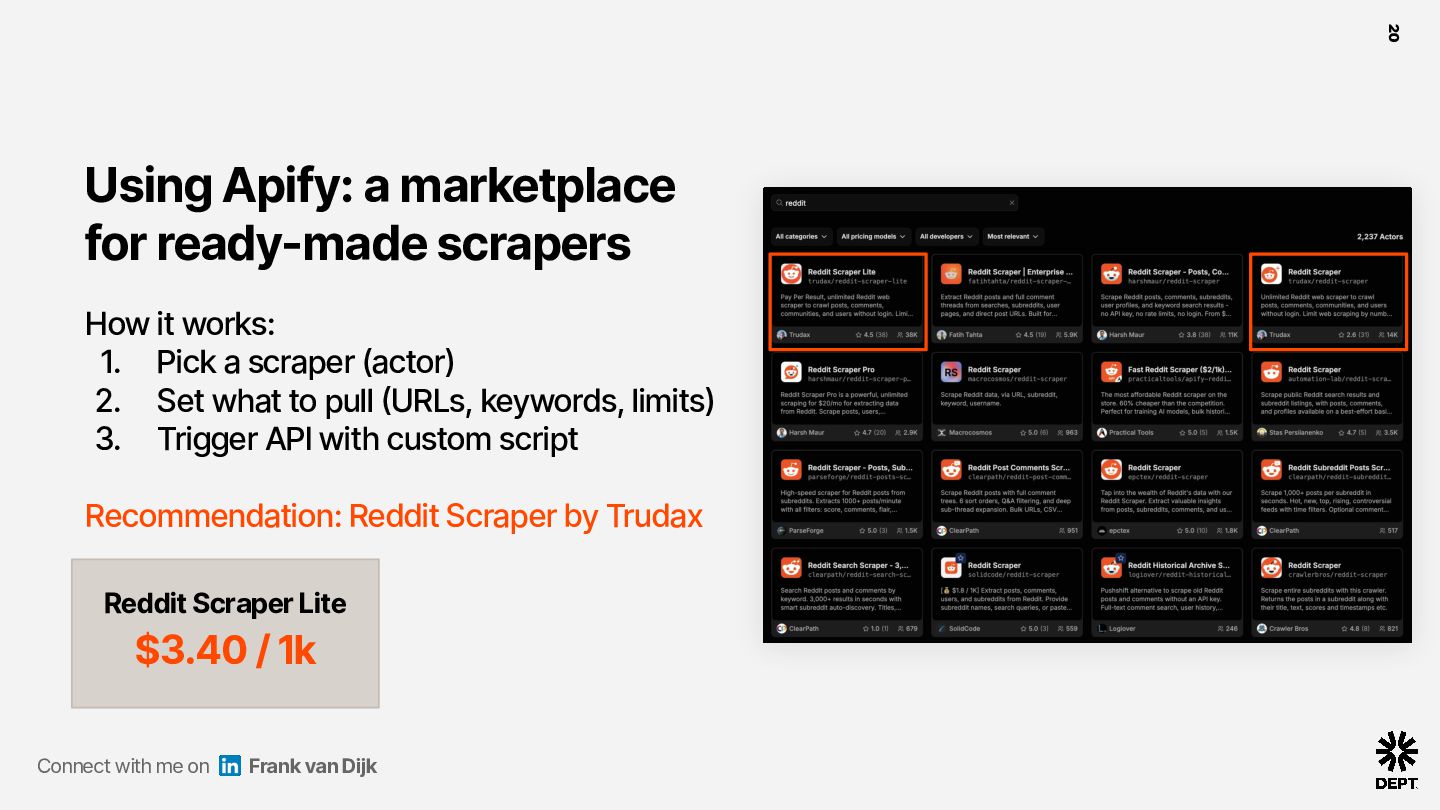
  18. 20 Using Apify: a marketplace for ready-made scrapers How it

    works: 1. Pick a scraper (actor) 2. Set what to pull (URLs, keywords, limits) 3. Trigger API with custom script Recommendation: Reddit Scraper by Trudax Reddit Scraper Lite $3.40 / 1k Connect with me on Frank van Dijk
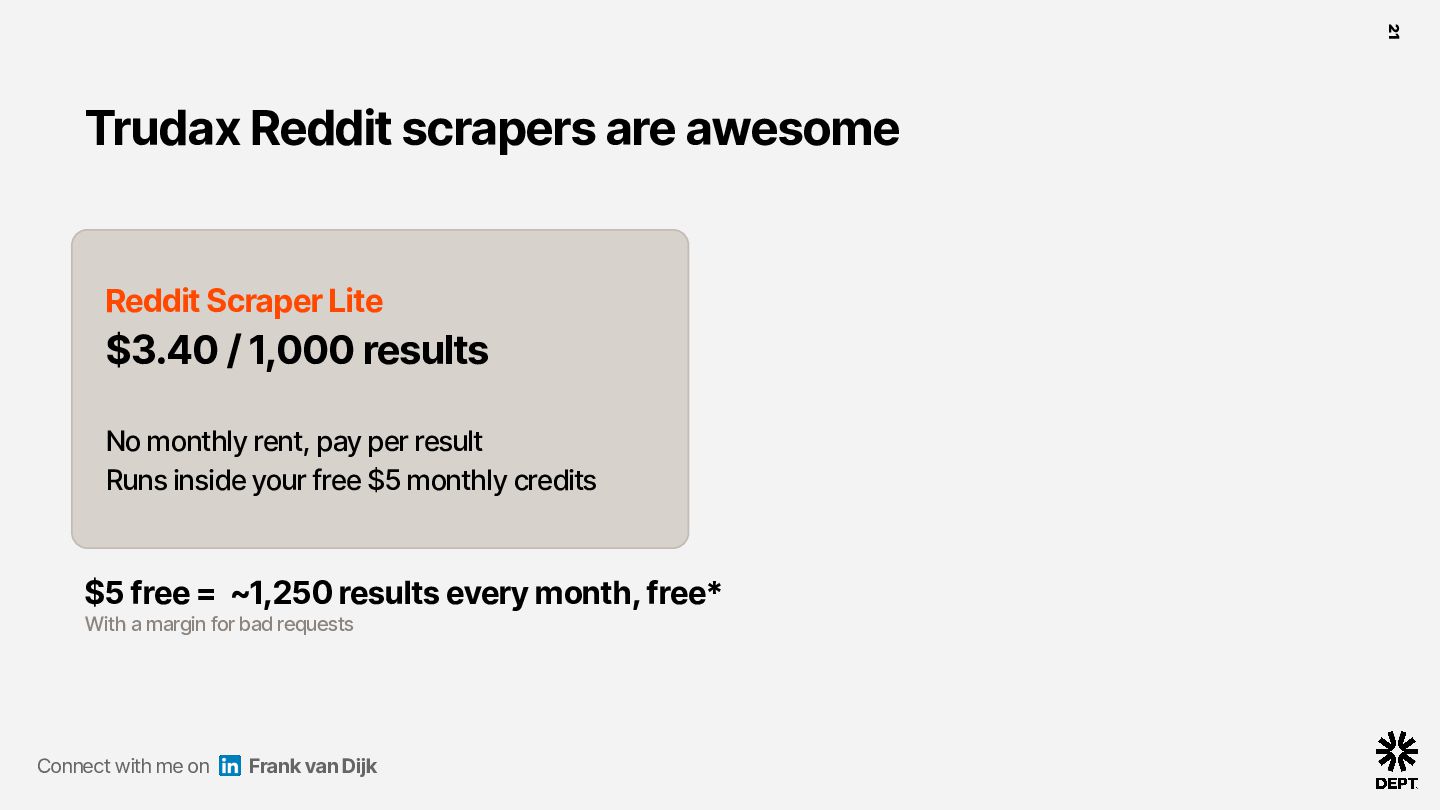
  19. 21 Trudax Reddit scrapers are awesome Reddit Scraper Lite $3.40

    / 1,000 results No monthly rent, pay per result Runs inside your free $5 monthly credits $5 free = ~1,250 results every month, free* With a margin for bad requests Connect with me on Frank van Dijk
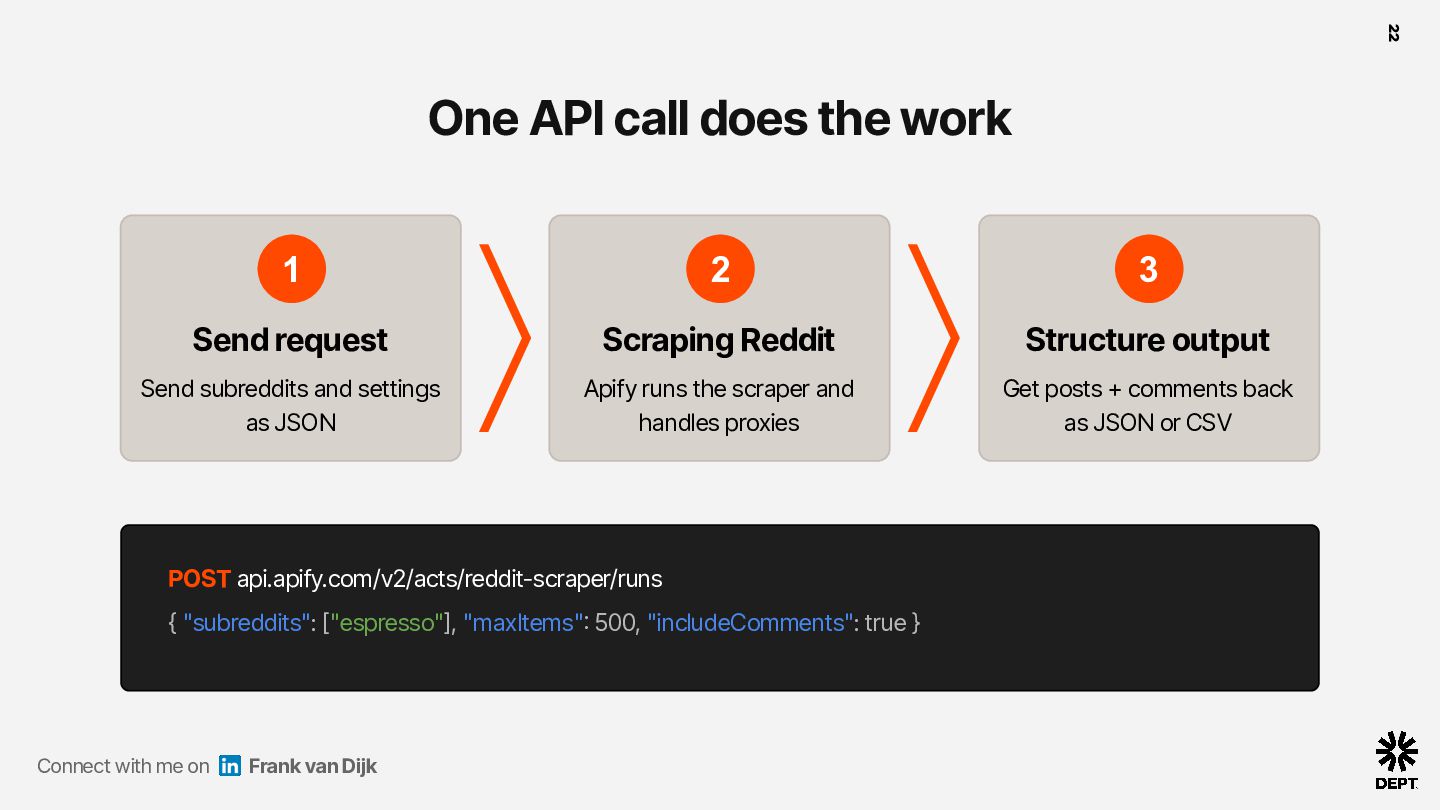
  20. 22 One API call does the work 1 2 3

    Send request Scraping Reddit Structure output Send subreddits and settings as JSON Apify runs the scraper and handles proxies Get posts + comments back as JSON or CSV POST api.apify.com/v2/acts/reddit-scraper/runs { "subreddits": ["espresso"], "maxItems": 500, "includeComments": true } Connect with me on Frank van Dijk
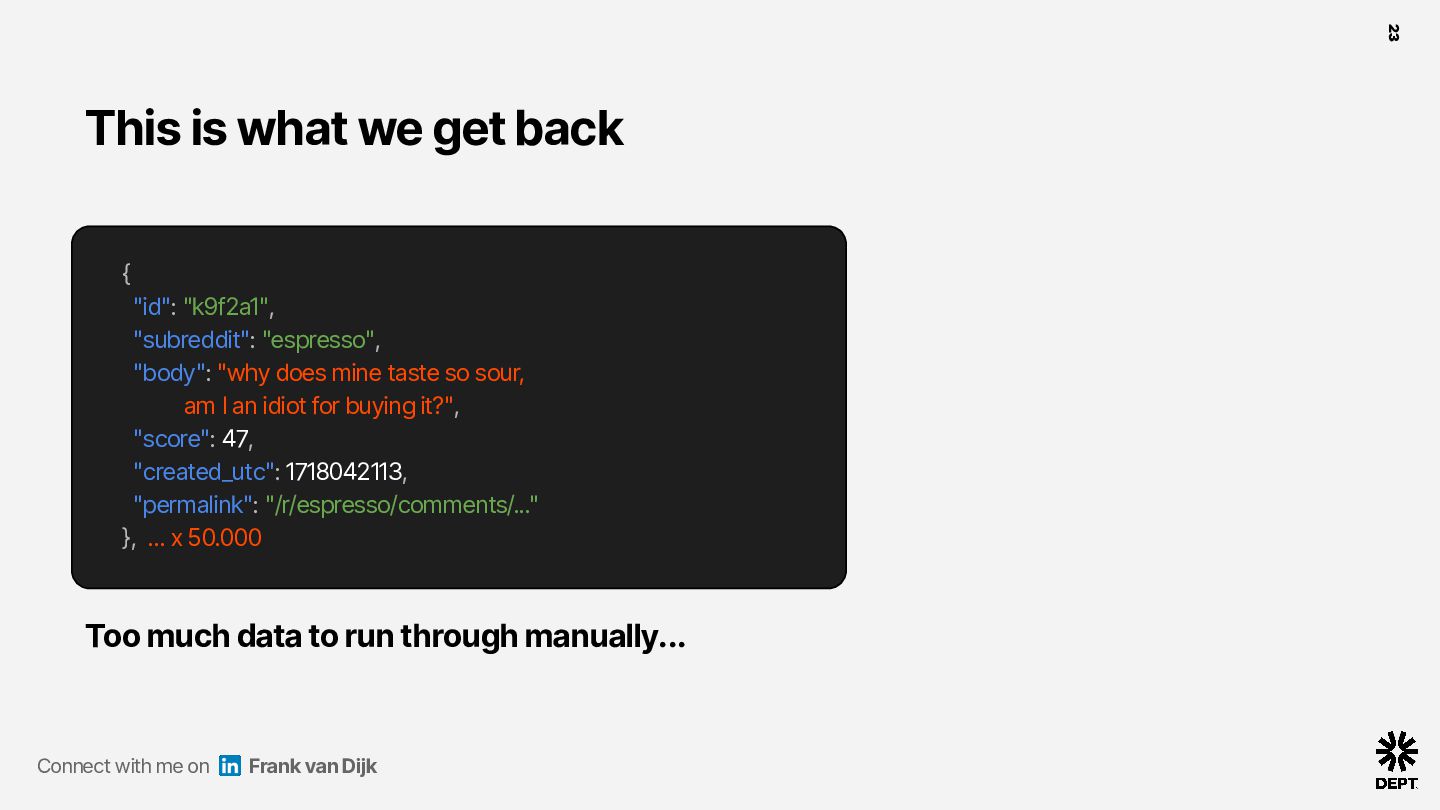
  21. 23 This is what we get back { "id": "k9f2a1",

    "subreddit": "espresso", "body": "why does mine taste so sour, am I an idiot for buying it?", "score": 47, "created_utc": 1718042113, "permalink": "/r/espresso/comments/..." }, ... x 50.000 Too much data to run through manually... Connect with me on Frank van Dijk
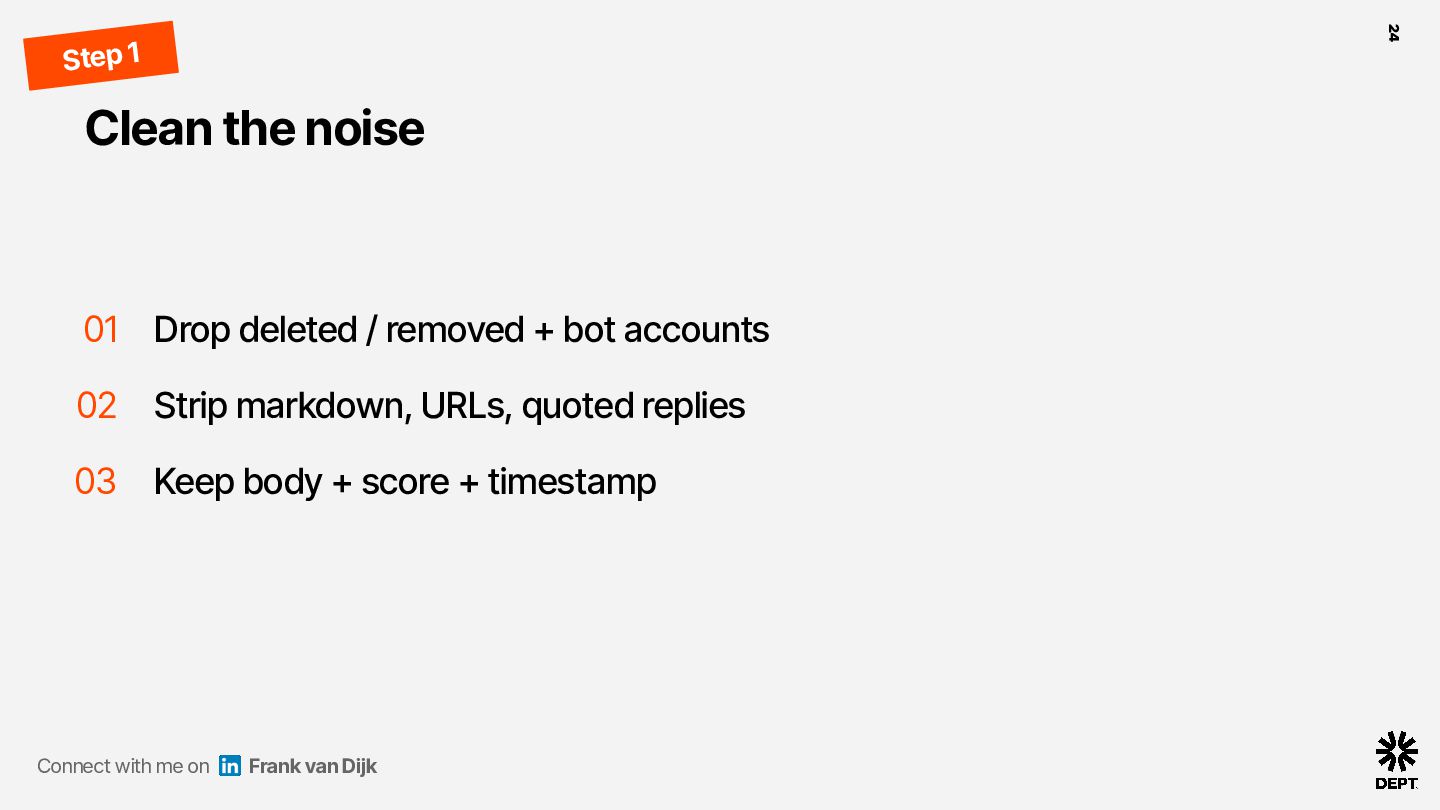
  22. 24 Step 1 Clean the noise 01 Drop deleted /

    removed + bot accounts 02 Strip markdown, URLs, quoted replies 03 Keep body + score + timestamp Connect with me on Frank van Dijk
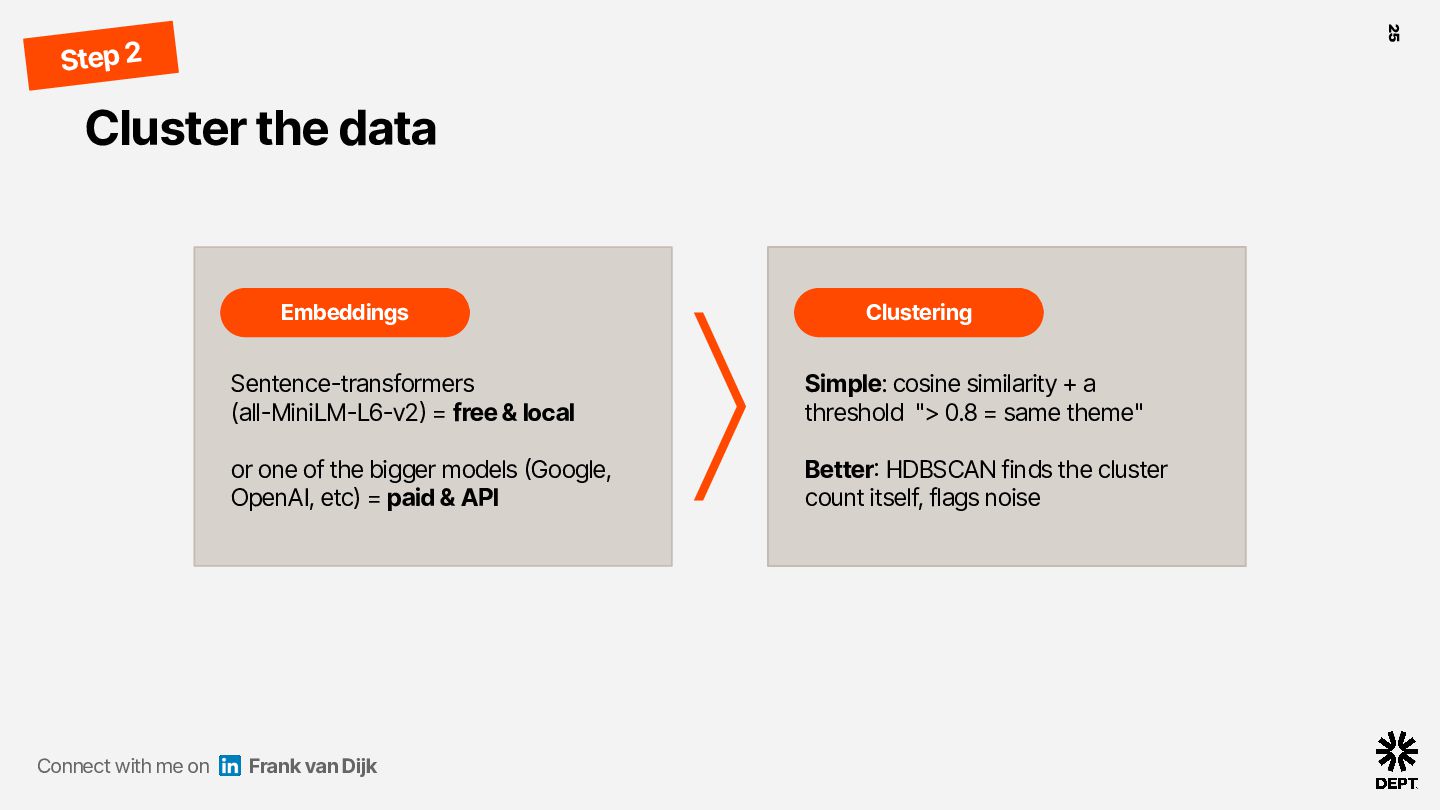
  23. 25 Step 2 Cluster the data Embeddings Connect with me

    on Clustering Sentence-transformers (all-MiniLM-L6-v2) = free & local Simple: cosine similarity + a threshold "> 0.8 = same theme" or one of the bigger models (Google, OpenAI, etc) = paid & API Better: HDBSCAN finds the cluster count itself, flags noise Frank van Dijk
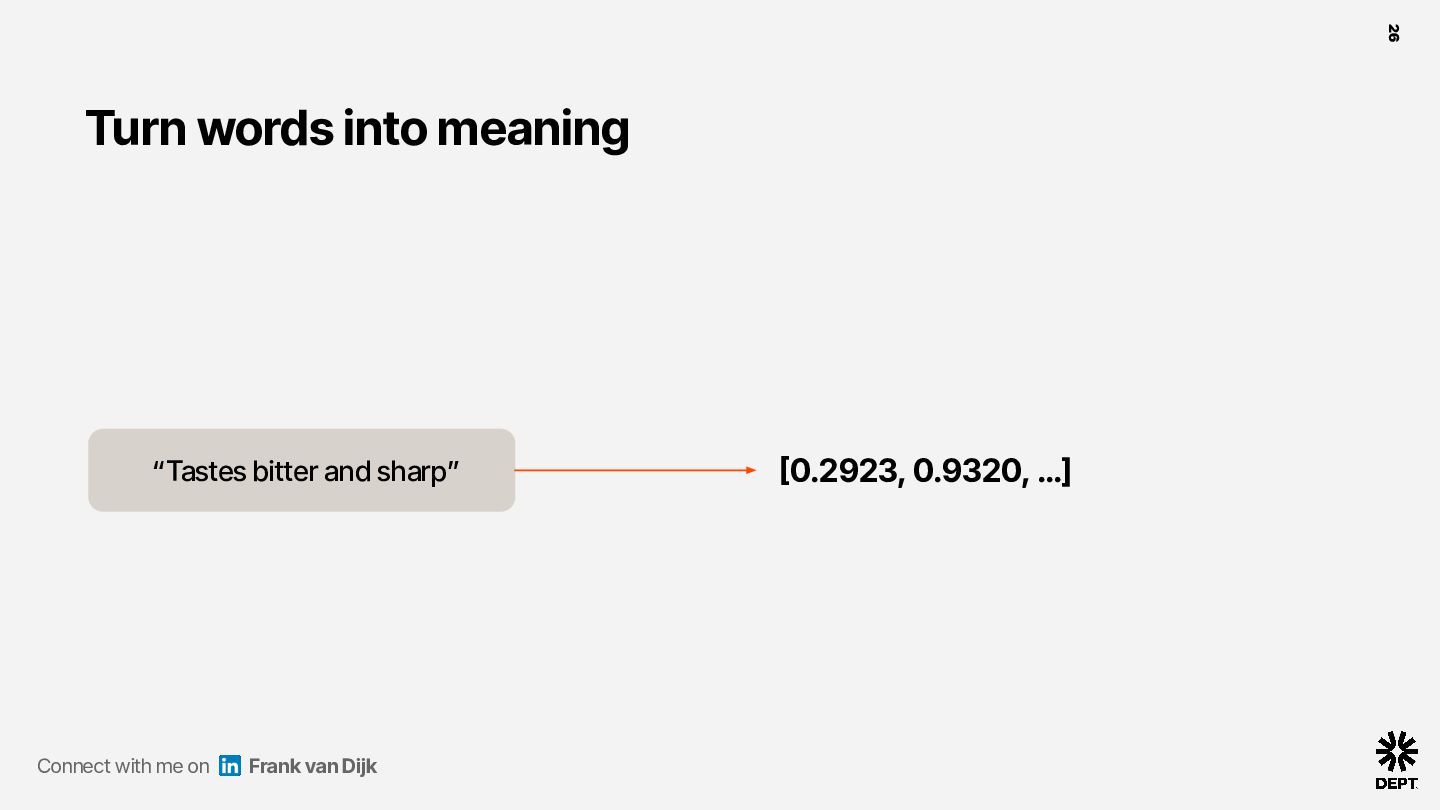
  24. 26 Turn words into meaning “Tastes bitter and sharp” Connect

    with me on Frank van Dijk [0.2923, 0.9320, …]
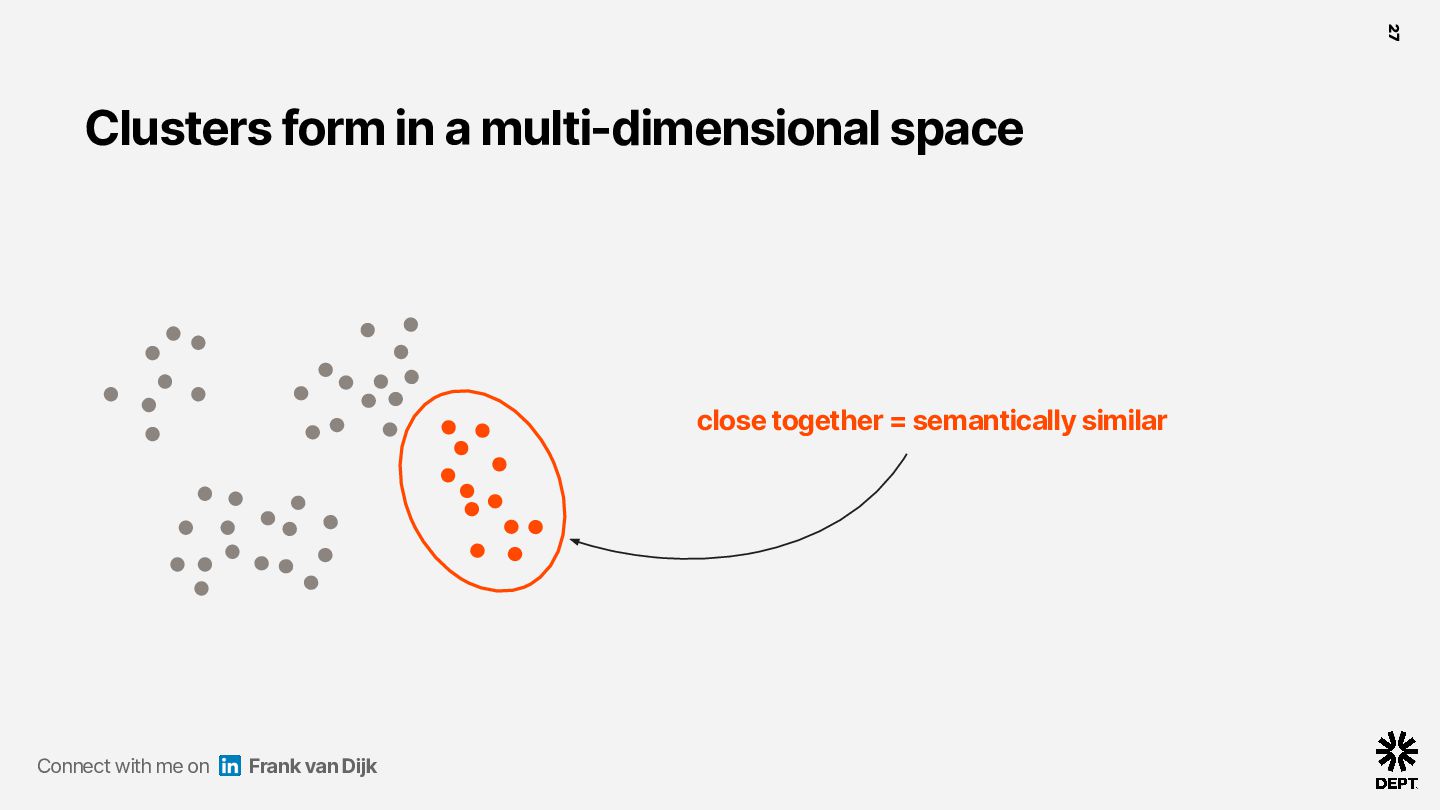
  25. 27 Clusters form in a multi-dimensional space close together =

    semantically similar Connect with me on Frank van Dijk
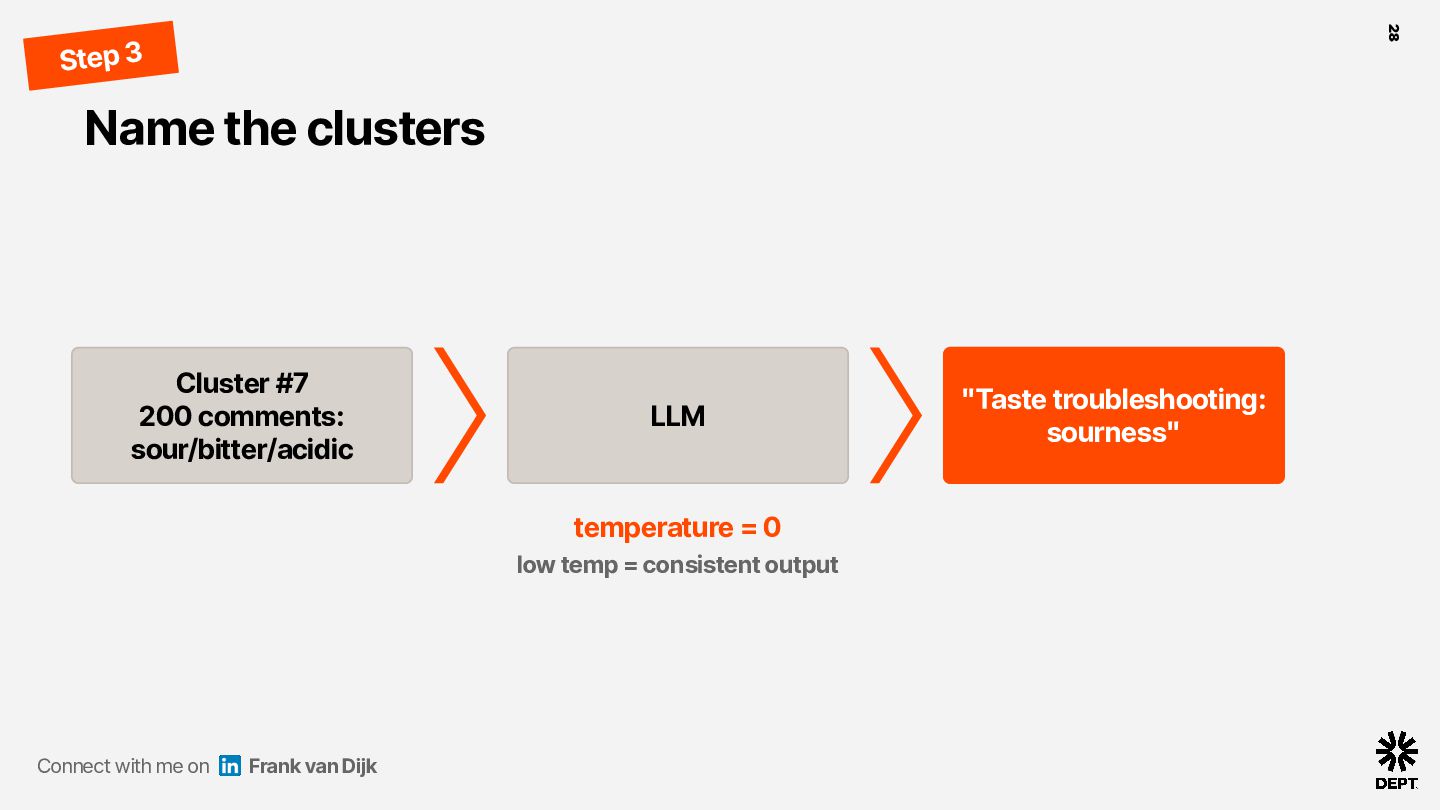
  26. 28 Step 3 Name the clusters Cluster #7 200 comments:

    sour/bitter/acidic LLM temperature = 0 low temp = consistent output Connect with me on Frank van Dijk "Taste troubleshooting: sourness"
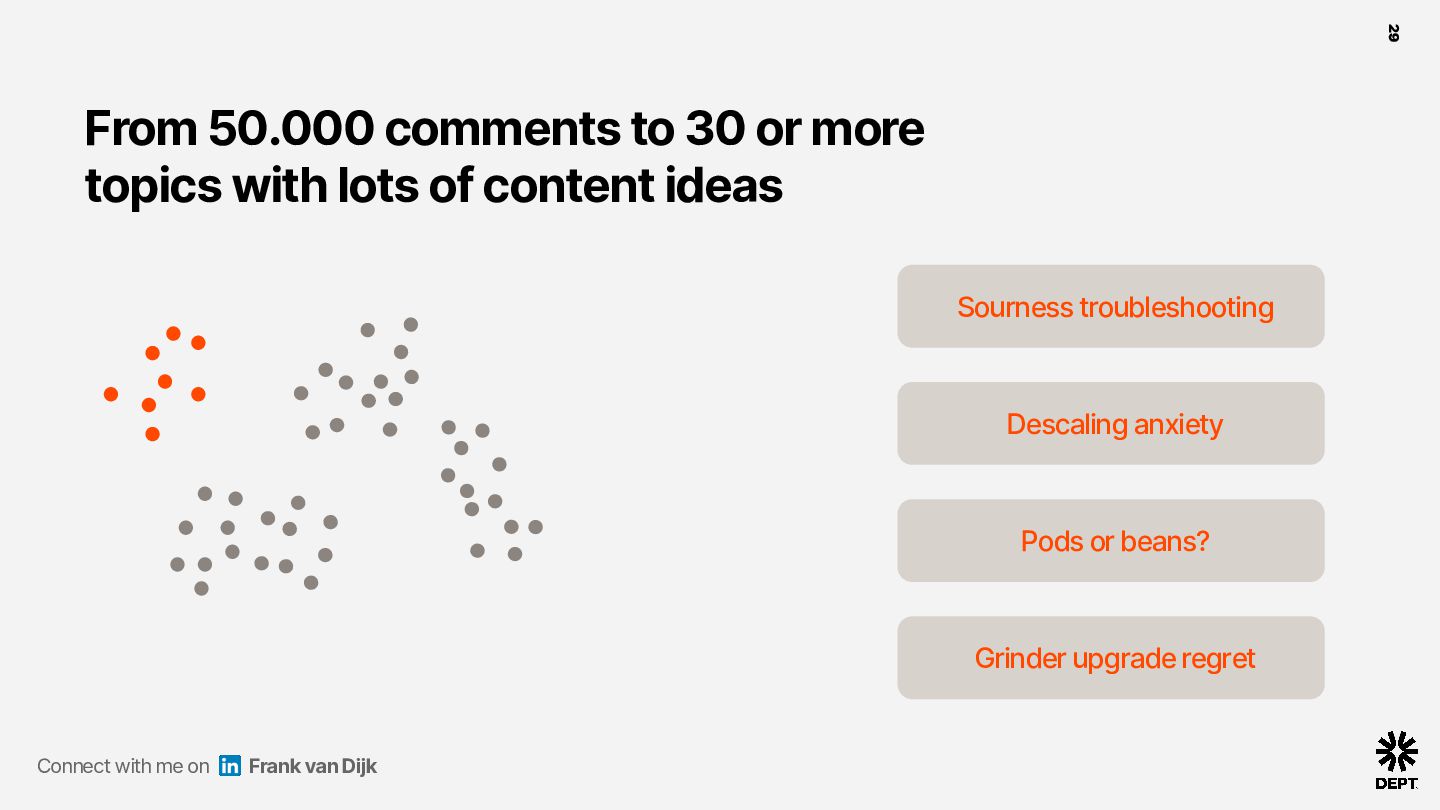
  27. 29 From 50.000 comments to 30 or more topics with

    lots of content ideas Sourness troubleshooting Descaling anxiety Pods or beans? Grinder upgrade regret Connect with me on Frank van Dijk
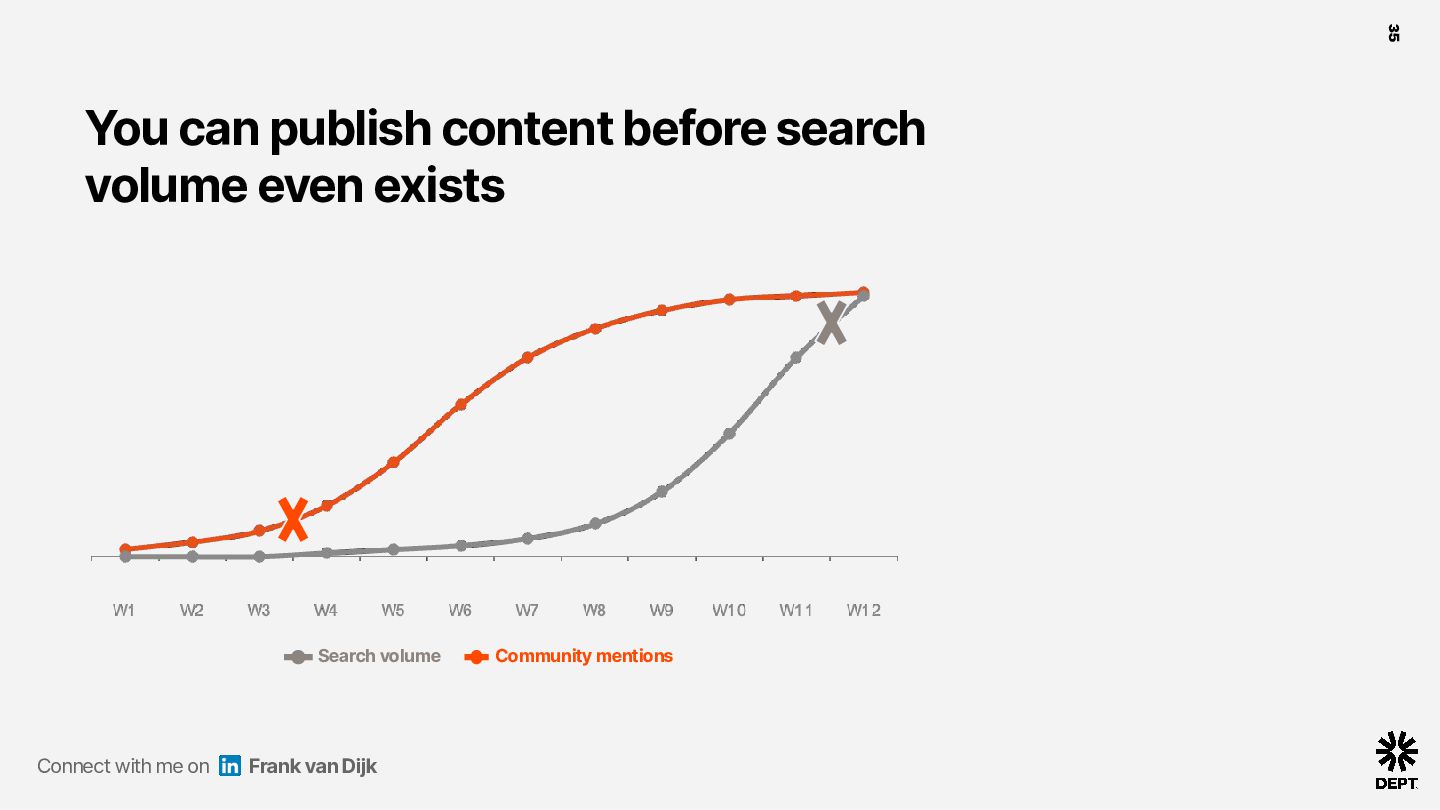
  28. 30 User-generated content shows trends before theyʼre here Trends appear

    here first before people start searching Connect with me on Frank van Dijk
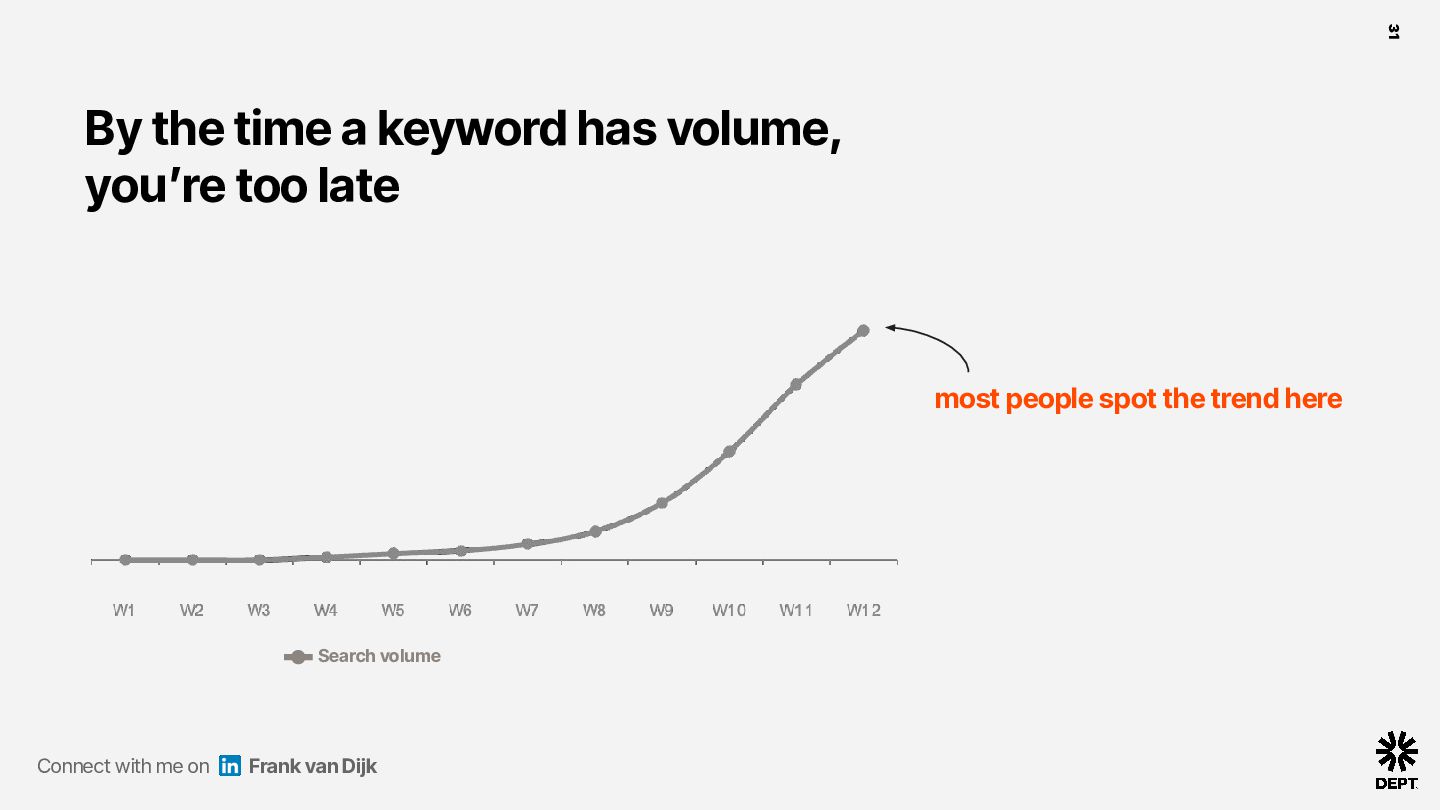
  29. 31 By the time a keyword has volume, youʼre too

    late most people spot the trend here Search volume Connect with me on Frank van Dijk
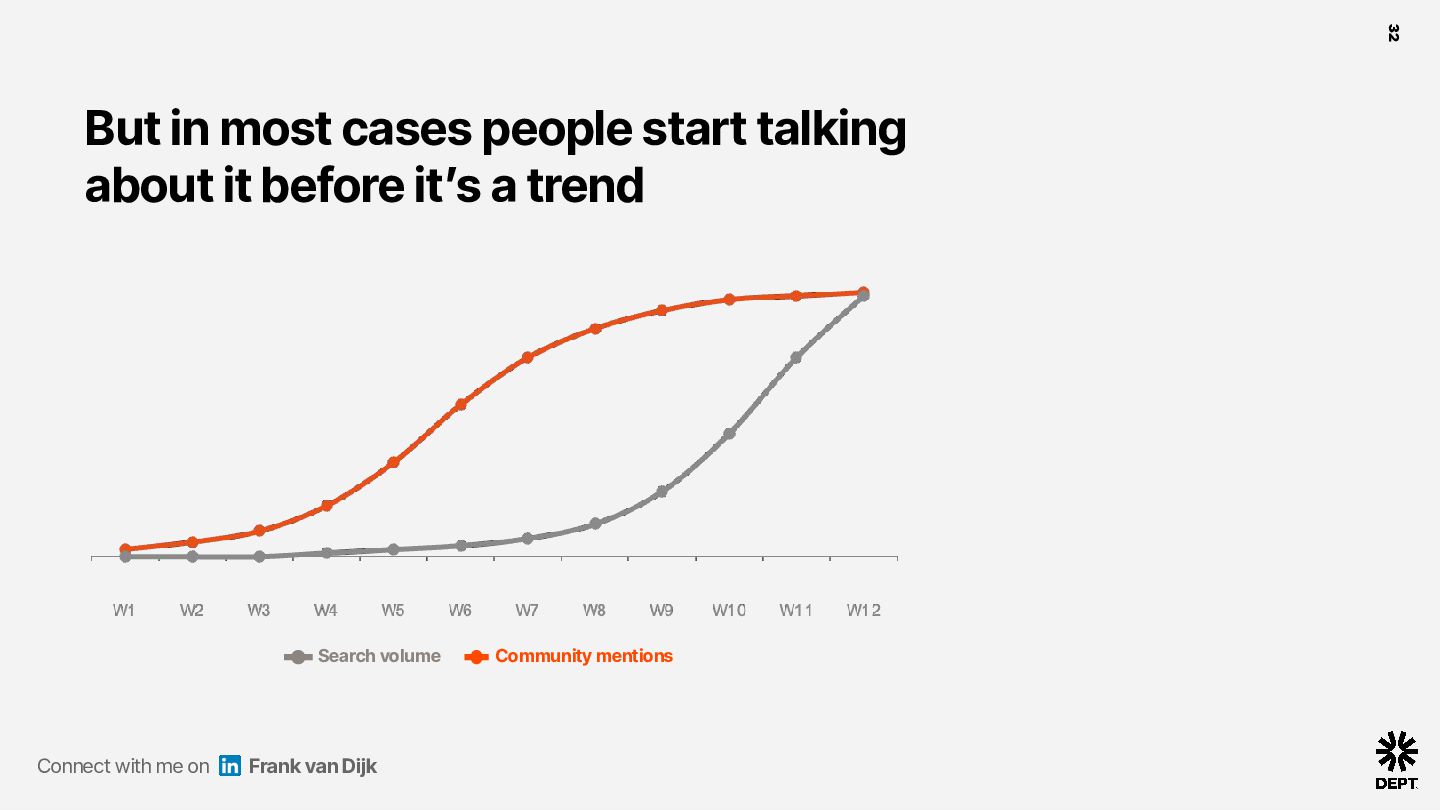
  30. 32 But in most cases people start talking about it

    before itʼs a trend Search volume Connect with me on Frank van Dijk Community mentions
  31. 33 We focus on velocity Velocity = mentions now vs

    mentions before 01 Count mentions of a term for a week 02 Compare to its own baseline 03 Spikes might mean something is brewing Connect with me on Frank van Dijk
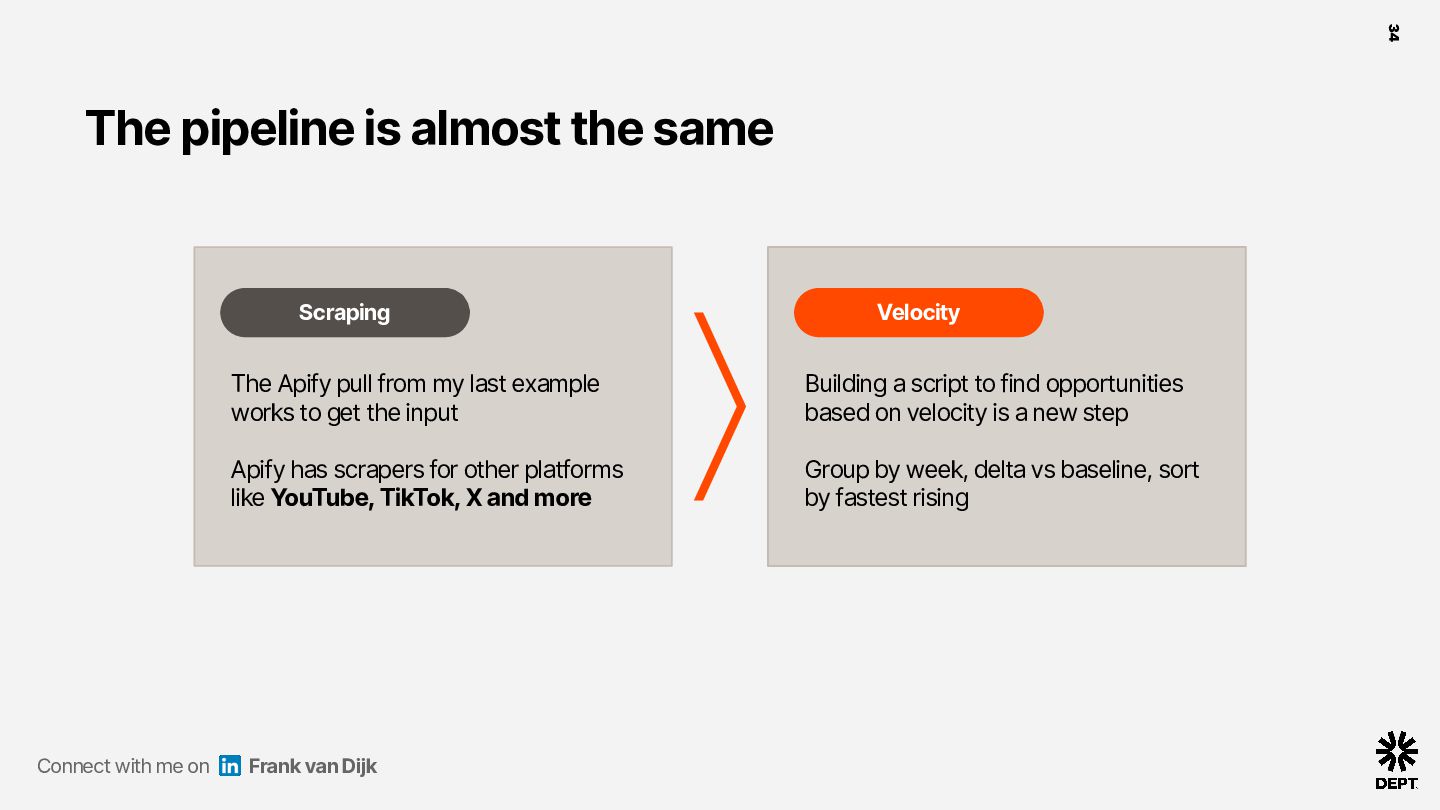
  32. 34 The pipeline is almost the same Scraping Connect with

    me on Velocity The Apify pull from my last example works to get the input Building a script to find opportunities based on velocity is a new step Apify has scrapers for other platforms like YouTube, TikTok, X and more Group by week, delta vs baseline, sort by fastest rising Frank van Dijk
  33. 35 You can publish content before search volume even exists

    Search volume Connect with me on Frank van Dijk Community mentions
  34. 36 Donʼt just rely on scraping, most companies have a

    goldmine Connect with me on Frank van Dijk
  35. 37 Every customer touchpoint has valuable information Calls Emails Contact

    forms Anywhere a customer tells you, in their own words, what they don't understand Connect with me on Frank van Dijk Chat logs
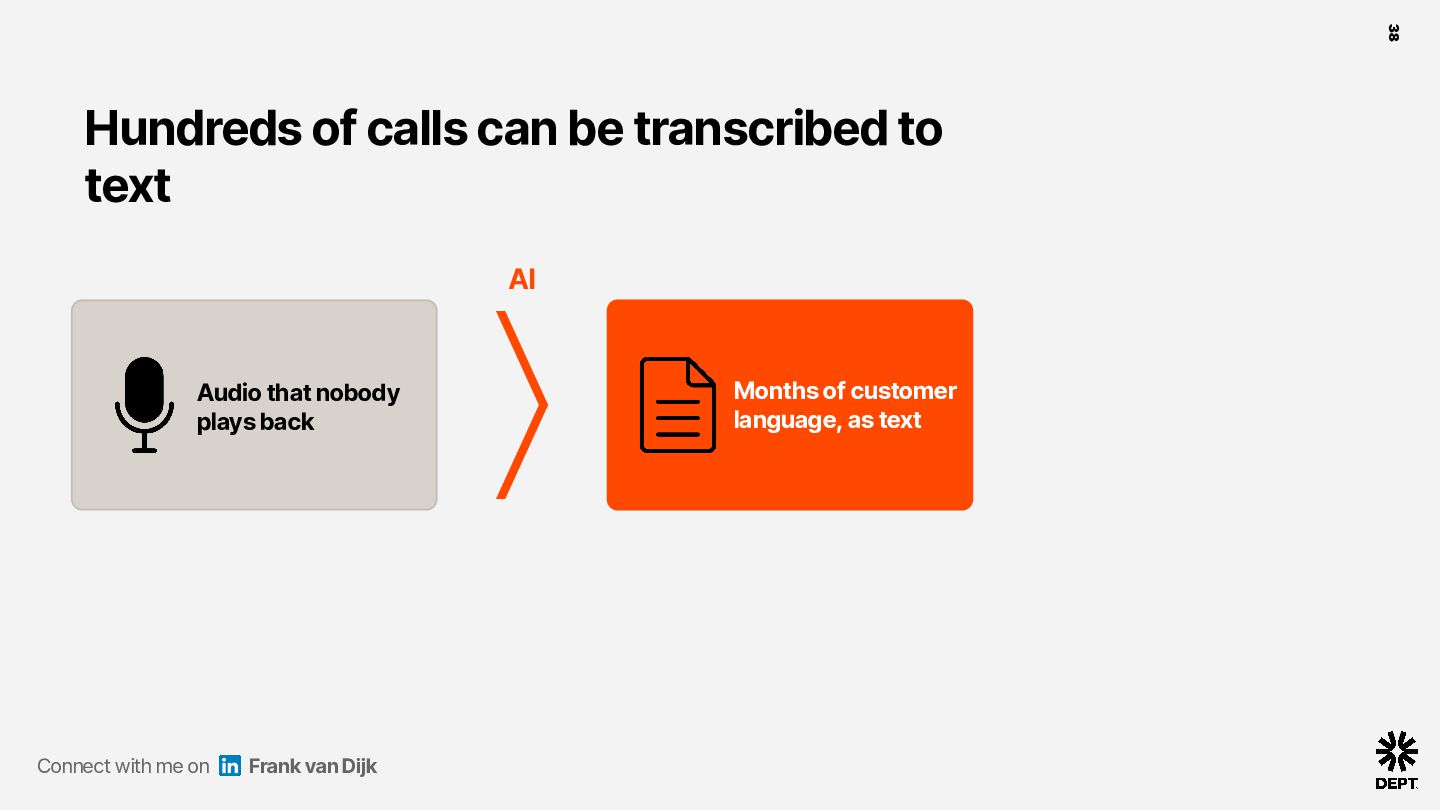
  36. 38 Hundreds of calls can be transcribed to text AI

    Audio that nobody plays back Connect with me on Frank van Dijk Months of customer language, as text
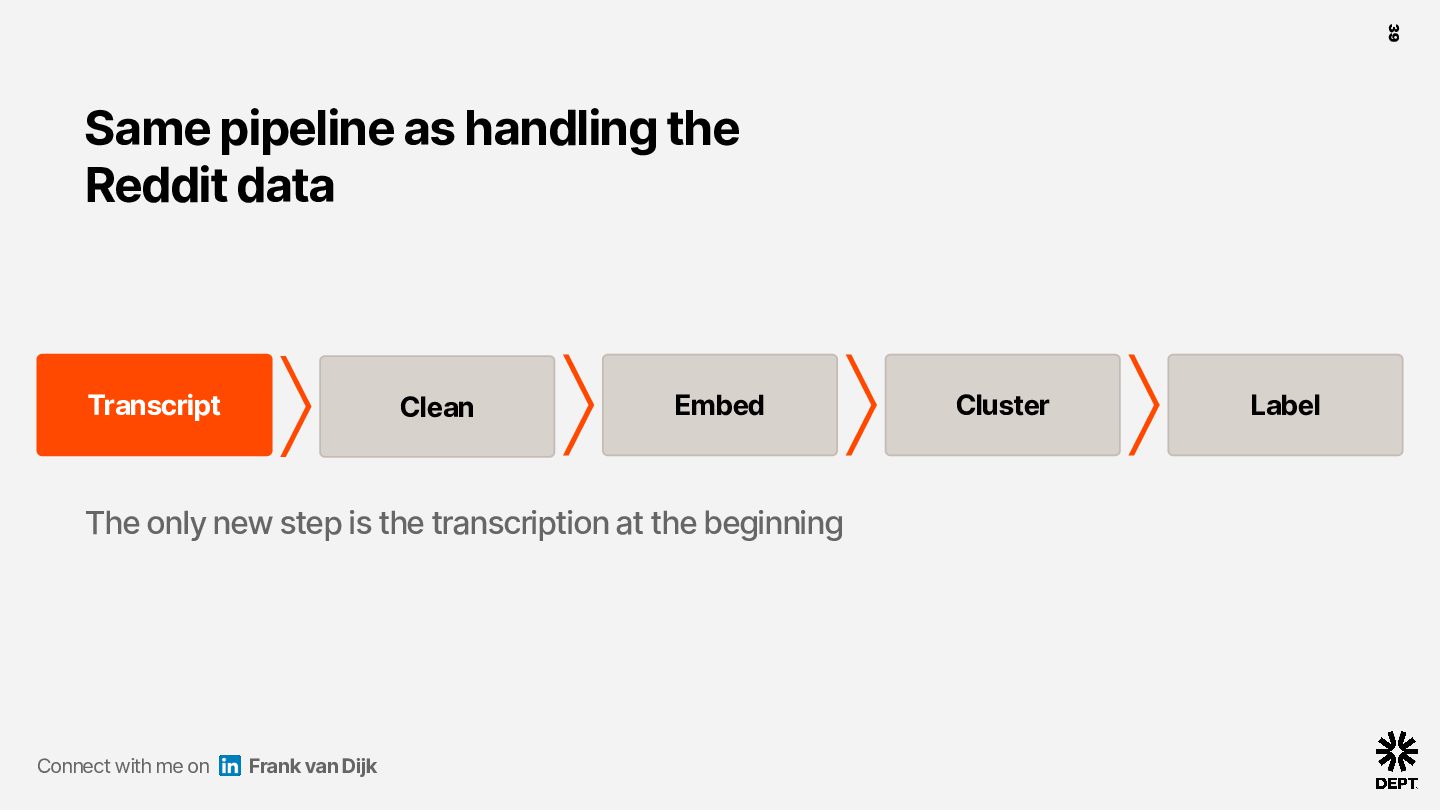
  37. 39 Same pipeline as handling the Reddit data Transcript Clean

    Embed The only new step is the transcription at the beginning Connect with me on Frank van Dijk Cluster Label
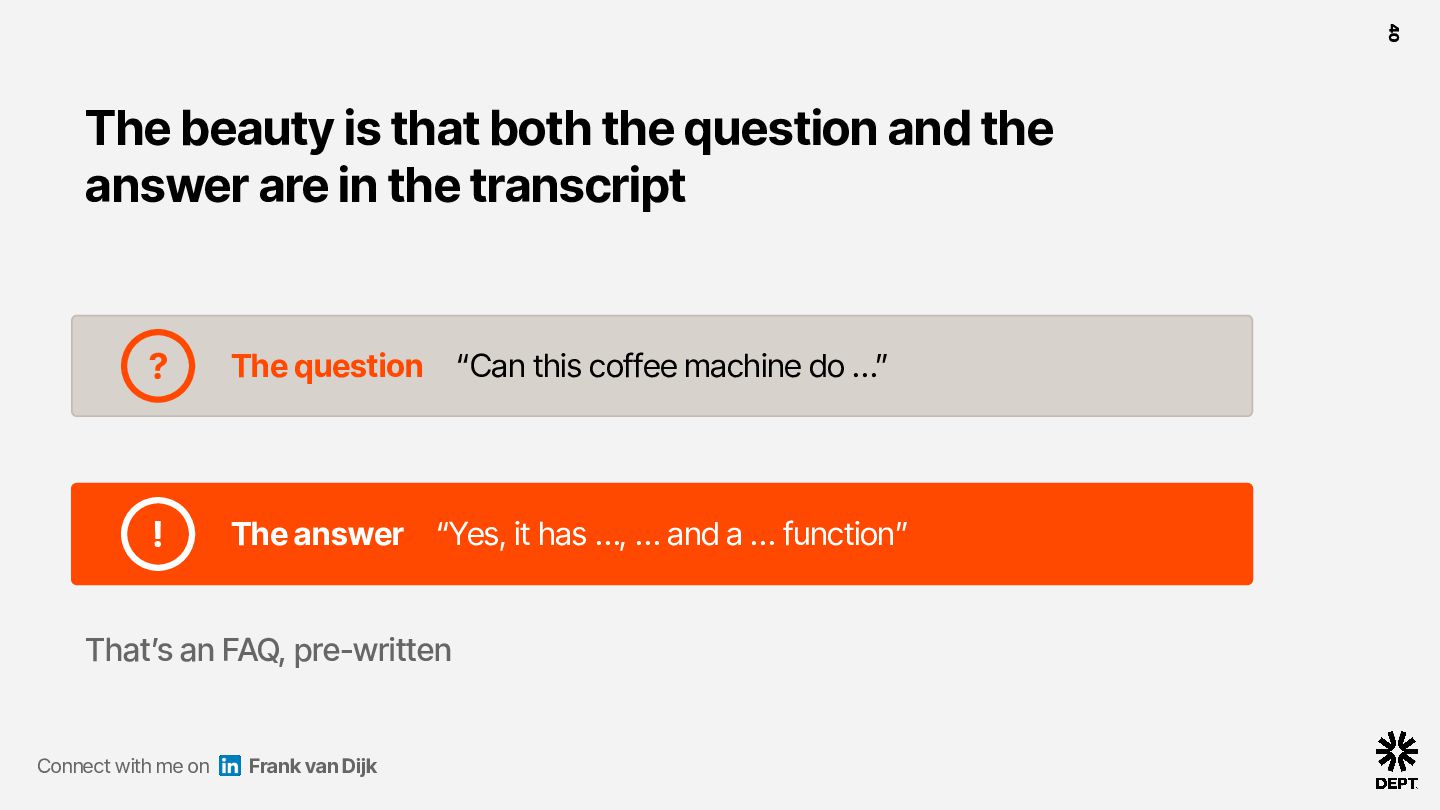
  38. 40 The beauty is that both the question and the

    answer are in the transcript ? The question “Can this coffee machine do …” ! The answer “Yes, it has …, … and a … function” Thatʼs an FAQ, pre-written Connect with me on Frank van Dijk
  39. 41 One source helps the business and adds value to

    SEO ? Product improvements Connect with me on Missing product information Frank van Dijk Blogs Customer service pages FAQs
  40. 42 Weʼve asked humans so far, letʼs now ask the

    machines Connect with me on Frank van Dijk
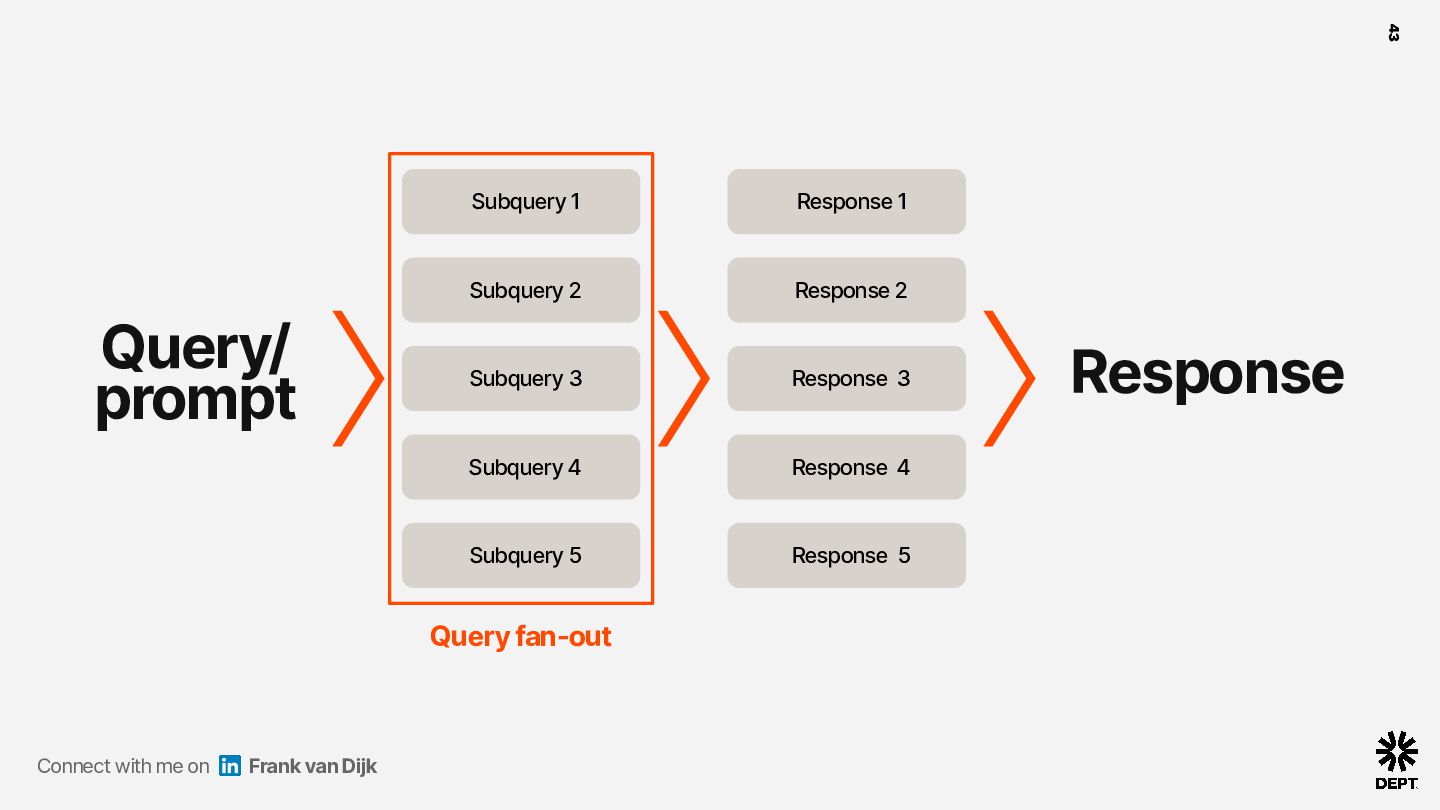
  41. 43 Query/ prompt Subquery 1 Response 1 Subquery 2 Response

    2 Subquery 3 Response 3 Subquery 4 Response 4 Subquery 5 Response 5 Query fan-out Connect with me on Frank van Dijk Response
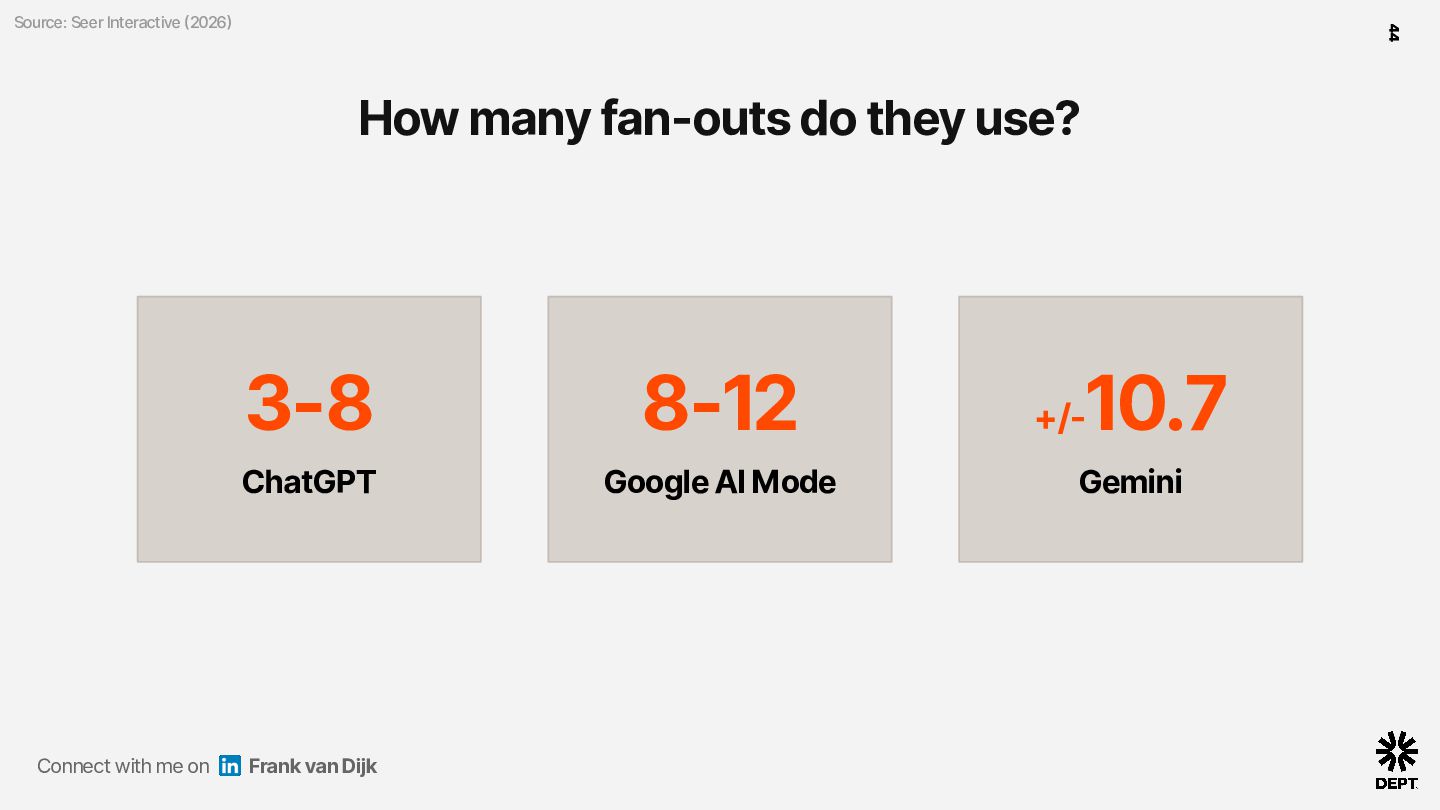
  42. 44 Source: Seer Interactive (2026) How many fan-outs do they

    use? Connect with me on 3-8 8-12 ChatGPT Google AI Mode Frank van Dijk +/- 10.7 Gemini
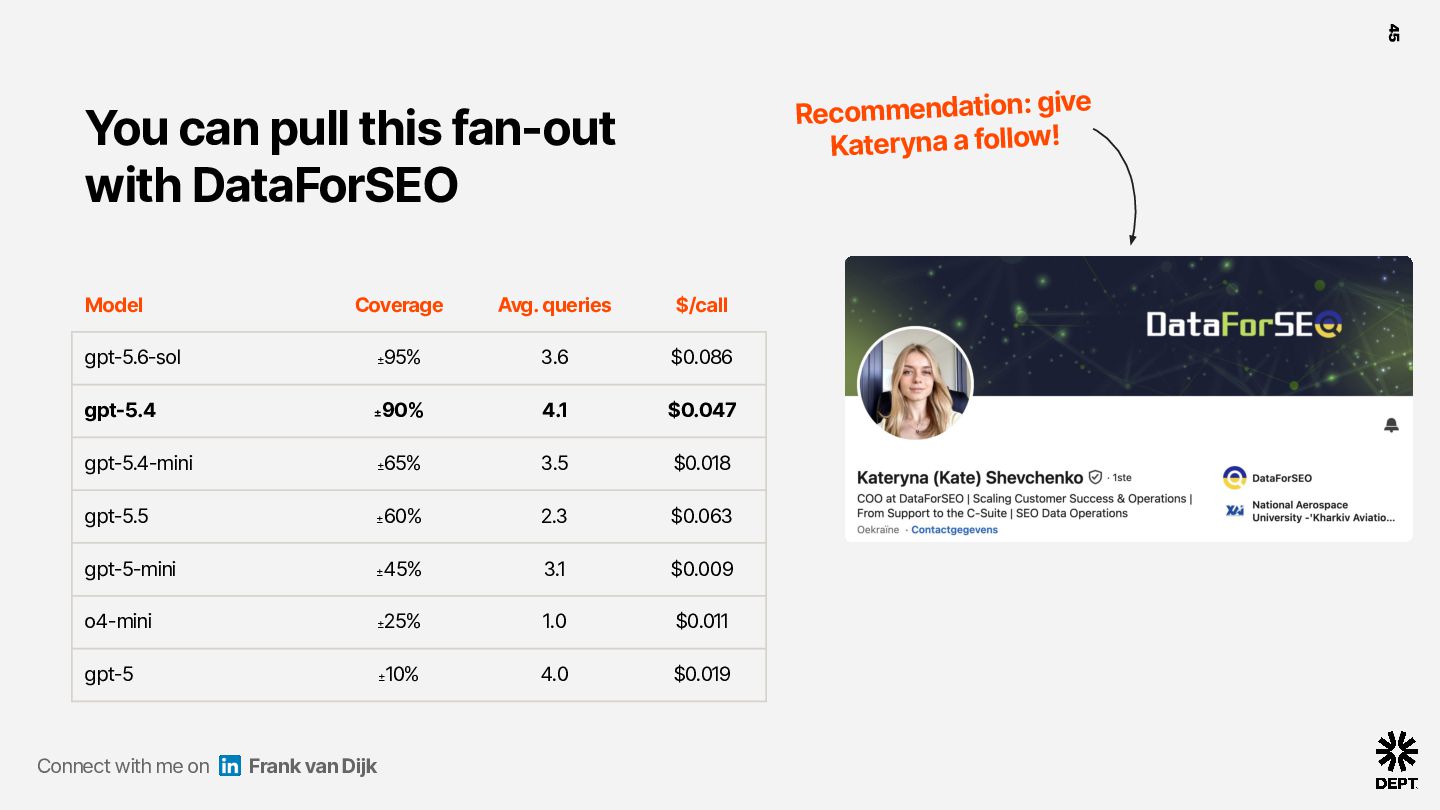
  43. 45 Recommendation: give Kateryna a follow! You can pull this

    fan-out with DataForSEO Model Coverage Avg. queries $/call 95% 3.6 $0.086 90% 4.1 $0.047 65% 3.5 $0.018 60% 2.3 $0.063 45% 3.1 $0.009 25% 1.0 $0.011 10% 4.0 $0.019 gpt-5.6-sol ± gpt-5.4 ± gpt-5.4-mini ± gpt-5.5 ± gpt-5-mini ± o4-mini ± gpt-5 ± Connect with me on Frank van Dijk
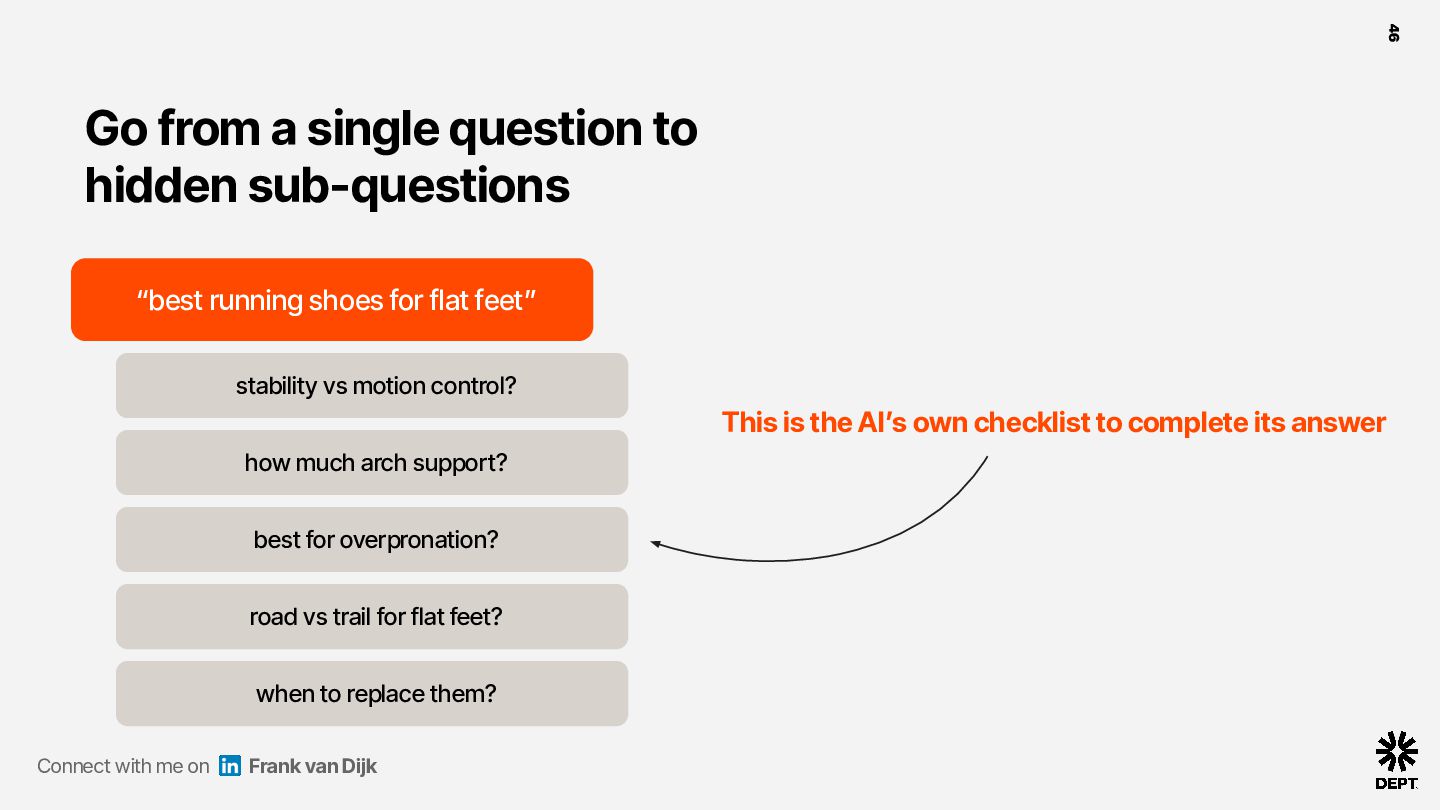
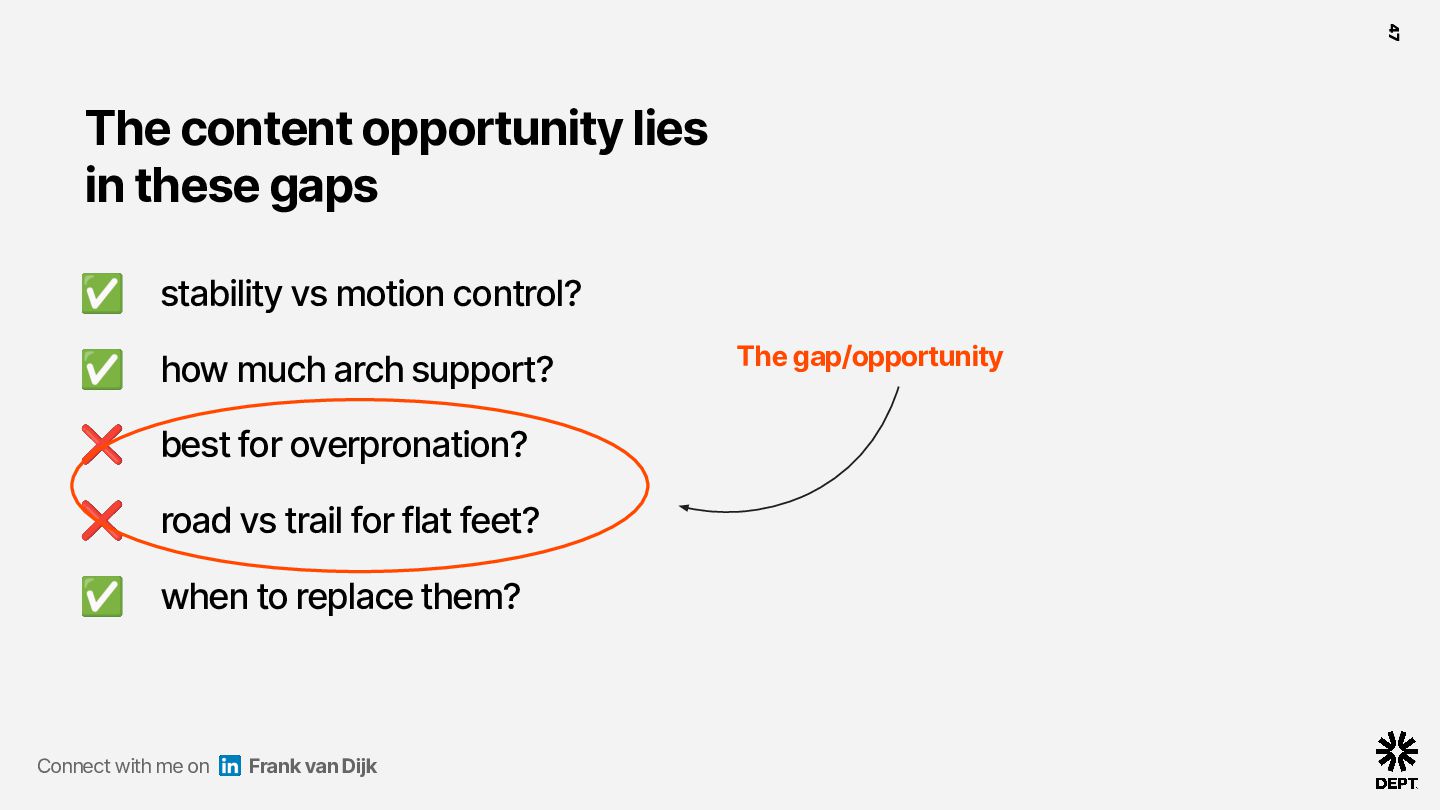
  44. 46 Go from a single question to hidden sub-questions “best

    running shoes for flat feet” stability vs motion control? This is the AIʼs own checklist to complete its answer how much arch support? best for overpronation? road vs trail for flat feet? when to replace them? Connect with me on Frank van Dijk
  45. 47 The content opportunity lies in these gaps ✅ stability

    vs motion control? ✅ how much arch support? ❌ best for overpronation? ❌ road vs trail for flat feet? ✅ when to replace them? Connect with me on Frank van Dijk The gap/opportunity
  46. 48 Then check if you show up Keep track of

    the rankings on those query fan-outs 01 Track your position on those fan-out queries 02 Check your presence in AIO 03 Watch visibility rise as you close these gaps Connect with me on Frank van Dijk
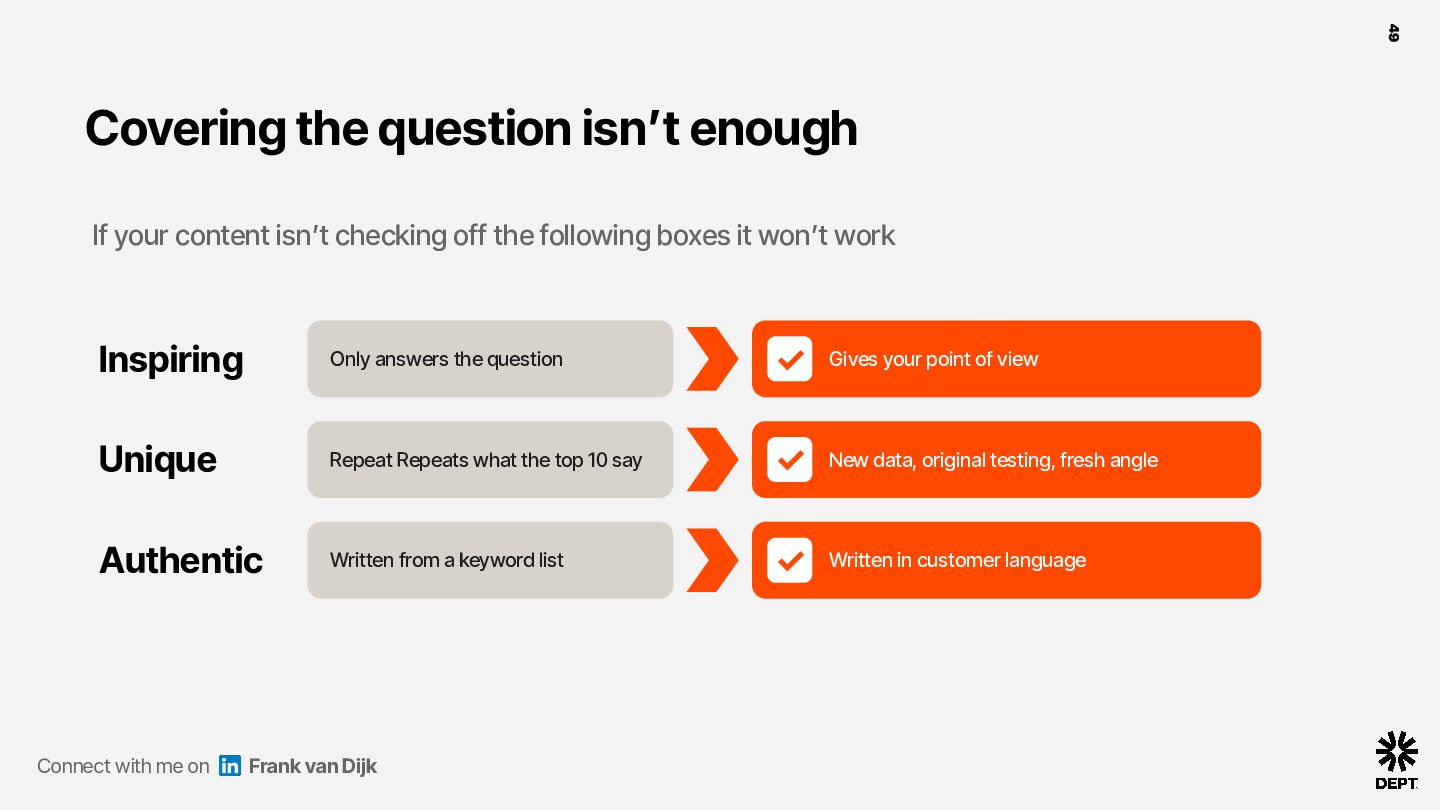
  47. 49 Covering the question isnʼt enough If your content isnʼt

    checking off the following boxes it wonʼt work Inspiring Only answers the question ✓ Gives your point of view Unique Repeat Repeats what the top 10 say ✓ New data, original testing, fresh angle Authentic Written from a keyword list ✓ Written in customer language Connect with me on Frank van Dijk
  48. 50 Because most SEO content is just a remix of

    the top 10 rankings Everybody is creating the same type of pages Connect with me on Frank van Dijk
  49. 51 Google doesnʼt like this, it wants pages that give

    new input Information Gain Score Google holds a patent that checks the information gain Connect with me on Frank van Dijk
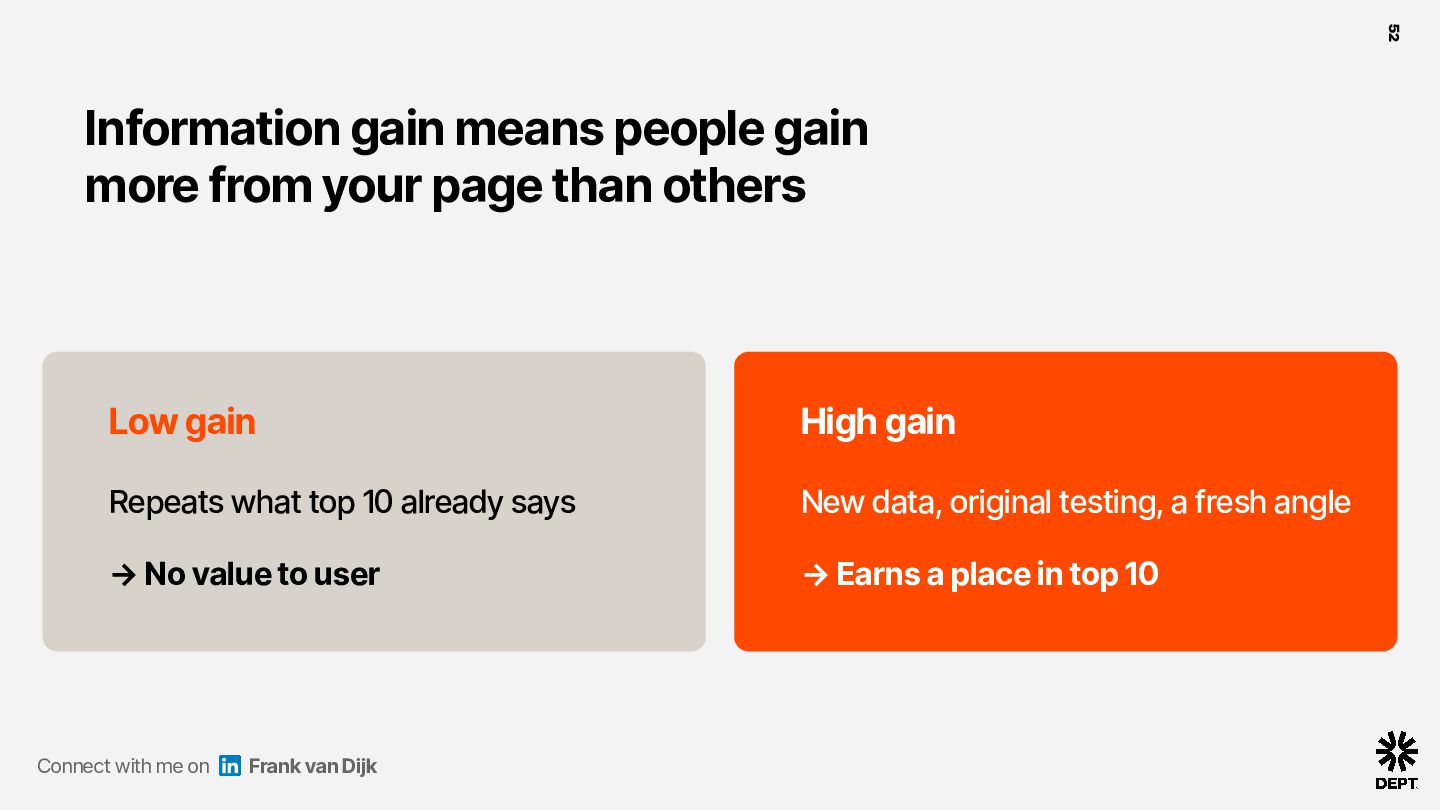
  50. 52 Information gain means people gain more from your page

    than others Low gain High gain Repeats what top 10 already says New data, original testing, a fresh angle -> No value to user -> Earns a place in top 10 Connect with me on Frank van Dijk
  51. 53 RAG systems seem to like this even more They're

    not looking for 10 sources saying the same thing Connect with me on �� �� �� �� �� �� �� �� �� �� Frank van Dijk
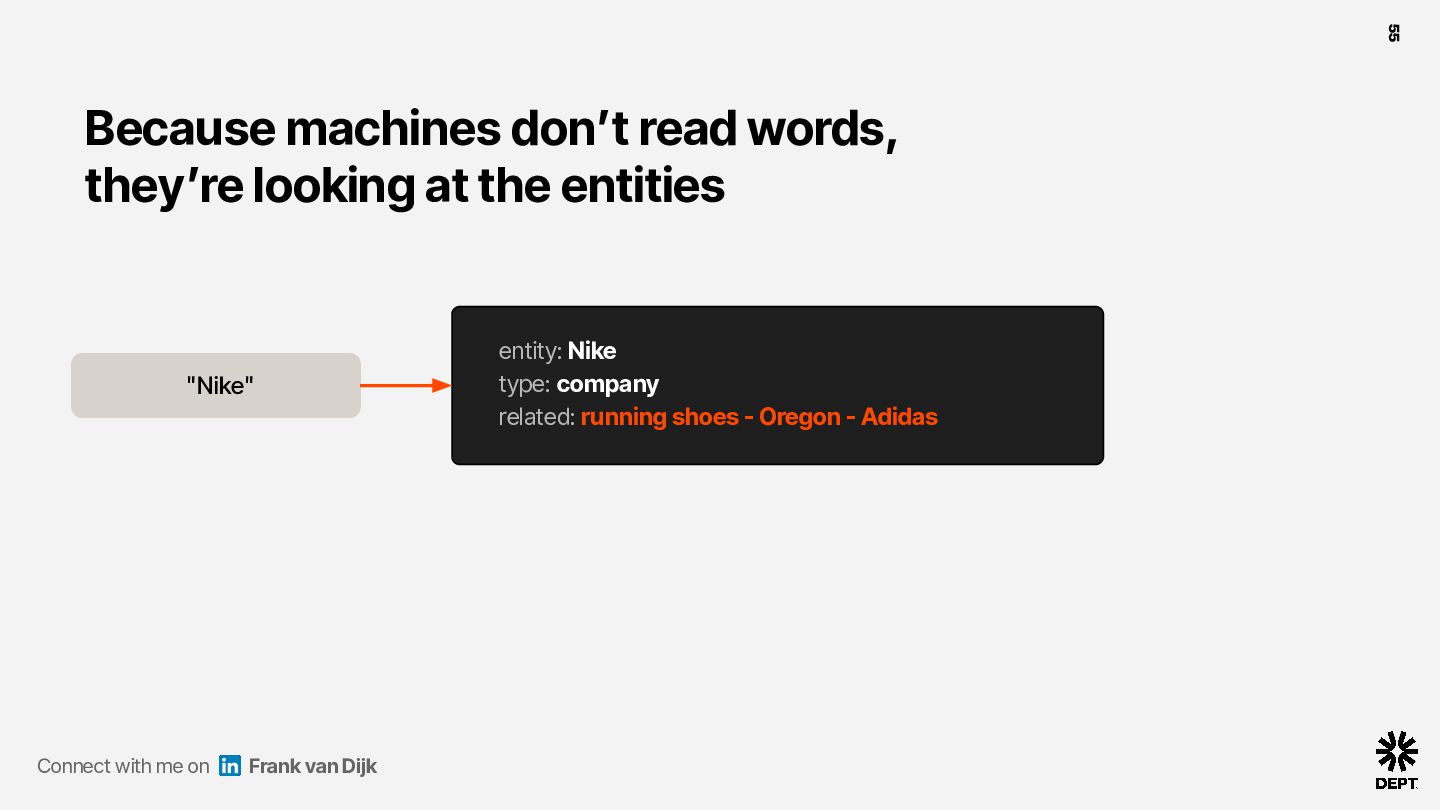
  52. 55 Because machines donʼt read words, theyʼre looking at the

    entities "Nike" Connect with me on Frank van Dijk entity: Nike type: company related: running shoes - Oregon - Adidas
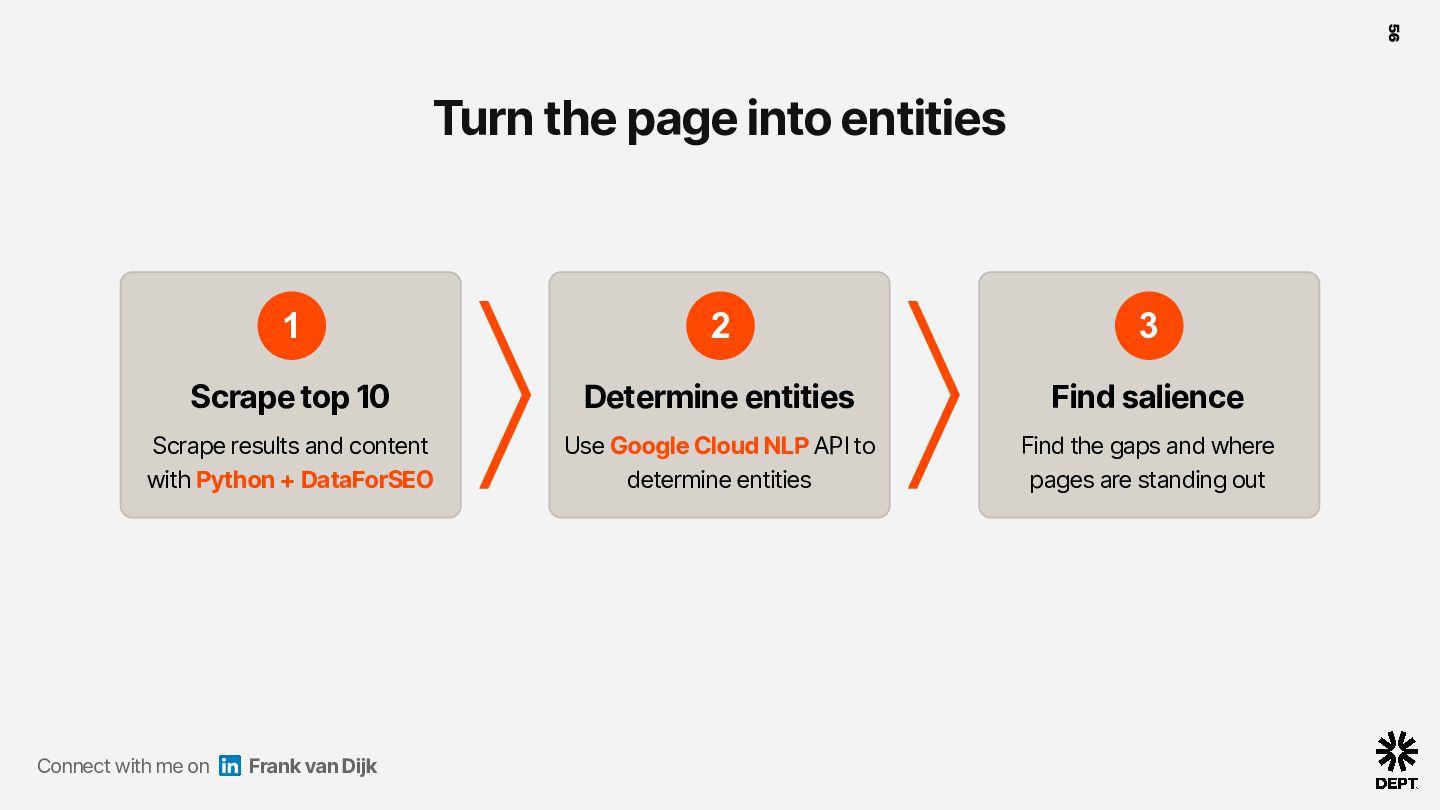
  53. 56 Turn the page into entities 1 2 3 Scrape

    top 10 Determine entities Find salience Scrape results and content with Python + DataForSEO Use Google Cloud NLP API to determine entities Find the gaps and where pages are standing out Connect with me on Frank van Dijk
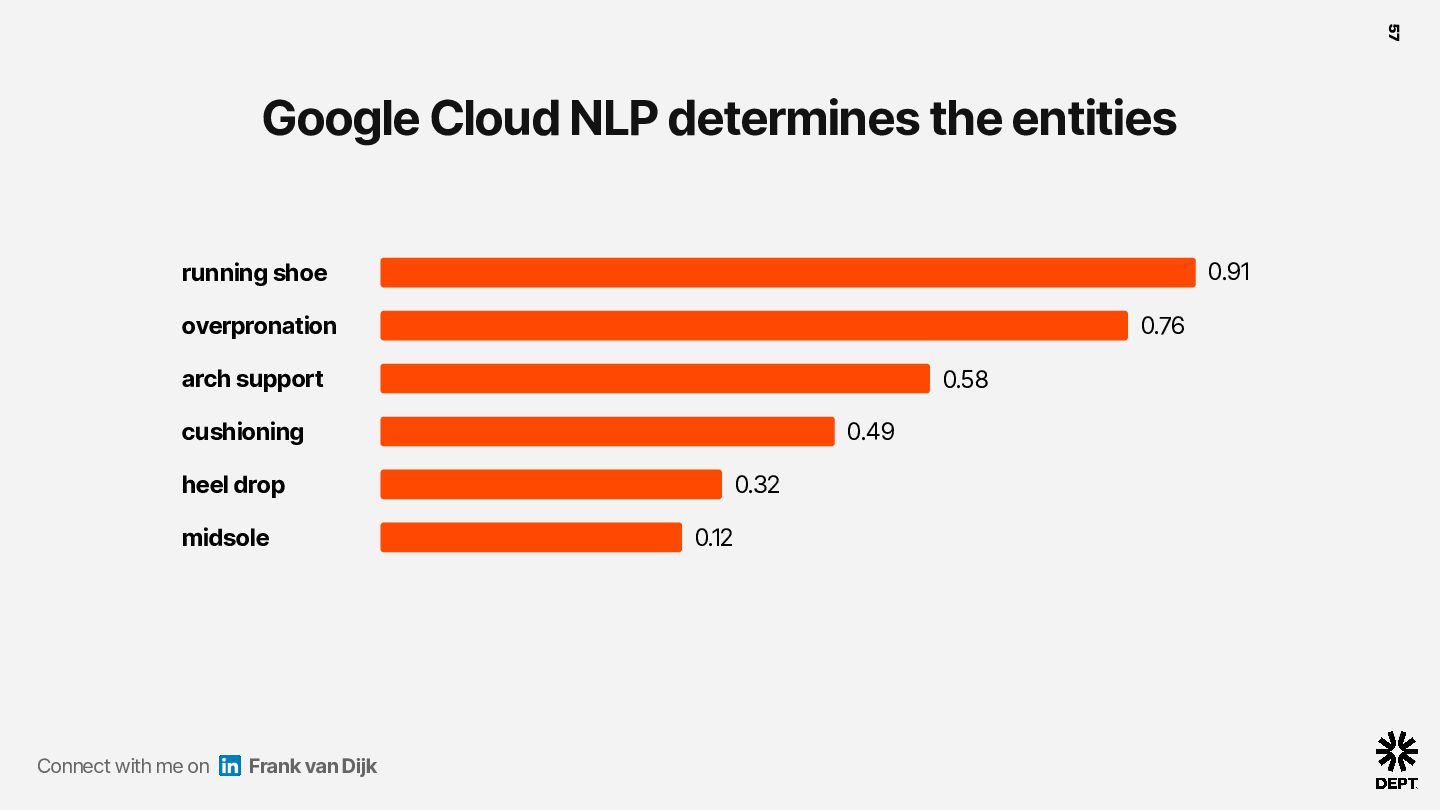
  54. 57 Google Cloud NLP determines the entities 0.91 running shoe

    0.76 overpronation arch support 0.58 0.49 cushioning 0.32 heel drop midsole Connect with me on Frank van Dijk 0.12
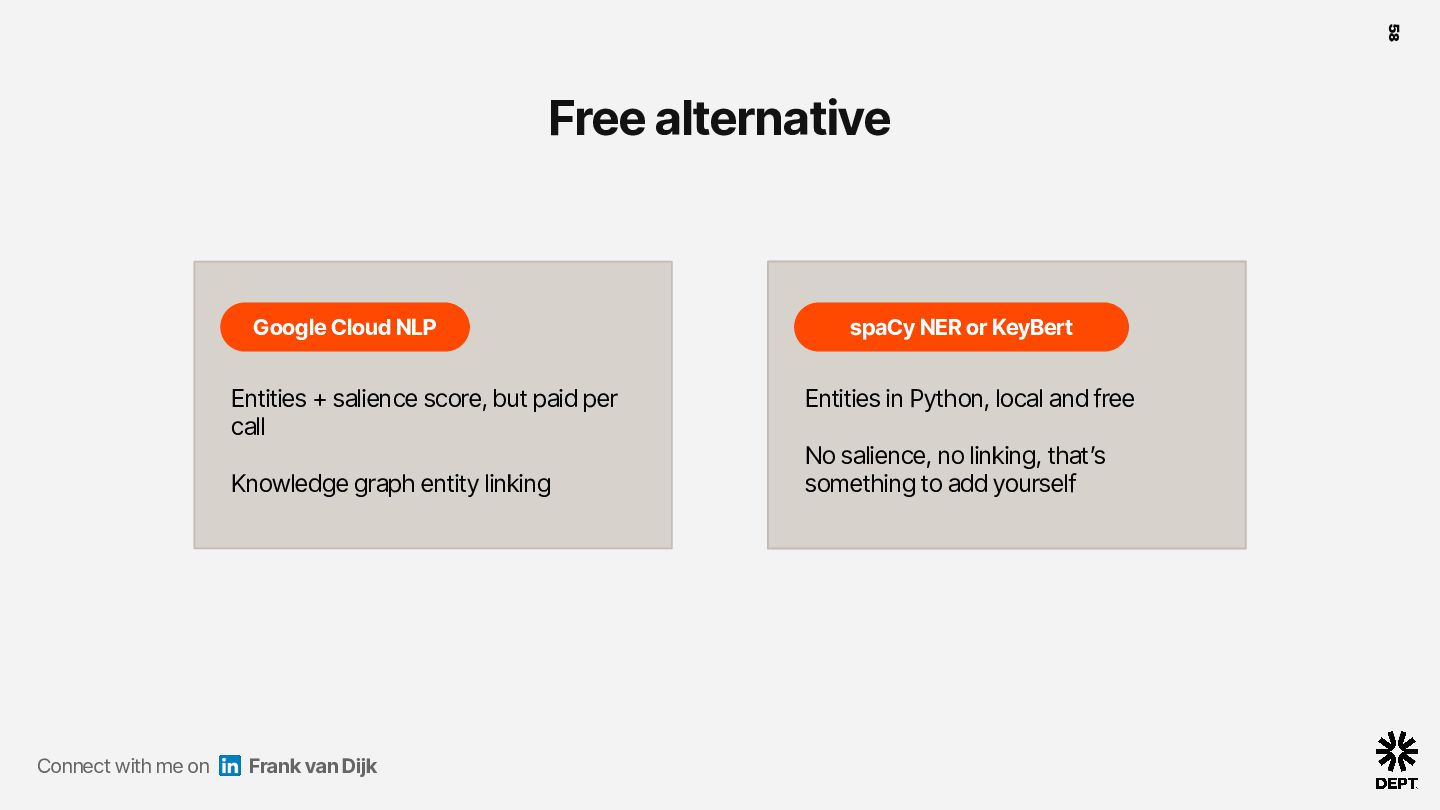
  55. 58 Free alternative Google Cloud NLP Entities + salience score,

    but paid per call Knowledge graph entity linking Connect with me on Frank van Dijk spaCy NER or KeyBert Entities in Python, local and free No salience, no linking, thatʼs something to add yourself
  56. 59 Based on these entities itʼs just a math calculation

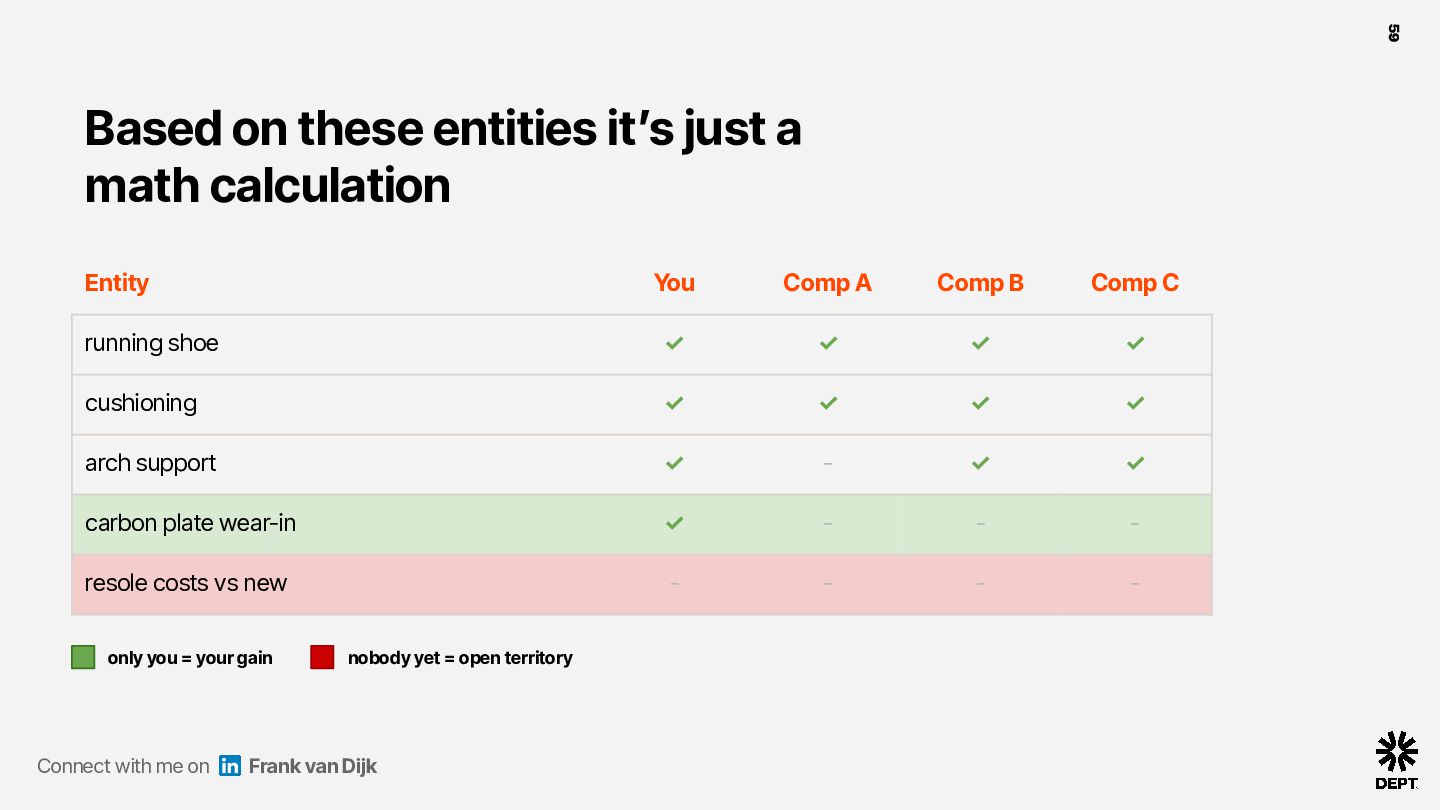
    Entity You Comp A Comp B Comp C running shoe ✓ ✓ ✓ ✓ cushioning ✓ ✓ ✓ ✓ arch support ✓ - ✓ ✓ carbon plate wear-in ✓ - - - resole costs vs new - - - - only you = your gain Connect with me on nobody yet = open territory Frank van Dijk
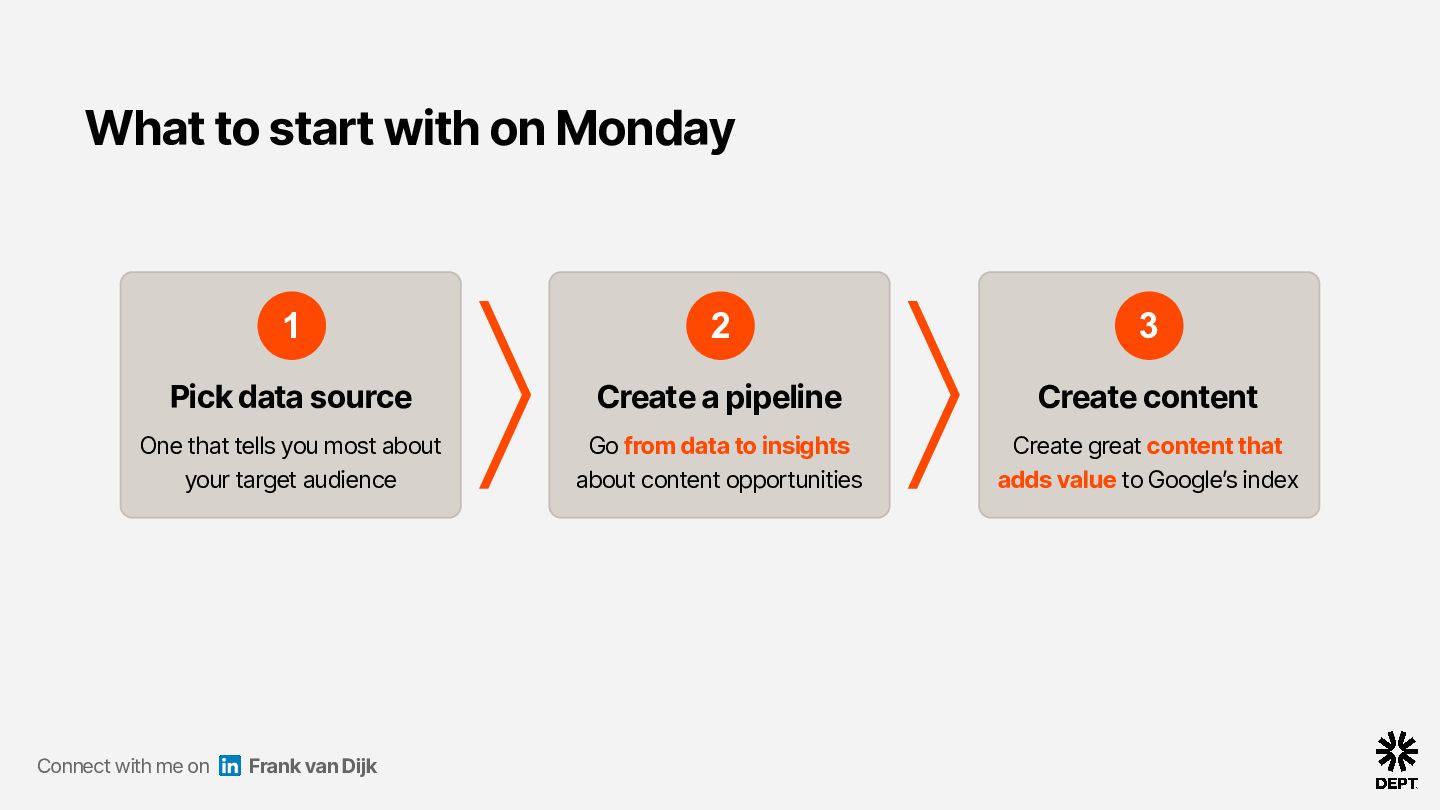
  57. What to start with on Monday 1 2 3 Pick

    data source Create a pipeline Create content One that tells you most about your target audience Go from data to insights about content opportunities Create great content that adds value to Googleʼs index Connect with me on Frank van Dijk