Share
Embed
The Software Engineering Part of Data Science
Presentation slides at PyCon Taiwan 2019
https://tw.pycon.org/2019/
Hacarus Inc.
September 21, 2019
Transcript
44 slides
-
Call me Ninz! - Software Engineer @ Hacarus - Studying
MSCS @ Ateneo de Manila University - Music enthusiast - Physics and astronomy is <3 - I love data! - Curious, always. -
Let’s begin! • Introduction • Identifying development challenges • Defining
solutions • Software engineer to data scientist • Improvements from Python -
• Product delivery • Code quality • Maintainability • Architecture/Boiler
plates • User oriented • App development • Product delivery • Model accuracy • Visualization of data • Notebooks • Data-driven • Mathematical computations -
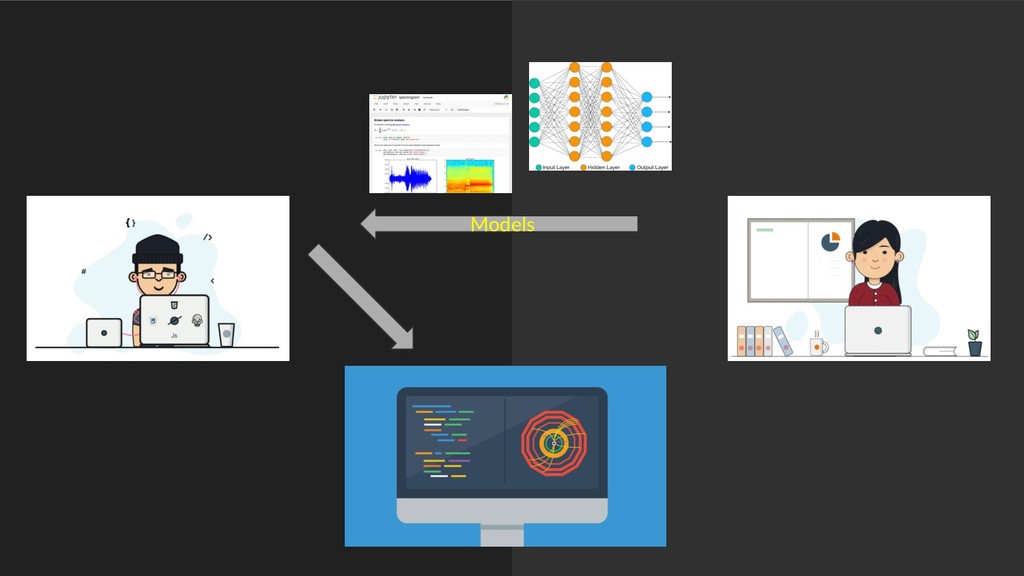
The software engineer • Code from data scientist SOMETIMES ARE
NOT EFFICIENT and CLEAN! • Models are based on limited training and testing data. • Data formats, input and output. • D O C U M E N T A T I O N ! -
Python bridges the gap • Common language • Easy to
understand • Consistency of setup (pyenv, pipenv, etc) • Faster prototyping -
Starting the Project • Data scientists and software engineers must
align their requirements ◦ Avoid high level planning ◦ Be very specific in resource requirements • “What data are we using?” • “Who will be using the data?” -
Code standards • Most data scientists don’t use linters! UGHHH
SAD! • If there will be errors, make it straight to the point • Don’t expect 100% code quality from Data Scientists • Utilize language feature ◦ Type hints in python ◦ Data classes -
Architectural Challenges • How different algorithms consume resource ◦ CPU
and memory limitations ◦ Storage options ◦ Multiprocessing vs multithreading • How models will be used by applications ◦ Interfaces ◦ Communication protocols -
Deployment • Identify deployment methods ◦ Cloud or Local ◦
Mobile ◦ Micro Controllers, etc • Scaling up cloud deployments • Scaling down for local deployments (minimal resource environment) • Continuous Integration -
Data Driven Development • Application structure and requirements will depend
on: ◦ What are the data inputs for the algorithms? ◦ What are the data outputs/results? ◦ How will the data be transformed throughout its lifecycle • Python provides several libraries that can be utilized in data driven development like Data Classes -
Data Driven Development Data inputs Transformation / processing Apply Model
Output P i p e l i n e Data sources Data storage Data workflow -
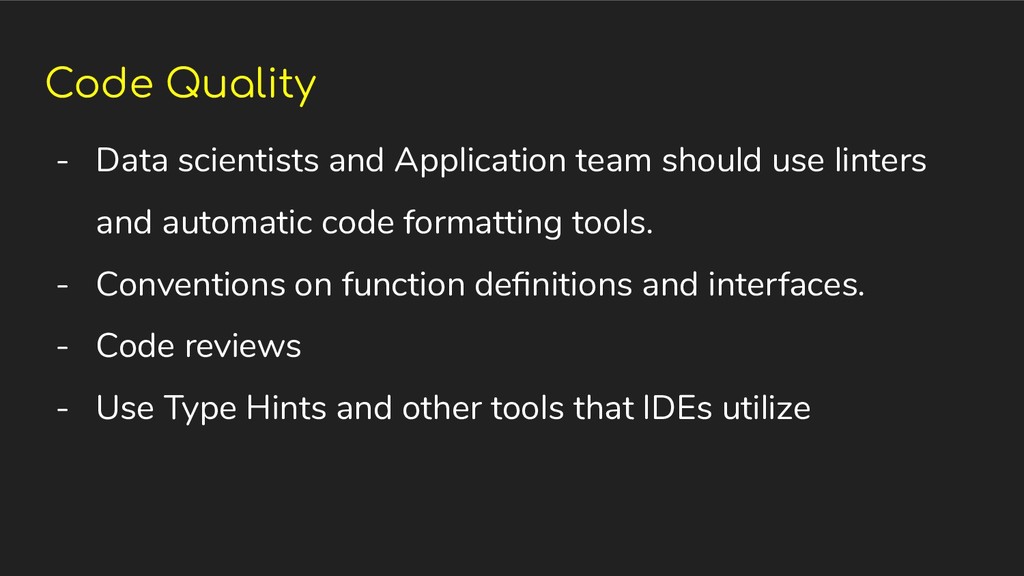
Code Quality - Data scientists and Application team should use
linters and automatic code formatting tools. - Conventions on function definitions and interfaces. - Code reviews - Use Type Hints and other tools that IDEs utilize -
Type hints from typing import List class User: def __init__(self,
name: str, age: int, alive: bool, hobbies: List[str]) -> object: print(f"My name is {name}") -
Error Handling - Standardize Errors - Meaningful errors - Warnings
vs Errors vs Fatal Errors -
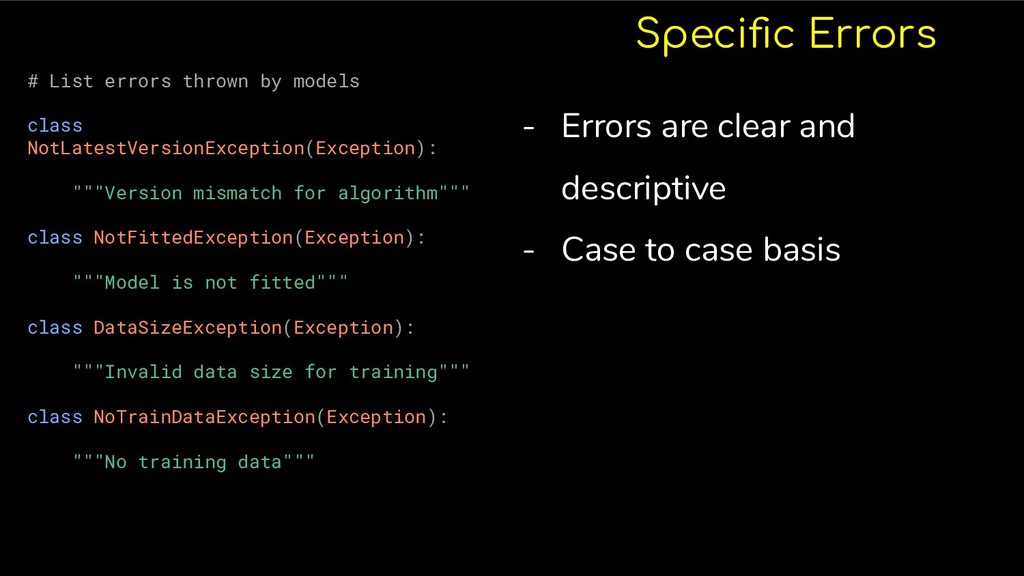
Specific Errors # List errors thrown by models class NotLatestVersionException(Exception):
"""Version mismatch for algorithm""" class NotFittedException(Exception): """Model is not fitted""" class DataSizeException(Exception): """Invalid data size for training""" class NoTrainDataException(Exception): """No training data""" - Errors are clear and descriptive - Case to case basis -
Data Integrity - Create data classes for strict type implementation
- Pre processing should be atomic in nature. - Single operation per data only - Data output and results must be stored as granular as possible -
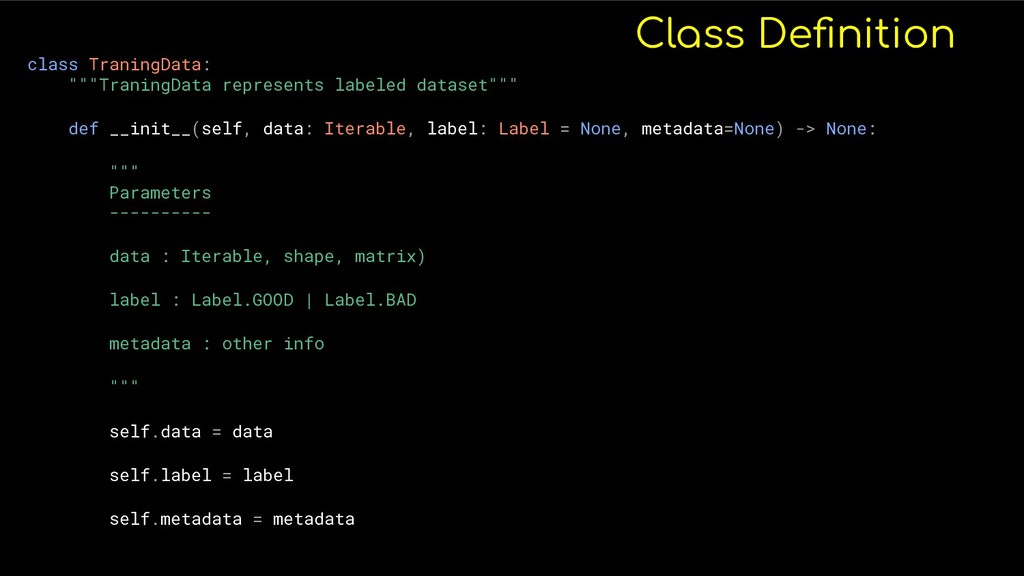
Class Definition class TraningData: """TraningData represents labeled dataset""" def __init__(self,
data: Iterable, label: Label = None, metadata=None) -> None: """ Parameters ---------- data : Iterable, shape, matrix) label : Label.GOOD | Label.BAD metadata : other info """ self.data = data self.label = label self.metadata = metadata -
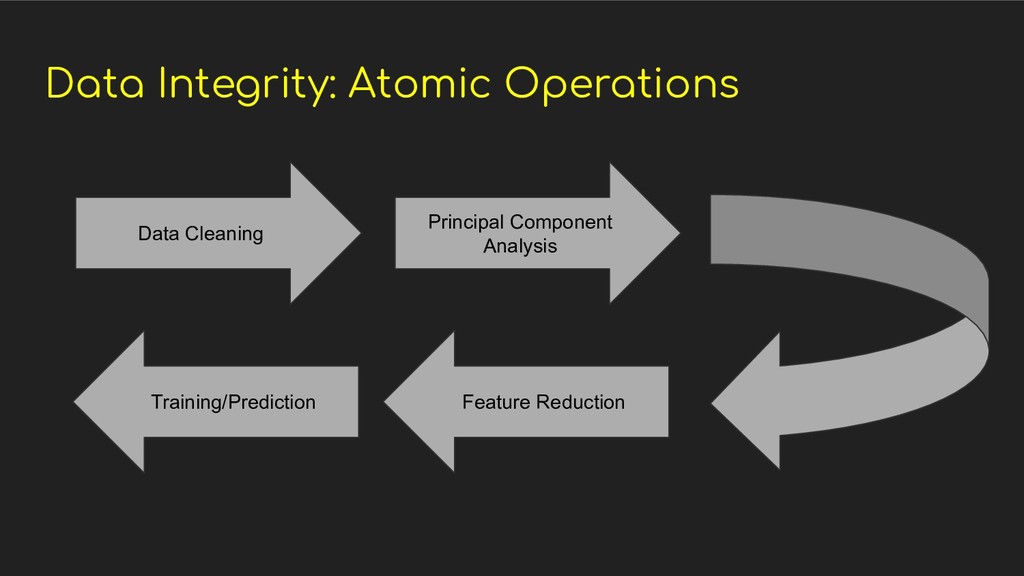
Data Integrity: Atomic Operations Data Cleaning Principal Component Analysis Feature
Reduction Training/Prediction -
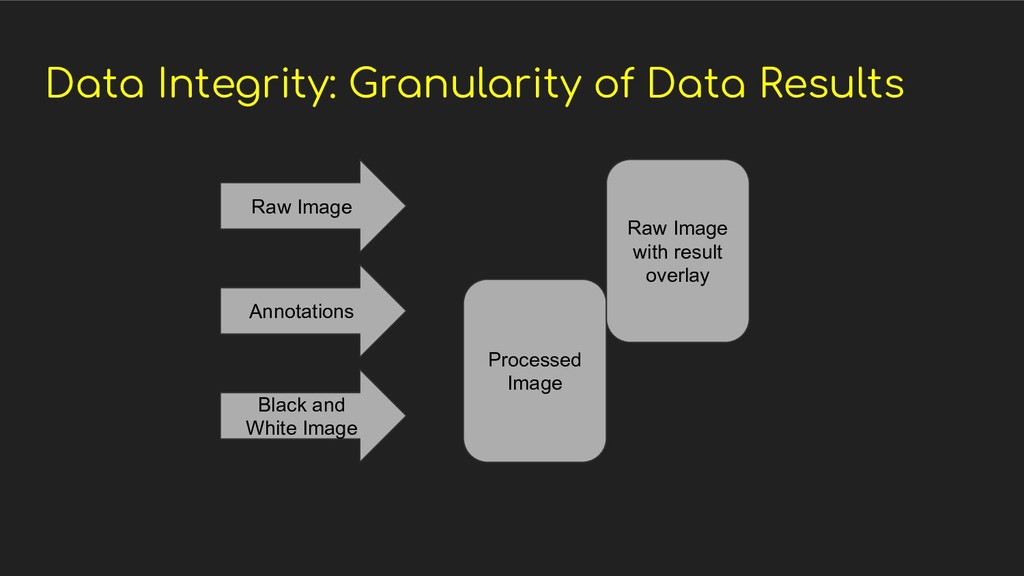
Data Integrity: Granularity of Data Results Raw Image Annotations Black
and White Image Processed Image Raw Image with result overlay -
Architectural Challenges • Memory vs CPU • CPU needed for
training • Memory needed for model storage • Consider the kind of algorithm the model uses • Sparse modeling usually performs well in smaller resource setup -
Architectural Challenges • Multithreading ◦ Good for memory bound algorithms
(Decision Trees) ◦ Easy to implement, much simpler • Multiprocessing ◦ Provides more throughput ◦ Better for algorithms with high CPU consumption (NN) ◦ A lot more difficult to implement -
Architectural Challenges • Software engineer must provide the “glue code”
for data scientists ◦ Utilize interfaces in python ◦ Class definitions -
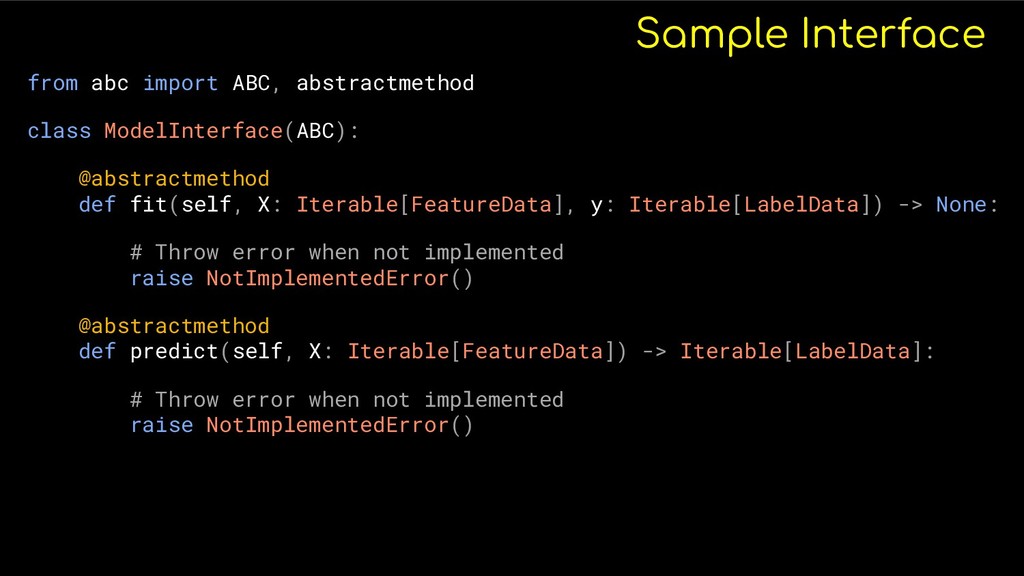
Sample Interface from abc import ABC, abstractmethod class ModelInterface(ABC): @abstractmethod
def fit(self, X: Iterable[FeatureData], y: Iterable[LabelData]) -> None: # Throw error when not implemented raise NotImplementedError() @abstractmethod def predict(self, X: Iterable[FeatureData]) -> Iterable[LabelData]: # Throw error when not implemented raise NotImplementedError() -
Sample Interface class MyModel(ModelInterface): def fit(self, X: Iterable[FeatureData], y: Iterable[LabelData])
-> None: self.model = RandomForestClassfier().fit(X, y) # Do some other stuff def predict(self, X: Iterable[FeatureData]) -> Iterable[LabelData]: result = self.model.predict(X) # Process result here return result -
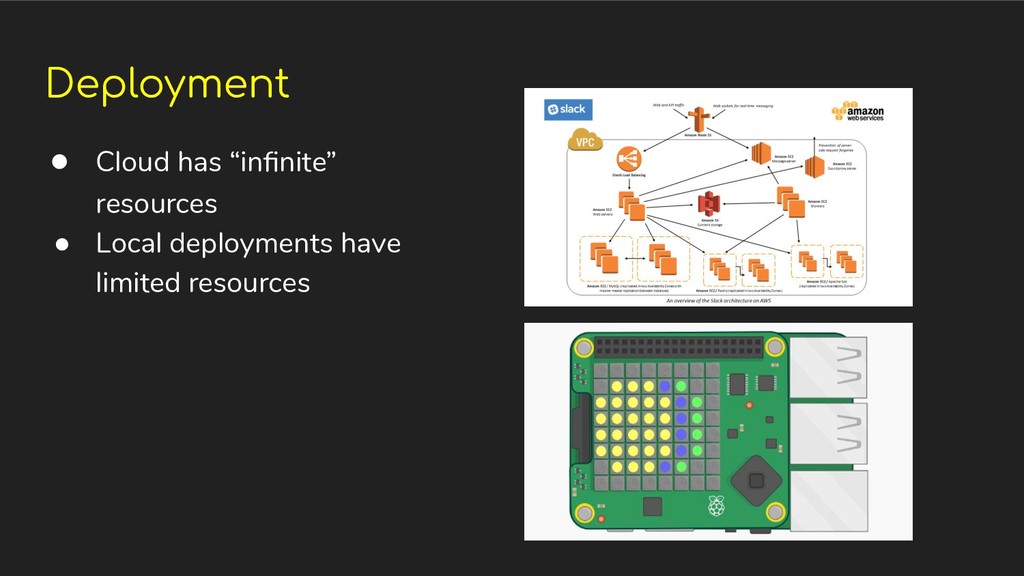
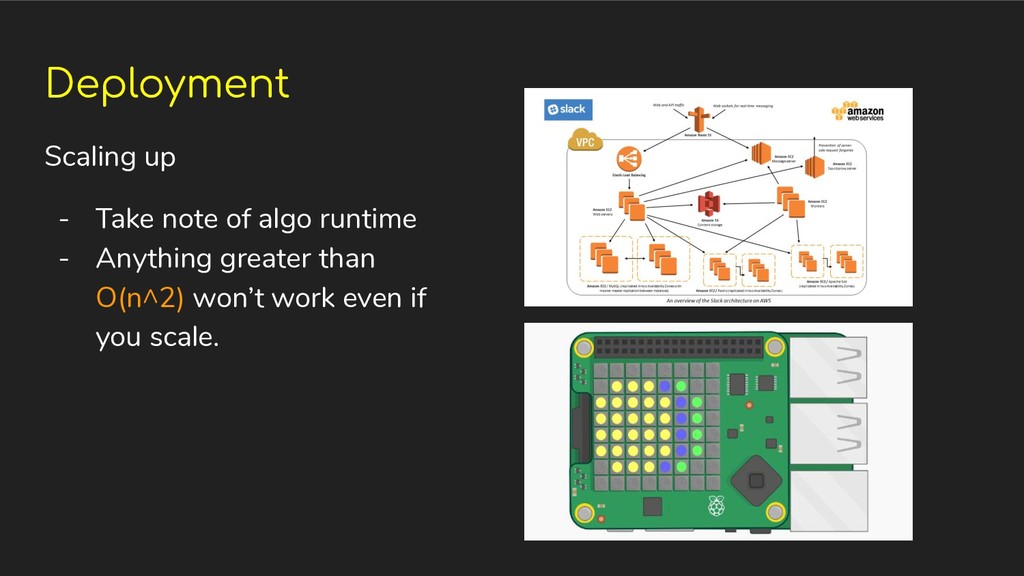
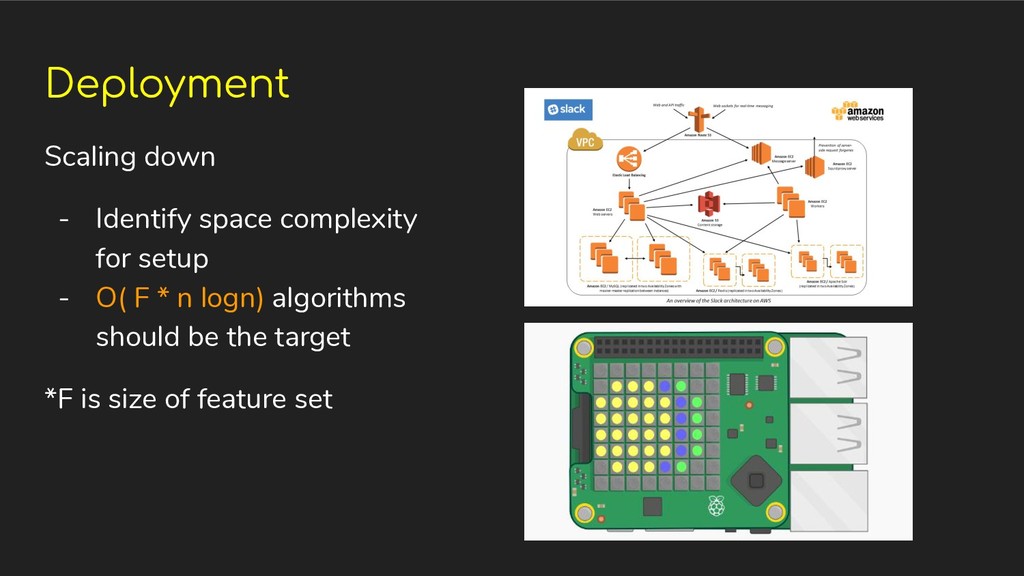
Deployment • Cloud has “infinite” resources • Local deployments have
limited resources -
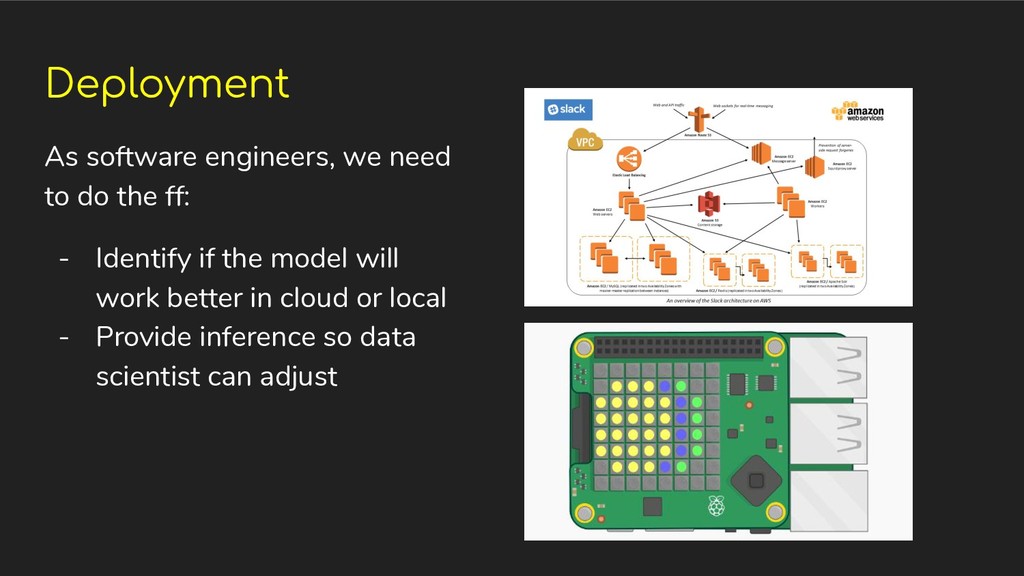
Deployment As software engineers, we need to do the ff:
- Identify if the model will work better in cloud or local - Provide inference so data scientist can adjust -
Deployment Scaling up - Take note of algo runtime -
Anything greater than O(n^2) won’t work even if you scale. -
Deployment Scaling down - Identify space complexity for setup -
O( F * n logn) algorithms should be the target *F is size of feature set -
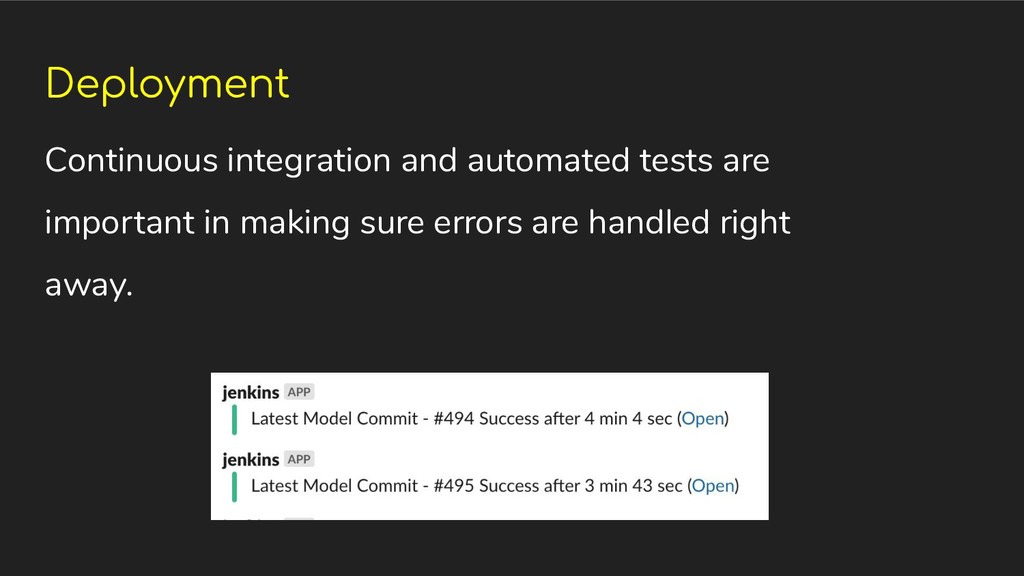
Deployment Continuous integration and automated tests are important in making
sure errors are handled right away. -
Shifting to Data Science • Formal study! Data Science has
LOTS OF MATH! ◦ Grad school offers data science courses ◦ Usually one year straight courses • Find related jobs ◦ Internships ◦ Data engineering is not data science but close enough :P -
Shifting to Data Science • Do research ◦ A lot
of research grants involve trainings, etc ◦ Good mentors in the form of PhD students ** Taking online tutorials and lessons are often not that good ** -
Software development Continuous addition of new features and usage -
import importlib.metadata, from concurrent.futures import ThreadPoolExecutor - Paradigm shifts - Functional support - Object oriented support - Rich library for application development - Micro service friendly structures -
Data Science Continuous addition of new features and usage -
Data classes - Support for data driven development - SUPER Extensive data science libraries - Easy to use for data scientist