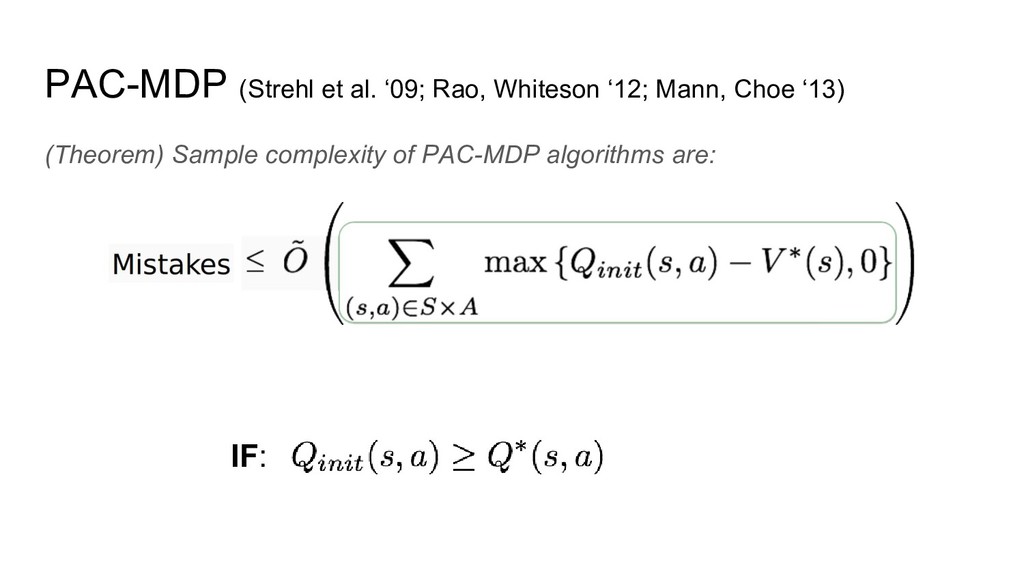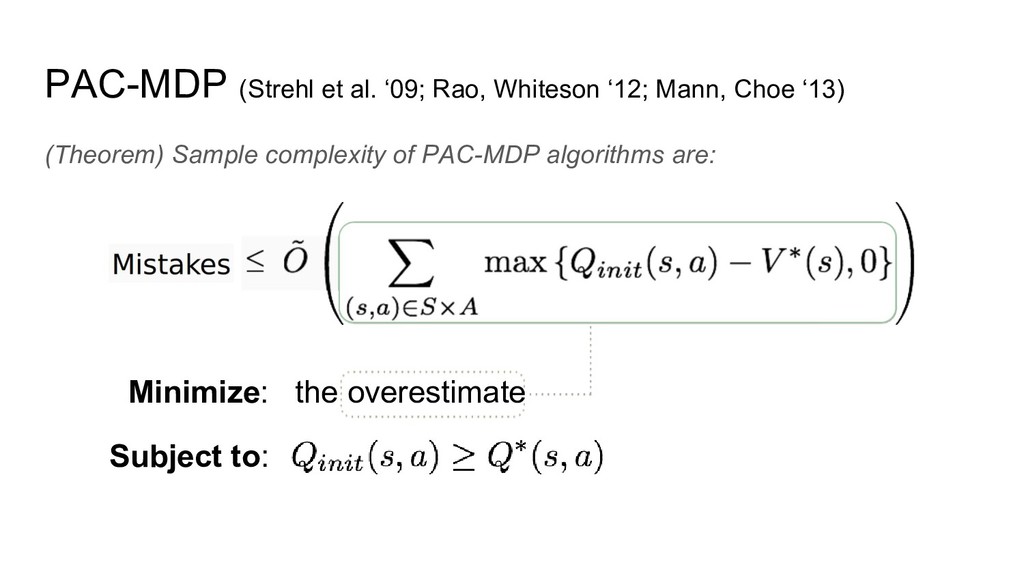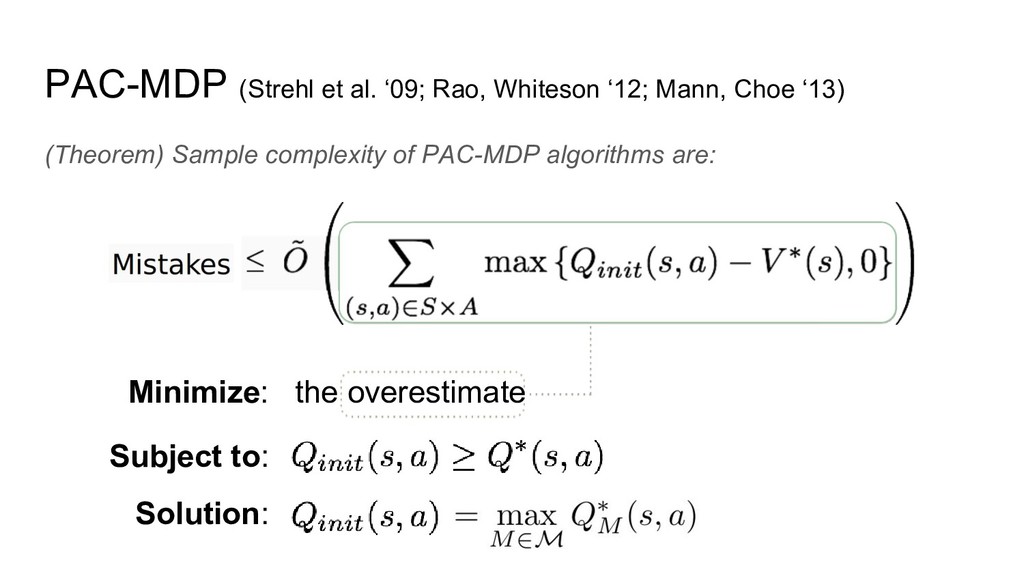Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
ICML2018読み会 Policy and Value Transfer in Lifelo...
Search
Yuu David Jinnai
July 28, 2018
Research
620
3
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
ICML2018読み会 Policy and Value Transfer in Lifelong Reinforcement Learning
Yuu David Jinnai
July 28, 2018
Other Decks in Research
See All in Research
マニアックセッション 〜次世代のメールプロトコルの斜め読み(2026年版)
hirachan
0
340
[webinaire du Ciirpo] Agnelages plein air : des éleveurs partagent leurs pratiques
institutdelelevage
PRO
0
310
Adapter les bergeries aux fortes chaleurs
institutdelelevage
PRO
0
170
20261101GISA-FOSS4G
tosseto
1
120
La longévité des troupeaux laitiers: état des lieux et perspectives
institutdelelevage
PRO
0
140
Byzantine Eventual Consistency for Reliable Local-First Software
ept
0
370
AI対話に何を挟むか ― 高回転対話・デジタル摘録・手書き記録による創造体験の違い|日本創造学会2026
ishiirikie
0
190
オンライン凸最適化の基礎とゲーム理論への応用 (IBIS 2026 チュートリアル)
taira_tsuchiya
2
1.4k
Prithvi-EO-2.0
satai
3
110
Empreinte carbone des ovins : une approche globale (technique, économique, environnementale) – 4 années de résultats avec LIFE GREEN SHEEP
institutdelelevage
PRO
0
150
Volatilité des marchés et sécheresse historique, l’élevage bovin viande sous contraintes en 2026
institutdelelevage
PRO
0
210
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
240
Featured
See All Featured
Evolving SEO for Evolving Search Engines
ryanjones
0
360
Unsuck your backbone
ammeep
672
58k
Pawsitive SEO: Lessons from My Dog (and Many Mistakes) on Thriving as a Consultant in the Age of AI
davidcarrasco
0
290
Design of three-dimensional binary manipulators for pick-and-place task avoiding obstacles (IECON2024)
konakalab
0
650
HTML-Aware ERB: The Path to Reactive Rendering @ RubyCon 2026, Rimini, Italy
marcoroth
5
900
A Tale of Four Properties
chriscoyier
163
24k
Fight the Zombie Pattern Library - RWD Summit 2016
marcelosomers
234
18k
The Anti-SEO Checklist Checklist. Pubcon Cyber Week
ryanjones
0
290
Game over? The fight for quality and originality in the time of robots
wayneb77
1
330
RailsConf & Balkan Ruby 2019: The Past, Present, and Future of Rails at GitHub
eileencodes
141
35k
YesSQL, Process and Tooling at Scale
rocio
174
15k
Docker and Python
trallard
47
4.3k
Transcript
Policy and Value Transfer in Lifelong Reinforcement Learning David Abel*,
Yuu Jinnai*, George Konidaris, Michael Littman, Yue Guo Brown University
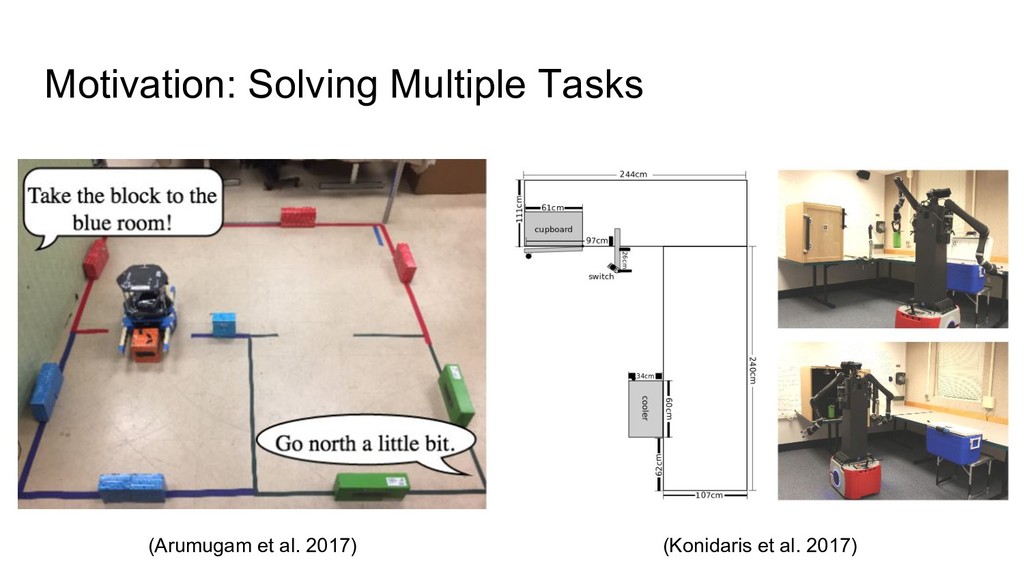
Motivation: Solving Multiple Tasks (Arumugam et al. 2017) (Konidaris et
al. 2017)
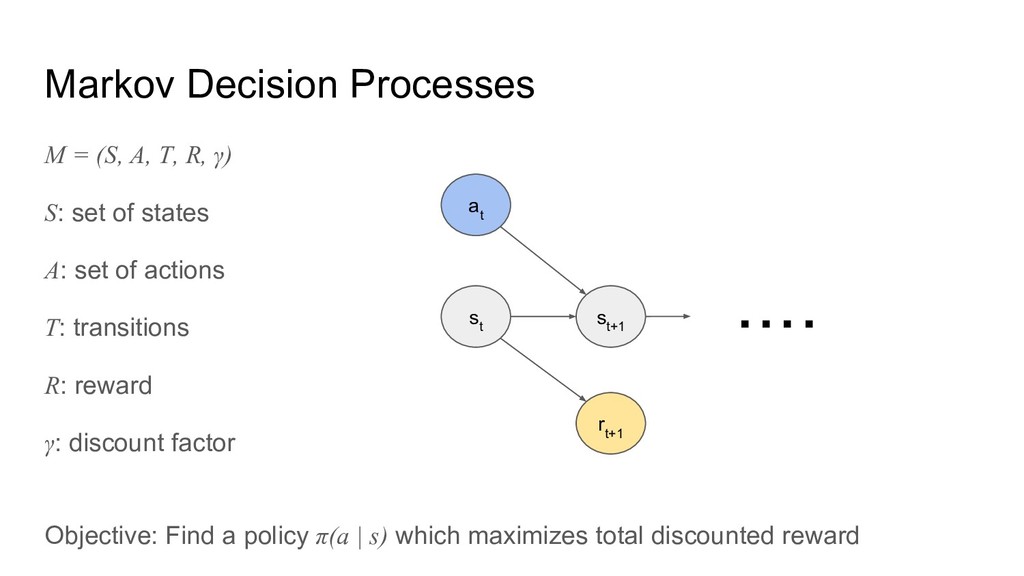
Markov Decision Processes M = (S, A, T, R, γ)
S: set of states A: set of actions T: transitions R: reward γ: discount factor Objective: Find a policy π(a | s) which maximizes total discounted reward s t s t+1 r t+1 a t ・・・・
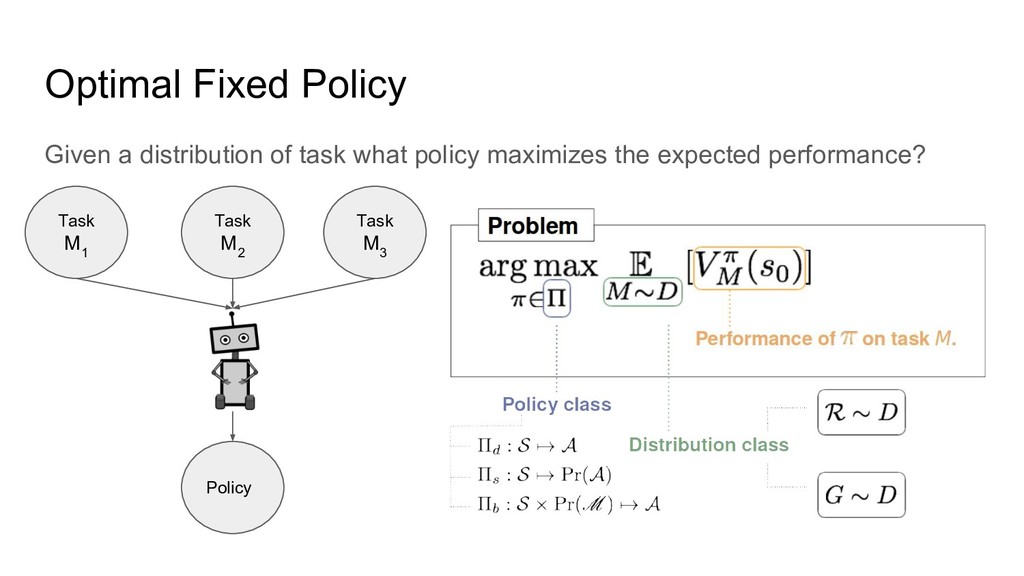
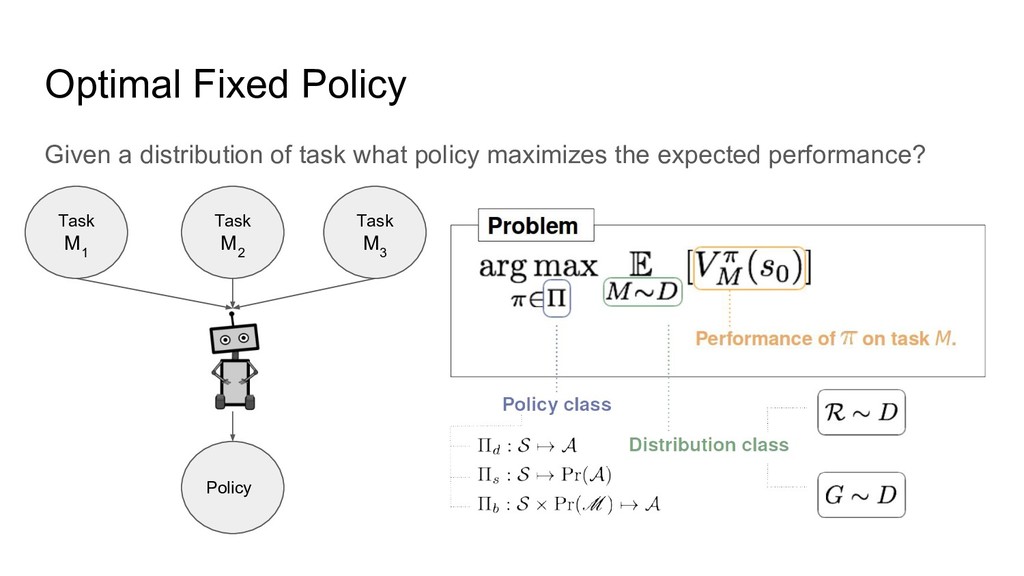
Optimal Fixed Policy Given a distribution of task what policy
maximizes the expected performance? Task M 1 Policy Task M 2 Task M 3
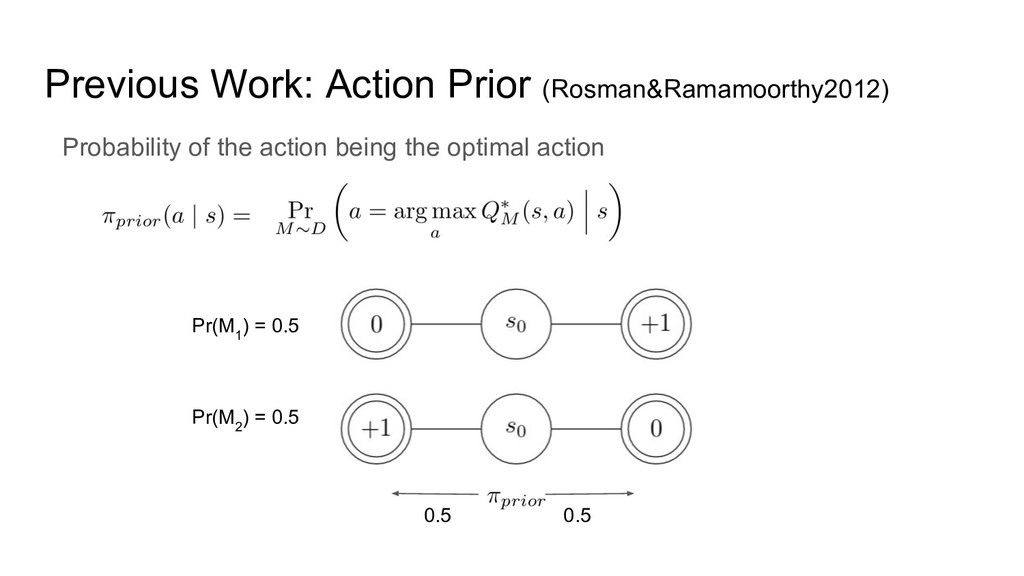
Previous Work: Action Prior (Rosman&Ramamoorthy2012) Pr(M 1 ) = 0.5
Pr(M 2 ) = 0.5 0.5 0.5 Probability of the action being the optimal action
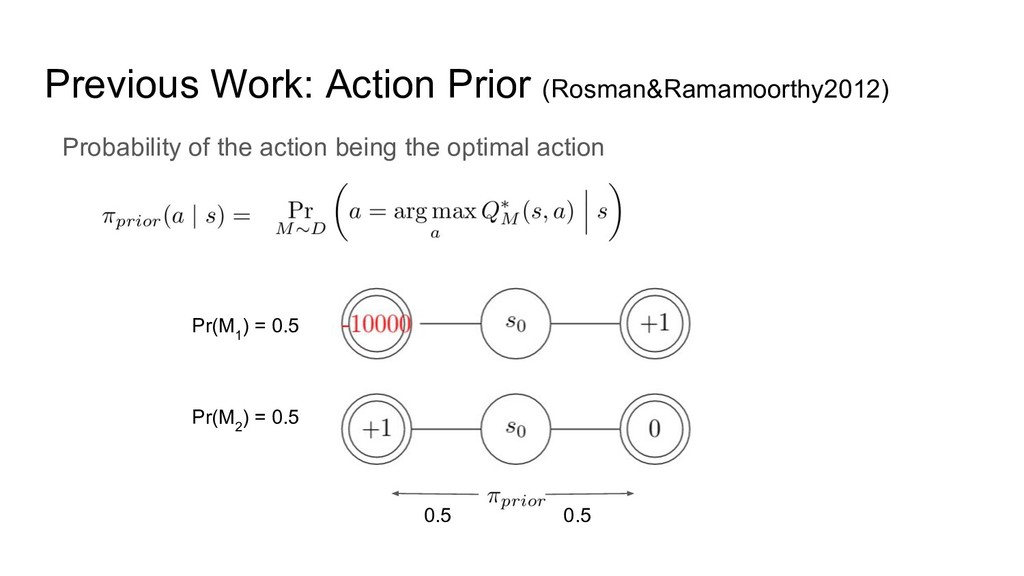
Pr(M 1 ) = 0.5 Pr(M 2 ) = 0.5
Probability of the action being the optimal action Previous Work: Action Prior (Rosman&Ramamoorthy2012) 0.5 0.5
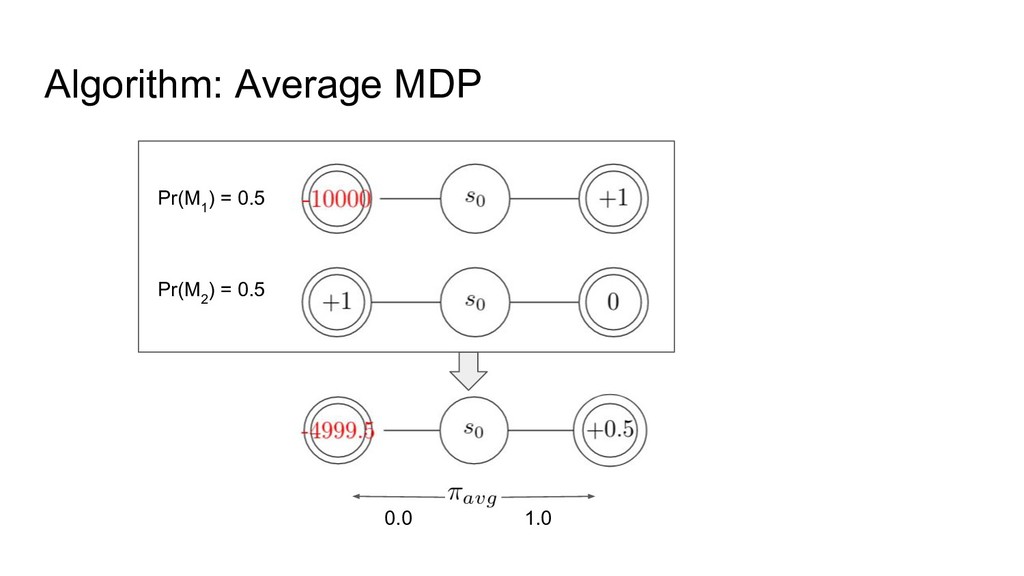
Algorithm: Average MDP Pr(M 1 ) = 0.5 Pr(M 2
) = 0.5 0.0 1.0
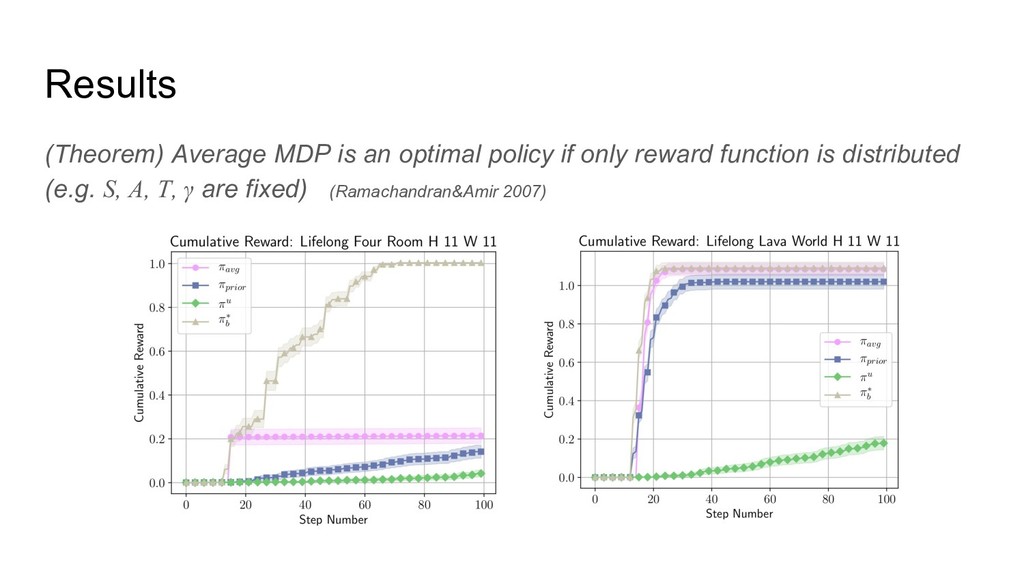
(Theorem) Average MDP is an optimal policy if only reward
function is distributed (e.g. S, A, T, γ are fixed) (Ramachandran&Amir 2007) Results
Optimal Fixed Policy Given a distribution of task what policy
maximizes the expected performance? Task M 1 Policy Task M 2 Task M 3
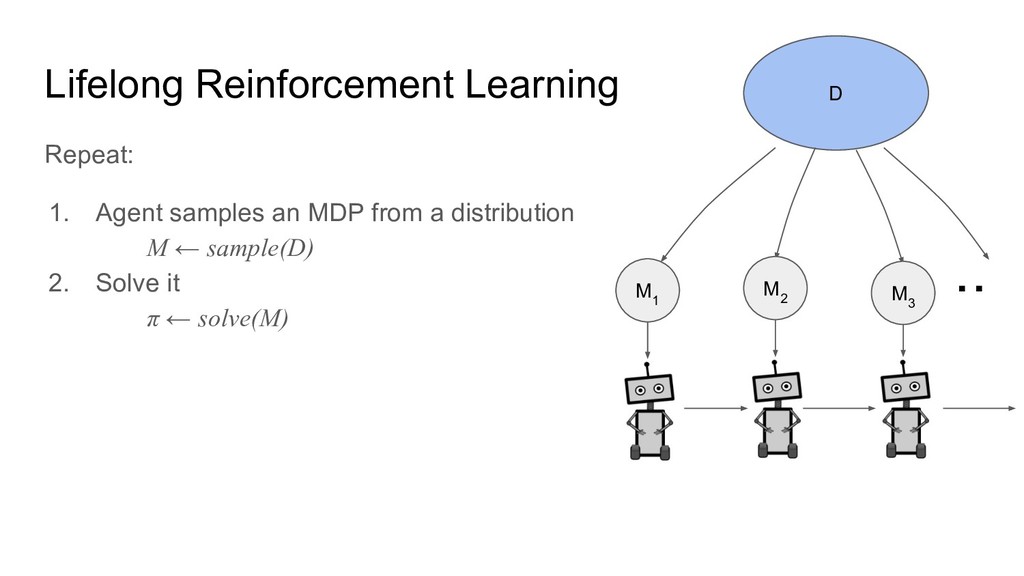
Lifelong Reinforcement Learning D ・・ Repeat: 1. Agent samples an
MDP from a distribution M ← sample(D) 2. Solve it π ← solve(M) M 1 M 2 M 3
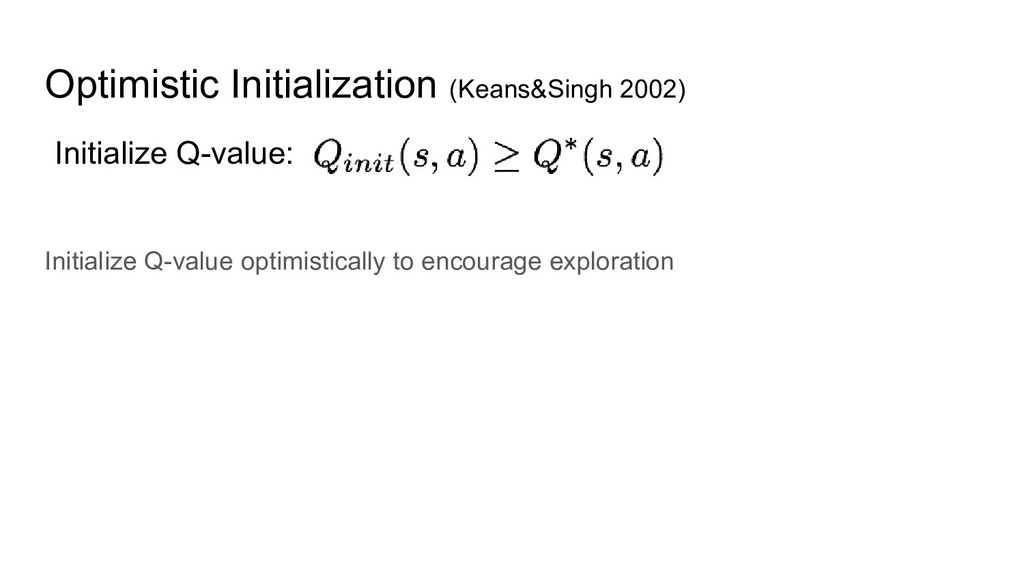
Optimistic Initialization (Keans&Singh 2002) Initialize Q-value: Initialize Q-value optimistically to
encourage exploration
PAC-MDP (Strehl et al. ‘09; Rao, Whiteson ‘12; Mann, Choe
‘13) (Theorem) Sample complexity of PAC-MDP algorithms are: IF:
PAC-MDP (Strehl et al. ‘09; Rao, Whiteson ‘12; Mann, Choe
‘13) (Theorem) Sample complexity of PAC-MDP algorithms are: Minimize: the overestimate Subject to:
PAC-MDP (Strehl et al. ‘09; Rao, Whiteson ‘12; Mann, Choe
‘13) (Theorem) Sample complexity of PAC-MDP algorithms are: Minimize: the overestimate Subject to: Solution:
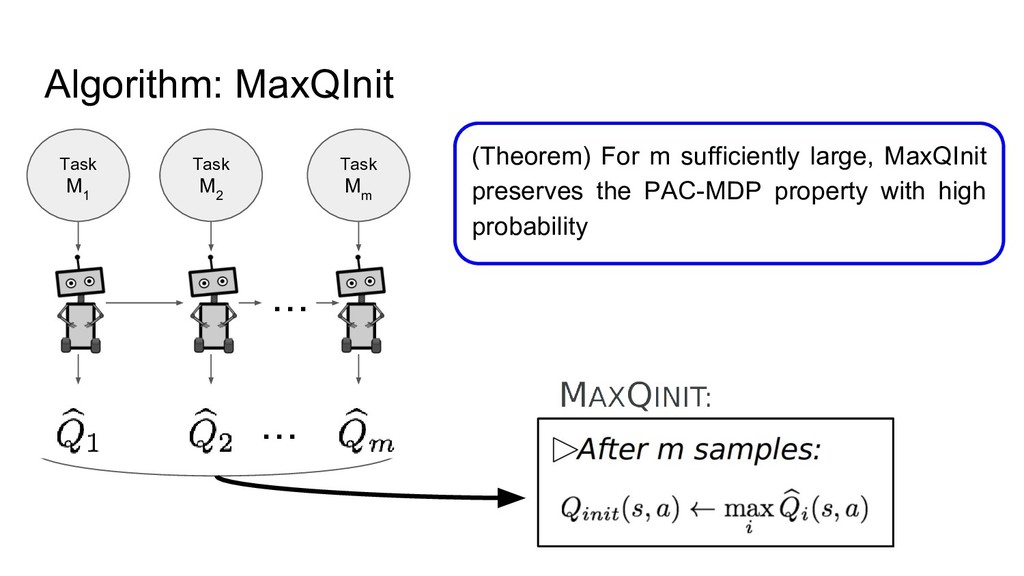
Algorithm: MaxQInit Task M 1 Task M 2 ・・・ Task
M m ・・・ (Theorem) For m sufficiently large, MaxQInit preserves the PAC-MDP property with high probability
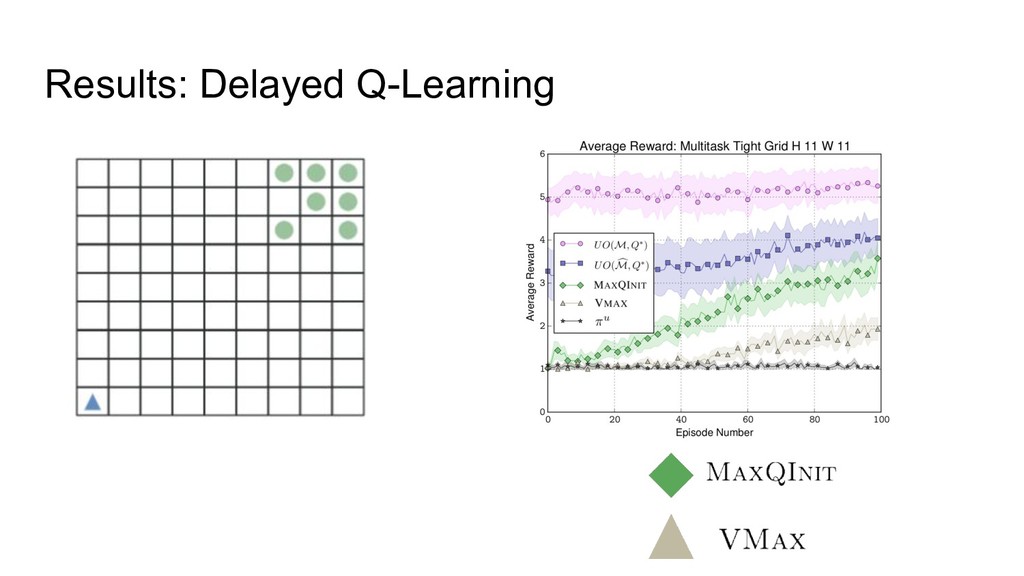
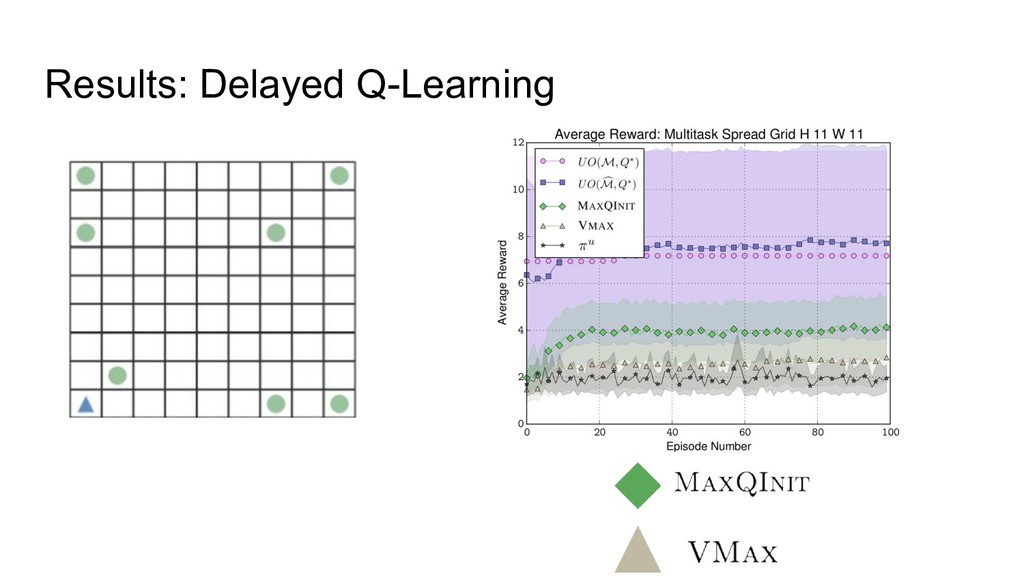
Results: Delayed Q-Learning
Results: Delayed Q-Learning
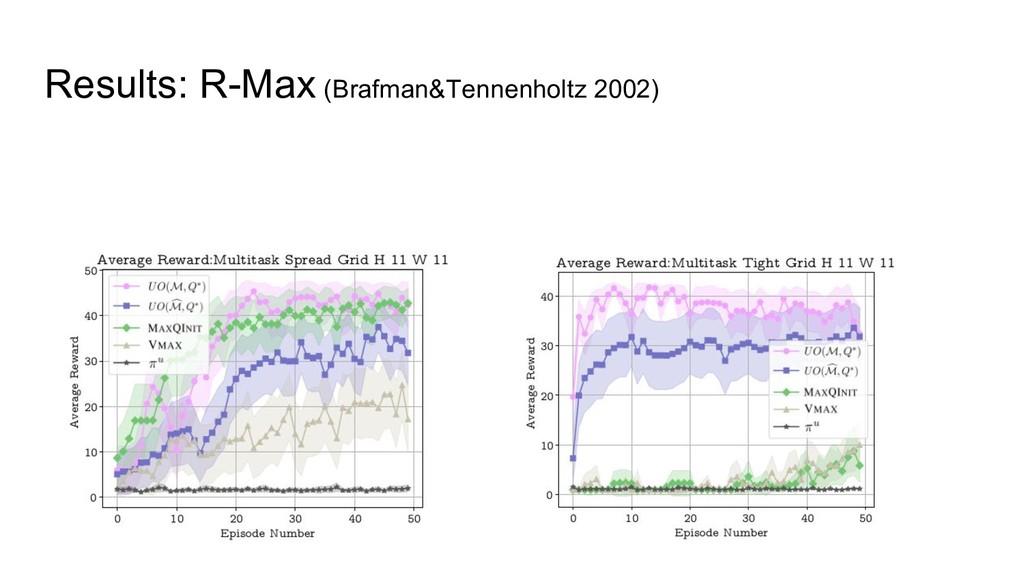
Results: R-Max (Brafman&Tennenholtz 2002)
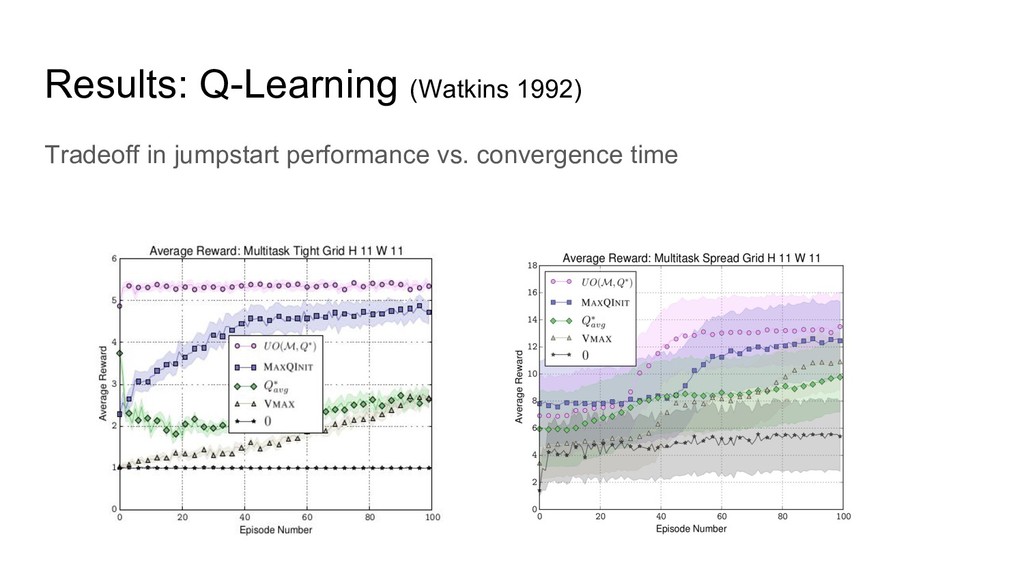
Results: Q-Learning (Watkins 1992) Tradeoff in jumpstart performance vs. convergence
time
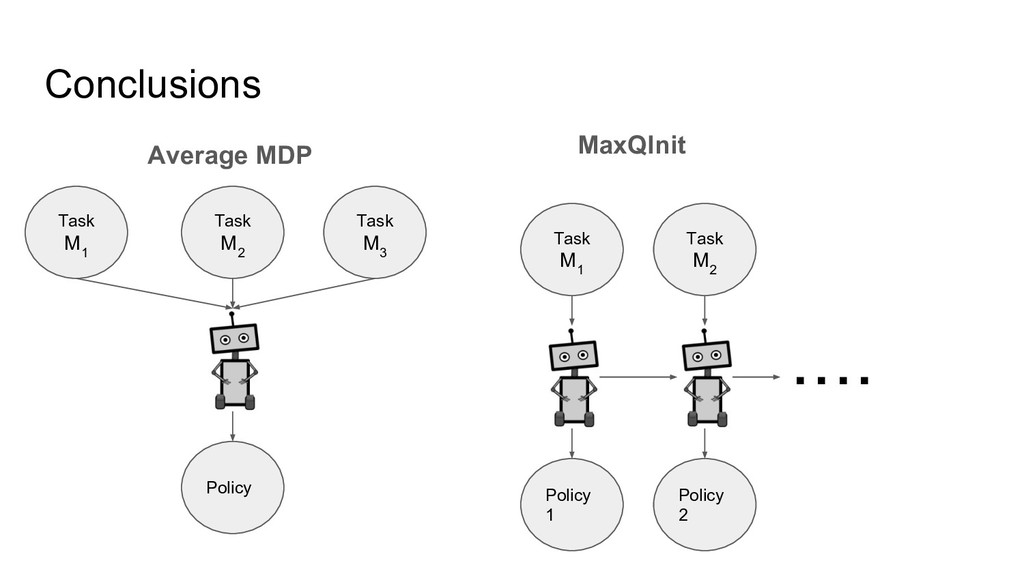
Conclusions Average MDP Task M 1 Policy 1 Task M
2 Policy 2 ・・・・ MaxQInit Task M 1 Policy Task M 2 Task M 3


 hirachan
 institutdelelevage
 tosseto
 ept
 ishiirikie
 taira_tsuchiya
 satai
 rikkabotan7
 ryanjones
 ammeep
 davidcarrasco
 konakalab
 marcoroth
 chriscoyier
 marcelosomers
 wayneb77
 eileencodes
 rocio
 trallard