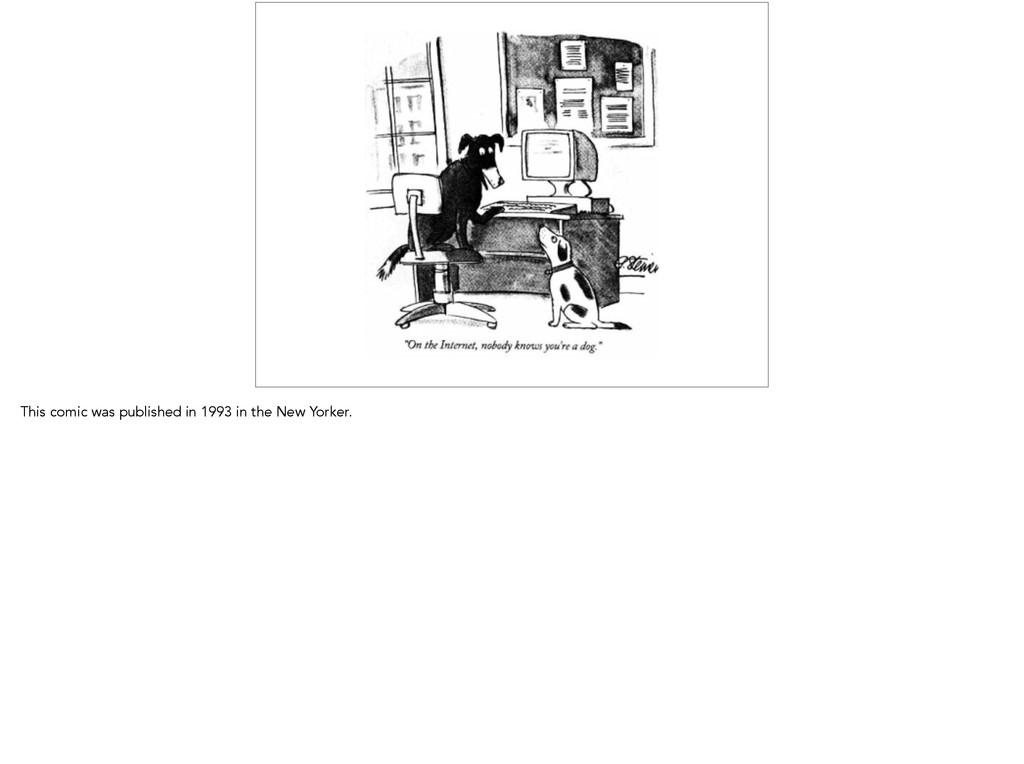
on trusty URIs. My name is Jonathan Wallace and I’m going to share how we can bring trust back to the internet. This talk is based on a paper written by Tobias Kuhn and Michel Dumontier.
authors bring up the context of nano-publications in scientific publishing. I don’t know anything about this arena but the scientific community cares about verifiability, immutability and permanence.
you know that the United States Supreme Court engages in retconning. If you’re not familiar with the term, this means that the Supreme Court will issue a decision at point t.
future point in time t + x, when they issue another decision, they will go back and change the content of their decision at point t to ensure continuity and conceptual integrity with their decision at the original point t. This matters.
by painstaking comparison of early versions of decisions to ones published years later.” http://www.nytimes.com/2014/05/25/us/final-word-on-us- law-isnt-supreme-court-keeps-editing.html?_r=0 Wouldn’t it be great if you didn’t have to do painstaking comparisons by hand?
this for us w/r/t the Supreme Court. But how are you supposed to know when changes have occurred? Wouldn’t it be great to know that the law has changed by examining tiny little hash outputs? Or that a web page has changed by examining tiny little hash outputs?
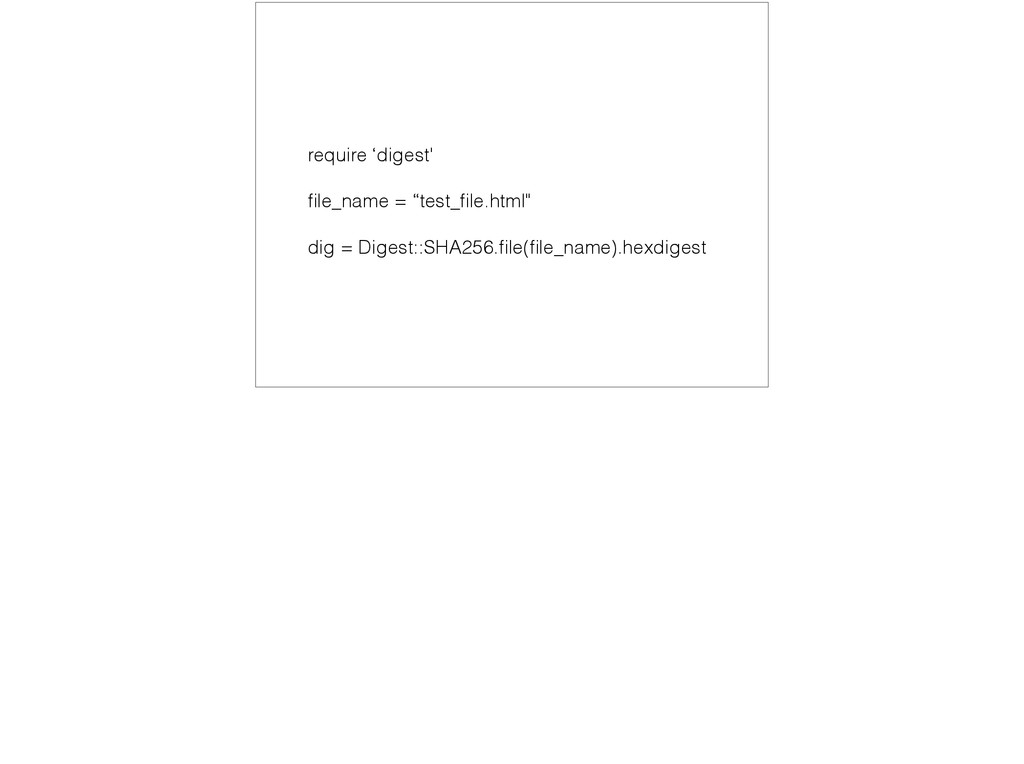
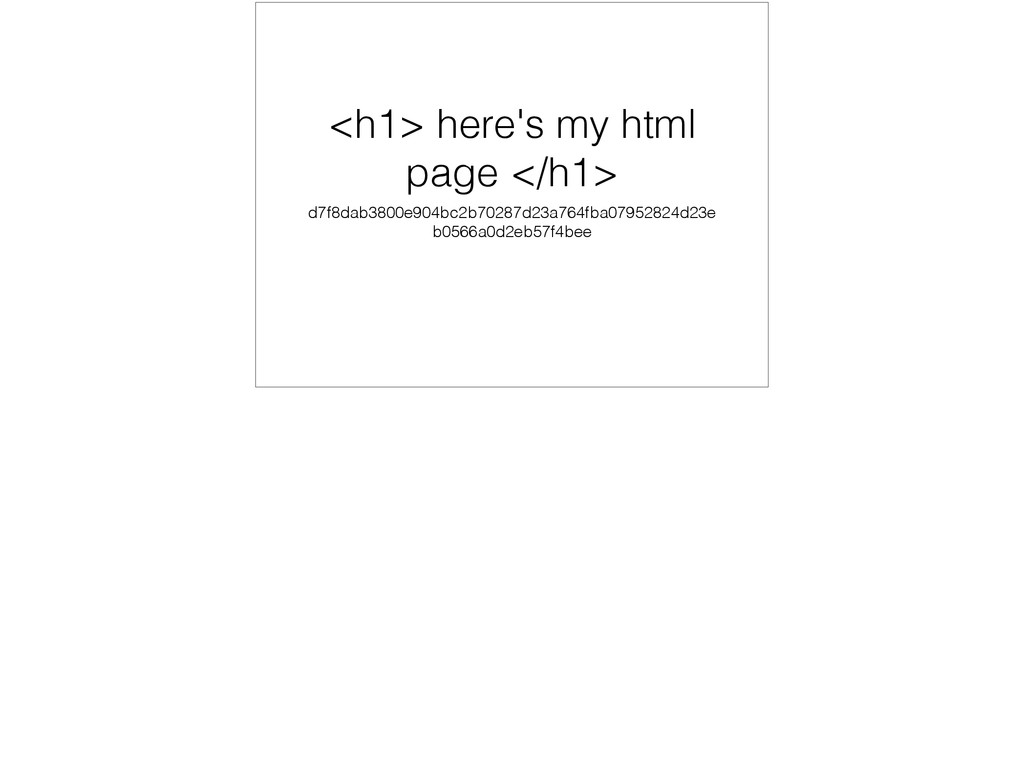
a hash algorithm is some code that takes a bunch input and converts it into a small piece of output. If you change one tiny piece of the input, the small output will change greatly.
is hard, if not impossible to determine the input. That makes a good hash algorithm. So to say a URI is verifiable means that you can compute the hash output for the content of the URI.
know that search engines crawl the web and cache content. By examining the cached URI, we’ll have “permanence.” In other words, if the original location is no longer available, we’ll have other places to retrieve the content.
We’re going to focus on byte content of files though the authors go into detail about RDF, something with which I don’t have a ton of experience. There’s two parts to the trusty URI that are relevant.
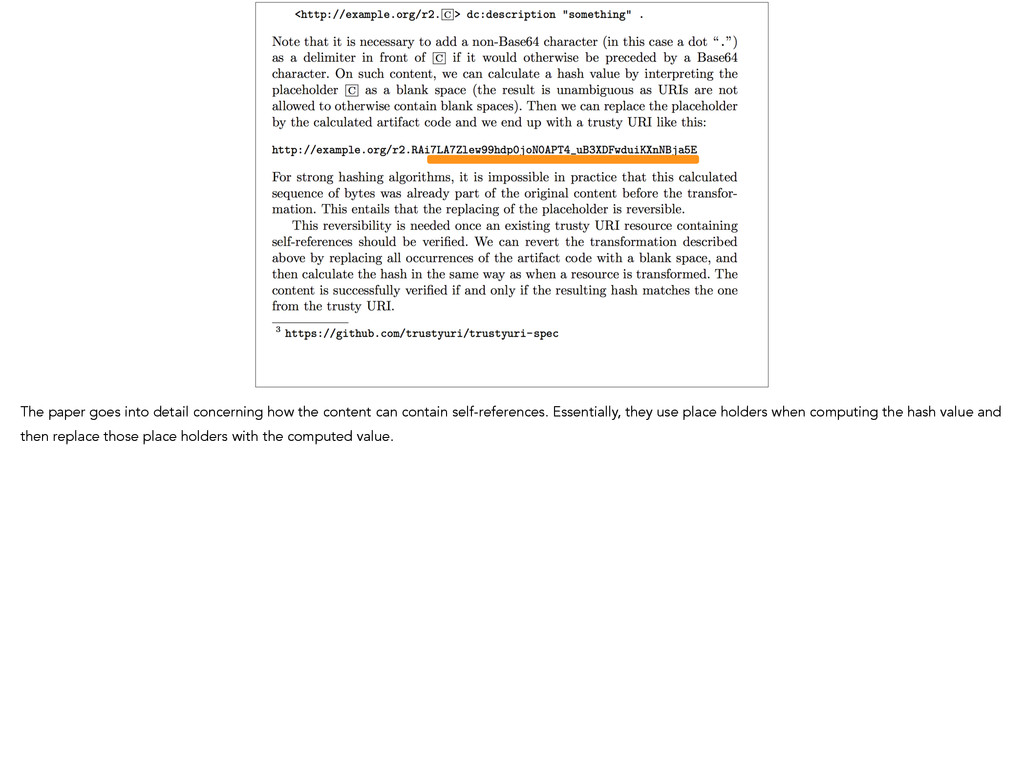
can contain self-references. Essentially, they use place holders when computing the hash value and then replace those place holders with the computed value.
hidden-changes-to-supreme-court-opinions/ • http://2014.eswc-conferences.org/sites/default/files/papers/ paper_106.pdf • http://en.wikipedia.org/wiki/On_the_Internet,_nobody_knows_you %27re_a_dog Check out the github organization. They have perl, python and java implementations. I was hoping to have a ruby version completed by this talk but I’m not quite there yet.


 jwallace
 yappli_developers
 takuyay0ne
 wadayusuke
 inariku
 jacopen
 ykimi
 fortegp05
 z63d
 say_no_w
 reverentgeek
 akademiya2063
 maltzj
 rasagy
 sergeychernyshev
 aleyda
 szymonslowik
 baasie
 cassininazir
 philnash
 morganepeng
 bermonpainter