Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Segmentation-Free Word Embedding for Unsegmente...
Search
katsutan
August 27, 2018
Technology
150
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Segmentation-Free Word Embedding for Unsegmented Languages ∗
文献紹介 勝田 哲弘
http://aclweb.org/anthology/D17-1080
katsutan
August 27, 2018
More Decks by katsutan
See All by katsutan
What does BERT learn about the structure of language?
katsutan
0
280
Simple and Effective Paraphrastic Similarity from Parallel Translations
katsutan
0
240
Simple task-specific bilingual word embeddings
katsutan
0
250
Retrofitting Contextualized Word Embeddings with Paraphrases
katsutan
0
300
Character Eyes: Seeing Language through Character-Level Taggers
katsutan
1
250
Improving Word Embeddings Using Kernel PCA
katsutan
0
250
Better Word Embeddings by Disentangling Contextual n-Gram Information
katsutan
0
370
Rotational Unit of Memory: A Novel Representation Unit for RNNs with Scalable Applications
katsutan
0
300
A robust self-learning method for fully unsupervised cross-lingual mappings of word embeddings
katsutan
0
320
Other Decks in Technology
See All in Technology
「事実」を「計測」して、「解釈」する 〜AWS Lambdaのメモリ最適解の見つけ方〜
maimyyym
0
170
『SAR衛星データ解析入門』の ご紹介とその応用
syuchimu
0
120
Rust で関数型ドメインモデリング
takonda
0
140
大型犬好きによるPugの紹介
yamanoku
1
160
1つのリクエストを追って理解する - llm-dのP/D分離
akhino
1
160
re:Invent初参加で変わったこと、2回目にやってみたいこと(JAWS-UG彩の国埼玉 #12)
mhrtech
2
230
[JAWS-UG彩の国埼玉#12]そろそろ準備する?re:Invent2026をやさしく解説 / reinvent2026-sainokuni
sh_fk2
1
340
S3 Filesで挑む! 八戸せんべい汁の食べ頃問題
usanchuu
0
100
Metadata - Section 1: HTML Basics
mohab1
0
120
Rustuna: Rustによる高速なOptuna実装
pfn
PRO
0
190
AI駆動で「他アプリの音を加工できる」アプリを作った
satomasahiro2005
0
150
AI コーディングと人間の認知スループット / CTO Night & Day 2026 Morning Session / AI Coding and Human Cognitive Throughput
prog893
4
1.1k
Featured
See All Featured
Visualization
eitanlees
153
17k
Taking LLMs out of the black box: A practical guide to human-in-the-loop distillation
inesmontani
PRO
3
2.5k
Sharpening the Axe: The Primacy of Toolmaking
bcantrill
46
3k
Let's Do A Bunch of Simple Stuff to Make Websites Faster
chriscoyier
508
140k
Claude Code のすすめ
schroneko
67
230k
Navigating Algorithm Shifts & AI Overviews - #SMXNext
aleyda
1
1.7k
The agentic SEO stack - context over prompts
schlessera
0
970
Large-scale JavaScript Application Architecture
addyosmani
516
110k
Building Experiences: Design Systems, User Experience, and Full Site Editing
marktimemedia
1
630
[RailsConf 2023] Rails as a piece of cake
palkan
59
7.1k
jQuery: Nuts, Bolts and Bling
dougneiner
66
8.6k
Producing Creativity
orderedlist
PRO
348
41k
Transcript
Segmentation-Free Word Embedding for Unsegmented Languages ∗ Takamasa Oshikiri Proceedings
of the 2017 Conference on Empirical Methods in Natural Language Processing, pages 767–772 長岡技術科学大学 自然言語処理研究室 修士1年 勝田 哲弘
Abstract • 単語分割されていない言語に対して、前処理として単語分割を必要としない単語ベ クトルの獲得方法の提案 ◦ segmentation-free word embedding • 基本的に、中国語や日本語のようにスペースで区切られない言語では単語の分割
が必要になるが、人手によるリソースが必要になる。 • 文字ngramによる共起情報をもとに分割を行い、Twitter、Weibo、Wikipediaでの 名詞カテゴリ予測タスクでは、従来のアプローチより優れていることが示されていま す。
Introduction • NLPでは大規模なコーパスから単語ベクトルを獲得するword embeddingが注目さ れている。前処理としてセグメントが必要。 ◦ 英語やスペイン語などの言語では、単純なルールベースと共起ベースのアプローチがとられる。 ◦ 中国語、日本語、タイ語などのセグメント化されていない言語では、機械学習ベースのアプローチ がNLPで広く使用されています。(
Kudo et al。、2004; Tseng et al。、2005) ▪ 辞書が必要、固有名詞が苦手 • 文字nグラムに基づいて可能なすべてのセグメント化を列挙し、共起頻度からnグラ ム・ベクトルを学習する 枠組みを提案
Related Work セグメントに依存しないモデル • character-based RNN model ◦ Dhingra et
al. (2016) • learns n-gram vectors from the corpus that segmented randomly ◦ Schütze (2017) これらの手法は、テキストまたは系列のベクトル表現を学習することを目的としている。
Conventional Approaches to Word Embeddings skip-gram model with negative sampling
(SGNS) (Mikolov et al., 2013) 以下の単語、コンテキストの目的関数を最小にするベクトルの学習を行う。
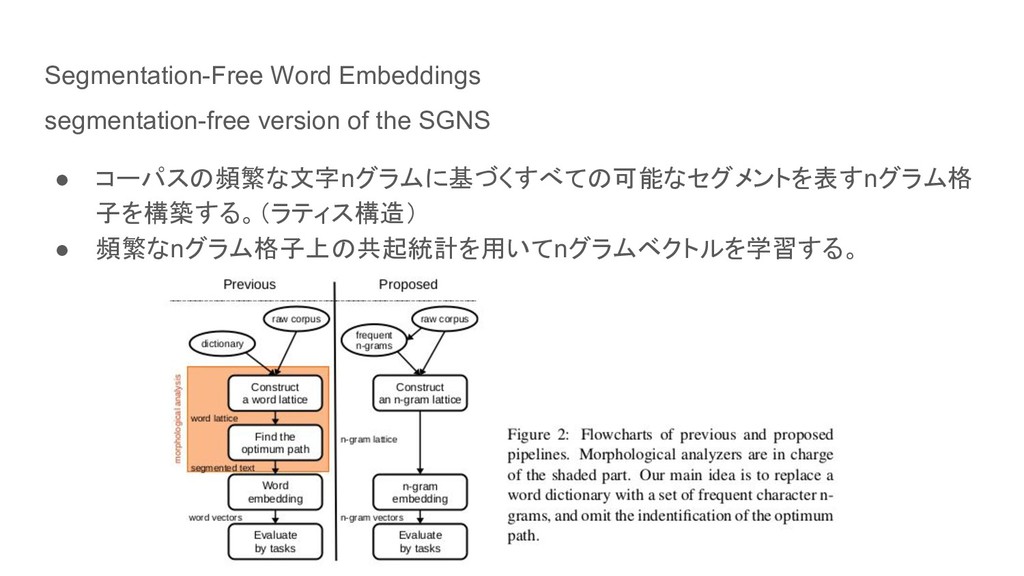
Segmentation-Free Word Embeddings segmentation-free version of the SGNS • コーパスの頻繁な文字nグラムに基づくすべての可能なセグメントを表すnグラム格
子を構築する。(ラティス構造) • 頻繁なnグラム格子上の共起統計を用いてnグラムベクトルを学習する。
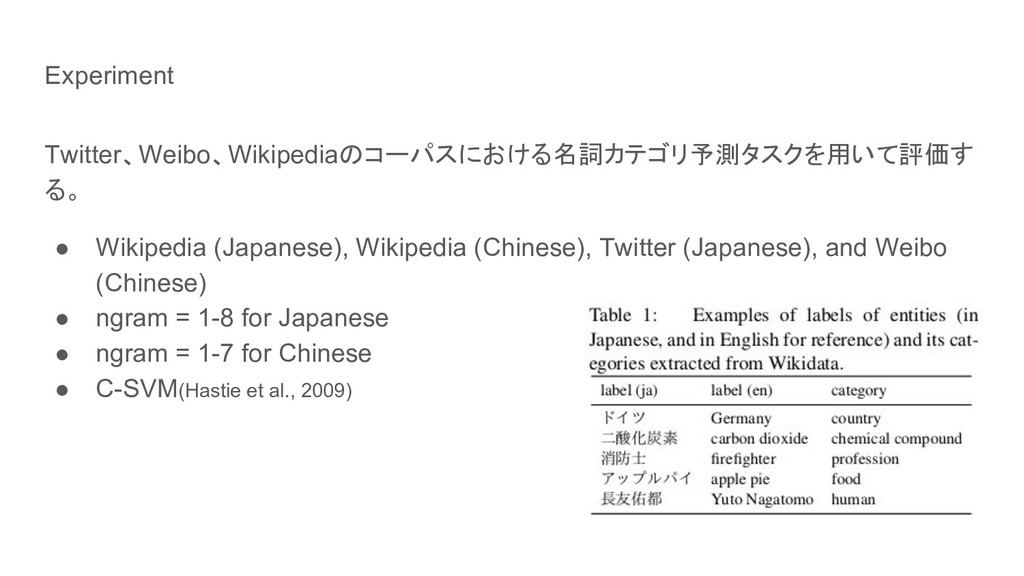
Experiment Twitter、Weibo、Wikipediaのコーパスにおける名詞カテゴリ予測タスクを用いて評価す る。 • Wikipedia (Japanese), Wikipedia (Chinese), Twitter (Japanese),
and Weibo (Chinese) • ngram = 1-8 for Japanese • ngram = 1-7 for Chinese • C-SVM(Hastie et al., 2009)
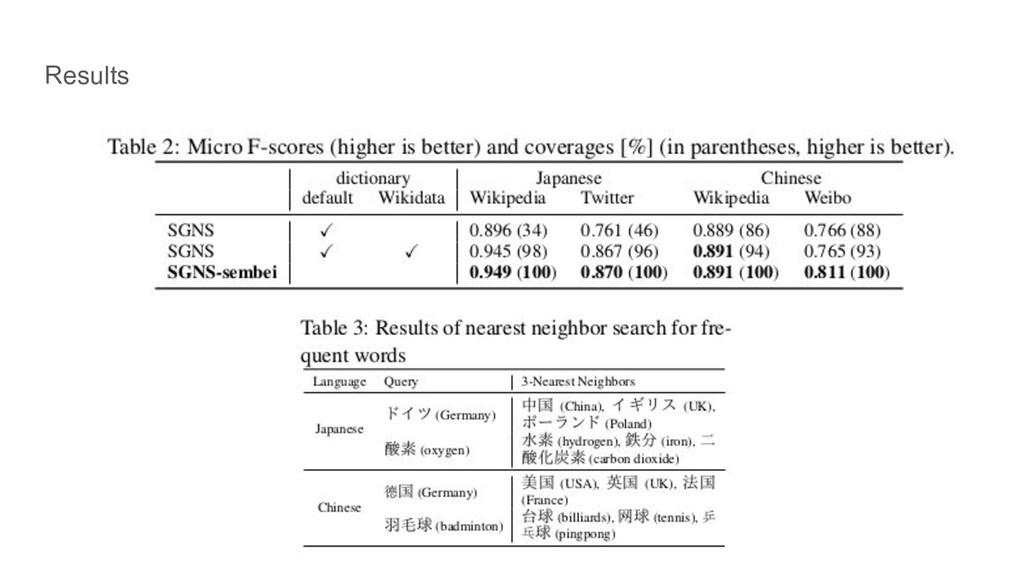
Results
Conclusion • 人手でアノテーションされたリソースに依存しない手法でその リソースに依存する手法を上回った。 • 将来的には別の手法を活用する ◦ the Stanford Word
Segmenter (Tseng et al., 2005) with k-best segmentations


 katsutan
 maimyyym
 syuchimu
 takonda
 yamanoku
 akhino
 mhrtech
 sh_fk2
 usanchuu
 mohab1
 pfn
 satomasahiro2005
 prog893
 eitanlees
 inesmontani
 bcantrill
 chriscoyier
 schroneko
 aleyda
 schlessera
 addyosmani
 marktimemedia
 palkan
 dougneiner
 orderedlist