Share
Embed
"Full Stack" Data Science with R
Gabriela de Queiroz
June 06, 2017
Transcript
18 slides
-
"Full Stack" Data Science with R Production data science &
engineering with open source tools Gabriela de Queiroz Ajay Gopal -
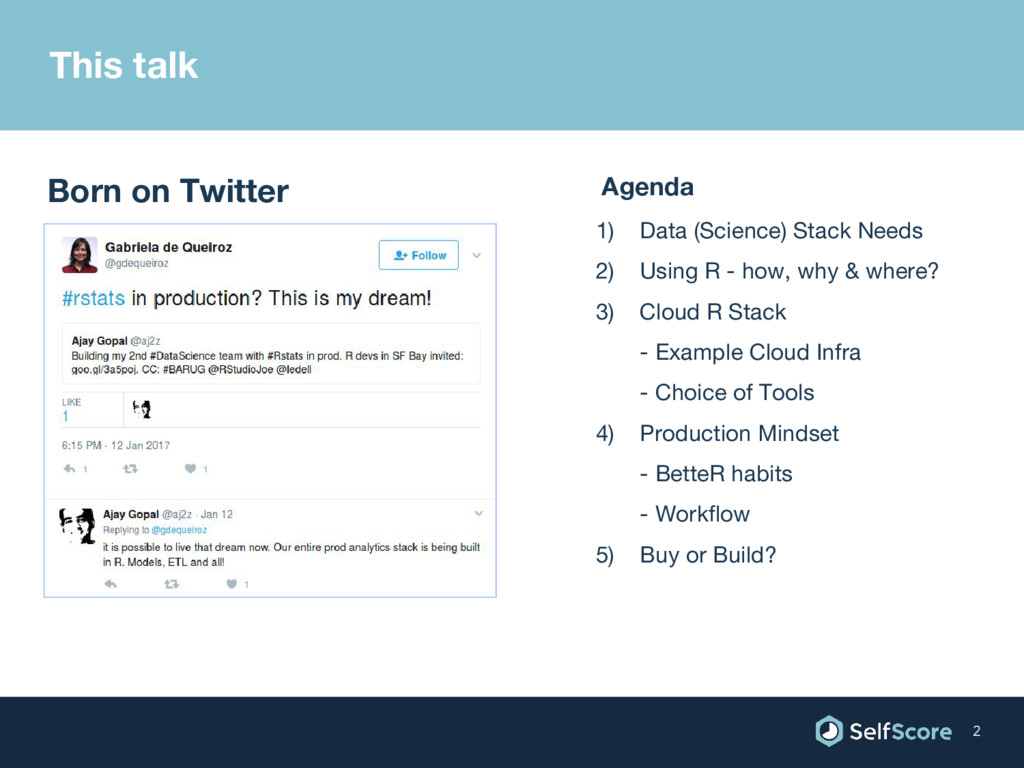
Agenda 1) Data (Science) Stack Needs 2) Using R -
how, why & where? 3) Cloud R Stack - Example Cloud Infra - Choice of Tools 4) Production Mindset - BetteR habits - Workflow 5) Buy or Build? This talk Born on Twitter 2 -
Gabriela de Queiroz Lead Data Scientist / : gdequeiroz First
met R: 2007 Ajay Gopal, PhD Chief Data Scientist : ajzz : @aj2z First met R: 2011 About us 3 -
What’s SelfScore? 4 Industry: FinTech Startup, Menlo Park, CA What
we do: use ML models with alternative financial signals to help deserving but underserved populations gain access to fair credit, starting with international students (2 products in market). Differentiator: Measure borrower’s credit potential instead of their credit history (SSN / FICO etc) Team: ~25 & growing (hiring local Sr R Data Engineer, Summer Intern) Funding: Series B Founded: 2013 -
The “Full Stack” Analogy 5 Front End Back End Data
Store Devops APIs UX Technology Puppet, Chef, Ansible, AWS EC2, Docker, ECS/GCE, Heroku MySQL, PostGres, MongoDB, Redis, MemCached etc. PHP, JS, Python, Ruby, ORMs, CI, Git Restify, Django, Rails, ASP.net, Lambda HTML/CSS, JS (Node, React), Bootstrap, iOS, Android, Ionic, Cordoba Email (SendGrid), SMS (Twilio), Push (SNS, Firebase), Msg Frmwks Function Multi-Channel Engagement Optimal Service Delivery Platform-agnostic function & information availability Business Logic Identities, Attribs, Relations Scaleable Services & Contingencies Goal: Scalable, Engaging, Valuable Service -
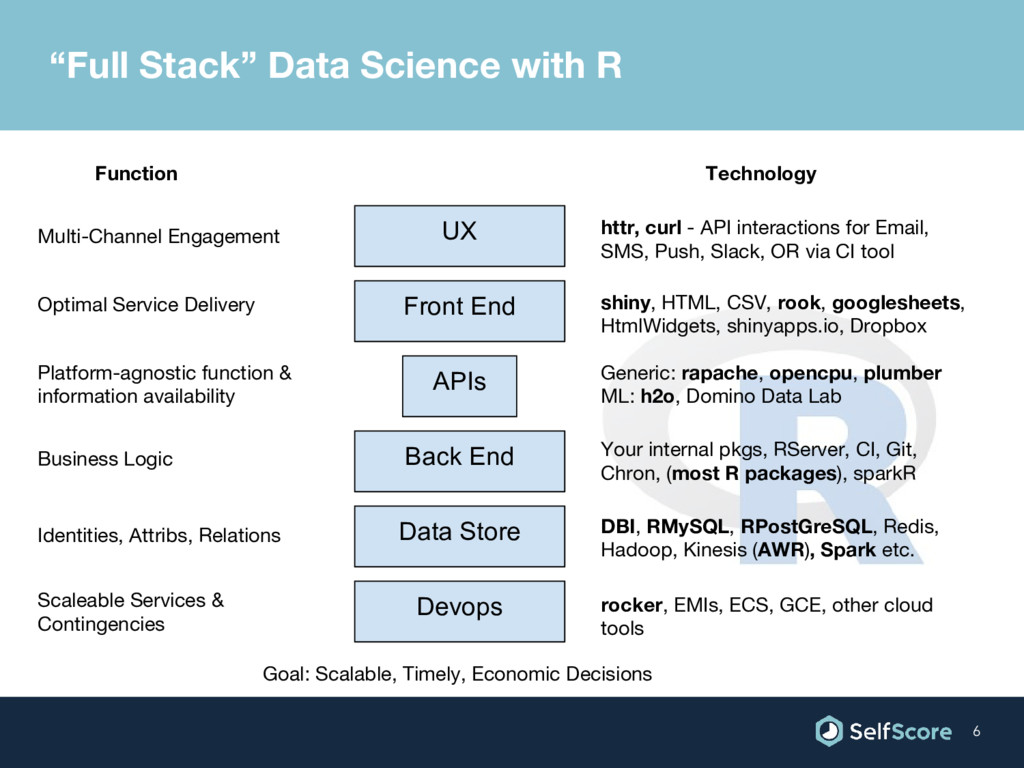
6 Front End Back End Data Store Devops APIs UX
Technology rocker, EMIs, ECS, GCE, other cloud tools DBI, RMySQL, RPostGreSQL, Redis, Hadoop, Kinesis (AWR), Spark etc. Your internal pkgs, RServer, CI, Git, Chron, (most R packages), sparkR shiny, HTML, CSV, rook, googlesheets, HtmlWidgets, shinyapps.io, Dropbox httr, curl - API interactions for Email, SMS, Push, Slack, OR via CI tool Function Multi-Channel Engagement Optimal Service Delivery Platform-agnostic function & information availability Business Logic Identities, Attribs, Relations Scaleable Services & Contingencies “Full Stack” Data Science with R Generic: rapache, opencpu, plumber ML: h2o, Domino Data Lab Goal: Scalable, Timely, Economic Decisions -
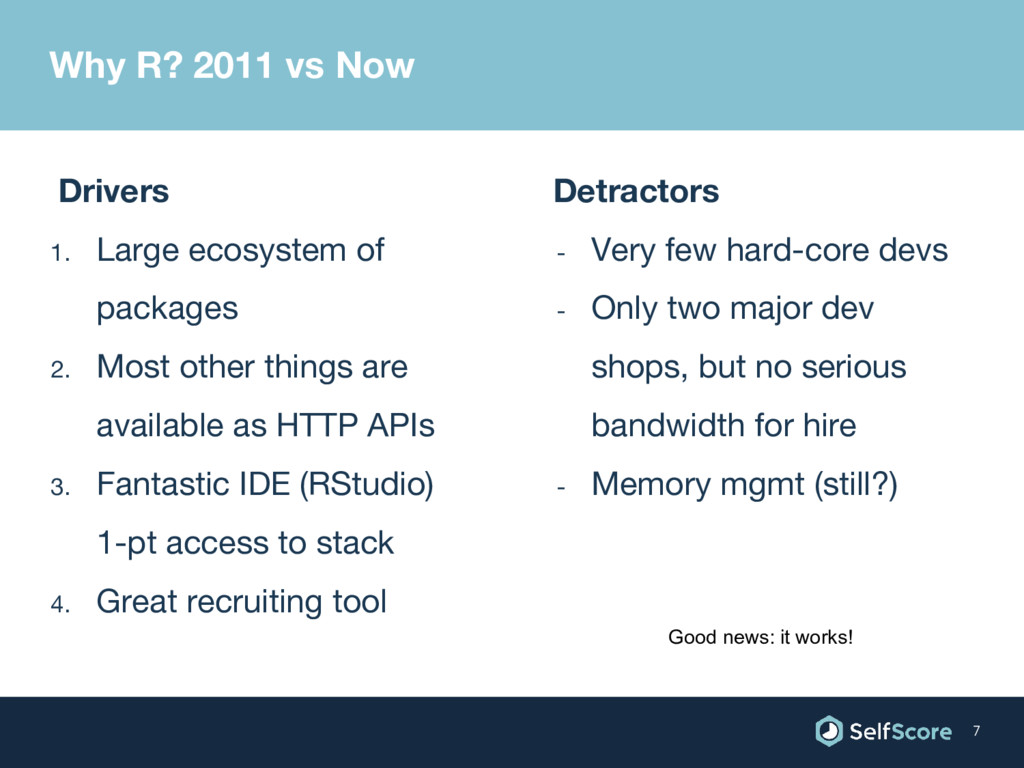
Detractors - Very few hard-core devs - Only two major
dev shops, but no serious bandwidth for hire - Memory mgmt (still?) Why R? 2011 vs Now Drivers 1. Large ecosystem of packages 2. Most other things are available as HTTP APIs 3. Fantastic IDE (RStudio) 1-pt access to stack 4. Great recruiting tool 7 Good news: it works! -
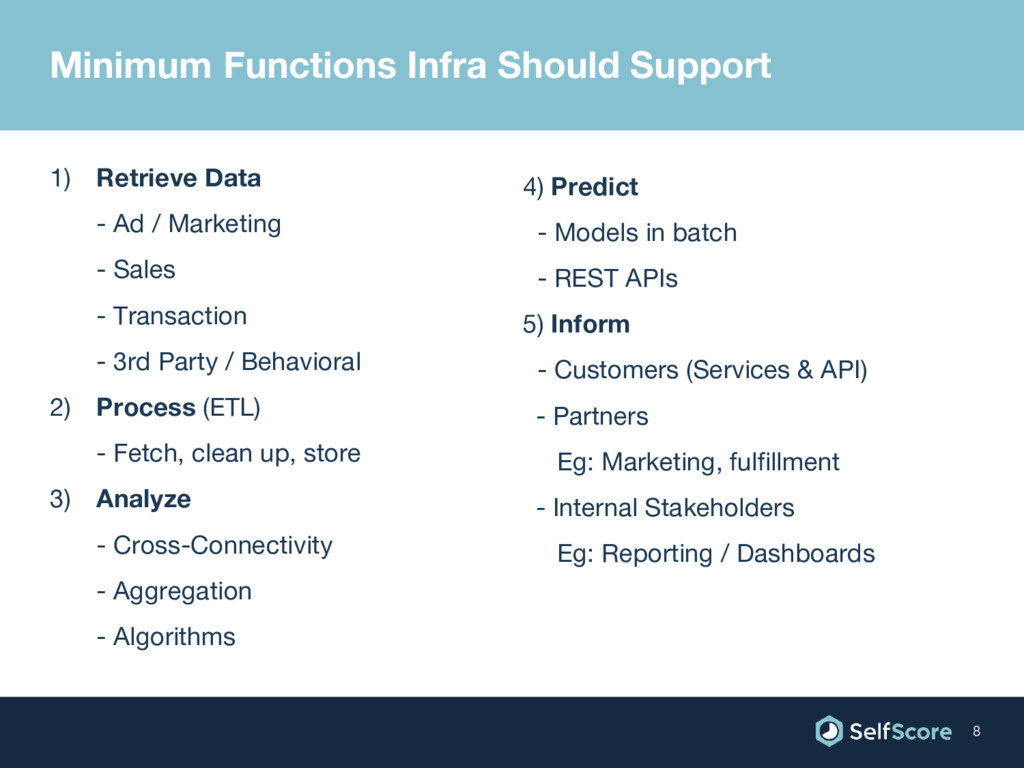
Minimum Functions Infra Should Support 1) Retrieve Data - Ad
/ Marketing - Sales - Transaction - 3rd Party / Behavioral 2) Process (ETL) - Fetch, clean up, store 3) Analyze - Cross-Connectivity - Aggregation - Algorithms 4) Predict - Models in batch - REST APIs 5) Inform - Customers (Services & API) - Partners Eg: Marketing, fulfillment - Internal Stakeholders Eg: Reporting / Dashboards 8 -
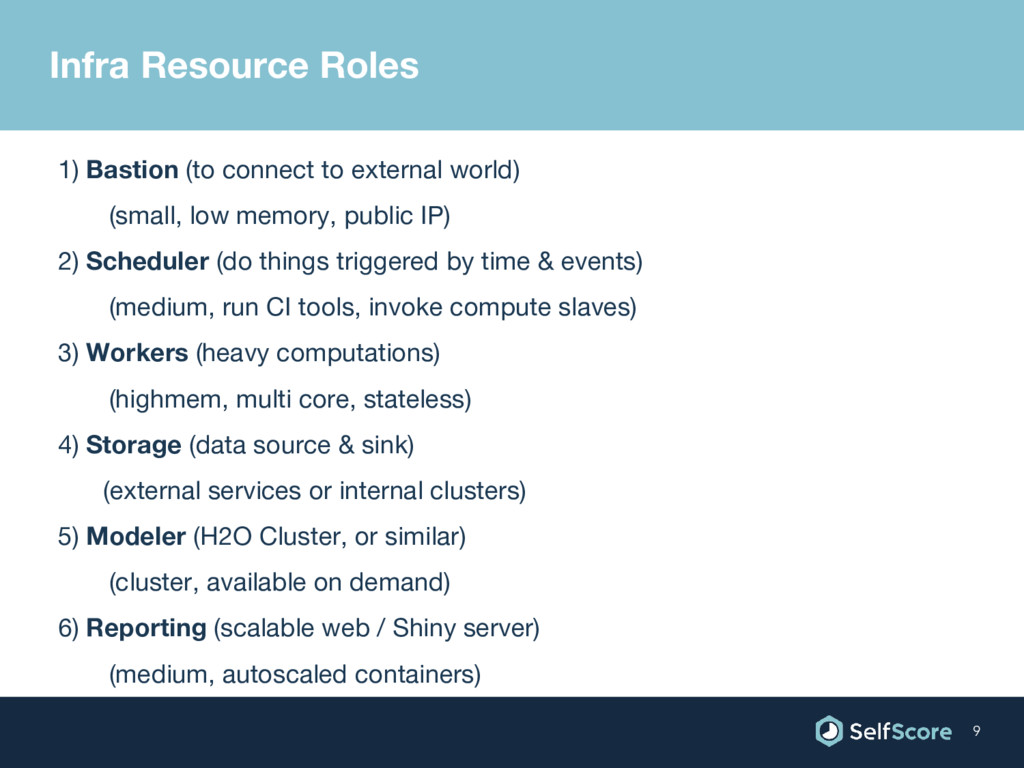
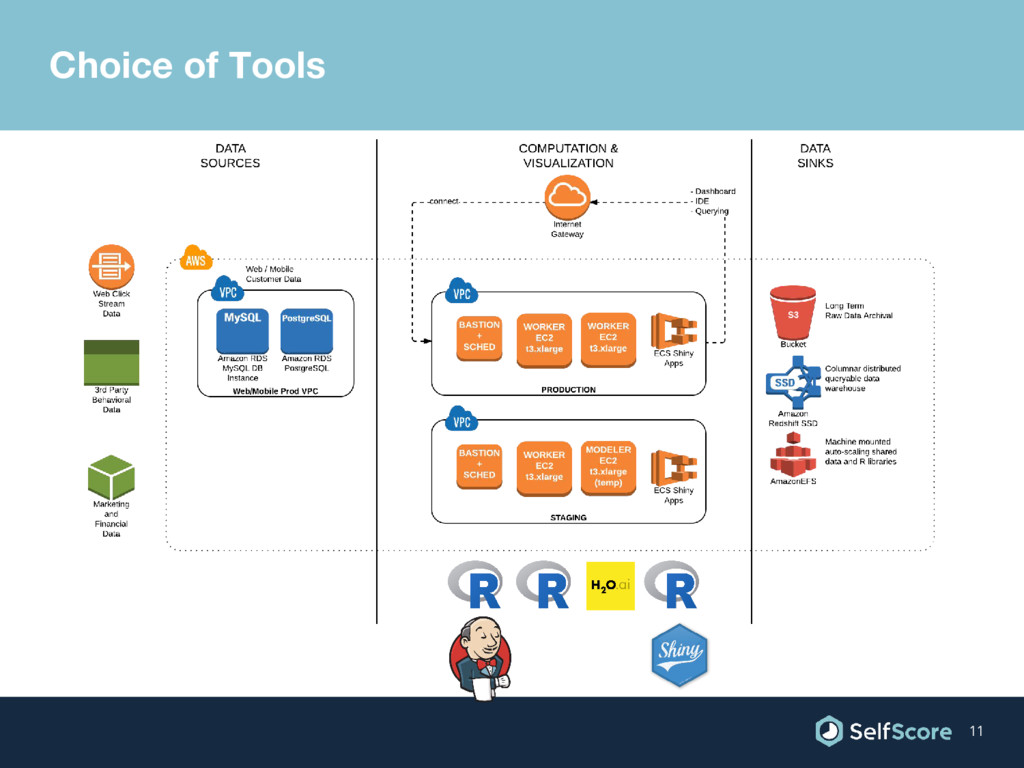
Infra Resource Roles 1) Bastion (to connect to external world)
(small, low memory, public IP) 2) Scheduler (do things triggered by time & events) (medium, run CI tools, invoke compute slaves) 3) Workers (heavy computations) (highmem, multi core, stateless) 4) Storage (data source & sink) (external services or internal clusters) 5) Modeler (H2O Cluster, or similar) (cluster, available on demand) 6) Reporting (scalable web / Shiny server) (medium, autoscaled containers) 9 -
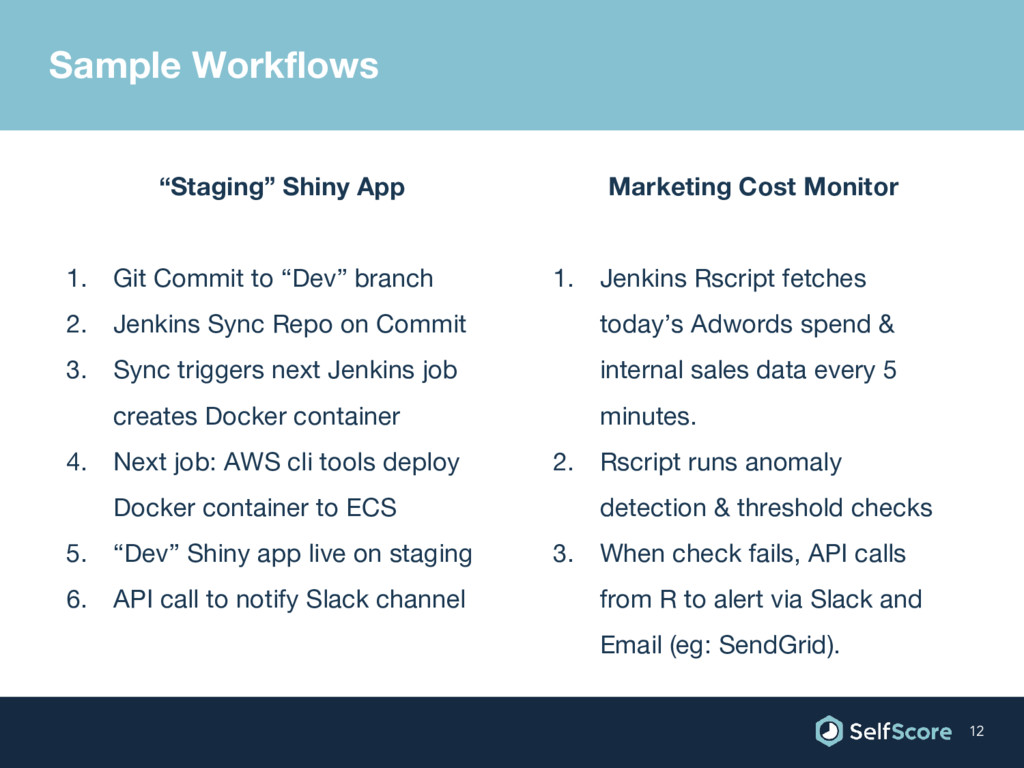
“Staging” Shiny App 1. Git Commit to “Dev” branch 2.
Jenkins Sync Repo on Commit 3. Sync triggers next Jenkins job creates Docker container 4. Next job: AWS cli tools deploy Docker container to ECS 5. “Dev” Shiny app live on staging 6. API call to notify Slack channel Sample Workflows Marketing Cost Monitor 1. Jenkins Rscript fetches today’s Adwords spend & internal sales data every 5 minutes. 2. Rscript runs anomaly detection & threshold checks 3. When check fails, API calls from R to alert via Slack and Email (eg: SendGrid). 12 -
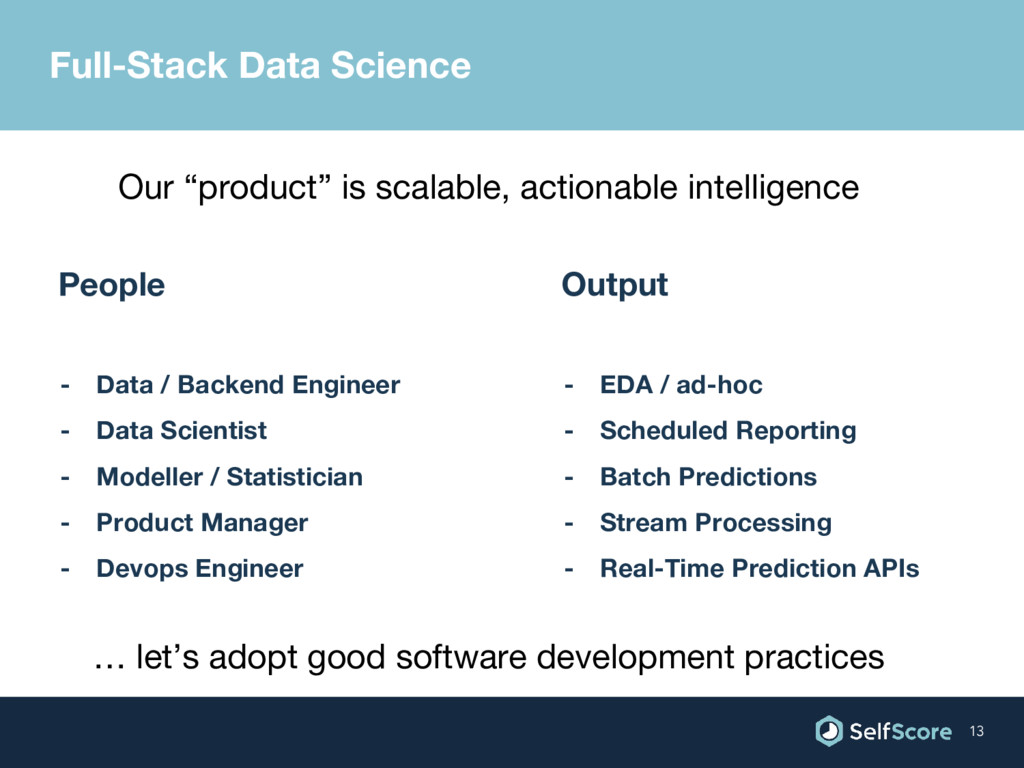
Full-Stack Data Science People - Data / Backend Engineer -
Data Scientist - Modeller / Statistician - Product Manager - Devops Engineer Output - EDA / ad-hoc - Scheduled Reporting - Batch Predictions - Stream Processing - Real-Time Prediction APIs Our “product” is scalable, actionable intelligence 13 … let’s adopt good software development practices -
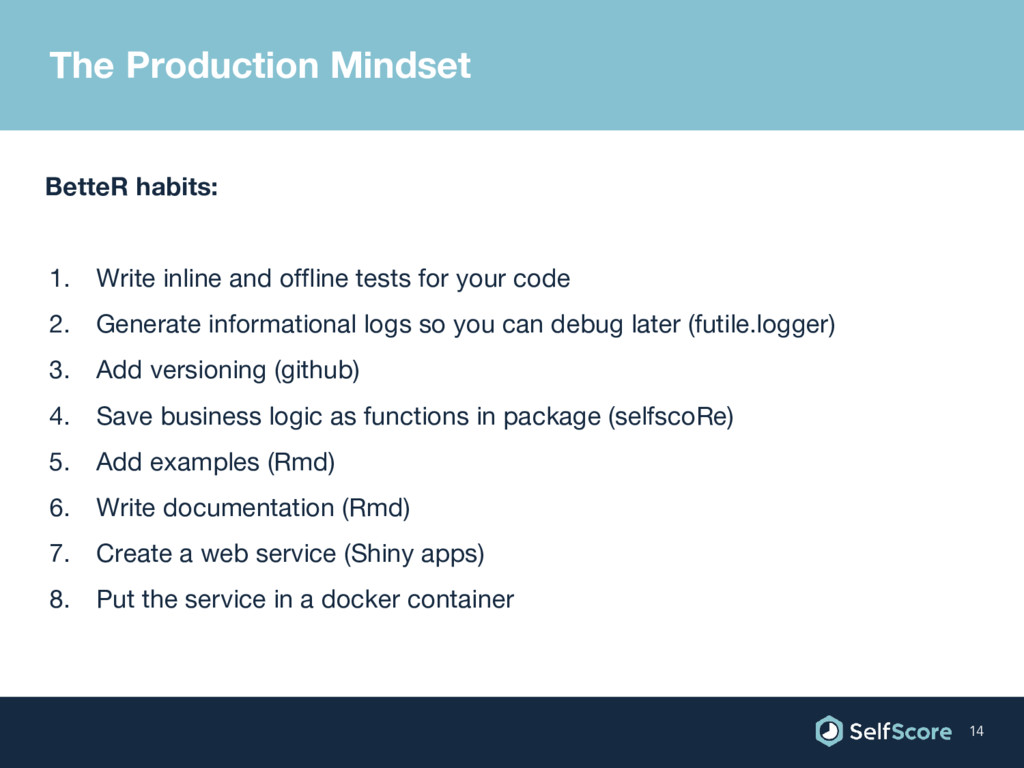
BetteR habits: 1. Write inline and offline tests for your
code 2. Generate informational logs so you can debug later (futile.logger) 3. Add versioning (github) 4. Save business logic as functions in package (selfscoRe) 5. Add examples (Rmd) 6. Write documentation (Rmd) 7. Create a web service (Shiny apps) 8. Put the service in a docker container The Production Mindset 14 -
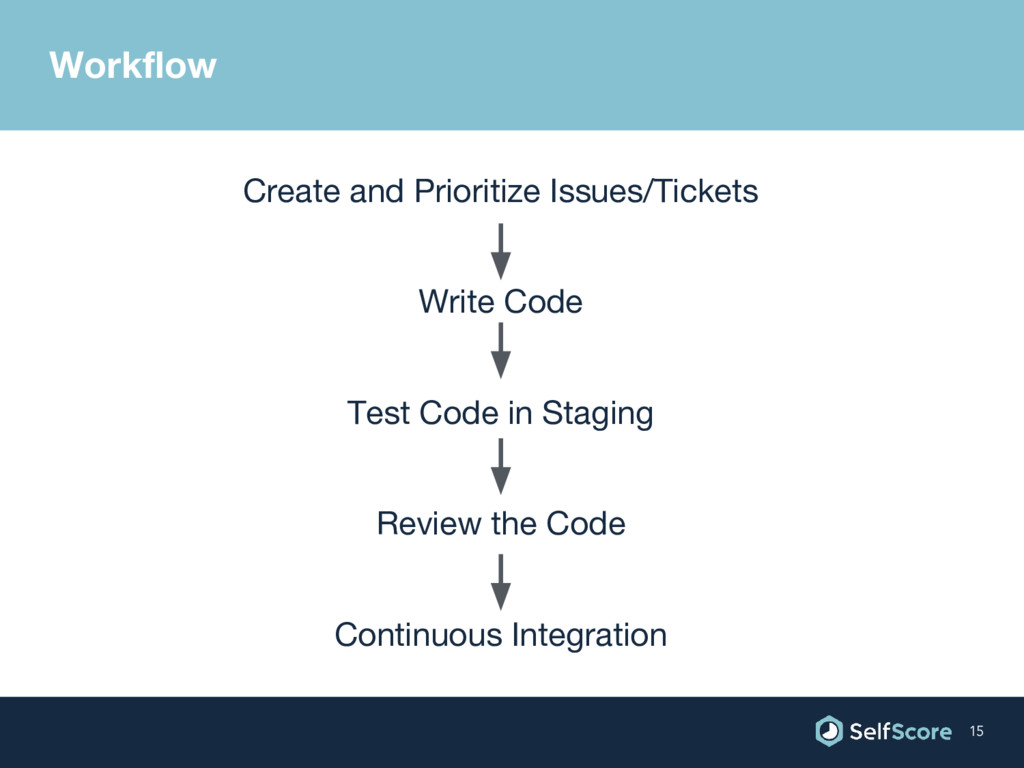
Create and Prioritize Issues/Tickets Write Code Test Code in Staging
Review the Code Continuous Integration Workflow 15 -
Should we buy or should we build? VS Should my
company buy the infra? Should my team build it? 16 -
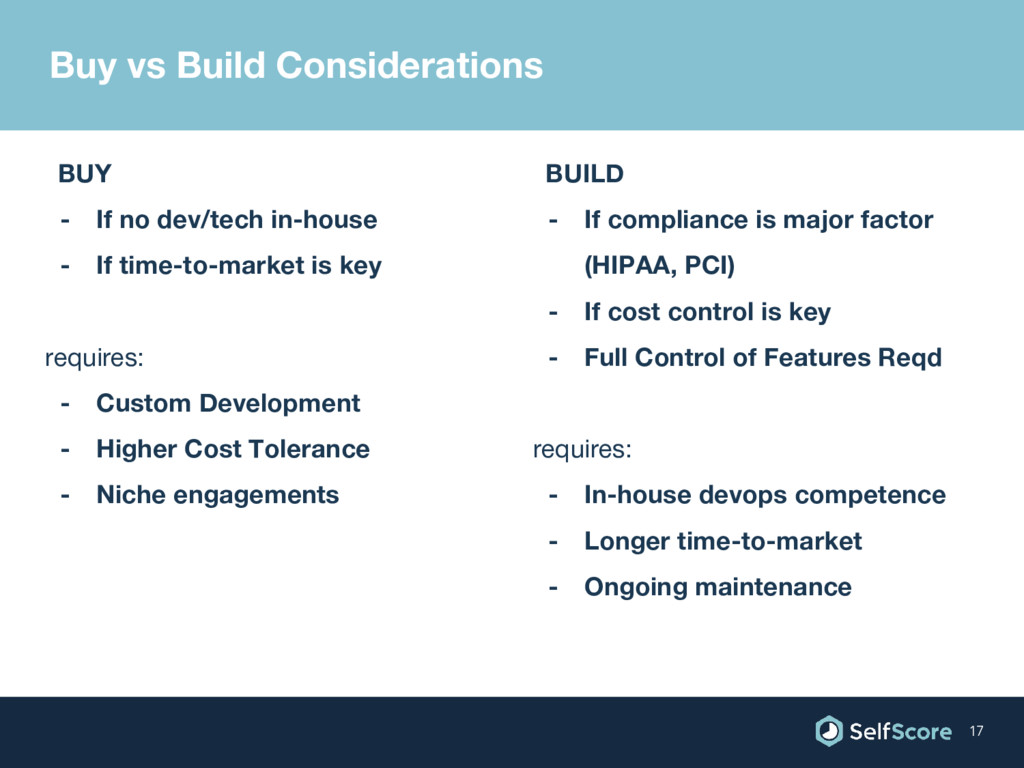
Buy vs Build Considerations BUY - If no dev/tech in-house
- If time-to-market is key requires: - Custom Development - Higher Cost Tolerance - Niche engagements BUILD - If compliance is major factor (HIPAA, PCI) - If cost control is key - Full Control of Features Reqd requires: - In-house devops competence - Longer time-to-market - Ongoing maintenance 17 -
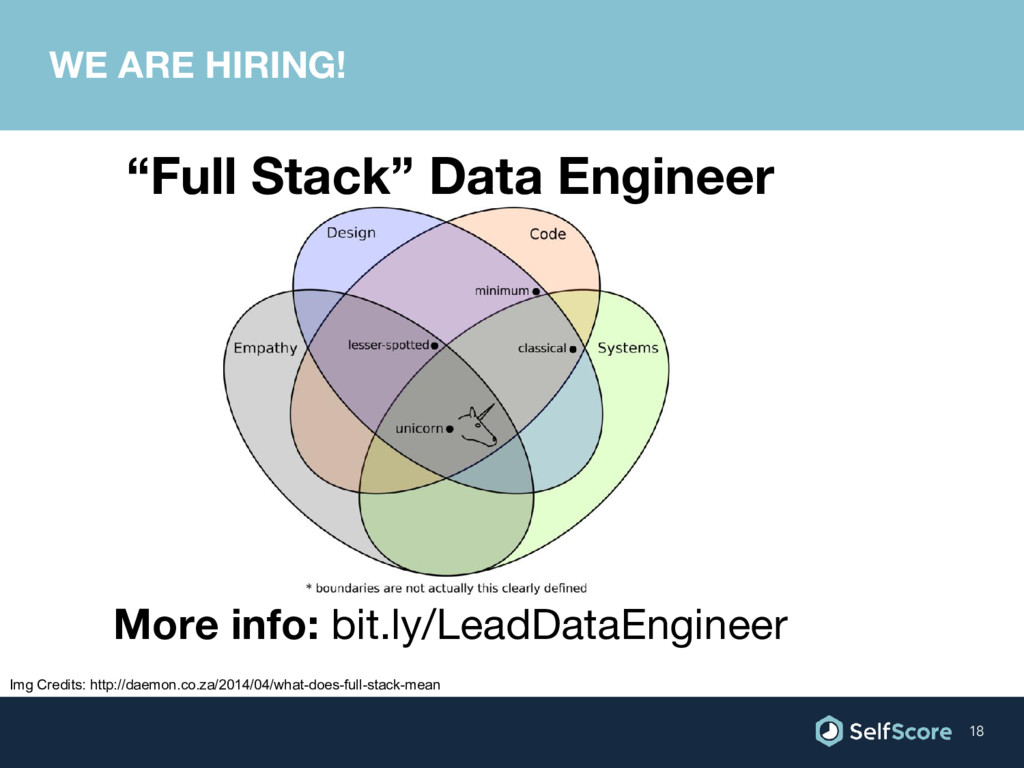
“Full Stack” Data Engineer More info: bit.ly/LeadDataEngineer WE ARE HIRING!
18 Img Credits: http://daemon.co.za/2014/04/what-does-full-stack-mean