Share
Embed
Automatic Synthesis of Combiners in the MapReduce Framework -- An Approach with Right Inverse
Talk in LOPSTR 2014
KINOSHITA Minoru
September 11, 2014
Transcript
41 slides
-
Automatic Synthesis of Combiners in the MapReduce Framework An Approach
with Right Inverse Minoru Kinoshita joint work with Kohei Suenaga and Atsushi Igarashi Kyoto University September 11, 2014 1 / 33 -
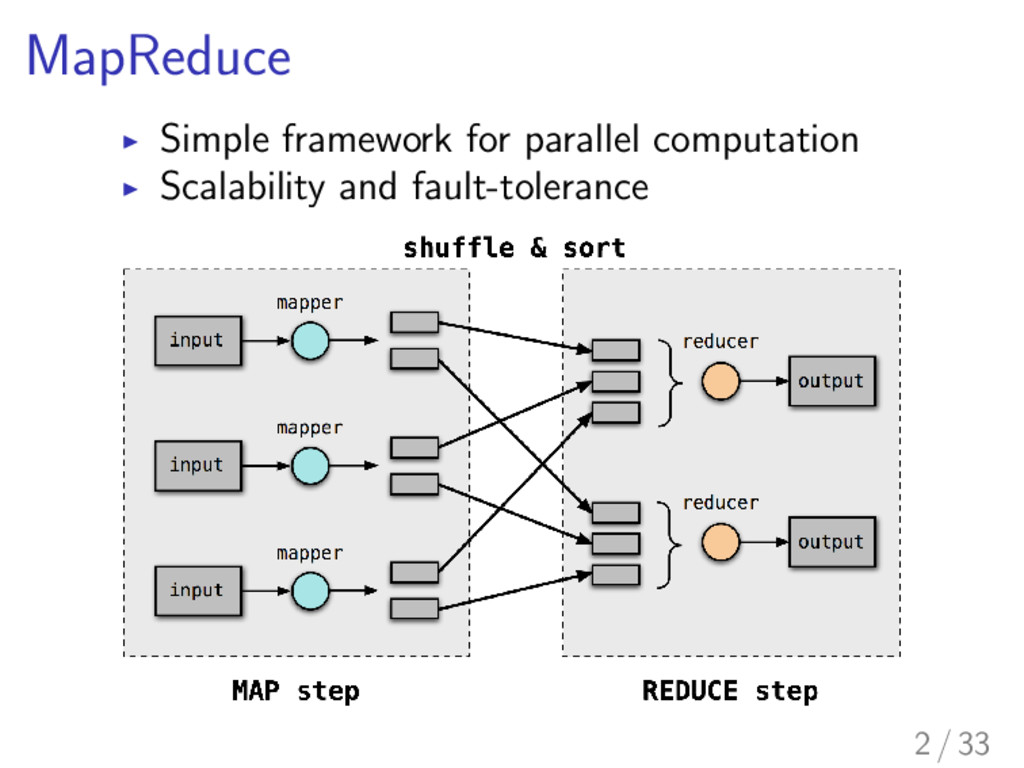
MapReduce I Simple framework for parallel computation I Scalability and
fault-tolerance 2 / 33 -
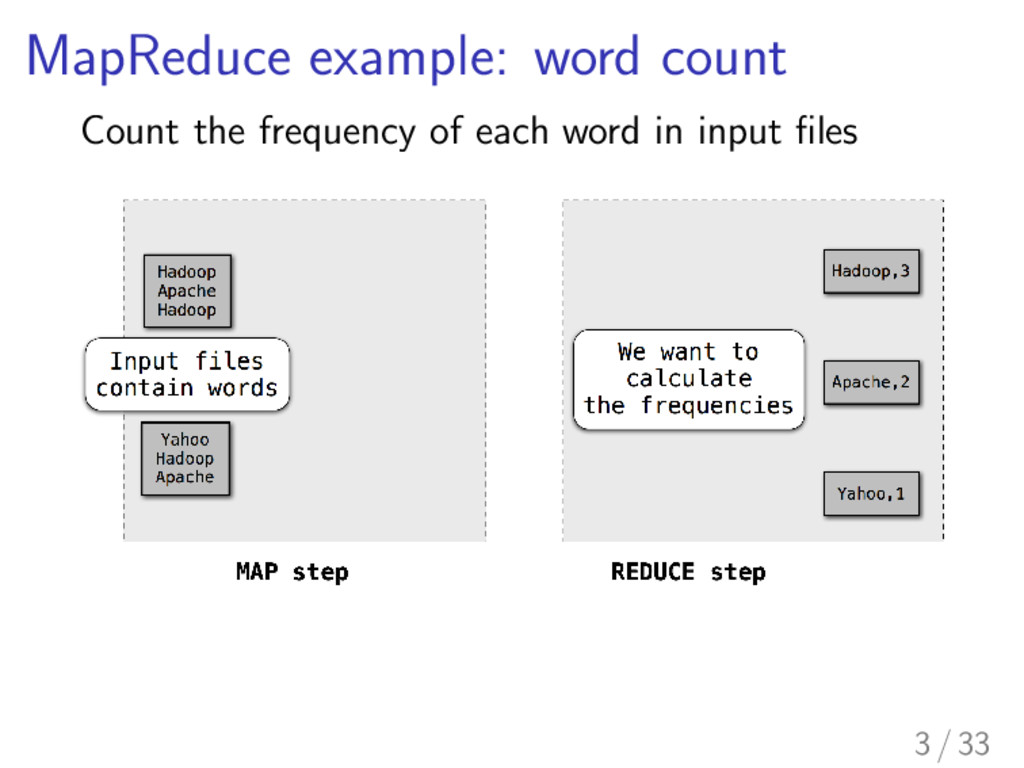
MapReduce example: word count Count the frequency of each word
in input files 3 / 33 -
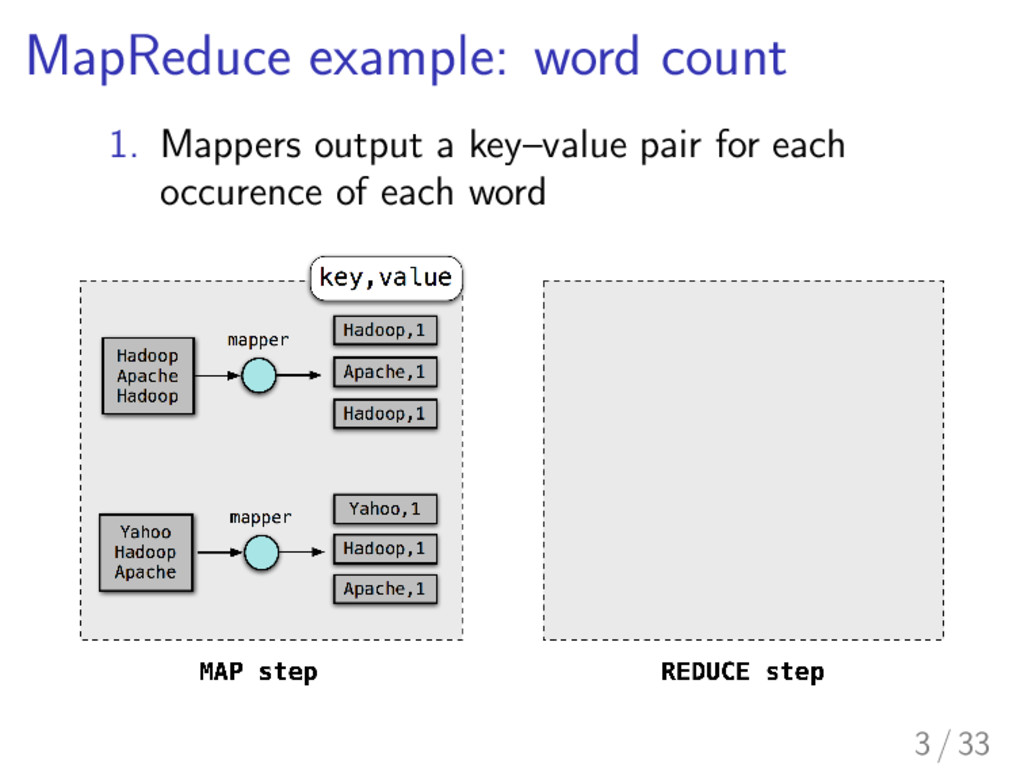
MapReduce example: word count 1. Mappers output a key–value pair
for each occurence of each word 3 / 33 -
MapReduce example: word count 2. The values with the same
key are transferred to one reducer 3 / 33 -
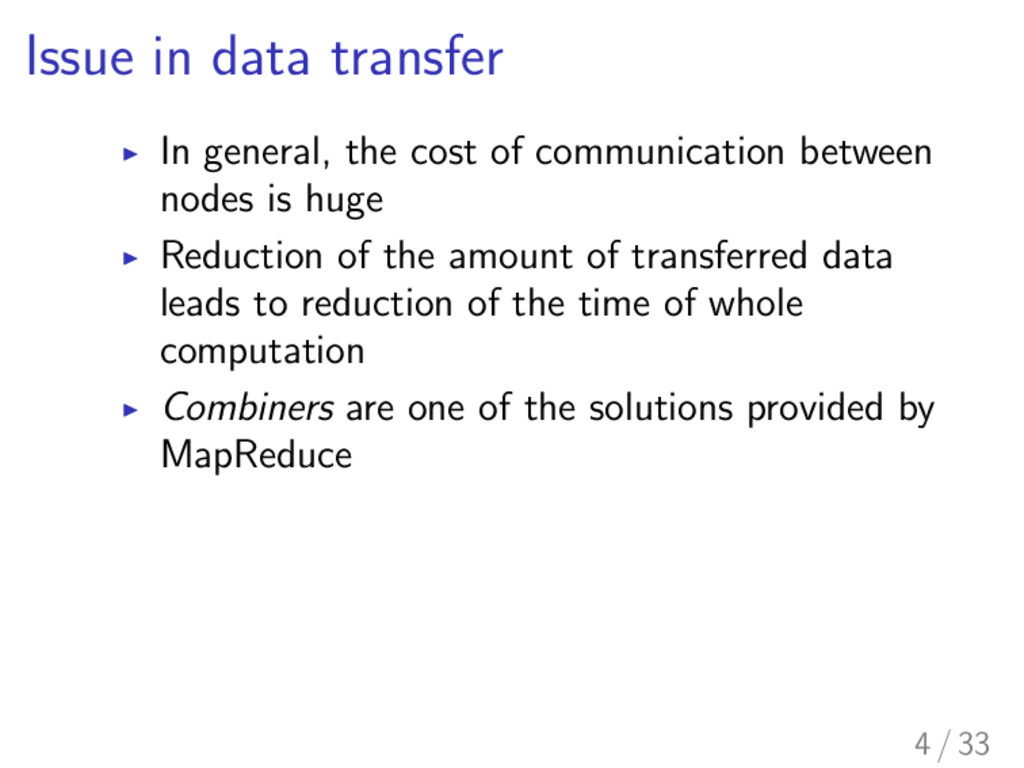
Issue in data transfer I In general, the cost of
communication between nodes is huge I Reduction of the amount of transferred data leads to reduction of the time of whole computation I Combiners are one of the solutions provided by MapReduce 4 / 33 -
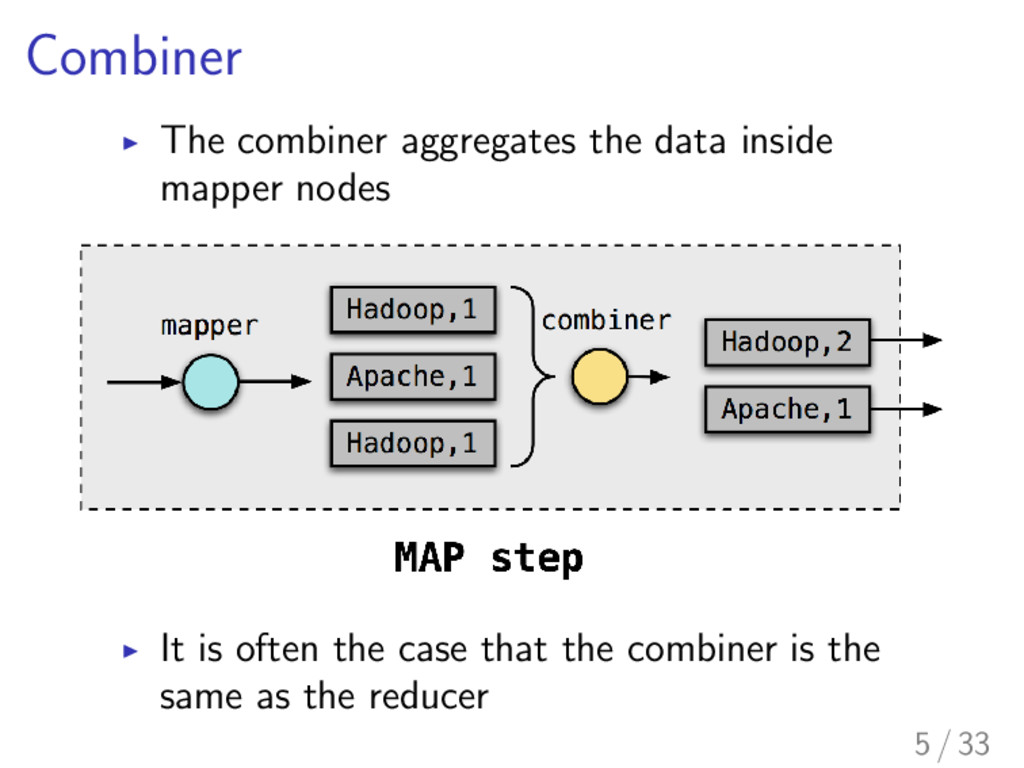
Combiner I The combiner aggregates the data inside mapper nodes
I It is often the case that the combiner is the same as the reducer 5 / 33 -
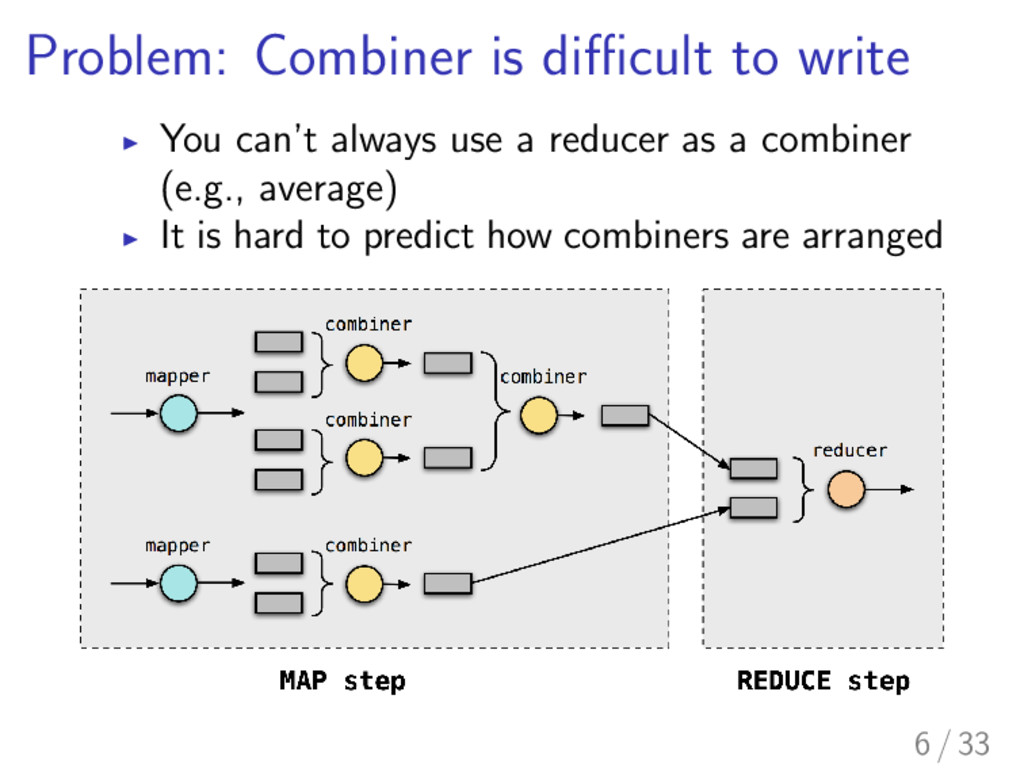
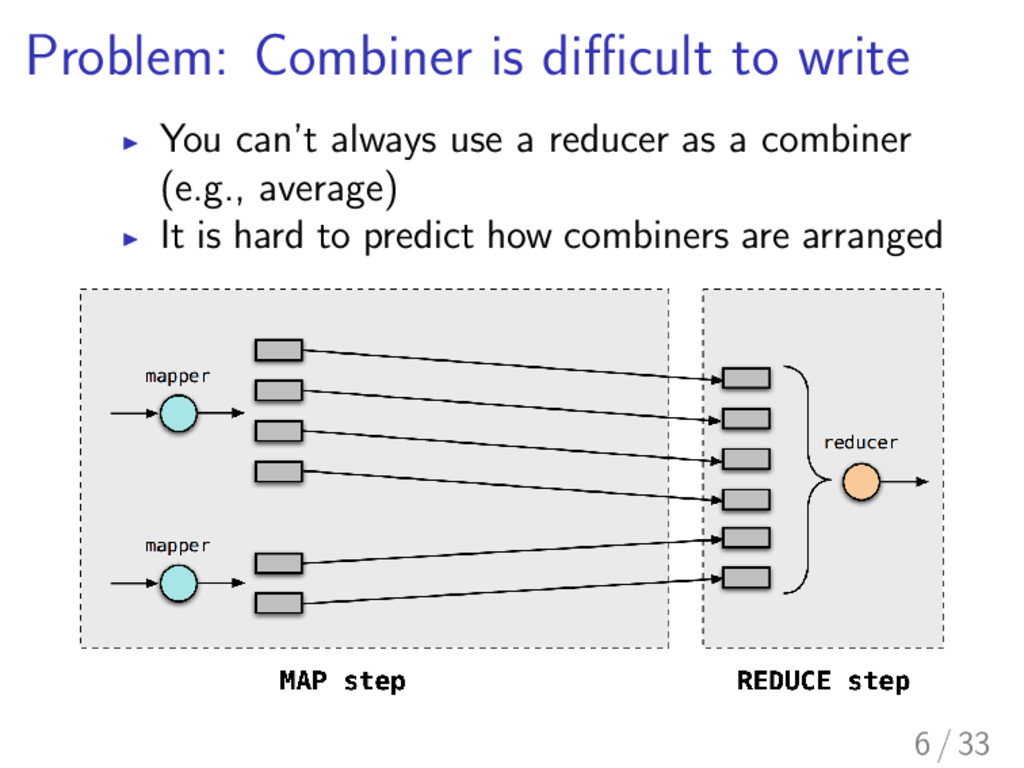
Problem: Combiner is di cult to write I You can’t
always use a reducer as a combiner (e.g., average) I It is hard to predict how combiners are arranged 6 / 33 -
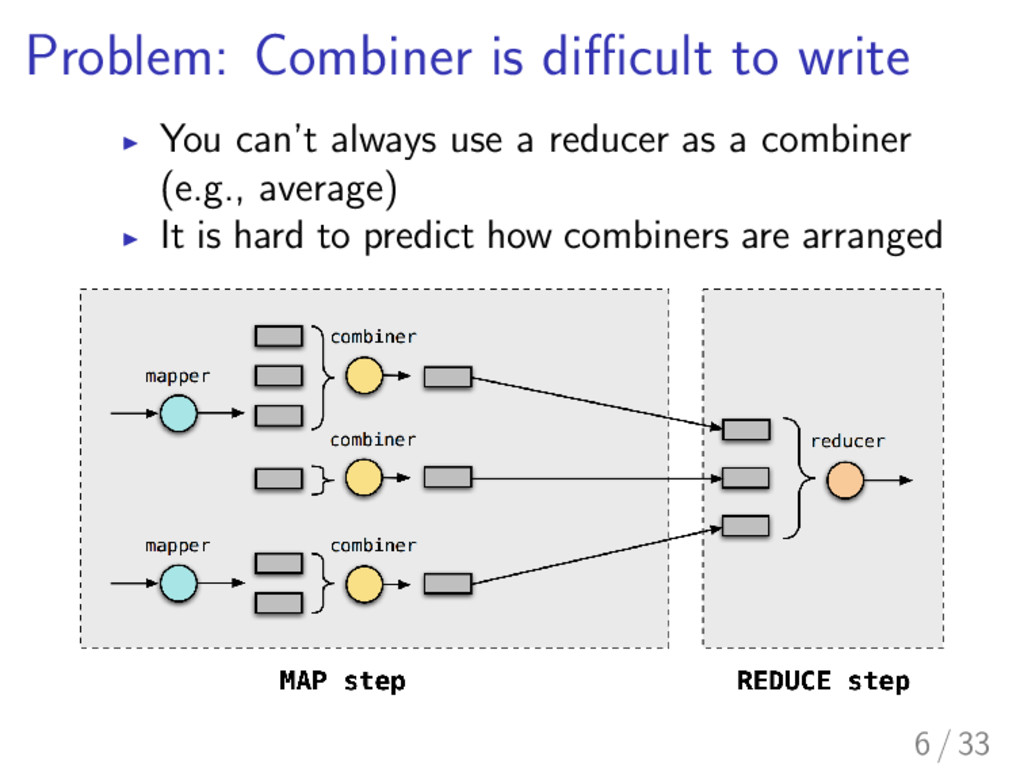
Problem: Combiner is di cult to write I You can’t
always use a reducer as a combiner (e.g., average) I It is hard to predict how combiners are arranged 6 / 33 -
Problem: Combiner is di cult to write I You can’t
always use a reducer as a combiner (e.g., average) I It is hard to predict how combiners are arranged 6 / 33 -
Our aim I Automatic derivation of a combiner that works
correctly input mapper, list-homomorphic reducer output mapper, combiner, reducer Benefit I Derived combiner is guaranteed to be correct by construction I Code duplication between combiner and reducer is avoided 7 / 33 -
Contribution I A method that synthesizes a combiner I Correctness
of the method I Implementation of the method for Hadoop: I The de facto standard MapReduce library implemented for Java I Experiment 8 / 33 -
Outline I MapReduce I Combiner Synthesis I Correctness I Implementation
I Experiment 9 / 33 -
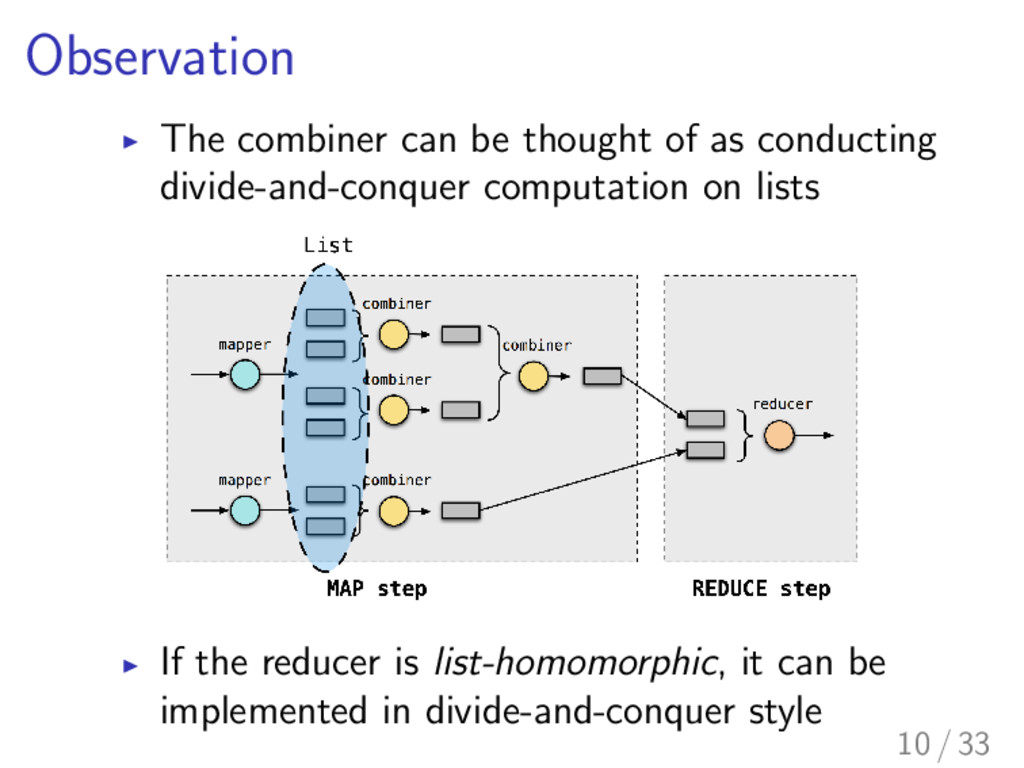
Observation I The combiner can be thought of as conducting
divide-and-conquer computation on lists I If the reducer is list-homomorphic , it can be implemented in divide-and-conquer style 10 / 33 -
List homomorphism Definition (List Homomorphism) h is list-homomorphic i↵ 9
, 8 x, y : list , h ( x + + y ) = h x h y I The answer can be obtained from the values for sublists I The list can be split in an arbitrary position I We will take as a combiner 11 / 33 -
If the combiner is list-homomorphic I To generate , we
can use the third homomorphism theorem 12 / 33 -
The third homomorphism theorem [Gibbons. JFP 1996] If h is
homomorphic, then is defined as t u = h ( h 1 t + + h 1 u ) where h 1 is a right inverse of h I Right inverse satsfies 8 x, h ( h 1( x )) = x 13 / 33 -
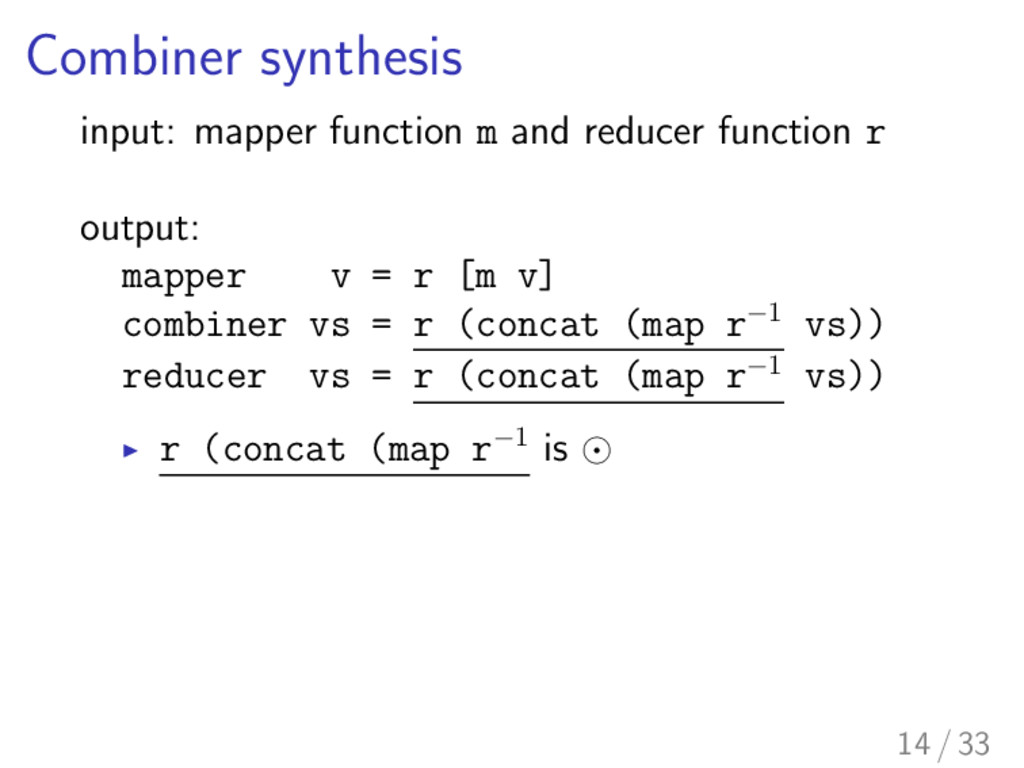
Combiner synthesis input: mapper function m and reducer function r
output: mapper v = r [m v] combiner vs = r (concat (map r 1 vs)) reducer vs = r (concat (map r 1 vs)) I r (concat (map r 1 is 14 / 33 -
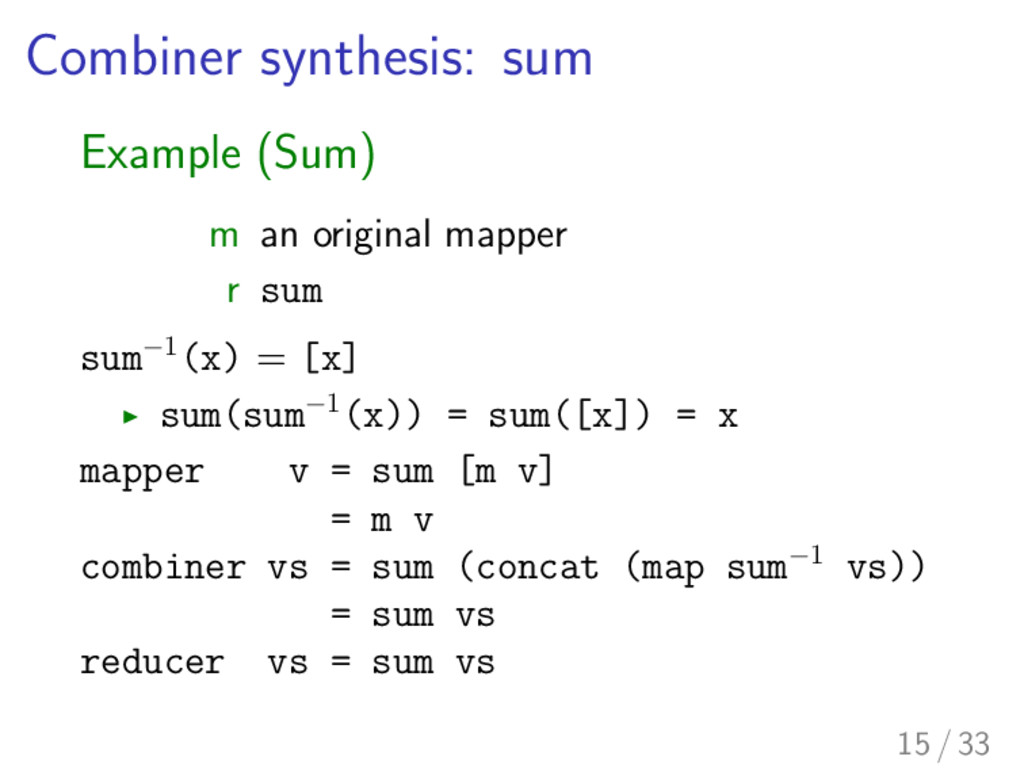
Combiner synthesis: sum Example (Sum) m an original mapper r
sum sum 1 (x) = [x] I sum(sum 1 (x)) = sum([x]) = x mapper v = sum [m v] = m v combiner vs = sum (concat (map sum 1 vs)) = sum vs reducer vs = sum vs 15 / 33 -
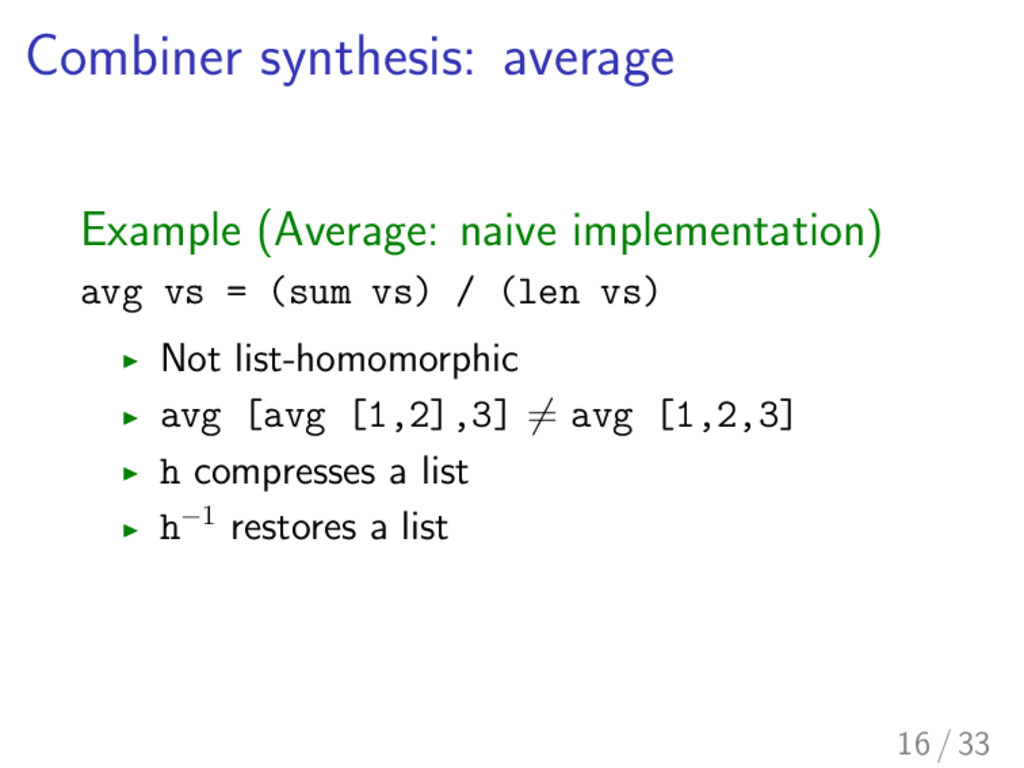
Combiner synthesis: average Example (Average: naive implementation) avg vs =
(sum vs) / (len vs) I Not list-homomorphic I avg [avg [1,2],3] 6= avg [1,2,3] I h compresses a list I h 1 restores a list 16 / 33 -
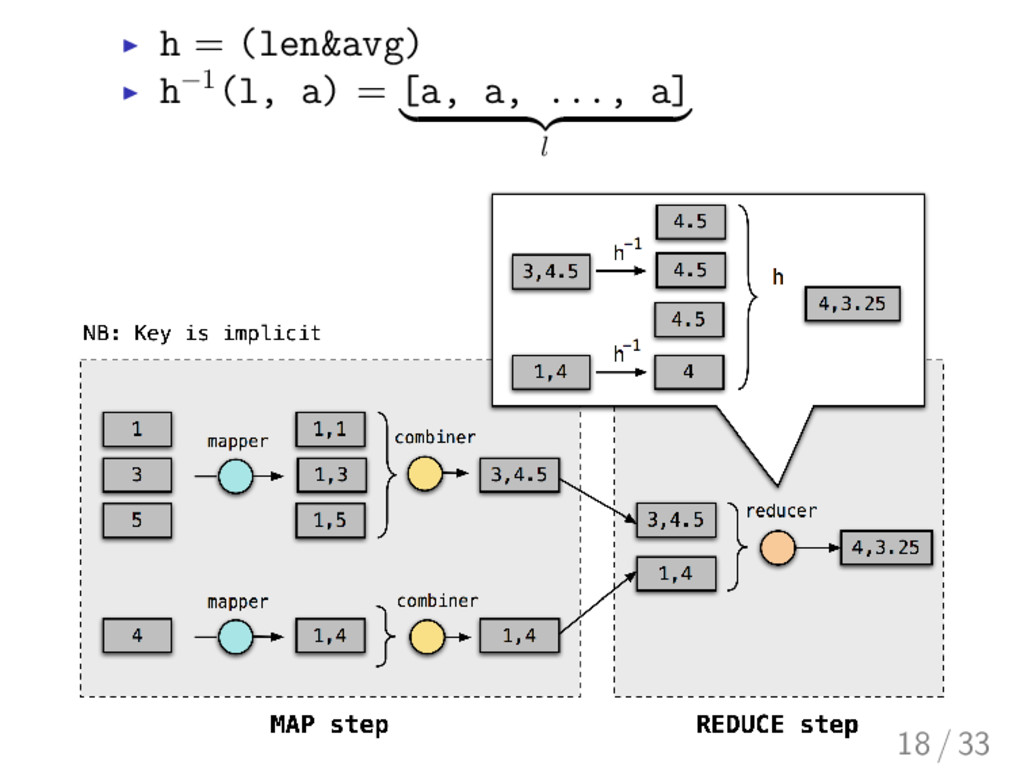
Combiner synthesis: average Example (Average) I h = (len&avg) is
list-homomorphic input a list output a pair of length & average I h 1 (l, a) = [a, a, ..., a] | {z } l mapper v = h [m v] = [(1, m v)] combiner vs = h (concat (map h 1 vs)) 17 / 33 -
I h = (len&avg) I h 1 (l, a) =
[a, a, ..., a] | {z } l 18 / 33 -
I h = (len&avg) I h 1 (l, a) =
[a, a, ..., a] | {z } l 18 / 33 -
Outline I MapReduce I Combiner Synthesis I Correctness I Implementation
I Experiment 19 / 33 -
Our model of MapReduce I A MapReduce execution is regarded
as a tree structure I We proved the correctness of our method using this model 20 / 33 -
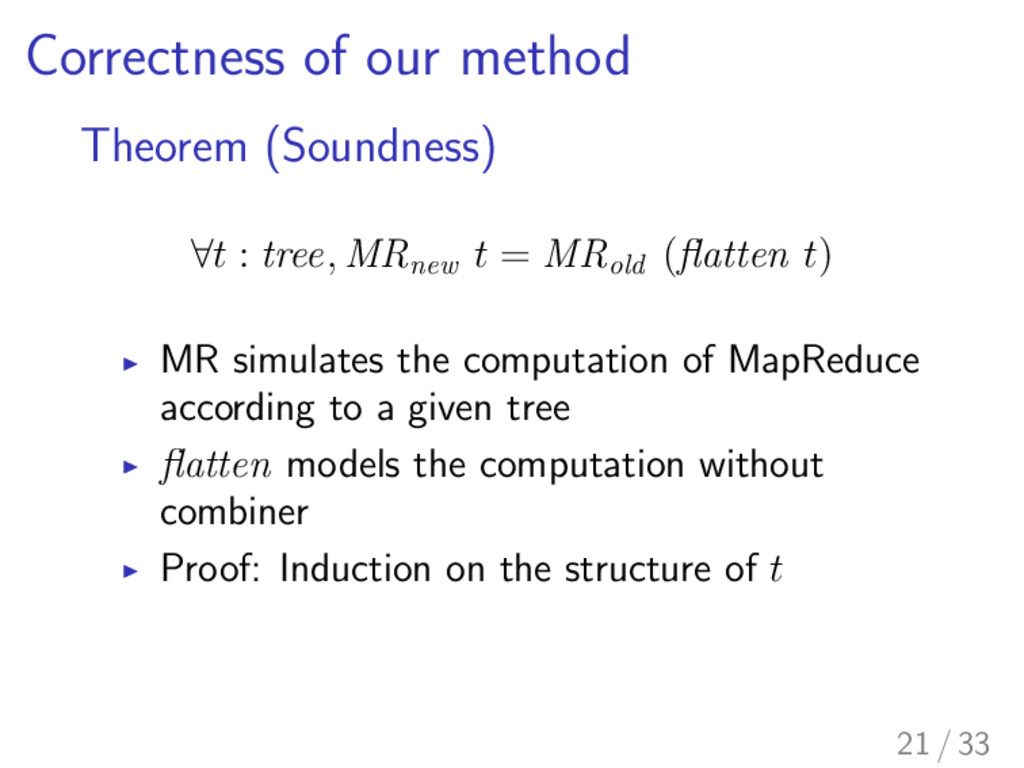
Correctness of our method Theorem (Soundness) 8 t : tree
, MR new t = MR old (flatten t ) I MR simulates the computation of MapReduce according to a given tree I flatten models the computation without combiner I Proof: Induction on the structure of t 21 / 33 -
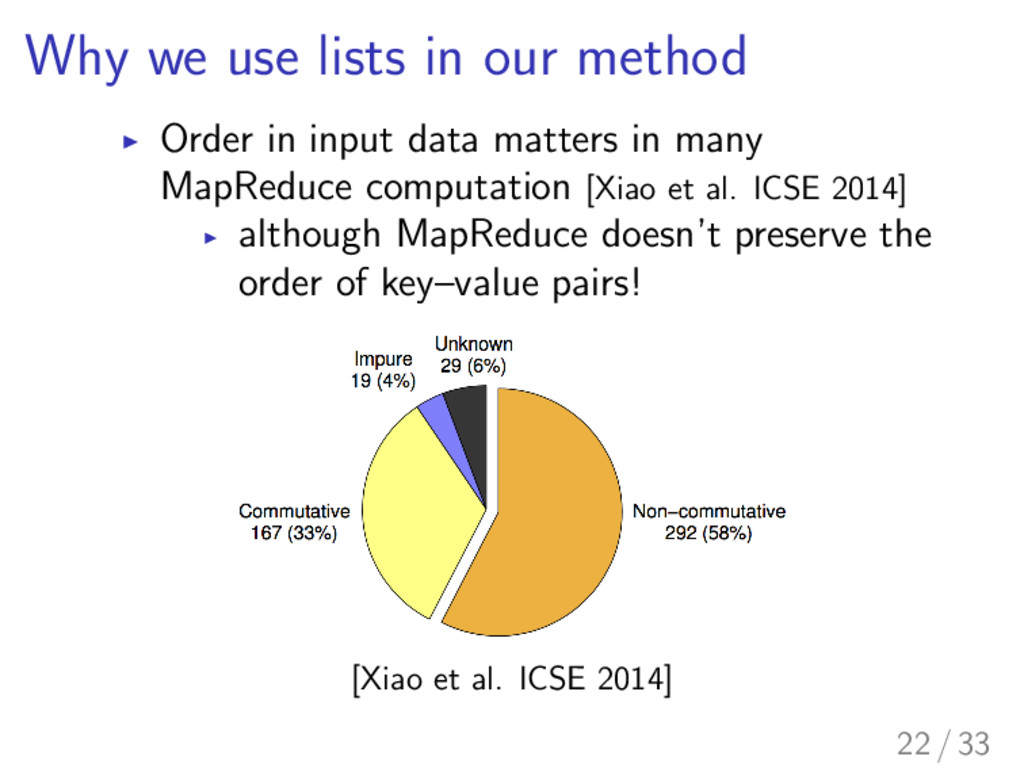
Why we use lists in our method I Order in
input data matters in many MapReduce computation [Xiao et al. ICSE 2014] I although MapReduce doesn’t preserve the order of key–value pairs! [Xiao et al. ICSE 2014] 22 / 33 -
Outline I MapReduce I Combiner Synthesis I Correctness I Implementation
I Experiment 23 / 33 -
Implementation We implemented the method for Hadoop input A mapper,
a list-homomorphic reducer, and a right inverse of the reducer output Hadoop classes Although an automatic derivation of a right inverse methods has been proposed [Morita et al. PLDI 2007], currently we specify a right inverse by hand 24 / 33 -
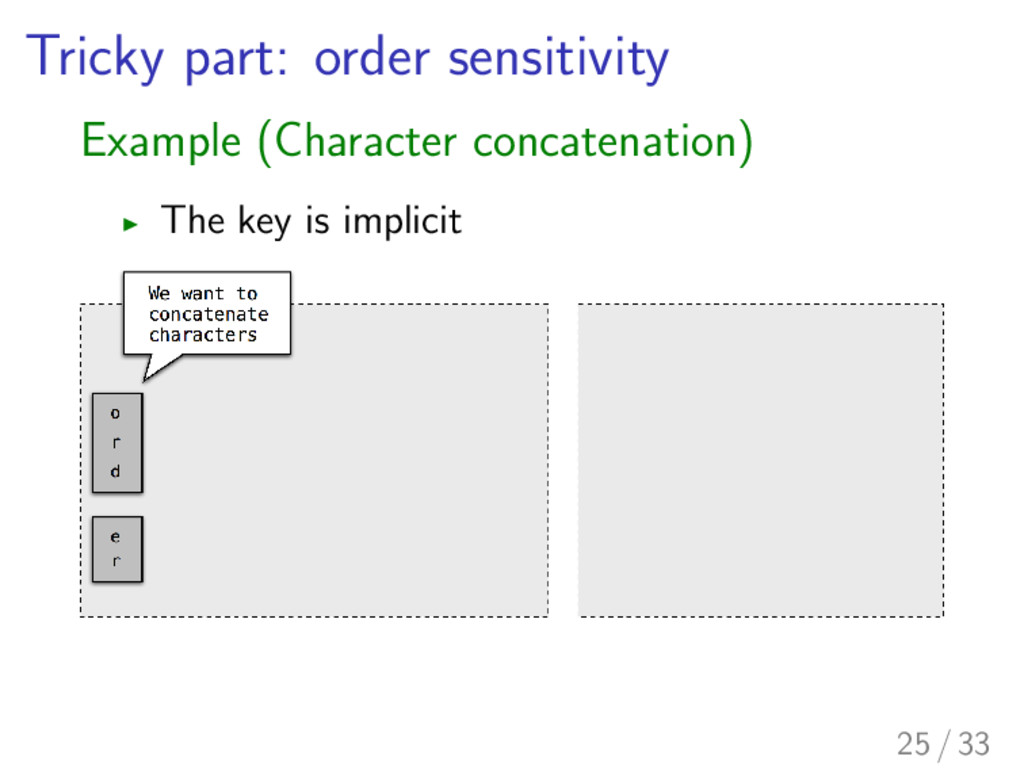
Tricky part: order sensitivity Example (Character concatenation) I The key
is implicit 25 / 33 -
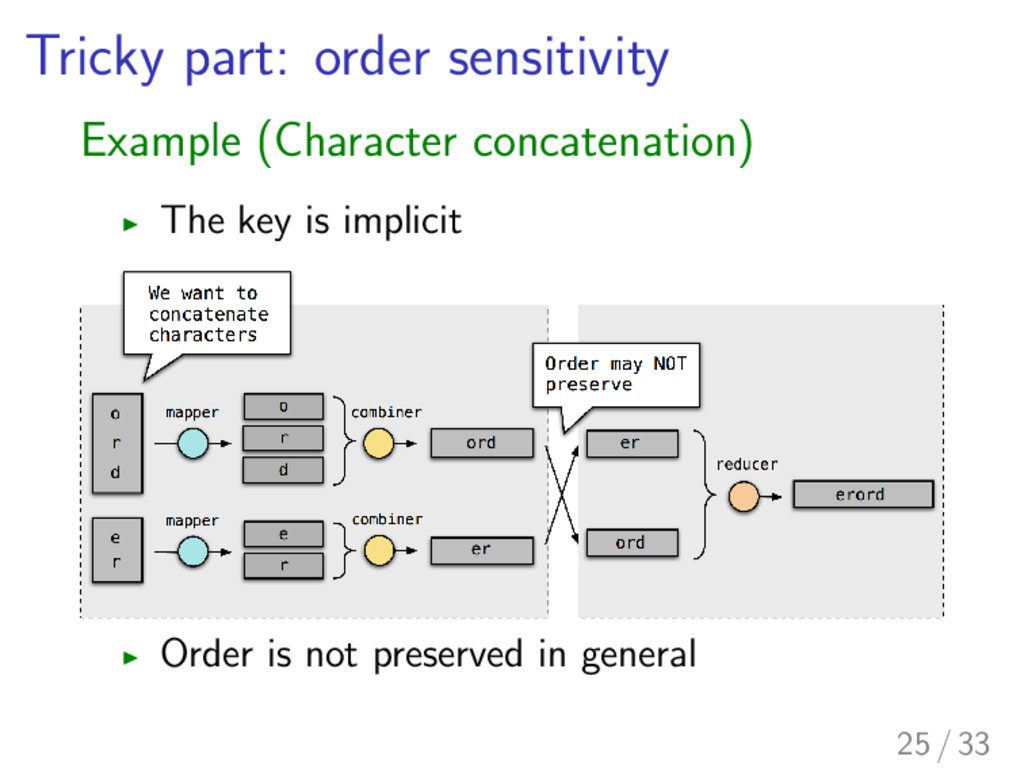
Tricky part: order sensitivity Example (Character concatenation) I The key
is implicit I Order is not preserved in general 25 / 33 -
Tricky part: order sensitivity Example (Character concatenation) I The key
is implicit I Users choose whether the generated program is order-sensitive or not 25 / 33 -
Outline I MapReduce I Combiner Synthesis I Correctness I Implementation
I Experiment 26 / 33 -
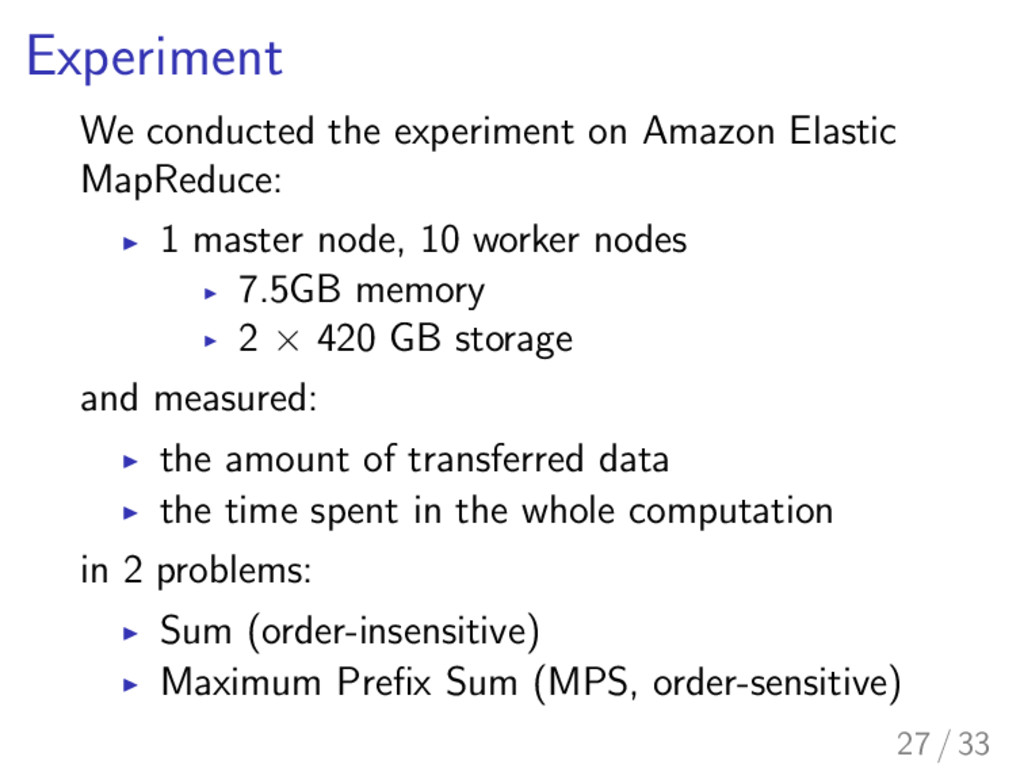
Experiment We conducted the experiment on Amazon Elastic MapReduce: I
1 master node, 10 worker nodes I 7.5GB memory I 2 ⇥ 420 GB storage and measured: I the amount of transferred data I the time spent in the whole computation in 2 problems: I Sum (order-insensitive) I Maximum Prefix Sum (MPS, order-sensitive) 27 / 33 -
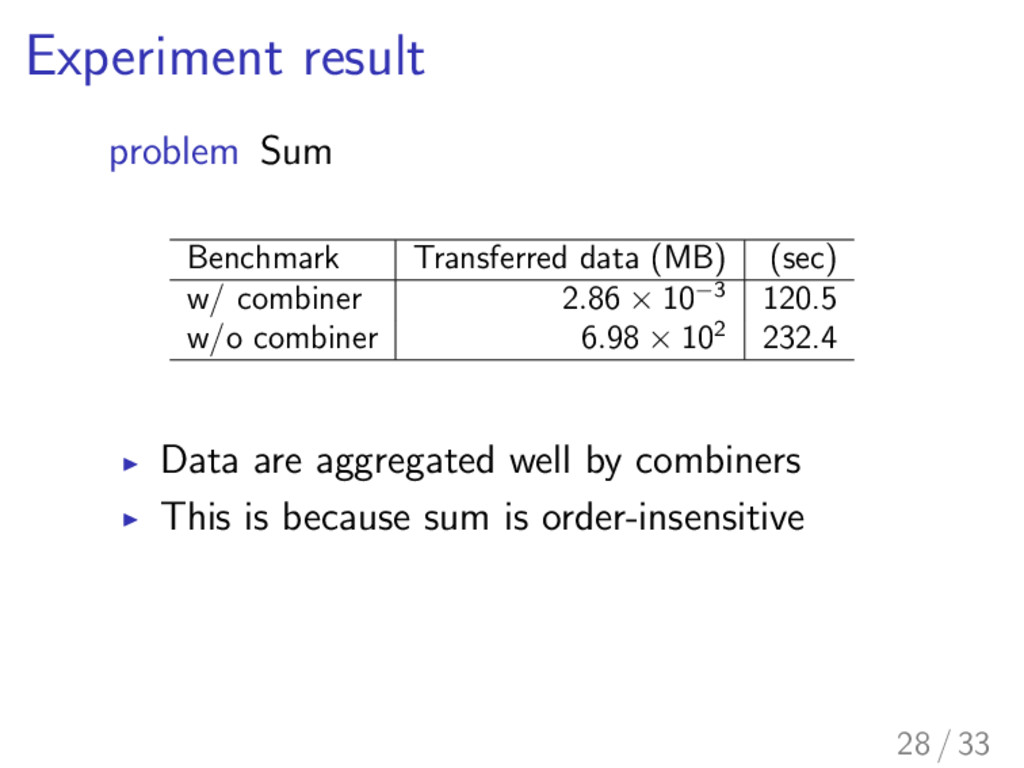
Experiment result problem Sum Benchmark Transferred data (MB) (sec) w/
combiner 2 . 86 ⇥ 10 3 120.5 w/o combiner 6 . 98 ⇥ 102 232.4 I Data are aggregated well by combiners I This is because sum is order-insensitive 28 / 33 -
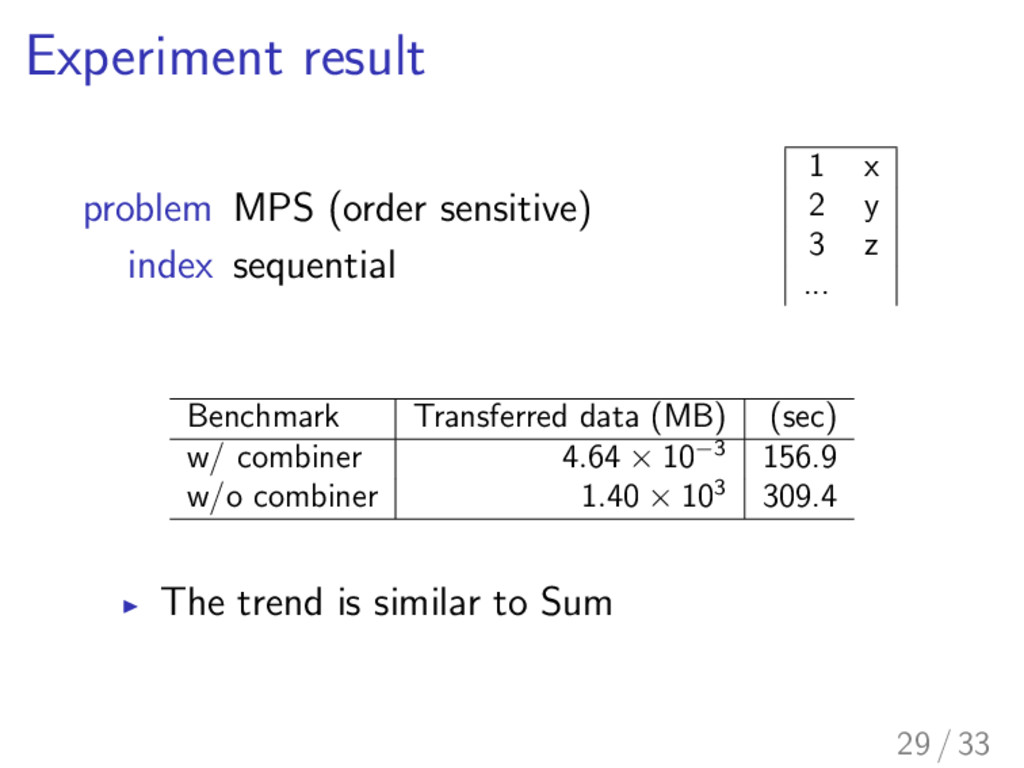
Experiment result problem MPS (order sensitive) index sequential 1 x
2 y 3 z ... Benchmark Transferred data (MB) (sec) w/ combiner 4 . 64 ⇥ 10 3 156.9 w/o combiner 1 . 40 ⇥ 103 309.4 I The trend is similar to Sum 29 / 33 -
Experiment result problem MPS (order sensitive) index random 5 x
9 y 2 z ... Benchmark Transferred data (MB) (sec) w/ combiner 2 . 06 ⇥ 103 510.4 w/o combiner 1 . 41 ⇥ 103 369.5 Worsened the result I Combiners can aggregate only consecutive data I Overhead of combiner (e.g., dealing with index) 30 / 33 -
Related work [Liu et al. Euro-Par 2011] also apply the
notion of the list homomorphism to MapReduce programs I Gets list homomorphism, execute MapReduce computation I Basically the same algorithm as ours I They don’t deal with combiners 31 / 33 -
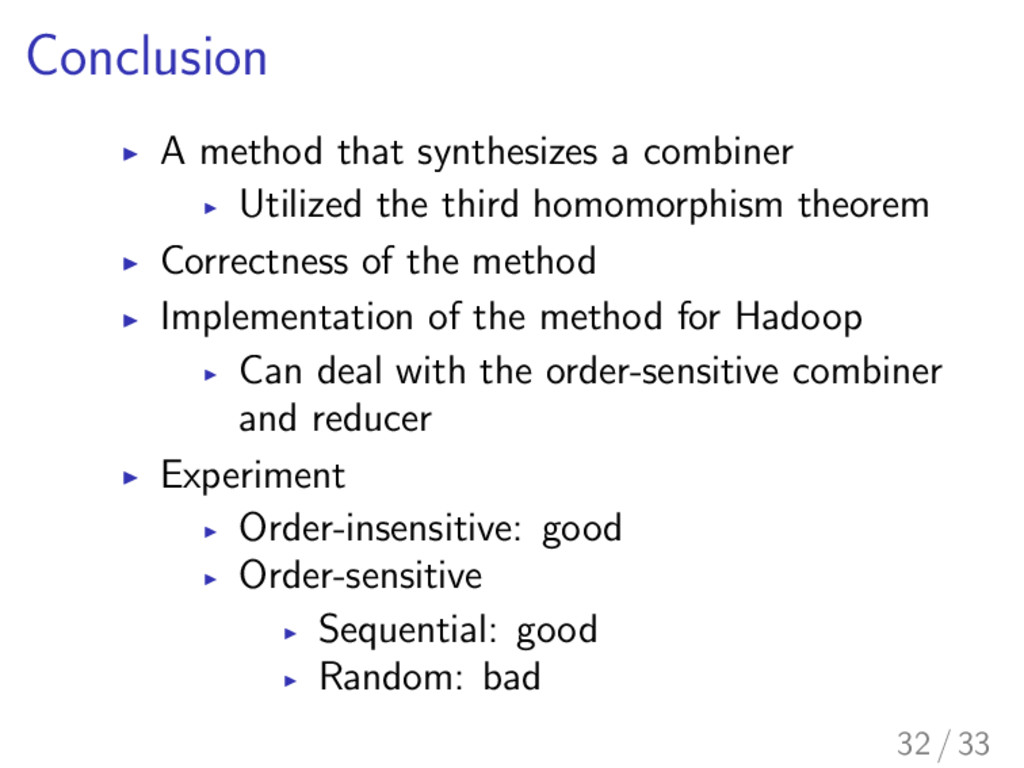
Conclusion I A method that synthesizes a combiner I Utilized
the third homomorphism theorem I Correctness of the method I Implementation of the method for Hadoop I Can deal with the order-sensitive combiner and reducer I Experiment I Order-insensitive: good I Order-sensitive I Sequential: good I Random: bad 32 / 33 -
Future work I Automatically decide whether the problem is order-sensitive
or not I Generate a right inverse automatically using [Morita et al. PLDI 2007] I Conduct more experiment 33 / 33