Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
vSphere環境でLLMをServeする
Search
masanara
December 20, 2023
Technology
300
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
vSphere環境でLLMをServeする
masanara
December 20, 2023
More Decks by masanara
See All by masanara
Cartographer入門
masanara
0
540
EKS Anywhere on vSphere
masanara
0
60
kpackによるコンテナイメージのビルド
masanara
0
140
Harbor RegistryのReplication機能
masanara
0
460
Kubernetes Operator for vSphere VM
masanara
0
71
Other Decks in Technology
See All in Technology
Claude の新機能を、 出た日に触って社内に届けるまで
rfdnxbro
1
170
DWH の限界突破! AI エージェント向け爆速リアルタイムデータ基盤 ClickHouse
jozono
1
470
JAWS-UGグッズ職人仕事の流儀
kentapapa
0
100
Active Record Connection Adaptersにおける長年の課題に再び取り組む
yahonda
0
140
スプシの手作業からの解脱 ~更新はClaude Codeに、見せ方と使い方はGASアプリに任せる~
kentarofujii
0
150
Metadata - Section 1: HTML Basics
mohab1
0
120
20261017福岡devIO 「AIは"良いダッシュボード"を作れるか?
jtakeda
0
140
触りたくないデータに、どう触るか AI時代のRBACアクセスガバナンス
ivry_presentationmaterials
0
260
自作バイナリを動かす「入口」8選
puhitaku
2
1.3k
パッチ更新でterraform initが落ちた日
grimoh
1
140
実体験から学ぶ分析エージェントの開発と運⽤
recruitengineers
PRO
8
2.4k
UniFi(ユニファイ)AIカメラの現場活用
ludicmind
1
440
Featured
See All Featured
What the history of the web can teach us about the future of AI
inesmontani
PRO
2
740
KATA
mclloyd
PRO
35
16k
HDC tutorial
michielstock
2
960
Producing Creativity
orderedlist
PRO
348
41k
SEOcharity - Dark patterns in SEO and UX: How to avoid them and build a more ethical web
sarafernandez
0
300
Organizational Design Perspectives: An Ontology of Organizational Design Elements
kimpetersen
PRO
1
850
Dealing with People You Can't Stand - Big Design 2015
cassininazir
367
27k
Money Talks: Using Revenue to Get Sh*t Done
nikkihalliwell
0
520
My Coaching Mixtape
mlcsv
0
360
Future Trends and Review - Lecture 12 - Web Technologies (1019888BNR)
signer
PRO
0
3.8k
Statistics for Hackers
jakevdp
799
230k
Into the Great Unknown - MozCon
thekraken
41
2.8k
Transcript
vSphere 環境で日本語対応 LLM を利用する Japan VMUG vExpert が語る #32 2023/12/20
本日の内容 VMware Private AI Reference Architecture for Open Sourceを参考に、vSphere環境 で日本語に対応したLLMを利用してみました。
• VMware Private AI Reference Architecture for Open Source https://github.com/vmware-ai-labs/VMware-generative-ai-reference-architecture • Ray Serveを利用した日本語LLM ELYZAの利用 - VMware Private AI https://www.netone.co.jp/media/detail/20231201-1/
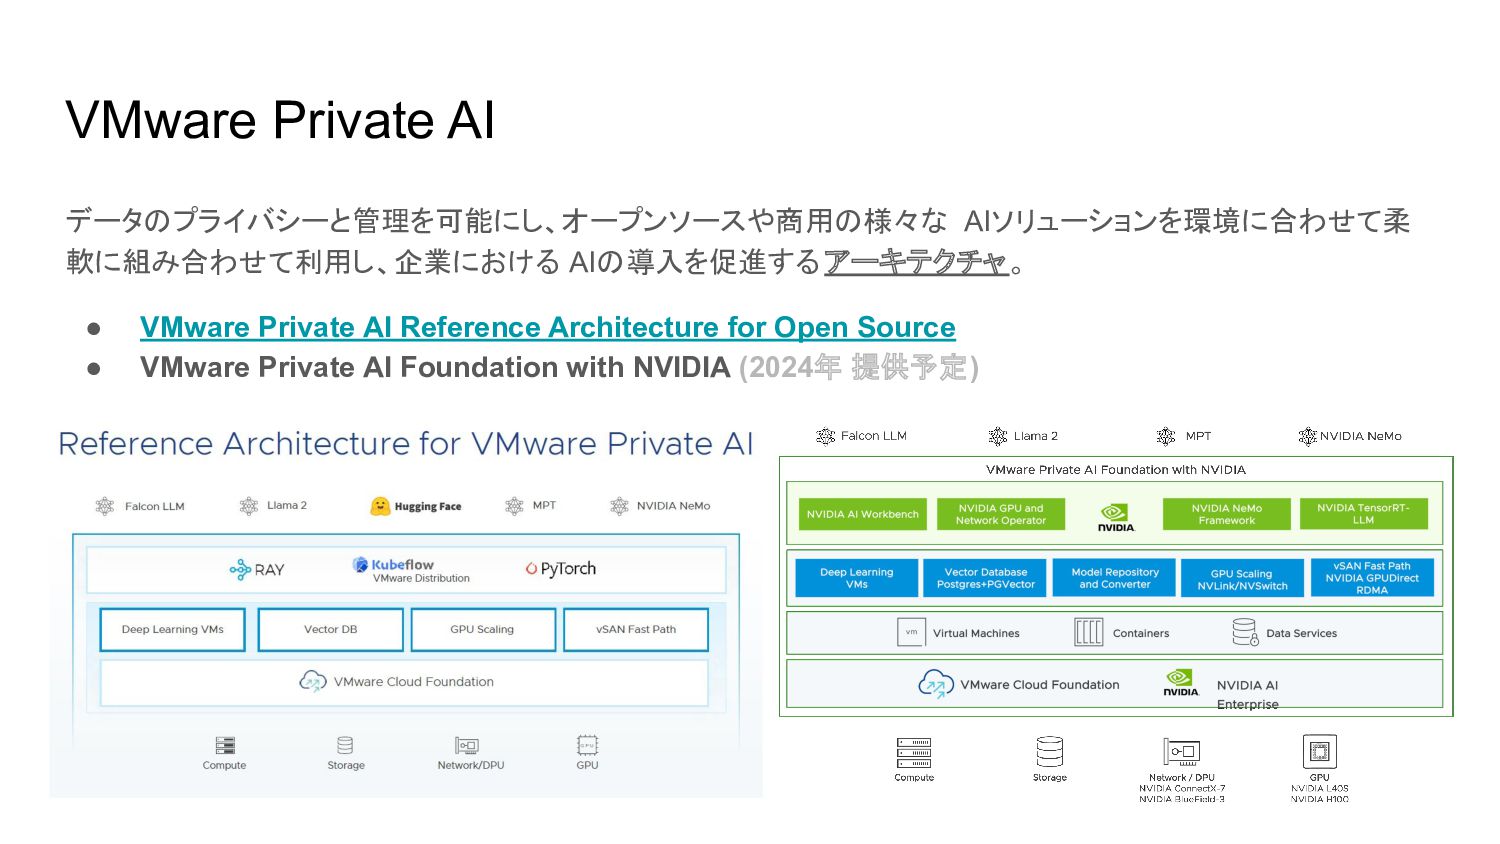
VMware Private AI データのプライバシーと管理を可能にし、オープンソースや商用の様々な AIソリューションを環境に合わせて柔 軟に組み合わせて利用し、企業における AIの導入を促進するアーキテクチャ。 • VMware Private
AI Reference Architecture for Open Source • VMware Private AI Foundation with NVIDIA (2024年 提供予定)
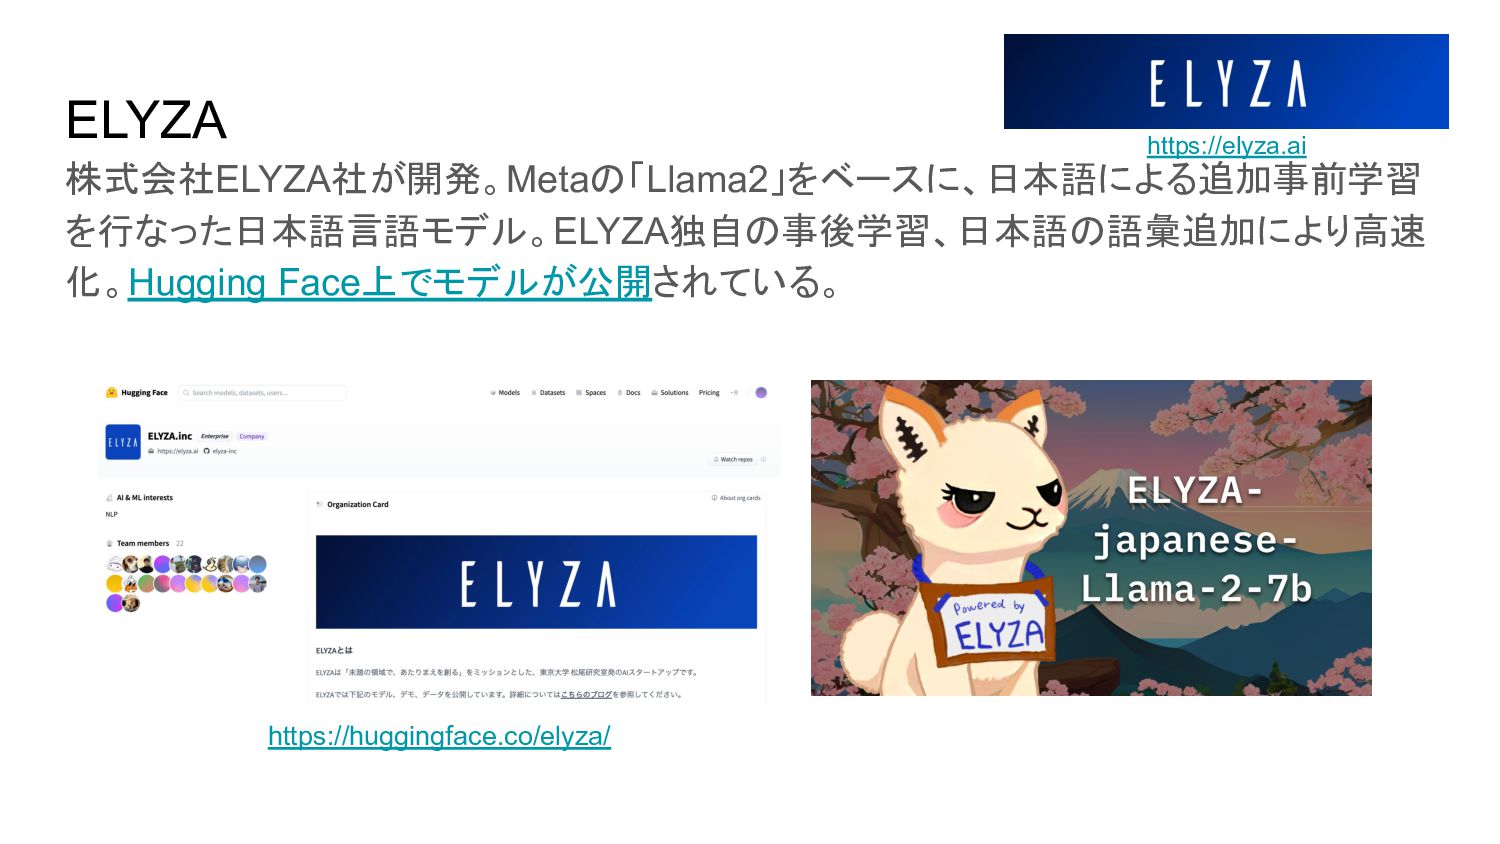
ELYZA 株式会社ELYZA社が開発。Metaの「Llama2」をベースに、日本語による追加事前学習 を行なった日本語言語モデル。ELYZA独自の事後学習、日本語の語彙追加により高速 化。Hugging Face上でモデルが公開されている。 https://huggingface.co/elyza/ https://elyza.ai
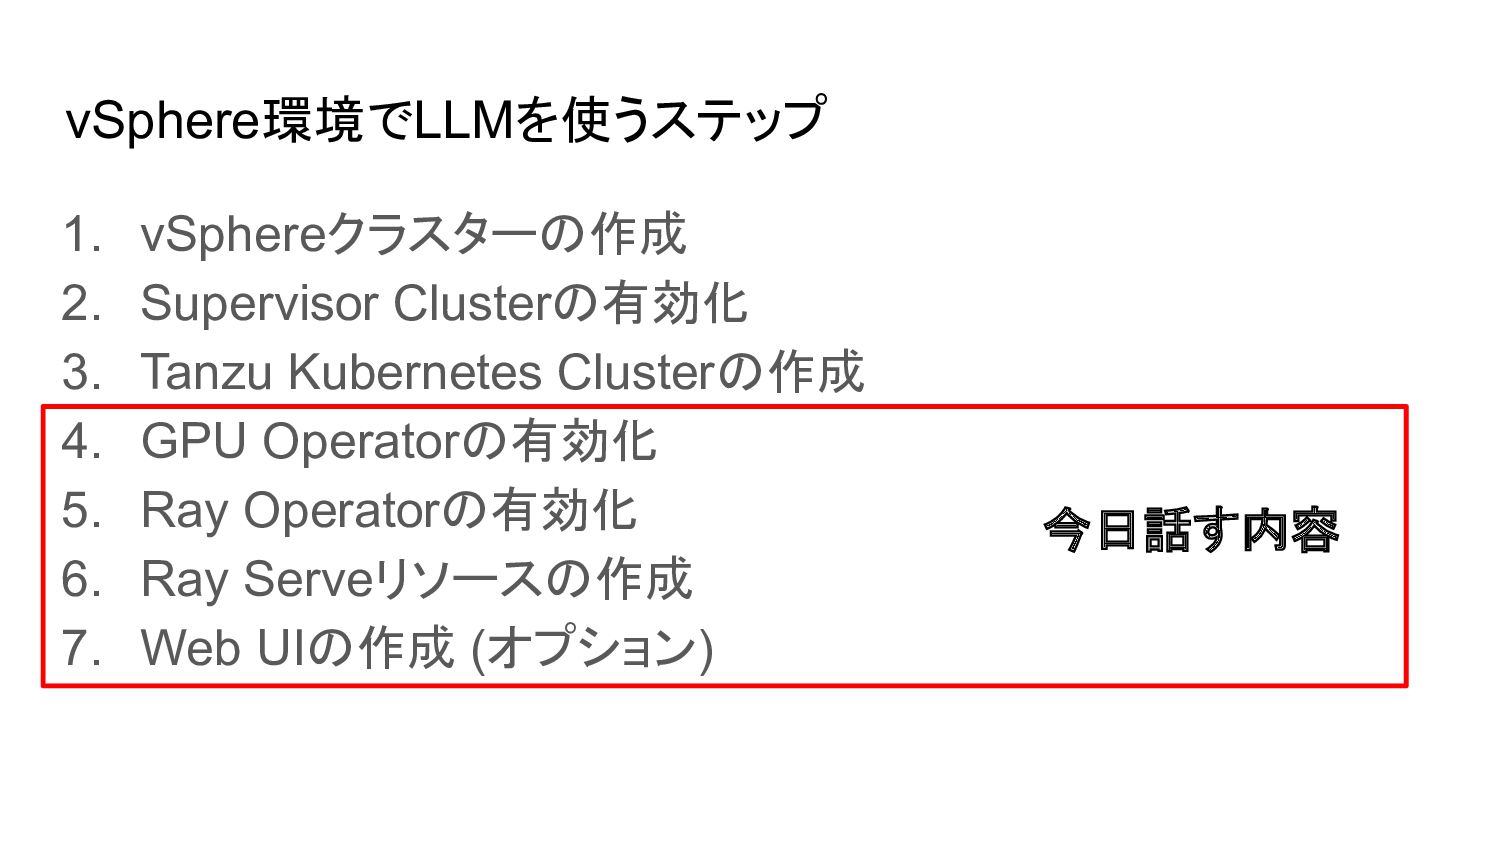
vSphere環境でLLMを使うステップ 1. vSphereクラスターの作成 2. Supervisor Clusterの有効化 3. Tanzu Kubernetes Clusterの作成
4. GPU Operatorの有効化 5. Ray Operatorの有効化 6. Ray Serveリソースの作成 7. Web UIの作成 (オプション) 今日話す内容
GPU Operator Kubernetesクラスターを構成するノードにGPUのドライバーをインストールする仕組み。 NFD(Node Feature Discovery) Podにより、GPUが搭載されたノードを認識。GPU搭載ノードにだけPodとして ドライバーがインストールされる。 ESXiのGPUをvGPUとしてVMに接続し、Kubernetesノードとして 利用可能。
Kubernetes vSphere Node (VM) vGPU Physical Server GPU Node (VM) vGPU Node (VM) GPU Driver nvidia.com/gpu: 1 NFD GPU Driver NFD NFD
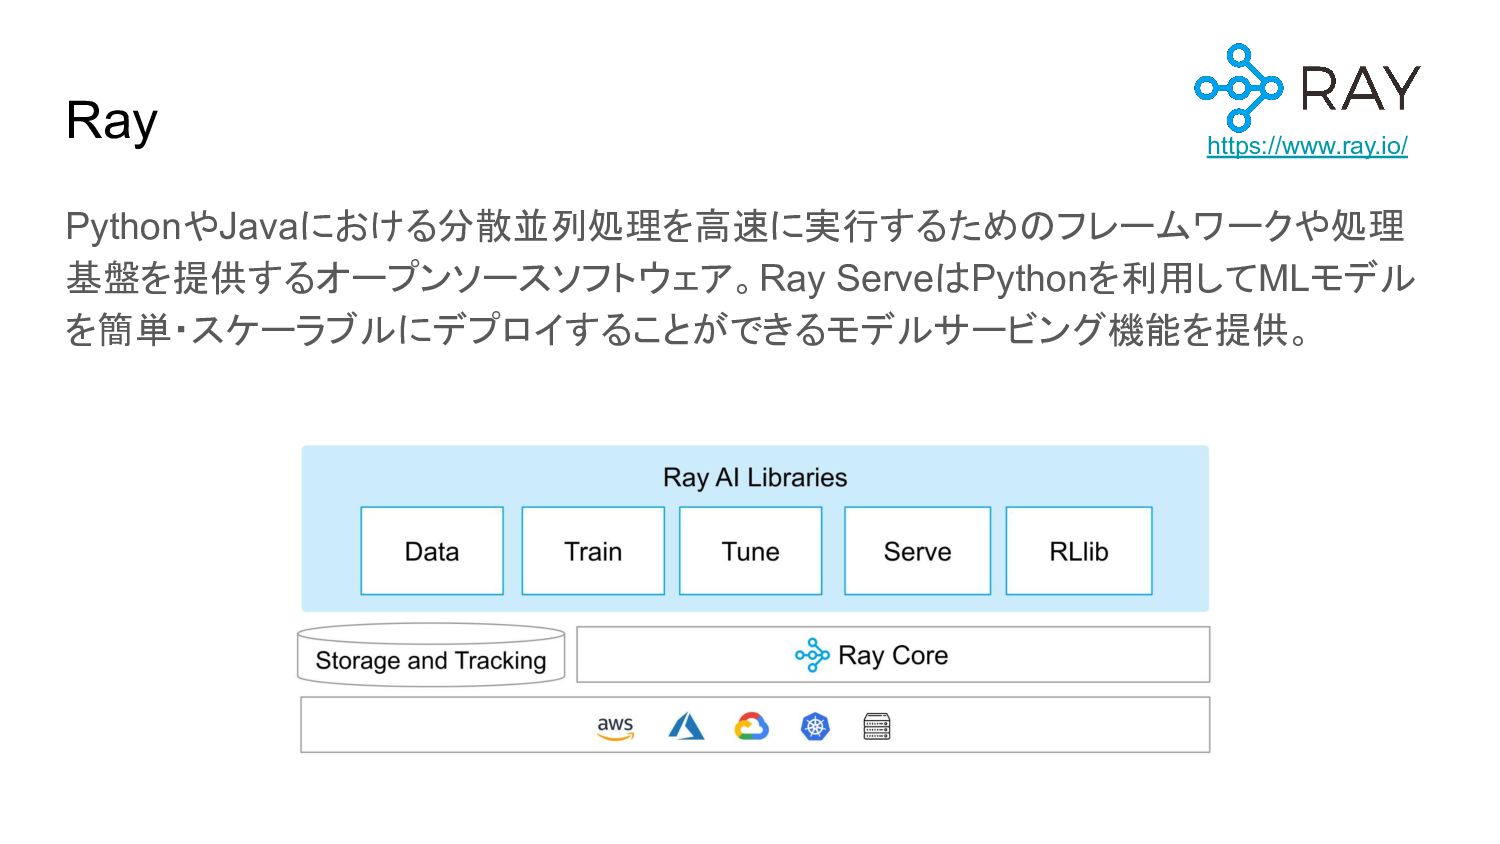
Ray PythonやJavaにおける分散並列処理を高速に実行するためのフレームワークや処理 基盤を提供するオープンソースソフトウェア。Ray ServeはPythonを利用してMLモデル を簡単・スケーラブルにデプロイすることができるモデルサービング機能を提供。 https://www.ray.io/
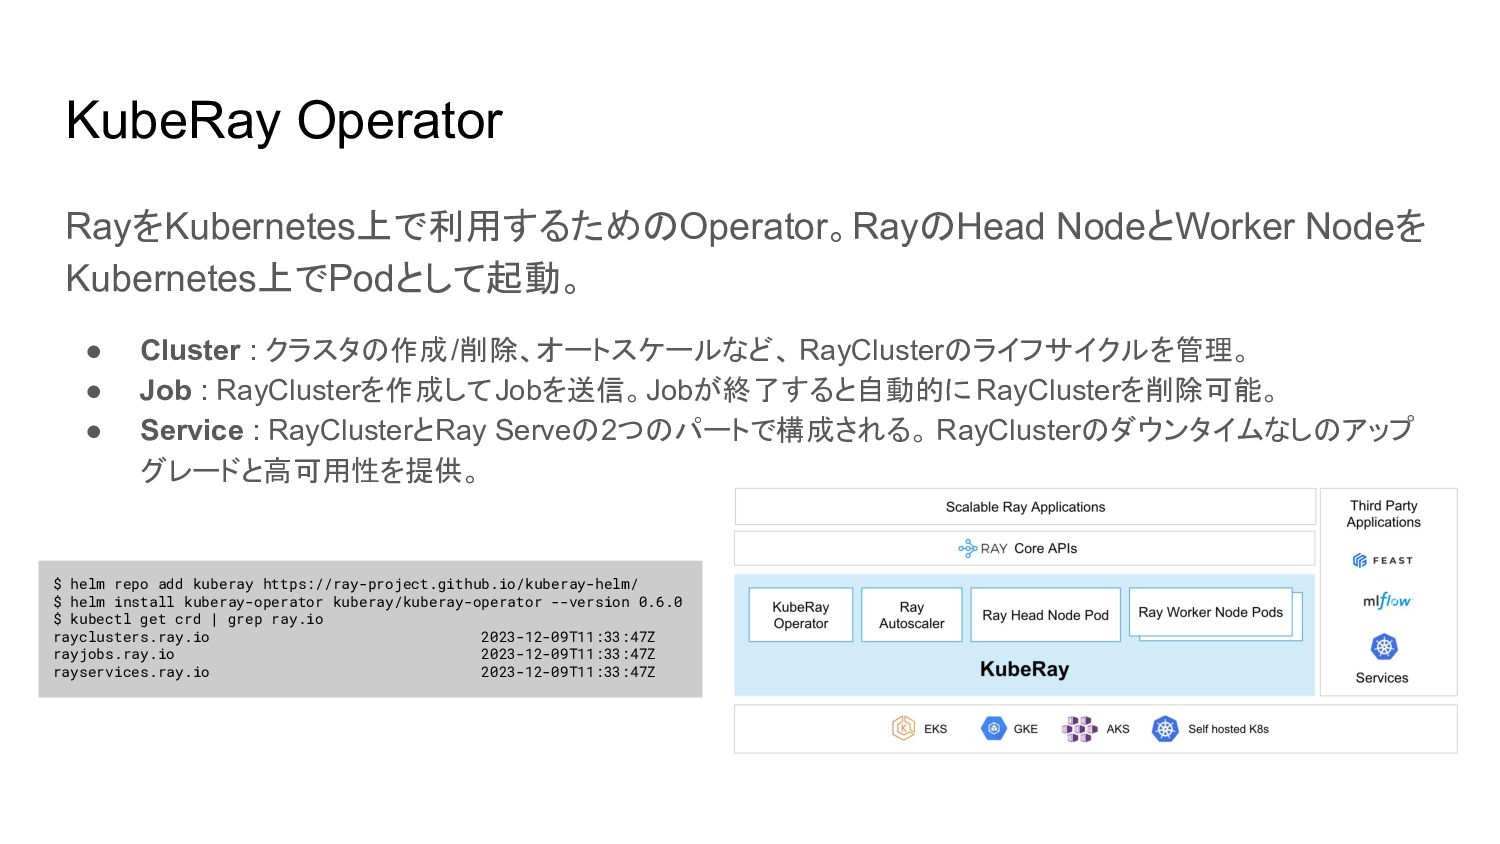
KubeRay Operator RayをKubernetes上で利用するためのOperator。RayのHead NodeとWorker Nodeを Kubernetes上でPodとして起動。 • Cluster : クラスタの作成/削除、オートスケールなど、
RayClusterのライフサイクルを管理。 • Job : RayClusterを作成してJobを送信。Jobが終了すると自動的に RayClusterを削除可能。 • Service : RayClusterとRay Serveの2つのパートで構成される。 RayClusterのダウンタイムなしのアップ グレードと高可用性を提供。 $ helm repo add kuberay https://ray-project.github.io/kuberay-helm/ $ helm install kuberay-operator kuberay/kuberay-operator --version 0.6.0 $ kubectl get crd | grep ray.io rayclusters.ray.io 2023-12-09T11:33:47Z rayjobs.ray.io 2023-12-09T11:33:47Z rayservices.ray.io 2023-12-09T11:33:47Z
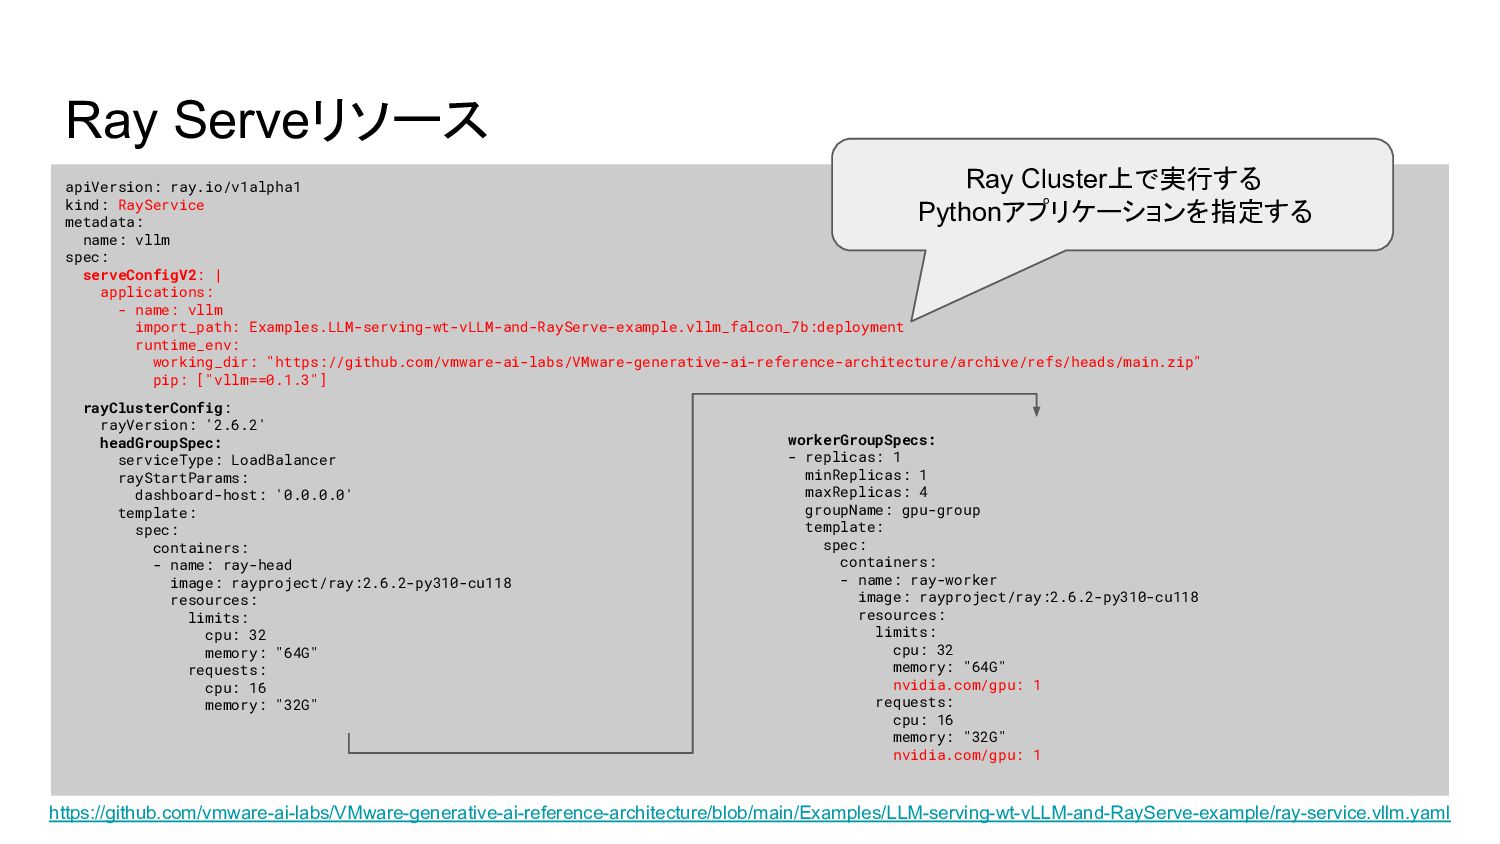
Ray Serveリソース apiVersion: ray.io/v1alpha1 kind: RayService metadata: name: vllm spec:
serveConfigV2: | applications: - name: vllm import_path: Examples.LLM-serving-wt-vLLM-and-RayServe-example.vllm_falcon_7b:deployment runtime_env: working_dir: "https://github.com/vmware-ai-labs/VMware-generative-ai-reference-architecture/archive/refs/heads/main.zip" pip: ["vllm==0.1.3"] workerGroupSpecs: - replicas: 1 minReplicas: 1 maxReplicas: 4 groupName: gpu-group template: spec: containers: - name: ray-worker image: rayproject/ray:2.6.2-py310-cu118 resources: limits: cpu: 32 memory: "64G" nvidia.com/gpu: 1 requests: cpu: 16 memory: "32G" nvidia.com/gpu: 1 rayClusterConfig: rayVersion: '2.6.2' headGroupSpec: serviceType: LoadBalancer rayStartParams: dashboard-host: '0.0.0.0' template: spec: containers: - name: ray-head image: rayproject/ray:2.6.2-py310-cu118 resources: limits: cpu: 32 memory: "64G" requests: cpu: 16 memory: "32G" https://github.com/vmware-ai-labs/VMware-generative-ai-reference-architecture/blob/main/Examples/LLM-serving-wt-vLLM-and-RayServe-example/ray-service.vllm.yaml Ray Cluster上で実行する Pythonアプリケーションを指定する
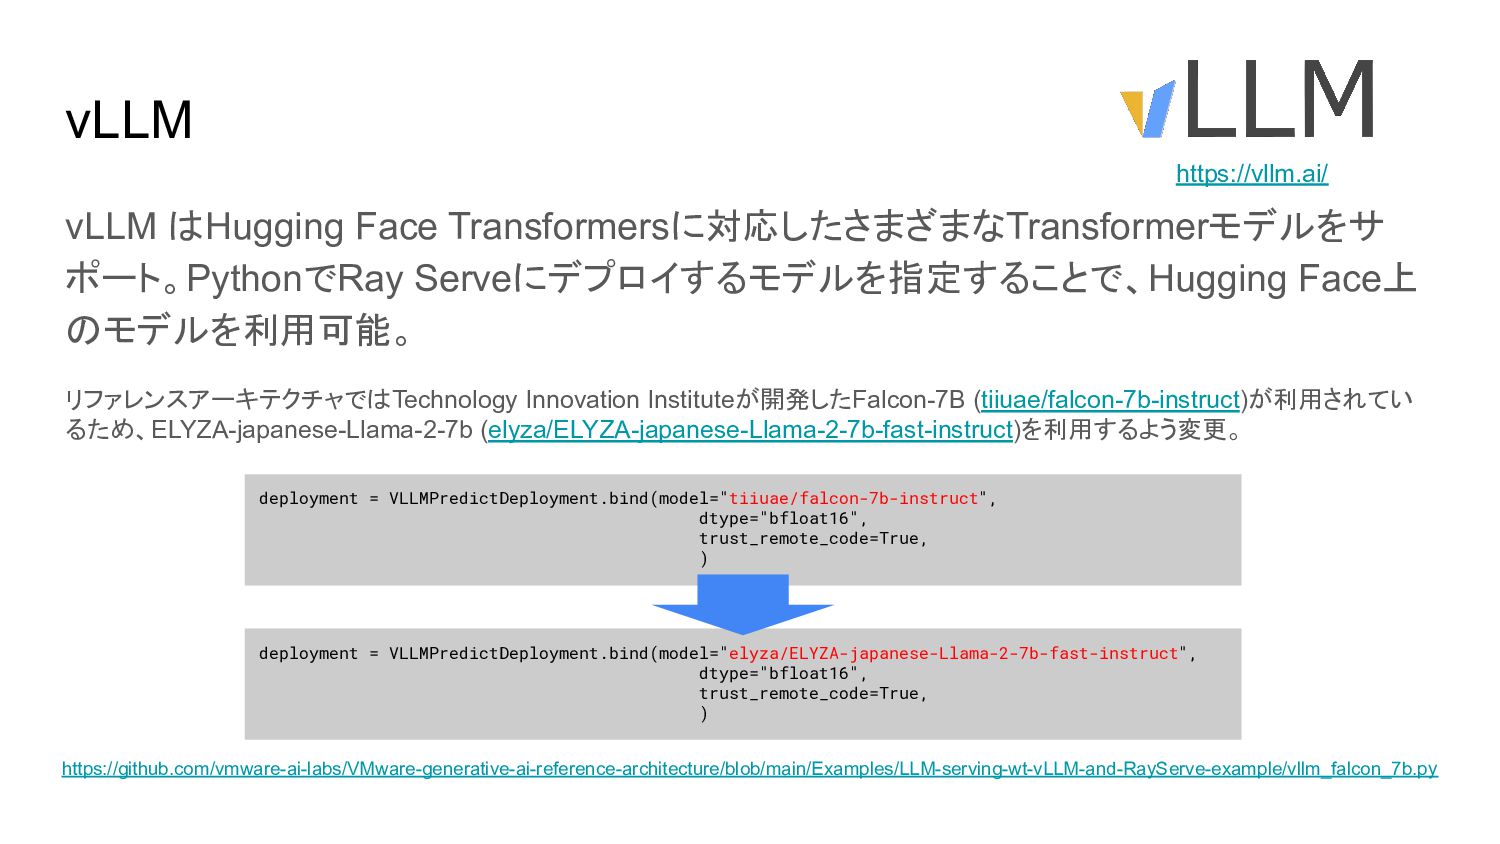
vLLM vLLM はHugging Face Transformersに対応したさまざまなTransformerモデルをサ ポート。PythonでRay Serveにデプロイするモデルを指定することで、Hugging Face上 のモデルを利用可能。 https://vllm.ai/
リファレンスアーキテクチャではTechnology Innovation Instituteが開発したFalcon-7B (tiiuae/falcon-7b-instruct)が利用されてい るため、ELYZA-japanese-Llama-2-7b (elyza/ELYZA-japanese-Llama-2-7b-fast-instruct)を利用するよう変更。 https://github.com/vmware-ai-labs/VMware-generative-ai-reference-architecture/blob/main/Examples/LLM-serving-wt-vLLM-and-RayServe-example/vllm_falcon_7b.py deployment = VLLMPredictDeployment.bind(model="tiiuae/falcon-7b-instruct", dtype="bfloat16", trust_remote_code=True, ) deployment = VLLMPredictDeployment.bind(model="elyza/ELYZA-japanese-Llama-2-7b-fast-instruct", dtype="bfloat16", trust_remote_code=True, )
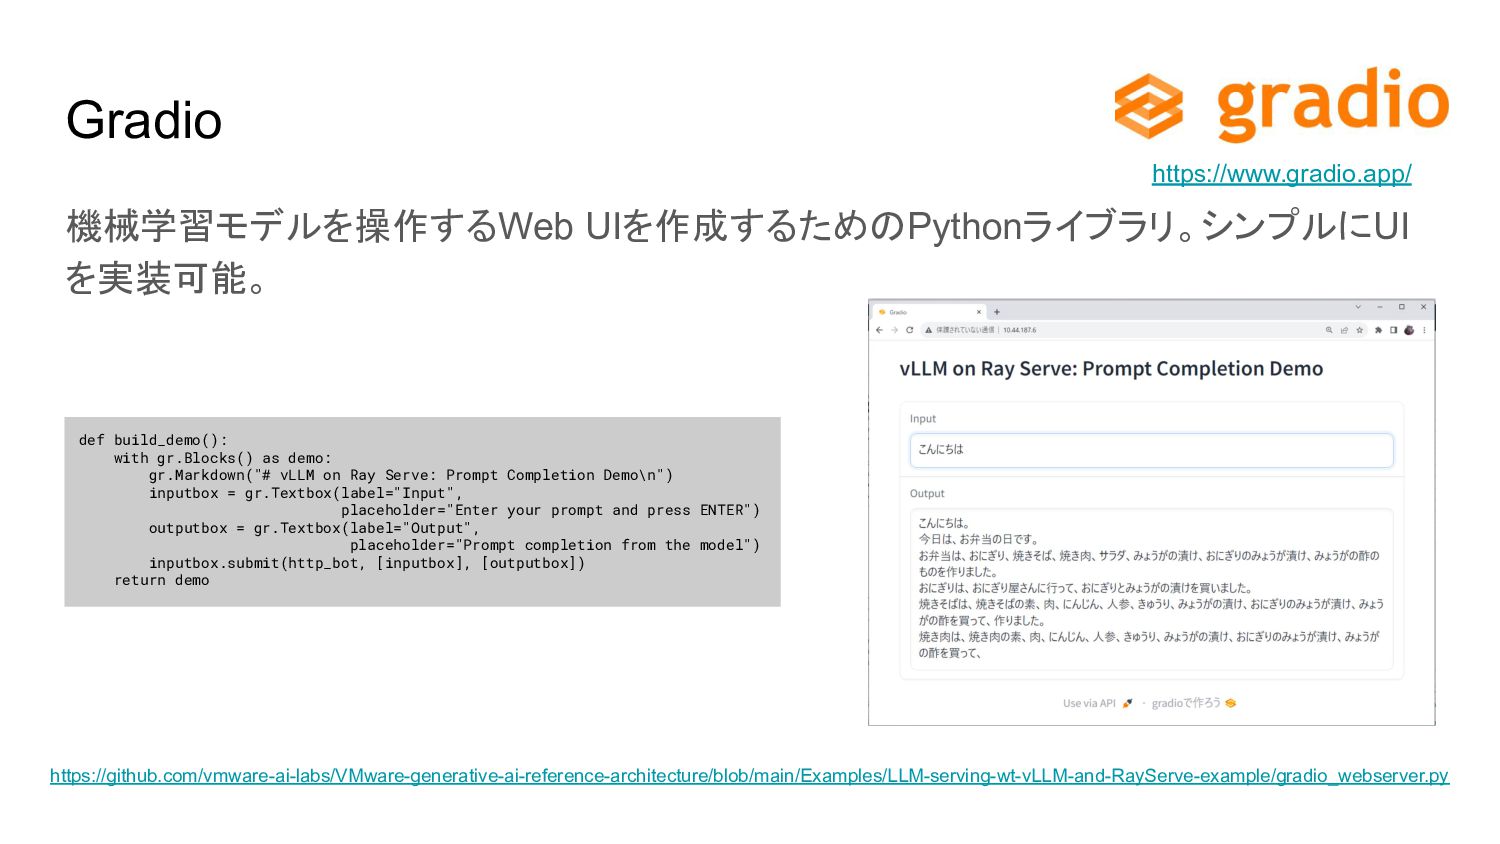
Gradio 機械学習モデルを操作するWeb UIを作成するためのPythonライブラリ。シンプルにUI を実装可能。 https://www.gradio.app/ def build_demo(): with gr.Blocks() as
demo: gr.Markdown("# vLLM on Ray Serve: Prompt Completion Demo\n") inputbox = gr.Textbox(label="Input", placeholder="Enter your prompt and press ENTER") outputbox = gr.Textbox(label="Output", placeholder="Prompt completion from the model") inputbox.submit(http_bot, [inputbox], [outputbox]) return demo https://github.com/vmware-ai-labs/VMware-generative-ai-reference-architecture/blob/main/Examples/LLM-serving-wt-vLLM-and-RayServe-example/gradio_webserver.py
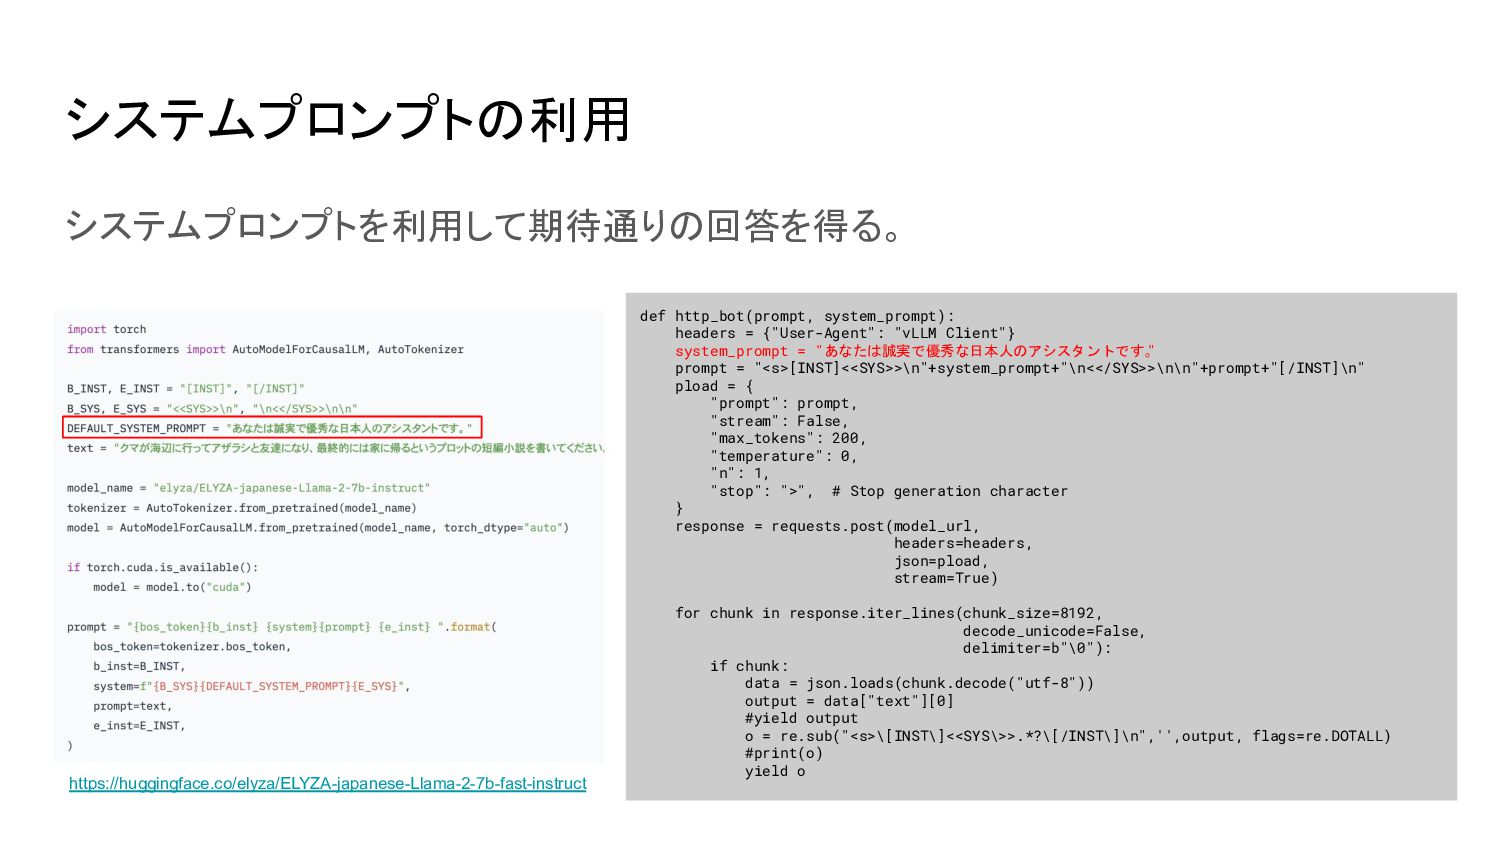
システムプロンプトの利用 システムプロンプトを利用して期待通りの回答を得る。 def http_bot(prompt, system_prompt): headers = {"User-Agent": "vLLM Client"}
system_prompt = "あなたは誠実で優秀な日本人のアシスタントです。 " prompt = "<s>[INST]<<SYS>>\n"+system_prompt+"\n<</SYS>>\n\n"+prompt+"[/INST]\n" pload = { "prompt": prompt, "stream": False, "max_tokens": 200, "temperature": 0, "n": 1, "stop": ">", # Stop generation character } response = requests.post(model_url, headers=headers, json=pload, stream=True) for chunk in response.iter_lines(chunk_size=8192, decode_unicode=False, delimiter=b"\0"): if chunk: data = json.loads(chunk.decode("utf-8")) output = data["text"][0] #yield output o = re.sub("<s>\[INST\]<<SYS\>>.*?\[/INST\]\n",'',output, flags=re.DOTALL) #print(o) yield o https://huggingface.co/elyza/ELYZA-japanese-Llama-2-7b-fast-instruct
ありがとうございました


 masanara
 rfdnxbro
 jozono
 kentapapa
 yahonda
 kentarofujii
 mohab1
 jtakeda
 ivry_presentationmaterials
 puhitaku
 grimoh
 recruitengineers
 ludicmind
 inesmontani
 mclloyd
 michielstock
 orderedlist
 sarafernandez
 kimpetersen
 cassininazir
 nikkihalliwell
 mlcsv
 signer
 jakevdp
 thekraken