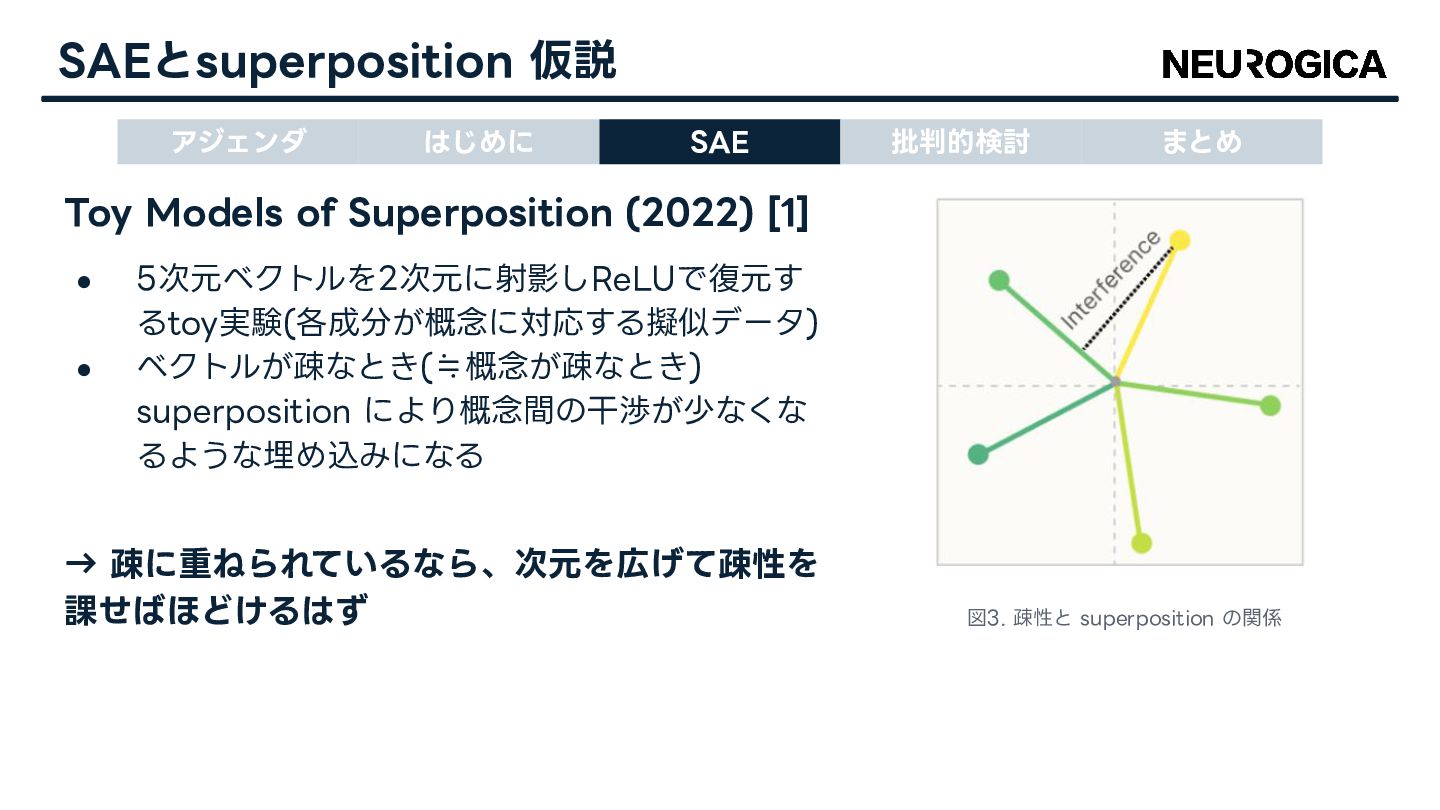
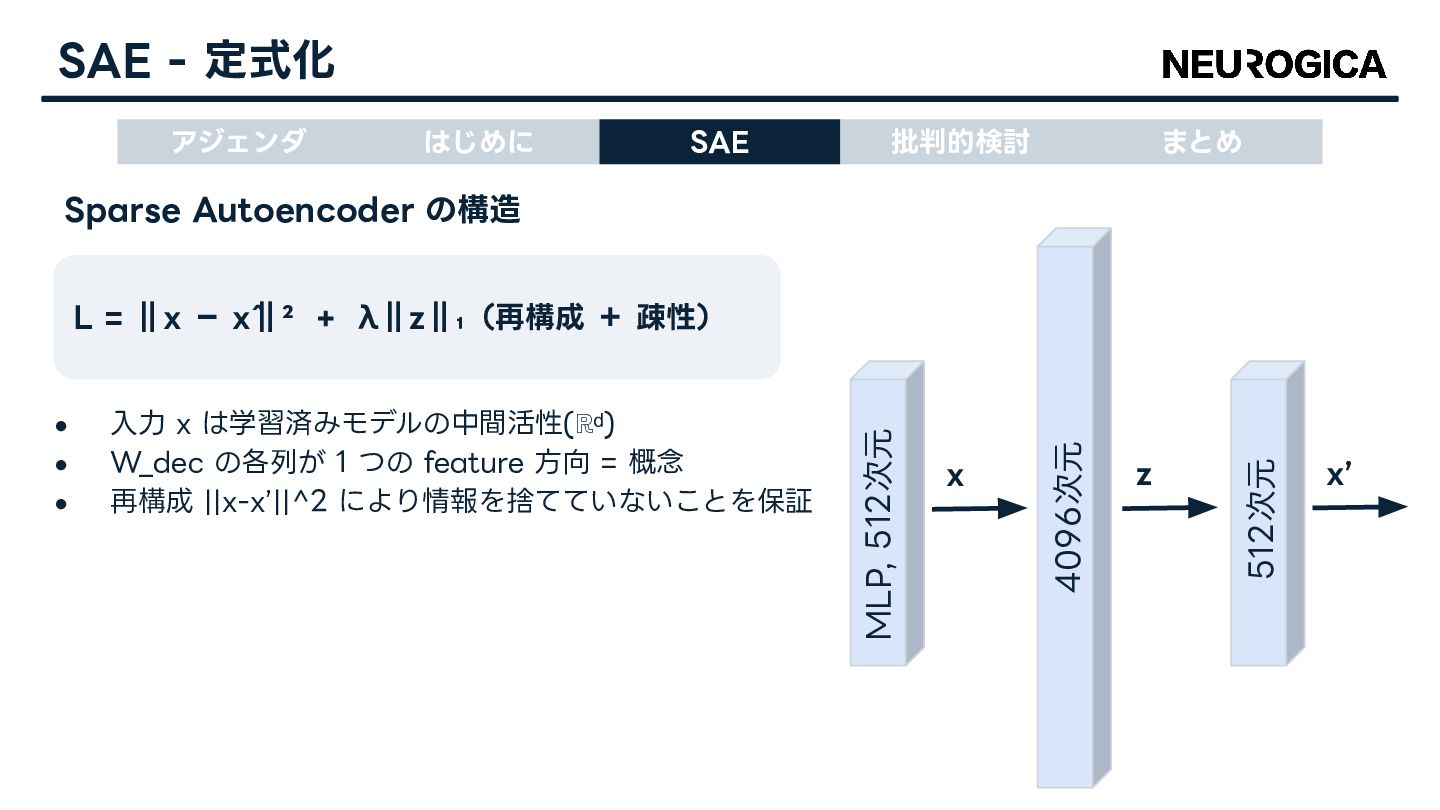
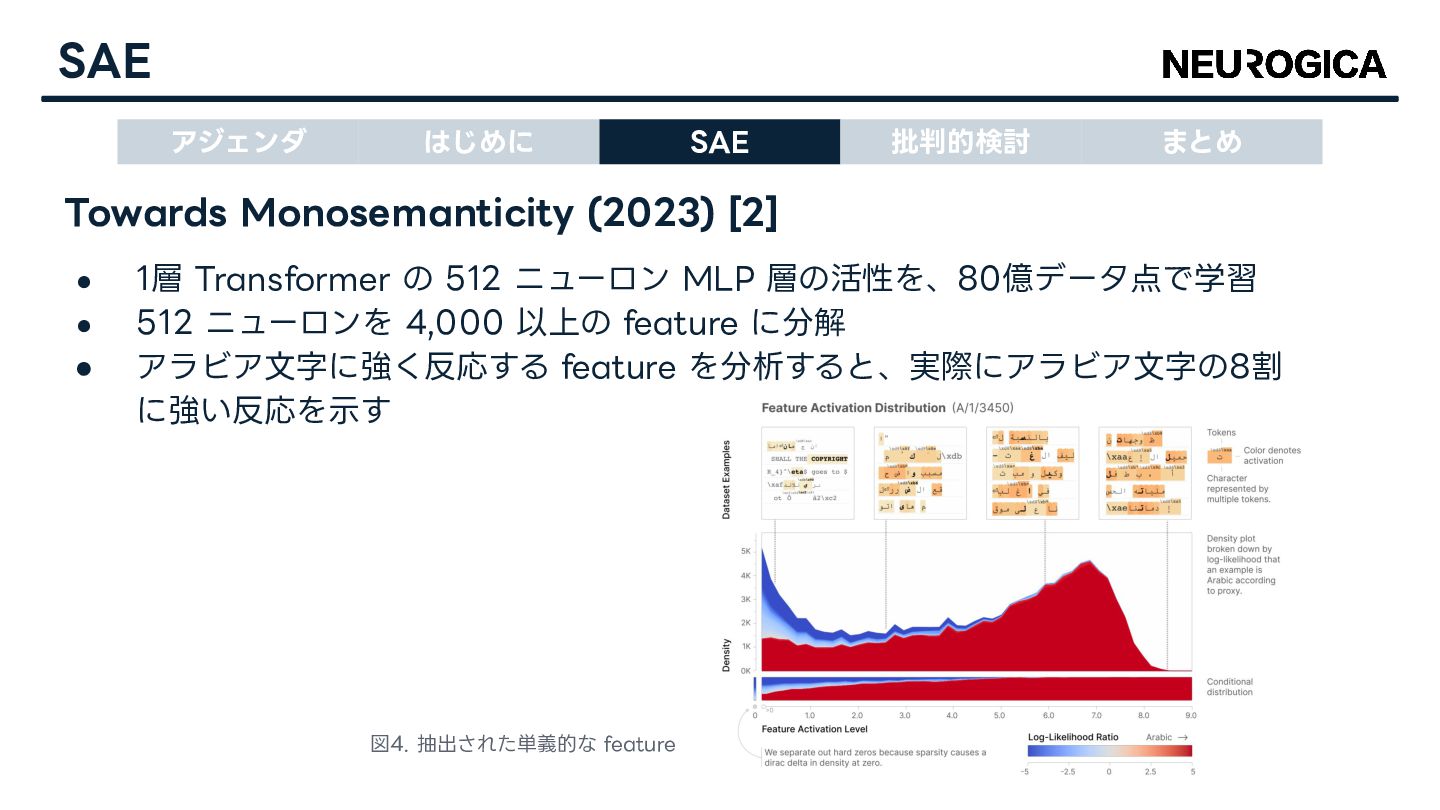
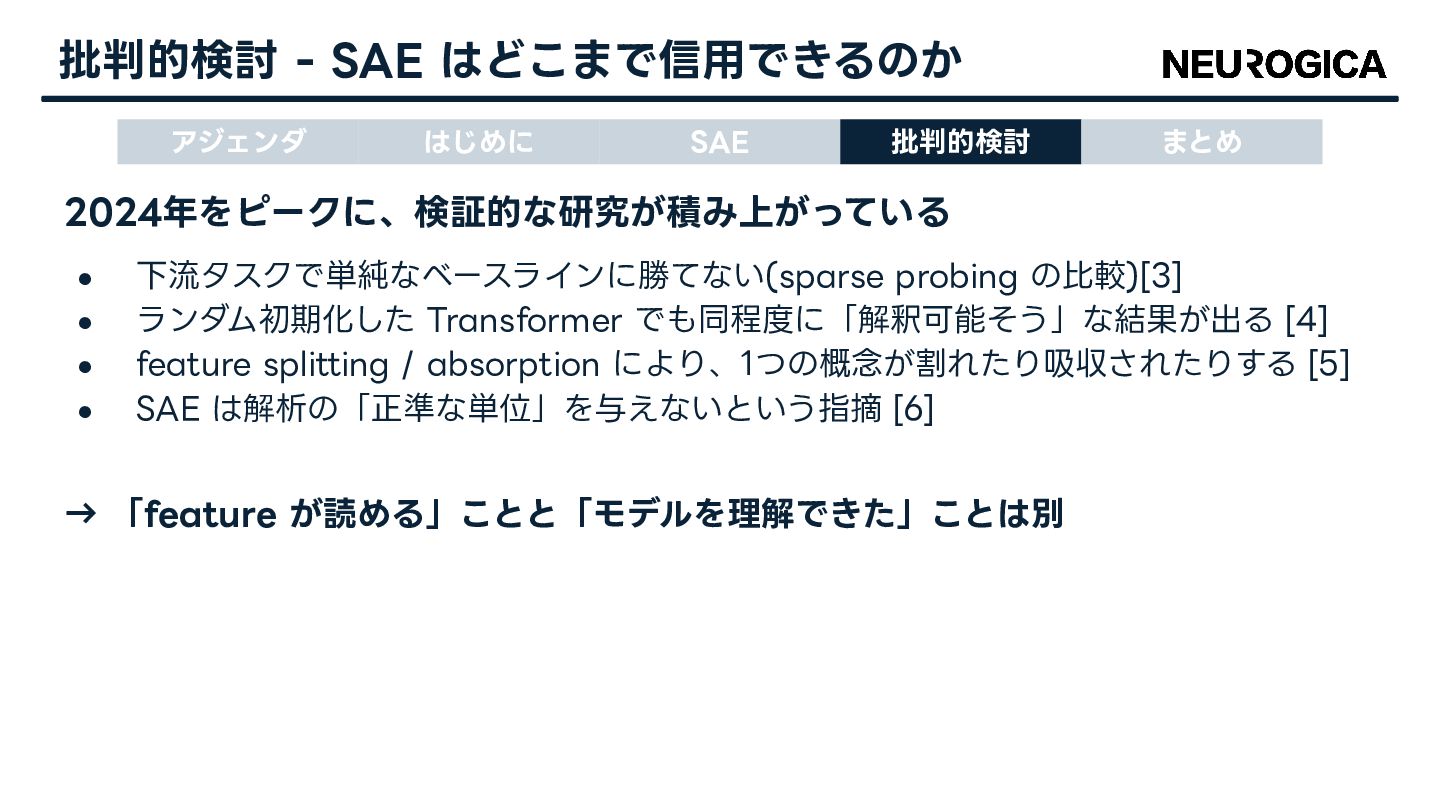
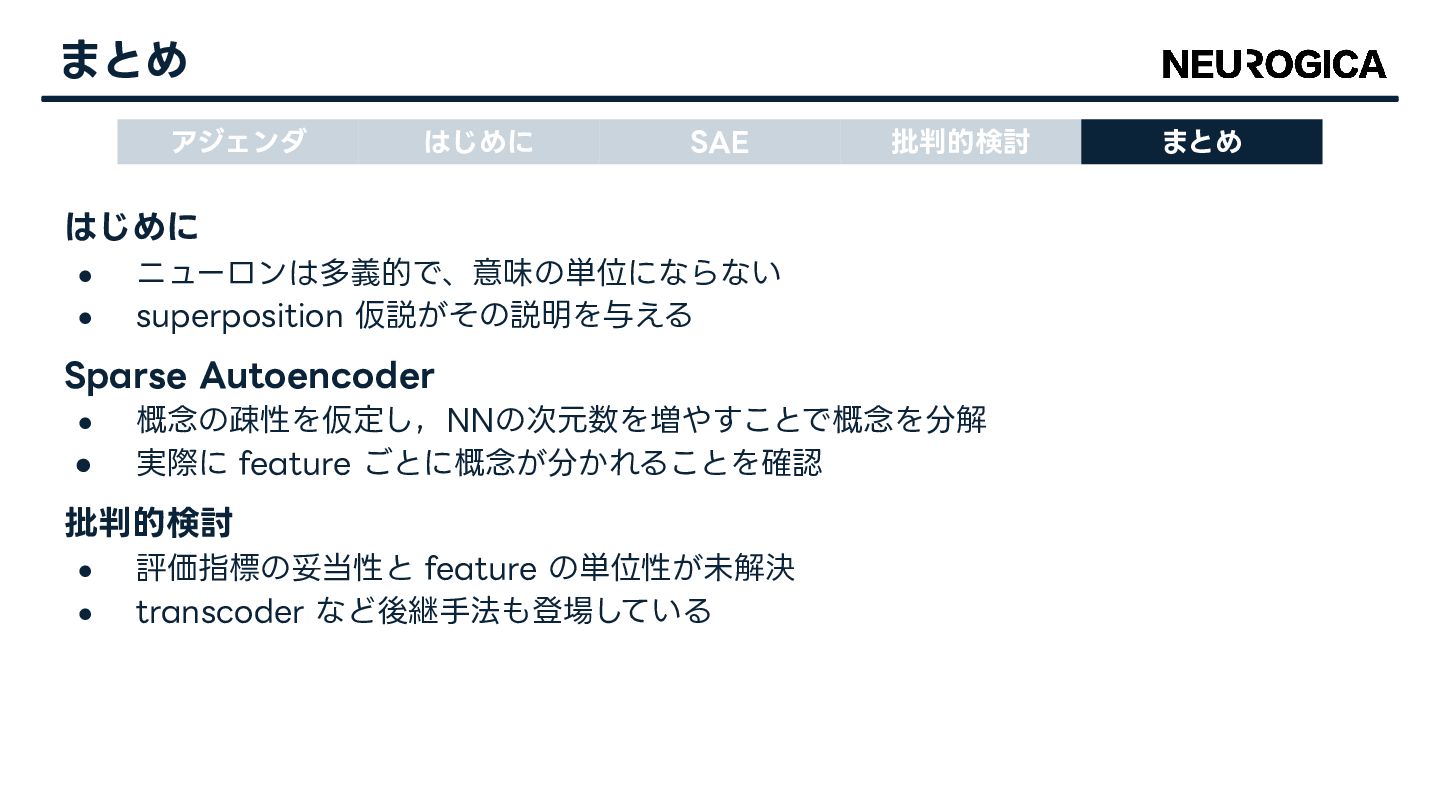
• Sparse Autoencoder Toy Models of Superposition(Elhage et al., 2022) Towards Monosemanticity(Bricken et al., 2023) • 2025年以降の批判的な⽴場 評価指標への疑義、feature の単位性、後継⼿法 • まとめ まとめ
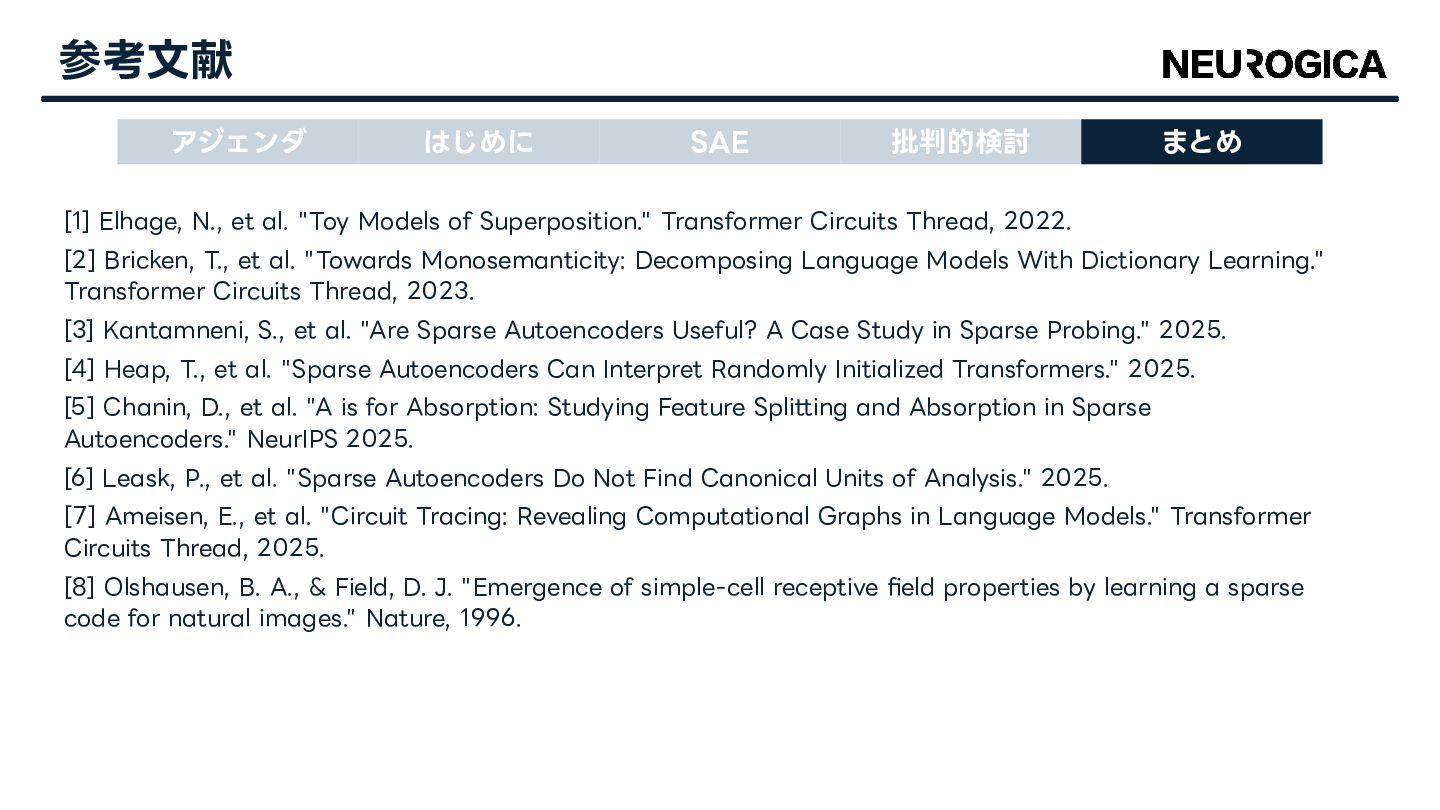
al. "Toy Models of Superposition." Transformer Circuits Thread, 2022. [2] Bricken, T., et al. "Towards Monosemanticity: Decomposing Language Models With Dictionary Learning." Transformer Circuits Thread, 2023. [3] Kantamneni, S., et al. "Are Sparse Autoencoders Useful? A Case Study in Sparse Probing." 2025. [4] Heap, T., et al. "Sparse Autoencoders Can Interpret Randomly Initialized Transformers." 2025. [5] Chanin, D., et al. "A is for Absorption: Studying Feature Splitting and Absorption in Sparse Autoencoders." NeurIPS 2025. [6] Leask, P., et al. "Sparse Autoencoders Do Not Find Canonical Units of Analysis." 2025. [7] Ameisen, E., et al. "Circuit Tracing: Revealing Computational Graphs in Language Models." Transformer Circuits Thread, 2025. [8] Olshausen, B. A., & Field, D. J. "Emergence of simple-cell receptive field properties by learning a sparse code for natural images." Nature, 1996.


 neurogica
 uhyo
 i35_267
 sassssan68
 7nohe
 bata_24
 alchemy1115
 cielo1985
 pirosikick
 thkt
 hikarusato
 tosite
 shimastripe
 eileencodes
 pwiseman
 tammielis
 thoeni
 iamctodd
 codingconduct
 bermonpainter
 leimatthew05
 honzajavorek
 matthewcrist
 aleyda
 garrettdimon