Share
Embed
Trends in Machine Learning
with a focus on the Python ecosystem. Talk given at Paris DataGeeks 2013. This is a preliminary version of the talk I will give at SciPy 2013. Feedback appreciated.
Olivier Grisel
May 20, 2013
Transcript
62 slides
-
Trends in Machine Learning and the SciPy Community Paris Datageeks
- May 2013 mardi 21 mai 13 -
About me • Regular contributor to scikit-learn • Interested in
NLP, Computer Vision, Predictive Modeling & ML in general • Interested in Cloud Tech and Scaling Stuff • Starting an ML consultancy, writing a book http://ogrisel.com mardi 21 mai 13 -
Outline • Black Box Models with scikit-learn • Probabilistic Programming
with PyMC • Deep Learning with PyLearn2 & Theano mardi 21 mai 13 -
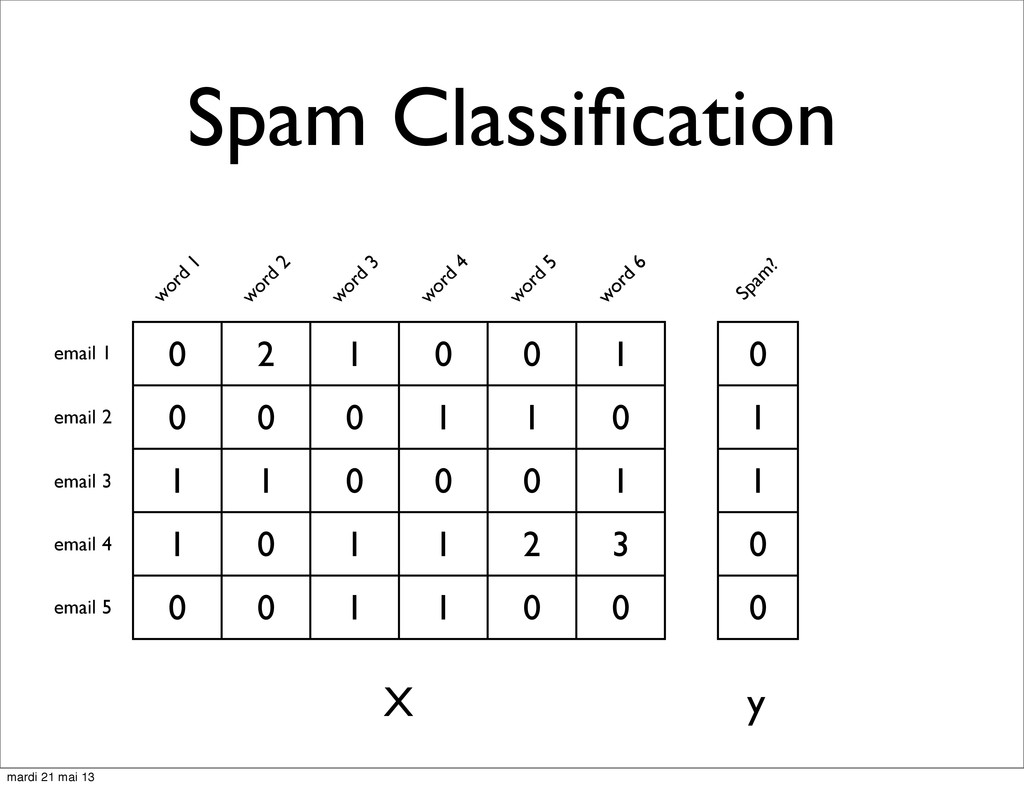
Spam Classification 0 2 1 0 0 1 0 0
0 1 1 0 1 1 0 0 0 1 1 0 1 1 2 3 0 0 1 1 0 0 word 1 word 2 word 3 word 4 word 5 word 6 email 1 email 2 email 3 email 4 email 5 X word 6 0 1 1 0 0 Spam ? y mardi 21 mai 13 -
Topic Classification 0 2 1 0 0 1 0 0
0 1 1 0 1 1 0 0 0 1 1 0 1 1 2 3 0 0 1 1 0 0 word 1 word 2 word 3 word 4 word 5 word 6 news 1 news 2 news 3 news 4 news 5 X 0 0 1 1 1 0 1 0 0 0 1 1 0 0 0 word 6 Sport Business Tech. y mardi 21 mai 13 -
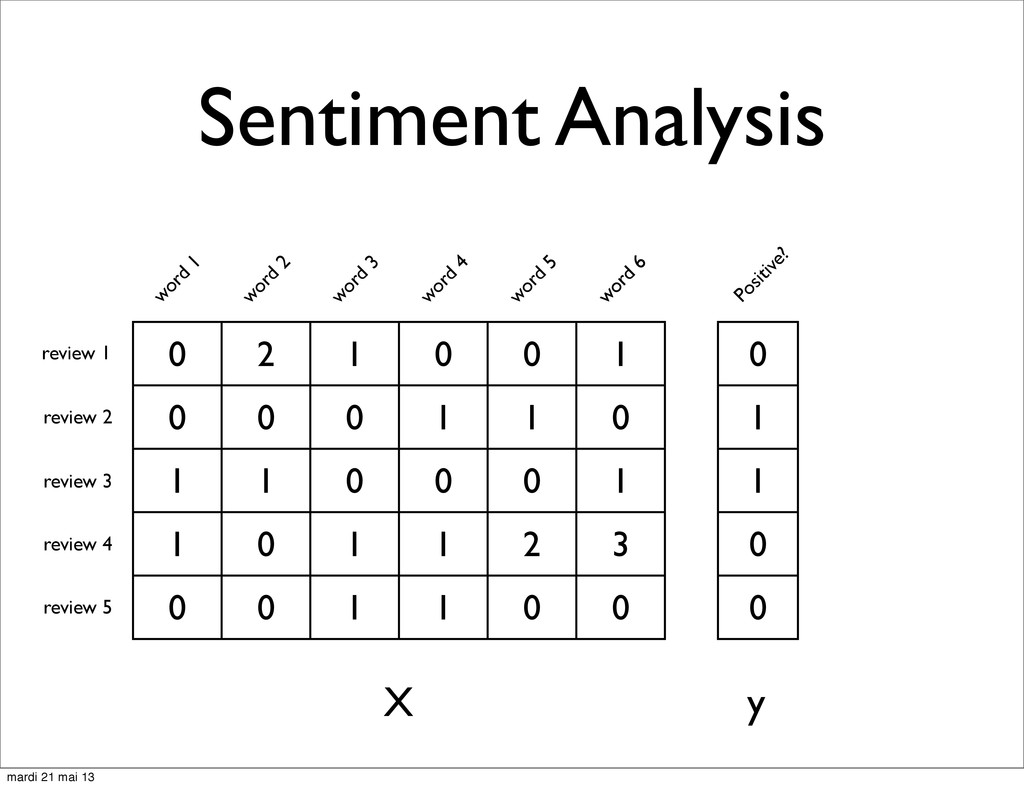
Sentiment Analysis 0 2 1 0 0 1 0 0
0 1 1 0 1 1 0 0 0 1 1 0 1 1 2 3 0 0 1 1 0 0 word 1 word 2 word 3 word 4 word 5 word 6 review 1 review 2 review 3 review 4 review 5 X 0 1 1 0 0 word 6 Positive? y mardi 21 mai 13 -
Vegetation Cover Type 46. 200. 1 0 0.0 N -30.
150. 2. 149 0.1 S 87. 50 1000 10 0.1 W 45. 10 10. 1 0.4 NW 5. 2. 67. 1. 0.2 E Latitude Altitude D istance to closest river Altitude closest river Slope Slope orientation location 1 X 0 1 0 1 0 0 0 0 1 0 1 0 1 0 0 Rain forest G rassland Arid Ice y location 2 location 3 location 4 location 5 mardi 21 mai 13 -
Object Classification in Images 0 2 1 0 0 1
0 0 0 1 1 0 1 1 0 0 0 1 1 0 1 1 2 3 0 0 1 1 0 0 SIFT word 1 SIFT word 2 SIFT word 3 SIFT word 4 SIFT word 5 SIFT word 6 image 1 image 2 image 3 image 4 image 5 X 0 0 1 1 1 0 1 0 0 0 1 1 0 0 0 C at C ar Pedestrian y mardi 21 mai 13 -
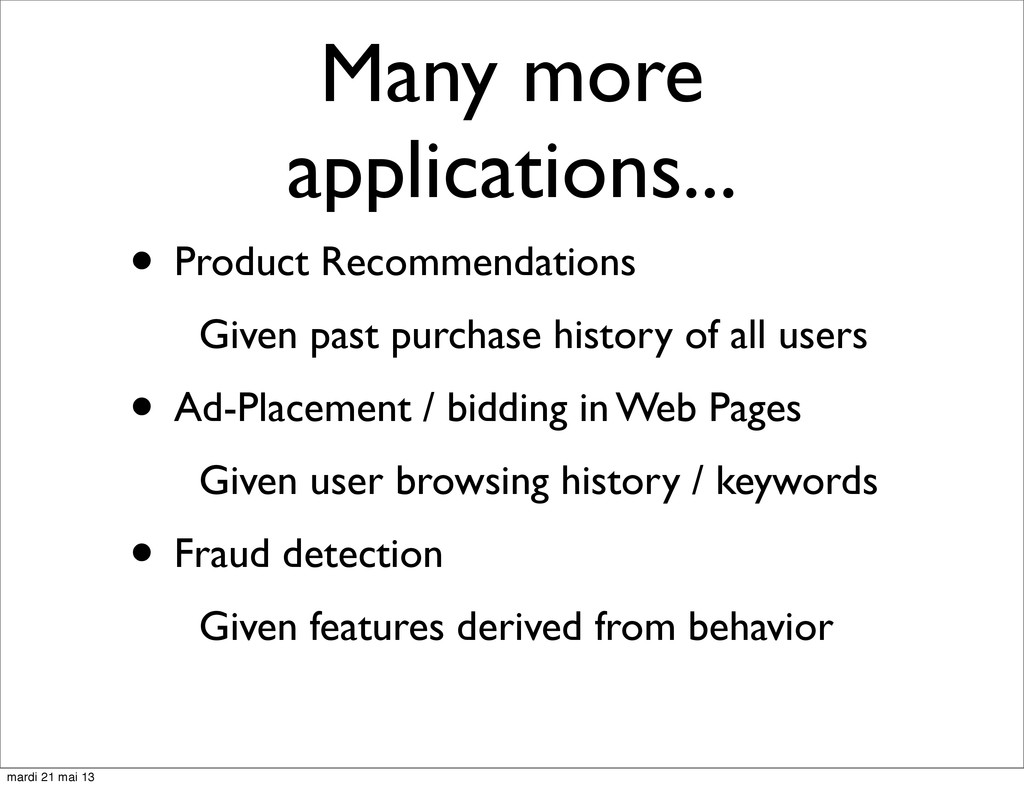
Many more applications... • Product Recommendations Given past purchase history
of all users • Ad-Placement / bidding in Web Pages Given user browsing history / keywords • Fraud detection Given features derived from behavior mardi 21 mai 13 -
Problem #1: Not So Blackbox • Feature Extraction: highly domain
specific • + Feature Normalization / Transformation • Unmet Statistical Assumptions • Linear Separability of the target classes • Correlations between features • Natural metric to for the features mardi 21 mai 13 -
Problem #2: Lack of Explainability Blackbox models can rarely explain
what they learned. Expert knowledge required to understand the model behavior and gain deeper insight on the data: this is model specific. mardi 21 mai 13 -
Possible Solutions • Problem #1: Costly Feature Engineering • Unsupervised
feature extraction with Deep Learning • Problem #2: Lack of Explainability • Probabilistic Programming with generic inference engines mardi 21 mai 13 -
What is Prob. Programming? • Model unknown causes of a
phenomenom with random variables • Write a programmatic story to derive observables from unknown variables • Plug data into observed variables • Use engine to invert the story and assign prob. distributions to unknown params. mardi 21 mai 13 -
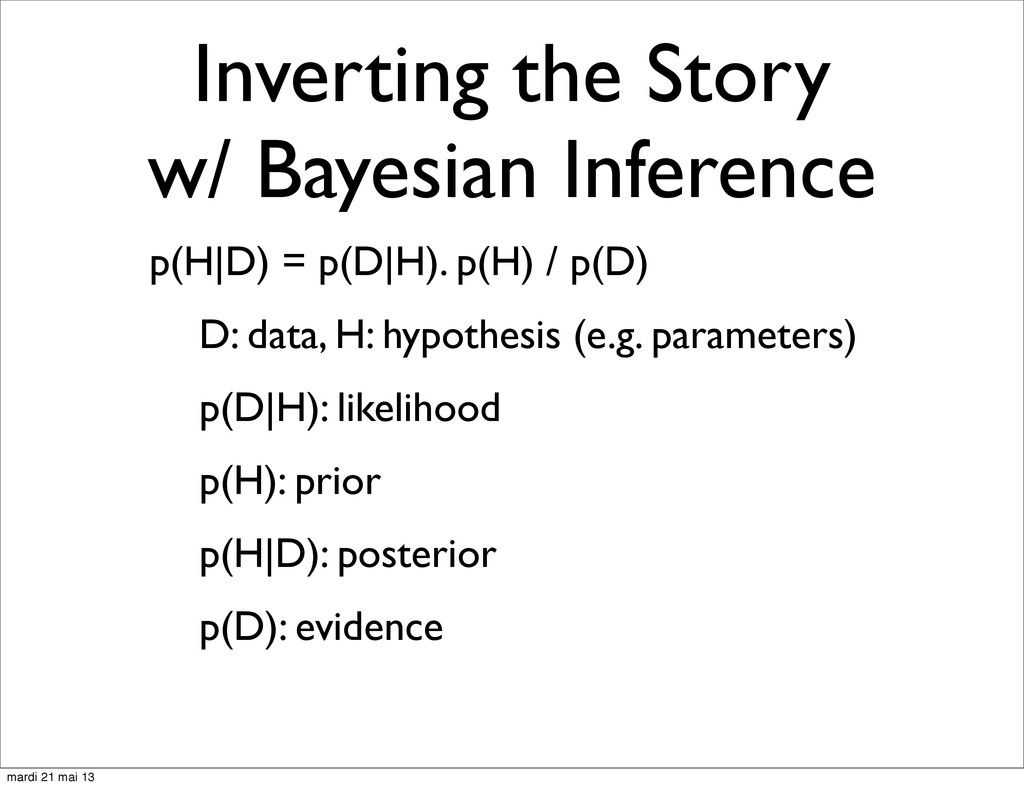
Inverting the Story w/ Bayesian Inference p(H|D) = p(D|H). p(H)
/ p(D) D: data, H: hypothesis (e.g. parameters) p(D|H): likelihood p(H): prior p(H|D): posterior p(D): evidence mardi 21 mai 13 -
Generic Inference with MCMC • Monte Carlo Markov Chains •
Start from a Random Point • Move Parameters values Randomly • Reject with new sample randomly depending on a likelihood test • Accumulate non-rejected samples and call it the trace mardi 21 mai 13 -
Alternatives to MCMC • Closed-Form Solutions • Belief Propagation •
Deterministic Approximations: ‣ Mean Field Approximation ‣ Variational Bayes and VMP mardi 21 mai 13 -
Alternatives to MCMC • Closed-Form Solutions • Belief Propagation •
Deterministic Approximations: ‣ Mean Field Approximation ‣ Variational Bayes and VMP Only is VMP seems as generic as MCMC for Prob. Programming mardi 21 mai 13 -
Implementations • Prob. Programming with MCMC • Stan: in C++
with R bindings • PyMC: in Python / NumPy / Theano • Prob. Programming with VMP • Infer.NET (C#, F#..., academic use only) • Infer.py (pythonnet bindings, very alpha) mardi 21 mai 13 -
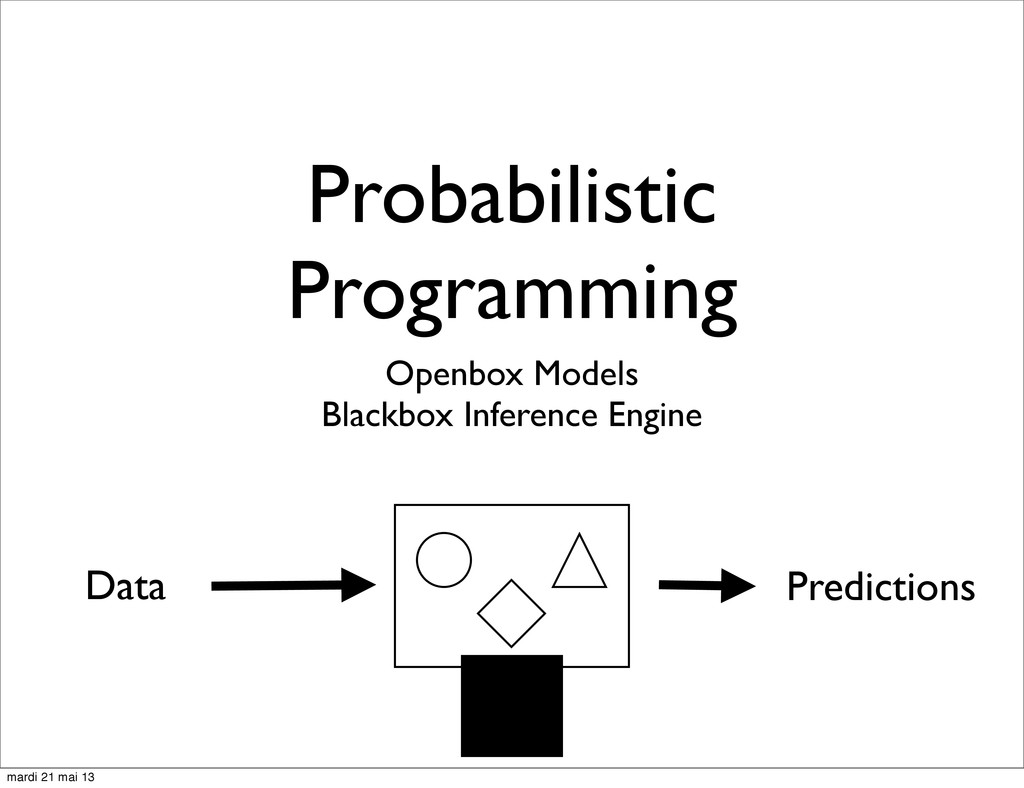
Why is Probabilistic Programming so cool? • Open Model that
tells a Generative Story • Story Telling is good for Human Understanding and Persuasion • Grounded in Quantitative Analysis and the sound theory of Bayesian Inference • Black Box inference Engine (e.g. MCMC): ‣ can be treated as Compiler Optimization mardi 21 mai 13 -
Why is Bayesian Inference so cool? • Makes it possible
explicitly inject uncertainty caused by lack of data using priors mardi 21 mai 13 -
Prob. Programming not so cool (yet)? • Scalability? Improving but
still... • Highly nonlinear dependencies lead to highy multi-modals posterior • Hard to mix between posterior modes: slow convergence • How to best build models? How to choose priors? mardi 21 mai 13 -
Old idea but recent developments • No-U-Turn Sampler (2011): breakthrough
for scalability of MCMC for some model classes (in Stan and PyMC3) • VMP (orig. paper 2005, generalized in 2011) in Infer.NET • New DARPA Program (2013-2017) to fund research on Prob. Programming. mardi 21 mai 13 -
Learning Prob. Programming • Probabilistic Programming and Bayesian Methods for
Hackers • Creative Commons Book on Github • Uses PyMC & IPython notebook • Doing Bayesian Data Analysis • Book with example in R and BUGS mardi 21 mai 13 -
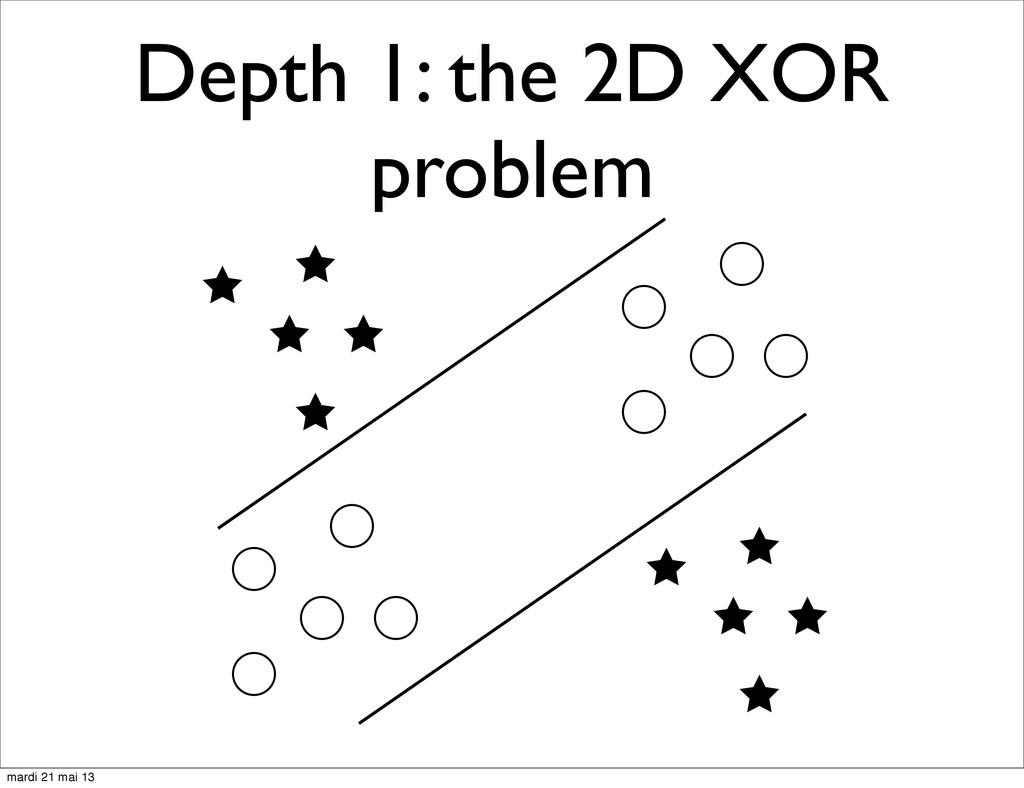
What is depth in ML? • Architectural depth, not decision
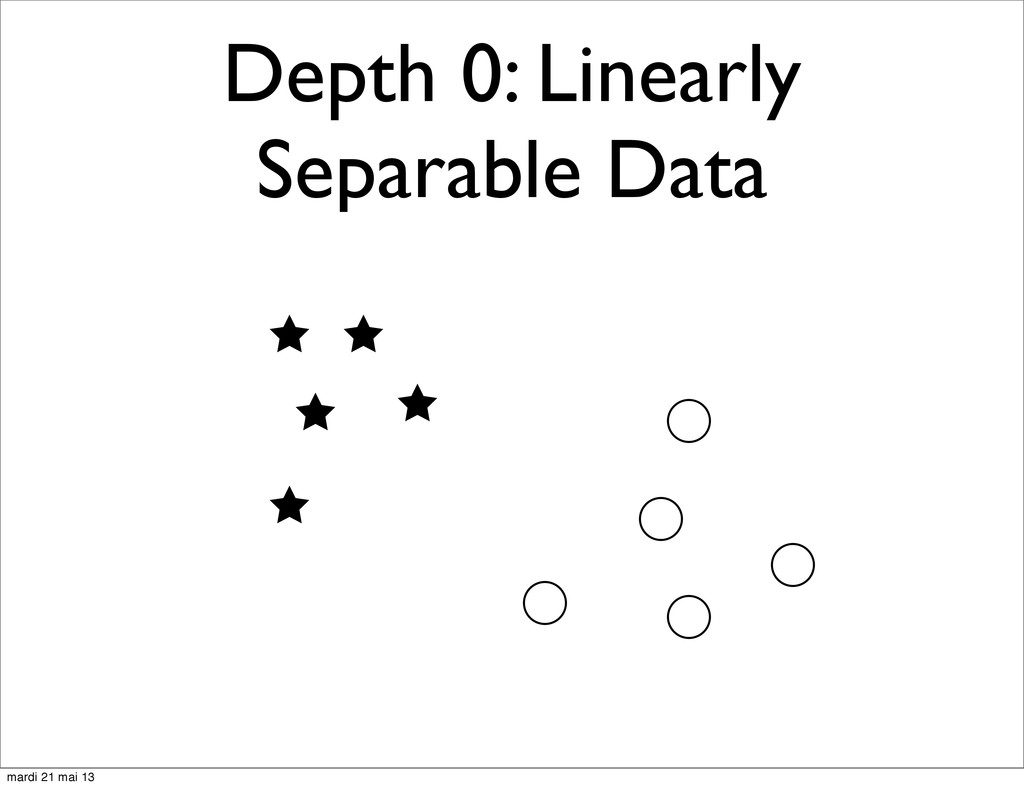
trees depth • Number of non-linearities between the unobserved “True”, “Real-World” factors of variations (causes) and the observed data (e.g. pixels in a robot’s camera) • But what is non-linearly separable data? mardi 21 mai 13 -
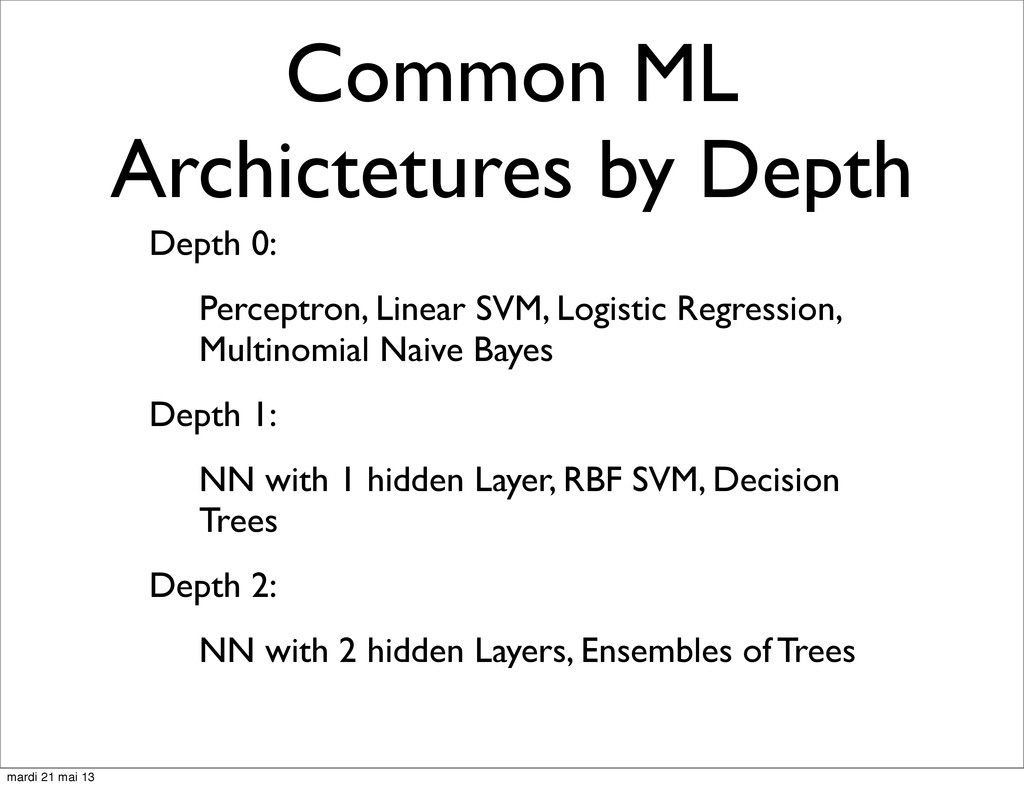
Common ML Archictetures by Depth Depth 0: Perceptron, Linear SVM,
Logistic Regression, Multinomial Naive Bayes Depth 1: NN with 1 hidden Layer, RBF SVM, Decision Trees Depth 2: NN with 2 hidden Layers, Ensembles of Trees mardi 21 mai 13 -
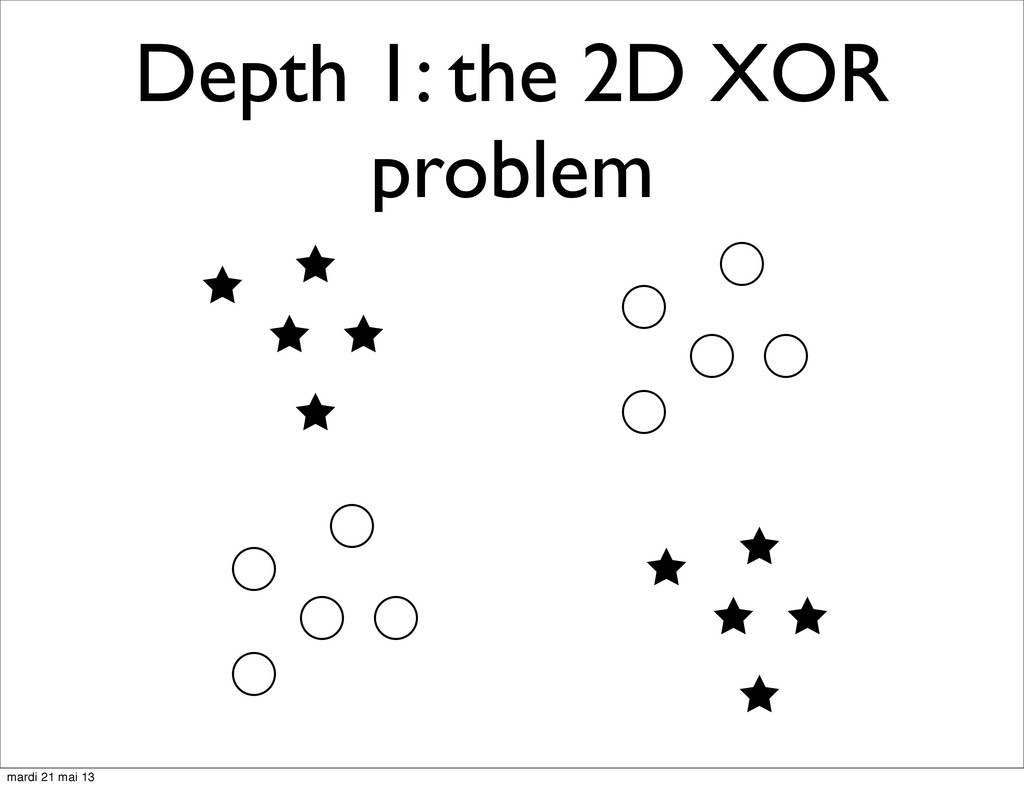
Generalizing the XOR problem to N dim • The Parity
Function: given N boolean variables, return 1 if number of positive values is even, 0 otherwise • Depth 1 models can learn the parity function but: • Need ~ 2^N hidden nodes / SVs • Require 1 example per local variation mardi 21 mai 13 -
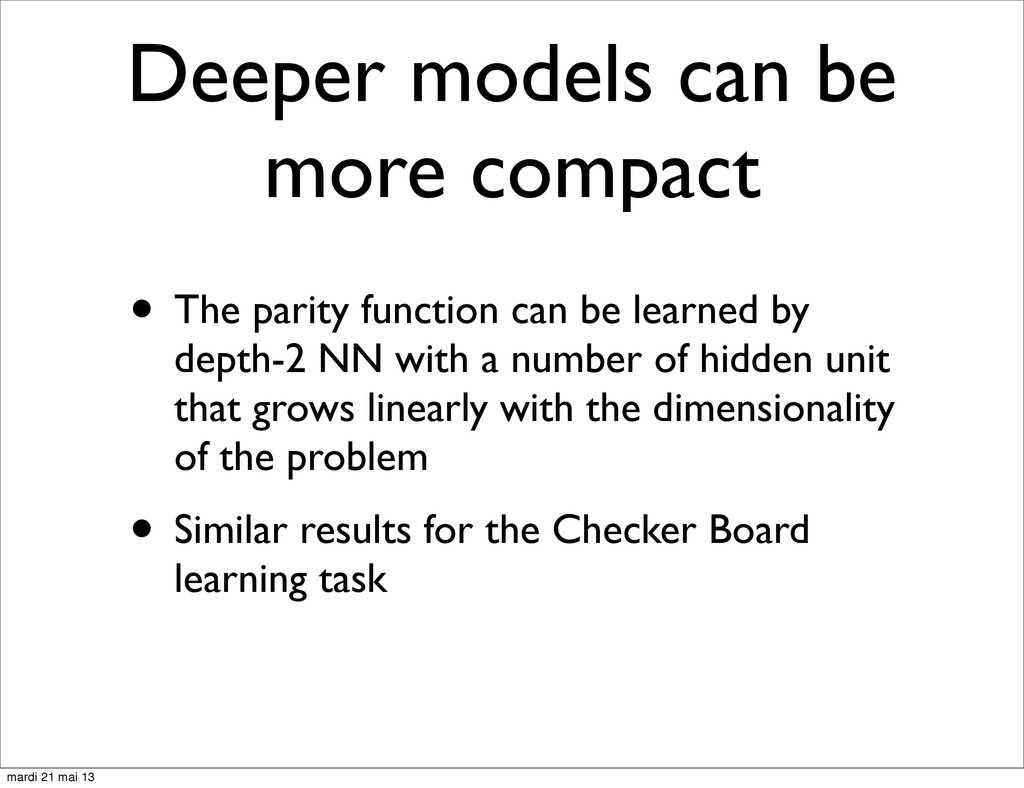
Deeper models can be more compact • The parity function
can be learned by depth-2 NN with a number of hidden unit that grows linearly with the dimensionality of the problem • Similar results for the Checker Board learning task mardi 21 mai 13 -
Common ML Archictetures by Depth Depth 0: Perceptron == NN
with 0 hidden layer Depth 1: NN with 1 hidden layer Depth 2: NN with 2 hidden layer mardi 21 mai 13 -
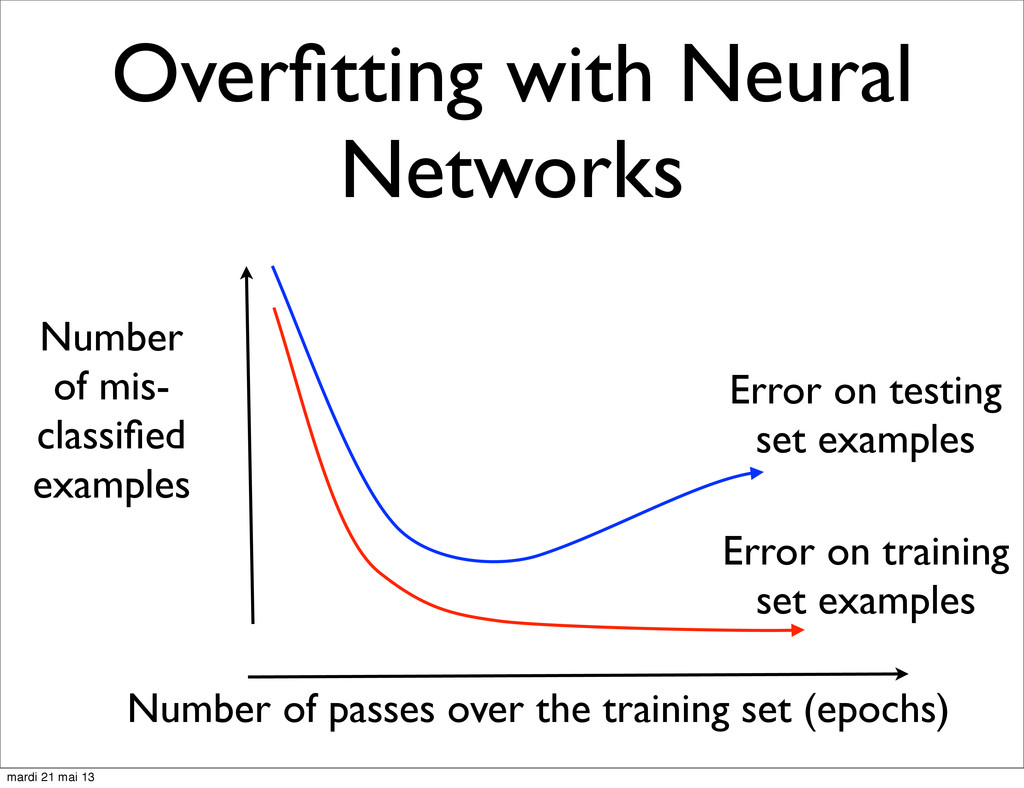
A bit of history • Neural Nets progressed in the
80s with early successes (e.g. Neural Nets for OCR) • 2 Major Problems: • Backprop does not work with more than 1 or 2 hidden layers • Overfitting: forces early stopping mardi 21 mai 13 -
Overfitting with Neural Networks Number of passes over the training
set (epochs) Number of mis- classified examples Error on testing set examples Error on training set examples mardi 21 mai 13 -
So in the 90s and early 00s • ML community
moved away from NN • SVM with kernel: less hyperparameters • Random Forests / Boosted Trees often beat all other models when enough labeled data and CPU time mardi 21 mai 13 -
But in 2006... • Breakthrough by Geof. Hinton at the
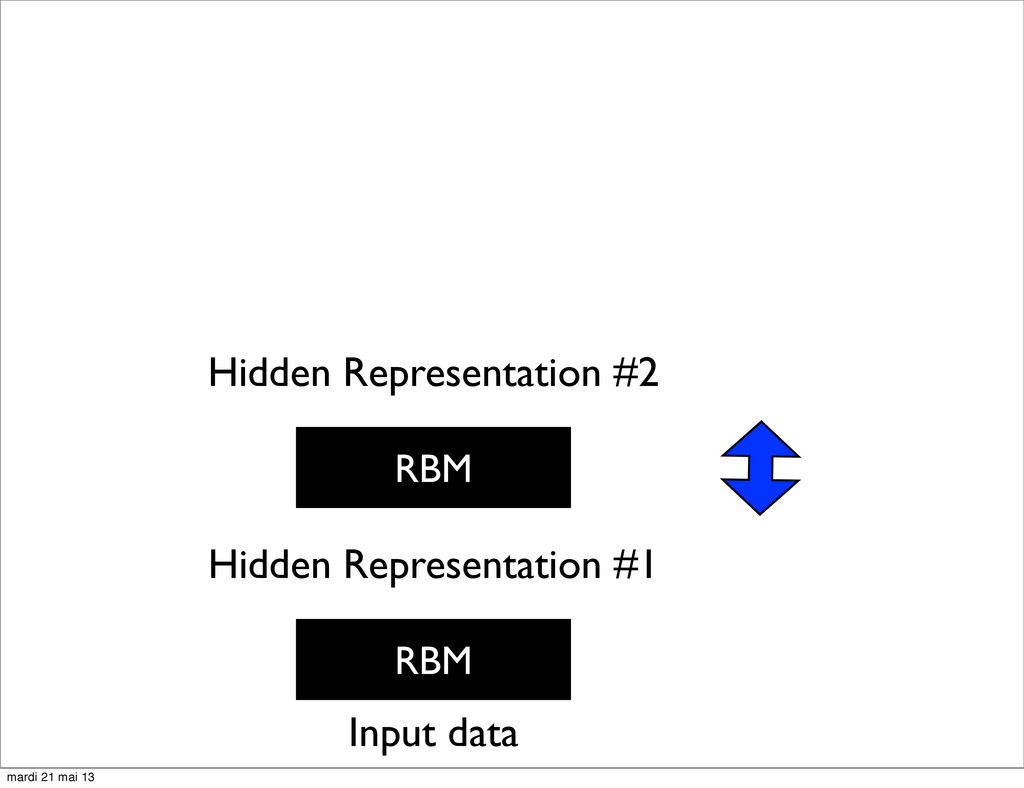
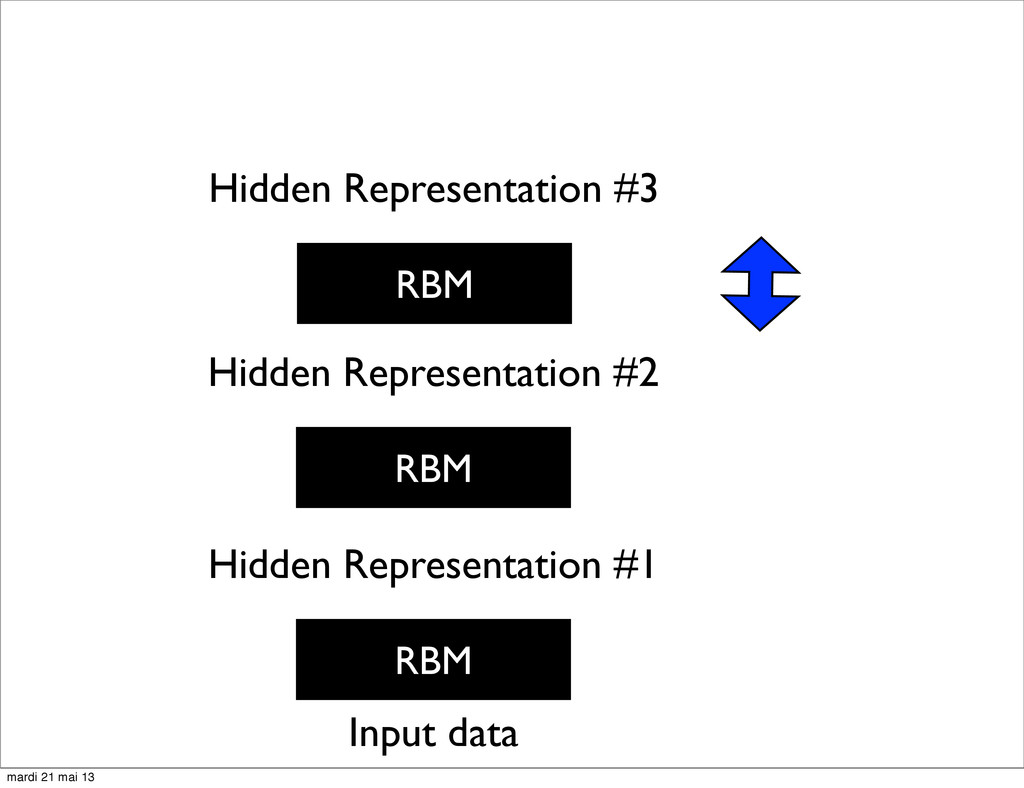
U. of Toronto • Unsupervised Pre-training of Deep Architectures (Deep Belief Networks) • Can be unfolded into a traditional NN for fine tuning mardi 21 mai 13 -
RBM Input data Hidden Representation #1 RBM Hidden Representation #2
RBM Hidden Representation #3 mardi 21 mai 13 -
RBM Input data Hidden Representation #1 RBM Hidden Representation #2
RBM Hidden Representation #3 Labels clf mardi 21 mai 13 -
Soon replicated and extended... • Bengio et al. in U.
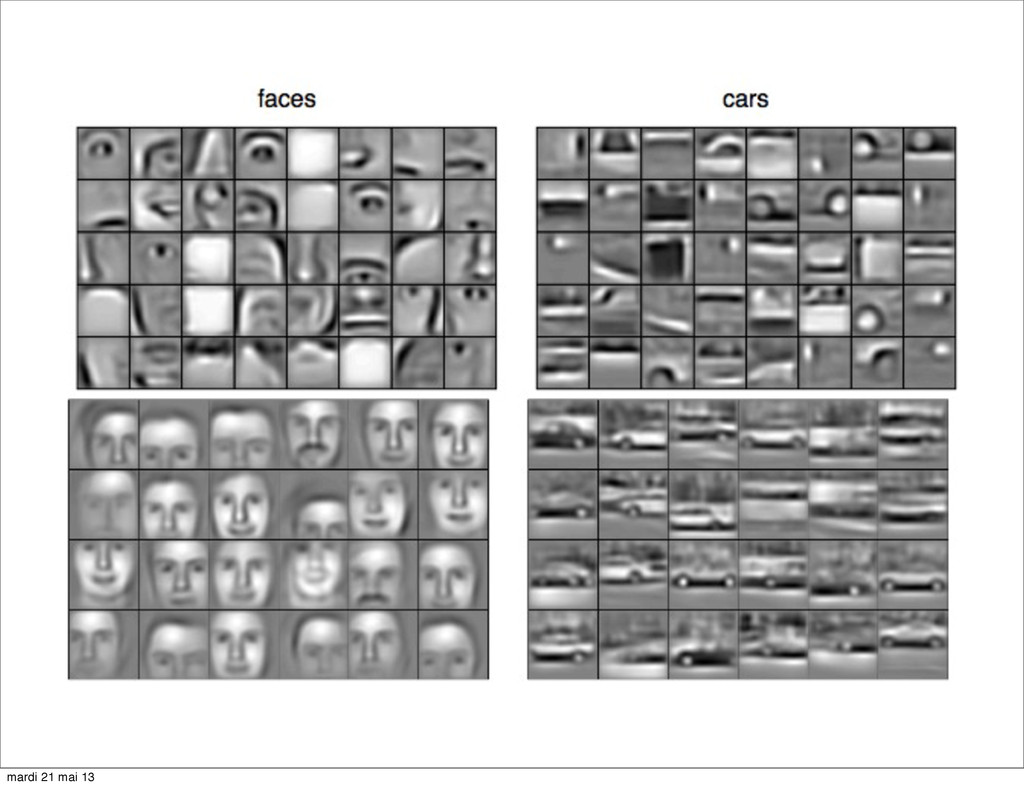
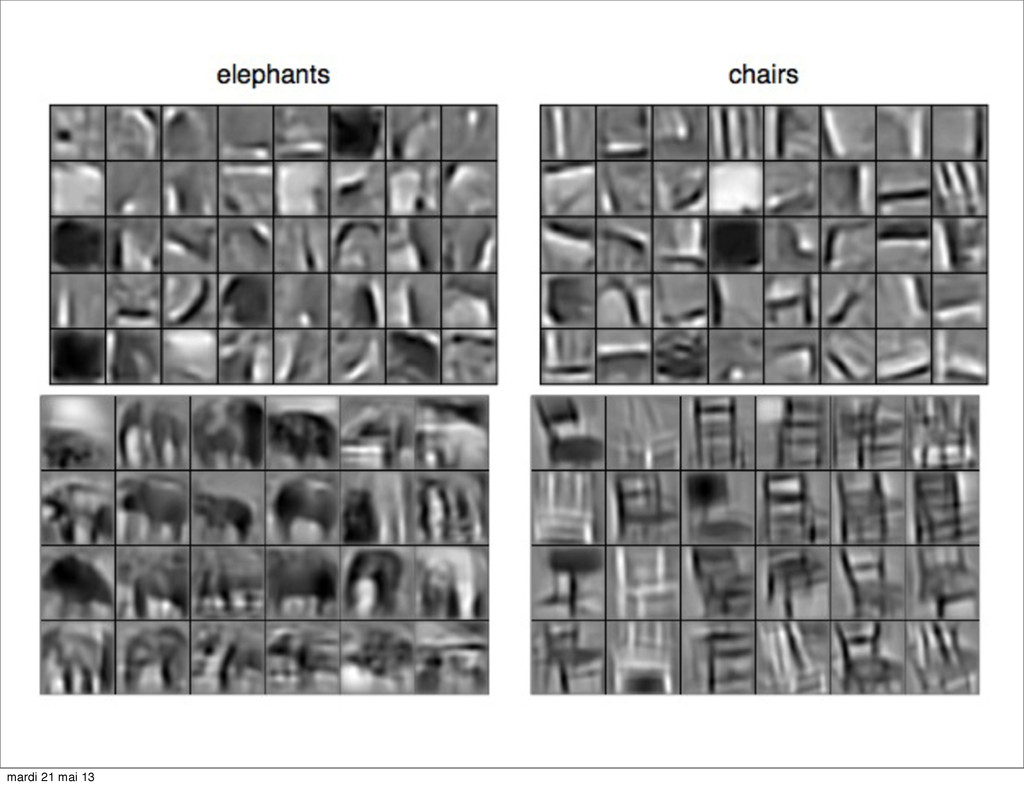
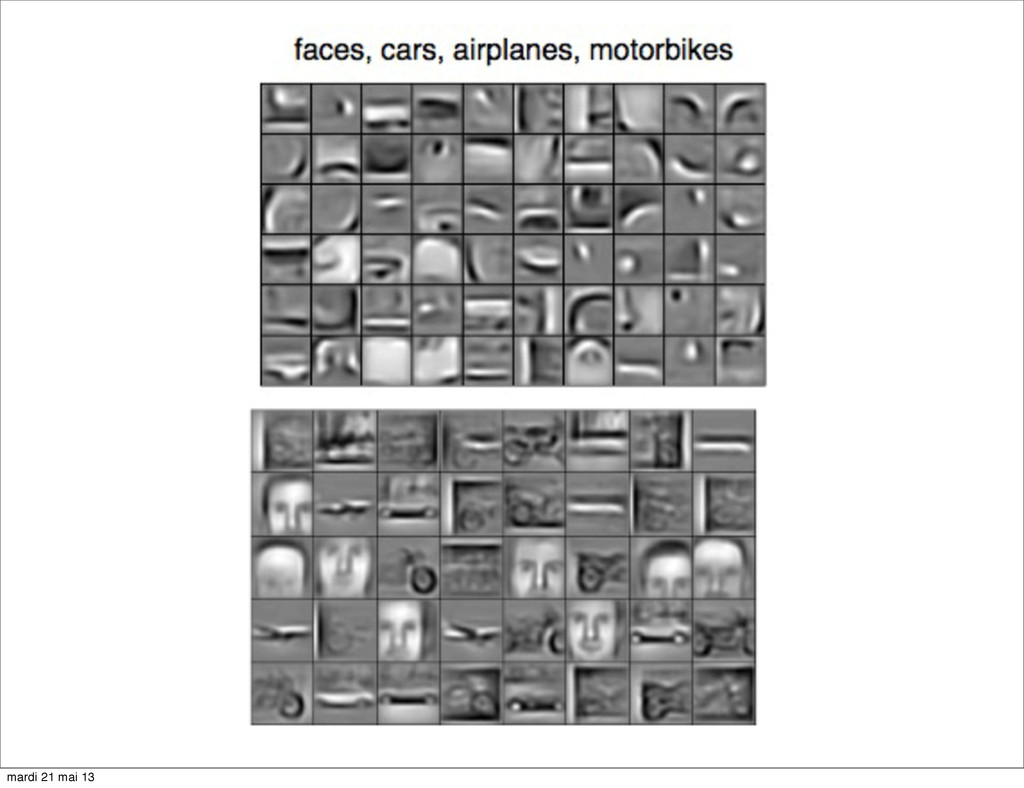
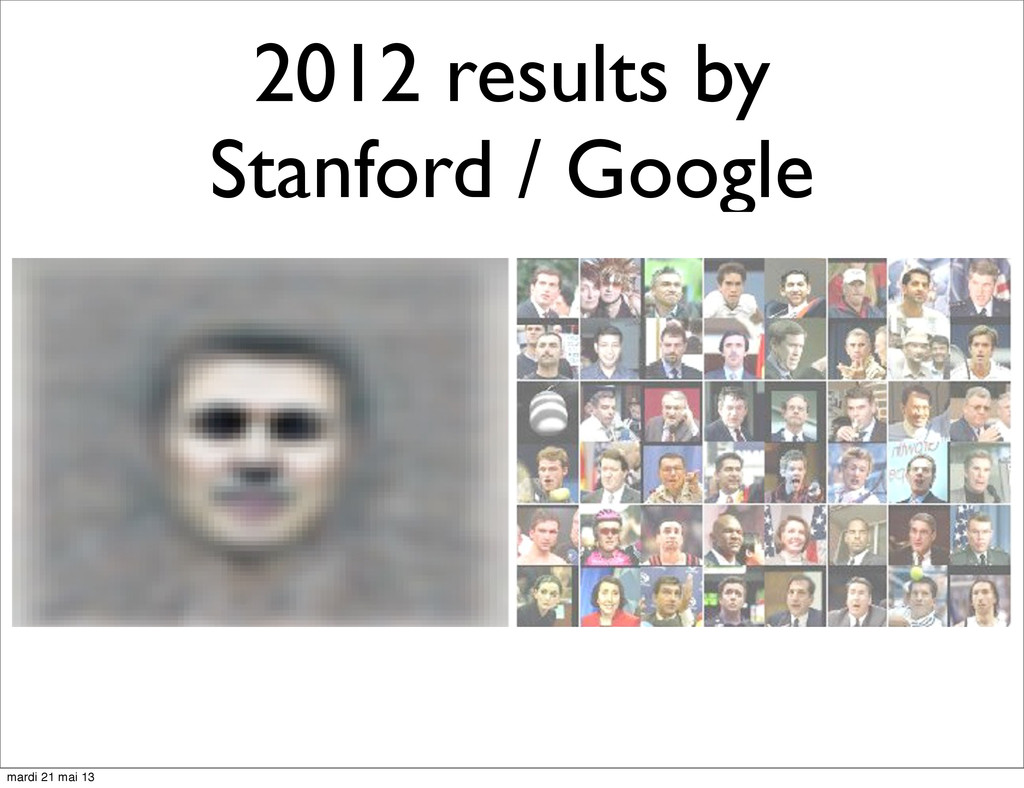
of Montreal • Ng et al. in Stanford • Replaced RBM with various other models such as Autoencoders in a denoising setting or with a sparsity penalty • Started to reach state of the art in speech recognition, image recognition... mardi 21 mai 13 -
Example: Convolutional DBN Convolutional Deep Belief Networks for Scalable Unsupervised
Learning of Hierarchical Representations Honglak Lee Roger Grosse Rajesh Ranganath Andrew Y. Ng mardi 21 mai 13 -
More recently • Second breakthrough in 2012 by Hinton again:
Dropout networks • New way to train deep feed forward neural networks with much less overfitting and without unsupervised pretraining • Allows NN to beat state of the art approaches on ImageNet (object recognition in images) mardi 21 mai 13 -
Even more recently • Maxout networks: • New non linearity
optimized for Dropout • Easier / faster to train • Implementation in Python / Theano • http://deeplearning.net/software/ pylearn2/ mardi 21 mai 13 -
Why is Deep Learning so cool? • Can automatically extract
high level, invariant, discriminative features from raw data (pixels, sound frequencies...) • Starting to reach or beat State of the Art in some Speech Understanding and Computer Vision tasks • Stacked Abstractions and Composability might be a path to build a real AI mardi 21 mai 13 -
Why is Deep Learning not so cool (yet)? • Requires
lots of training data • Typically requires running a GPU for days to fit a model + many hyperparameters • Under-fitting issues for large models • Not yet that useful with high level abstract input (e.g. text data): shallow models can already do very well for text classification mardi 21 mai 13 -
DL: very hot research area • Big Industry Players (Google,
Microsoft...) investing in DL for speech understanding and computer vision • Many top ML researchers are starting to look at DL & some on the theory side mardi 21 mai 13