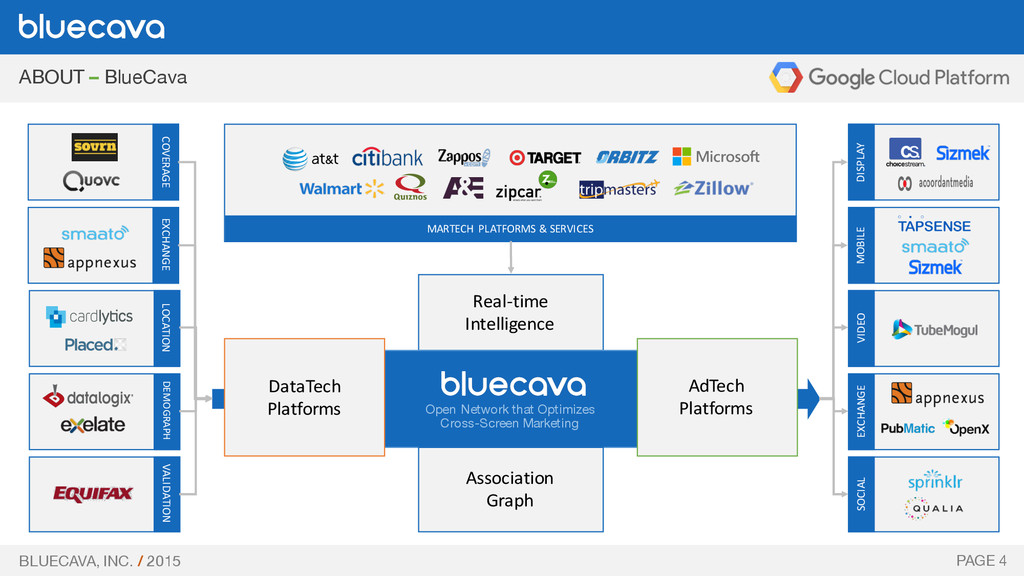
My Presentation as Speaker in Google Cloud Platform Big Data Summit in Google Venice Office, talking about how we utilize Google Big Query and other Big Data stack in BlueCava
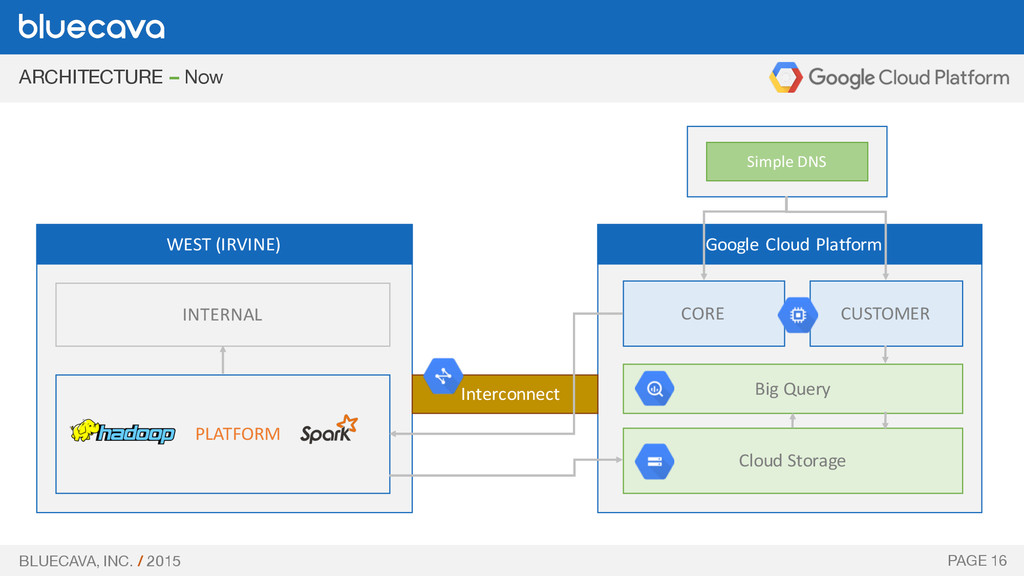
@ BlueCava • Work with Google Big Data Team in past 1.5 years • Move from 100% Private Cloud to Hybrid Environment • Deep Integration with Big Query Email [email protected] Twitter @qorbani
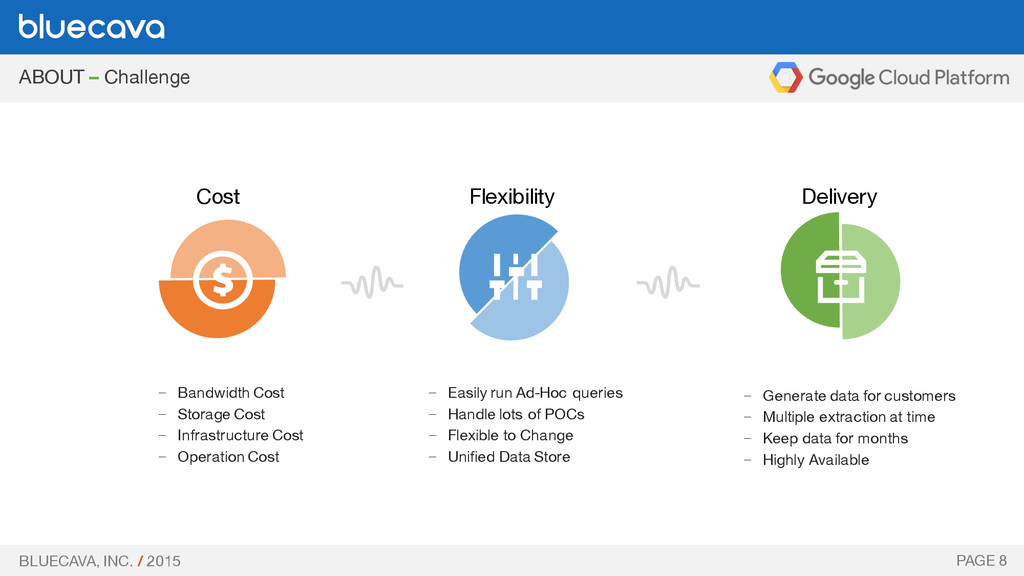
Generate data for customers − Multiple extraction at time − Keep data for months − Highly Available − Easily run Ad-Hoc queries − Handle lots of POCs − Flexible to Change − Unified Data Store − Bandwidth Cost − Storage Cost − Infrastructure Cost − Operation Cost Cost Flexibility Delivery
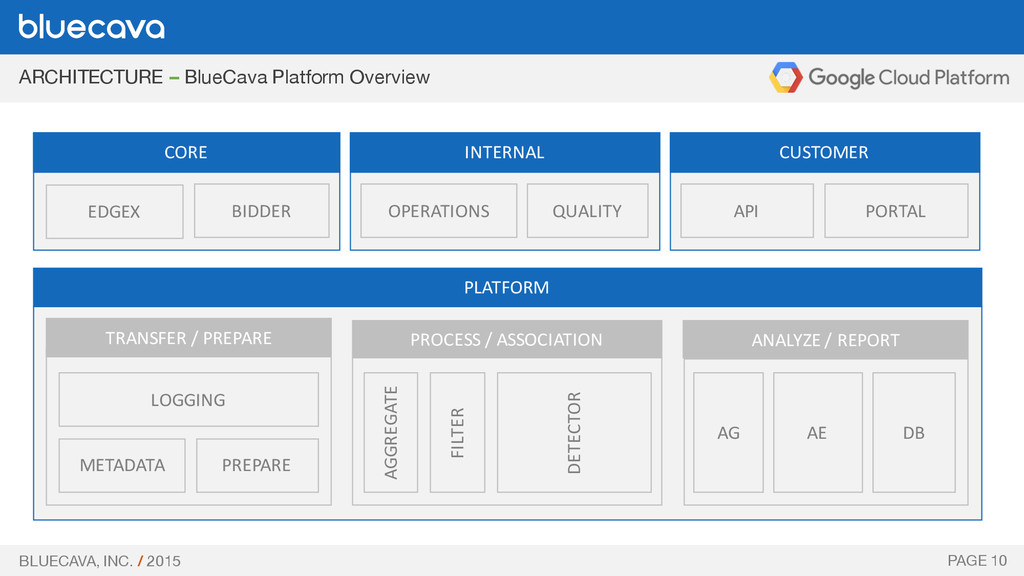
10 CORE INTERNAL CUSTOMER PLATFORM EDGEX BIDDER OPERATIONS QUALITY API PORTAL METADATA PREPARE LOGGING AGGREGATE FILTER DETECTOR TRANSFER / PREPARE PROCESS / ASSOCIATION ANALYZE / REPORT AG AE DB
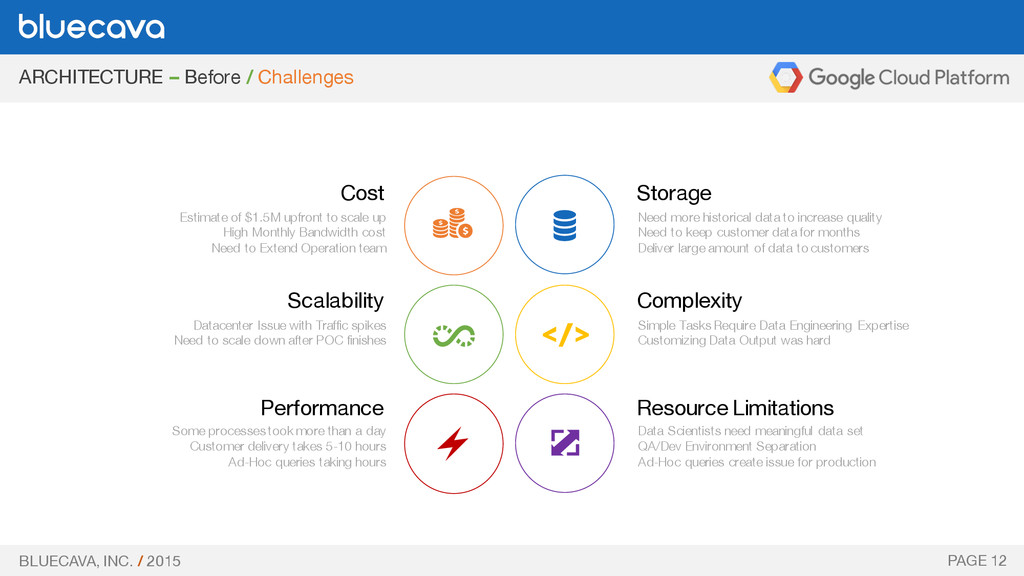
12 Cost Estimate of $1.5M upfront to scale up High Monthly Bandwidth cost Need to Extend Operation team Scalability Performance Storage Complexity Resource Limitations Datacenter Issue with Traffic spikes Need to scale down after POC finishes Some processes took more than a day Customer delivery takes 5-10 hours Ad-Hoc queries taking hours Need more historical data to increase quality Need to keep customer data for months Deliver large amount of data to customers Simple Tasks Require Data Engineering Expertise Customizing Data Output was hard Data Scientists need meaningful data set QA/Dev Environment Separation Ad-Hoc queries create issue for production
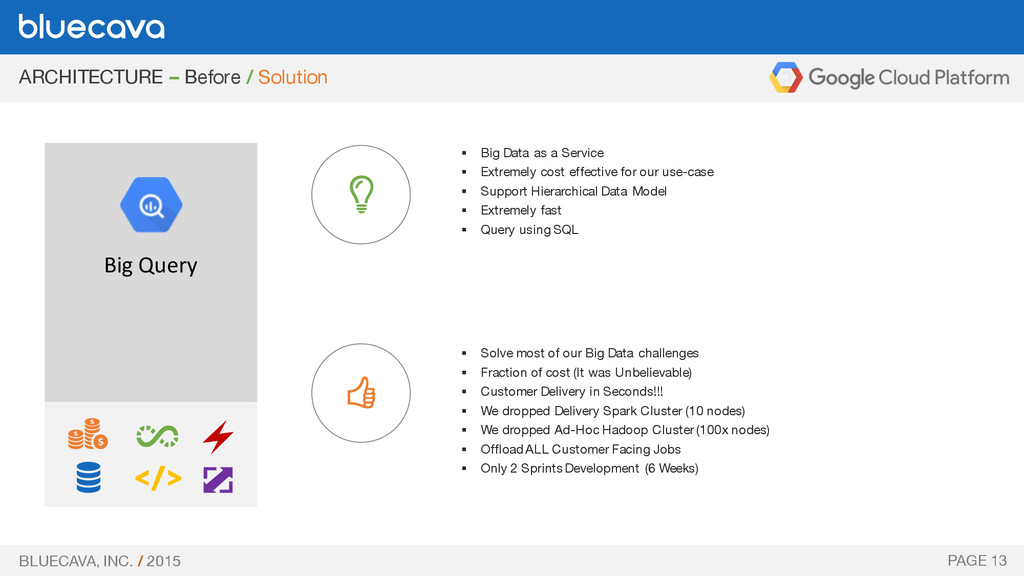
13 Big Query § Big Data as a Service § Extremely cost effective for our use-case § Support Hierarchical Data Model § Extremely fast § Query using SQL § Solve most of our Big Data challenges § Fraction of cost (It was Unbelievable) § Customer Delivery in Seconds!!! § We dropped Delivery Spark Cluster (10 nodes) § We dropped Ad-Hoc Hadoop Cluster (100x nodes) § Offload ALL Customer Facing Jobs § Only 2 Sprints Development (6 Weeks)
14 Cloud Storage § Nice integration with Big Query § No file size limit like S3 § HDFS Integration using Hadoop Connector § Seamless Cost Saving: DRA and Nearline § Solved most of our Storage challenges § Simplified our file delivery § Extremely competitive pricing § No need for Backup J
15 Compute Engine § Great Sustained Pricing § No need for long-term contract § Simple CLI for Automation § BDUtil Library for Hadoop § Elastic Environment which saved us on Cost § 100+ nodes Hadoop under 6 minutes § Use as On-Demand Resource as needed § Stop purchasing more hardware!
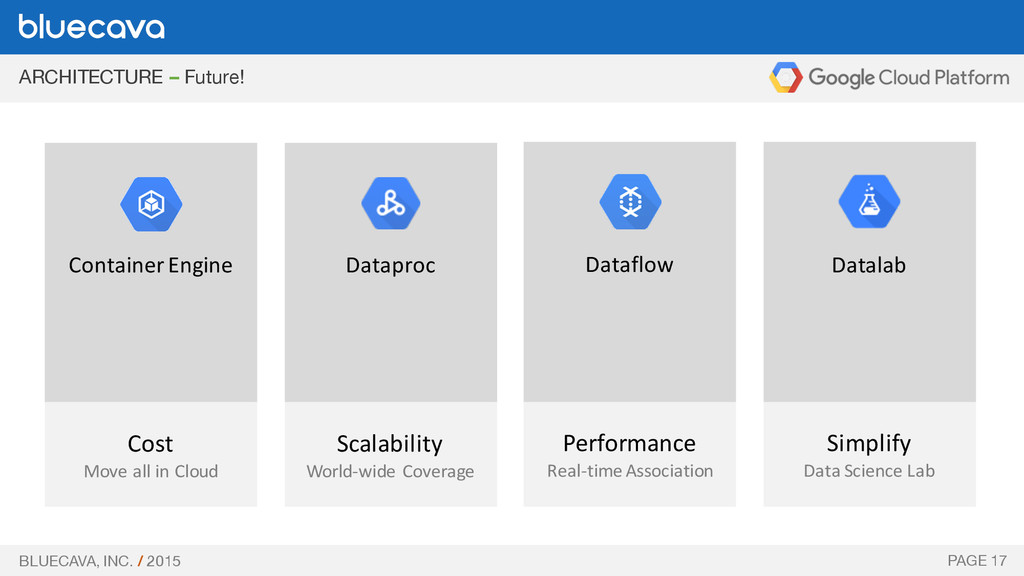
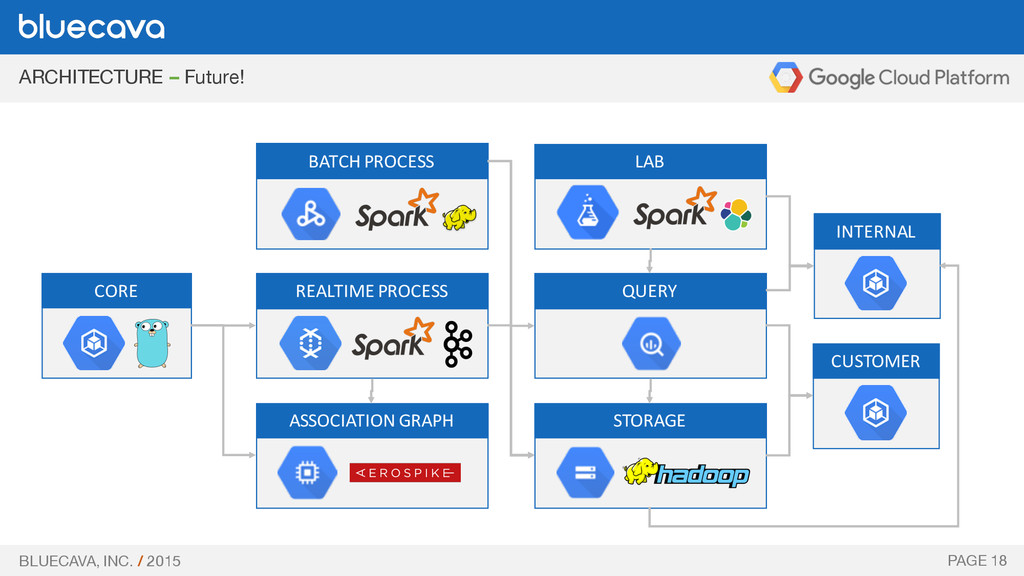
Move all in Cloud Scalability World-wide Coverage Performance Real-time Association Simplify Data Science Lab Container Engine Dataproc Dataflow Datalab


 kaminashi
 y0hgi
 yahonda
 tokuty
 yamanoku
 pfn
 terapyon
 prog893
 kenichiodo
 ivry_presentationmaterials
 persolserverworks
 akhino
 greggifford
 soysaucechin
 trishagee
 mkilby
 rakko
 rkendrick25
 chriscoyier
 reverentgeek
 jonoalderson
 rasmusluckow
 csswizardry