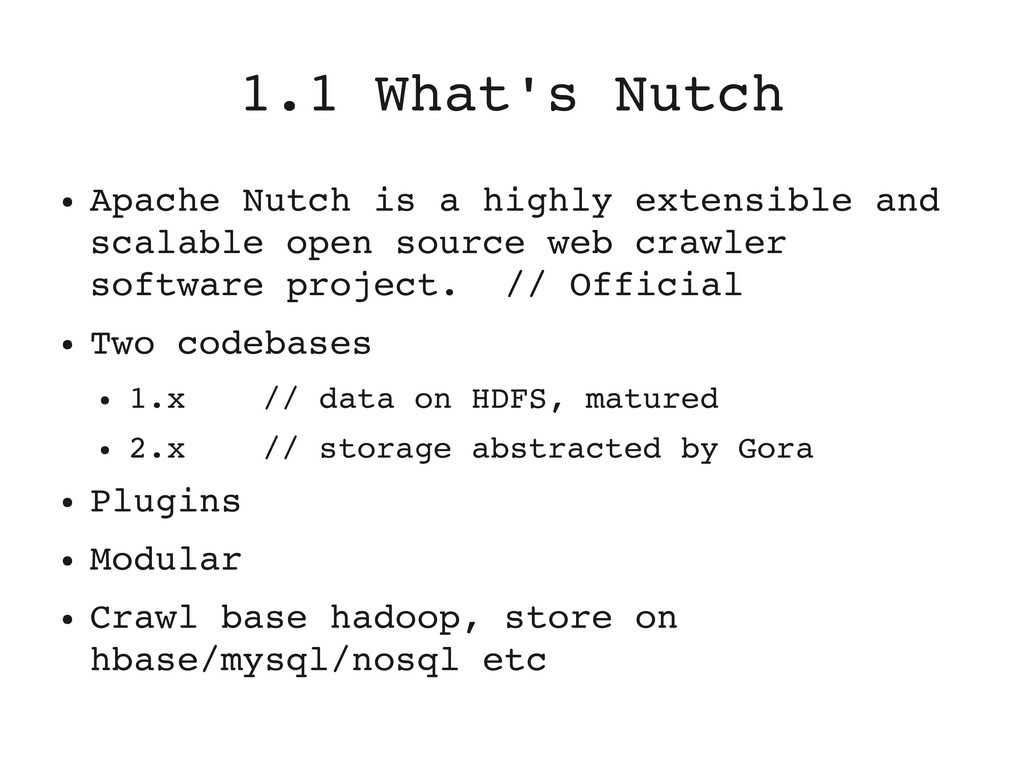
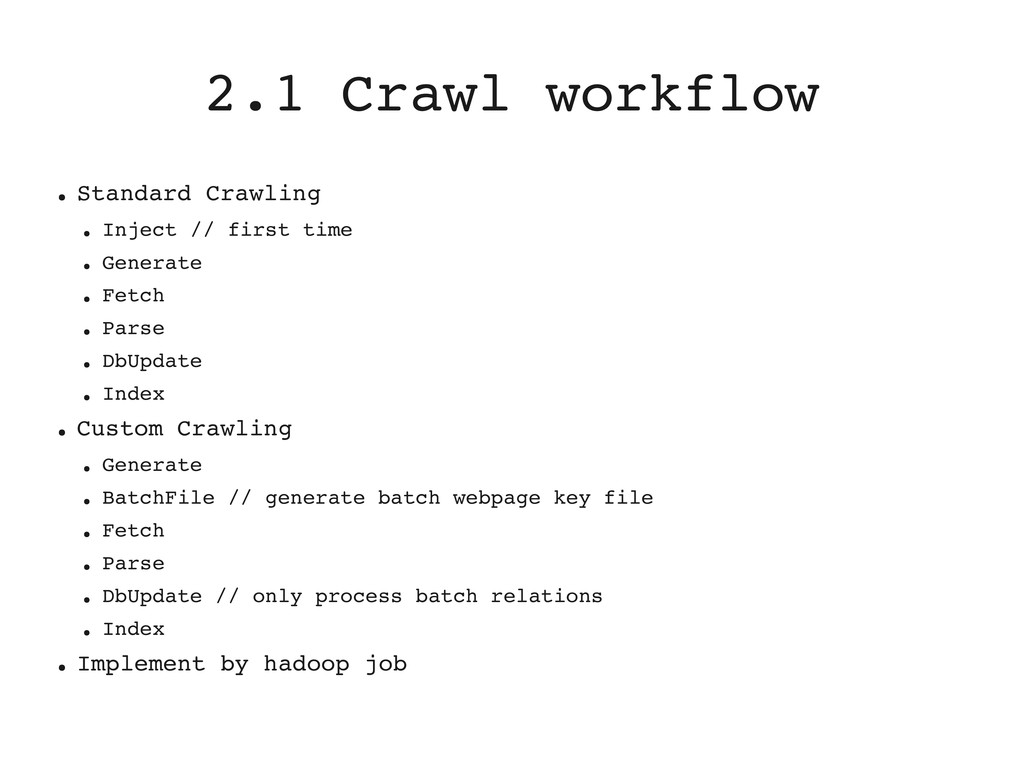
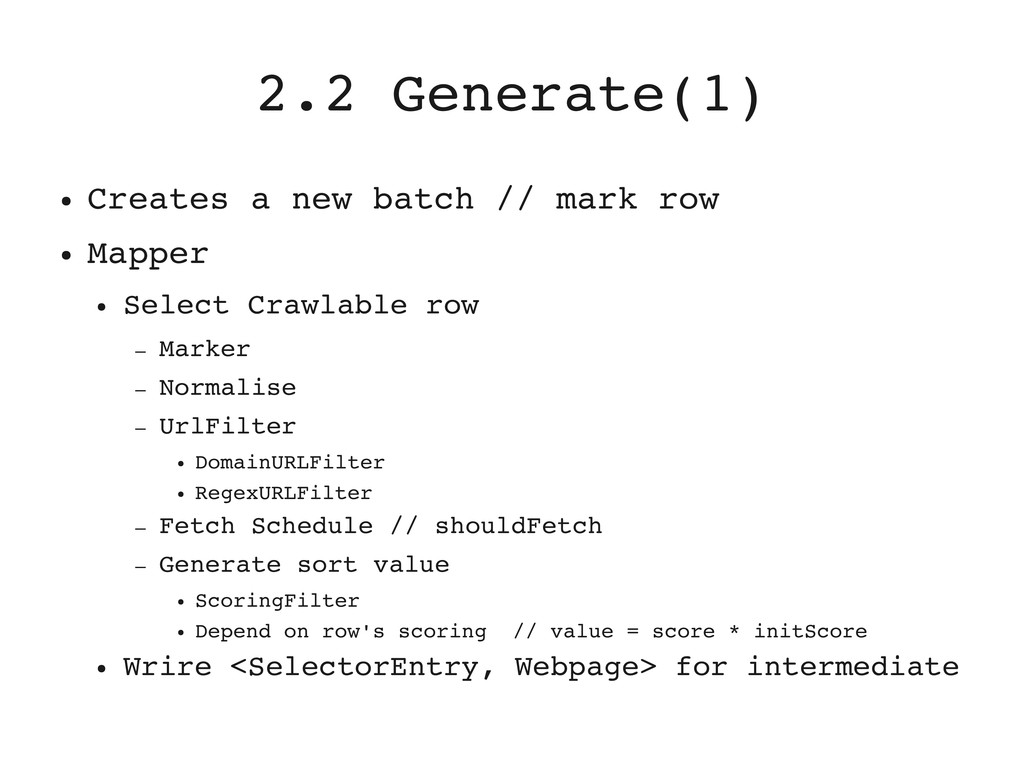
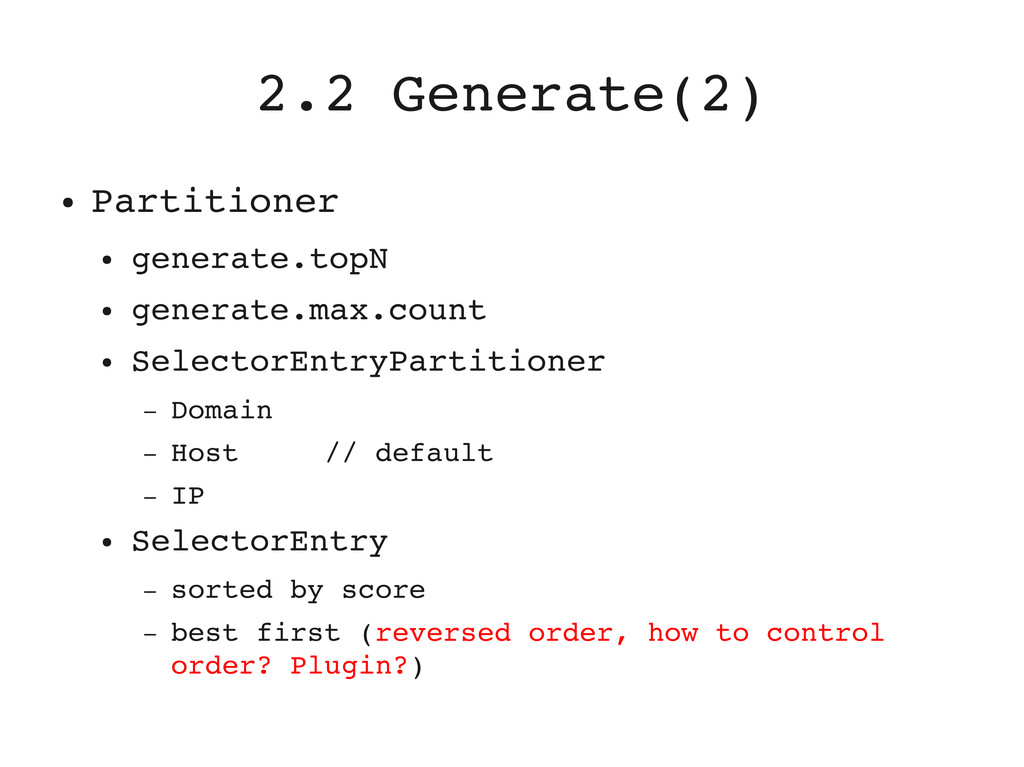
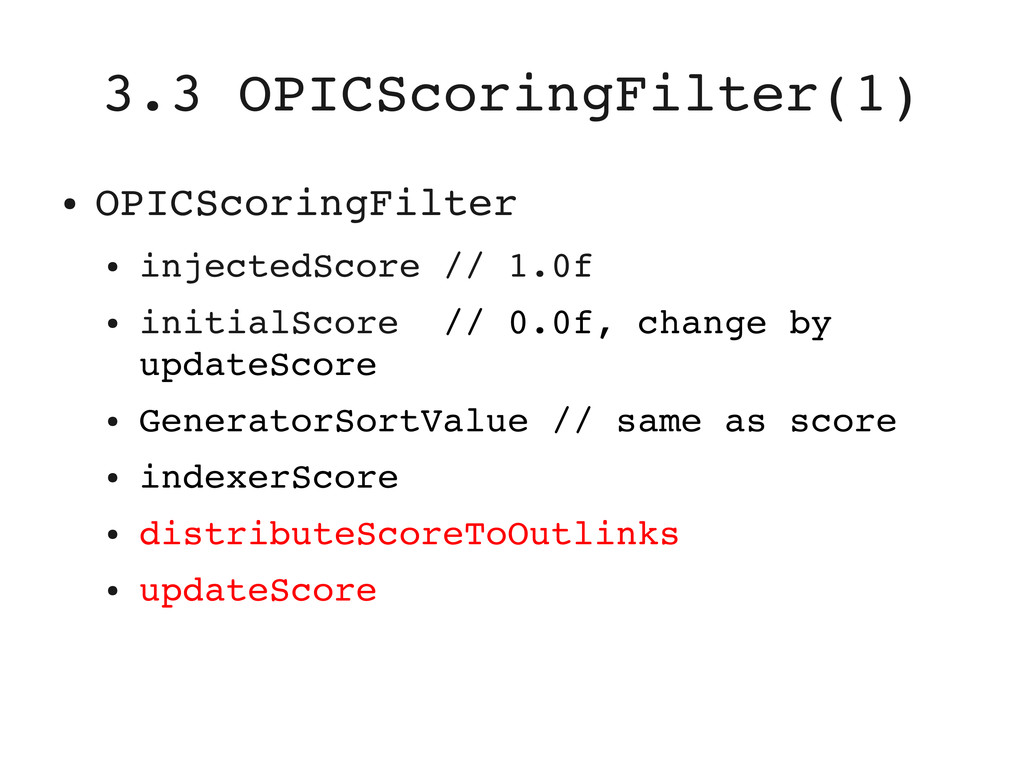
and scalable open source web crawler software project. // Official • Two codebases • 1.x // data on HDFS, matured • 2.x // storage abstracted by Gora • Plugins • Modular • Crawl base hadoop, store on hbase/mysql/nosql etc
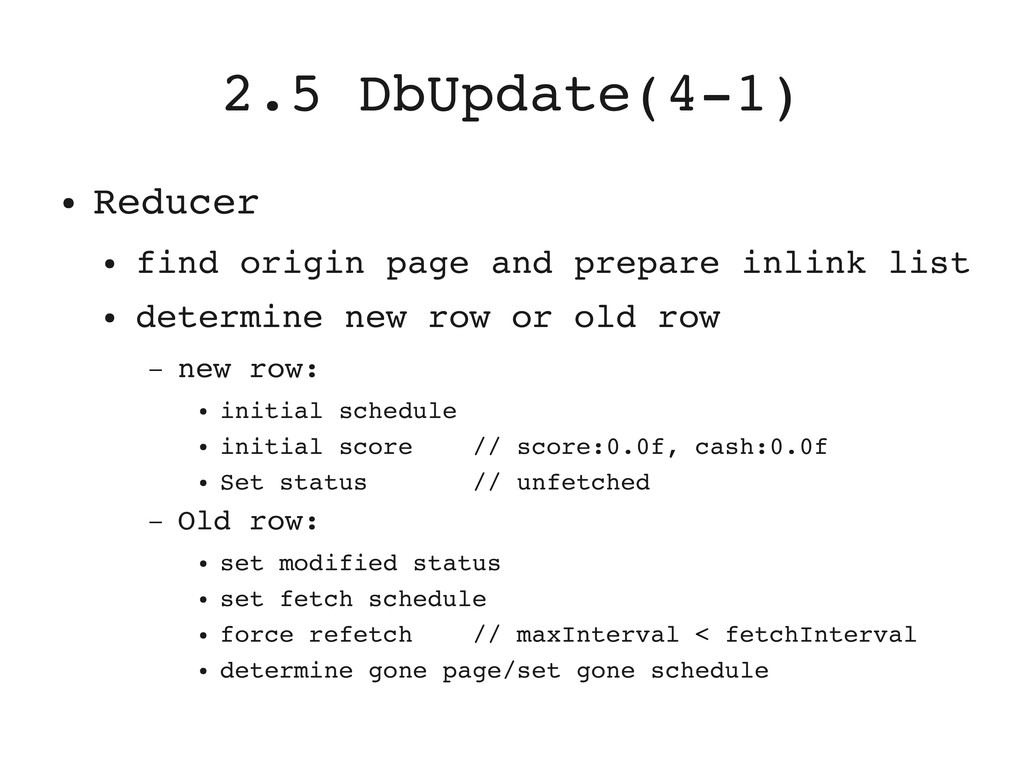
inlink list • determine new row or old row – new row: • initial schedule • initial score // score:0.0f, cash:0.0f • Set status // unfetched – Old row: • set modified status • set fetch schedule • force refetch // maxInterval < fetchInterval • determine gone page/set gone schedule


 hschwentner
 dske104
 yutobara
 ryu1013
 gonta
 nabondance
 ___akari11
 econanringo
 eed3si9n
 o0h
 lynnswap
 keathley
 ryanjones
 swwweet
 helenjbeal
 kimpetersen
 codingconduct
 katiecoart
 lauravandoore
 nikkihalliwell
 andyhume
 retrage
 portentint