Share
Embed
Data sharing and reproducible research
A presentation given at Janelia farm during the workshop on BioImage Informatics.
Satrajit Ghosh
September 21, 2011
Transcript
60 slides
-
data sharing and reproducible research barriers and solu-ons Satrajit Ghosh
[email protected] Massachusetts Institute of Technology -
problems solutions future barriers to data and code sharing current
approaches in neuroimaging can we have reproducible research? -
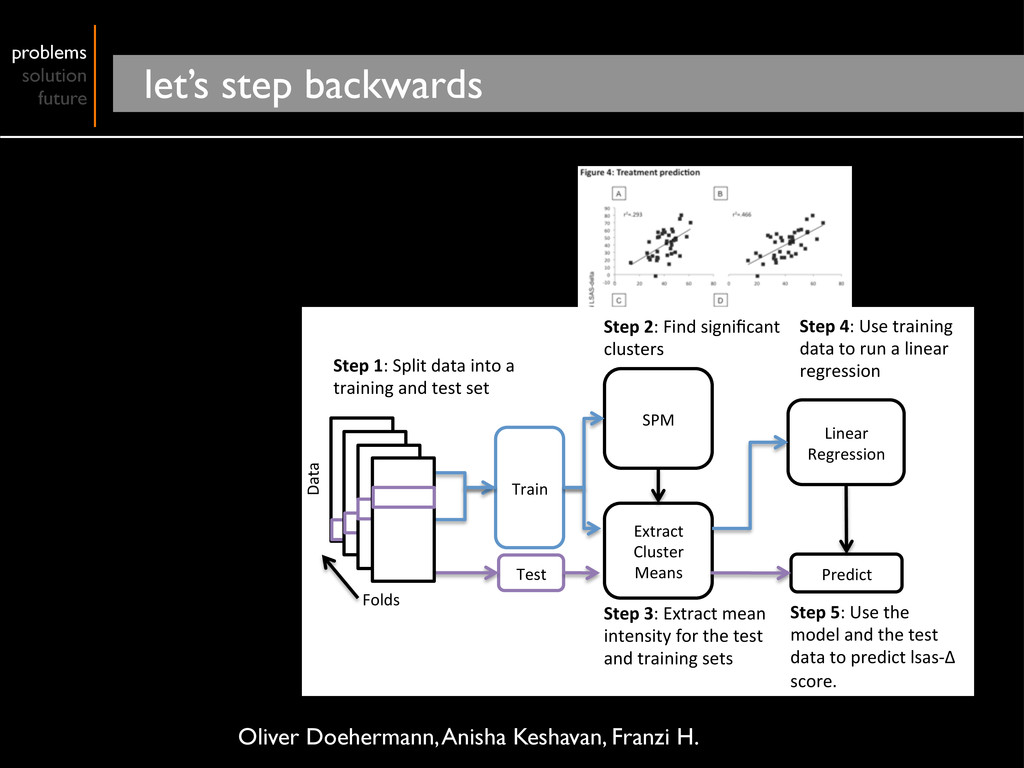
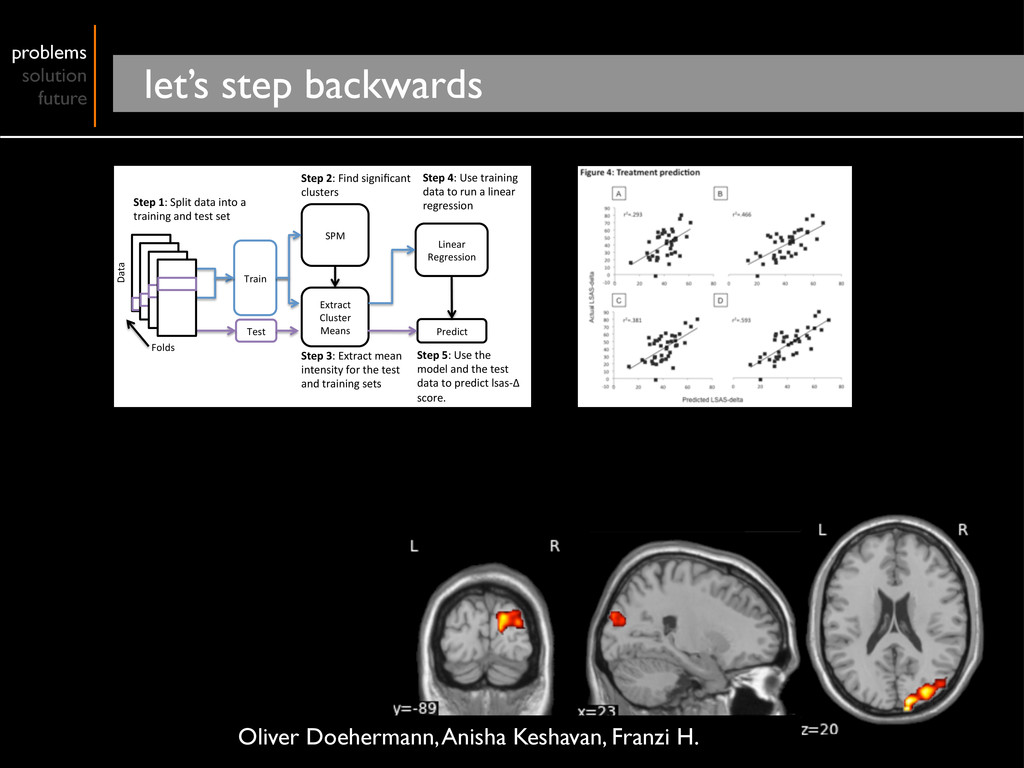
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Oliver Doehermann, Anisha Keshavan, Franzi H. -
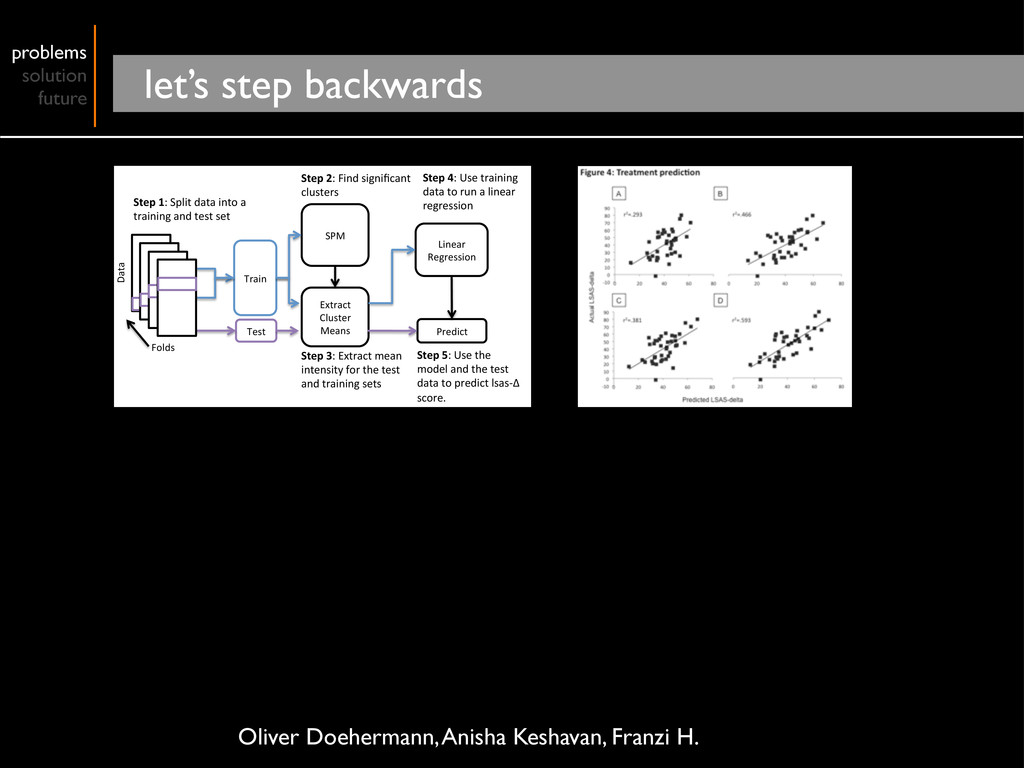
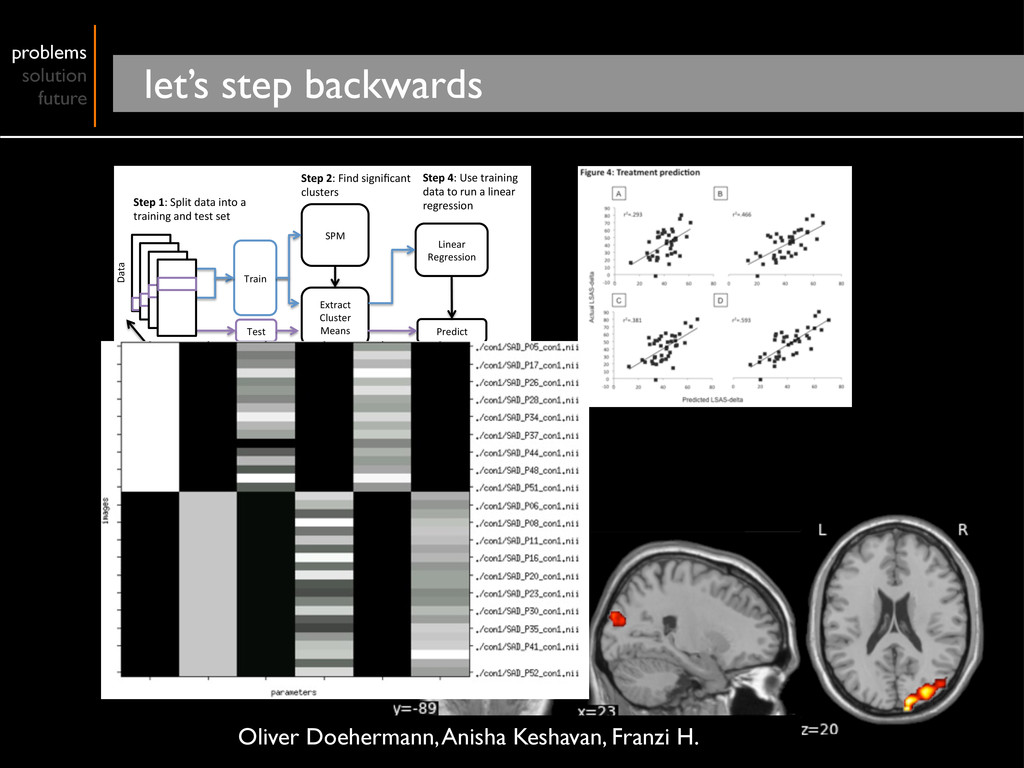
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Oliver Doehermann, Anisha Keshavan, Franzi H. -
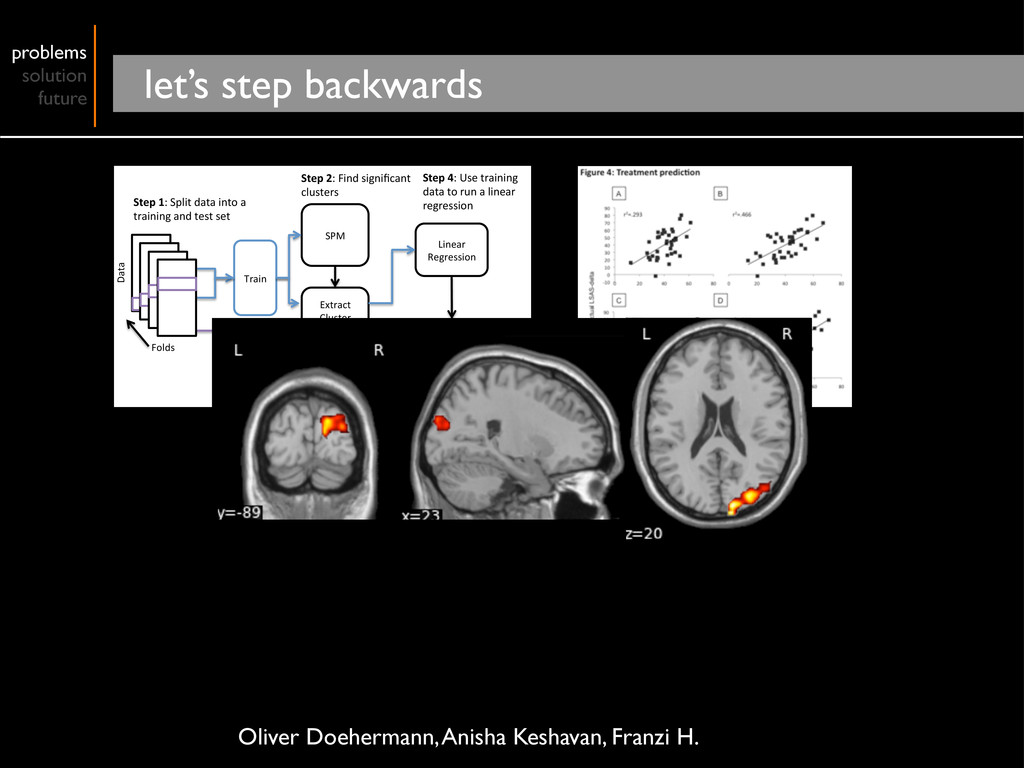
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Oliver Doehermann, Anisha Keshavan, Franzi H. -
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Oliver Doehermann, Anisha Keshavan, Franzi H. -
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Oliver Doehermann, Anisha Keshavan, Franzi H. -
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Oliver Doehermann, Anisha Keshavan, Franzi H. -
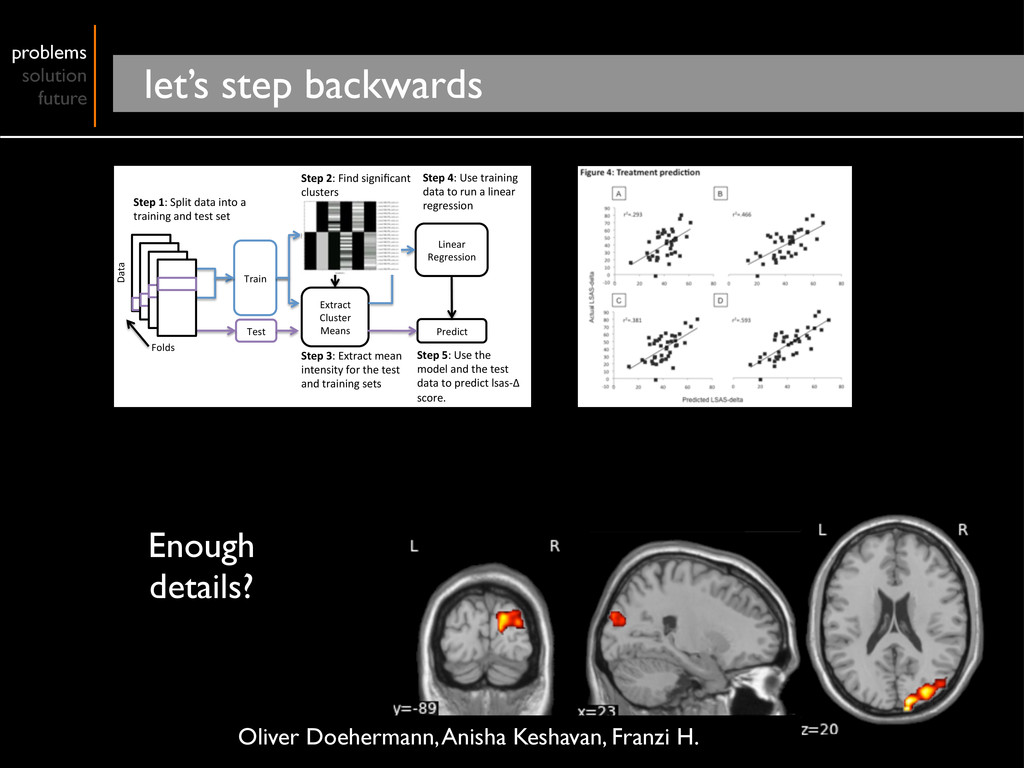
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Enough details? Oliver Doehermann, Anisha Keshavan, Franzi H. -
problems solution future let’s step backwards Train Test SPM Extract
Cluster Means Linear Regression Predict Step 1: Split data into a training and test set Step 2: Find significant clusters Step 3: Extract mean intensity for the test and training sets Step 4: Use training data to run a linear regression Step 5: Use the model and the test data to predict lsas‐Δ score. Folds Data Enough details? No Oliver Doehermann, Anisha Keshavan, Franzi H. -
problems solution future let’s step backwards What else? Where did
the input data come from? What procedure was used to collect clinical data? What were the process parameters? -
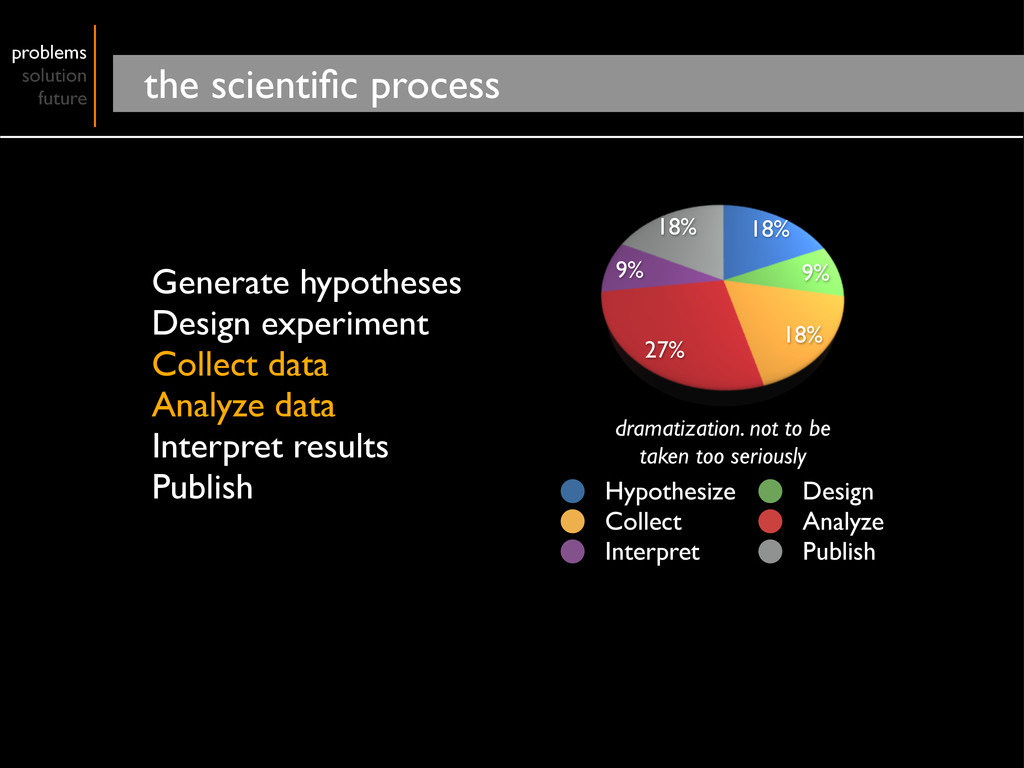
problems solution future the scientific process Generate hypotheses Design experiment
Collect data Analyze data Interpret results Publish -
problems solution future the scientific process Generate hypotheses Design experiment
Collect data Analyze data Interpret results Publish 18% 9% 18% 27% 9% 18% Hypothesize Design Collect Analyze Interpret Publish dramatization. not to be taken too seriously -
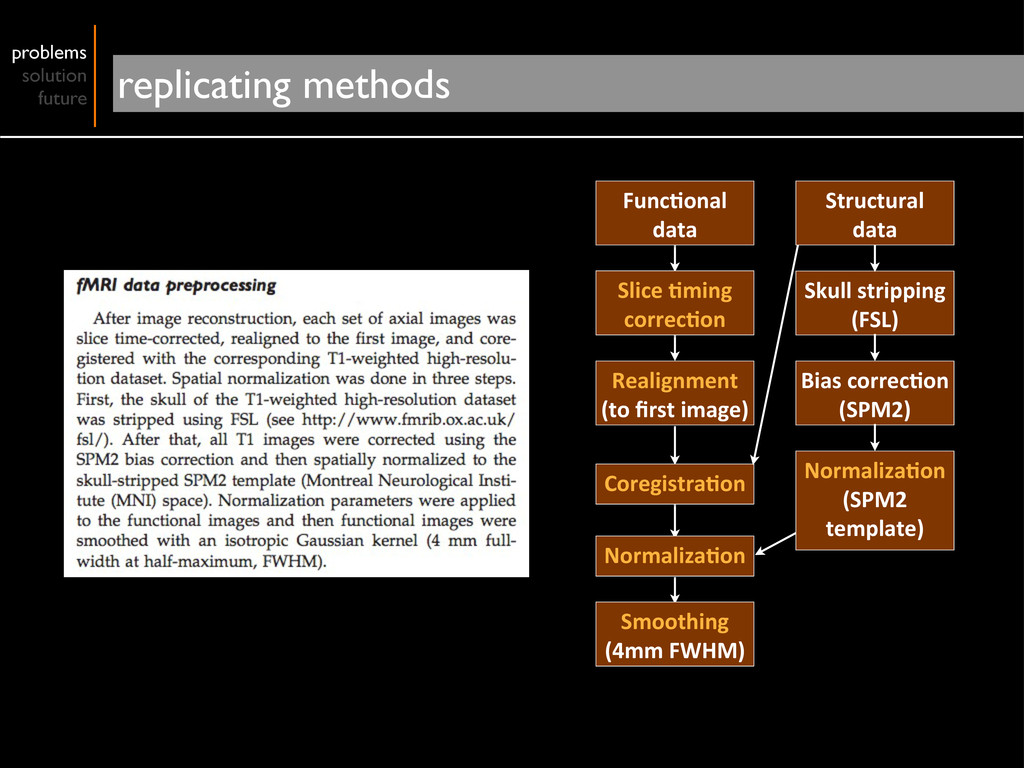
Slice 6ming correc6on Realignment (to first image) Func6onal
data Structural data Skull stripping (FSL) Bias correc6on (SPM2) Normaliza6on (SPM2 template) Smoothing (4mm FWHM) Normaliza6on Coregistra6on problems solution future replicating methods -
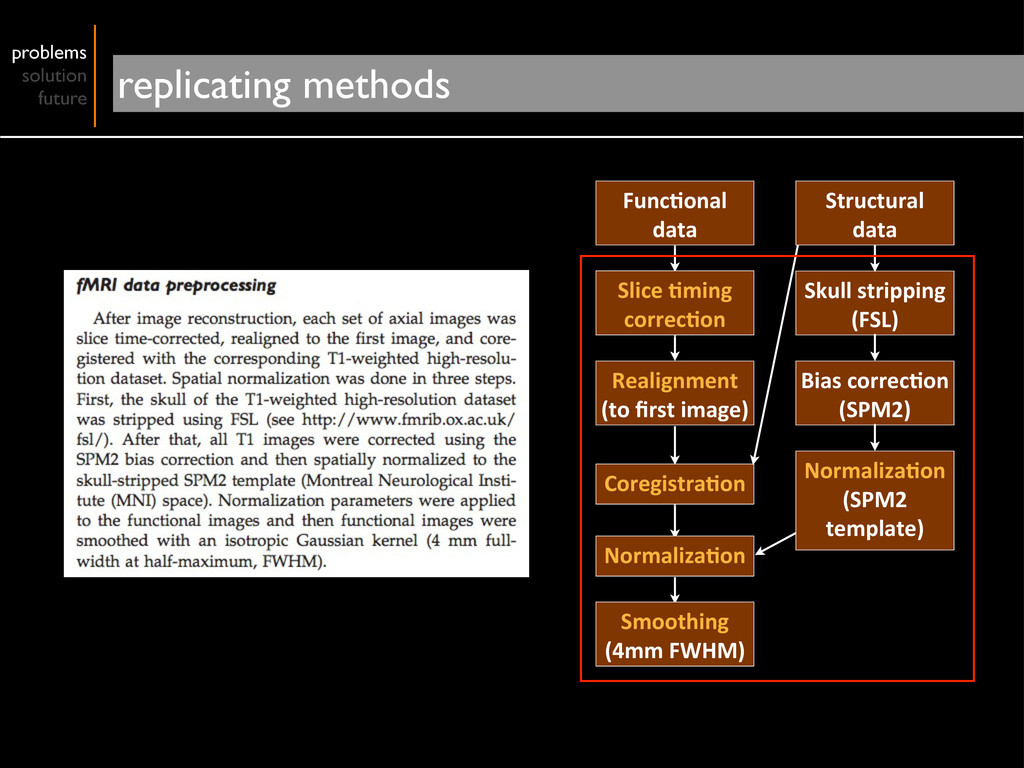
Slice 6ming correc6on Realignment (to first image) Func6onal
data Structural data Skull stripping (FSL) Bias correc6on (SPM2) Normaliza6on (SPM2 template) Smoothing (4mm FWHM) Normaliza6on Coregistra6on problems solution future replicating methods -
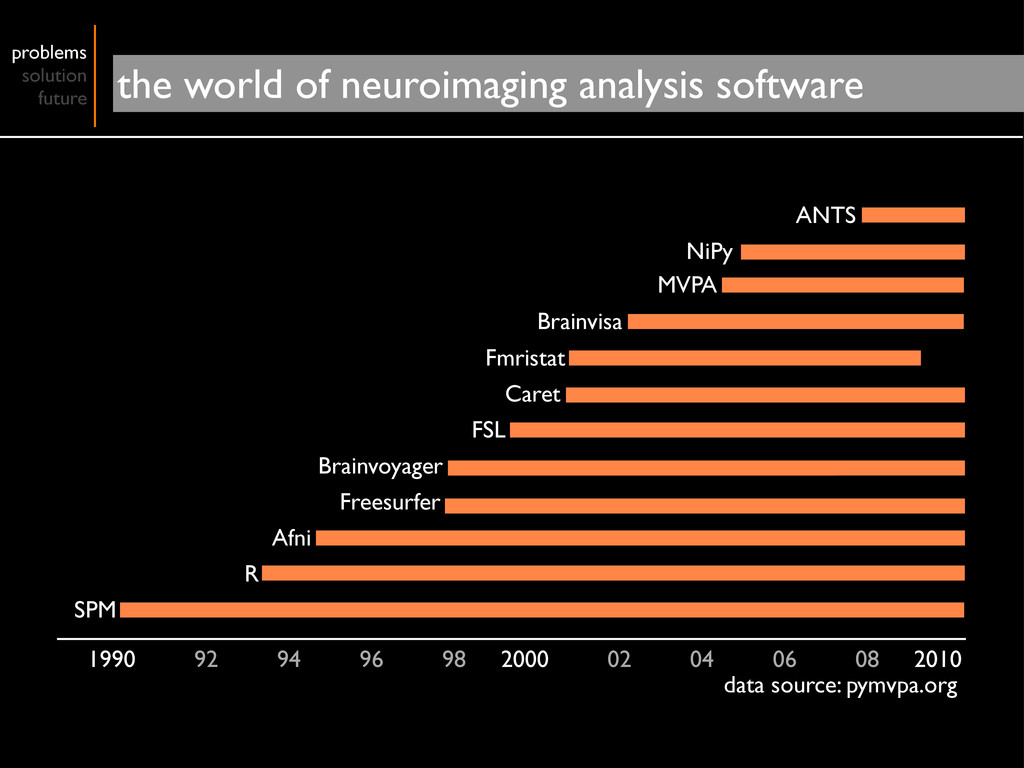
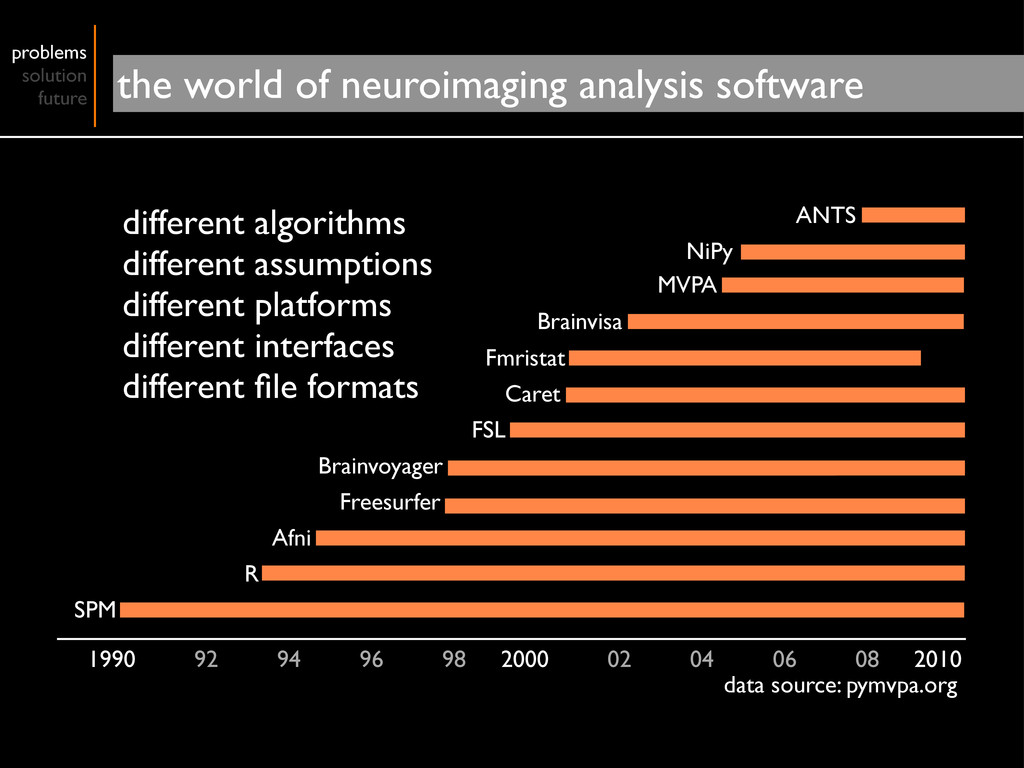
problems solution future the world of neuroimaging analysis software data
source: pymvpa.org 1990 92 94 96 98 2000 02 04 06 08 2010 Afni Brainvoyager Freesurfer R Caret Fmristat FSL MVPA NiPy ANTS SPM Brainvisa -
different algorithms different assumptions different platforms different interfaces different file
formats problems solution future the world of neuroimaging analysis software data source: pymvpa.org 1990 92 94 96 98 2000 02 04 06 08 2010 Afni Brainvoyager Freesurfer R Caret Fmristat FSL MVPA NiPy ANTS SPM Brainvisa -
problems solution future the scientific process “The scientific method’s central
motivation is the ubiquity of error - the awareness that mistakes and self-delusion can creep in absolutely anywhere and that the scientist’s effort is primarily expended in recognizing and rooting out error.” Donoho et al. (2009) assumed veracity of publications dependence on peer review as a proxy for testing -
special populations : enables aggregation of large data sets problems
solution future but why share data and code? -
special populations : enables aggregation of large data sets (e.g.,
Autism, ADHD, Schizophrenia) problems solution future but why share data and code? -
special populations : enables aggregation of large data sets (e.g.,
Autism, ADHD, Schizophrenia) cross-discipline interaction : problems solution future but why share data and code? -
special populations : enables aggregation of large data sets (e.g.,
Autism, ADHD, Schizophrenia) cross-discipline interaction : - provides data to test their algorithms problems solution future but why share data and code? -
special populations : enables aggregation of large data sets (e.g.,
Autism, ADHD, Schizophrenia) cross-discipline interaction : - provides data to test their algorithms - increases sample size for learning algorithms problems solution future but why share data and code? -
special populations : enables aggregation of large data sets (e.g.,
Autism, ADHD, Schizophrenia) cross-discipline interaction : - provides data to test their algorithms - increases sample size for learning algorithms pedagogy : problems solution future but why share data and code? -
special populations : enables aggregation of large data sets (e.g.,
Autism, ADHD, Schizophrenia) cross-discipline interaction : - provides data to test their algorithms - increases sample size for learning algorithms pedagogy : provides easy mechanism to train new personnel problems solution future but why share data and code? -
most publications do not include data, code problems solution future
current barriers -
most publications do not include data, code some journals mandate
but provide no infrastructure for storage, distribution problems solution future current barriers -
most publications do not include data, code some journals mandate
but provide no infrastructure for storage, distribution most scientists do not have the time to curate data problems solution future current barriers -
most publications do not include data, code some journals mandate
but provide no infrastructure for storage, distribution most scientists do not have the time to curate data no standard ontology for describing experiments, data, derived data, workflows problems solution future current barriers -
how to share data/code? what to share? problems solution future
other practical matters -
how to share data/code? what to share? where to share?
problems solution future other practical matters -
how to share data/code? what to share? where to share?
how to include manual intervention? problems solution future other practical matters -
problems solutions future barriers to data and code sharing current
approaches in neuroimaging can we have reproducible research? -
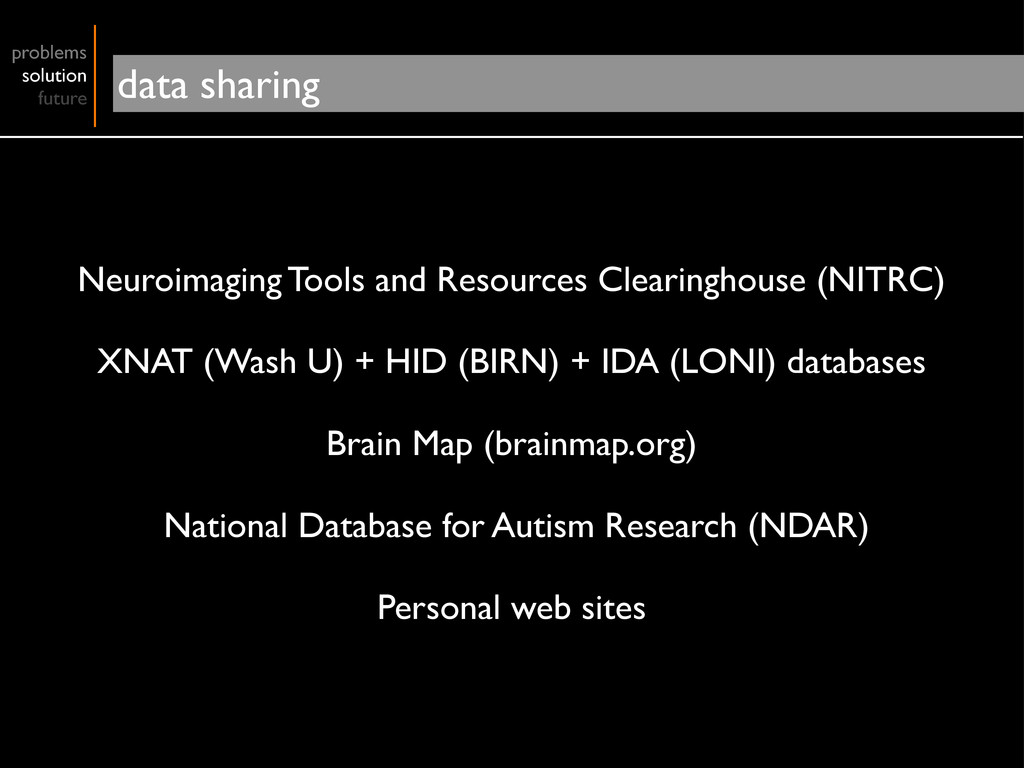
problems solution future data sharing Neuroimaging Tools and Resources Clearinghouse
(NITRC) XNAT (Wash U) + HID (BIRN) + IDA (LONI) databases Brain Map (brainmap.org) National Database for Autism Research (NDAR) Personal web sites -
ipython scipy + numpy networkx sympy matplotlib mayavi + tvtk
problems solution future open-source scientific computing stack -
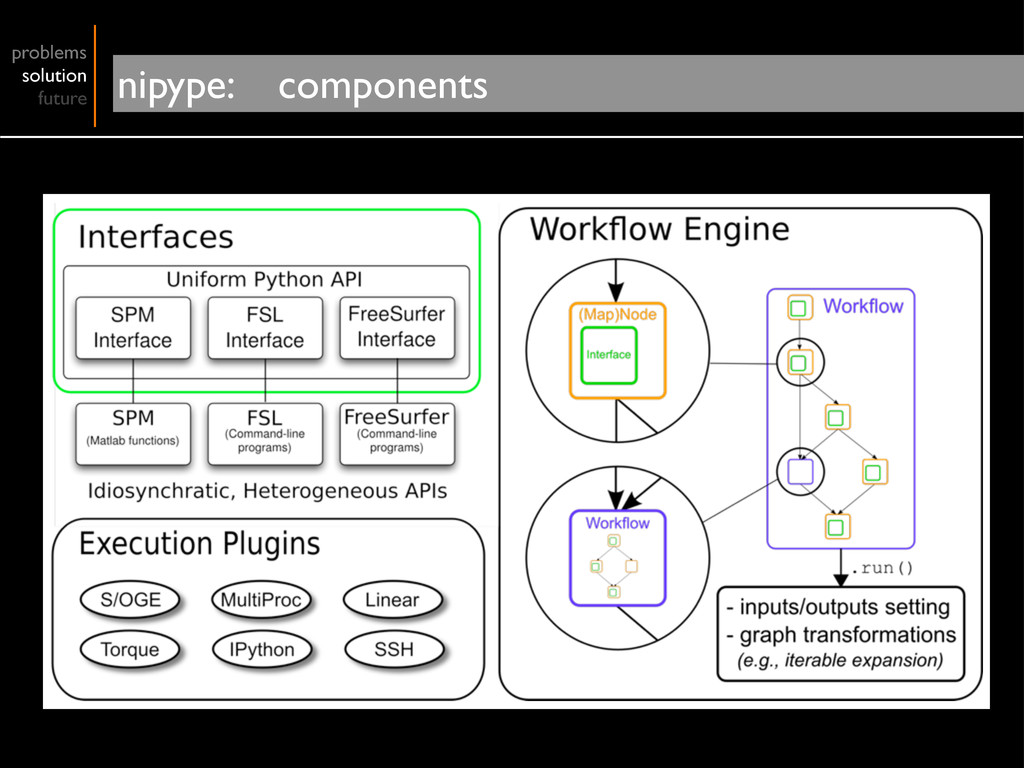
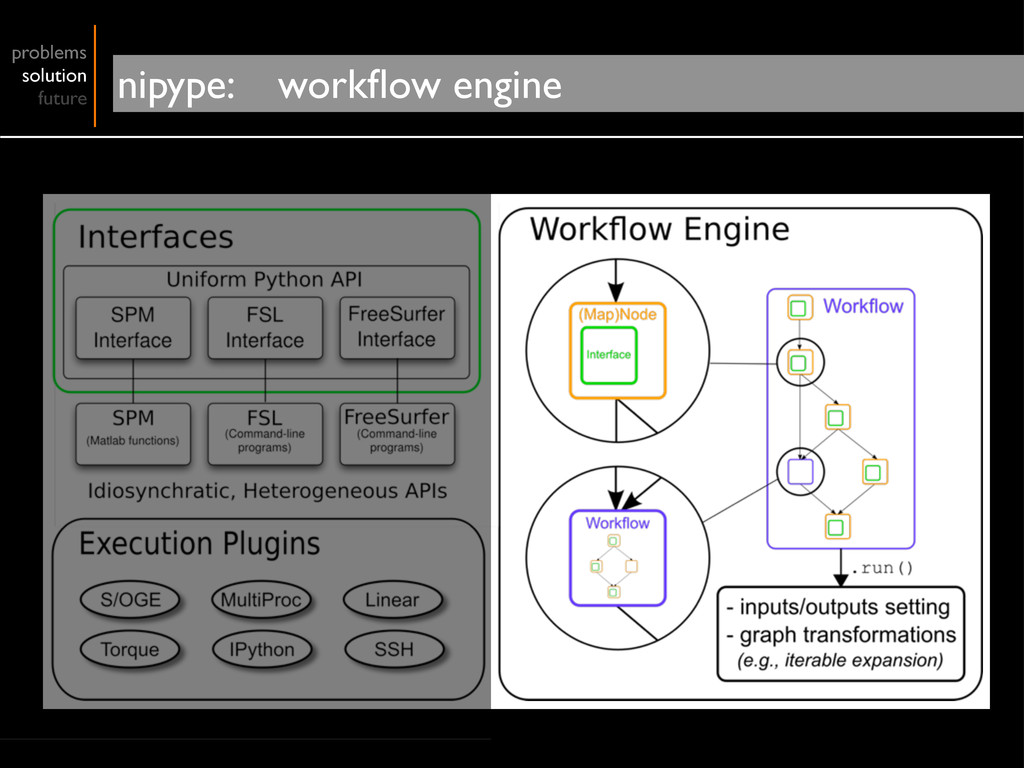
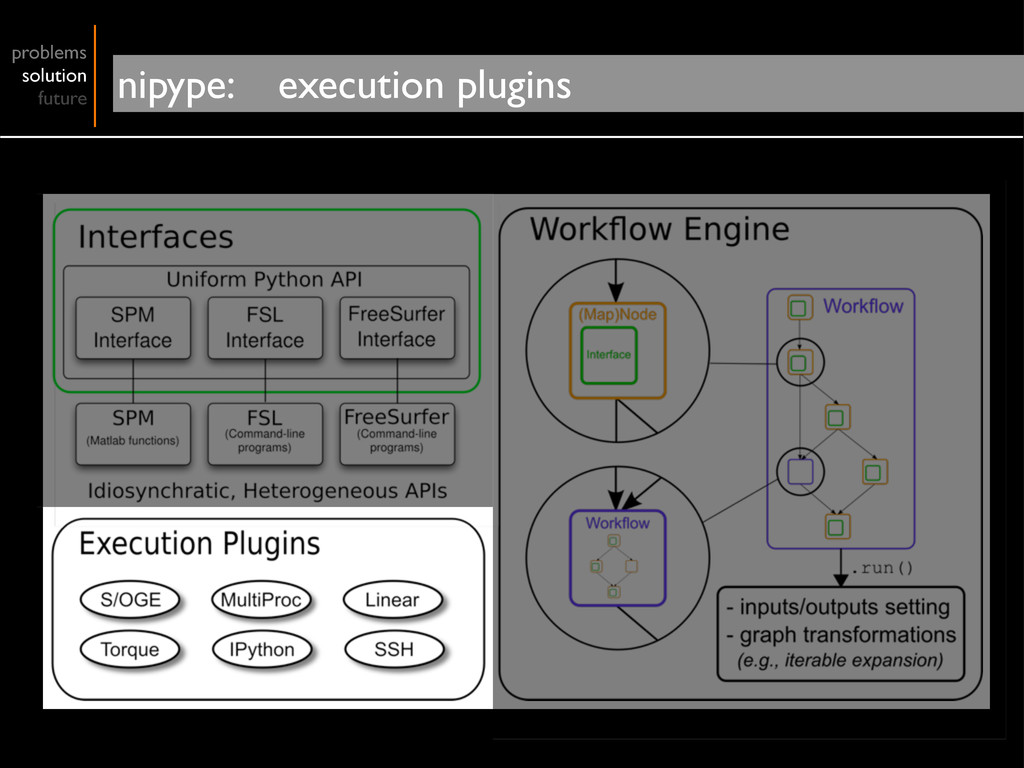
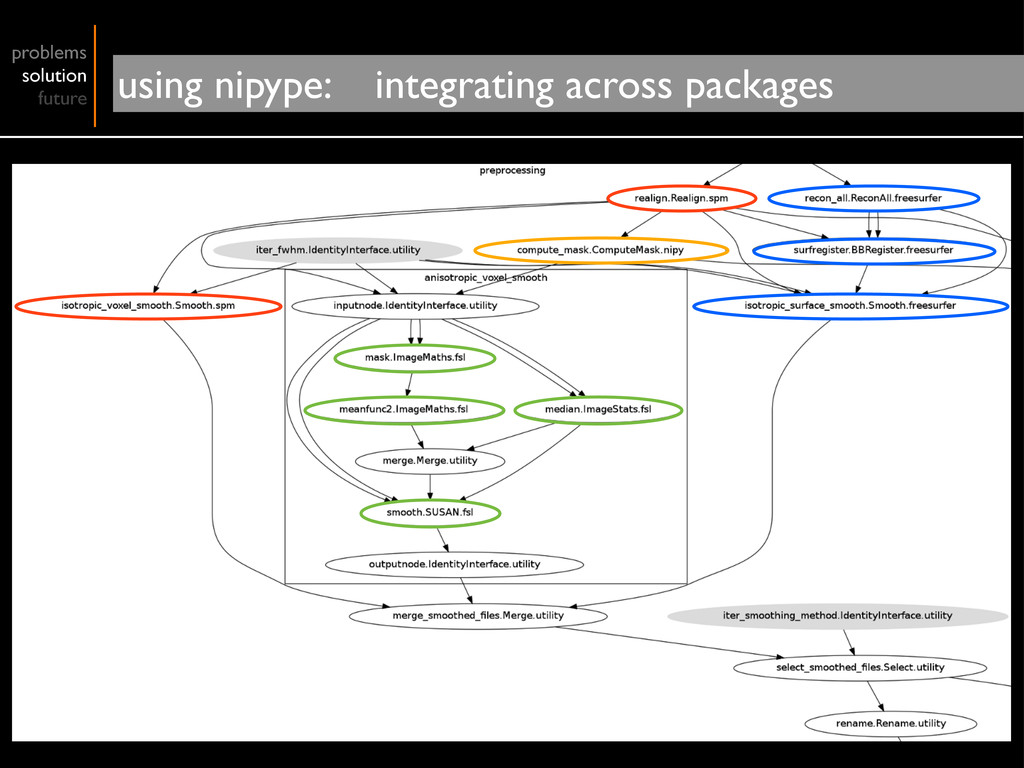
problems solution future code sharing: formalized interfaces and workflows Neuroimaging
Pipelines and Interfaces nipy.org/nipype -
problems solutions future barriers to data and code sharing current
approaches in neuroimaging can we have reproducible research? -
problems solution future technical options Electronic computable notebooks (cdf :
computable document format) Virtual environments Standard ontology Formalized interfaces Federated databases