Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Tutorial on Migrating Phase Field Codes to GPUs
Search
Daniel Wheeler
July 21, 2022
Science
230
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Tutorial on Migrating Phase Field Codes to GPUs
Daniel Wheeler
July 21, 2022
More Decks by Daniel Wheeler
See All by Daniel Wheeler
Semi-supervised Learning Approaches For Microstructure Classification
wd15
0
180
Deep Materials Informatics: Illustrative Applications of Deep Learning in Materials Science
wd15
0
300
Fitting Free Energies with Neural Networks
wd15
0
180
SymPhas: Symbolic Algebra for Phase-Field Simulations
wd15
0
270
PFHUB REIMPLEMENTATION FOR FAIR DATA COLLECTION
wd15
0
150
Preparing for Exascale Phase-Field Simulations: Phase-Field Modeling in ExaAM and AEOLUS
wd15
0
190
Selected Highlights of Accelerated Microstructure Design Using the High Performance Materials Simulation Framework Pace3D
wd15
0
200
Phase Field Methods + FEniCS/Firedrake
wd15
0
1.2k
Phase Field Modeling with COMSOL Multiphysics
wd15
0
830
Other Decks in Science
See All in Science
「AIエージェントを作る」とは、何を設計することか
salt2
0
210
O(log n)-Approximation Algorithms for Bipartiteness Ratio
tasusu
0
260
20260410_SystemsThinking
takusamar
1
160
コーヒー豆様核 (Coffee-bean nuclei) における形態学的サブタイピングと精選・焙煎特性の同定
jagupath
PRO
0
190
データベース01: データベースを使わない世界
trycycle
PRO
1
1.5k
AI for Phage-Host prediction
michielstock
0
140
機械学習 - K近傍法 & 機械学習のお作法
trycycle
PRO
1
1.7k
AWS WAFのAIトラフィック収益化機能を考えてみる_20260626
masakiokuda
1
100
機械学習 - SVM
trycycle
PRO
2
1.3k
J-STAGE全文XML登載必須化について
xspa2012
0
1.6k
プレイがつなぐ研究と社会:市⺠‧クリエイター‧SF作家による実践を通じて
hayataka88
1
120
Massey Ratings for Match Outcome Prediction in Table Tennis: Evidence of Greater Stability than the ITTF World Ranking
konakalab
0
160
Featured
See All Featured
CoffeeScript is Beautiful & I Never Want to Write Plain JavaScript Again
sstephenson
162
16k
Sharpening the Axe: The Primacy of Toolmaking
bcantrill
46
3k
Ethics towards AI in product and experience design
skipperchong
2
420
Fantastic passwords and where to find them - at NoRuKo
philnash
53
4k
Building a Modern Day E-commerce SEO Strategy
aleyda
45
9.2k
The Director’s Chair: Orchestrating AI for Truly Effective Learning
tmiket
1
320
The untapped power of vector embeddings
frankvandijk
2
1.9k
Design in an AI World
tapps
1
350
How to Ace a Technical Interview
jacobian
280
24k
Digital Projects Gone Horribly Wrong (And the UX Pros Who Still Save the Day) - Dean Schuster
uxyall
1
3.3k
Exploring anti-patterns in Rails
aemeredith
4
520
Performance Is Good for Brains [We Love Speed 2024]
tammyeverts
12
1.9k
Transcript
Tutorial on Migrating Phase Field Codes to GPUs Jin Zhang
Voorhees Group, Northwestern University May 11, 2022
Outline The GPU hardware Brief introduction to CUDA Example: Allen-Cahn
equation The standard way: CUDA The ‘easy’ way: Standard C++ 2 / 22
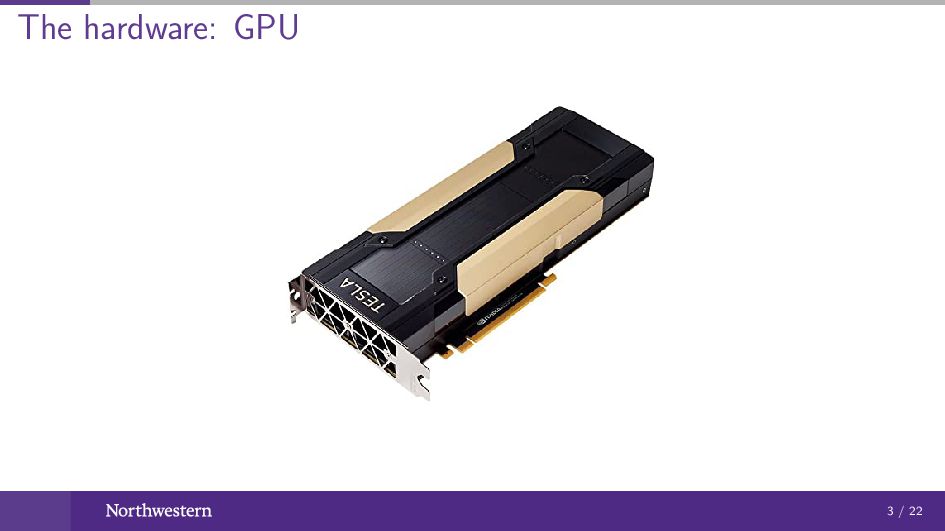
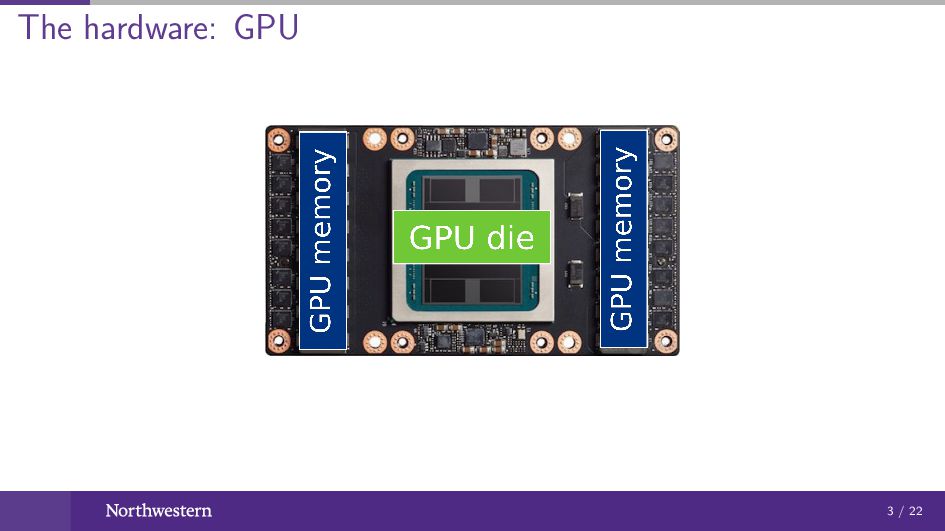
The hardware: GPU 3 / 22
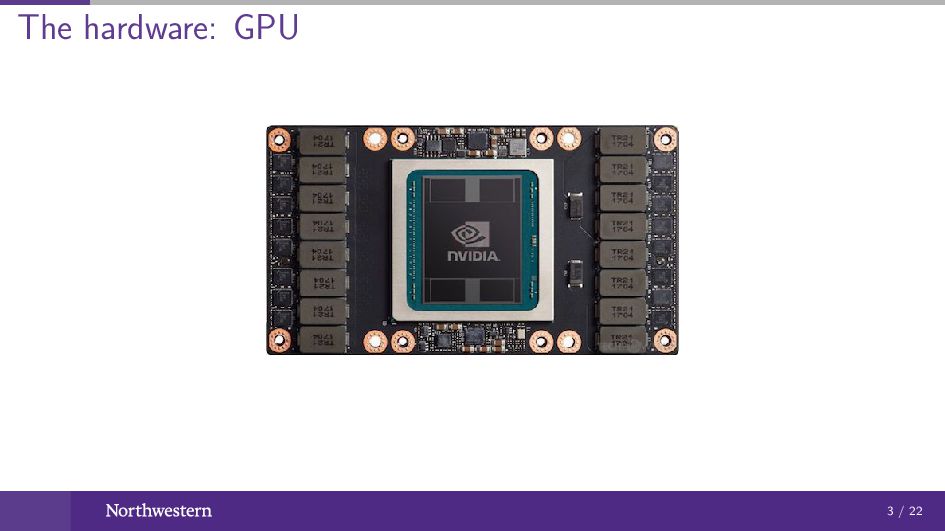
The hardware: GPU 3 / 22
The hardware: GPU 3 / 22
The hardware: GPU 3 / 22
The hardware: GPU 3 / 22
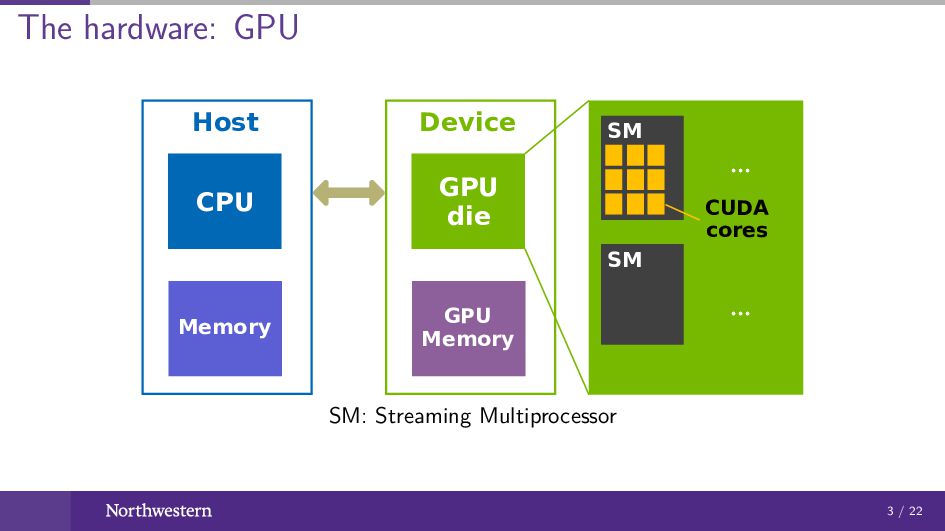
The hardware: GPU CPU Memory Host GPU die GPU Memory
Device ... ... SM SM ... ... CUDA cores SM: Streaming Multiprocessor 3 / 22
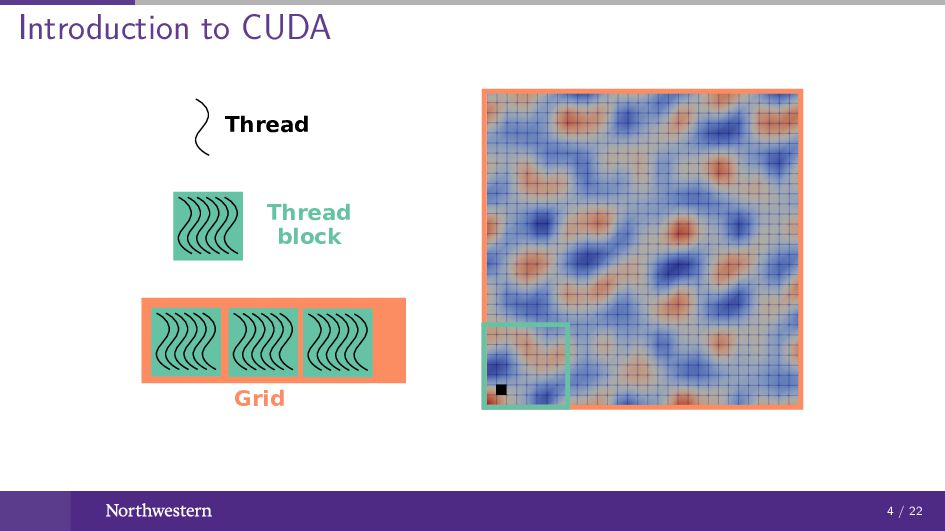
Introduction to CUDA Thread Thread block Grid 4 / 22
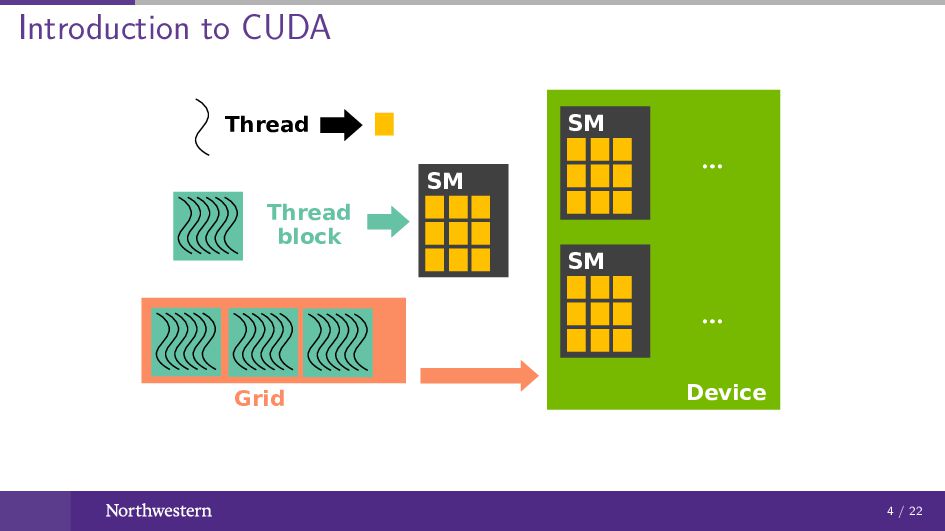
Introduction to CUDA Thread Thread block Grid ... ... SM
... ... Device SM SM 4 / 22
Introduction to CUDA CUDA development tools Need an NVIDIA GPU
Install NVIDIA Driver Install compiler: CUDA Toolkit/NVIDIA HPC SDK 4 / 22
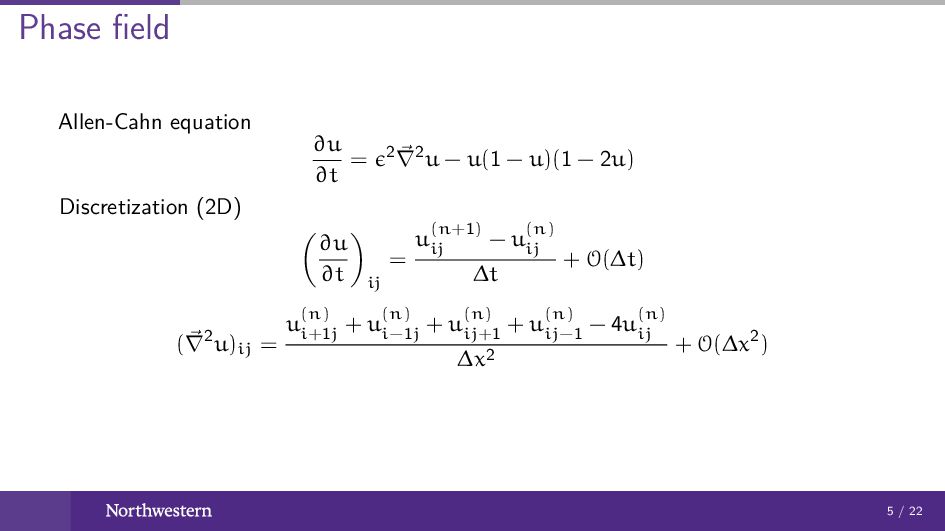
Phase field Allen-Cahn equation ∂u ∂t = 2∇2u − u(1
− u)(1 − 2u) Discretization (2D) ∂u ∂t ij = u(n+1) ij − u(n) ij ∆t + O(∆t) (∇2u)ij = u(n) i+1j + u(n) i−1j + u(n) ij+1 + u(n) ij−1 − 4u(n) ij ∆x2 + O(∆x2) 5 / 22
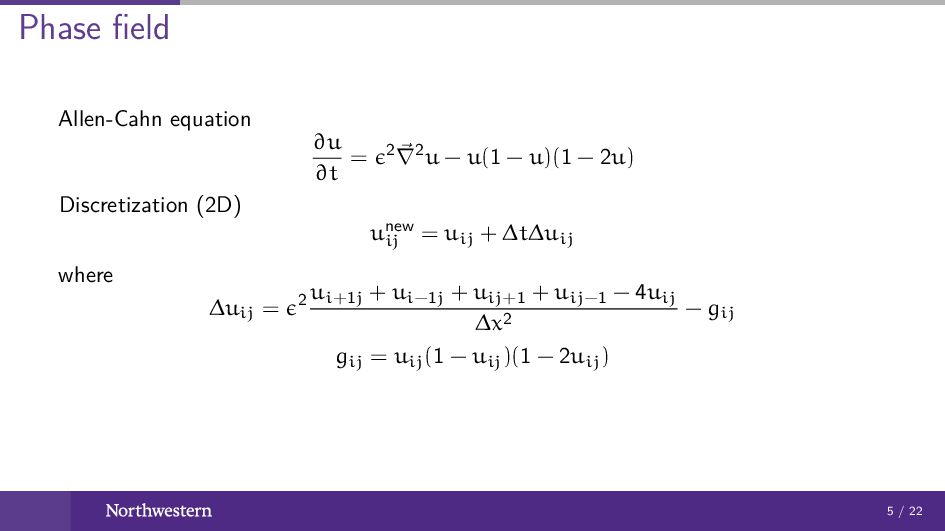
Phase field Allen-Cahn equation ∂u ∂t = 2∇2u − u(1
− u)(1 − 2u) Discretization (2D) unew ij = uij + ∆t∆uij where ∆uij = 2 ui+1j + ui−1j + uij+1 + uij−1 − 4uij ∆x2 − gij gij = uij(1 − uij)(1 − 2uij) 5 / 22
Our task Implement a CPU code Modify it to run
on GPU 6 / 22
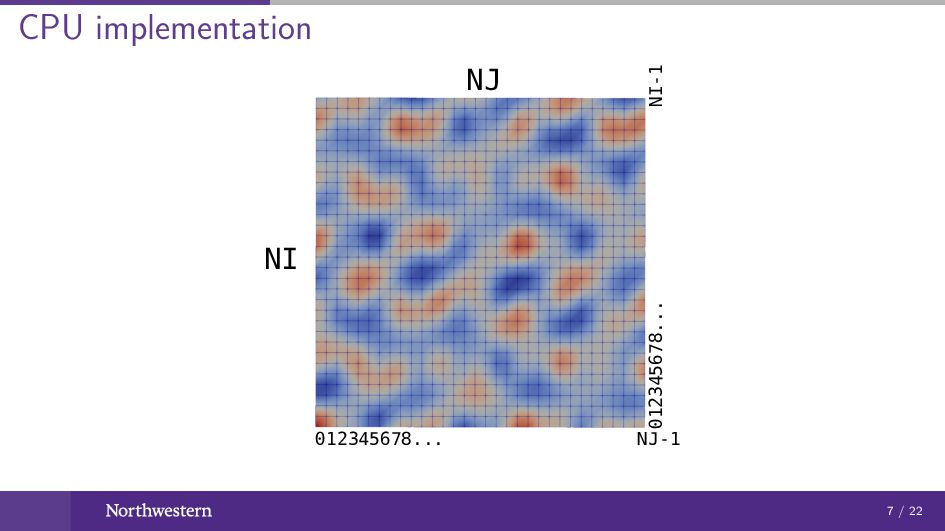
CPU implementation NJ NI 012345678... NJ-1 012345678... NI-1 7 /
22
CPU implementation 1 int main(int argc , char *argv [])
2 { 3 double *u, *u1; // order parameter 4 u = (double *)malloc(NI*NJ * sizeof(double)); // old value 5 u1 = (double *)malloc(NI*NJ * sizeof(double)); // new value 6 // ... 7 ic(u); // initial condition 8 for (long t=1L; t<=n; t++){ // loop timesteps 9 sweep(u, u1 , e, dt); // u1 = u + du 10 double *tmp = u1; u1 = u; u = tmp; // u <-> u1 11 } 12 } 8 / 22
CPU implementation 1 void sweep(double *u, double *u1 , double
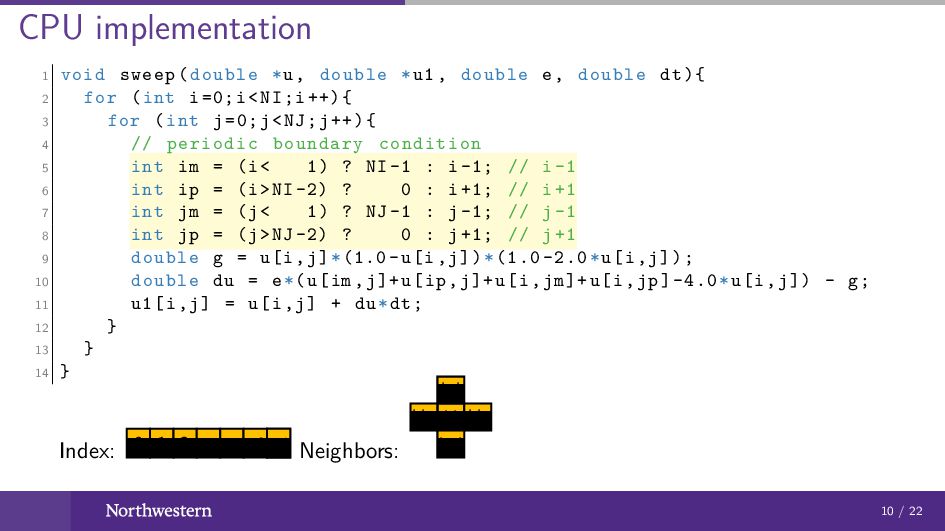
e, double dt){ 2 for (int i=0;i<NI;i++){ 3 for (int j=0;j<NJ;j++){ 4 // periodic boundary condition 5 int im = (i< 1) ? NI -1 : i-1; // i-1 6 int ip = (i>NI -2) ? 0 : i+1; // i+1 7 int jm = (j< 1) ? NJ -1 : j-1; // j-1 8 int jp = (j>NJ -2) ? 0 : j+1; // j+1 9 double g = u[i,j]*(1.0-u[i,j])*(1.0 -2.0*u[i,j]); 10 double du = e*(u[im ,j]+u[ip ,j]+u[i,jm]+u[i,jp] -4.0*u[i,j]) - g; 11 u1[i,j] = u[i,j] + du*dt; 12 } 13 } 14 } System size NI×NJ, Index: 0 1 2 N-1 N-2 9 / 22
CPU implementation 1 void sweep(double *u, double *u1 , double
e, double dt){ 2 for (int i=0;i<NI;i++){ 3 for (int j=0;j<NJ;j++){ 4 // periodic boundary condition 5 int im = (i< 1) ? NI -1 : i-1; // i-1 6 int ip = (i>NI -2) ? 0 : i+1; // i+1 7 int jm = (j< 1) ? NJ -1 : j-1; // j-1 8 int jp = (j>NJ -2) ? 0 : j+1; // j+1 9 double g = u[i,j]*(1.0-u[i,j])*(1.0 -2.0*u[i,j]); 10 double du = e*(u[im ,j]+u[ip ,j]+u[i,jm]+u[i,jp] -4.0*u[i,j]) - g; 11 u1[i,j] = u[i,j] + du*dt; 12 } 13 } 14 } Index: 0 1 2 N-1 N-2 Neighbors: i,j i m ,j i p ,j i,j m i,j p 10 / 22
CPU implementation 1 void sweep(double *u, double *u1 , double
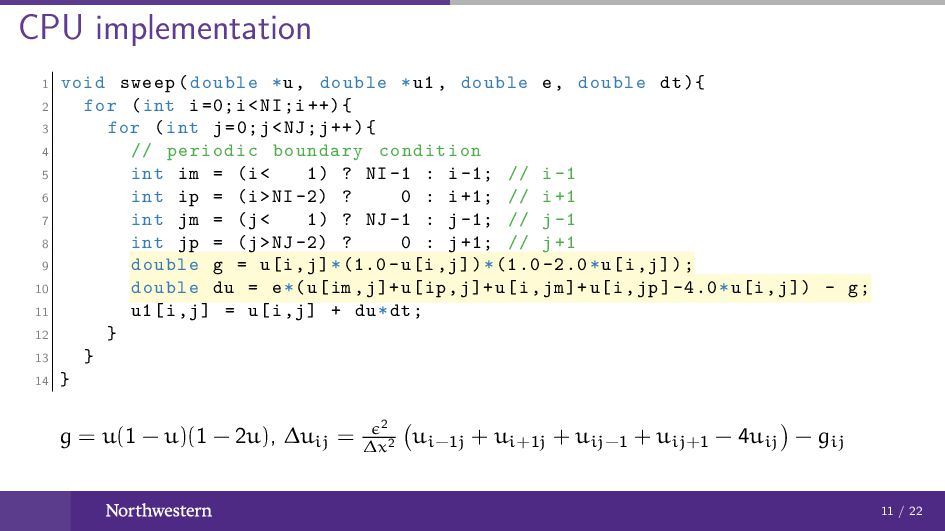
e, double dt){ 2 for (int i=0;i<NI;i++){ 3 for (int j=0;j<NJ;j++){ 4 // periodic boundary condition 5 int im = (i< 1) ? NI -1 : i-1; // i-1 6 int ip = (i>NI -2) ? 0 : i+1; // i+1 7 int jm = (j< 1) ? NJ -1 : j-1; // j-1 8 int jp = (j>NJ -2) ? 0 : j+1; // j+1 9 double g = u[i,j]*(1.0-u[i,j])*(1.0 -2.0*u[i,j]); 10 double du = e*(u[im ,j]+u[ip ,j]+u[i,jm]+u[i,jp] -4.0*u[i,j]) - g; 11 u1[i,j] = u[i,j] + du*dt; 12 } 13 } 14 } g = u(1 − u)(1 − 2u), ∆uij = 2 ∆x2 ui−1j + ui+1j + uij−1 + uij+1 − 4uij − gij 11 / 22
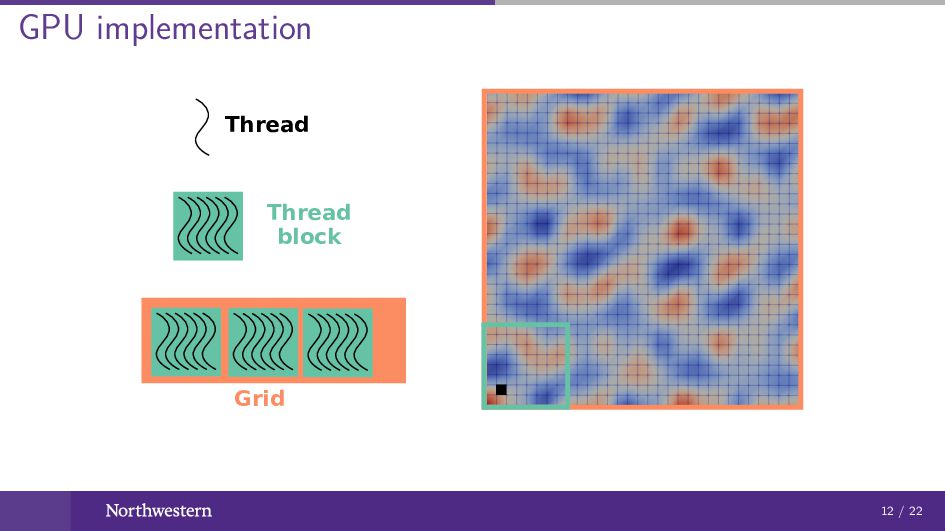
GPU implementation Thread Thread block Grid 12 / 22
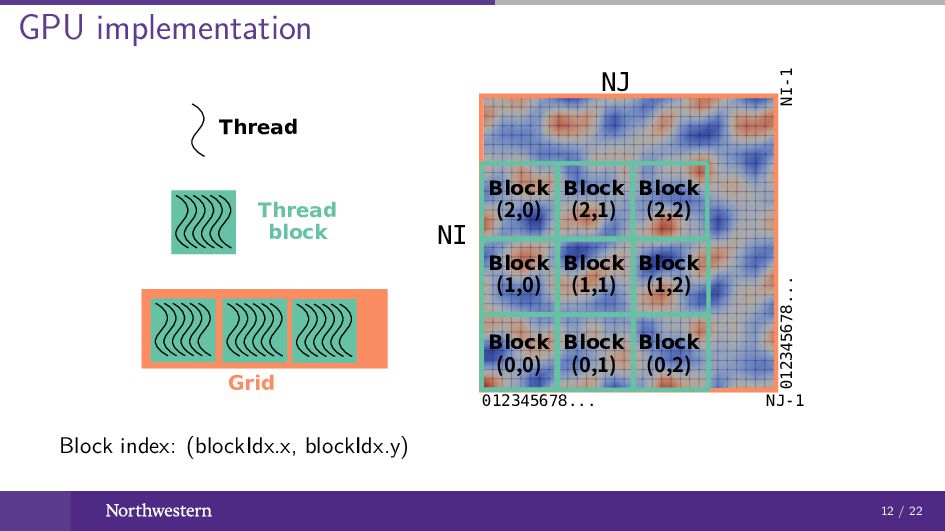
GPU implementation NJ NI 012345678... NJ-1 012345678... NI-1 Thread Thread
block Grid Block (0,0) Block (0,1) Block (0,2) Block (1,0) Block (1,1) Block (1,2) Block (2,0) Block (2,1) Block (2,2) Block index: (blockIdx.x, blockIdx.y) 12 / 22
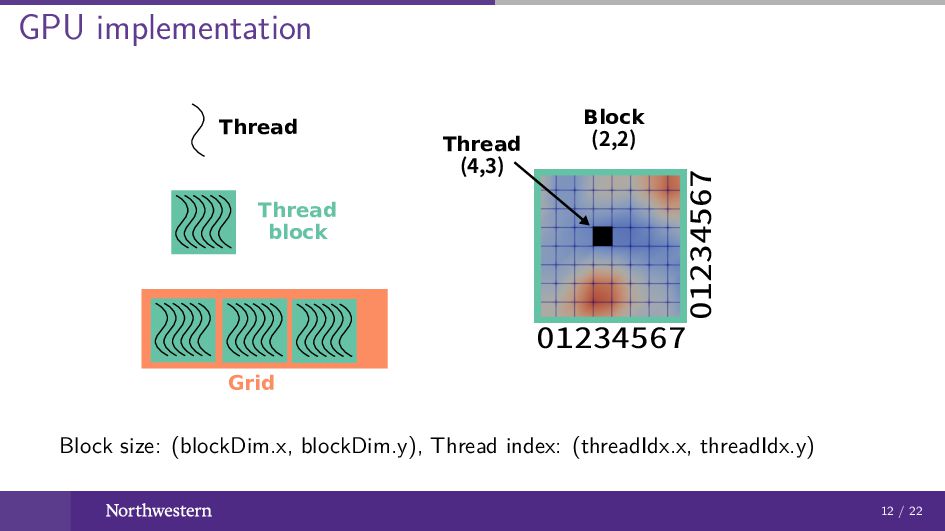
GPU implementation Thread Thread block Grid Block (2,2) 01234567 01234567
Thread (4,3) Block size: (blockDim.x, blockDim.y), Thread index: (threadIdx.x, threadIdx.y) 12 / 22
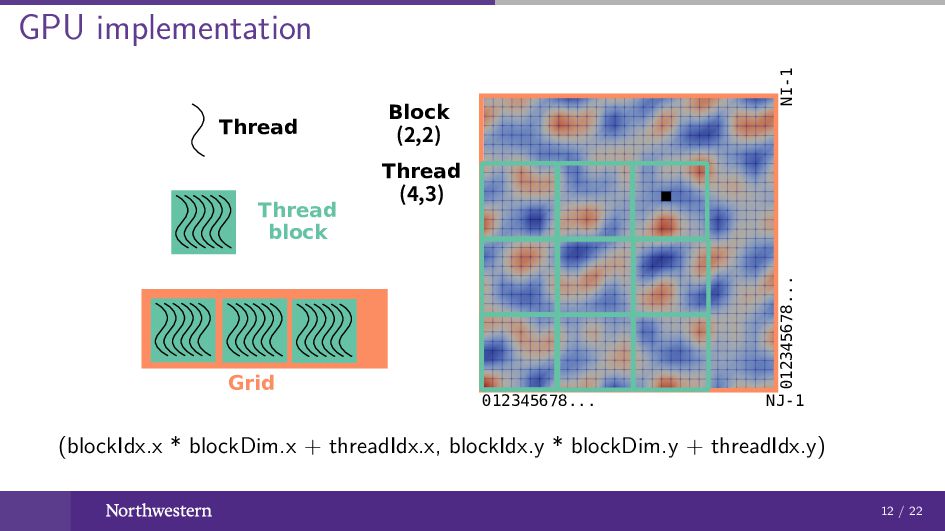
GPU implementation 012345678... NJ-1 012345678... NI-1 Thread Thread block Grid
Block (2,2) Thread (4,3) (blockIdx.x * blockDim.x + threadIdx.x, blockIdx.y * blockDim.y + threadIdx.y) 12 / 22
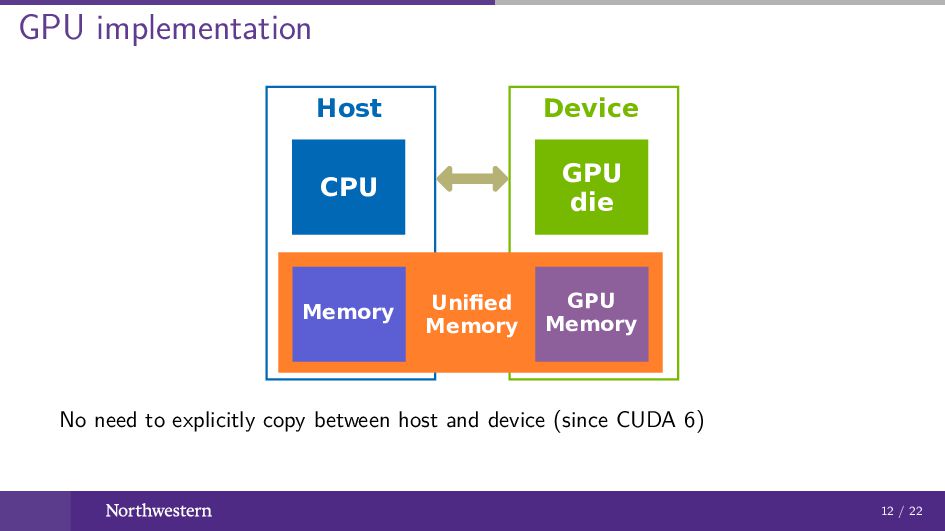
GPU implementation CPU Host GPU die Device Unified Memory Memory
GPU Memory No need to explicitly copy between host and device (since CUDA 6) 12 / 22
CUDA implementation 1 int main(int argc , char *argv [])
2 { 3 double *u, *u1; // order parameter 4 cudaMallocManaged ( &u, NI*NJ * sizeof(double)); // old value 5 cudaMallocManaged (&u1 , NI*NJ * sizeof(double)); // new value 6 dim3 dimBlock(BLOCK_X , BLOCK_Y); 7 dim3 dimGrid(NI/BLOCK_X , NJ/BLOCK_Y); 8 // ... 9 ic(u); // initial condition 10 for (long t=1L; t<=n; t++){ 11 sweep<<<dimGrid, dimBlock>>>(u, u1 , e, dt); 12 double *tmp = u1; u1 = u; u = tmp; // u <-> u1 13 } 14 } 13 / 22
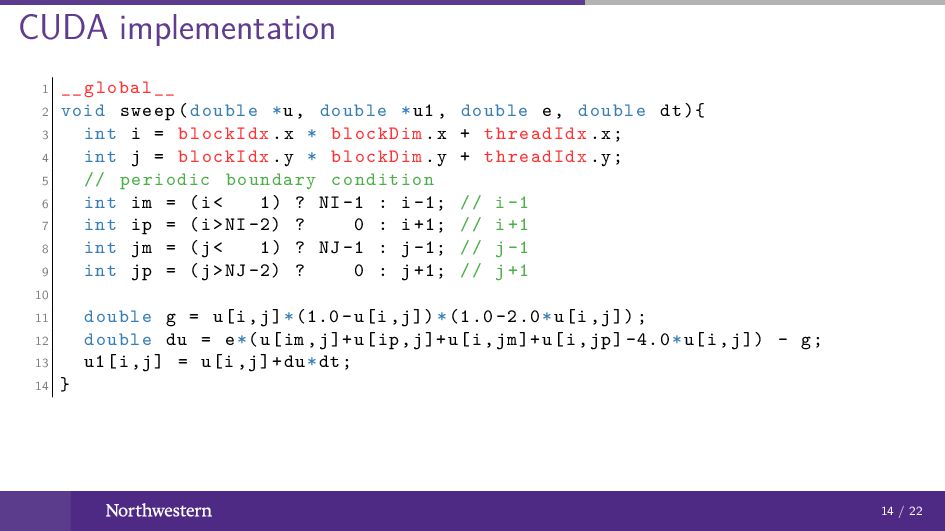
CUDA implementation 1 __global__ 2 void sweep(double *u, double *u1
, double e, double dt){ 3 int i = blockIdx.x * blockDim.x + threadIdx.x; 4 int j = blockIdx.y * blockDim.y + threadIdx.y; 5 // periodic boundary condition 6 int im = (i< 1) ? NI -1 : i-1; // i-1 7 int ip = (i>NI -2) ? 0 : i+1; // i+1 8 int jm = (j< 1) ? NJ -1 : j-1; // j-1 9 int jp = (j>NJ -2) ? 0 : j+1; // j+1 10 11 double g = u[i,j]*(1.0-u[i,j])*(1.0 -2.0*u[i,j]); 12 double du = e*(u[im ,j]+u[ip ,j]+u[i,jm]+u[i,jp] -4.0*u[i,j]) - g; 13 u1[i,j] = u[i,j]+du*dt; 14 } 14 / 22
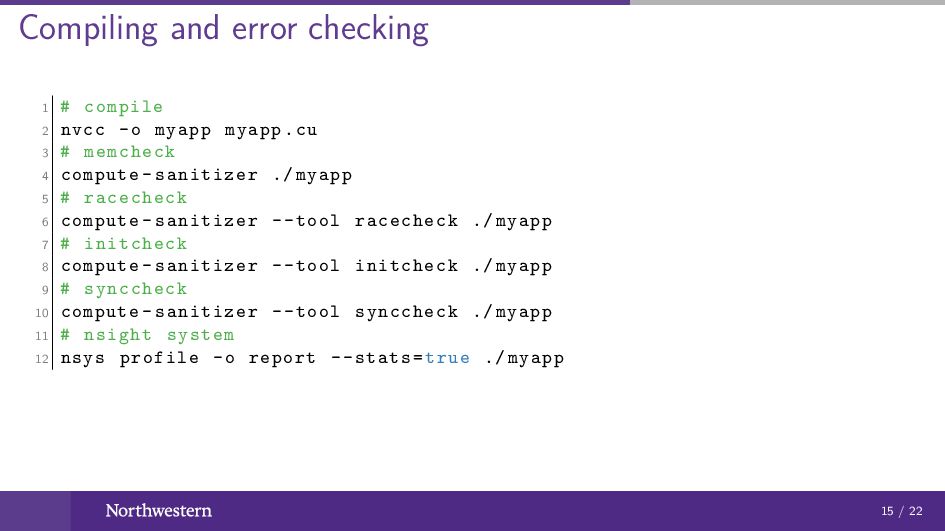
Compiling and error checking 1 # compile 2 nvcc -o
myapp myapp.cu 3 # memcheck 4 compute -sanitizer ./ myapp 5 # racecheck 6 compute -sanitizer --tool racecheck ./ myapp 7 # initcheck 8 compute -sanitizer --tool initcheck ./ myapp 9 # synccheck 10 compute -sanitizer --tool synccheck ./ myapp 11 # nsight system 12 nsys profile -o report --stats=true ./ myapp 15 / 22
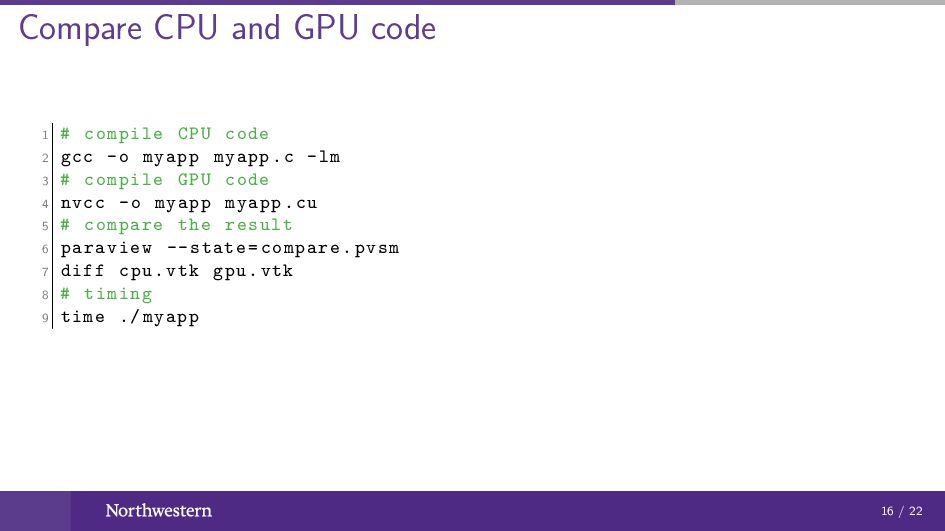
Compare CPU and GPU code 1 # compile CPU code
2 gcc -o myapp myapp.c -lm 3 # compile GPU code 4 nvcc -o myapp myapp.cu 5 # compare the result 6 paraview --state=compare.pvsm 7 diff cpu.vtk gpu.vtk 8 # timing 9 time ./ myapp 16 / 22
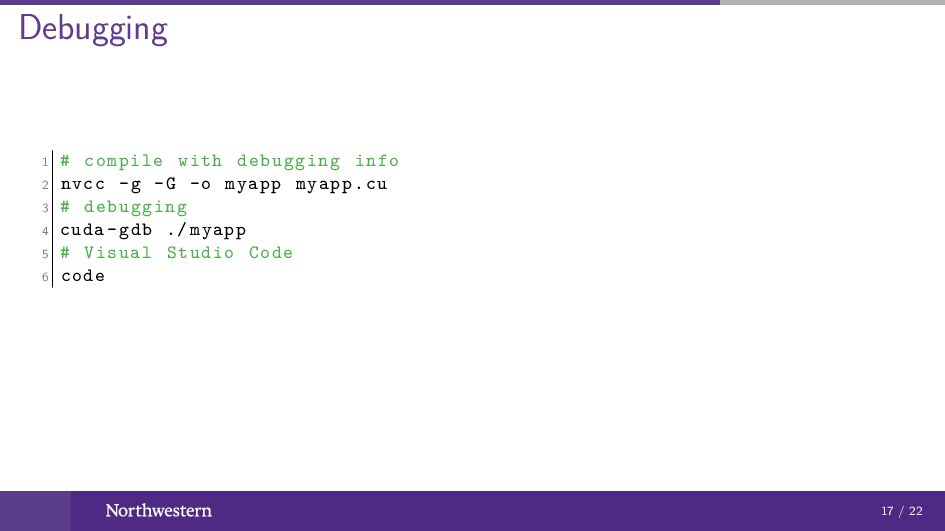
Debugging 1 # compile with debugging info 2 nvcc -g
-G -o myapp myapp.cu 3 # debugging 4 cuda -gdb ./ myapp 5 # Visual Studio Code 6 code 17 / 22
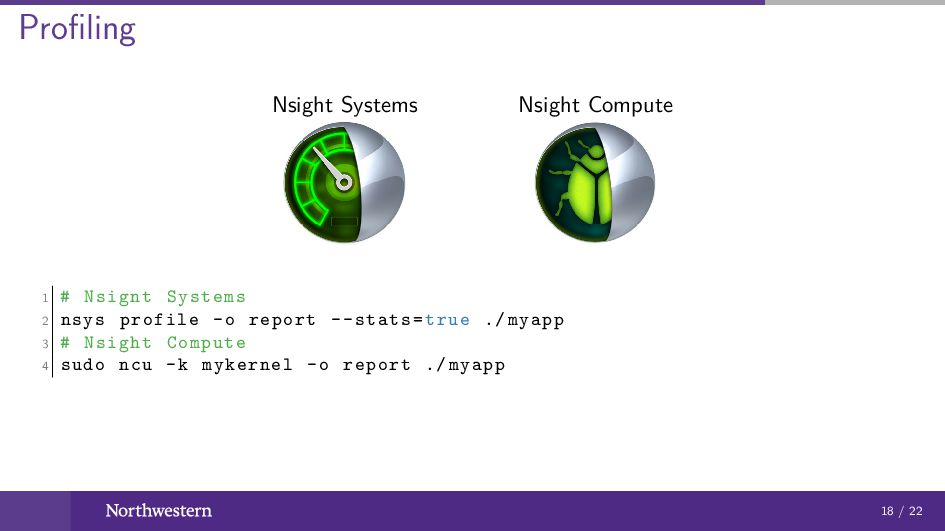
Profiling Nsight Systems blank Nsight Compute 1 # Nsignt Systems
2 nsys profile -o report --stats=true ./ myapp 3 # Nsight Compute 4 sudo ncu -k mykernel -o report ./ myapp 18 / 22
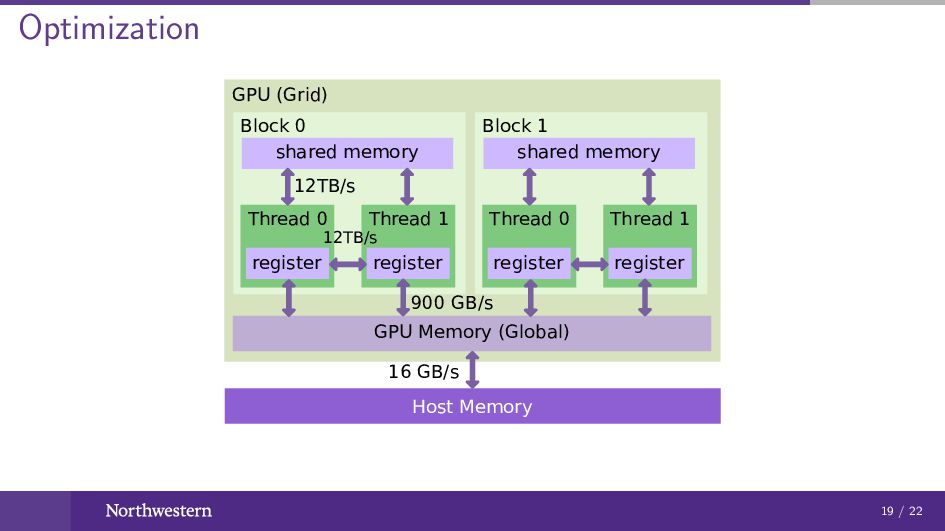
Optimization Size of a block (multiple of 32) Memory hierarchy
Contiguous memory access Parallel reduction Warp (warp-level primitives) Shared memory (bank conflict) 19 / 22
Optimization Host Memory GPU (Grid) GPU Memory (Global) 16 GB/s
Block 0 Thread 0 register shared memory Thread 1 register Block 1 Thread 0 register shared memory Thread 1 register 900 GB/s 12TB/s 12TB/s 19 / 22
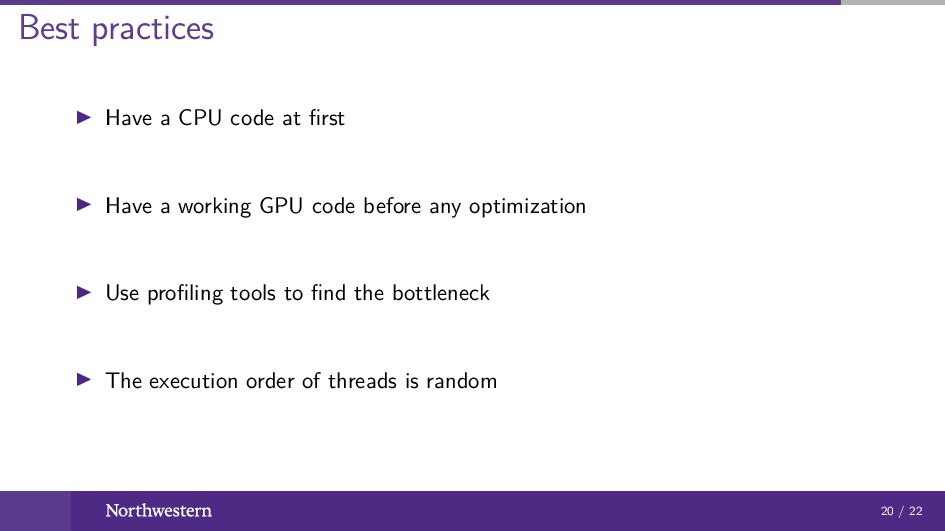
Best practices Have a CPU code at first Have a
working GPU code before any optimization Use profiling tools to find the bottleneck The execution order of threads is random 20 / 22
An ‘easy’ way: Standard C++ Parallelism (C++20) 1 void sweep(double
*u, double *u1 , double e, double dt){ 2 auto v = std:: ranges :: views :: iota(0, NI*NJ); 3 std:: for_each( 4 std:: execution :: par_unseq , 5 std:: begin(v), std::end(v), 6 [=] (auto idx){ 7 int i = idx / NJ; 8 int j = idx % NJ; 9 // periodic boundary condition 10 int im = (i< 1) ? NI -1 : i-1; // i-1 11 int ip = (i>NI -2) ? 0 : i+1; // i+1 12 int jm = (j< 1) ? NJ -1 : j-1; // j-1 13 int jp = (j>NJ -2) ? 0 : j+1; // j+1 14 double g = u[i,j]*(1.0-u[i,j])*(1.0 -2.0*u[i,j]); 15 double du= e*(u[im ,j]+u[ip ,j]+u[i,jm]+u[i,jp] -4.0*u[i,j]) - g; 16 u1[i,j] = u[i,j]+du*dt; 17 }); 18 } 21 / 22
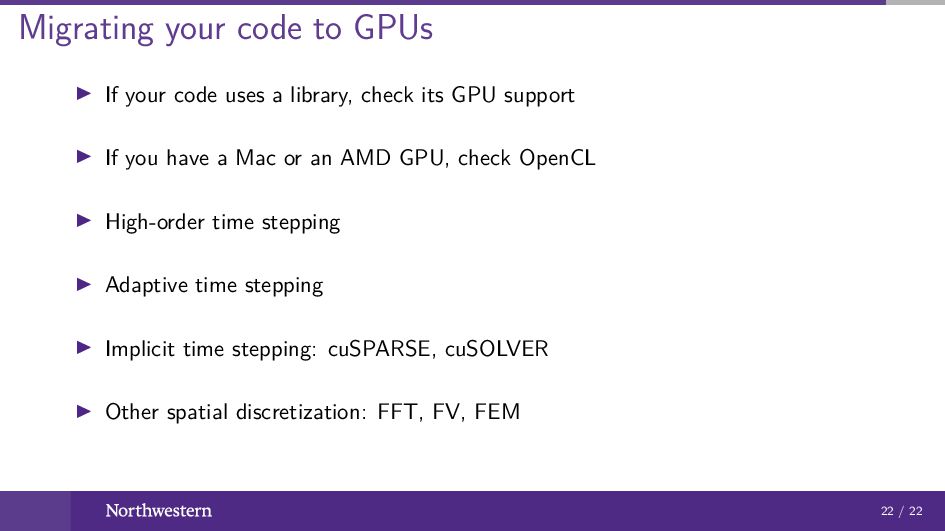
Migrating your code to GPUs If your code uses a
library, check its GPU support If you have a Mac or an AMD GPU, check OpenCL High-order time stepping Adaptive time stepping Implicit time stepping: cuSPARSE, cuSOLVER Other spatial discretization: FFT, FV, FEM 22 / 22


 wd15
 salt2
 tasusu
 takusamar
 jagupath
 trycycle
 michielstock
 masakiokuda
 xspa2012
 hayataka88
 konakalab
 sstephenson
 bcantrill
 skipperchong
 philnash
 aleyda
 tmiket
 frankvandijk
 tapps
 jacobian
 uxyall
 aemeredith
 tammyeverts