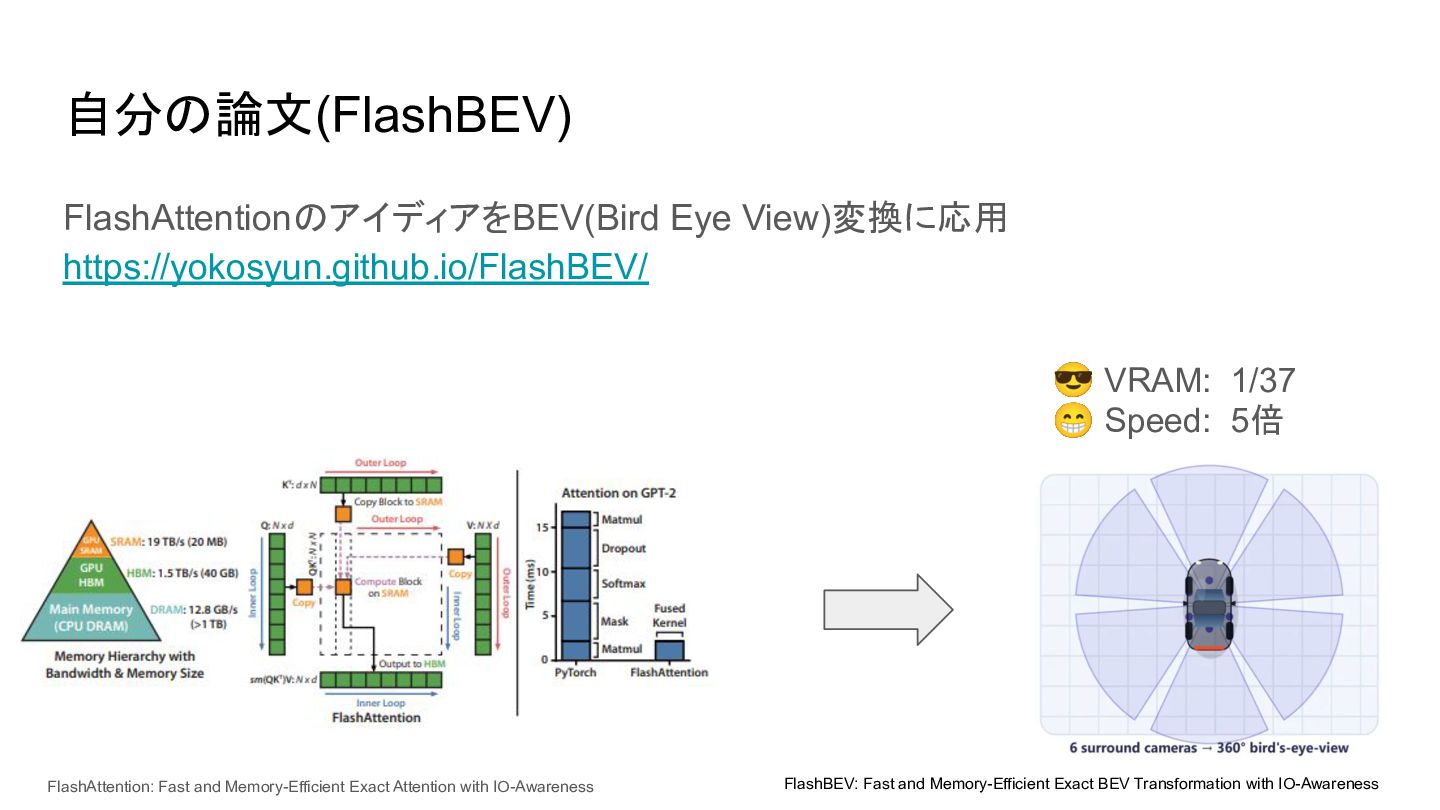
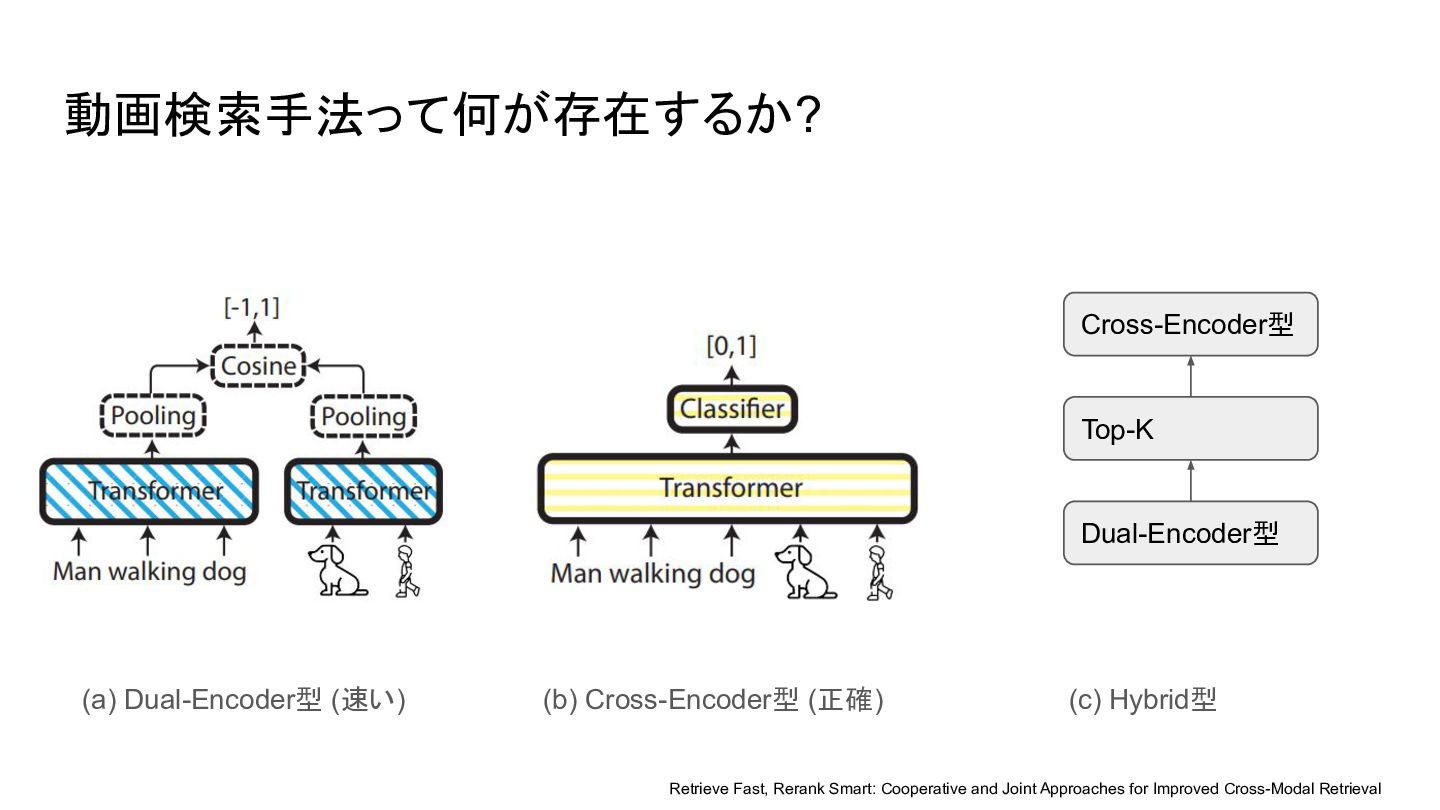
5倍 FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness FlashBEV: Fast and Memory-Efficient Exact BEV Transformation with IO-Awareness
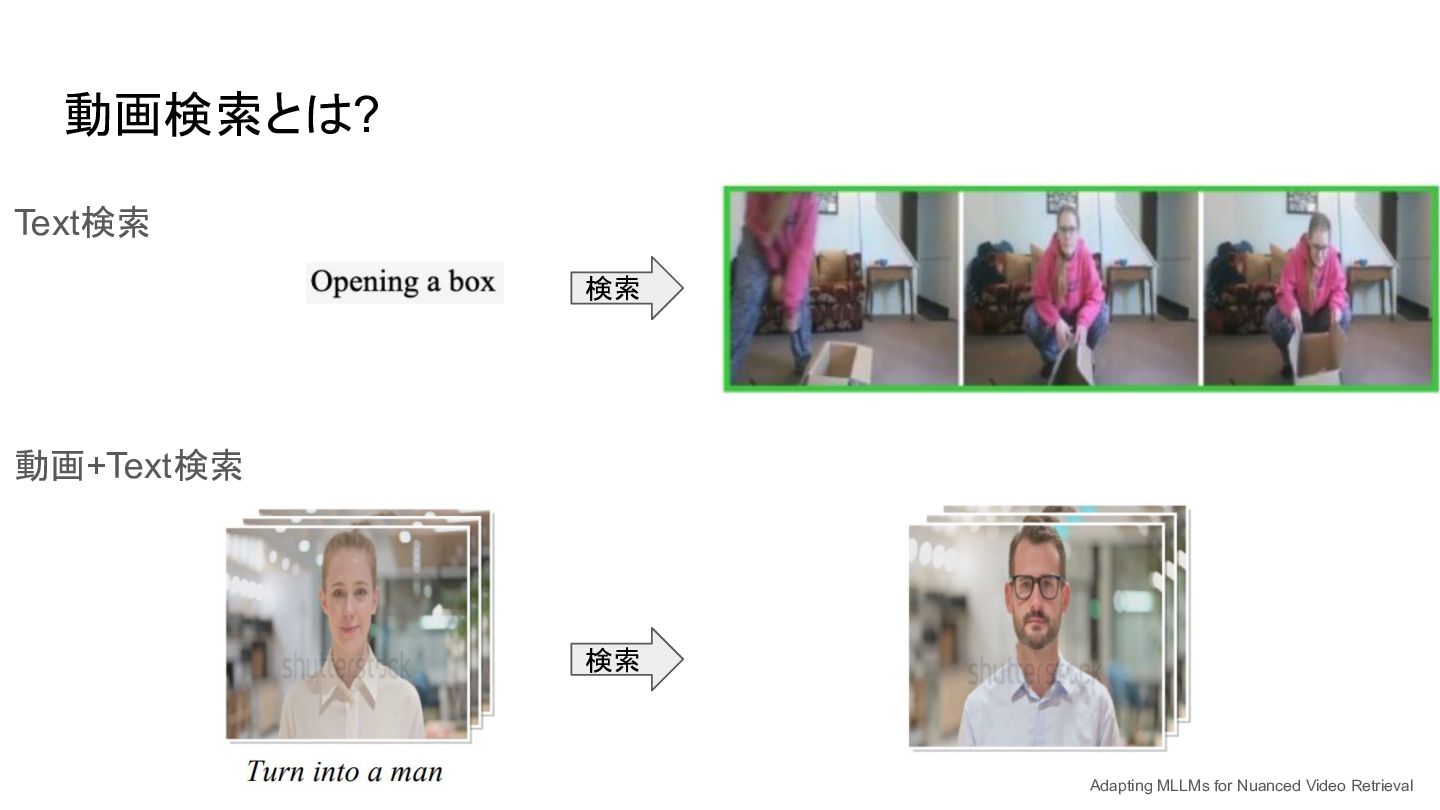
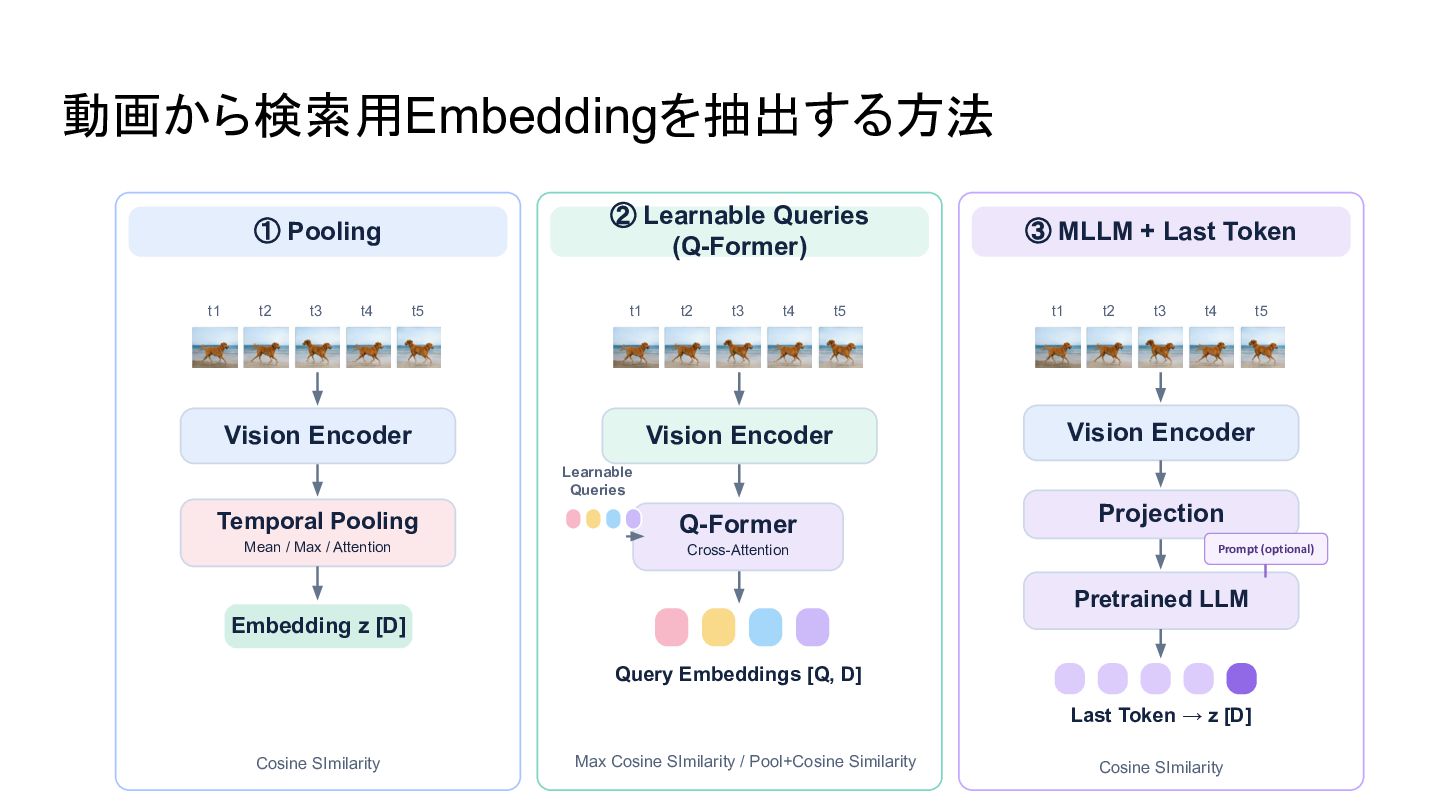
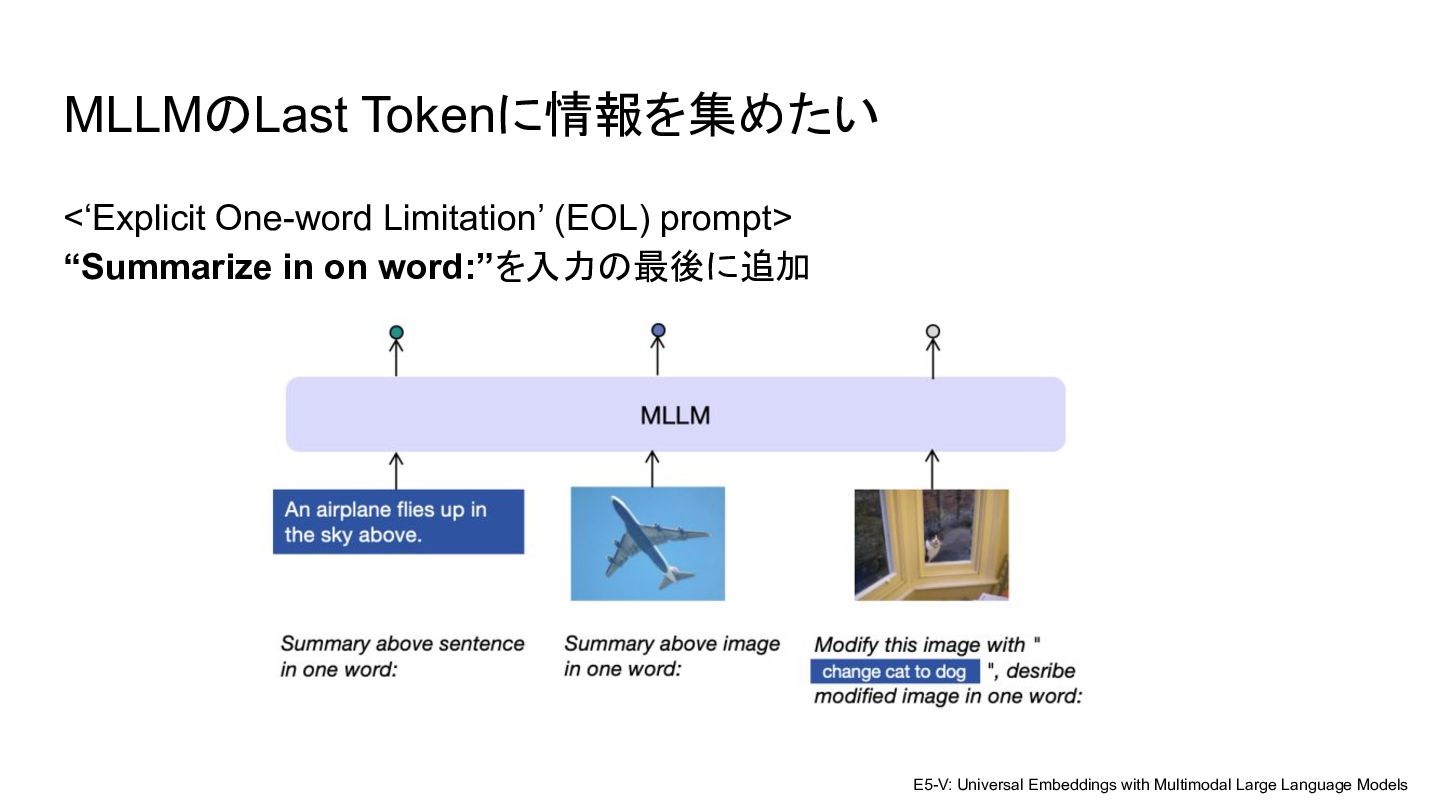
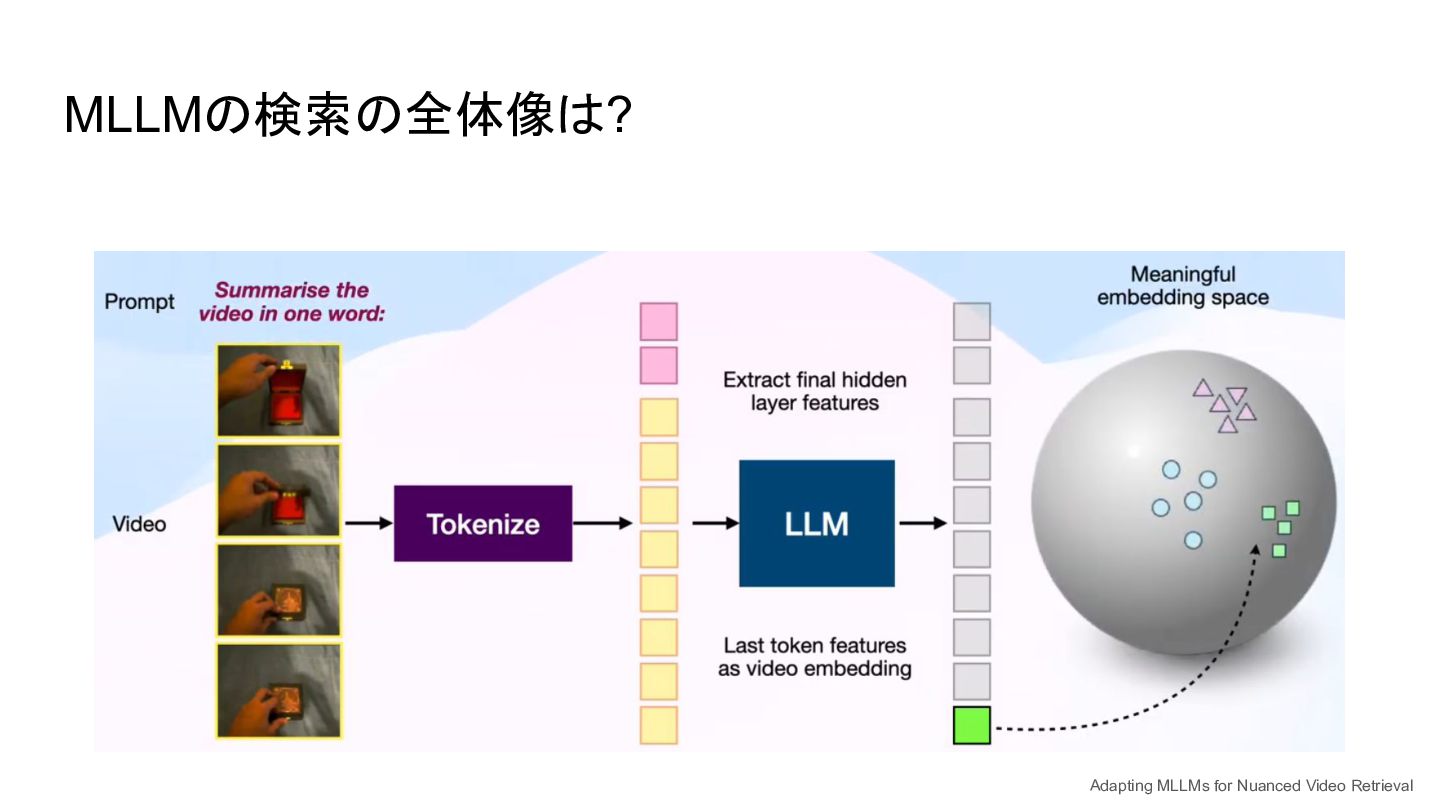
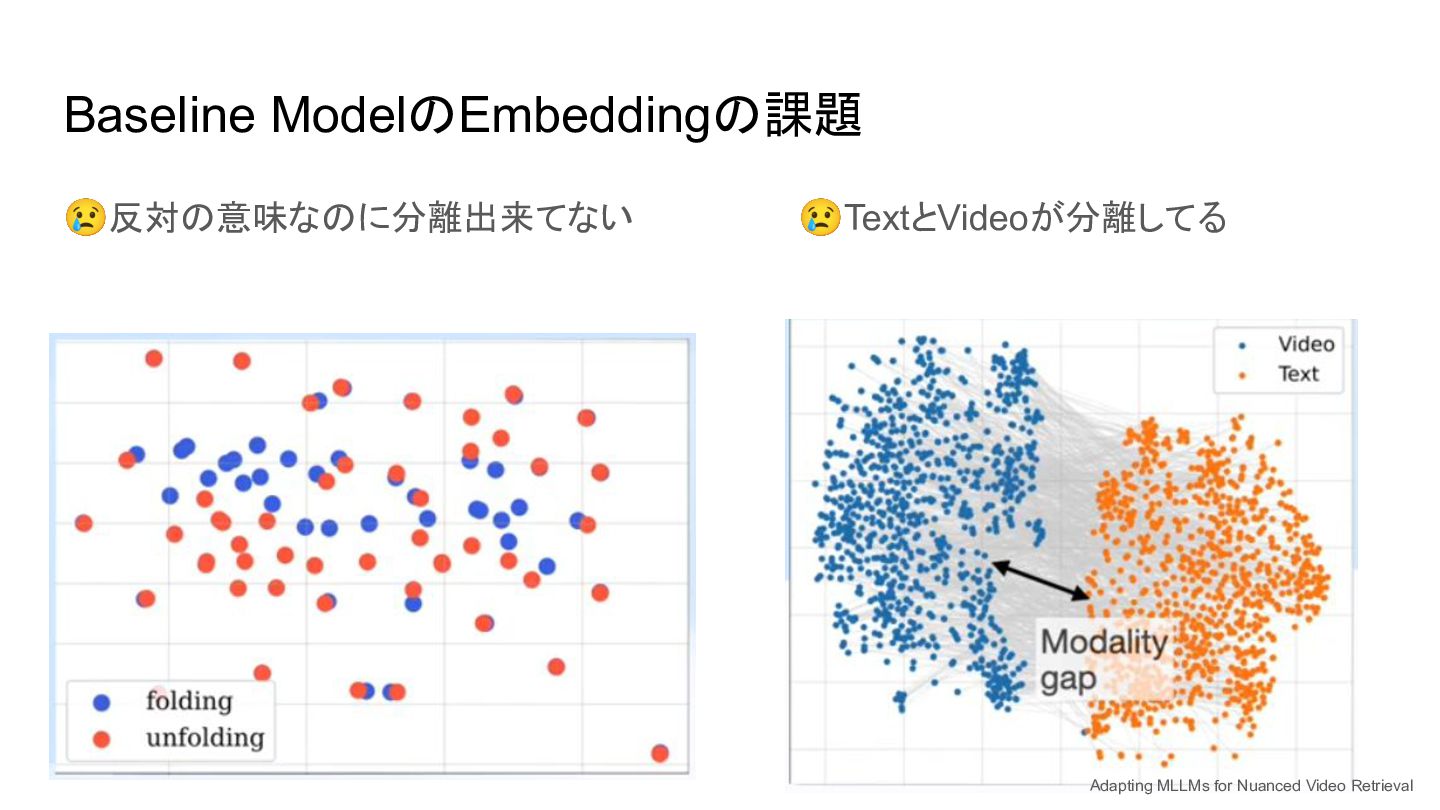
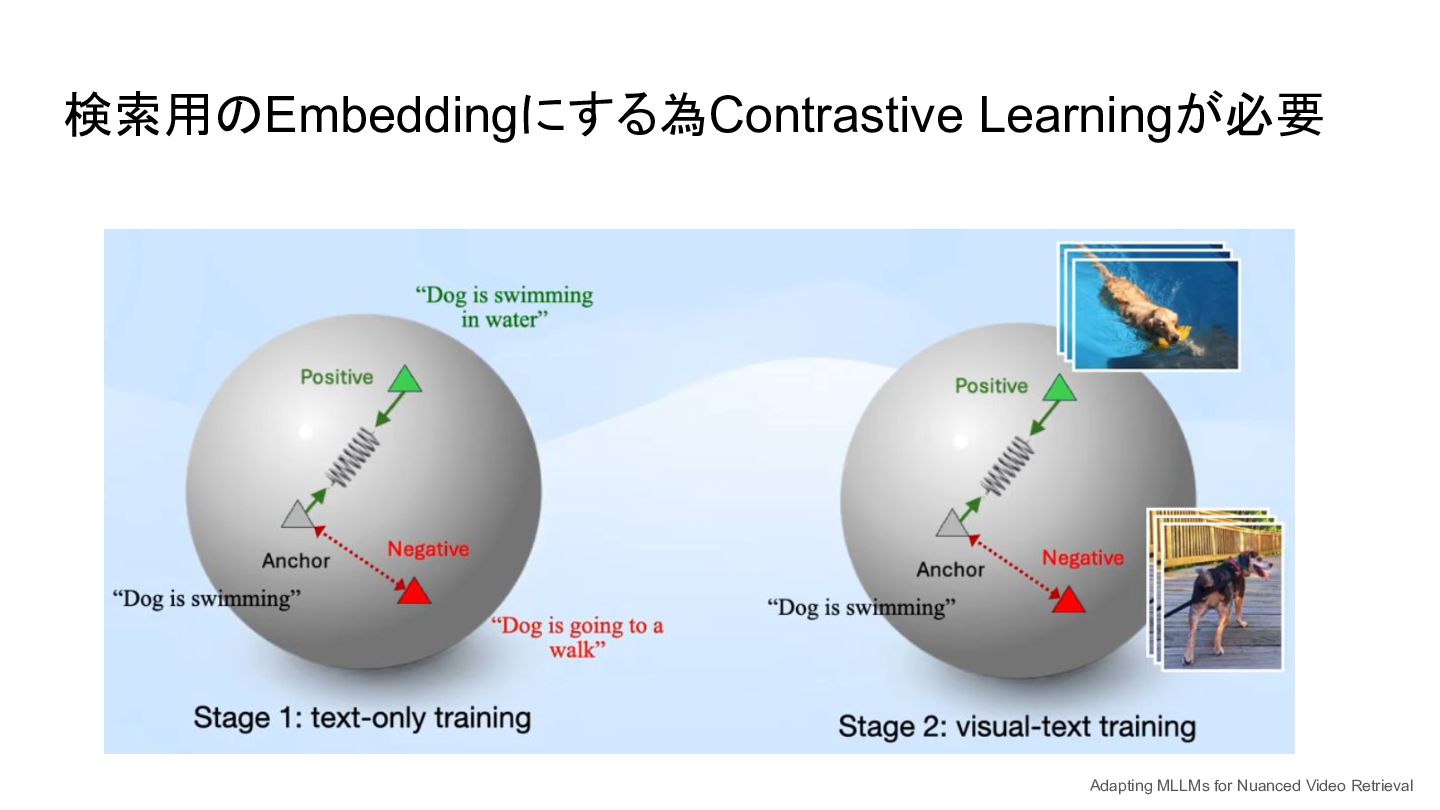
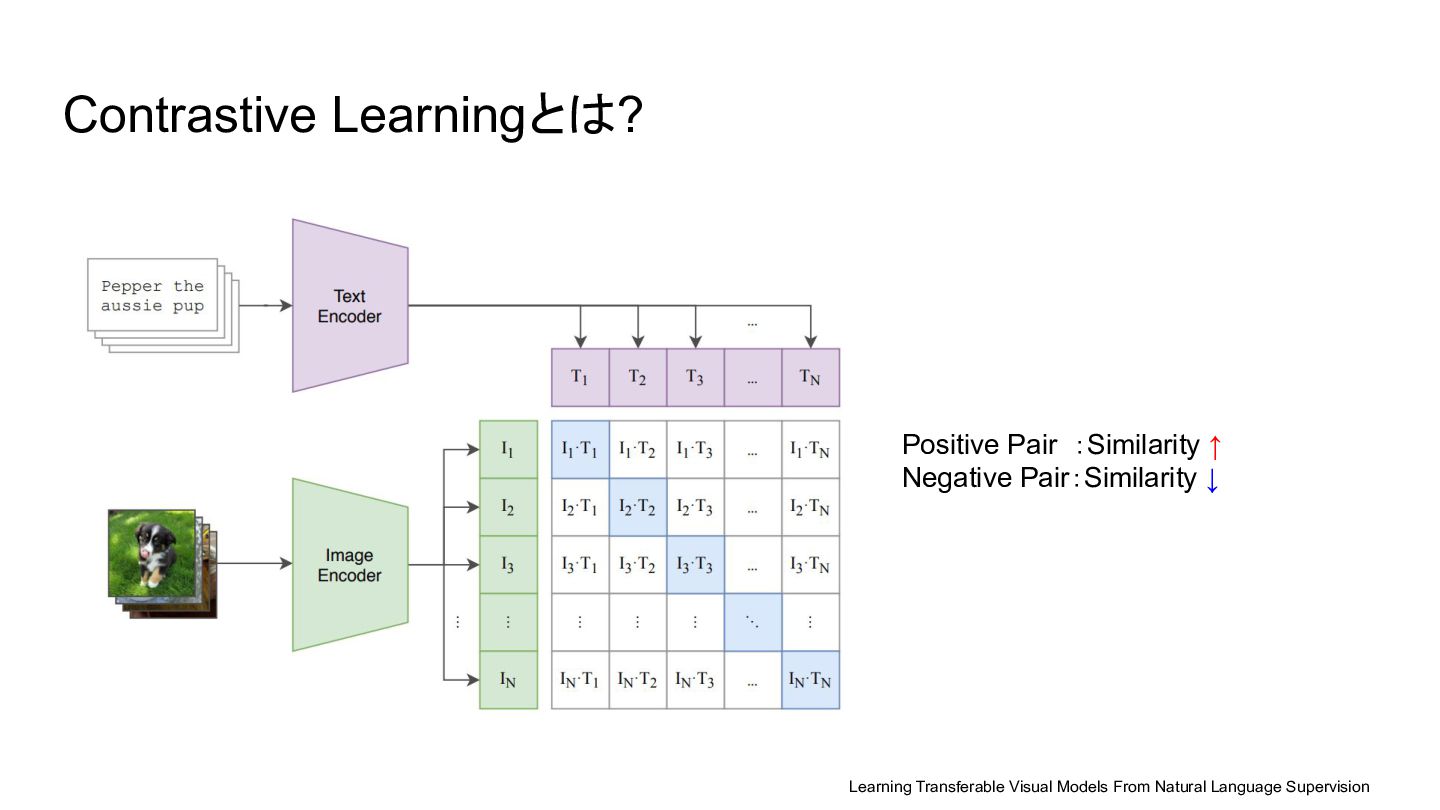
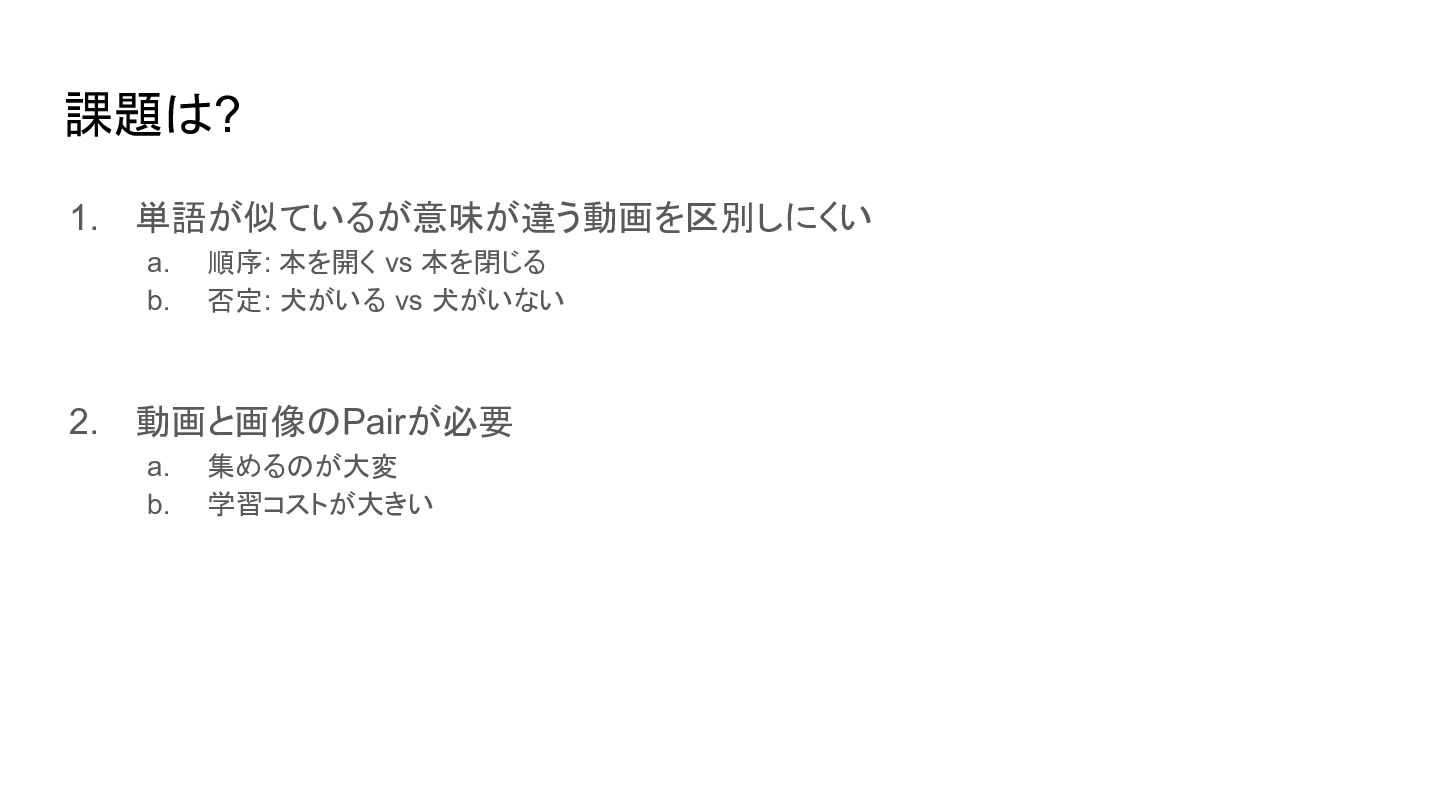
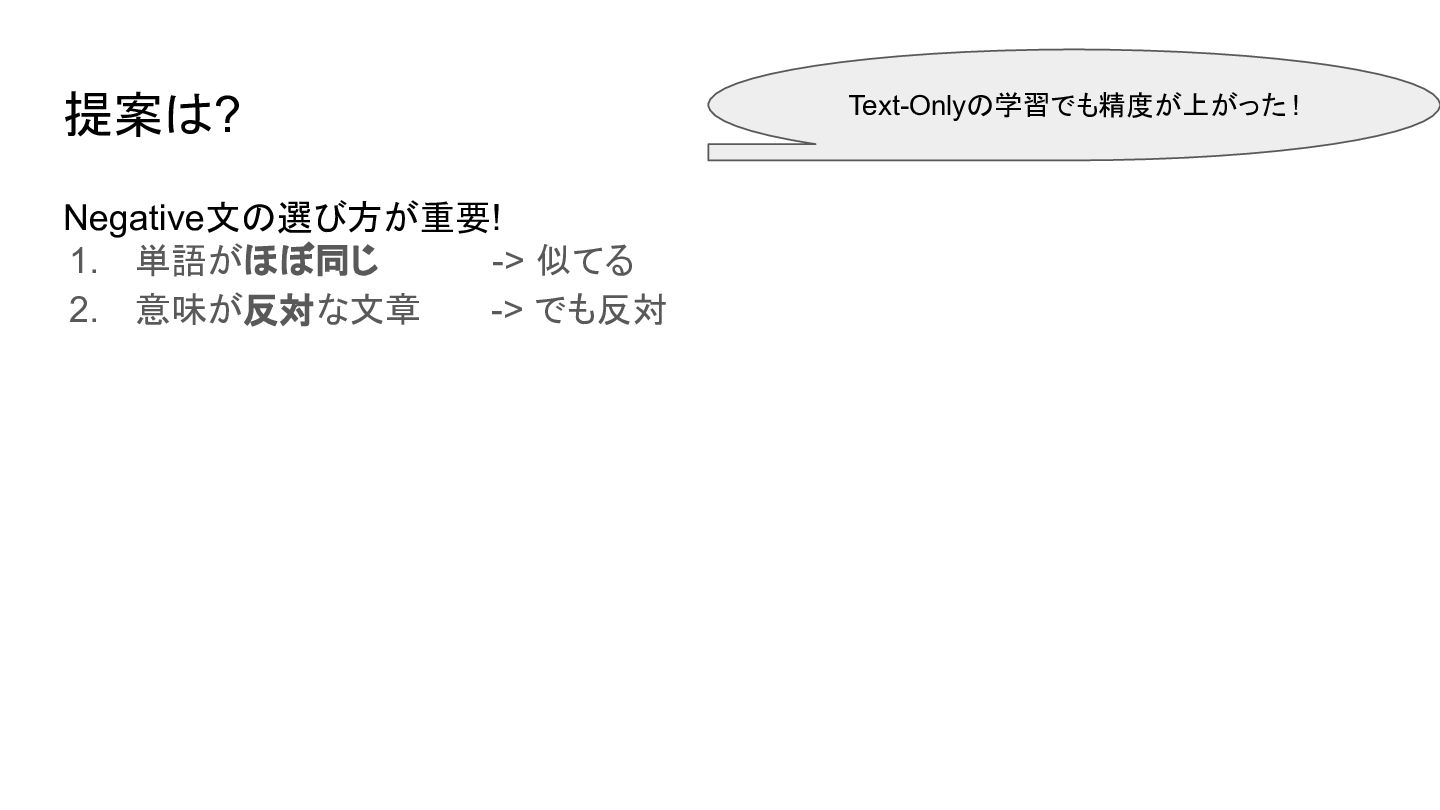
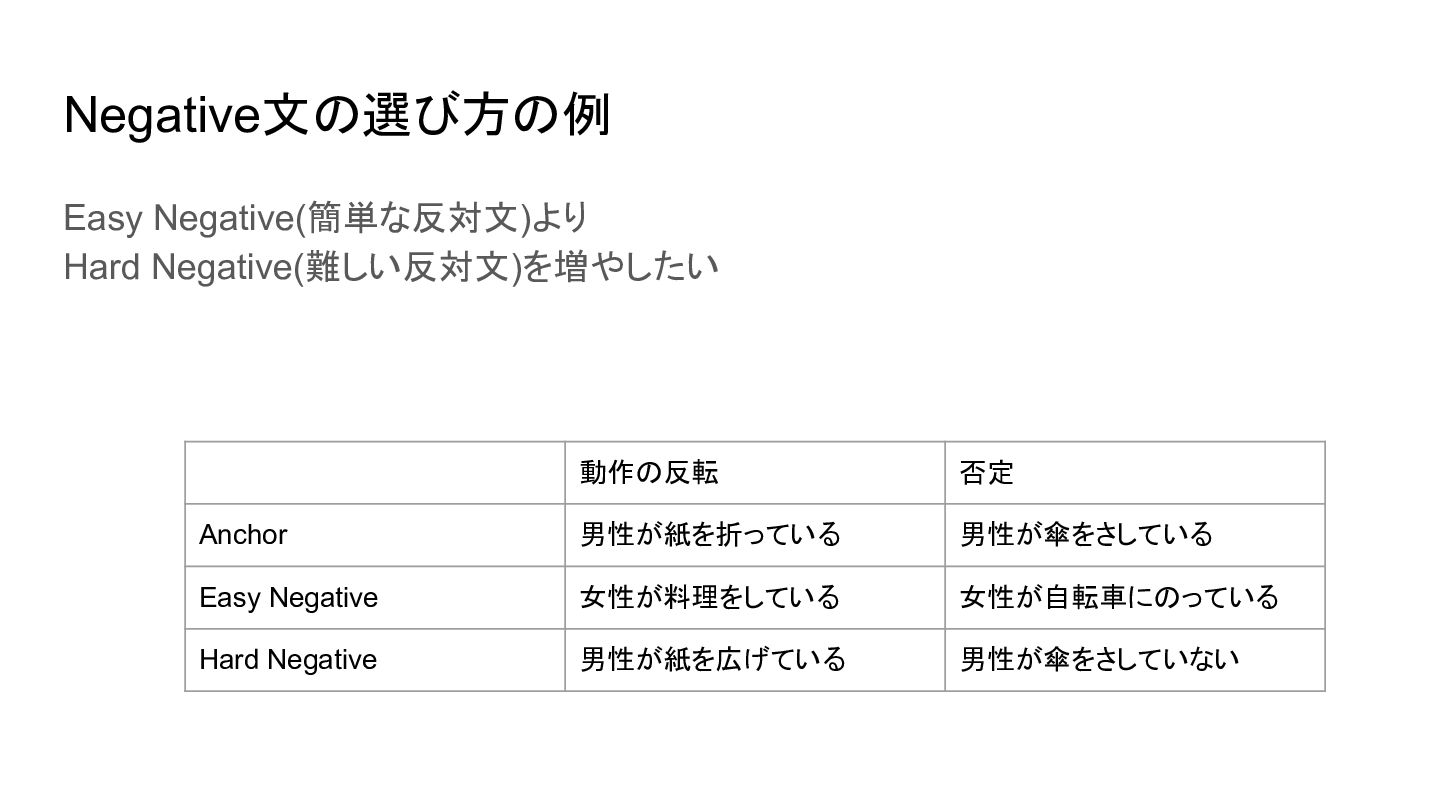
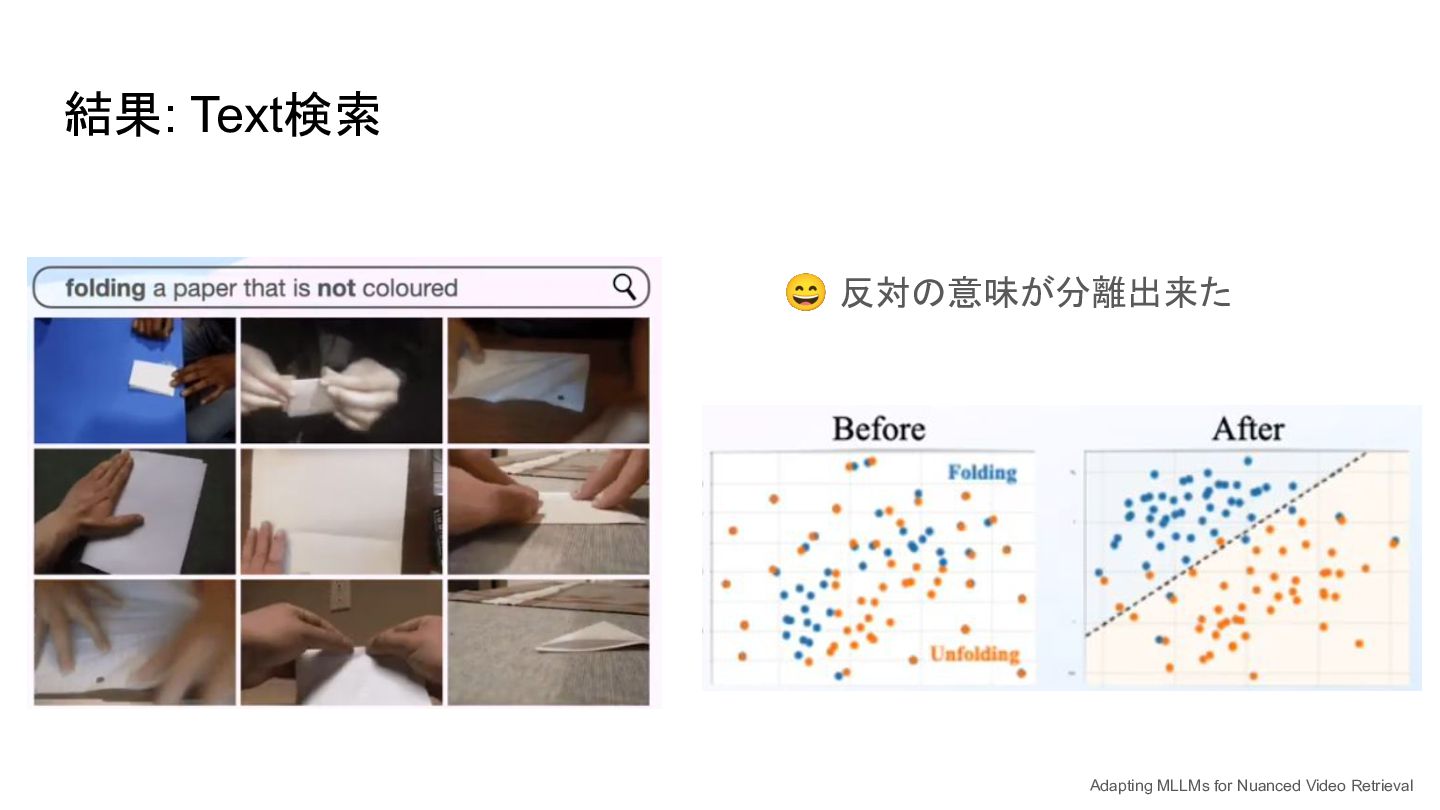
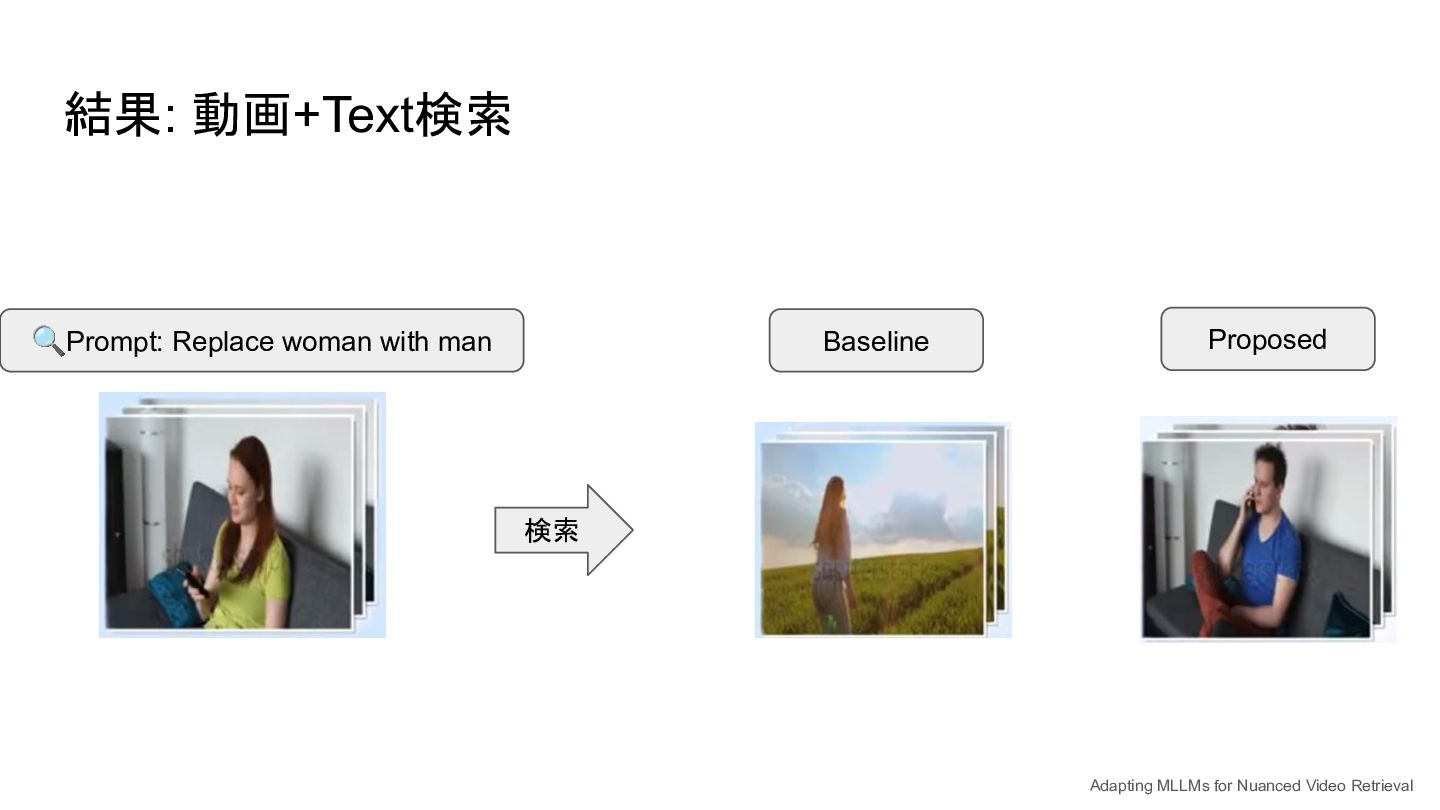
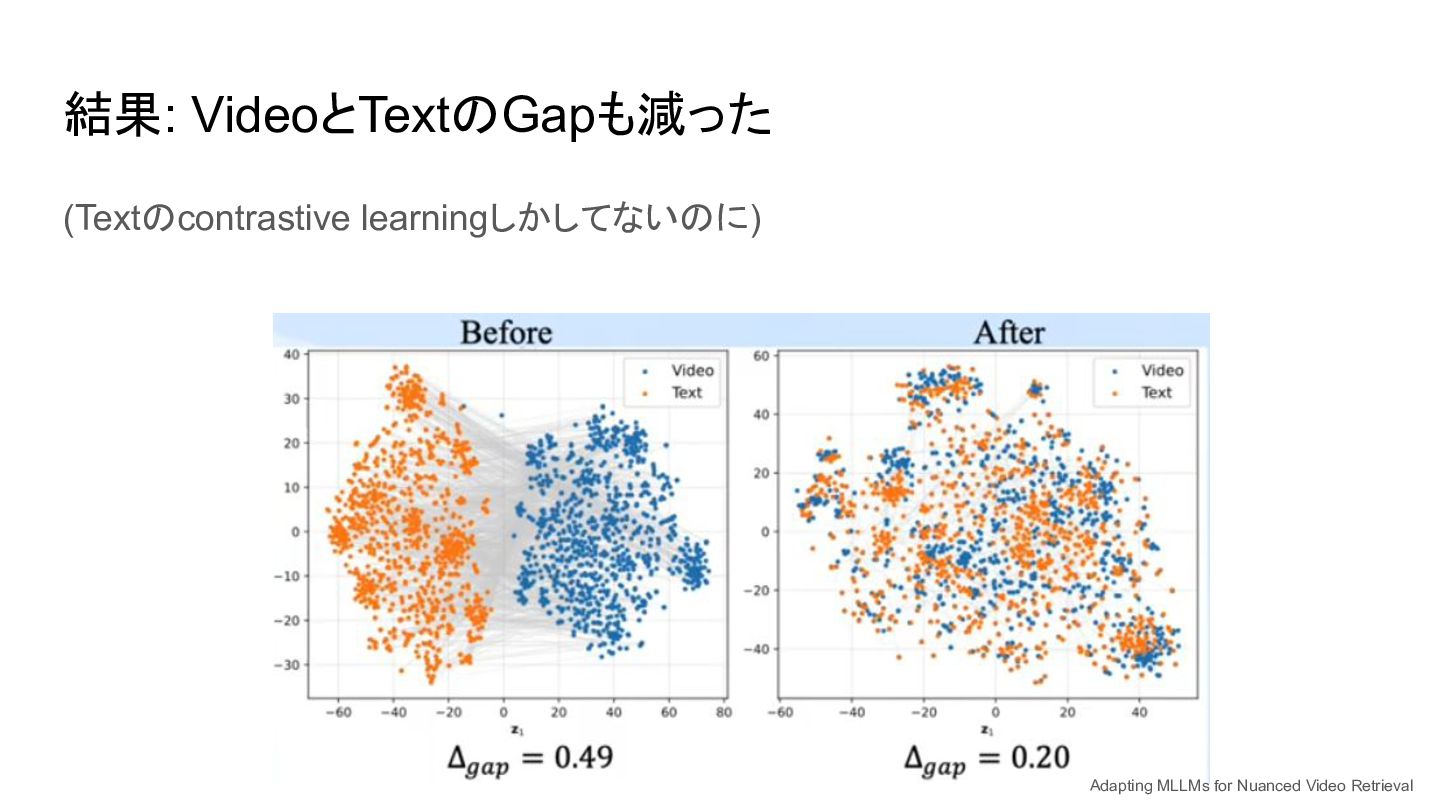
Fast and Memory-Efficient Exact BEV Transformation with IO-Awareness Register Any Point: Scaling 3D Point Cloud Registration by Flow Matching Adapting MLLMs for Nuanced Video Retrieval Visual Instruction Tuning(LLaVA) Tarsier2: Advancing Large Vision-Language Models from Detailed Video Description to Comprehensive Video Understanding Mind the Gap: Understanding the Modality Gap in Multi-modal Contrastive Representation Learning BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models E5-V: Universal Embeddings with Multimodal Large Language Models(EOL Prompting)


 kento1109
 tattaka
 de9uch1
 institutdelelevage
 pman0214
 yumaichikawa
 imai448
 koide3
 pomcho555
 mickey_0226
 kobayashi31
 helmedeiros
 akosma
 seathinner
 addyosmani
 ipullrank
 baasie
 schlessera
 tomoyanonymous
 katiecoart
 rocio
 soudai
 matthewcrist