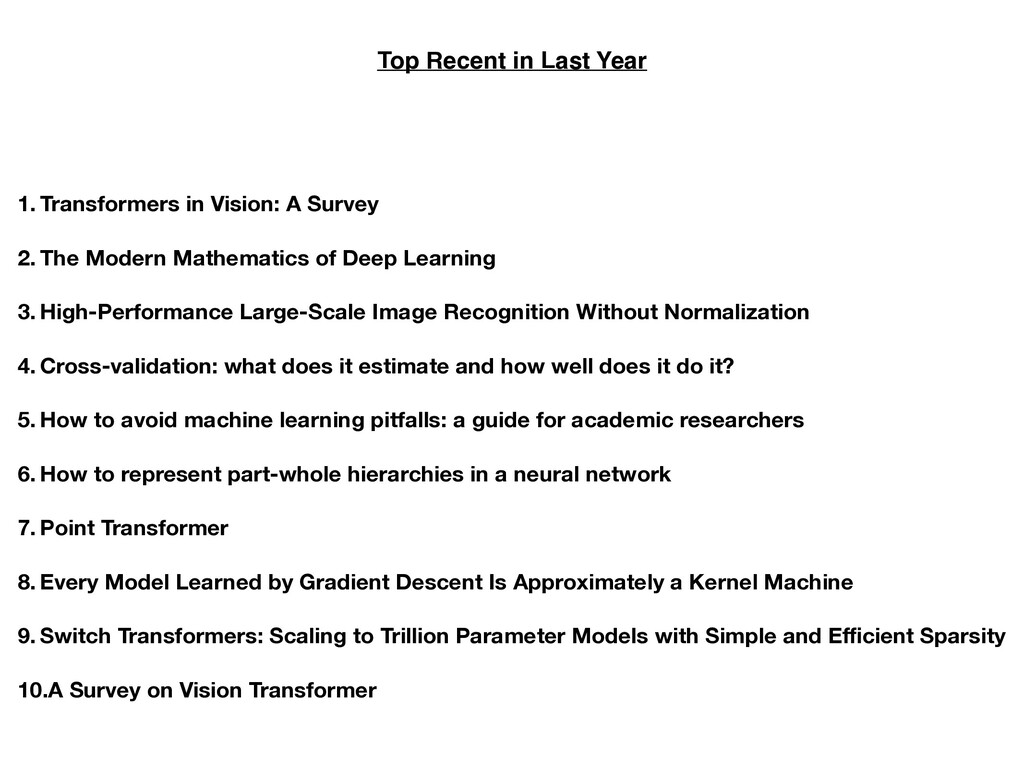
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E ff i cient Sparsity 10.A Survey on Vision Transformer
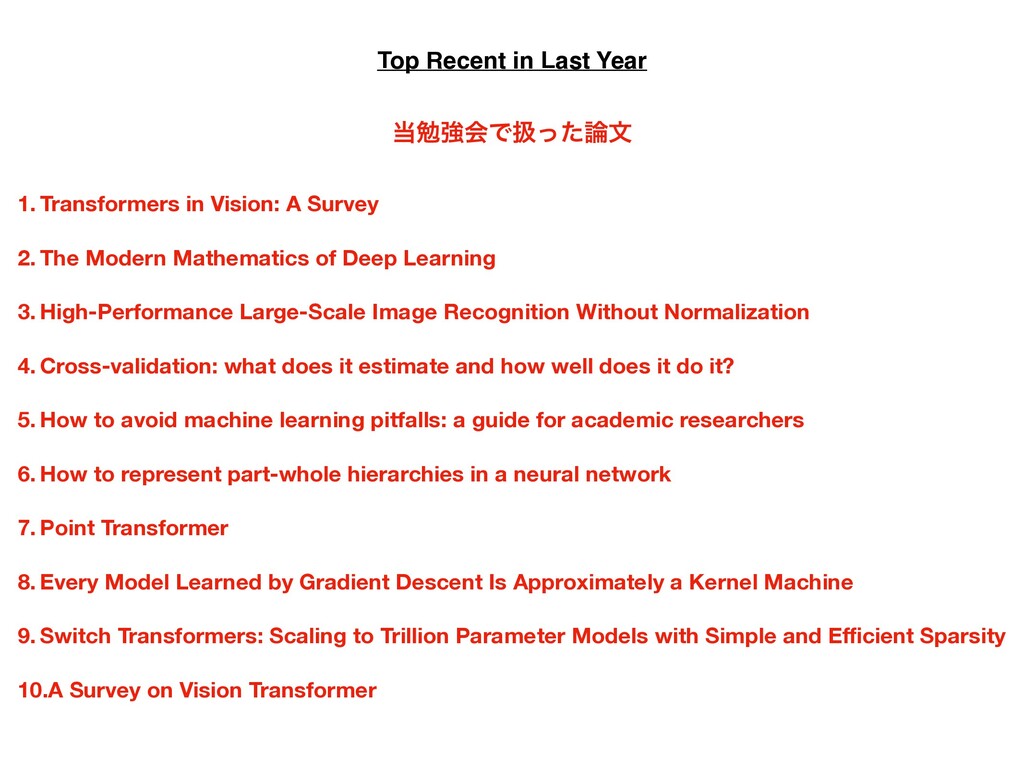
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E ff i cient Sparsity 10.A Survey on Vision Transformer ษڧձͰѻͬͨจ
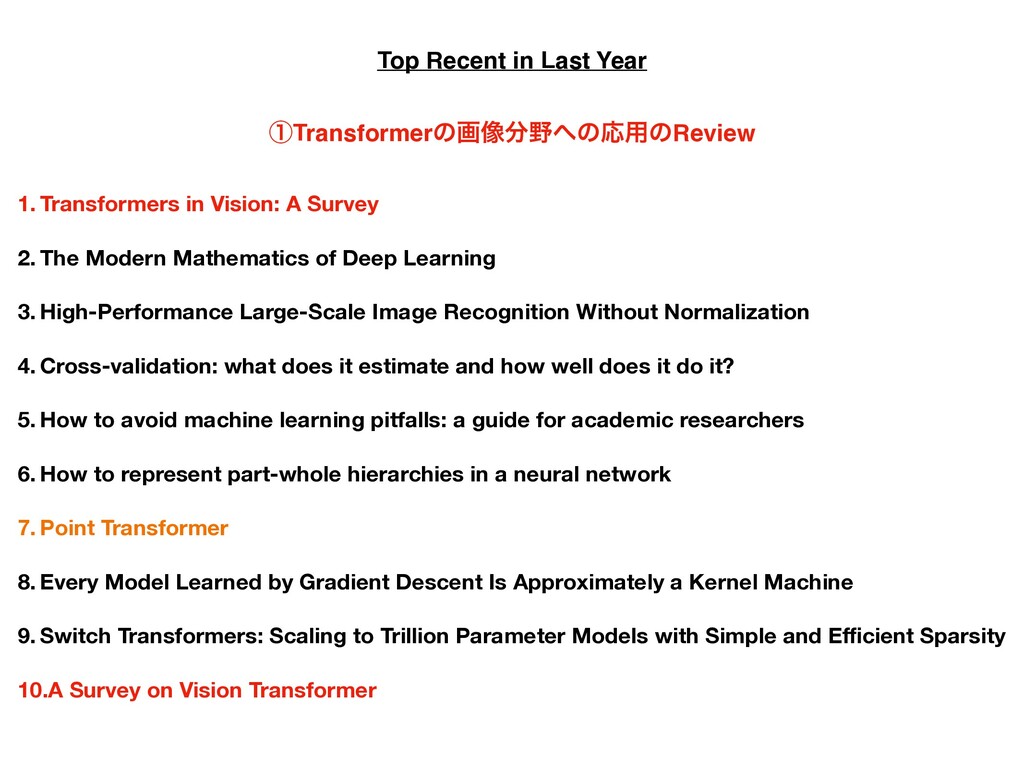
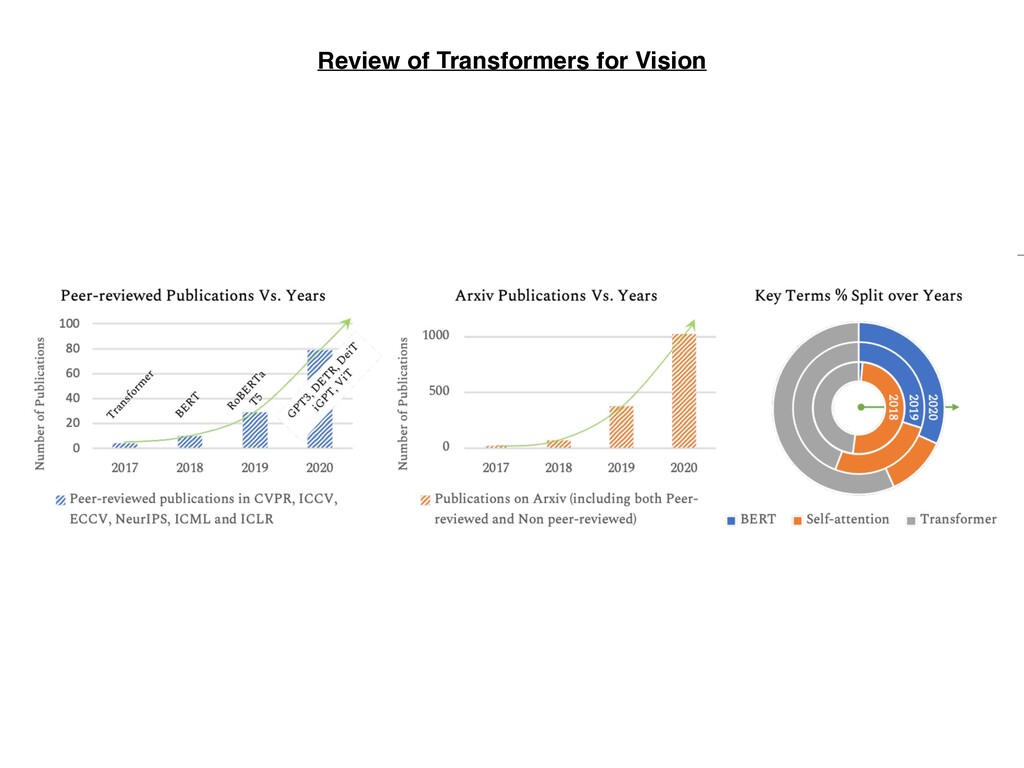
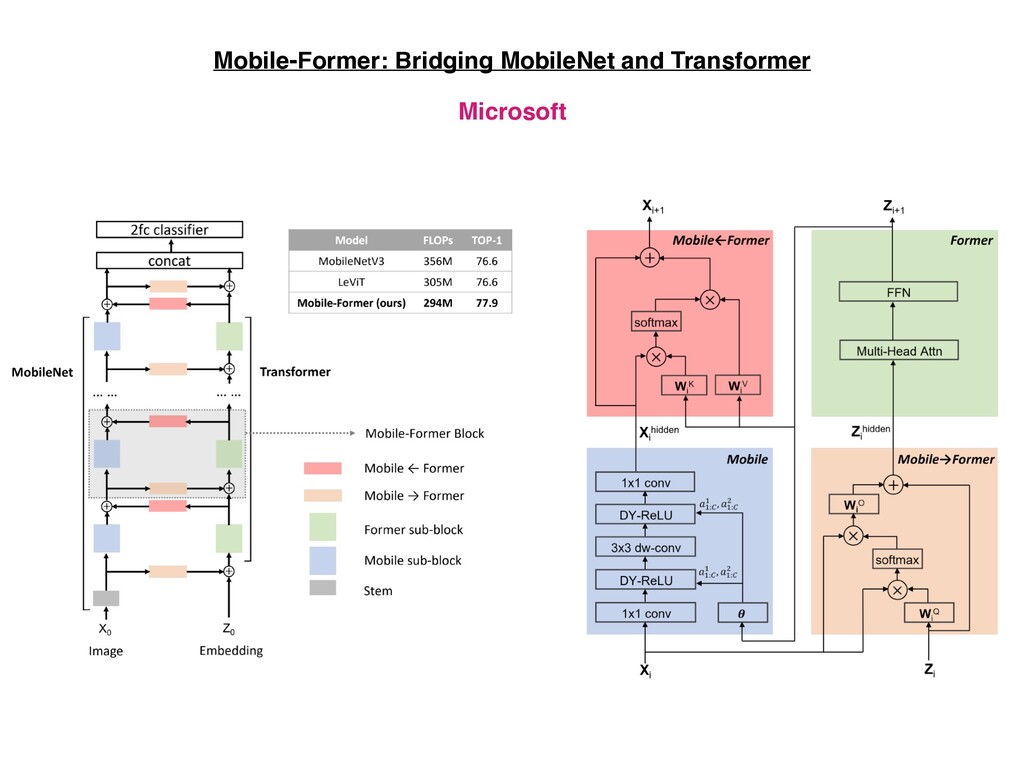
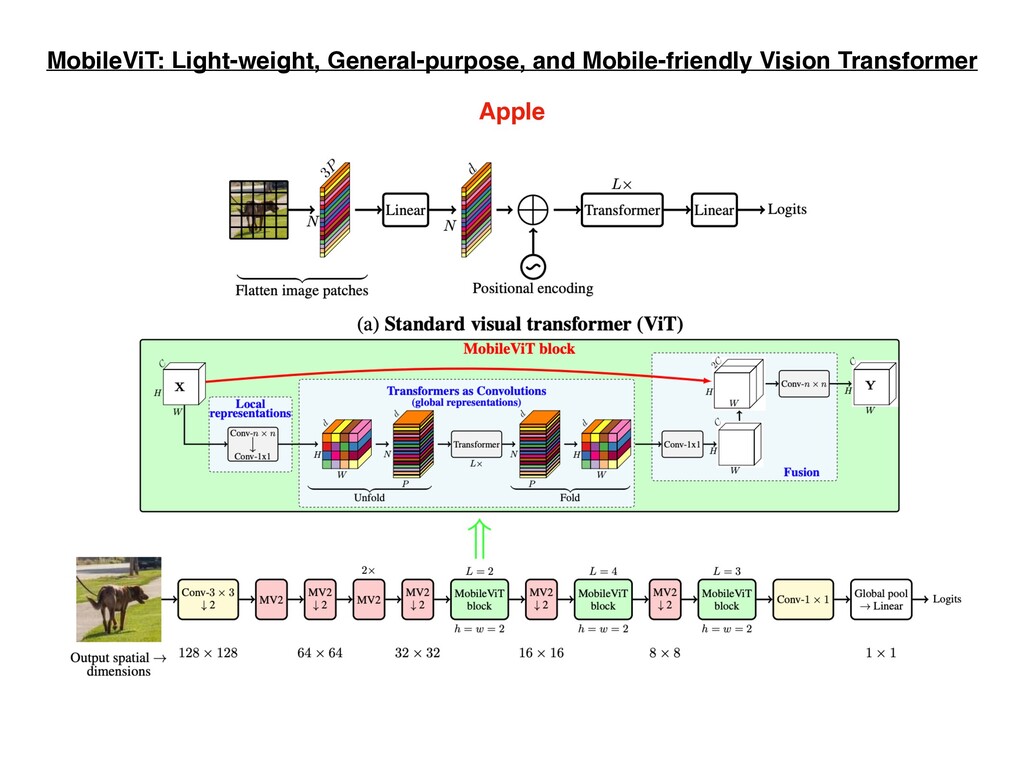
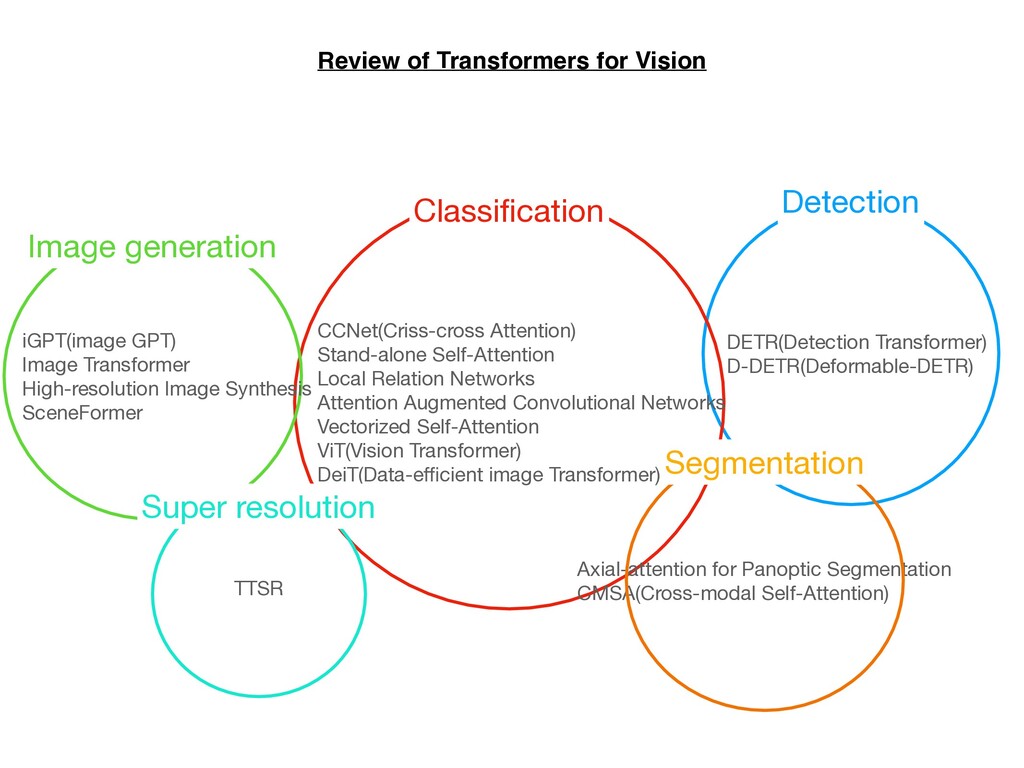
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E ff i cient Sparsity 10.A Survey on Vision Transformer ᶃTransformerͷը૾ͷԠ༻ͷReview
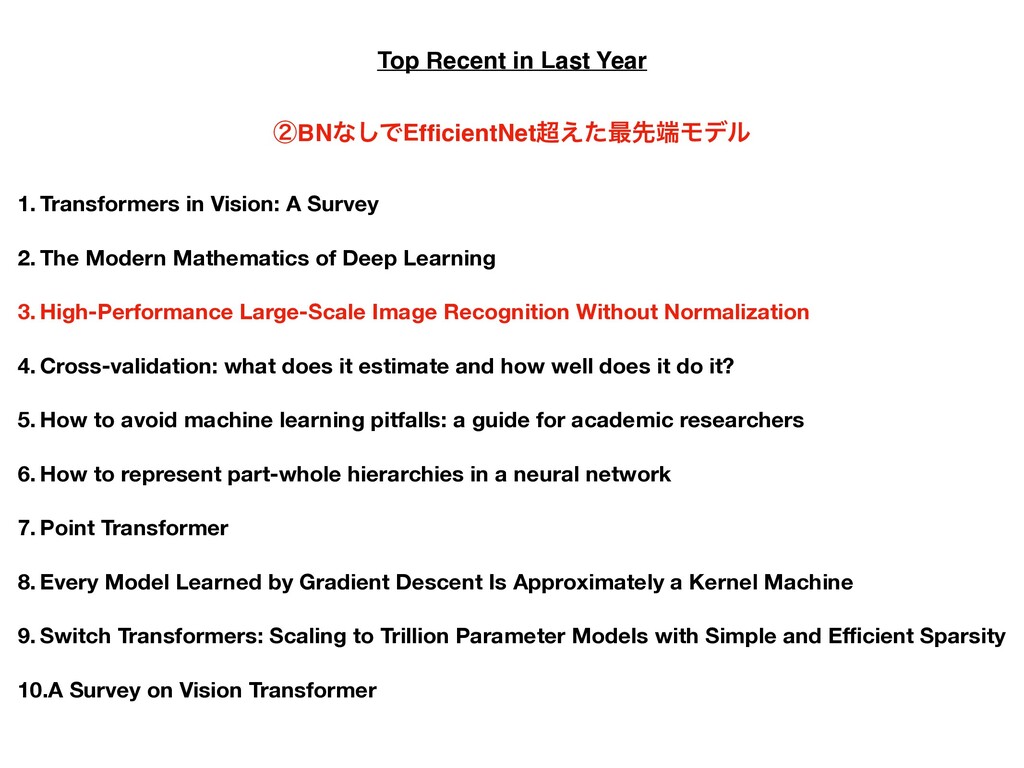
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E ff i cient Sparsity 10.A Survey on Vision Transformer ᶄBNͳ͠ͰEf fi cientNet͑ͨ࠷ઌϞσϧ
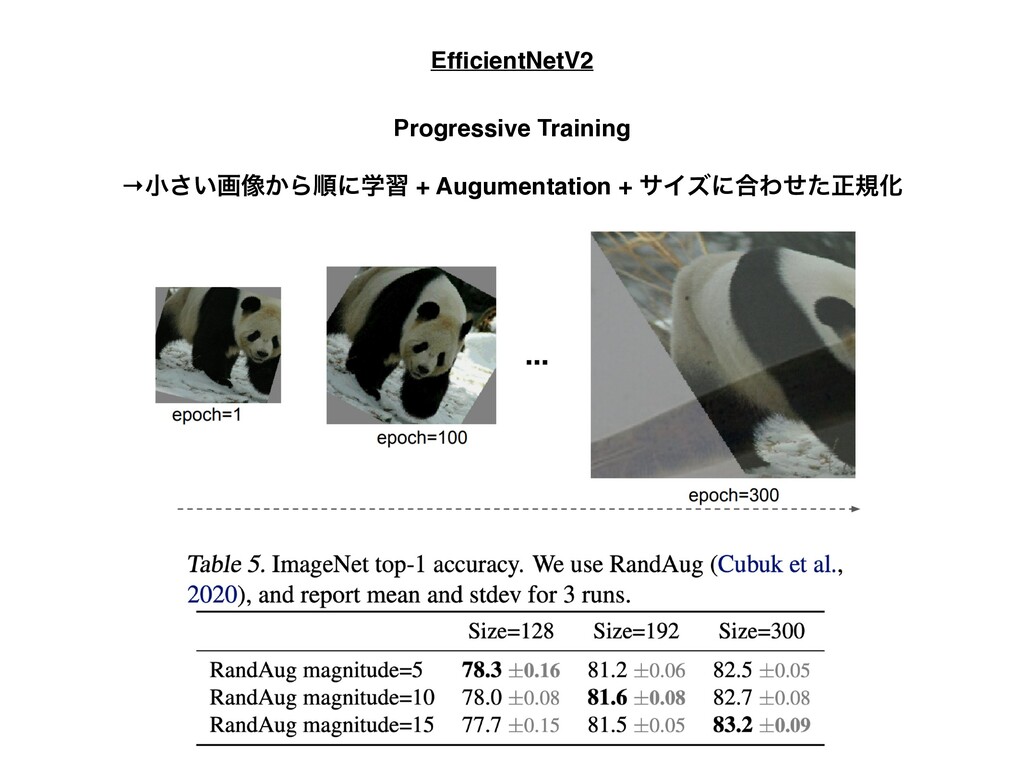
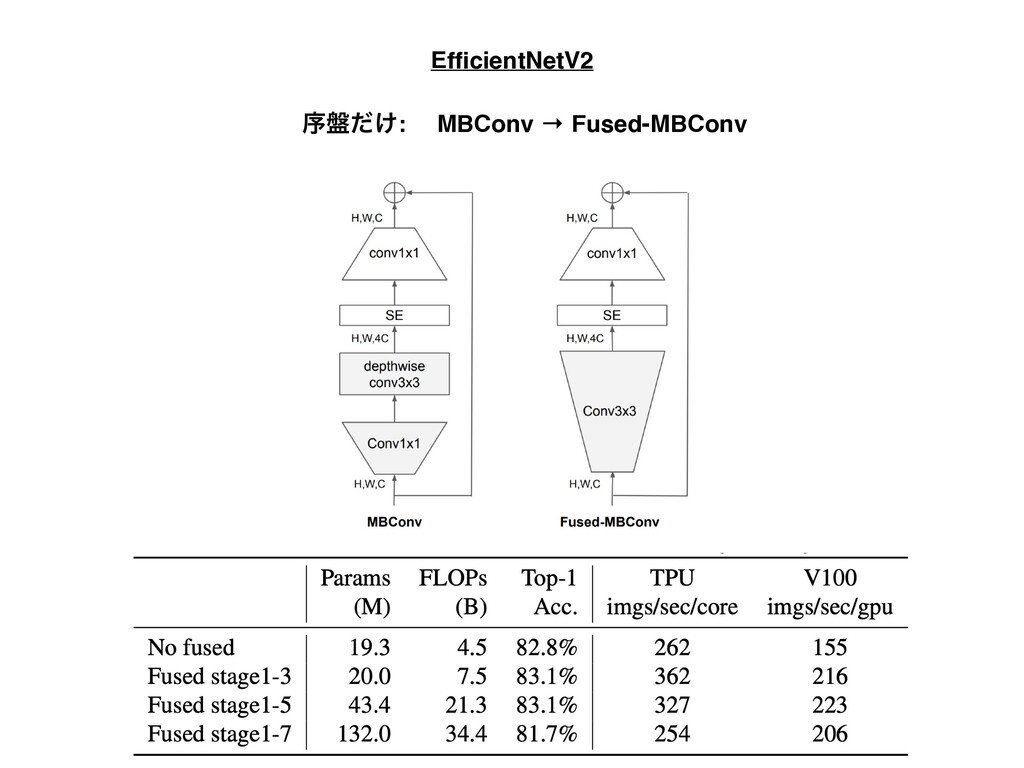
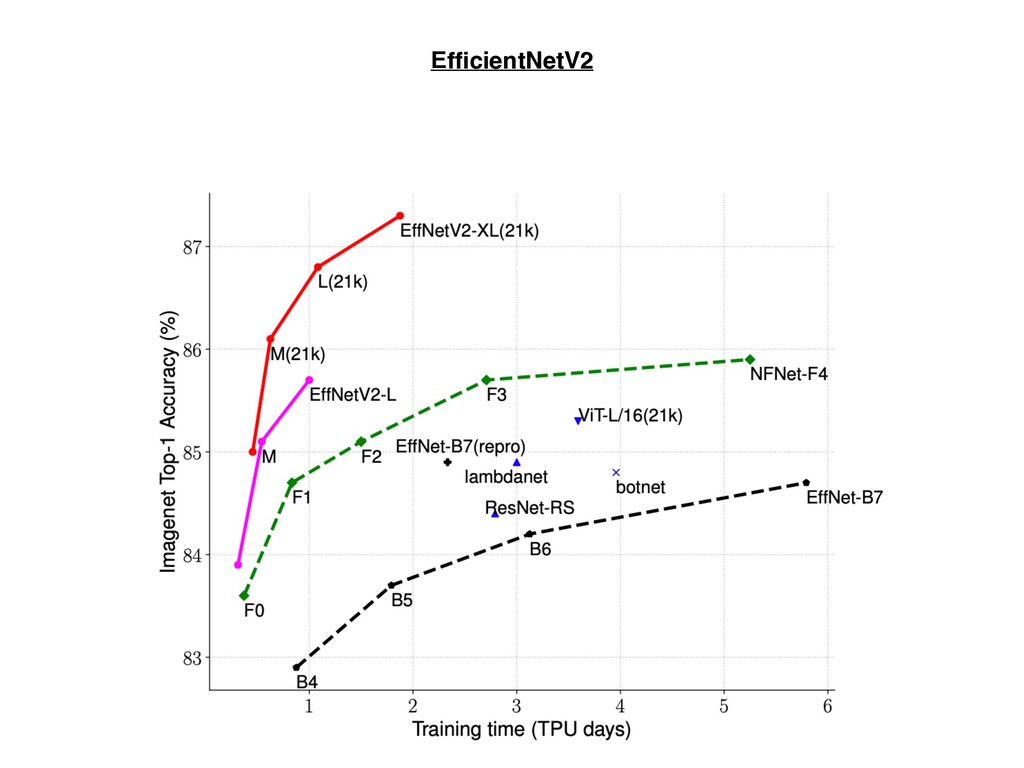
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E fi cientNet͑ͨ࠷ઌϞσϧ E ffi cientNetV2: Smaller Models and Faster Training ᶄ͞ΒʹͦΕΛ͑ͨEf fi cientNetV2
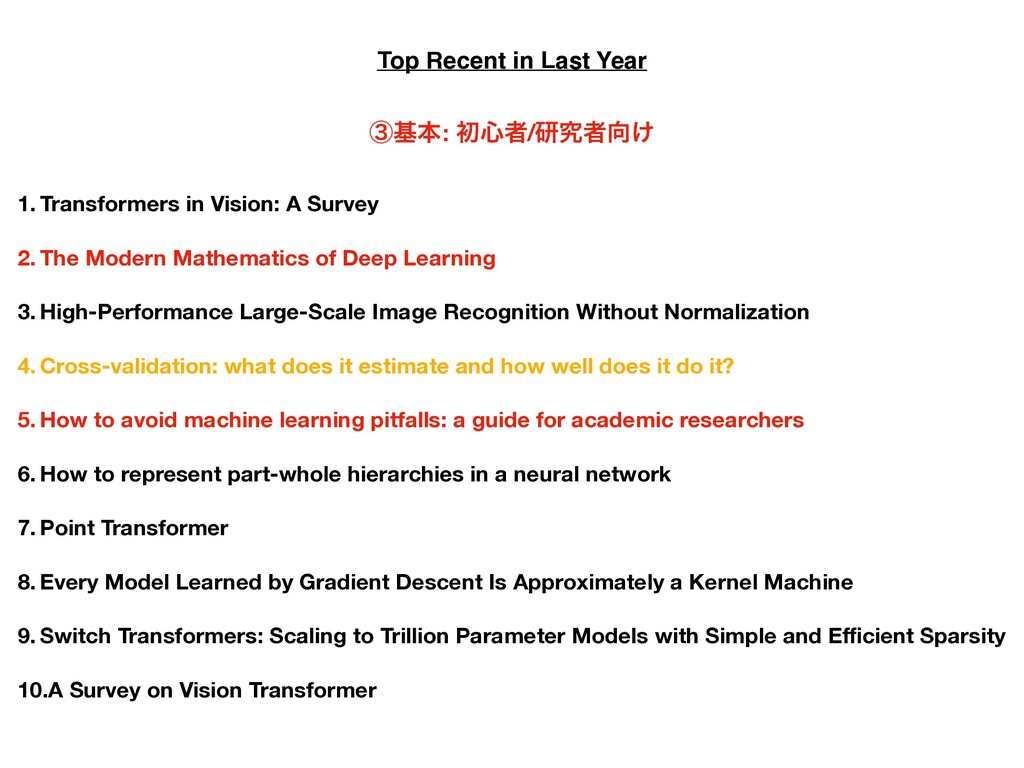
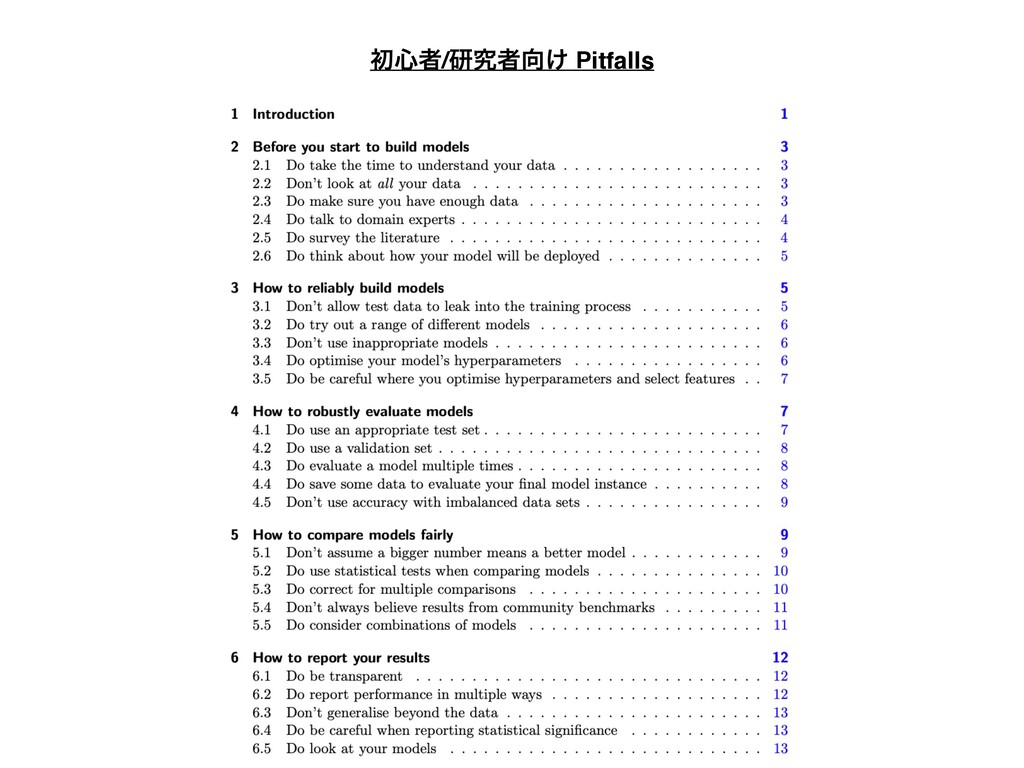
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E ff i cient Sparsity 10.A Survey on Vision Transformer ᶅجຊ: ॳ৺ऀ/ݚڀऀ͚
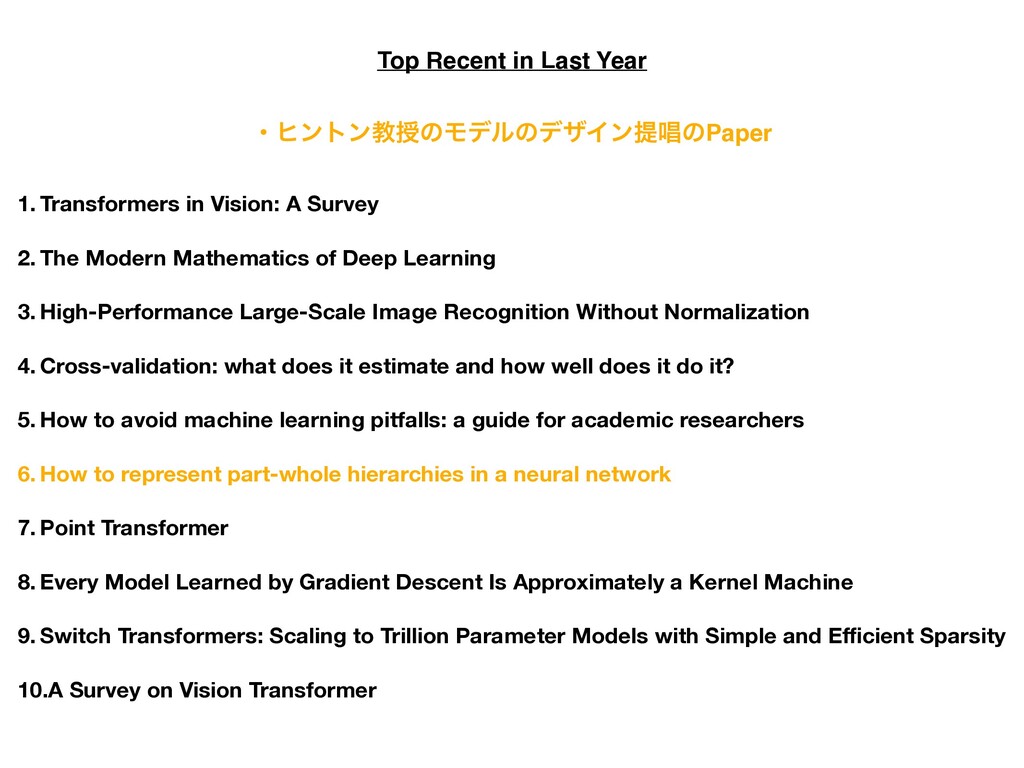
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E ff i cient Sparsity 10.A Survey on Vision Transformer ɾώϯτϯڭतͷϞσϧͷσβΠϯఏএͷPaper
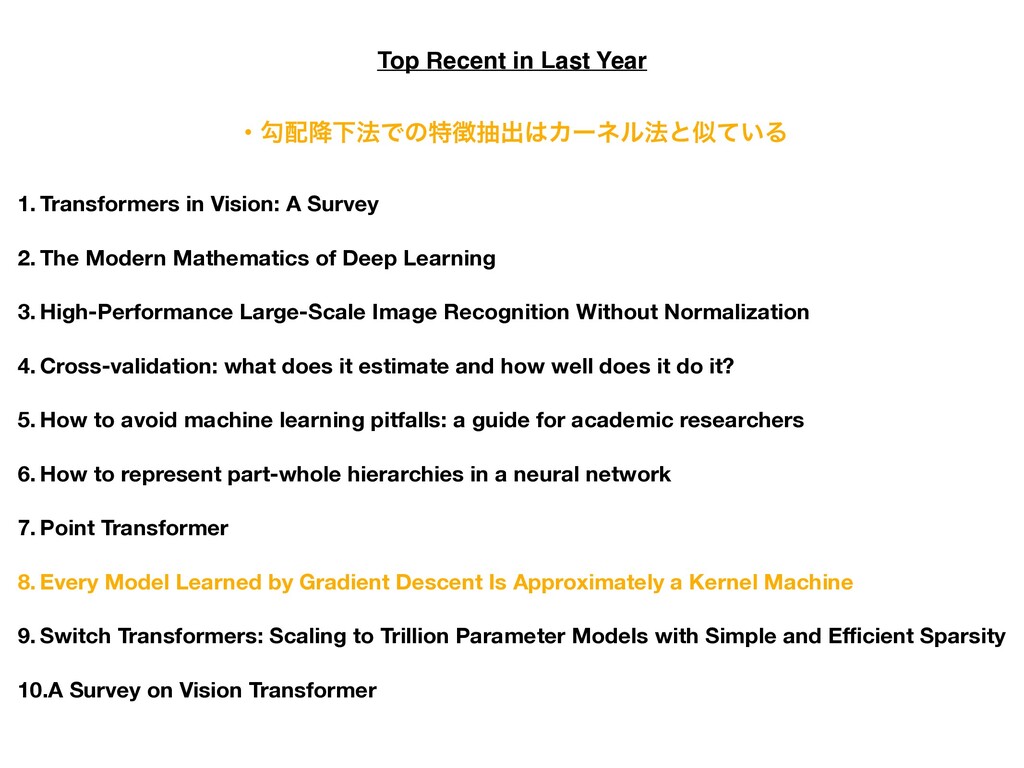
Survey 2. The Modern Mathematics of Deep Learning 3. High-Performance Large-Scale Image Recognition Without Normalization 4. Cross-validation: what does it estimate and how well does it do it? 5. How to avoid machine learning pitfalls: a guide for academic researchers 6. How to represent part-whole hierarchies in a neural network 7. Point Transformer 8. Every Model Learned by Gradient Descent Is Approximately a Kernel Machine 9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and E ff i cient Sparsity 10.A Survey on Vision Transformer ɾޯ߱Լ๏Ͱͷಛநग़Χʔωϧ๏ͱࣅ͍ͯΔ


 ailaboocu
 madhuri28
 hiola
 bunnchinn3
 rashwhitman
 kentaroy47
 signer
 baltimoreniso
 spring_aki
 mu7889yoon
 neuroiwm
 aleyda
 codingconduct
 morganepeng
 reverentgeek
 inesmontani
 honzajavorek
 mza
 axbom
 bcantrill
 frankvandijk
 uxyall