Share
Embed
SOC 4015 & SOC 5050 - Lecture 07
Lecture slides for Lecture 07 of the Saint Louis University Course Quantitative Analysis: Applied Inferential Statistics. These slides cover the topics related to difference of mean testing by hand.
Christopher Prener
October 08, 2018
Transcript
98 slides
-
DIFFERENCE OF MEANS (PART 1) QUANTITATIVE ANALYSIS CHRISTOPHER PRENER, PH.D.
FALL 2018 WEEK 07 LECTURE 07 -
AGENDA QUANTITATIVE ANALYSIS / WEEK 07 / LECTURE 07 1.
Front Matter 2. Revisiting Distributions 3. One Sample 4. Independent Samples 5. Dependent Samples 6. Effect Sizes 7. Back Matter -
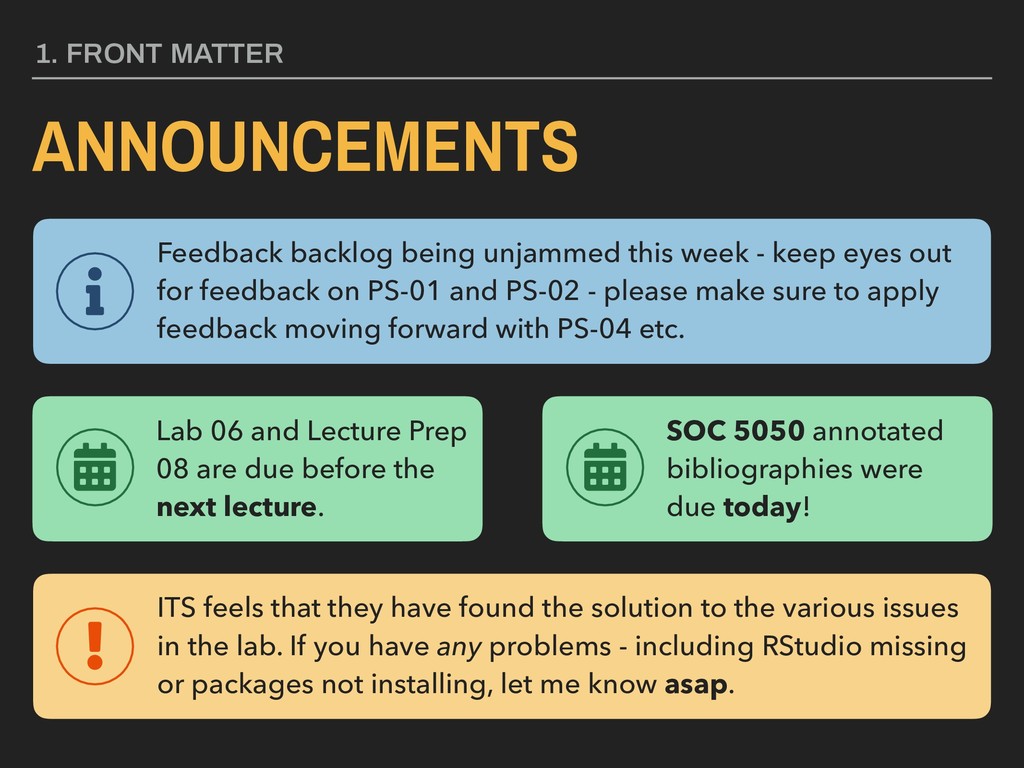
1. FRONT MATTER ANNOUNCEMENTS ITS feels that they have found
the solution to the various issues in the lab. If you have any problems - including RStudio missing or packages not installing, let me know asap. SOC 5050 annotated bibliographies were due today! Lab 06 and Lecture Prep 08 are due before the next lecture. Feedback backlog being unjammed this week - keep eyes out for feedback on PS-01 and PS-02 - please make sure to apply feedback moving forward with PS-04 etc. -
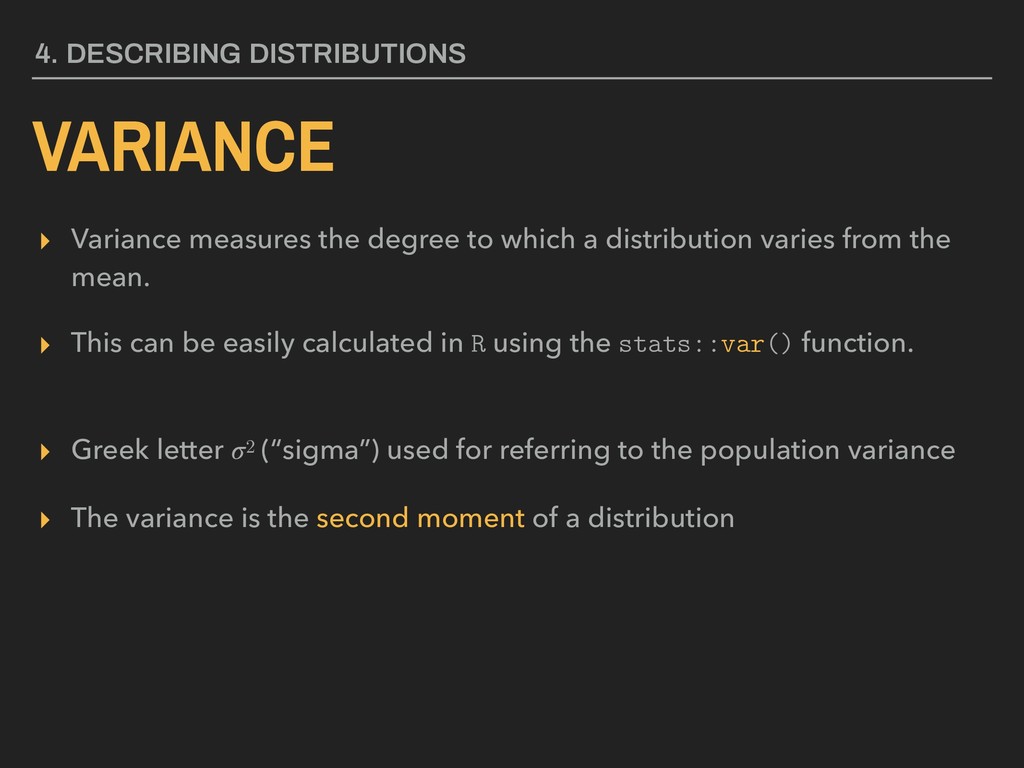
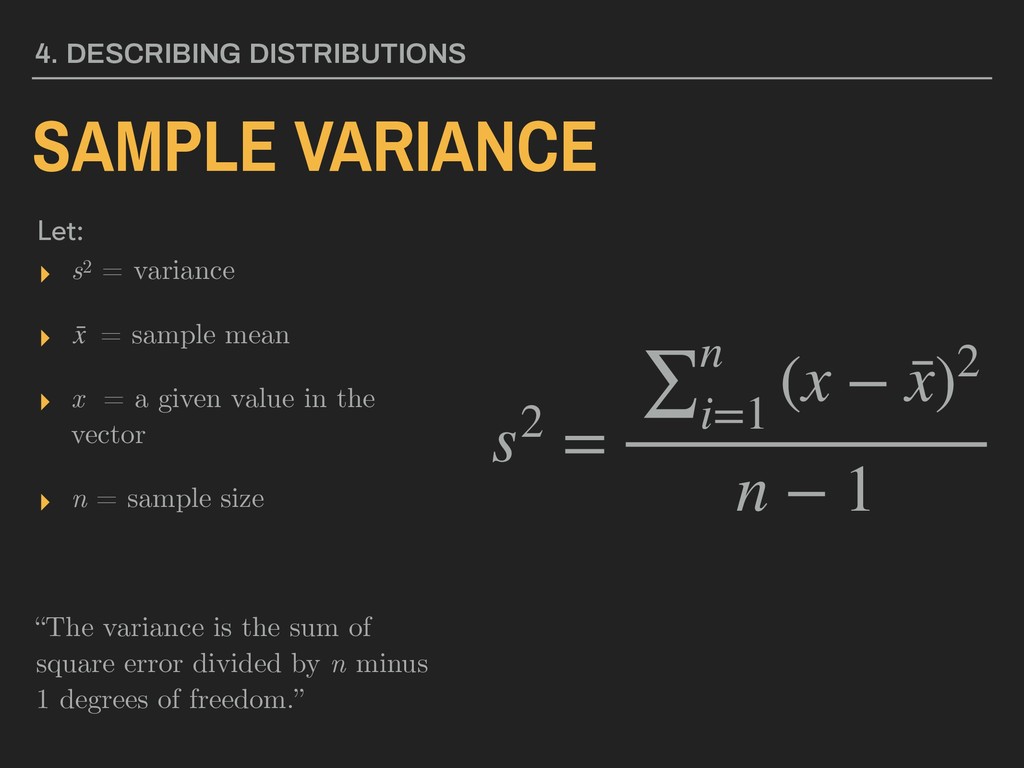
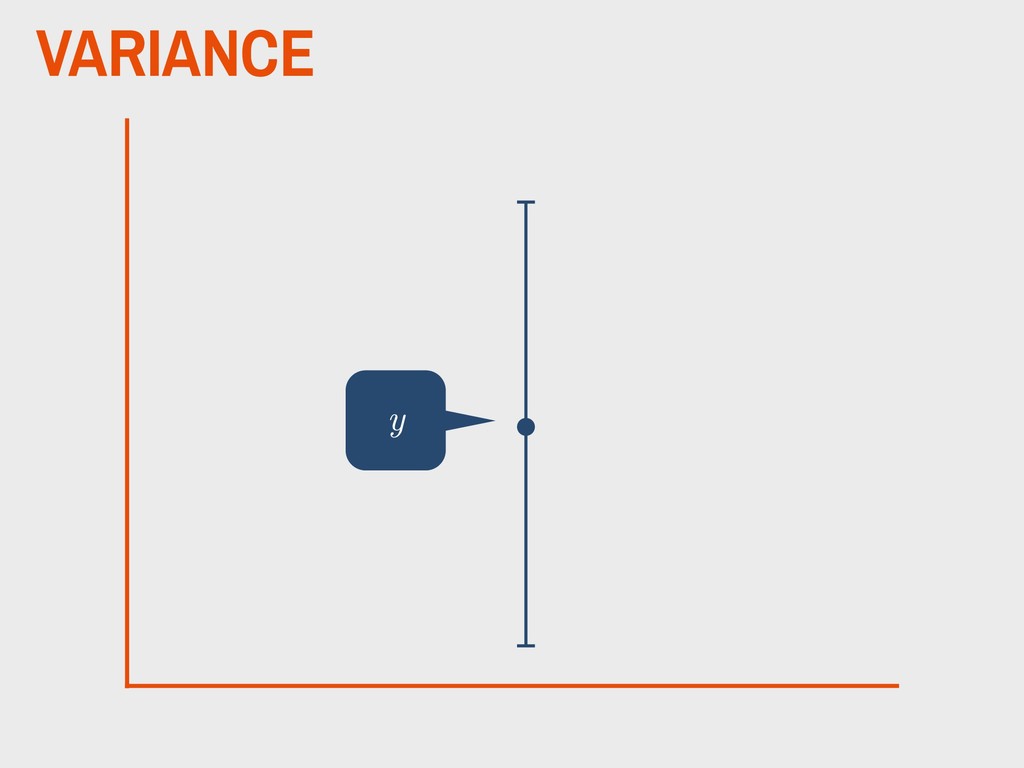
VARIANCE ▸ Variance measures the degree to which a distribution
varies from the mean. ▸ This can be easily calculated in R using the stats::var() function. ▸ Greek letter 2 (“sigma”) used for referring to the population variance ▸ The variance is the second moment of a distribution 4. DESCRIBING DISTRIBUTIONS -
▸ s2 = variance ▸ = sample mean ▸ x
= a given value in the vector ▸ n = sample size “The variance is the sum of square error divided by n minus 1 degrees of freedom.” 4. DESCRIBING DISTRIBUTIONS Let: SAMPLE VARIANCE s2 = ∑n i=1 (x − ¯ x)2 n − 1 ¯ x -
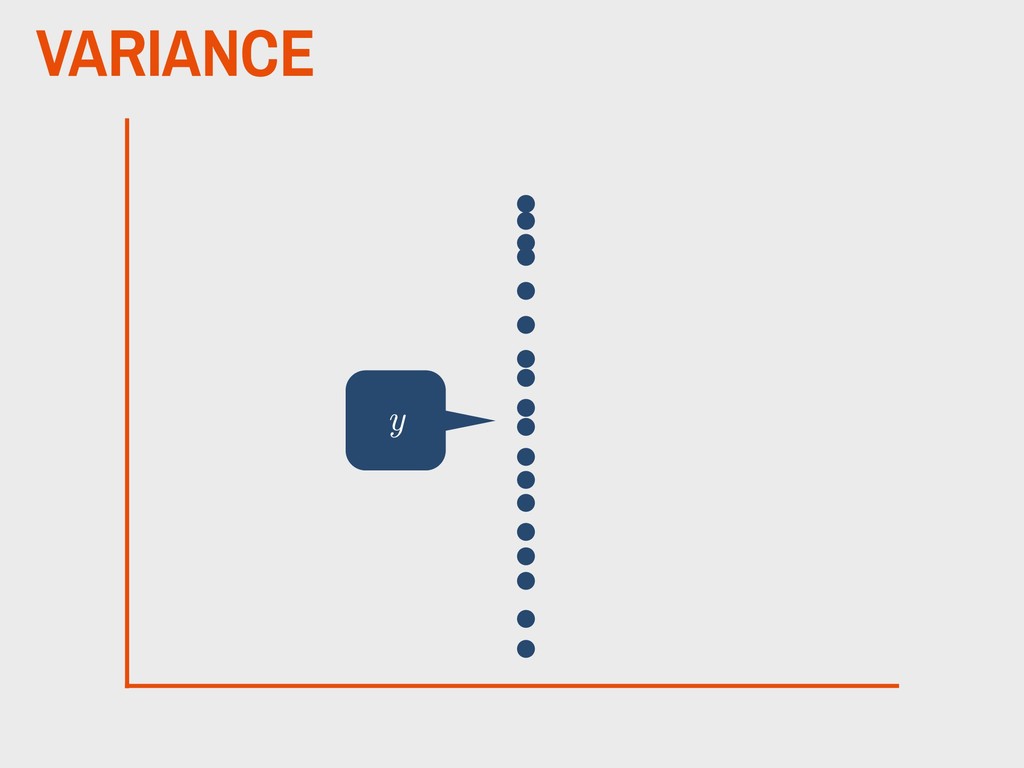
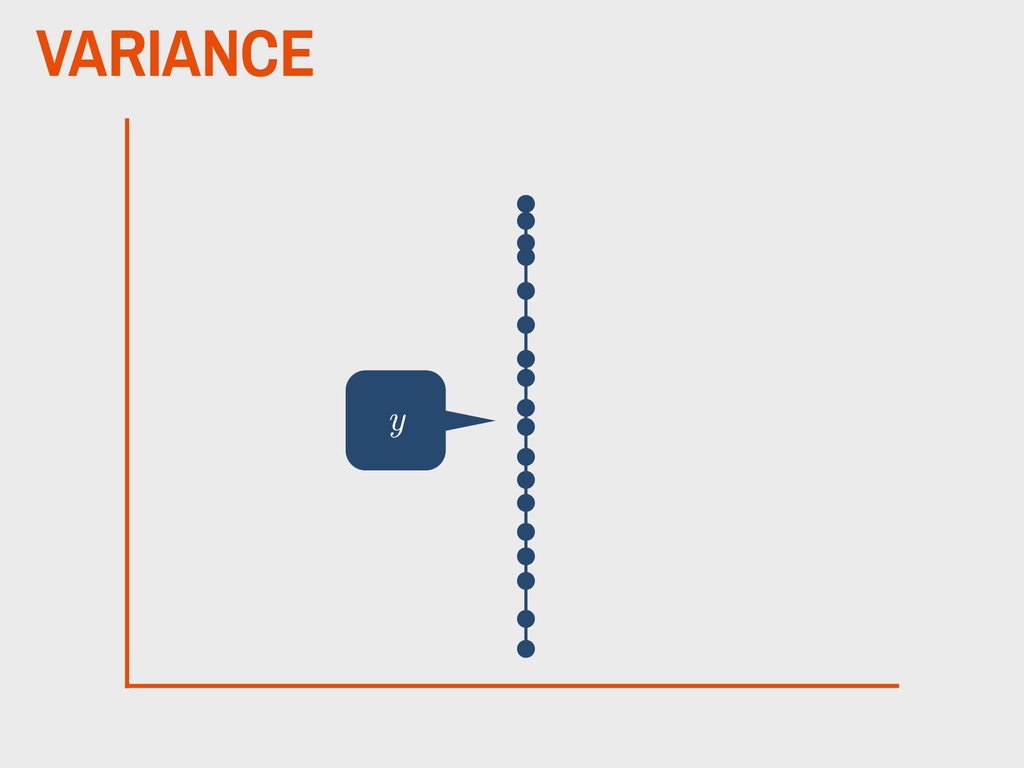
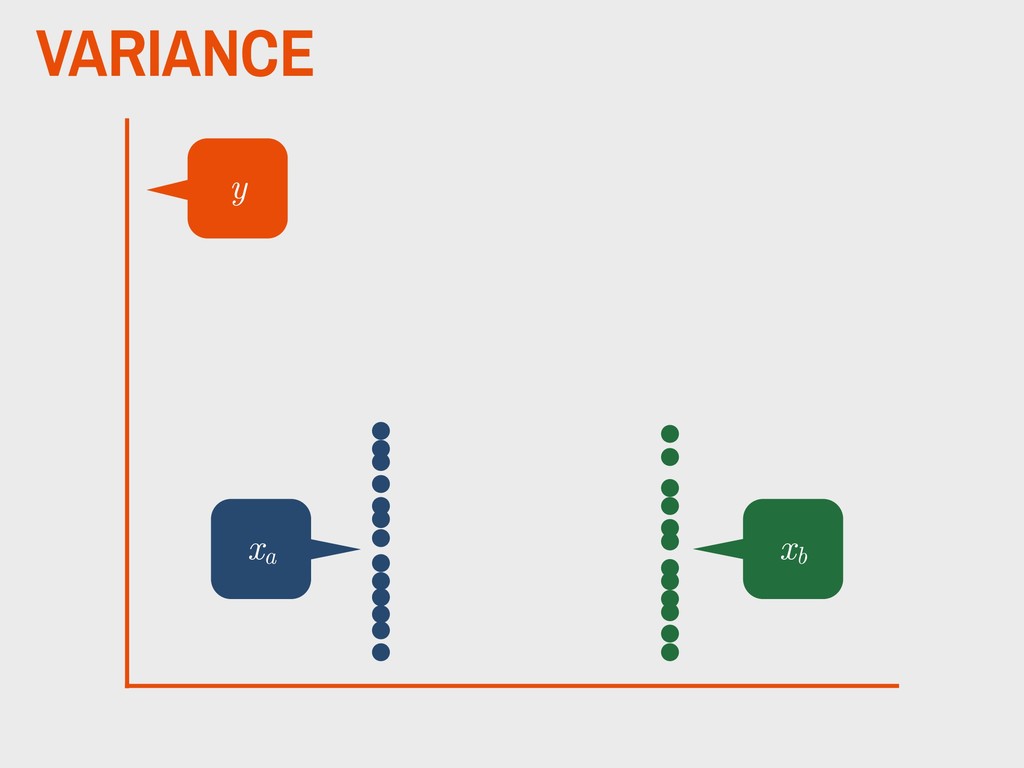
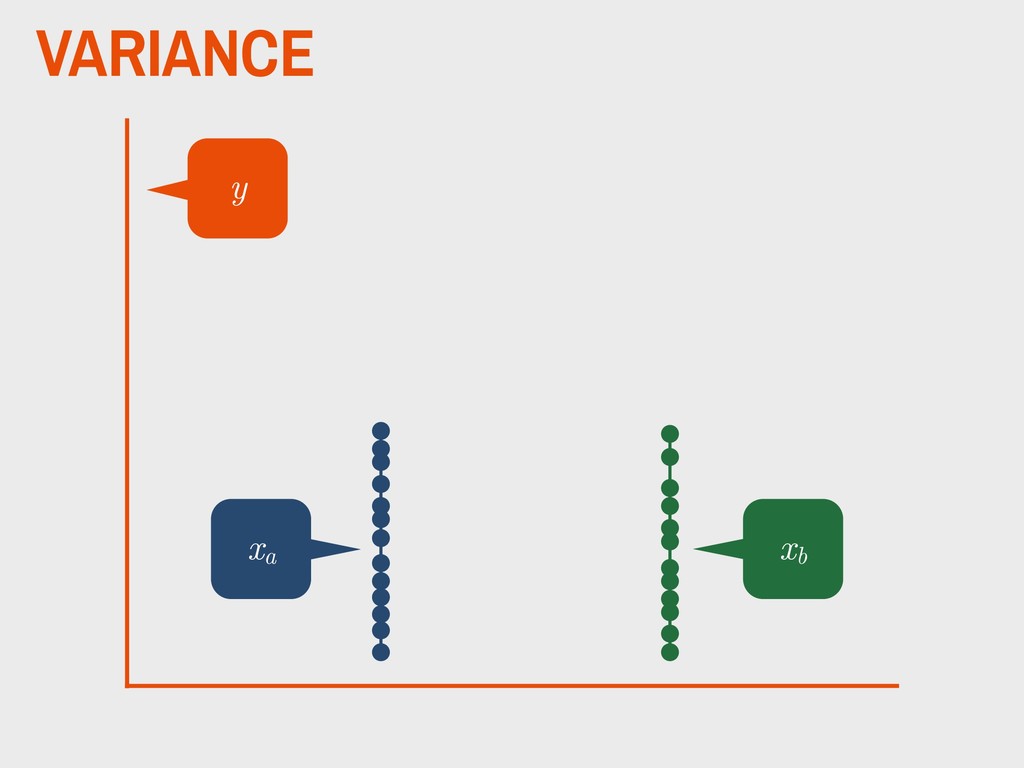
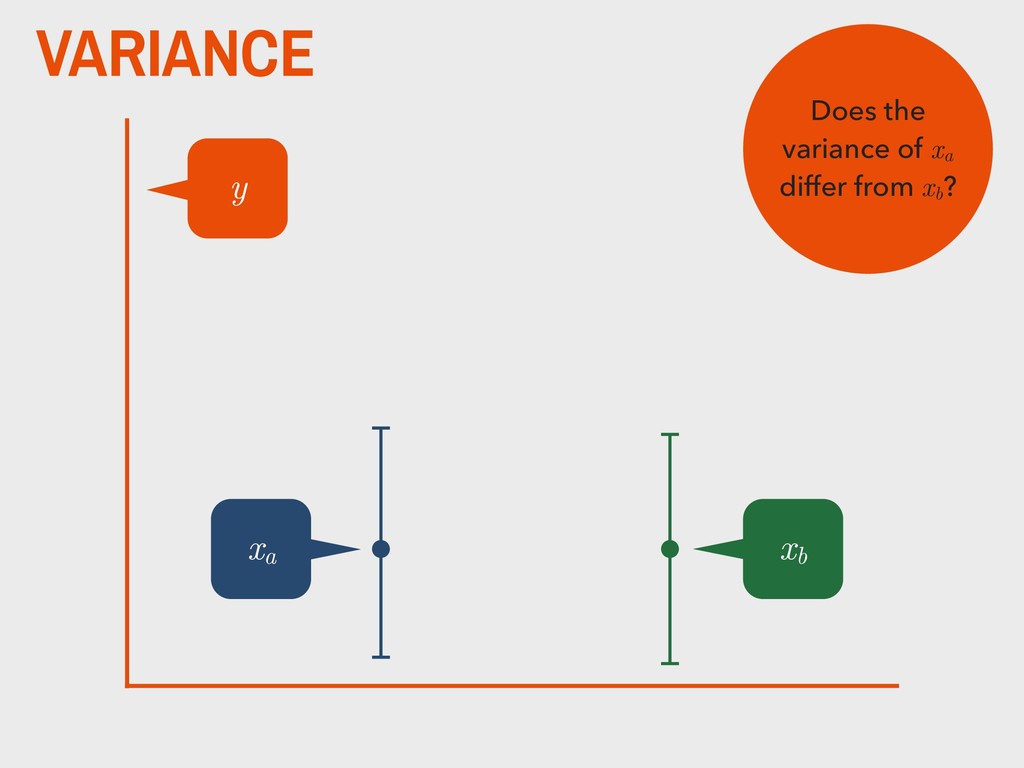
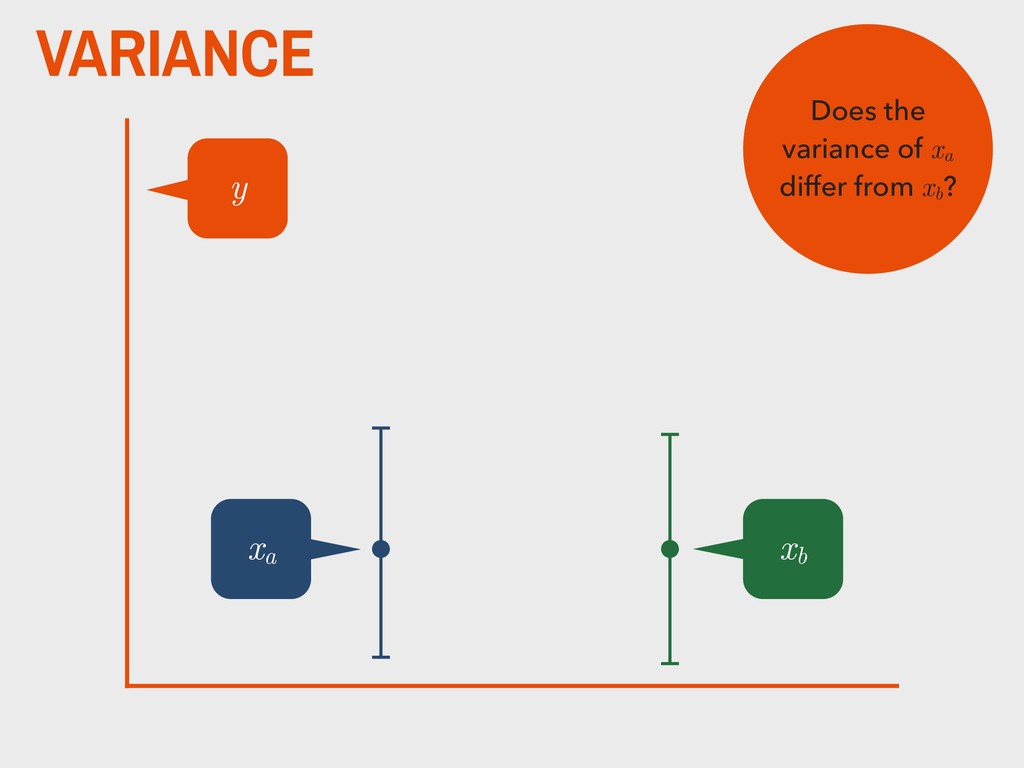
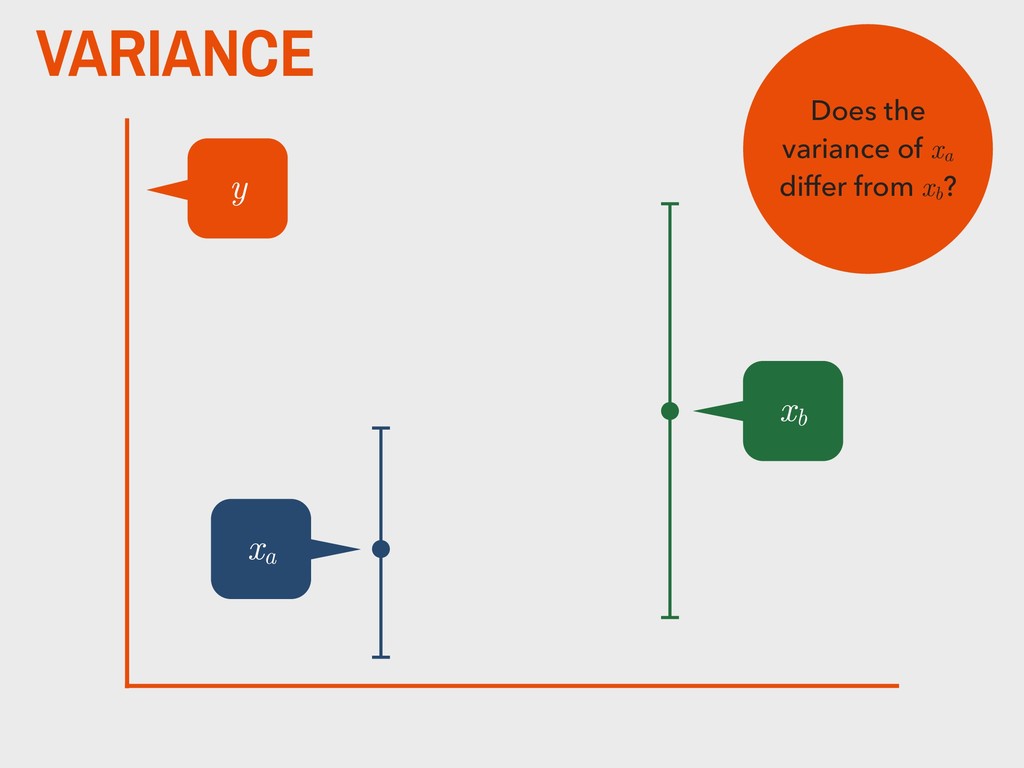
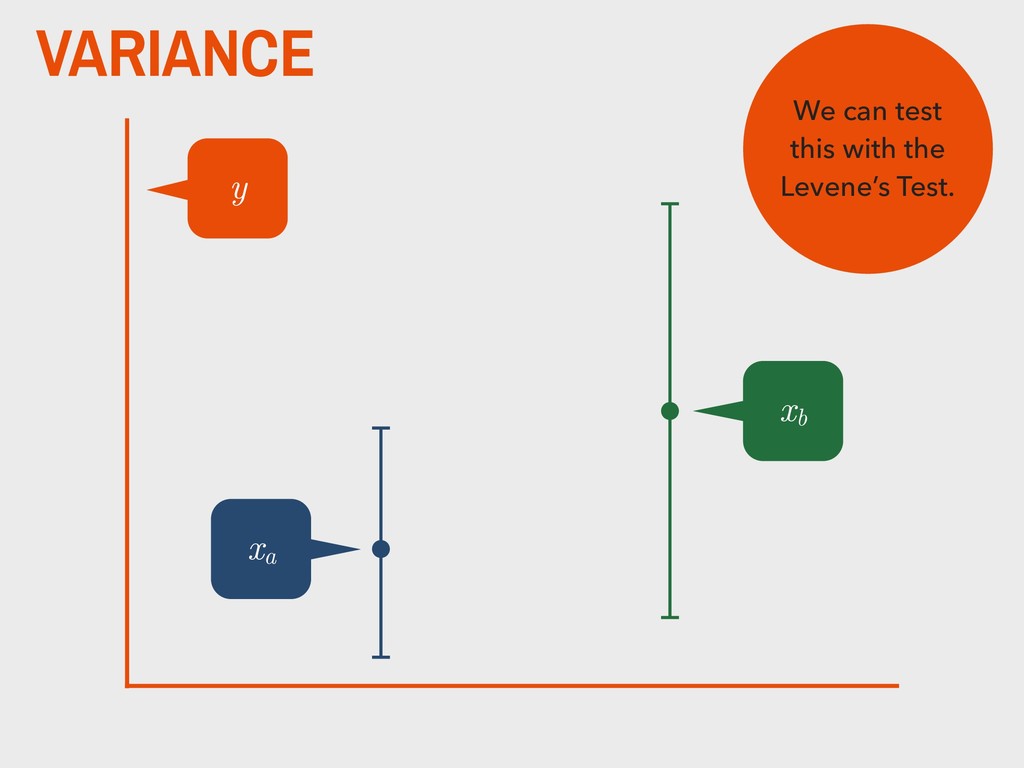
VARIANCE xa y We can test this with the
Levene’s Test. xb -
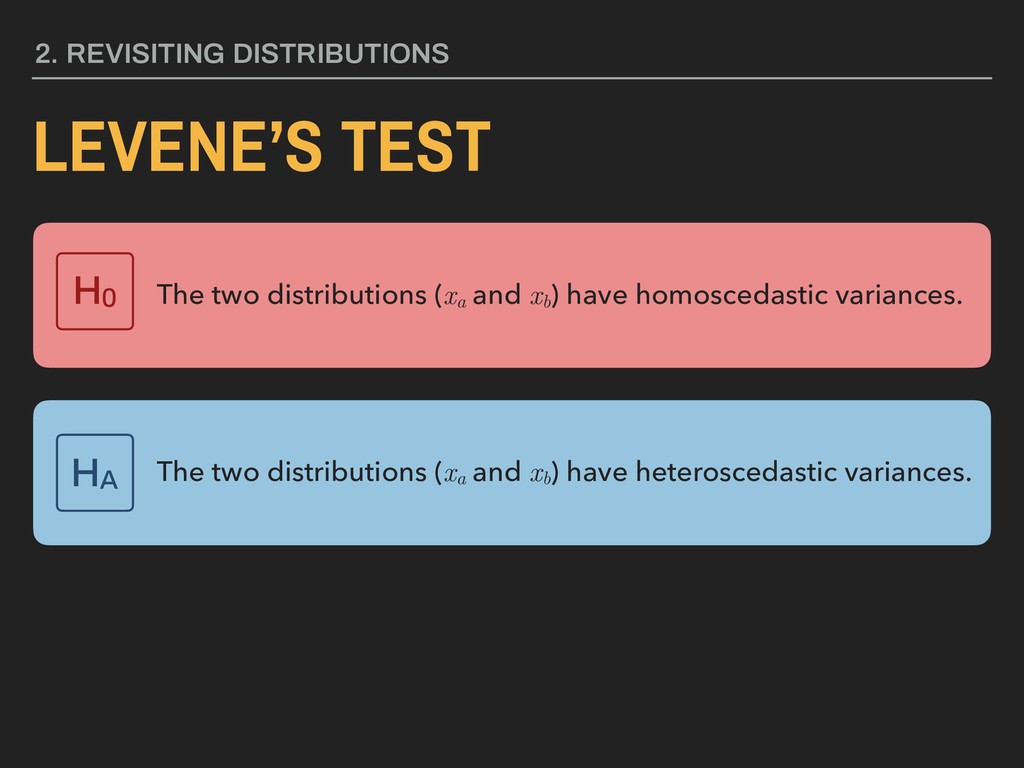
2. REVISITING DISTRIBUTIONS LEVENE’S TEST The two distributions (xa and
xb ) have homoscedastic variances. H0 The two distributions (xa and xb ) have heteroscedastic variances. HA -
KEY TERM Homoscedasticity refers to two or more distributions that
have the same underlying variance. This is a key assumption in inferential statistics. -
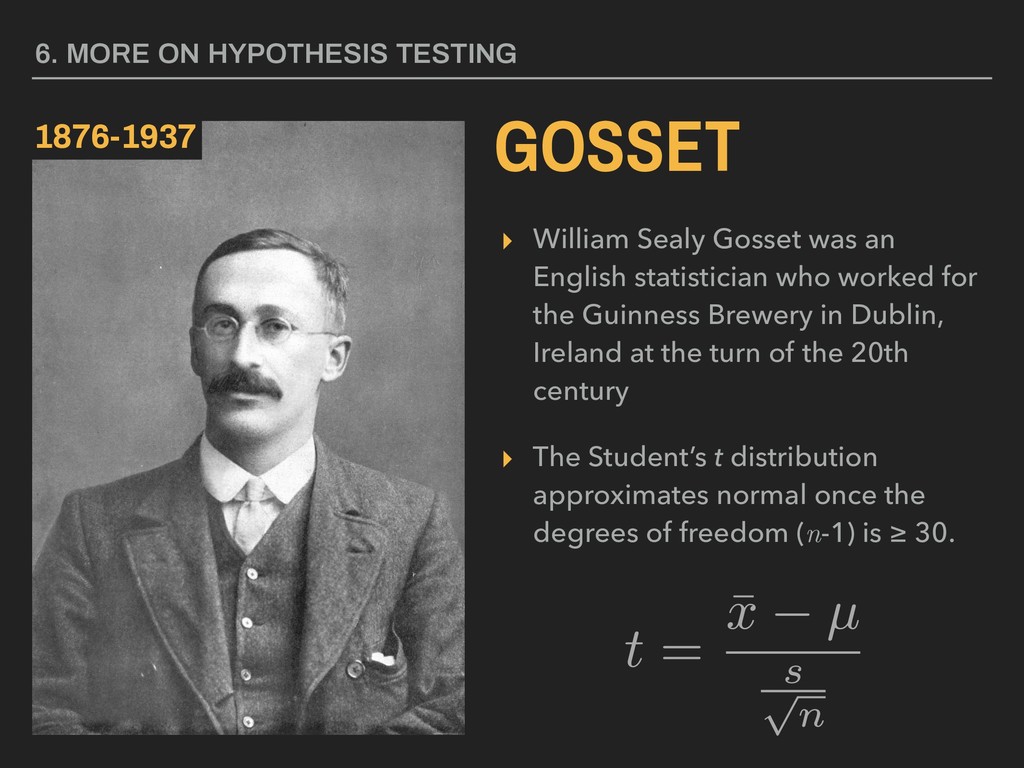
▸ William Sealy Gosset was an English statistician who worked
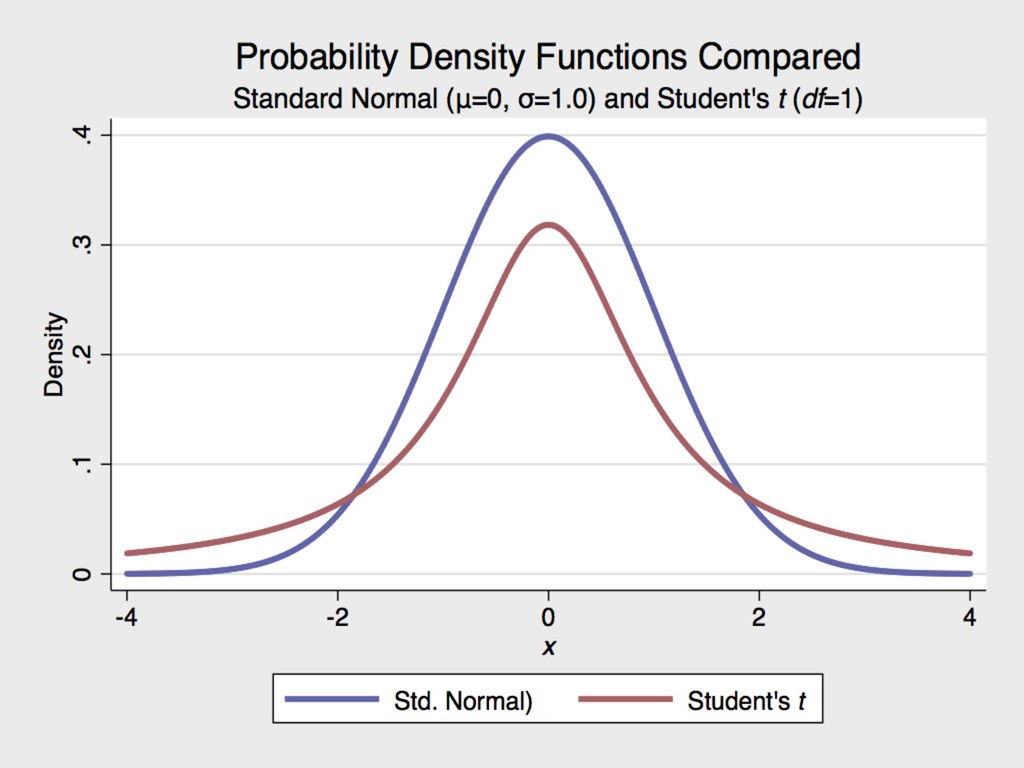
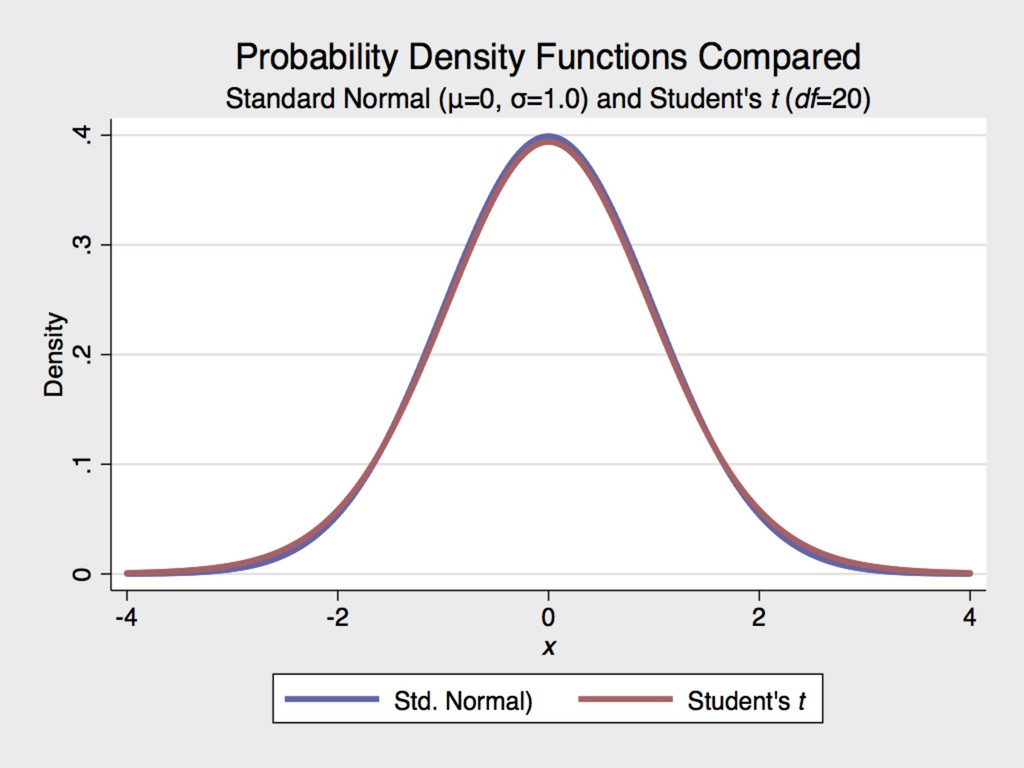
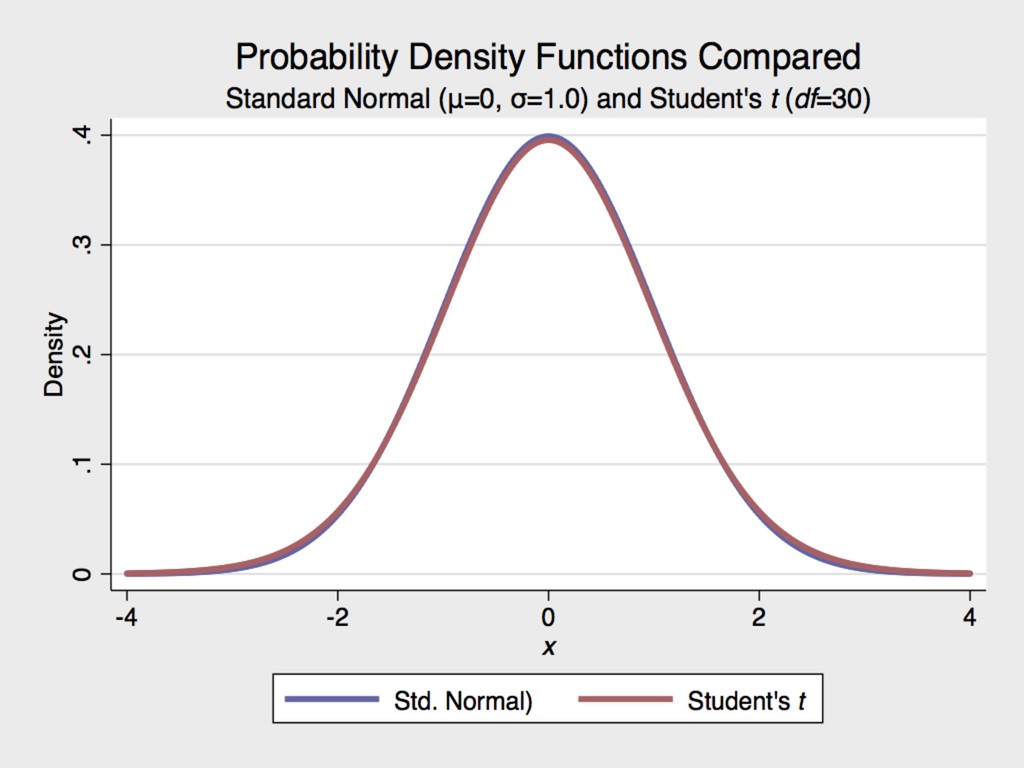
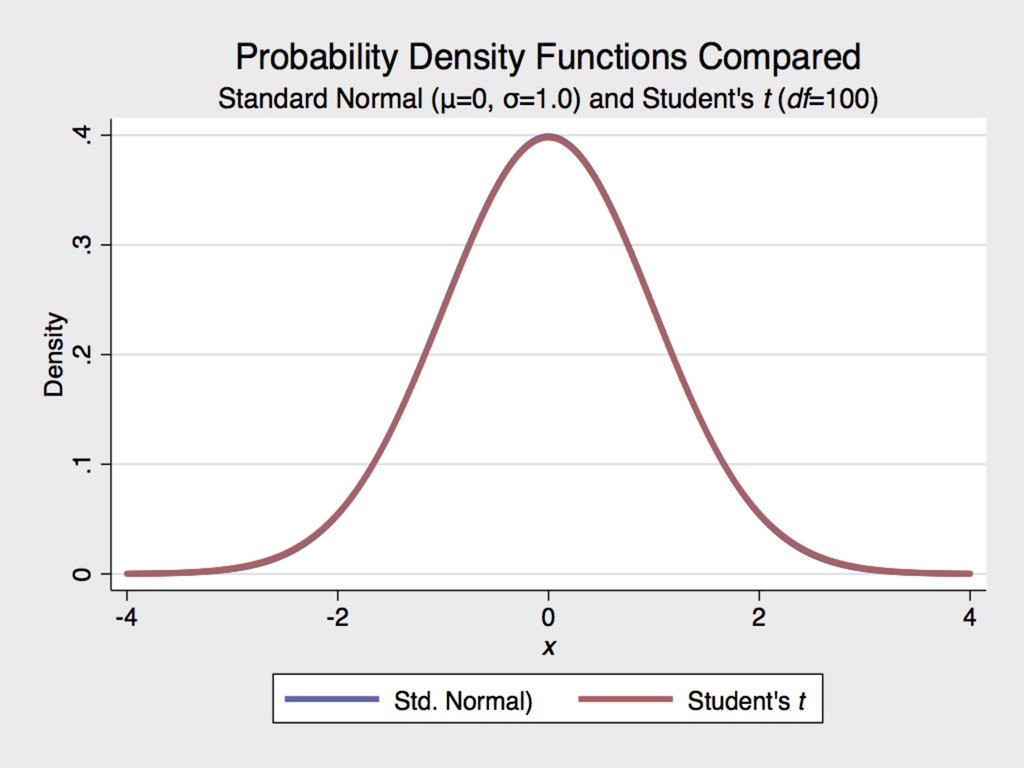
for the Guinness Brewery in Dublin, Ireland at the turn of the 20th century ▸ The Student’s t distribution approximates normal once the degrees of freedom (n-1) is ≥ 30. 6. MORE ON HYPOTHESIS TESTING GOSSET 1876-1937 -
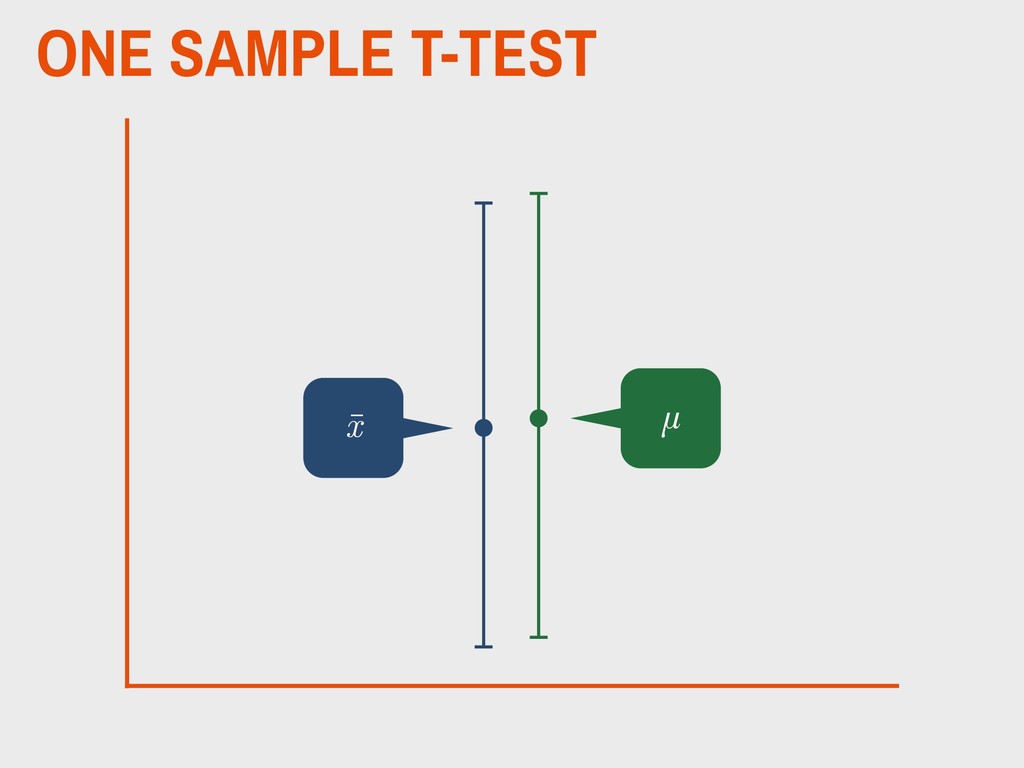
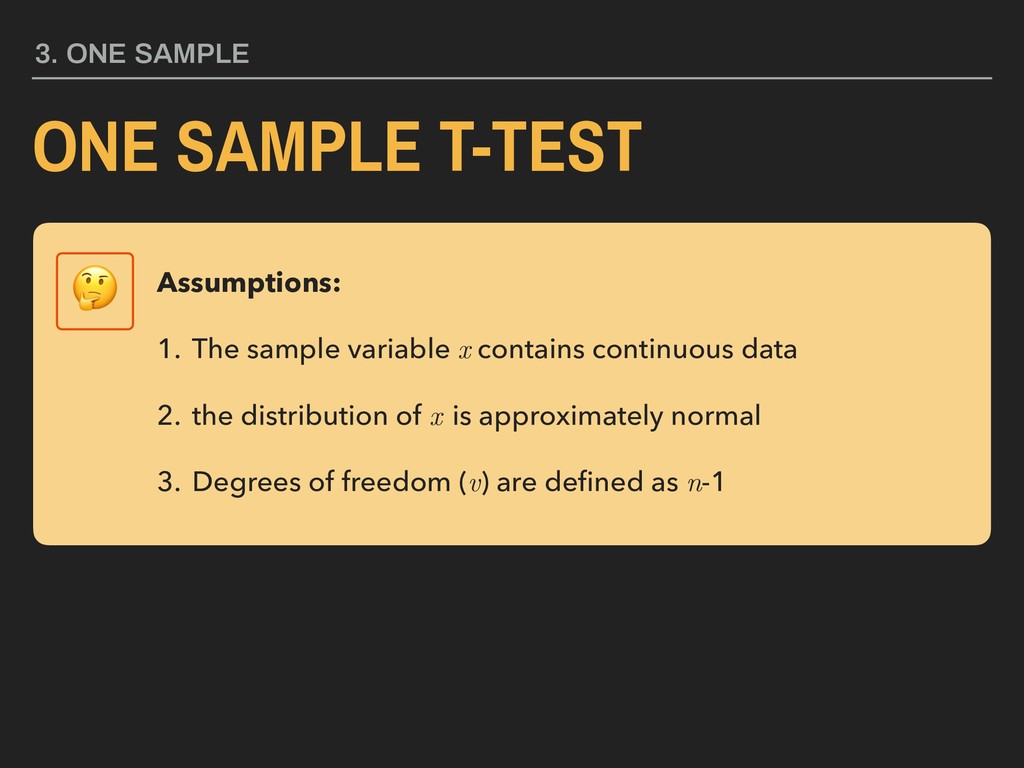
3. ONE SAMPLE ONE SAMPLE T-TEST Assumptions: 1. The
sample variable x contains continuous data 2. the distribution of x is approximately normal 3. Degrees of freedom (v) are defined as n-1 -
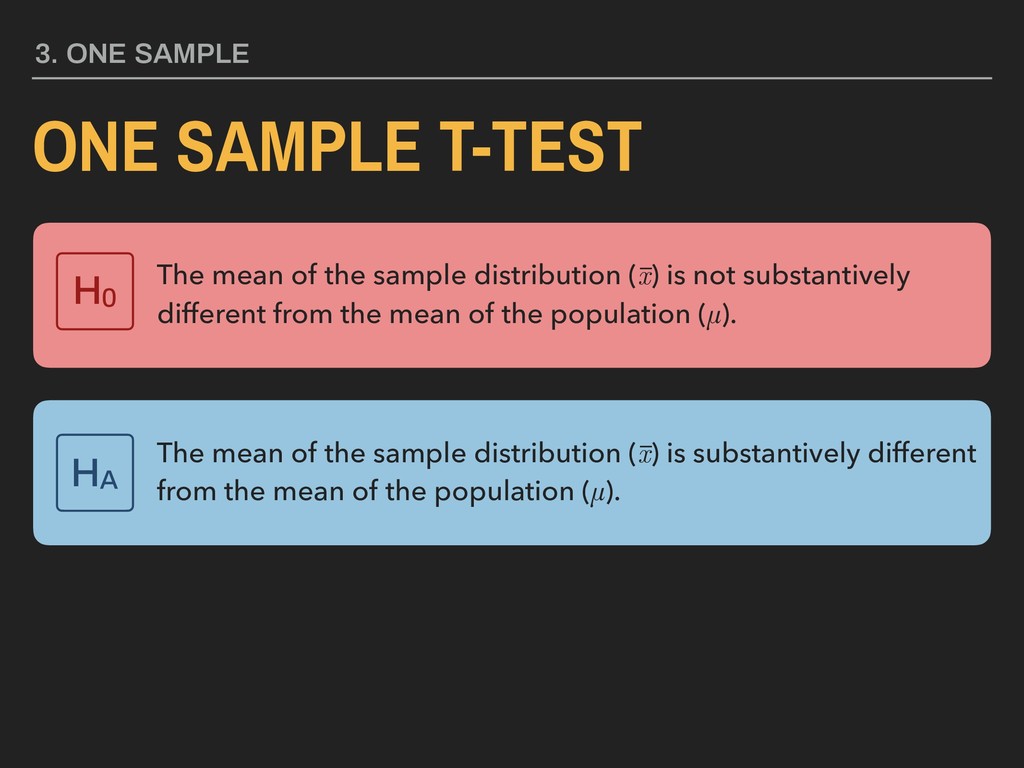
3. ONE SAMPLE ONE SAMPLE T-TEST The mean of the
sample distribution (x) is not substantively different from the mean of the population (µ). H0 The mean of the sample distribution (x) is substantively different from the mean of the population (µ). HA _ _ -
CHALLENGE There is no function in base R for
calculating two- tailed probabilities under the t distribution. -
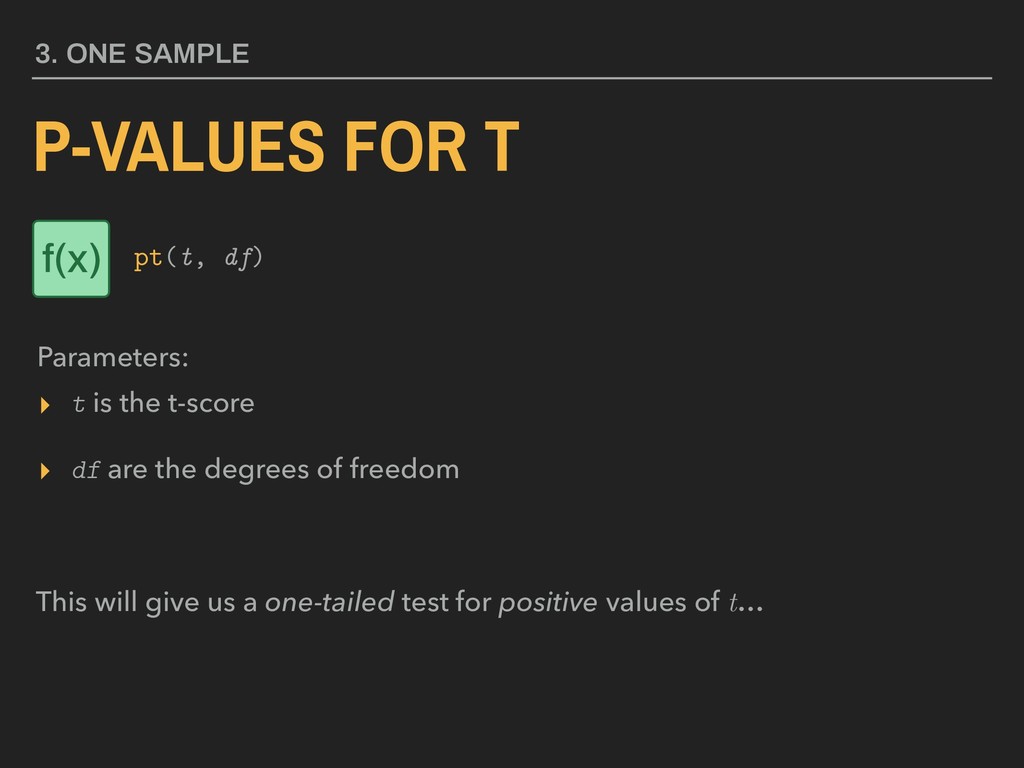
▸ t is the t-score ▸ df are the degrees
of freedom This will give us a one-tailed test for positive values of t… 3. ONE SAMPLE P-VALUES FOR T Parameters: pt(t, df) f(x) -
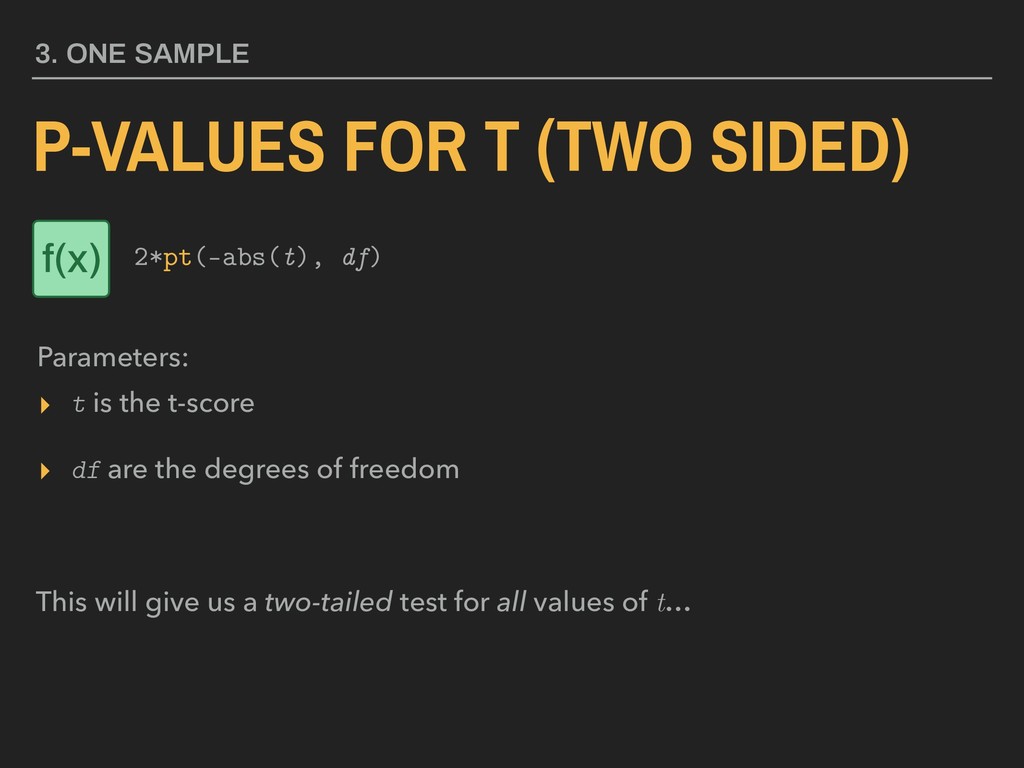
▸ t is the t-score ▸ df are the degrees
of freedom This will give us a two-tailed test for all values of t… 3. ONE SAMPLE P-VALUES FOR T (TWO SIDED) Parameters: 2*pt(-abs(t), df) f(x) -
DESIGNING FOR REPLICATION #' Two-tailed Probabilities Under the t Distribution
#' #' @description This function calculates the probability of observing a t score #' at least as extreme as the given t value. #' #' @param t A given t score #' @param n The sample size associated with t #' #' @return A probability value #’ 3. ONE SAMPLE -
DESIGNING FOR REPLICATION probt <- function(t, n){ # calculate the
degrees of freedom given n df <- n-1 # calculate the p value out <- 2*pt(q = -abs(t), df = df) # return output return(out) } 3. ONE SAMPLE -
DESIGNING FOR REPLICATION ## Load Dependencies This notebook requires `dplyr`.
```{r load-packages} # tidyverse packages library(dplyr) # data cleaning # other packages library(here) # file path management ``` This notebook also uses a custom function `probt`: ```{r load-functions} source(here(“source”, “probt.R”)) ``` 3. ONE SAMPLE -
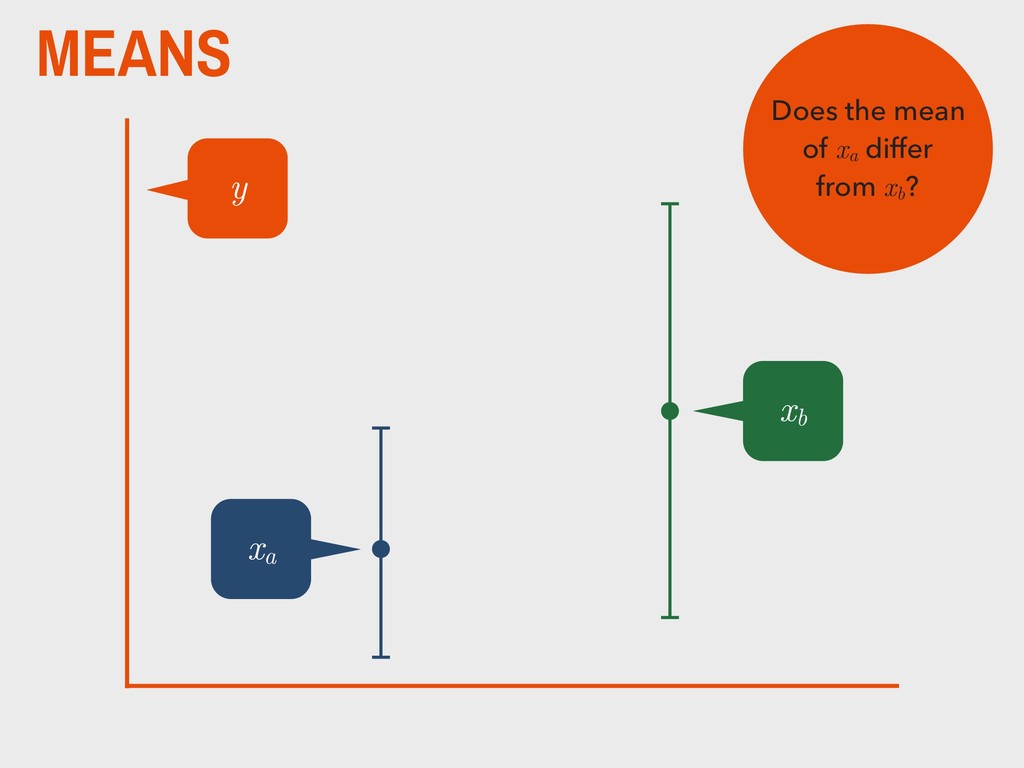
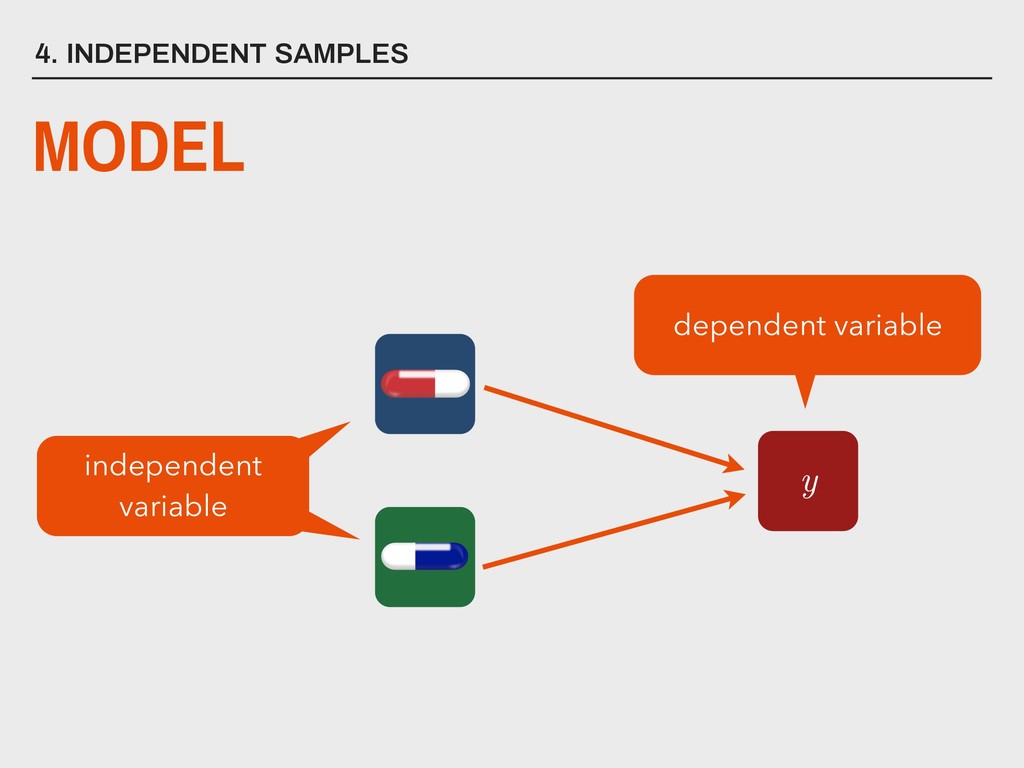
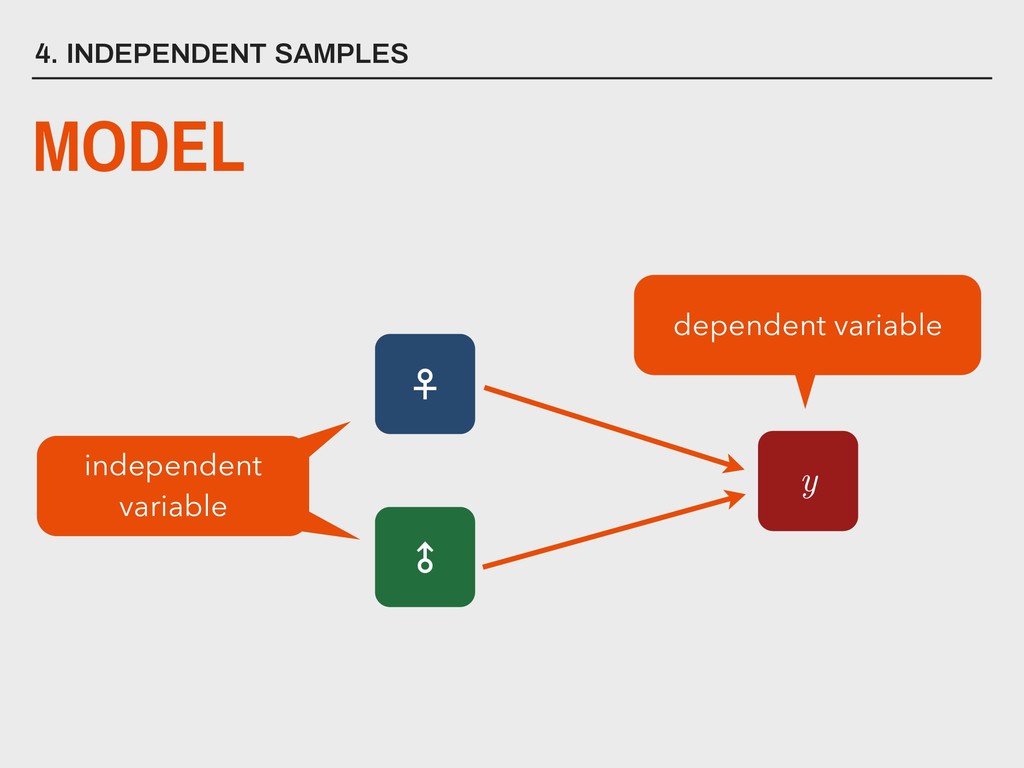
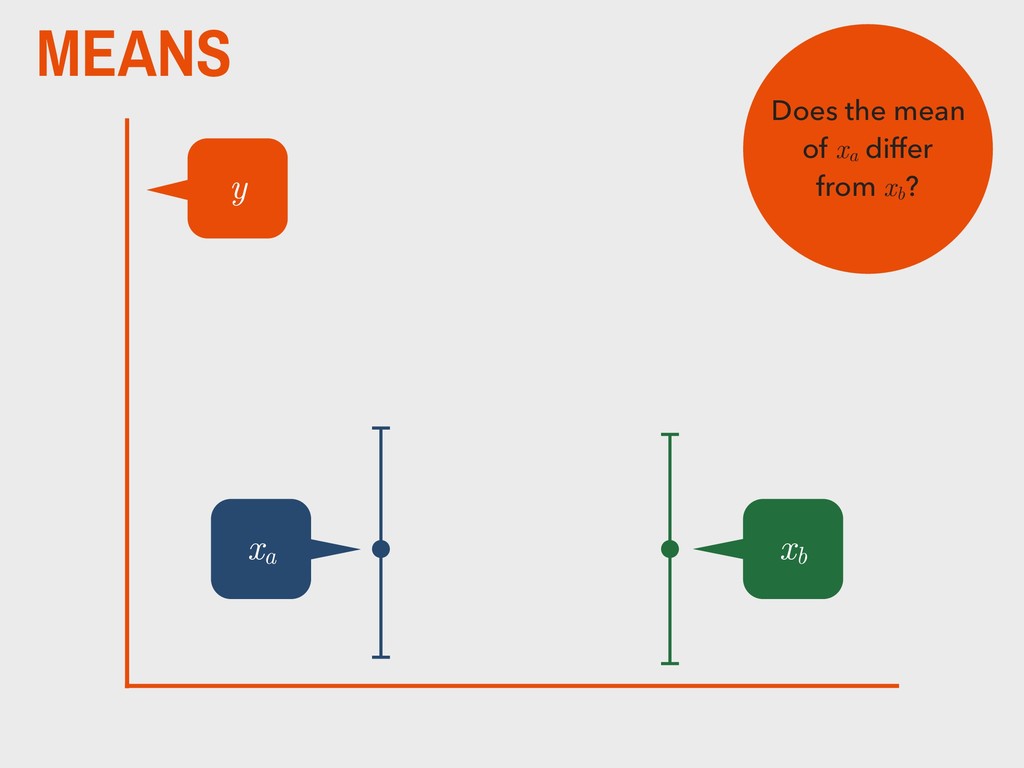
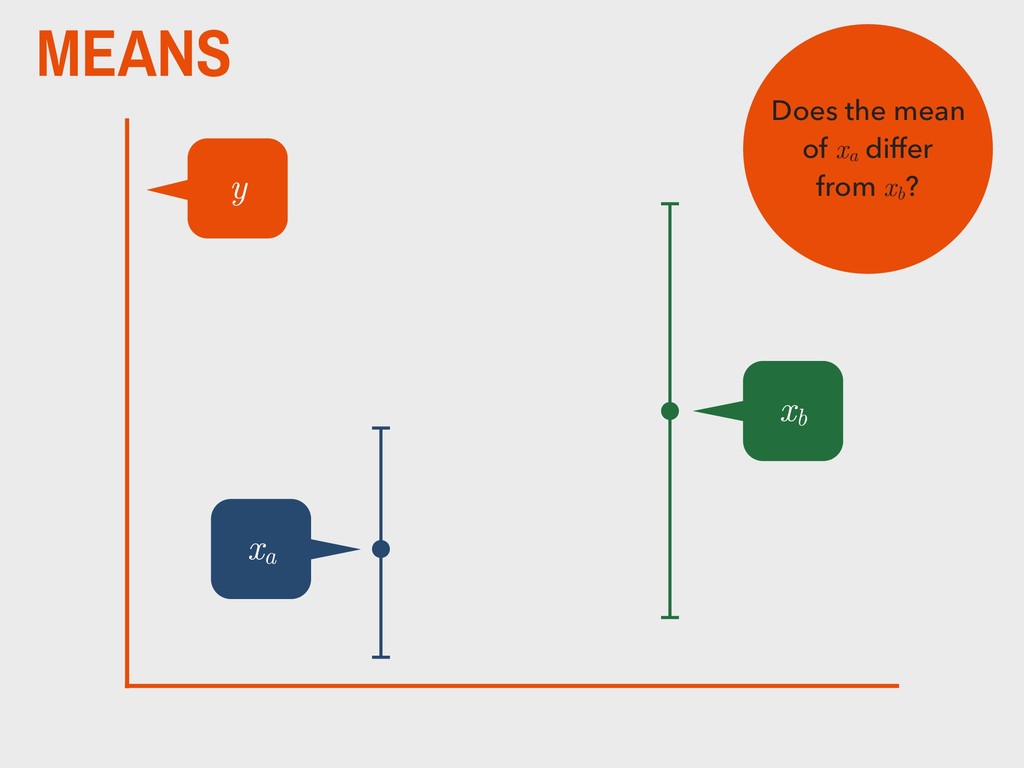
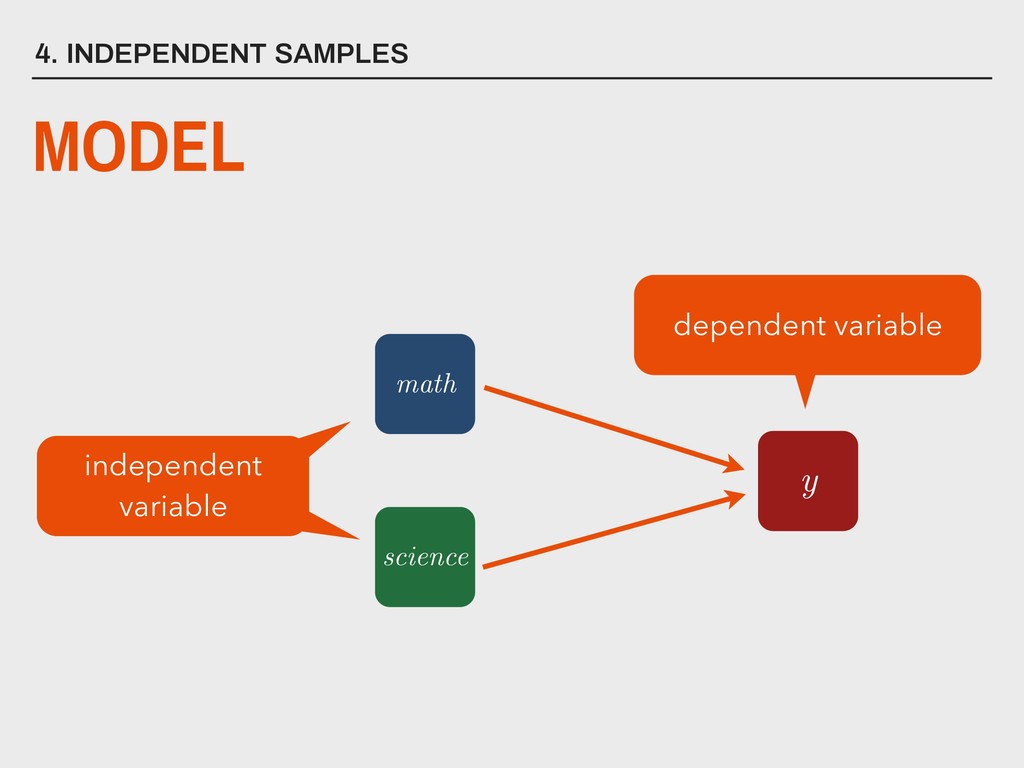
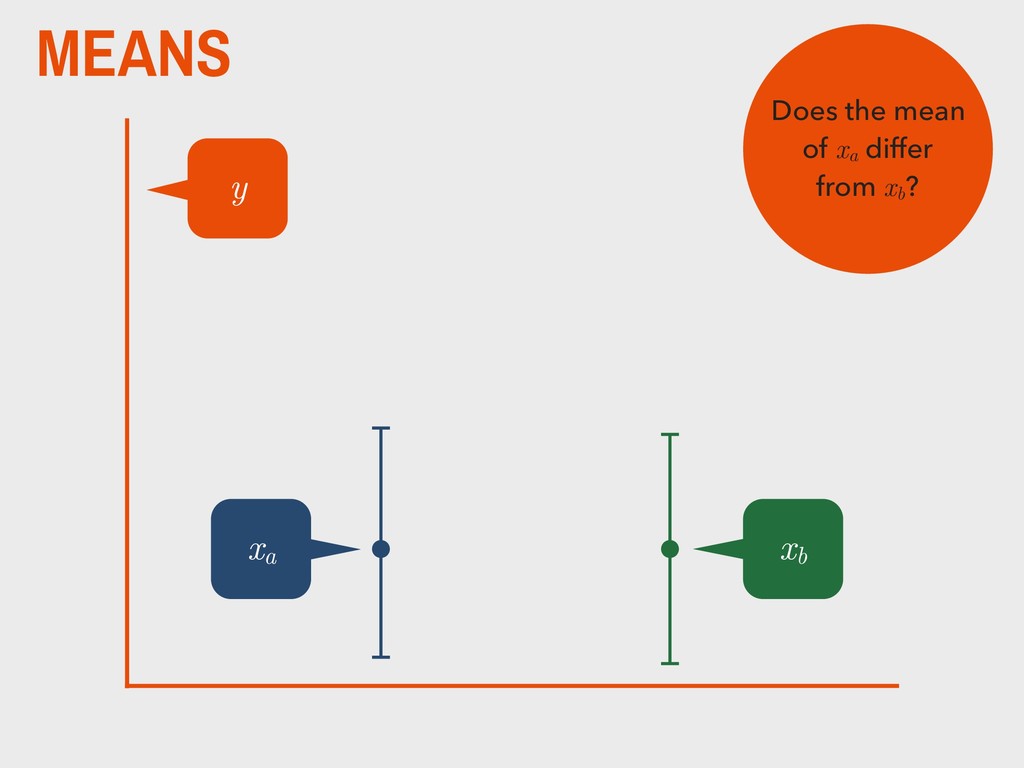
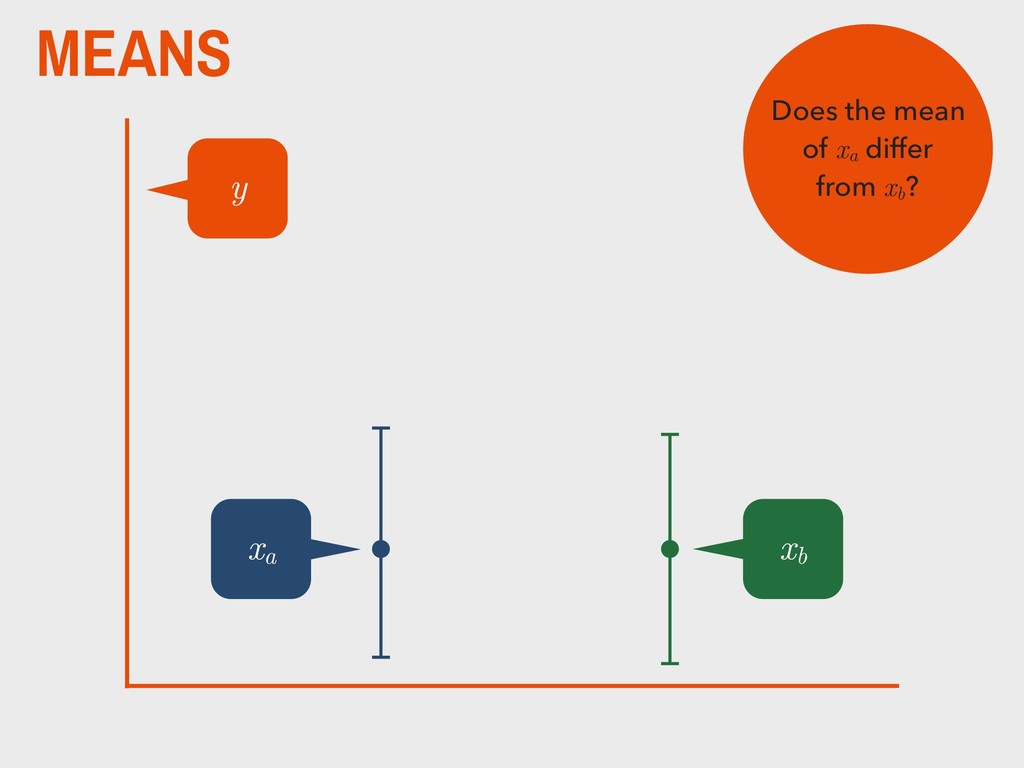
MEANS xb xa y Does the mean of xa differ
from xb ? -
MEANS xa y xb Does the mean of xa differ
from xb ? -
MEANS xa y xb Does the mean of xa differ
from xb ? -
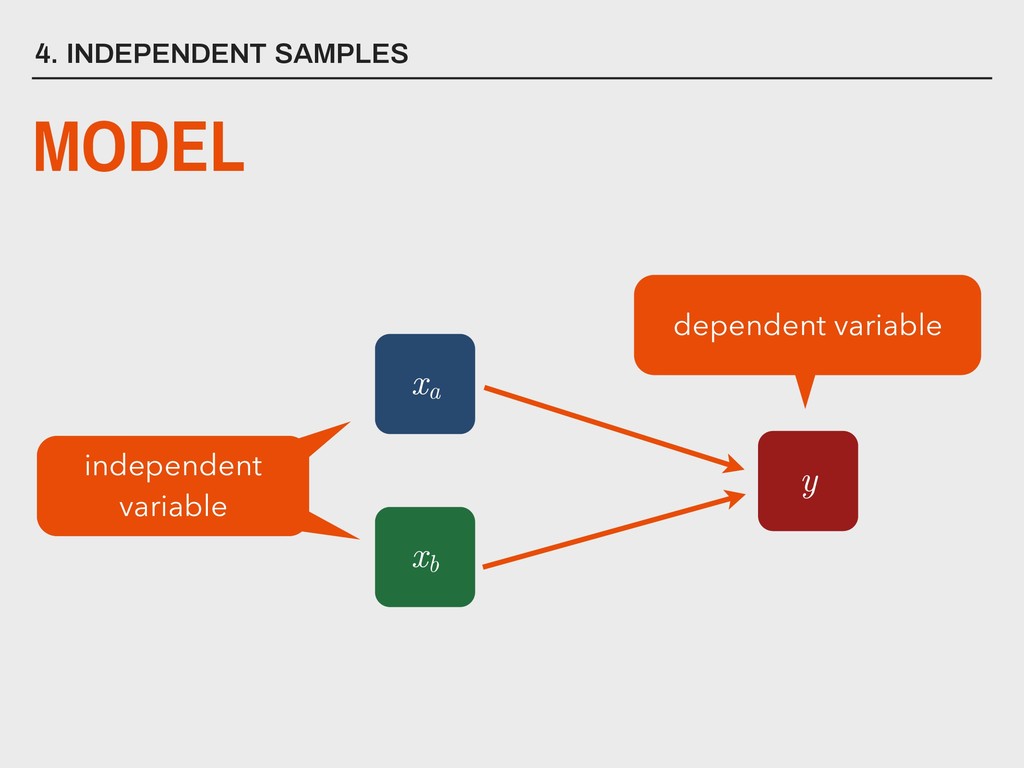
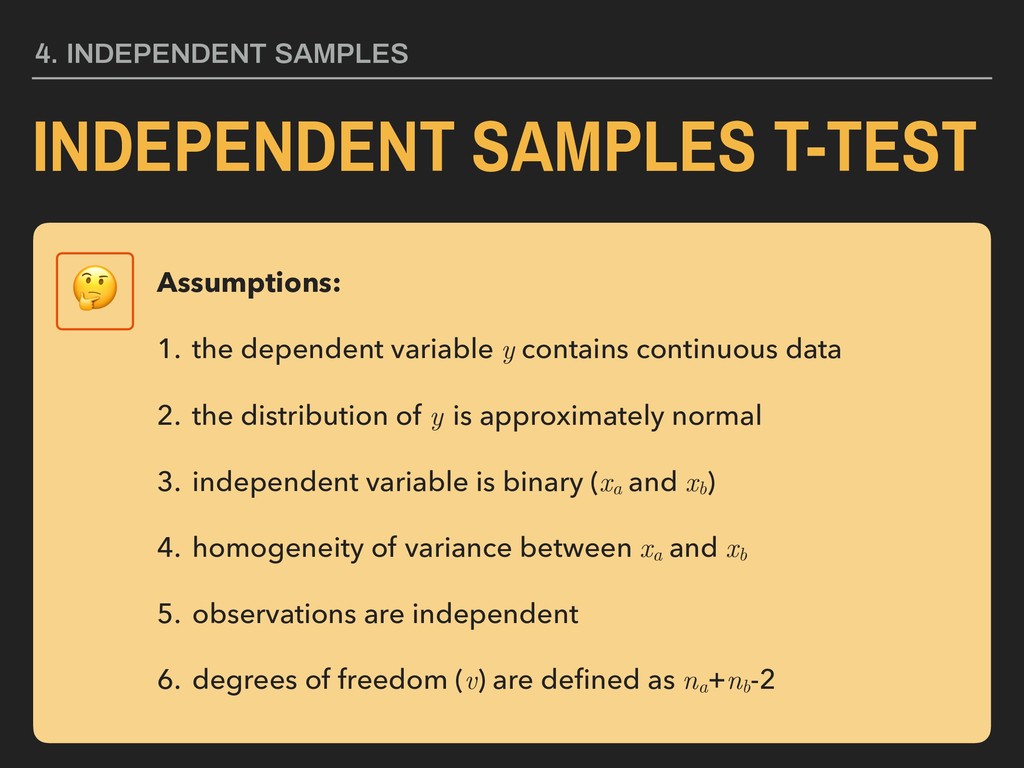
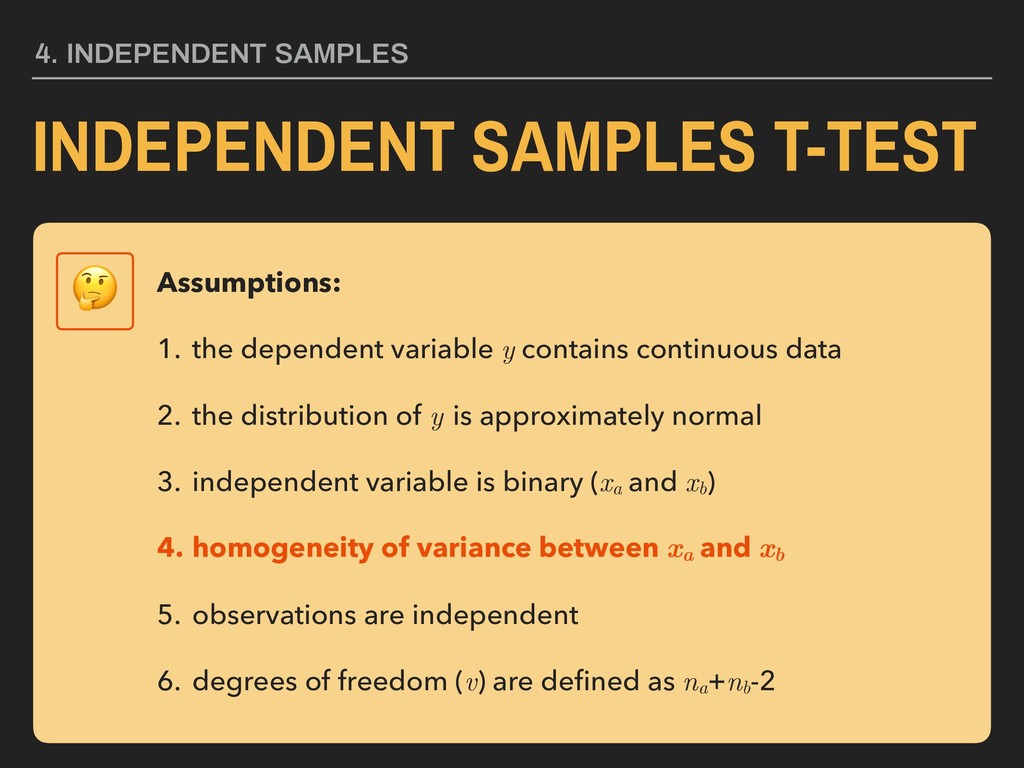
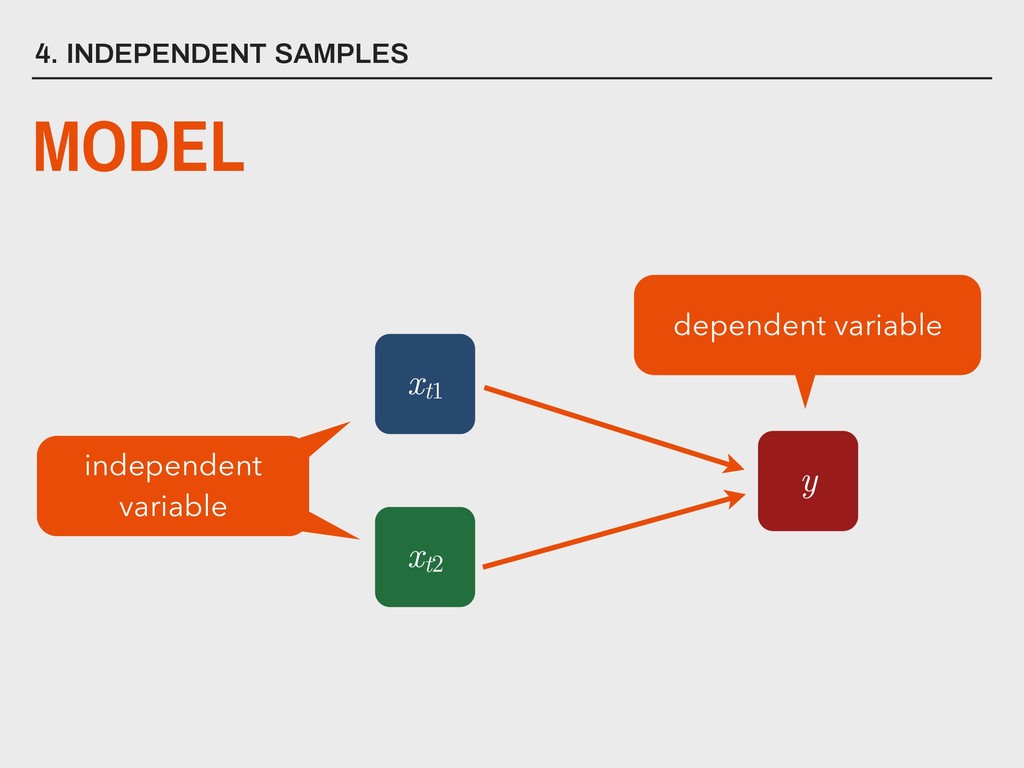
4. INDEPENDENT SAMPLES INDEPENDENT SAMPLES T-TEST Assumptions: 1. the
dependent variable y contains continuous data 2. the distribution of y is approximately normal 3. independent variable is binary (xa and xb ) 4. homogeneity of variance between xa and xb 5. observations are independent 6. degrees of freedom (v) are defined as na +nb -2 -
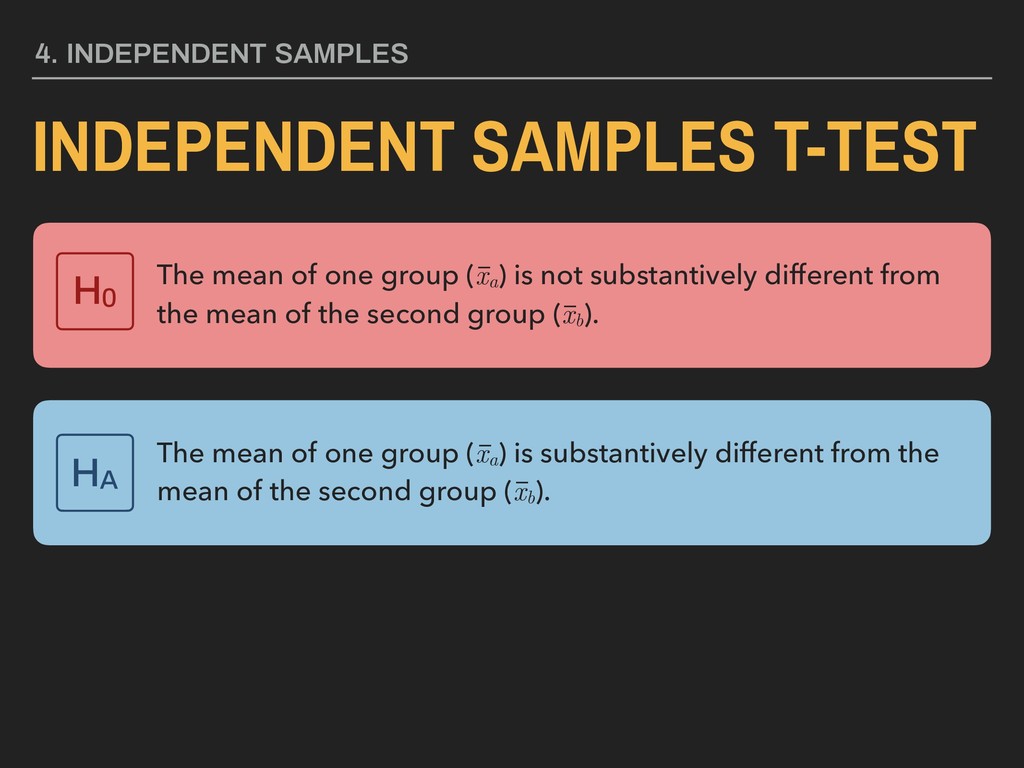
4. INDEPENDENT SAMPLES INDEPENDENT SAMPLES T-TEST The mean of one
group (xa ) is not substantively different from the mean of the second group (xb ). H0 The mean of one group (xa ) is substantively different from the mean of the second group (xb ). HA _ _ _ _ -
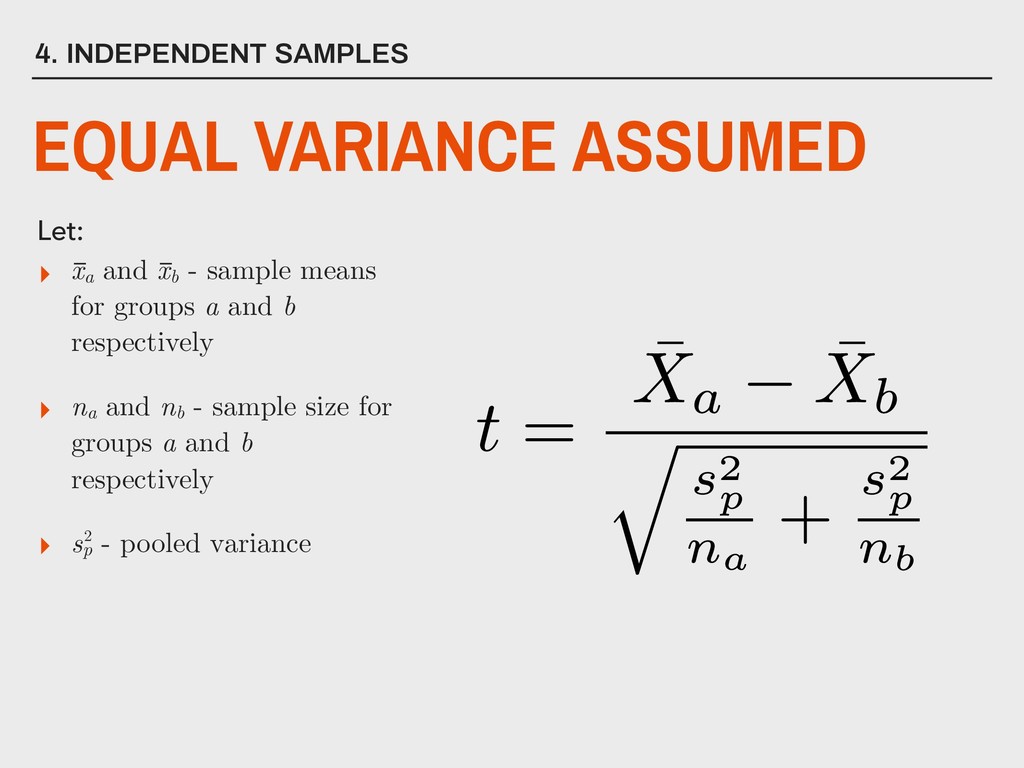
▸ xa and xb - sample means for groups a
and b respectively ▸ na and nb - sample size for groups a and b respectively ▸ sp - pooled variance 4. INDEPENDENT SAMPLES Let: EQUAL VARIANCE ASSUMED _ _ 2 -
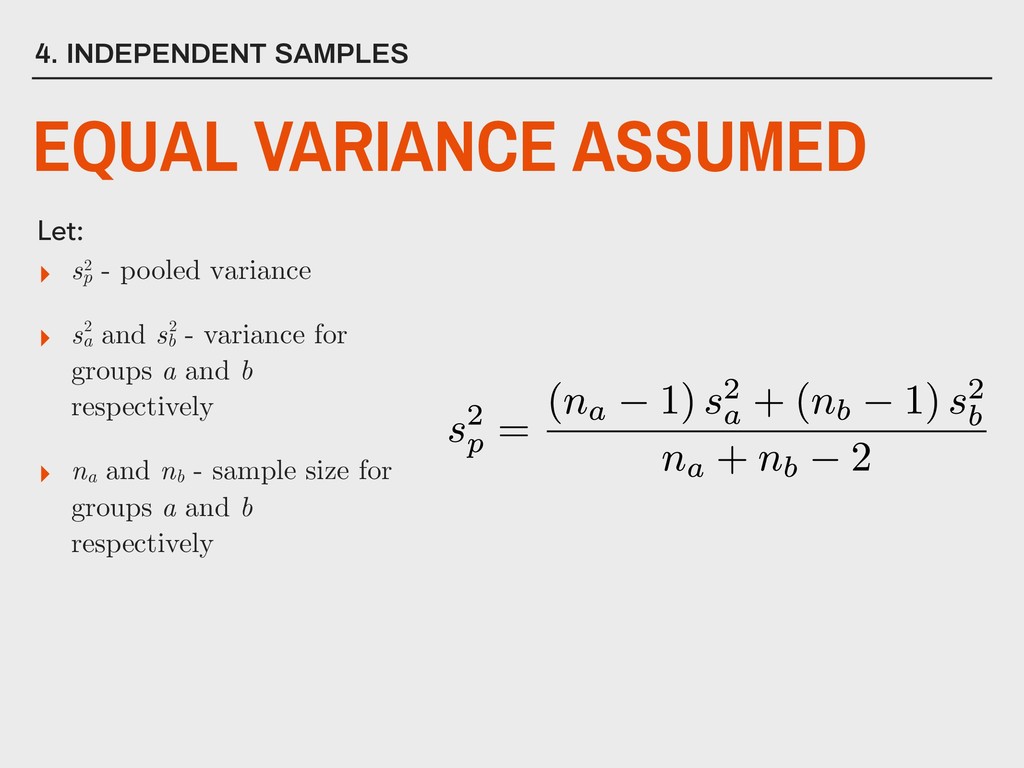
▸ sp - pooled variance ▸ sa and sb -
variance for groups a and b respectively ▸ na and nb - sample size for groups a and b respectively 4. INDEPENDENT SAMPLES Let: EQUAL VARIANCE ASSUMED 2 2 2 -
MEANS xa y xb Does the mean of xa differ
from xb ? -
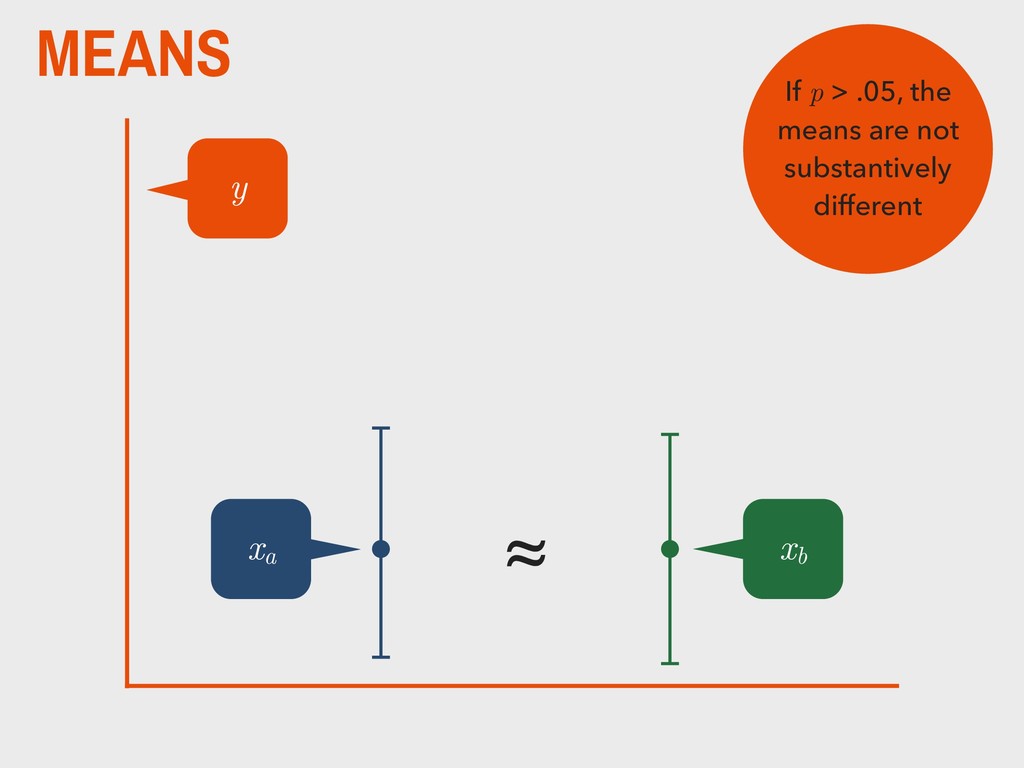
MEANS xa y xb If p > .05, the means
are not substantively different ≈ -
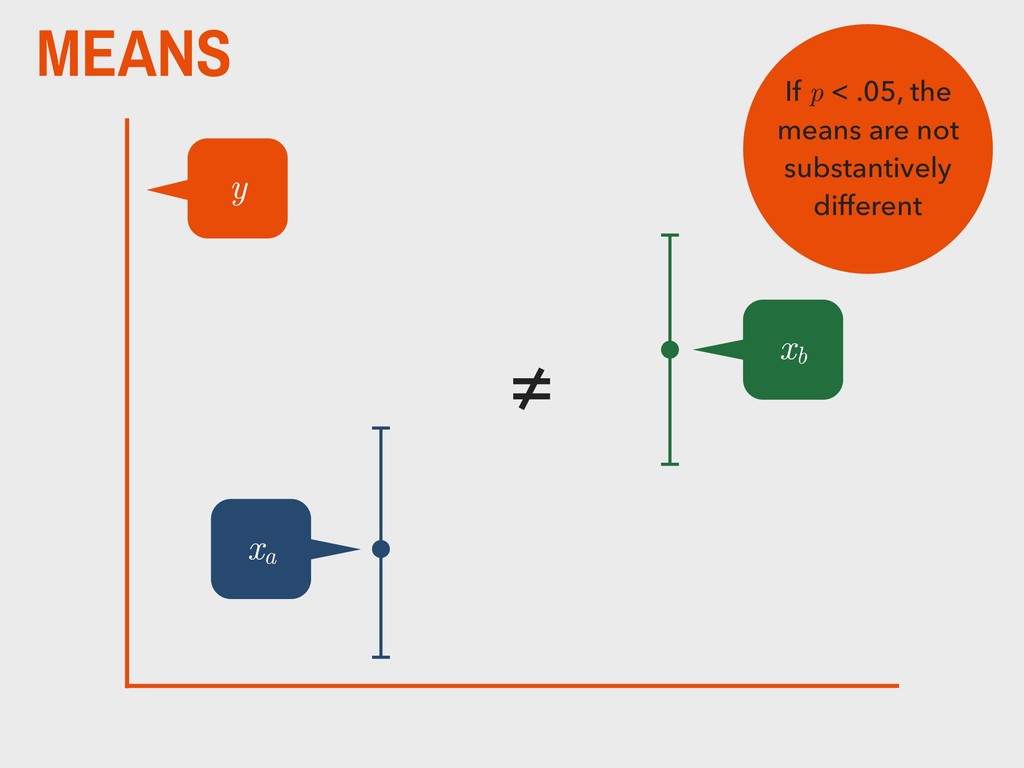
MEANS xa y If p < .05, the means are
not substantively different xb ≠ -
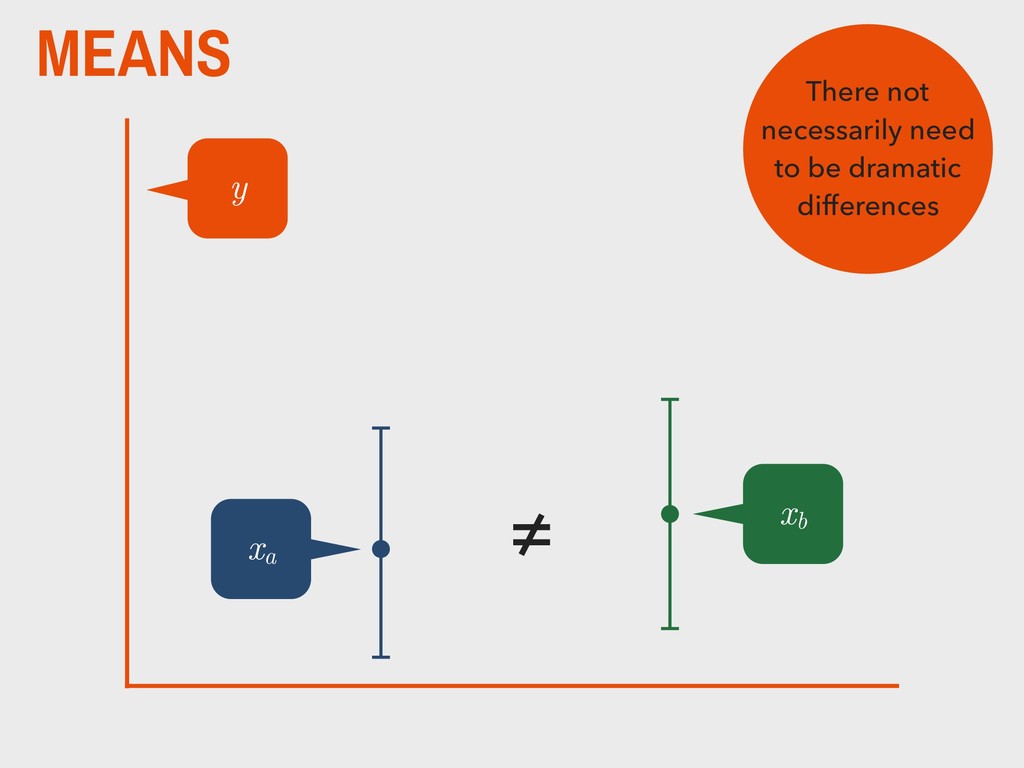
MEANS xa y There not necessarily need to be dramatic
differences xb ≠ -
4. INDEPENDENT SAMPLES INDEPENDENT SAMPLES T-TEST Assumptions: 1. the
dependent variable y contains continuous data 2. the distribution of y is approximately normal 3. independent variable is binary (xa and xb ) 4. homogeneity of variance between xa and xb 5. observations are independent 6. degrees of freedom (v) are defined as na +nb -2 -
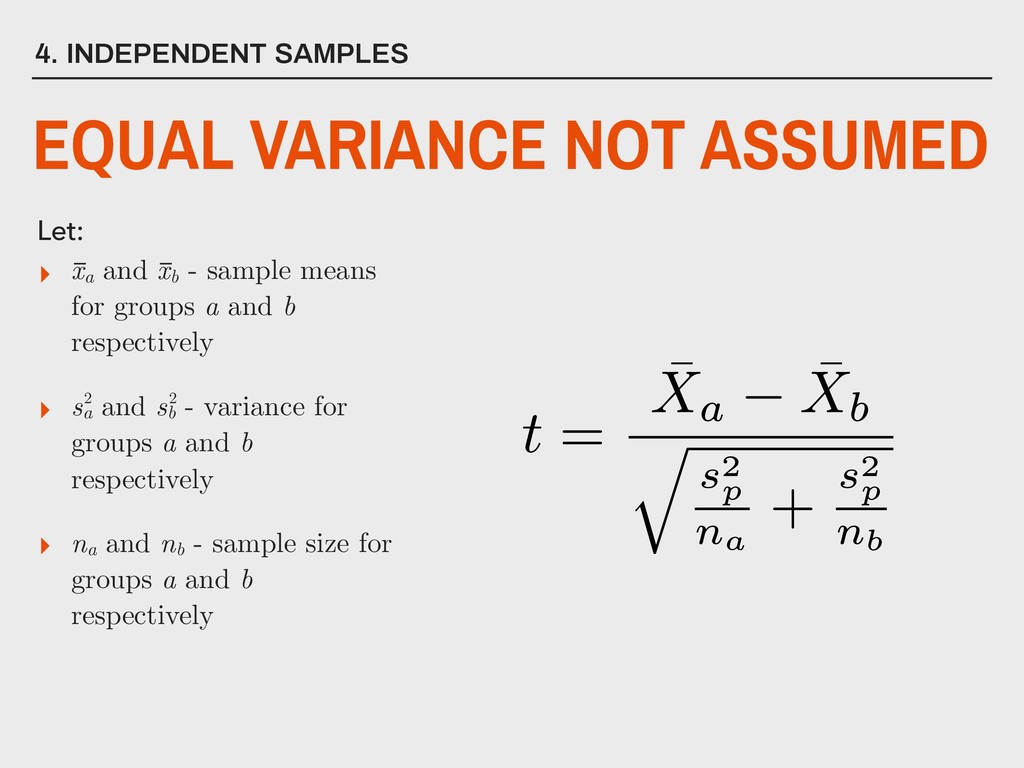
▸ xa and xb - sample means for groups a
and b respectively ▸ sa and sb - variance for groups a and b respectively ▸ na and nb - sample size for groups a and b respectively 4. INDEPENDENT SAMPLES Let: EQUAL VARIANCE NOT ASSUMED _ _ 2 2 -
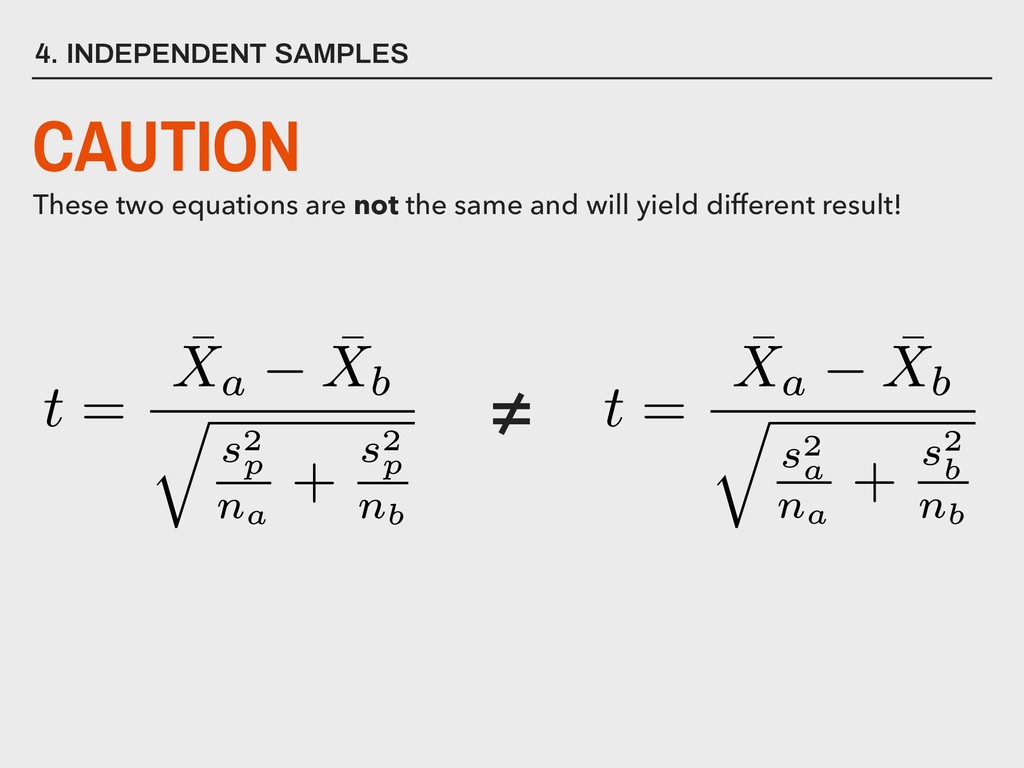
4. INDEPENDENT SAMPLES CAUTION These two equations are not the
same and will yield different result! ≠ -
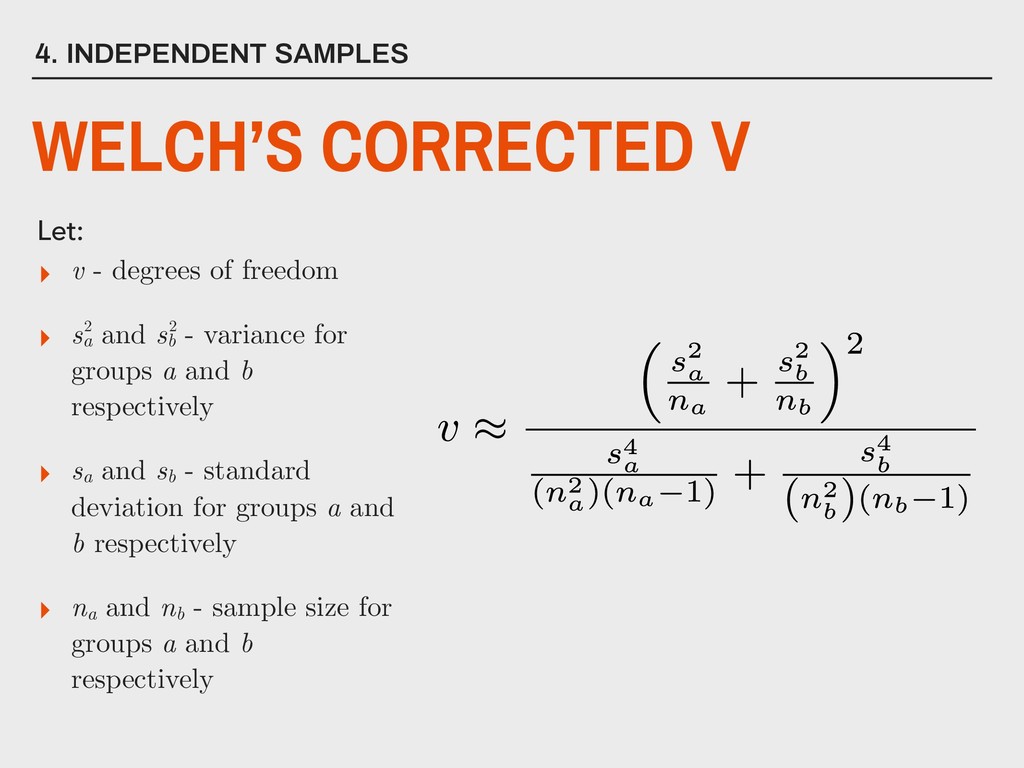
▸ v - degrees of freedom ▸ sa and sb
- variance for groups a and b respectively ▸ sa and sb - standard deviation for groups a and b respectively ▸ na and nb - sample size for groups a and b respectively 4. INDEPENDENT SAMPLES Let: WELCH’S CORRECTED V 2 2 -
MEANS xa y xb Does the mean of xa differ
from xb ? -
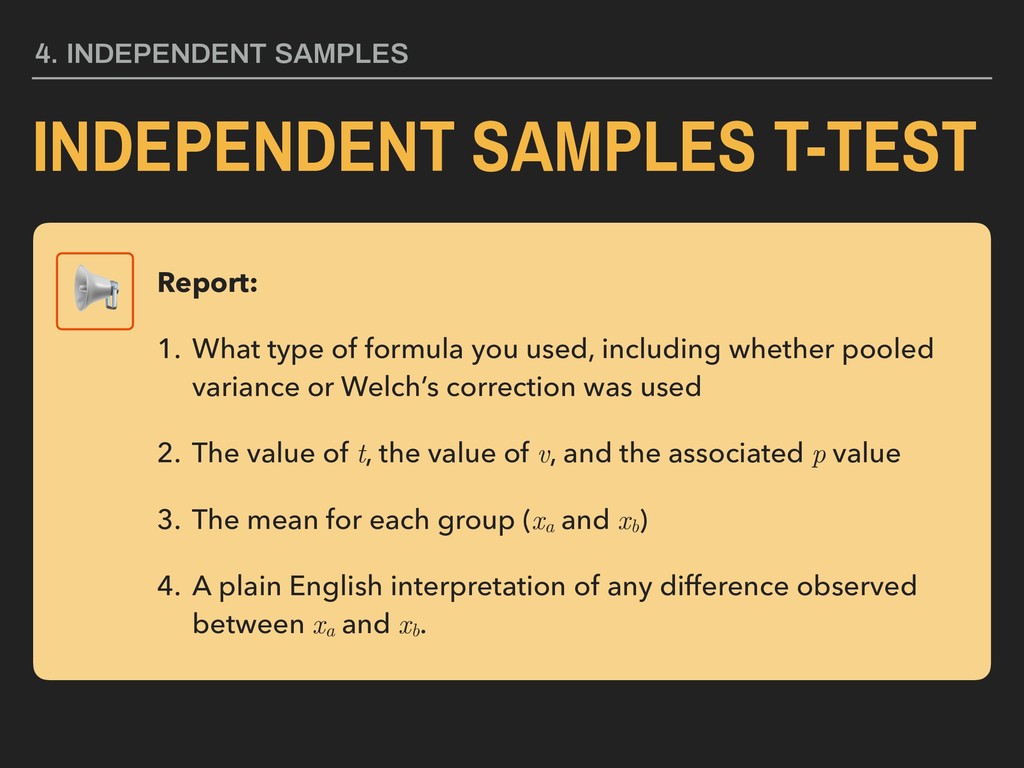
4. INDEPENDENT SAMPLES INDEPENDENT SAMPLES T-TEST Report: 1. What
type of formula you used, including whether pooled variance or Welch’s correction was used 2. The value of t, the value of v, and the associated p value 3. The mean for each group (xa and xb ) 4. A plain English interpretation of any difference observed between xa and xb . -
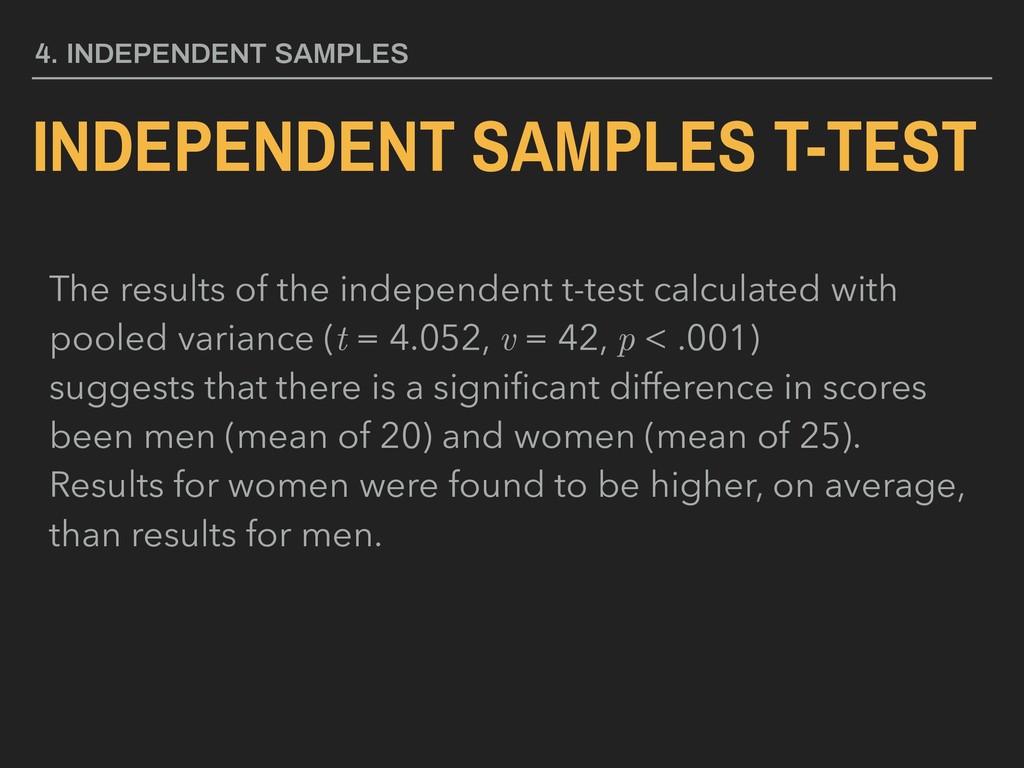
4. INDEPENDENT SAMPLES INDEPENDENT SAMPLES T-TEST The results of the
independent t-test calculated with pooled variance (t = 4.052, v = 42, p < .001) suggests that there is a significant difference in scores been men (mean of 20) and women (mean of 25). Results for women were found to be higher, on average, than results for men. -
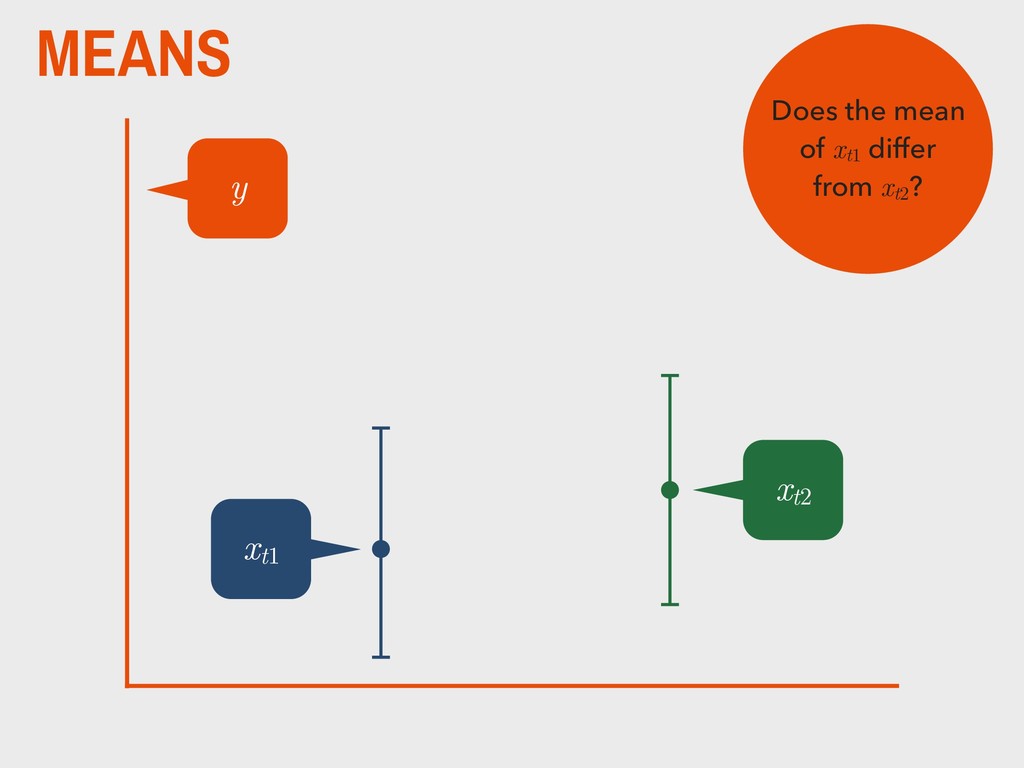
MEANS xt1 y xt2 Does the mean of xt1 differ
from xt2 ? -
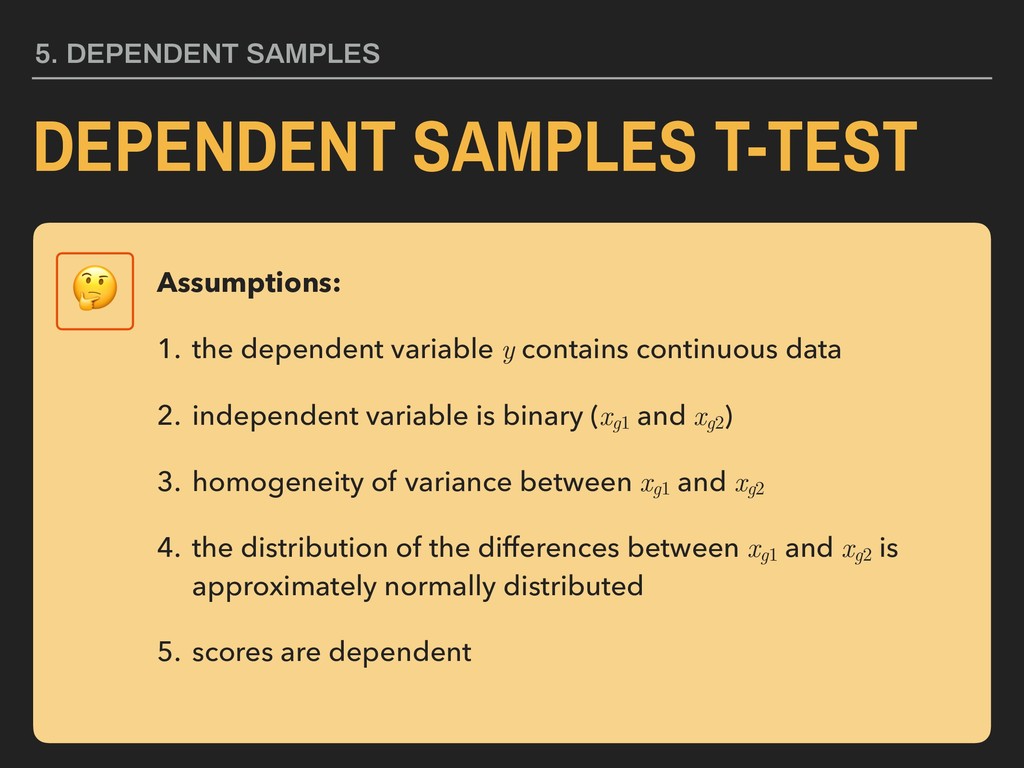
5. DEPENDENT SAMPLES DEPENDENT SAMPLES T-TEST Assumptions: 1. the
dependent variable y contains continuous data 2. independent variable is binary (xg1 and xg2 ) 3. homogeneity of variance between xg1 and xg2 4. the distribution of the differences between xg1 and xg2 is approximately normally distributed 5. scores are dependent -
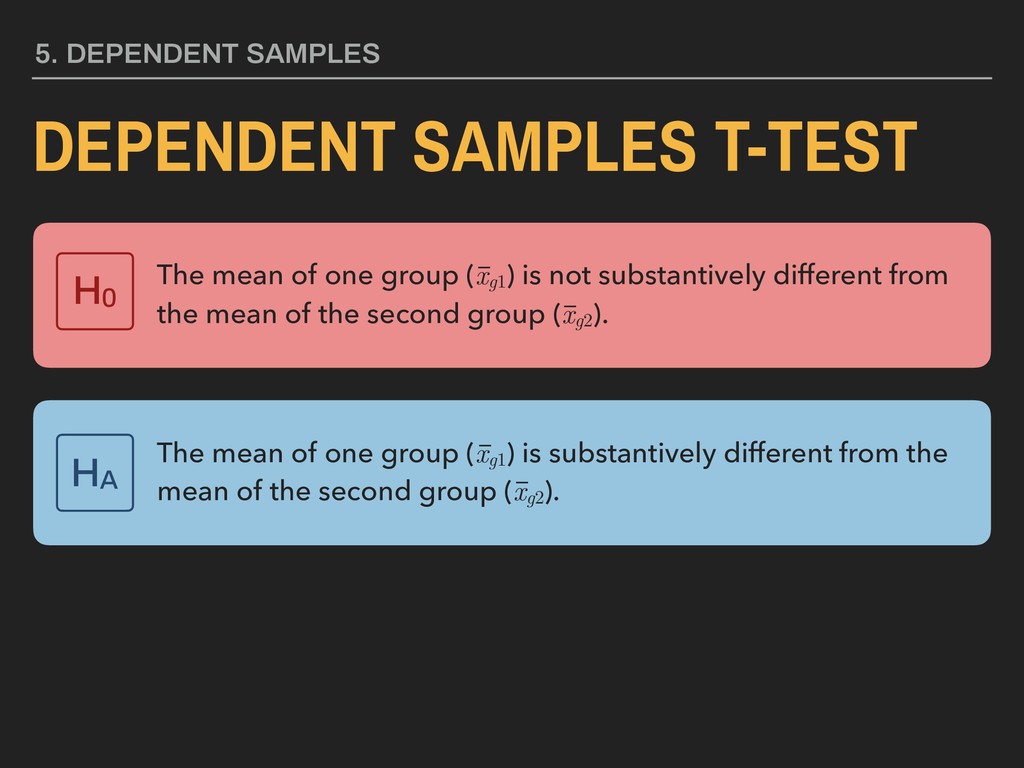
5. DEPENDENT SAMPLES DEPENDENT SAMPLES T-TEST The mean of one
group (xg1 ) is not substantively different from the mean of the second group (xg2 ). H0 The mean of one group (xg1 ) is substantively different from the mean of the second group (xg2 ). HA _ _ _ _ -
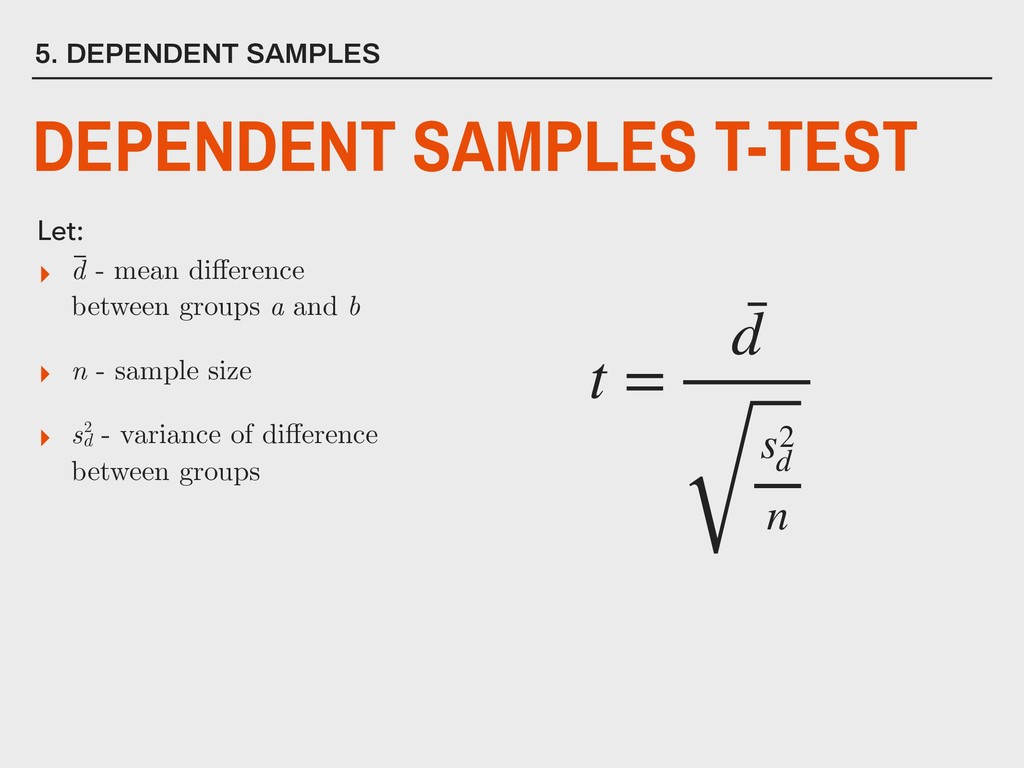
▸ d - mean difference between groups a and b
▸ n - sample size ▸ sd - variance of difference between groups 5. DEPENDENT SAMPLES Let: DEPENDENT SAMPLES T-TEST _ 2 t = ¯ d s2 d n -
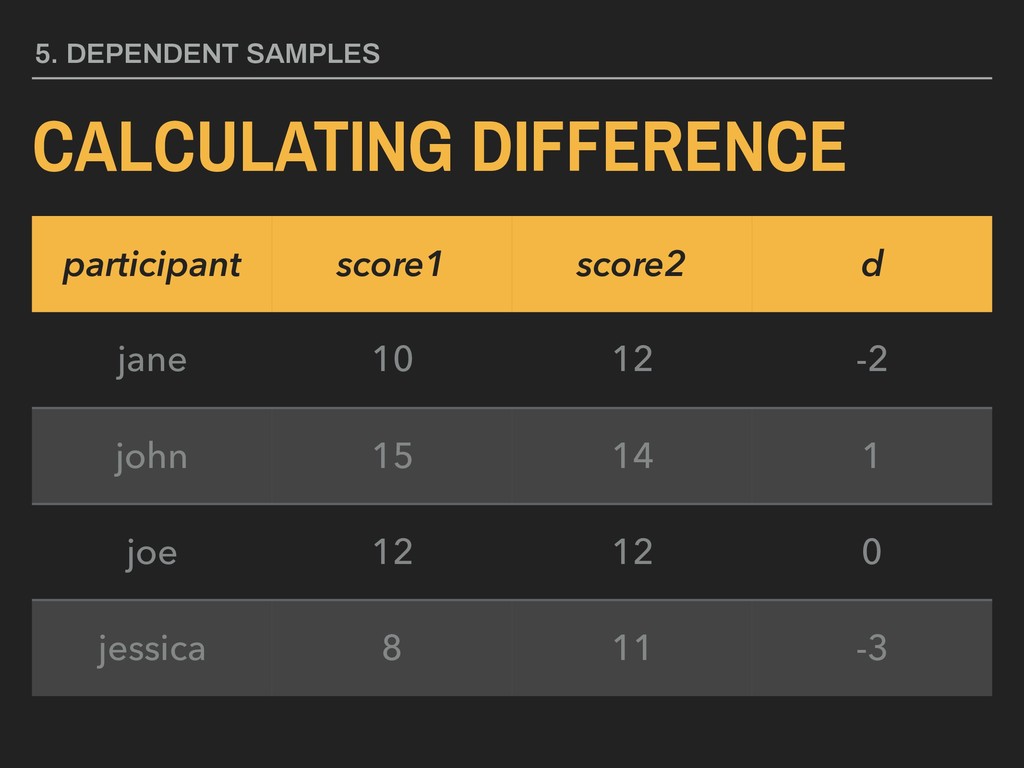
5. DEPENDENT SAMPLES CALCULATING DIFFERENCE participant score1 score2 d jane
10 12 -2 john 15 14 1 joe 12 12 0 jessica 8 11 -3 -
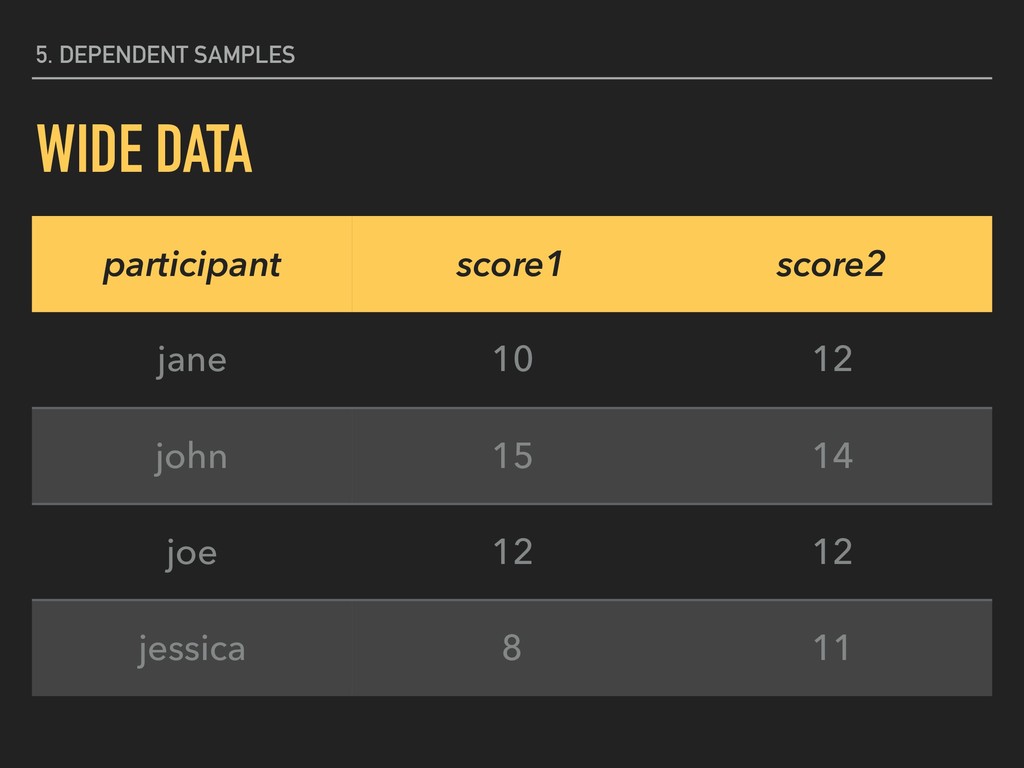
5. DEPENDENT SAMPLES WIDE DATA participant score1 score2 jane 10
12 john 15 14 joe 12 12 jessica 8 11 -
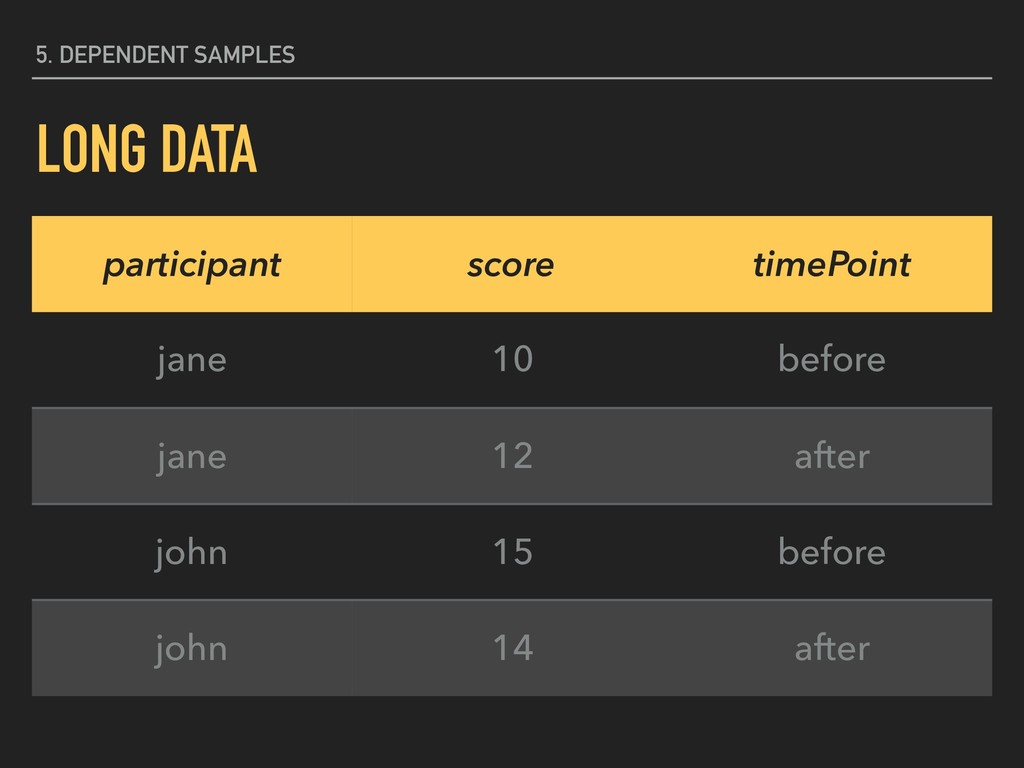
5. DEPENDENT SAMPLES LONG DATA participant score timePoint jane 10
before jane 12 after john 15 before john 14 after -
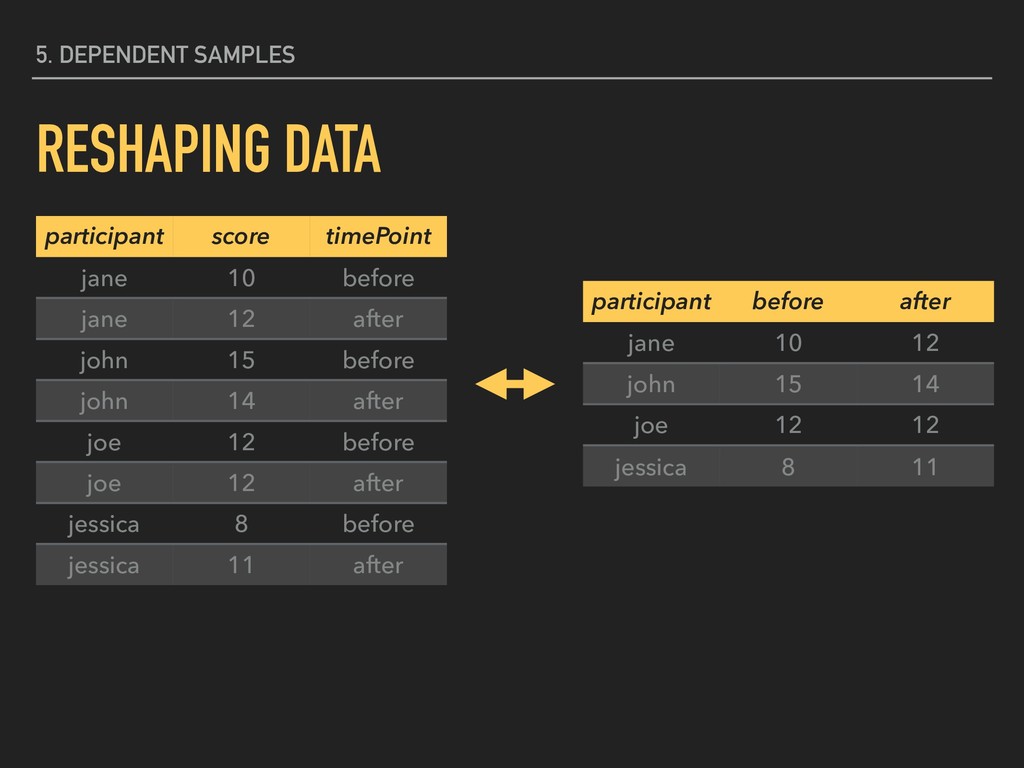
5. DEPENDENT SAMPLES RESHAPING DATA participant score timePoint jane 10
before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after participant before after jane 10 12 john 15 14 joe 12 12 jessica 8 11 -
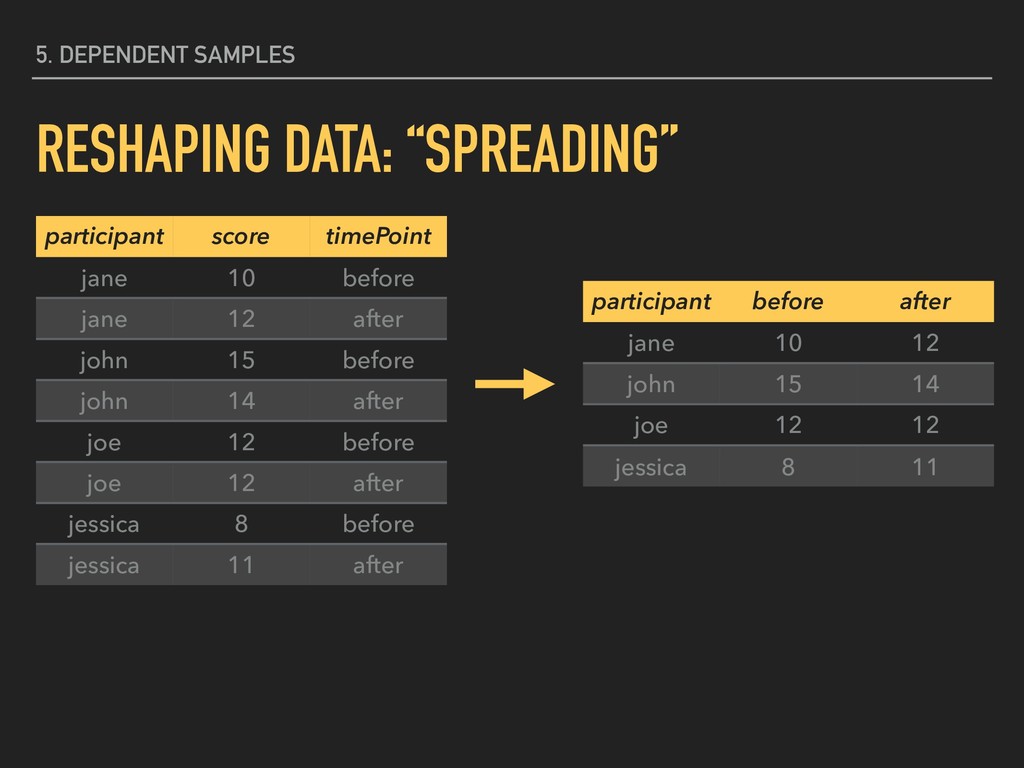
5. DEPENDENT SAMPLES RESHAPING DATA: “SPREADING” participant score timePoint jane
10 before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after participant before after jane 10 12 john 15 14 joe 12 12 jessica 8 11 -
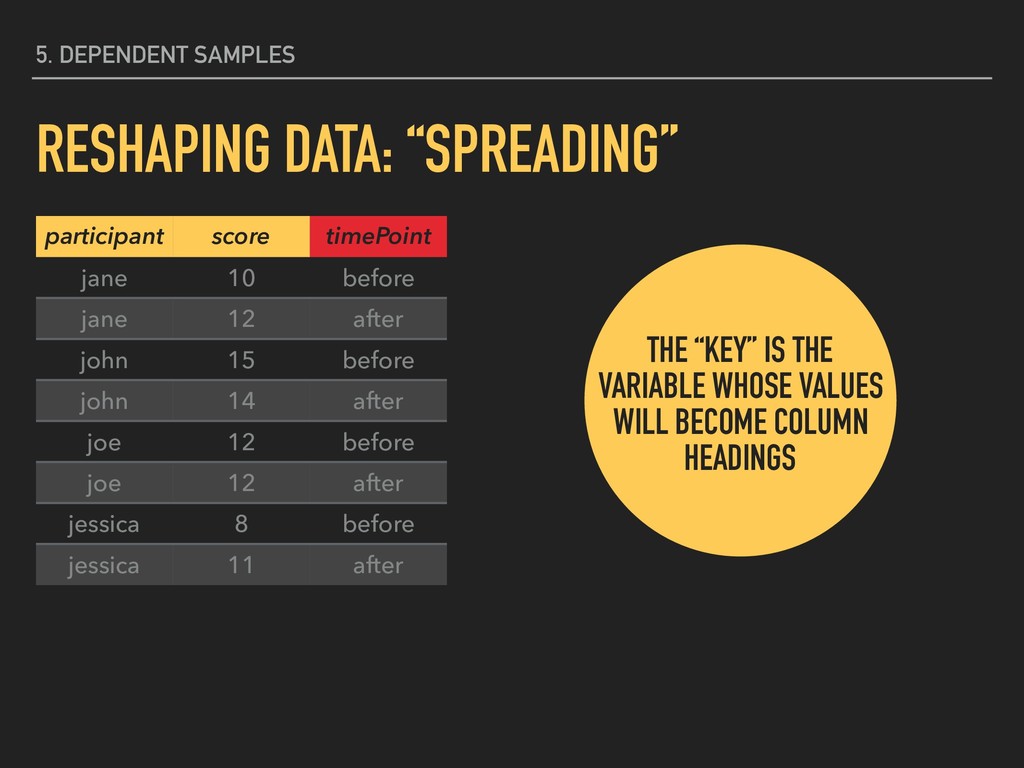
5. DEPENDENT SAMPLES RESHAPING DATA: “SPREADING” participant score timePoint jane
10 before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after THE “KEY” IS THE VARIABLE WHOSE VALUES WILL BECOME COLUMN HEADINGS -
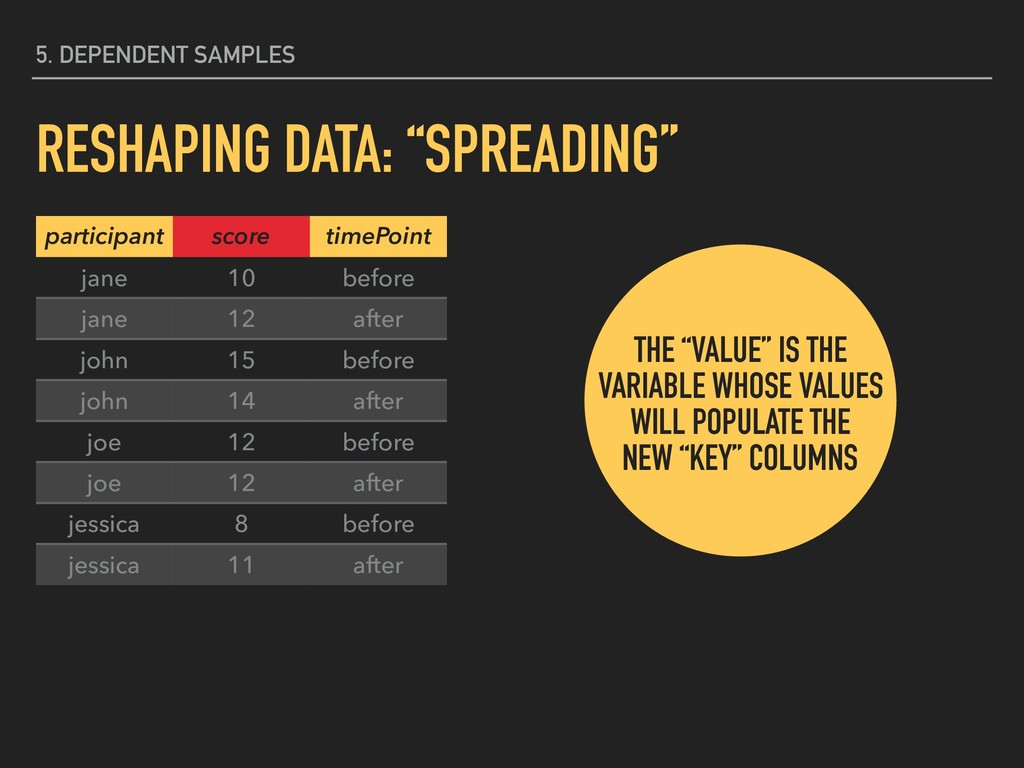
5. DEPENDENT SAMPLES RESHAPING DATA: “SPREADING” participant score timePoint jane
10 before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after THE “VALUE” IS THE VARIABLE WHOSE VALUES WILL POPULATE THE NEW “KEY” COLUMNS -
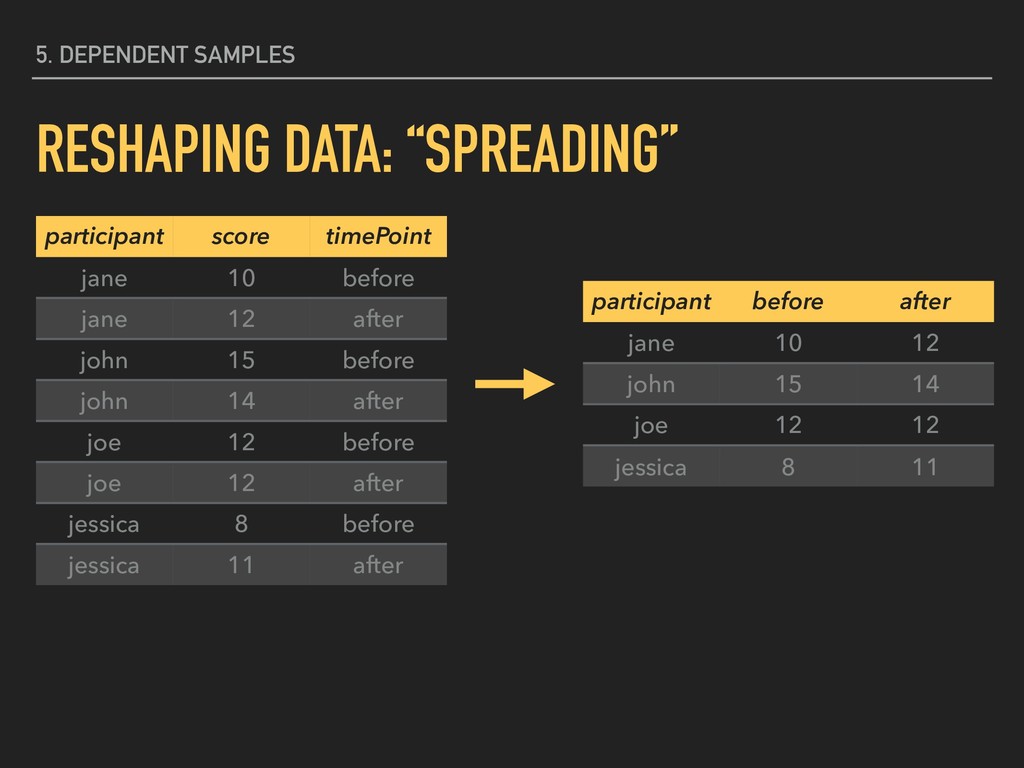
5. DEPENDENT SAMPLES RESHAPING DATA: “SPREADING” participant score timePoint jane
10 before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after participant before after jane 10 12 john 15 14 joe 12 12 jessica 8 11 -
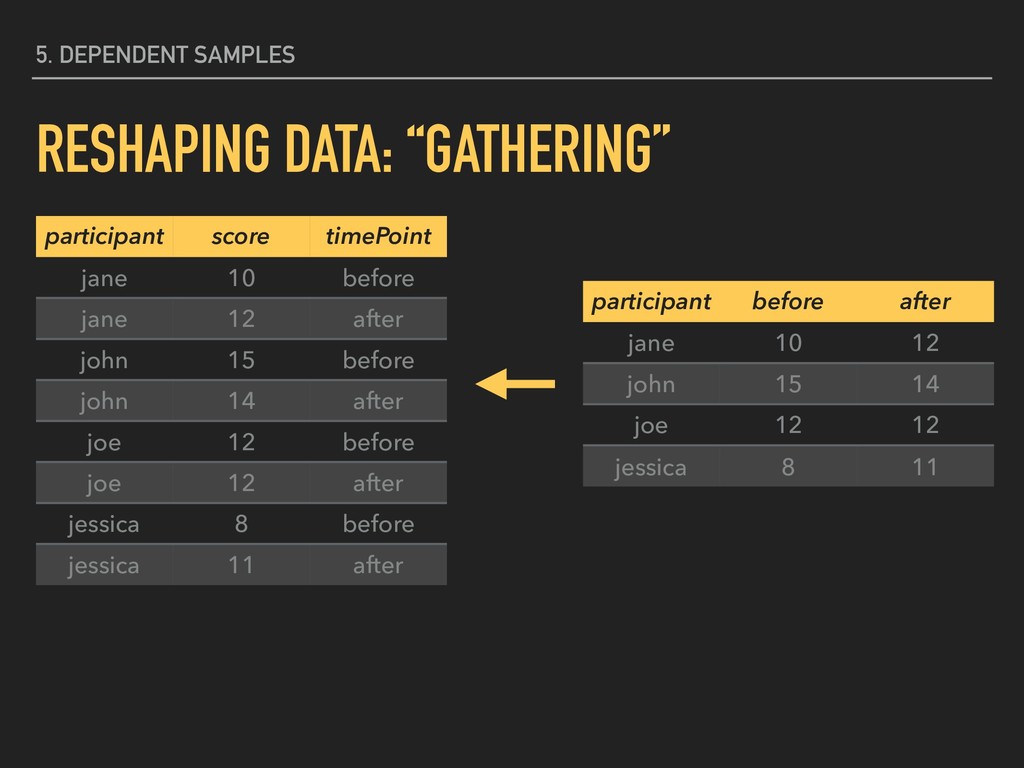
5. DEPENDENT SAMPLES RESHAPING DATA: “GATHERING” participant score timePoint jane
10 before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after participant before after jane 10 12 john 15 14 joe 12 12 jessica 8 11 -
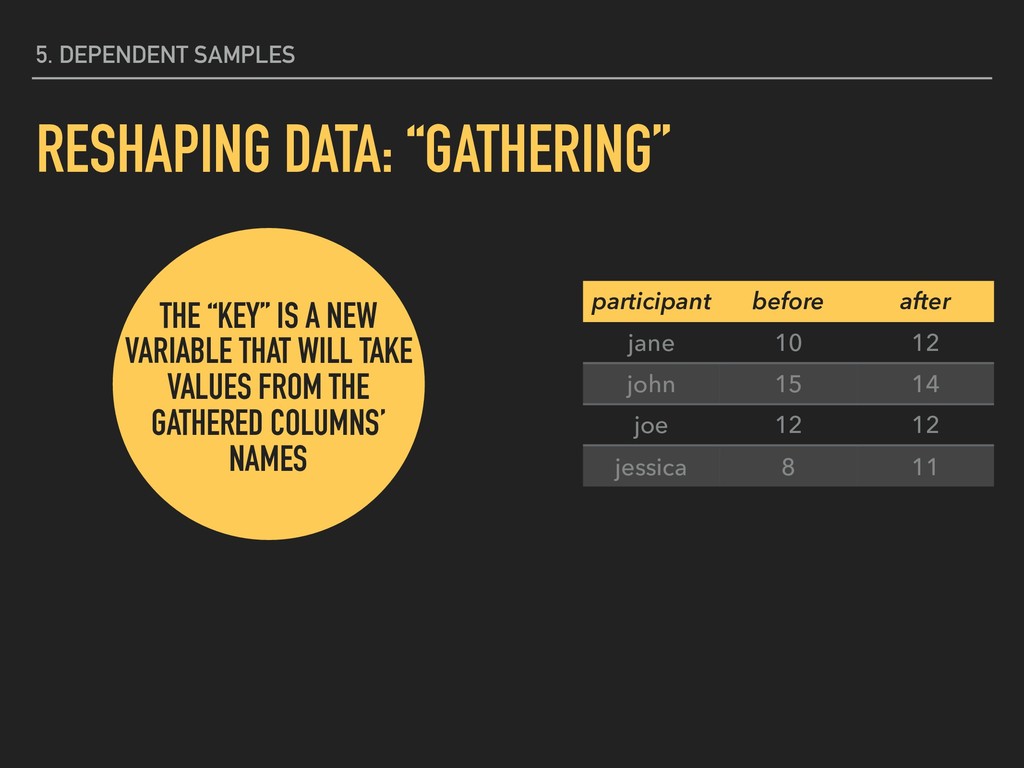
5. DEPENDENT SAMPLES RESHAPING DATA: “GATHERING” participant before after jane
10 12 john 15 14 joe 12 12 jessica 8 11 THE “KEY” IS A NEW VARIABLE THAT WILL TAKE VALUES FROM THE GATHERED COLUMNS’ NAMES -
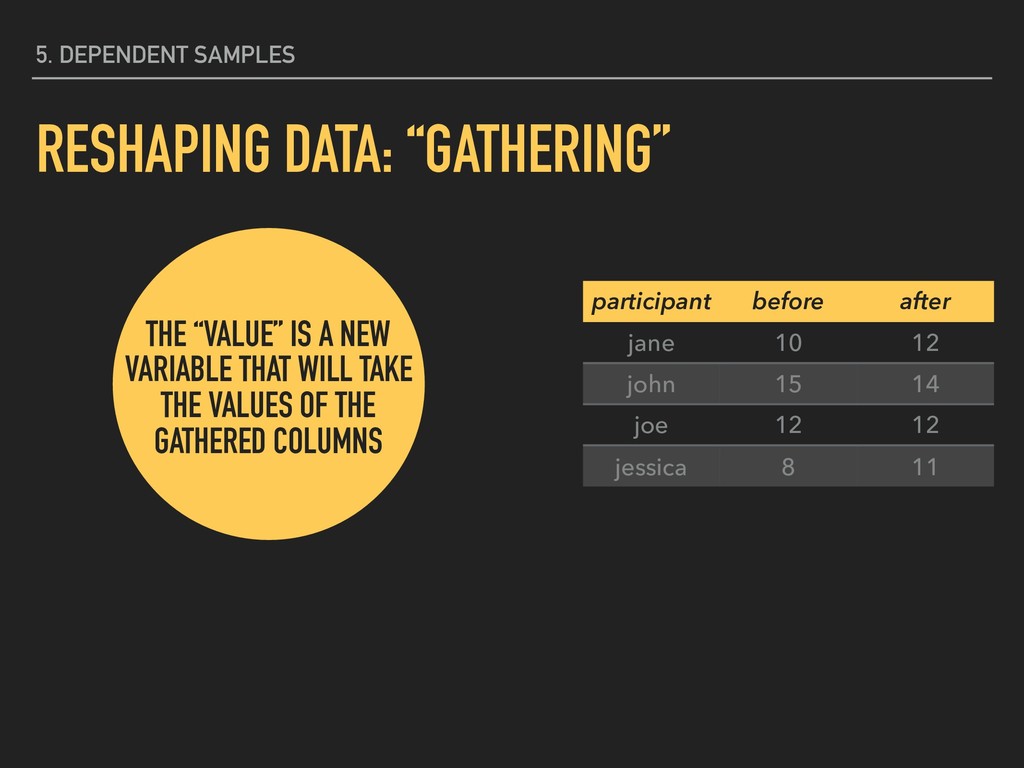
5. DEPENDENT SAMPLES RESHAPING DATA: “GATHERING” participant before after jane
10 12 john 15 14 joe 12 12 jessica 8 11 THE “VALUE” IS A NEW VARIABLE THAT WILL TAKE THE VALUES OF THE GATHERED COLUMNS -
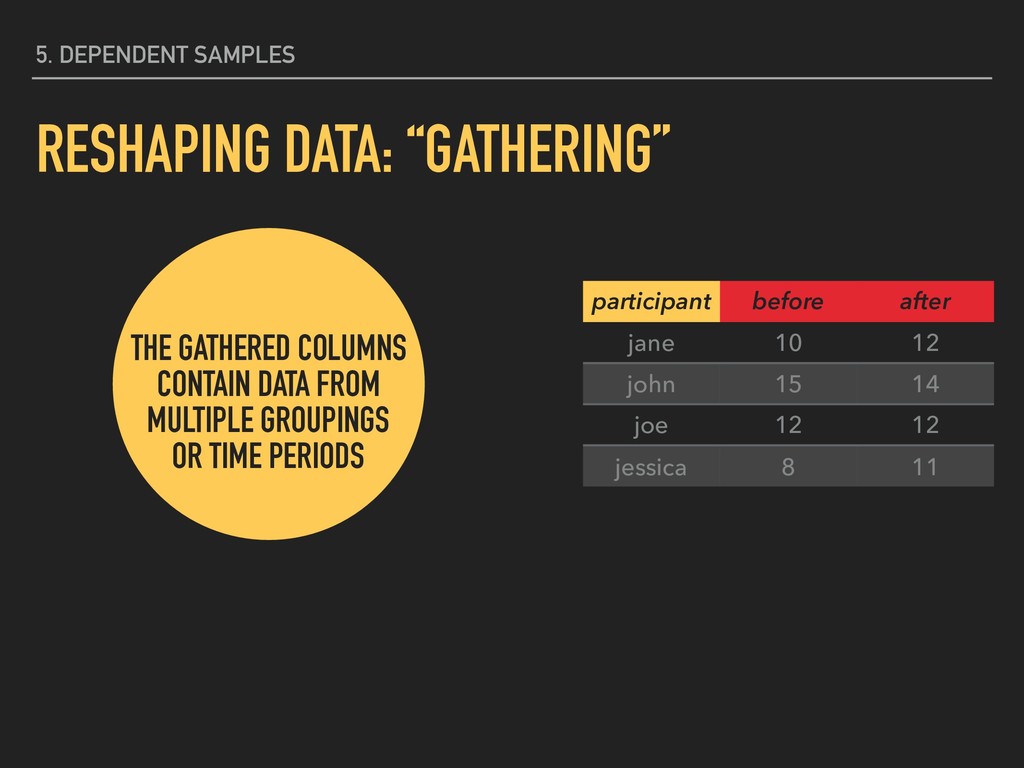
5. DEPENDENT SAMPLES RESHAPING DATA: “GATHERING” participant before after jane
10 12 john 15 14 joe 12 12 jessica 8 11 THE GATHERED COLUMNS CONTAIN DATA FROM MULTIPLE GROUPINGS OR TIME PERIODS -
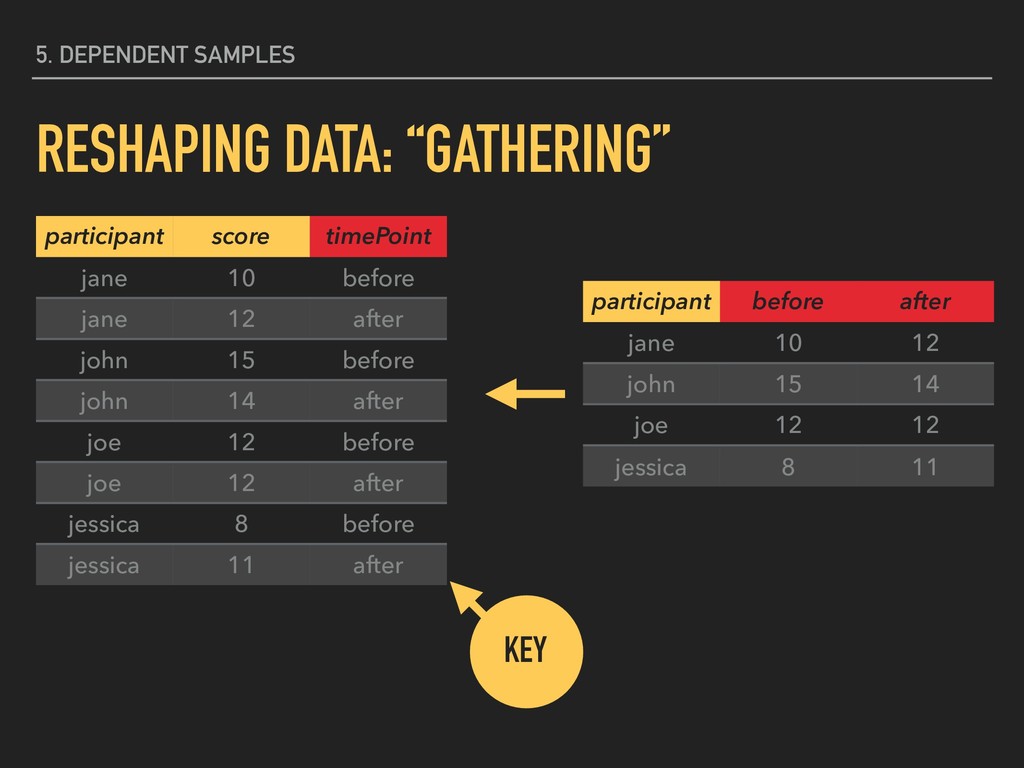
5. DEPENDENT SAMPLES RESHAPING DATA: “GATHERING” participant score timePoint jane
10 before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after participant before after jane 10 12 john 15 14 joe 12 12 jessica 8 11 KEY -
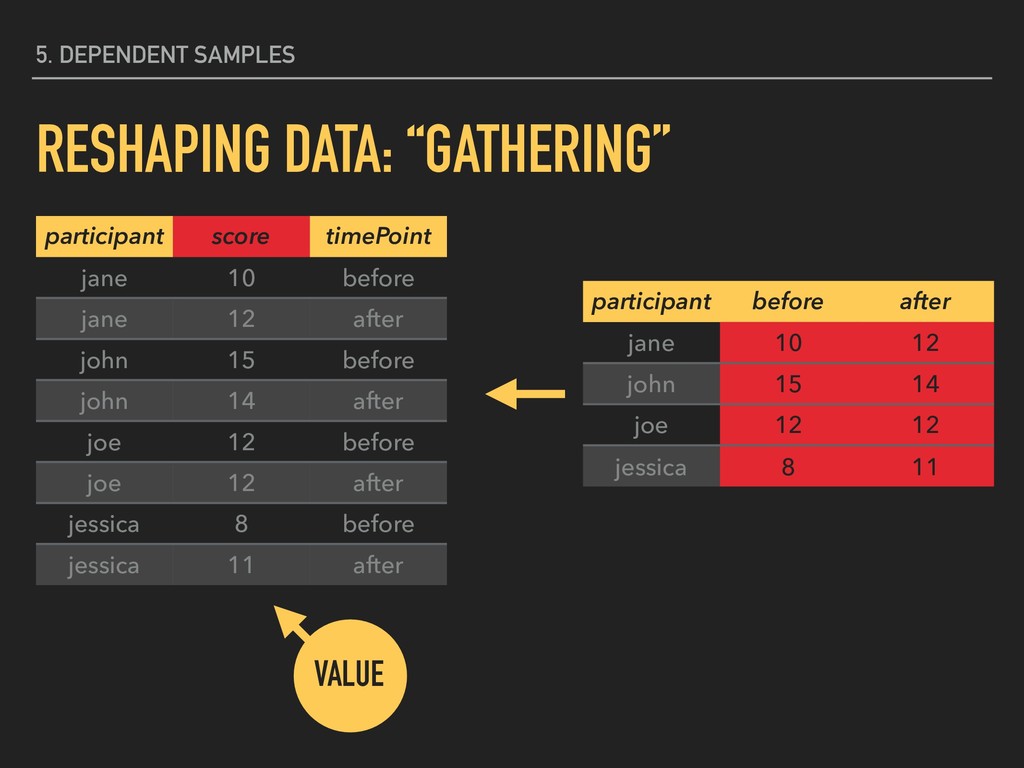
5. DEPENDENT SAMPLES RESHAPING DATA: “GATHERING” participant score timePoint jane
10 before jane 12 after john 15 before john 14 after joe 12 before joe 12 after jessica 8 before jessica 11 after participant before after jane 10 12 john 15 14 joe 12 12 jessica 8 11 VALUE -
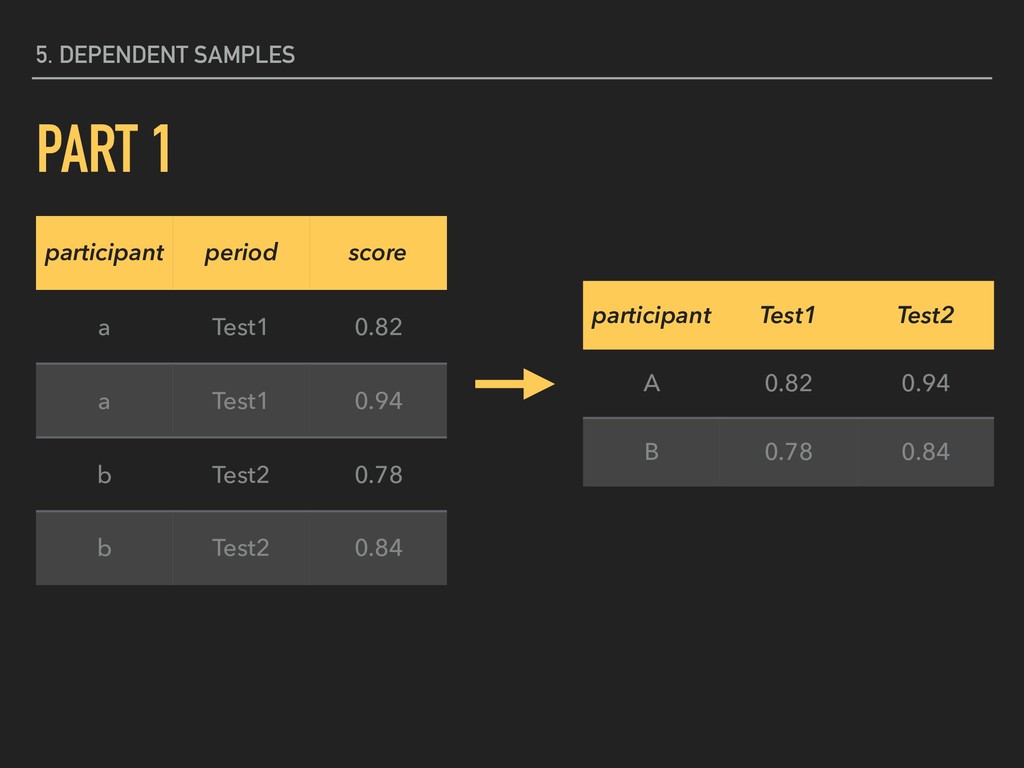
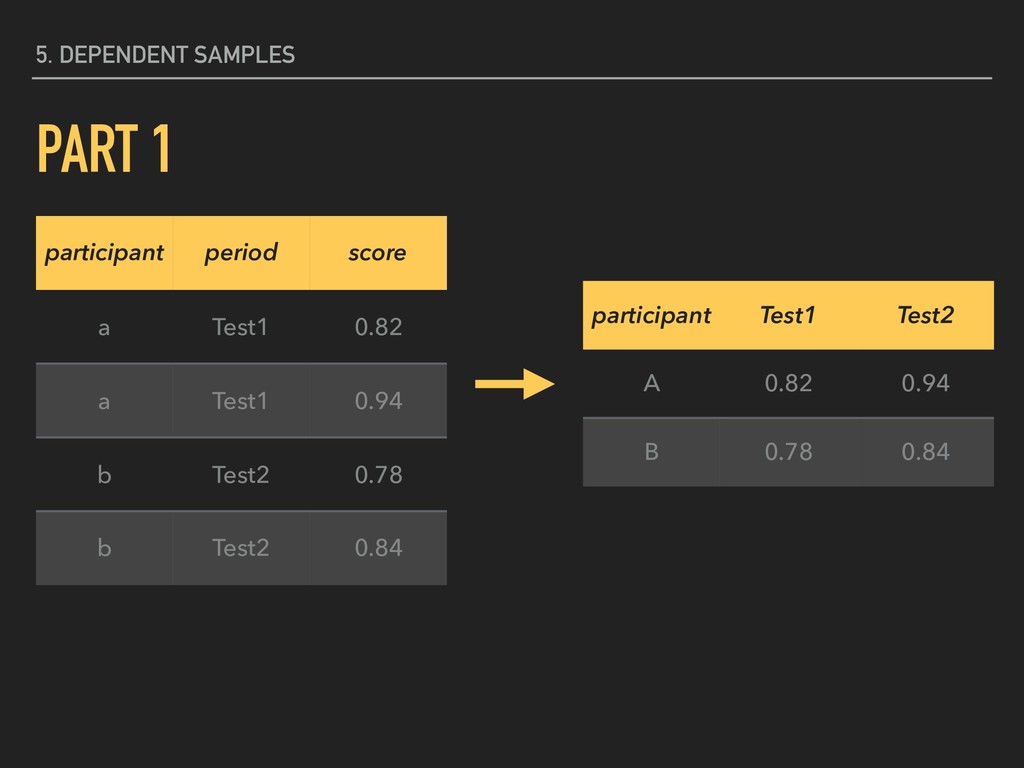
5. DEPENDENT SAMPLES PART 1 participant period score a Test1
0.82 a Test1 0.94 b Test2 0.78 b Test2 0.84 participant Test1 Test2 A 0.82 0.94 B 0.78 0.84 -
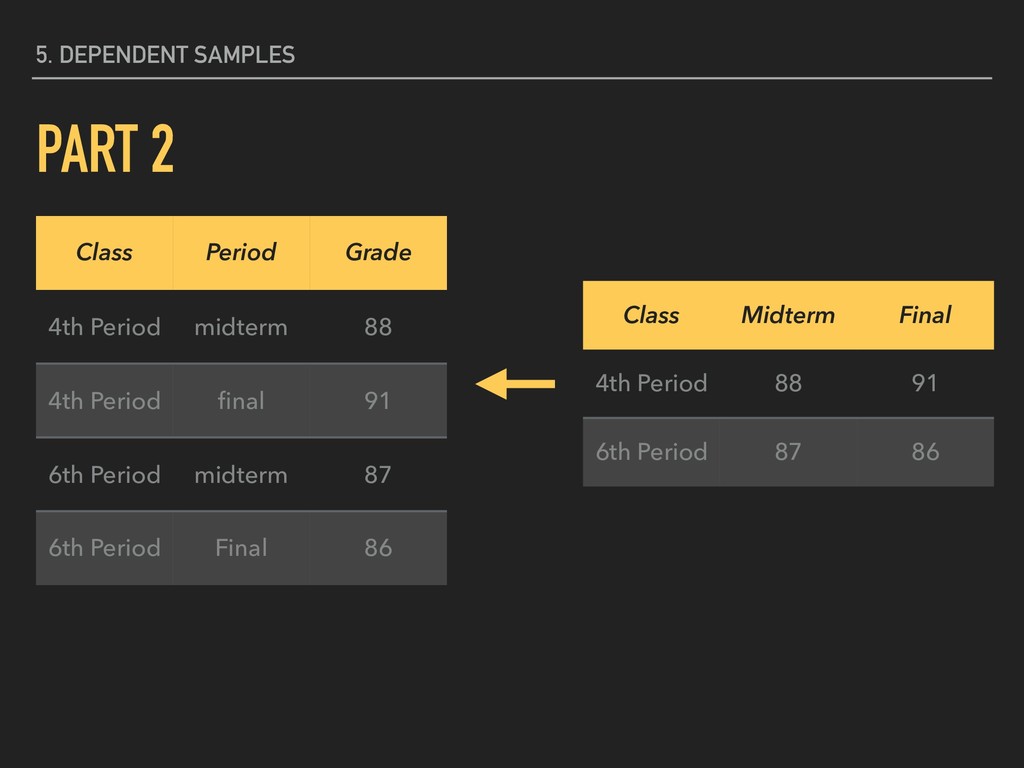
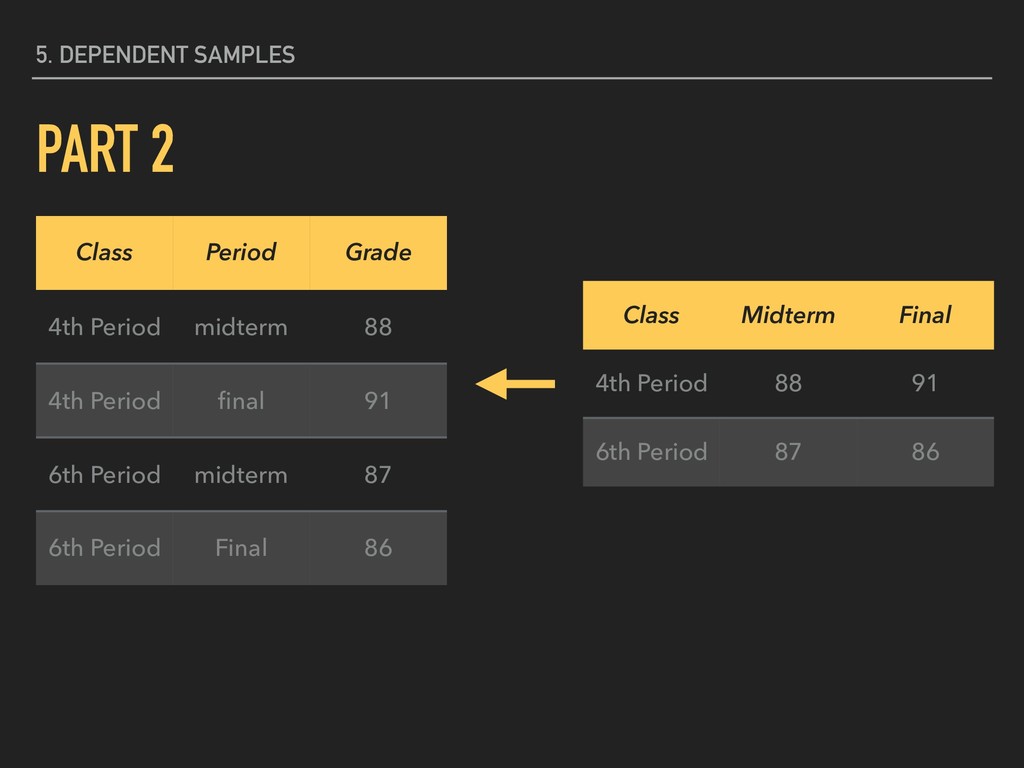
5. DEPENDENT SAMPLES PART 2 Class Period Grade 4th Period
midterm 88 4th Period final 91 6th Period midterm 87 6th Period Final 86 Class Midterm Final 4th Period 88 91 6th Period 87 86 -
5. DEPENDENT SAMPLES PART 1 participant period score a Test1
0.82 a Test1 0.94 b Test2 0.78 b Test2 0.84 participant Test1 Test2 A 0.82 0.94 B 0.78 0.84 -
5. DEPENDENT SAMPLES PART 2 Class Period Grade 4th Period
midterm 88 4th Period final 91 6th Period midterm 87 6th Period Final 86 Class Midterm Final 4th Period 88 91 6th Period 87 86 -
CHALLENGE Statistical significance and real world significance are not the
same thing. Effect sizes give us a language for speaking about real world significance. -
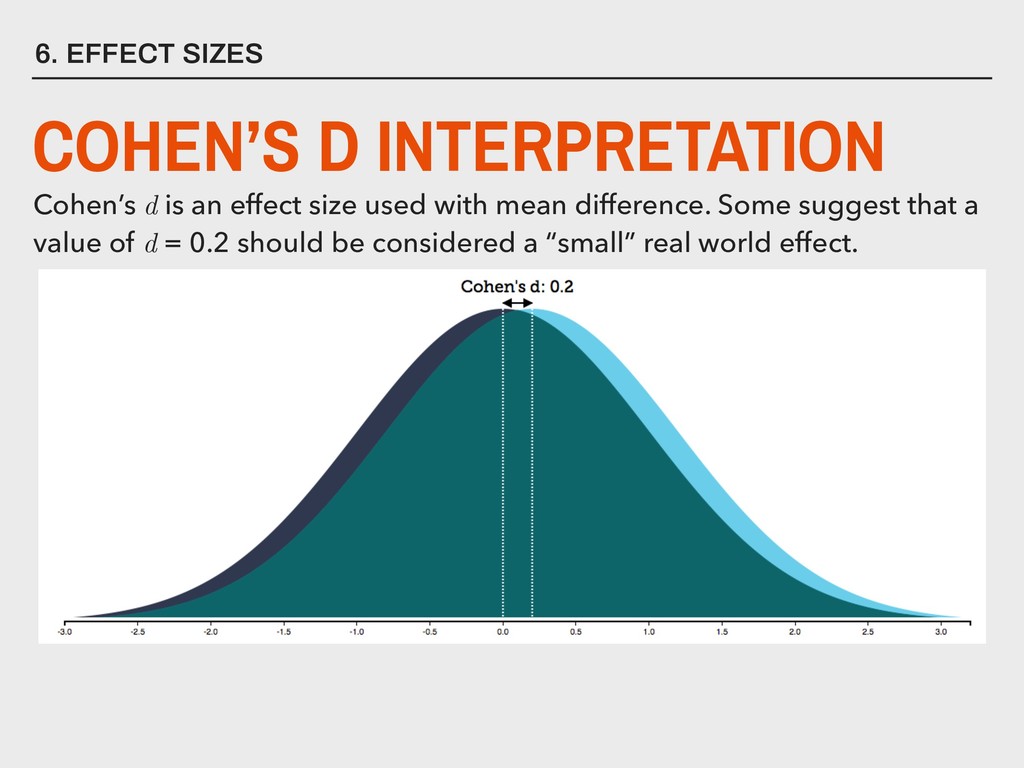
6. EFFECT SIZES COHEN’S D INTERPRETATION Cohen’s d is an
effect size used with mean difference. Some suggest that a value of d = 0.2 should be considered a “small” real world effect. -
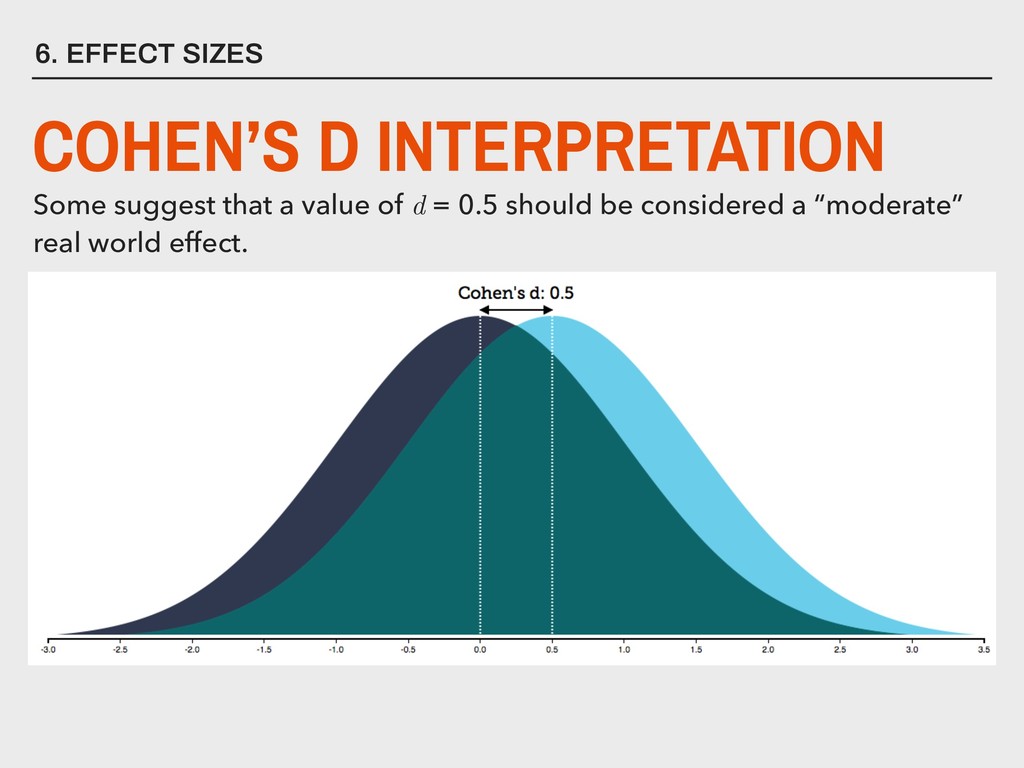
6. EFFECT SIZES COHEN’S D INTERPRETATION Some suggest that a
value of d = 0.5 should be considered a “moderate” real world effect. -
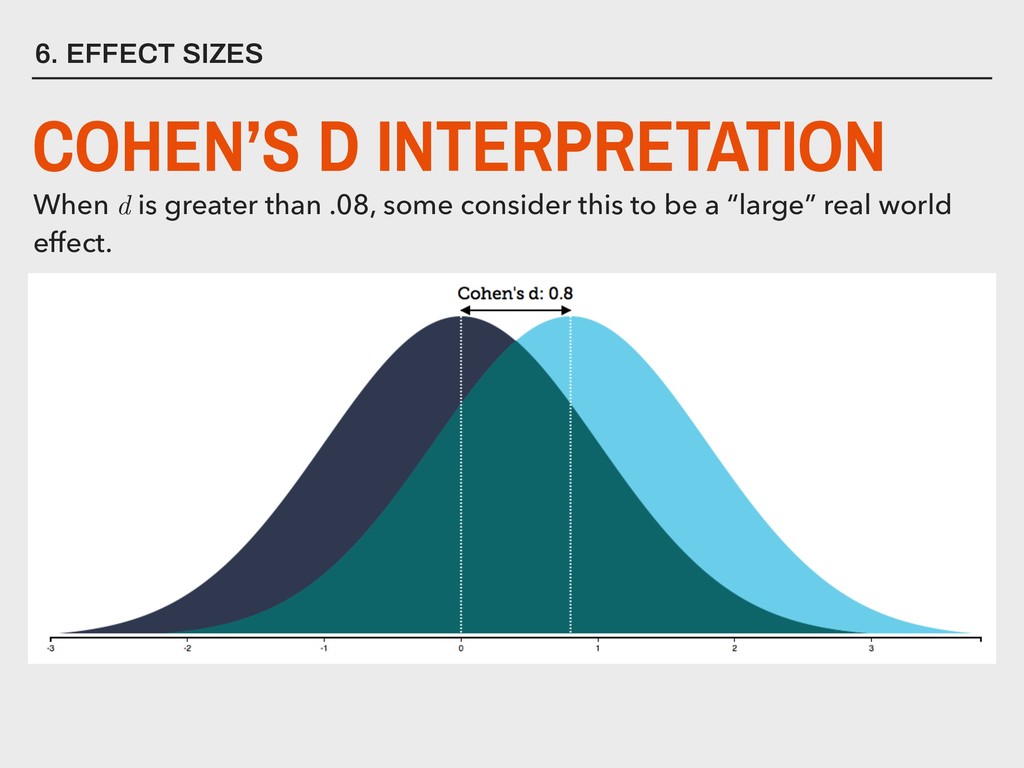
6. EFFECT SIZES COHEN’S D INTERPRETATION When d is greater
than .08, some consider this to be a “large” real world effect. -
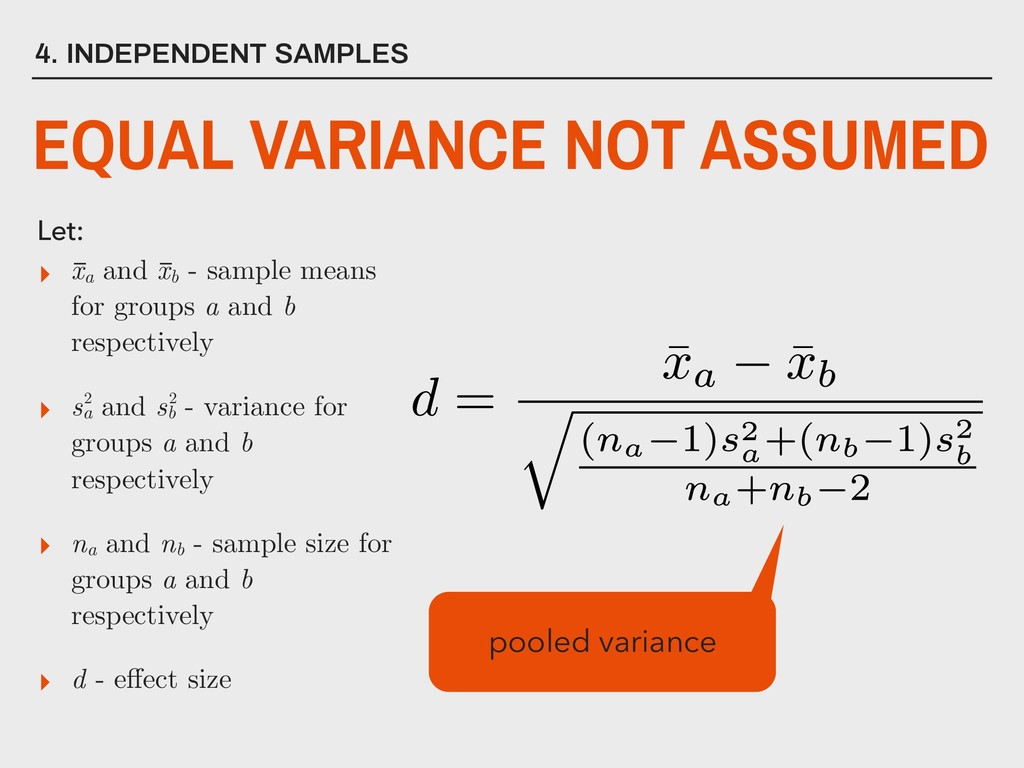
▸ xa and xb - sample means for groups a
and b respectively ▸ sa and sb - variance for groups a and b respectively ▸ na and nb - sample size for groups a and b respectively ▸ d - effect size 4. INDEPENDENT SAMPLES Let: EQUAL VARIANCE NOT ASSUMED _ _ 2 2 pooled variance -
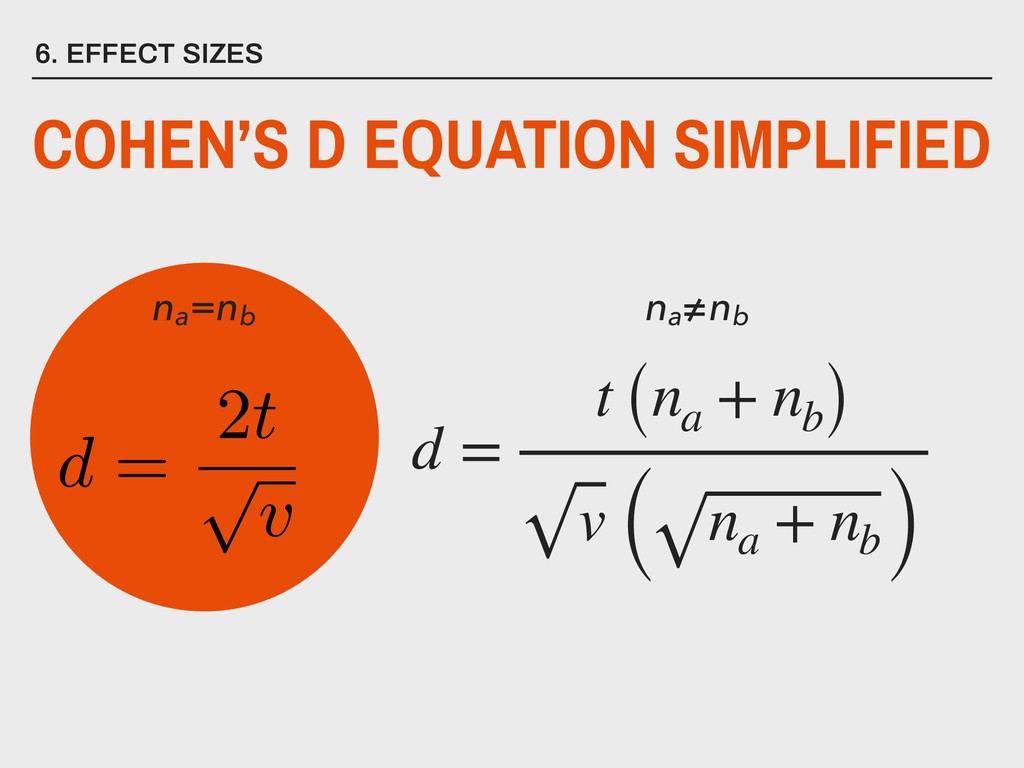
6. EFFECT SIZES COHEN’S D EQUATION SIMPLIFIED na =nb na
≠nb d = t (na + nb) v ( na + nb) -
AGENDA REVIEW 7. BACK MATTER 2. Revisiting Distributions 3. One
Sample 4. Independent Samples 5. Dependent Samples 6. Effect Sizes -
REMINDERS 7. BACK MATTER ITS feels that they have found
the solution to the various issues in the lab. If you have any problems - including RStudio missing or packages not installing, let me know asap. SOC 5050 annotated bibliographies were due today! Lab 06 and Lecture Prep 08 are due before the next lecture. Feedback backlog being unjammed this week - keep eyes out for feedback on PS-01 and PS-02 - please make sure to apply feedback moving forward with PS-04 etc.