Share
Hardwood: Building a Parquet Library From Scratch (With a Little Help From AI) -- Devoxx Belgium 2026
Apache Parquet has become the lingua franca of the modern data ecosystem, powering data lakes and table formats like Apache Iceberg—but for Java, the go-to library parquet-java pulls in Hadoop and a truckload of other dependencies, and its reader is single-threaded. This was bugging me enough to start Hardwood, a brand-new Parquet parser written from scratch in modern Java, applying some of the performance lessons learned from the One Billion Row Challenge. Come and join me for this talk, where we'll look at:
- The internals of the Parquet format and what makes parallelizing its decoding surprisingly tricky
- Techniques for achieving high throughput, such as page-level parallelism, adaptive prefetching, and avoiding auto-boxing in hot loops
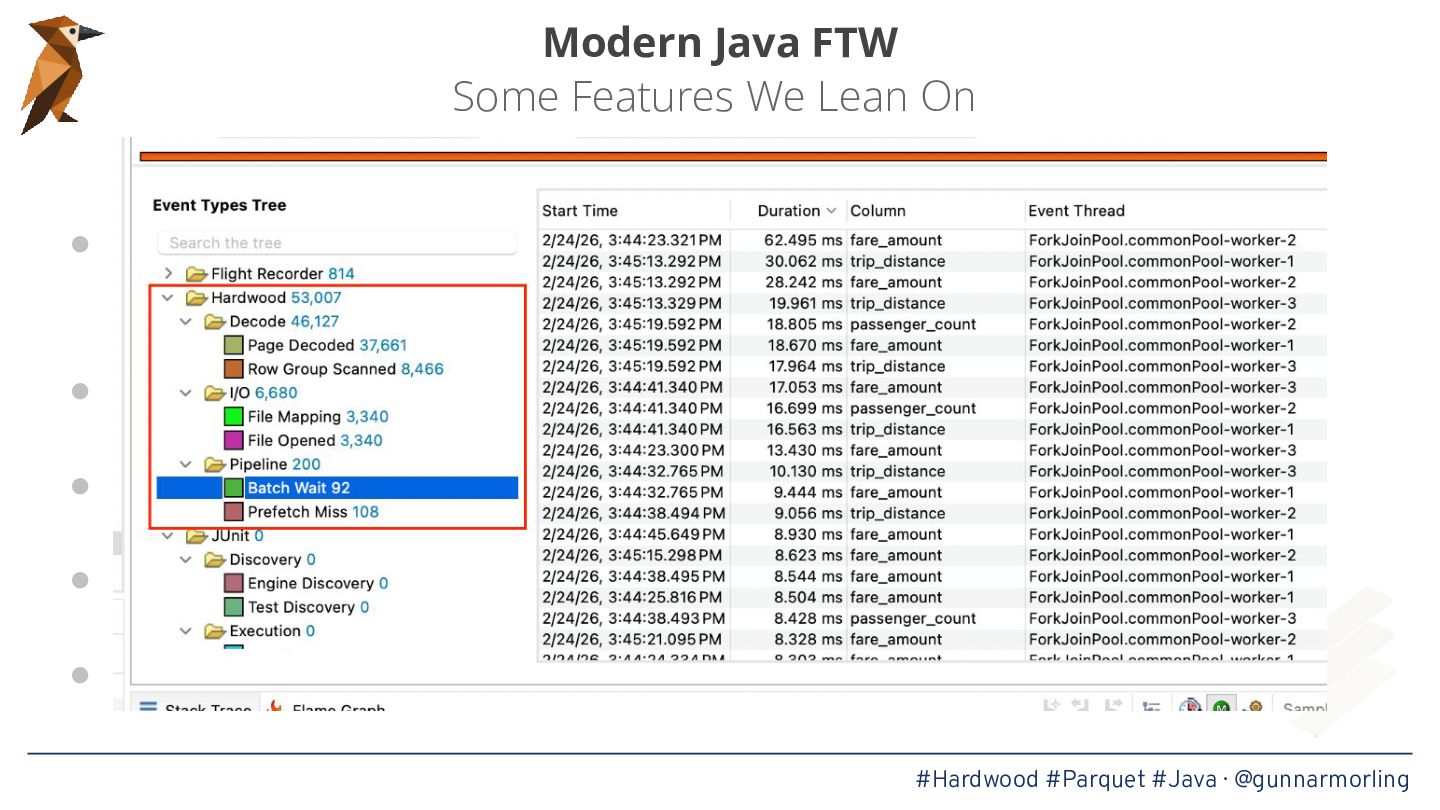
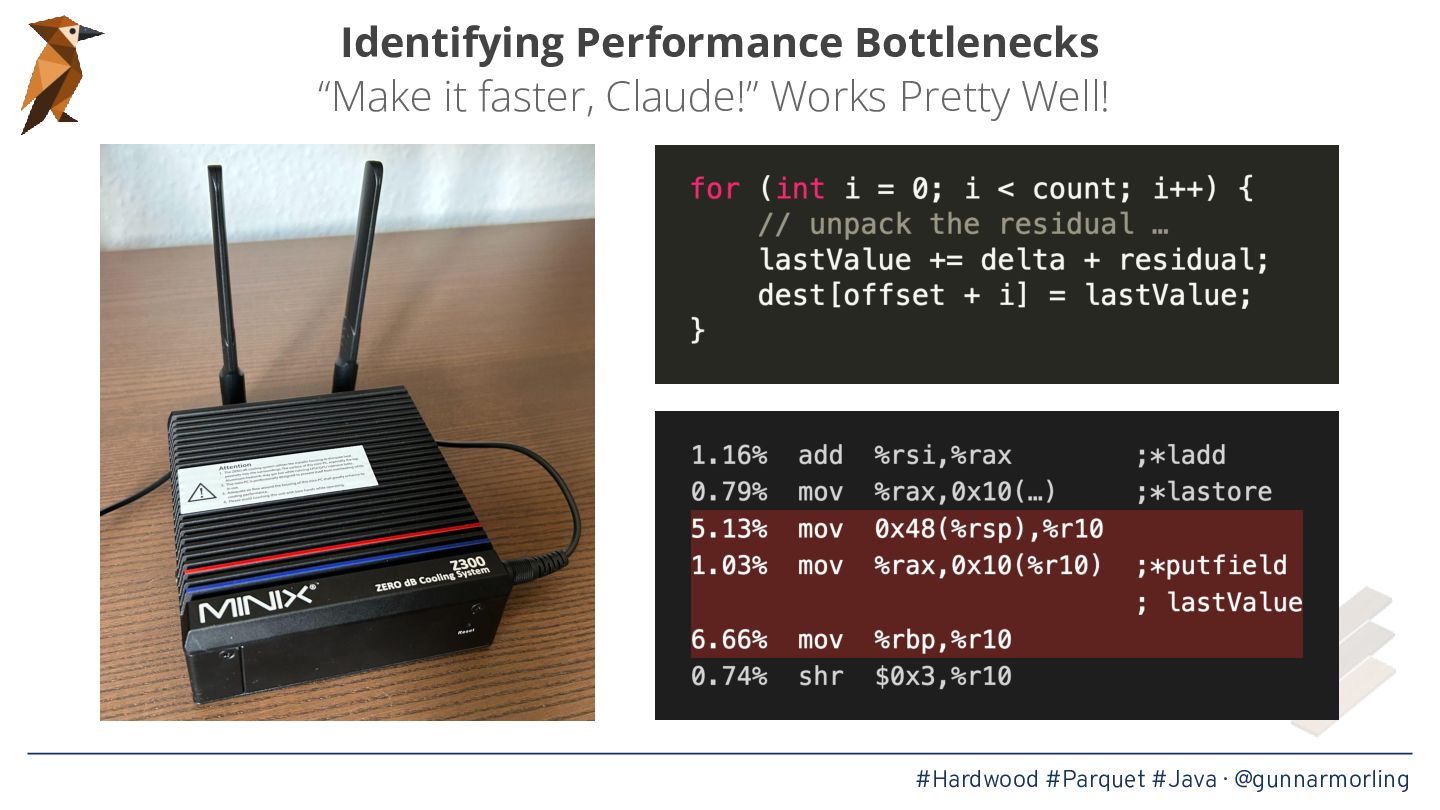
- How to use JDK Flight Recorder for identifying performance bottlenecks
- Practical learnings from using AI (specifically, Claude Code) as a coding companion—what works well, where you need to stay sharp, and why "built with AI" doesn't mean "vibe-coded"
Whether you're interested in file formats, Java performance, or getting a realistic take on AI-assisted development, there should be something in here for you.
Gunnar Morling
Transcript
51 slides
-
Library Hardwood: Building a Parquet Parser From Scratch (With a
Little Help From AI) Gunnar Morling @gunnarmorling © Dale Cruse https://flic.kr/p/2s68Vpa (CC BY 4.0) -
What if accessing Parquet in Java didn’t need Hadoop —
and used all your CPU cores? #Hardwood #Parquet #Java · @gunnarmorling -
Gunnar Morling Technologist at Confluent • Creator of Hardwood •
Former project lead of Debezium • kcctl 🧸, JfrUnit, ModiTect, MapStruct • One Billion Row Challenge 🐝🏎 • Java Champion #Hardwood #Parquet #Java · @gunnarmorling -
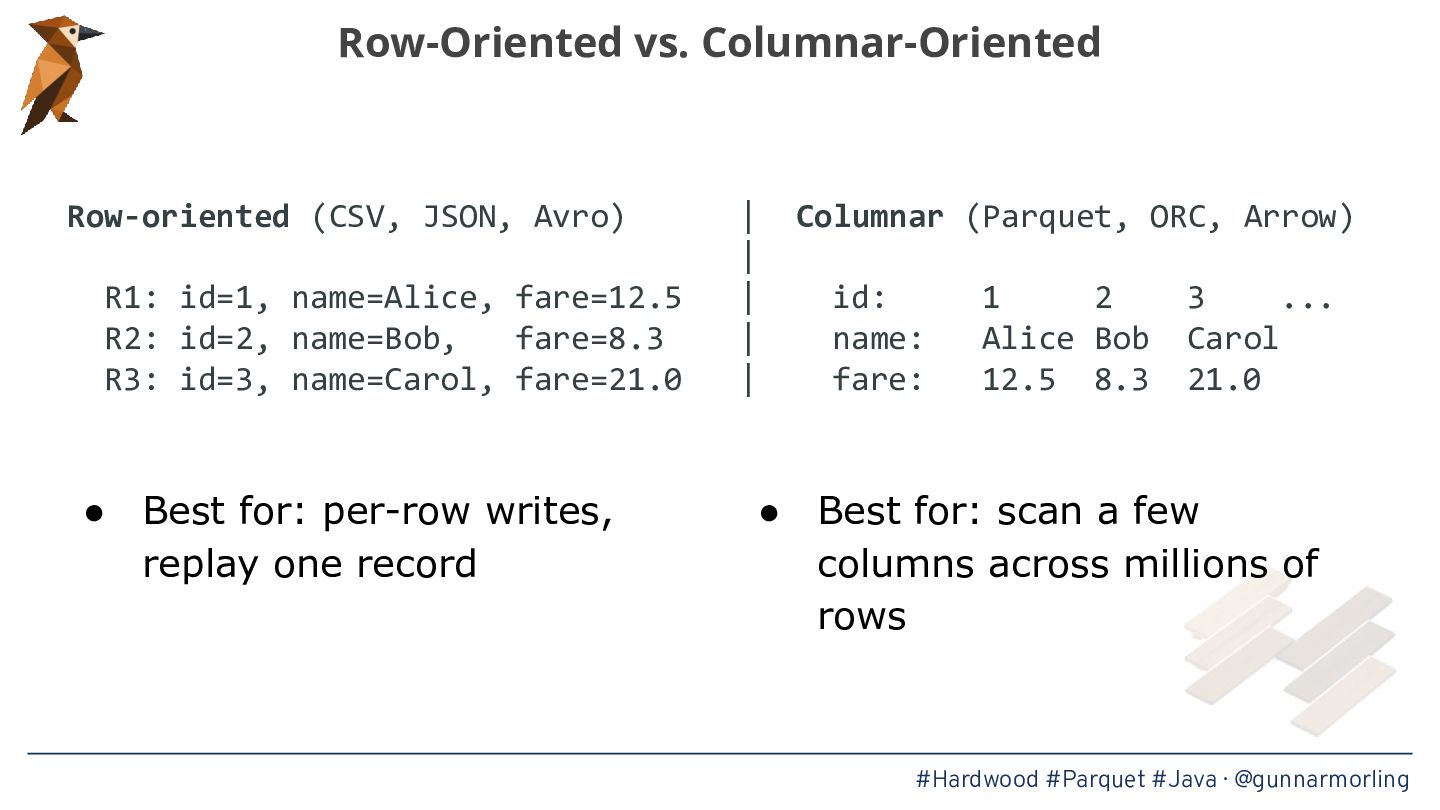
Row-Oriented vs. Columnar-Oriented Row-oriented (CSV, JSON, Avro) R1: id=1, name=Alice,
fare=12.5 R2: id=2, name=Bob, fare=8.3 R3: id=3, name=Carol, fare=21.0 • Best for: per-row writes, replay one record | | | | | Columnar (Parquet, ORC, Arrow) id: name: fare: 1 2 Alice Bob 12.5 8.3 3 ... Carol 21.0 • Best for: scan a few columns across millions of rows #Hardwood #Parquet #Java · @gunnarmorling -
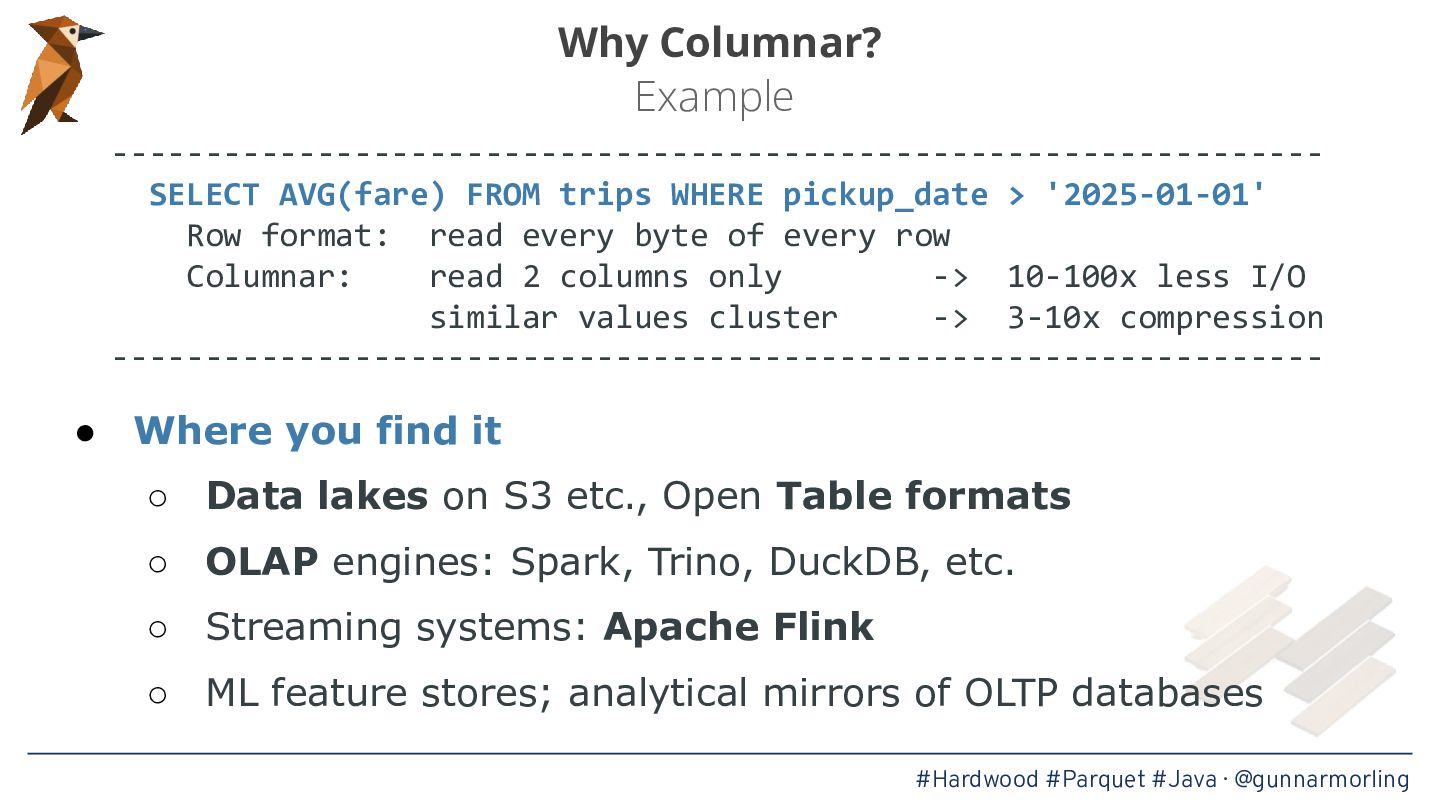
Why Columnar? Example ----------------------------------------------------------------SELECT AVG(fare) FROM trips WHERE pickup_date >
'2025-01-01' Row format: read every byte of every row Columnar: read 2 columns only -> 10-100x less I/O similar values cluster -> 3-10x compression ----------------------------------------------------------------- • Where you find it ◦ Data lakes on S3 etc., Open Table formats ◦ OLAP engines: Spark, Trino, DuckDB, etc. ◦ Streaming systems: Apache Flink ◦ ML feature stores; analytical mirrors of OLTP databases #Hardwood #Parquet #Java · @gunnarmorling -
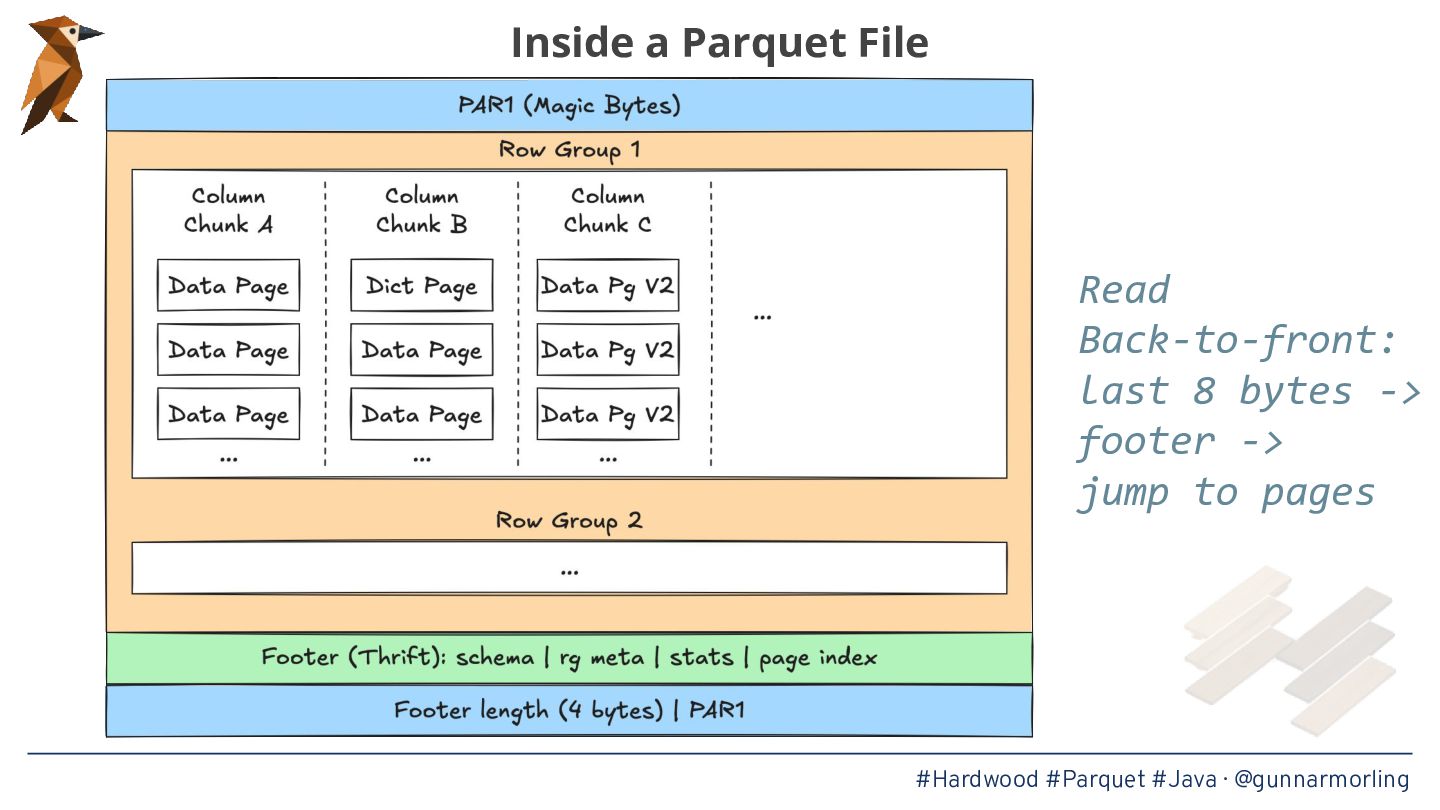
Inside a Parquet File Read Back-to-front: last 8 bytes ->
footer -> jump to pages #Hardwood #Parquet #Java · @gunnarmorling -
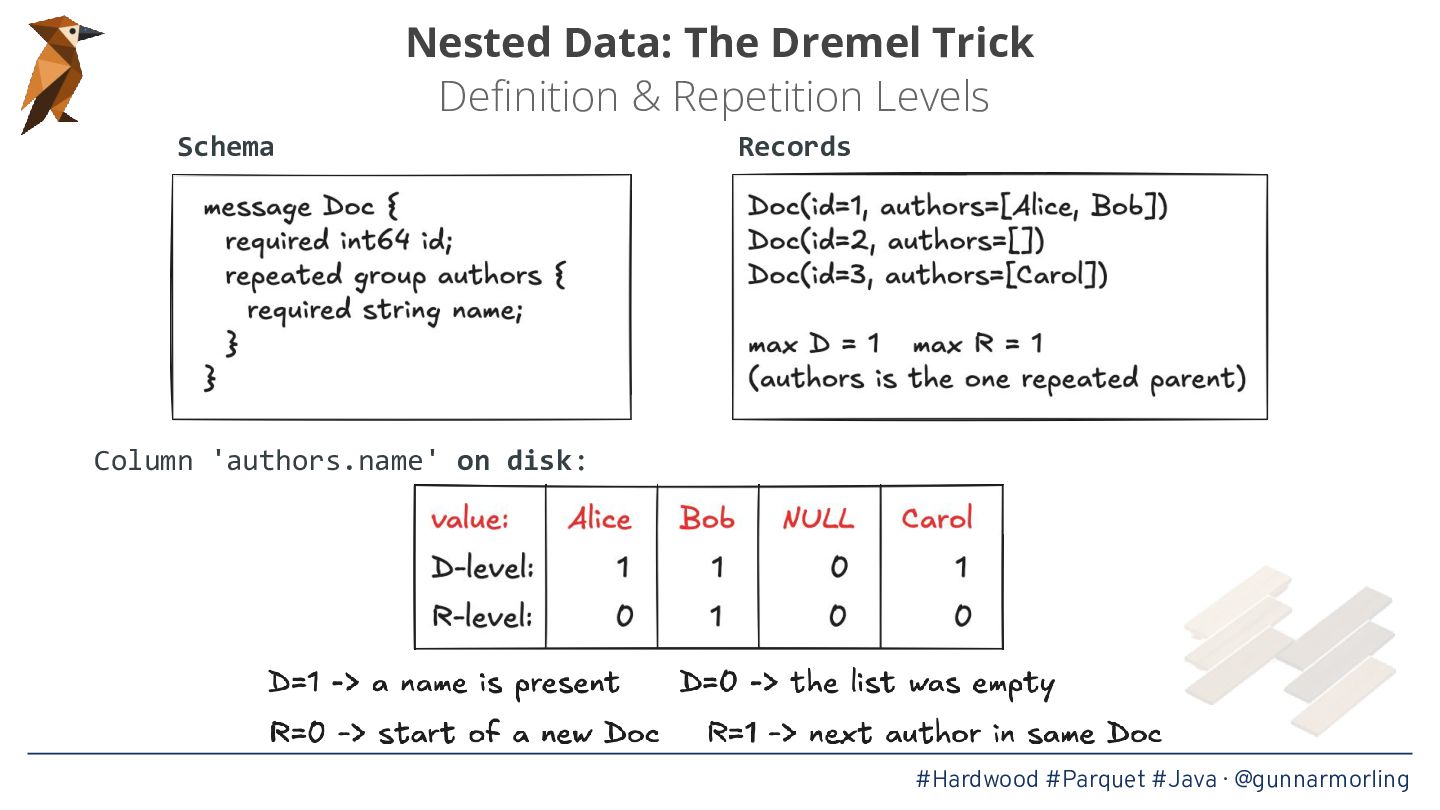
Nested Data: The Dremel Trick Definition & Repetition Levels Schema
Records Column 'authors.name' on disk: #Hardwood #Parquet #Java · @gunnarmorling -
Apache Parquet A Long Tail of Capabilities • Different compression
algorithms • Many different encodings • Predicate push-down (statistics, bloom filters) • VARIANT column type • Encryption #Hardwood #Parquet #Java · @gunnarmorling -
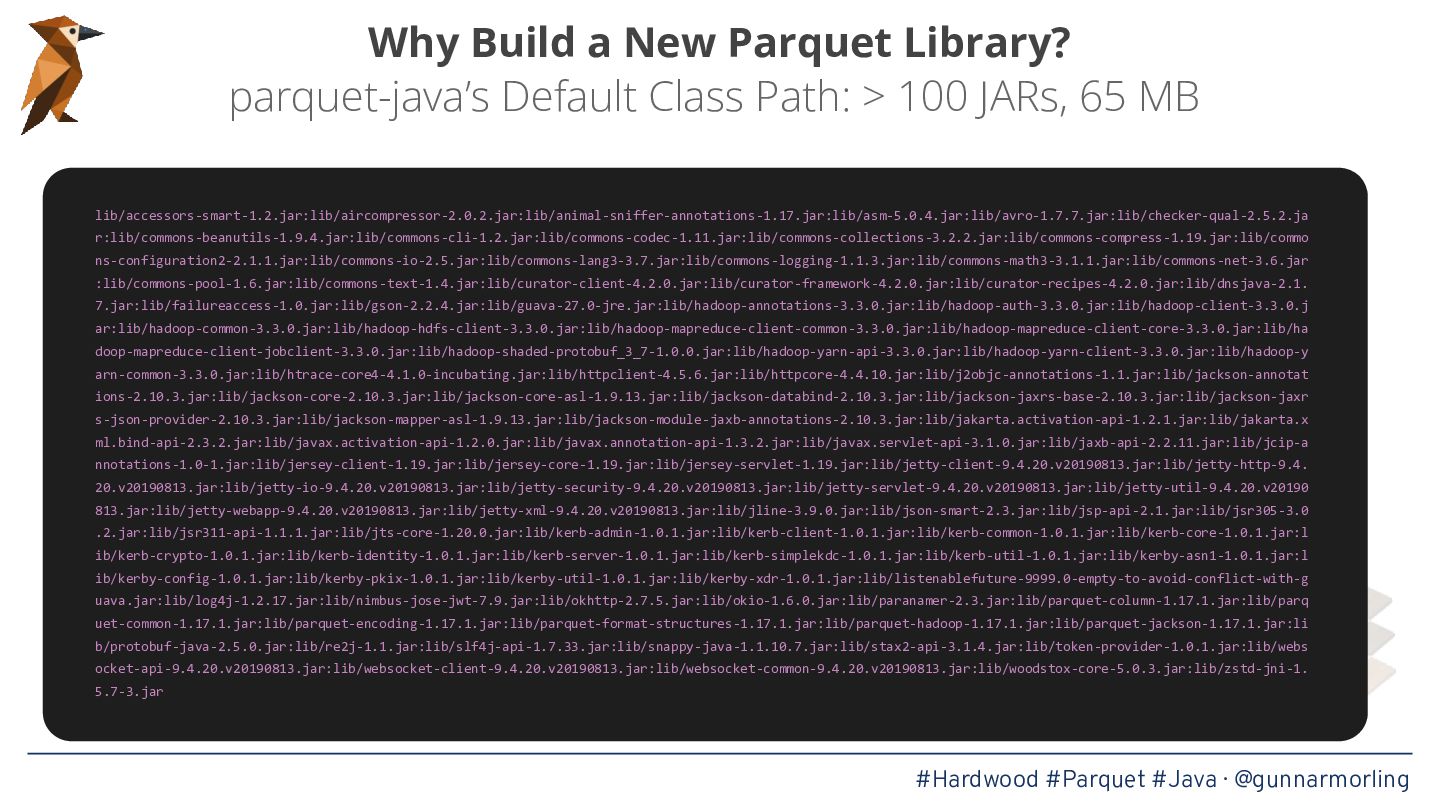
Why Build a New Parquet Library? parquet-java’s Default Class Path:
> 100 JARs, 65 MB lib/accessors-smart-1.2.jar:lib/aircompressor-2.0.2.jar:lib/animal-sniffer-annotations-1.17.jar:lib/asm-5.0.4.jar:lib/avro-1.7.7.jar:lib/checker-qual-2.5.2.ja r:lib/commons-beanutils-1.9.4.jar:lib/commons-cli-1.2.jar:lib/commons-codec-1.11.jar:lib/commons-collections-3.2.2.jar:lib/commons-compress-1.19.jar:lib/commo ns-configuration2-2.1.1.jar:lib/commons-io-2.5.jar:lib/commons-lang3-3.7.jar:lib/commons-logging-1.1.3.jar:lib/commons-math3-3.1.1.jar:lib/commons-net-3.6.jar :lib/commons-pool-1.6.jar:lib/commons-text-1.4.jar:lib/curator-client-4.2.0.jar:lib/curator-framework-4.2.0.jar:lib/curator-recipes-4.2.0.jar:lib/dnsjava-2.1. 7.jar:lib/failureaccess-1.0.jar:lib/gson-2.2.4.jar:lib/guava-27.0-jre.jar:lib/hadoop-annotations-3.3.0.jar:lib/hadoop-auth-3.3.0.jar:lib/hadoop-client-3.3.0.j ar:lib/hadoop-common-3.3.0.jar:lib/hadoop-hdfs-client-3.3.0.jar:lib/hadoop-mapreduce-client-common-3.3.0.jar:lib/hadoop-mapreduce-client-core-3.3.0.jar:lib/ha doop-mapreduce-client-jobclient-3.3.0.jar:lib/hadoop-shaded-protobuf_3_7-1.0.0.jar:lib/hadoop-yarn-api-3.3.0.jar:lib/hadoop-yarn-client-3.3.0.jar:lib/hadoop-y arn-common-3.3.0.jar:lib/htrace-core4-4.1.0-incubating.jar:lib/httpclient-4.5.6.jar:lib/httpcore-4.4.10.jar:lib/j2objc-annotations-1.1.jar:lib/jackson-annotat ions-2.10.3.jar:lib/jackson-core-2.10.3.jar:lib/jackson-core-asl-1.9.13.jar:lib/jackson-databind-2.10.3.jar:lib/jackson-jaxrs-base-2.10.3.jar:lib/jackson-jaxr s-json-provider-2.10.3.jar:lib/jackson-mapper-asl-1.9.13.jar:lib/jackson-module-jaxb-annotations-2.10.3.jar:lib/jakarta.activation-api-1.2.1.jar:lib/jakarta.x ml.bind-api-2.3.2.jar:lib/javax.activation-api-1.2.0.jar:lib/javax.annotation-api-1.3.2.jar:lib/javax.servlet-api-3.1.0.jar:lib/jaxb-api-2.2.11.jar:lib/jcip-a nnotations-1.0-1.jar:lib/jersey-client-1.19.jar:lib/jersey-core-1.19.jar:lib/jersey-servlet-1.19.jar:lib/jetty-client-9.4.20.v20190813.jar:lib/jetty-http-9.4. 20.v20190813.jar:lib/jetty-io-9.4.20.v20190813.jar:lib/jetty-security-9.4.20.v20190813.jar:lib/jetty-servlet-9.4.20.v20190813.jar:lib/jetty-util-9.4.20.v20190 813.jar:lib/jetty-webapp-9.4.20.v20190813.jar:lib/jetty-xml-9.4.20.v20190813.jar:lib/jline-3.9.0.jar:lib/json-smart-2.3.jar:lib/jsp-api-2.1.jar:lib/jsr305-3.0 .2.jar:lib/jsr311-api-1.1.1.jar:lib/jts-core-1.20.0.jar:lib/kerb-admin-1.0.1.jar:lib/kerb-client-1.0.1.jar:lib/kerb-common-1.0.1.jar:lib/kerb-core-1.0.1.jar:l ib/kerb-crypto-1.0.1.jar:lib/kerb-identity-1.0.1.jar:lib/kerb-server-1.0.1.jar:lib/kerb-simplekdc-1.0.1.jar:lib/kerb-util-1.0.1.jar:lib/kerby-asn1-1.0.1.jar:l ib/kerby-config-1.0.1.jar:lib/kerby-pkix-1.0.1.jar:lib/kerby-util-1.0.1.jar:lib/kerby-xdr-1.0.1.jar:lib/listenablefuture-9999.0-empty-to-avoid-conflict-with-g uava.jar:lib/log4j-1.2.17.jar:lib/nimbus-jose-jwt-7.9.jar:lib/okhttp-2.7.5.jar:lib/okio-1.6.0.jar:lib/paranamer-2.3.jar:lib/parquet-column-1.17.1.jar:lib/parq uet-common-1.17.1.jar:lib/parquet-encoding-1.17.1.jar:lib/parquet-format-structures-1.17.1.jar:lib/parquet-hadoop-1.17.1.jar:lib/parquet-jackson-1.17.1.jar:li b/protobuf-java-2.5.0.jar:lib/re2j-1.1.jar:lib/slf4j-api-1.7.33.jar:lib/snappy-java-1.1.10.7.jar:lib/stax2-api-3.1.4.jar:lib/token-provider-1.0.1.jar:lib/webs ocket-api-9.4.20.v20190813.jar:lib/websocket-client-9.4.20.v20190813.jar:lib/websocket-common-9.4.20.v20190813.jar:lib/woodstox-core-5.0.3.jar:lib/zstd-jni-1. 5.7-3.jar #Hardwood #Parquet #Java · @gunnarmorling -
Why Build a New Parquet Library? parquet-java Pain Points •
Pulls in Hadoop: …and a truckload of transitive deps • Reader is single-threaded: leaves cores idle on modern hardware But also: Explore how far LLMs will take you? #Hardwood #Parquet #Java · @gunnarmorling -
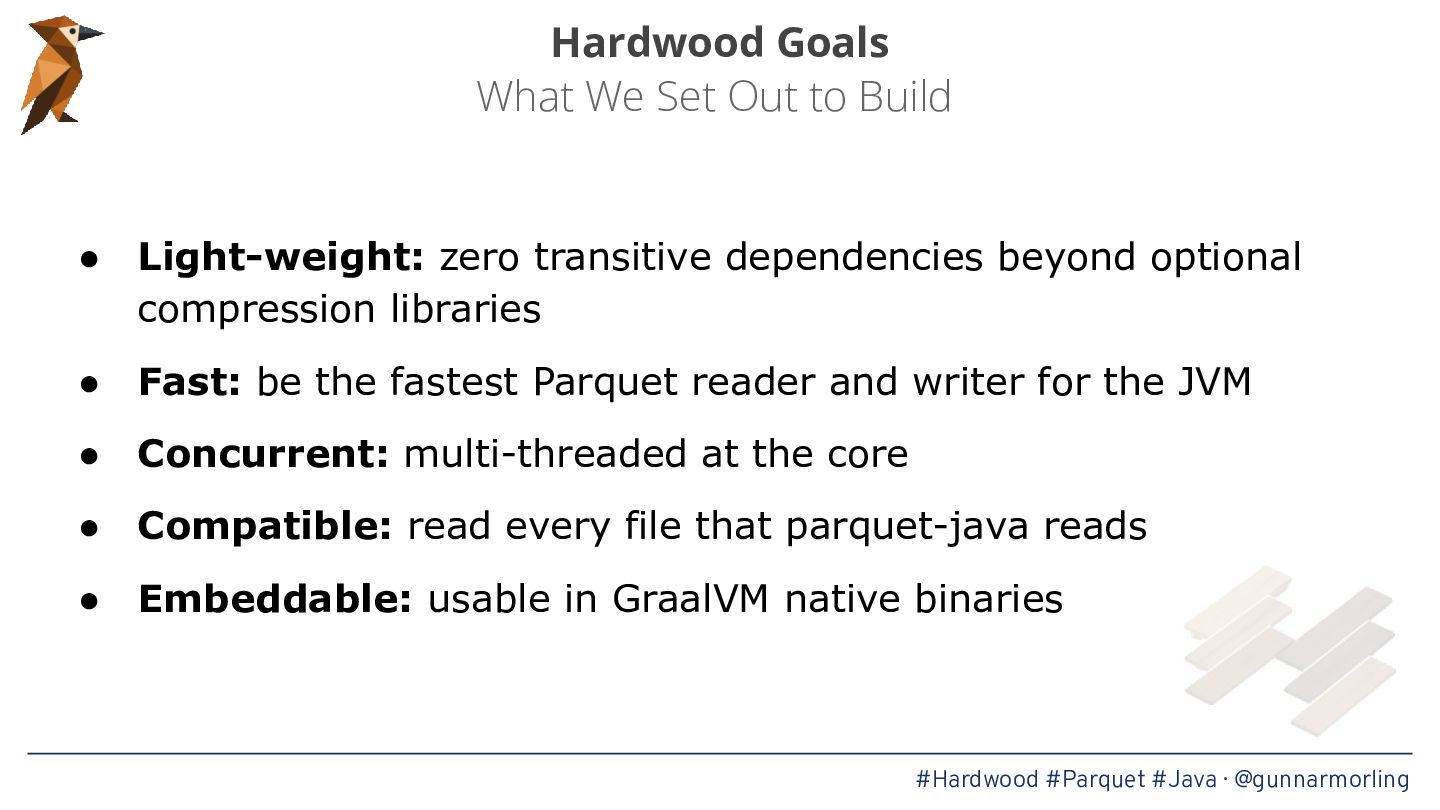
Hardwood Goals What We Set Out to Build • Light-weight:
zero transitive dependencies beyond optional compression libraries • Fast: be the fastest Parquet reader and writer for the JVM • Concurrent: multi-threaded at the core • Compatible: read every file that parquet-java reads • Embeddable: usable in GraalVM native binaries #Hardwood #Parquet #Java · @gunnarmorling -
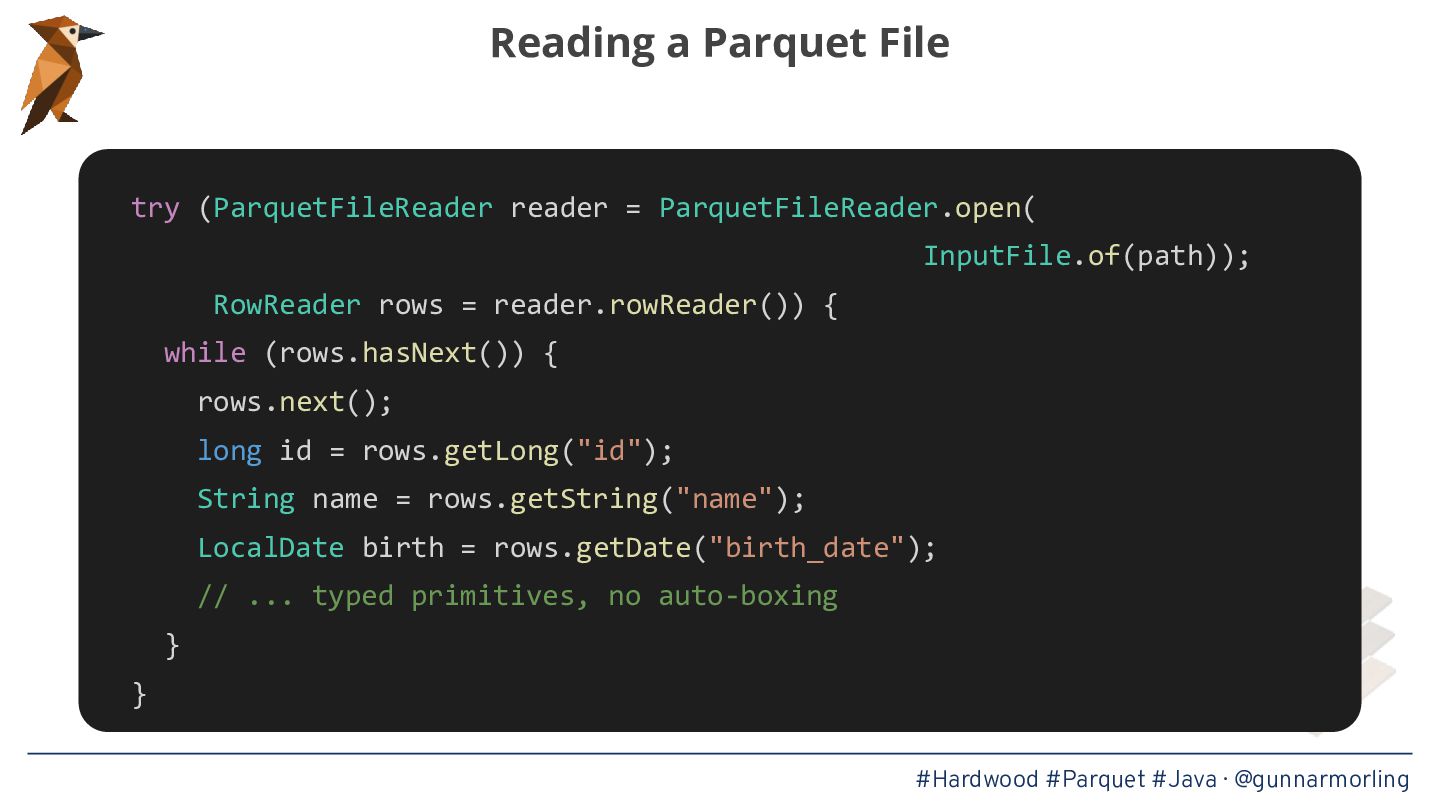
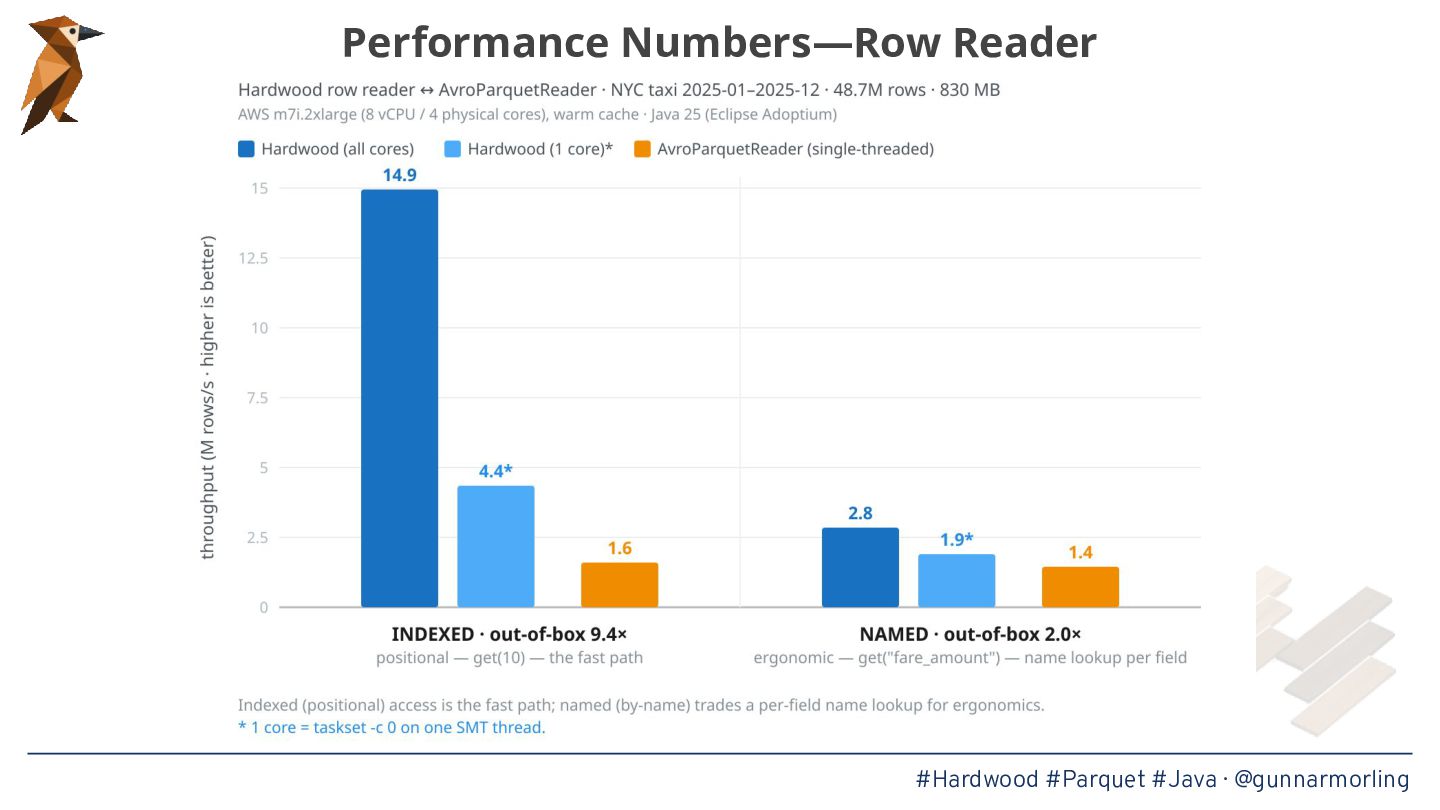
Reading a Parquet File try (ParquetFileReader reader = ParquetFileReader.open( InputFile.of(path));
RowReader rows = reader.rowReader()) { while (rows.hasNext()) { rows.next(); long id = rows.getLong("id"); String name = rows.getString("name"); LocalDate birth = rows.getDate("birth_date"); // ... typed primitives, no auto-boxing } } #Hardwood #Parquet #Java · @gunnarmorling -
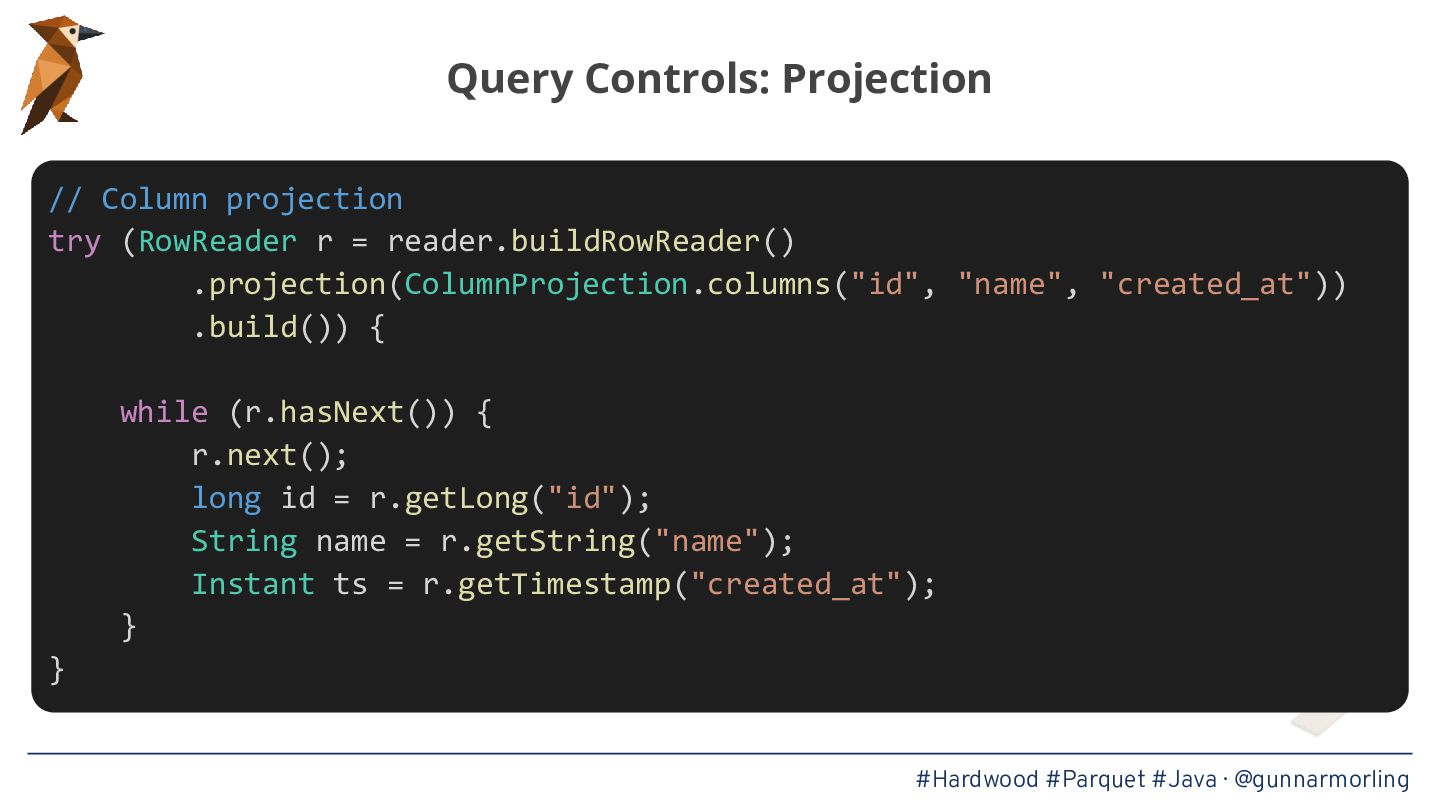
Query Controls: Projection // Column projection try (RowReader r =
reader.buildRowReader() .projection(ColumnProjection.columns("id", "name", "created_at")) .build()) { while (r.hasNext()) { r.next(); long id = r.getLong("id"); String name = r.getString("name"); Instant ts = r.getTimestamp("created_at"); } } #Hardwood #Parquet #Java · @gunnarmorling -
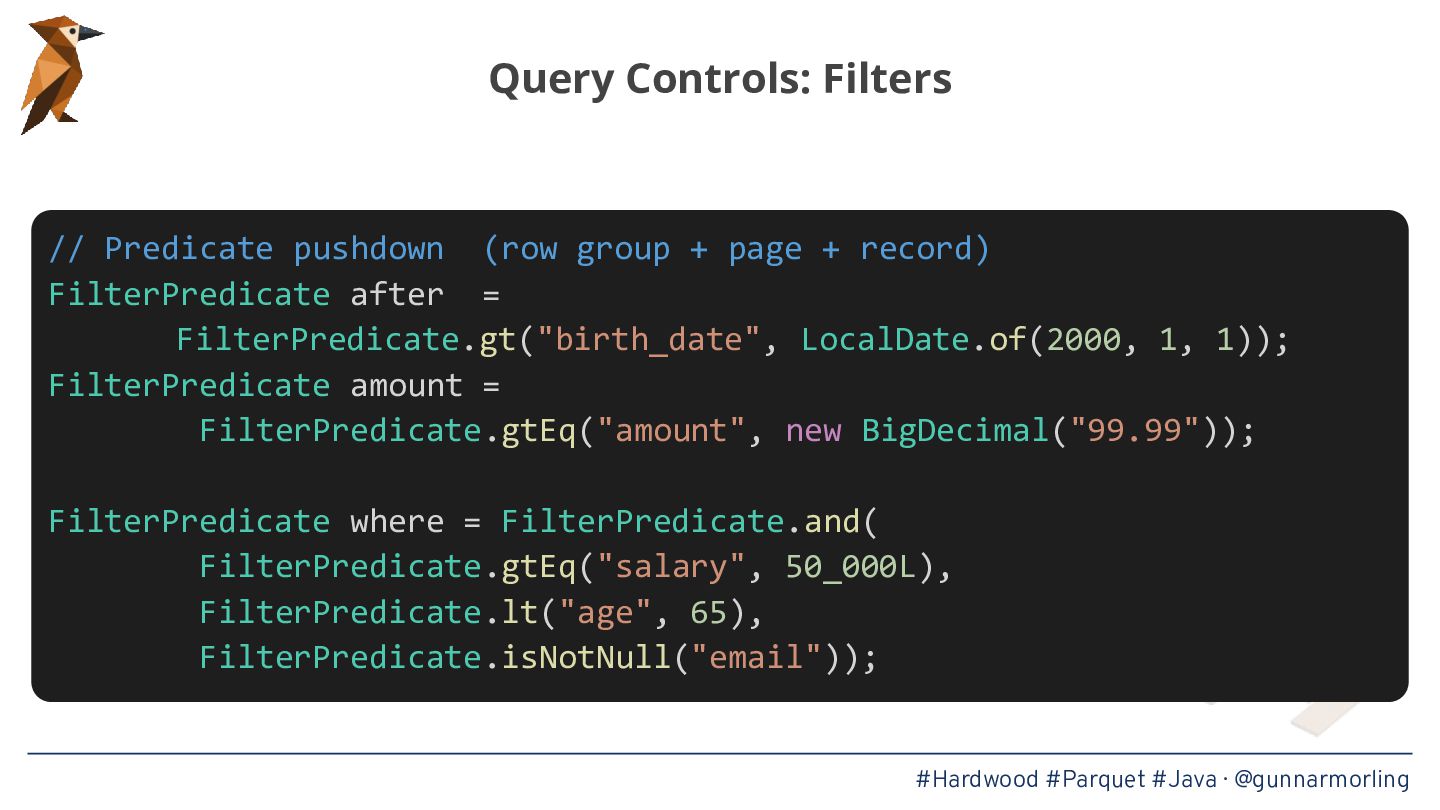
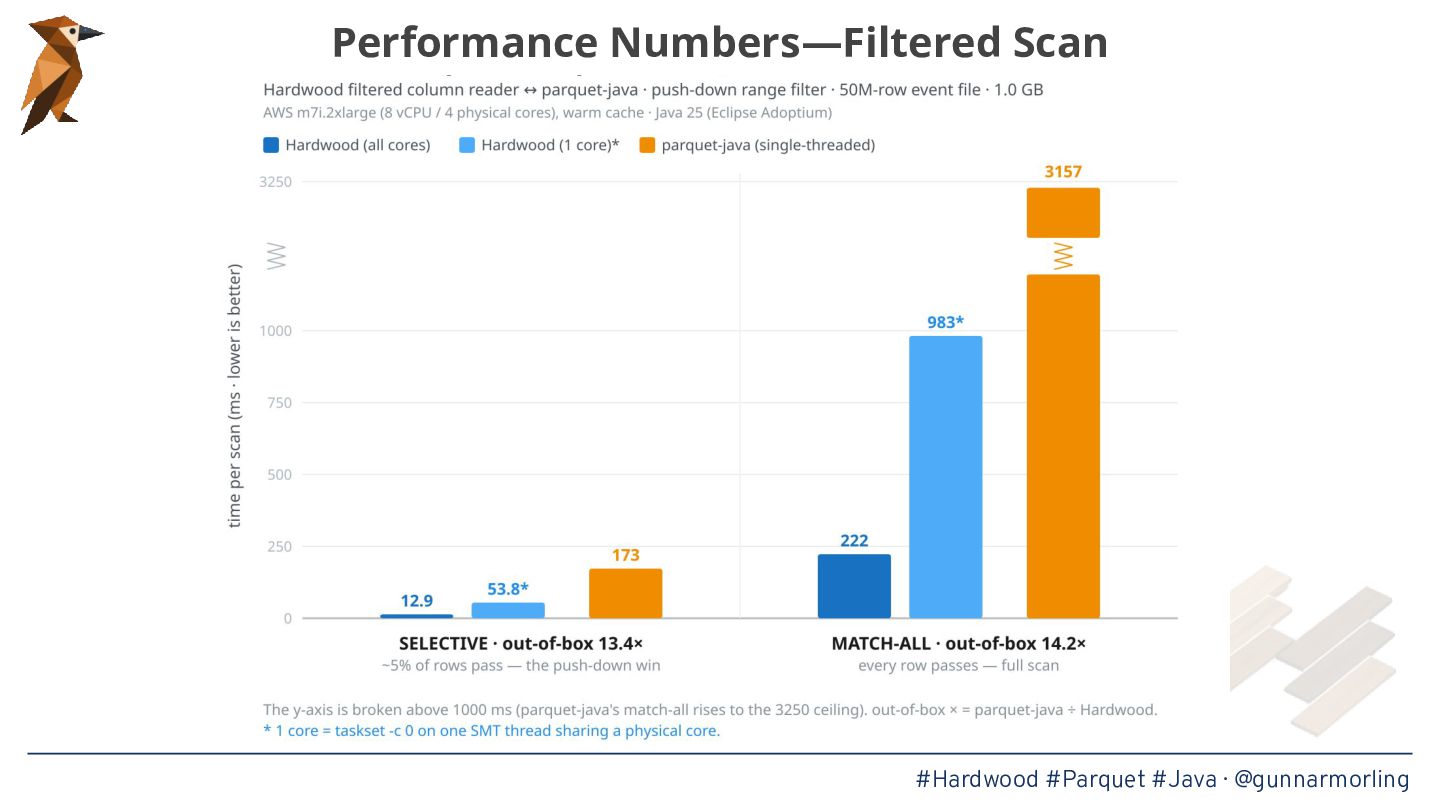
Query Controls: Filters // Predicate pushdown (row group + page
+ record) FilterPredicate after = FilterPredicate.gt("birth_date", LocalDate.of(2000, 1, 1)); FilterPredicate amount = FilterPredicate.gtEq("amount", new BigDecimal("99.99")); FilterPredicate where = FilterPredicate.and( FilterPredicate.gtEq("salary", 50_000L), FilterPredicate.lt("age", 65), FilterPredicate.isNotNull("email")); #Hardwood #Parquet #Java · @gunnarmorling -
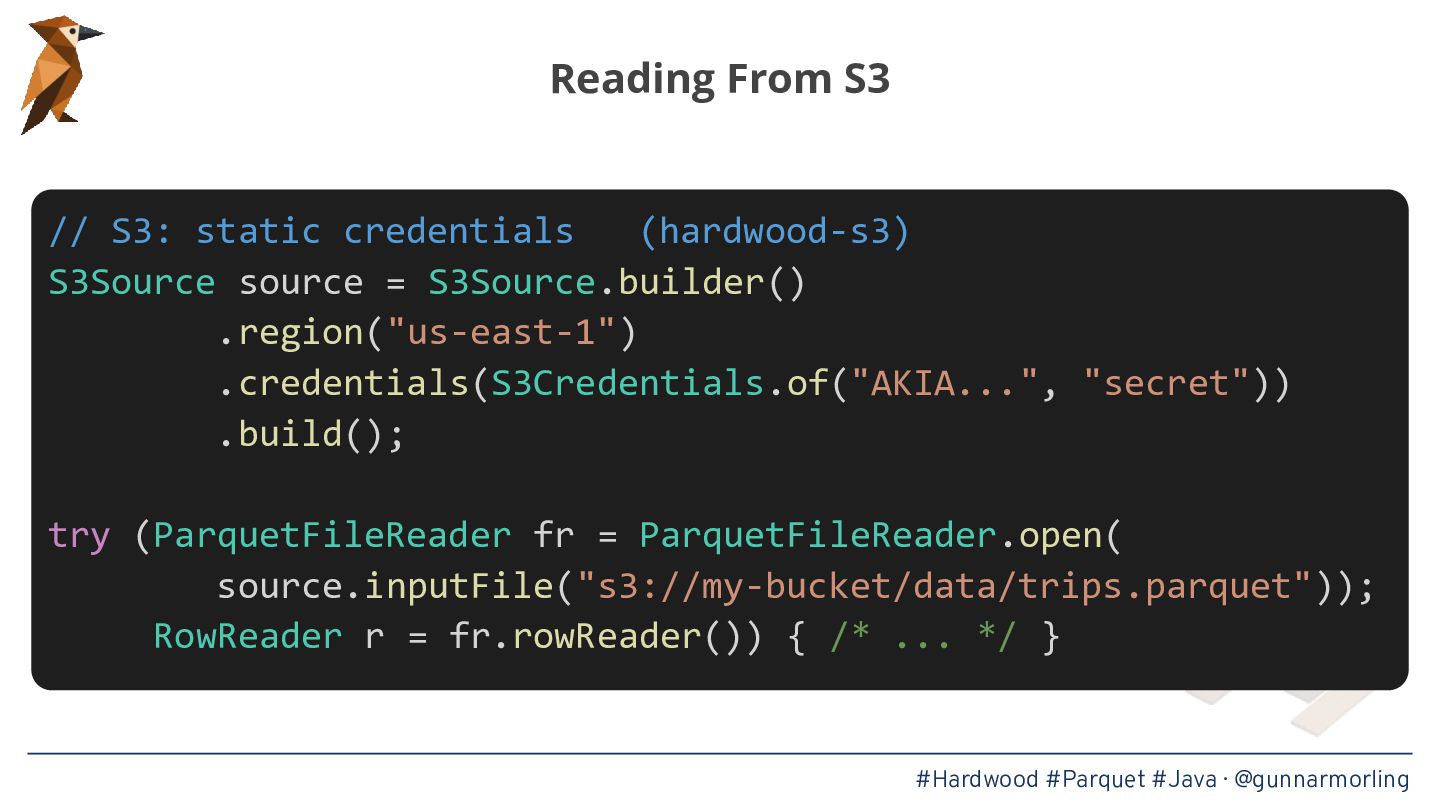
Reading From S3 // S3: static credentials (hardwood-s3) S3Source source
= S3Source.builder() .region("us-east-1") .credentials(S3Credentials.of("AKIA...", "secret")) .build(); try (ParquetFileReader fr = ParquetFileReader.open( source.inputFile("s3://my-bucket/data/trips.parquet")); RowReader r = fr.rowReader()) { /* ... */ } #Hardwood #Parquet #Java · @gunnarmorling -
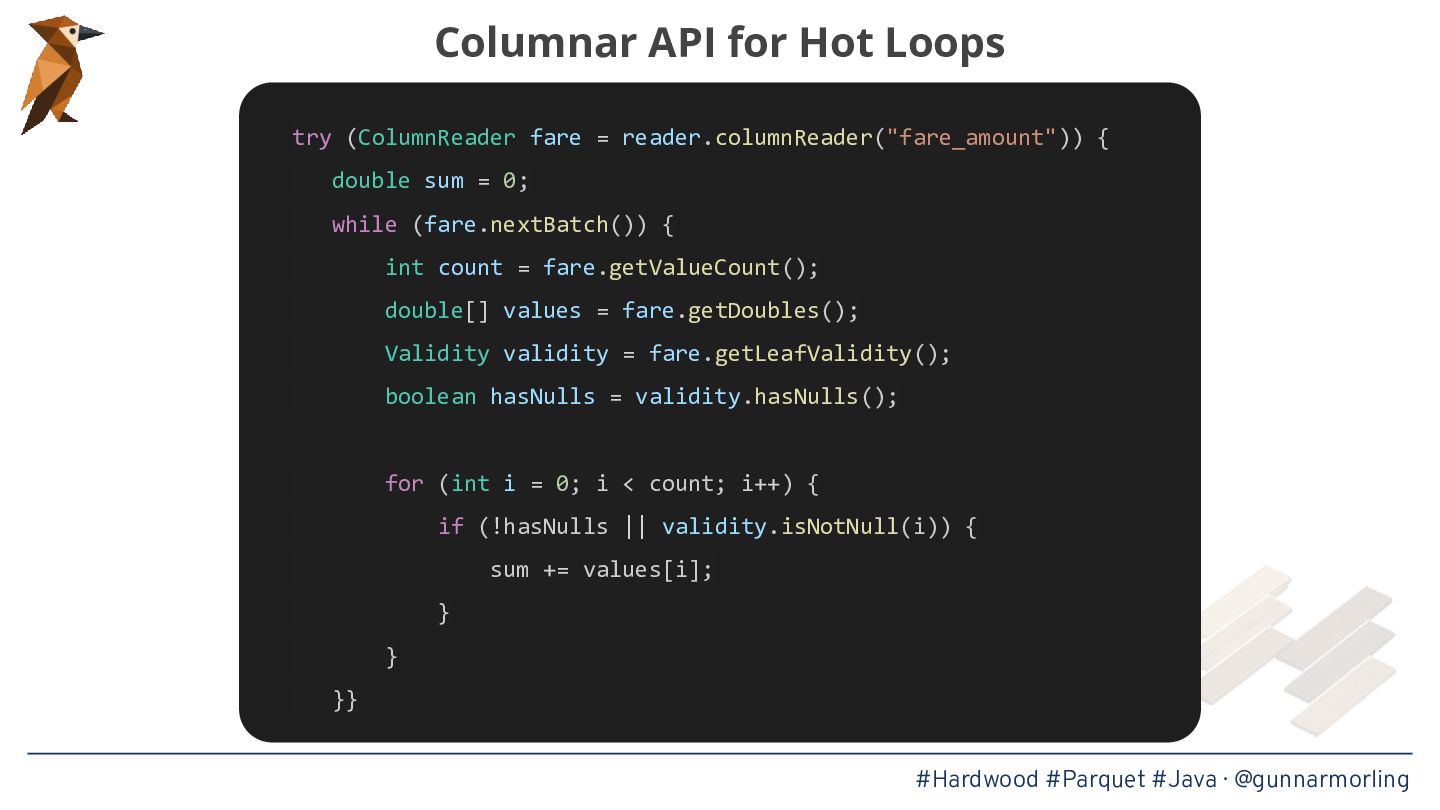
Columnar API for Hot Loops try (ColumnReader fare = reader.columnReader("fare_amount"))
{ double sum = 0; while (fare.nextBatch()) { int count = fare.getValueCount(); double[] values = fare.getDoubles(); Validity validity = fare.getLeafValidity(); boolean hasNulls = validity.hasNulls(); for (int i = 0; i < count; i++) { if (!hasNulls || validity.isNotNull(i)) { sum += values[i]; } } }} #Hardwood #Parquet #Java · @gunnarmorling -
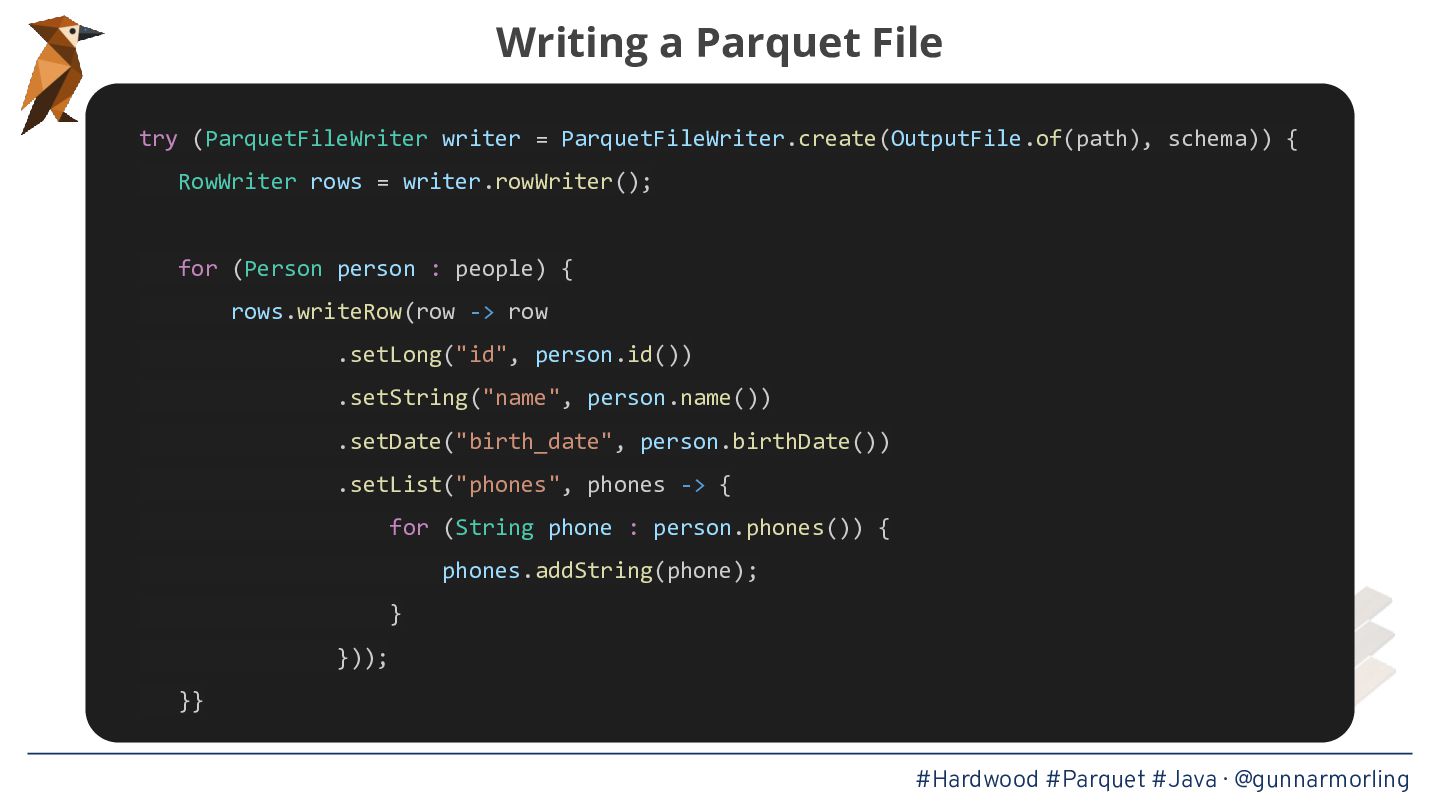
Writing a Parquet File try (ParquetFileWriter writer = ParquetFileWriter.create(OutputFile.of(path), schema))
{ RowWriter rows = writer.rowWriter(); for (Person person : people) { rows.writeRow(row -> row .setLong("id", person.id()) .setString("name", person.name()) .setDate("birth_date", person.birthDate()) .setList("phones", phones -> { for (String phone : person.phones()) { phones.addString(phone); } })); }} #Hardwood #Parquet #Java · @gunnarmorling -
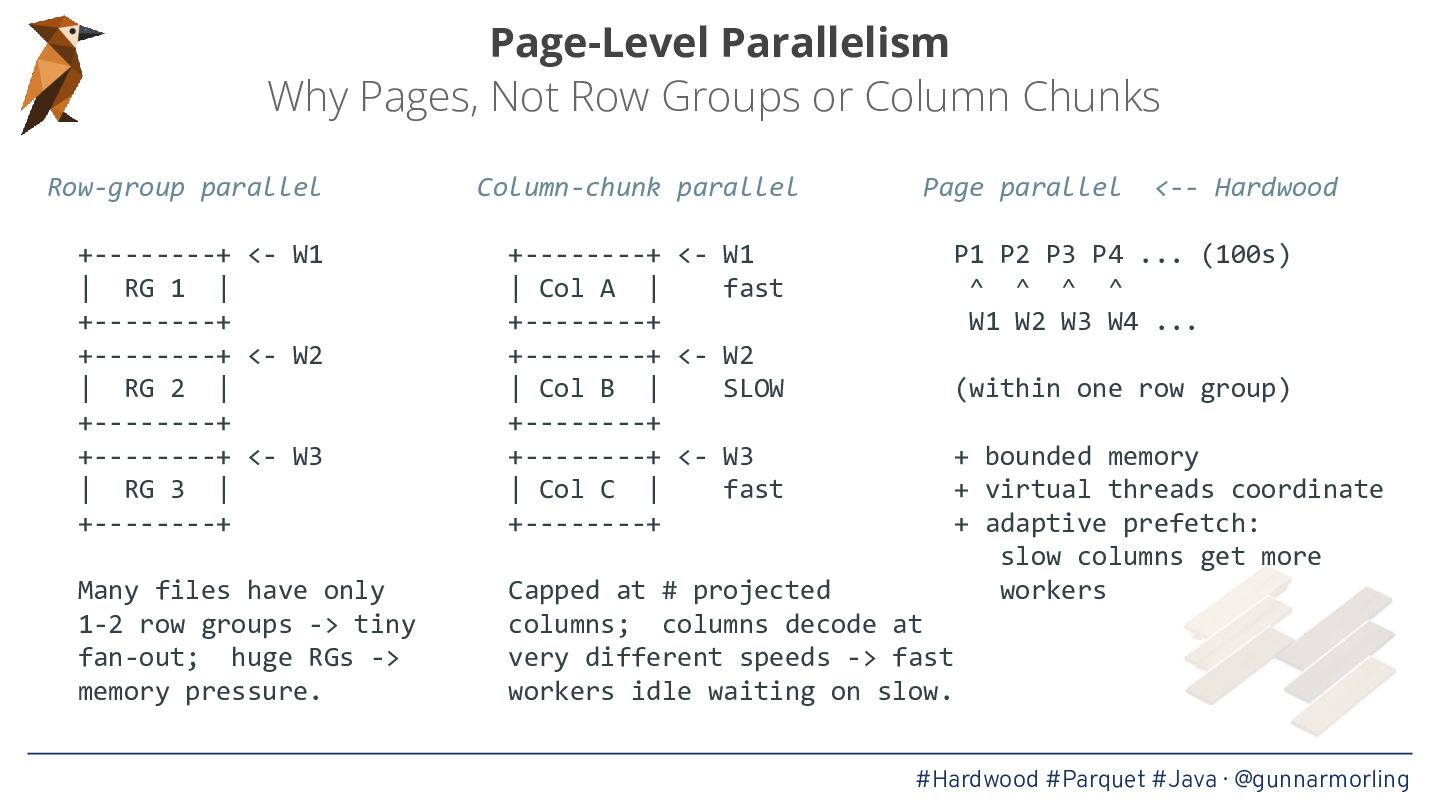
Page-Level Parallelism Why Pages, Not Row Groups or Column Chunks
Row-group parallel Column-chunk parallel Page parallel +--------+ <- W1 | RG 1 | +--------+ +--------+ <- W2 | RG 2 | +--------+ +--------+ <- W3 | RG 3 | +--------+ +--------+ <- W1 | Col A | fast +--------+ +--------+ <- W2 | Col B | SLOW +--------+ +--------+ <- W3 | Col C | fast +--------+ Many files have only 1-2 row groups -> tiny fan-out; huge RGs -> memory pressure. Capped at # projected columns; columns decode at very different speeds -> fast workers idle waiting on slow. <-- Hardwood P1 P2 P3 P4 ... (100s) ^ ^ ^ ^ W1 W2 W3 W4 ... (within one row group) + bounded memory + virtual threads coordinate + adaptive prefetch: slow columns get more workers #Hardwood #Parquet #Java · @gunnarmorling -
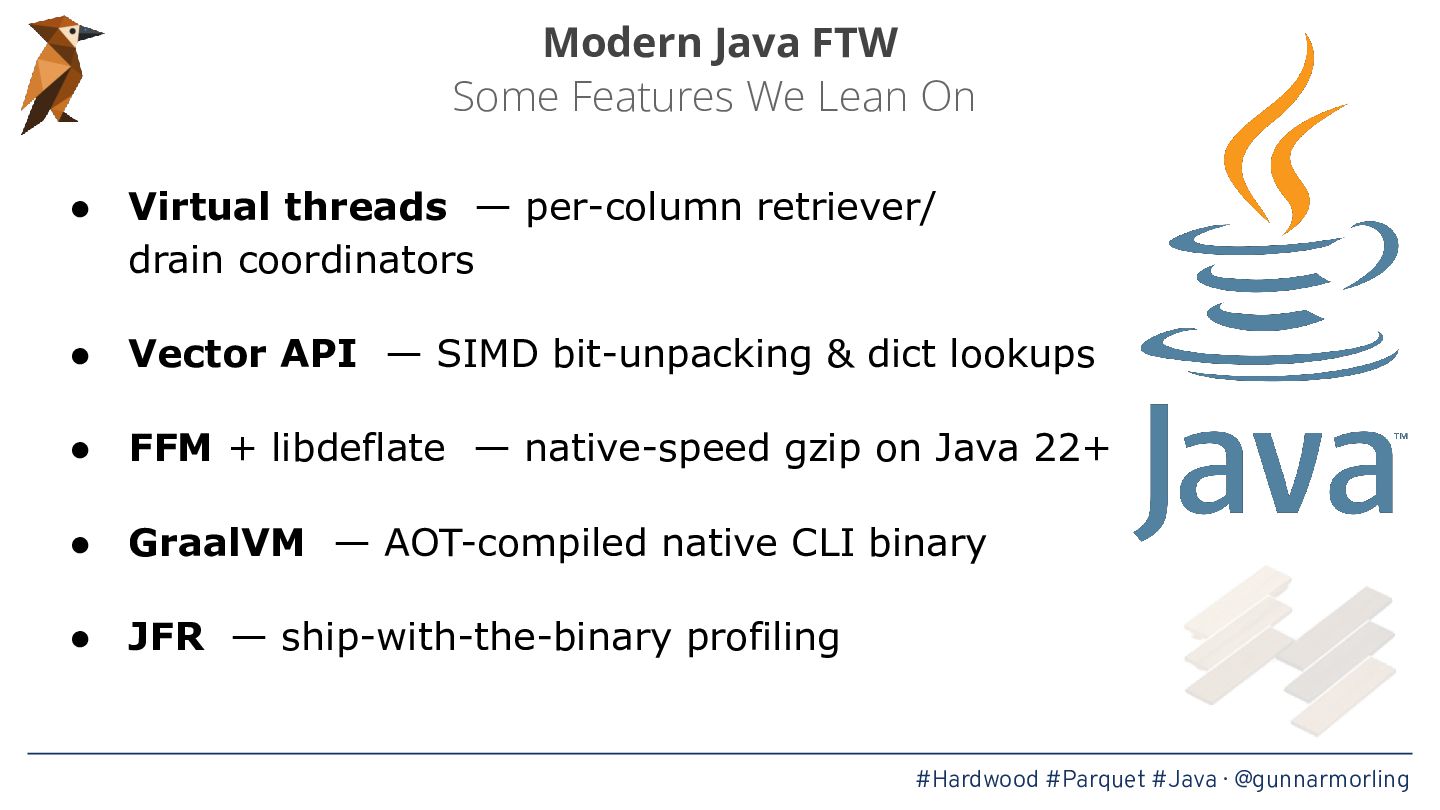
Modern Java FTW Some Features We Lean On • Virtual
threads — per-column retriever/ drain coordinators • Vector API — SIMD bit-unpacking & dict lookups • FFM + libdeflate — native-speed gzip on Java 22+ • GraalVM — AOT-compiled native CLI binary • JFR — ship-with-the-binary profiling #Hardwood #Parquet #Java · @gunnarmorling -
Modern Java FTW Some Features We Lean On • Virtual
threads — per-column retriever/drain coordinators; decode itself runs on a fixed OS-thread pool • Vector API — SIMD bit-unpacking & dict lookups • FFM + libdeflate — native-speed gzip on Java 22+ • GraalVM — AOT-compiled native CLI binary • JFR — ship-with-the-binary profiling #Hardwood #Parquet #Java · @gunnarmorling -
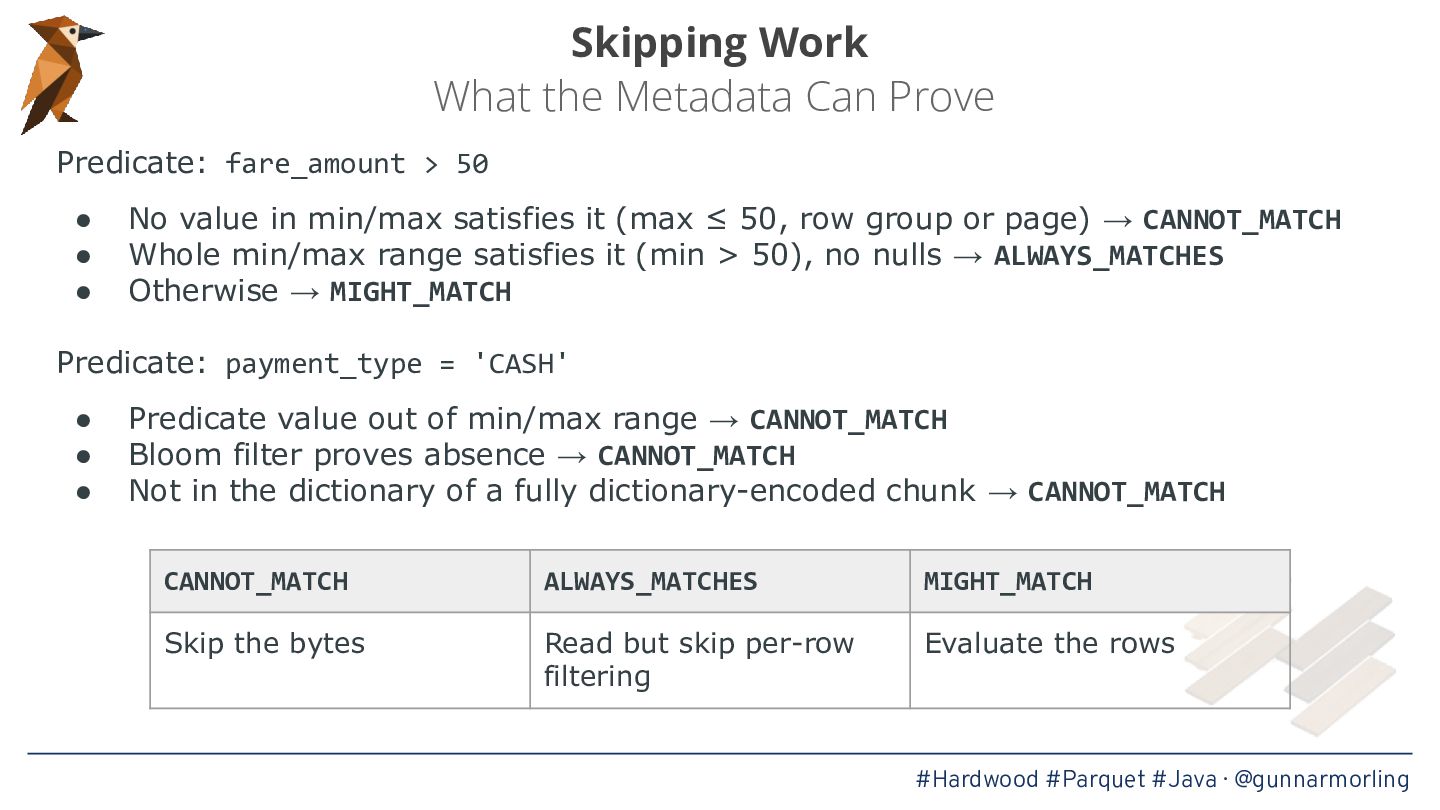
Skipping Work What the Metadata Can Prove Predicate: fare_amount >
50 • • • No value in min/max satisfies it (max ≤ 50, row group or page) → CANNOT_MATCH Whole min/max range satisfies it (min > 50), no nulls → ALWAYS_MATCHES Otherwise → MIGHT_MATCH Predicate: payment_type = 'CASH' • • • Predicate value out of min/max range → CANNOT_MATCH Bloom filter proves absence → CANNOT_MATCH Not in the dictionary of a fully dictionary-encoded chunk → CANNOT_MATCH CANNOT_MATCH ALWAYS_MATCHES MIGHT_MATCH Skip the bytes Read but skip per-row filtering Evaluate the rows #Hardwood #Parquet #Java · @gunnarmorling -
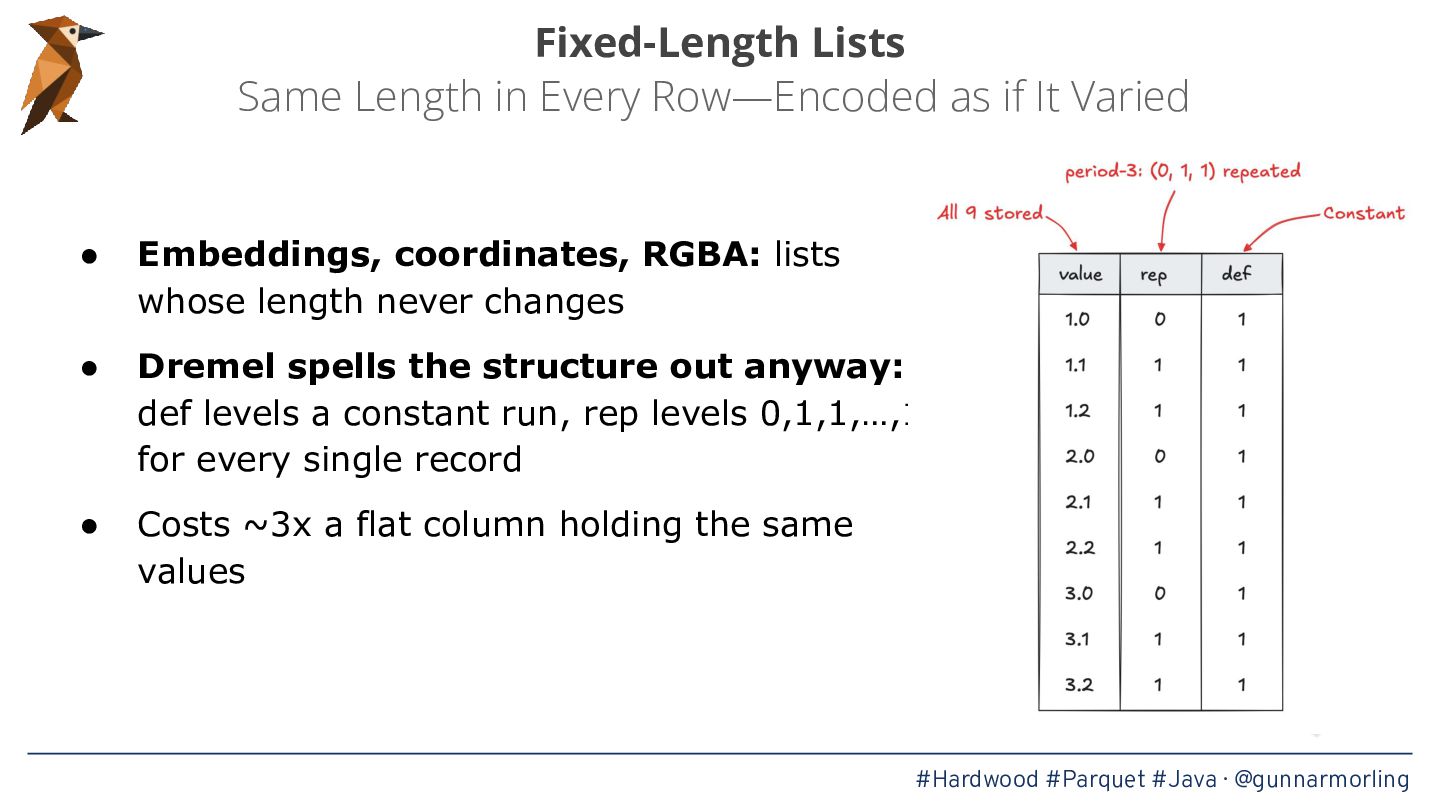
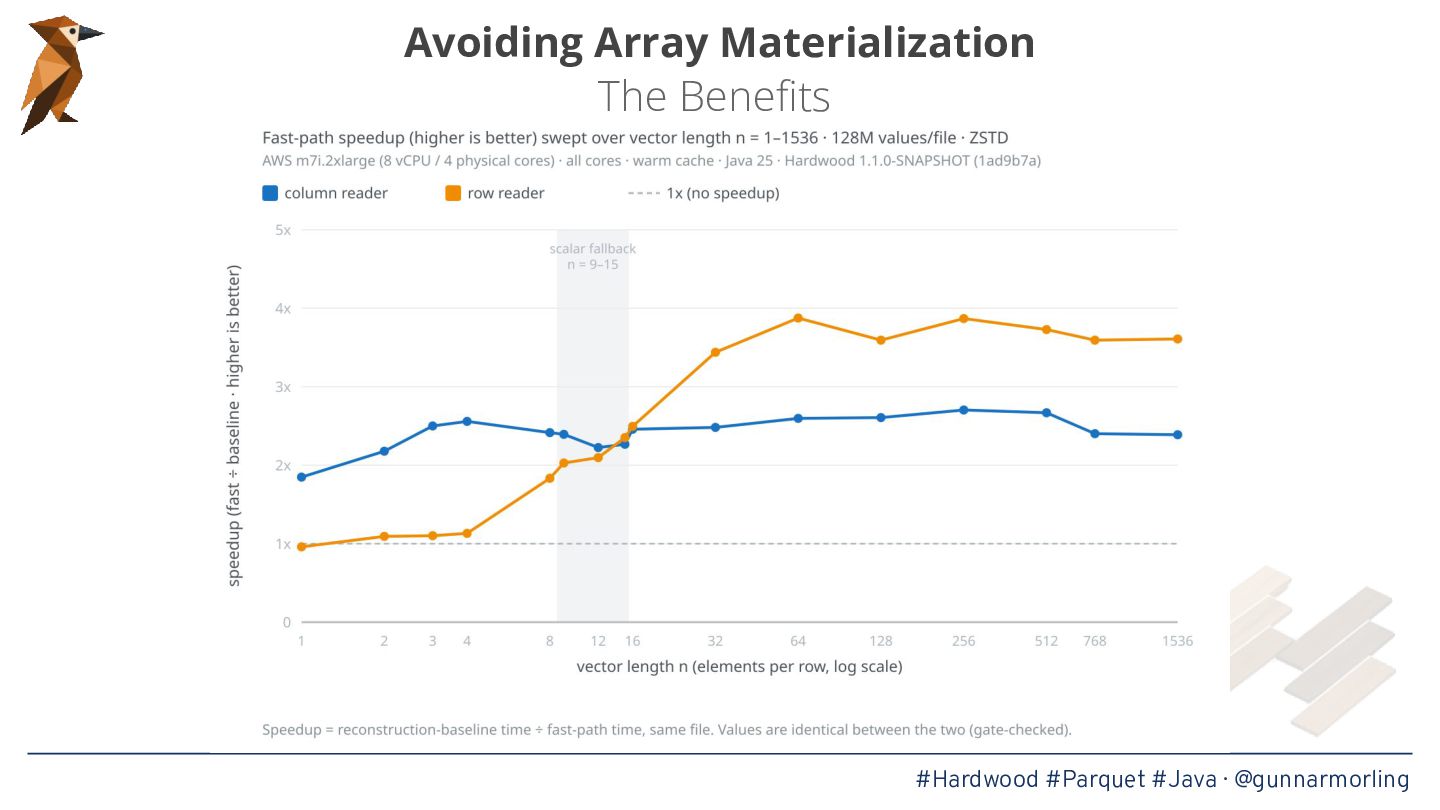
Fixed-Length Lists Same Length in Every Row—Encoded as if It
Varied • Embeddings, coordinates, RGBA: lists whose length never changes • Dremel spells the structure out anyway: def levels a constant run, rep levels 0,1,1,…,1 for every single record • Costs ~3x a flat column holding the same values #Hardwood #Parquet #Java · @gunnarmorling -
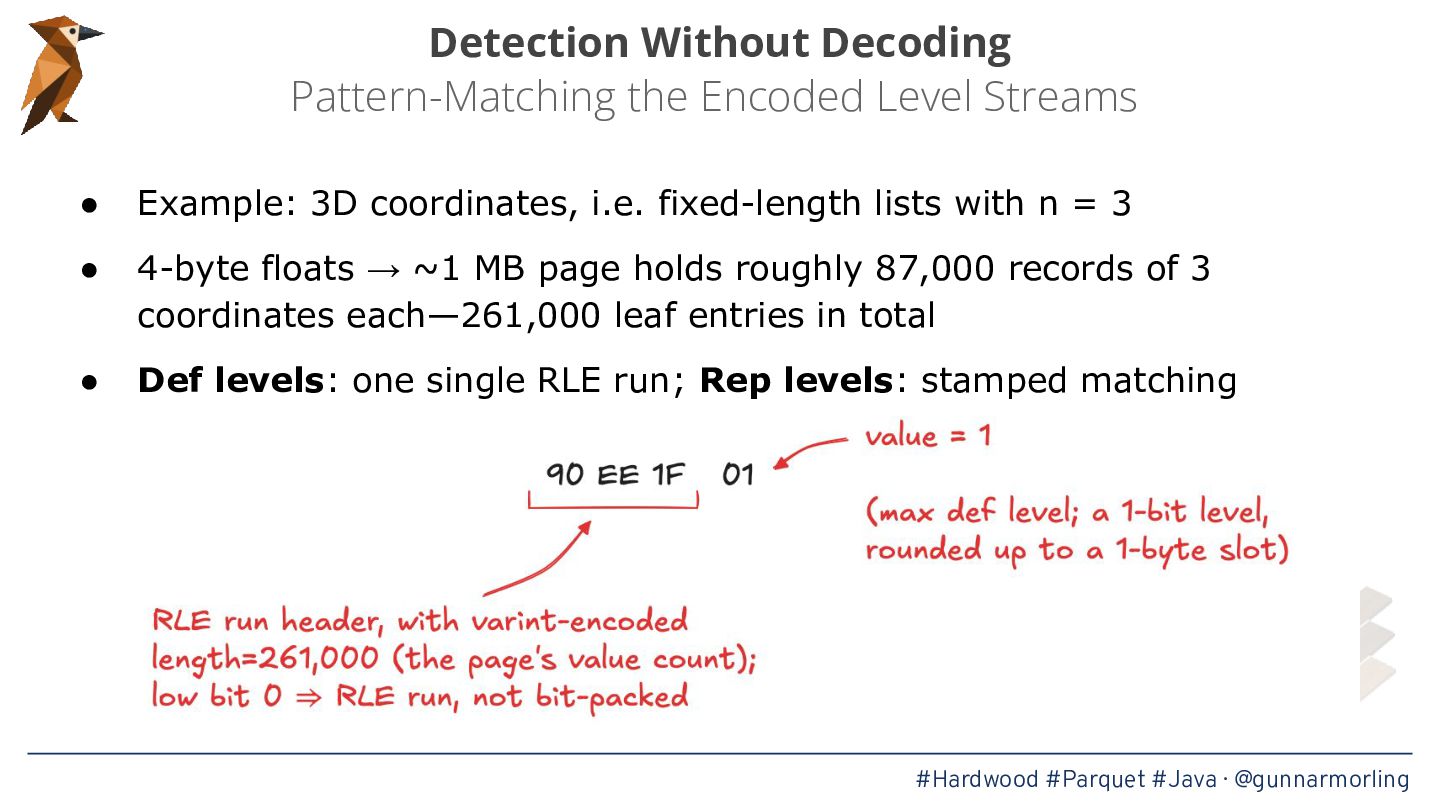
Detection Without Decoding Pattern-Matching the Encoded Level Streams • Example:
3D coordinates, i.e. fixed-length lists with n = 3 • 4-byte floats → ~1 MB page holds roughly 87,000 records of 3 coordinates each—261,000 leaf entries in total • Def levels: one single RLE run; Rep levels: stamped matching #Hardwood #Parquet #Java · @gunnarmorling -
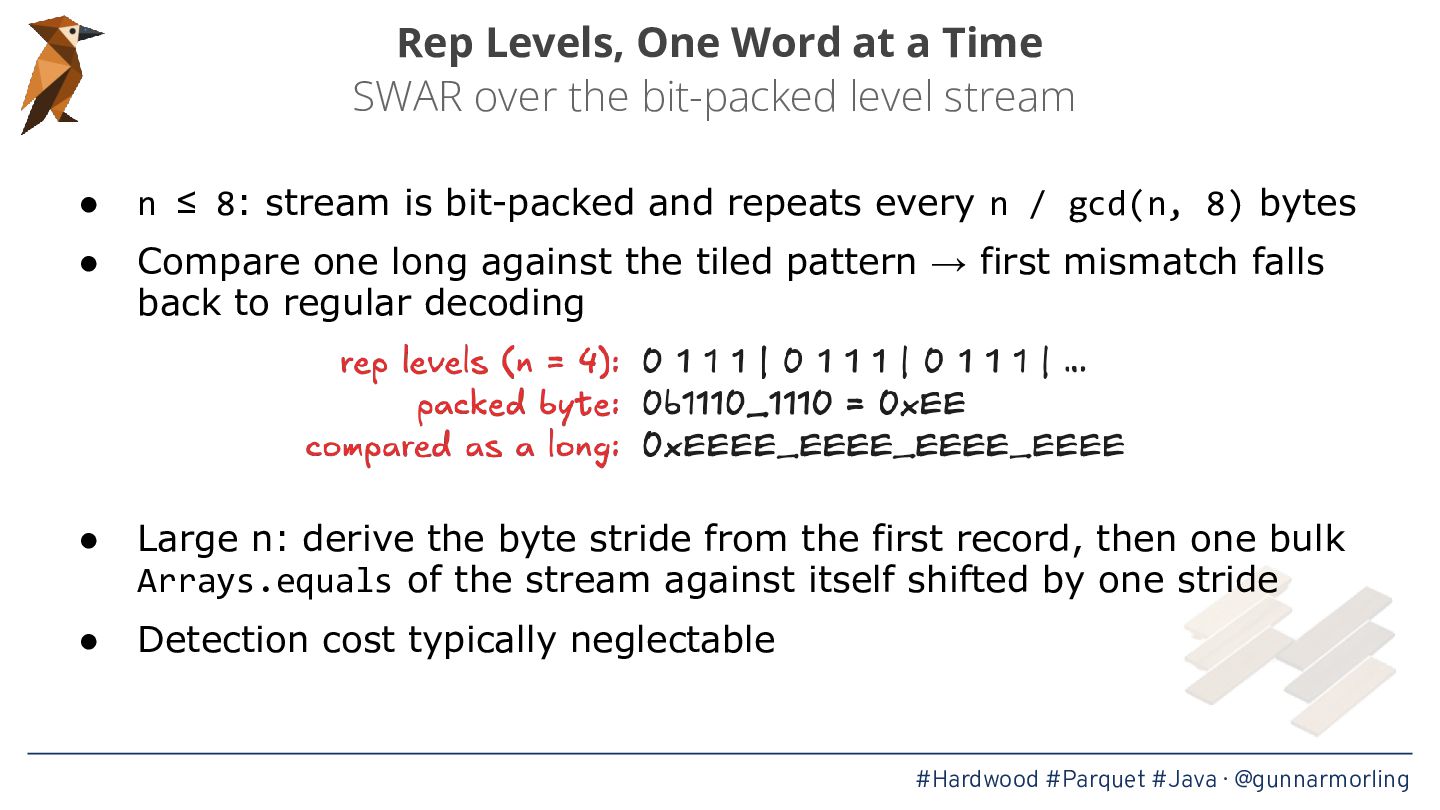
Rep Levels, One Word at a Time SWAR over the
bit-packed level stream • n ≤ 8: stream is bit-packed and repeats every n / gcd(n, 8) bytes • Compare one long against the tiled pattern → first mismatch falls back to regular decoding • Large n: derive the byte stride from the first record, then one bulk Arrays.equals of the stream against itself shifted by one stride • Detection cost typically neglectable #Hardwood #Parquet #Java · @gunnarmorling -
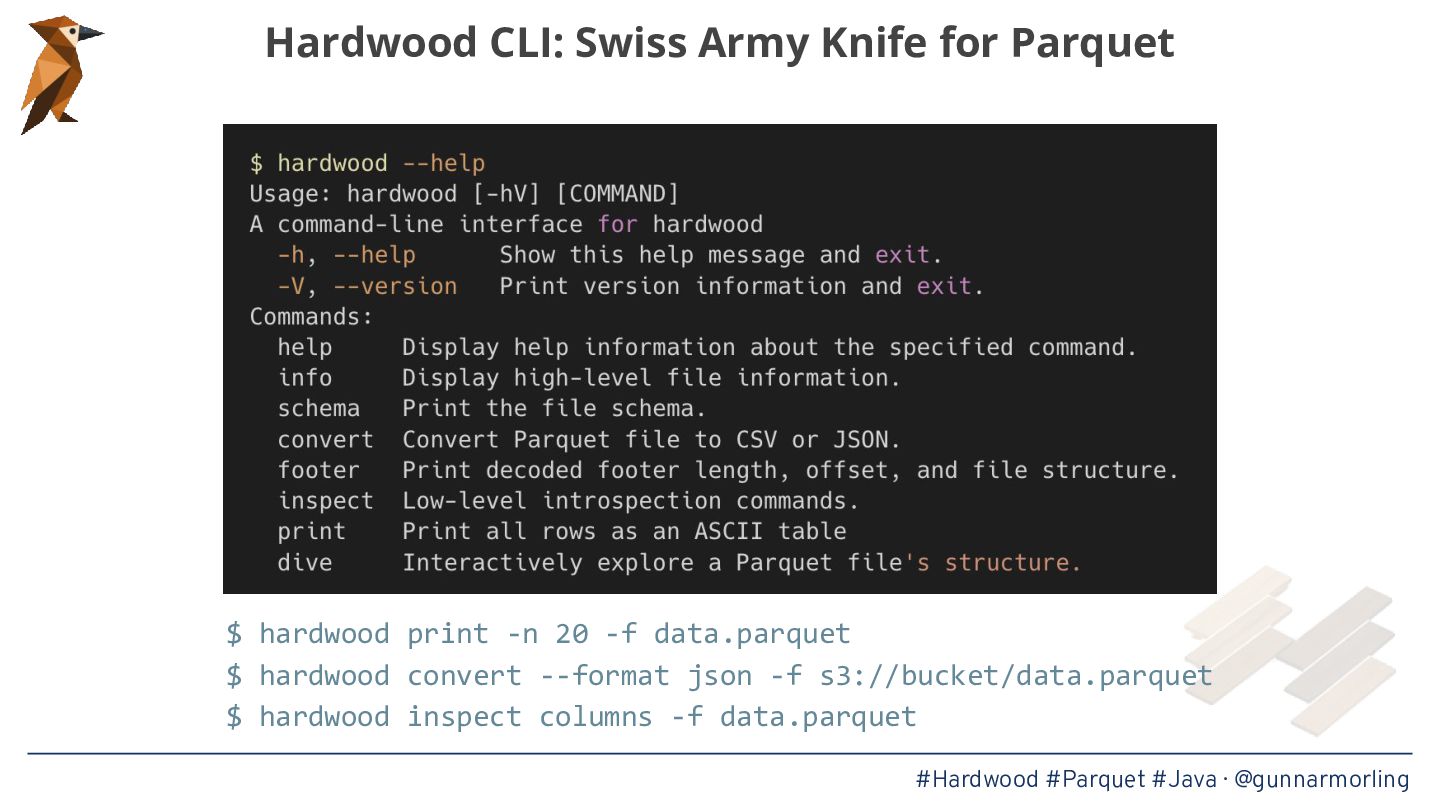
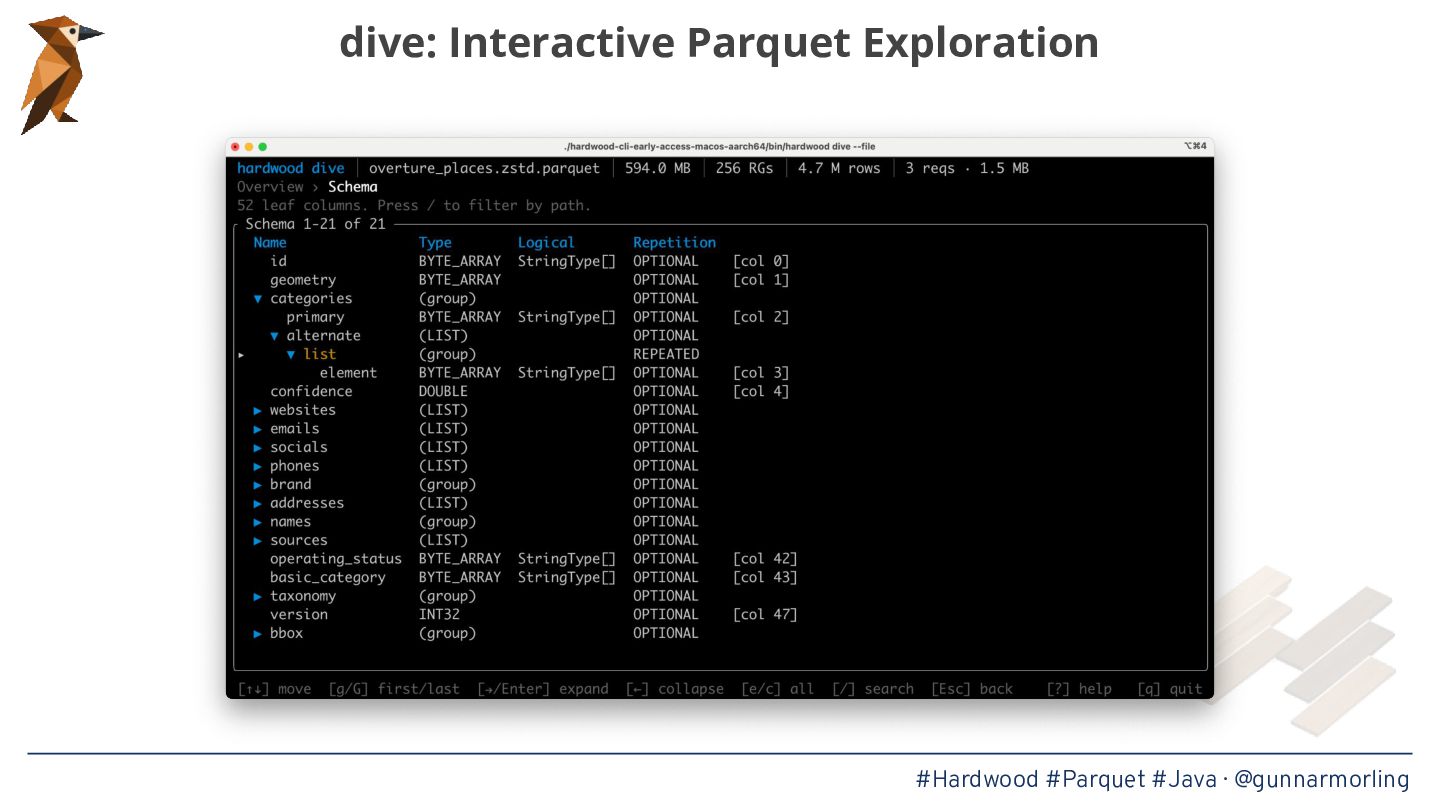
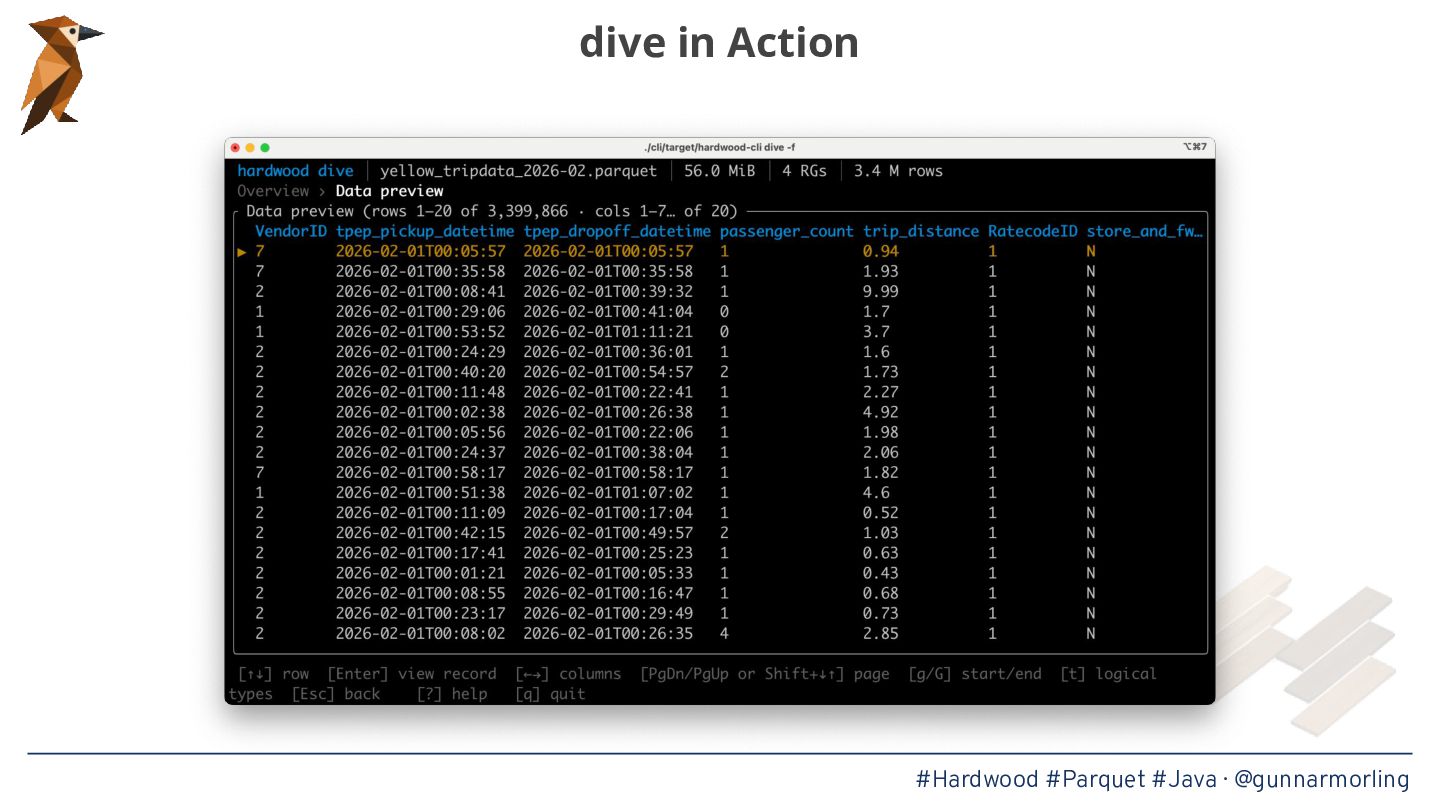
Hardwood CLI: Swiss Army Knife for Parquet $ hardwood print
-n 20 -f data.parquet $ hardwood convert --format json -f s3://bucket/data.parquet $ hardwood inspect columns -f data.parquet #Hardwood #Parquet #Java · @gunnarmorling -
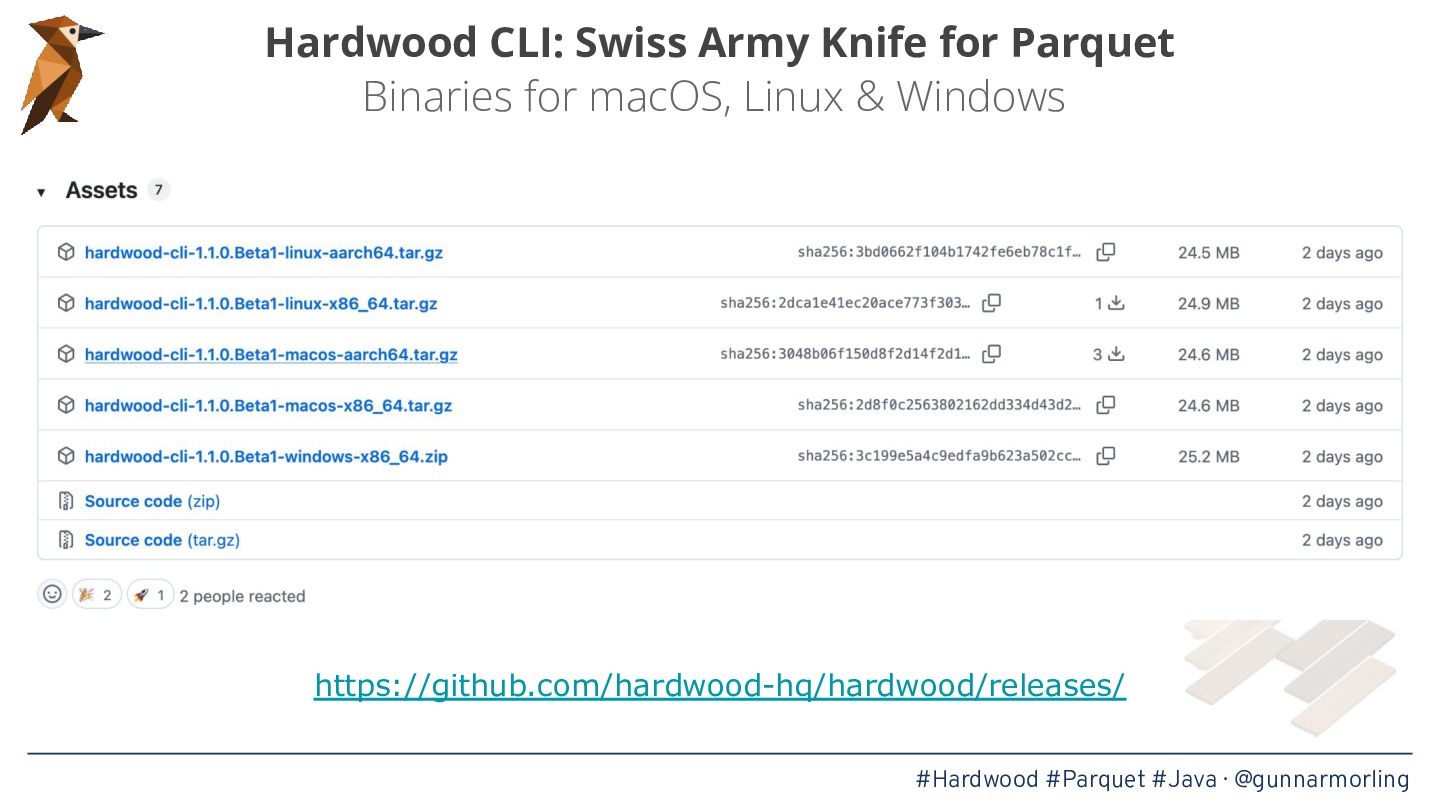
Hardwood CLI: Swiss Army Knife for Parquet Binaries for macOS,
Linux & Windows https://github.com/hardwood-hq/hardwood/releases/ #Hardwood #Parquet #Java · @gunnarmorling -
What AI Does Well • Implementing a spec — encodings,
page headers, Thrift Compact Protocol • Driving test suites — parquet-testing corpus, plus parquet-java & DuckDB as test-scope oracles • Triaging failures — “what does this hex dump tell us?” • Boilerplate — JMH harnesses, Testcontainers setup, GraalVM hints #Hardwood #Parquet #Java · @gunnarmorling -
Identifying Performance Bottlenecks “Make it faster, Claude!” Works Pretty Well!
#Hardwood #Parquet #Java · @gunnarmorling -
Where You Need to Stay Sharp • Duplicated logic —
two near-identical decoders instead of one, because it’s easier than refactoring • Paper-over corner cases — another if/else instead of fixing the underlying bug • Quietly excluding test cases — instead of figuring out why the unexpected result happened • “Plausible” performance “wins” — that benchmarks reveal as no-ops or regressions #Hardwood #Parquet #Java · @gunnarmorling -
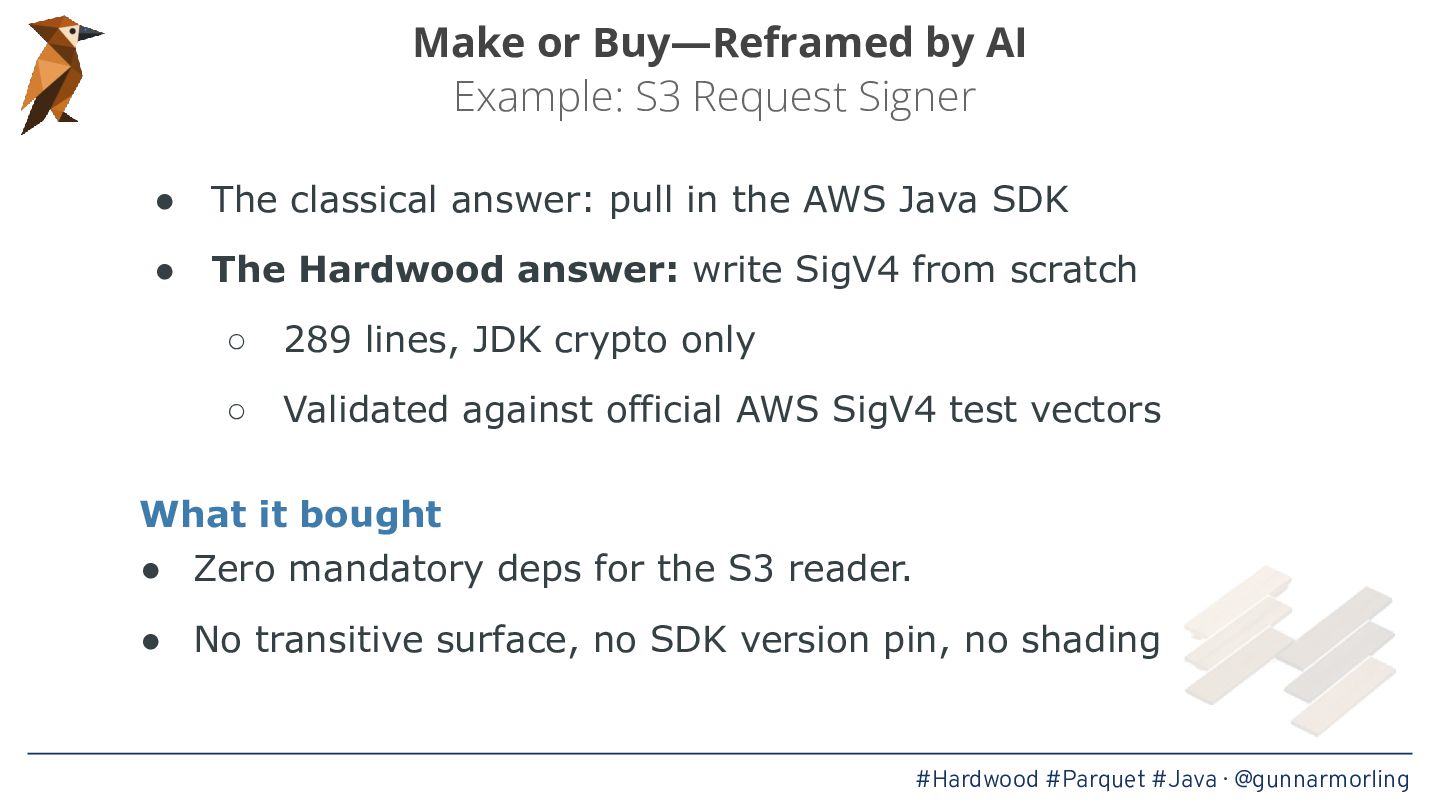
Make or Buy—Reframed by AI Example: S3 Request Signer •
The classical answer: pull in the AWS Java SDK • The Hardwood answer: write SigV4 from scratch ◦ 289 lines, JDK crypto only ◦ Validated against official AWS SigV4 test vectors What it bought • Zero mandatory deps for the S3 reader. • No transitive surface, no SDK version pin, no shading #Hardwood #Parquet #Java · @gunnarmorling -
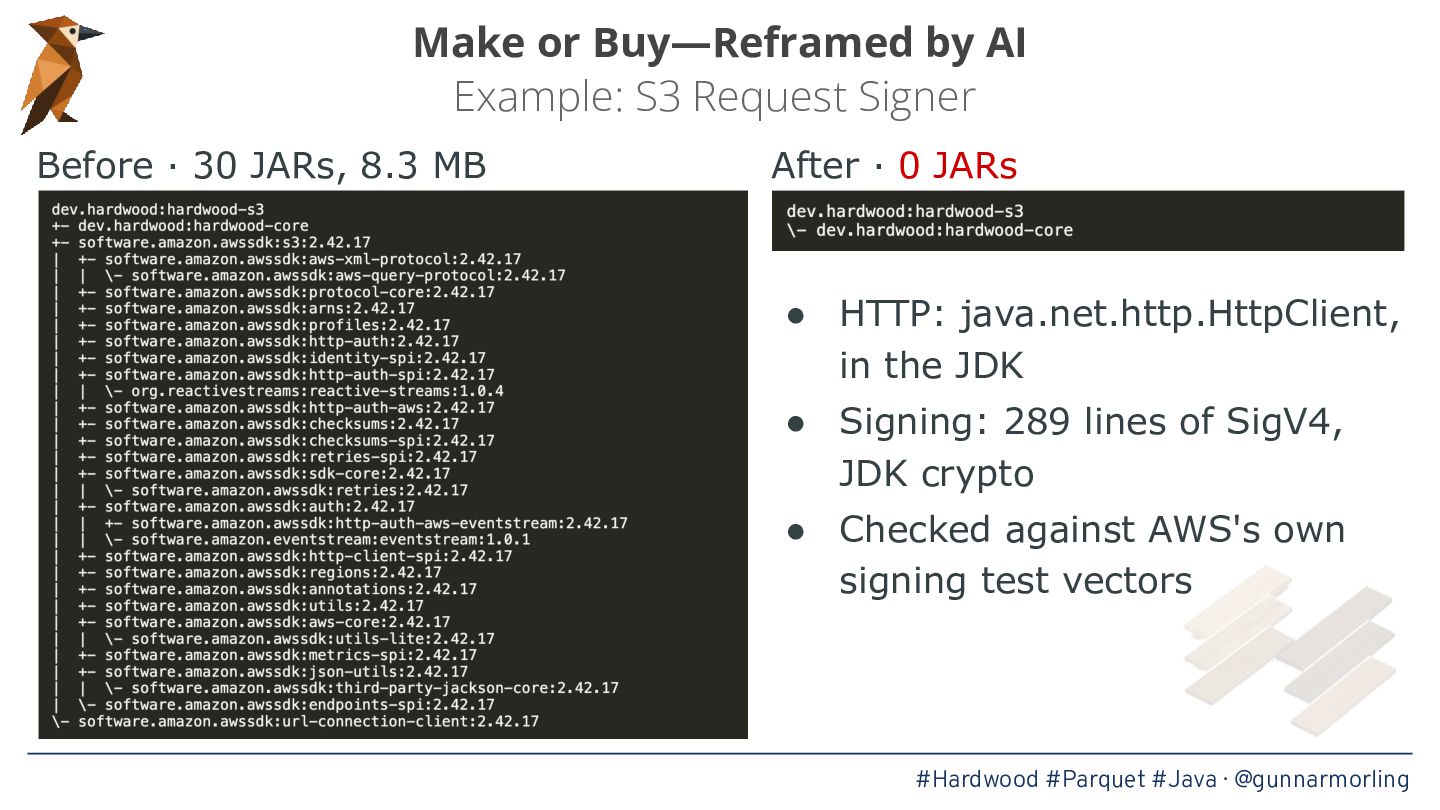
Make or Buy—Reframed by AI Example: S3 Request Signer Before
· 30 JARs, 8.3 MB After · 0 JARs • HTTP: java.net.http.HttpClient, in the JDK • Signing: 289 lines of SigV4, JDK crypto • Checked against AWS's own signing test vectors #Hardwood #Parquet #Java · @gunnarmorling -
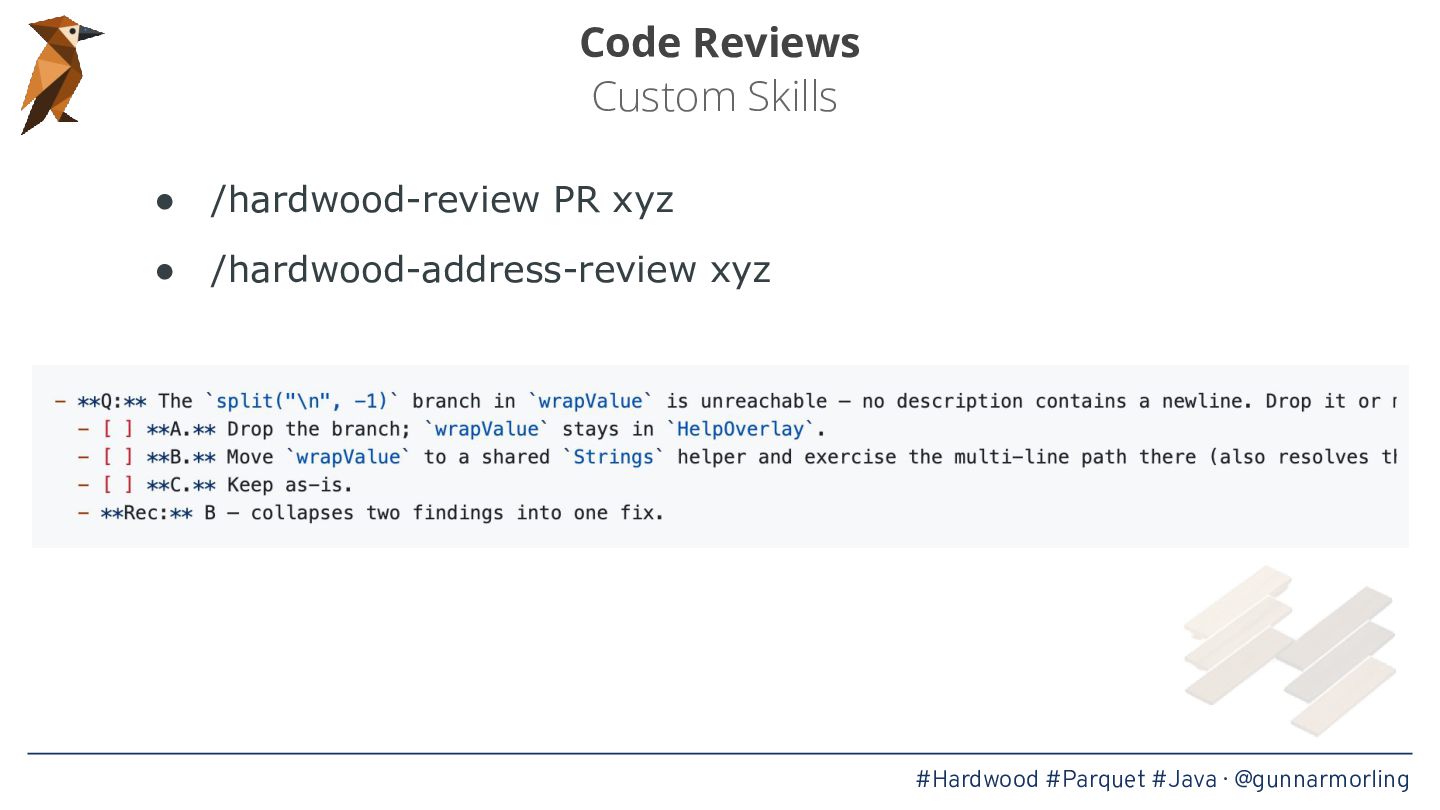
Code Reviews Custom Skills • /hardwood-review PR xyz • /hardwood-address-review
xyz #Hardwood #Parquet #Java · @gunnarmorling -
Built with AI ≠ Vibe-Coded LLM-assisted contributions are welcome. Vibe
coding is not. • You must be able to explain the change • You own the architecture: invariants, threading, allocation budget • Benchmarks are the ground truth, not Claude’s narration AI-generated code is a starting point, not an end state. #Hardwood #Parquet #Java · @gunnarmorling -
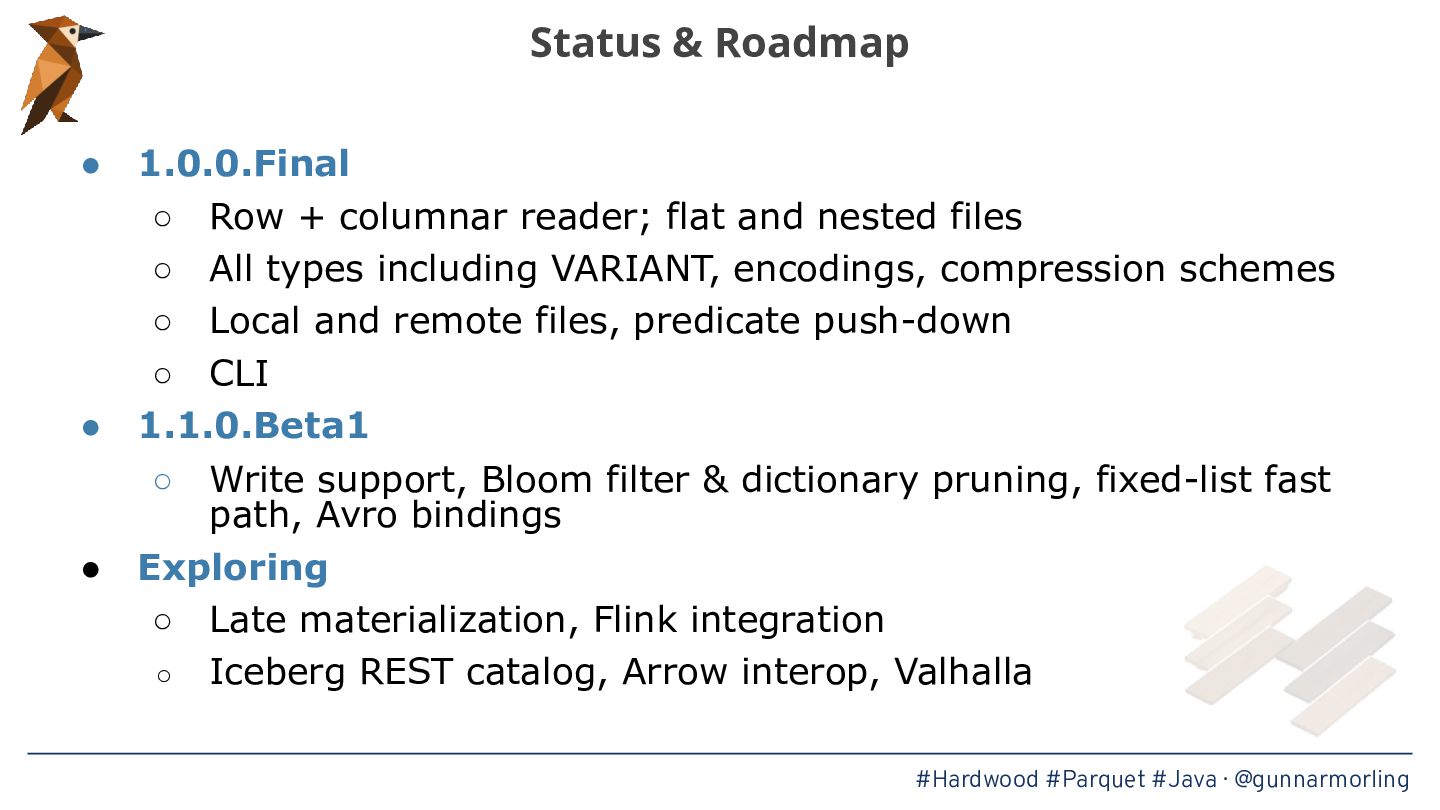
Status & Roadmap • • 1.0.0.Final ◦ Row + columnar
reader; flat and nested files ◦ All types including VARIANT, encodings, compression schemes ◦ Local and remote files, predicate push-down ◦ CLI 1.1.0.Beta1 Write support, Bloom filter & dictionary pruning, fixed-list fast path, Avro bindings Exploring ◦ Late materialization, Flink integration ◦ Iceberg REST catalog, Arrow interop, Valhalla ◦ • #Hardwood #Parquet #Java · @gunnarmorling -
Summary Learn more on hardwood.dev • Hardwood: ◦ Fast, zero-dependency
Parquet library for the JVM ◦ Modern Java pays off in real numbers ◦ AI is a force multiplier — but you stay the engineer #Hardwood #Parquet #Java · @gunnarmorling -
Get In Touch 📧[email protected] @gunnarmorling @gunnarmorling.dev �� morling.dev �� #Hardwood
#Parquet #Java · @gunnarmorling