Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
文献紹介_20180518_Pixel-Level Domain Transfer
Search
hrsma2i
May 18, 2018
Research
72
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
文献紹介_20180518_Pixel-Level Domain Transfer
文献紹介
hrsma2i
May 18, 2018
More Decks by hrsma2i
See All by hrsma2i
文献紹介_20181123_SeqGAN_ Sequence Generative Adversarial Nets with Policy Gradient
hrsma2i
0
110
文献紹介_20180622_MUNIT _ Multimodal Unsupervised Image-to-Image Translation
hrsma2i
0
110
文献紹介_20180420_CSN _ Learning Type-Aware Embeddings for Fashion Compatibility
hrsma2i
0
190
文献紹介_20171110_QRNN _ Quasi-Recurrent Neural Networks
hrsma2i
0
63
Other Decks in Research
See All in Research
Prithvi-EO-2.0
satai
3
100
VLMの推論を高速化する視覚トークン削減の仕組み
tattaka
2
380
視覚若手の会LENSって何??
mickey_0226
0
360
PHTalks Bengaluru - SSRF When All Else Fails
dk999
0
1.2k
Visual SLAM未来予測 / Future Prediction in Visual SLAM
koide3
1
1.3k
Vector Map as Language: Toward Unified Remote Sensing Vector Mapping
satai
3
320
Pesée et pointage par imagerie 3D : PHENO3D entre en phase de test terrains
institutdelelevage
PRO
0
110
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
300
完全自律LLMエージェントでDIVER OSINT CTF 2026に挑戦してみた
analokmaus
0
770
Empreinte carbone des ovins : une approche globale (technique, économique, environnementale) – 4 années de résultats avec LIFE GREEN SHEEP
institutdelelevage
PRO
0
110
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
220
Sleuthcon Keynote - How Cybercriminals (ab)use AI
fr0gger
0
390
Featured
See All Featured
Are puppies a ranking factor?
jonoalderson
2
4.1k
Speed Design
sergeychernyshev
33
2.2k
Optimizing for Happiness
mojombo
378
71k
The State of eCommerce SEO: How to Win in Today's Products SERPs - #SEOweek
aleyda
2
12k
Future Trends and Review - Lecture 12 - Web Technologies (1019888BNR)
signer
PRO
0
3.8k
Joys of Absence: A Defence of Solitary Play
codingconduct
1
550
Refactoring Trust on Your Teams (GOTO; Chicago 2020)
rmw
35
3.8k
Making the Leap to Tech Lead
cromwellryan
135
10k
Dealing with People You Can't Stand - Big Design 2015
cassininazir
367
27k
The Impact of AI in SEO - AI Overviews June 2024 Edition
aleyda
6
1.2k
Intergalactic Javascript Robots from Outer Space
tanoku
273
28k
Self-Hosted WebAssembly Runtime for Runtime-Neutral Checkpoint/Restore in Edge–Cloud Continuum
chikuwait
0
890
Transcript
文献紹介 Pixel-Level Domain Transfer author: Yoo, Donggeun
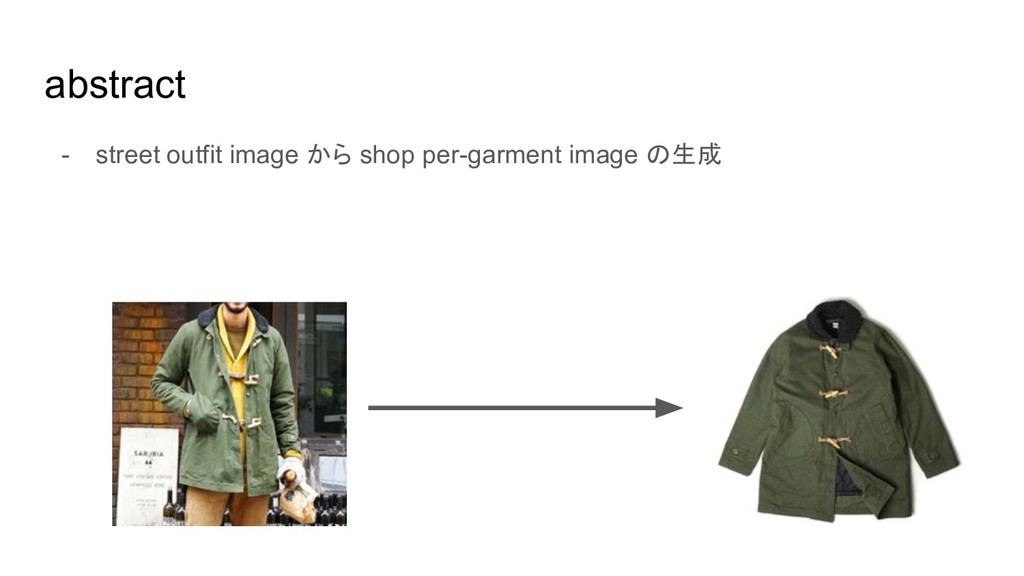
abstract - street outfit image から shop per-garment image の生成
Table of Contents - Introduction - Domain adaptation - GANs
- Method - Results - manual evaluation - automated evaluation
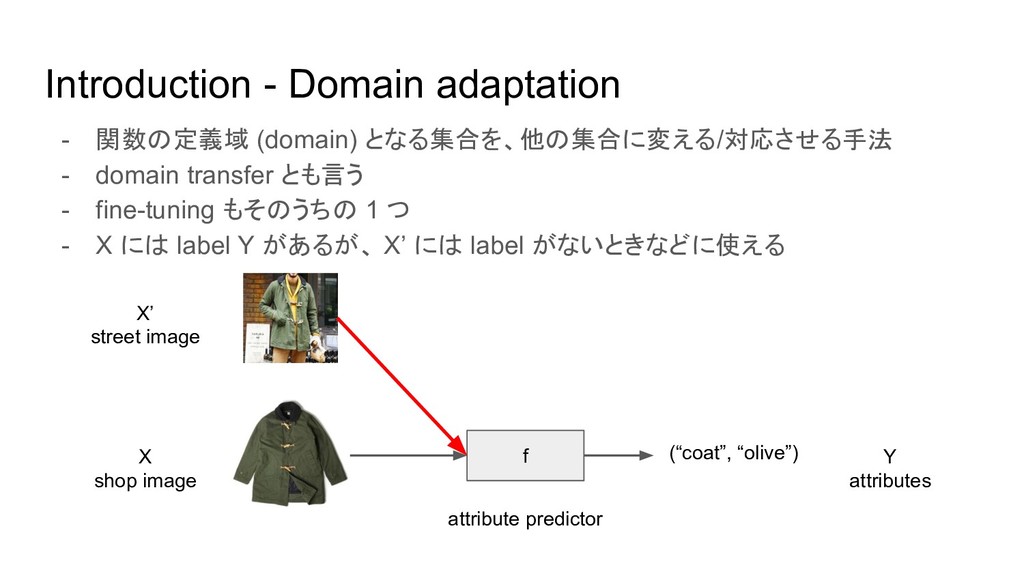
Introduction - Domain adaptation - 関数の定義域 (domain) となる集合を、他の集合に変える/対応させる手法 - domain
transfer とも言う - fine-tuning もそのうちの 1 つ - X には label Y があるが、 X’ には label がないときなどに使える f X shop image Y attributes (“coat”, “olive”) X’ street image attribute predictor
Introduction - street to shop - domain adaptation, domain transfer
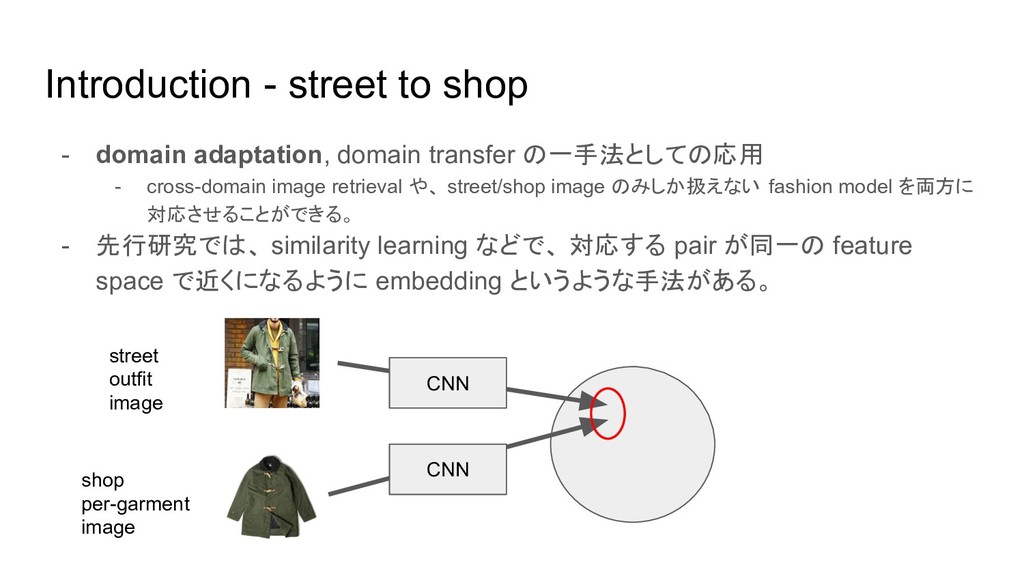
の一手法としての応用 - cross-domain image retrieval や、 street/shop image のみしか扱えない fashion model を両方に 対応させることができる。 - 先行研究では、 similarity learning などで、 対応する pair が同一の feature space で近くになるように embedding というような手法がある。 CNN CNN street outfit image shop per-garment image
Introduction - our work - 今回は、 street image から shop
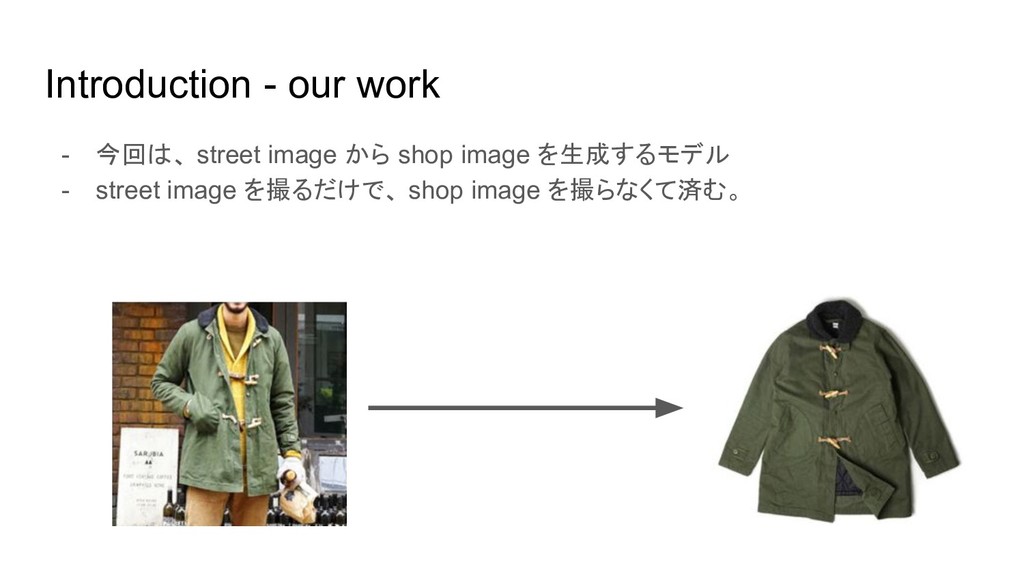
image を生成するモデル - street image を撮るだけで、 shop image を撮らなくて済む。
Introduction - GANs: Generative Adversarial Networks - 設計の難しい loss 関数に対し、その
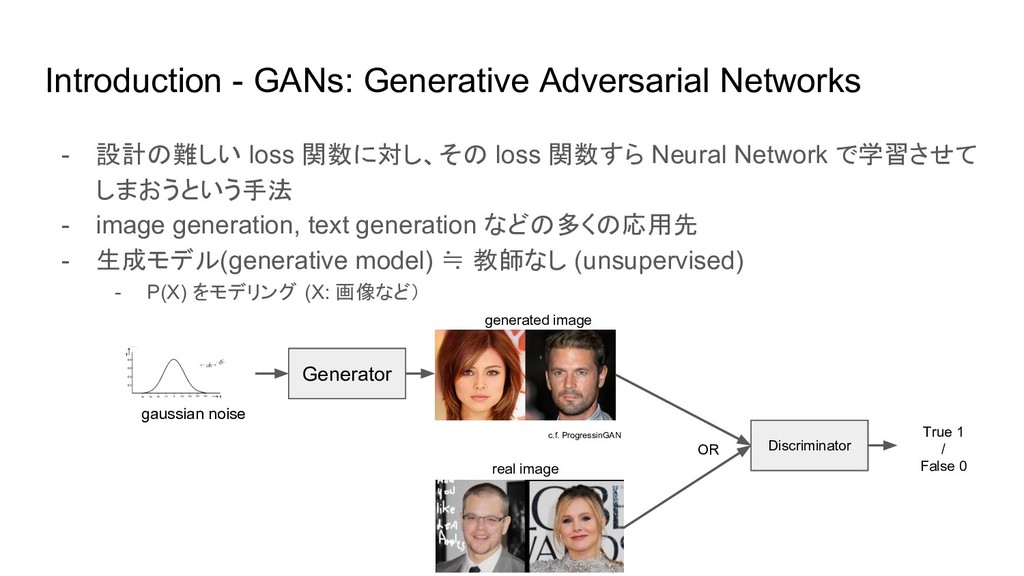
loss 関数すら Neural Network で学習させて しまおうという手法 - image generation, text generation などの多くの応用先 - 生成モデル(generative model) ≒ 教師なし (unsupervised) - P(X) をモデリング (X: 画像など) Generator c.f. ProgressinGAN gaussian noise generated image OR Discriminator real image True 1 / False 0
Introduction - GANs: Generative Adversarial Networks - Generator, Discriminator を交互に学習させる。
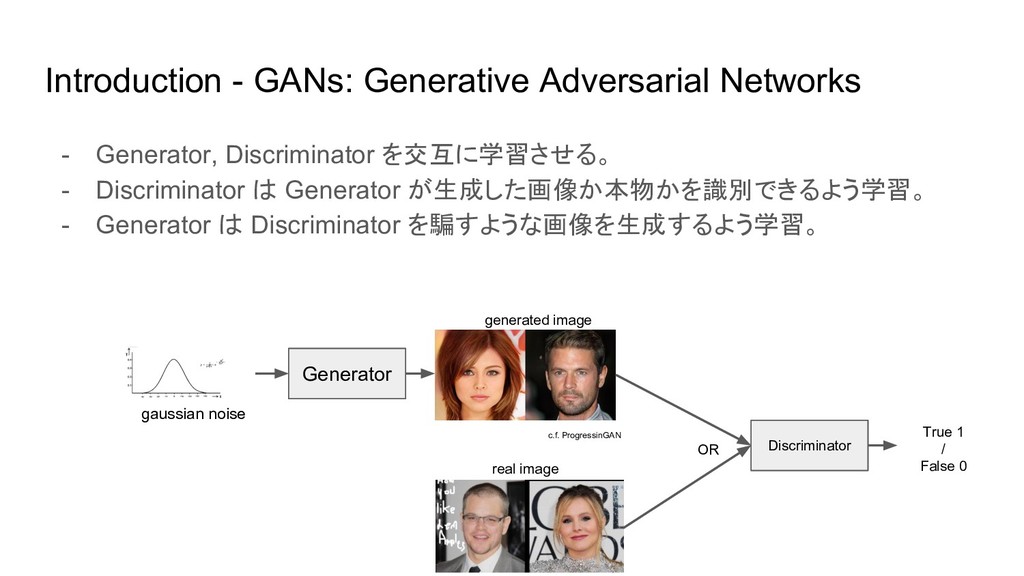
- Discriminator は Generator が生成した画像か本物かを識別できるよう学習。 - Generator は Discriminator を騙すような画像を生成するよう学習。 Generator c.f. ProgressinGAN gaussian noise generated image OR Discriminator real image True 1 / False 0
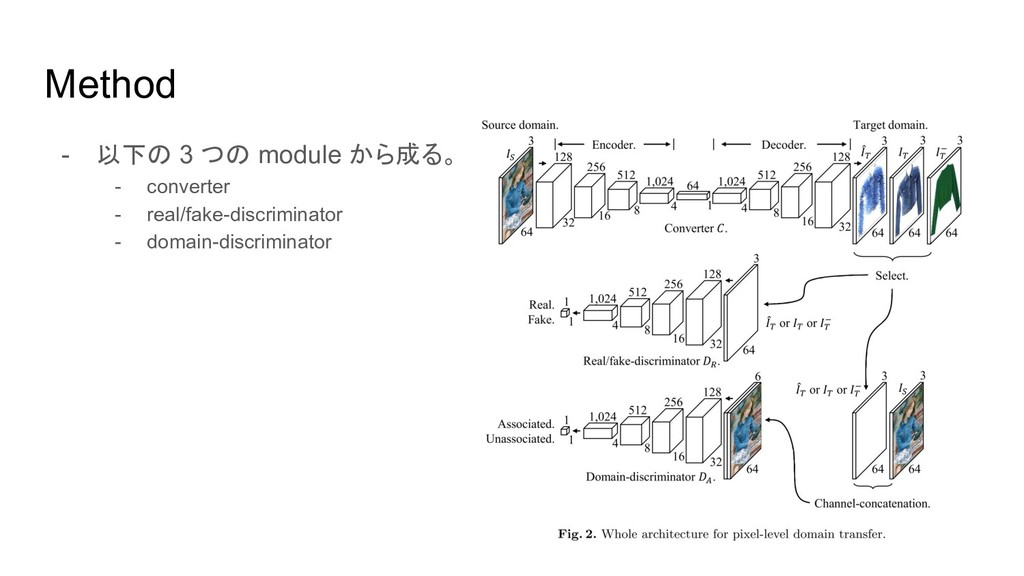
Method - 以下の 3 つの module から成る。 - converter -
real/fake-discriminator - domain-discriminator
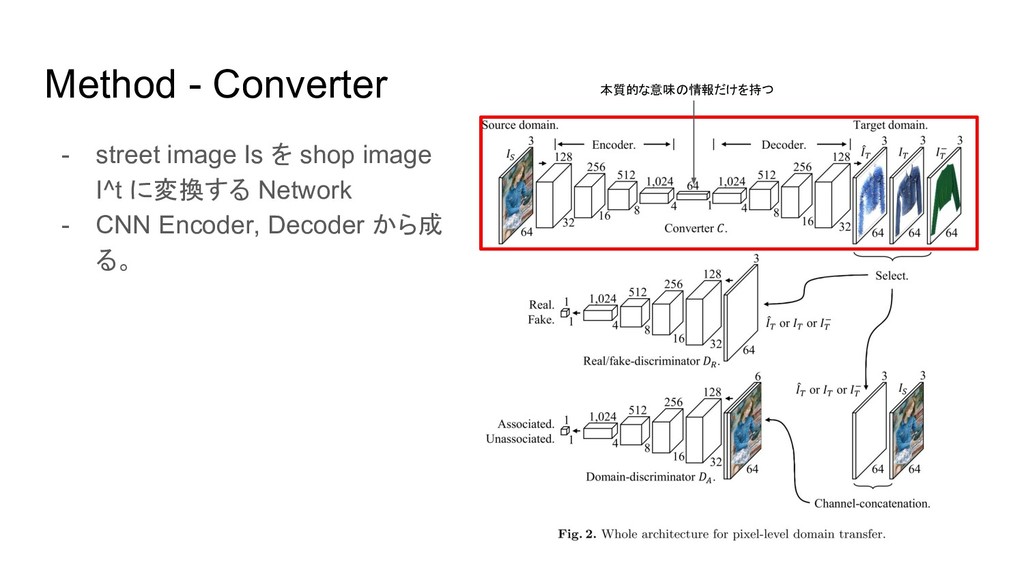
Method - Converter - street image Is を shop image
I^t に変換する Network - CNN Encoder, Decoder から成 る。 本質的な意味の情報だけを持つ
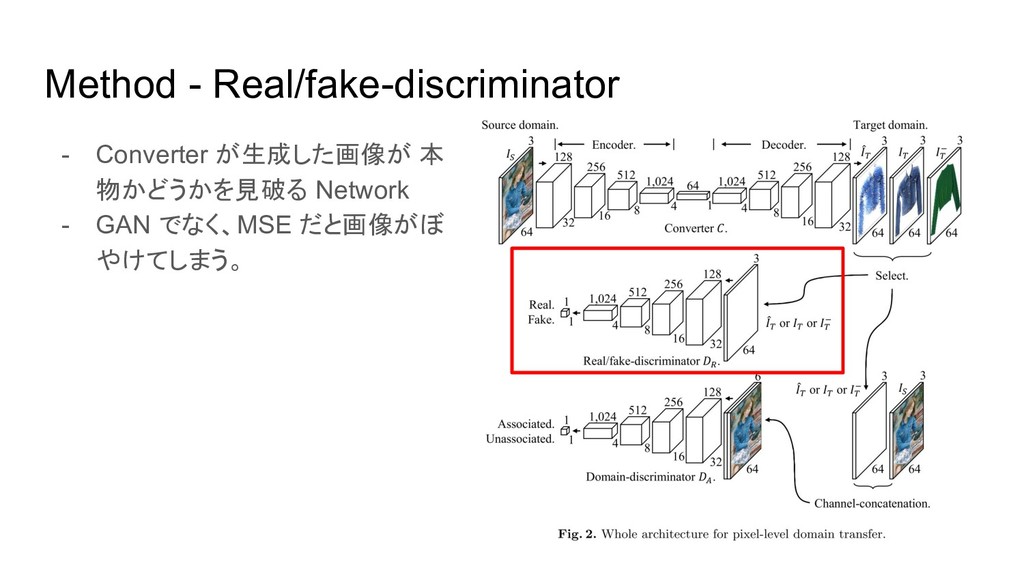
Method - Real/fake-discriminator - Converter が生成した画像が 本 物かどうかを見破る Network -
GAN でなく、MSE だと画像がぼ やけてしまう。
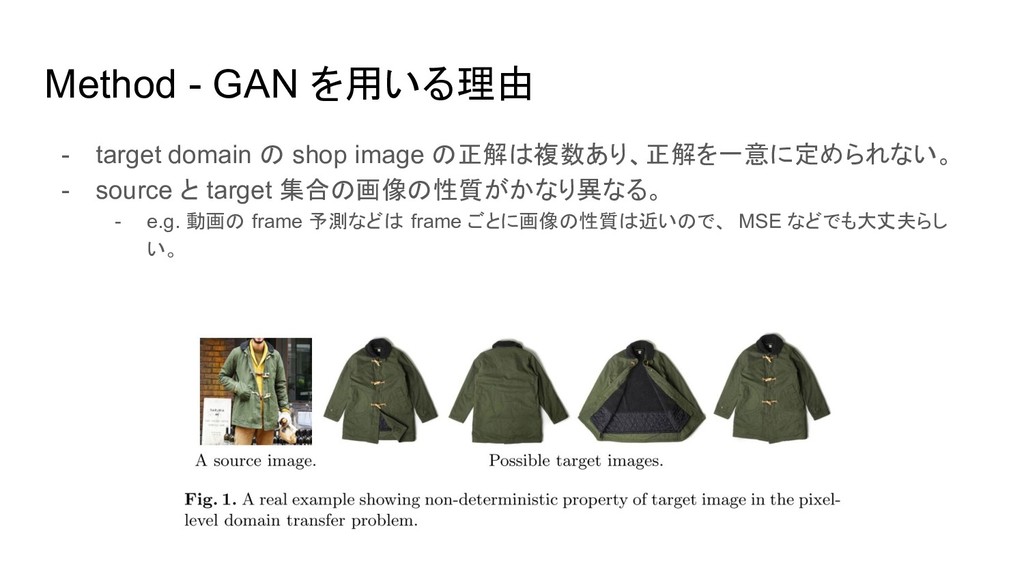
Method - GAN を用いる理由 - target domain の shop image
の正解は複数あり、正解を一意に定められない。 - source と target 集合の画像の性質がかなり異なる。 - e.g. 動画の frame 予測などは frame ごとに画像の性質は近いので、 MSE などでも大丈夫らし い。
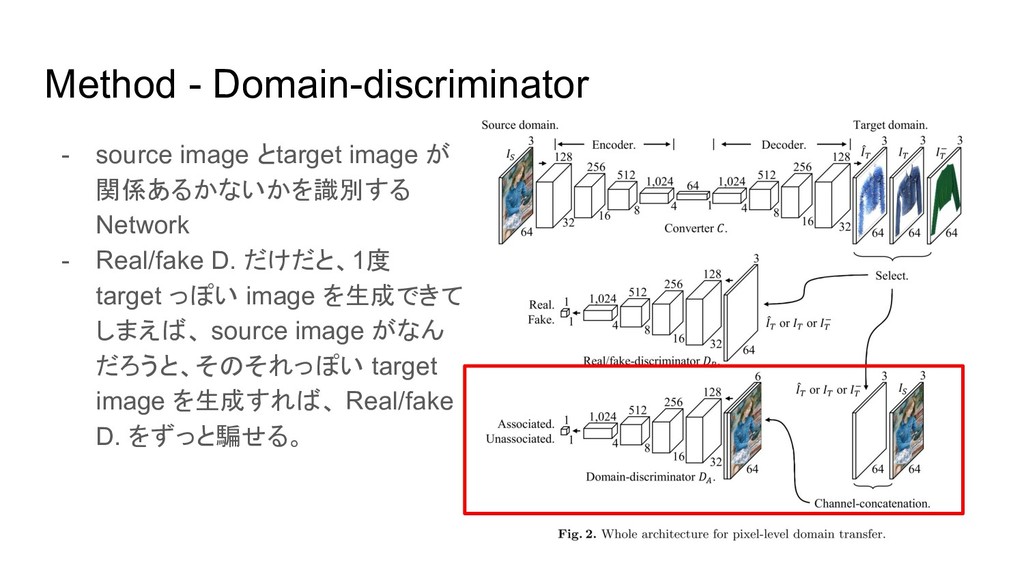
Method - Domain-discriminator - source image とtarget image が 関係あるかないかを識別する
Network - Real/fake D. だけだと、1度 target っぽい image を生成できて しまえば、 source image がなん だろうと、そのそれっぽい target image を生成すれば、 Real/fake D. をずっと騙せる。
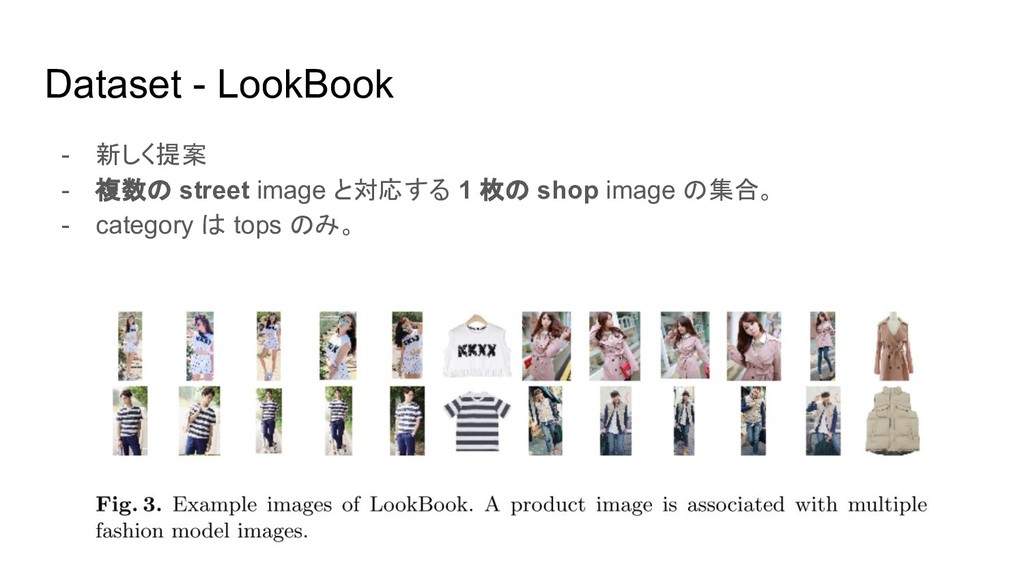
Dataset - LookBook - 新しく提案 - 複数の street image と対応する
1 枚の shop image の集合。 - category は tops のみ。
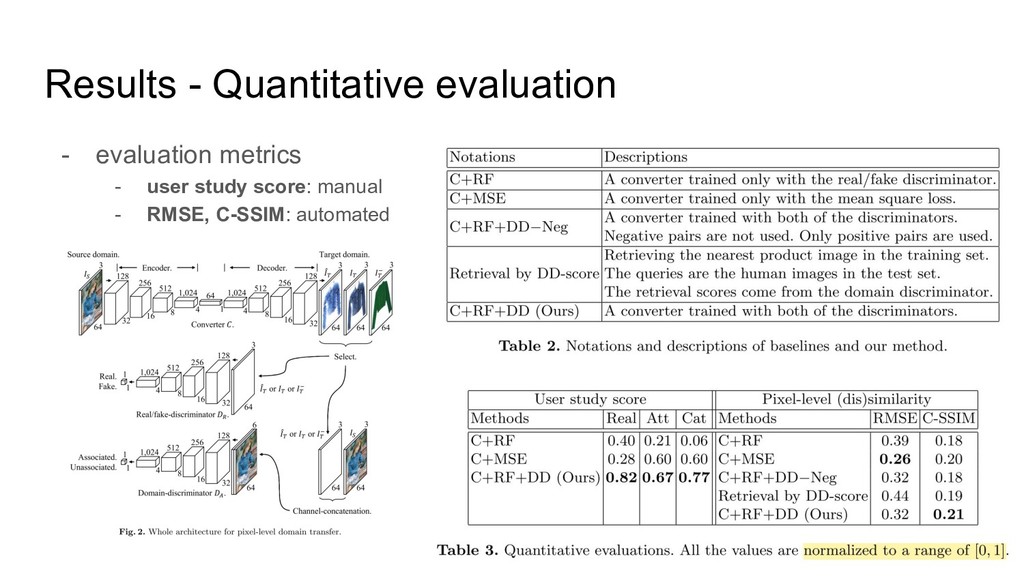
Results - Quantitative evaluation - evaluation metrics - user study
score: manual - RMSE, C-SSIM: automated
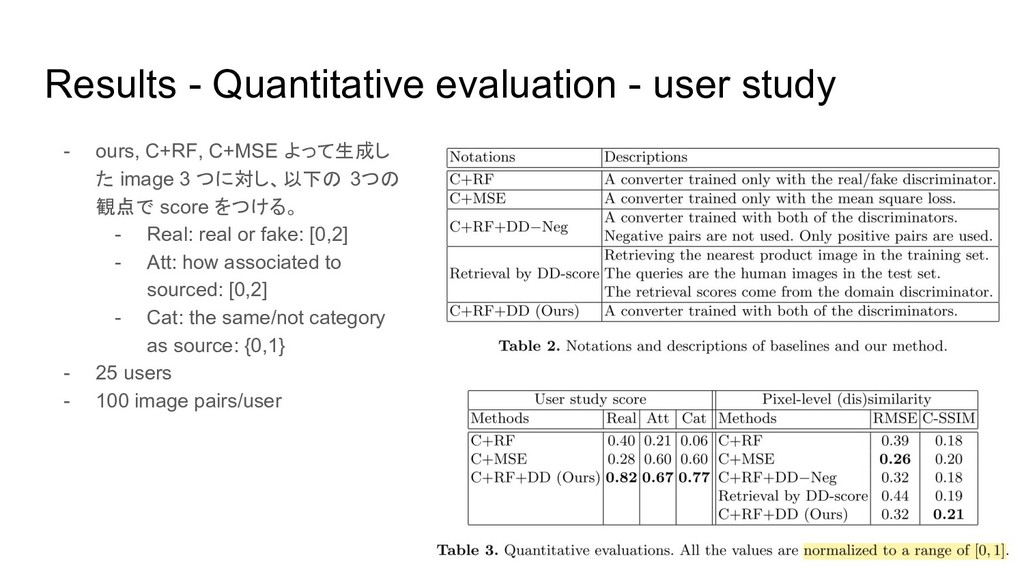
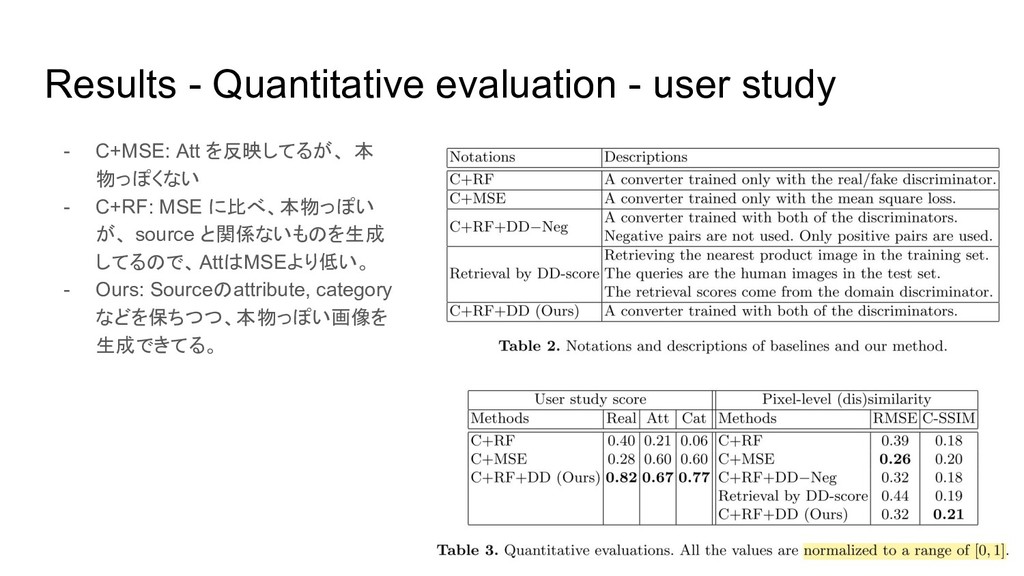
Results - Quantitative evaluation - user study - ours, C+RF,
C+MSE よって生成し た image 3 つに対し、以下の 3つの 観点で score をつける。 - Real: real or fake: [0,2] - Att: how associated to sourced: [0,2] - Cat: the same/not category as source: {0,1} - 25 users - 100 image pairs/user
Results - Quantitative evaluation - user study - C+MSE: Att
を反映してるが、 本 物っぽくない - C+RF: MSE に比べ、本物っぽい が、 source と関係ないものを生成 してるので、AttはMSEより低い。 - Ours: Sourceのattribute, category などを保ちつつ、本物っぽい画像を 生成できてる。
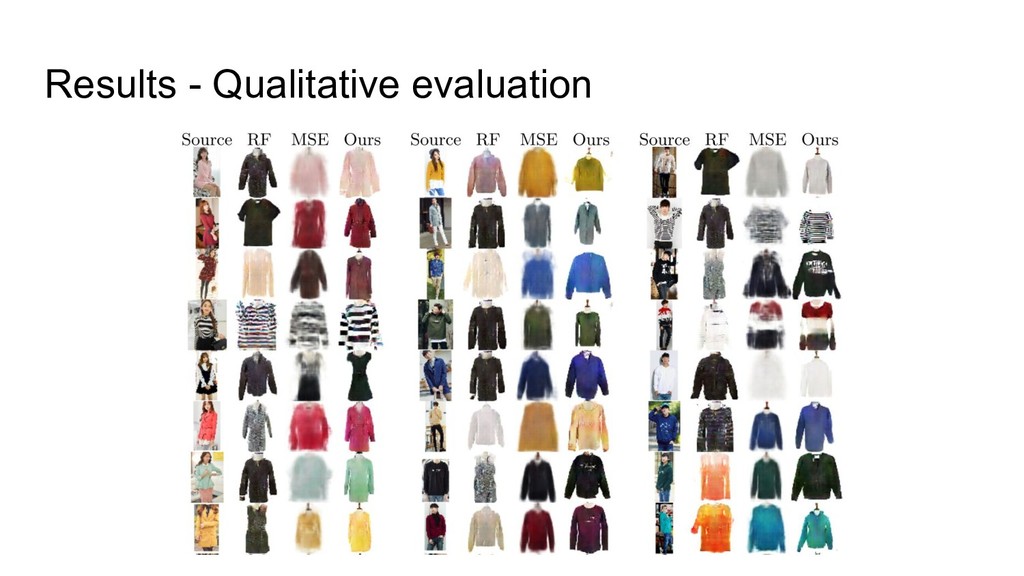
Results - Qualitative evaluation
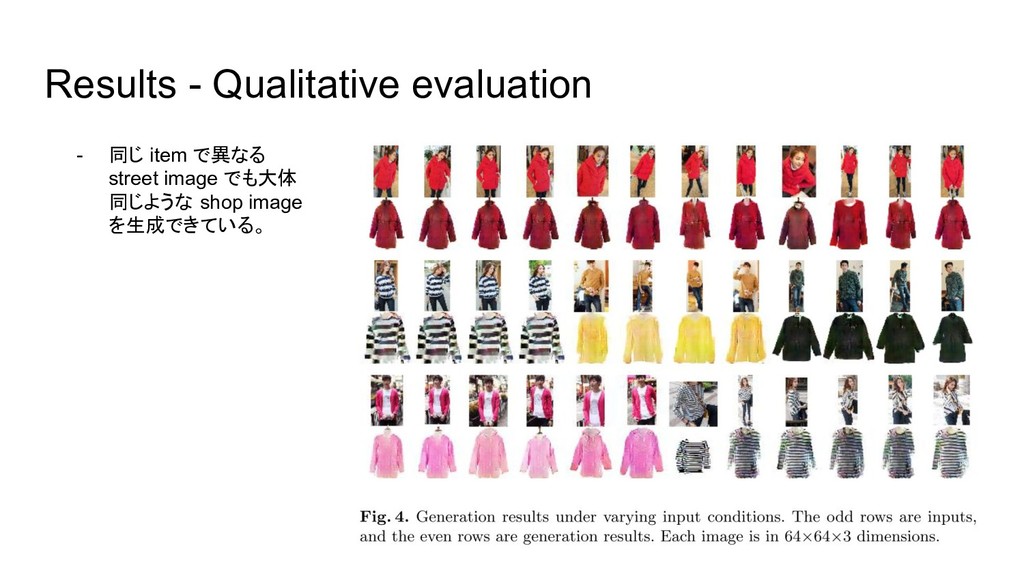
Results - Qualitative evaluation - 同じ item で異なる street image
でも大体 同じような shop image を生成できている。
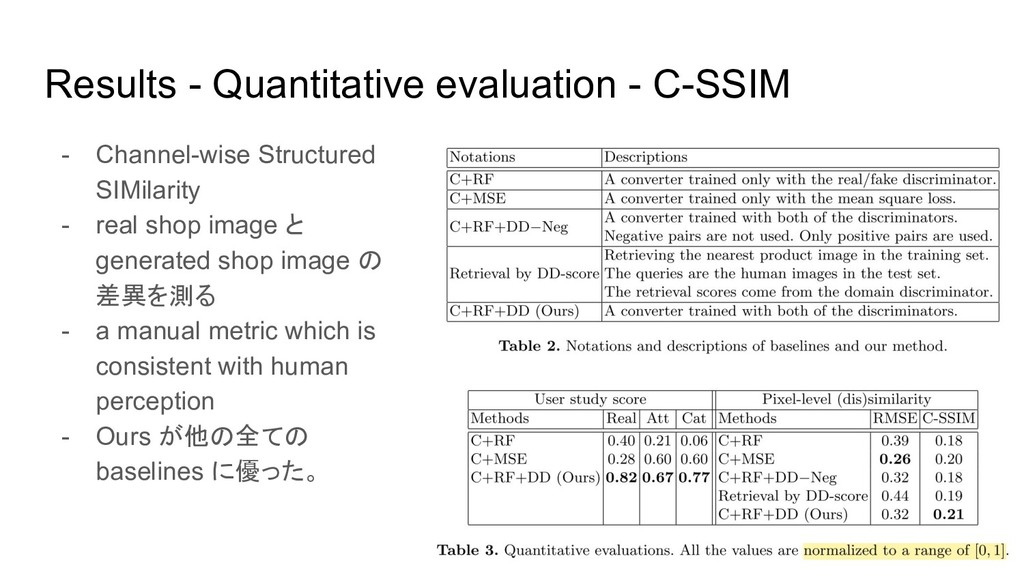
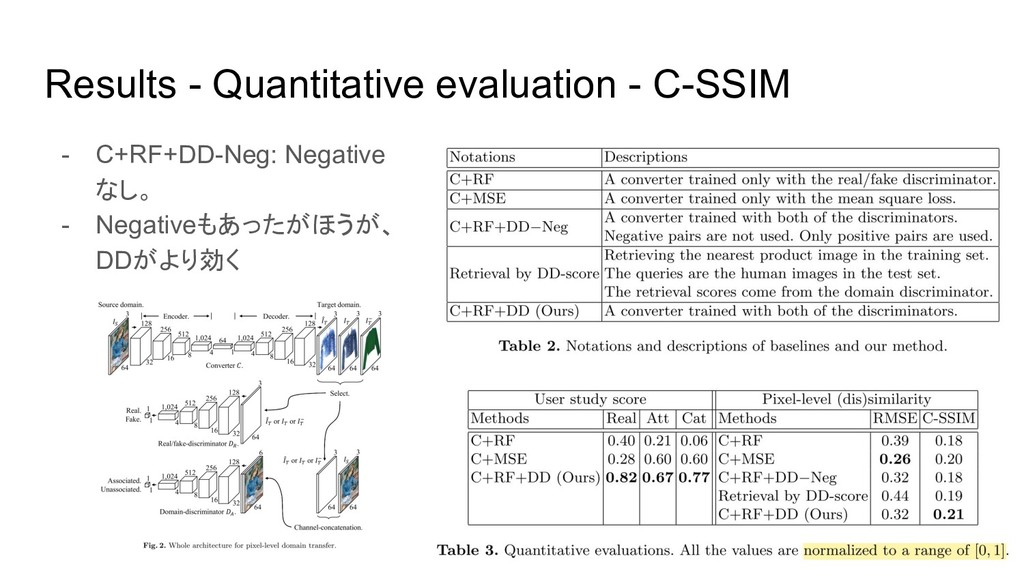
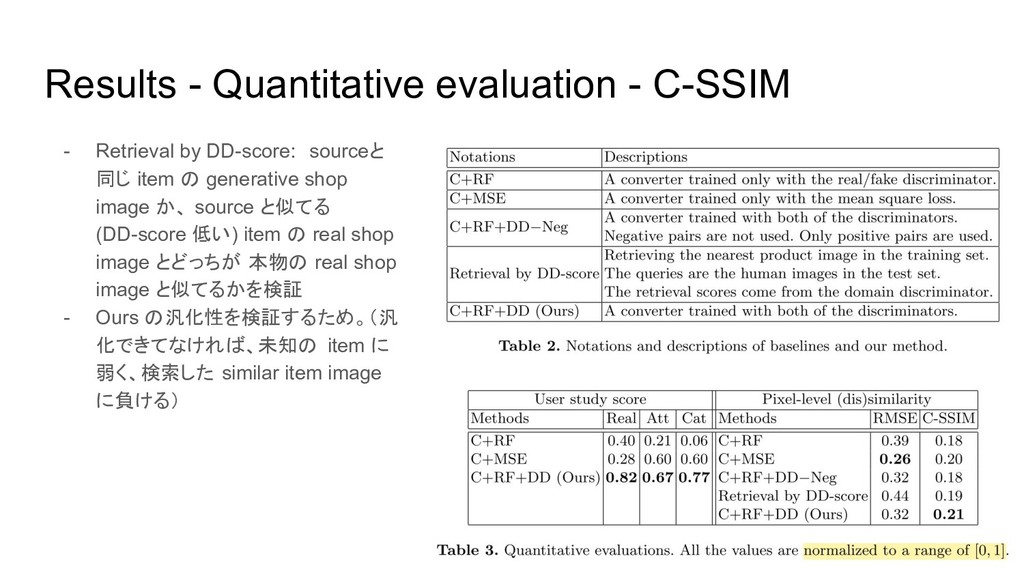
Results - Quantitative evaluation - C-SSIM - Channel-wise Structured SIMilarity
- real shop image と generated shop image の 差異を測る - a manual metric which is consistent with human perception - Ours が他の全ての baselines に優った。
Results - Quantitative evaluation - C-SSIM - C+RF+DD-Neg: Negative なし。
- Negativeもあったがほうが、 DDがより効く
Results - Quantitative evaluation - C-SSIM - Retrieval by DD-score: sourceと
同じ item の generative shop image か、 source と似てる (DD-score 低い) item の real shop image とどっちが 本物の real shop image と似てるかを検証 - Ours の汎化性を検証するため。(汎 化できてなければ、未知の item に 弱く、検索した similar item image に負ける)
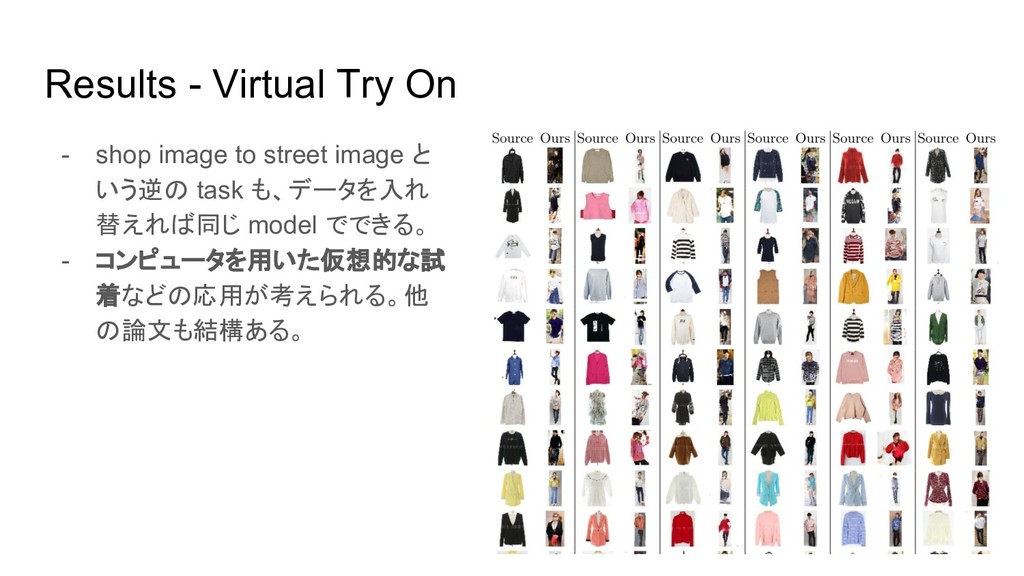
Results - Virtual Try On - shop image to street
image と いう逆の task も、データを入れ 替えれば同じ model でできる。 - コンピュータを用いた仮想的な試 着などの応用が考えられる。他 の論文も結構ある。
Conclusion - street2shop image generation で pixel-level での domain trasfer
の手法を初め て提案した。 - Domain-discriminator により、 Source の意味情報を保ったまま、本物っぽい画像 の生成ができるようになった。 - street-shop image の novel dataset を提案。


 hrsma2i
 satai
 tattaka
 mickey_0226
 dk999
 koide3
 institutdelelevage
 s_mizuki_nlp
 analokmaus
 rikkabotan7
 fr0gger
 jonoalderson
 sergeychernyshev
 mojombo
 aleyda
 signer
 codingconduct
 rmw
 cromwellryan
 cassininazir
 tanoku
 chikuwait