Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
文献紹介_20171110_QRNN _ Quasi-Recurrent Neural Net...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
hrsma2i
November 10, 2017
Research
63
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
文献紹介_20171110_QRNN _ Quasi-Recurrent Neural Networks
文献紹介
hrsma2i
November 10, 2017
More Decks by hrsma2i
See All by hrsma2i
文献紹介_20181123_SeqGAN_ Sequence Generative Adversarial Nets with Policy Gradient
hrsma2i
0
110
文献紹介_20180622_MUNIT _ Multimodal Unsupervised Image-to-Image Translation
hrsma2i
0
110
文献紹介_20180518_Pixel-Level Domain Transfer
hrsma2i
0
72
文献紹介_20180420_CSN _ Learning Type-Aware Embeddings for Fashion Compatibility
hrsma2i
0
190
Other Decks in Research
See All in Research
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
220
HAKARI-Bench - 実運用視点での情報検索モデル評価ベンチマーク
hotchpotch
1
820
最先端NLP勉強会2026 論文紹介:Reasoning with Sampling: Your Base Model is Smarter Than You Think (ICLR 2026 paper)
kogoro
4
720
[IEICE-Soceity-Conf2026] セマンティック通信を見据えたマルチスケールセンシングと 学習の融合によるデジタルツイン基盤 / Digital Twin Infrastructure via the Fusion of Multi-Scale Sensing and Learning toward Semantic Communications
pman0214
0
110
論文紹介:Doc-to-LoRA: Learning to Instantly Internalize Contexts
yukako_nakano
0
200
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
190
全国町字単位空き家率推定データver1.0データ仕様
microbaseinc
0
290
Easy to Guess, Hard to Verify: Lessons from AIMO 3 for Olympiad-Level AI Mathematics
corochann
0
130
完全自律LLMエージェントでDIVER OSINT CTF 2026に挑戦してみた
analokmaus
0
780
【Zozo Research 技術共有会】三次元領域の現在と展望
mickey_0226
3
680
就労支援の現場での生成AI活用
enochan
0
150
Vector Map as Language: Toward Unified Remote Sensing Vector Mapping
satai
3
320
Featured
See All Featured
Build your cross-platform service in a week with App Engine
jlugia
234
19k
JAMstack: Web Apps at Ludicrous Speed - All Things Open 2022
reverentgeek
1
640
Rebuilding a faster, lazier Slack
samanthasiow
85
9.7k
New Earth Scene 8
popppiees
4
2.7k
Speed Design
sergeychernyshev
33
2.2k
Leo the Paperboy
mayatellez
10
2.4k
[Rails World 2026] Durable orchestration on Rails: from continuation to workflow
palkan
1
750
The Invisible Side of Design
smashingmag
301
52k
Testing 201, or: Great Expectations
jmmastey
46
8.3k
Building Adaptive Systems
keathley
44
3.3k
Why Your Marketing Sucks and What You Can Do About It - Sophie Logan
marketingsoph
0
430
HTML-Aware ERB: The Path to Reactive Rendering @ RubyCon 2026, Rimini, Italy
marcoroth
5
830
Transcript
James Bradbury∗, Stephen Merity∗ , Caiming Xiong & Richard Socher
Salesforce Research Palo Alto, California arXiv:1611.01576v2 [cs.NE] 21 Nov 2016 ICLR 2017 accepted 文献紹介 QRNN: QUASI-RECURRENT NEURAL NETWORKS
Abstract - QRNN = RNN processing like CNN - can
process sequential data in parallel - up to 16 times faster than LSTM in train/test - can make visual analysis of weights easy
Outline - Introduction - review of RNN/LSTM - Model (QRNN)
- Variants - Results - sentiment classification - language modeling - character-level machine translation - Conclusion - Reference
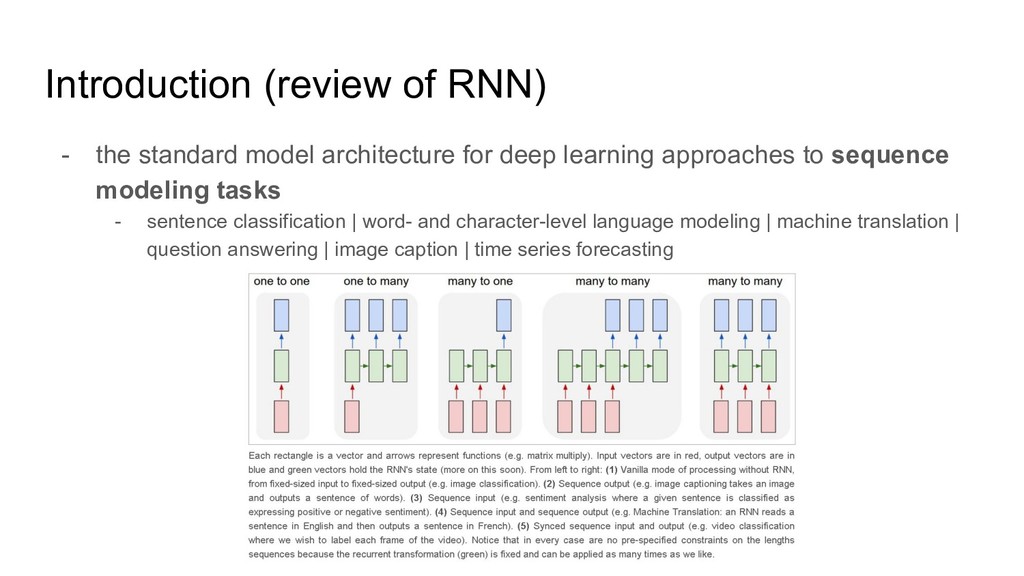
Introduction (review of RNN) - the standard model architecture for
deep learning approaches to sequence modeling tasks - sentence classification | word- and character-level language modeling | machine translation | question answering | image caption | time series forecasting
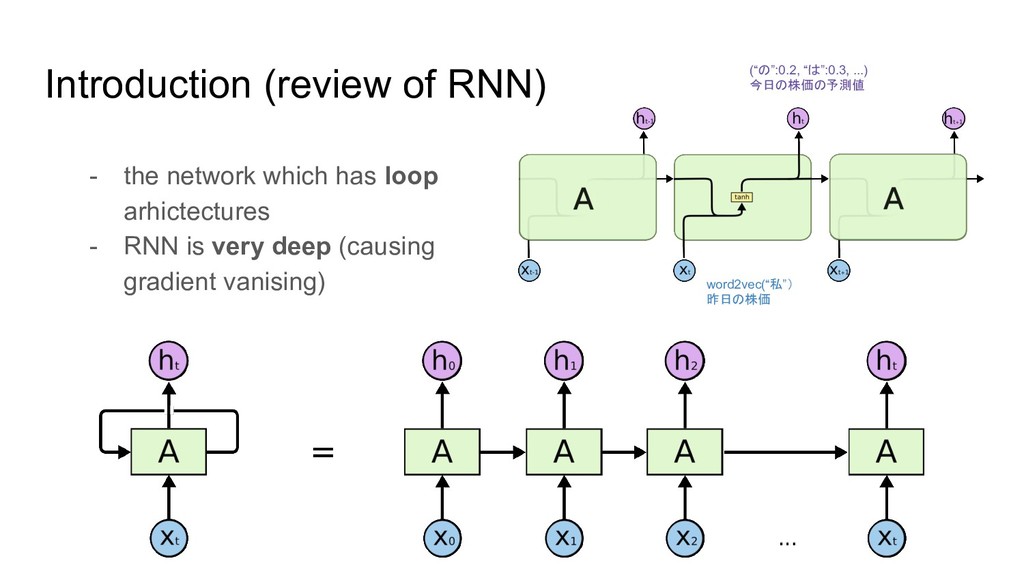
Introduction (review of RNN) - the network which has loop
arhictectures - RNN is very deep (causing gradient vanising) word2vec(“私”) 昨日の株価 (“の”:0.2, “は”:0.3, ...) 今日の株価の予測値
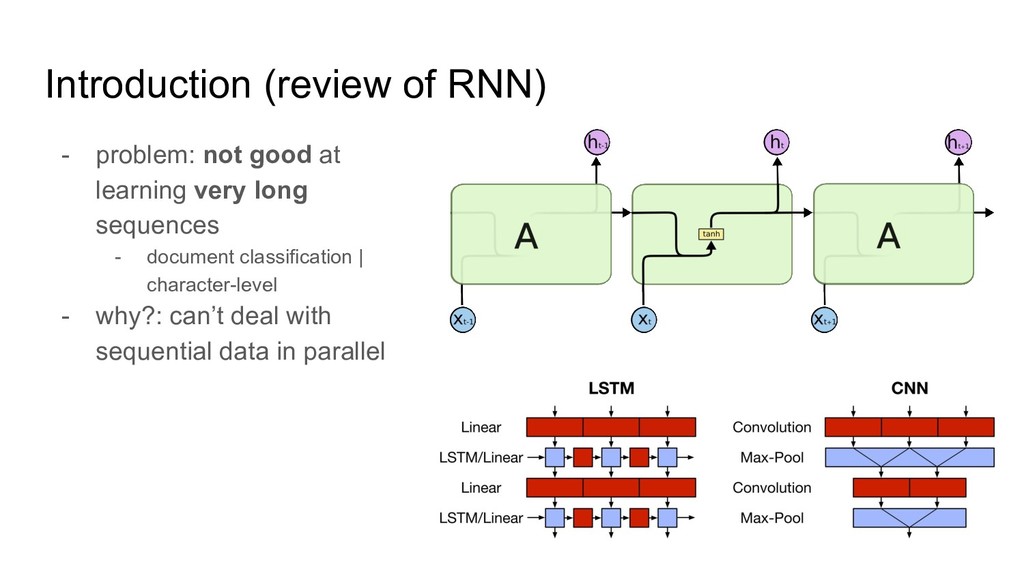
Introduction (review of RNN) - problem: not good at learning
very long sequences - document classification | character-level - why?: can’t deal with sequential data in parallel
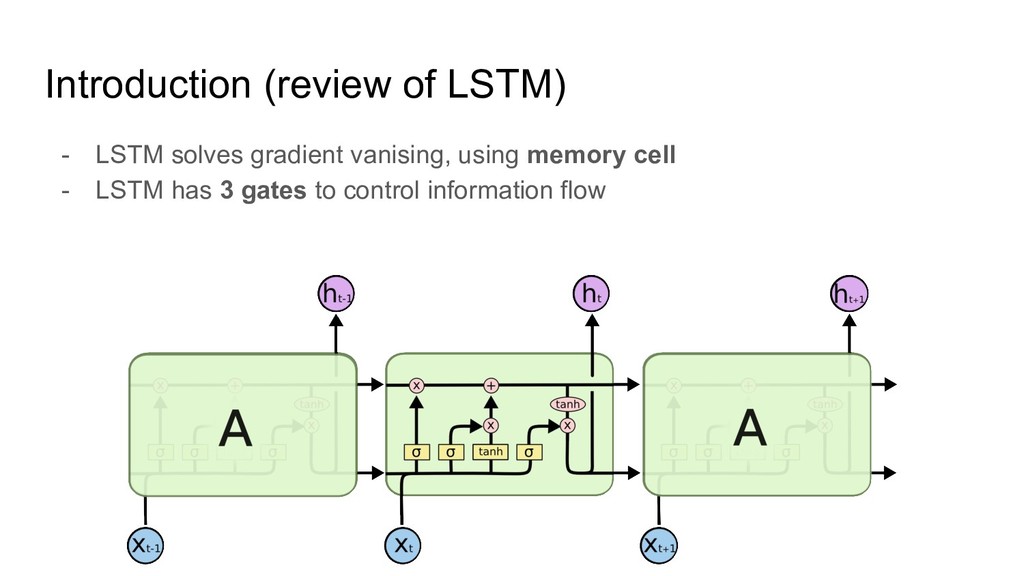
Introduction (review of LSTM) - LSTM solves gradient vanising, using
memory cell - LSTM has 3 gates to control information flow
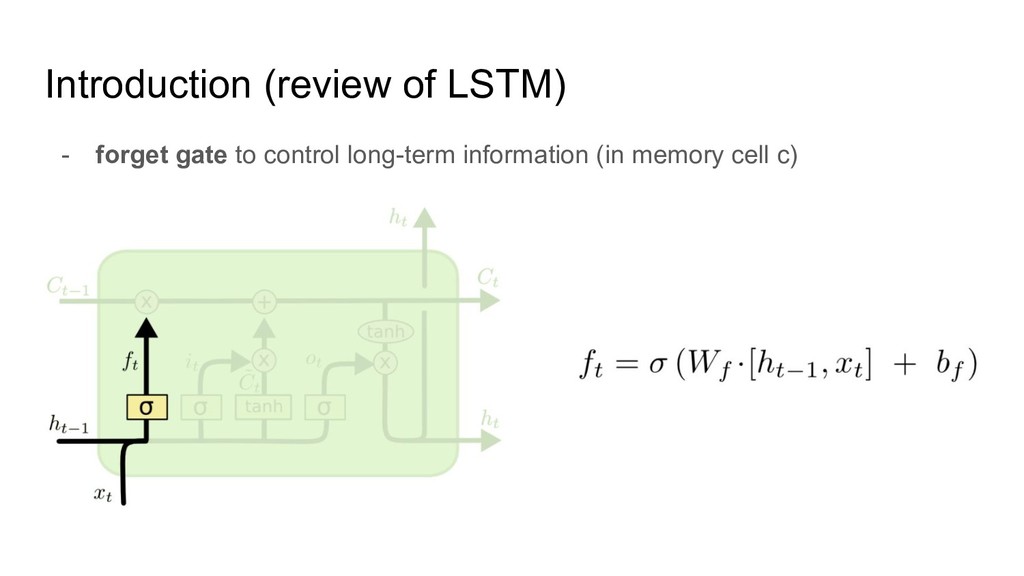
Introduction (review of LSTM) - forget gate to control long-term
information (in memory cell c)
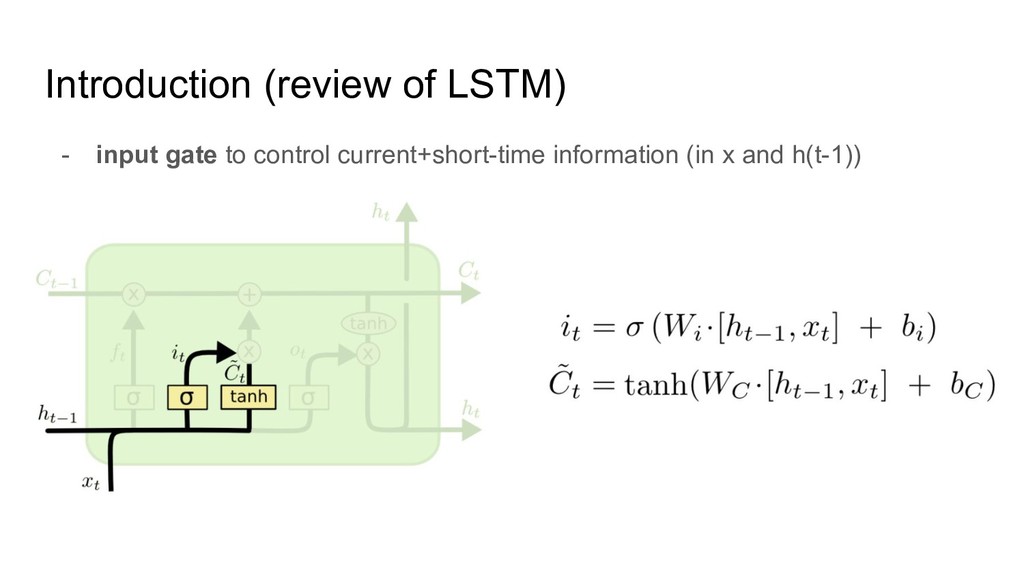
Introduction (review of LSTM) - input gate to control current+short-time
information (in x and h(t-1))
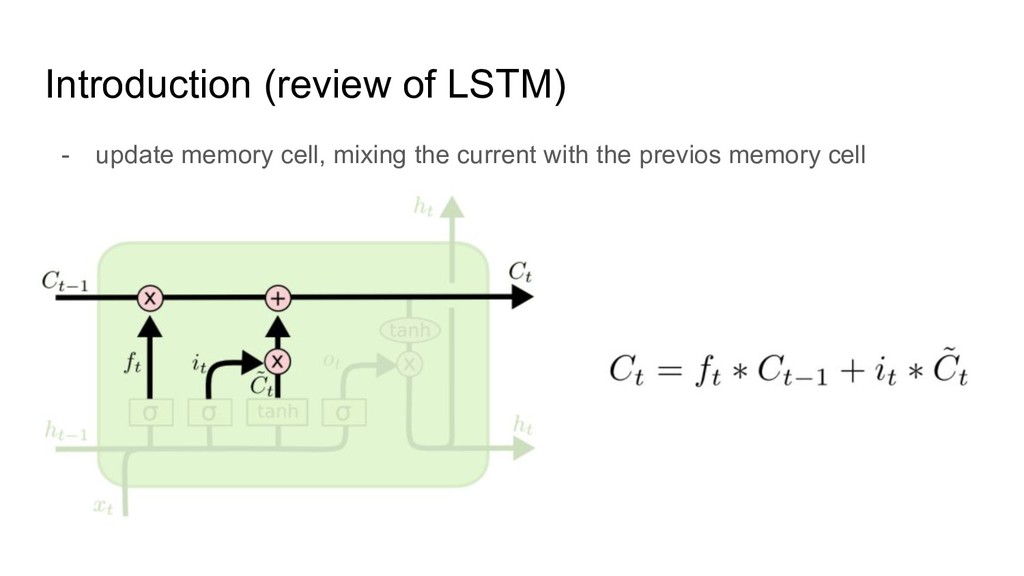
Introduction (review of LSTM) - update memory cell, mixing the
current with the previos memory cell
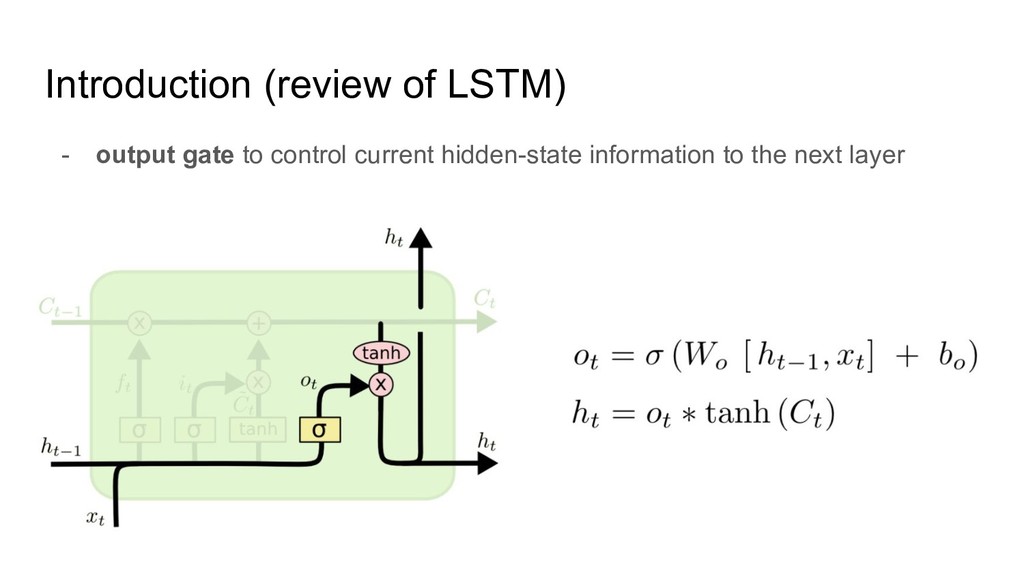
- output gate to control current hidden-state information to the
next layer Introduction (review of LSTM)
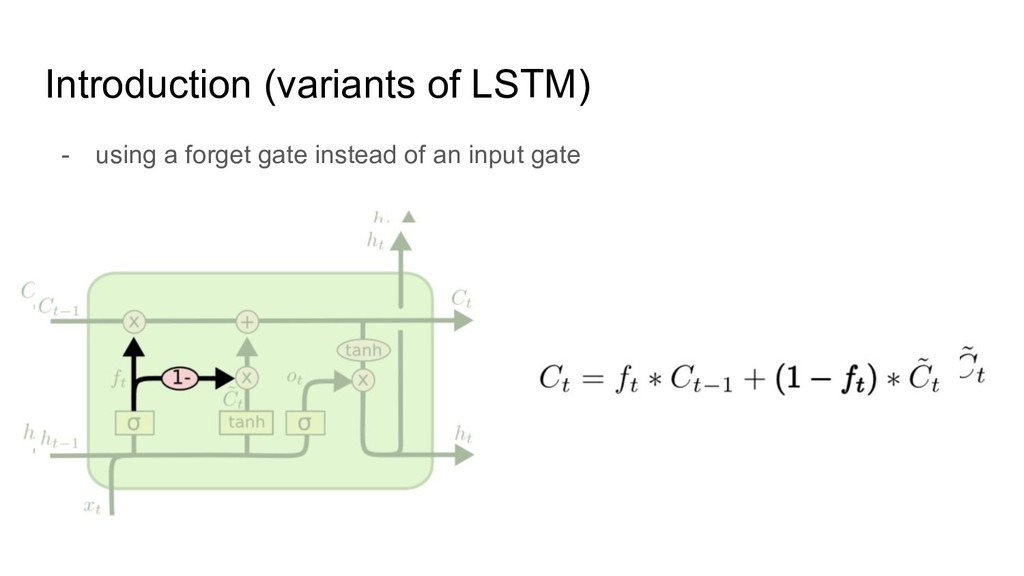
- using a forget gate instead of an input gate
Introduction (variants of LSTM)
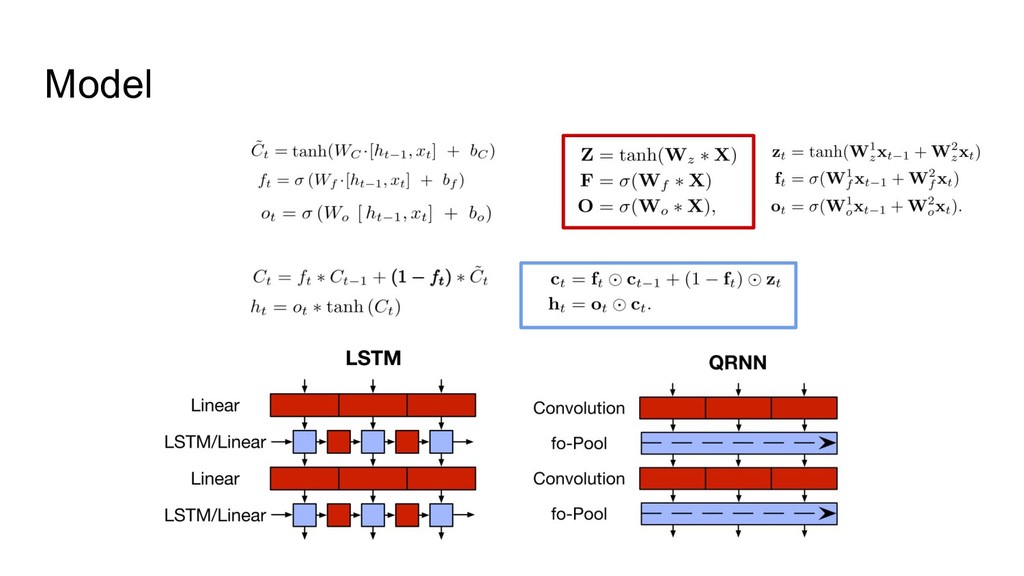
Model
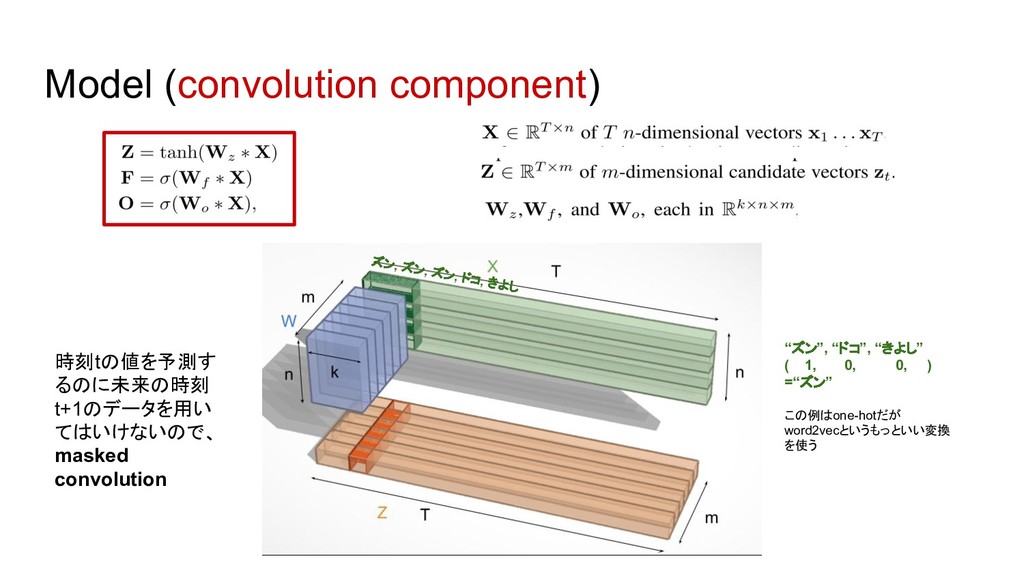
Model (convolution component) “ズン”, “ドコ”, “きよし” ( 1, 0, 0,
) =“ズン” この例はone-hotだが word2vecというもっといい変換 を使う ズン, ズン, ズン, ドコ, きよし 時刻tの値を予測す るのに未来の時刻 t+1のデータを用い てはいけないので、 masked convolution
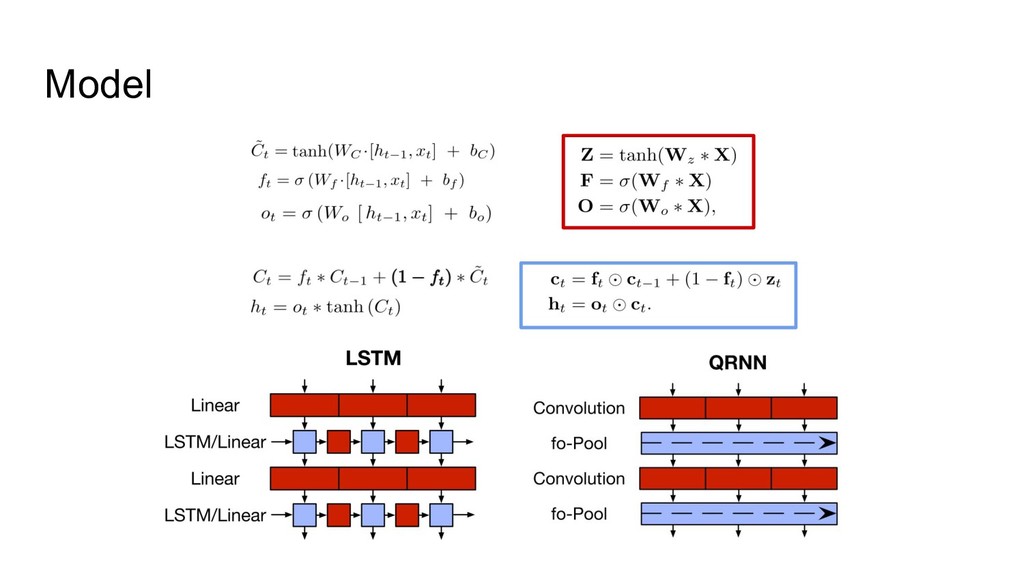
Model
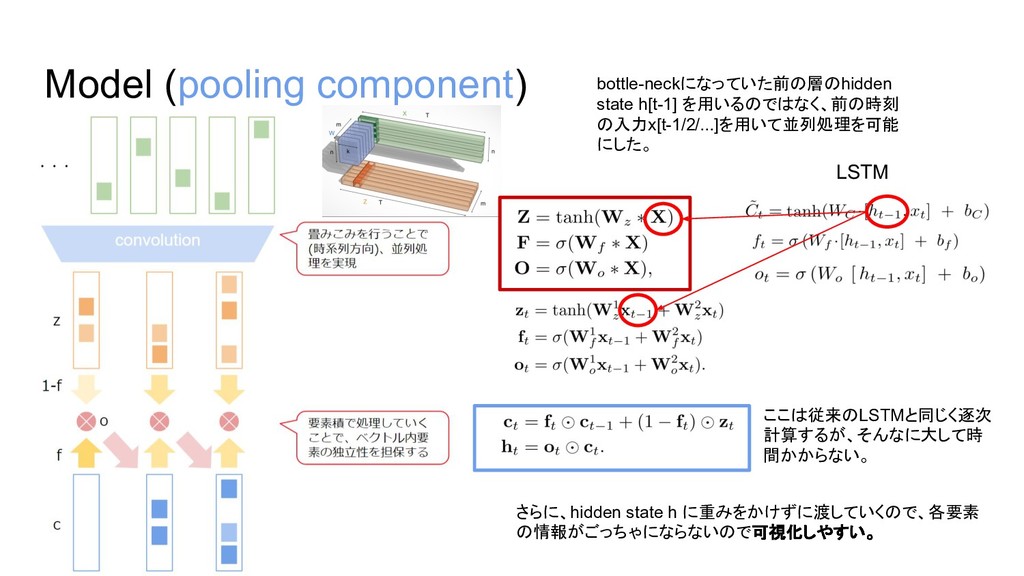
bottle-neckになっていた前の層のhidden state h[t-1] を用いるのではなく、前の時刻 の入力x[t-1/2/...]を用いて並列処理を可能 にした。 Model (pooling component) LSTM
さらに、hidden state h に重みをかけずに渡していくので、各要素 の情報がごっちゃにならないので可視化しやすい。 ここは従来のLSTMと同じく逐次 計算するが、そんなに大して時 間かからない。
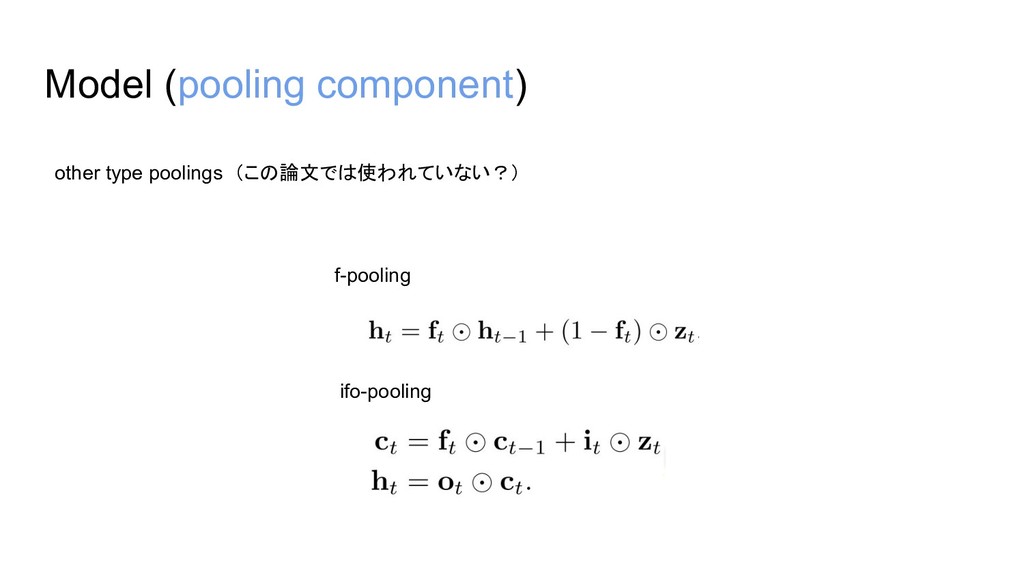
Model (pooling component) other type poolings (この論文では使われていない?) f-pooling ifo-pooling
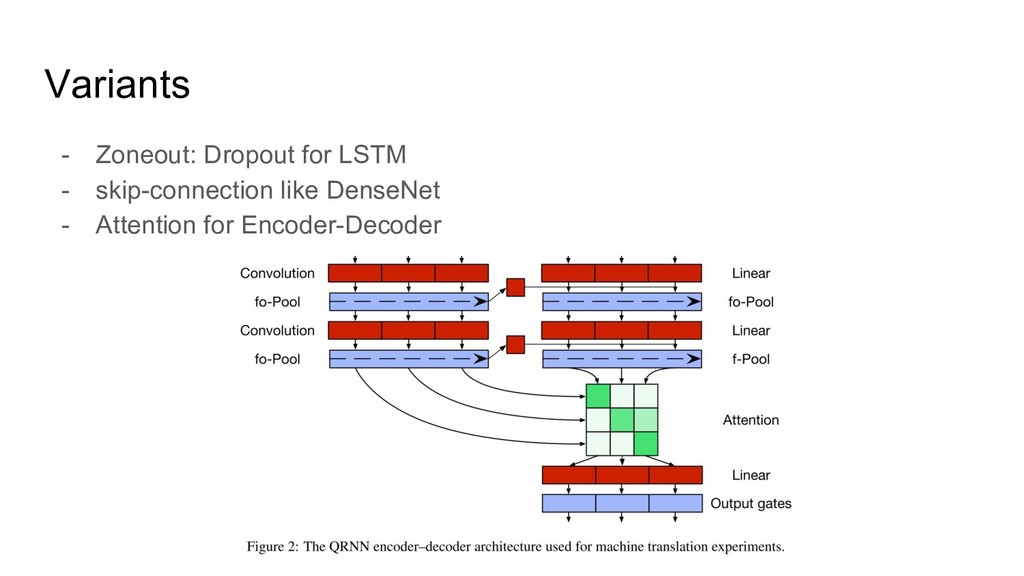
Variants - Zoneout: Dropout for LSTM - skip-connection like DenseNet
- Attention for Encoder-Decoder
Experiments - Sentiment Classification (document binary-classification) - IMDb movie review
- 25,000 positive/negative reviews - Language Modeling (word-level prediction) - PTB: Penn Treebank - Character-level Machine Translatoin - IWST English-German spoken language translation task
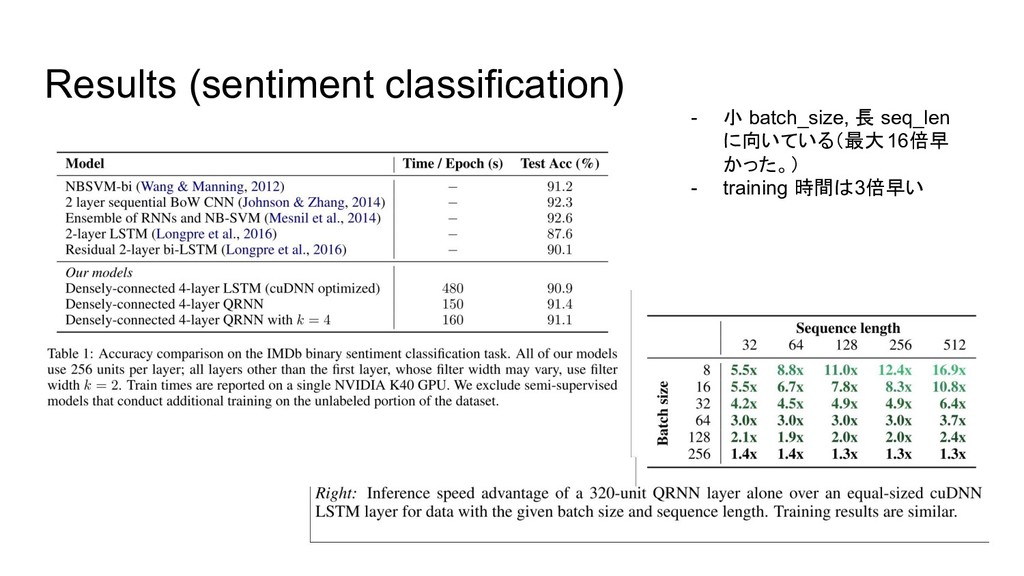
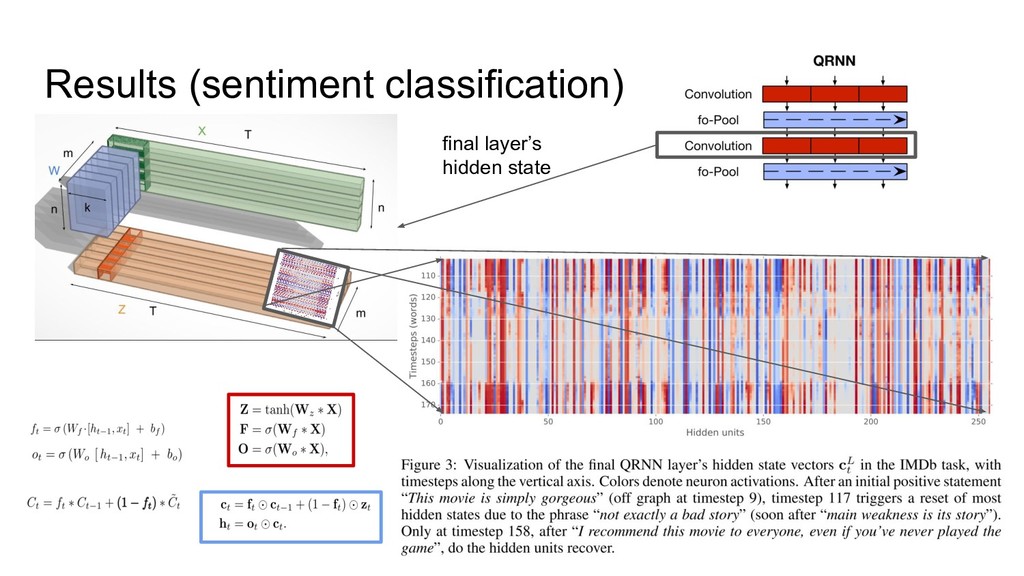
Results (sentiment classification) - 小 batch_size, 長 seq_len に向いている(最大16倍早 かった。)
- training 時間は3倍早い
Results (sentiment classification) final layer’s hidden state
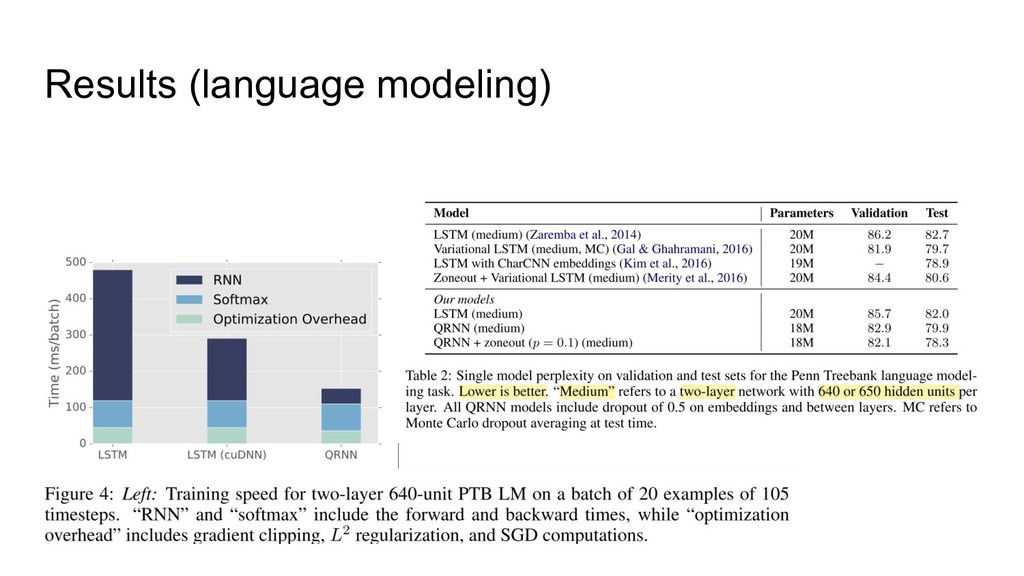
Results (language modeling)
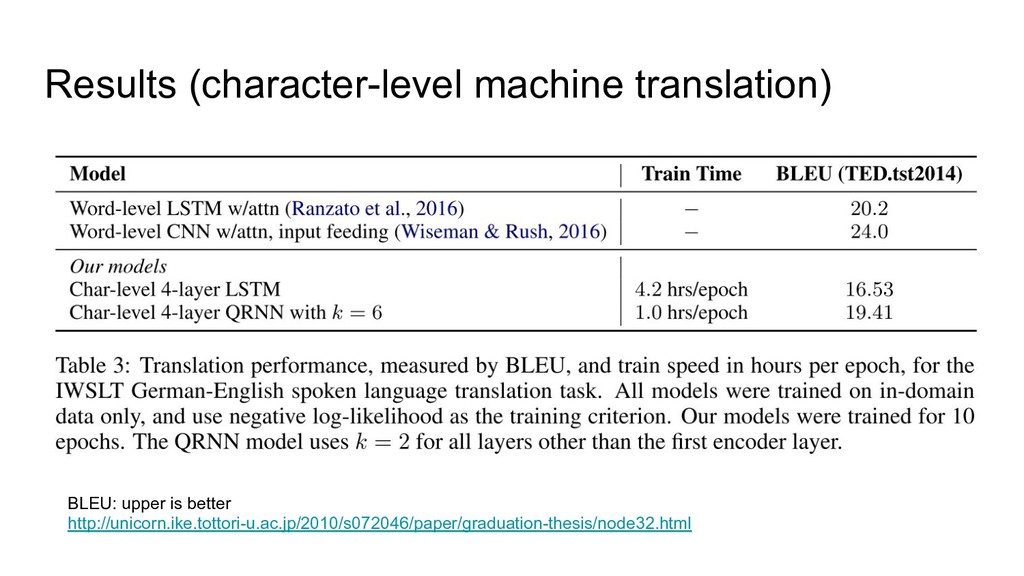
Results (character-level machine translation) BLEU: upper is better http://unicorn.ike.tottori-u.ac.jp/2010/s072046/paper/graduation-thesis/node32.html
考察 - LSTMに精度で少し負けてしまった理由は、隠れ層の状態 h[t-1] ではなく、直前の 入力 x[t-1|t-2|,...]を使って近似したからと考えられる。 - 入力で、隠れ層の状態を近似する場合、使う、前の時刻の filter
size k を無限大ま で長くすれば一致する。(sentiment classificationのtaskではkを大きくしたら精度 上がった) - なので、filter-sizeを大きくすればいいが、そうすると、計算速度はどれほど落ちる のかが問題。
Conclusion - QRNN = RNN processing like CNN - can
process sequential data in parallel - up to 16x faster than LSTM in train/test - can make visual analysis of weights easy
Reference - LSTM - LSTMネットワークの概要 https://qiita.com/KojiOhki/items/89cd7b69a8a6239d67ca - わかるLSTM ~ 最近の動向と共に
https://qiita.com/KojiOhki/items/89cd7b69a8a6239d67ca - ニューラルネットワーク勉強会 http://isw3.naist.jp/~neubig/student/2015/seitaro-s/161025neuralnet_study_LSTM.pdf - conv の 3D図作成 - thinkercad https://www.tinkercad.com/ - QRNN - LSTMを超える期待の新星、QRNN https://qiita.com/icoxfog417/items/d77912e10a7c60ae680e - slideshare https://www.slideshare.net/DeepLearningJP2016/dlquasirecurrent-neural-networks?qid=a4ead77d-d8dd-458b-965c-5e53723d7757 &v=&b=&from_search=1 - pytorchでの公式実装 https://github.com/salesforce/pytorch-qrnn/blob/master/torchqrnn/qrnn.py

 Your Podcast. Everywhere. Effortlessly.


 hrsma2i
 rikkabotan7
 hotchpotch
 kogoro
 pman0214
 yukako_nakano
 microbaseinc
 corochann
 analokmaus
 mickey_0226
 enochan
 satai
 jlugia
 reverentgeek
 samanthasiow
 popppiees
 sergeychernyshev
 mayatellez
 palkan
 smashingmag
 jmmastey
 keathley
 marketingsoph
 marcoroth