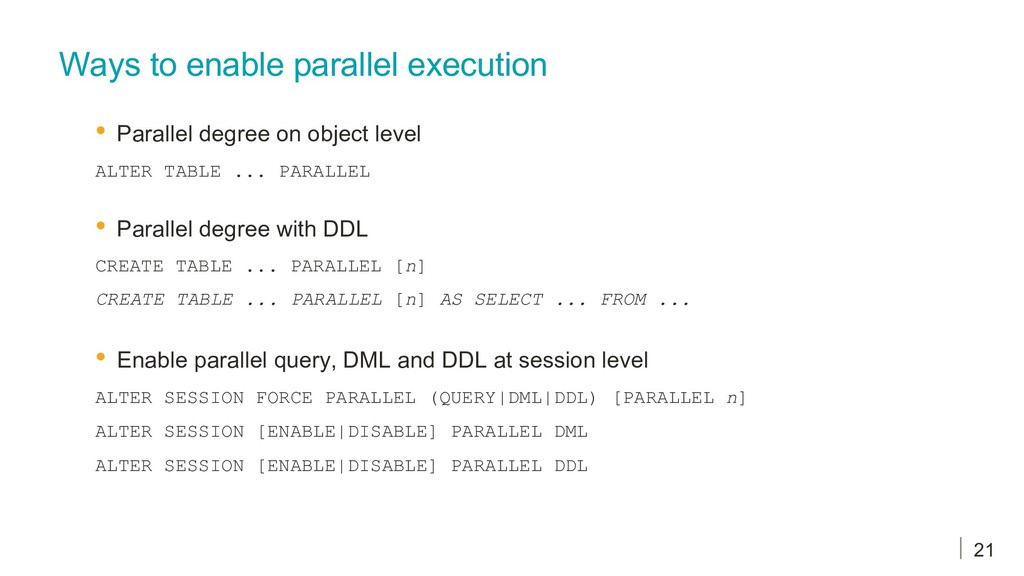
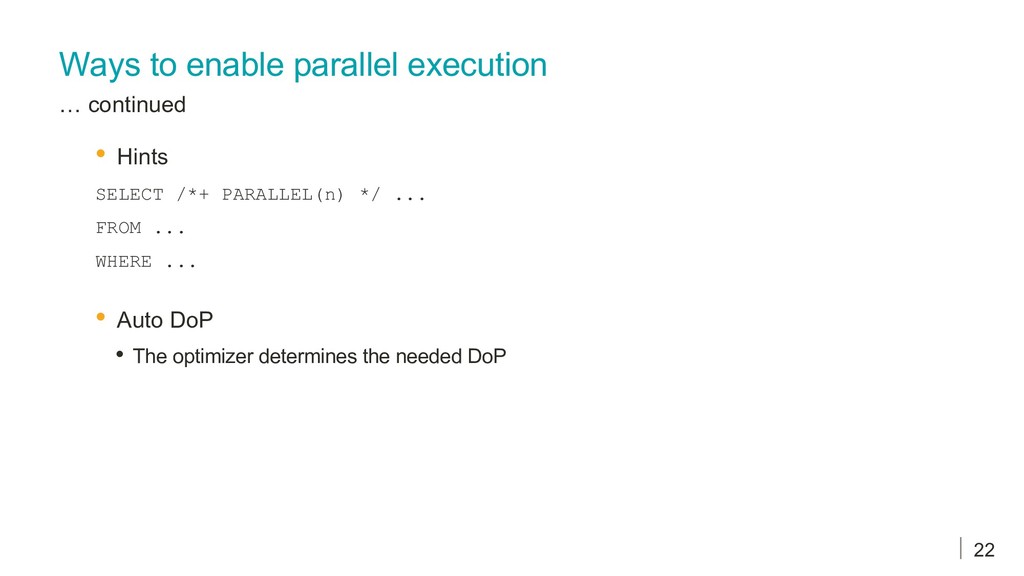
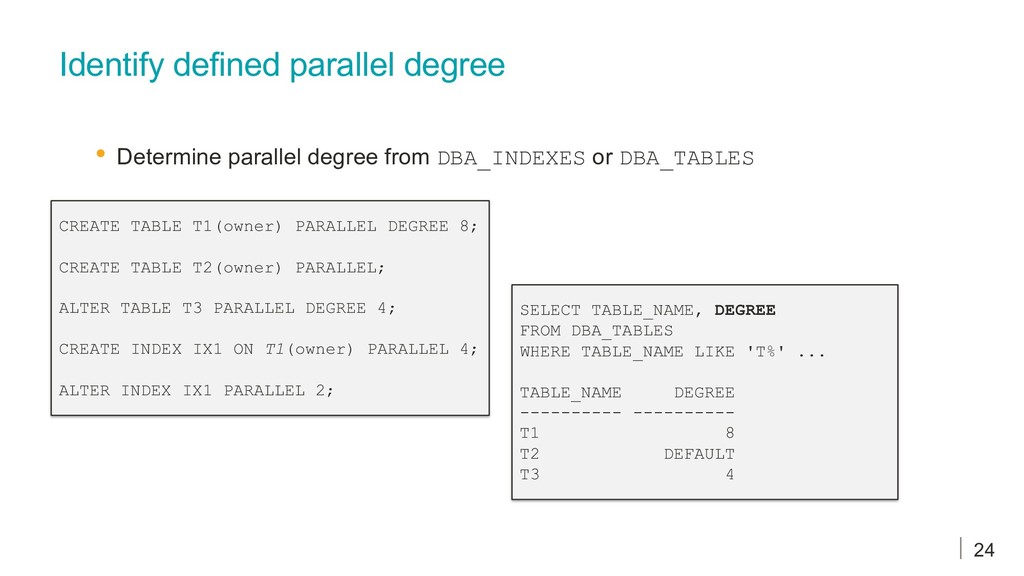
conquer” algorithms are adapted for multi-processor architectures • Problem is break down into more than one sub-problem of same or related type • The solutions of each sub-problem are combined to give a solution to the original problem • Oracle’s technique: divide the data in granules and do the processing 7
full scans, partitioned index range scans and tables • Nested loops, hash joins, sort merge, star transformation • Queries and subqueries • DDL and DML statements INSERT, UPDATE, DELETE, CTAS, CREATE/REBUILD INDEX, MOVE/SPLIT/COALESCE PARTITION 9
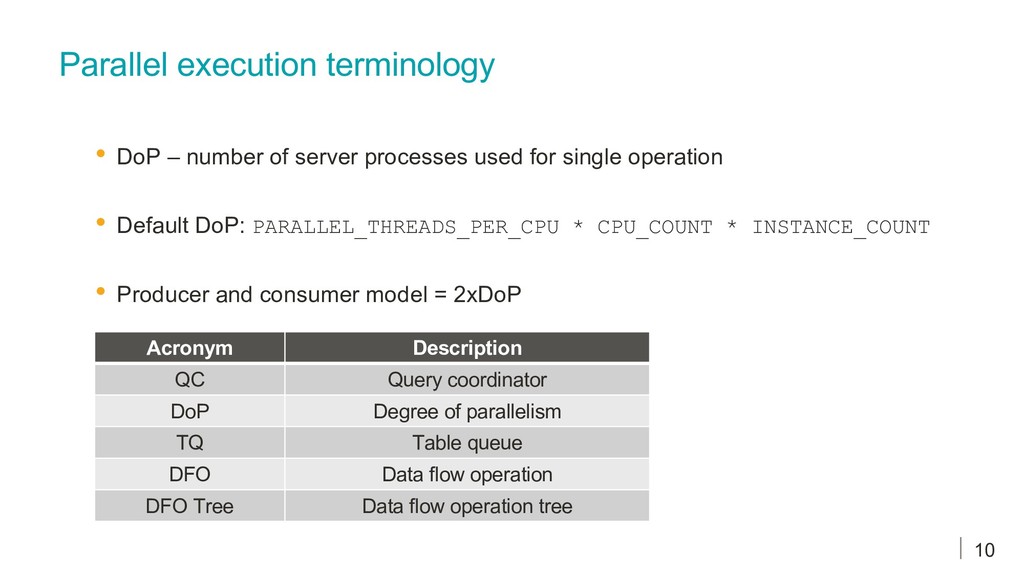
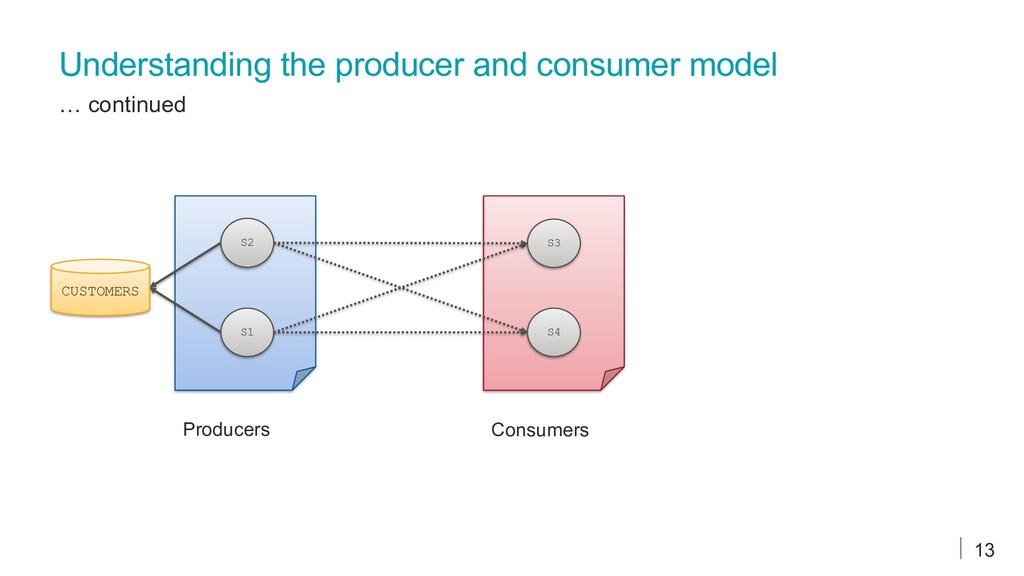
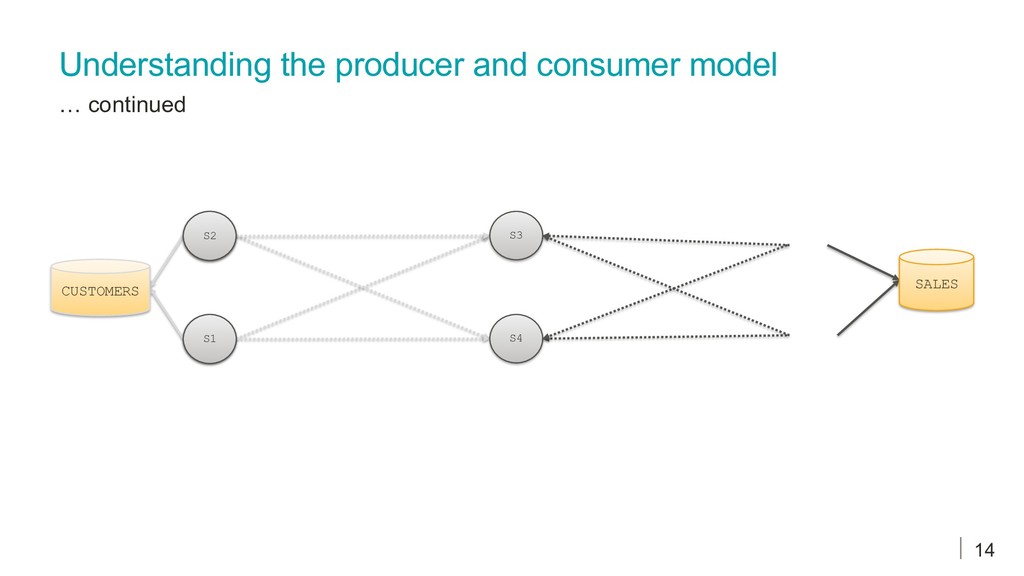
used for single operation • Default DoP: PARALLEL_THREADS_PER_CPU * CPU_COUNT * INSTANCE_COUNT • Producer and consumer model = 2xDoP Acronym Description QC Query coordinator DoP Degree of parallelism TQ Table queue DFO Data flow operation DFO Tree Data flow operation tree 10
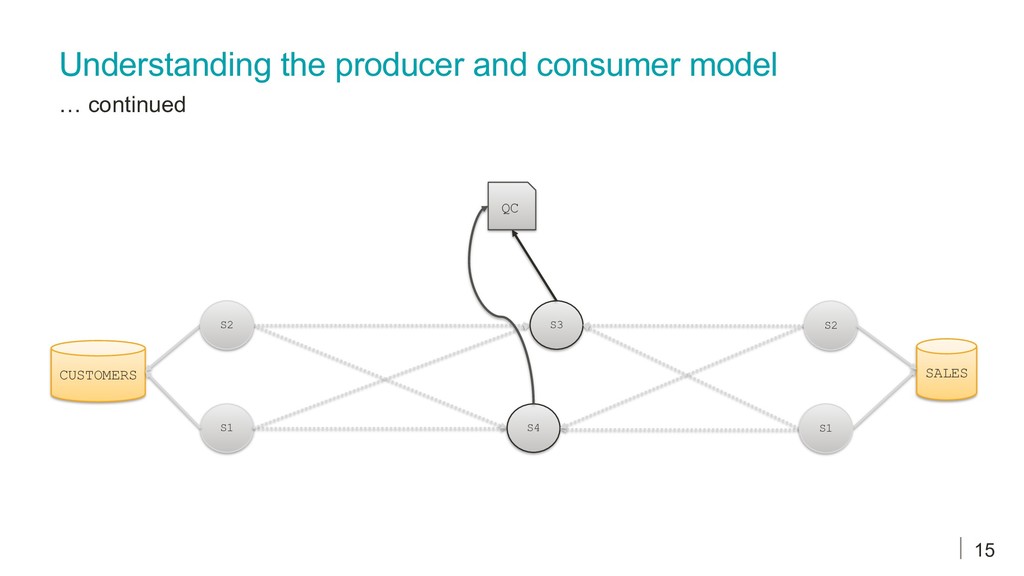
(foreground) process becomes the query coordinator • The DoP is determined before actual query execution • QC assigns each of the PX slaves with work • Starting 12c, one of the available PX servers will execute serial steps from the execution plan • Responsible to deliver the result to the client process 11
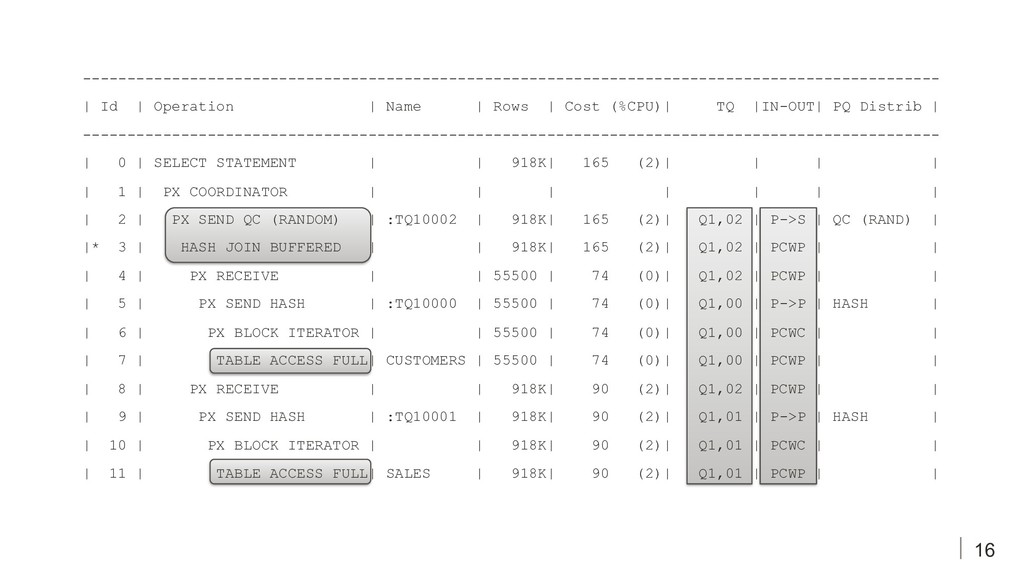
from previous example ? • DoP represents the number of processes (PX slaves) associated with a single operation (i.e. table scan, hash join etc.) • Due to the producer and consumer model, 2xDoP might be allocated. The DoP is allocated per set of slaves (max. of two sets) • The rule of 2xDoP is not always enforced. Example: single table scan needs only one set of PX processes 17
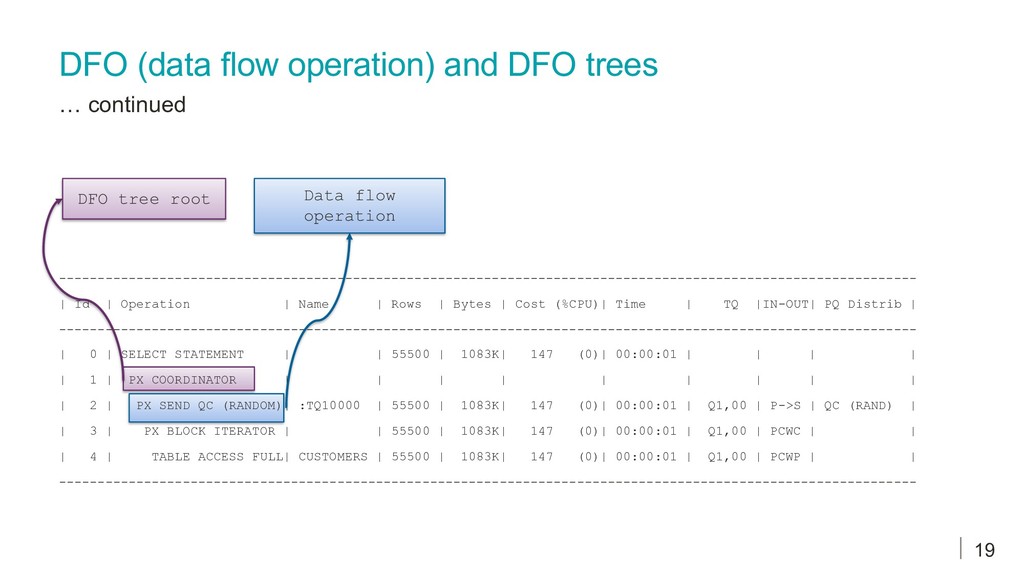
operation - basic unit of work carried by PX servers • Identified by PX SEND operation in the execution plan • Multiple DFO’s can appear • One DFO = 1 PX server set is being used • Multiple DFO’s = most of 2 PX server sets are being used • DFO’s are grouped under one DFO tree (PX coordinator) 18
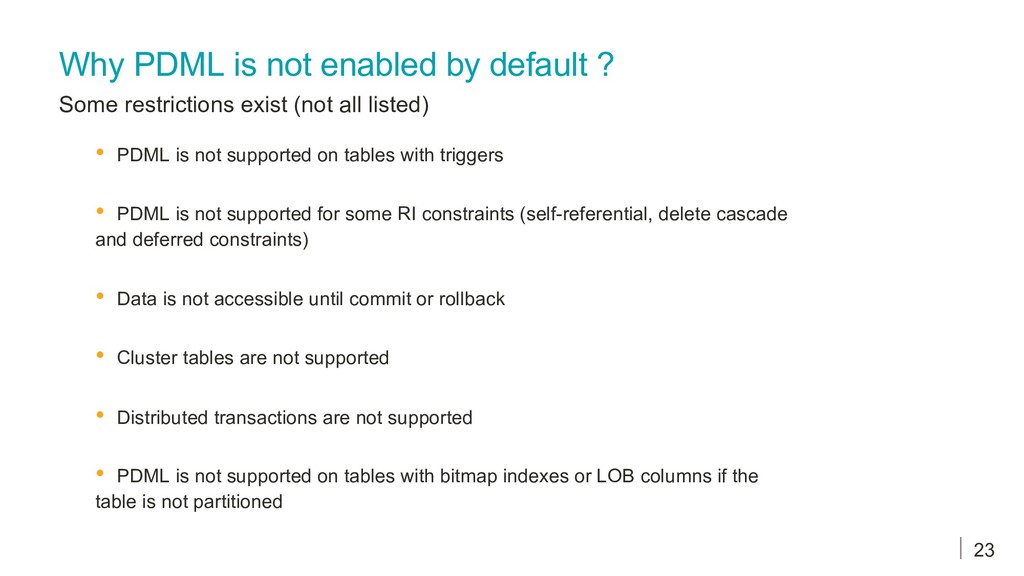
exist (not all listed) • PDML is not supported on tables with triggers • PDML is not supported for some RI constraints (self-referential, delete cascade and deferred constraints) • Data is not accessible until commit or rollback • Cluster tables are not supported • Distributed transactions are not supported • PDML is not supported on tables with bitmap indexes or LOB columns if the table is not partitioned 23
level degree has precedence over object level degree • Statement level is controlled with query hints • Object level parallel degree definition does not support hints 25
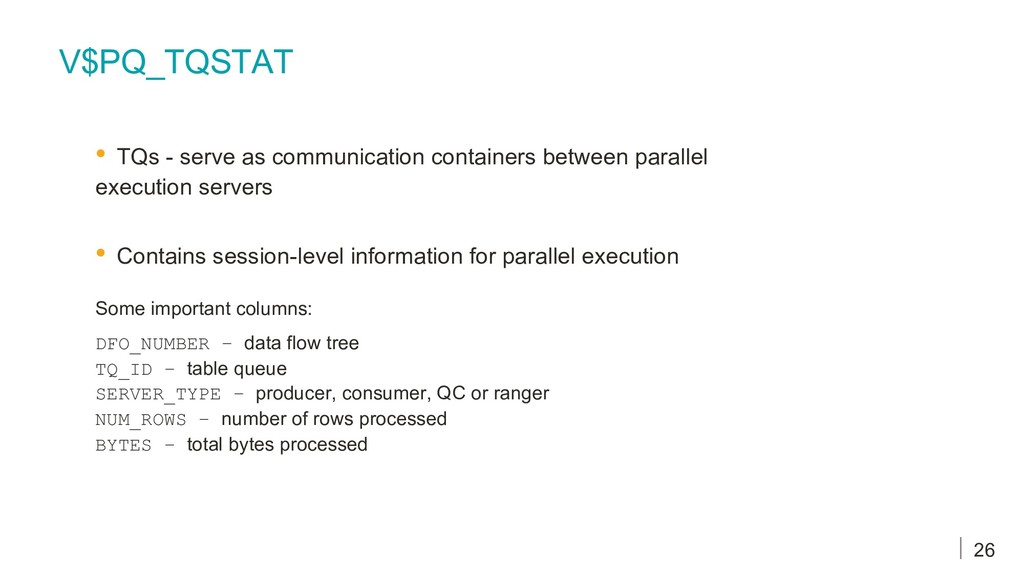
execution servers • Contains session-level information for parallel execution Some important columns: DFO_NUMBER – data flow tree TQ_ID – table queue SERVER_TYPE – producer, consumer, QC or ranger NUM_ROWS – number of rows processed BYTES – total bytes processed 26
Your own session’s DoP can be determined by looking at V$PQ_TQSTAT and V$PQ_SESSTAT. But, those views are not relevant for other sessions. • Views: V$PX_SESSION, V$PX_PROCESS, V$TRANSACTION • SQL Monitor • Look at PX_FLAGS column in [G]V$ACTIVE_SESSION_HISTORY Get query’s actual DoP with TRUNC(PX_FLAGS/2097152) 28
• Sessions are easily identified with SADDR, SID and SERIAL# columns • DoP downgrades can be identified by looking at DEGREE and REQ_DEGREE columns • In RAC you can identify from which instance the QC is running • Identify how many PX servers run concurrently in case of multiple parallelizers 29
AVAILABLE or IN USE, the STATUS column • Operating system process ID can be identified from SPID column • Starting 12c, an indicator IS_GV has been added to easily identify if the PX process is a normal one or a GV$ process • Selects on GV$ views use PX processes named PZ9n across nodes 30
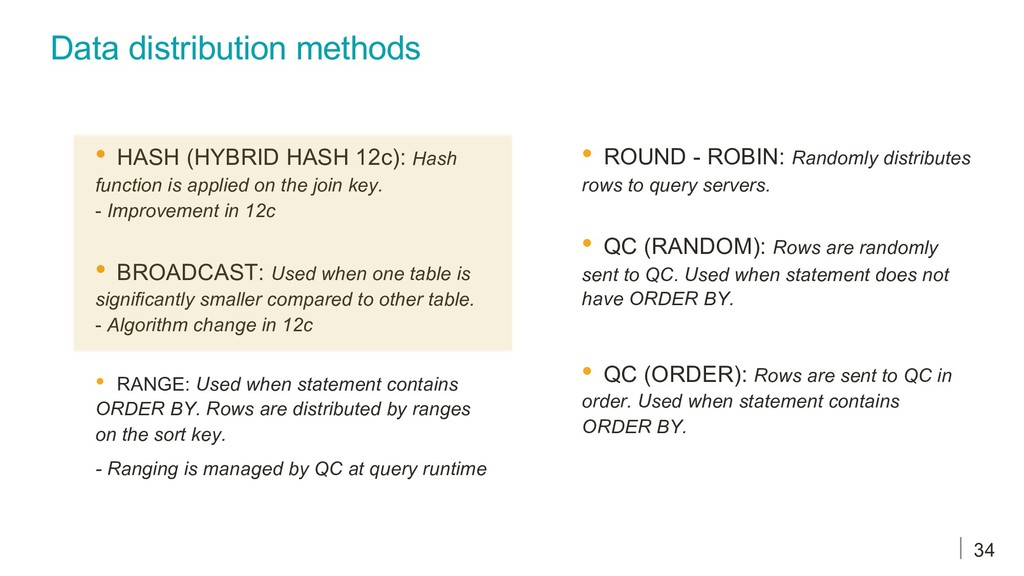
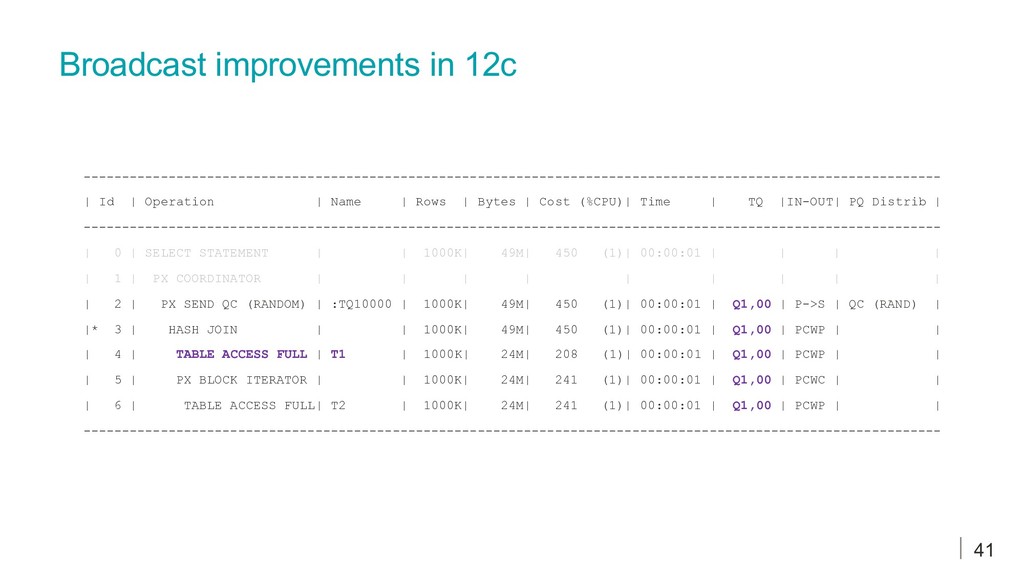
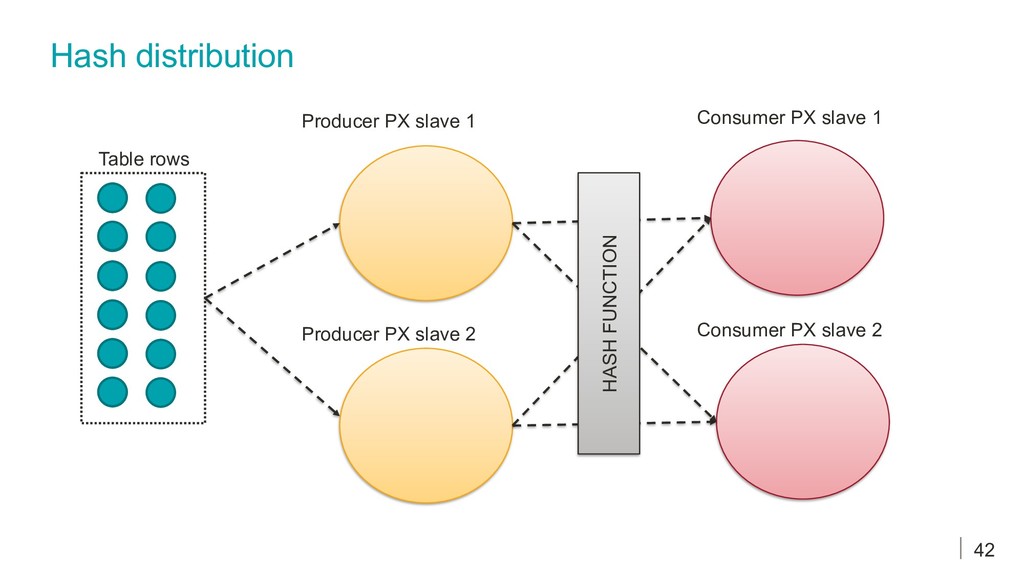
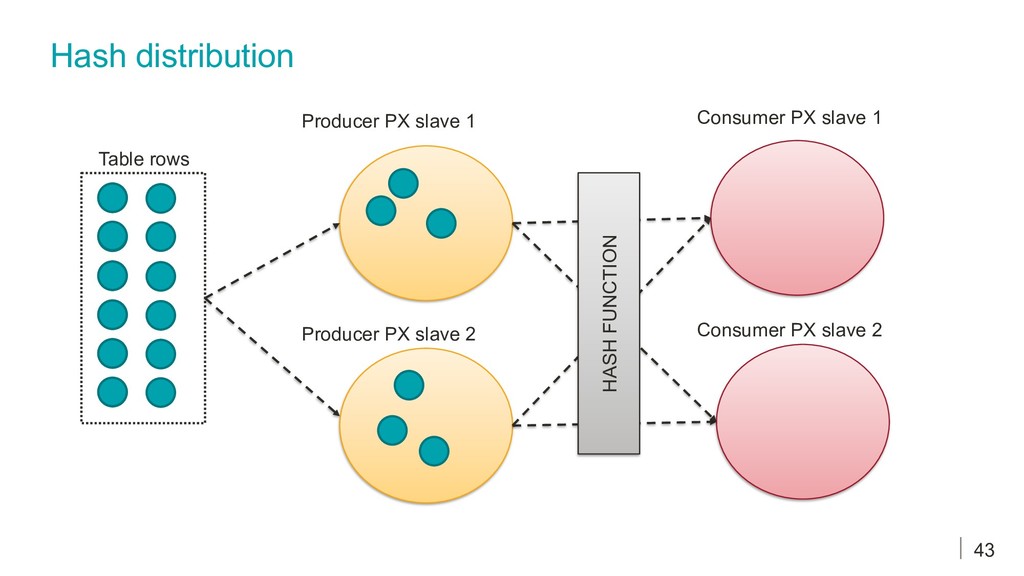
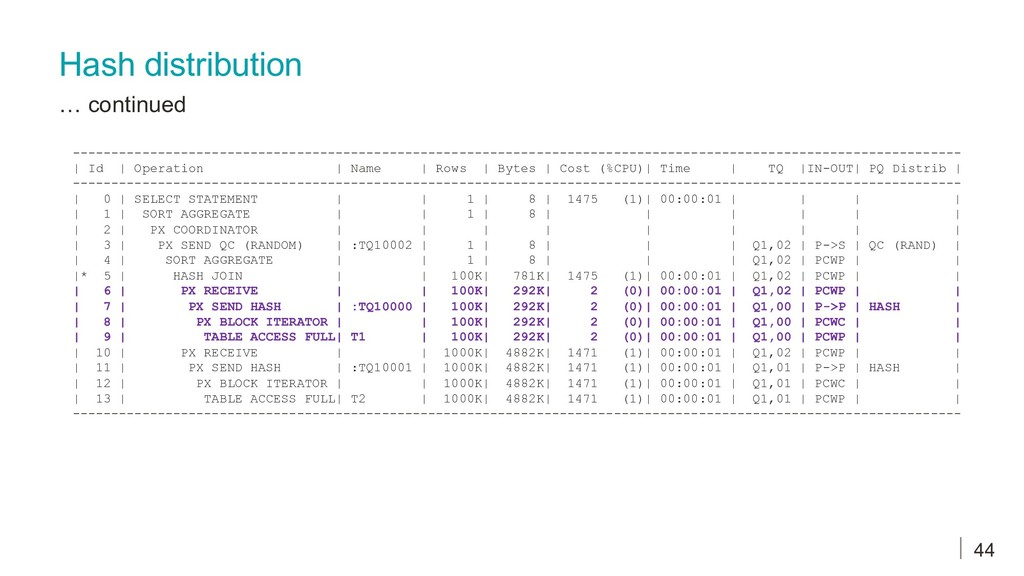
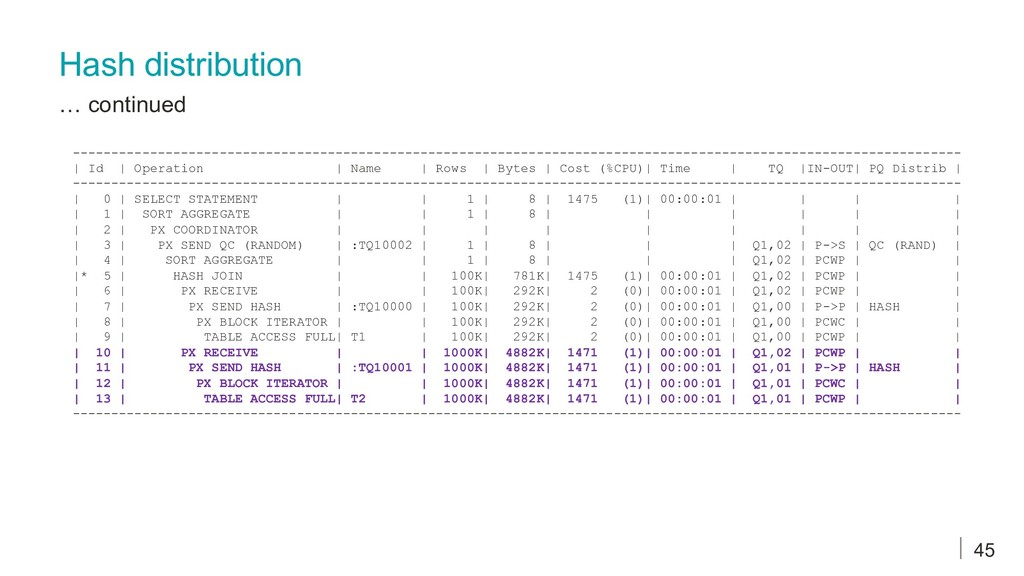
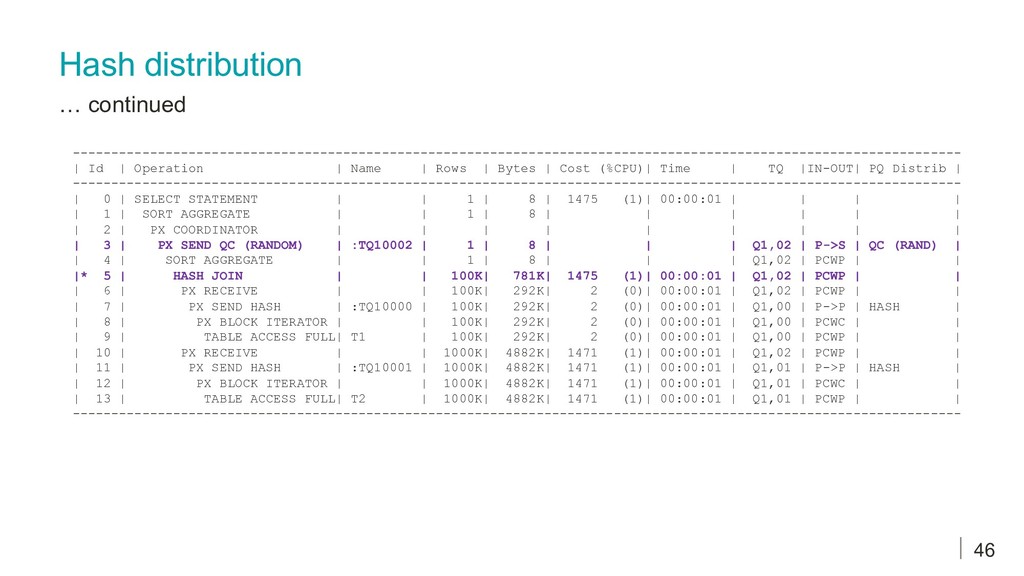
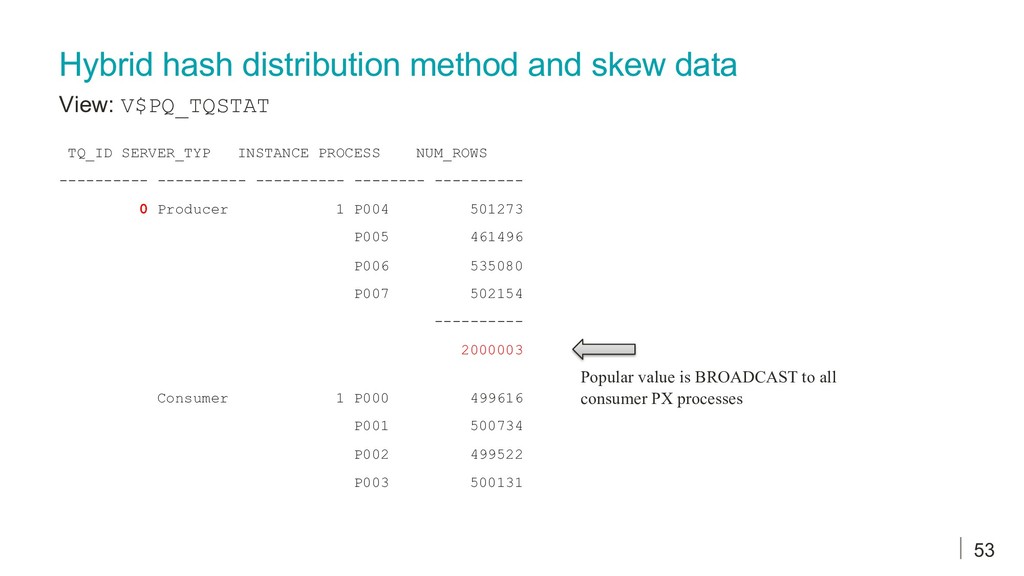
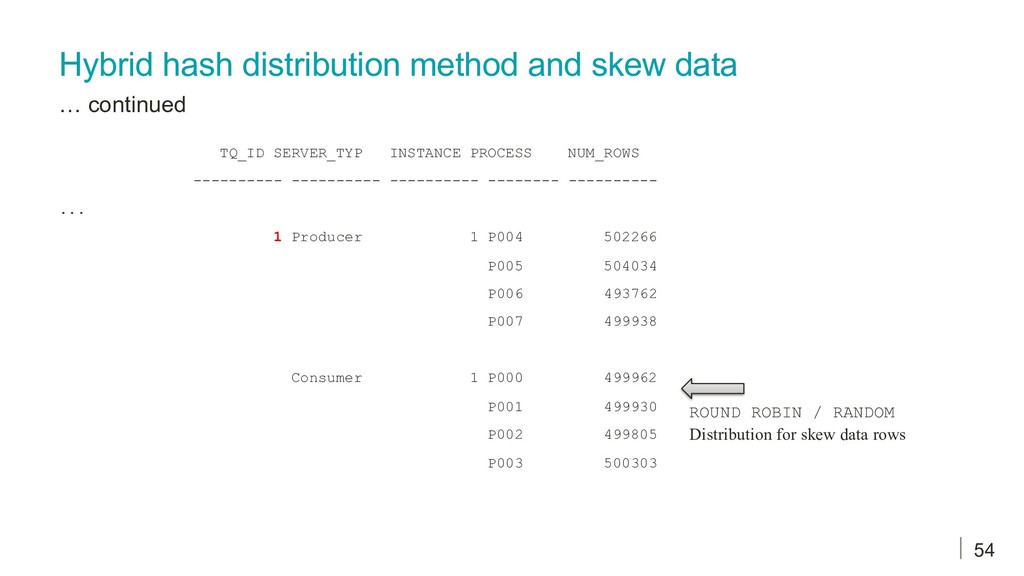
the join key. - Improvement in 12c • BROADCAST: Used when one table is significantly smaller compared to other table. - Algorithm change in 12c • RANGE: Used when statement contains ORDER BY. Rows are distributed by ranges on the sort key. - Ranging is managed by QC at query runtime • ROUND - ROBIN: Randomly distributes rows to query servers. • QC (RANDOM): Rows are randomly sent to QC. Used when statement does not have ORDER BY. • QC (ORDER): Rows are sent to QC in order. Used when statement contains ORDER BY. Data distribution methods 34
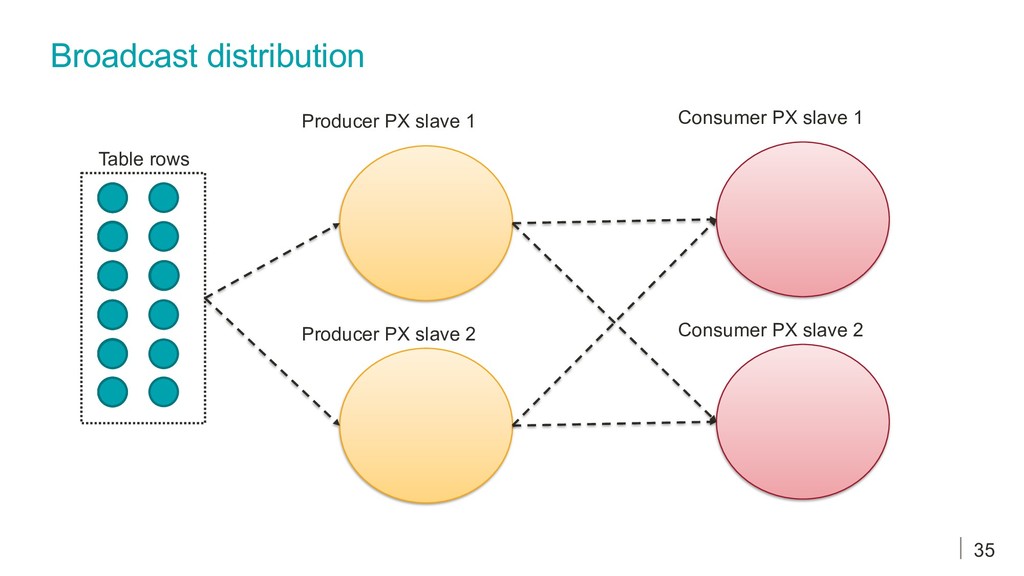
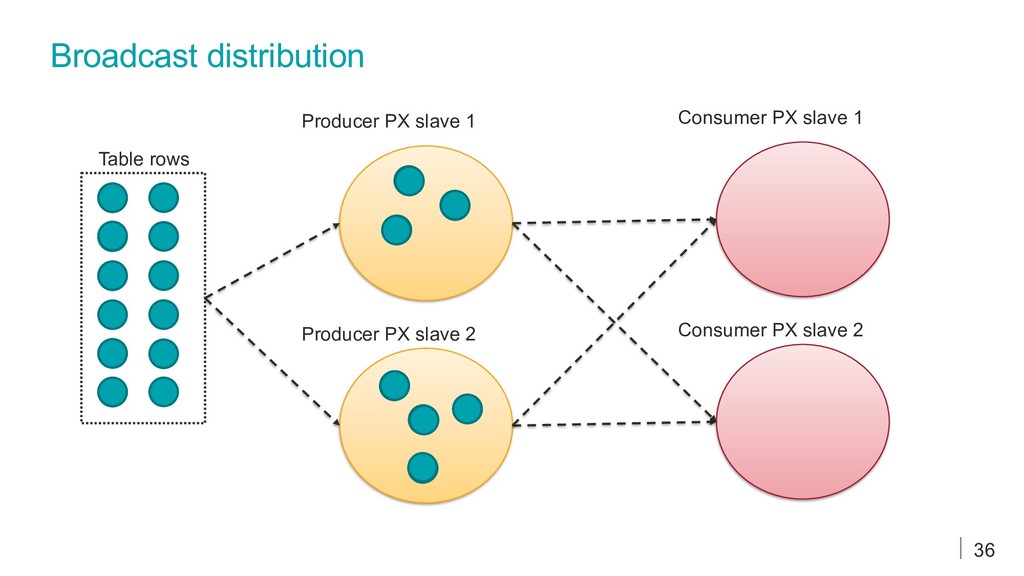
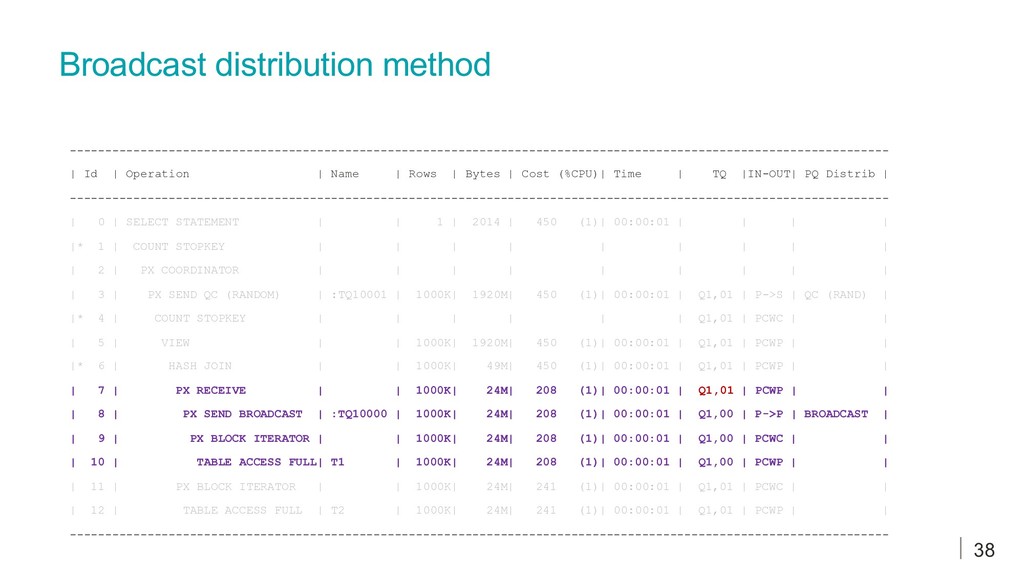
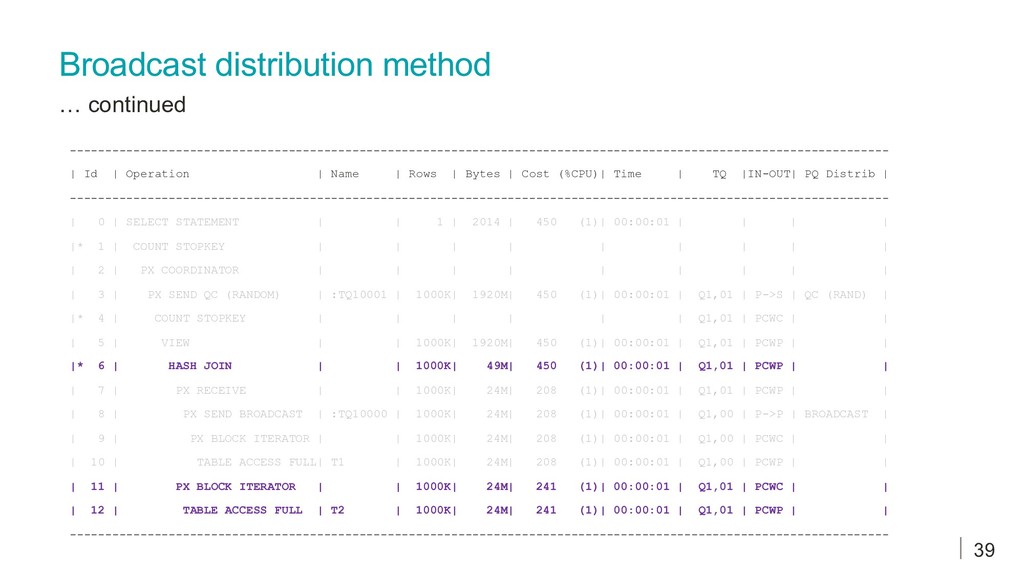
result sets is much smaller than the other • Data is duplicated to all PX consumer servers • Larger results set doesn’t have to be re-distributed • Statistics are very important to CBO to pick effective distribution 37
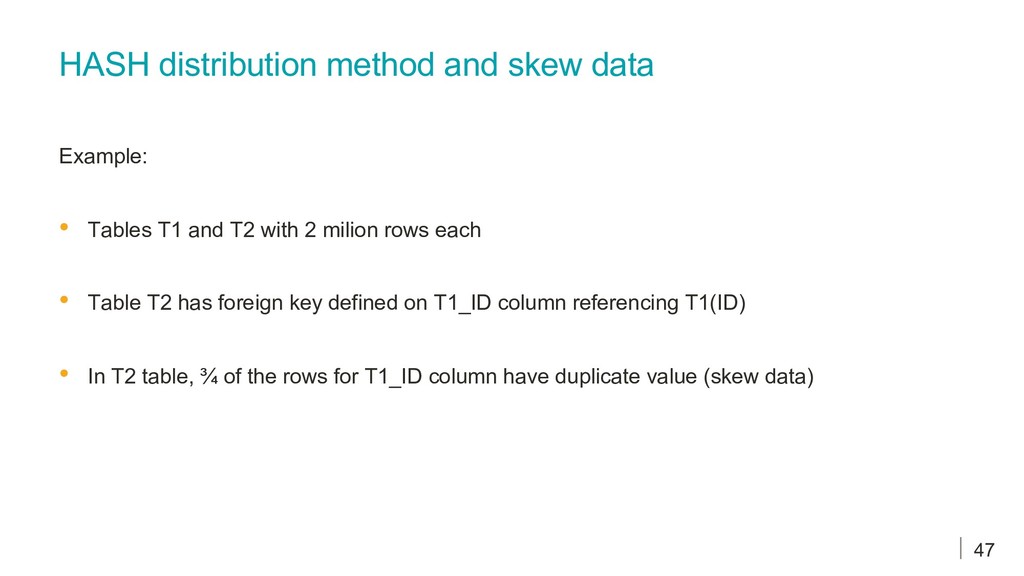
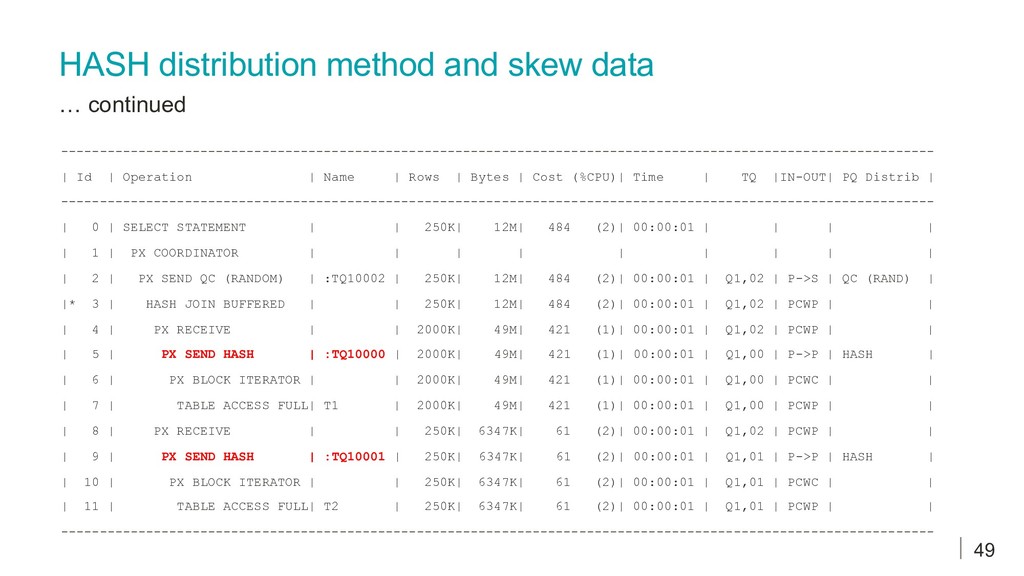
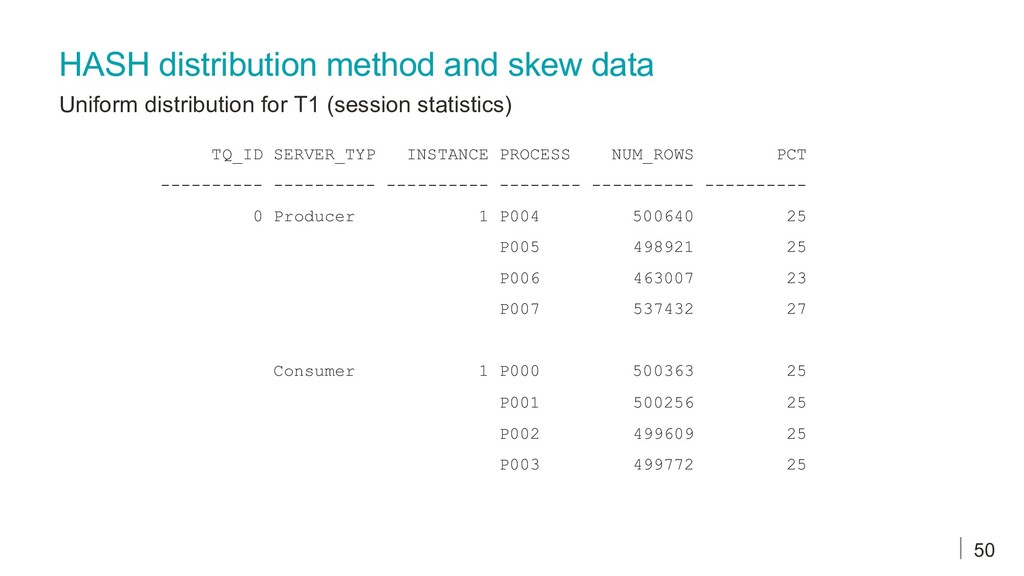
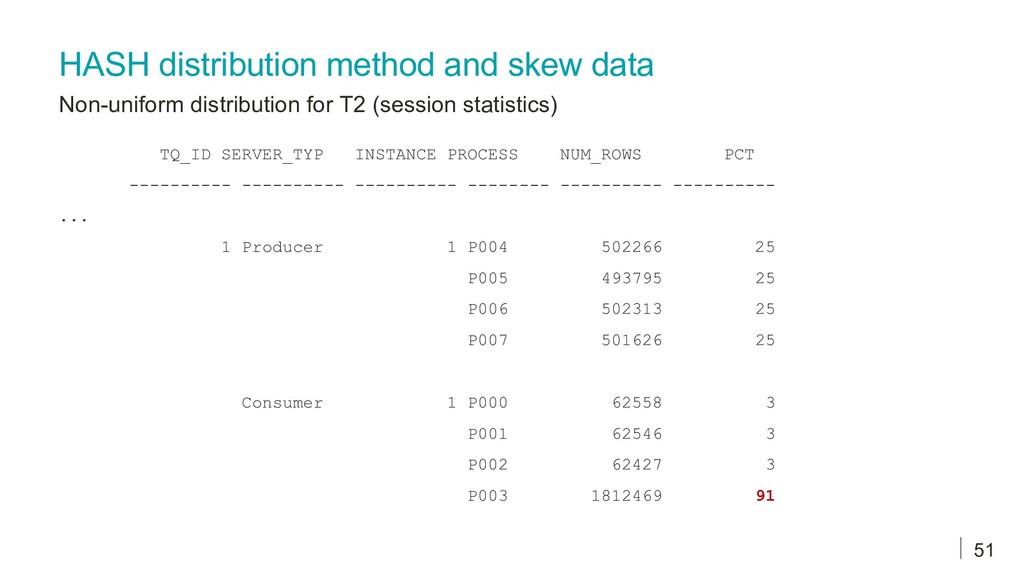
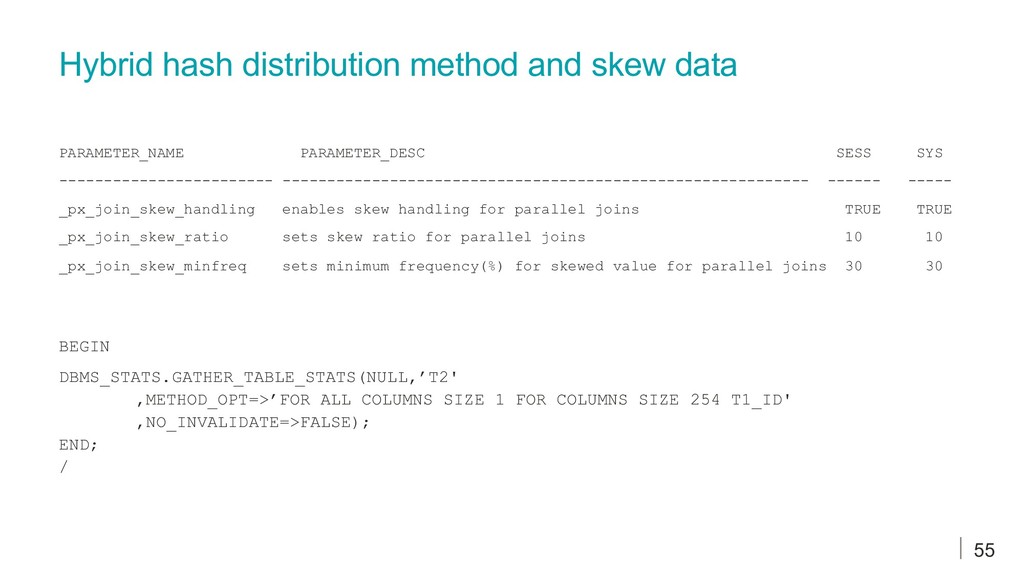
and T2 with 2 milion rows each • Table T2 has foreign key defined on T1_ID column referencing T1(ID) • In T2 table, ¾ of the rows for T1_ID column have duplicate value (skew data) 47
at runtime • The source is broadcast if: 12.1 inflection point: rows < DoP*2 12.2/18c inflection point: changed, but not documented • Identified by PX SEND HYBRID HASH and STATISTICS COLLECTOR operations in the execution plan 52
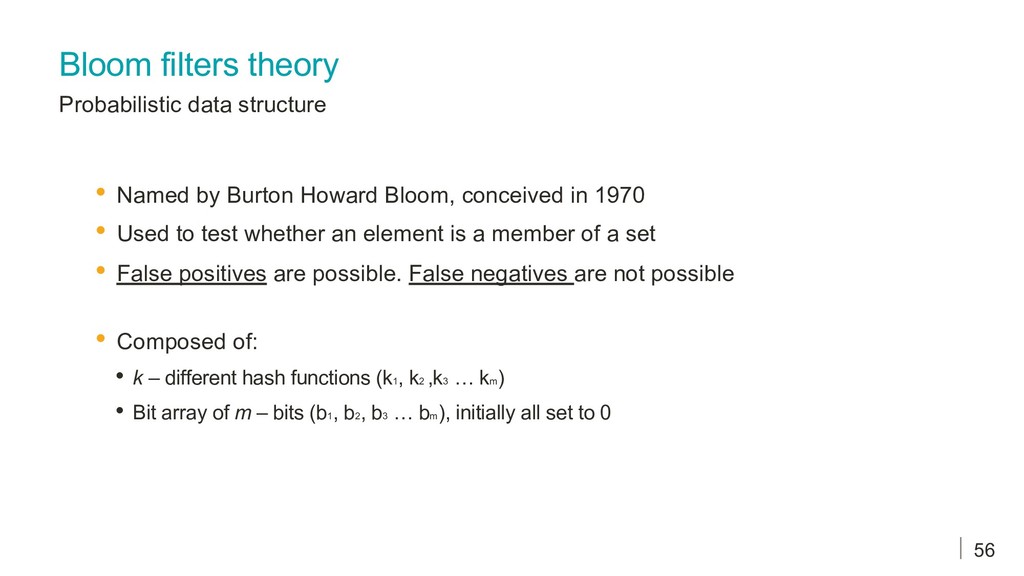
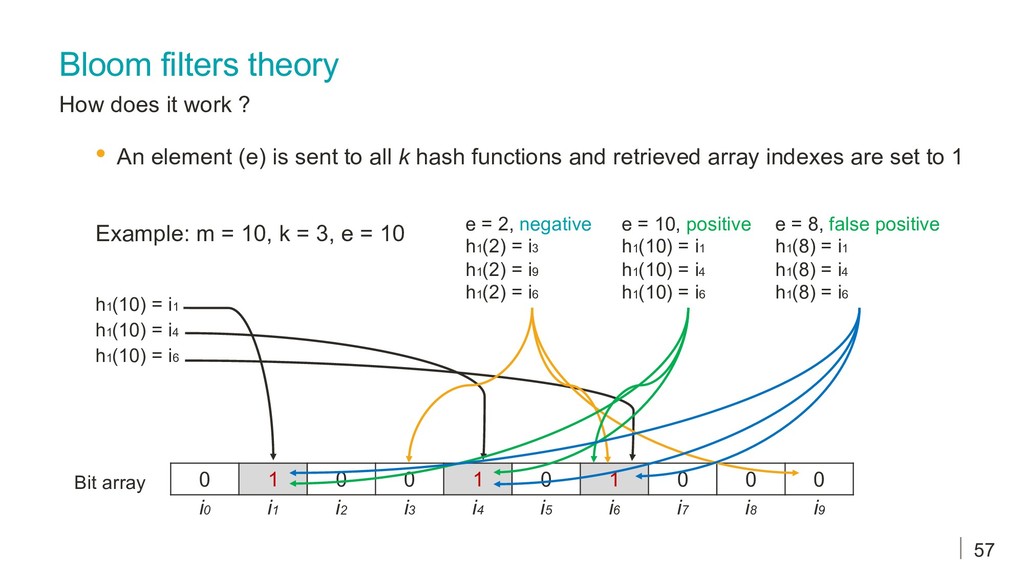
Howard Bloom, conceived in 1970 • Used to test whether an element is a member of a set • False positives are possible. False negatives are not possible • Composed of: • k – different hash functions (k1 , k2 ,k3 … km ) • Bit array of m – bits (b1 , b2 , b3 … bm ), initially all set to 0 56
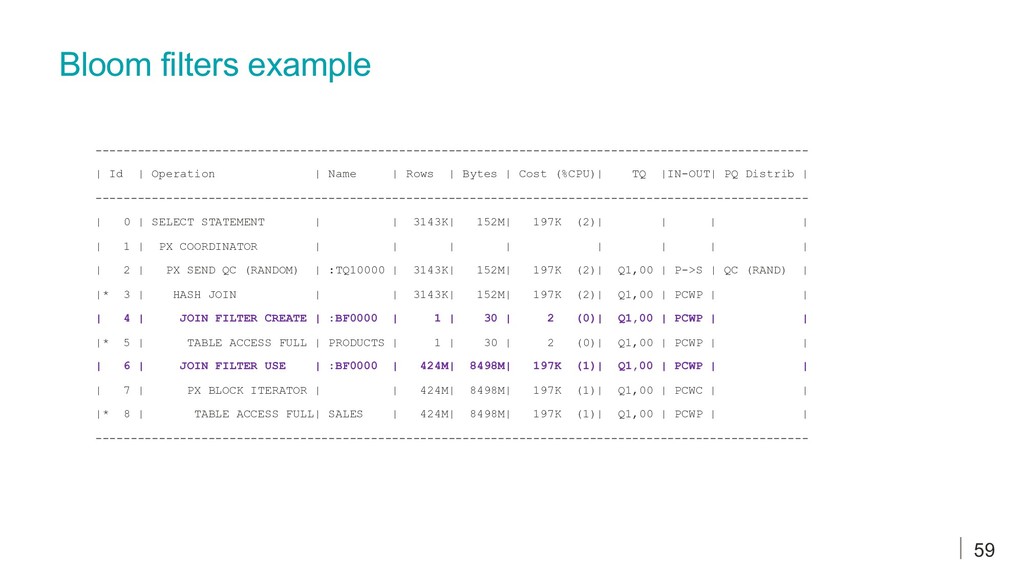
between PX sets • The CBO decides whether it should use bloom filters • You can “control” bloom filter usage with a query hint: - PX_JOIN_FILTER - NO_PX_JOIN_FILTER • System or session wide control with "_bloom_filter_enabled” • Exadata smart-scan also benefits from bloom filters 58
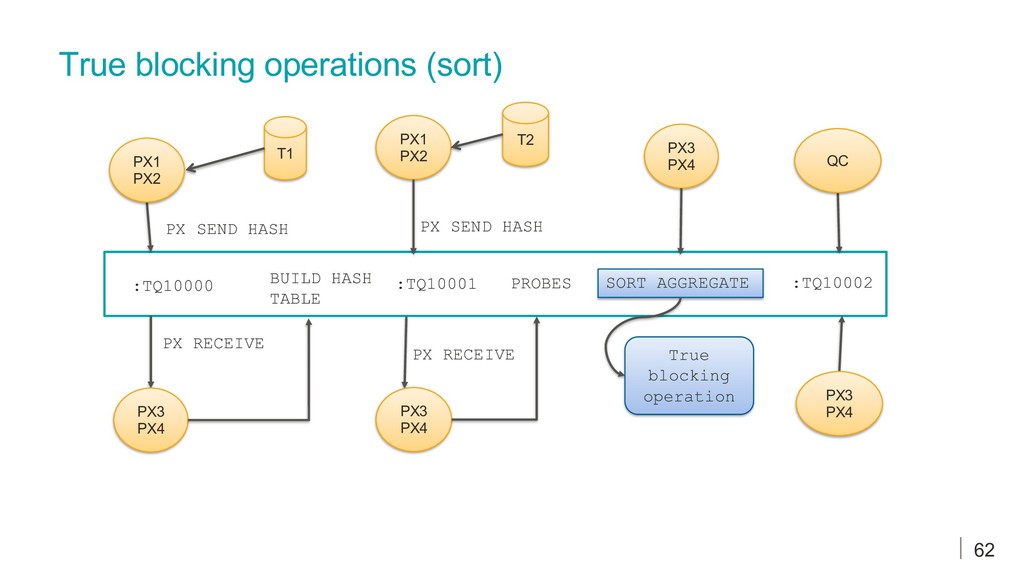
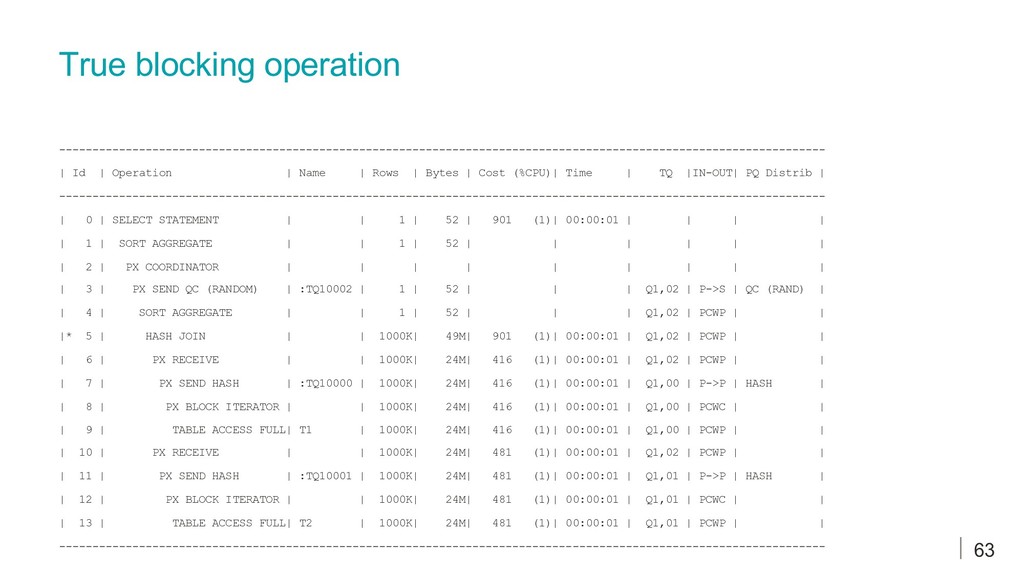
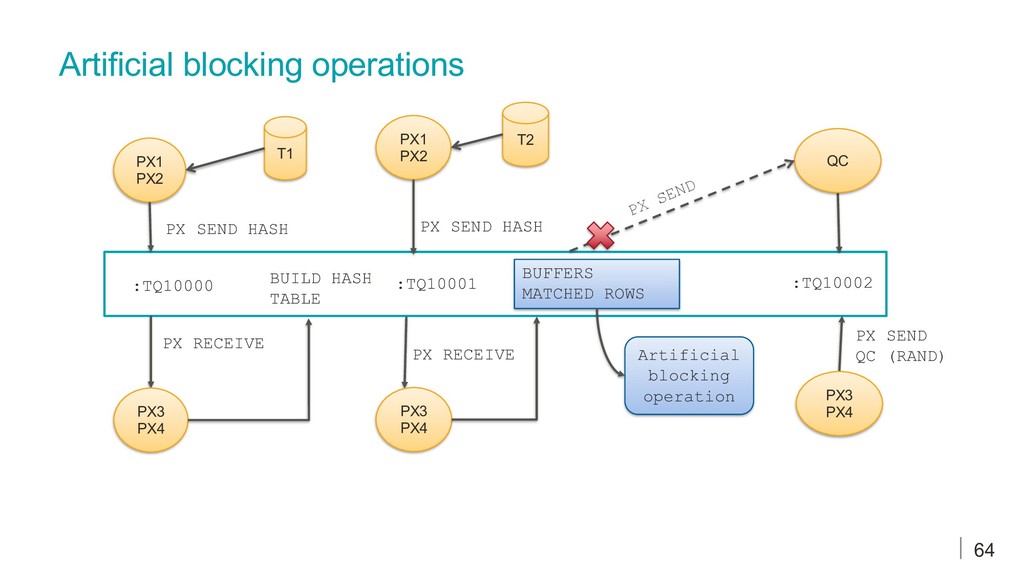
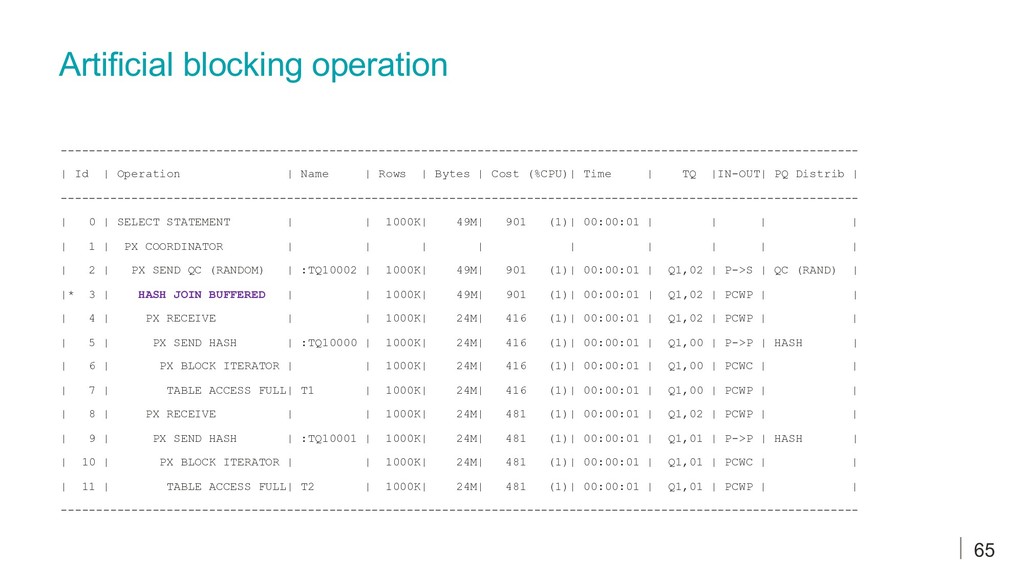
• If the data has to be processed by next (different) PX Slave set it has to be “parked” • True blocking operations • Artificial blocking operations 61


 iarsov
 willnet
 takahashim
 kakehashi
 onk
 pfn
 carta_engineering
 jyouryuusui
 gogutan
 codmoninc
 yuuuuuuu168
 shugo
 koukihosaka
 csswizardry
 portentint
 nmsamuel
 jct
 productmarketing
 codingconduct
 greggifford
 stuffmc
 jlugia
 pedronauck
 axbom
 lara