Share
Embed

Transcript
113 slides
-
About Me • Software Engineer & Data Nerd since 1997
• Doing “media stuff” since 2012 • Principal @ AOL since 2014 • @ieatkillerbees • http://samanthaquinones.com -
What We’ll Cover • Intro to Elasticsearch • CRUD •
Creating Mappings • Analyzers • Basic Querying & Searching • Scoring & Relevance • Aggregations Basics -
What is Elasticsearch? • Near real-time (documents are available for
search quickly after being indexed) search engine powered by Lucene • Clustered for H/A and performance via federation with shards and replicas -
What’s it Used For? • Logging (we use Elasticsearch to
centralize traffic logs, exception logs, and audit logs) • Content management and search • Statistical analysis -
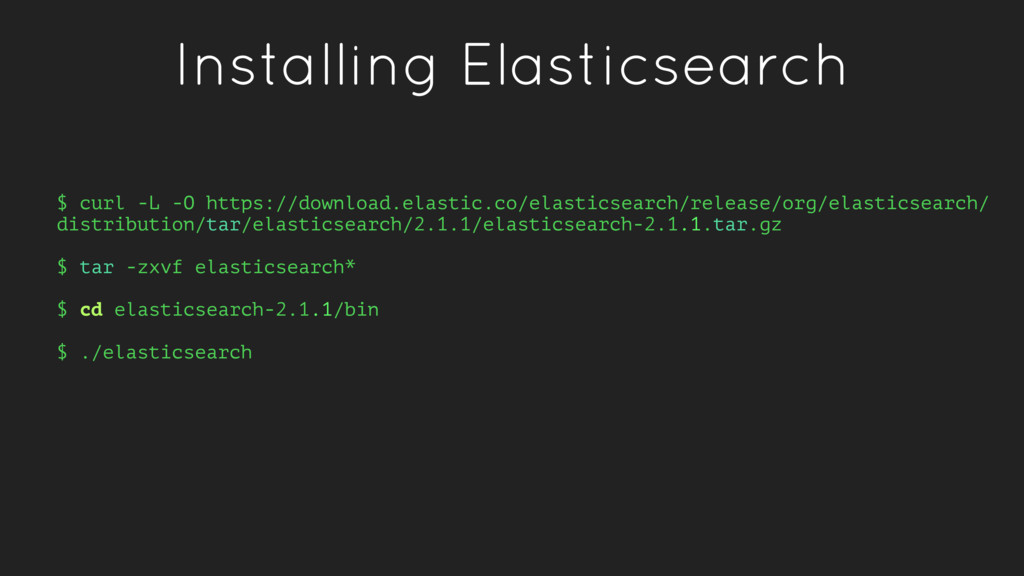
Installing Elasticsearch $ curl -L -O https://download.elastic.co/elasticsearch/release/org/elasticsearch/ distribution/tar/elasticsearch/2.1.1/elasticsearch-2.1.1.tar.gz $ tar
-zxvf elasticsearch* $ cd elasticsearch-2.1.1/bin $ ./elasticsearch -
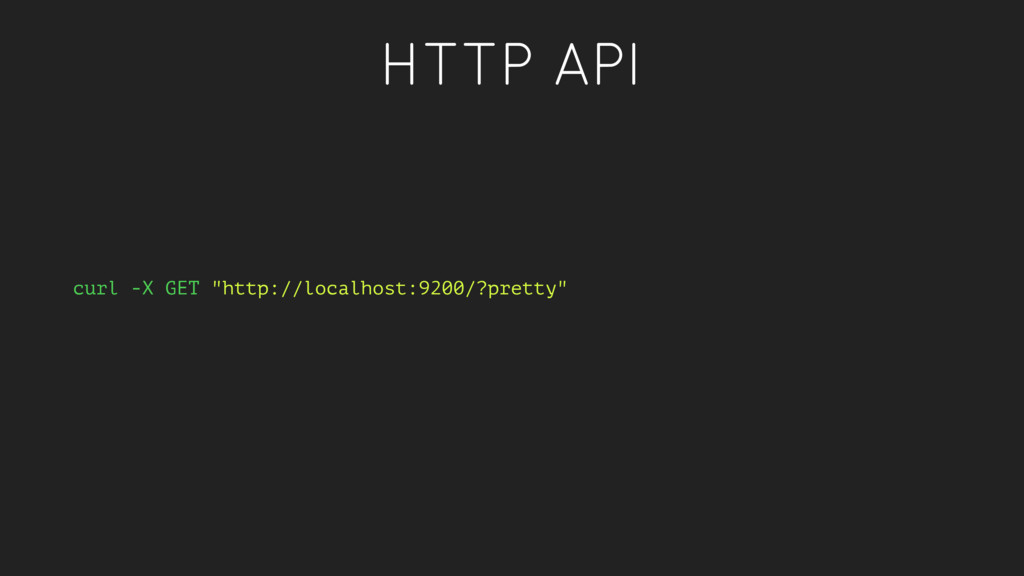
Connecting to Elasticsearch • Via Java, there are two native
clients which connect to an ES cluster on port 9300 • Most commonly, we access Elasticsearch via HTTP API -
Data Format • Elasticsearch is a document-oriented database • All
operations are performed against documents (object graphs expressed as JSON) -
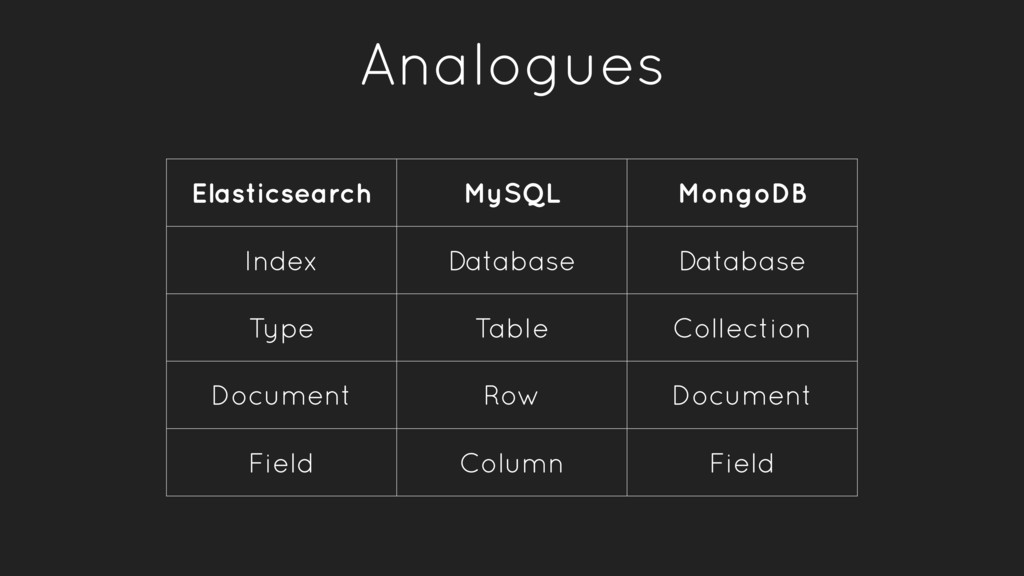
Analogues Elasticsearch MySQL MongoDB Index Database Database Type Table Collection
Document Row Document Field Column Field -
Index Madness • Index is an overloaded term. • As
a verb, to index a document is store a document in an index. This is analogous to an SQL INSERT operation. • As a noun, an index is a collection of documents. • Fields within a document have inverted indexes, similar to how a column in an SQL table may have an index. -
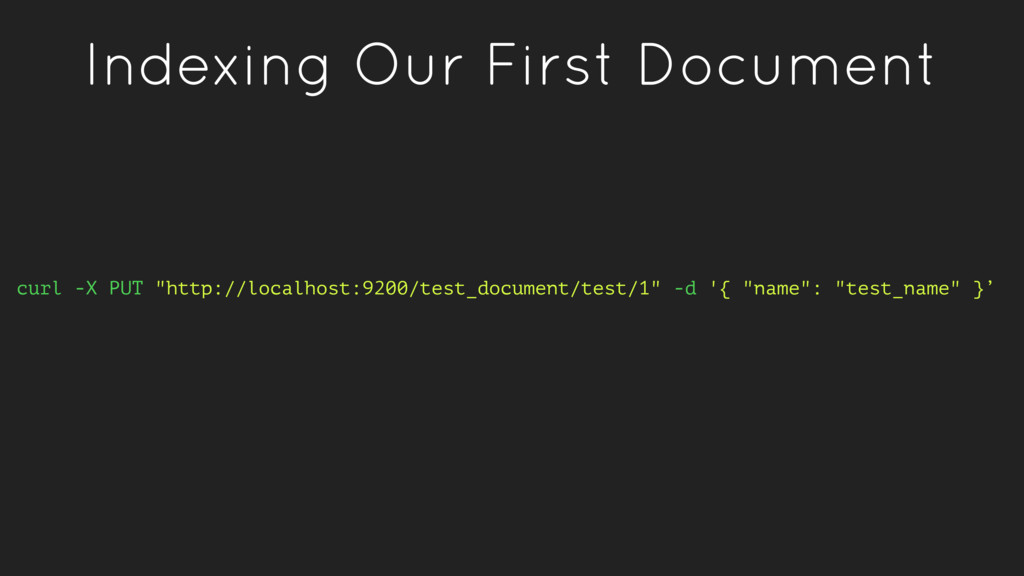
Indexing Our First Document curl -X PUT "http://localhost:9200/test_document/test/1" -d '{
"name": "test_name" }’ -
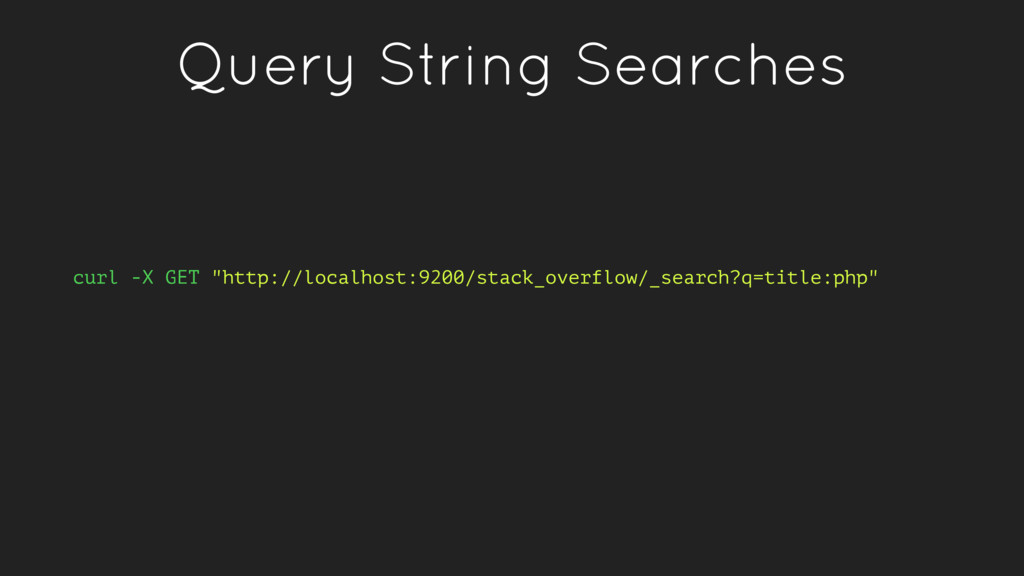
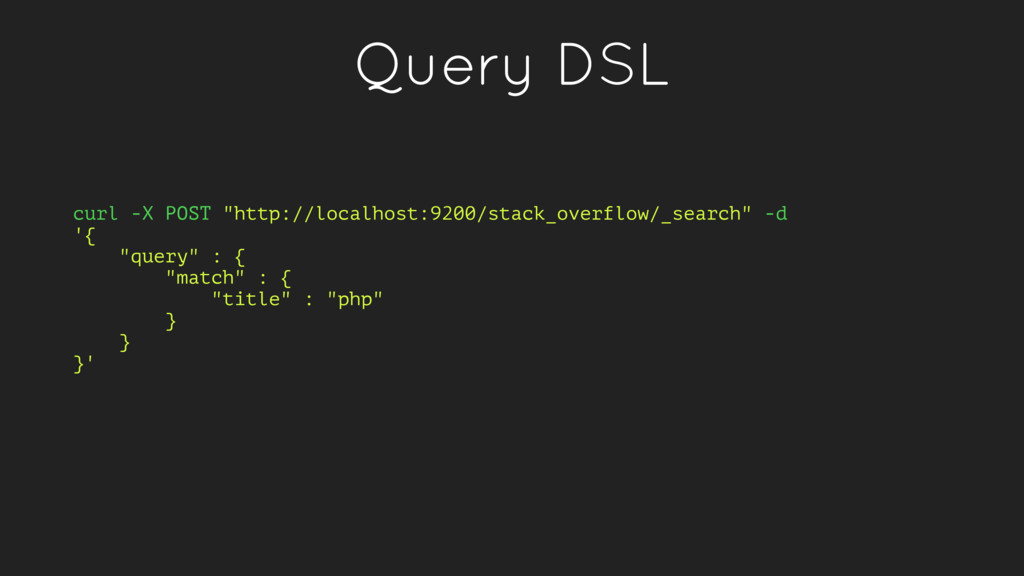
Query DSL curl -X POST "http://localhost:9200/stack_overflow/_search" -d '{ "query" :
{ "match" : { "title" : "php" } } }' -
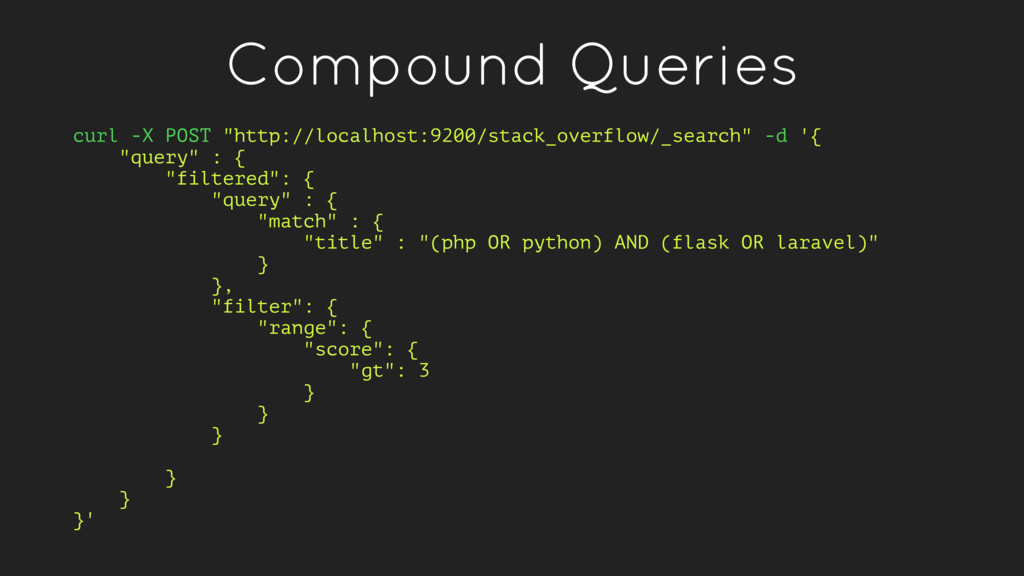
Compound Queries curl -X POST "http://localhost:9200/stack_overflow/_search" -d '{ "query" :
{ "filtered": { "query" : { "match" : { "title" : "(php OR python) AND (flask OR laravel)" } }, "filter": { "range": { "score": { "gt": 3 } } } } } }' -
Full-Text Searching curl -X POST "http://localhost:9200/stack_overflow/_search" -d '{ "query" :
{ "match" : { "title" : "php loop" } } }' -
Relevancy • When searching (in query context), results are scored
by a relevancy algorithm • Results are presented in order from highest to lowest score -
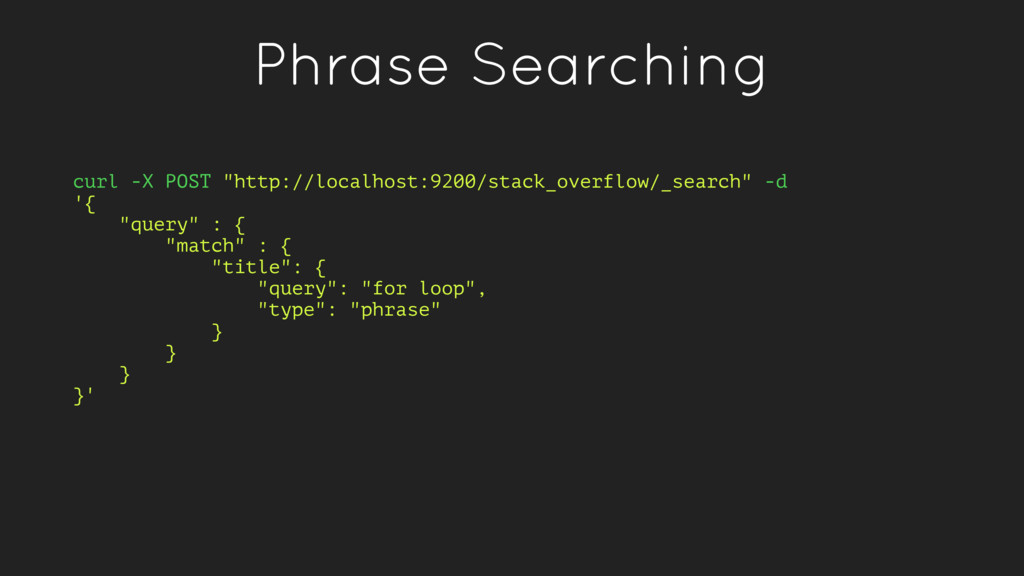
Phrase Searching curl -X POST "http://localhost:9200/stack_overflow/_search" -d '{ "query" :
{ "match" : { "title": { "query": "for loop", "type": "phrase" } } } }' -
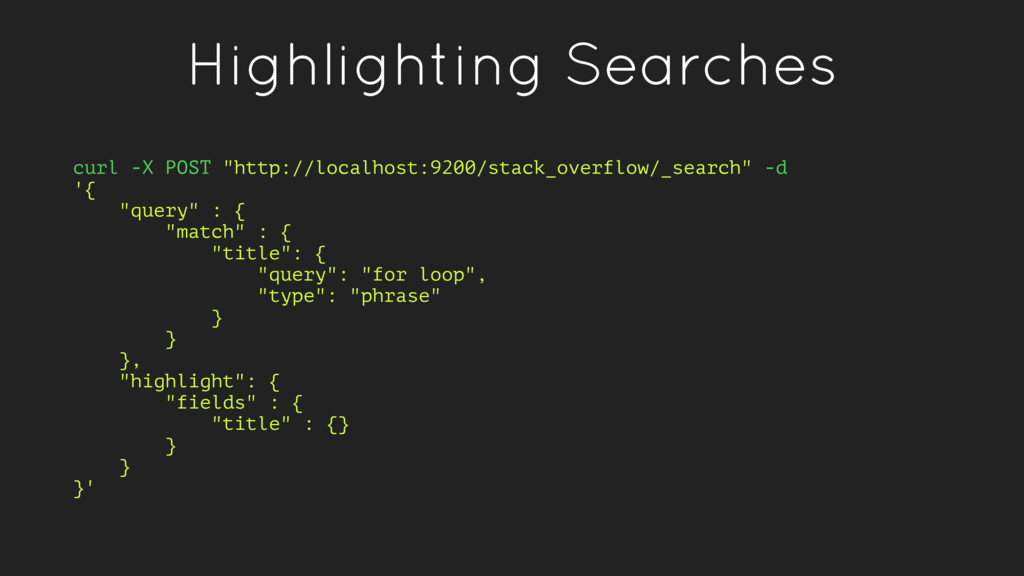
Highlighting Searches curl -X POST "http://localhost:9200/stack_overflow/_search" -d '{ "query" :
{ "match" : { "title": { "query": "for loop", "type": "phrase" } } }, "highlight": { "fields" : { "title" : {} } } }' -
Aggregations • Run statistical operations over your data • Also
near real-time! • Complex aggregations are abstracted away behind simple interfaces— you don’t need to be a statistician -
Analyzing Tags curl -X POST "http://localhost:9200/stack_overflow/_search" -d '{ "size": 0,
"aggs": { "all_tags": { "terms": { "field": "tags", "size": 0 } } } }' -
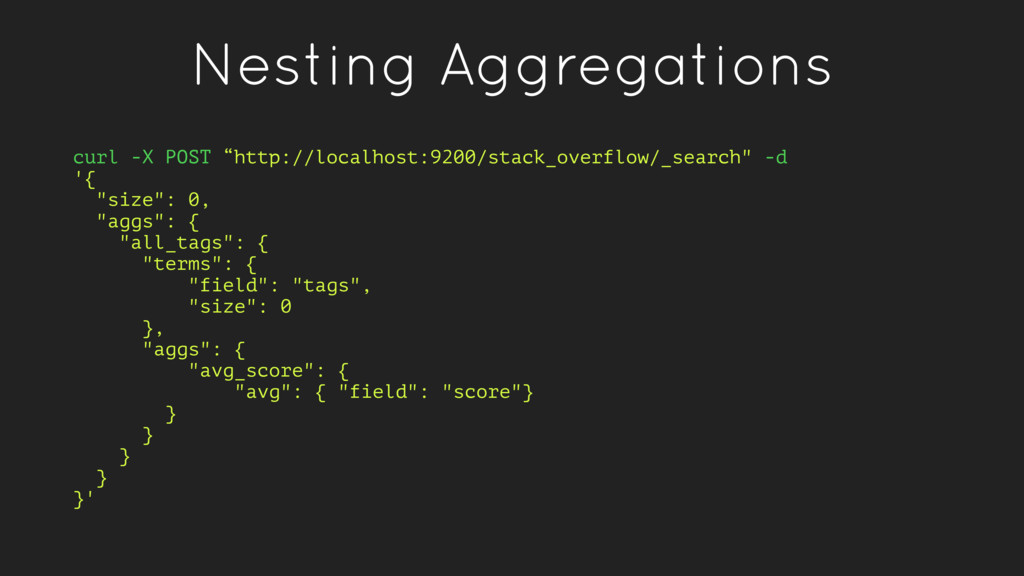
Nesting Aggregations curl -X POST “http://localhost:9200/stack_overflow/_search" -d '{ "size": 0,
"aggs": { "all_tags": { "terms": { "field": "tags", "size": 0 }, "aggs": { "avg_score": { "avg": { "field": "score"} } } } } }' -
Under the Hood • Elasticsearch is designed from the ground-up
to run in a distributed fashion. • Indices (collections of documents) are partitioned in to shards. • Shards can be stored on a single or multiple nodes. • Shards are balanced across the cluster to improve performance • Shards are replicated for redundancy and high availability -
What is a Cluster? • One or more nodes (servers)
that work together to… • serve a dataset that exceeds the capacity of a single server… • provide federated indexing (writes) and searching (reads)… • provide H/A through sharing and replication of data -
What are Nodes? • Individual servers within a cluster •
Can providing indexing and searching capabilities -
What is an Index? • An index is logically a
collection of documents, roughly analogous to a database in MySQL • An index is in reality a namespace that points to one or more physical shards which contain data • When indexing a document, if the specified index does not exist, it will be created automatically -
What are Shards? • Low-level units that hold a slice
of available data • A shard represents a single instance of lucene and is fully- functional, self-contained search engine • Shards are either primary or replicas and are assigned to nodes -
What is Replication? • Shards can have replicas • Replicas
primarily provide redundancy for when shards/nodes fail • Replicas should not be allocated on the same node as the shard it replicates -
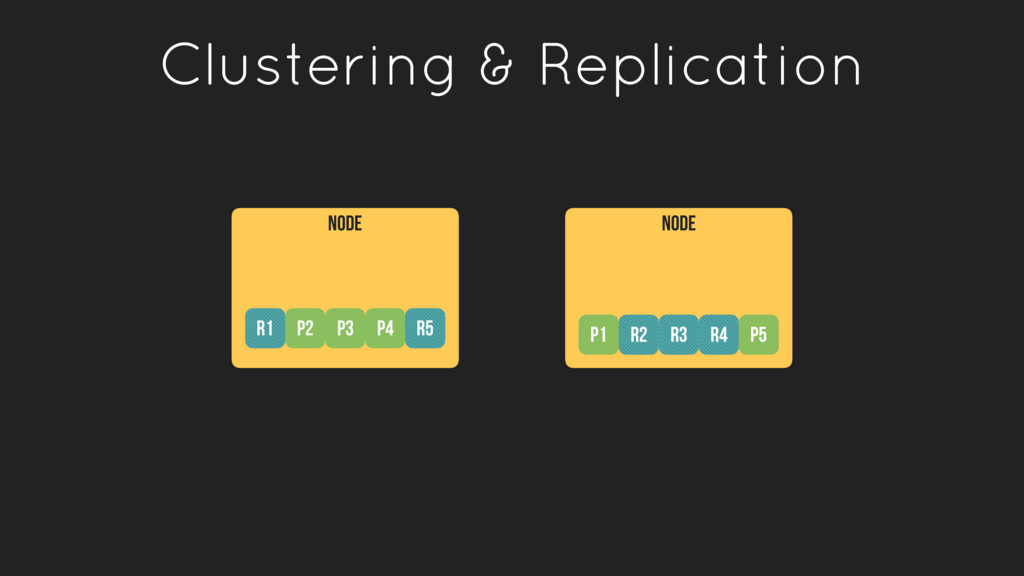
Default Topology • 5 primary shards per index • 1
replica per shard -
NODE Clustering & Replication NODE R1 P2 P3 R2 R3
P4 R5 P1 R4 P5 -
_cat API • Display human-readable information about parts of the
ES system • Provides some limited documentation of functions -
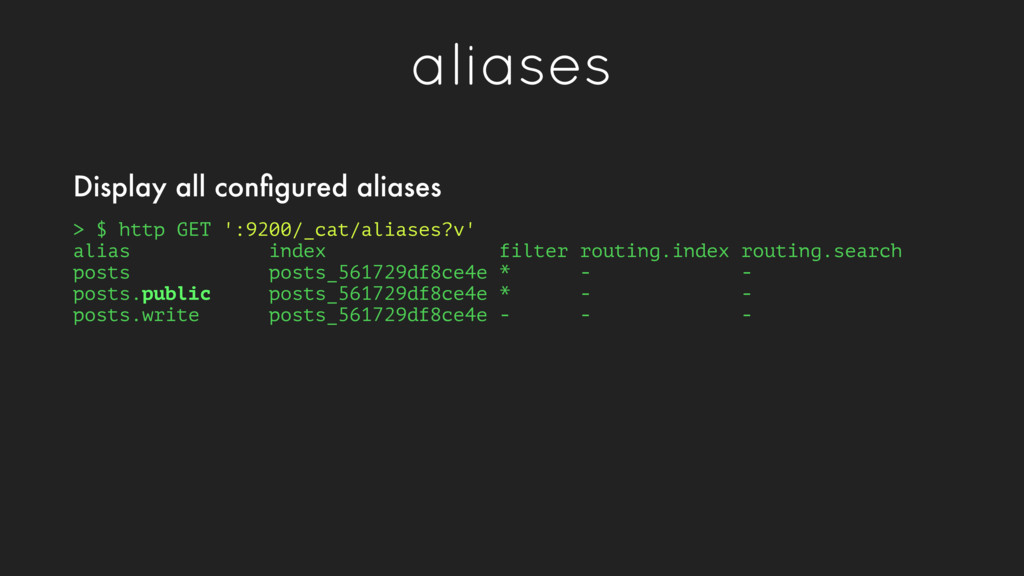
aliases > $ http GET ':9200/_cat/aliases?v' alias index filter routing.index
routing.search posts posts_561729df8ce4e * - - posts.public posts_561729df8ce4e * - - posts.write posts_561729df8ce4e - - - Display all configured aliases -
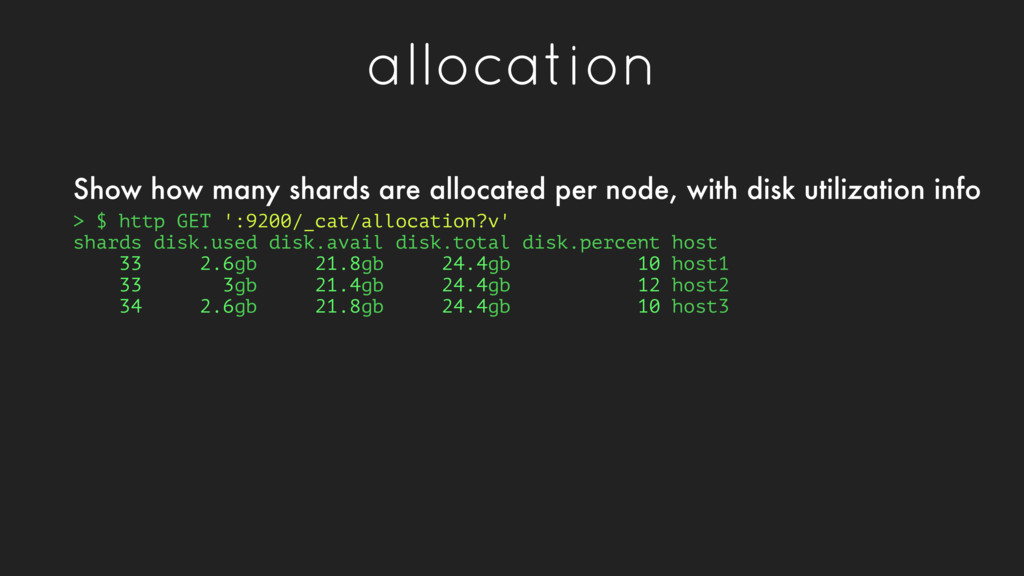
allocation > $ http GET ':9200/_cat/allocation?v' shards disk.used disk.avail disk.total
disk.percent host 33 2.6gb 21.8gb 24.4gb 10 host1 33 3gb 21.4gb 24.4gb 12 host2 34 2.6gb 21.8gb 24.4gb 10 host3 Show how many shards are allocated per node, with disk utilization info -
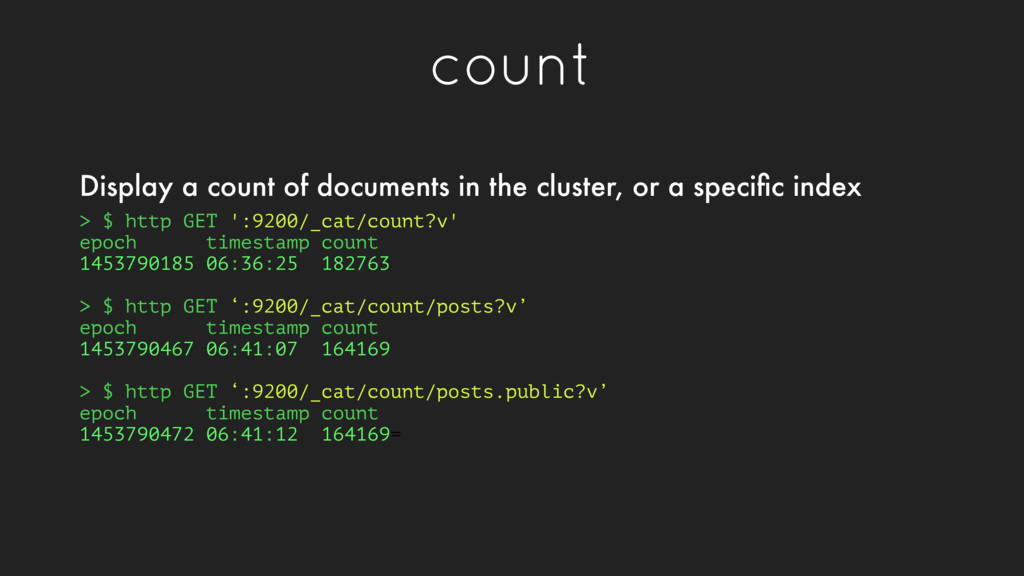
count > $ http GET ':9200/_cat/count?v' epoch timestamp count 1453790185
06:36:25 182763 > $ http GET ‘:9200/_cat/count/posts?v’ epoch timestamp count 1453790467 06:41:07 164169 > $ http GET ‘:9200/_cat/count/posts.public?v’ epoch timestamp count 1453790472 06:41:12 164169= Display a count of documents in the cluster, or a specific index -
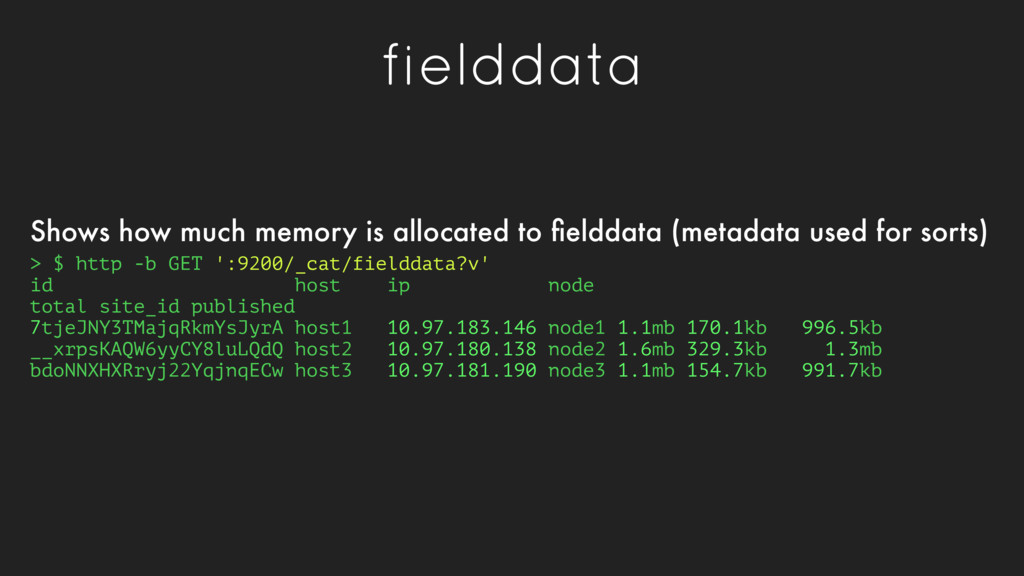
fielddata > $ http -b GET ':9200/_cat/fielddata?v' id host ip
node total site_id published 7tjeJNY3TMajqRkmYsJyrA host1 10.97.183.146 node1 1.1mb 170.1kb 996.5kb __xrpsKAQW6yyCY8luLQdQ host2 10.97.180.138 node2 1.6mb 329.3kb 1.3mb bdoNNXHXRryj22YqjnqECw host3 10.97.181.190 node3 1.1mb 154.7kb 991.7kb Shows how much memory is allocated to fielddata (metadata used for sorts) -
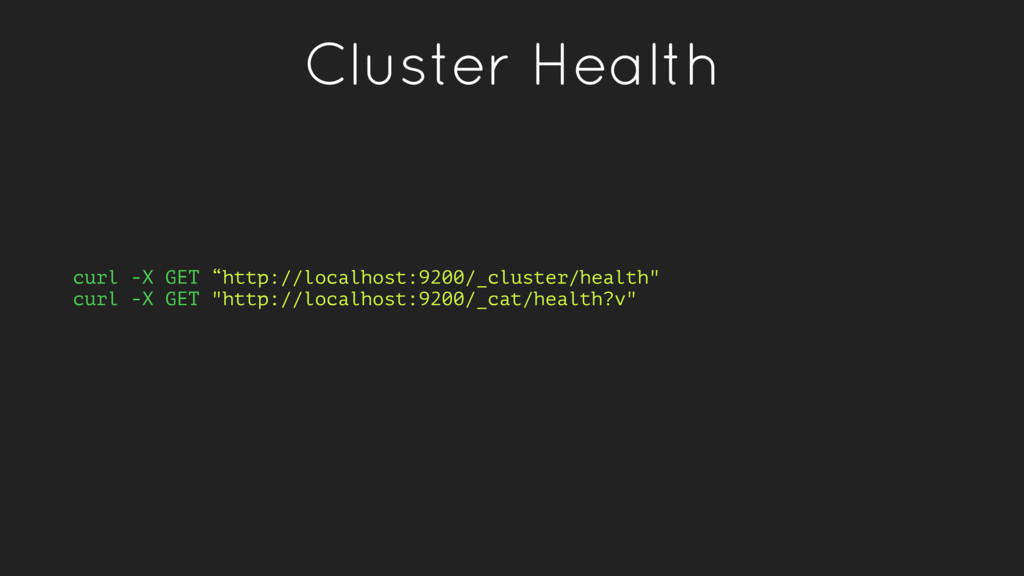
health > $ http -b GET ':9200/_cat/health?v' epoch timestamp cluster
status node.total node.data shards pri relo init unassign pending_tasks 1453829723 17:35:23 ampehes_prod_cluster green 3 3 100 50 0 0 0 0 -
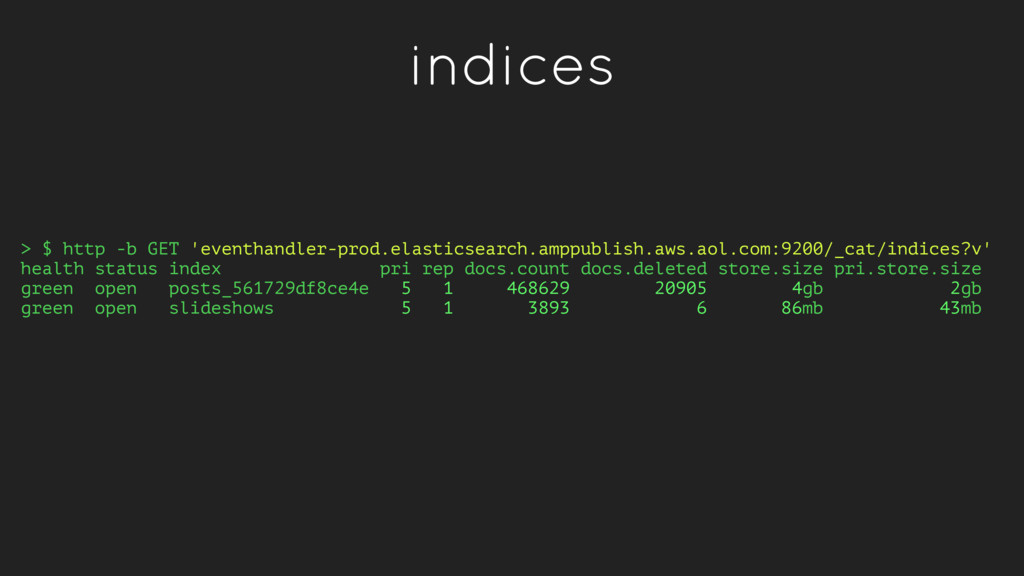
indices > $ http -b GET 'eventhandler-prod.elasticsearch.amppublish.aws.aol.com:9200/_cat/indices?v' health status index
pri rep docs.count docs.deleted store.size pri.store.size green open posts_561729df8ce4e 5 1 468629 20905 4gb 2gb green open slideshows 5 1 3893 6 86mb 43mb -
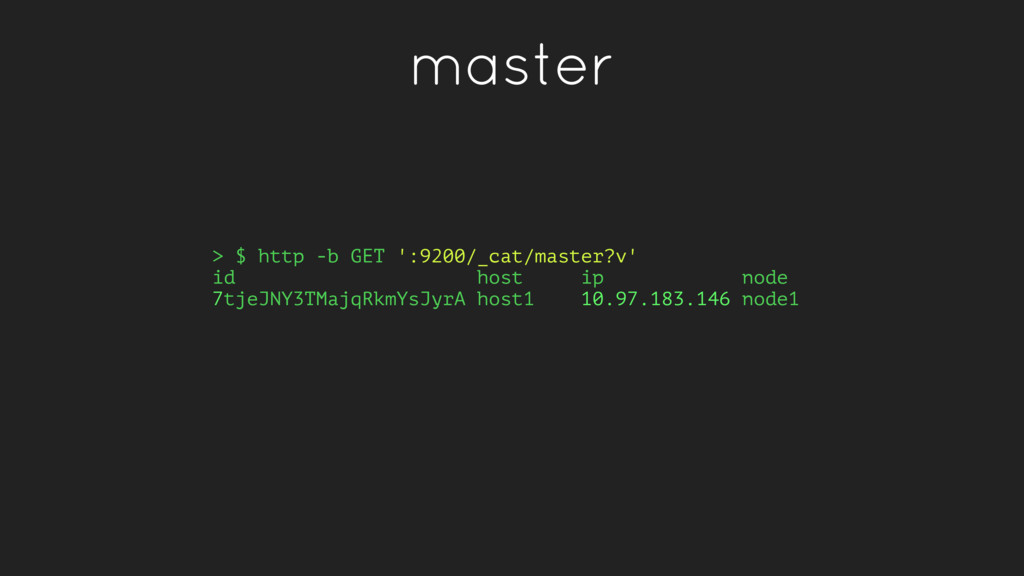
master > $ http -b GET ':9200/_cat/master?v' id host ip
node 7tjeJNY3TMajqRkmYsJyrA host1 10.97.183.146 node1 -
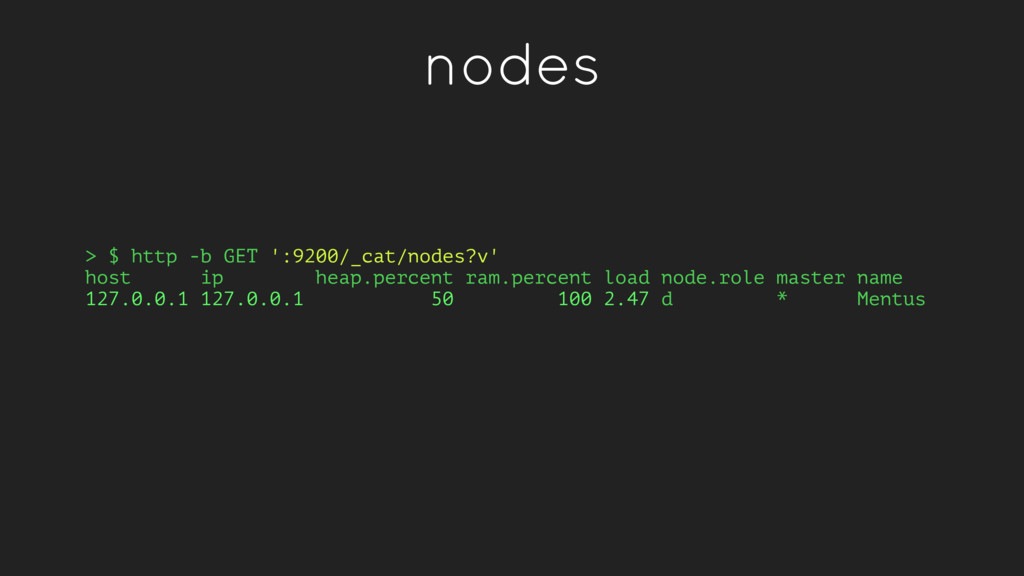
nodes > $ http -b GET ':9200/_cat/nodes?v' host ip heap.percent
ram.percent load node.role master name 127.0.0.1 127.0.0.1 50 100 2.47 d * Mentus -
pending tasks % curl 'localhost:9200/_cat/pending_tasks?v' insertOrder timeInQueue priority source 1685
855ms HIGH update-mapping [foo][t] 1686 843ms HIGH update-mapping [foo][t] 1693 753ms HIGH refresh-mapping [foo][[t]] 1688 816ms HIGH update-mapping [foo][t] 1689 802ms HIGH update-mapping [foo][t] 1690 787ms HIGH update-mapping [foo][t] 1691 773ms HIGH update-mapping [foo][t] -
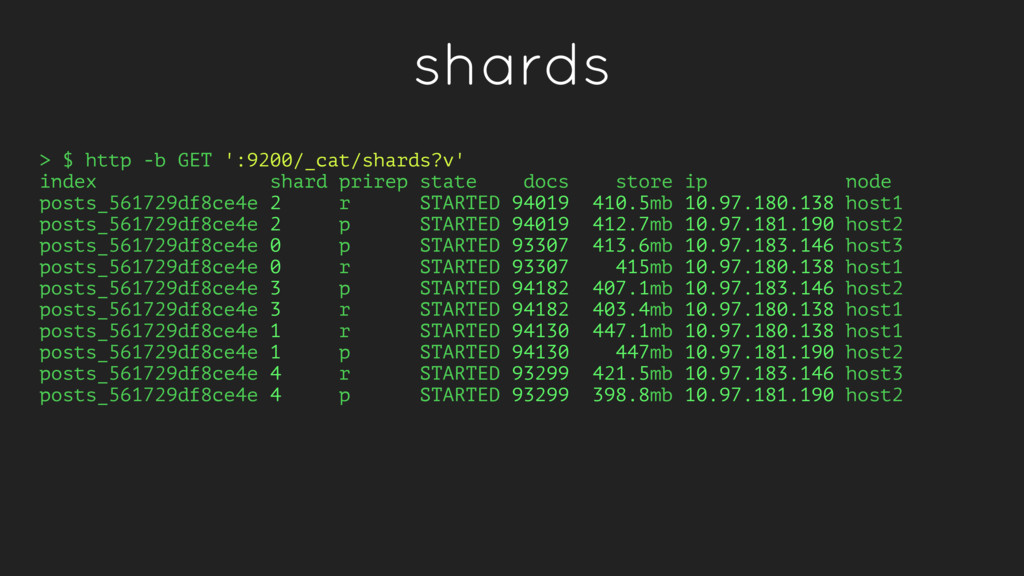
shards > $ http -b GET ':9200/_cat/shards?v' index shard prirep
state docs store ip node posts_561729df8ce4e 2 r STARTED 94019 410.5mb 10.97.180.138 host1 posts_561729df8ce4e 2 p STARTED 94019 412.7mb 10.97.181.190 host2 posts_561729df8ce4e 0 p STARTED 93307 413.6mb 10.97.183.146 host3 posts_561729df8ce4e 0 r STARTED 93307 415mb 10.97.180.138 host1 posts_561729df8ce4e 3 p STARTED 94182 407.1mb 10.97.183.146 host2 posts_561729df8ce4e 3 r STARTED 94182 403.4mb 10.97.180.138 host1 posts_561729df8ce4e 1 r STARTED 94130 447.1mb 10.97.180.138 host1 posts_561729df8ce4e 1 p STARTED 94130 447mb 10.97.181.190 host2 posts_561729df8ce4e 4 r STARTED 93299 421.5mb 10.97.183.146 host3 posts_561729df8ce4e 4 p STARTED 93299 398.8mb 10.97.181.190 host2 -
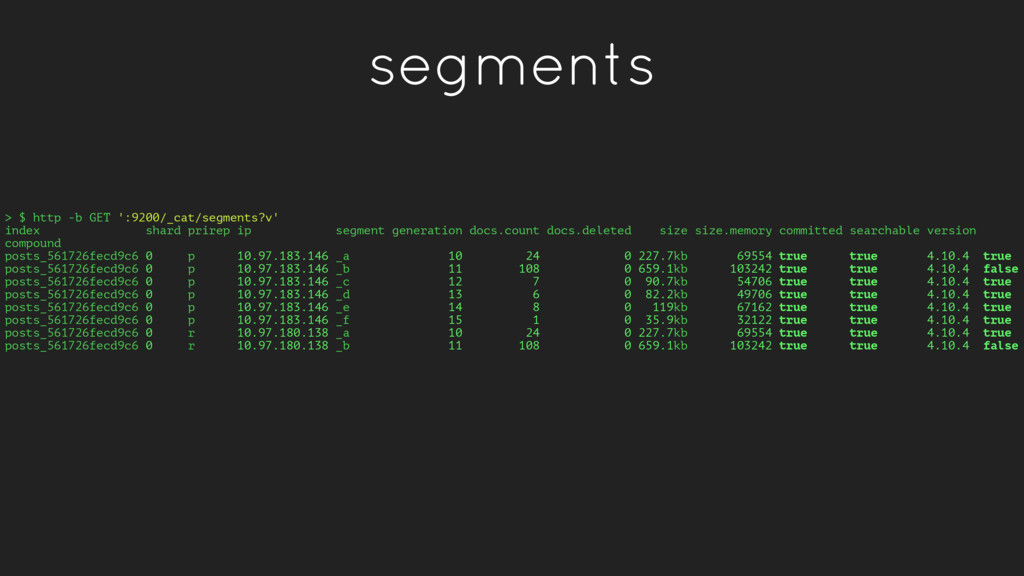
segments > $ http -b GET ':9200/_cat/segments?v' index shard prirep
ip segment generation docs.count docs.deleted size size.memory committed searchable version compound posts_561726fecd9c6 0 p 10.97.183.146 _a 10 24 0 227.7kb 69554 true true 4.10.4 true posts_561726fecd9c6 0 p 10.97.183.146 _b 11 108 0 659.1kb 103242 true true 4.10.4 false posts_561726fecd9c6 0 p 10.97.183.146 _c 12 7 0 90.7kb 54706 true true 4.10.4 true posts_561726fecd9c6 0 p 10.97.183.146 _d 13 6 0 82.2kb 49706 true true 4.10.4 true posts_561726fecd9c6 0 p 10.97.183.146 _e 14 8 0 119kb 67162 true true 4.10.4 true posts_561726fecd9c6 0 p 10.97.183.146 _f 15 1 0 35.9kb 32122 true true 4.10.4 true posts_561726fecd9c6 0 r 10.97.180.138 _a 10 24 0 227.7kb 69554 true true 4.10.4 true posts_561726fecd9c6 0 r 10.97.180.138 _b 11 108 0 659.1kb 103242 true true 4.10.4 false -
Document Model • Documents represent objects • By default, all
fields in all documents are analyzed, and indexed -
Metadata • _index - The index in which a document
resides • _type - The class of object that a document represents • _id - The document’s unique identifier. Auto-generated when not provided -
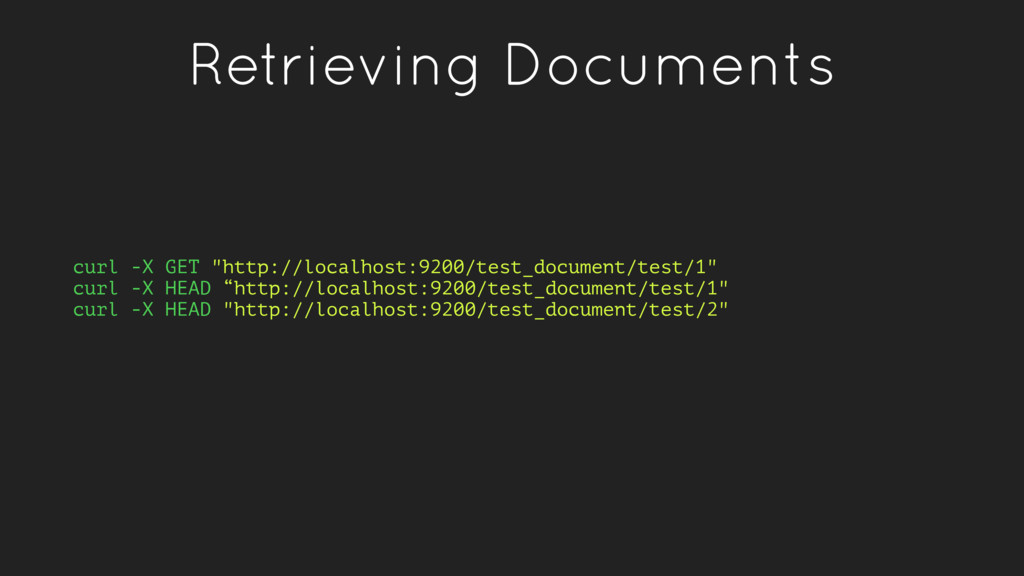
Retrieving Documents curl -X GET "http://localhost:9200/test_document/test/1" curl -X HEAD “http://localhost:9200/test_document/test/1"
curl -X HEAD "http://localhost:9200/test_document/test/2" -
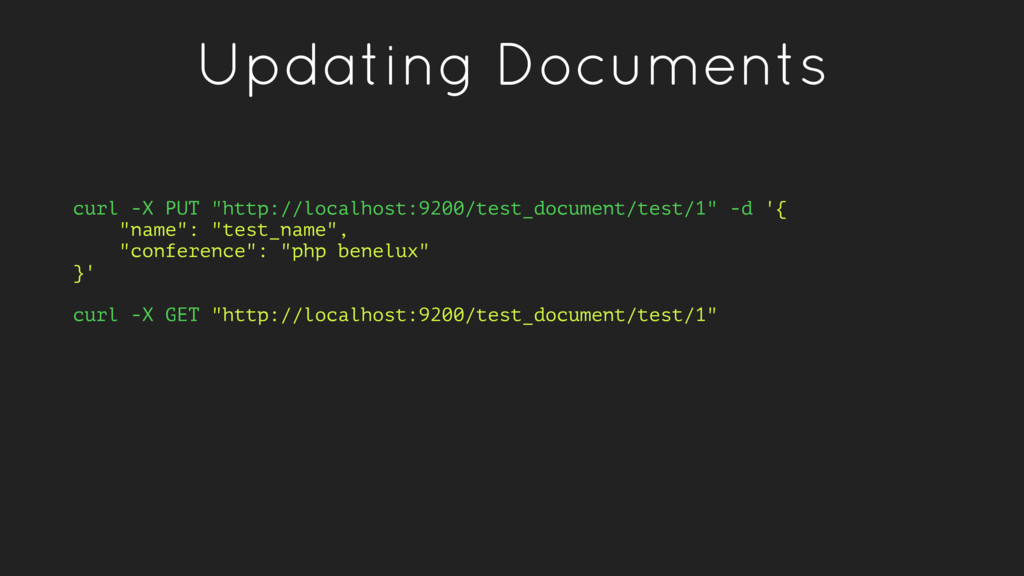
Updating Documents curl -X PUT "http://localhost:9200/test_document/test/1" -d '{ "name": "test_name",
"conference": "php benelux" }' curl -X GET "http://localhost:9200/test_document/test/1" -
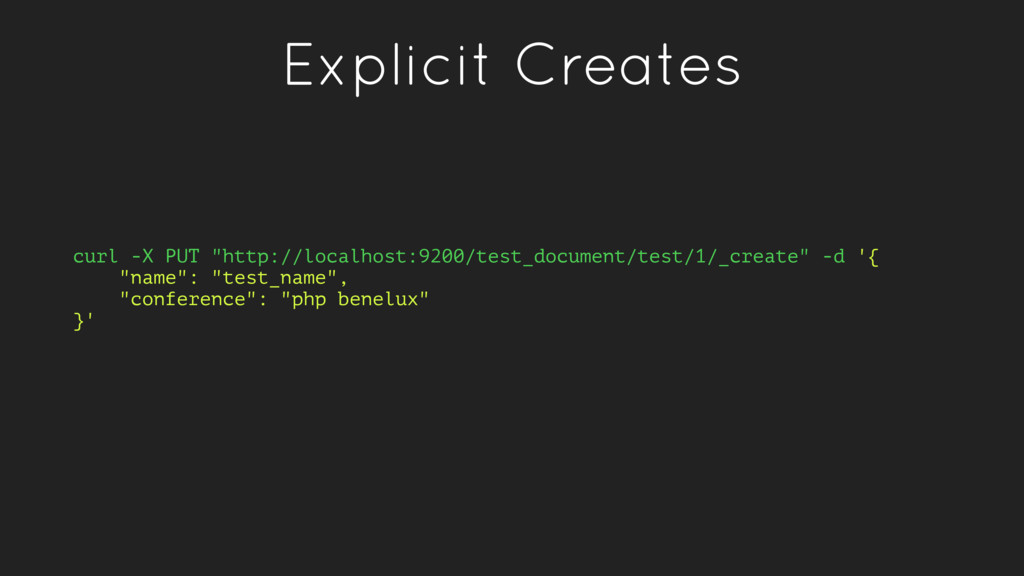
Explicit Creates curl -X PUT "http://localhost:9200/test_document/test/1/_create" -d '{ "name": "test_name",
"conference": "php benelux" }' -
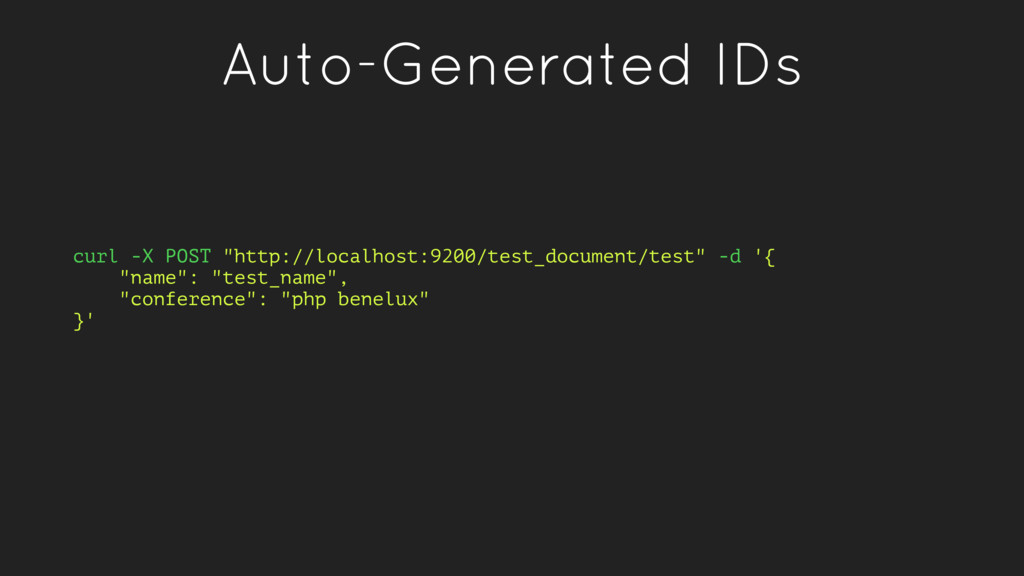
Auto-Generated IDs curl -X POST "http://localhost:9200/test_document/test" -d '{ "name": "test_name",
"conference": "php benelux" }' -
Bulk API • Perform many operations in a single request
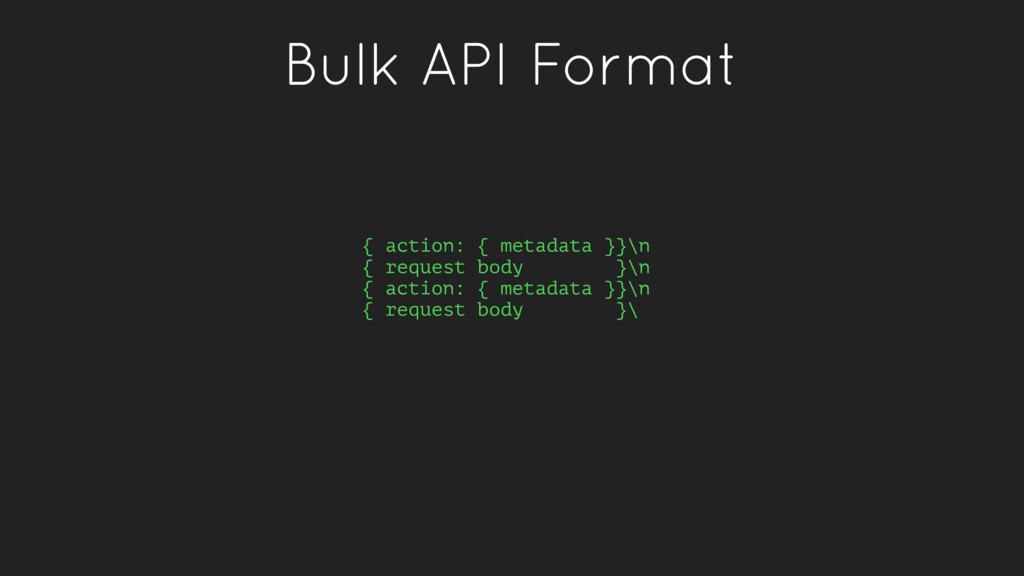
• Efficient batching of actions • Bulk queries take the form of a stream of single-line JSON objects that define actions and document bodies -
Bulk Actions • create - Index a document IFF it
doesn’t exist already • index - Index a document, replacing it if it exists • update - Apply a partial update to a document • delete - Delete a document -
Bulk API Format { action: { metadata }}\n { request
body }\n { action: { metadata }}\n { request body }\ -
Sizing Bulk Requests • Balance quantity of documents with size
of documents • Docs list the sweet-spot between 5-15 MB per request • AOL Analytics Cluster indexes 5000 documents per batch (approx 7MB) -
Searching Documents • Structured queries - queries against concrete fields
like “title” or “score” which return specific documents. • Full-text queries - queries that find documents which match a search query and return them sorted by relevance -
Search Elements • Mappings - Defines how data in fields
are interpreted • Analysis - How text is parsed and processed to make it searchable • Query DSL - Elasticsearch’s query language -
About Queries • Leaf Queries - Searches for a value
in a given field. These queries are standalone. Examples: match, range, term • Compound Queries - Combinations of leaf queries and other compound queries which combine operations together either logically (e.g. bool queries) or alter their behavior (e.g. score queries) -
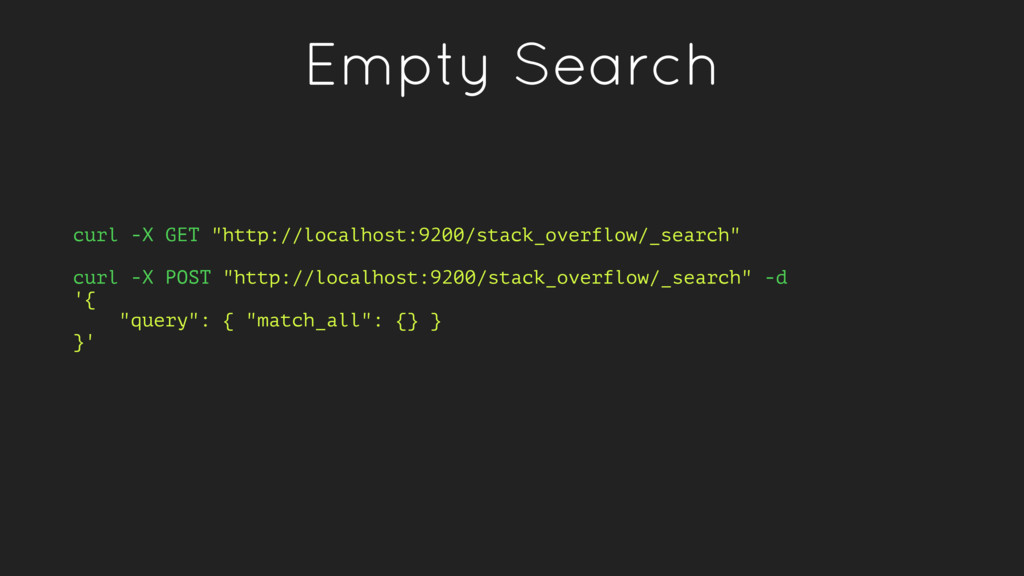
Empty Search curl -X GET "http://localhost:9200/stack_overflow/_search" curl -X POST "http://localhost:9200/stack_overflow/_search"
-d '{ "query": { "match_all": {} } }' -
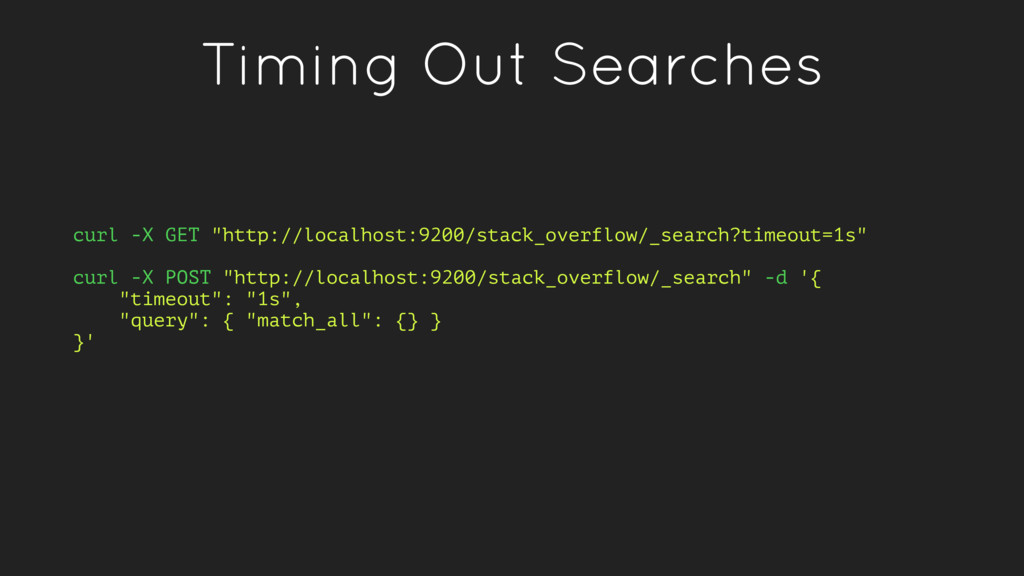
Timing Out Searches curl -X GET "http://localhost:9200/stack_overflow/_search?timeout=1s" curl -X POST
"http://localhost:9200/stack_overflow/_search" -d '{ "timeout": "1s", "query": { "match_all": {} } }' -
Multi-Index Use Cases • Dated indices for logging • Roll-off
indices for content-aging • Analytic roll-ups -
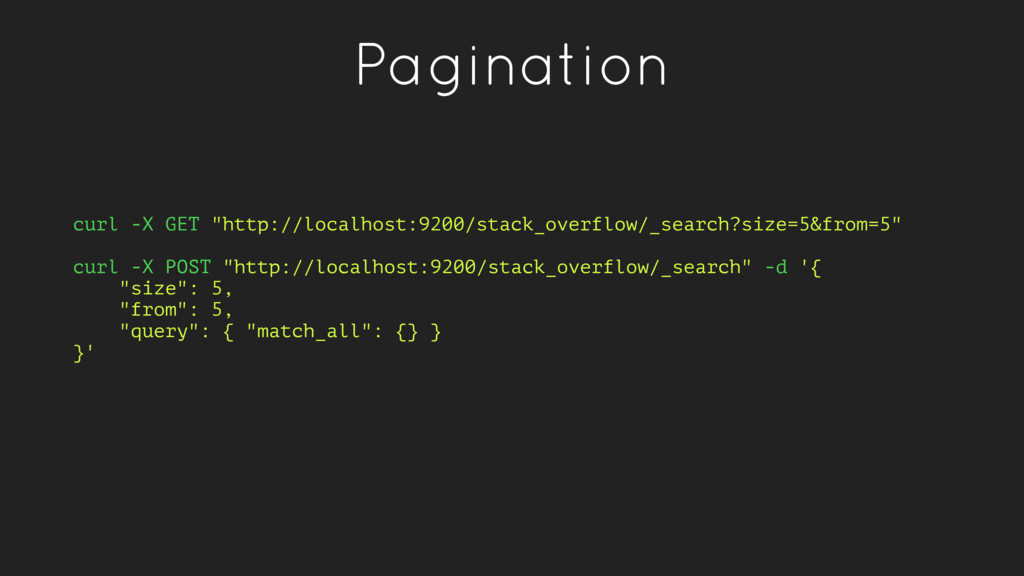
Pagination curl -X GET "http://localhost:9200/stack_overflow/_search?size=5&from=5" curl -X POST "http://localhost:9200/stack_overflow/_search" -d
'{ "size": 5, "from": 5, "query": { "match_all": {} } }' -
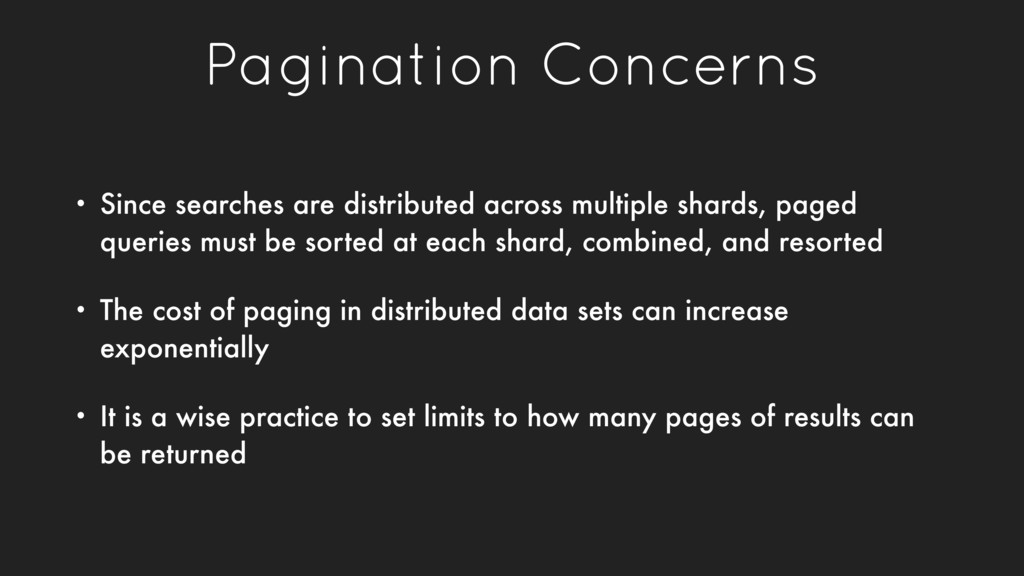
Pagination Concerns • Since searches are distributed across multiple shards,
paged queries must be sorted at each shard, combined, and resorted • The cost of paging in distributed data sets can increase exponentially • It is a wise practice to set limits to how many pages of results can be returned -
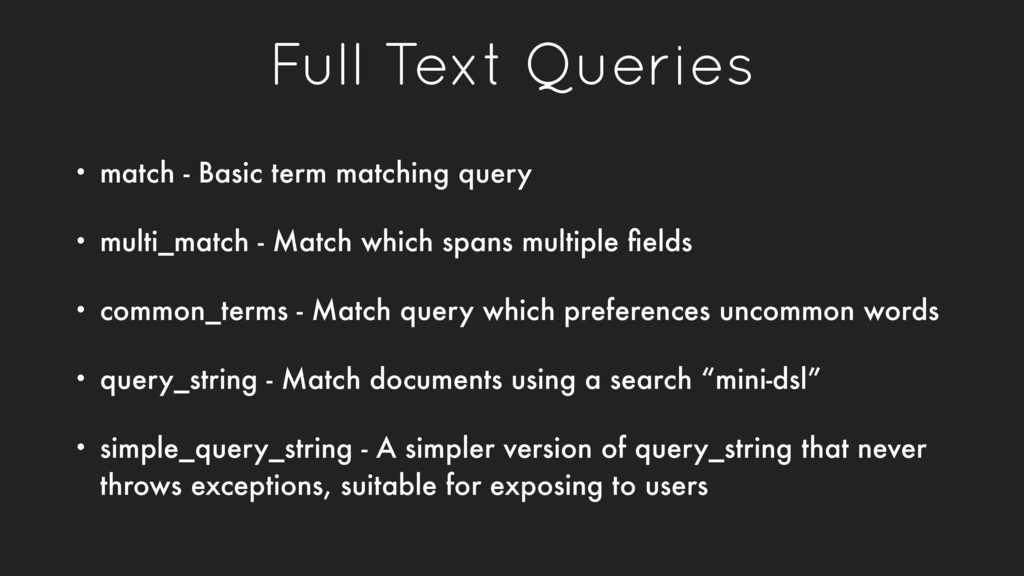
Full Text Queries • match - Basic term matching query
• multi_match - Match which spans multiple fields • common_terms - Match query which preferences uncommon words • query_string - Match documents using a search “mini-dsl” • simple_query_string - A simpler version of query_string that never throws exceptions, suitable for exposing to users -
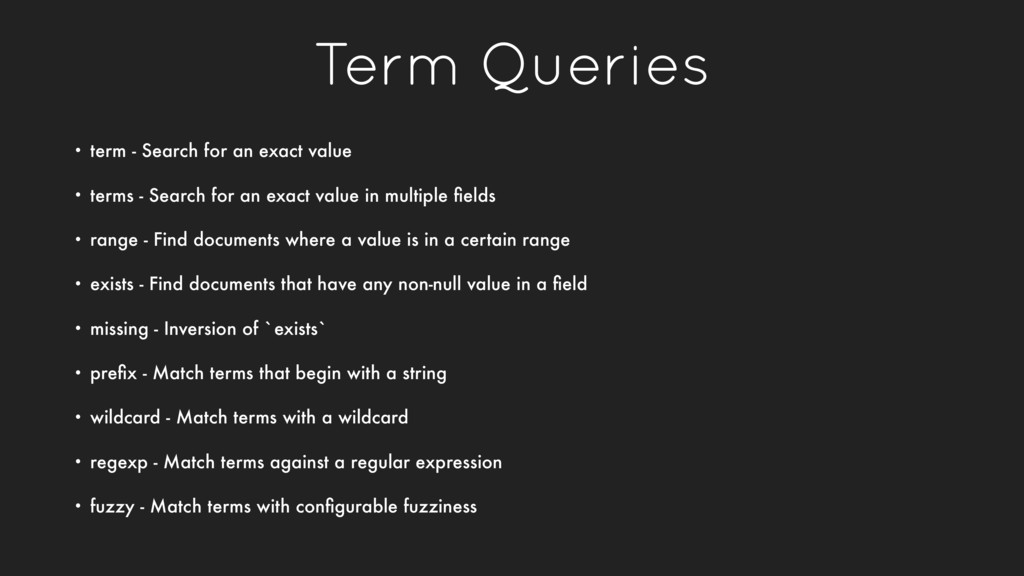
Term Queries • term - Search for an exact value
• terms - Search for an exact value in multiple fields • range - Find documents where a value is in a certain range • exists - Find documents that have any non-null value in a field • missing - Inversion of `exists` • prefix - Match terms that begin with a string • wildcard - Match terms with a wildcard • regexp - Match terms against a regular expression • fuzzy - Match terms with configurable fuzziness -
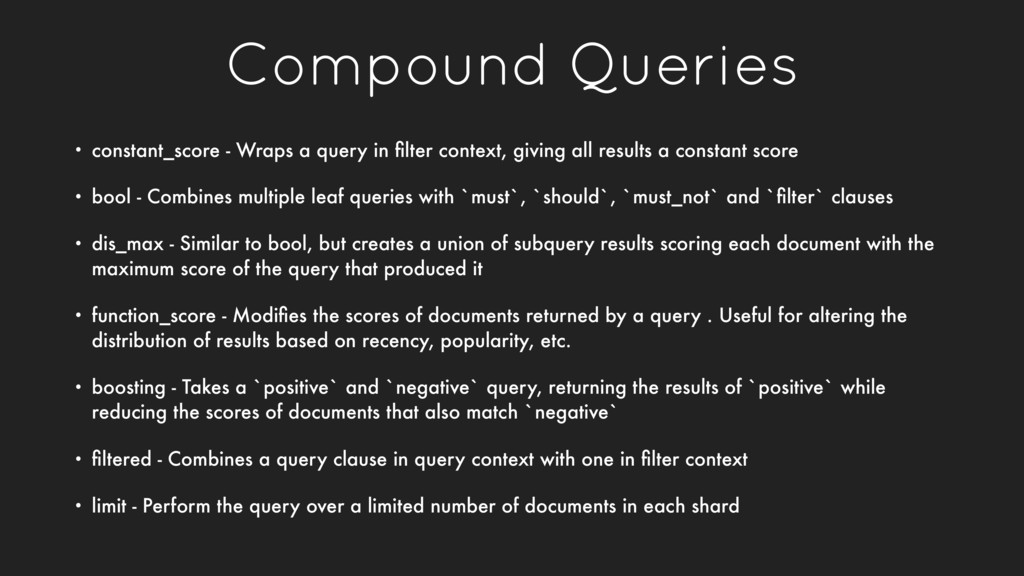
Compound Queries • constant_score - Wraps a query in filter
context, giving all results a constant score • bool - Combines multiple leaf queries with `must`, `should`, `must_not` and `filter` clauses • dis_max - Similar to bool, but creates a union of subquery results scoring each document with the maximum score of the query that produced it • function_score - Modifies the scores of documents returned by a query . Useful for altering the distribution of results based on recency, popularity, etc. • boosting - Takes a `positive` and `negative` query, returning the results of `positive` while reducing the scores of documents that also match `negative` • filtered - Combines a query clause in query context with one in filter context • limit - Perform the query over a limited number of documents in each shard -
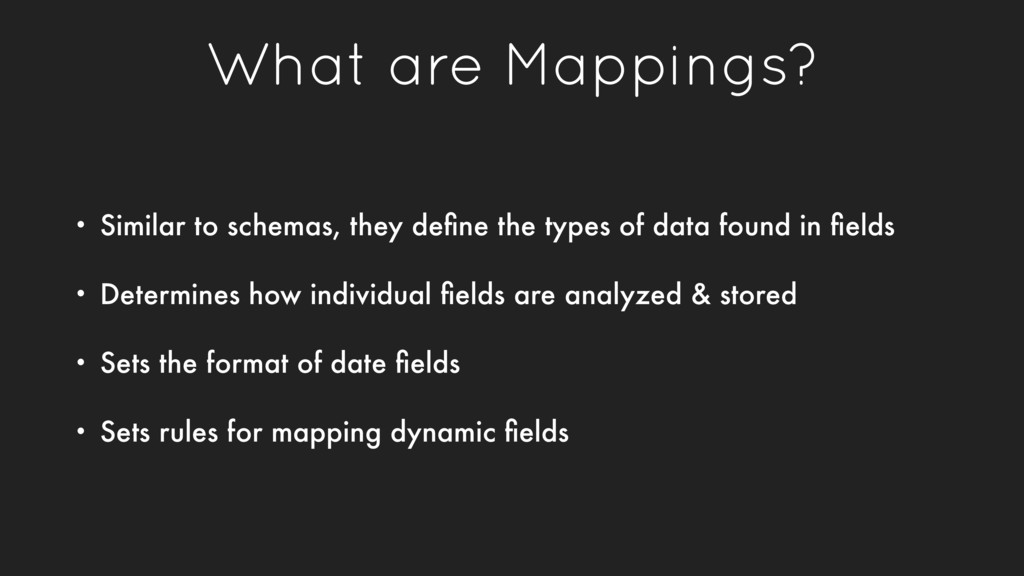
What are Mappings? • Similar to schemas, they define the
types of data found in fields • Determines how individual fields are analyzed & stored • Sets the format of date fields • Sets rules for mapping dynamic fields -
Mapping Types • Indices have one or more mapping types
which group documents logically. • Types contain meta fields, which can be used to customize metadata like _index, _id, _type, and _source • Types can also list fields that have consistent structure across types. -
Data Types • Scalar Values - string, long, double, boolean
• Special Scalars - date, ip • Structural Types - object, nested • Special Types - geo_shape, geo_point, completion • Compound Types - string arrays, nested objects -
Dynamic vs Explicit Mapping • Dynamic fields are not defined
prior to indexing • Elasticsearch selects the most likely type for dynamic fields, based on configurable rules • Explicit fields are defined exactly prior to indexing • Types cannot accept data that is the wrong type for an explicit mapping -
Shared Fields • Fields that are defined in multiple mapping
types must be identical if: • They have the same name • Live in the same index • Map to the same field internally -
Dynamic Mappings • Mappings are generated when a type is
created, if no mapping was previously specified. • Elasticsearch is good at identifying fields much of the time, but it’s far from perfect! • Fields can contain basic data-types, but importantly, mappings optimize a field for either structured (exact) or full-text searching -
Structured Data vs Full Text • Exact values contain exact
strings which are not subject to natural language interpretation. • Full-text values must be interpreted in the context of natural language -
Natural Language • “us” can be interpreted differently in natural
language • Abbreviation for “United States” • The English dative personal pronoun • An alternative symbol for µs • The French word us -
Analyzing Text • Elasticsearch is optimized for full text search
• Text is analyzed in a two-step process • First, text is tokenized in to individual terms • Second, terms are normalized through a filter -
Analyzers • Analyzers perform the analysis process • Character filters
clean up text, removing or modifying the text • Tokenizers break the text down in to terms • Token filters modify, remove, or add terms -
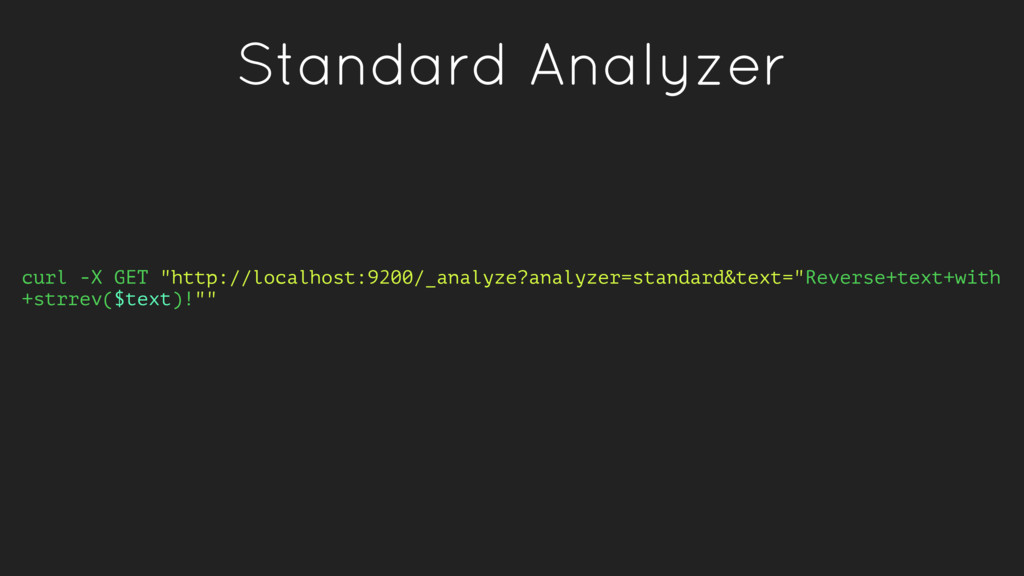
Standard Analyzer • General purpose analyzer that works for most
natural language. • Splits text on word boundaries, removes punctuation, and lowercases all tokens. -
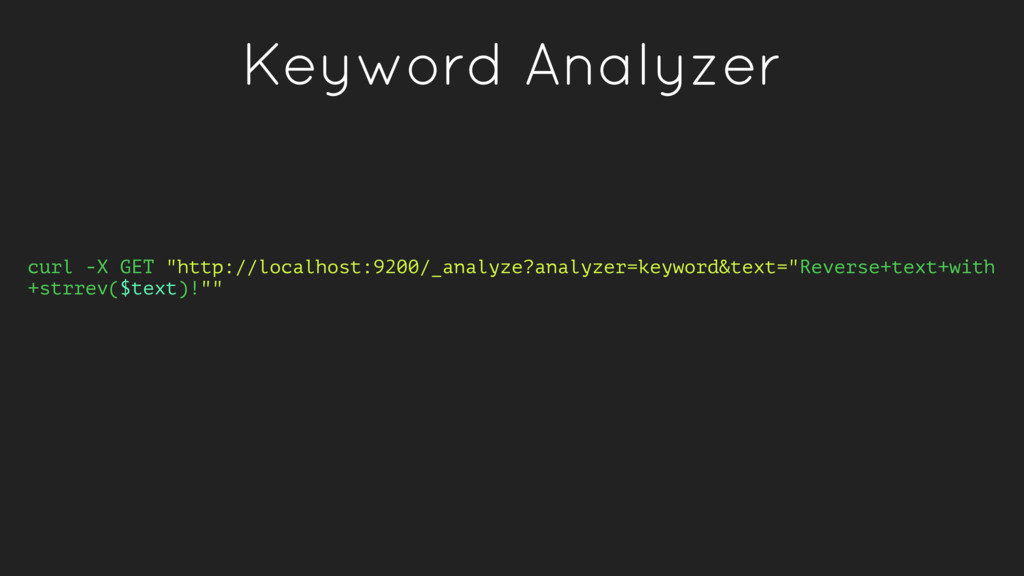
Keyword Analyzer • Tokenizes the entire text as a single
string. • Used for things that should be kept whole, like ID numbers, postal codes, etc -
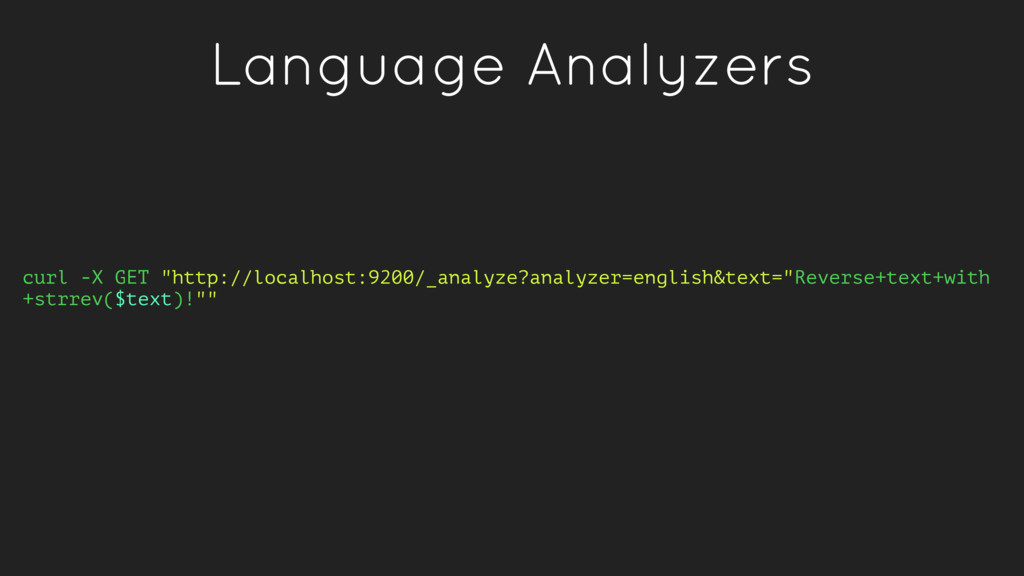
Language Analyzers • Analyzers optimized for specific natural languages. •
Reduce tokens to stems (jumper, jumped → jump) -
Analyzers • Analyzers are applied when documents are indexed •
Analyzers are applied when a full-text search is performed against a field, in order to produce the correct set of terms to search for -
Character Filters • html_strip - Removes HTML from text •
mapping - Filter based on a map of original → new ( { “ph”: “f” }) • pattern_replace - Similar to mapping, using regular expressions -
Index Templates • Template mappings that are applied to newly
created indices • Templates also contain index configuration information • Powerful when combined with dated indices -
Scoring • Scoring is based on a boolean model and
scoring function • Boolean model applies AND/OR logic to an inverse index to produce a list of matching documents -
Term Frequency • Terms that appear frequently in a document
increase the document’s relevancy score. • term_frequency(term in document) = √number_of_appearances -
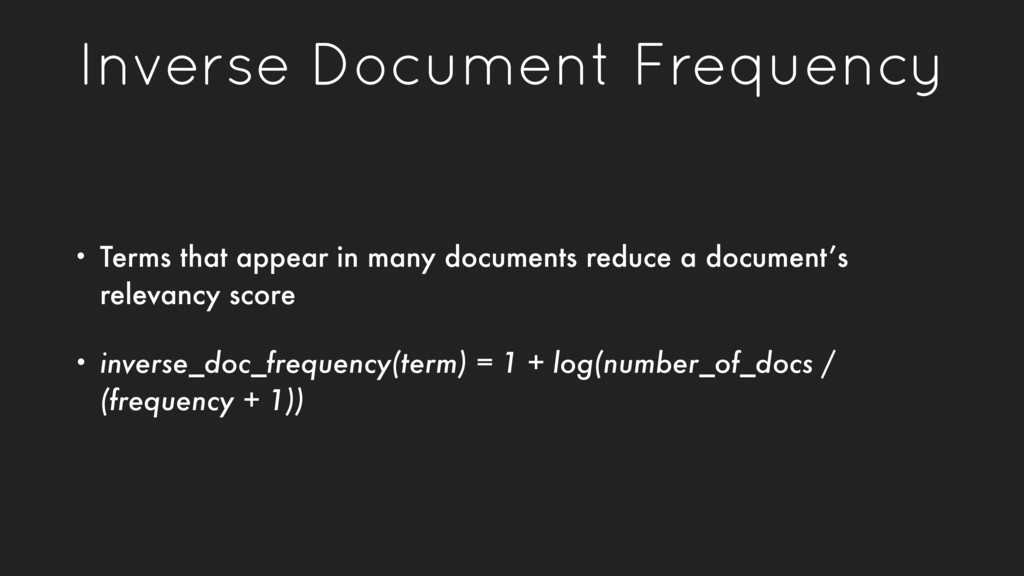
Inverse Document Frequency • Terms that appear in many documents
reduce a document’s relevancy score • inverse_doc_frequency(term) = 1 + log(number_of_docs / (frequency + 1)) -
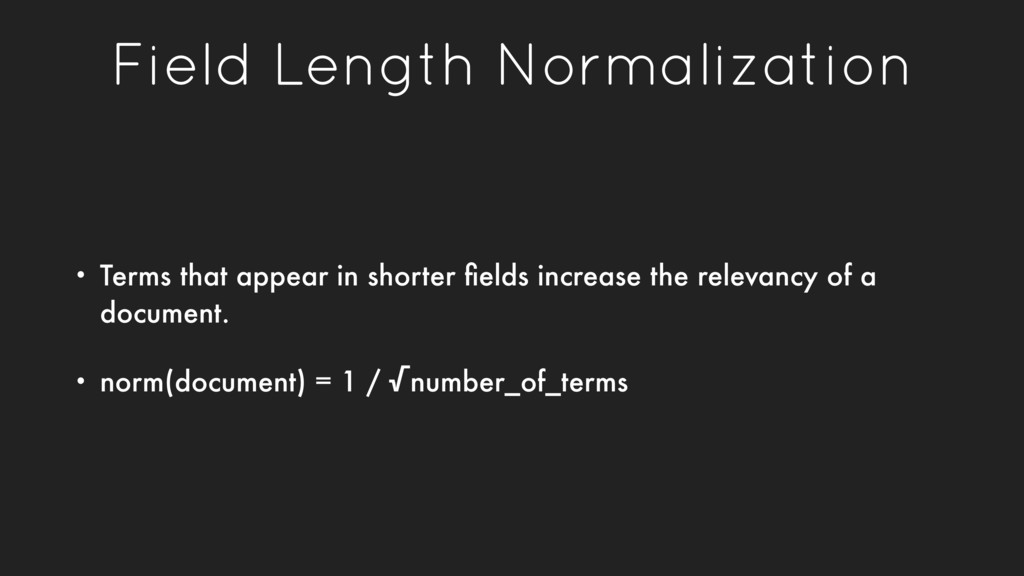
Field Length Normalization • Terms that appear in shorter fields
increase the relevancy of a document. • norm(document) = 1 / √number_of_terms -
Example from the Docs • Given the text “quick brown
fox” the term “fox” scores… • Term Frequency: 1.0 • Inverse Doc Frequency: 0.30685282 • Field Norm: 0.5 • Score: 0.15342641 -
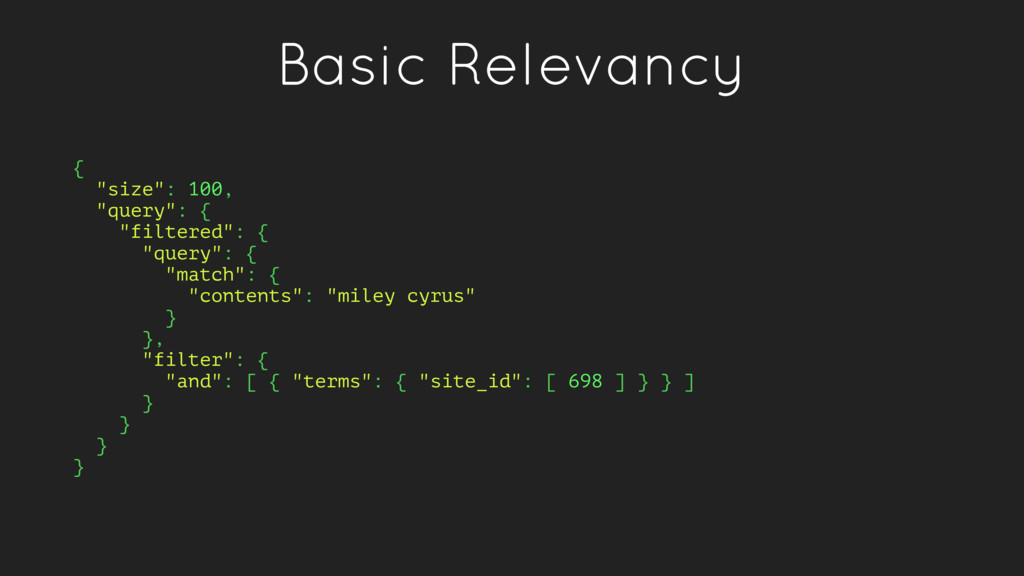
Basic Relevancy { "size": 100, "query": { "filtered": { "query":
{ "match": { "contents": "miley cyrus" } }, "filter": { "and": [ { "terms": { "site_id": [ 698 ] } } ] } } } } -
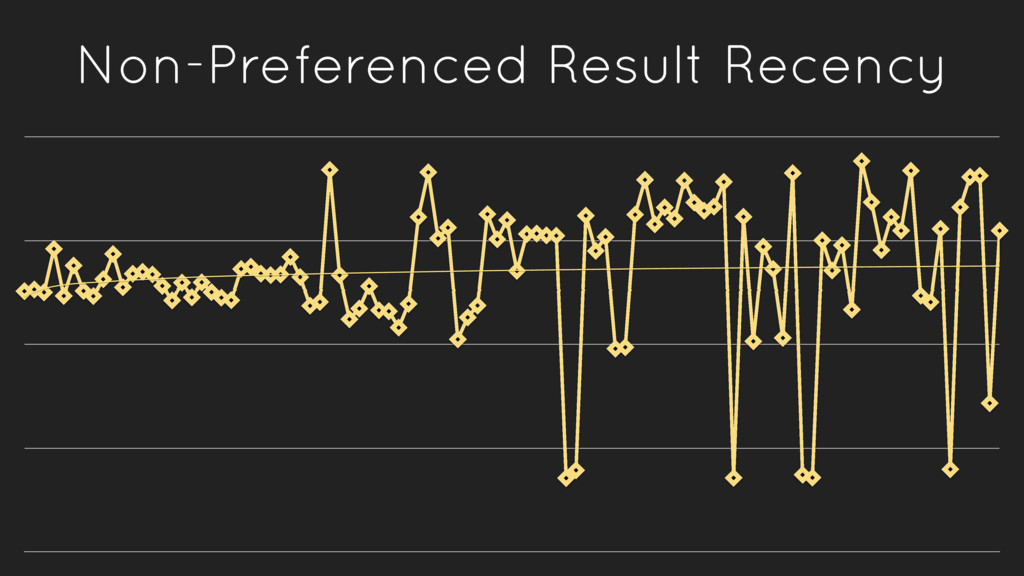
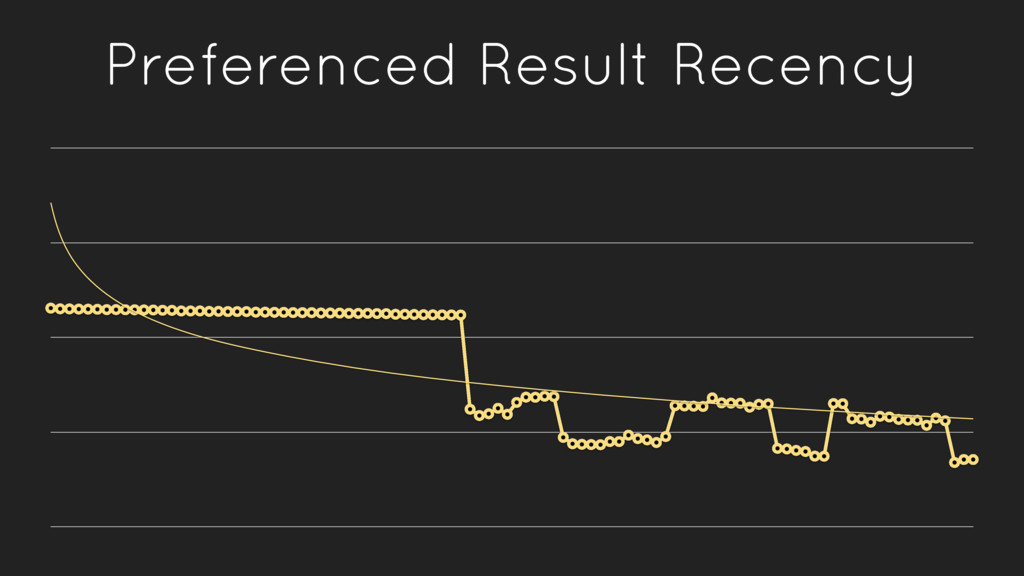
Recency-Adjusted Query { "query": { "function_score": { "functions": [ {
"gauss": { "published": { "origin": "now", "scale": "10d", "offset": "1d", "decay": 0.3 } } } ], "query": { "filtered": { "query": { "match": { "contents": "miley cyrus" } }, "filter": { "and": [ { "terms": { "site_id": [ 698 ] } } ] } } } } } } -
Importing Energy Data curl -X PUT "http://localhost:9200/energy_use" --data-binary "@queries/ mapping_energy.json"
curl -X PUT "http://localhost:9200/_bulk" --data-binary "@queries/ bulk_insert_energy_data.json" curl -X GET "http://localhost:9200/energy_use/_search" -
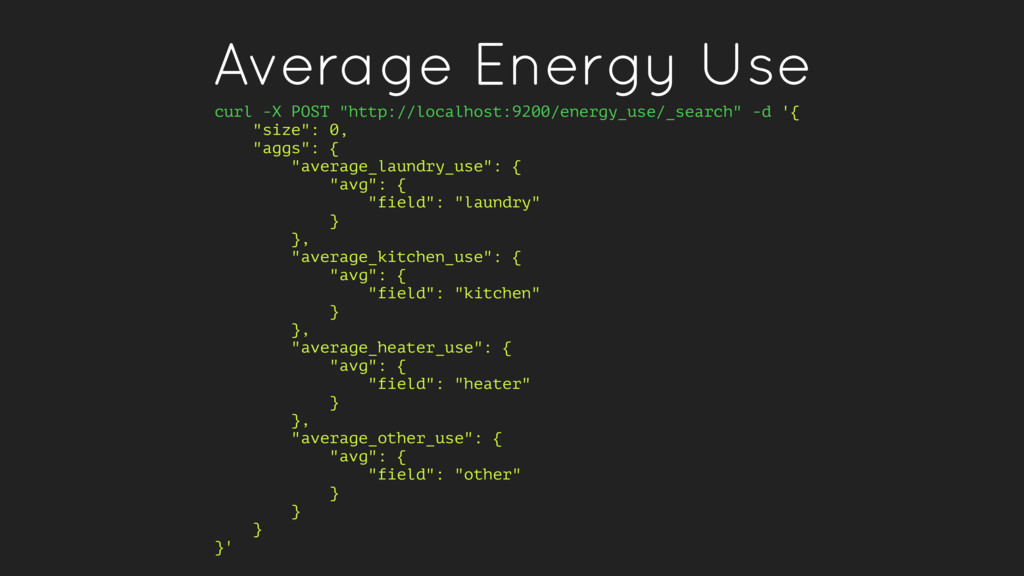
Average Energy Use curl -X POST "http://localhost:9200/energy_use/_search" -d '{ "size":
0, "aggs": { "average_laundry_use": { "avg": { "field": "laundry" } }, "average_kitchen_use": { "avg": { "field": "kitchen" } }, "average_heater_use": { "avg": { "field": "heater" } }, "average_other_use": { "avg": { "field": "other" } } } }' -
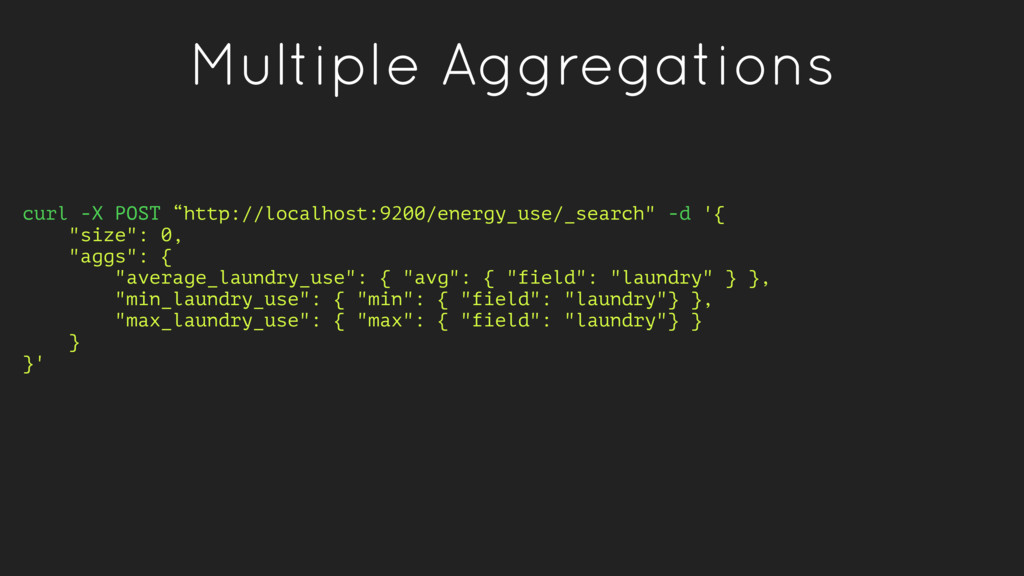
Multiple Aggregations curl -X POST “http://localhost:9200/energy_use/_search" -d '{ "size": 0,
"aggs": { "average_laundry_use": { "avg": { "field": "laundry" } }, "min_laundry_use": { "min": { "field": "laundry"} }, "max_laundry_use": { "max": { "field": "laundry"} } } }' -
Nesting Aggregations curl -X POST “http://localhost:9200/energy_use/_search" -d '{ "size": 0,
"aggs": { "by_date": { "terms": { "field": "date" }, "aggs": { "average_laundry_use": { "avg": { "field": "laundry" } }, "min_laundry_use": { "min": { "field": "laundry"} }, "max_laundry_use": { "max": { "field": "laundry"} } } } } }' -
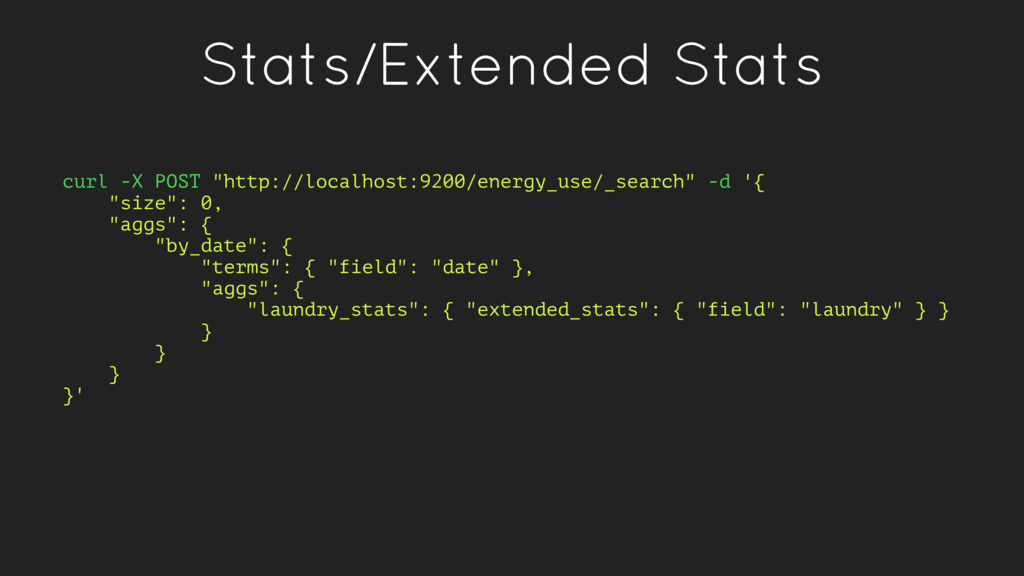
Stats/Extended Stats curl -X POST "http://localhost:9200/energy_use/_search" -d '{ "size": 0,
"aggs": { "by_date": { "terms": { "field": "date" }, "aggs": { "laundry_stats": { "extended_stats": { "field": "laundry" } } } } } }' -
Bucket Aggregations • Date Histogram • Term/Terms • Geo* •
Significant Terms
 ieatkillerbees
 wind111
 nealle
 sue445
 ren8k
 knwoop
 biwashi
 amarelo_n24
 uhyo
 oidfj
 bengo4com
 sat
 timakin
 akashhashmi
 hatefulcrawdad
 tomoyanonymous
 holman
 lara
 cassininazir
 jeffersonlam
 tammyeverts
 codingconduct
 iamctodd
 destraynor