Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Split and Rephrase: Better Evaluation and a Str...
Search
Sponsored
·
SiteGround - Reliable hosting with speed, security, and support you can count on.
→
katsutan
November 12, 2018
Technology
190
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Split and Rephrase: Better Evaluation and a Stronger Baseline
文献紹介
katsutan
November 12, 2018
More Decks by katsutan
See All by katsutan
What does BERT learn about the structure of language?
katsutan
0
280
Simple and Effective Paraphrastic Similarity from Parallel Translations
katsutan
0
240
Simple task-specific bilingual word embeddings
katsutan
0
250
Retrofitting Contextualized Word Embeddings with Paraphrases
katsutan
0
300
Character Eyes: Seeing Language through Character-Level Taggers
katsutan
1
250
Improving Word Embeddings Using Kernel PCA
katsutan
0
250
Better Word Embeddings by Disentangling Contextual n-Gram Information
katsutan
0
370
Rotational Unit of Memory: A Novel Representation Unit for RNNs with Scalable Applications
katsutan
0
310
A robust self-learning method for fully unsupervised cross-lingual mappings of word embeddings
katsutan
0
330
Other Decks in Technology
See All in Technology
AI時代、つくる力を自分たちの手に。 ──電通×KAG、アジャイルとAI駆動開発で挑む開発の変革
yuukiyo
3
420
SLOを阻む不安
sraku2159
0
100
LLMの知識とAIエージェント
happysamurai294
0
120
Adversary Infrastructure Hunting101
disconinja
0
170
ひとりで始めた AI駆動開発、チームに広げて何が変わったのか
kenichiodo
1
150
AWSセキュリティで活用するAI機能
cmusudakeisuke
1
360
ビジネス部門からPOを迎えての半年間の進歩と課題
zozotech
PRO
0
170
外国人エンジニアがVueプロトタイプで仕様を合わせている話 / Vue Fes Japan 2026 LT
eluwing
0
300
国際カードブランドルール変更に伴うクレジットカード決済取引仕様変更について
k1style
0
260
Claude Code on Bedrock で統制をかける小ネタ集/claude-code-bedrock-governance-tips
emiki
1
13k
Flutter Widget Previewerで始めるUIプレビューとVRTの自動化
sakusaku3939
0
170
Agent × Maestro で始める モバイル E2E 端末準備からテスト実行・結果確認まで
sansantech
PRO
0
230
Featured
See All Featured
Building an army of robots
kneath
307
47k
How to train your dragon (web standard)
notwaldorf
96
6.9k
VelocityConf: Rendering Performance Case Studies
addyosmani
331
25k
Agile Actions for Facilitating Distributed Teams - ADO2019
mkilby
0
320
How to Create Impact in a Changing Tech Landscape [PerfNow 2023]
tammyeverts
56
3.5k
Build The Right Thing And Hit Your Dates
maggiecrowley
39
3.5k
Bridging the Design Gap: How Collaborative Modelling removes blockers to flow between stakeholders and teams @FastFlow conf
baasie
0
740
Marketing to machines
jonoalderson
1
5.9k
Public Speaking Without Barfing On Your Shoes - THAT 2023
reverentgeek
1
650
Being A Developer After 40
akosma
PRO
92
590k
エンジニアに許された特別な時間の終わり
watany
109
250k
The AI Search Optimization Roadmap by Aleyda Solis
aleyda
2
6.4k
Transcript
Split and Rephrase: Better Evaluation and a Stronger Baseline Roee
Aharoni & Yoav Goldberg Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Short Papers), pages 719–724 Melbourne, Australia, July 15 - 20, 2018. 長岡技術科学大学 自然言語処理研究室 勝田 哲弘
Abstract Split and Rephrase • 複数の文が含まれている文から意味を保持したまま、分割と言い換えを行う 新たな分割データセット、モデルの提案 2
Introduction “Split-and-Rephrase” by Narayan et al. (2017) • データセット、評価方法、ベースラインの設定 •
BlEU ◦ 48.9 for the best text-to-text system. ◦ 78.7 for the best RDF-aware one. text-to-textモデルに注目 3
Introduction • より困難なデータセットの提案 ◦ 既存のデータセットには問題がある ◦ new split : Githubで公開
• より優れたモデルを構築 ◦ copy mechanismの拡張 4
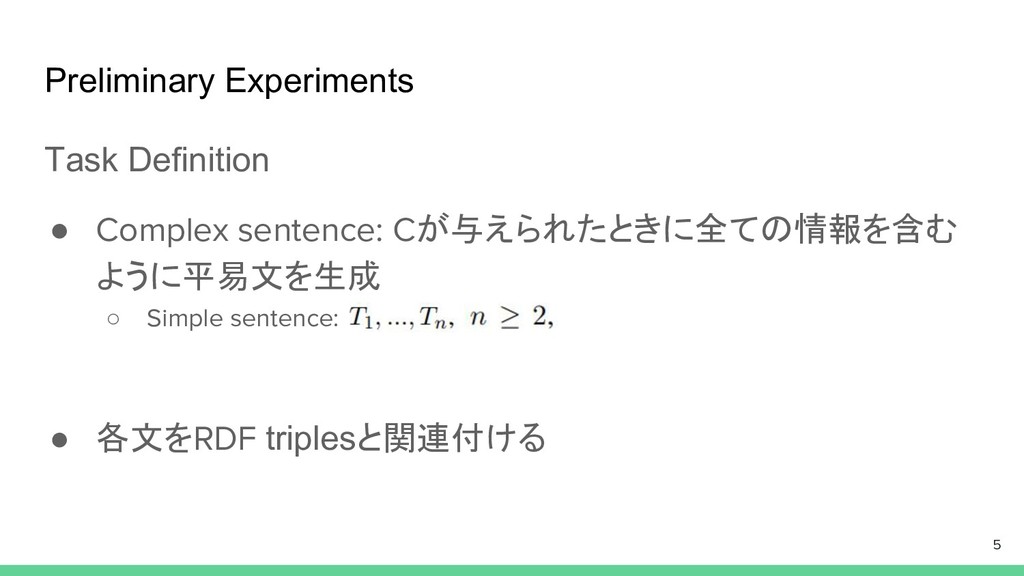
Preliminary Experiments Task Definition • Complex sentence: Cが与えられたときに全ての情報を含む ように平易文を生成 ◦
Simple sentence: • 各文をRDF triplesと関連付ける 5
Preliminary Experiments Experimental Details • vanilla sequence-to-sequence models with attention
(Bahdanau et al., 2015) ◦ OPENNMT-PY toolkit (Klein et al., 2017) ◦ LSTM cell size (128, 256 and 512, respectively) 6
Results RDFを用いるベースラインより優れている Narayan et al. (2017)のモデルは 過剰に分割を行っている 7
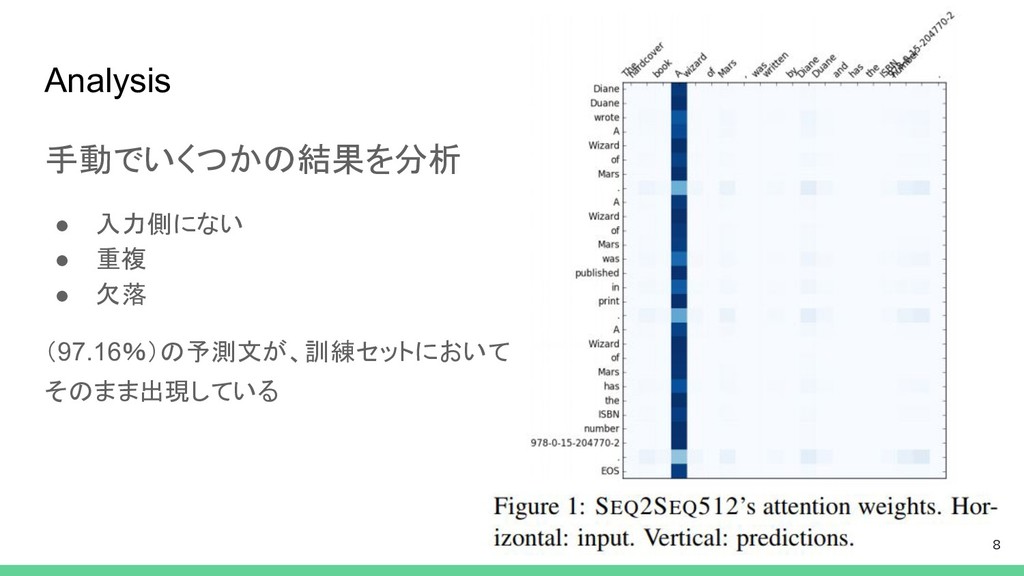
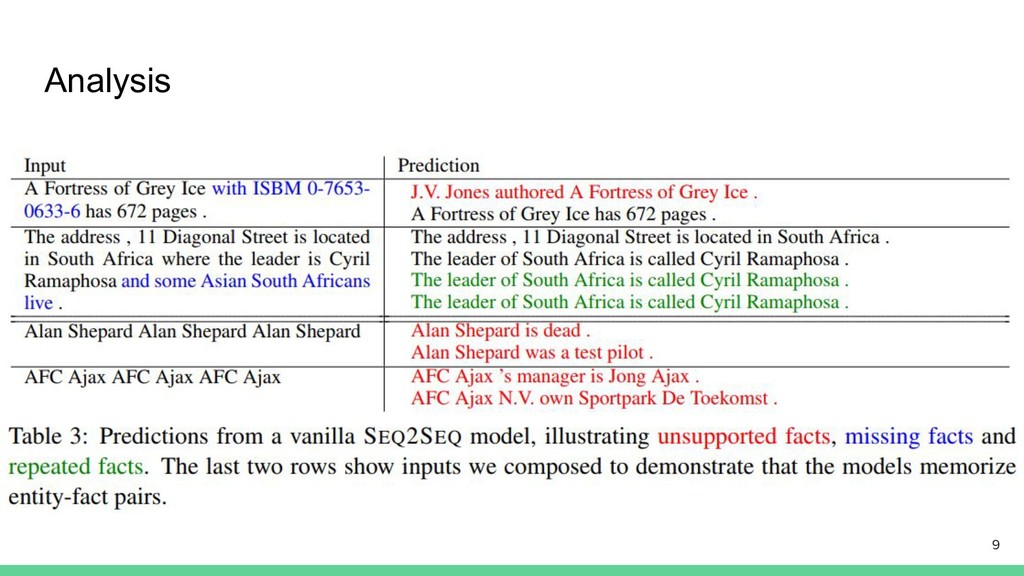
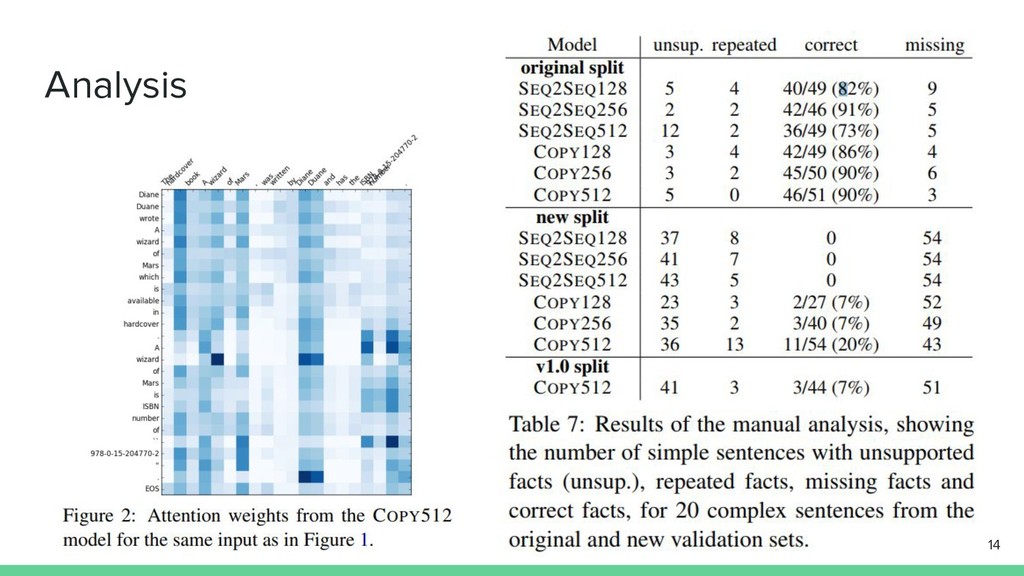
Analysis 手動でいくつかの結果を分析 • 入力側にない • 重複 • 欠落 (97.16%)の予測文が、訓練セットにおいて そのまま出現している
8
Analysis 9
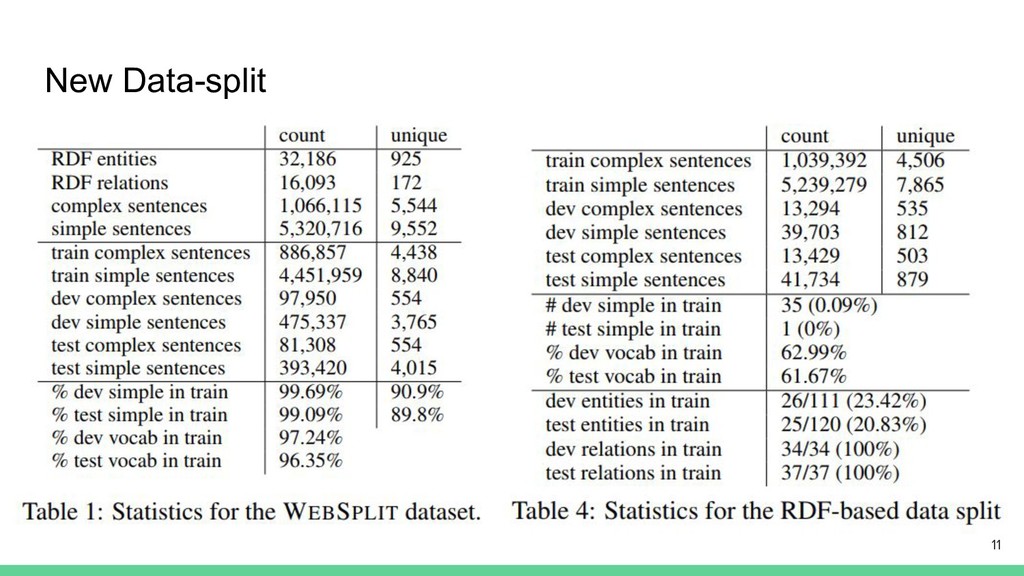
New Data-split 今のデータセットは問題を一般化するために適していない、より良 いデータセットの構築を行う RDFを使用し、以下の条件でランダムに文を分割する(5,554 sentences) • 全てのRDF relationを学習データに含める •
全てのRDF triplesは分割した1文で表現される 10
New Data-split 11
Experiments and Results 新しいデータセットによる評価 • new data split • v1.0
モデルの拡張: Copy • copy-enhanced models of varying LSTM widths ◦ (128, 256 and 512) 12
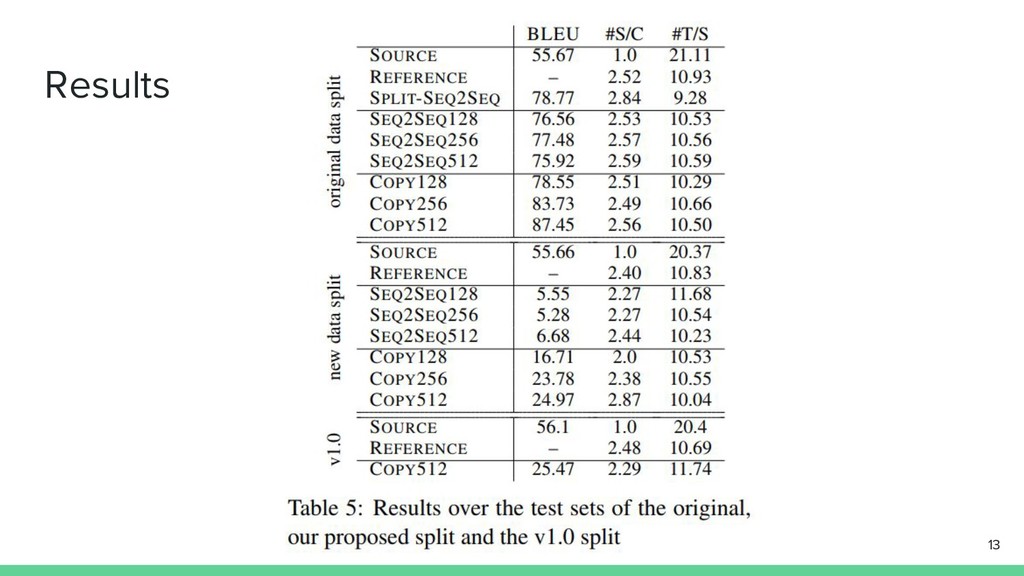
Results 13
Analysis 14
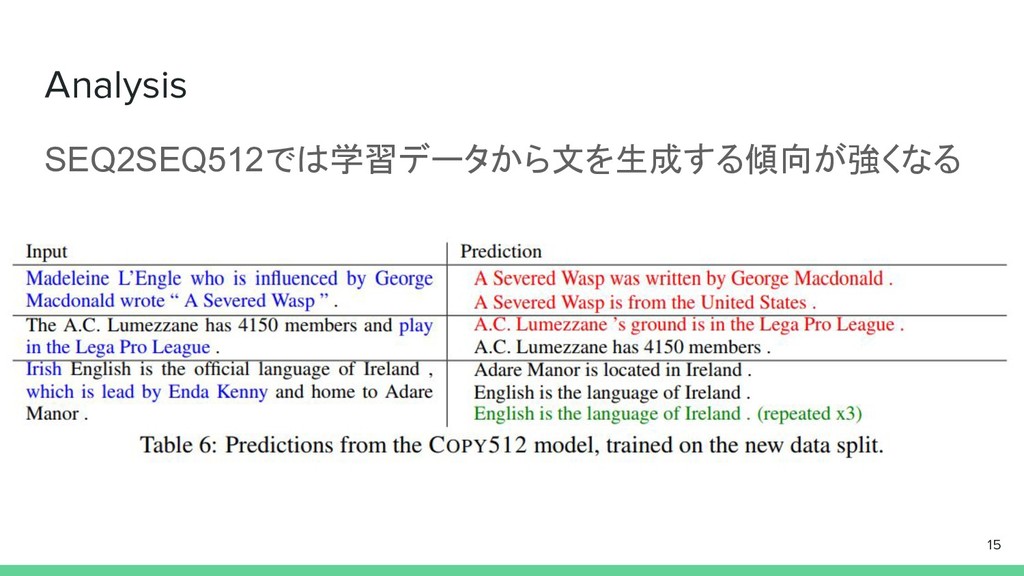
Analysis SEQ2SEQ512では学習データから文を生成する傾向が強くなる 15
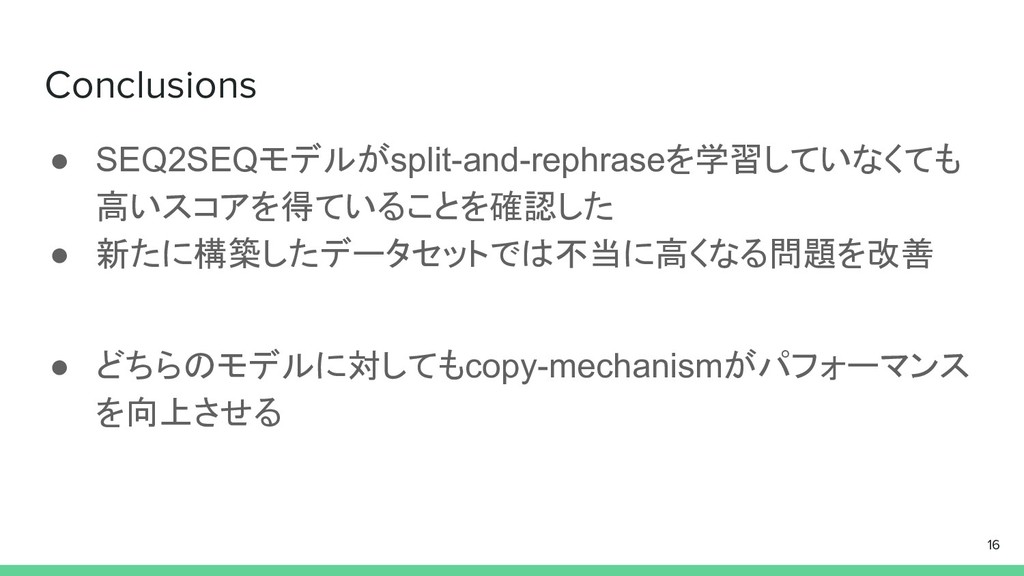
Conclusions • SEQ2SEQモデルがsplit-and-rephraseを学習していなくても 高いスコアを得ていることを確認した • 新たに構築したデータセットでは不当に高くなる問題を改善 • どちらのモデルに対してもcopy-mechanismがパフォーマンス を向上させる 16

 SiteGround - Reliable hosting with speed, security, and support you can count on.


 katsutan
 yuukiyo
 sraku2159
 happysamurai294
 disconinja
 kenichiodo
 cmusudakeisuke
 zozotech
 eluwing
 k1style
 emiki
 sakusaku3939
 sansantech
 kneath
 notwaldorf
 addyosmani
 mkilby
 tammyeverts
 maggiecrowley
 baasie
 jonoalderson
 reverentgeek
 akosma
 watany
 aleyda