Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[RSJ25] Multilingual Scene Text-Aware Multimoda...
Search
Semantic Machine Intelligence Lab., Keio Univ.
PRO
September 01, 2025
Technology
170
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[RSJ25] Multilingual Scene Text-Aware Multimodal Retrieval for Everyday Objects Based on Deep State Space Models
Semantic Machine Intelligence Lab., Keio Univ.
PRO
September 01, 2025
More Decks by Semantic Machine Intelligence Lab., Keio Univ.
See All by Semantic Machine Intelligence Lab., Keio Univ.
[EMNLP26] RIGEL: Self-Distilled Score Adaptation for Image and Video Captioning Evaluation
keio_smilab
PRO
0
59
[RSJ26] Building a VLA Model Based on Self-Distilled Classification
keio_smilab
PRO
0
210
[RSJ26] AnoleVLA: Lightweight Vision-Language-Action Model with Deep State Space Models for Mobile Manipulation
keio_smilab
PRO
0
180
[RSJ26] NarrativeFlow: Flow-Based Vision-Language-Action Model Using Robot Velocity Fields
keio_smilab
PRO
0
250
[RSJ26] Flow as Flow: Modeling Robot Velocity Fields as Probability Velocity Fields
keio_smilab
PRO
1
240
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Augmented Generation for Embodied Question Answering
keio_smilab
PRO
1
200
[MIRU26] Open-Vocabulary Intention-Guided Object Detection in Diverse Scenes
keio_smilab
PRO
0
250
[Journal club] Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
keio_smilab
PRO
0
73
[MIRU26] To What Extent Does MLLM-as-a-Judge Exhibit Cross-Model Preference Bias?
keio_smilab
PRO
0
330
Other Decks in Technology
See All in Technology
Optunaの最新リリースv5.0について
pfn
PRO
0
120
実体験から学ぶ分析エージェントの開発と運⽤
recruitengineers
PRO
8
2.4k
CTO Night|NotionのAIエージェントとFDE
kzkhykw1991
0
210
触りたくないデータに、どう触るか AI時代のRBACアクセスガバナンス
ivry_presentationmaterials
0
270
JAWS-UGグッズ職人仕事の流儀
kentapapa
0
120
OptunaHub: ブラックボックス最適化のためのプラットフォーム
pfn
PRO
0
140
M5Stackで作る BLEマウス GPSログの世界
tomokusaba
PRO
0
430
Persisting Massive Data with Rails ~Designing for 60 billion rows, and fighting the bottlenecks~ Railsで挑む大量データ永続化 〜600億件を永続化するための設計とボトルネックとの戦い〜
occhi
0
730
TinyGoでオブザーバビリティ?OpenTelemetryはTinyGoで使えるのか / Is OpenTelemetry available in TinyGo environment?
ymotongpoo
2
140
継続的なAIコスト最適化
bgpat
1
350
フロントエンドカンファレンス関西2026 - 速すぎるUIに、待ち時間を
teamlab
PRO
0
180
Tofu-Controller lightning talk @ Containerday 2026
gionn
0
120
Featured
See All Featured
Documentation Writing (for coders)
carmenintech
77
5.6k
The Limits of Empathy - UXLibs8
cassininazir
2
720
I Don’t Have Time: Getting Over the Fear to Launch Your Podcast
jcasabona
35
2.9k
Designing Powerful Visuals for Engaging Learning
tmiket
1
610
The Spectacular Lies of Maps
axbom
PRO
1
1.1k
jQuery: Nuts, Bolts and Bling
dougneiner
66
8.6k
Optimizing for Happiness
mojombo
378
71k
Bridging the Design Gap: How Collaborative Modelling removes blockers to flow between stakeholders and teams @FastFlow conf
baasie
0
730
Side Projects
sachag
456
43k
Test your architecture with Archunit
thirion
2
2.4k
Utilizing Notion as your number one productivity tool
mfonobong
4
620
WCS-LA-2024
lcolladotor
0
890
Transcript
慶應義塾大学 西牧宙輝,八島大地,戸倉健登,杉浦孔明 多言語シーンテキストを考慮した 深層状態空間モデルに基づく実世界検索エンジン
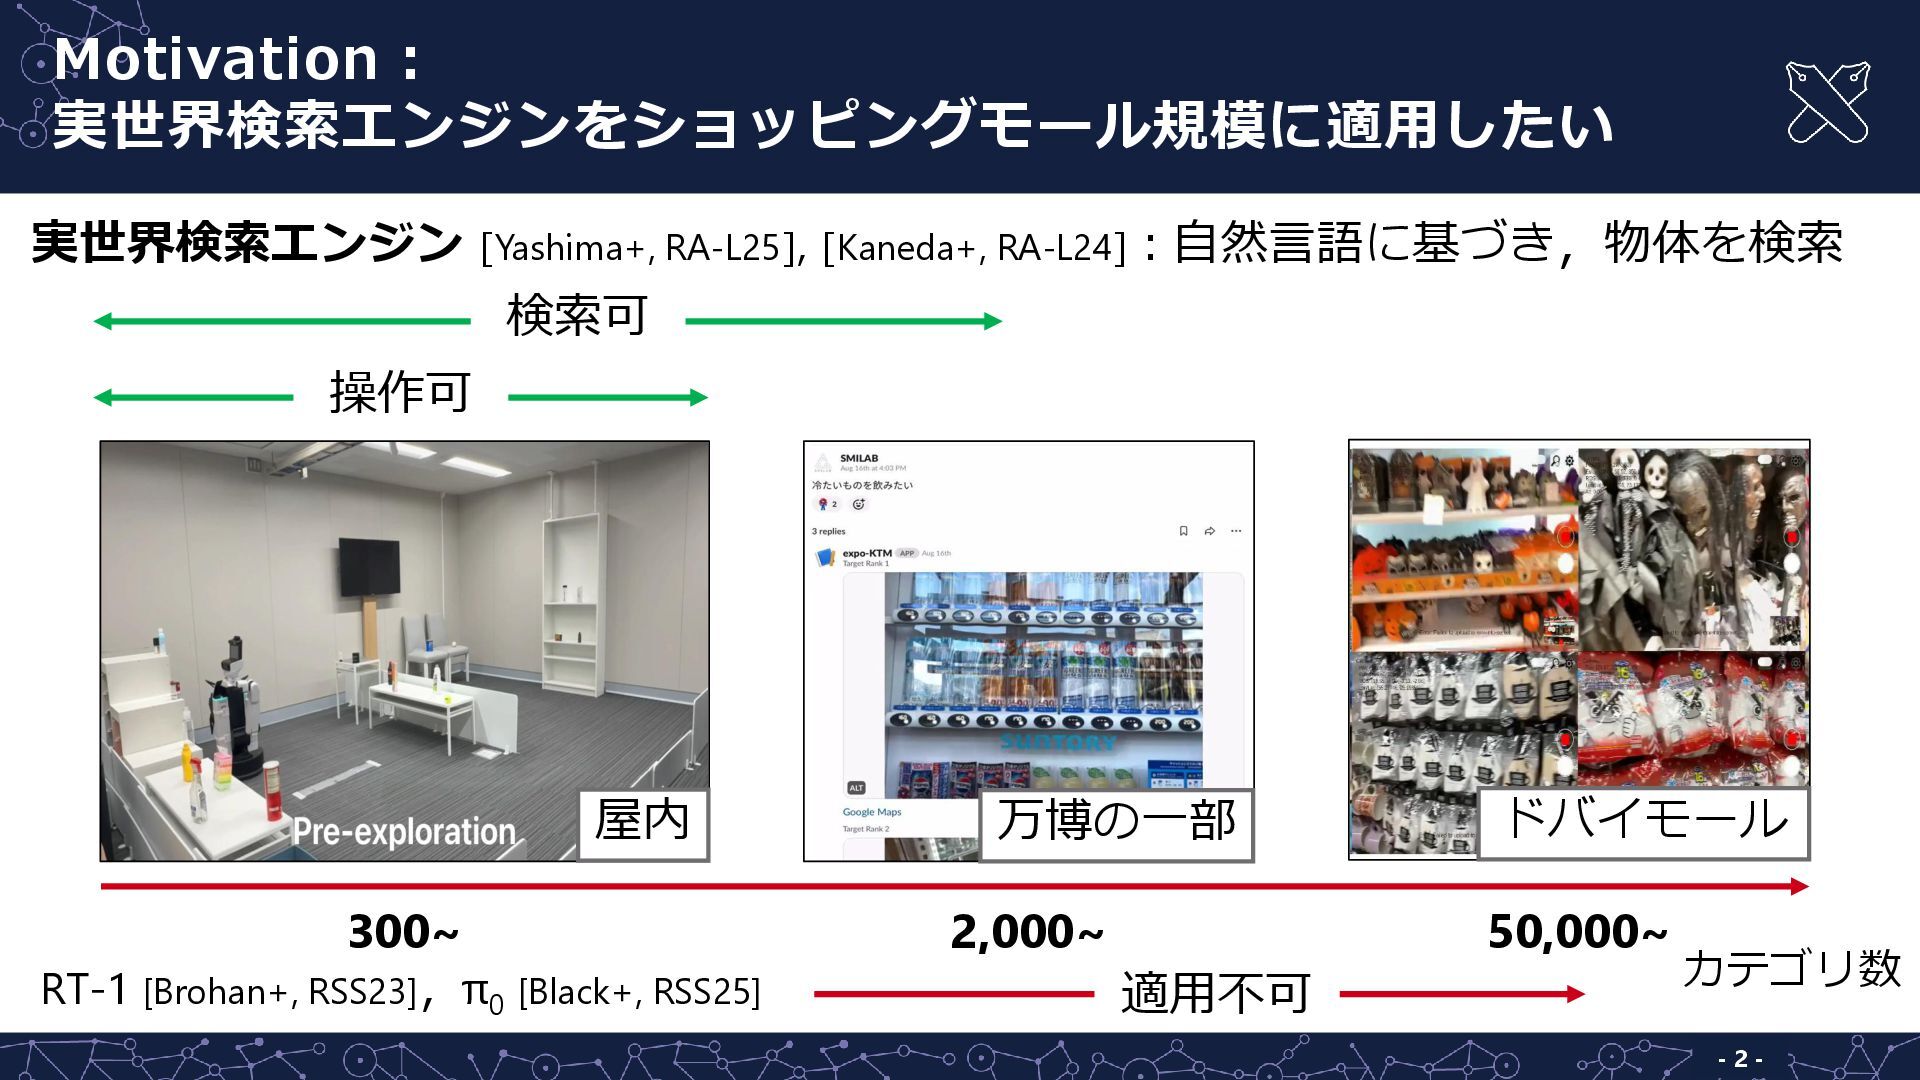
Motivation: 実世界検索エンジンをショッピングモール規模に適用したい - 2 - 実世界検索エンジン [Yashima+, RA-L25], [Kaneda+, RA-L24]:自然言語に基づき,物体を検索
屋内 ドバイモール 万博の一部 カテゴリ数 RT-1 [Brohan+, RSS23],π0 [Black+, RSS25] 300~ 2,000~ 50,000~ 検索可 操作可 適用不可
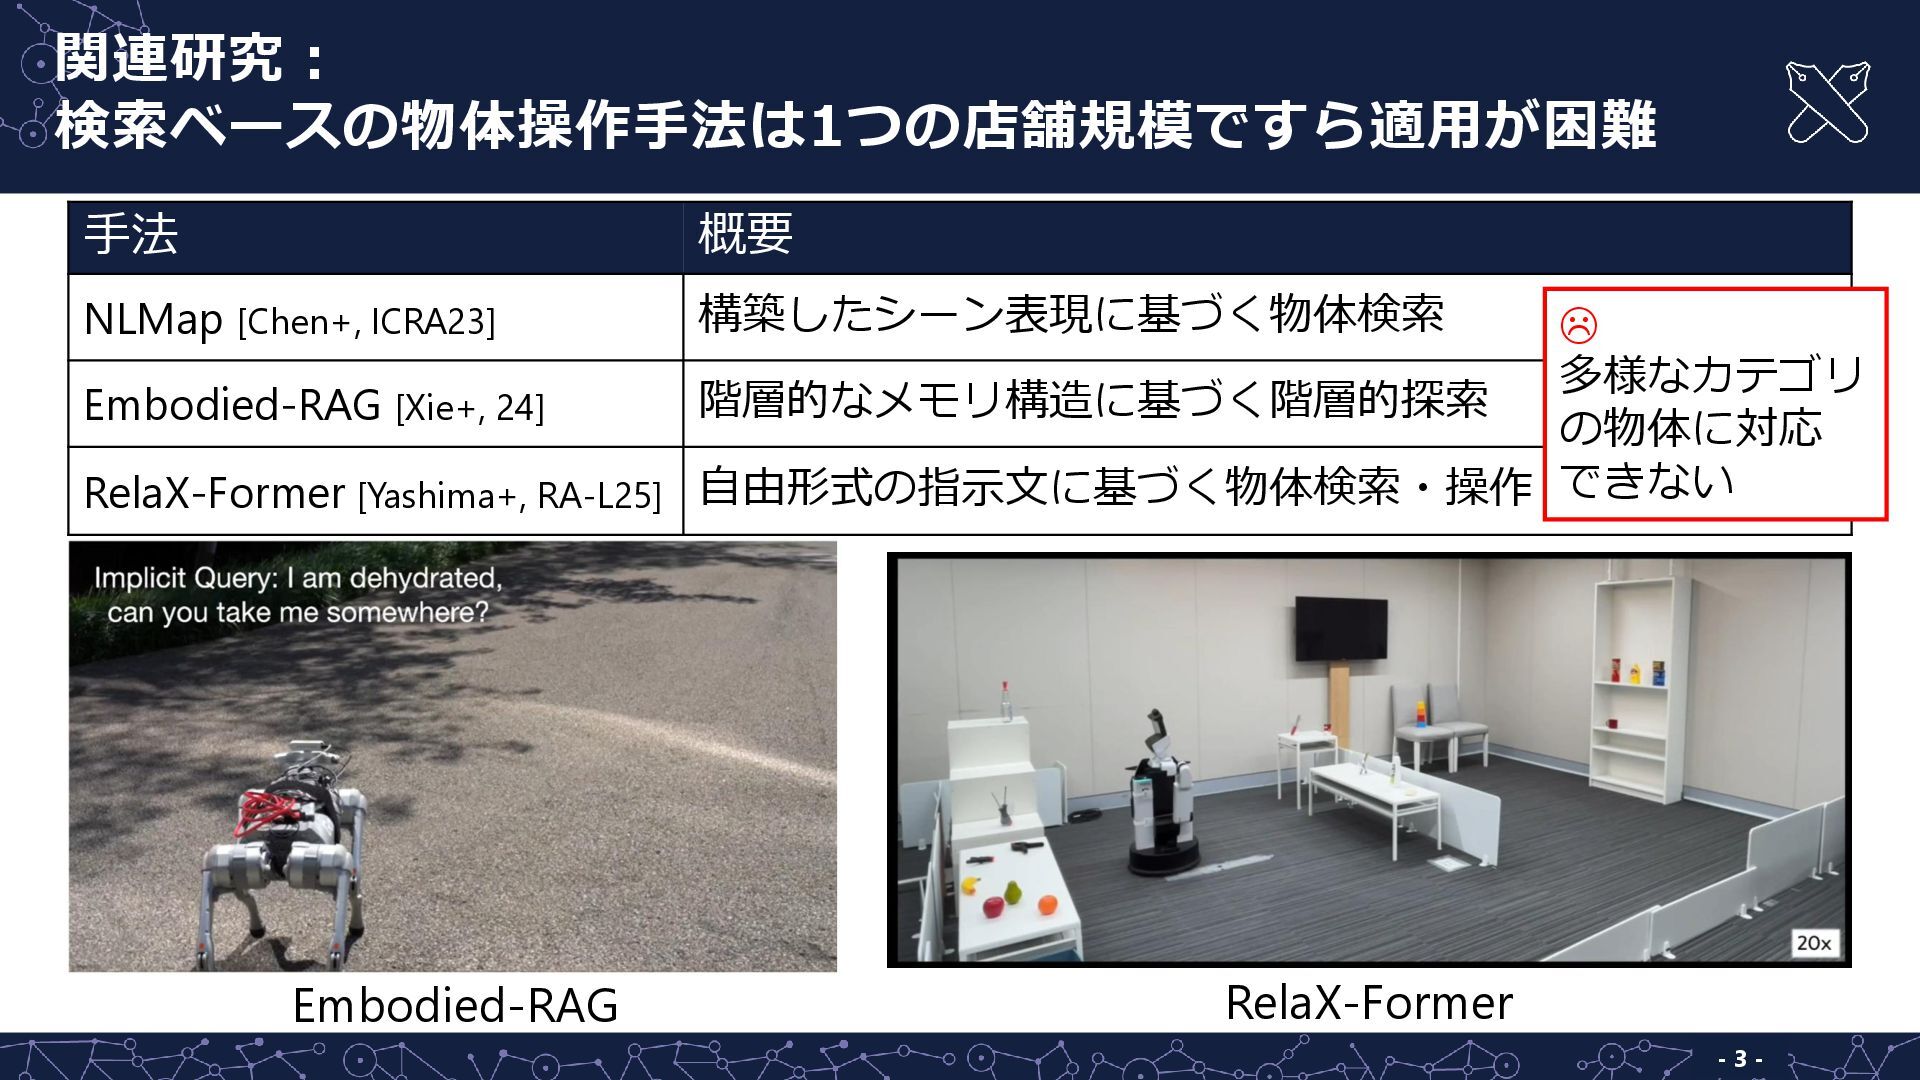
手法 概要 NLMap [Chen+, ICRA23] 構築したシーン表現に基づく物体検索 Embodied-RAG [Xie+, 24] 階層的なメモリ構造に基づく階層的探索
RelaX-Former [Yashima+, RA-L25] 自由形式の指示文に基づく物体検索・操作 関連研究: 検索ベースの物体操作手法は1つの店舗規模ですら適用が困難 - 3 - RelaX-Former Embodied-RAG 多様なカテゴリ の物体に対応 できない
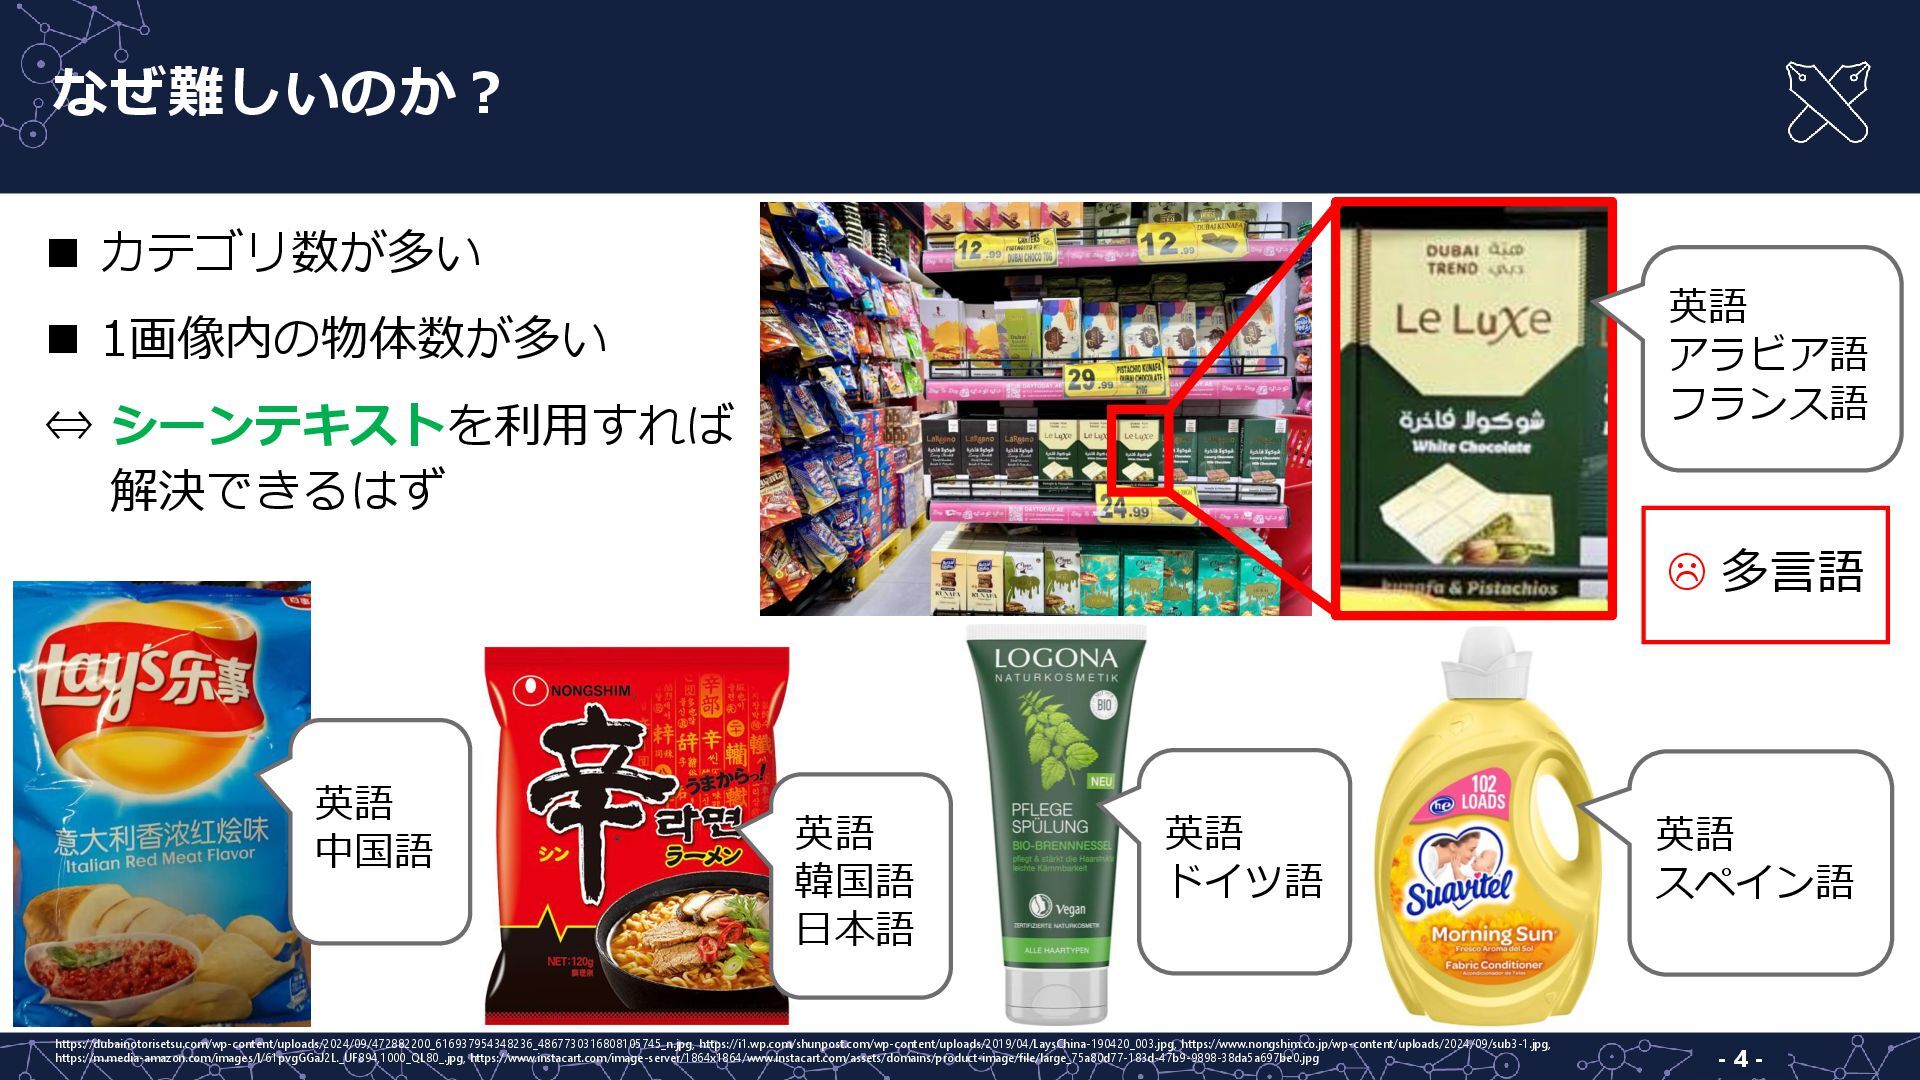
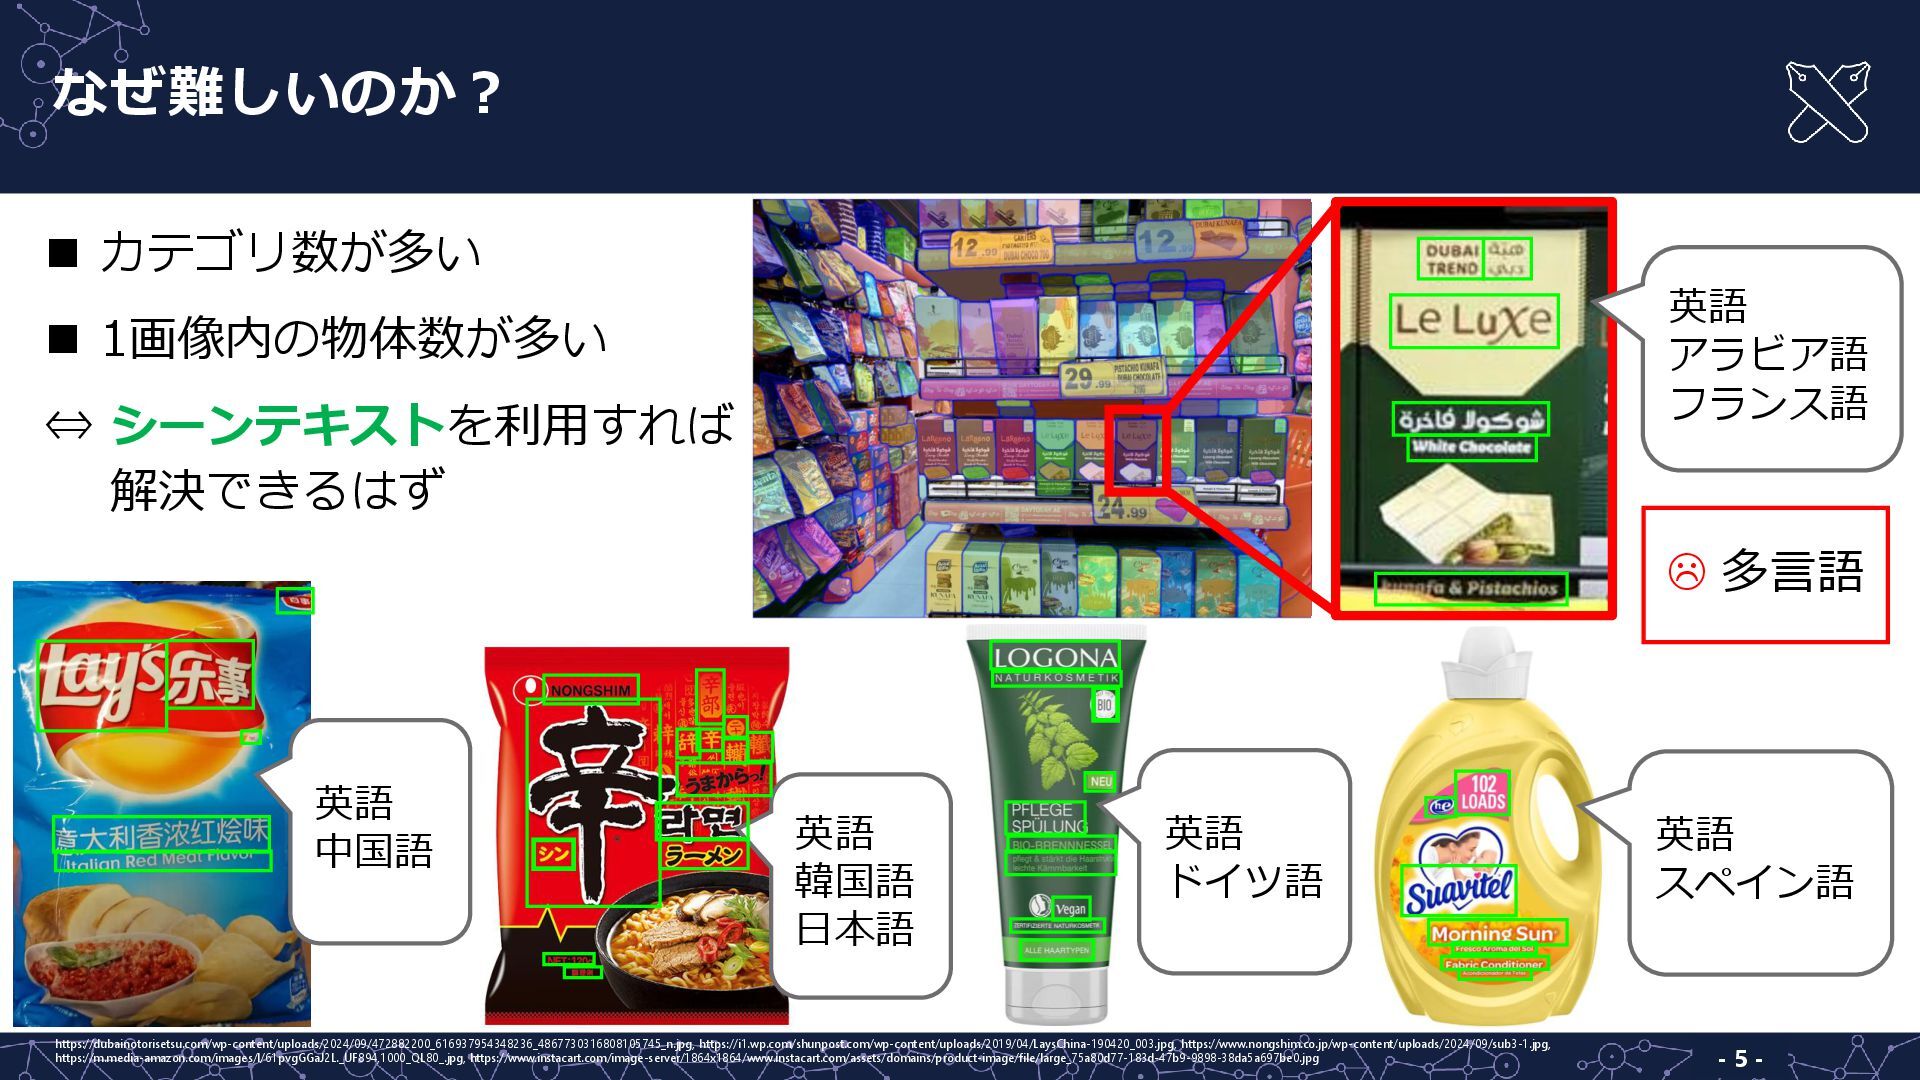
なぜ難しいのか? - 4 - ◼ カテゴリ数が多い ◼ 1画像内の物体数が多い ⇔ シーンテキストを利用すれば
解決できるはず 英語 アラビア語 フランス語 https://dubainotorisetsu.com/wp-content/uploads/2024/09/472882200_616937954348236_4867730316808105745_n.jpg, https://i1.wp.com/shunpost.com/wp-content/uploads/2019/04/LaysChina-190420_003.jpg, https://www.nongshim.co.jp/wp-content/uploads/2024/09/sub3-1.jpg, https://m.media-amazon.com/images/I/61pvgGGaJ2L._UF894,1000_QL80_.jpg, https://www.instacart.com/image-server/1864x1864/www.instacart.com/assets/domains/product-image/file/large_75a80d77-183d-47b9-9898-38da5a697be0.jpg 英語 中国語 英語 韓国語 日本語 英語 スペイン語 英語 ドイツ語 多言語
なぜ難しいのか? - 5 - ◼ カテゴリ数が多い ◼ 1画像内の物体数が多い ⇔ シーンテキストを利用すれば
解決できるはず 英語 アラビア語 フランス語 https://dubainotorisetsu.com/wp-content/uploads/2024/09/472882200_616937954348236_4867730316808105745_n.jpg, https://i1.wp.com/shunpost.com/wp-content/uploads/2019/04/LaysChina-190420_003.jpg, https://www.nongshim.co.jp/wp-content/uploads/2024/09/sub3-1.jpg, https://m.media-amazon.com/images/I/61pvgGGaJ2L._UF894,1000_QL80_.jpg, https://www.instacart.com/image-server/1864x1864/www.instacart.com/assets/domains/product-image/file/large_75a80d77-183d-47b9-9898-38da5a697be0.jpg 英語 中国語 英語 韓国語 日本語 英語 スペイン語 英語 ドイツ語 多言語
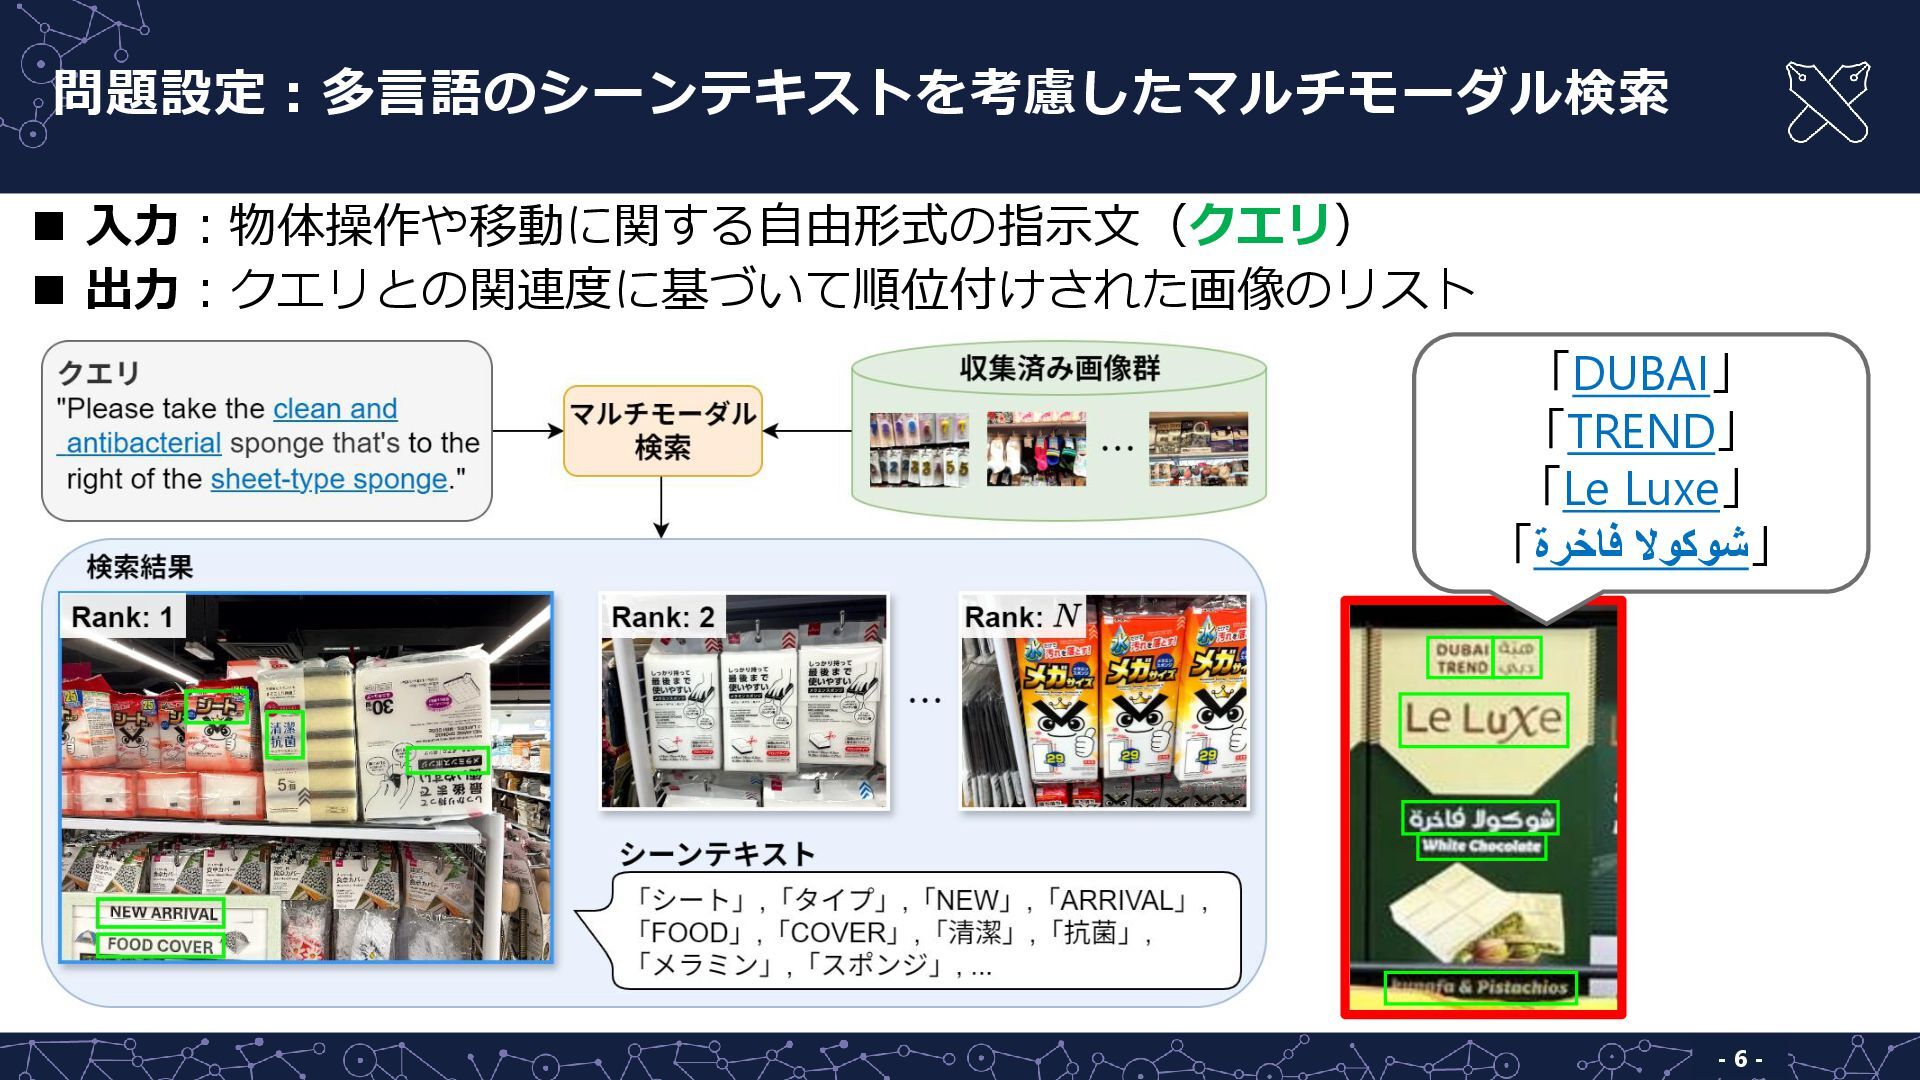
問題設定:多言語のシーンテキストを考慮したマルチモーダル検索 - 6 - ◼ 入力:物体操作や移動に関する自由形式の指示文(クエリ) ◼ 出力:クエリとの関連度に基づいて順位付けされた画像のリスト 「DUBAI」 「TREND」
「Le Luxe」 「ةرخاف الوكوش」
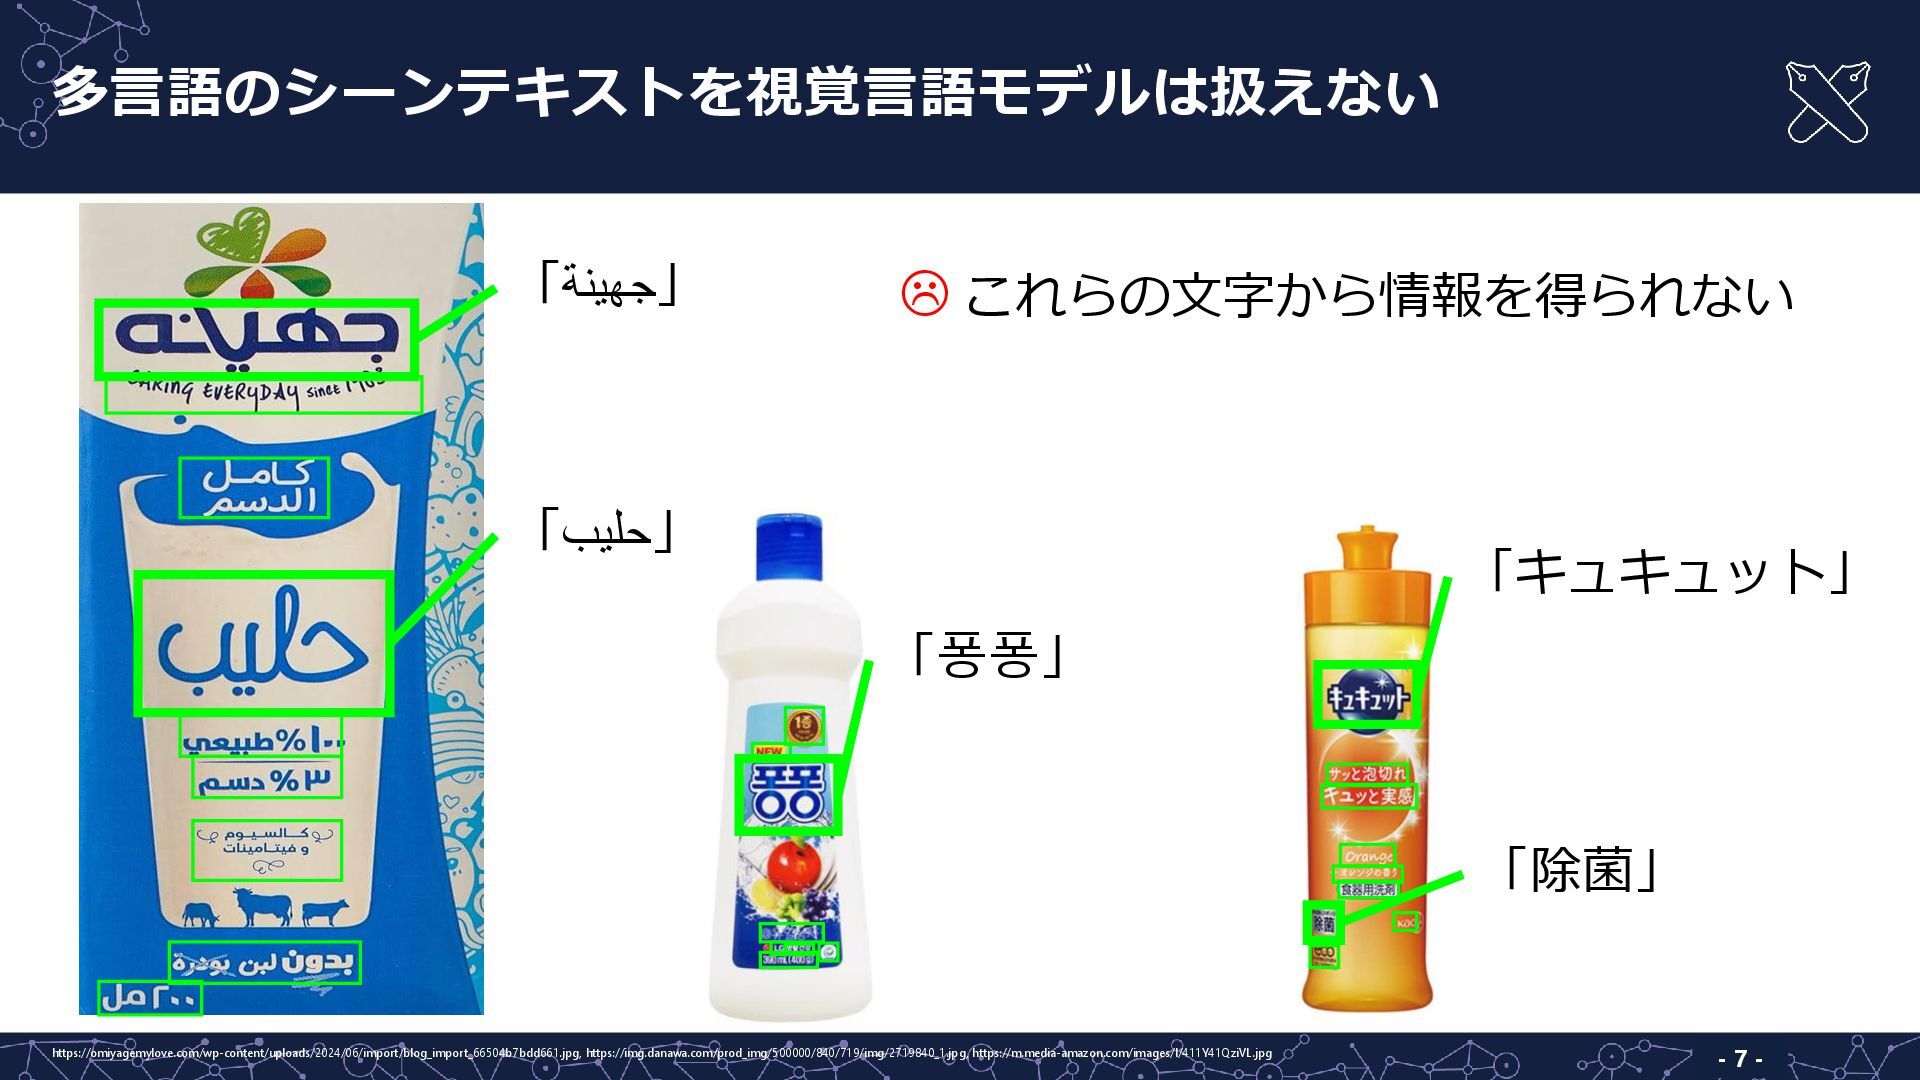
- 7 - 多言語のシーンテキストを視覚言語モデルは扱えない 「ةنيهج」 「بيلح」 https://omiyagemylove.com/wp-content/uploads/2024/06/import/blog_import_66504b7bdd661.jpg, https://img.danawa.com/prod_img/500000/840/719/img/2719840_1.jpg, https://m.media-amazon.com/images/I/411Y41QziVL.jpg
これらの文字から情報を得られない 「퐁퐁」 「キュキュット」 「除菌」
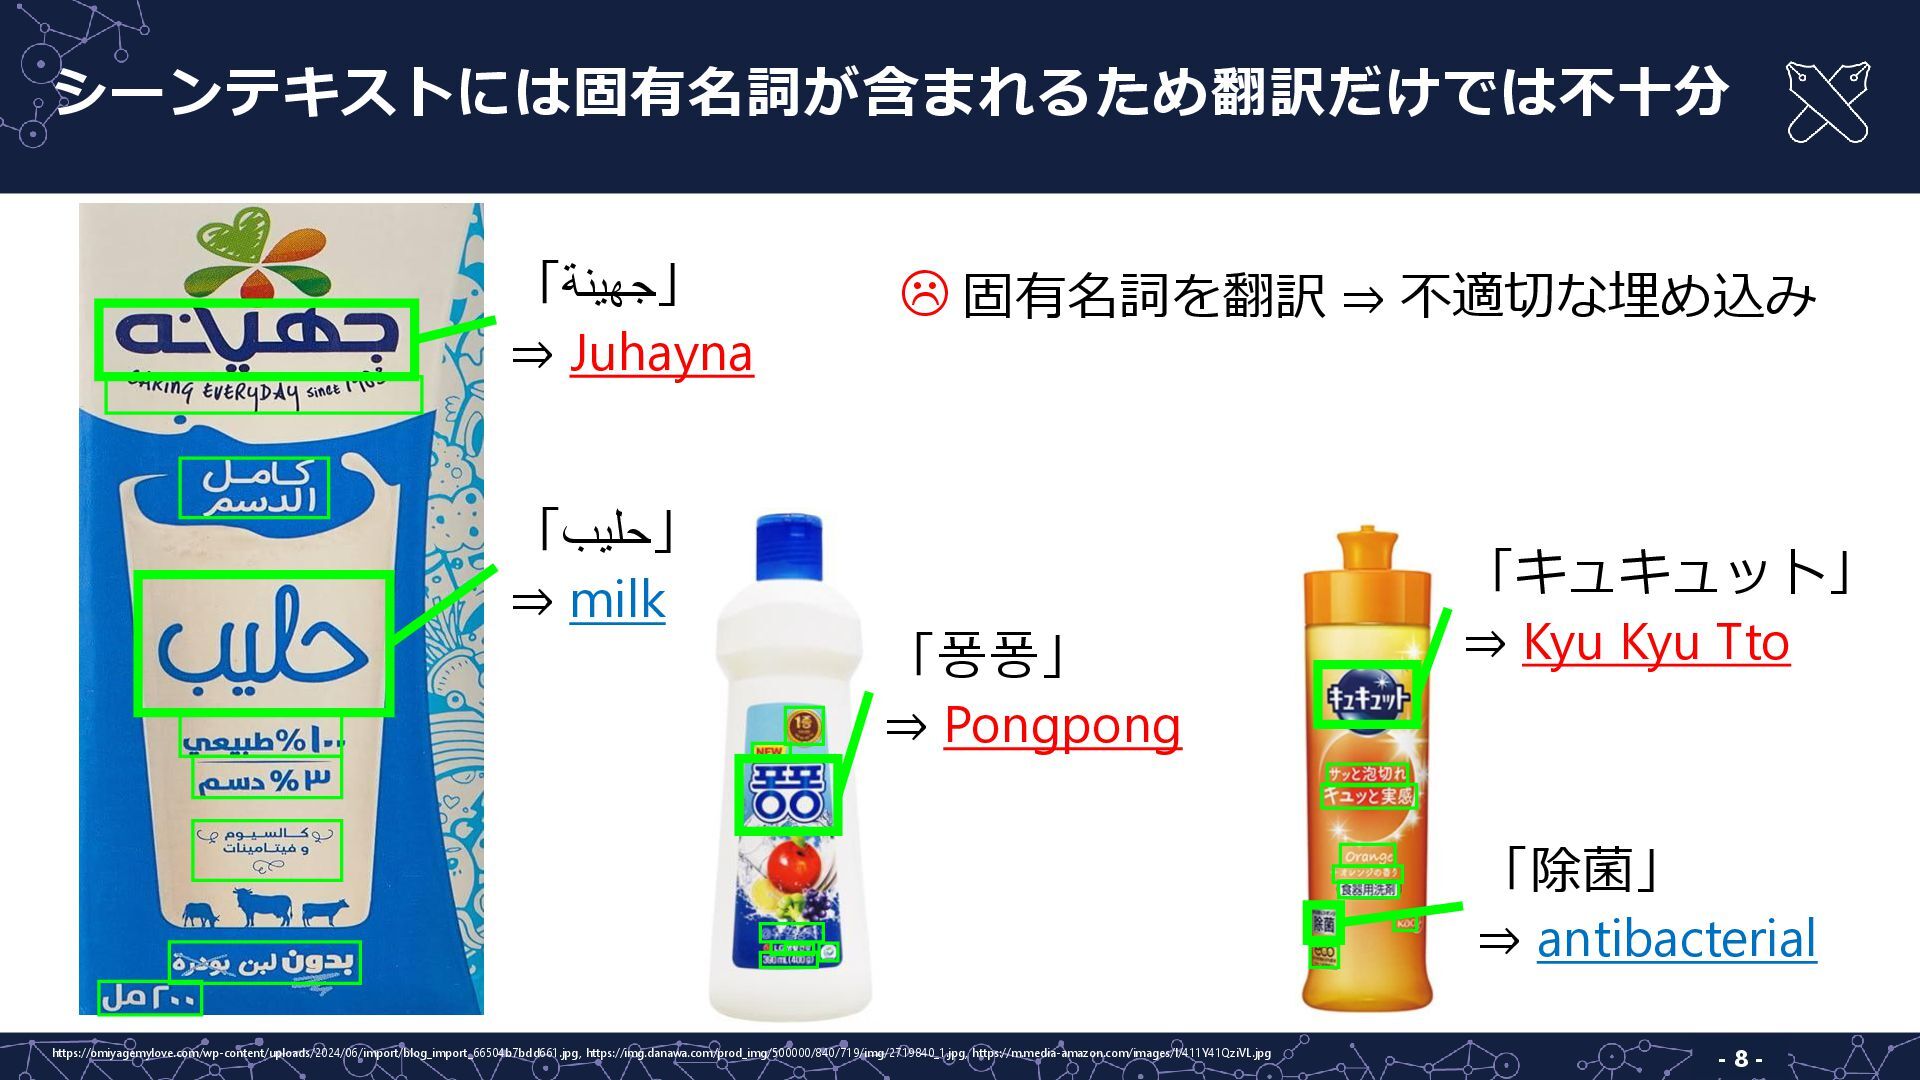
- 8 - シーンテキストには固有名詞が含まれるため翻訳だけでは不十分 「ةنيهج」 ⇒ Juhayna 「بيلح」 ⇒ milk
https://omiyagemylove.com/wp-content/uploads/2024/06/import/blog_import_66504b7bdd661.jpg, https://img.danawa.com/prod_img/500000/840/719/img/2719840_1.jpg, https://m.media-amazon.com/images/I/411Y41QziVL.jpg 固有名詞を翻訳 ⇒ 不適切な埋め込み 「퐁퐁」 ⇒ Pongpong 「キュキュット」 ⇒ Kyu Kyu Tto 「除菌」 ⇒ antibacterial
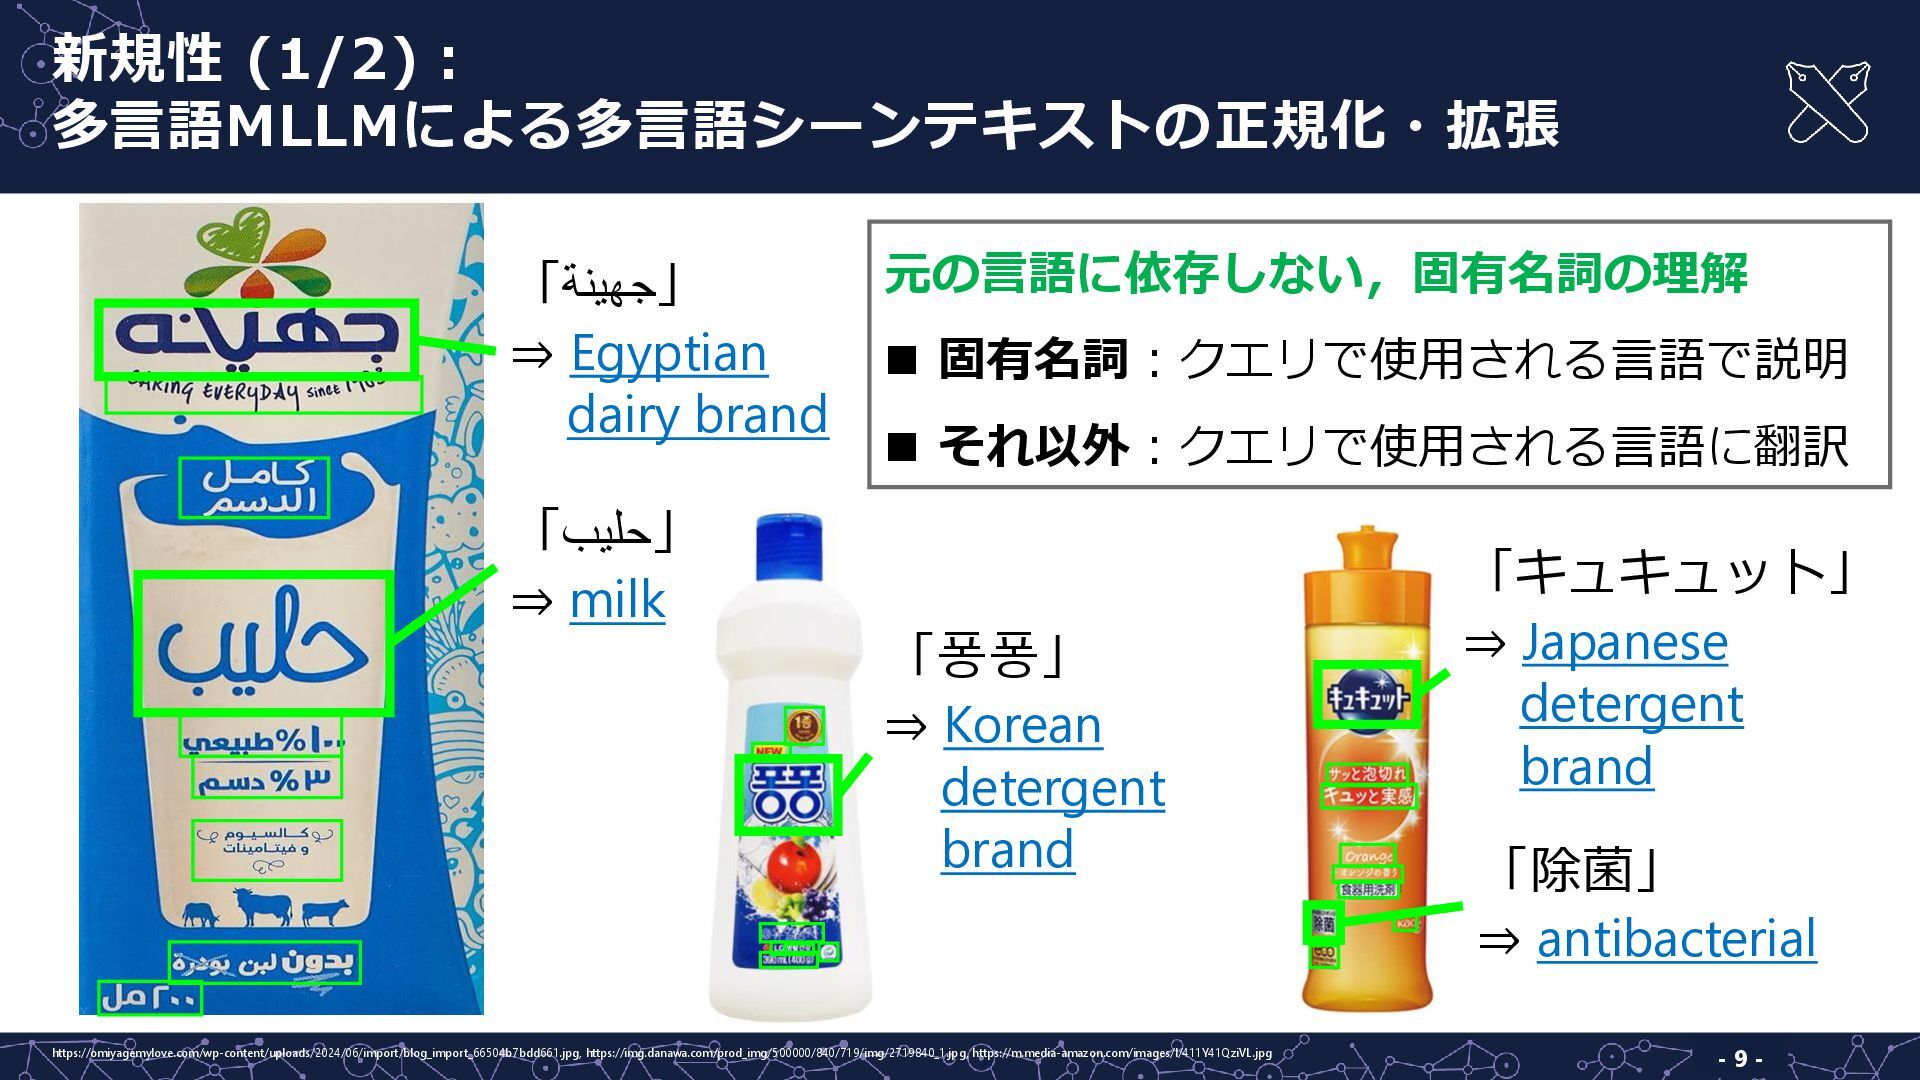
- 9 - 新規性 (1/2): 多言語MLLMによる多言語シーンテキストの正規化・拡張 「ةنيهج」 ⇒ Egyptian dairy
brand 「بيلح」 ⇒ milk https://omiyagemylove.com/wp-content/uploads/2024/06/import/blog_import_66504b7bdd661.jpg, https://img.danawa.com/prod_img/500000/840/719/img/2719840_1.jpg, https://m.media-amazon.com/images/I/411Y41QziVL.jpg 「퐁퐁」 ⇒ Korean detergent brand 「キュキュット」 ⇒ Japanese detergent brand 「除菌」 ⇒ antibacterial 元の言語に依存しない,固有名詞の理解 ◼ 固有名詞:クエリで使用される言語で説明 ◼ それ以外:クエリで使用される言語に翻訳
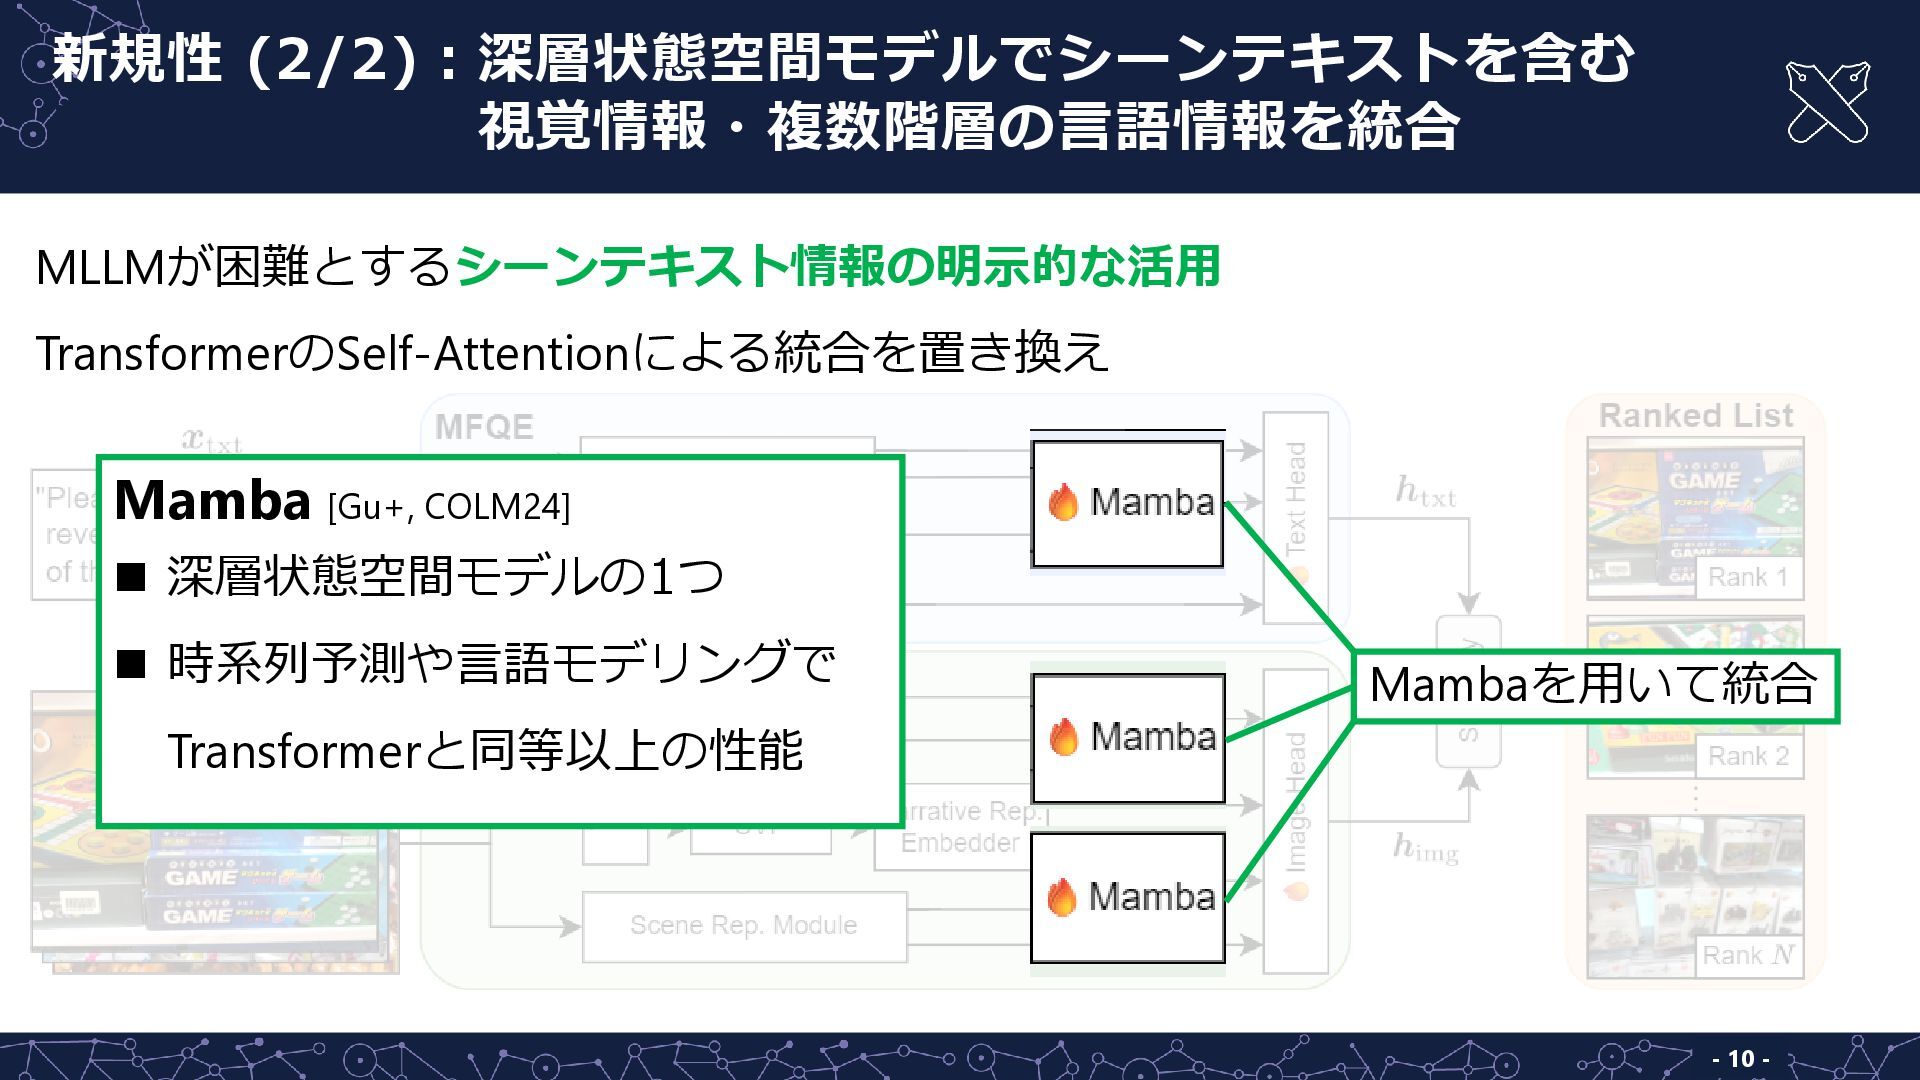
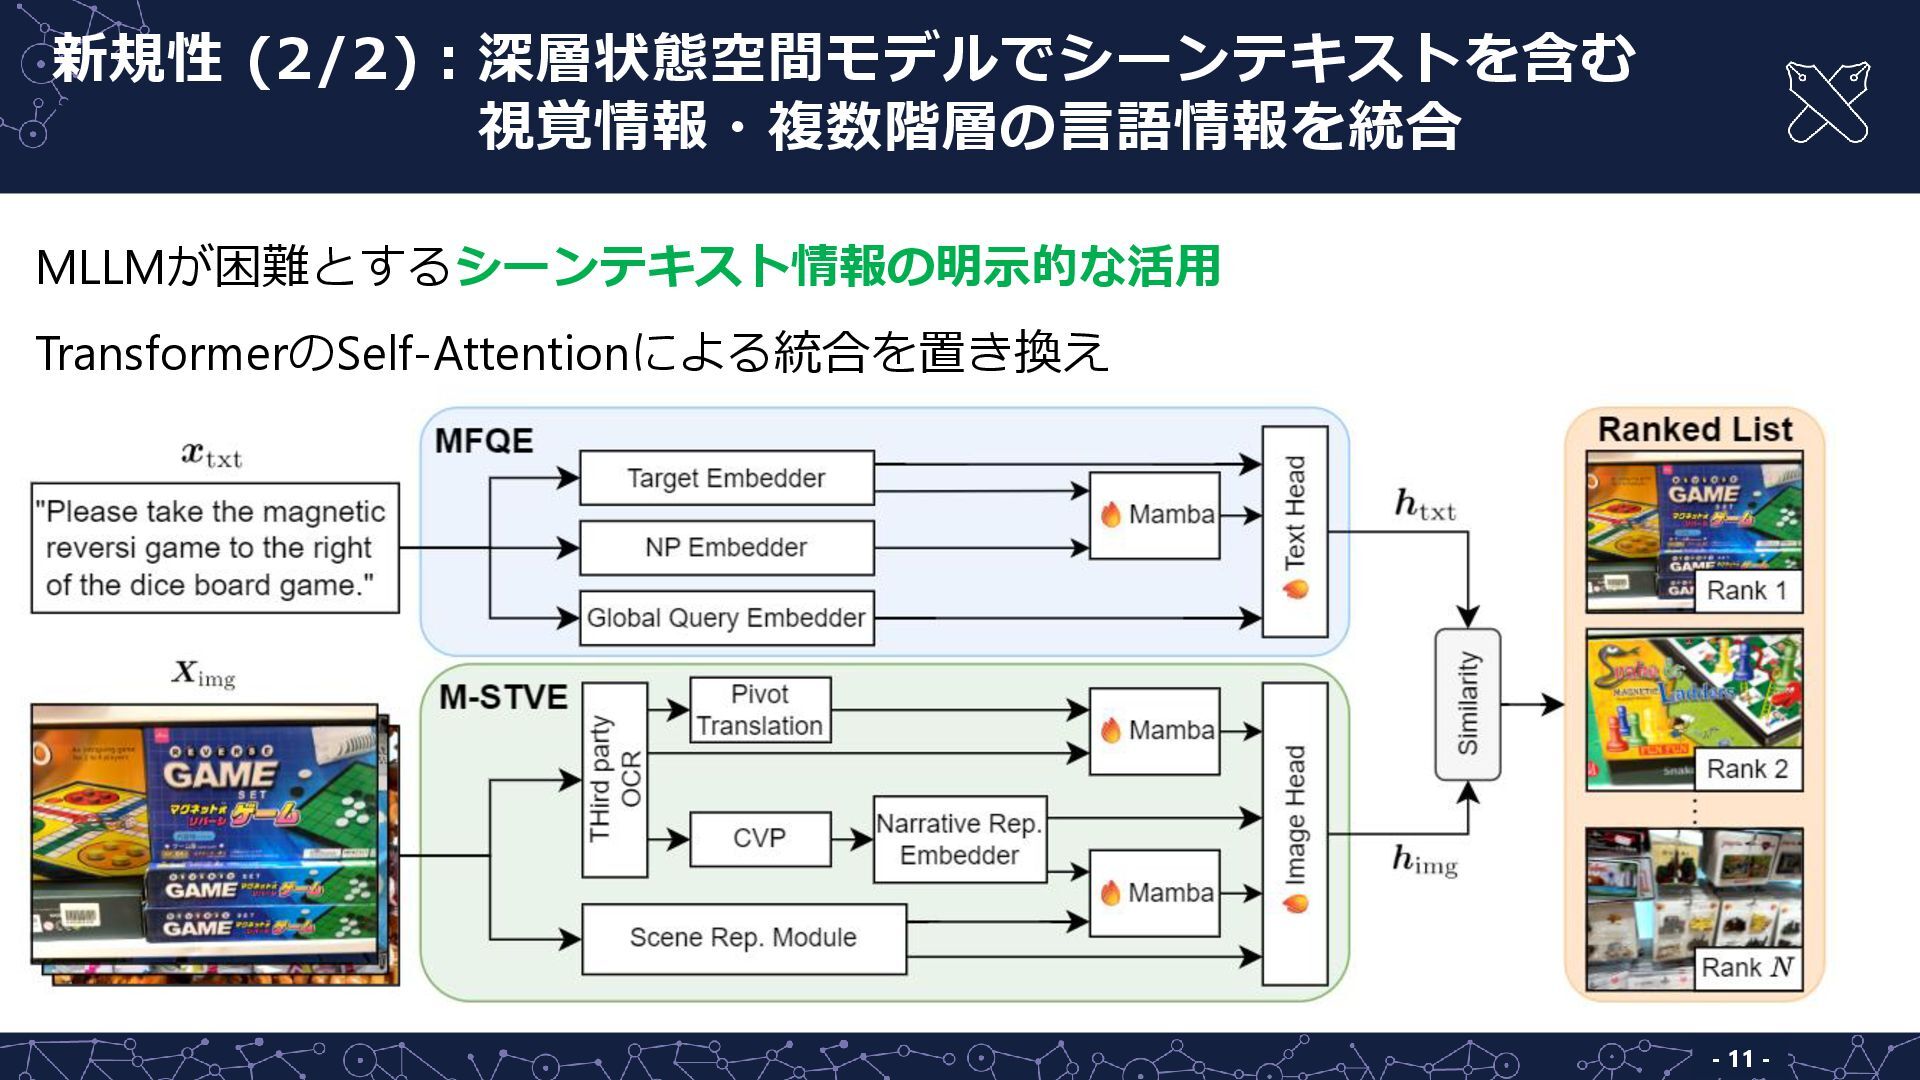
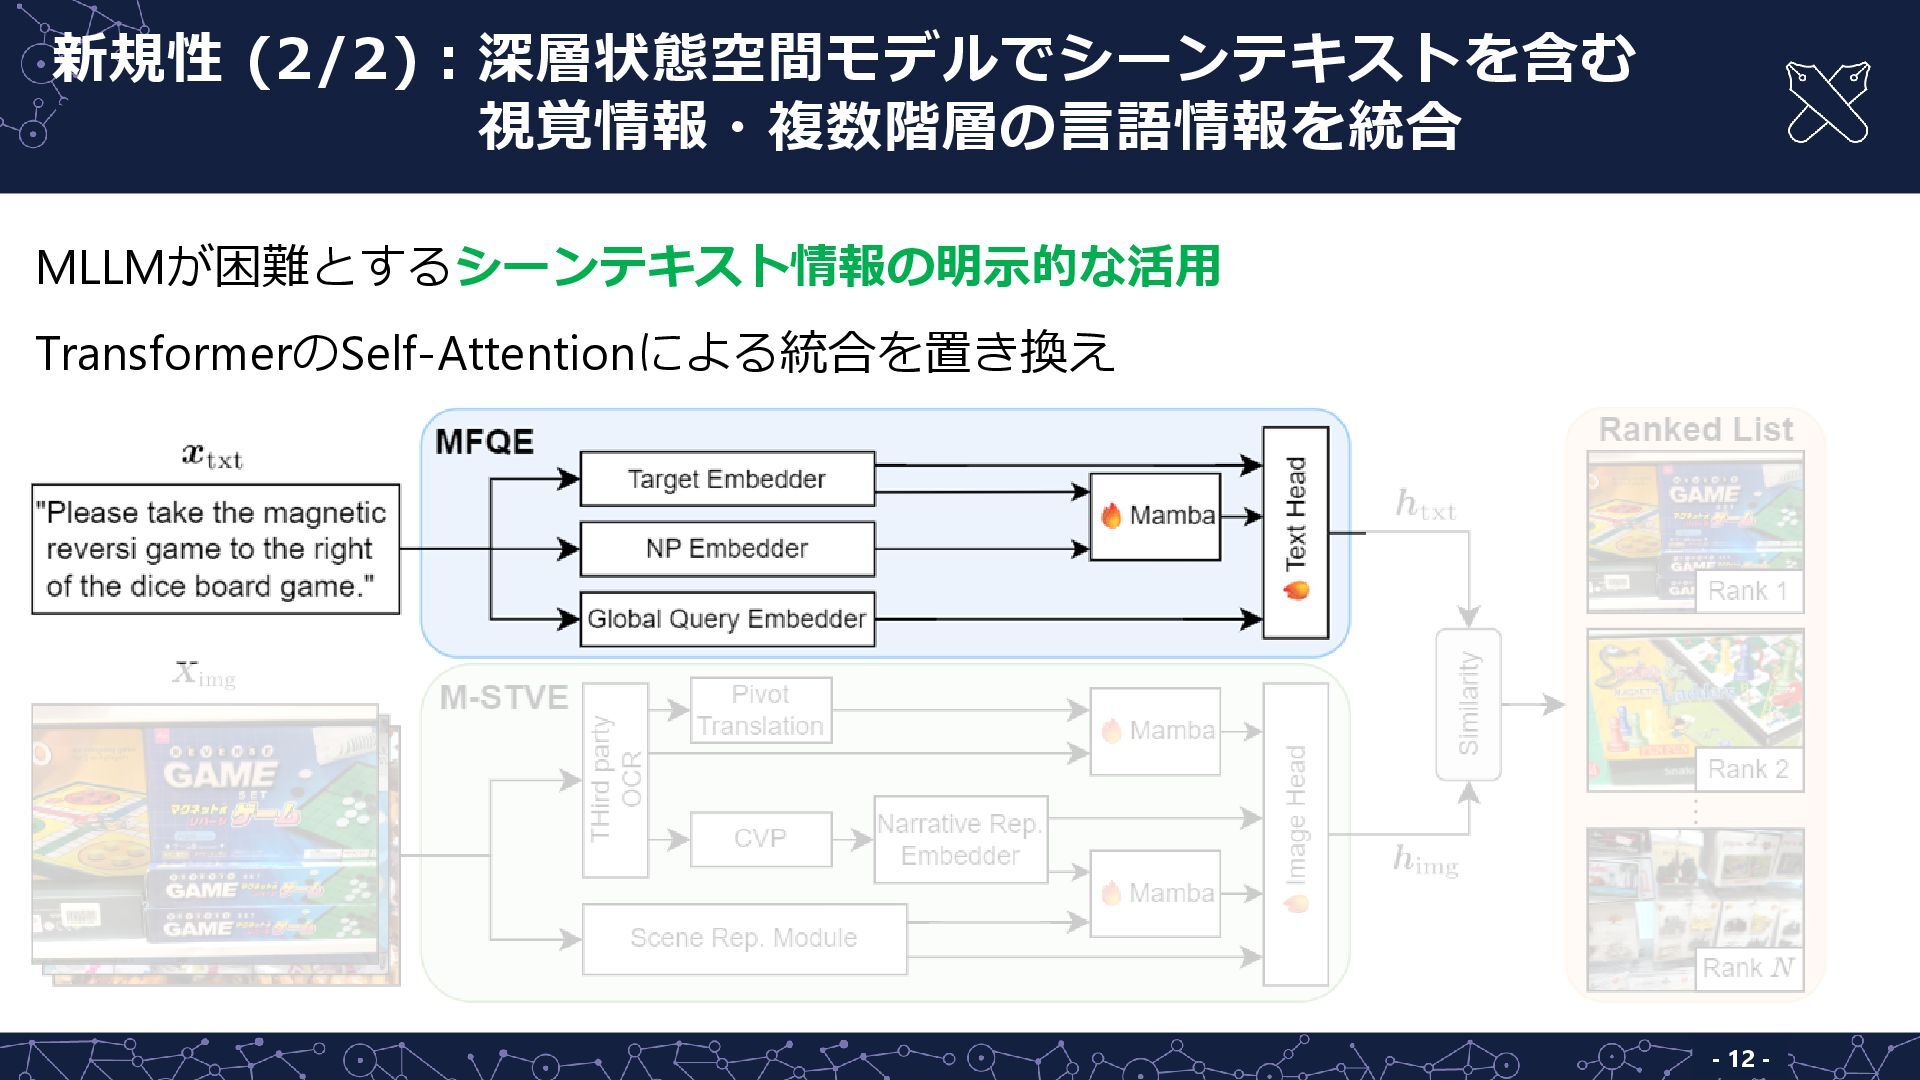
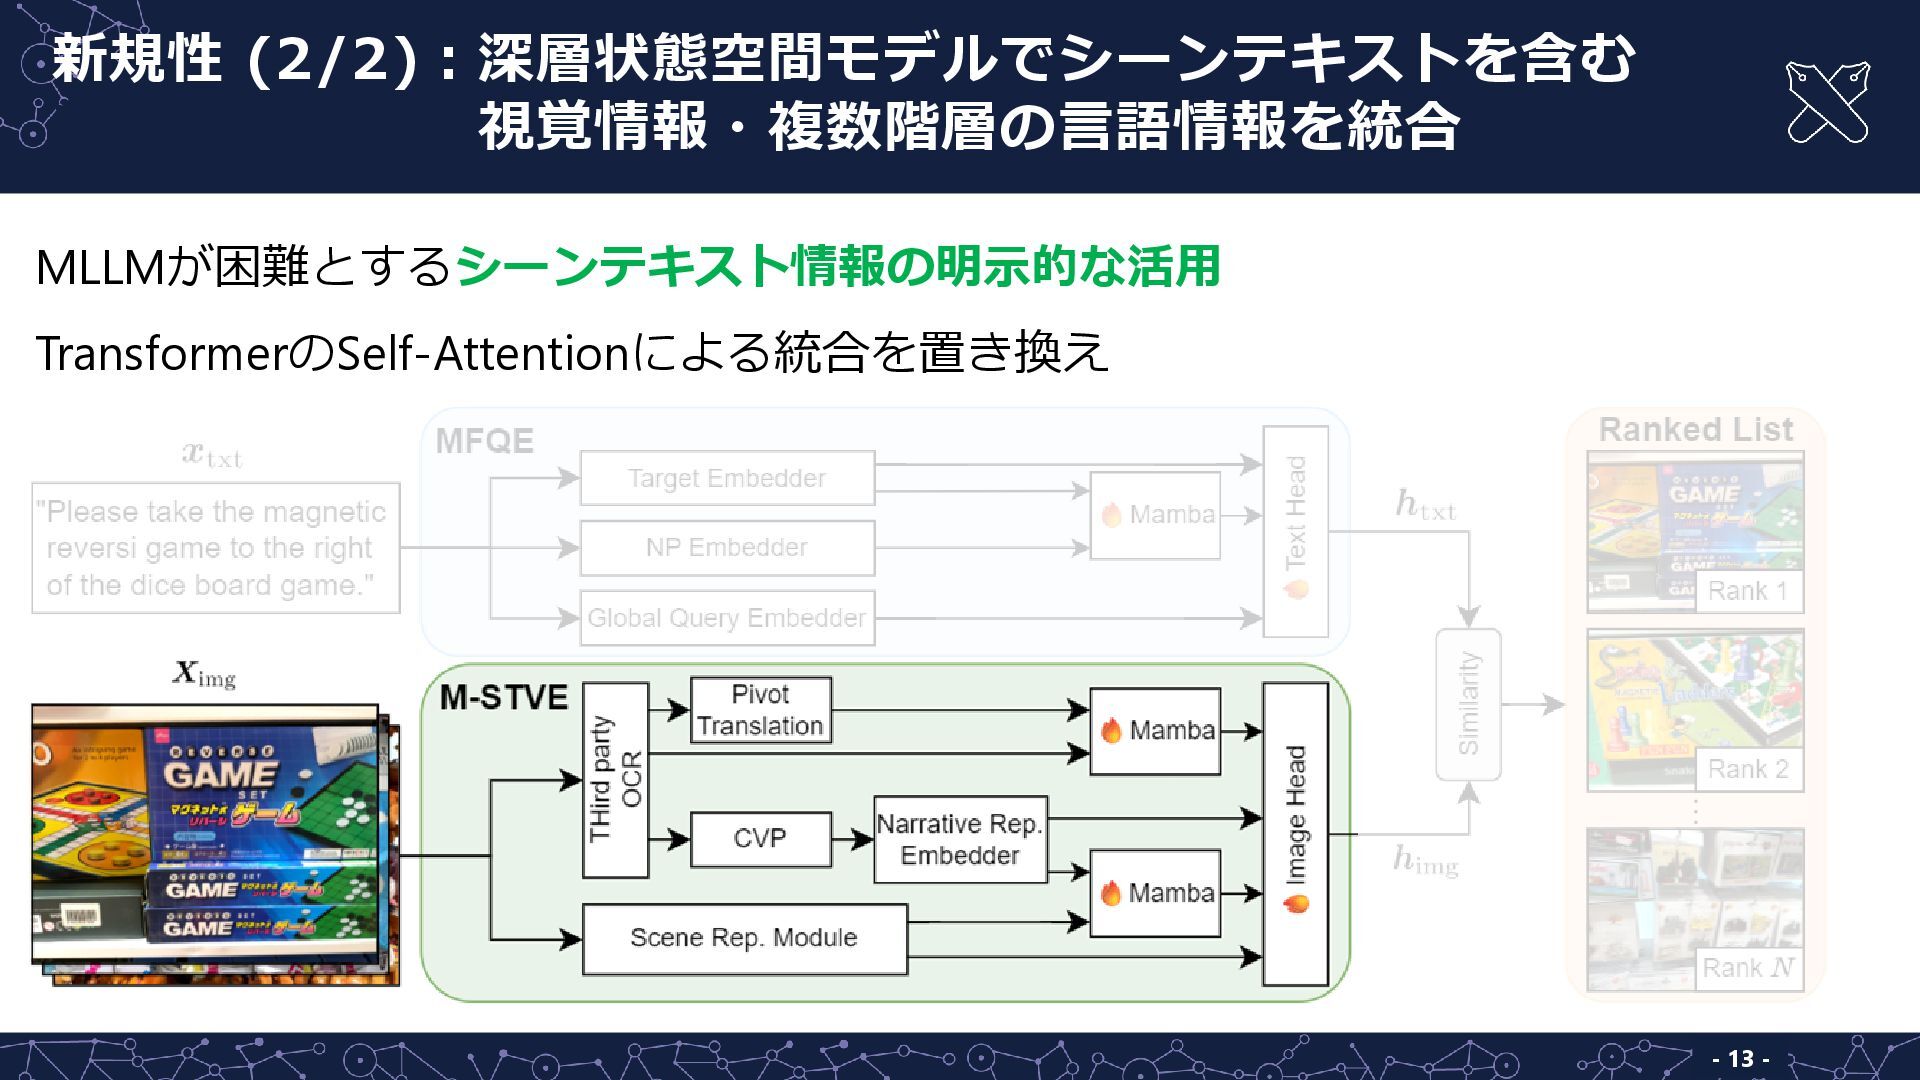
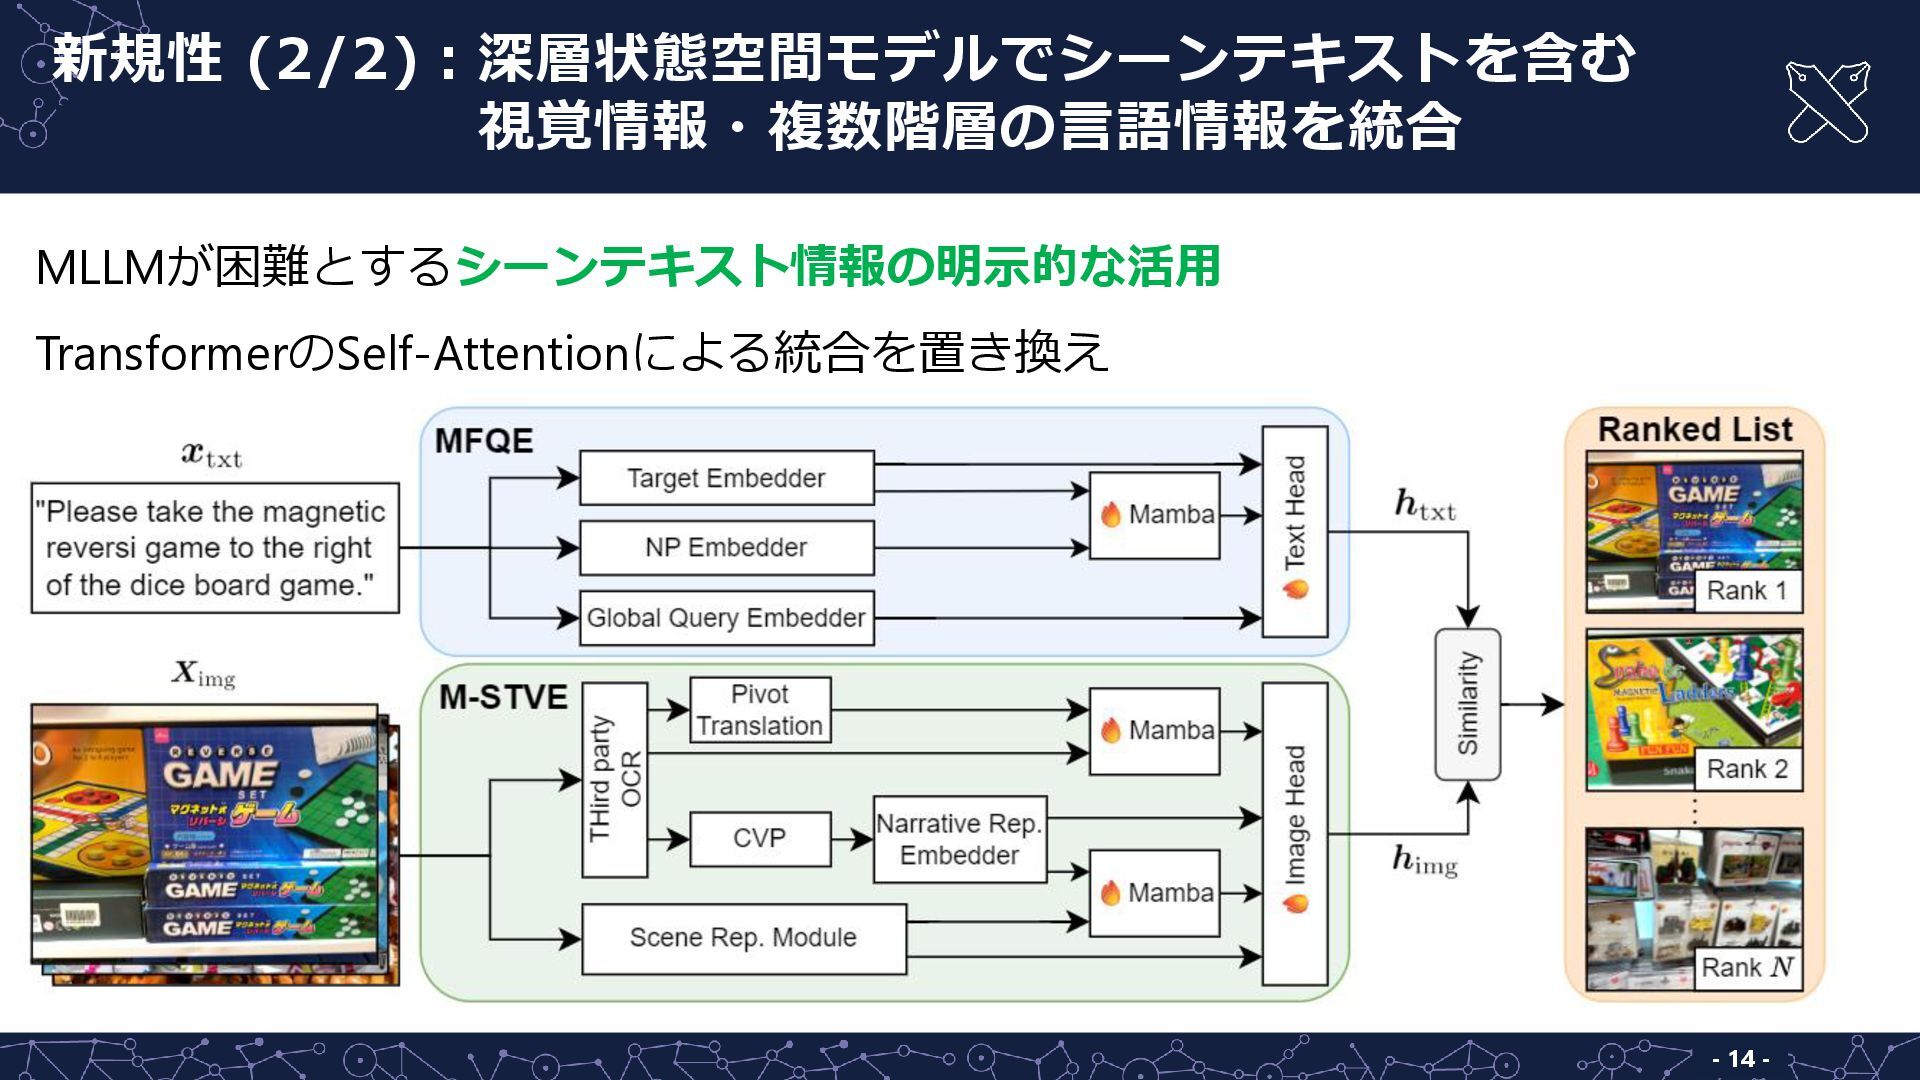
- 10 - 新規性 (2/2):深層状態空間モデルでシーンテキストを含む 新規性 (2/2):視覚情報・複数階層の言語情報を統合 MLLMが困難とするシーンテキスト情報の明示的な活用 TransformerのSelf-Attentionによる統合を置き換え Mamba
[Gu+, COLM24] ◼ 深層状態空間モデルの1つ ◼ 時系列予測や言語モデリングで Transformerと同等以上の性能 Mambaを用いて統合
- 11 - MLLMが困難とするシーンテキスト情報の明示的な活用 TransformerのSelf-Attentionによる統合を置き換え 新規性 (2/2):深層状態空間モデルでシーンテキストを含む 新規性 (2/2):視覚情報・複数階層の言語情報を統合
- 12 - MLLMが困難とするシーンテキスト情報の明示的な活用 TransformerのSelf-Attentionによる統合を置き換え 新規性 (2/2):深層状態空間モデルでシーンテキストを含む 新規性 (2/2):視覚情報・複数階層の言語情報を統合
- 13 - MLLMが困難とするシーンテキスト情報の明示的な活用 TransformerのSelf-Attentionによる統合を置き換え 新規性 (2/2):深層状態空間モデルでシーンテキストを含む 新規性 (2/2):視覚情報・複数階層の言語情報を統合
- 14 - MLLMが困難とするシーンテキスト情報の明示的な活用 TransformerのSelf-Attentionによる統合を置き換え 新規性 (2/2):深層状態空間モデルでシーンテキストを含む 新規性 (2/2):視覚情報・複数階層の言語情報を統合
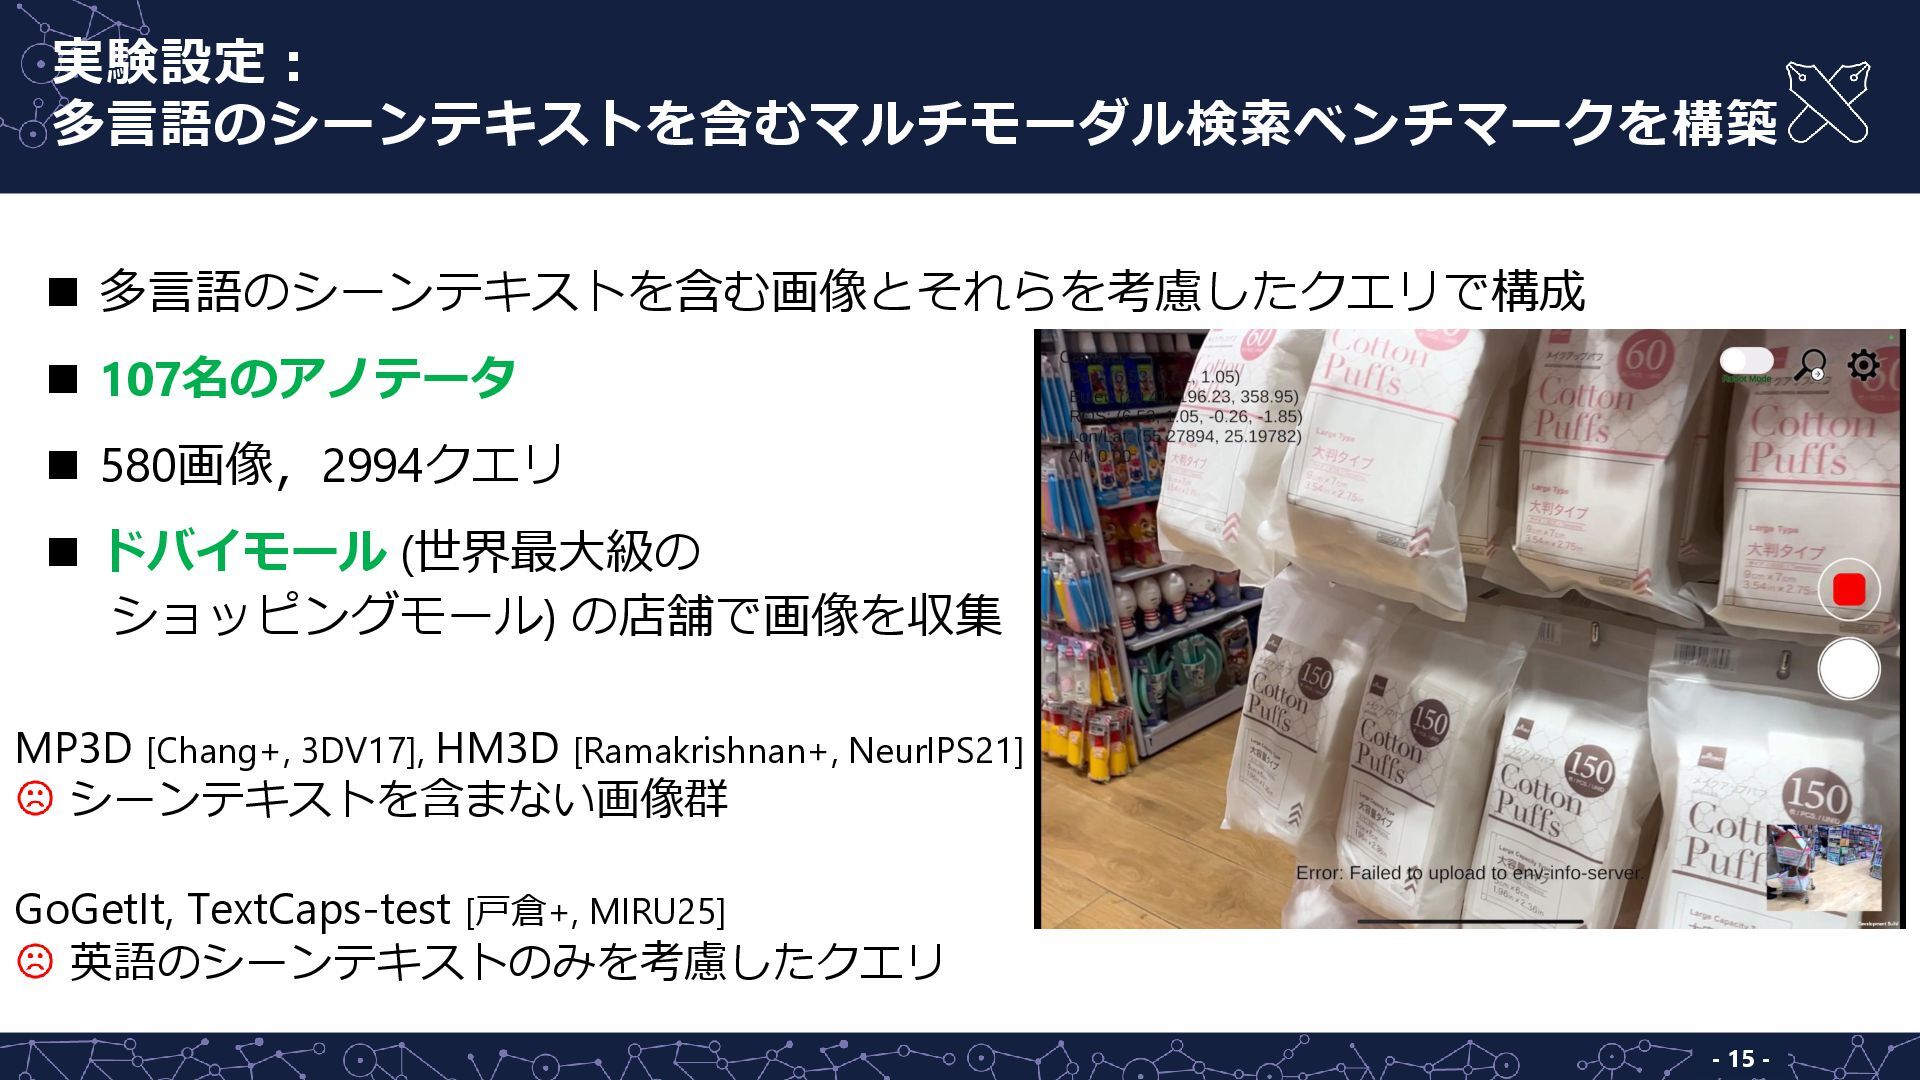
実験設定: 多言語のシーンテキストを含むマルチモーダル検索ベンチマークを構築 - 15 - ◼ 多言語のシーンテキストを含む画像とそれらを考慮したクエリで構成 ◼ 107名のアノテータ ◼
580画像,2994クエリ ◼ ドバイモール (世界最大級の ショッピングモール) の店舗で画像を収集 MP3D [Chang+, 3DV17], HM3D [Ramakrishnan+, NeurIPS21] シーンテキストを含まない画像群 GoGetIt, TextCaps-test [戸倉+, MIRU25] 英語のシーンテキストのみを考慮したクエリ
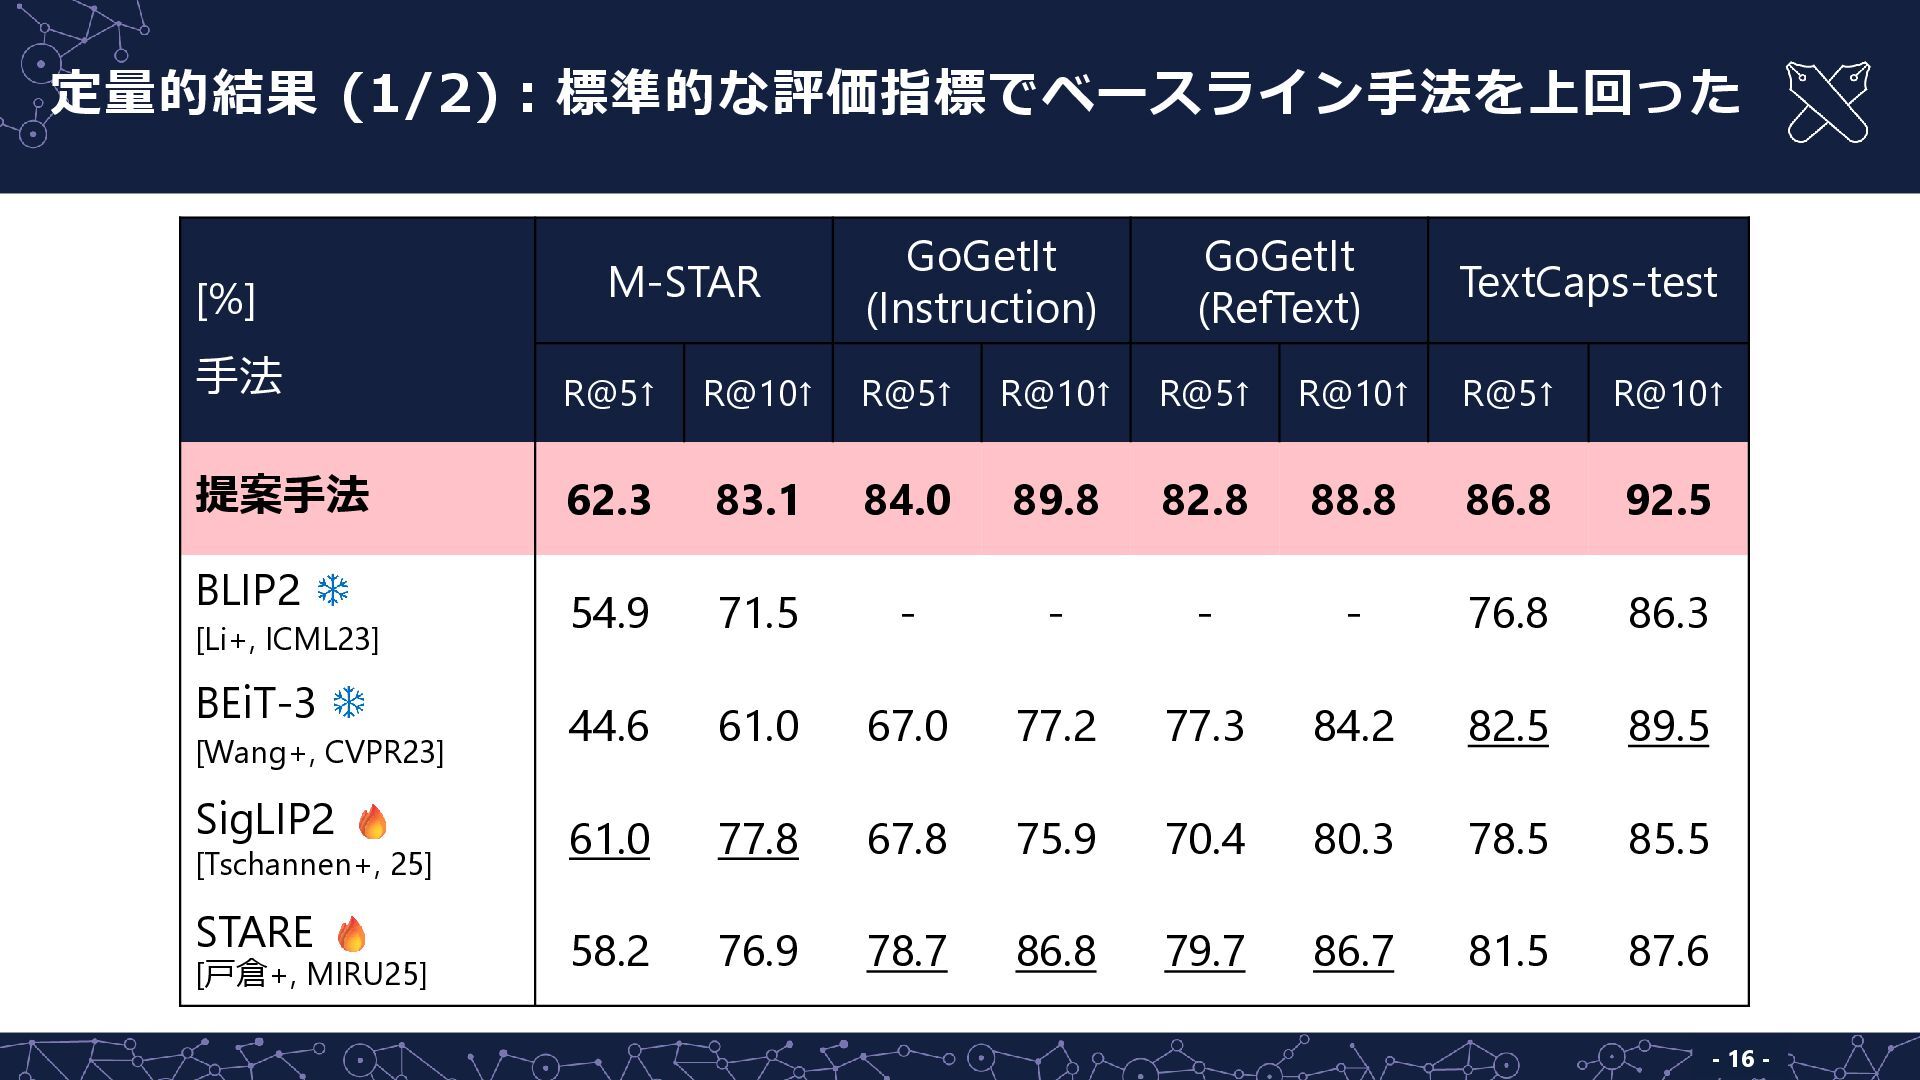
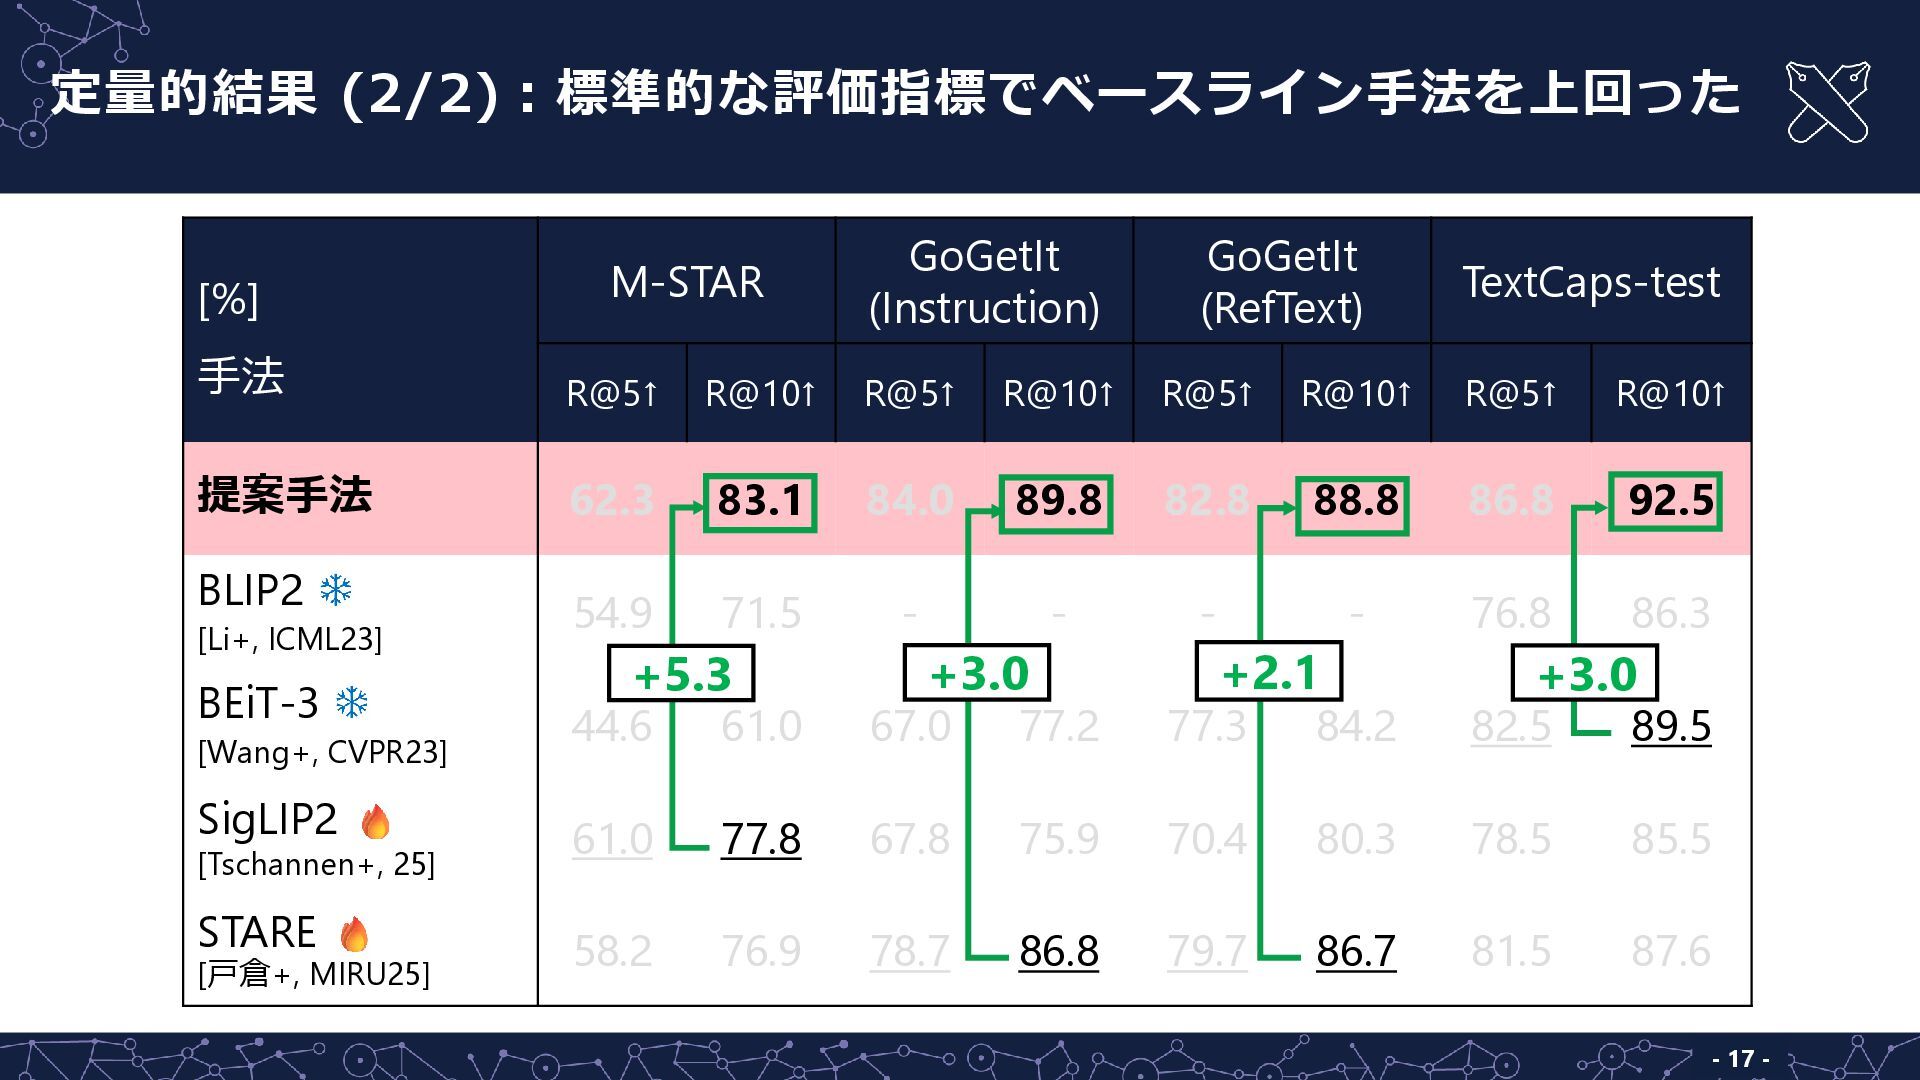
定量的結果 (1/2):標準的な評価指標でベースライン手法を上回った - 16 - [%] 手法 M-STAR GoGetIt (Instruction)
GoGetIt (RefText) TextCaps-test R@5↑ R@10↑ R@5↑ R@10↑ R@5↑ R@10↑ R@5↑ R@10↑ 提案手法 62.3 83.1 84.0 89.8 82.8 88.8 86.8 92.5 BLIP2 [Li+, ICML23] 54.9 71.5 - - - - 76.8 86.3 BEiT-3 [Wang+, CVPR23] 44.6 61.0 67.0 77.2 77.3 84.2 82.5 89.5 SigLIP2 [Tschannen+, 25] 61.0 77.8 67.8 75.9 70.4 80.3 78.5 85.5 STARE [戸倉+, MIRU25] 58.2 76.9 78.7 86.8 79.7 86.7 81.5 87.6
[%] 手法 M-STAR GoGetIt (Instruction) GoGetIt (RefText) TextCaps-test R@5↑ R@10↑
R@5↑ R@10↑ R@5↑ R@10↑ R@5↑ R@10↑ 提案手法 62.3 83.1 84.0 89.8 82.8 88.8 86.8 92.5 BLIP2 [Li+, ICML23] 54.9 71.5 - - - - 76.8 86.3 BEiT-3 [Wang+, CVPR23] 44.6 61.0 67.0 77.2 77.3 84.2 82.5 89.5 SigLIP2 [Tschannen+, 25] 61.0 77.8 67.8 75.9 70.4 80.3 78.5 85.5 STARE [戸倉+, MIRU25] 58.2 76.9 78.7 86.8 79.7 86.7 81.5 87.6 - 17 - +5.3 +3.0 +2.1 +3.0 定量的結果 (2/2):標準的な評価指標でベースライン手法を上回った
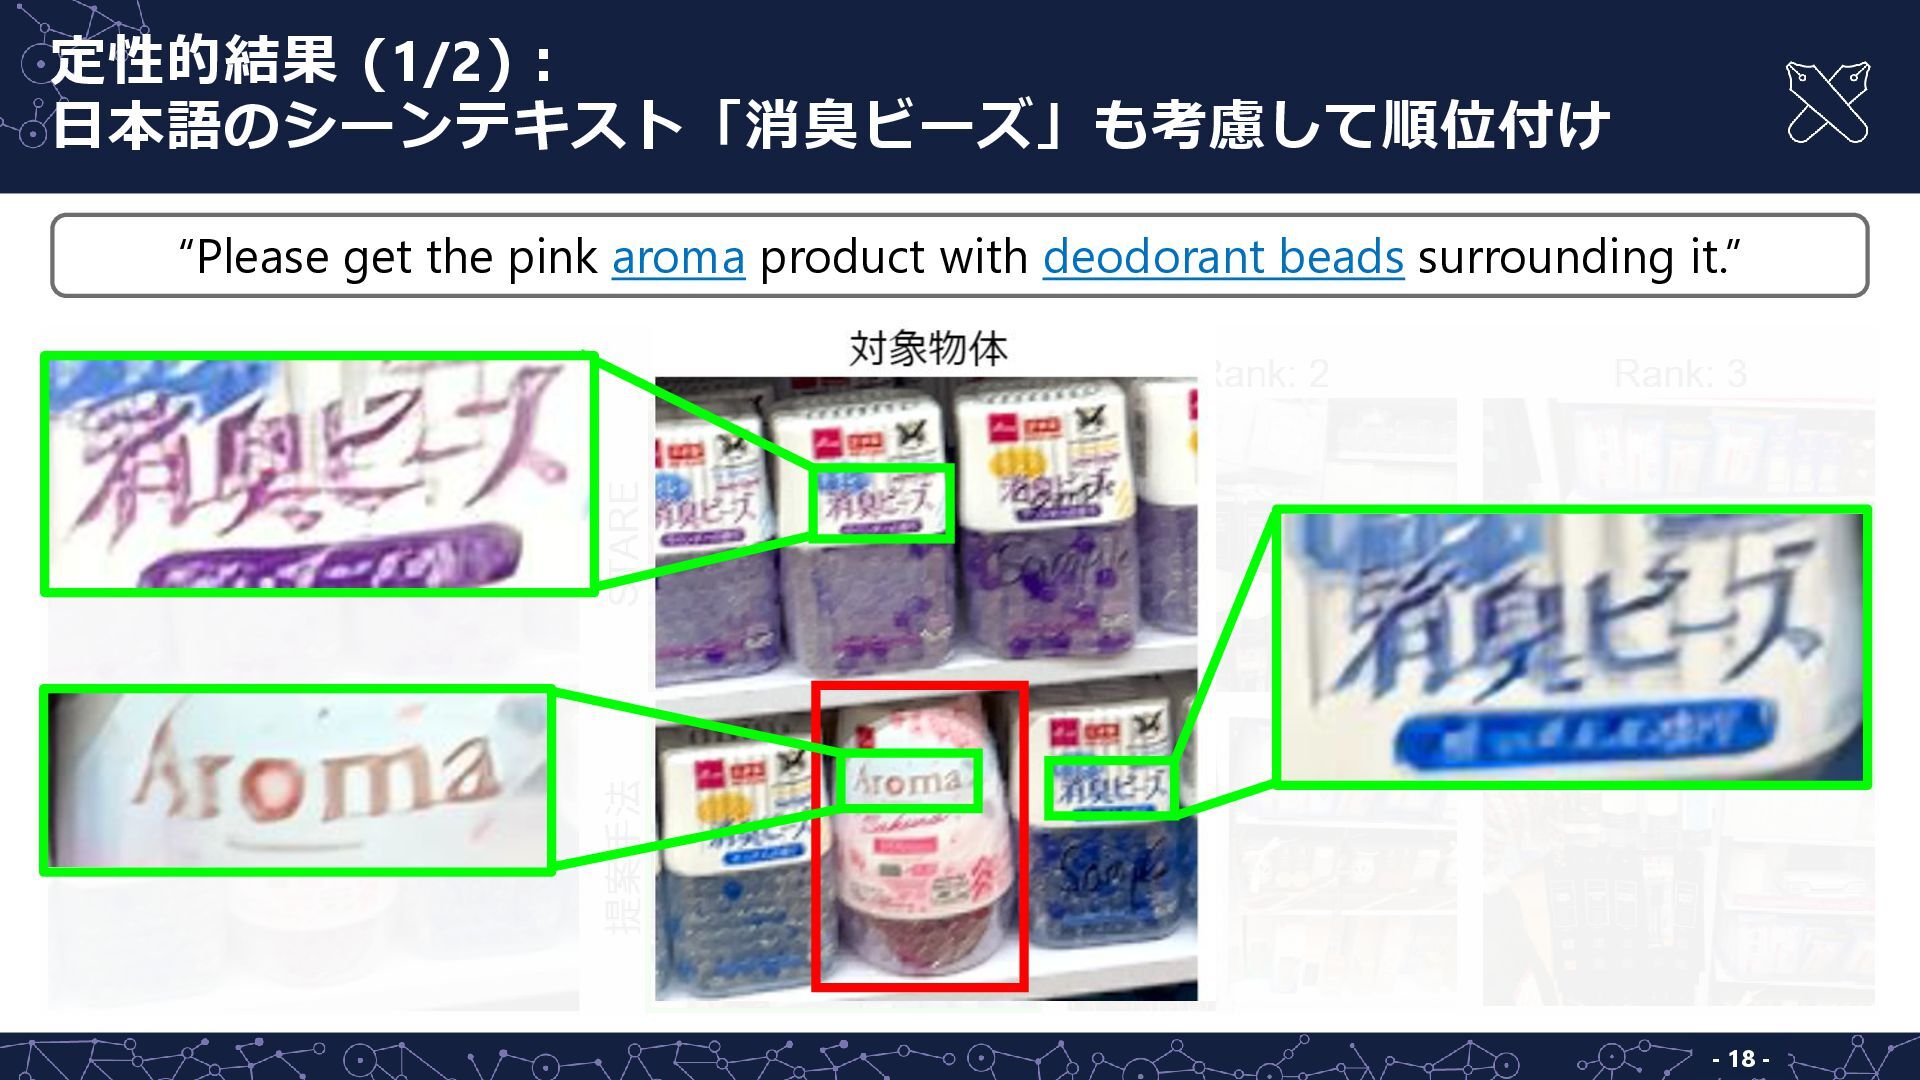
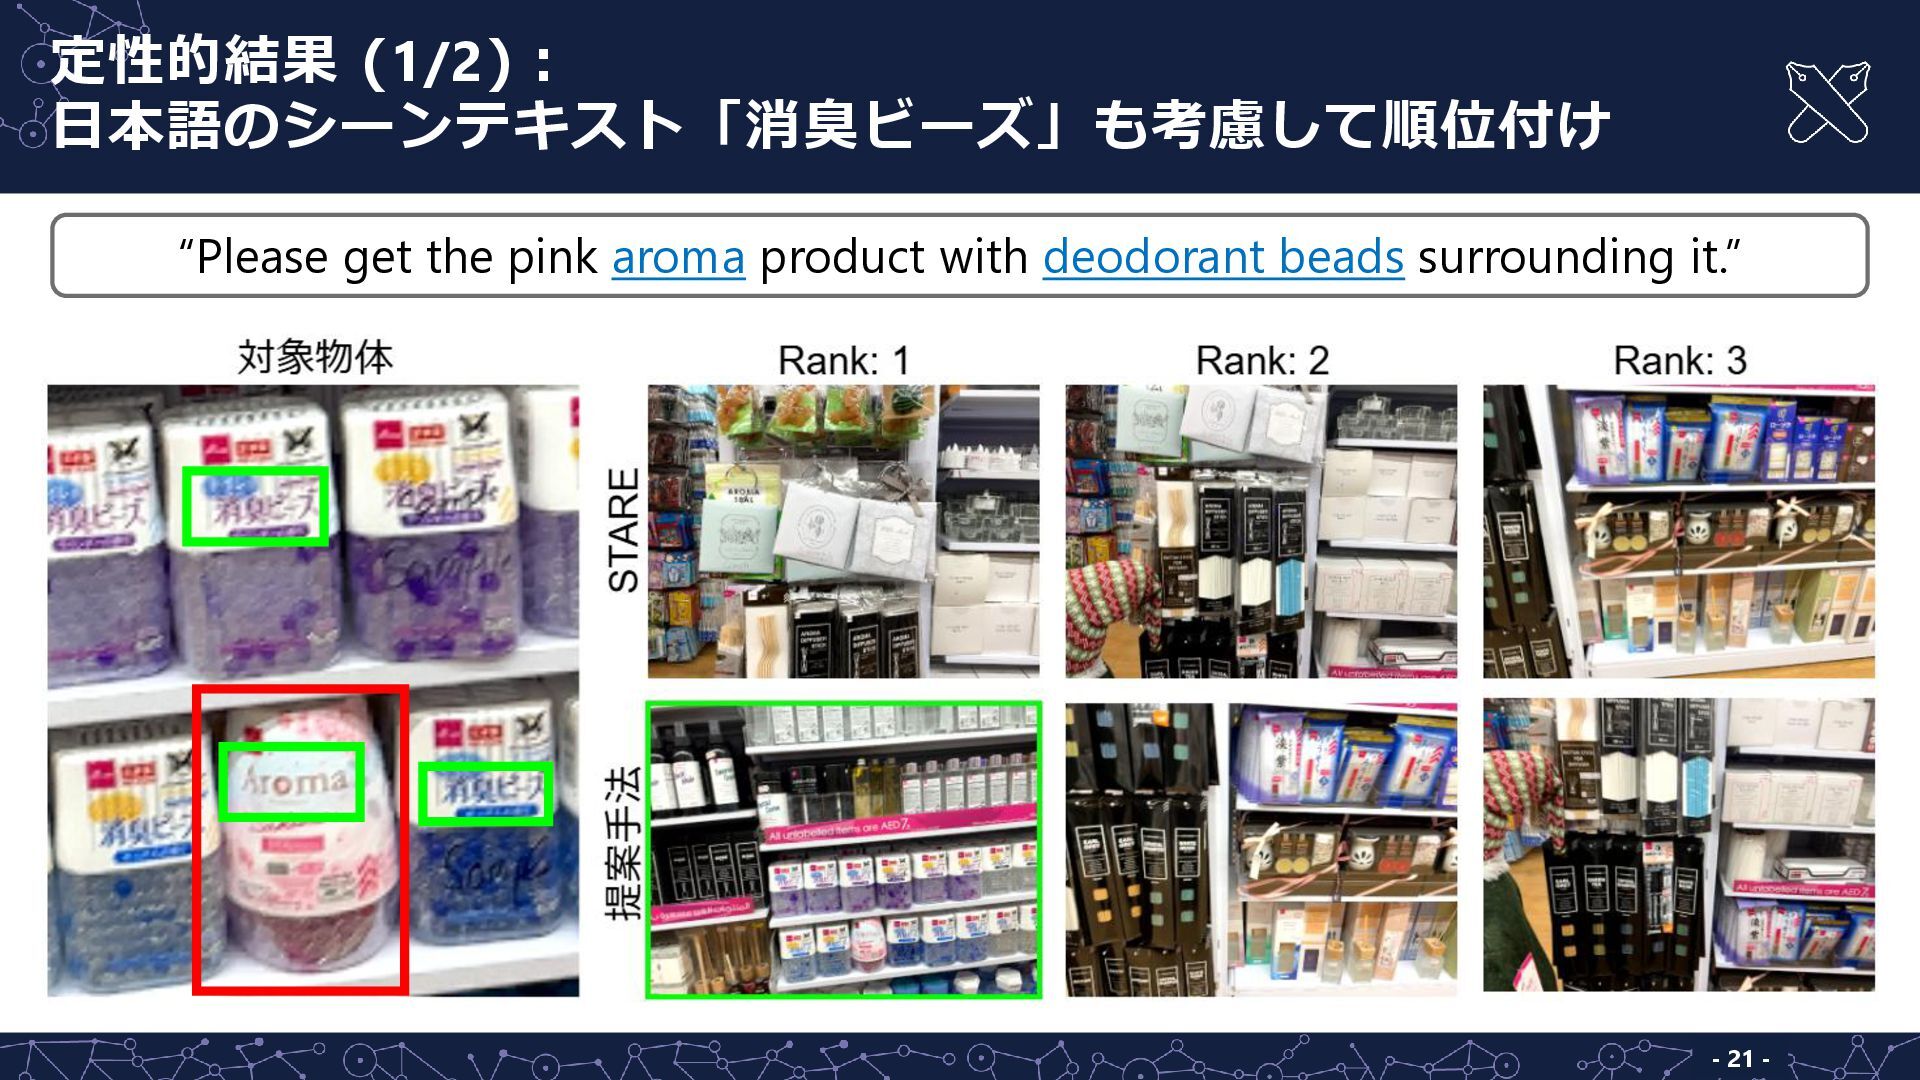
- 18 - 定性的結果 (1/2): 日本語のシーンテキスト「消臭ビーズ」も考慮して順位付け “Please get the pink
aroma product with deodorant beads surrounding it.”
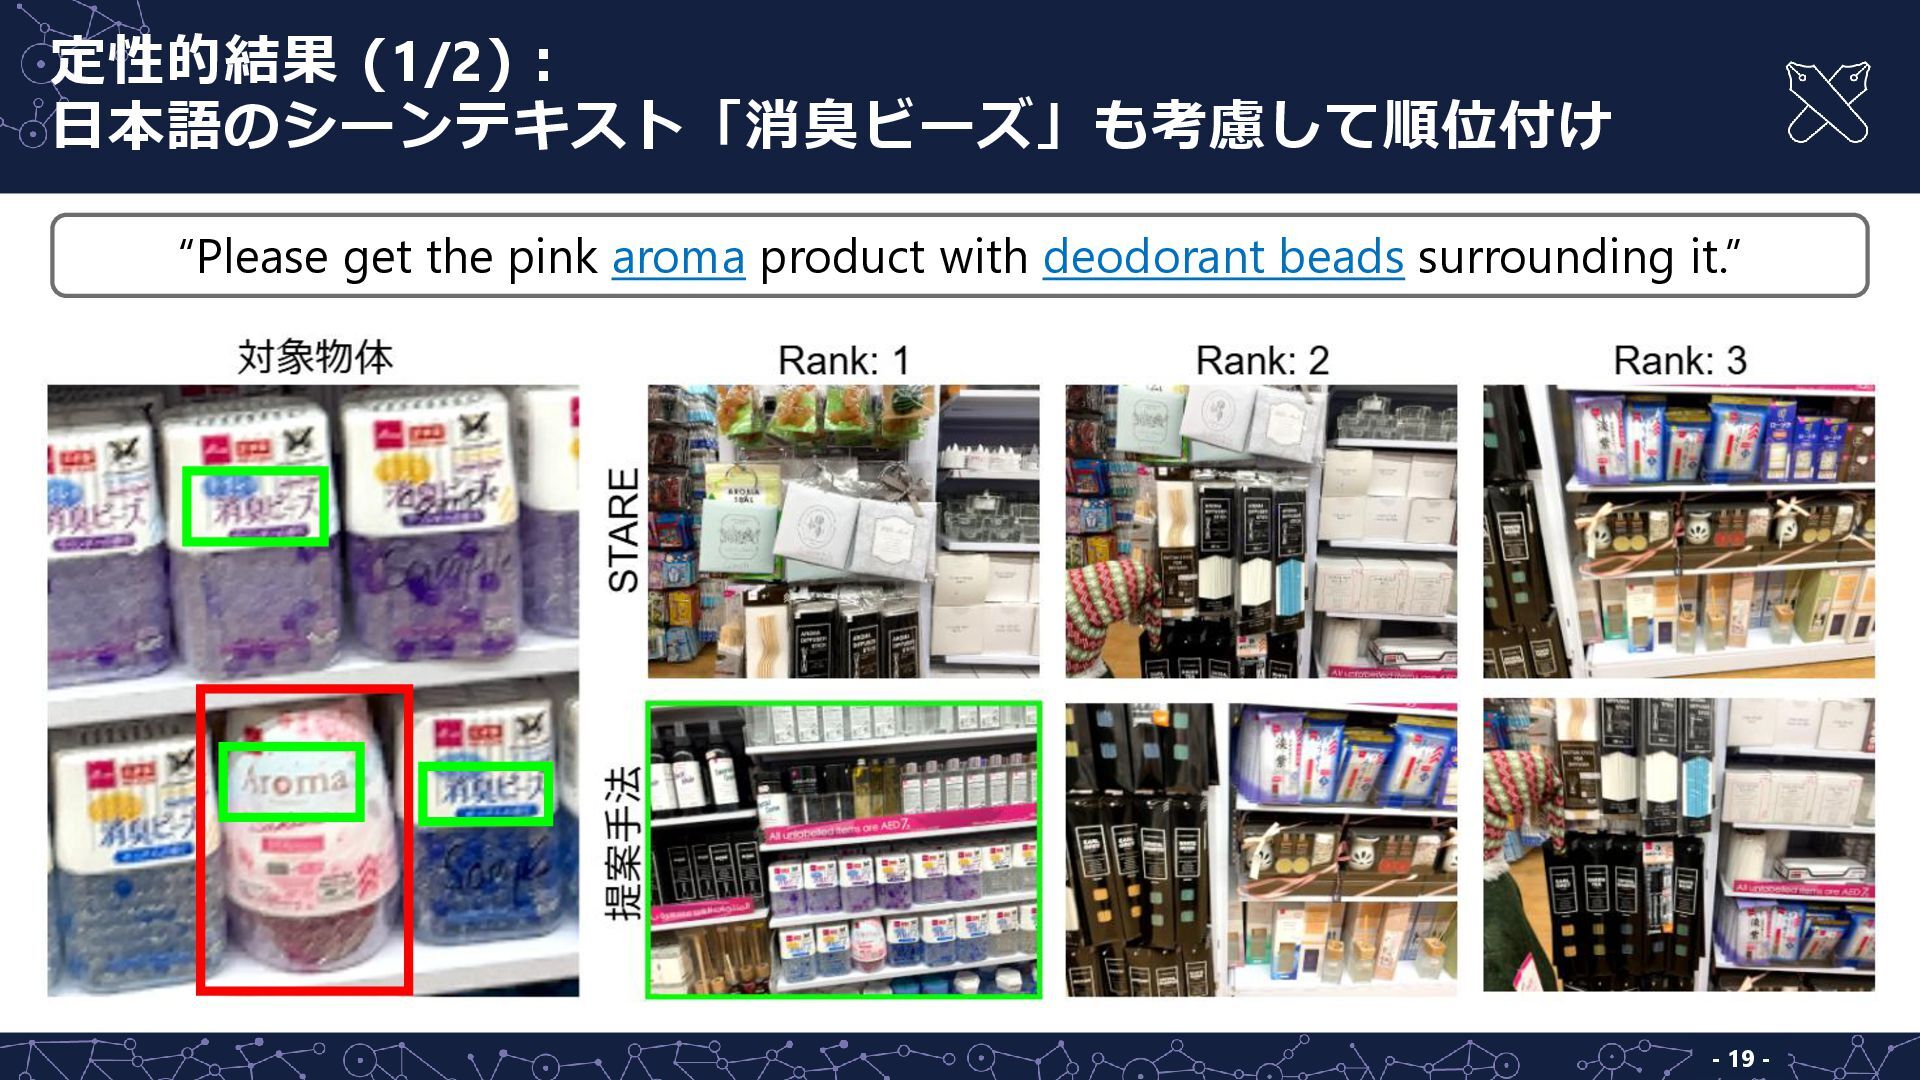
- 19 - 定性的結果 (1/2): 日本語のシーンテキスト「消臭ビーズ」も考慮して順位付け “Please get the pink
aroma product with deodorant beads surrounding it.”
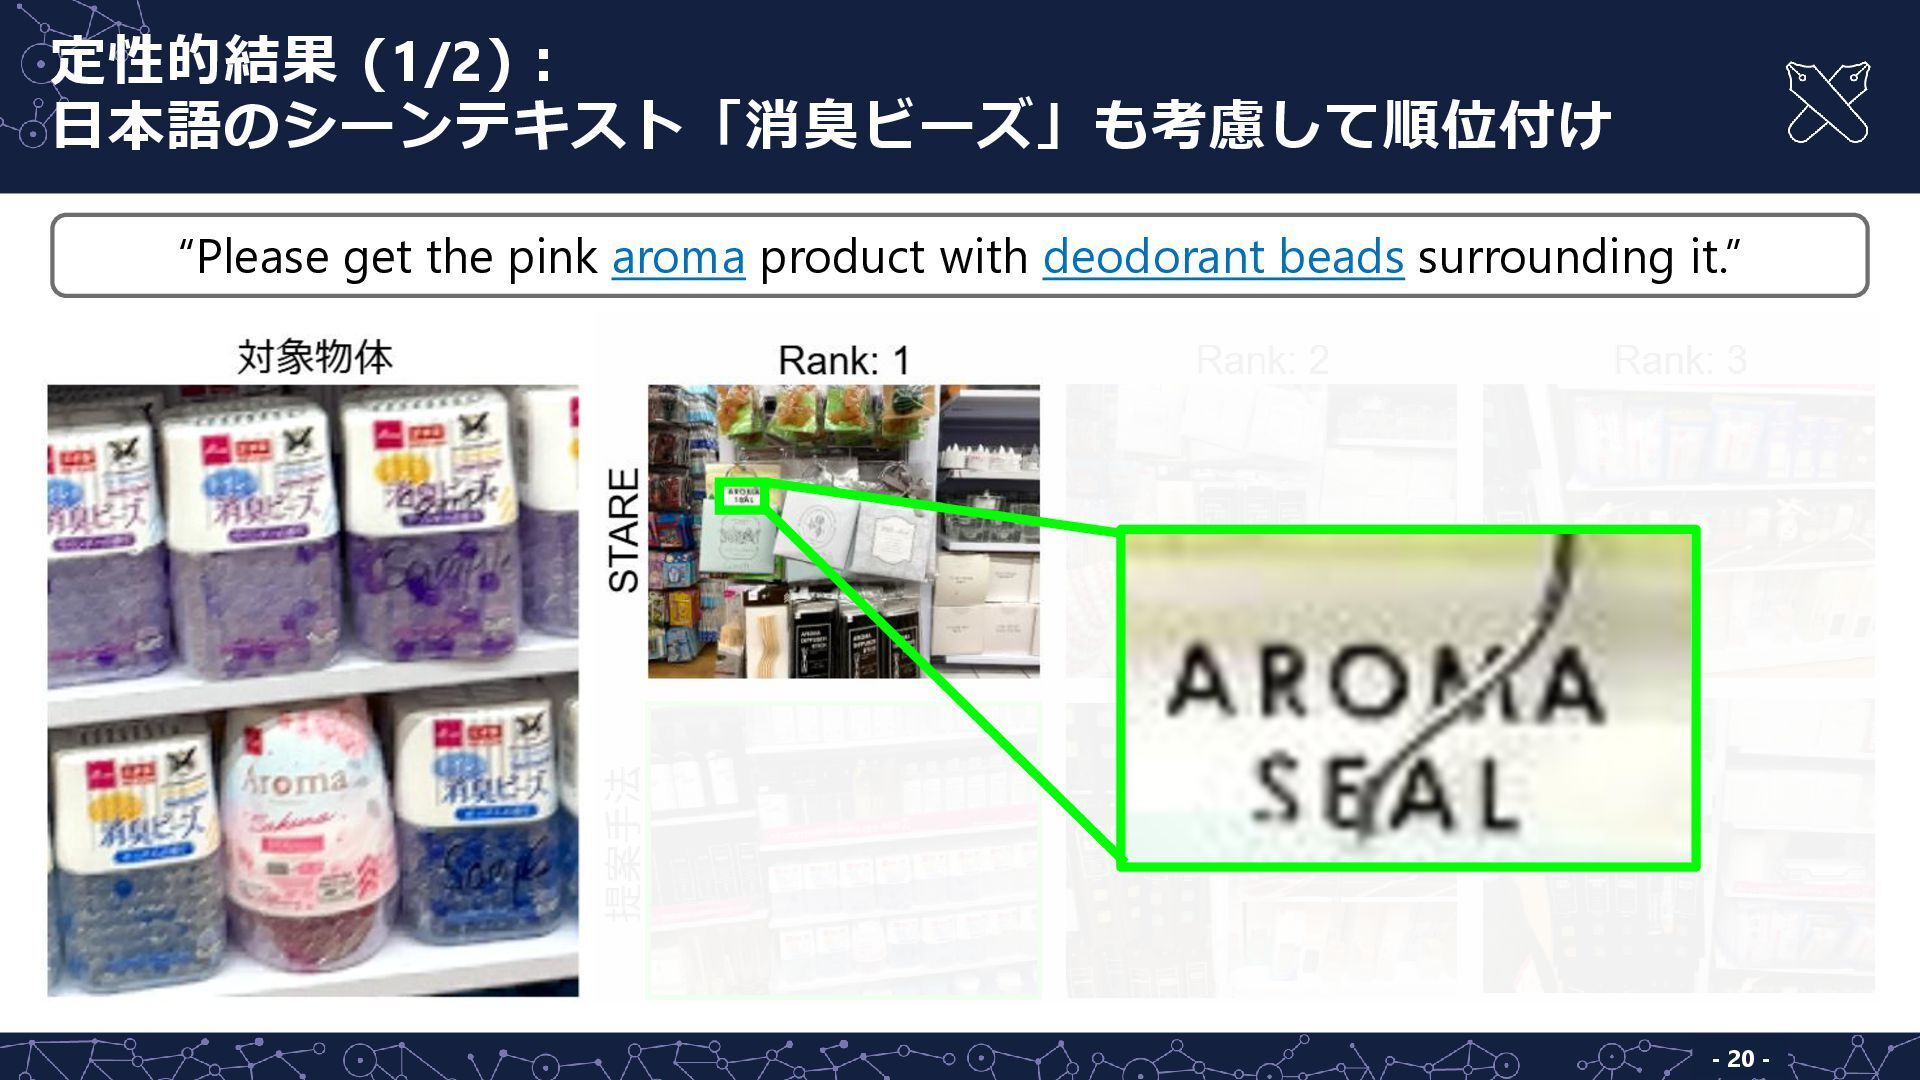
- 20 - 定性的結果 (1/2): 日本語のシーンテキスト「消臭ビーズ」も考慮して順位付け “Please get the pink
aroma product with deodorant beads surrounding it.”
- 21 - 定性的結果 (1/2): 日本語のシーンテキスト「消臭ビーズ」も考慮して順位付け “Please get the pink
aroma product with deodorant beads surrounding it.”
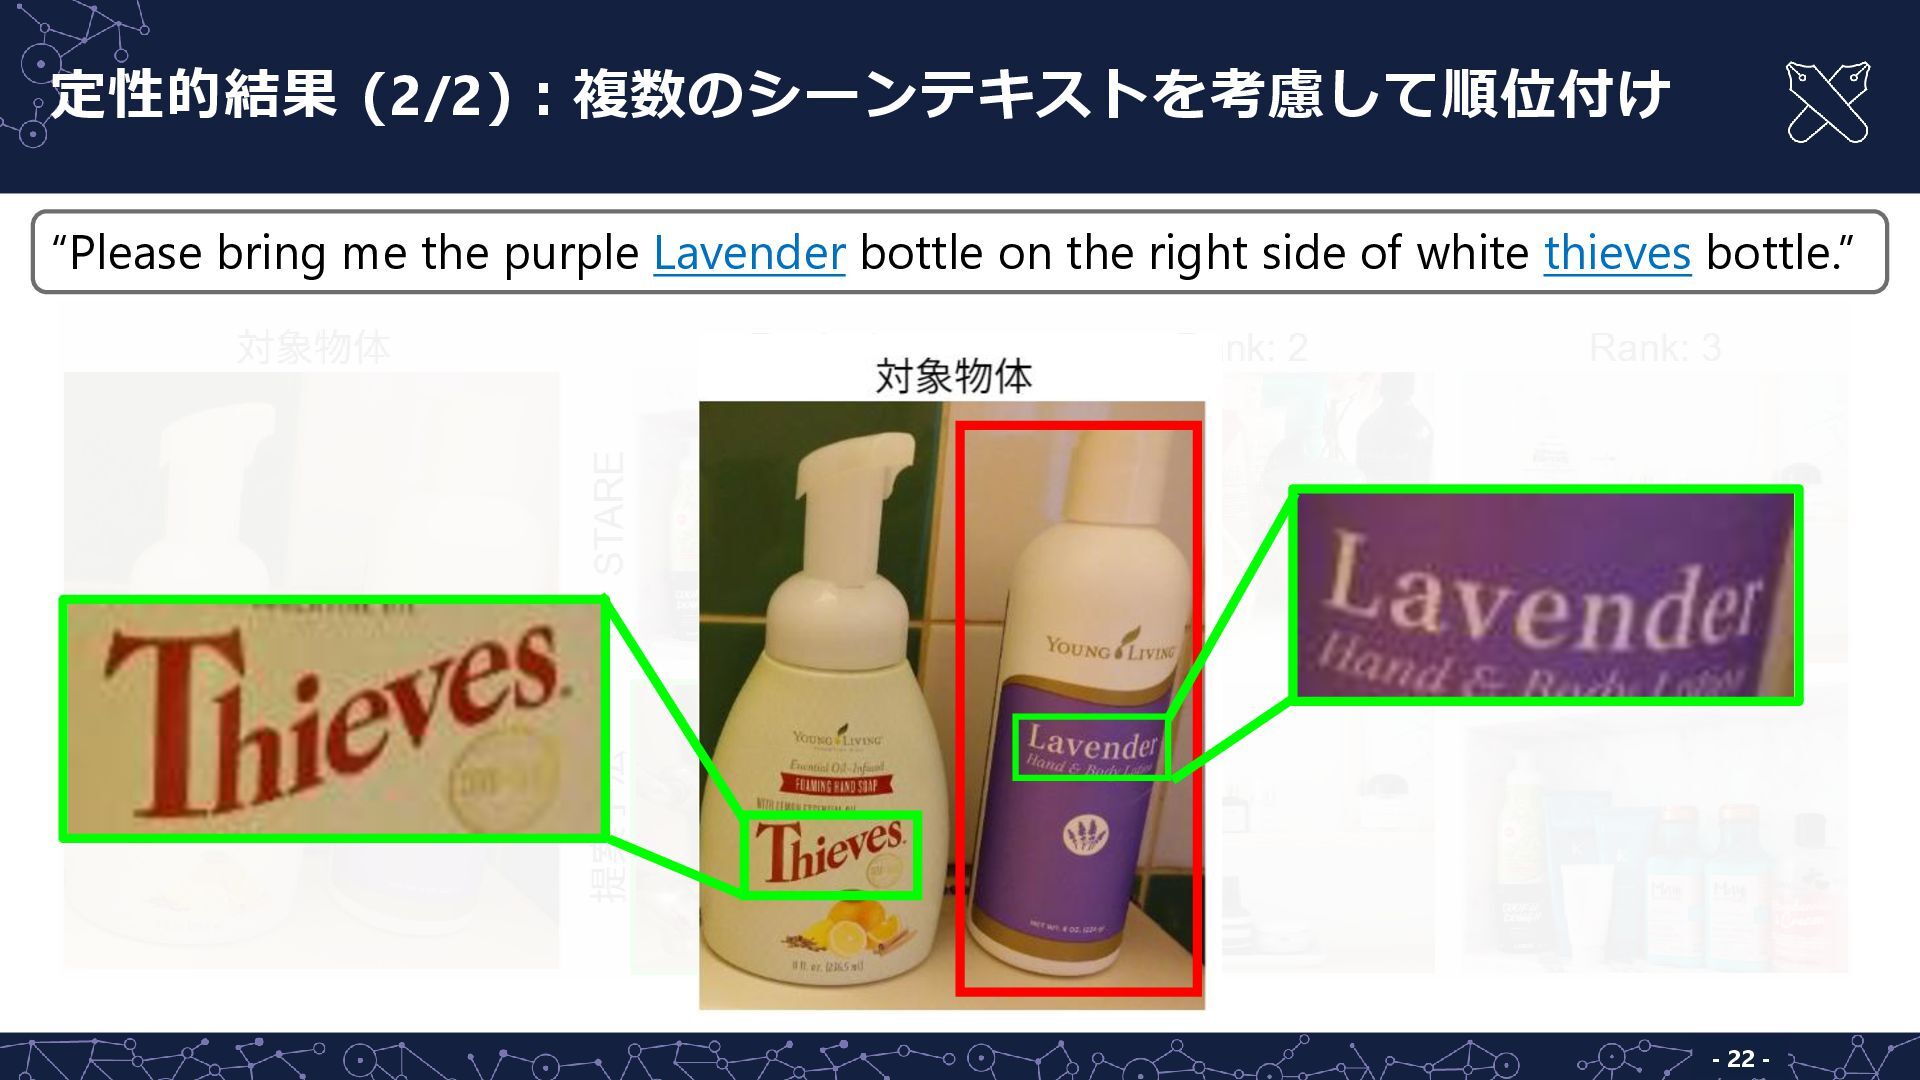
- 22 - 定性的結果 (2/2):複数のシーンテキストを考慮して順位付け “Please bring me the purple
Lavender bottle on the right side of white thieves bottle.”
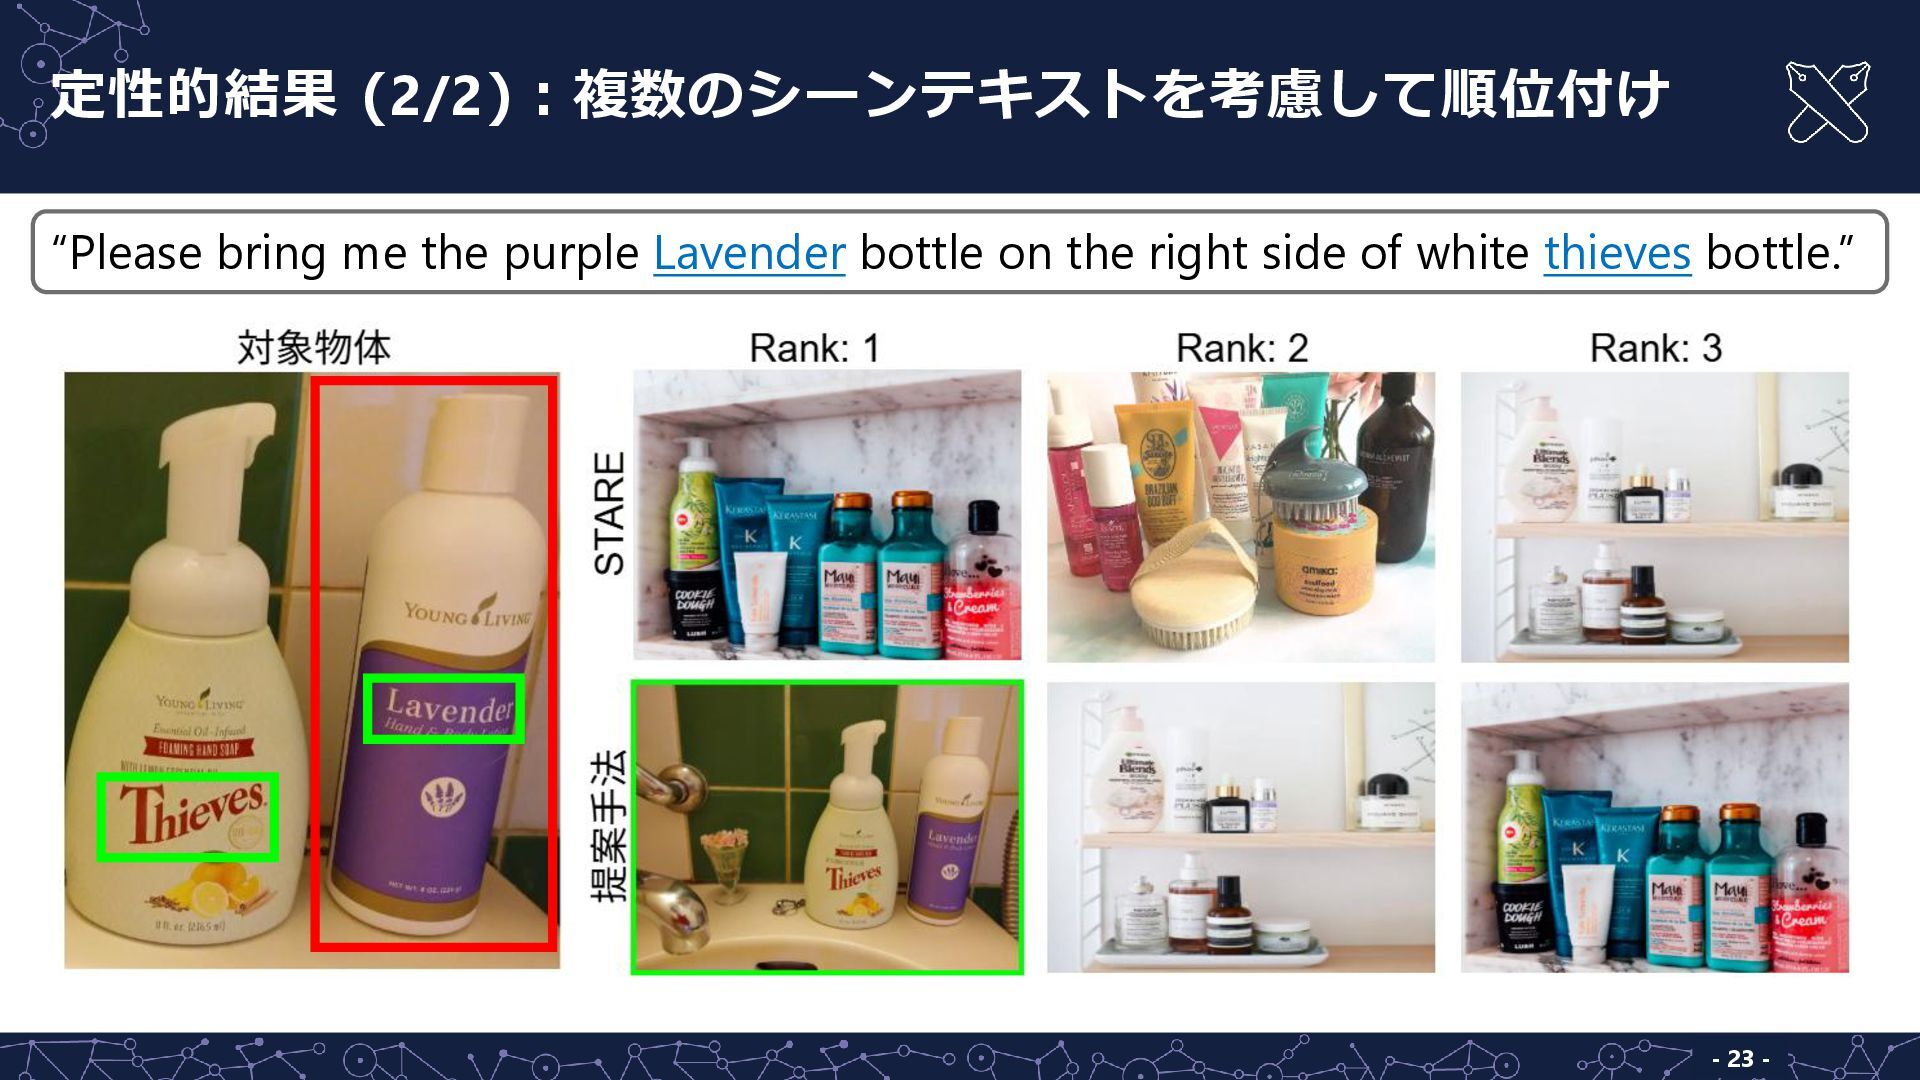
- 23 - 定性的結果 (2/2):複数のシーンテキストを考慮して順位付け “Please bring me the purple
Lavender bottle on the right side of white thieves bottle.”
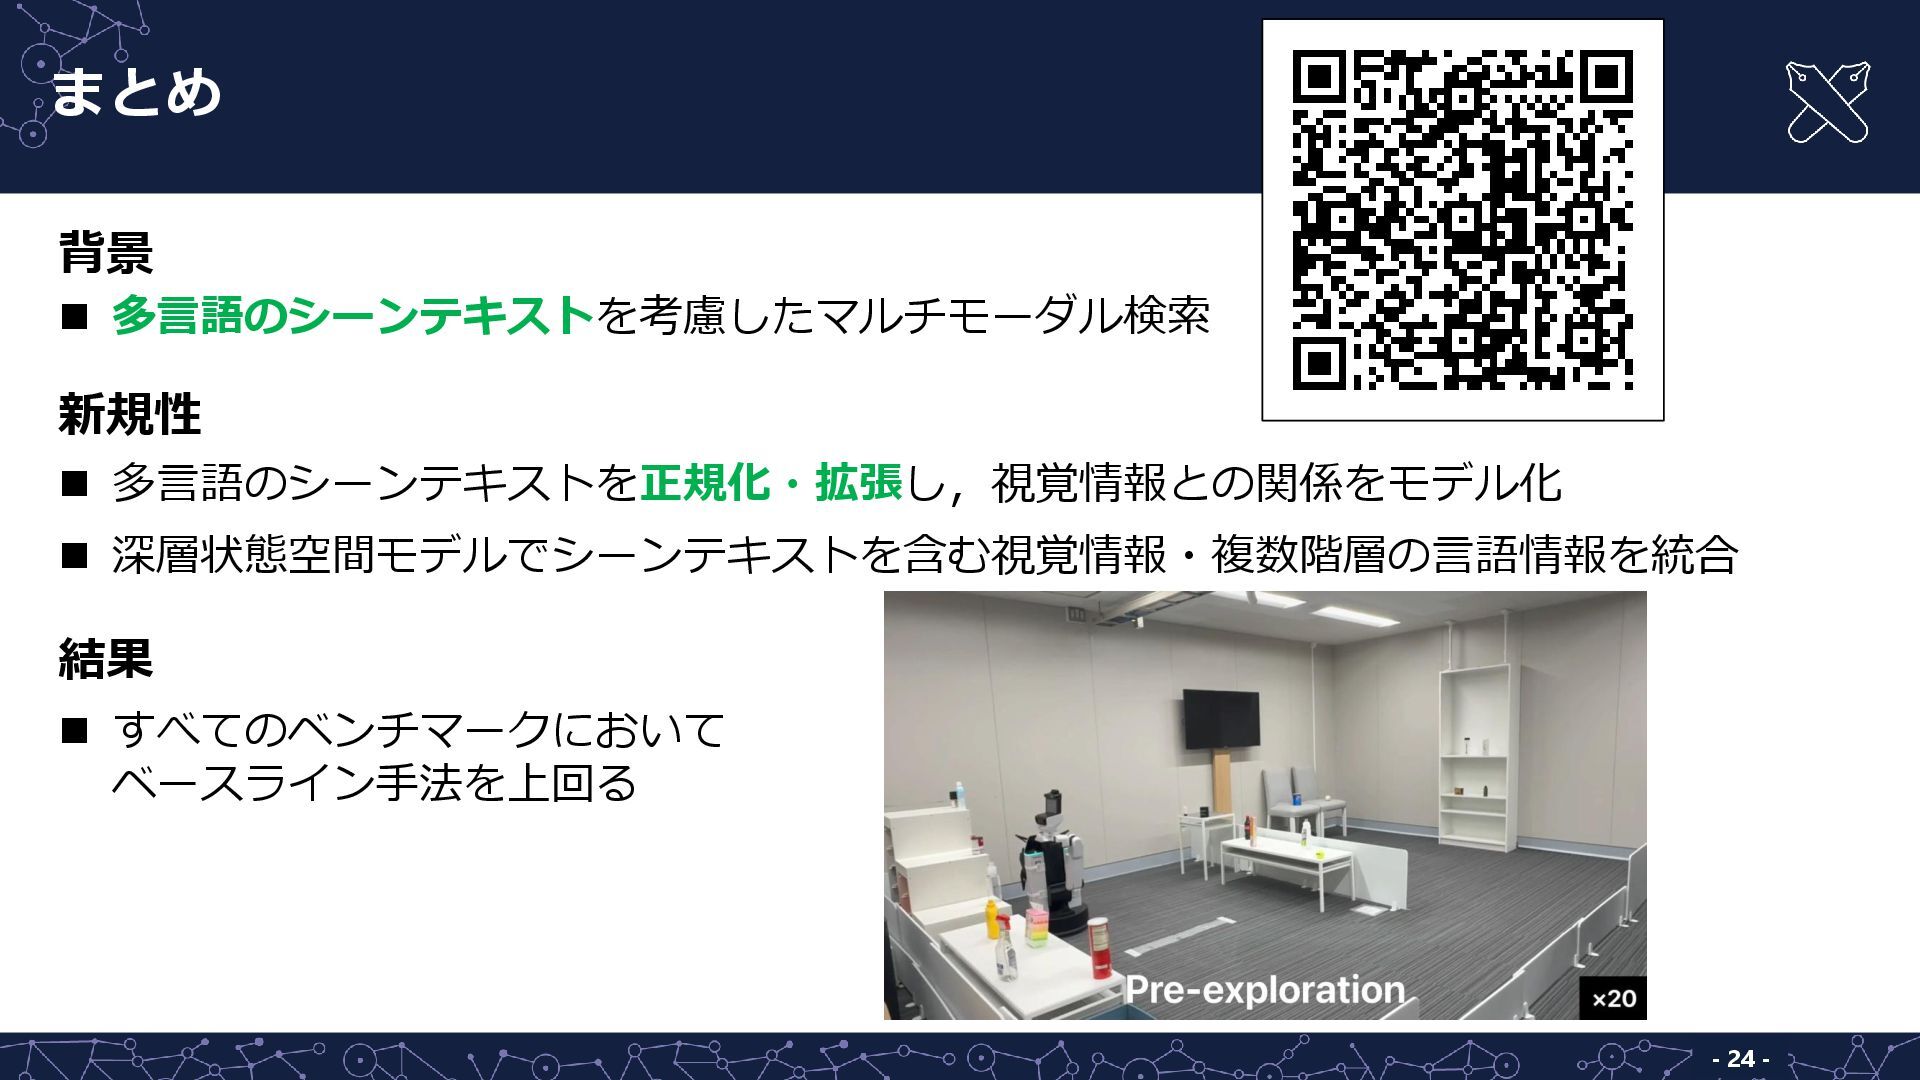
- 24 - 背景 ◼ 多言語のシーンテキストを考慮したマルチモーダル検索 新規性 ◼ 多言語のシーンテキストを正規化・拡張し,視覚情報との関係をモデル化 ◼
深層状態空間モデルでシーンテキストを含む視覚情報・複数階層の言語情報を統合 結果 ◼ すべてのベンチマークにおいて ベースライン手法を上回る まとめ
Appendix 25
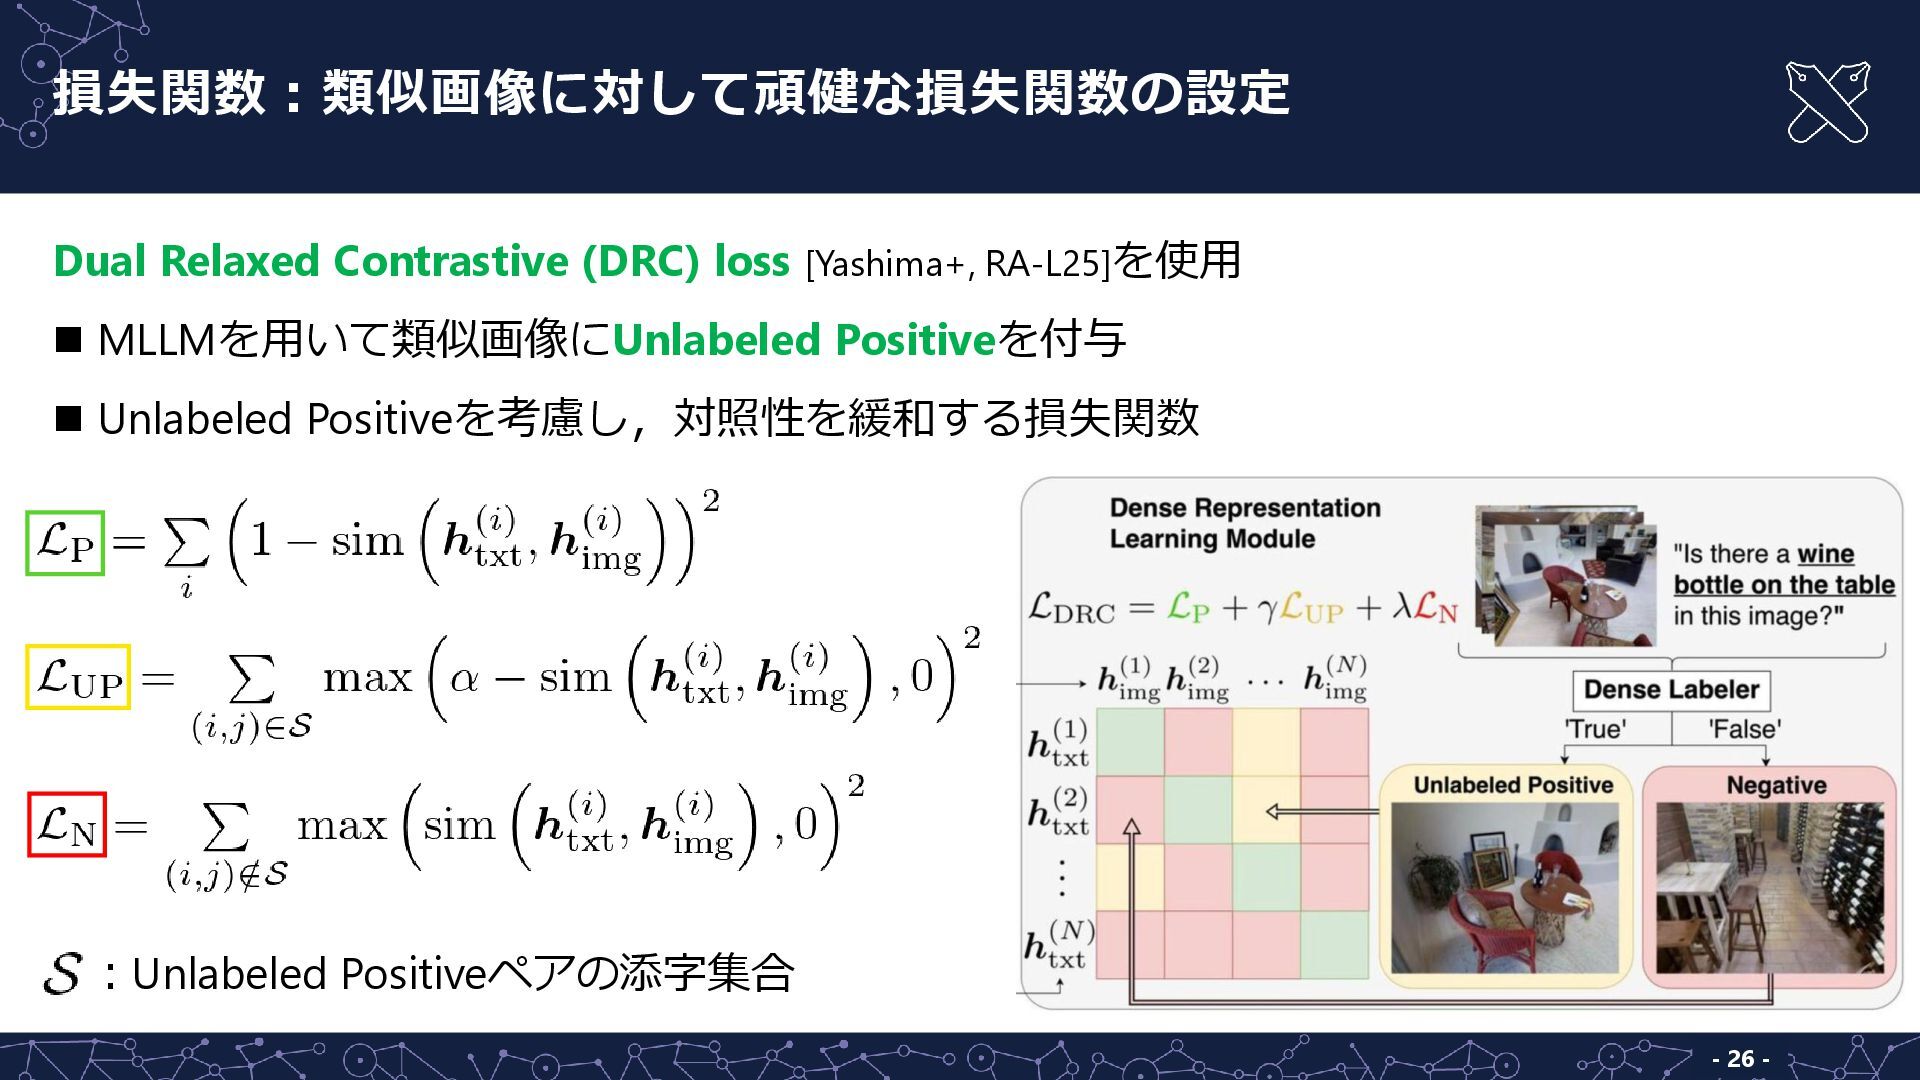
- 26 - 損失関数:類似画像に対して頑健な損失関数の設定 Dual Relaxed Contrastive (DRC) loss [Yashima+,
RA-L25]を使用 ◼ MLLMを用いて類似画像にUnlabeled Positiveを付与 ◼ Unlabeled Positiveを考慮し,対照性を緩和する損失関数 :Unlabeled Positiveペアの添字集合
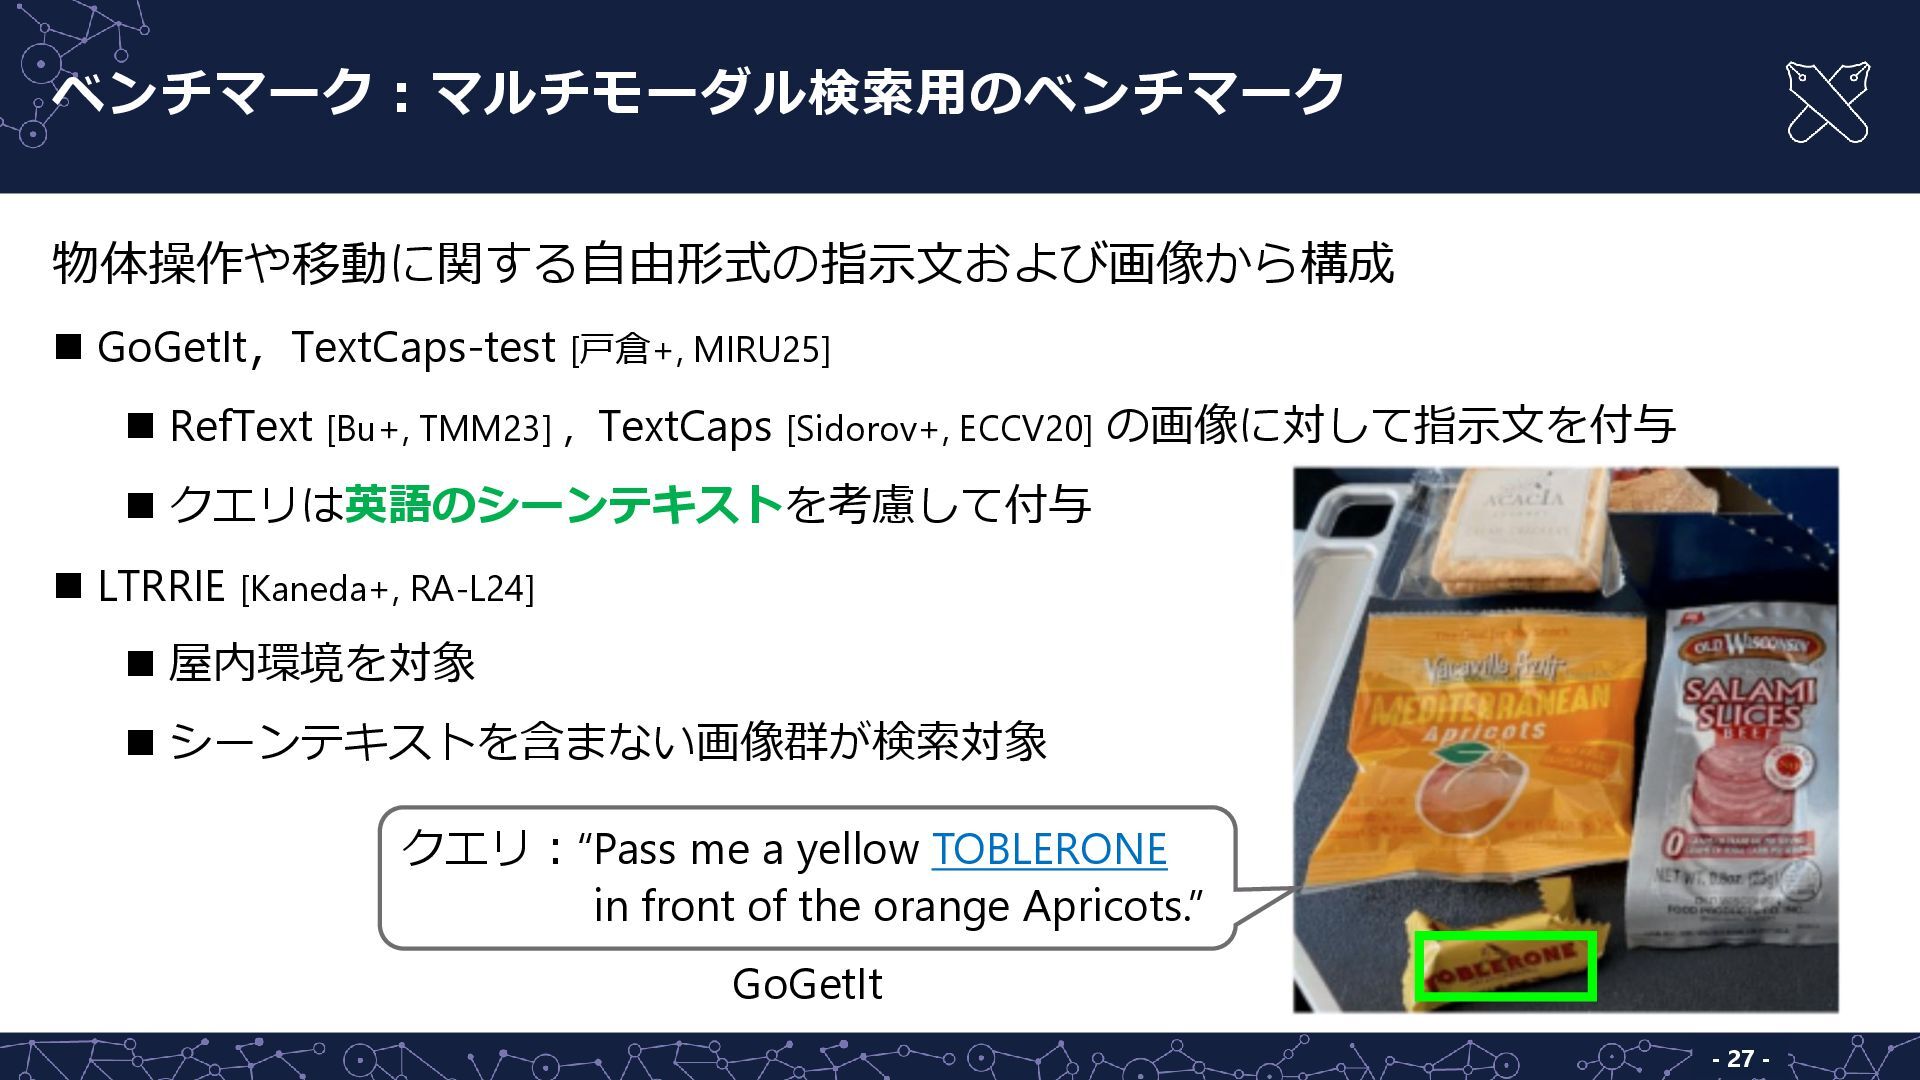
- 27 - ベンチマーク:マルチモーダル検索用のベンチマーク 物体操作や移動に関する自由形式の指示文および画像から構成 ◼ GoGetIt,TextCaps-test [戸倉+, MIRU25] ◼
RefText [Bu+, TMM23] ,TextCaps [Sidorov+, ECCV20] の画像に対して指示文を付与 ◼ クエリは英語のシーンテキストを考慮して付与 ◼ LTRRIE [Kaneda+, RA-L24] ◼ 屋内環境を対象 ◼ シーンテキストを含まない画像群が検索対象 クエリ:“Pass me a yellow TOBLERONE in front of the orange Apricots.” GoGetIt
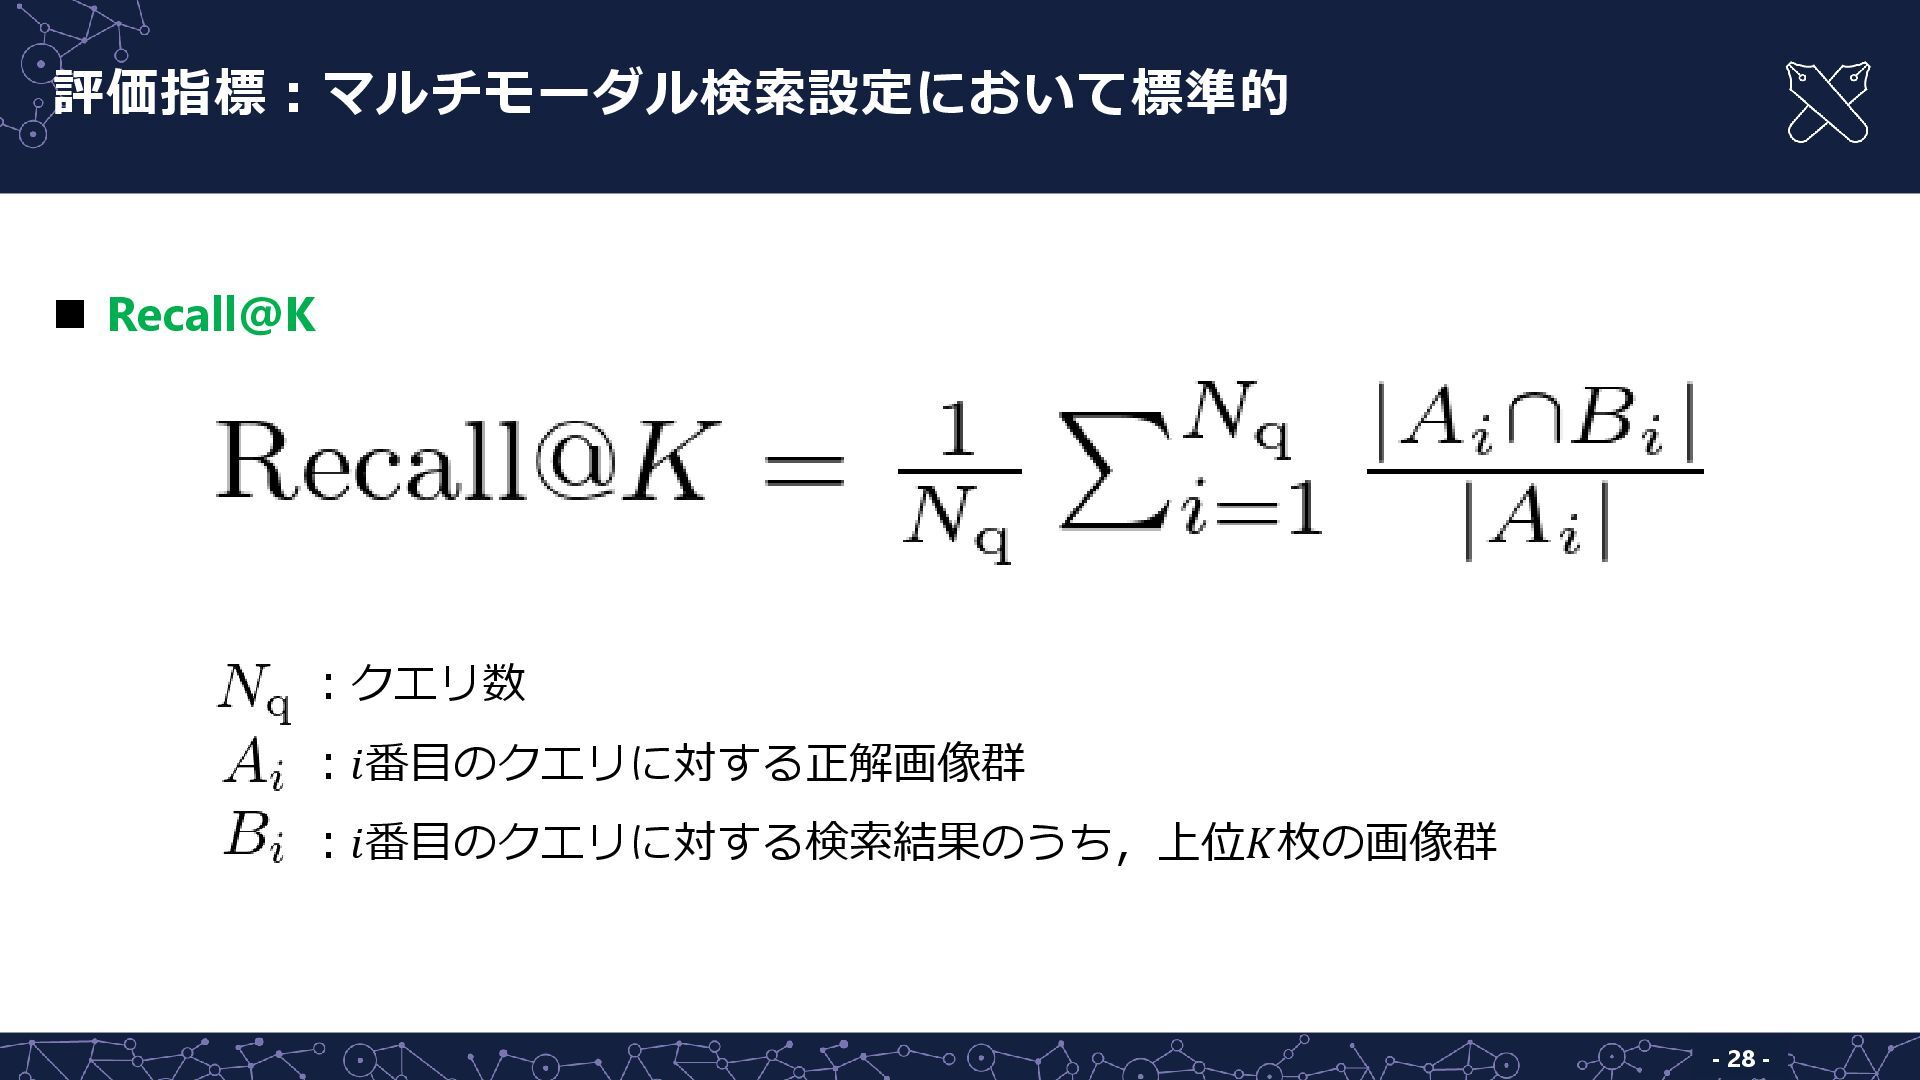
- 28 - 評価指標:マルチモーダル検索設定において標準的 ◼ Recall@K :クエリ数 :𝑖番目のクエリに対する正解画像群 :𝑖番目のクエリに対する検索結果のうち,上位𝐾枚の画像群
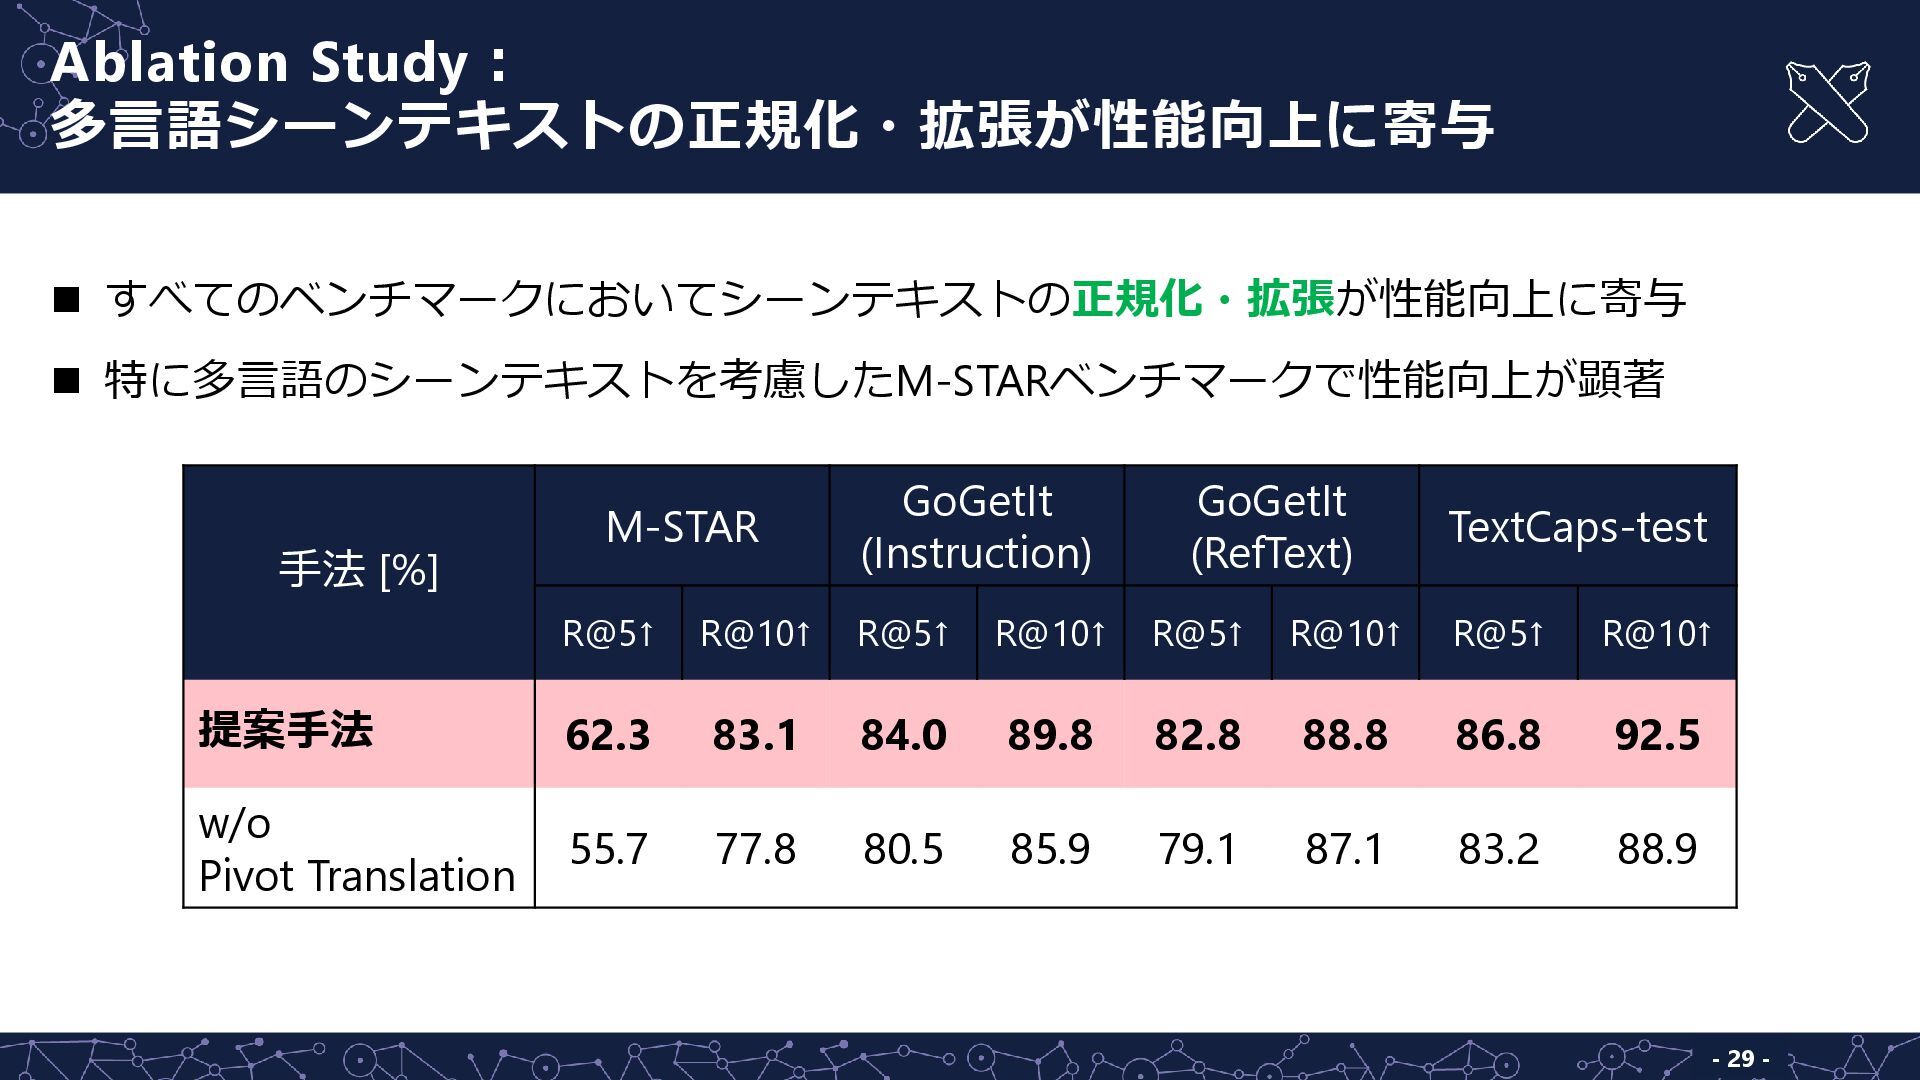
Ablation Study: 多言語シーンテキストの正規化・拡張が性能向上に寄与 - 29 - 手法 [%] M-STAR GoGetIt
(Instruction) GoGetIt (RefText) TextCaps-test R@5↑ R@10↑ R@5↑ R@10↑ R@5↑ R@10↑ R@5↑ R@10↑ 提案手法 62.3 83.1 84.0 89.8 82.8 88.8 86.8 92.5 w/o Pivot Translation 55.7 77.8 80.5 85.9 79.1 87.1 83.2 88.9 ◼ すべてのベンチマークにおいてシーンテキストの正規化・拡張が性能向上に寄与 ◼ 特に多言語のシーンテキストを考慮したM-STARベンチマークで性能向上が顕著
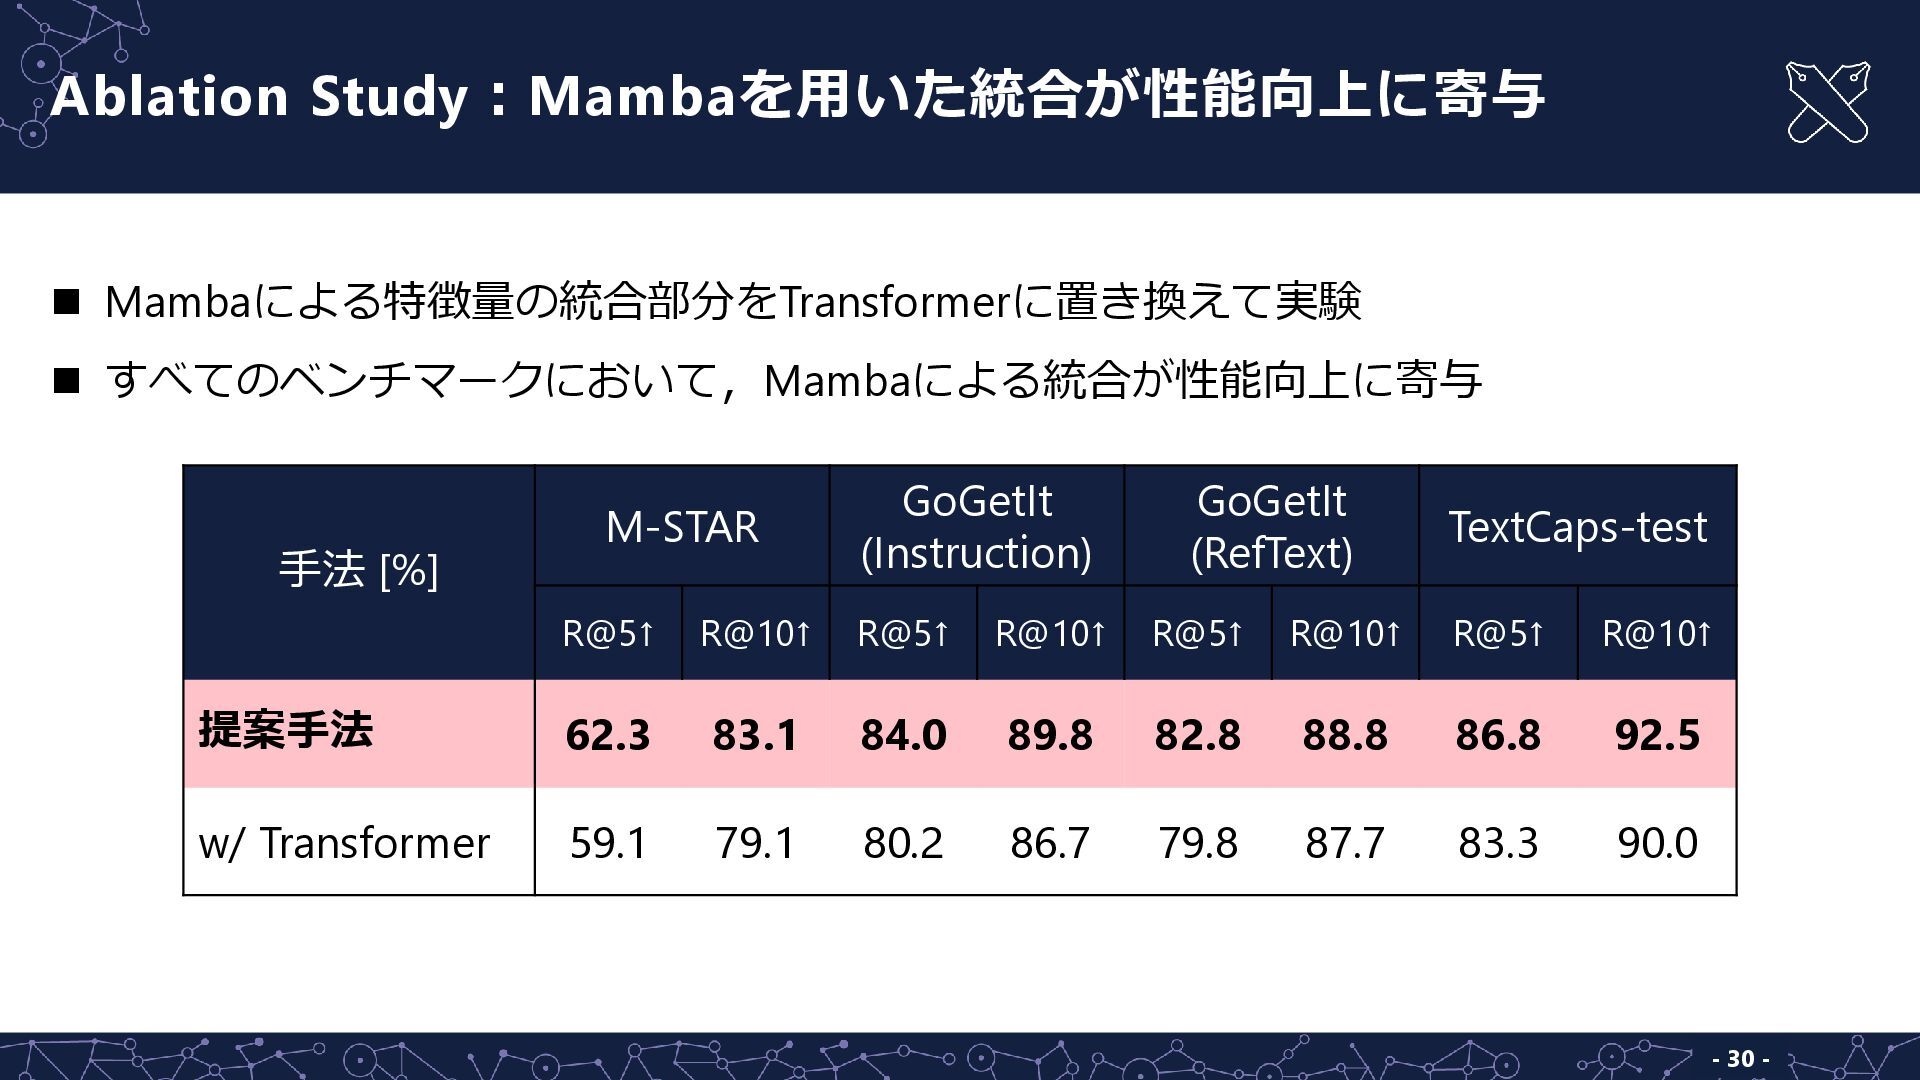
Ablation Study:Mambaを用いた統合が性能向上に寄与 - 30 - 手法 [%] M-STAR GoGetIt (Instruction)
GoGetIt (RefText) TextCaps-test R@5↑ R@10↑ R@5↑ R@10↑ R@5↑ R@10↑ R@5↑ R@10↑ 提案手法 62.3 83.1 84.0 89.8 82.8 88.8 86.8 92.5 w/ Transformer 59.1 79.1 80.2 86.7 79.8 87.7 83.3 90.0 ◼ Mambaによる特徴量の統合部分をTransformerに置き換えて実験 ◼ すべてのベンチマークにおいて,Mambaによる統合が性能向上に寄与
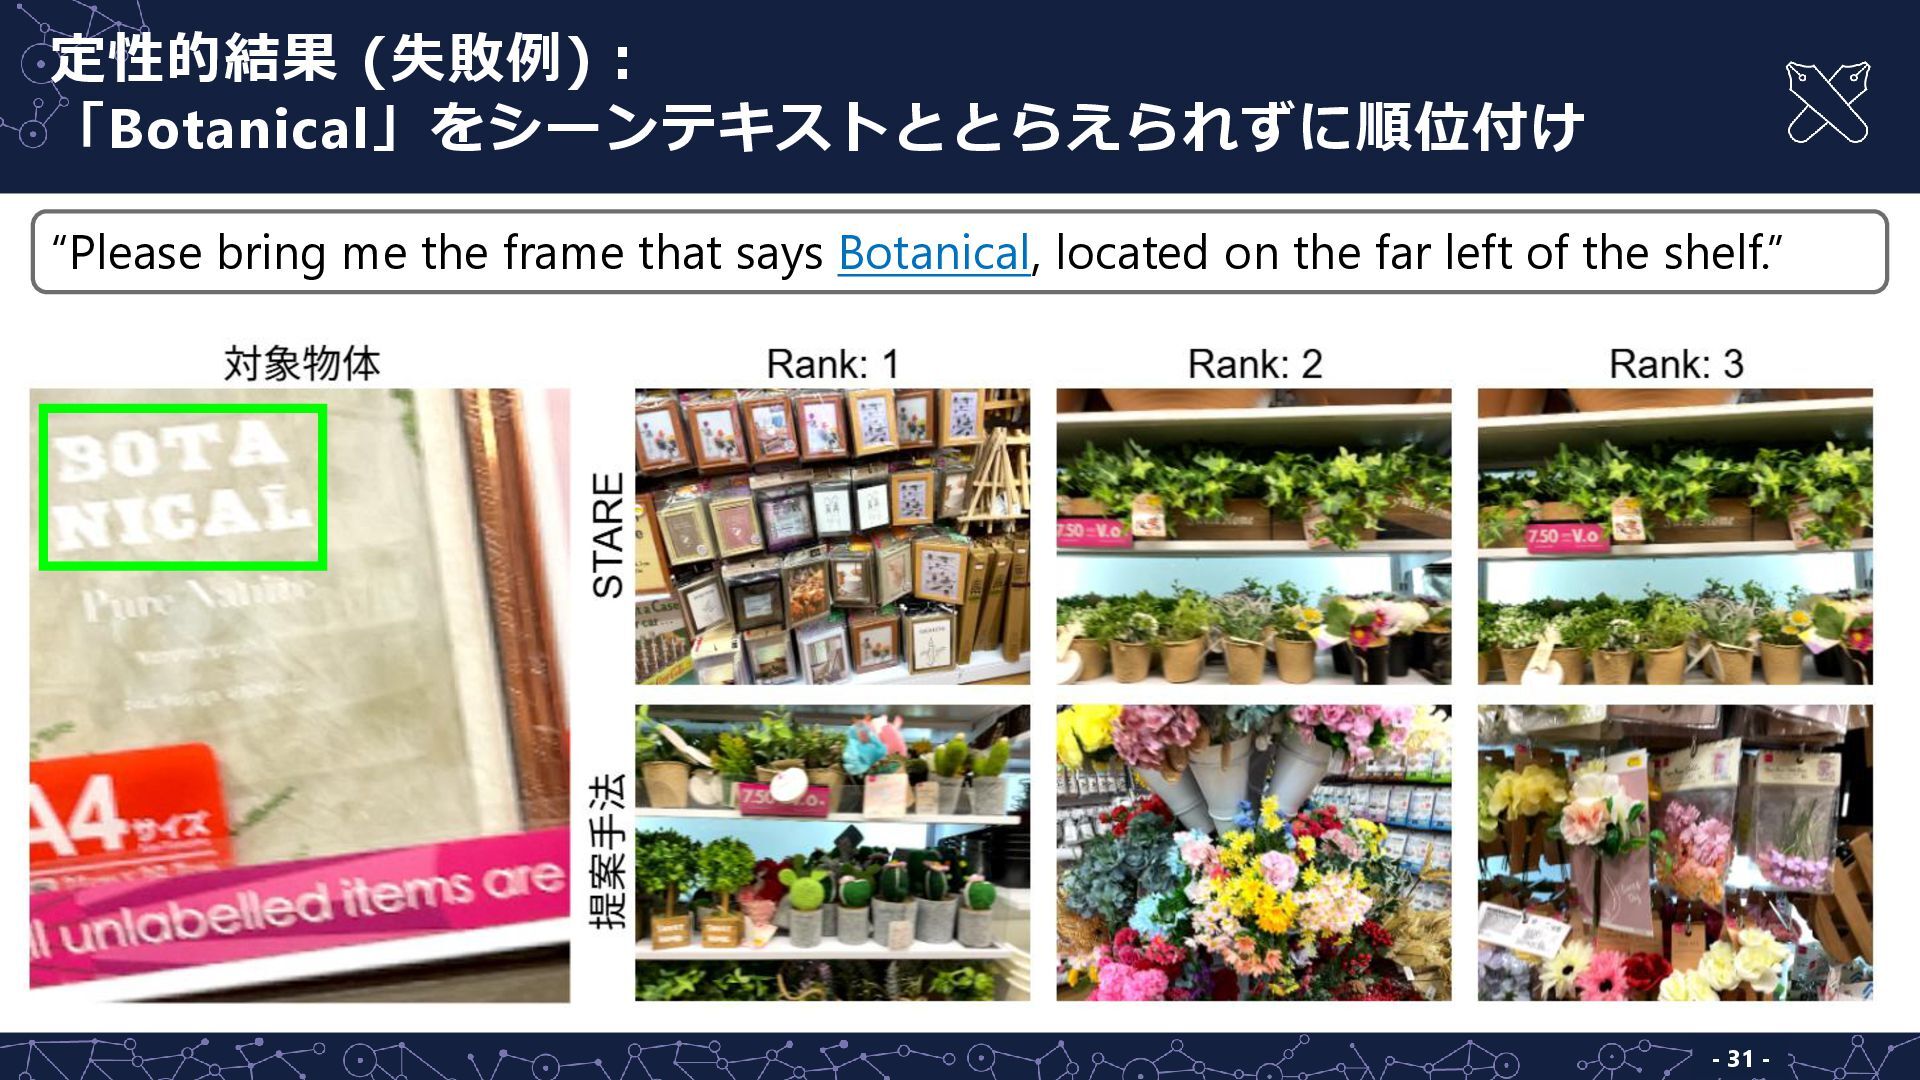
- 31 - 定性的結果 (失敗例): 「Botanical」をシーンテキストととらえられずに順位付け “Please bring me the
frame that says Botanical, located on the far left of the shelf.”
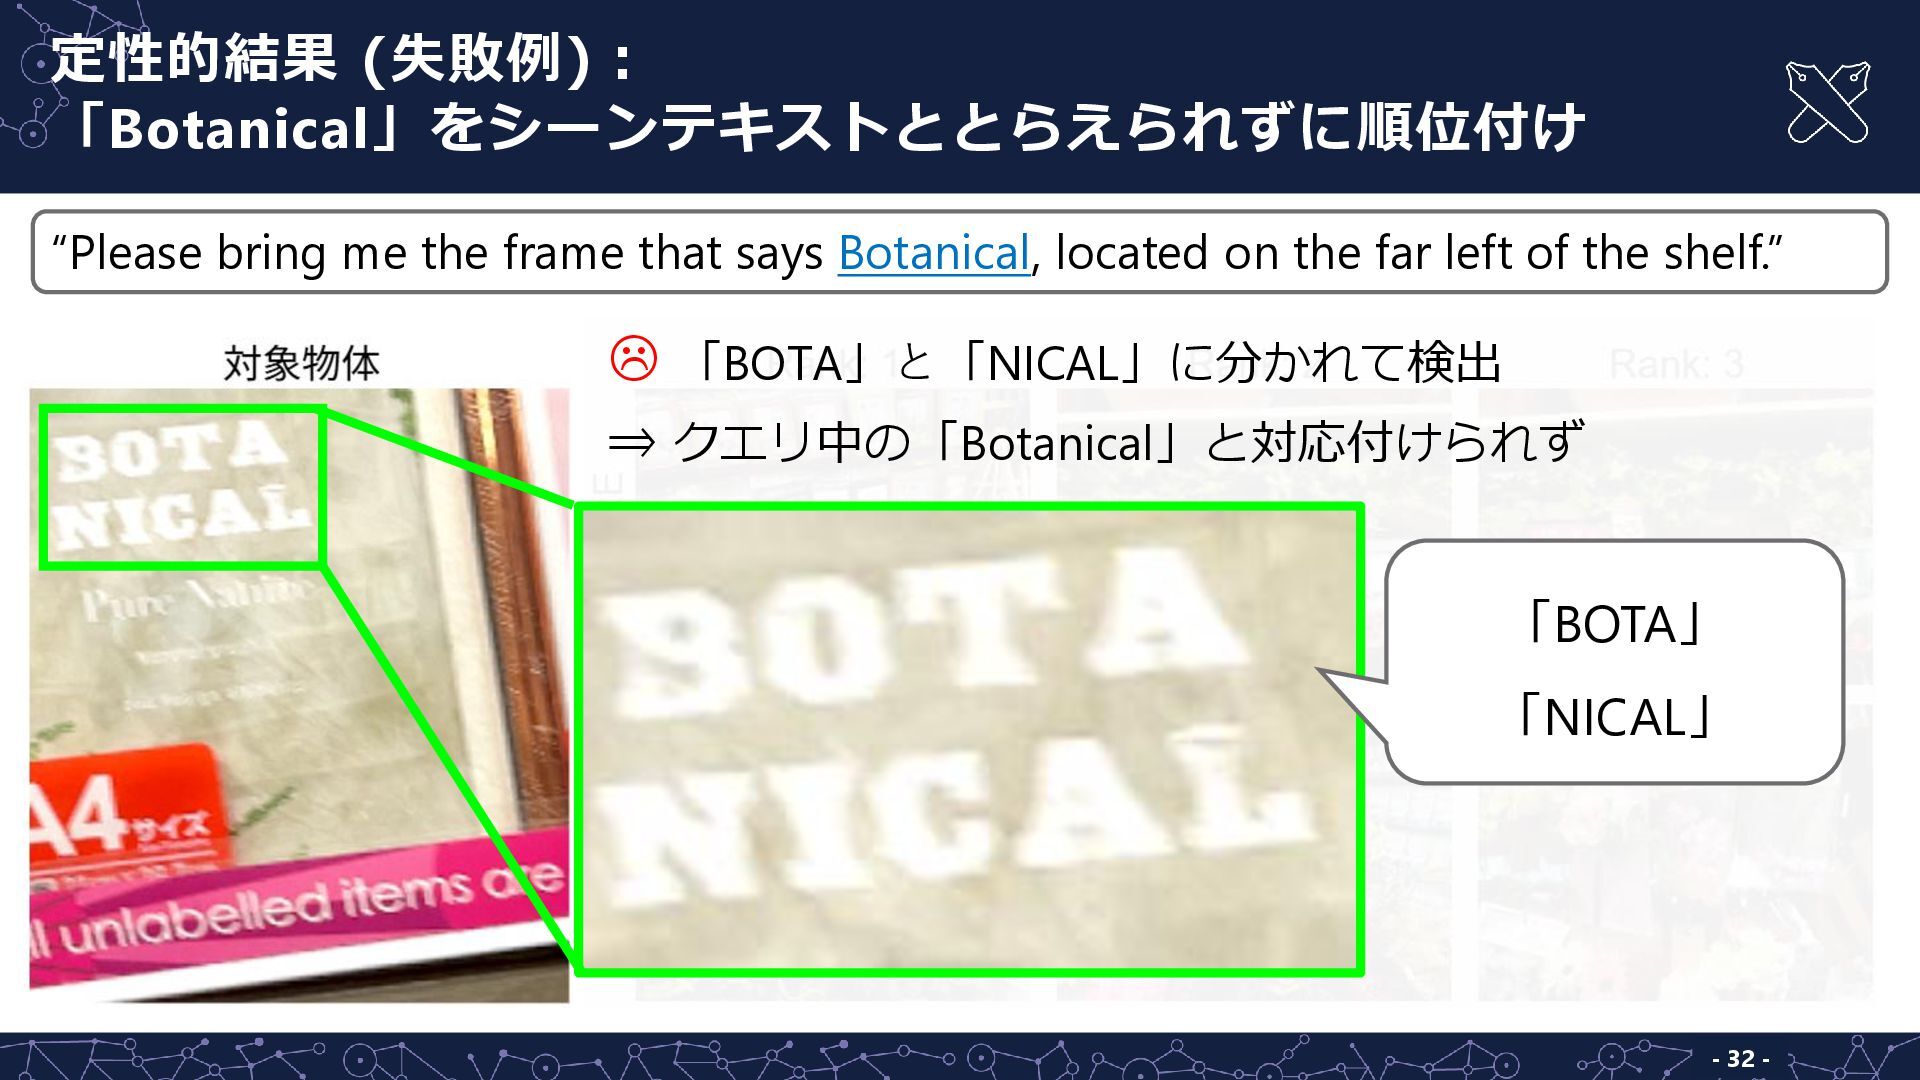
- 32 - 定性的結果 (失敗例): 「Botanical」をシーンテキストととらえられずに順位付け “Please bring me the
frame that says Botanical, located on the far left of the shelf.” 「BOTA」と「NICAL」に分かれて検出 ⇒ クエリ中の「Botanical」と対応付けられず 「BOTA」 「NICAL」


 keio_smilab
 pfn
 recruitengineers
 kzkhykw1991
 ivry_presentationmaterials
 kentapapa
 tomokusaba
 occhi
 ymotongpoo
 bgpat
 teamlab
 gionn
 carmenintech
 cassininazir
 jcasabona
 tmiket
 axbom
 dougneiner
 mojombo
 baasie
 sachag
 thirion
 mfonobong
 lcolladotor