Share
Embed
Pub/Sub and DataFlow
Krunal Kapadiya
August 29, 2021
Transcript
32 slides
-
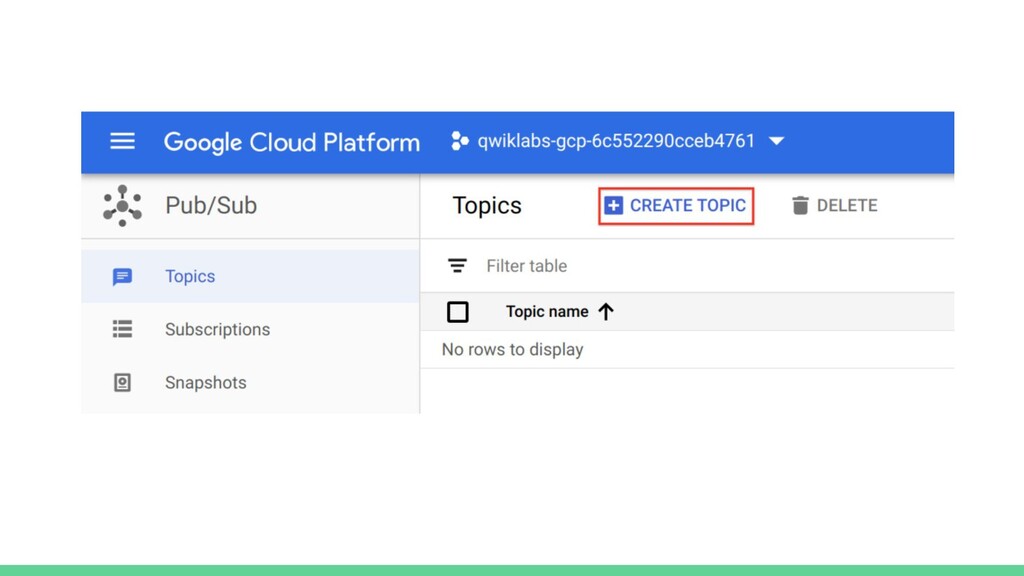
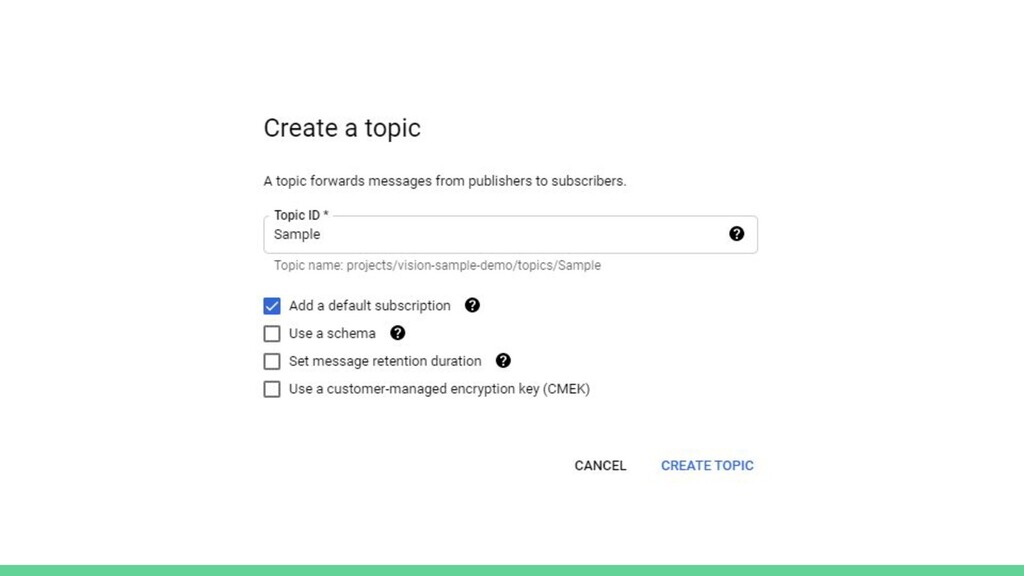
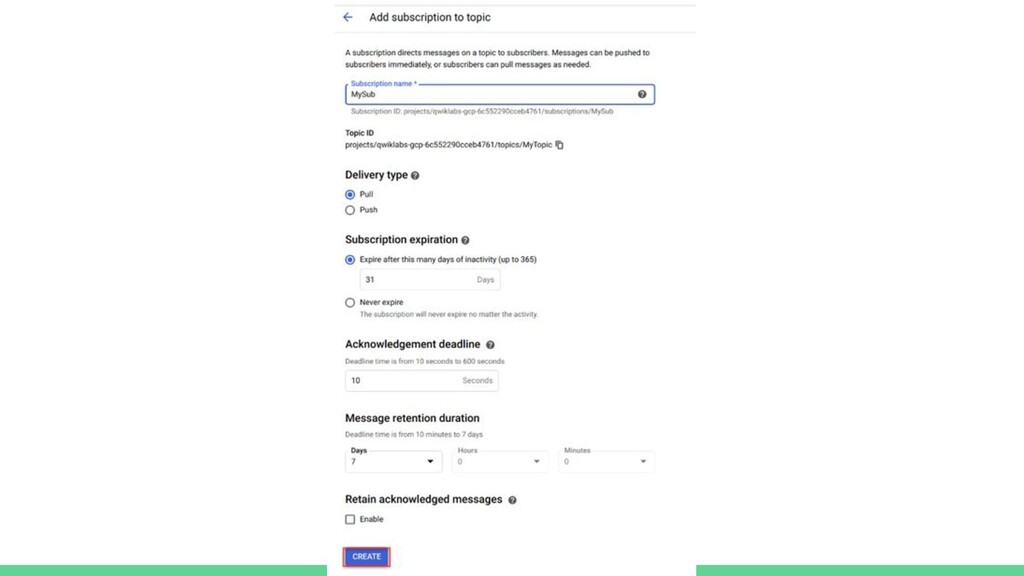
Agenda - Pub/Sub Core Concepts - How to Create PubSub
topic - Benefits of PubSub - What DataFlow Supports - Data Pipelines - DataFlow Worker - Example of DataFlow - Benefits of DataFlow -
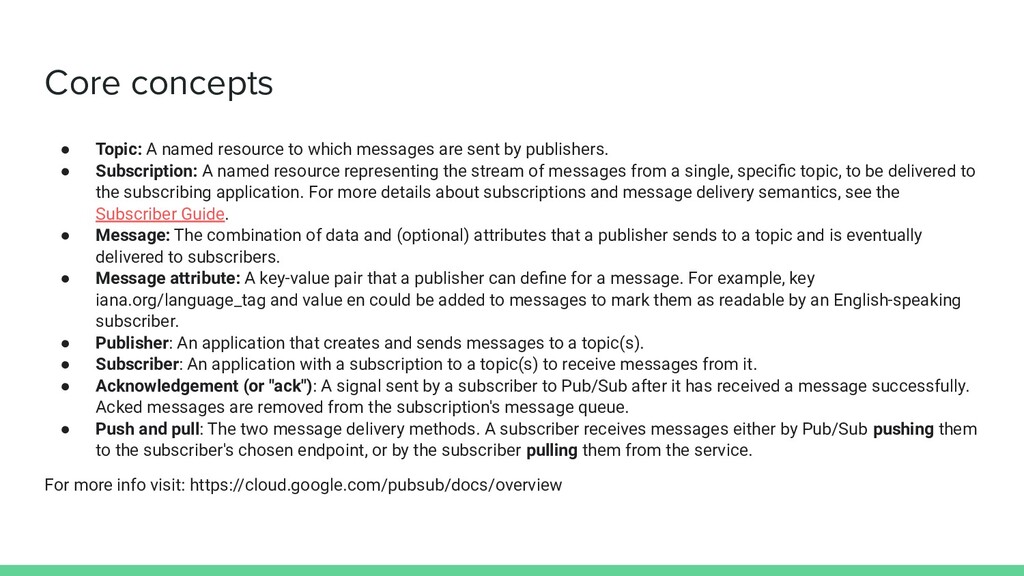
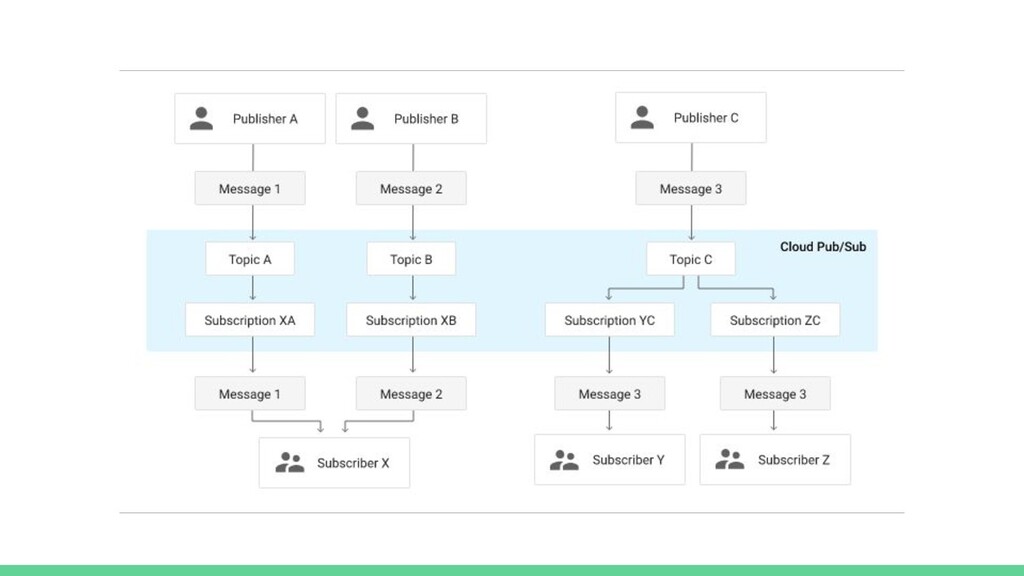
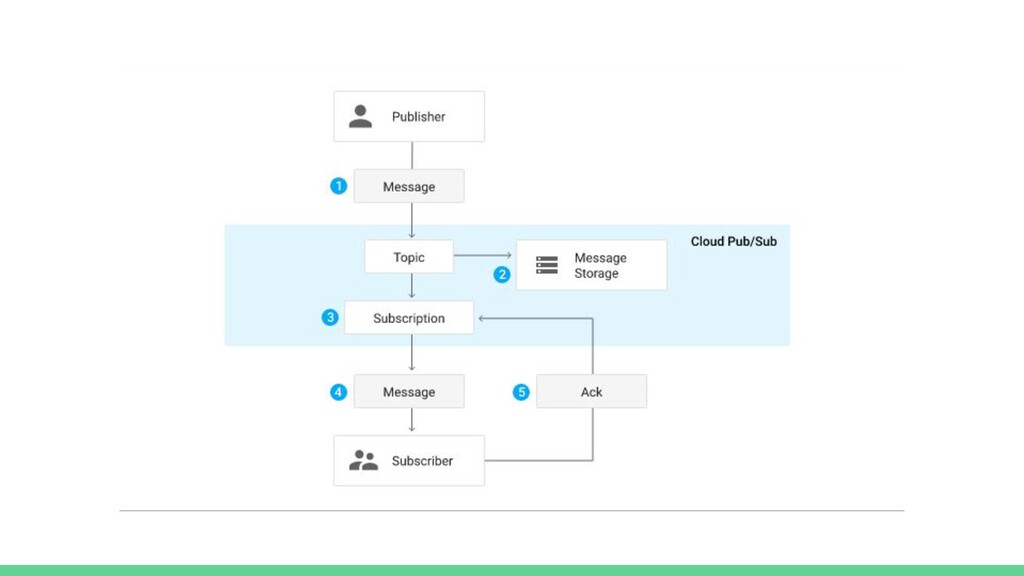
Core concepts • Topic: A named resource to which messages
are sent by publishers. • Subscription: A named resource representing the stream of messages from a single, specific topic, to be delivered to the subscribing application. For more details about subscriptions and message delivery semantics, see the Subscriber Guide. • Message: The combination of data and (optional) attributes that a publisher sends to a topic and is eventually delivered to subscribers. • Message attribute: A key-value pair that a publisher can define for a message. For example, key iana.org/language_tag and value en could be added to messages to mark them as readable by an English-speaking subscriber. • Publisher: An application that creates and sends messages to a topic(s). • Subscriber: An application with a subscription to a topic(s) to receive messages from it. • Acknowledgement (or "ack"): A signal sent by a subscriber to Pub/Sub after it has received a message successfully. Acked messages are removed from the subscription's message queue. • Push and pull: The two message delivery methods. A subscriber receives messages either by Pub/Sub pushing them to the subscriber's chosen endpoint, or by the subscriber pulling them from the service. For more info visit: https://cloud.google.com/pubsub/docs/overview -
What DataFlow Supports - Create Job From Template - Create
Job From SQL - To Run Jupyter Notebook, Notebooks API Available for No-GPU and NVIDIA Tesla T4 - Can Save Snapshots from the Running Jobs - Need data in BigQuery/Storage/PubSub and Endpoint will be Storage - Do not support SaaS apps, like Facebook Ads, SalesForce and Stripe - Supports Python and Java APIs - For Streaming uses Pub/Sub API -
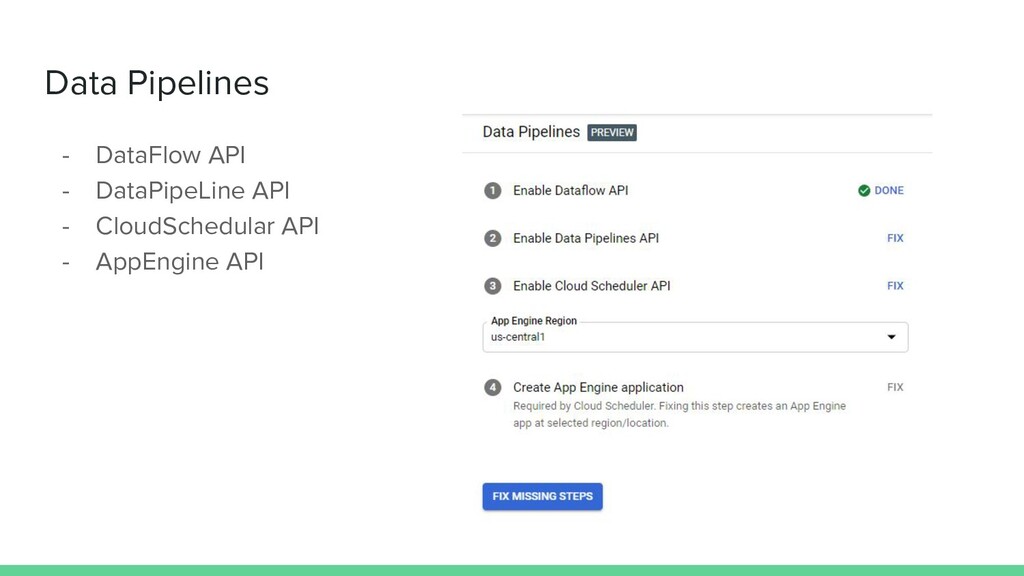
Data Pipelines - DataFlow API - DataPipeLine API - CloudSchedular
API - AppEngine API -
Dataflow workers consume the following resources, each billed on a
per second basis. • vCPU • Memory • Storage: Persistent Disk • GPU (optional) -
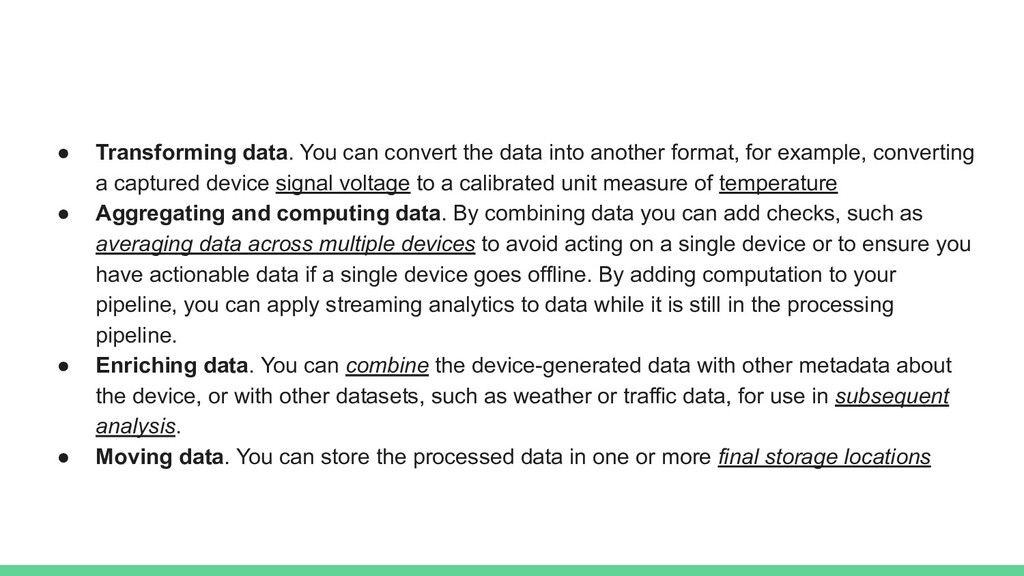
• Transforming data. You can convert the data into another
format, for example, converting a captured device signal voltage to a calibrated unit measure of temperature • Aggregating and computing data. By combining data you can add checks, such as averaging data across multiple devices to avoid acting on a single device or to ensure you have actionable data if a single device goes offline. By adding computation to your pipeline, you can apply streaming analytics to data while it is still in the processing pipeline. • Enriching data. You can combine the device-generated data with other metadata about the device, or with other datasets, such as weather or traffic data, for use in subsequent analysis. • Moving data. You can store the processed data in one or more final storage locations -
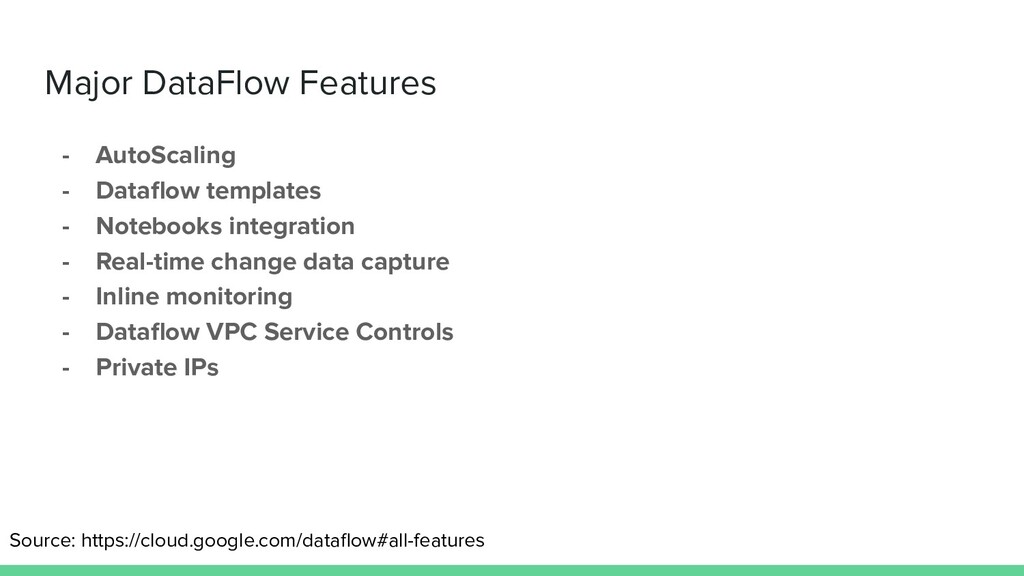
Major DataFlow Features - AutoScaling - Dataflow templates - Notebooks
integration - Real-time change data capture - Inline monitoring - Dataflow VPC Service Controls - Private IPs Source: https://cloud.google.com/dataflow#all-features -
Pub/Sub Data FIRST_NAMES = ['Monet', 'Julia', 'Angelique', 'Stephane', 'Allan', 'Ulrike',
'Vella', 'Melia', 'Noel', 'Terrence', 'Leigh', 'Rubin', 'Tanja', 'Shirlene', 'Deidre', 'Dorthy', 'Leighann', 'Mamie', 'Gabriella', 'Tanika', 'Kennith', 'Merilyn', 'Tonda', 'Adolfo', 'Von', 'Agnus', 'Kieth', 'Lisette', 'Hui', 'Lilliana',] CITIES = ['Washington', 'Springfield', 'Franklin', 'Greenville', 'Bristol', 'Fairview', 'Salem', 'Madison', 'Georgetown', 'Arlington', 'Ashland',] STATES = ['MO','SC','IN','CA','IA','DE','ID','AK','NE','VA','PR','IL','ND','OK','VT','DC','CO','MS', 'CT','ME','MN','NV','HI','MT','PA','SD','WA','NJ','NC','WV','AL','AR','FL','NM','KY','GA','MA', 'KS','VI','MI','UT','AZ','WI','RI','NY','TN','OH','TX','AS','MD','OR','MP','LA','WY','GU','NH'] PRODUCTS = ['Product 2', 'Product 2 XL', 'Product 3', 'Product 3 XL', 'Product 4', 'Product 4 XL', 'Product 5', 'Product 5 XL',] -
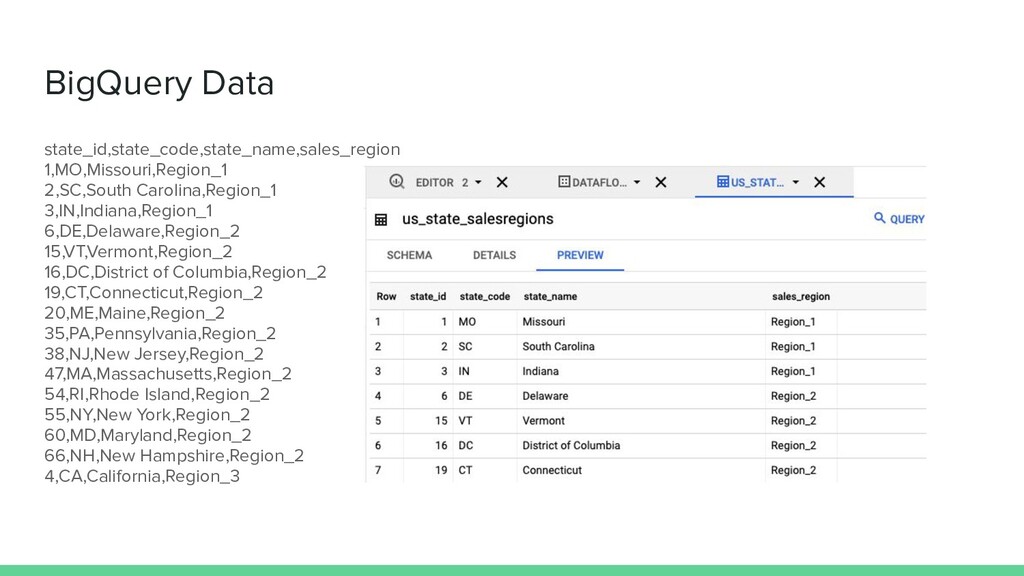
BigQuery Data state_id,state_code,state_name,sales_region 1,MO,Missouri,Region_1 2,SC,South Carolina,Region_1 3,IN,Indiana,Region_1 6,DE,Delaware,Region_2 15,VT,Vermont,Region_2 16,DC,District
of Columbia,Region_2 19,CT,Connecticut,Region_2 20,ME,Maine,Region_2 35,PA,Pennsylvania,Region_2 38,NJ,New Jersey,Region_2 47,MA,Massachusetts,Region_2 54,RI,Rhode Island,Region_2 55,NY,New York,Region_2 60,MD,Maryland,Region_2 66,NH,New Hampshire,Region_2 4,CA,California,Region_3 -
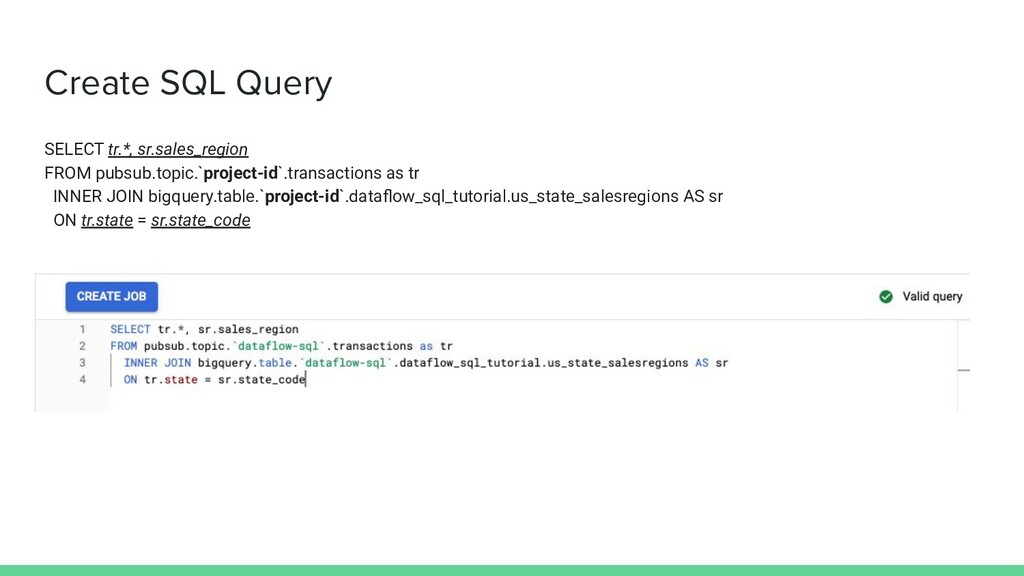
Create SQL Query SELECT tr.*, sr.sales_region FROM pubsub.topic.`project-id`.transactions as tr
INNER JOIN bigquery.table.`project-id`.dataflow_sql_tutorial.us_state_salesregions AS sr ON tr.state = sr.state_code -
Workers • You can override default worker count for the
job • For autoscalling need to specify maximum numbers of workers needs to be allotted. -
Data Pipeline use restrictions • Quota limits: ◦ Max num
of pipelines per project: 500 ◦ Max num of pipelines per organization: 2500 • Available only App-Engine supported regions only -
References - https://cloud.google.com/pubsub/docs/overview - https://googlecoursera.qwiklabs.com/focuses/17398882 - https://cloud.google.com/products/calculator - https://cloud.google.com/about/locations -
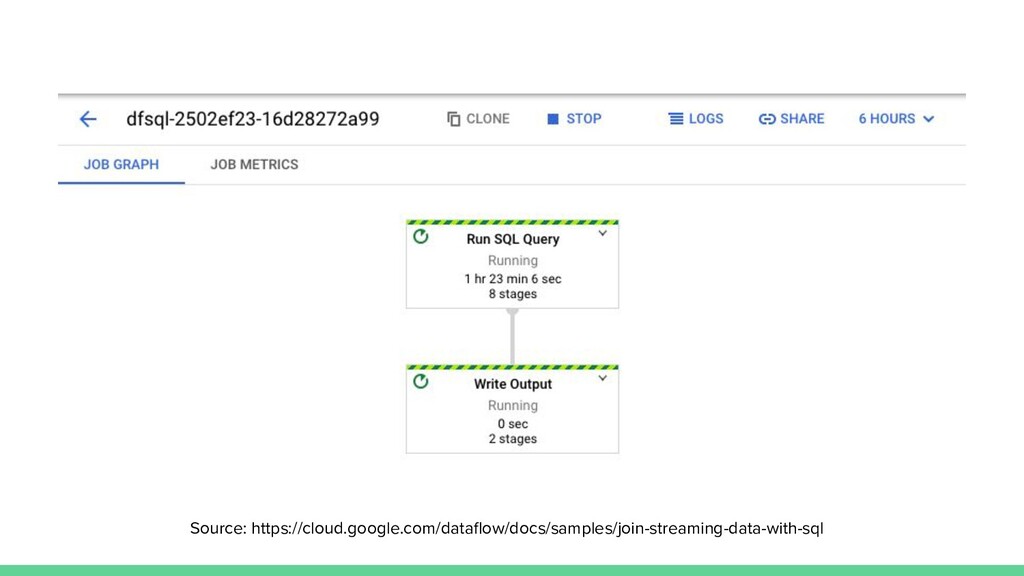
https://cloud.google.com/dataflow/docs/samples/join-streaming-data-with-sql