Share
Embed
Khmer ASR using Deep Learning
Mann
May 04, 2016
Transcript
27 slides
-
Toward Deep Learning on Speech Recognition for Khmer Language Author:
Chanmann Lim Faculty Advisor: Dr. Yunxin Zhao 05/04/2016 University of Missouri-Columbia 1 -
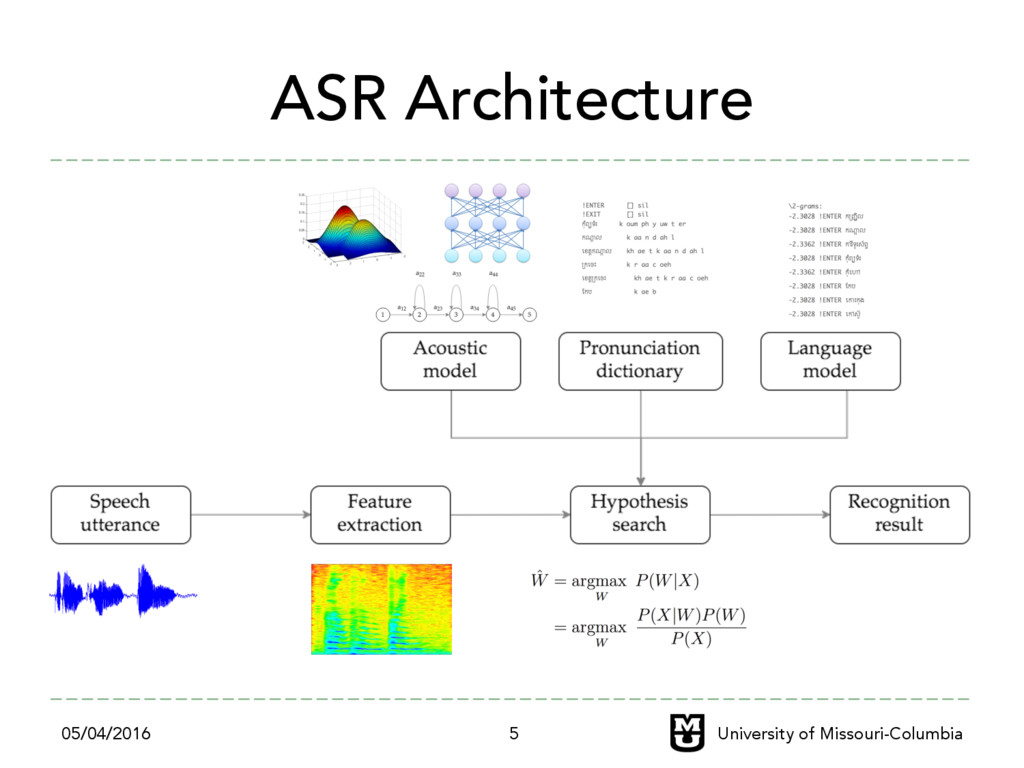
Agenda ‣ ASR Architecture ‣ Motivation and Khmer Dataset ‣
Data-preprocessing ‣ Acoustic Modeling and Results ‣ Conclusion 05/04/2016 University of Missouri-Columbia 2 -
Agenda ‣ ASR Architecture ‣ Motivation and Khmer Dataset ‣
Data-preprocessing ‣ Acoustic Modeling and Results ‣ Conclusion 05/04/2016 University of Missouri-Columbia 3 -
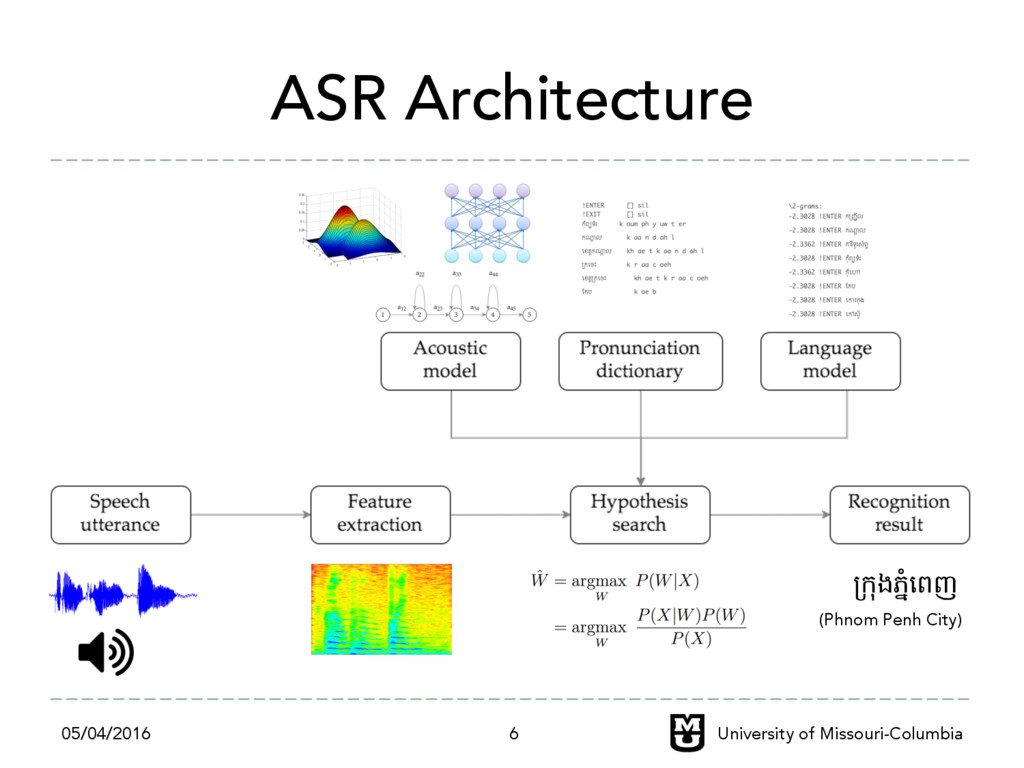
Agenda ‣ ASR Architecture ‣ Motivation and Khmer Dataset ‣
Data-preprocessing ‣ Acoustic Modeling and Results ‣ Conclusion 05/04/2016 University of Missouri-Columbia 7 -
Motivation ‣ Building an ASR for a new language remains
challenging – Lack of training data – Interdisciplinary field of research (linguistic, signal processing and machine learning) ‣ To build ASR for my own language ``Khmer (+្"រ)” ‣ To preserve Khmer language in this modern digital age 05/04/2016 University of Missouri-Columbia 8 -
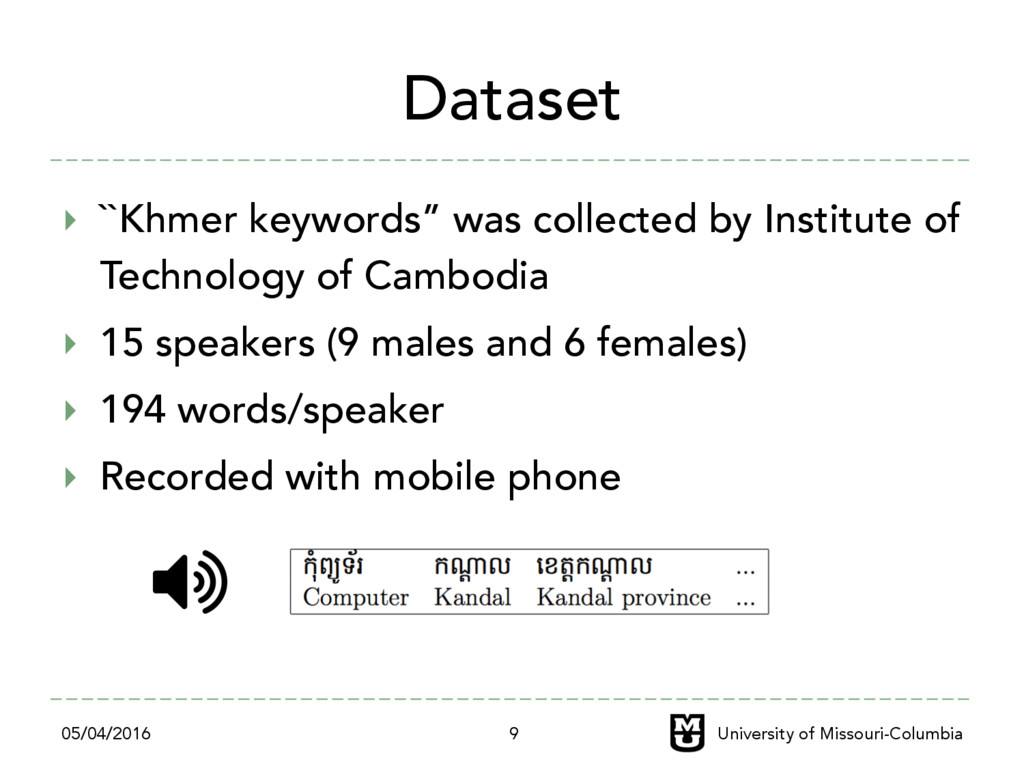
Dataset ‣ ``Khmer keywords” was collected by Institute of Technology
of Cambodia ‣ 15 speakers (9 males and 6 females) ‣ 194 words/speaker ‣ Recorded with mobile phone 05/04/2016 University of Missouri-Columbia 9 -
Agenda ‣ ASR Architecture ‣ Motivation and Khmer Dataset ‣
Data-preprocessing ‣ Acoustic Modeling and Results ‣ Conclusion 05/04/2016 University of Missouri-Columbia 10 -
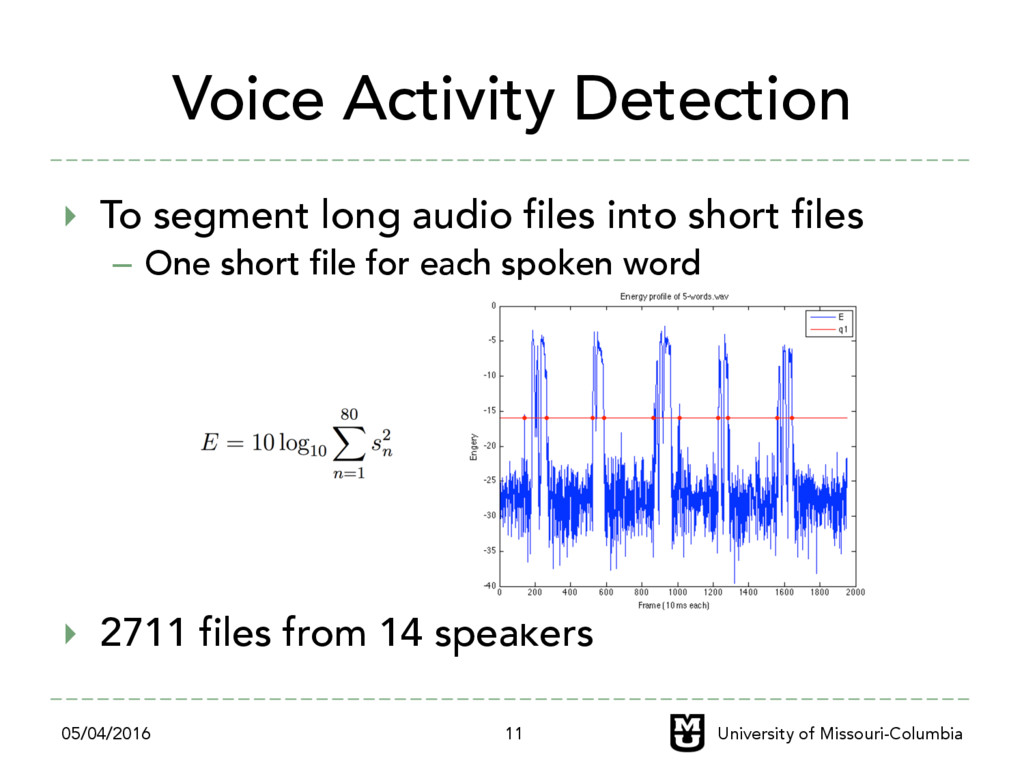
Voice Activity Detection ‣ To segment long audio files into
short files – One short file for each spoken word ‣ 2711 files from 14 speakers 05/04/2016 University of Missouri-Columbia 11 -
Training and test set ‣ 10 training speakers – 1934
utterances (254,458 frames) ‣ 4 test speakers – 777 utterances 05/04/2016 University of Missouri-Columbia 12 -
Agenda ‣ ASR Architecture ‣ Motivation and Khmer Dataset ‣
Data-preprocessing ‣ Acoustic Modeling and Results ‣ Conclusion 05/04/2016 University of Missouri-Columbia 13 -
1. Gaussian Mixture Model HMM ‣ Each state of HMMs
is represented by a GMM 05/04/2016 University of Missouri-Columbia 14 /p/ -
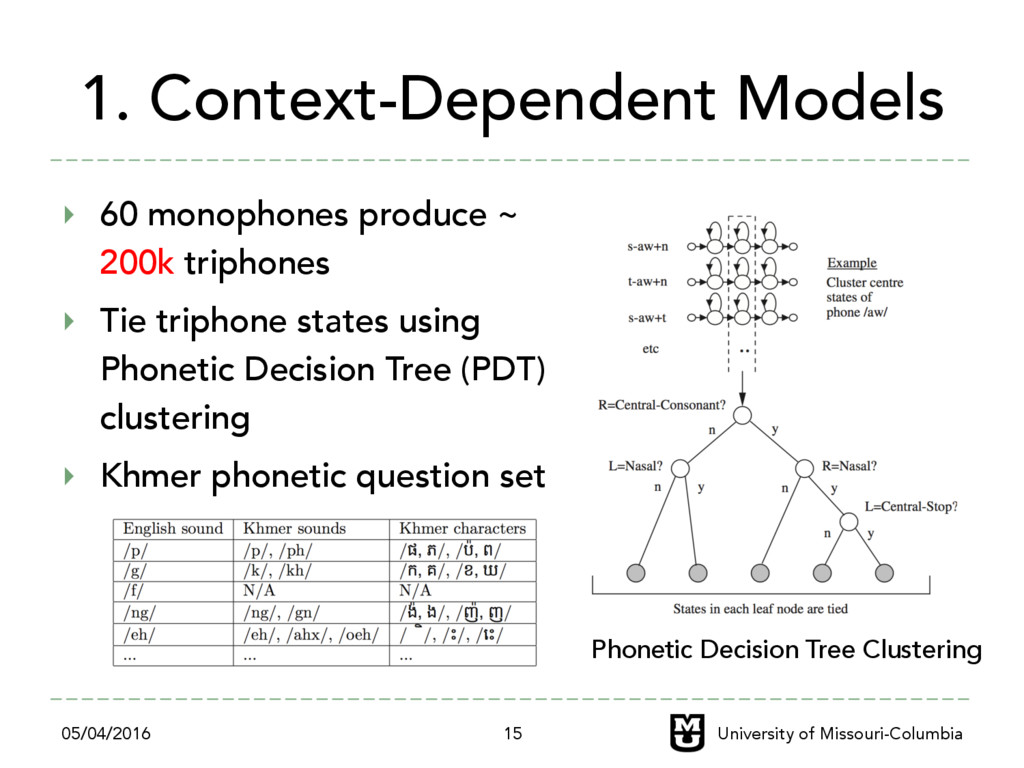
1. Context-Dependent Models ‣ 60 monophones produce ~ 200k triphones
‣ Tie triphone states using Phonetic Decision Tree (PDT) clustering ‣ Khmer phonetic question set 05/04/2016 University of Missouri-Columbia 15 Phonetic Decision Tree Clustering -
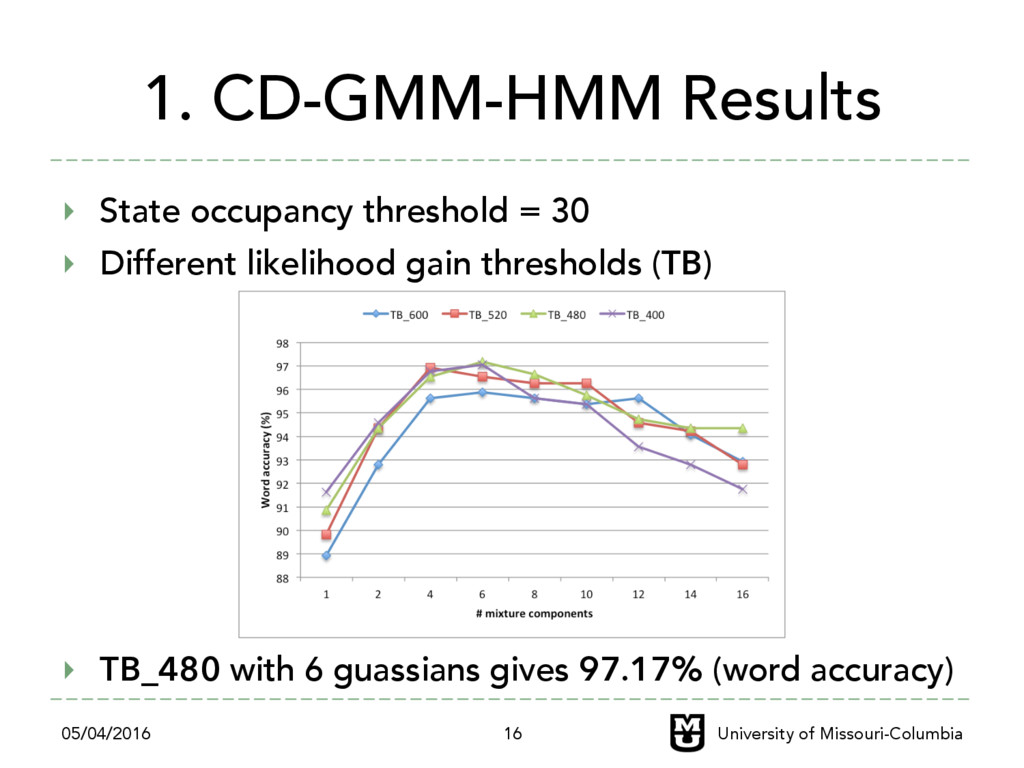
1. CD-GMM-HMM Results ‣ State occupancy threshold = 30 ‣
Different likelihood gain thresholds (TB) ‣ TB_480 with 6 guassians gives 97.17% (word accuracy) 05/04/2016 University of Missouri-Columbia 16 -
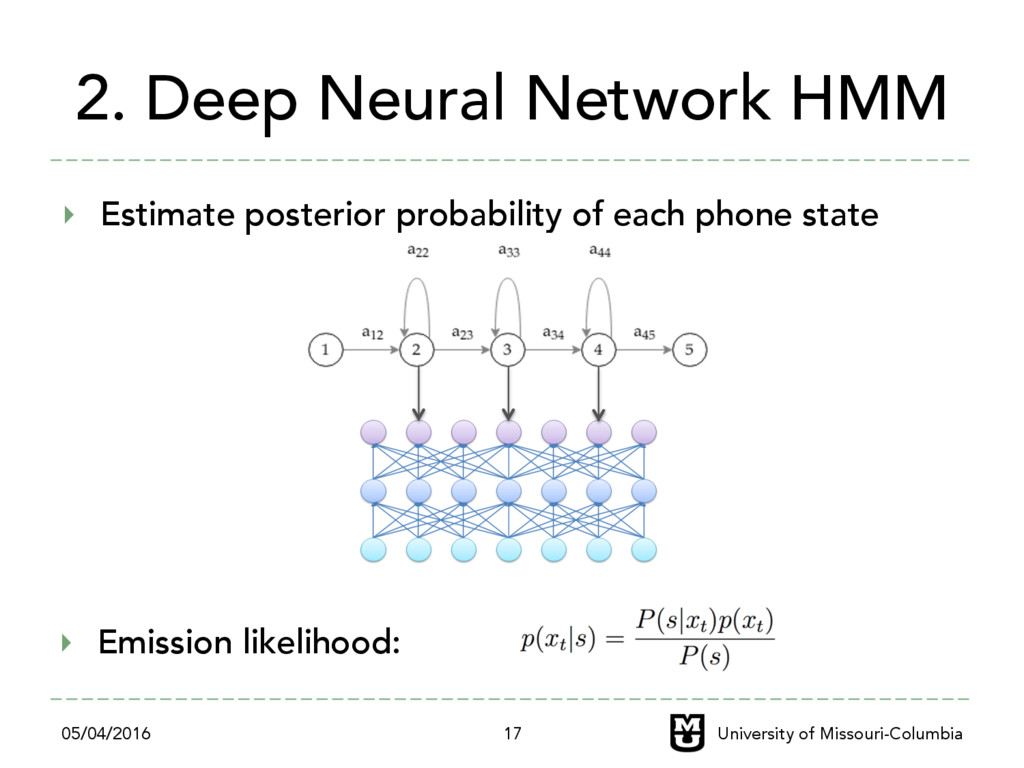
2. Deep Neural Network HMM ‣ Estimate posterior probability of
each phone state 05/04/2016 University of Missouri-Columbia 17 ‣ Emission likelihood: -
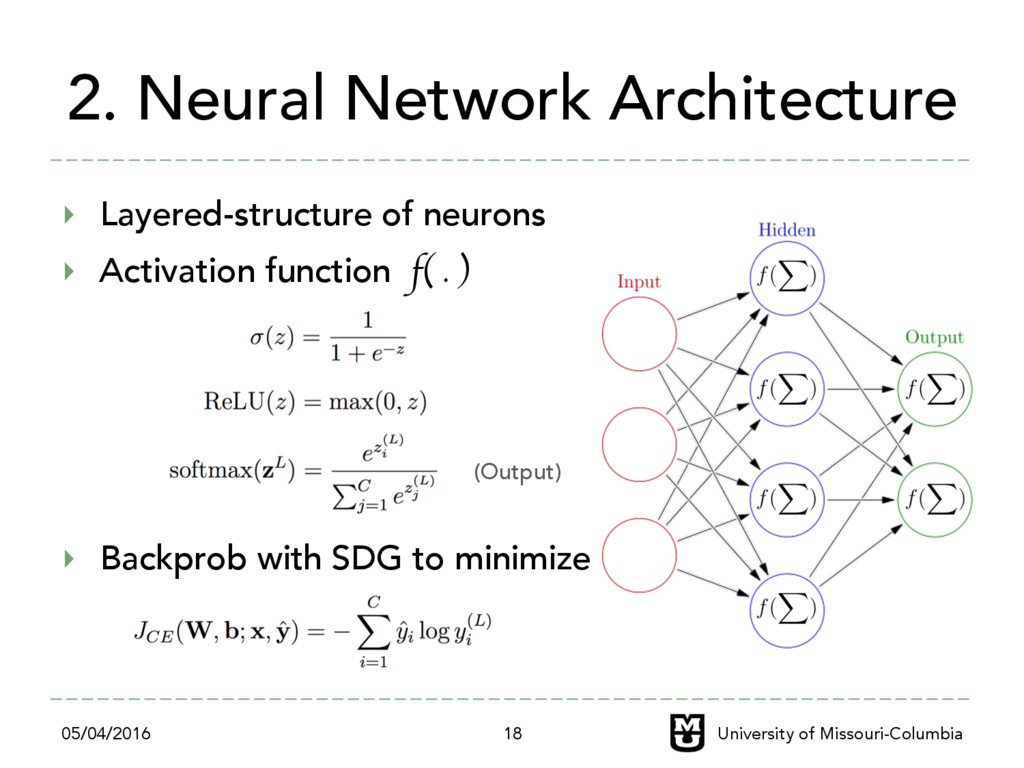
2. Neural Network Architecture ‣ Layered-structure of neurons ‣ Activation
function f( . ) ‣ Backprob with SDG to minimize 05/04/2016 University of Missouri-Columbia 18 (Output) -
2. Gradient Refinement ‣ Prevent gradient vanishing or explosion ‣
Popular techniques – Gradient Clipping: Clip the gradient once it exceed the threshold – Weight Decay: Penalize objective function by adding scaled L2-norm – Momentum: Speed up convergence by adding velocity from the previous gradient – Max-norm: Set the maximum L2-norm bound and scale the weight once it exceed the bound 05/04/2016 University of Missouri-Columbia 19 -
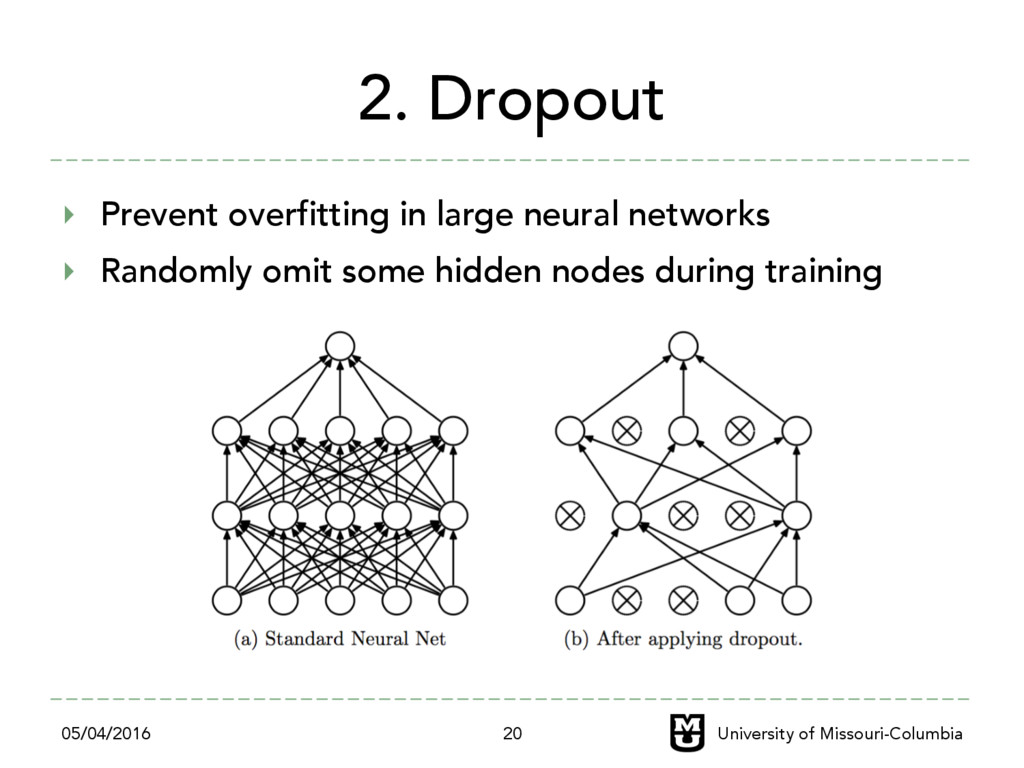
2. Dropout ‣ Prevent overfitting in large neural networks ‣
Randomly omit some hidden nodes during training 05/04/2016 University of Missouri-Columbia 20 -
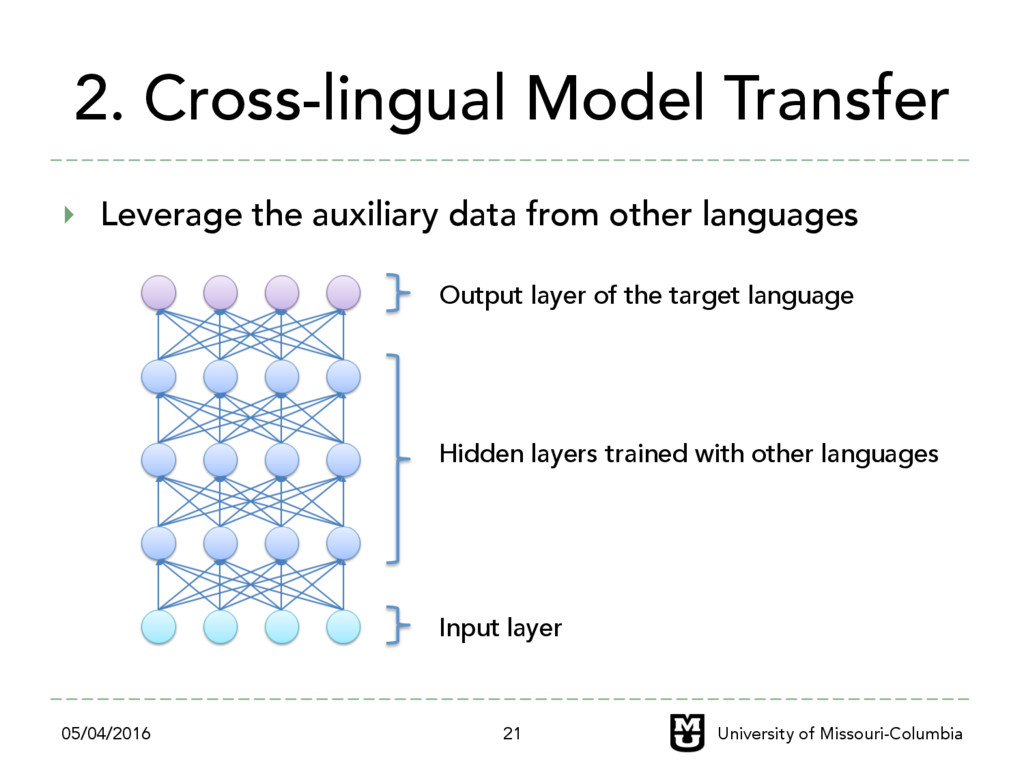
2. Cross-lingual Model Transfer ‣ Leverage the auxiliary data from
other languages 05/04/2016 University of Missouri-Columbia 21 Input layer Hidden layers trained with other languages Output layer of the target language -
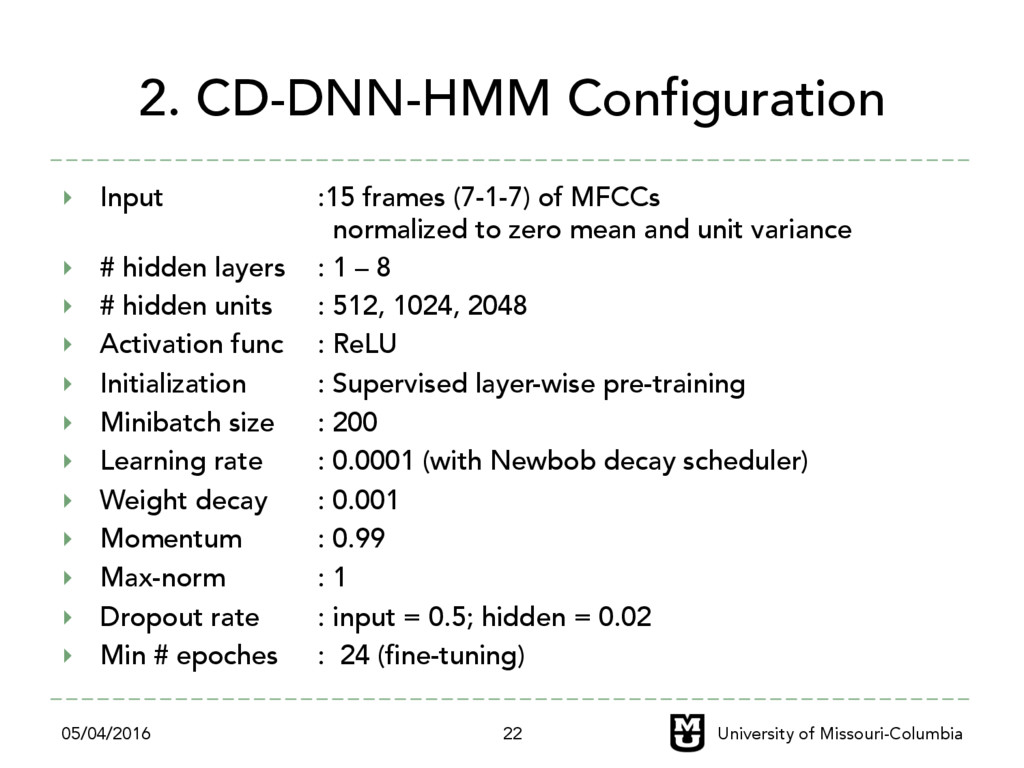
2. CD-DNN-HMM Configuration ‣ Input :15 frames (7-1-7) of MFCCs
normalized to zero mean and unit variance ‣ # hidden layers : 1 – 8 ‣ # hidden units : 512, 1024, 2048 ‣ Activation func : ReLU ‣ Initialization : Supervised layer-wise pre-training ‣ Minibatch size : 200 ‣ Learning rate : 0.0001 (with Newbob decay scheduler) ‣ Weight decay : 0.001 ‣ Momentum : 0.99 ‣ Max-norm : 1 ‣ Dropout rate : input = 0.5; hidden = 0.02 ‣ Min # epoches : 24 (fine-tuning) 05/04/2016 University of Missouri-Columbia 22 -
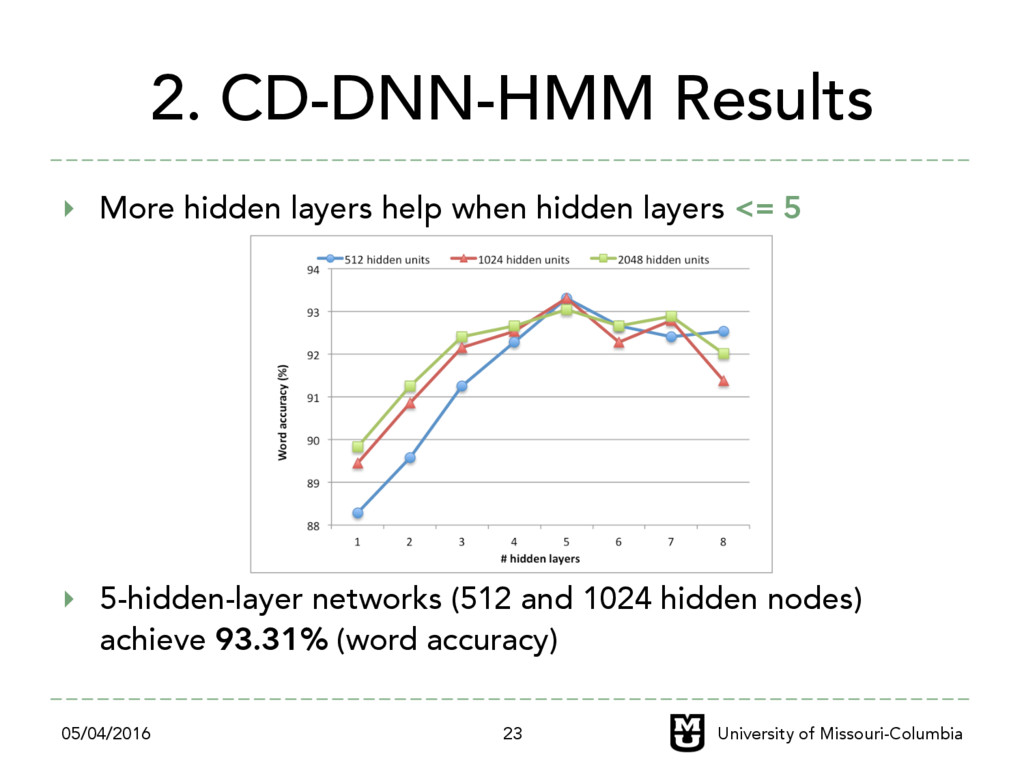
2. CD-DNN-HMM Results ‣ More hidden layers help when hidden
layers <= 5 ‣ 5-hidden-layer networks (512 and 1024 hidden nodes) achieve 93.31% (word accuracy) 05/04/2016 University of Missouri-Columbia 23 -
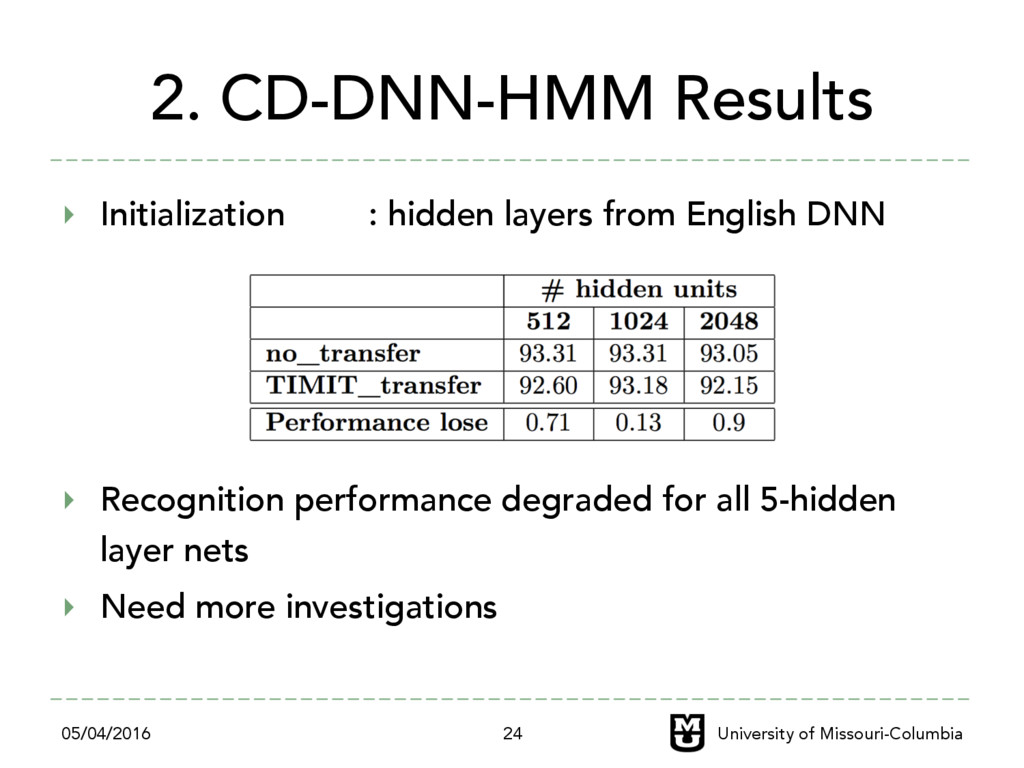
2. CD-DNN-HMM Results ‣ Initialization : hidden layers from English
DNN ‣ Recognition performance degraded for all 5-hidden layer nets ‣ Need more investigations 05/04/2016 University of Missouri-Columbia 24 -
Agenda ‣ ASR Architecture ‣ Motivation and Khmer Dataset ‣
Data-preprocessing ‣ Acoustic Modeling and Results ‣ Conclusion 05/04/2016 University of Missouri-Columbia 25 -
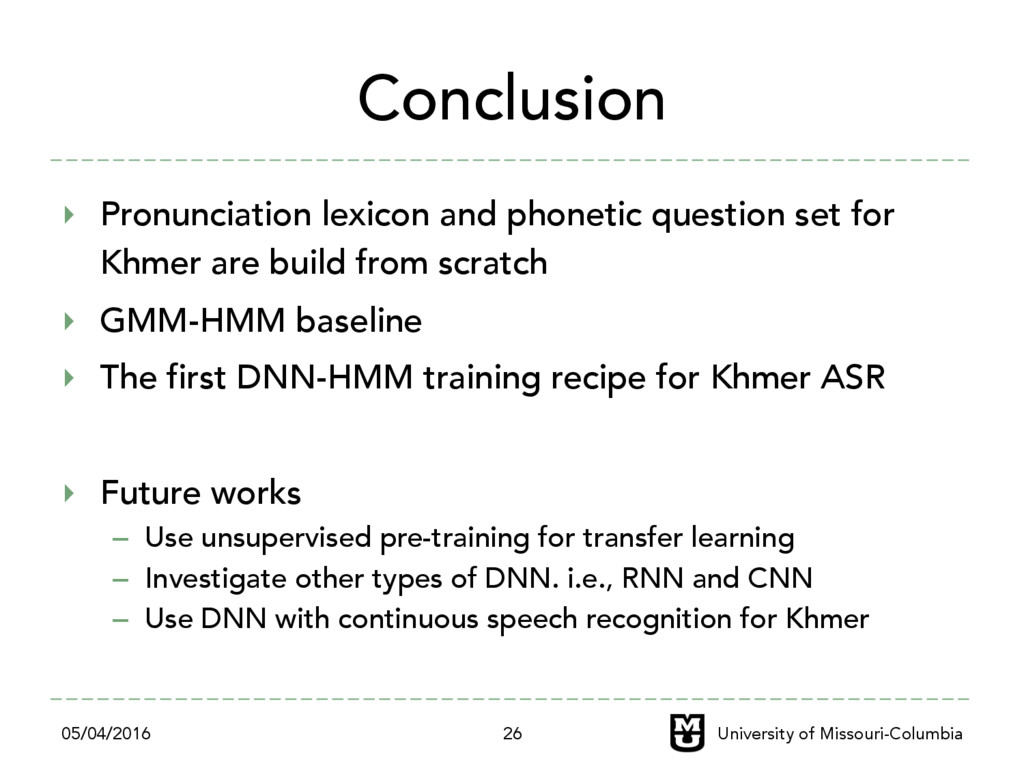
Conclusion ‣ Pronunciation lexicon and phonetic question set for Khmer
are build from scratch ‣ GMM-HMM baseline ‣ The first DNN-HMM training recipe for Khmer ASR ‣ Future works – Use unsupervised pre-training for transfer learning – Investigate other types of DNN. i.e., RNN and CNN – Use DNN with continuous speech recognition for Khmer 05/04/2016 University of Missouri-Columbia 26