Share
Embed
Metadata Embeddings for User and Item Cold-start Recommendations
Maciej Kula
September 20, 2015
Transcript
26 slides
-
480 retailers 4 12,000 designers 12,000 new products added
every day. We continually scrape fashion products from around the web: -
Most recent items are the most relevant. Traditional MF
will not do, need a hybrid model. Products are relatively short-lived. A huge cold-start problem. Made worse by characteristics of fashion. 5 -
7 Users and items characterised by sets of metadata features:
• Designer • Category • Colour • User Country • User Gender • Interaction Context (desktop/mobile) -
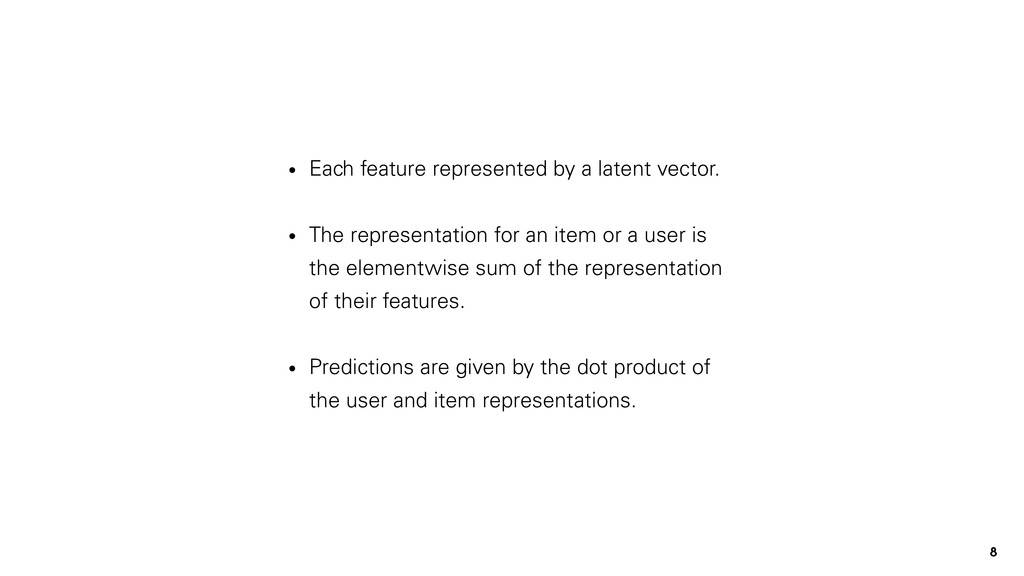
• Each feature represented by a latent vector. • The
representation for an item or a user is the elementwise sum of the representation of their features. • Predictions are given by the dot product of the user and item representations. 8 8 -
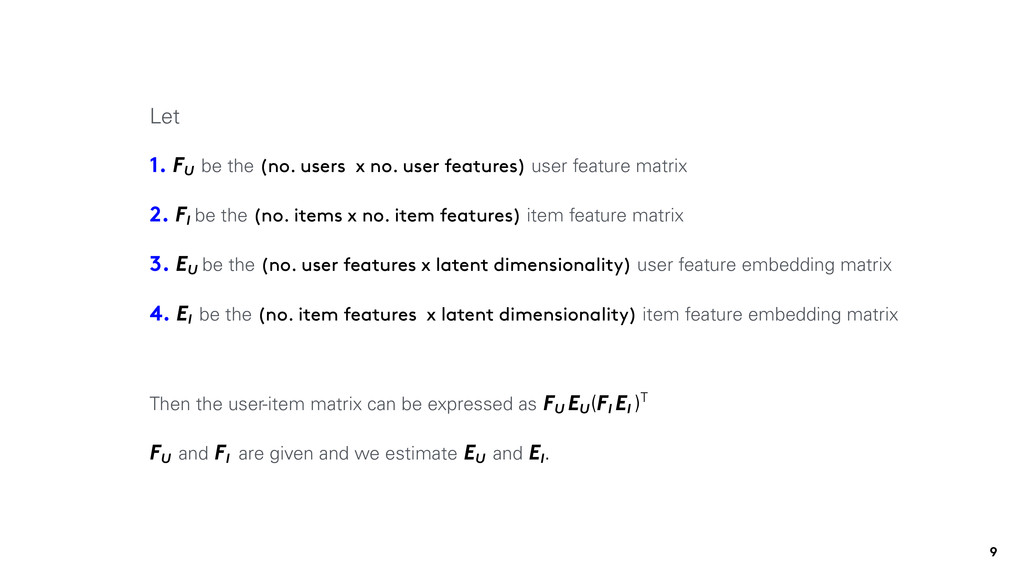
9 Let 1. FU be the (no. users x no.
user features) user feature matrix 2. FI be the (no. items x no. item features) item feature matrix 3. EU be the (no. user features x latent dimensionality) user feature embedding matrix 4. EI be the (no. item features x latent dimensionality) item feature embedding matrix Then the user-item matrix can be expressed as FU EU (FI EI )T FU and FI are given and we estimate EU and EI . -
10 If we only use item/user indicator variables as features
(FU and FI are identity matrices), the model reduces to a traditional MF model. As we add metadata features,we gain the ability to make predictions for cold start items and users. -
11 Experiments on two datasets MovieLens 10M 10 million
rankings, 71 thousand users, 10 thousand movies. CrossValidated 6 thousand users, 44 thousand questions, 190 thousand answers and comments. Full experiment code available at https://github.com/lyst/lightfm-paper -
12 Training data: • In the Movielens experiment, items rated
4 or higher are positives. • In the CrossValidated dataset, answered questions are positives and negatives are randomly sample unanswered questions. Two experiments: • warm-start: random 80%/20% split of all interactions. • cold-start: all interactions for 20% of items are moved to the test set. 12 -
13 MF: a conventional matrix factorisation model. LSI-LR: a content-based
model using per-user logistic regression models on top of principal components of the item metadata matrix. LSI-UP: a hybrid model that represents user profiles as linear combinations of items' content vectors, then applies LSI to the resulting matrix to obtain latent user and item representations. Baselines -
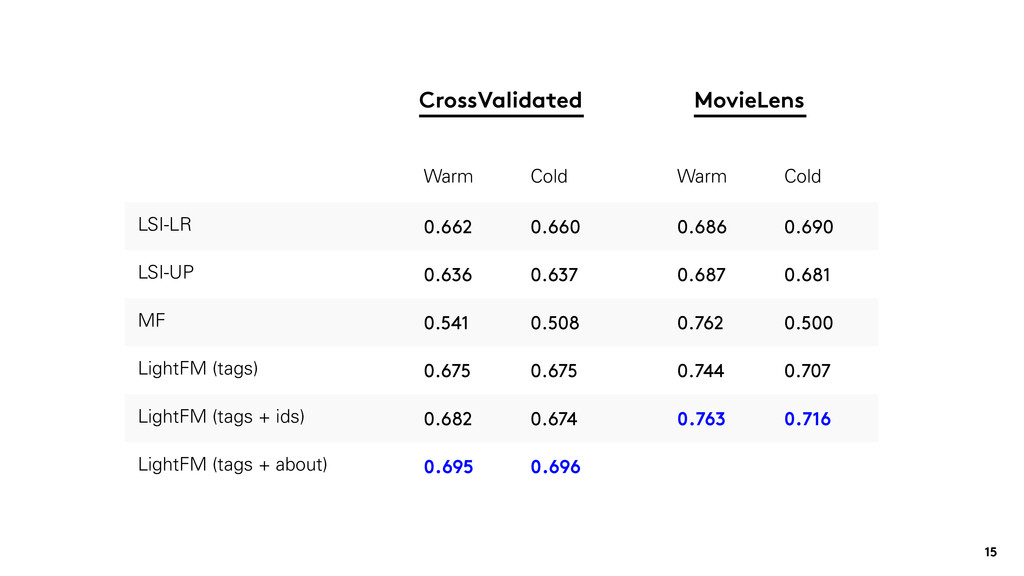
14 Results LightFM performs as well as or better than
standard MF in the warm-start setting. It outperforms the content-based baselines in the cold-start setting. We can have a single model that performs well across the data sparsity spectrum. -
15 Warm Cold Warm Cold LSI-LR 0.662 0.660 0.686 0.690
LSI-UP 0.636 0.637 0.687 0.681 MF 0.541 0.508 0.762 0.500 LightFM (tags) 0.675 0.675 0.744 0.707 LightFM (tags + ids) 0.682 0.674 0.763 0.716 LightFM (tags + about) 0.695 0.696 CrossValidated MovieLens -
16 Example with our own data Small sample of product
page views. Very sparse. Mixture of warm and cold-start users and items. Item implicit binary feedback setting. Model trained with WARP loss. -
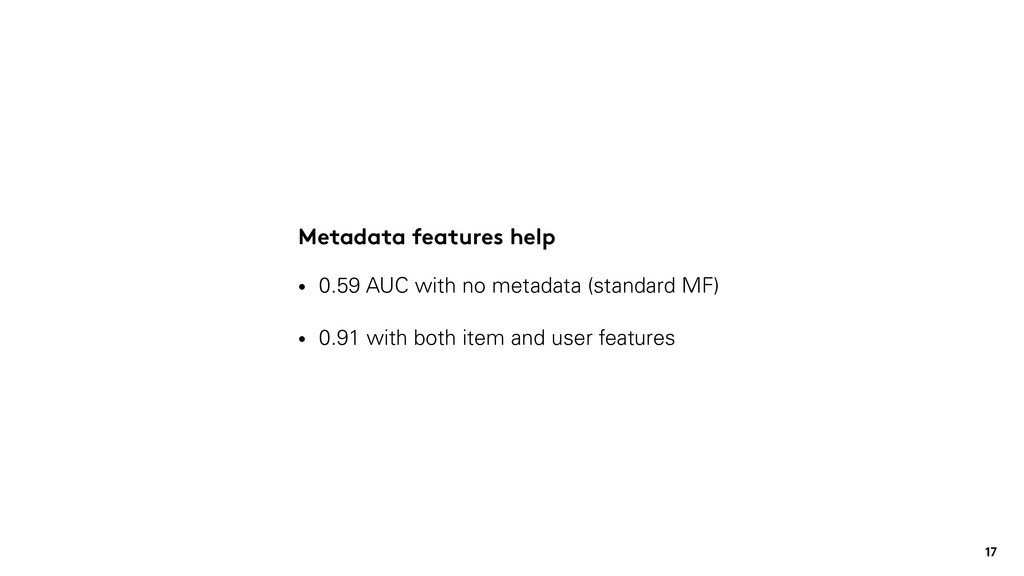
17 Metadata features help • 0.59 AUC with no metadata
(standard MF) • 0.91 with both item and user features -
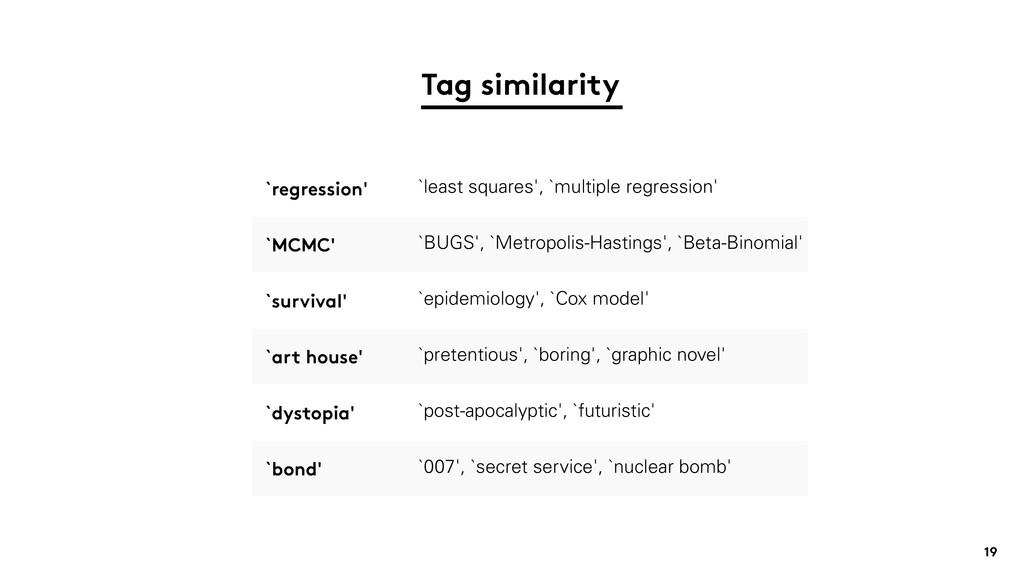
19 `regression' `least squares', `multiple regression' `MCMC' `BUGS', `Metropolis-Hastings', `Beta-Binomial'
`survival' `epidemiology', `Cox model' `art house' `pretentious', `boring', `graphic novel' `dystopia' `post-apocalyptic', `futuristic' `bond' `007', `secret service', `nuclear bomb' Tag similarity -
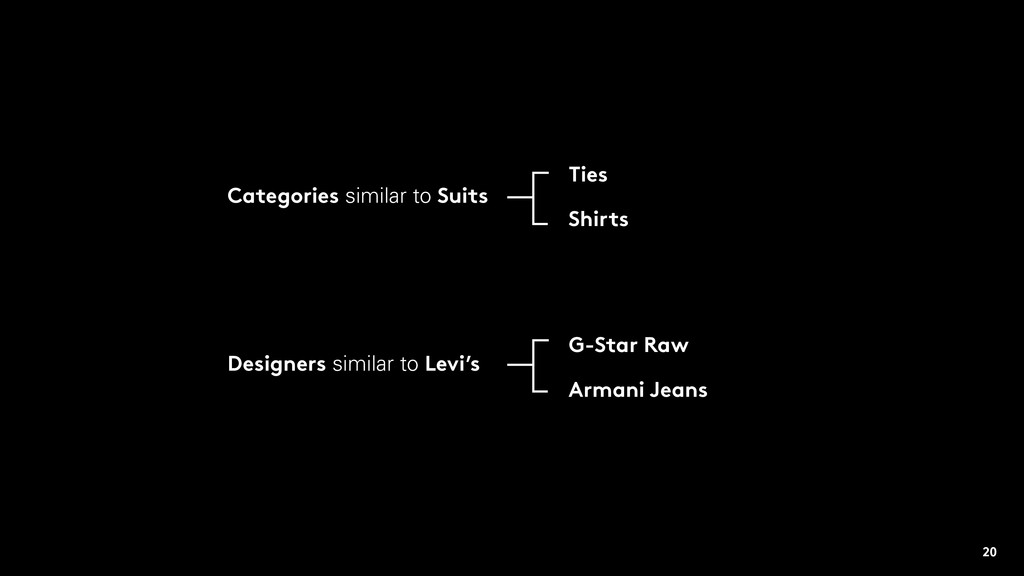
Categories similar to Suits 20 Ties Shirts Designers similar to
Levi’s G-Star Raw Armani Jeans 20 -
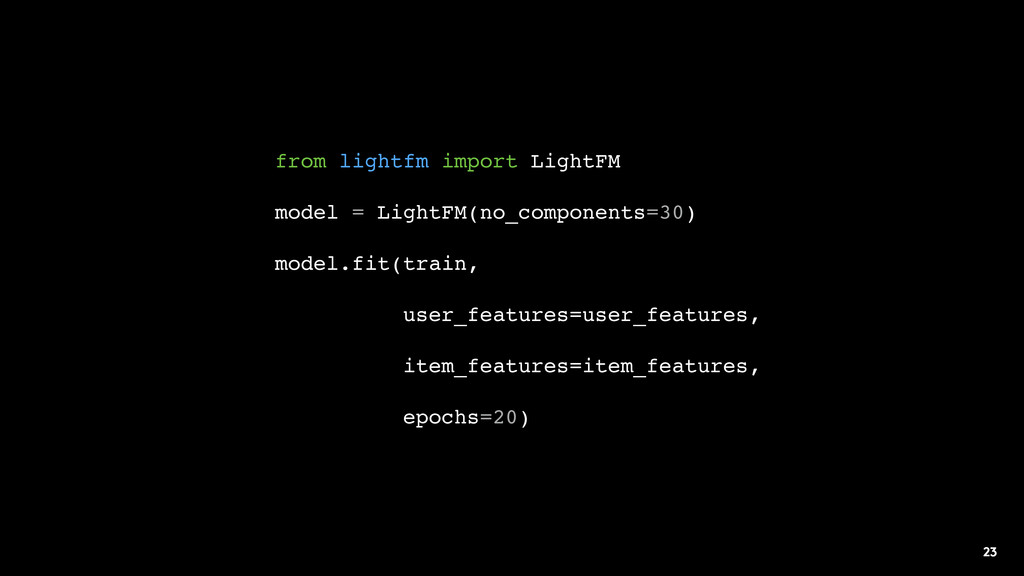
23 from lightfm import LightFM model = LightFM(no_components=30) model.fit(train, user_features=user_features,
item_features=item_features, epochs=20) 23 -
24 Multiple loss functions • Logistic loss for explicit binary
feedback • BPR • WARP • k-th order statistic WARP loss -
Two learning rate schedules: • adagrad • adadelta Trained with
asynchronous stochastic gradient descent. 25