Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Lessons learned running data pipeline on AWS
Search
Majid Fatemian
March 14, 2019
Technology
130
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Lessons learned running data pipeline on AWS
Here are the slides from the talk at ConFoo Montreal 2019.
Majid Fatemian
March 14, 2019
More Decks by Majid Fatemian
See All by Majid Fatemian
Getting started with Apache Spark (Developer's edition)
majidfn
0
84
Other Decks in Technology
See All in Technology
PHPカンファレンス関西の招待状 / Invitation to PHP Conference Kansai
ykanoh
0
110
Classmethod Company Deck
satoshi7
1
680
DGX Spark でどこまでハッキングができるのか?
kash1064
3
1.3k
20261017福岡devIO 「AIは"良いダッシュボード"を作れるか?
jtakeda
0
140
分析の民主化を支えるメタデータ整備の実践
kakehashi
PRO
4
1.4k
Refining Active Record
shugo
0
150
OptunaHub: ブラックボックス最適化のためのプラットフォーム
pfn
PRO
0
140
"優秀な誰か"の下位互換にならないために
yut0naga1_fa
1
1.8k
Rustuna: Rustによる高速なOptuna実装
pfn
PRO
0
190
AIがコードを書く時代に、エンジニアは何で自分の価値を証明するのか / In an era where AI writes code how do engineers prove their value
carta_engineering
3
1.1k
Post AI時代のリファクタリング実践記 / Refactoring in the post AI era
kaminashi
1
230
アウトプット初心者、半年間のふりかえり
4o1sobblue
0
430
Featured
See All Featured
Darren the Foodie - Storyboard
khoart
PRO
4
4k
Exploring the relationship between traditional SERPs and Gen AI search
raygrieselhuber
PRO
4
4.4k
実際に使うSQLの書き方 徹底解説 / pgcon21j-tutorial
soudai
PRO
203
77k
Optimising Largest Contentful Paint
csswizardry
37
4k
Abbi's Birthday
coloredviolet
4
10k
CoffeeScript is Beautiful & I Never Want to Write Plain JavaScript Again
sstephenson
162
16k
[SF Ruby Conf 2025] Rails X
palkan
3
1.5k
A Guide to Academic Writing Using Generative AI - A Workshop
ks91
PRO
1
520
Game over? The fight for quality and originality in the time of robots
wayneb77
1
300
Designing for humans not robots
tammielis
254
26k
Rails Girls Zürich Keynote
gr2m
96
14k
How People are Using Generative and Agentic AI to Supercharge Their Products, Projects, Services and Value Streams Today
helenjbeal
2
360
Transcript
DATA PIPELINE ON AWS LESSONS LEARNED RUNNING
Majid Fatemian R E D V E N T U
R E S
[email protected]
@majidfn aws CERTIFIED - SAA
TECH & DATA-DRIVEN CUSTOMER ACQUISITION SALES & MARKETING R E
D V E N T U R E S
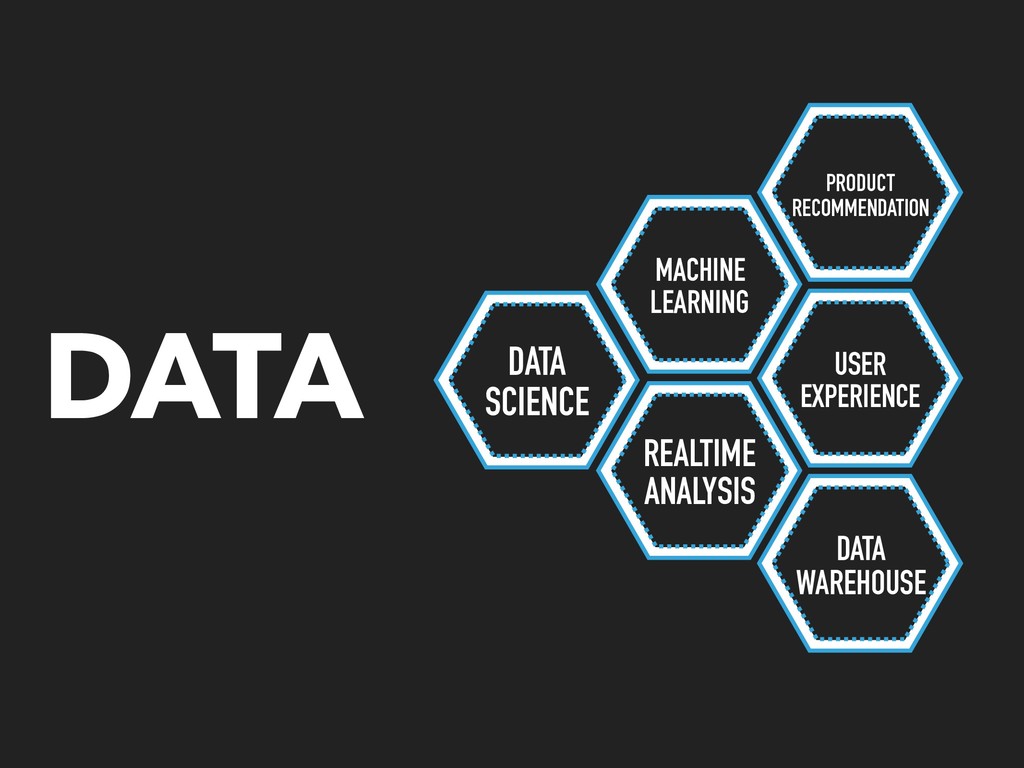
MACHINE LEARNING PRODUCT RECOMMENDATION DATA SCIENCE REALTIME ANALYSIS USER EXPERIENCE
DATA WAREHOUSE DATA
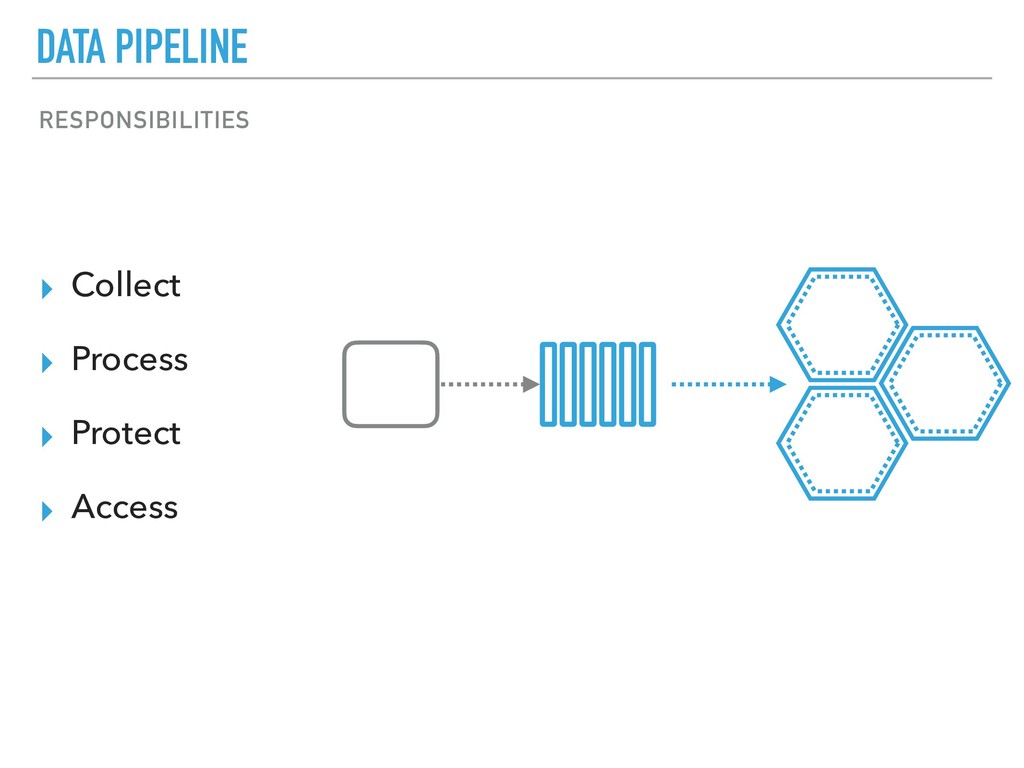
▸ Collect ▸ Process ▸ Protect ▸ Access DATA PIPELINE
RESPONSIBILITIES
DATA PIPELINE AVAILABLE D U R A B L E
DESIRED PROPERTIES
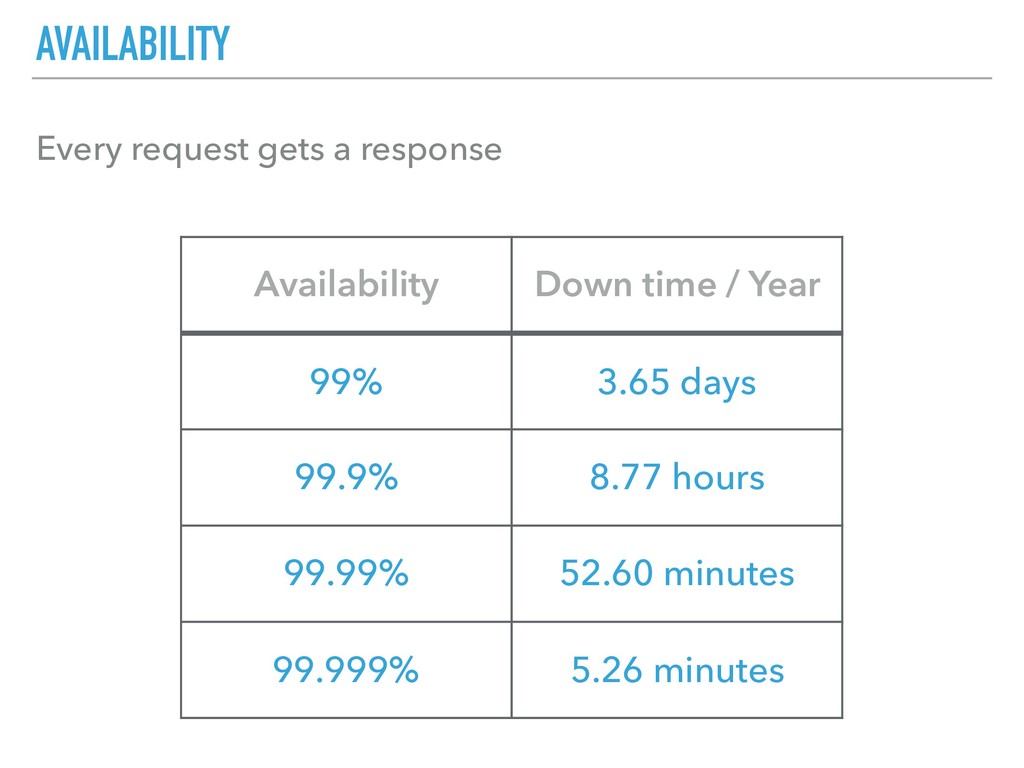
AVAILABILITY Every request gets a response Availability Down time /
Year 99% 3.65 days 99.9% 8.77 hours 99.99% 52.60 minutes 99.999% 5.26 minutes
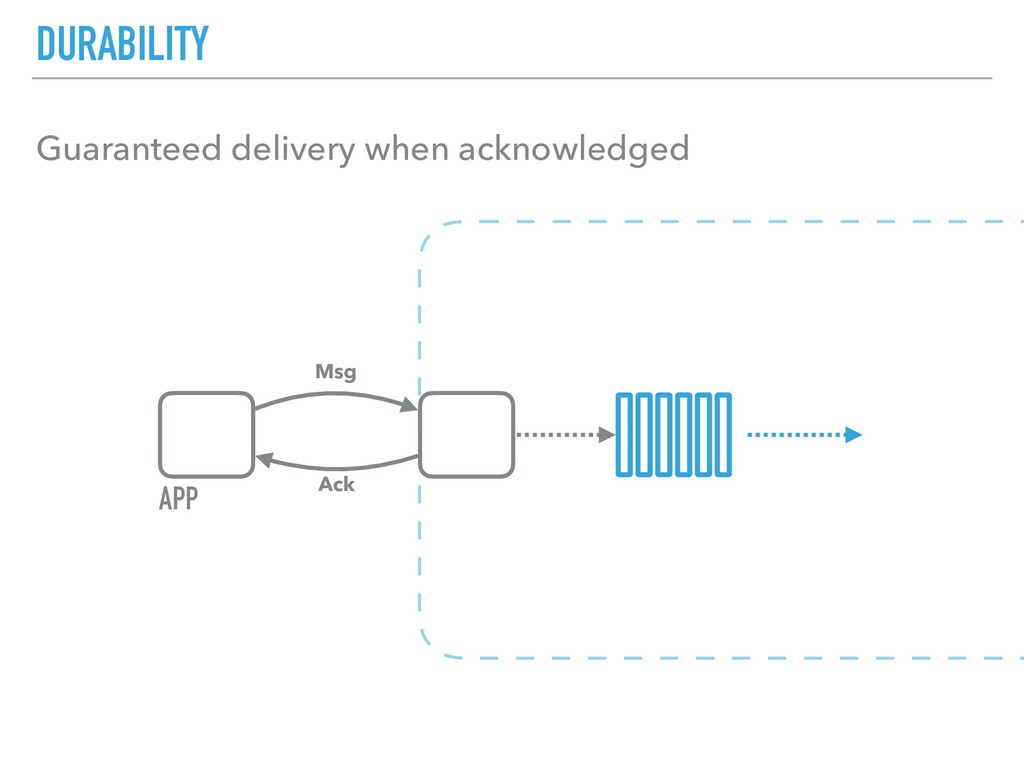
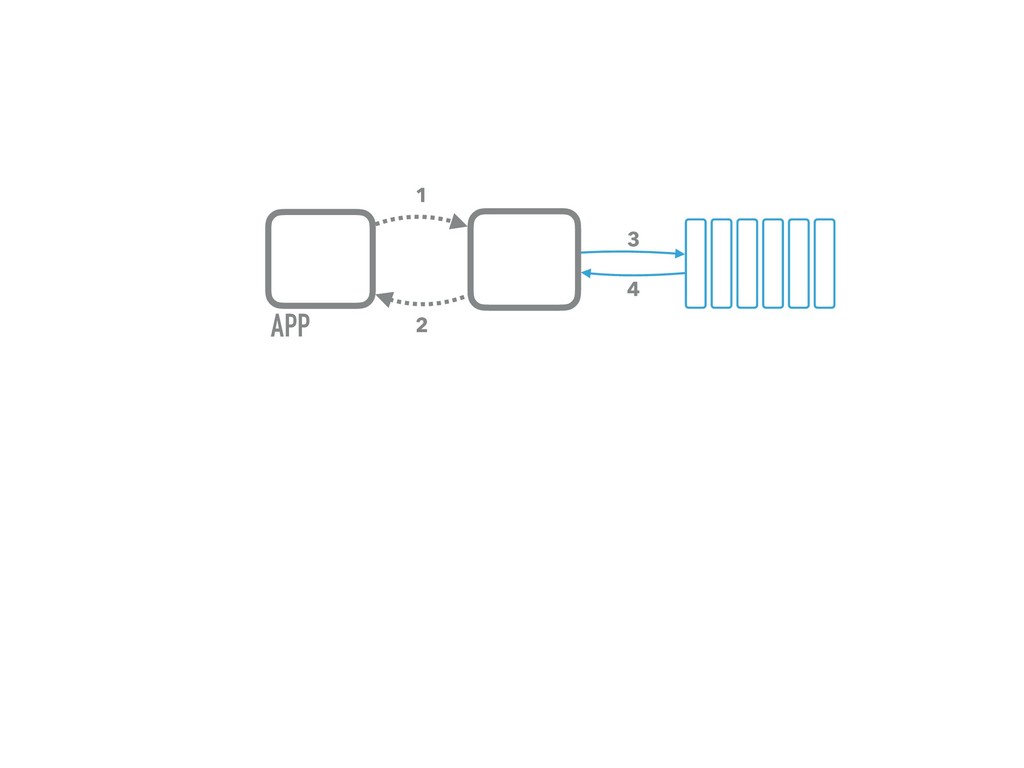
DURABILITY Guaranteed delivery when acknowledged APP Msg Ack
DATA IMMUTABLE DESIRED PROPERTIES S C H E M A
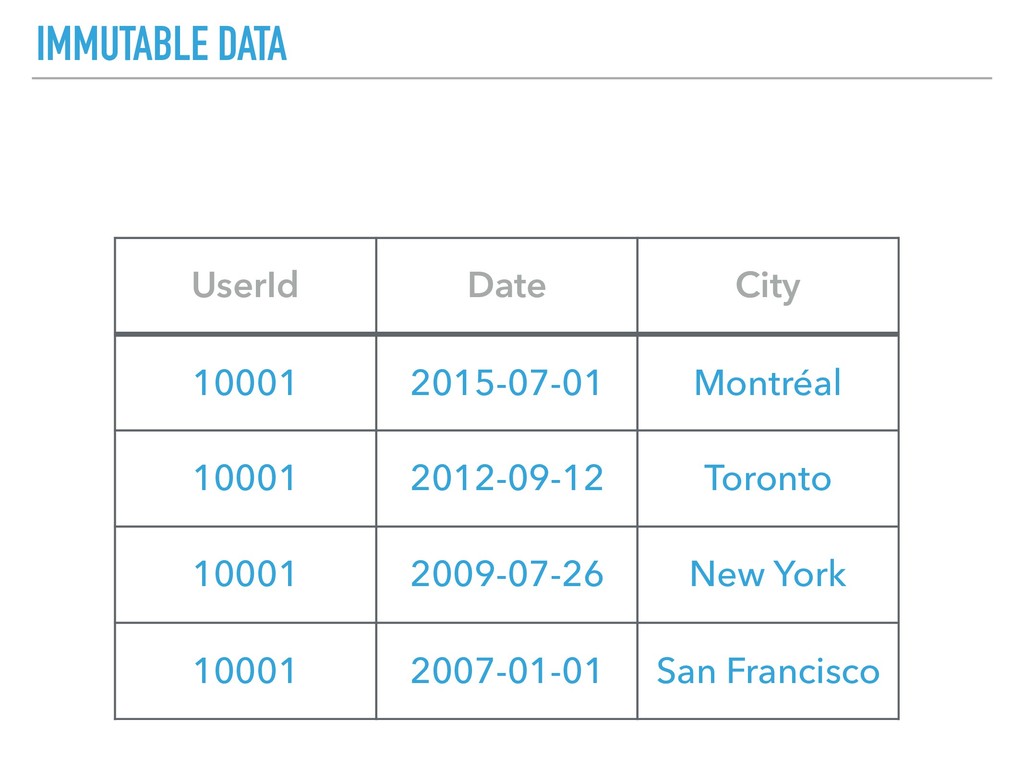
IMMUTABLE DATA ▸ No UPDATE (Immutable data) ▸ Changes are
stored as sequence of events ▸ Current State = Applying the history of changes
IMMUTABLE DATA UserId Date City 10001 2015-07-01 Montréal 10001 2012-09-12
Toronto 10001 2009-07-26 New York 10001 2007-01-01 San Francisco
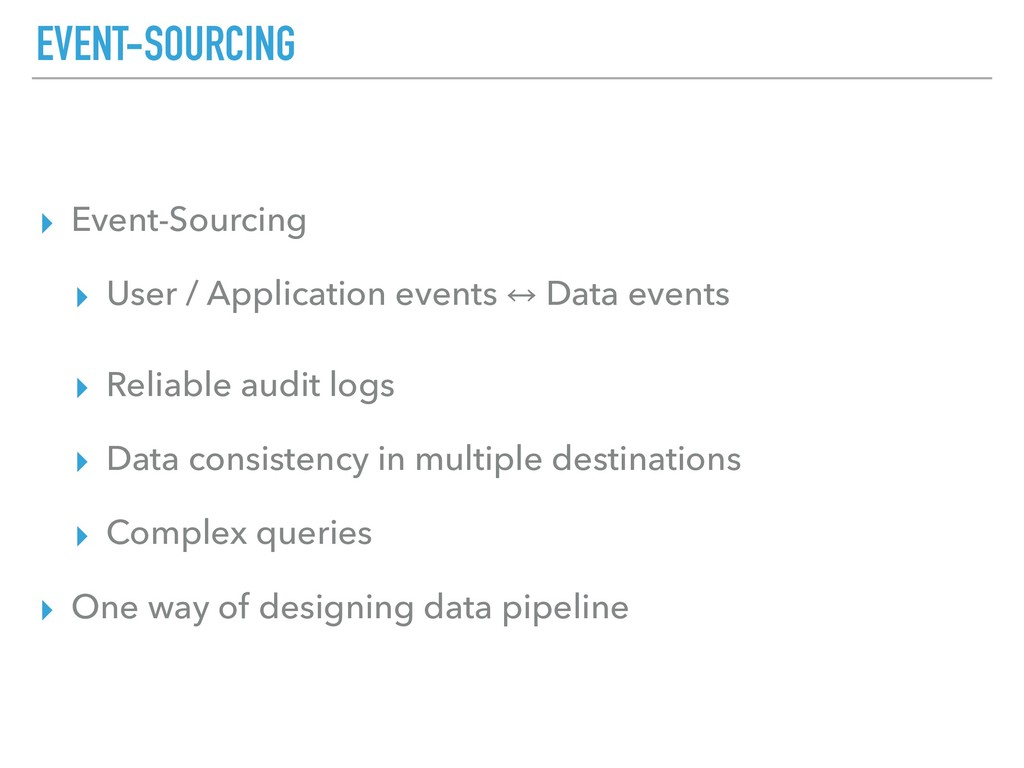
EVENT-SOURCING ▸ Event-Sourcing ▸ User / Application events 㲗 Data
events ▸ Reliable audit logs ▸ Data consistency in multiple destinations ▸ Complex queries ▸ One way of designing data pipeline
SCHEMA ▸ Enforced schema ▸ Data is structured ▸ Avoids
data corruption
▸ Apache Thrift ▸ Protocol Buffers ▸ Avro ▸ …
SERIALIZATION FRAMEWORKS
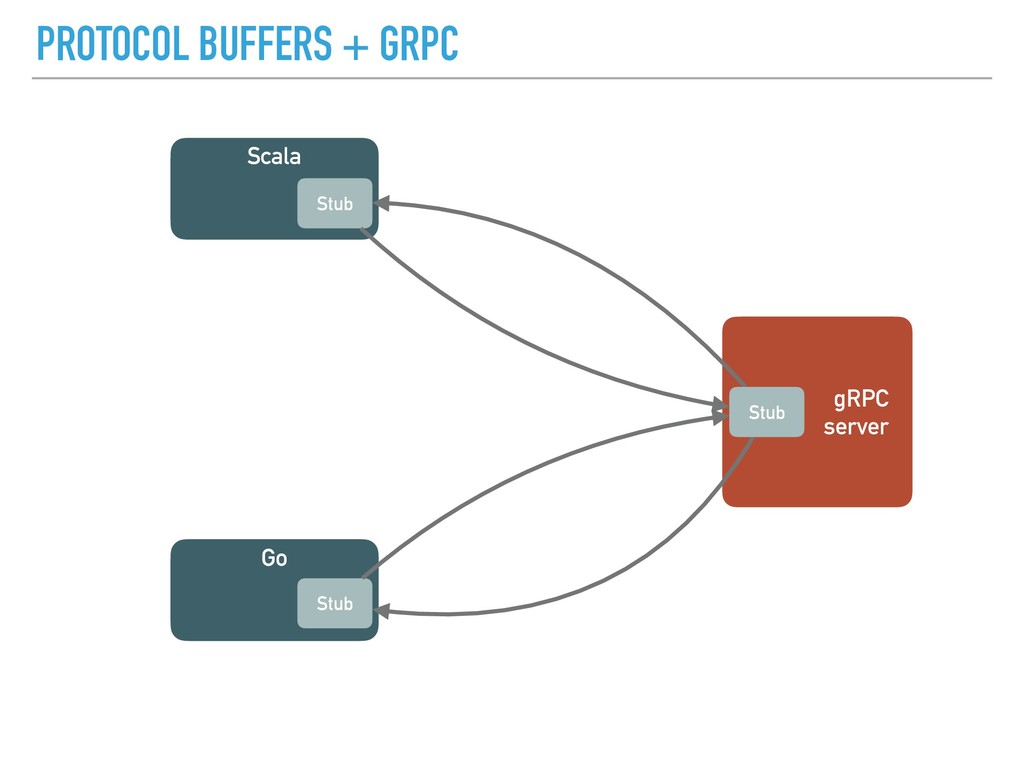
PROTOCOL BUFFERS + GRPC ▸ Serialization framework ▸ Schema ▸
gRPC is a binary RPC protocol grpc.io
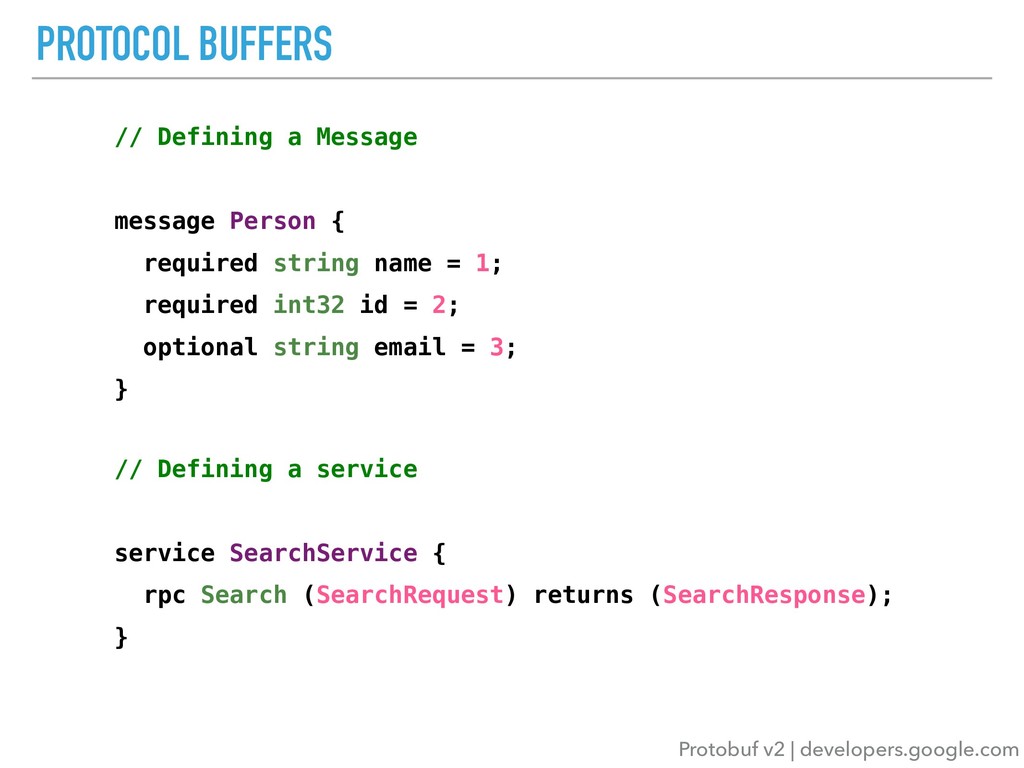
PROTOCOL BUFFERS Protobuf v2 | developers.google.com // Defining a Message
message Person { required string name = 1; required int32 id = 2; optional string email = 3; } // Defining a service service SearchService { rpc Search (SearchRequest) returns (SearchResponse); }
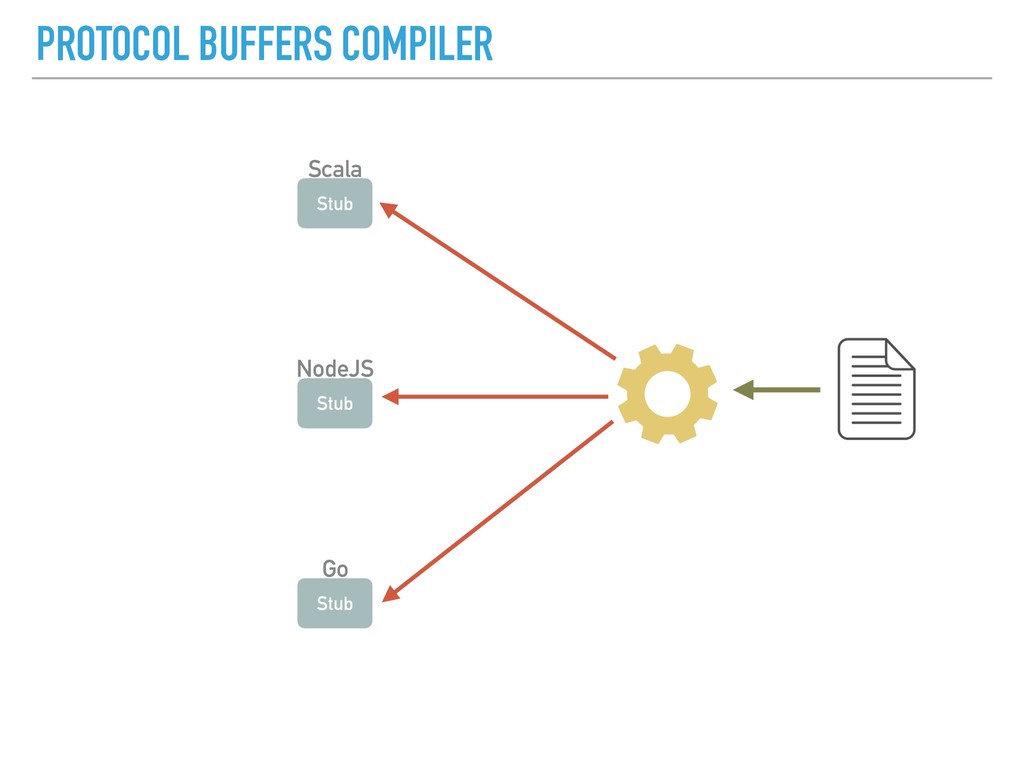
PROTOCOL BUFFERS COMPILER Stub Stub Stub Scala NodeJS Go
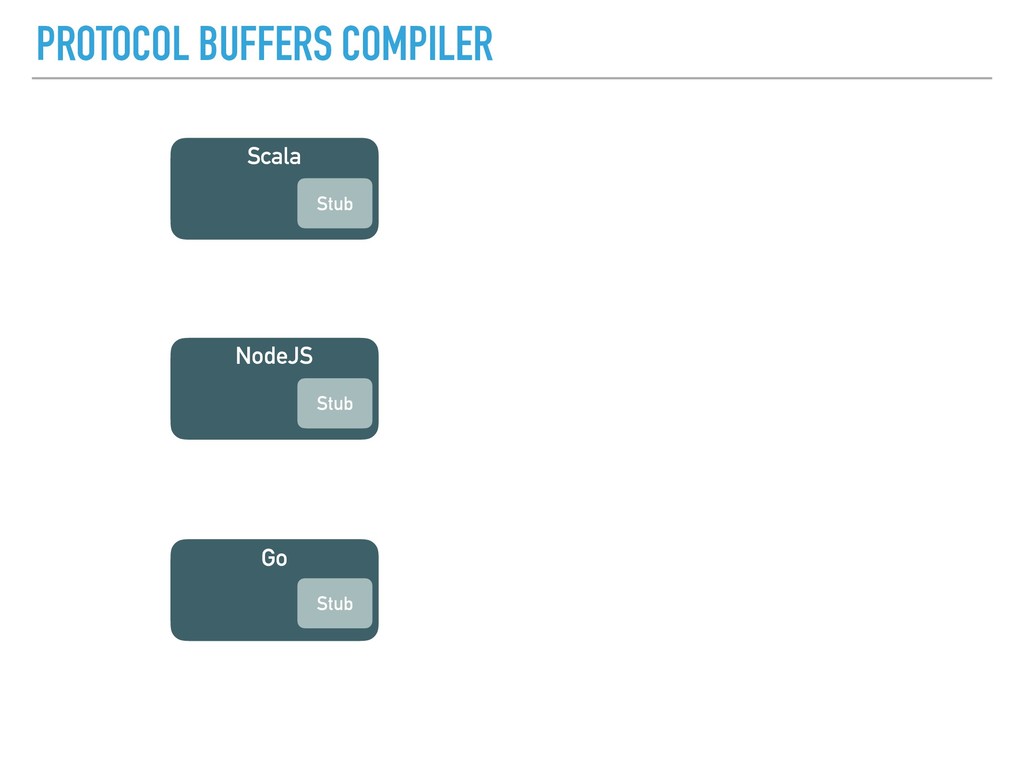
PROTOCOL BUFFERS COMPILER Scala Go Stub Stub NodeJS Stub
PROTOCOL BUFFERS + GRPC Scala Go Stub Stub Stub gRPC
server
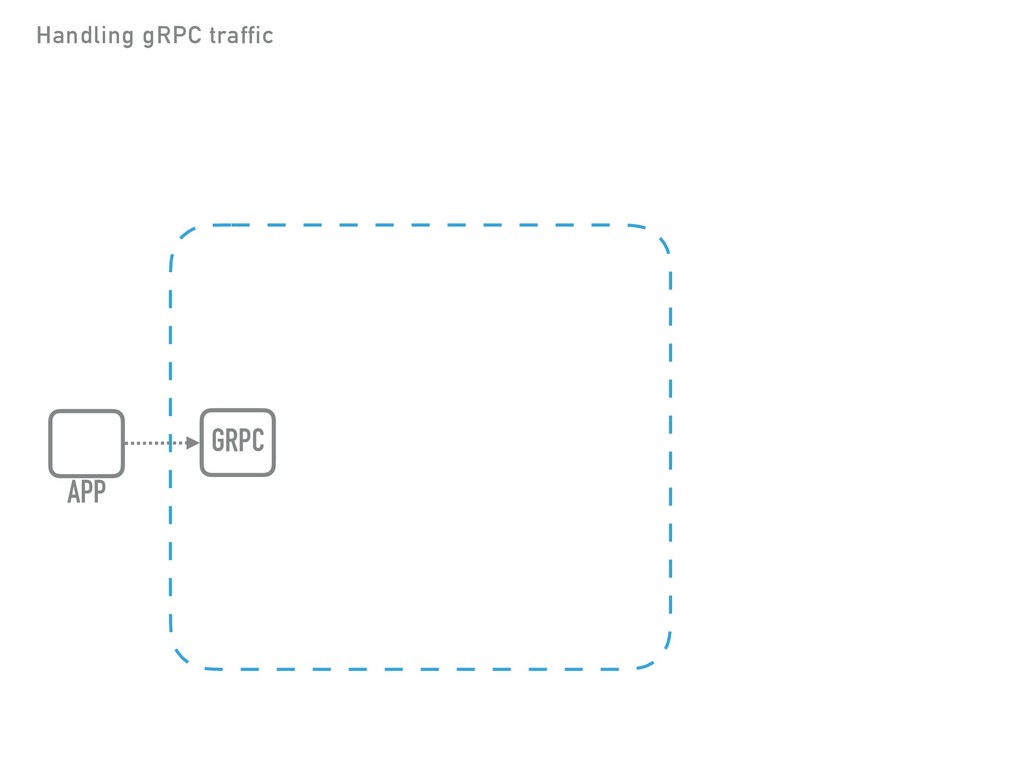
GRPC Handling gRPC traffic
GRPC APP Handling gRPC traffic
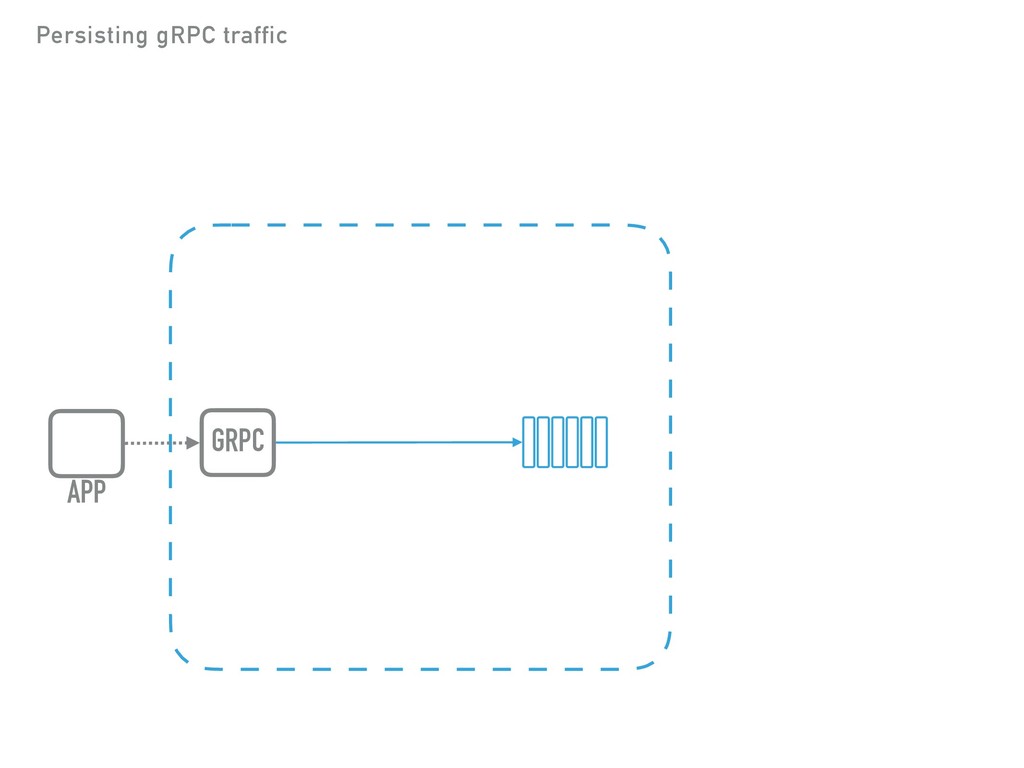
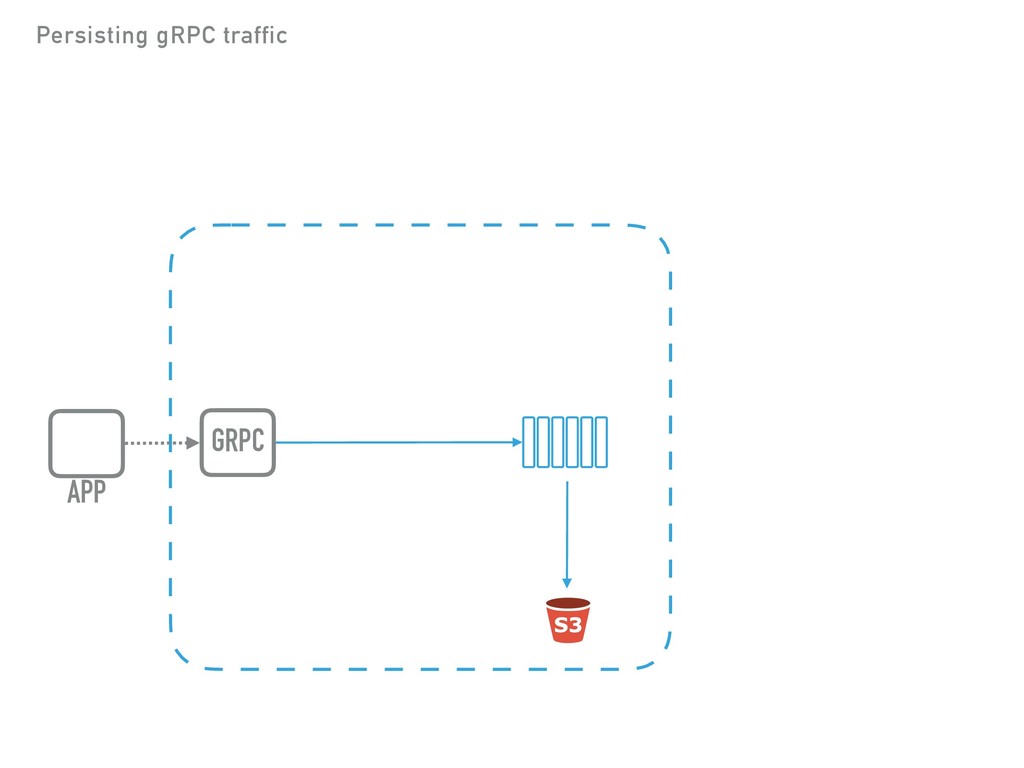
GRPC APP Persisting gRPC traffic
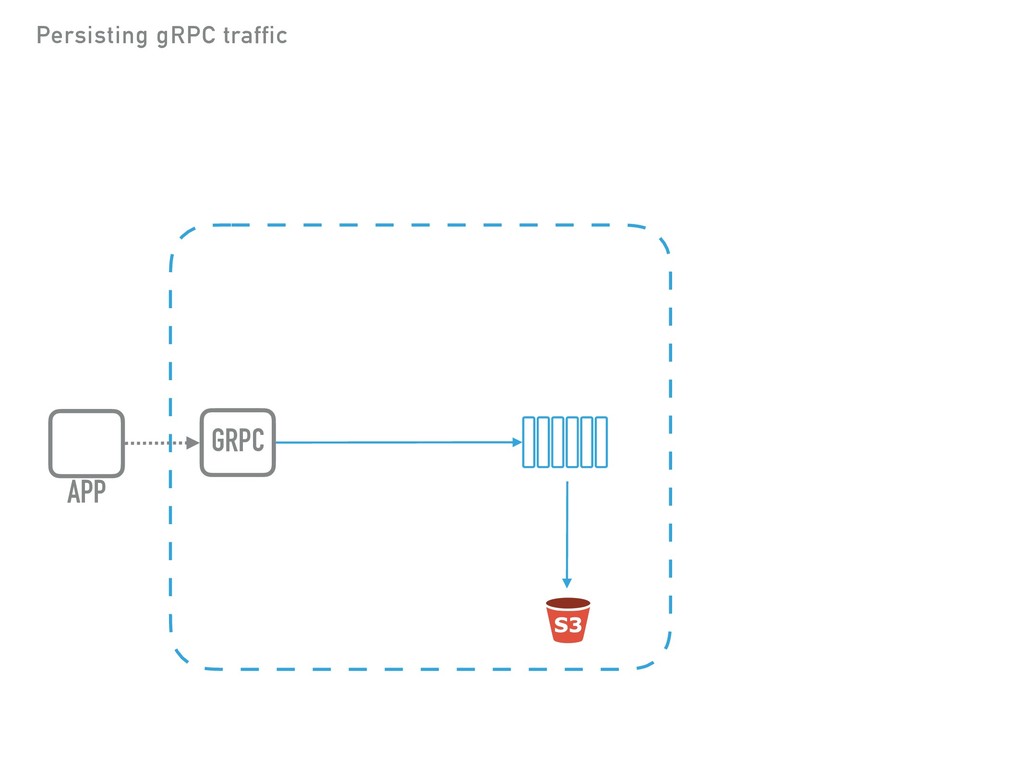
GRPC APP Persisting gRPC traffic
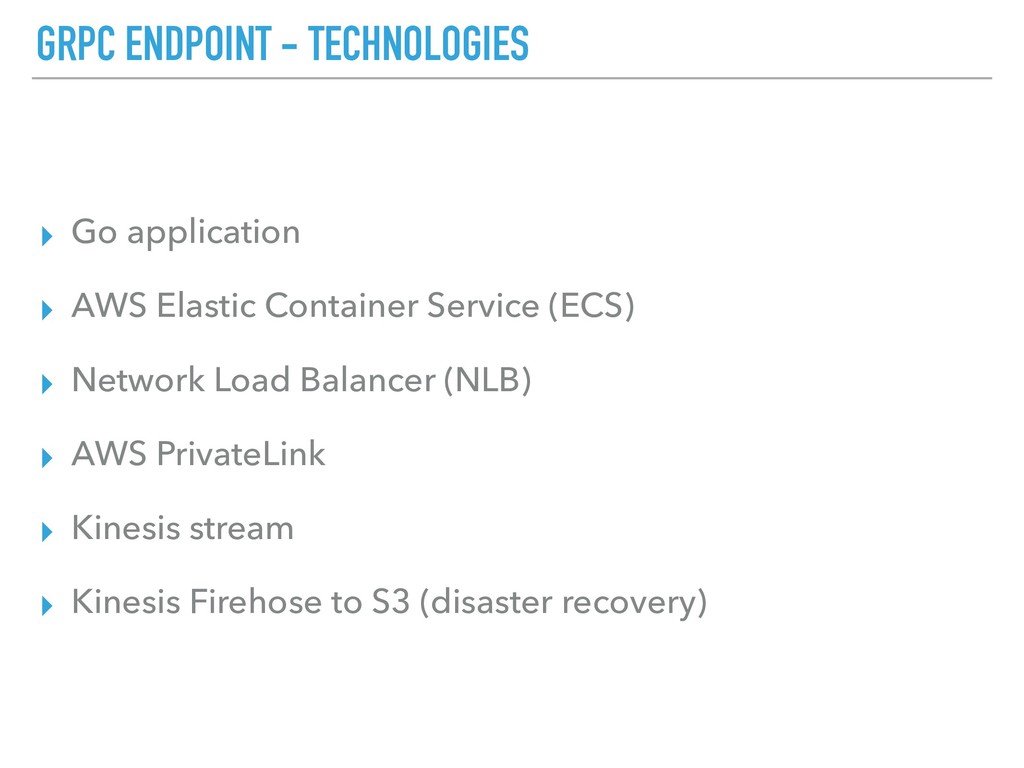
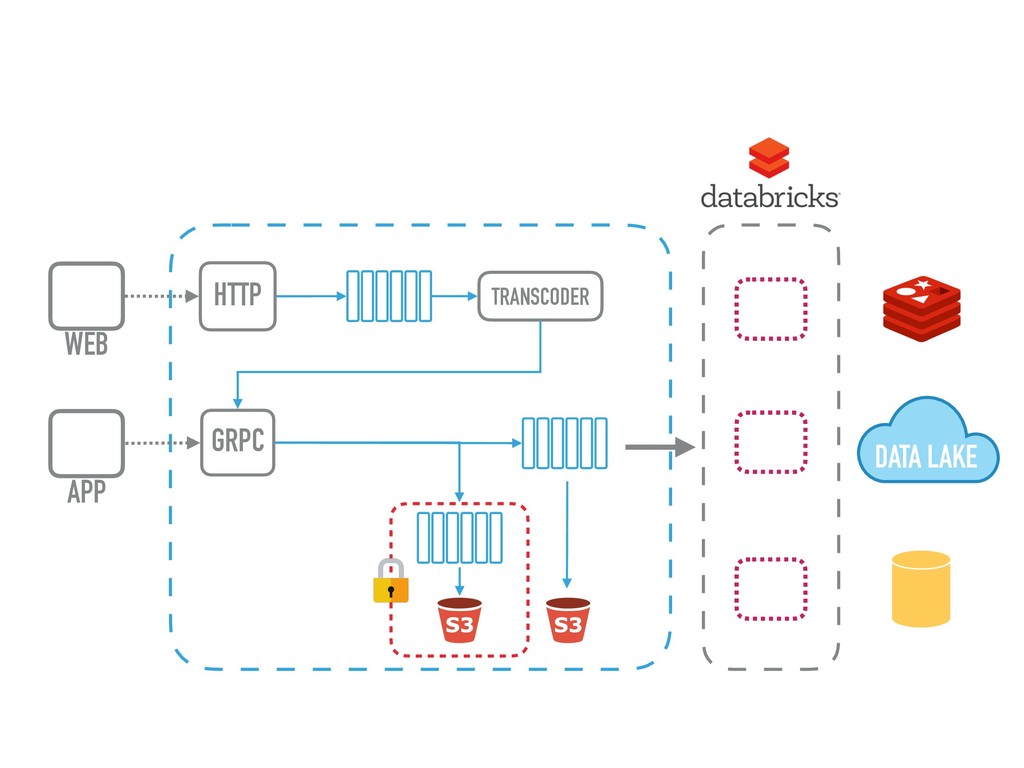
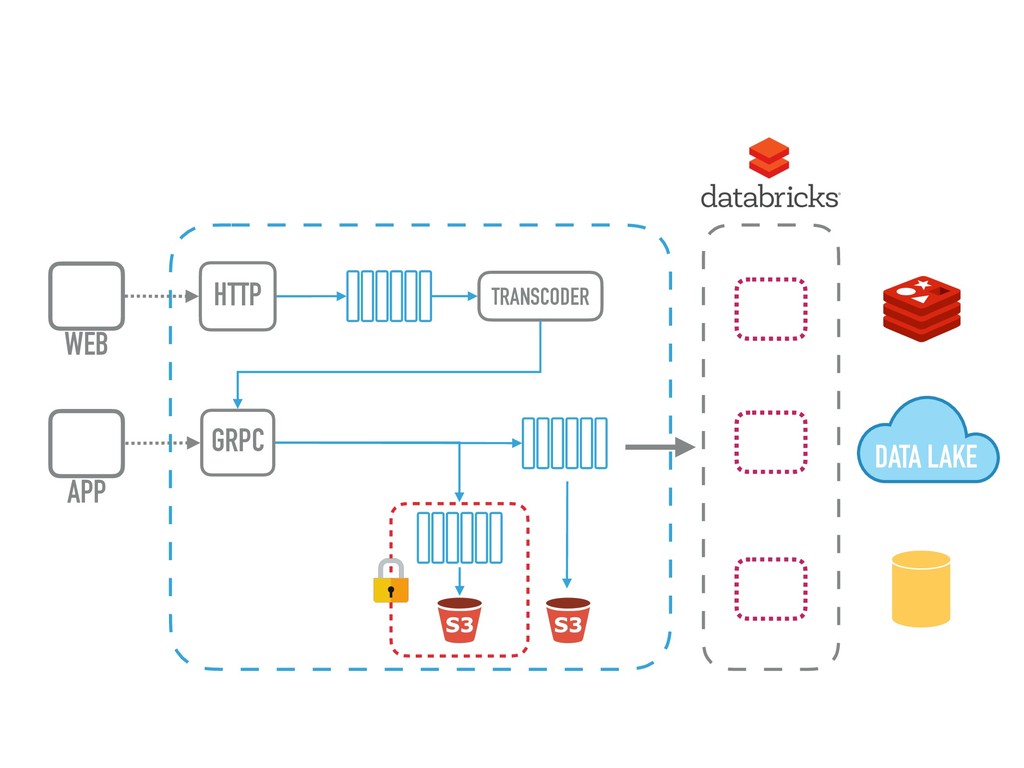
GRPC ENDPOINT - TECHNOLOGIES ▸ Go application ▸ AWS Elastic
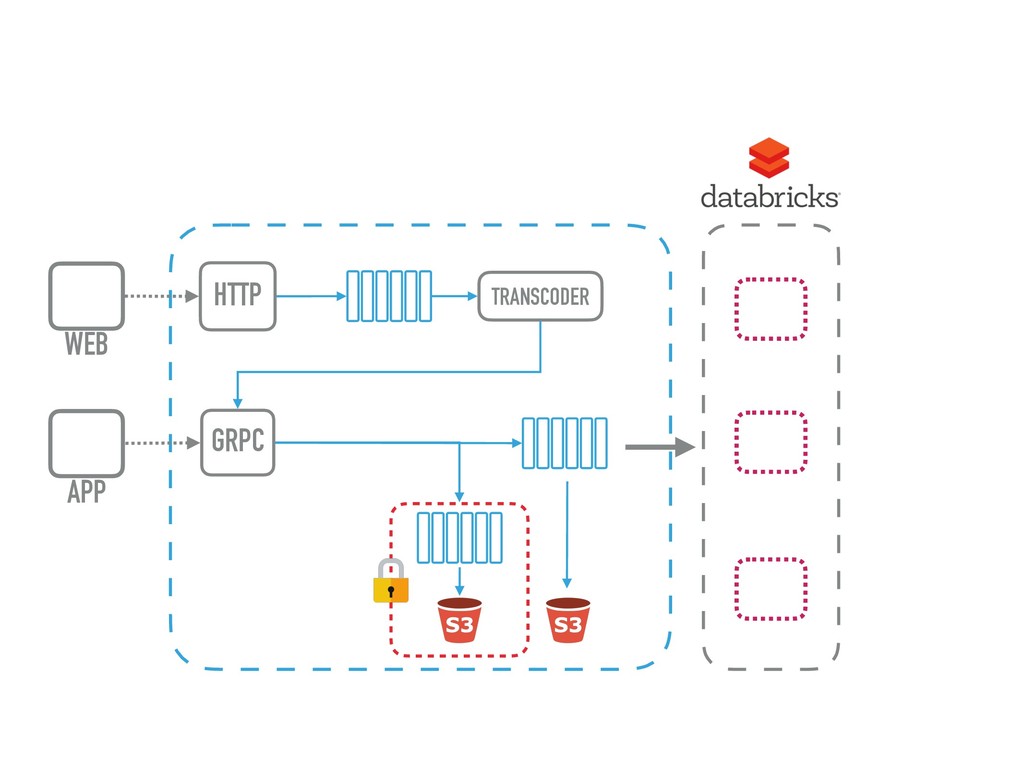
Container Service (ECS) ▸ Network Load Balancer (NLB) ▸ AWS PrivateLink ▸ Kinesis stream ▸ Kinesis Firehose to S3 (disaster recovery)
GRPC APP Persisting gRPC traffic
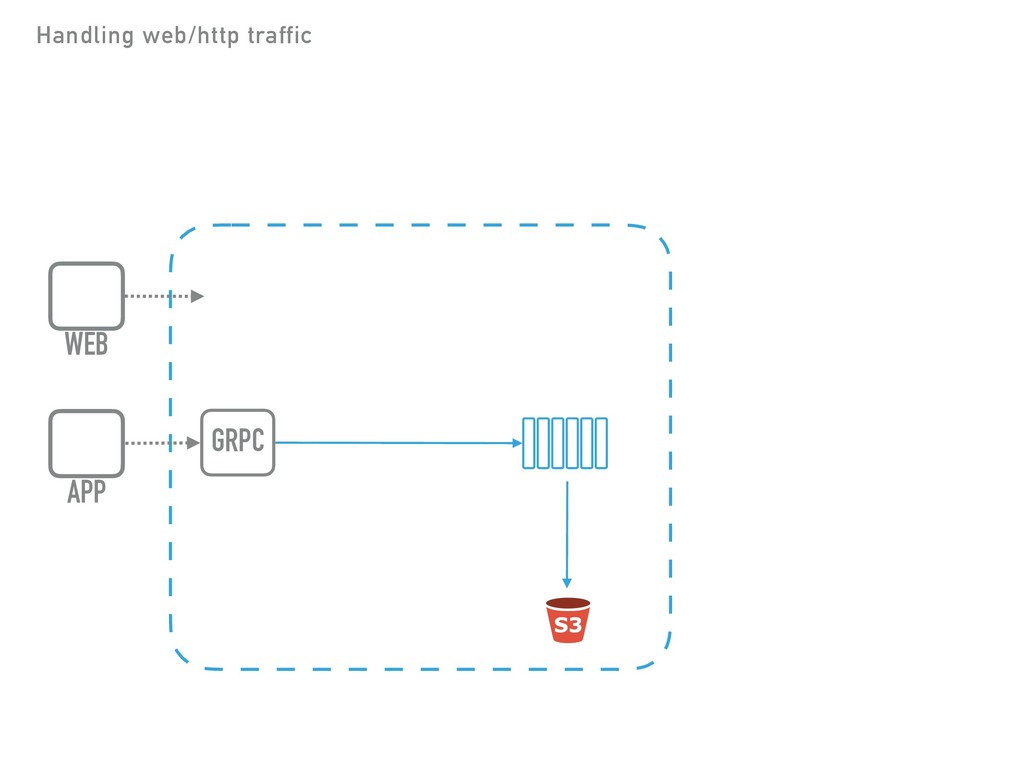
GRPC APP WEB Handling web/http traffic
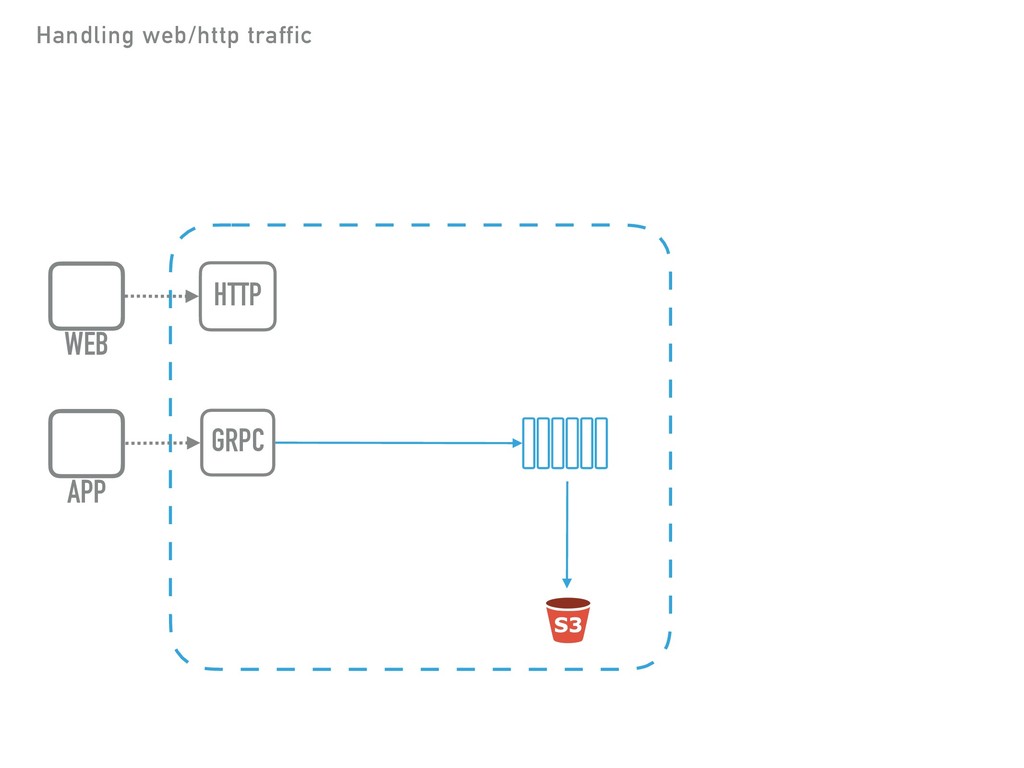
GRPC APP HTTP WEB Handling web/http traffic
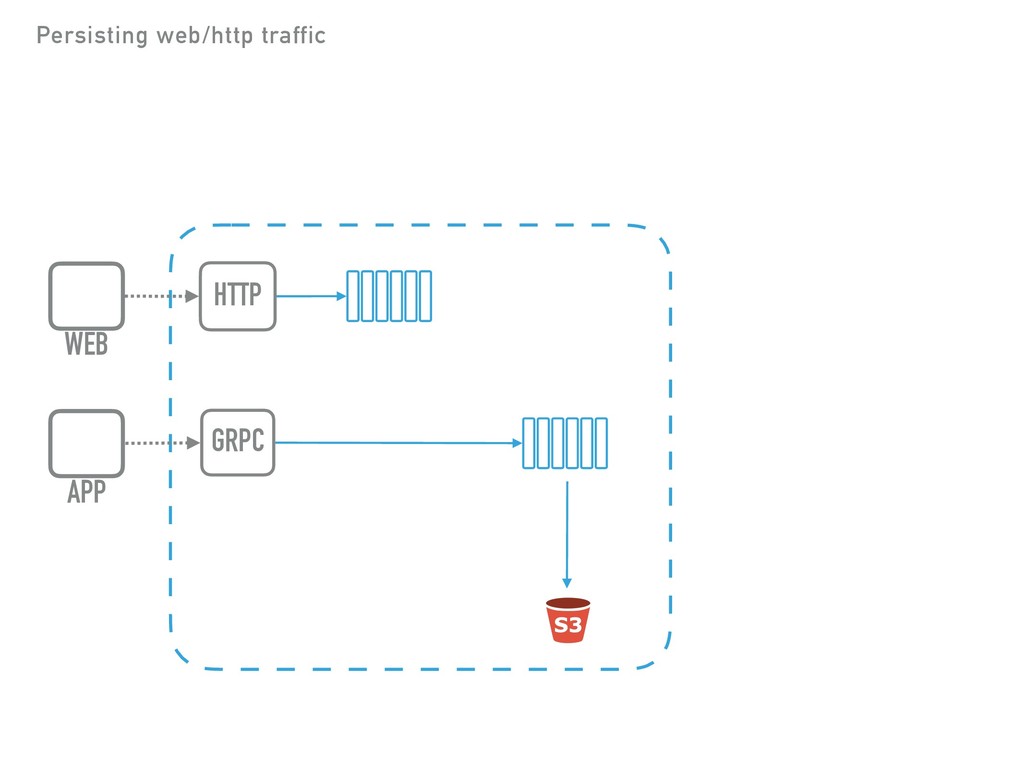
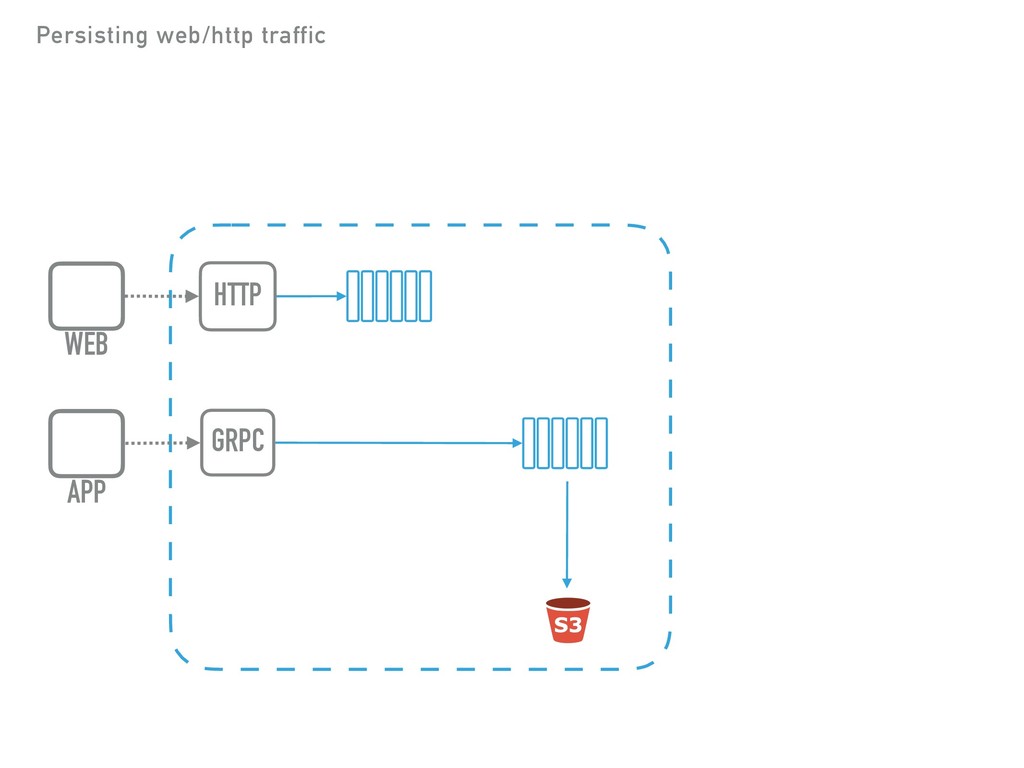
GRPC APP WEB HTTP Persisting web/http traffic
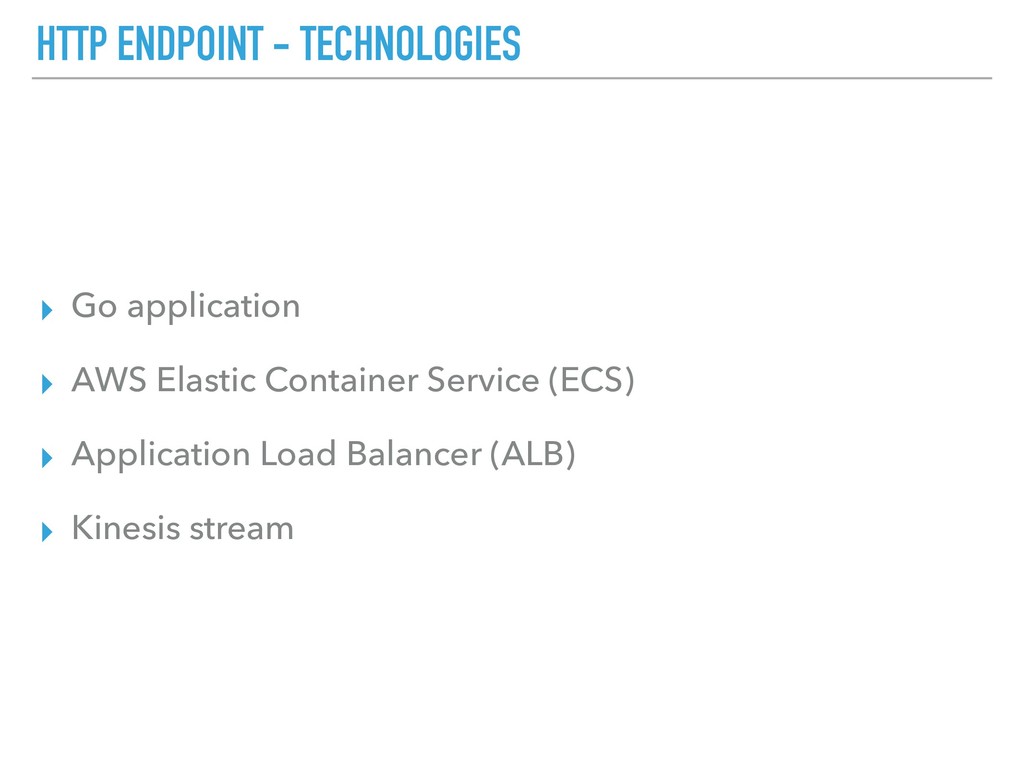
HTTP ENDPOINT - TECHNOLOGIES ▸ Go application ▸ AWS Elastic
Container Service (ECS) ▸ Application Load Balancer (ALB) ▸ Kinesis stream
GRPC APP WEB HTTP Persisting web/http traffic
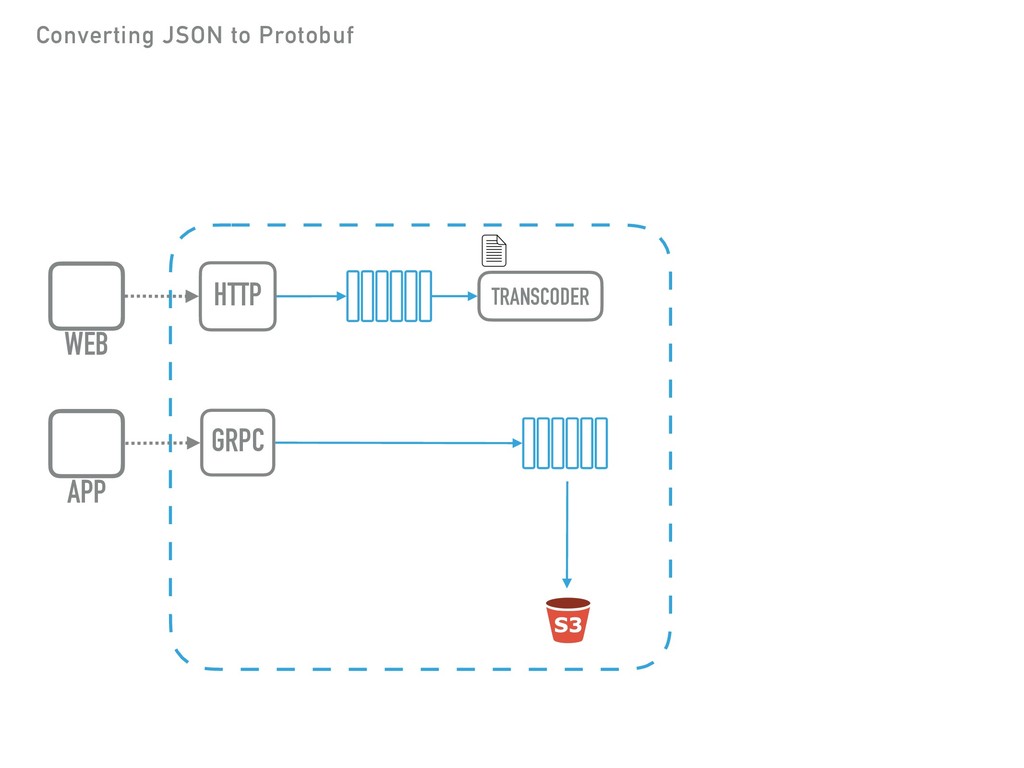
GRPC APP WEB HTTP TRANSCODER Converting JSON to Protobuf
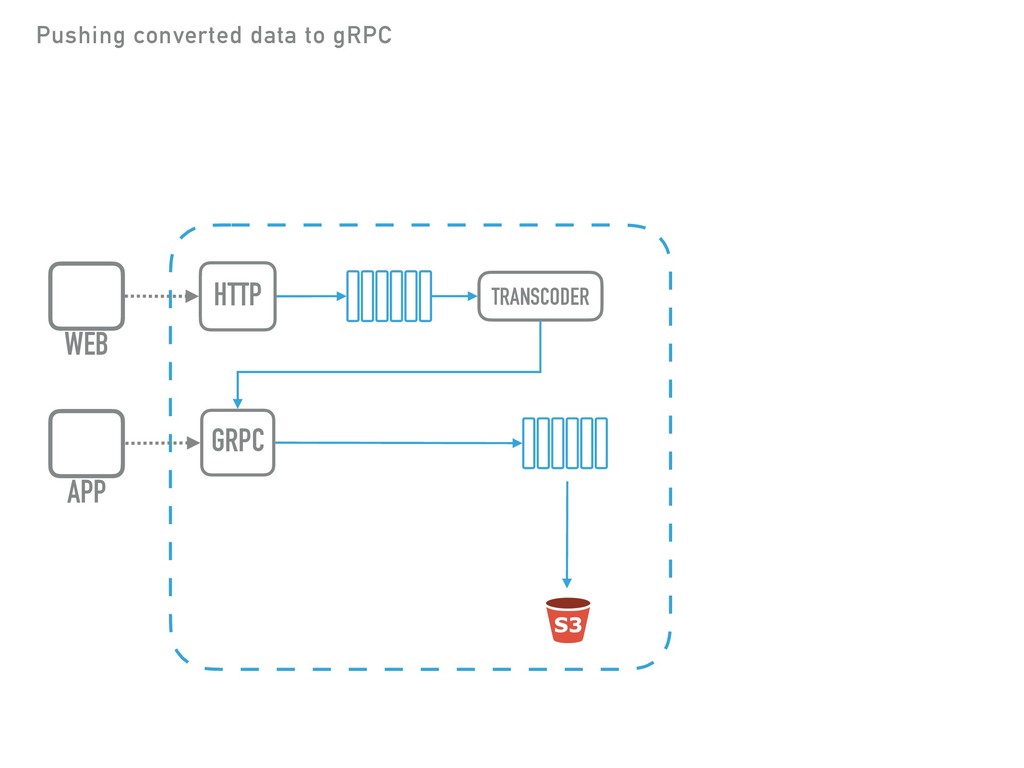
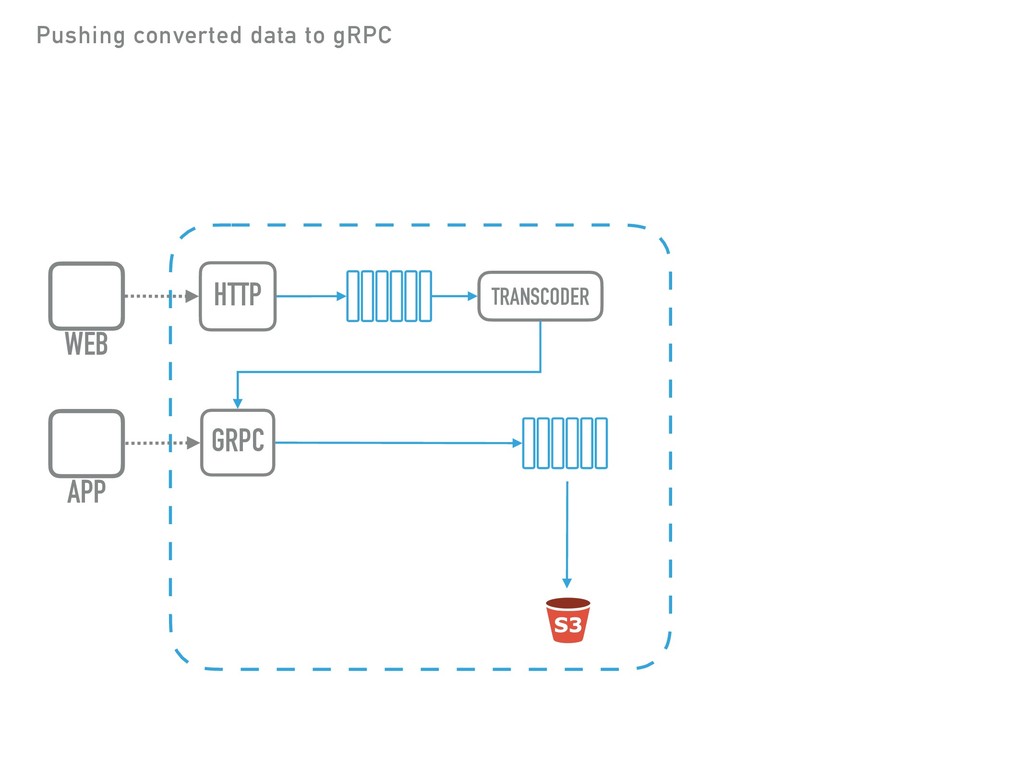
HTTP GRPC TRANSCODER WEB APP Pushing converted data to gRPC
TRANSCODER - TECHNOLOGIES ▸ Scala application ▸ AWS Elastic Container
Service (ECS) ▸ Kinesis Enhanced Fanout
HTTP GRPC TRANSCODER WEB APP Pushing converted data to gRPC
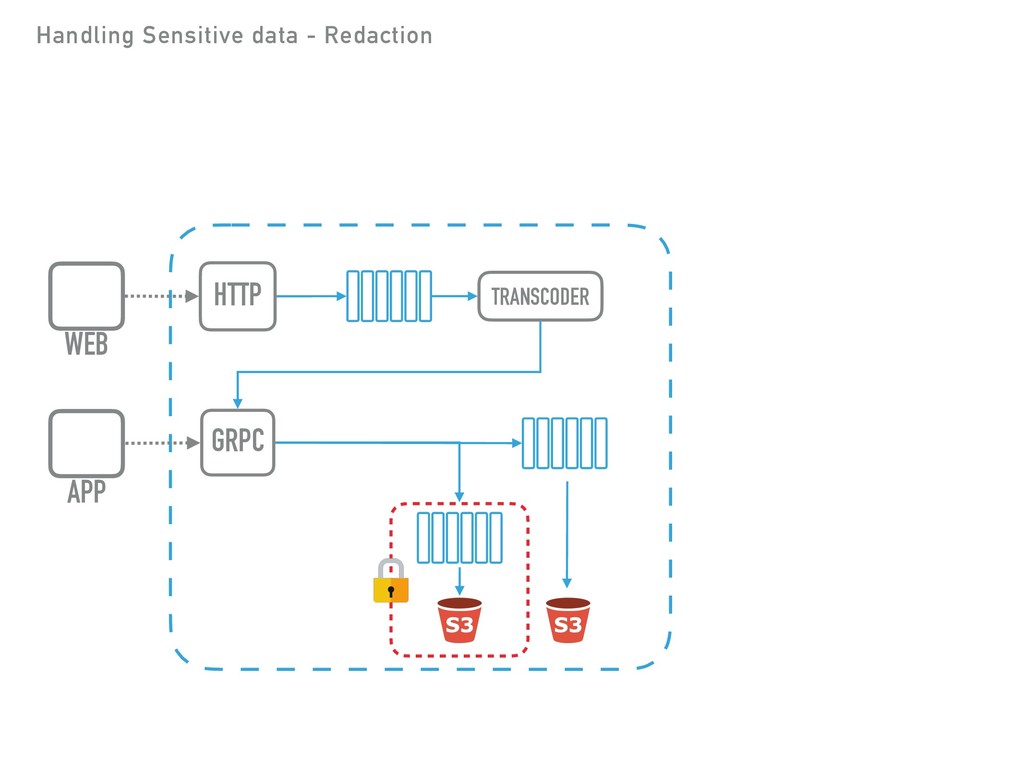
HTTP GRPC TRANSCODER WEB APP Handling Sensitive data - Redaction
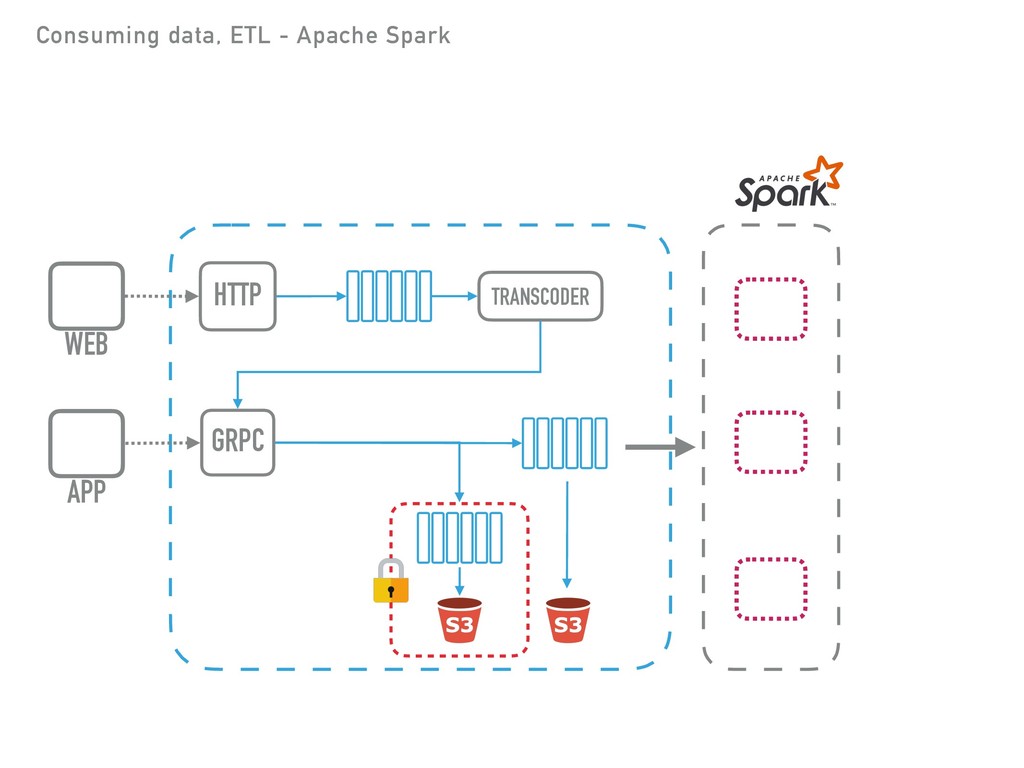
HTTP GRPC TRANSCODER WEB APP Consuming data, ETL - Apache
Spark
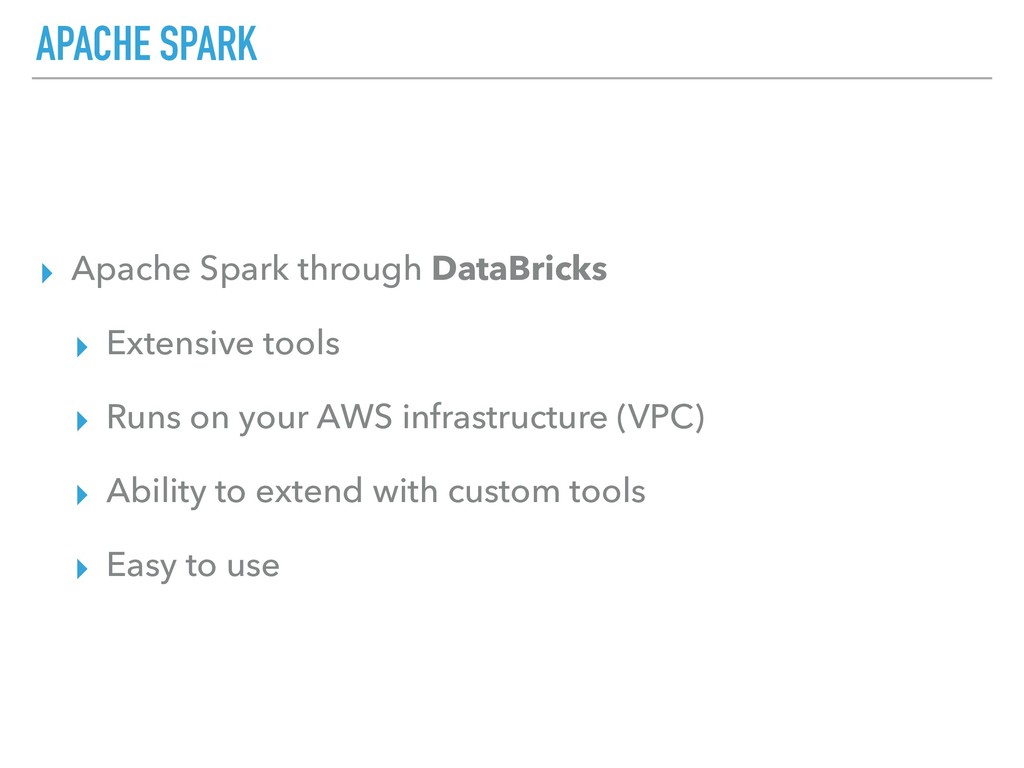
APACHE SPARK ▸ Apache Spark through DataBricks ▸ Extensive tools
▸ Runs on your AWS infrastructure (VPC) ▸ Ability to extend with custom tools ▸ Easy to use
HTTP GRPC TRANSCODER WEB APP
HTTP GRPC TRANSCODER WEB APP
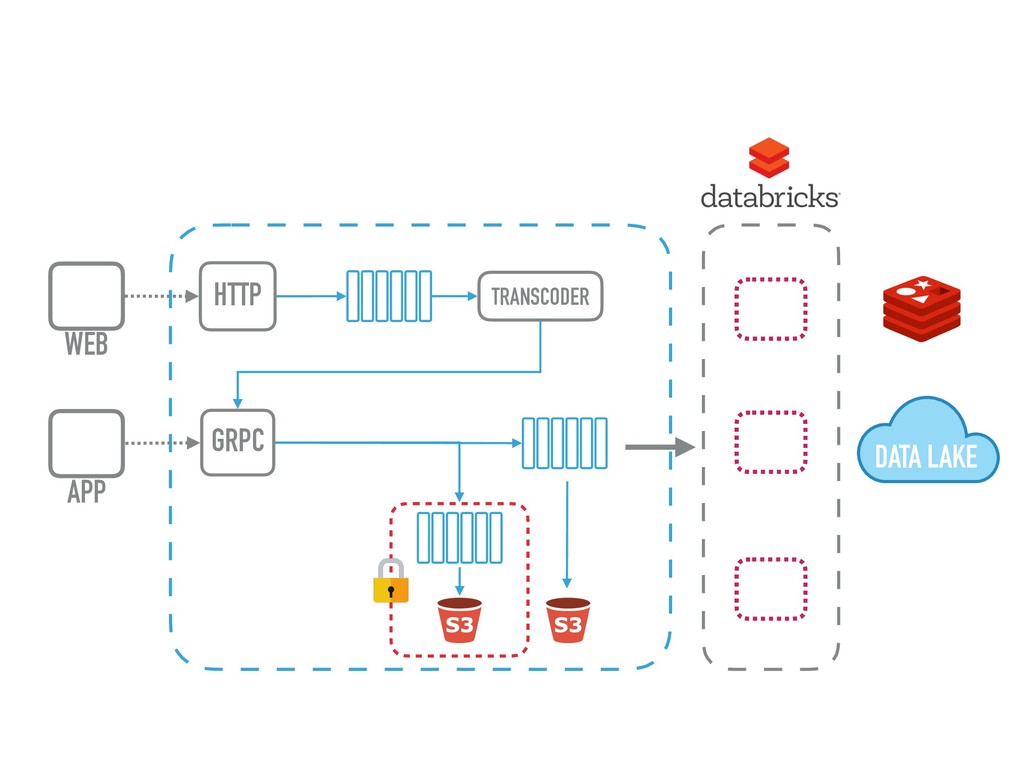
DATA LAKE HTTP GRPC TRANSCODER WEB APP
DATA LAKE HTTP GRPC TRANSCODER WEB APP
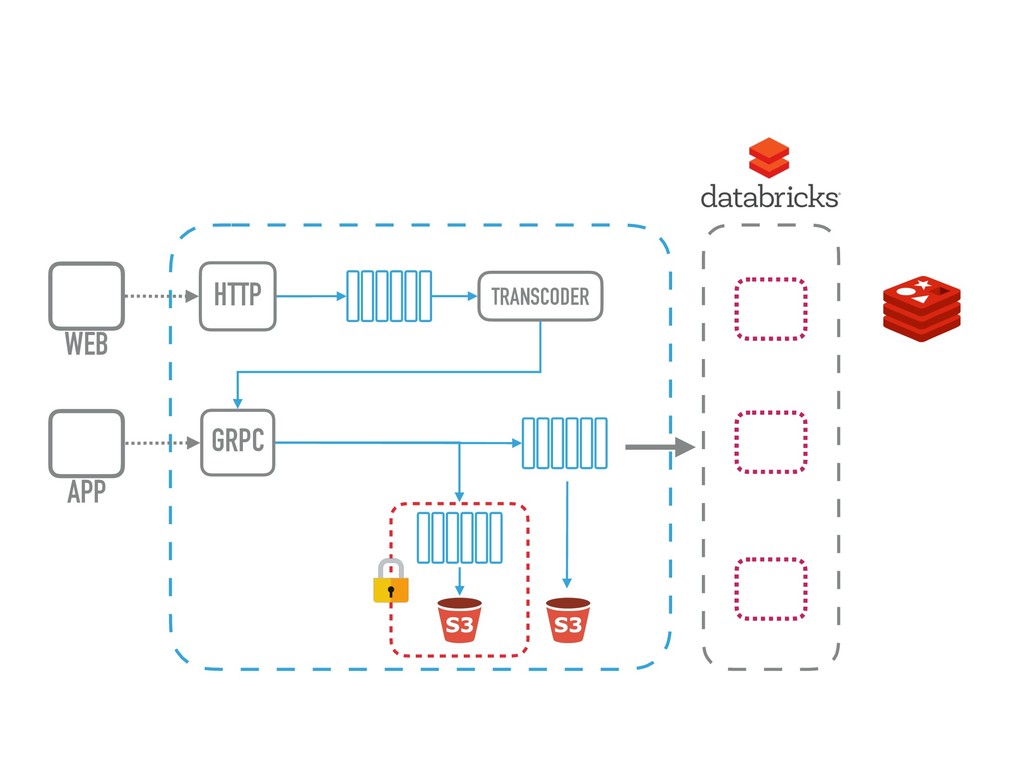
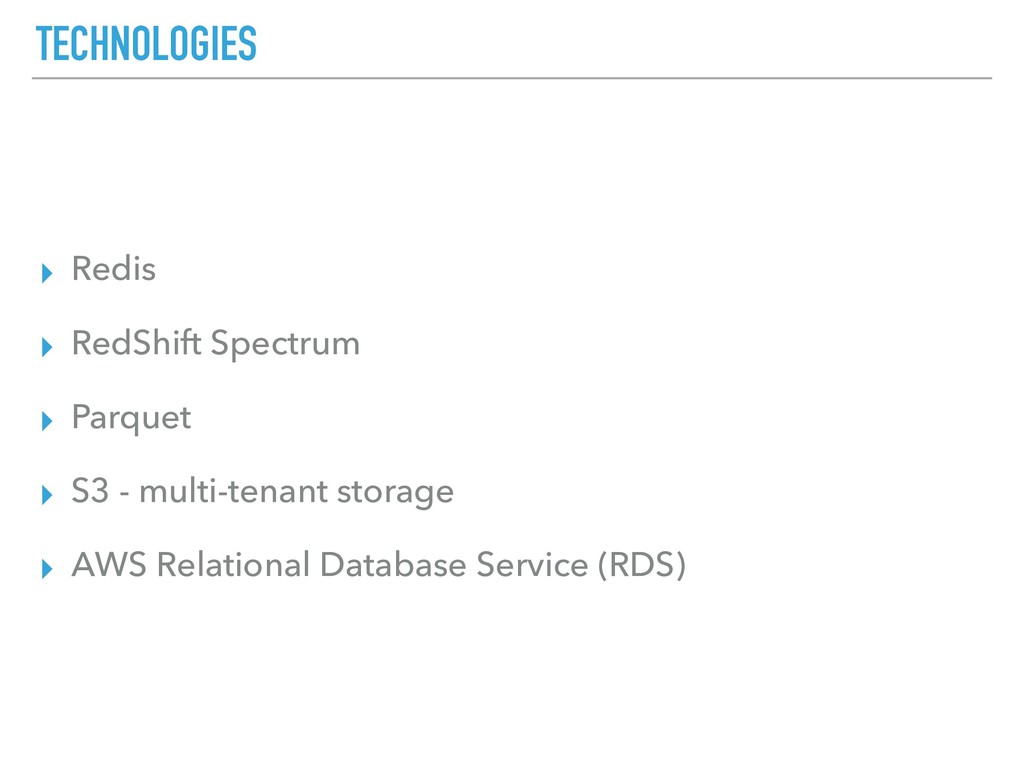
TECHNOLOGIES ▸ Redis ▸ RedShift Spectrum ▸ Parquet ▸ S3
- multi-tenant storage ▸ AWS Relational Database Service (RDS)
DATA LAKE HTTP GRPC TRANSCODER WEB APP
LEARNED 6 LESSONS
OBSERVABILITY 1/6
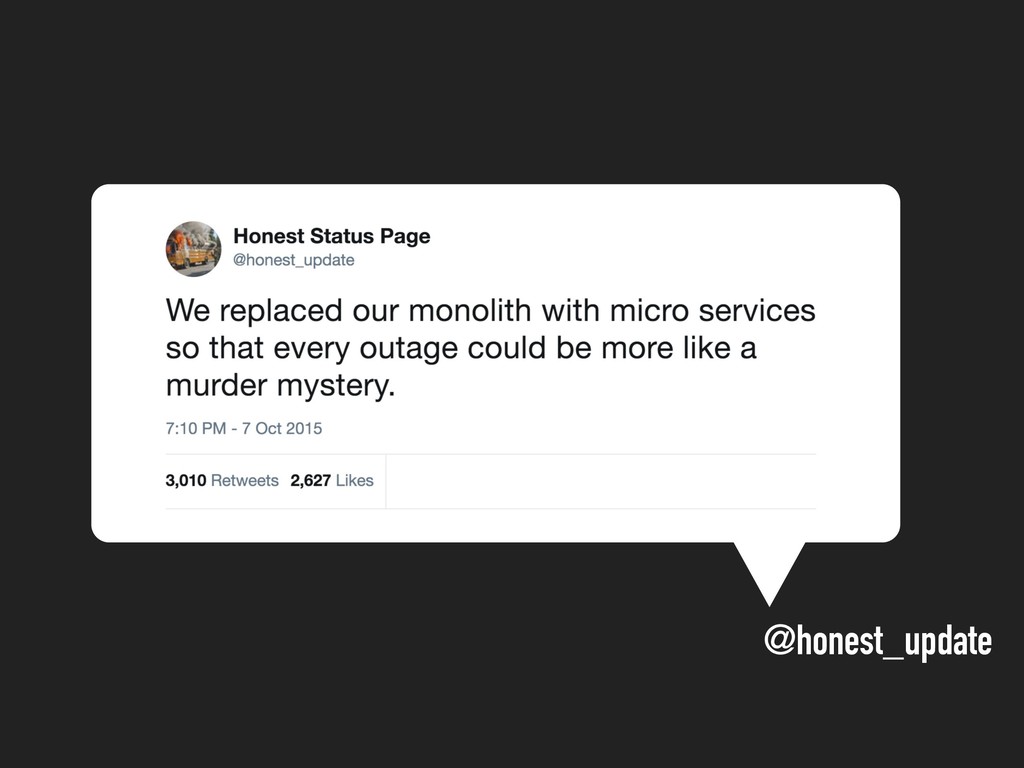
@honest_update
▸ Golden metrics ▸ Latency ▸ Traffic ▸ Errors ▸
Saturation MONITORING Google | Site Reliability Engineering
▸ Analyzing long-term trends ▸ Predict future capacity ▸ Detect
anomalies in trends ▸ Symptoms vs. Causes ▸ What’s broken & why MONITORING Google | Site Reliability Engineering
▸ Black box monitoring ▸ Periodic test message ▸ Measure
end-to-end ▸ White box monitoring ▸ Monitor individual components MONITORING Google | Site Reliability Engineering
DISTRIBUTED TRACING
▸ Visibility to system over time ▸ Locally aggregated logs
▸ Centralized logs DISTRIBUTED TRACING
▸ Define thresholds ▸ Define appropriate resolution ▸ Signal vs.
Noise ▸ Define escalation paths ALERTING
DURABILITY 2/6
APP 1 2 3 4
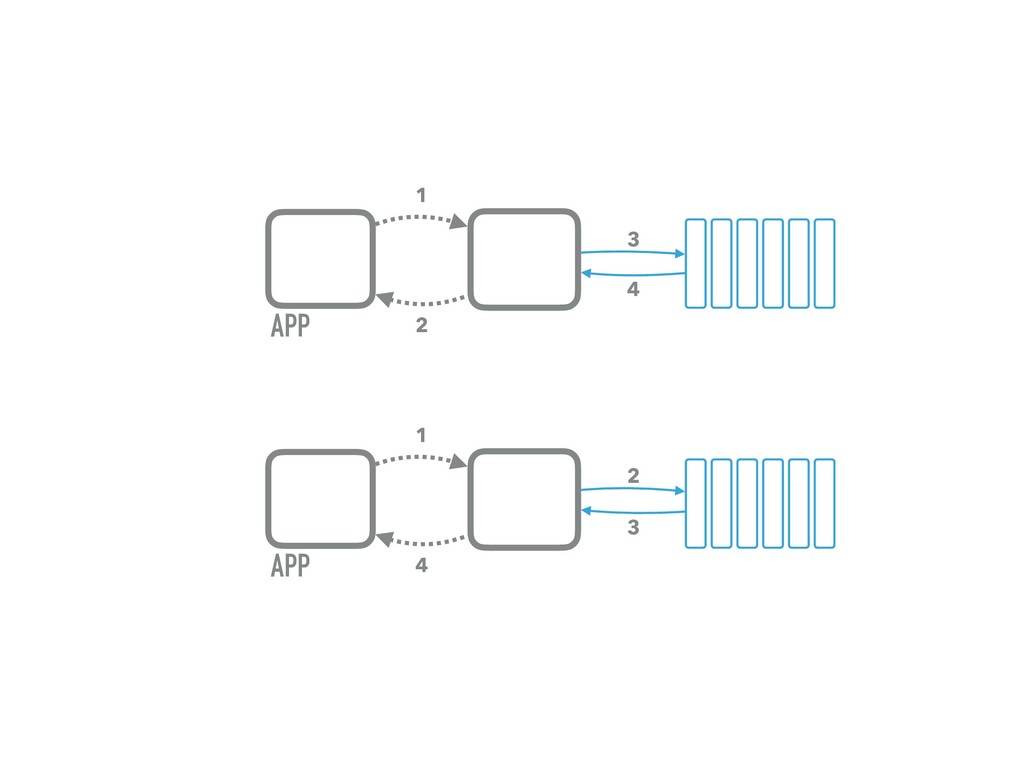
APP 1 2 3 APP 1 4 2 4 3
APP 1 2 3 APP 1 4 2 4 3
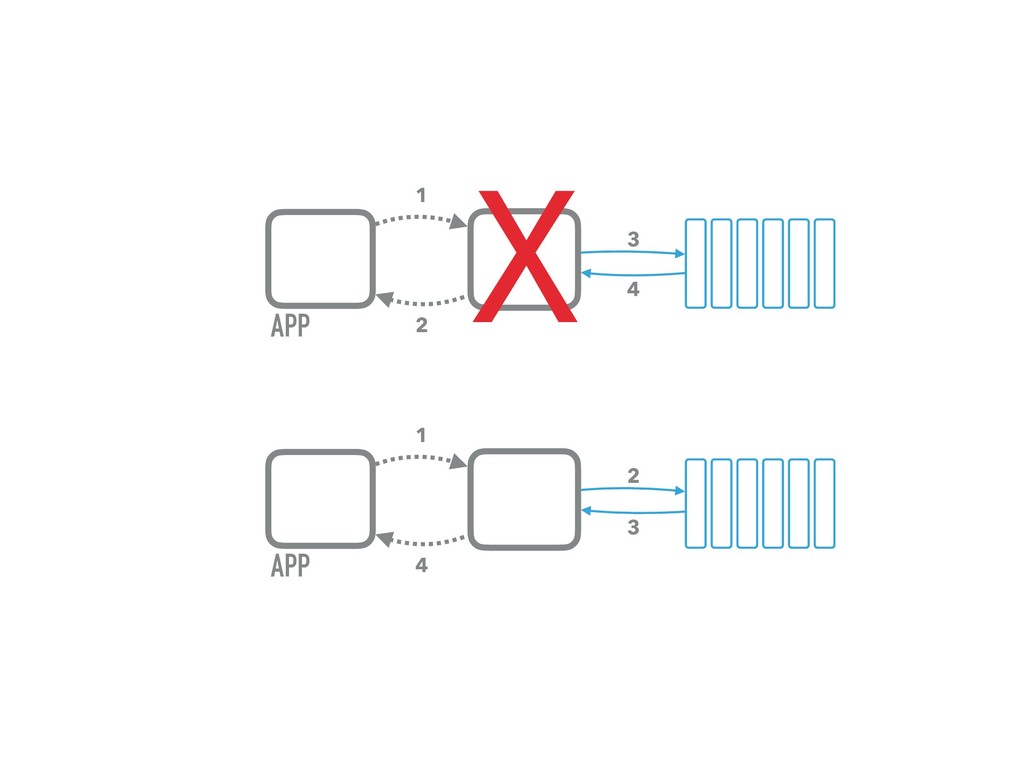
X
APP 1 2 3 APP 1 4 2 4 3
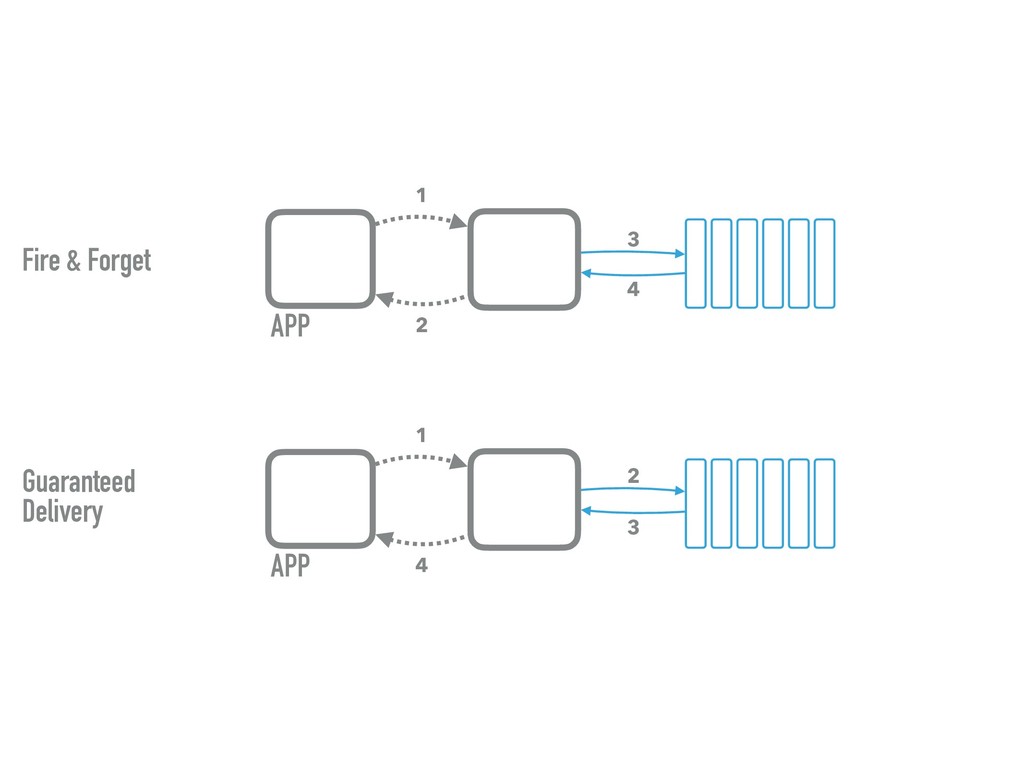
Fire & Forget Guaranteed Delivery
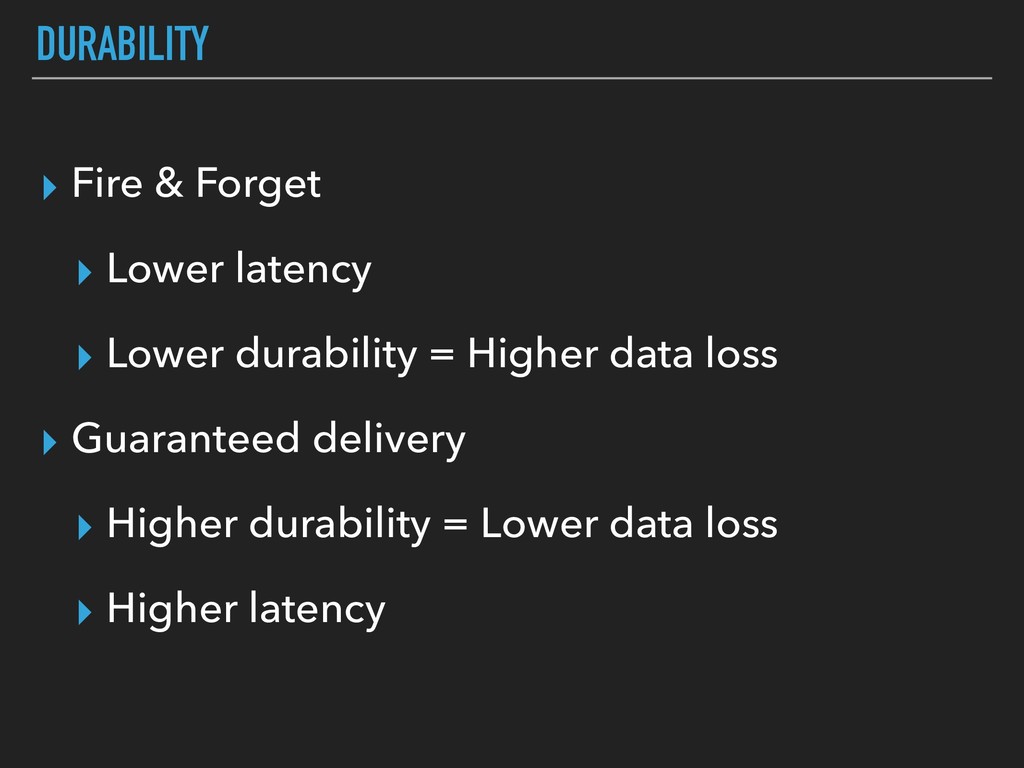
▸ Fire & Forget ▸ Lower latency ▸ Lower durability
= Higher data loss ▸ Guaranteed delivery ▸ Higher durability = Lower data loss ▸ Higher latency DURABILITY
▸ Delivery semantics ▸ At least once ▸ Exactly once
▸ At most once DURABILITY
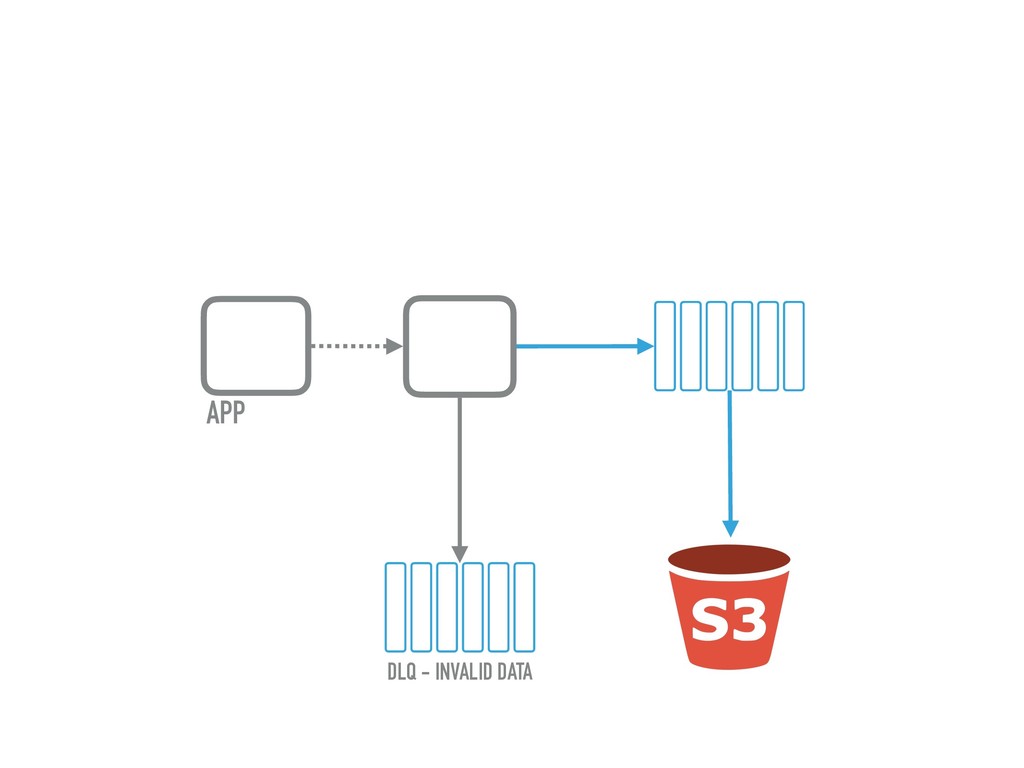
▸ Human error / Machine error ▸ Simple collectors ▸
Immutable data ▸ Disaster recovery / Replay of historical data ▸ Dead Letter Queue (DLQ) for invalid data FAULT TOLERANCE
APP DLQ - INVALID DATA
ARCHITECTURE & Technologies 3/6
ARCHITECTURE & TECHNOLOGIES AS SIMPLE AS POSSIBLE, BUT NOT SIMPLER
Albert Einstein
▸ Understand the technologies ▸ Understand the trade-offs ▸ Build
vs. Buy TECHNOLOGIES
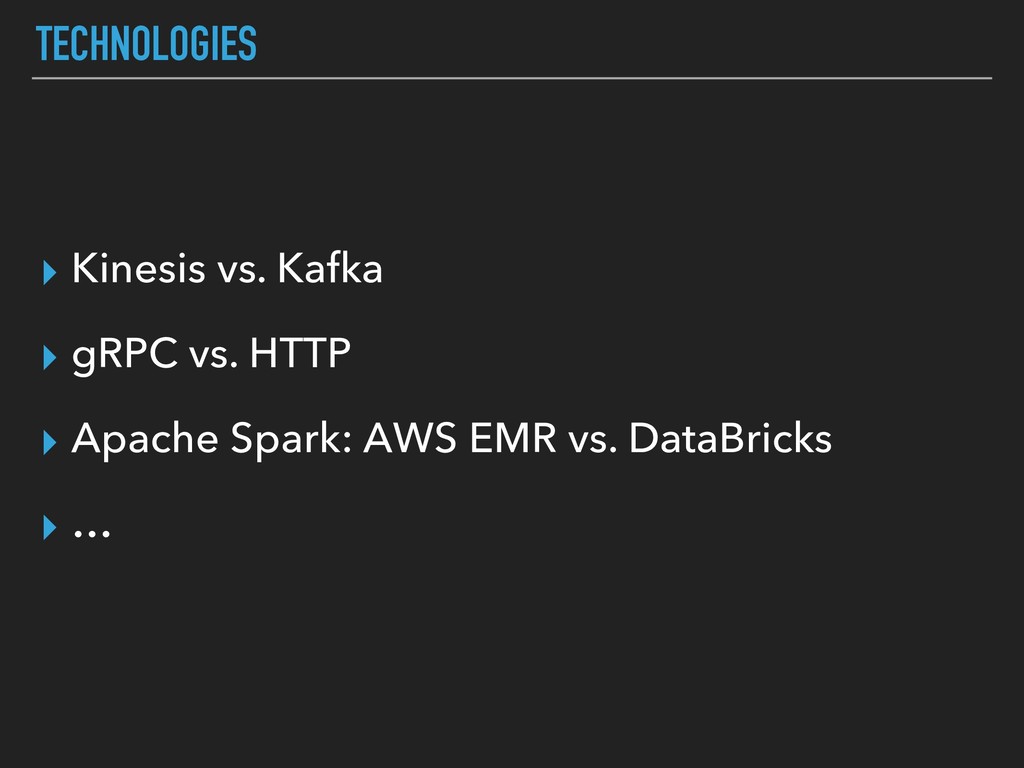
▸ Kinesis vs. Kafka ▸ gRPC vs. HTTP ▸ Apache
Spark: AWS EMR vs. DataBricks ▸ … TECHNOLOGIES
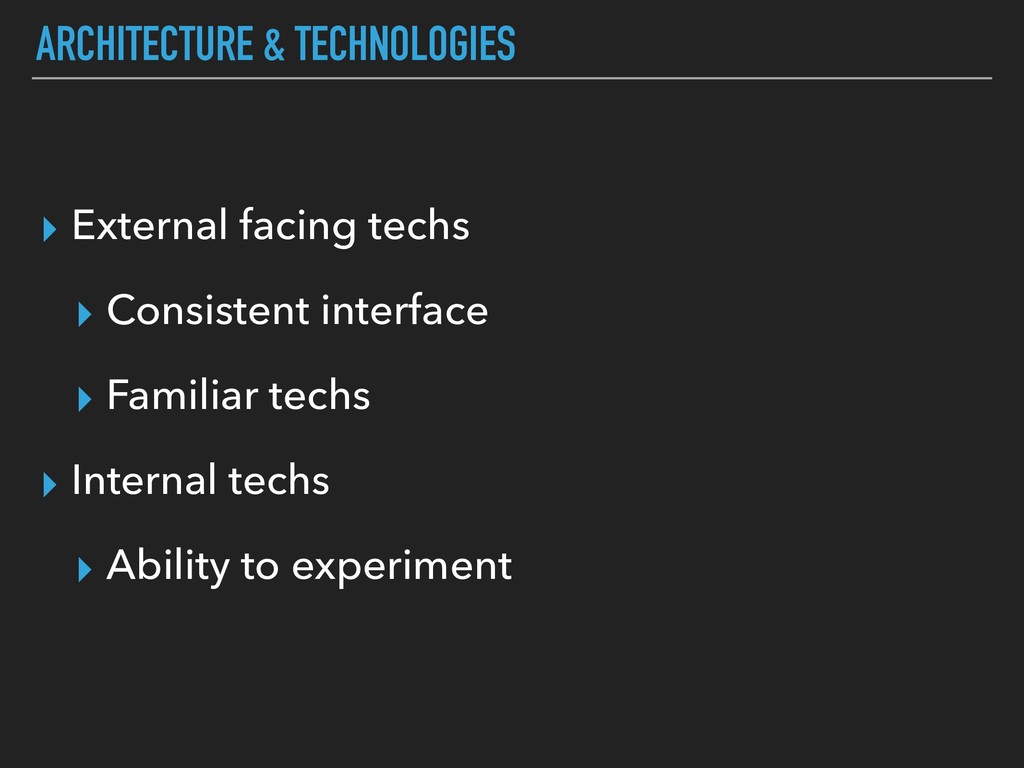
▸ External facing techs ▸ Consistent interface ▸ Familiar techs
▸ Internal techs ▸ Ability to experiment ARCHITECTURE & TECHNOLOGIES
SDK Software Development Kit 4/6
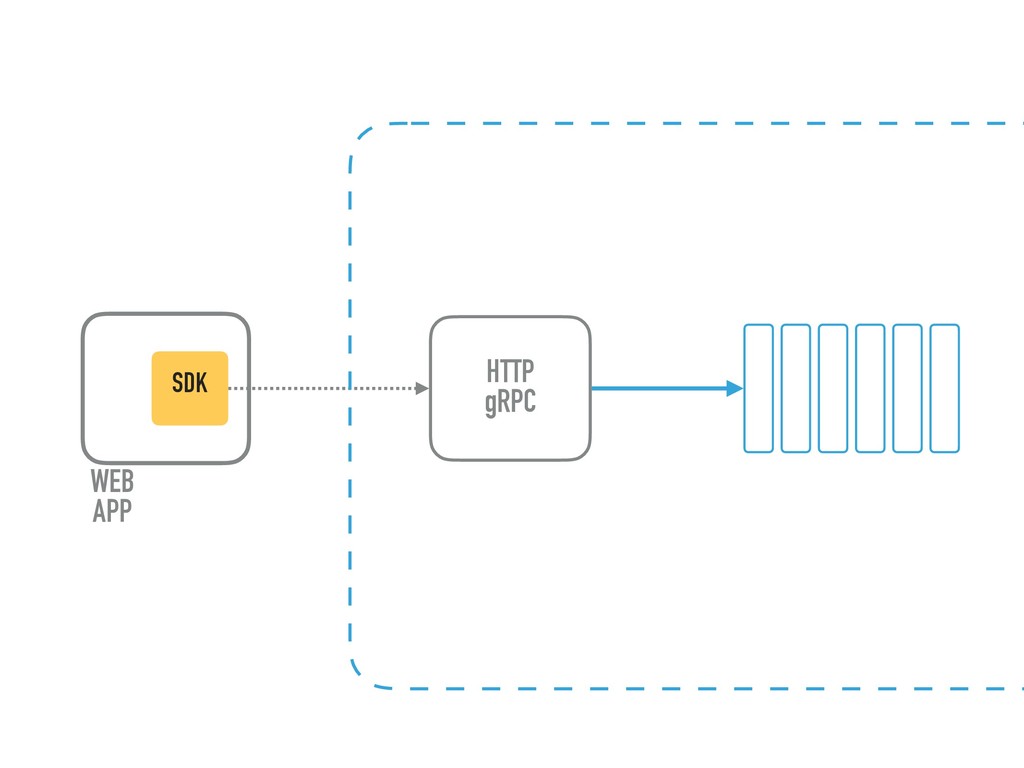
HTTP gRPC WEB APP SDK
▸ Provide in early stages ▸ Easier adoption of service
▸ Take control ▸ Build resiliency ▸ Retry mechanism ▸ Circuit breaker SDK
SECURITY Everyone’s Responsibility 5/6
▸ Do not collect the data you do not need
SECURITY
▸ Encryption: Rest vs. In-transit ▸ Anonymizing vs. Pseudonymizing ▸
Life cycle policies ▸ Enrichment SECURITY
▸ Multiple copies of the data? ▸ Right to be
forgotten (GDPR) SECURITY
AUTOMATION 6/6
▸ Builds and Deployments (CI / CD) ▸ Automate infrastructure
provisioning AUTOMATE
▸ Automatic provisioning ▸ Parameterized infrastructure code ▸ Reproducible environments
▸ Short-lived environments (tests) INFRASTRUCTURE AS CODE
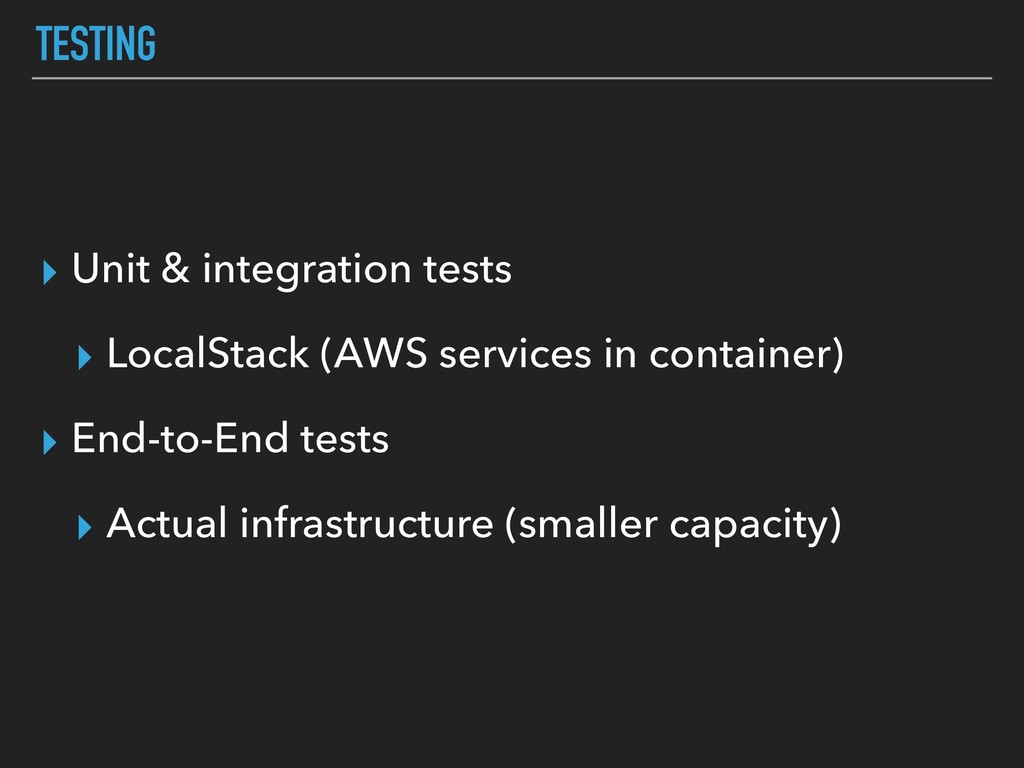
▸ Unit & integration tests ▸ LocalStack (AWS services in
container) ▸ End-to-End tests ▸ Actual infrastructure (smaller capacity) TESTING
TRADE-OFFS
▸ Maintainability ▸ Operations ▸ Security ▸ Simplicity ▸ Adoption
▸ Performance ▸ … TRADE-OFFS
INFORMED DECISIONS
QUESTIONS?
▸ Google | Site Reliability Engineering ▸ Designing Data Intensive
Applications RESOURCES
None


 majidfn
 ykanoh
 satoshi7
 kash1064
 jtakeda
 kakehashi
 shugo
 pfn
 yut0naga1_fa
 carta_engineering
 kaminashi
 4o1sobblue
 khoart
 raygrieselhuber
 soudai
 csswizardry
 coloredviolet
 sstephenson
 palkan
 ks91
 wayneb77
 tammielis
 gr2m
 helenjbeal