Share
Embed
ScalaDays 2019 : High performance privacy by design using Matryoshka & Spark

Olivier Girardot
June 13, 2019
Transcript
133 slides
-
High performance privacy by design using Matryoshka & Spark Olivier
Girardot Wiem Zine Elabidine @ogirardot @WiemZin High performance privacy by design using Matryoshka & Spark -
Who we are? Wiem Zine Elabidine Scala Backend Developer at
MOIA Github: wi101 Twitter: @WiemZin Olivier GIRARDOT Big Data Architect / Engineer / CoFounder @ Lateral Thoughts Github: ogirardot Twitter: @ogirardot -
Privacy Framework Recursive Data structures Recursion schemes using Matryoshka Privacy
engine using Matryoshka Plan -
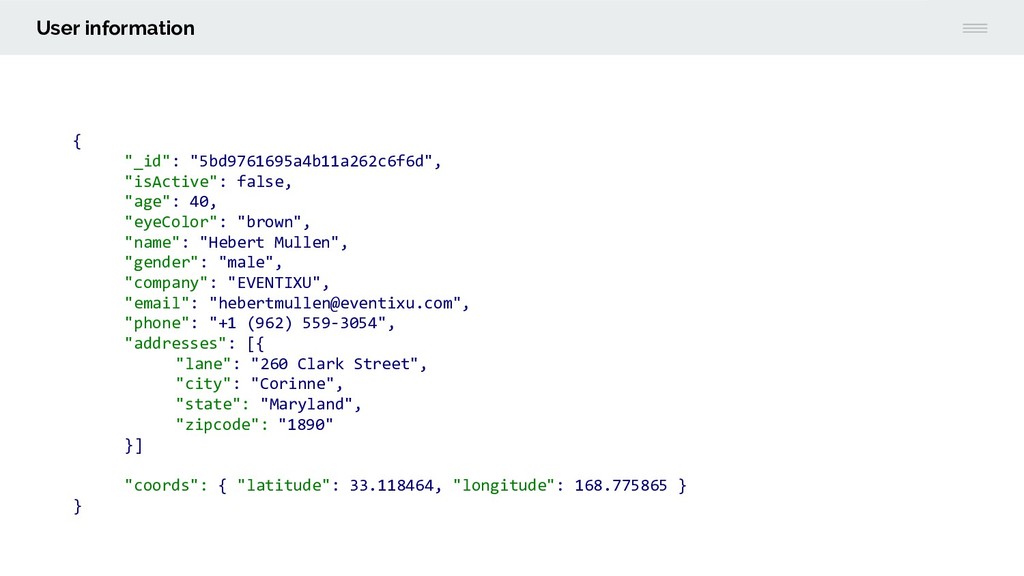
{ "_id": "5bd9761695a4b11a262c6f6d", "isActive": false, "age": 40, "eyeColor": "brown", "name":
"Hebert Mullen", "gender": "male", "company": "EVENTIXU", "email": "[email protected]", "phone": "+1 (962) 559-3054", "addresses": [{ "lane": "260 Clark Street", "city": "Corinne", "state": "Maryland", "zipcode": "1890" }] "coords": { "latitude": 33.118464, "longitude": 168.775865 } } User information -
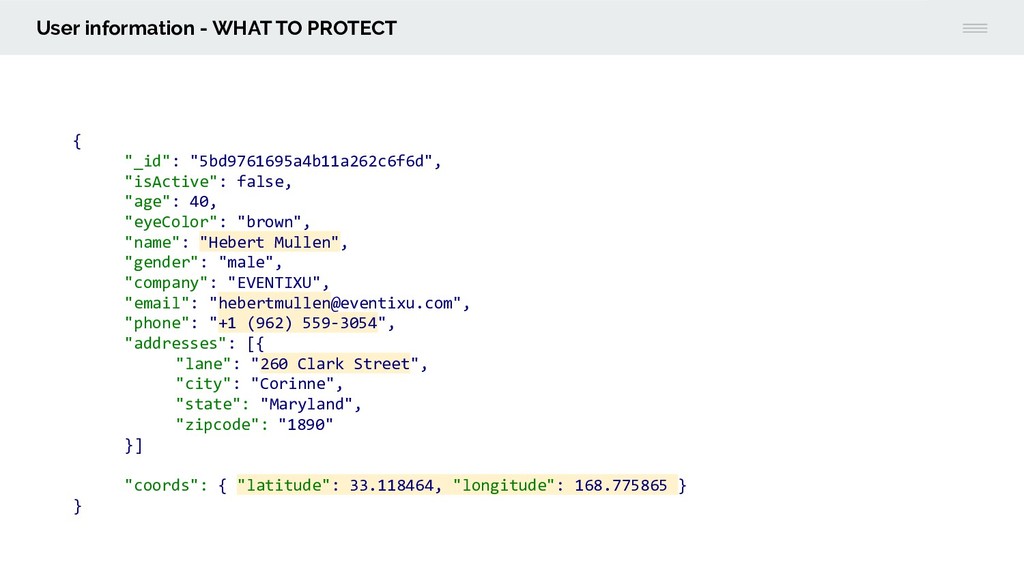
User information - WHAT TO PROTECT { "_id": "5bd9761695a4b11a262c6f6d", "isActive":
false, "age": 40, "eyeColor": "brown", "name": "Hebert Mullen", "gender": "male", "company": "EVENTIXU", "email": "[email protected]", "phone": "+1 (962) 559-3054", "addresses": [{ "lane": "260 Clark Street", "city": "Corinne", "state": "Maryland", "zipcode": "1890" }] "coords": { "latitude": 33.118464, "longitude": 168.775865 } } -
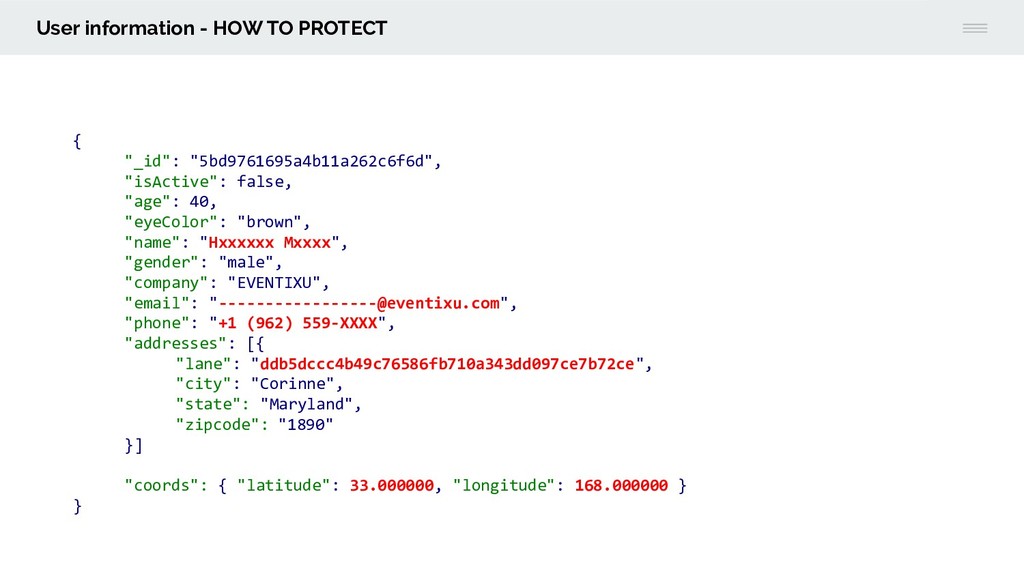
User information - HOW TO PROTECT { "_id": "5bd9761695a4b11a262c6f6d", "isActive":
false, "age": 40, "eyeColor": "brown", "name": "Hxxxxxx Mxxxx", "gender": "male", "company": "EVENTIXU", "email": "[email protected]", "phone": "+1 (962) 559-XXXX", "addresses": [{ "lane": "ddb5dccc4b49c76586fb710a343dd097ce7b72ce", "city": "Corinne", "state": "Maryland", "zipcode": "1890" }] "coords": { "latitude": 33.000000, "longitude": 168.000000 } } -
• Build a generic privacy framework • Dynamically apply privacy
on specified fields with different encryption functions. Goal -
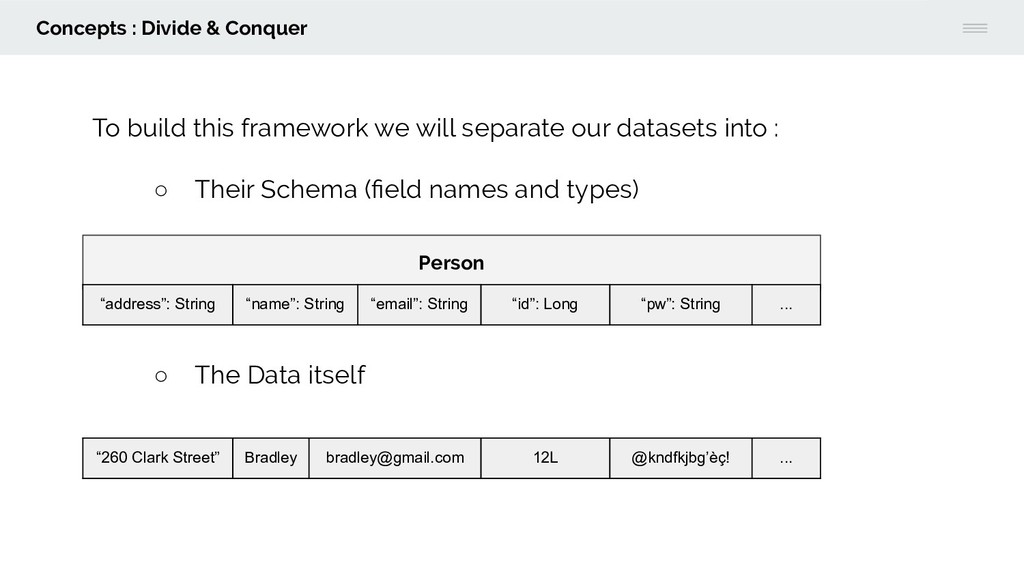
To build this framework we will separate our datasets into
: ◦ Their Schema (field names and types) ◦ The Data itself Concepts : Divide & Conquer Person “address”: String “name”: String “email”: String “id”: Long “pw”: String ... “260 Clark Street” Bradley [email protected] 12L @kndfkjbg’èç! ... -
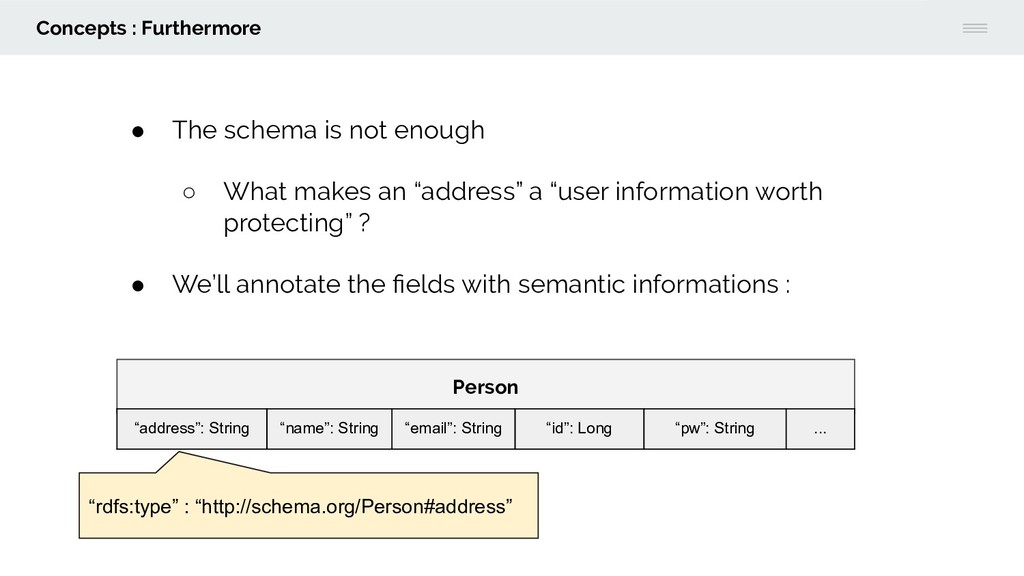
• The schema is not enough ◦ What makes an
“address” a “user information worth protecting” ? • We’ll annotate the fields with semantic informations : Concepts : Furthermore Person “address”: String “name”: String “email”: String “id”: Long “pw”: String ... “rdfs:type” : “http://schema.org/Person#address” -
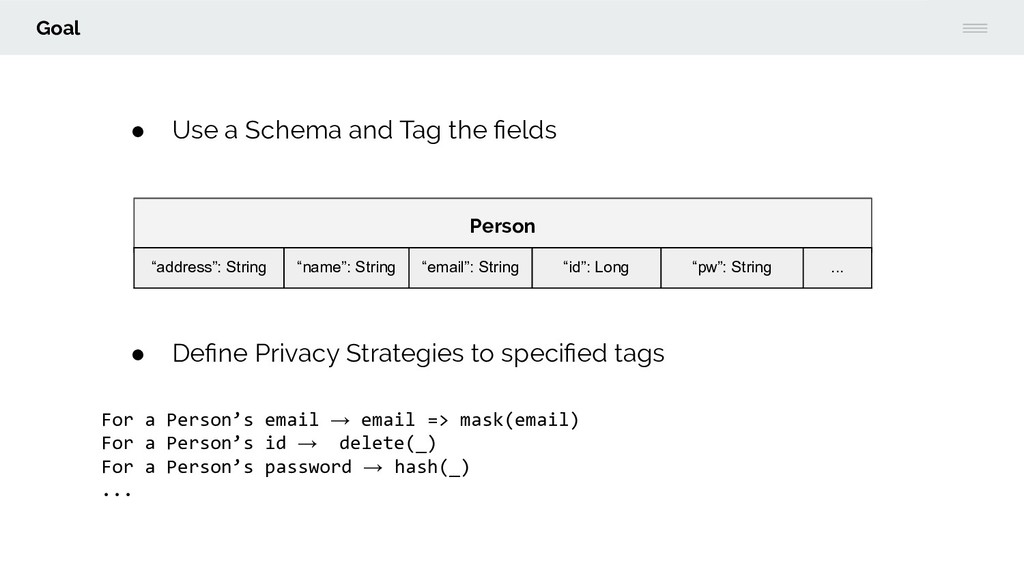
Goal • Use a Schema and Tag the fields •
Define Privacy Strategies to specified tags Person “address”: String “name”: String “email”: String “id”: Long “pw”: String ... For a Person’s email → email => mask(email) For a Person’s id → delete(_) For a Person’s password → hash(_) ... -
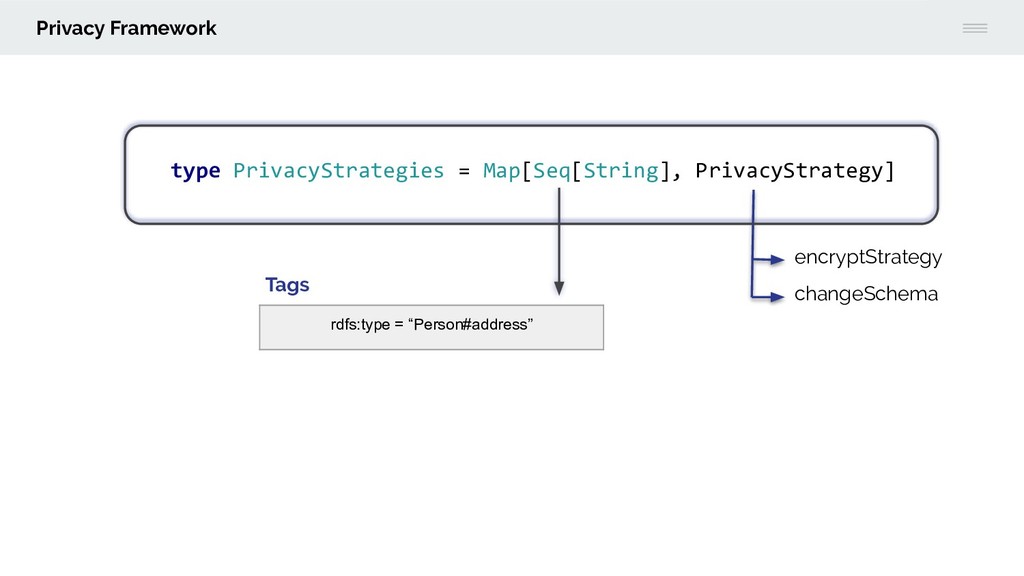
Privacy Framework Tags rdfs:type = “Person#address” encryptStrategy changeSchema type PrivacyStrategies
= Map[Seq[String], PrivacyStrategy] -
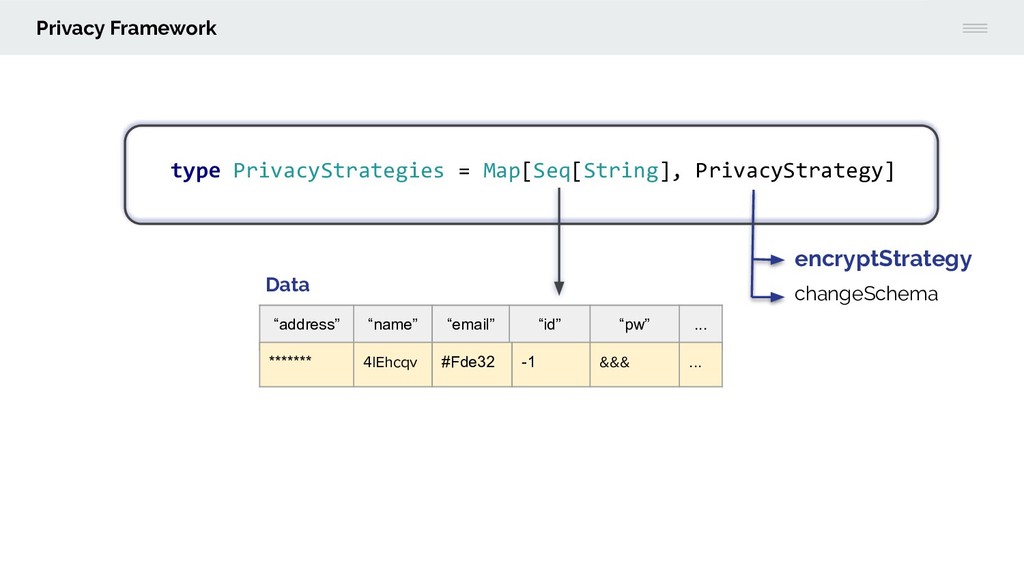
Privacy Framework Data “address” “name” “email” “id” “pw” ... encryptStrategy
changeSchema type PrivacyStrategies = Map[Seq[String], PrivacyStrategy] ******* 4lEhcqv #Fde32 -1 &&& ... -
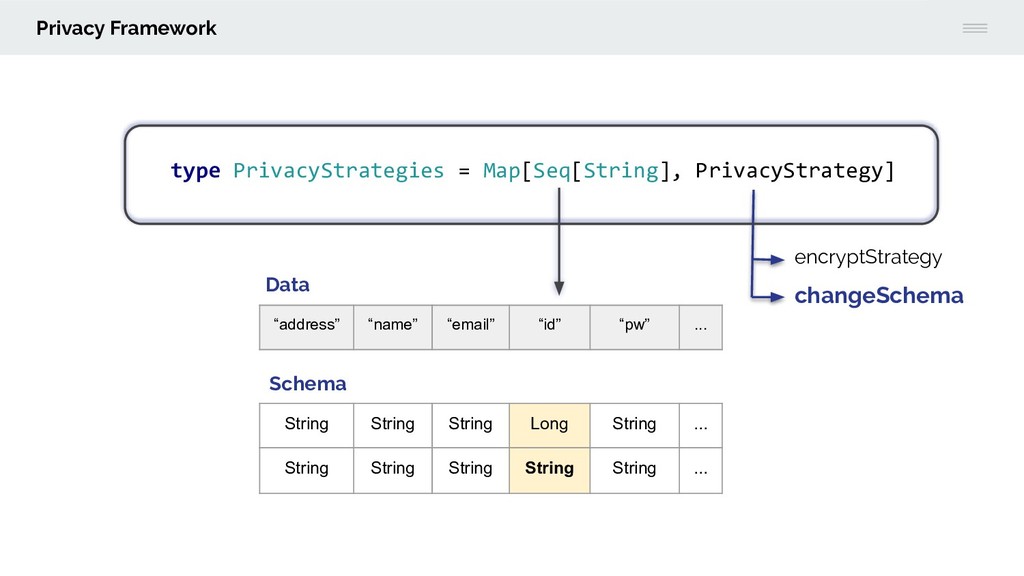
Privacy Framework Data “address” “name” “email” “id” “pw” ... encryptStrategy
changeSchema type PrivacyStrategies = Map[Seq[String], PrivacyStrategy] Schema String String String Long String ... String String String String String ... -
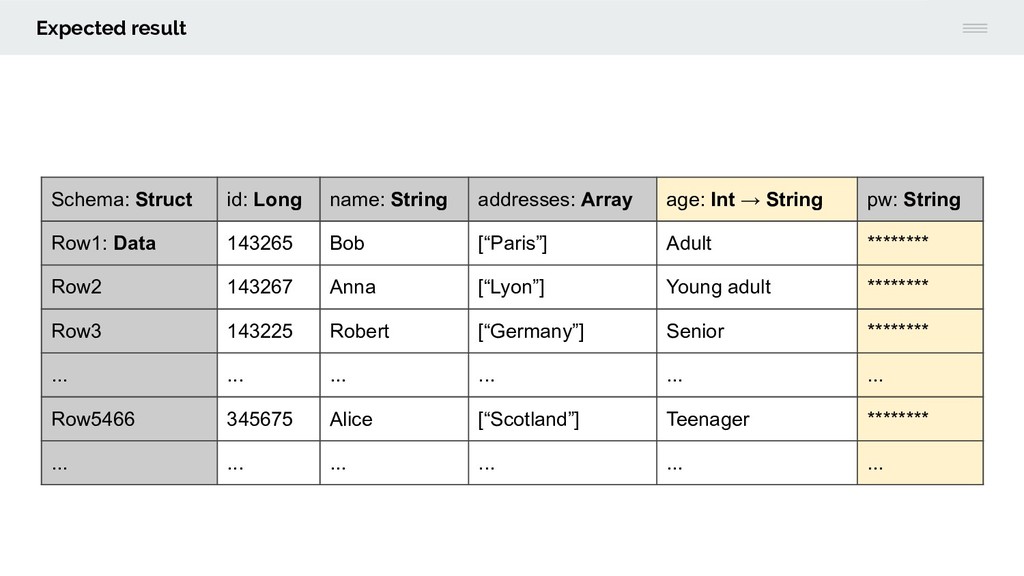
Expected result Schema: Struct id: Long name: String addresses: Array
age: Int → String pw: String Row1: Data 143265 Bob [“Paris”] Adult ******** Row2 143267 Anna [“Lyon”] Young adult ******** Row3 143225 Robert [“Germany”] Senior ******** ... ... ... ... ... ... Row5466 345675 Alice [“Scotland”] Teenager ******** ... ... ... ... ... ... -
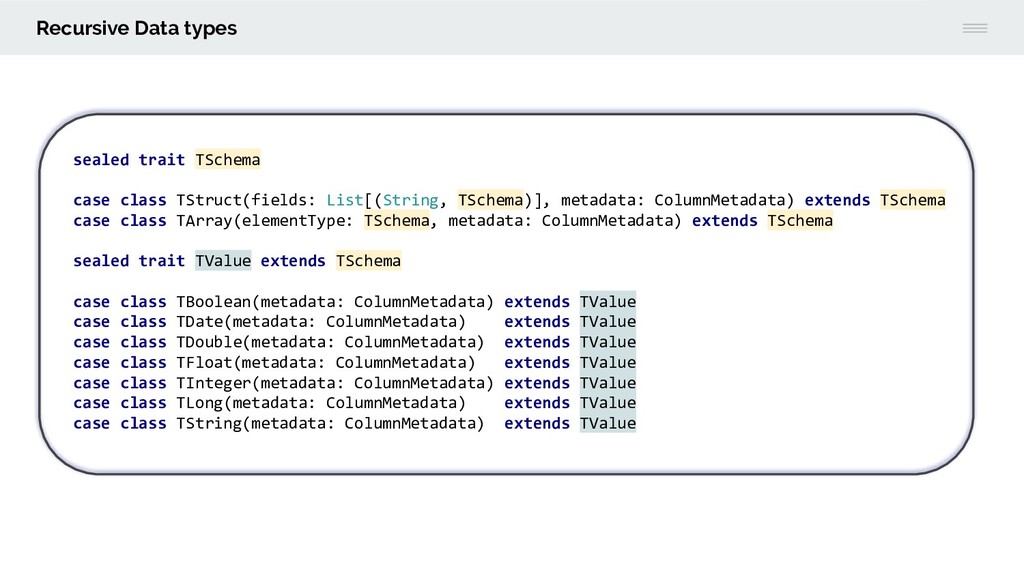
Recursive Data types sealed trait TSchema case class TStruct(fields: List[(String,
TSchema)], metadata: ColumnMetadata) extends TSchema case class TArray(elementType: TSchema, metadata: ColumnMetadata) extends TSchema sealed trait TValue extends TSchema case class TBoolean(metadata: ColumnMetadata) extends TValue case class TDate(metadata: ColumnMetadata) extends TValue case class TDouble(metadata: ColumnMetadata) extends TValue case class TFloat(metadata: ColumnMetadata) extends TValue case class TInteger(metadata: ColumnMetadata) extends TValue case class TLong(metadata: ColumnMetadata) extends TValue case class TString(metadata: ColumnMetadata) extends TValue -
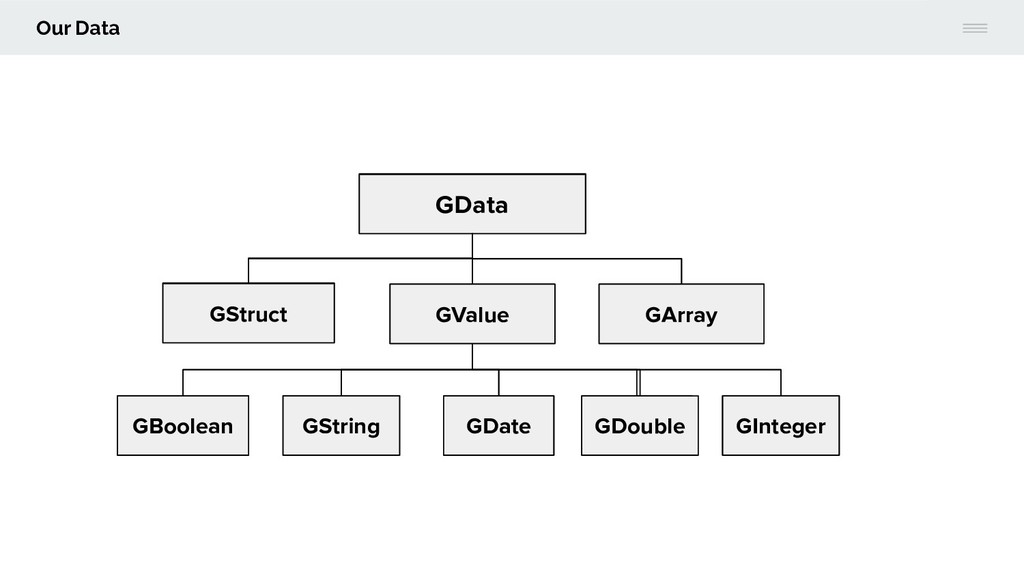
Our Data TSchema TDate TInteger TBoolean TStruct TArray TString TDouble
TValue GData GDate GInteger GBoolean GStruct GArray GString GDouble GValue -
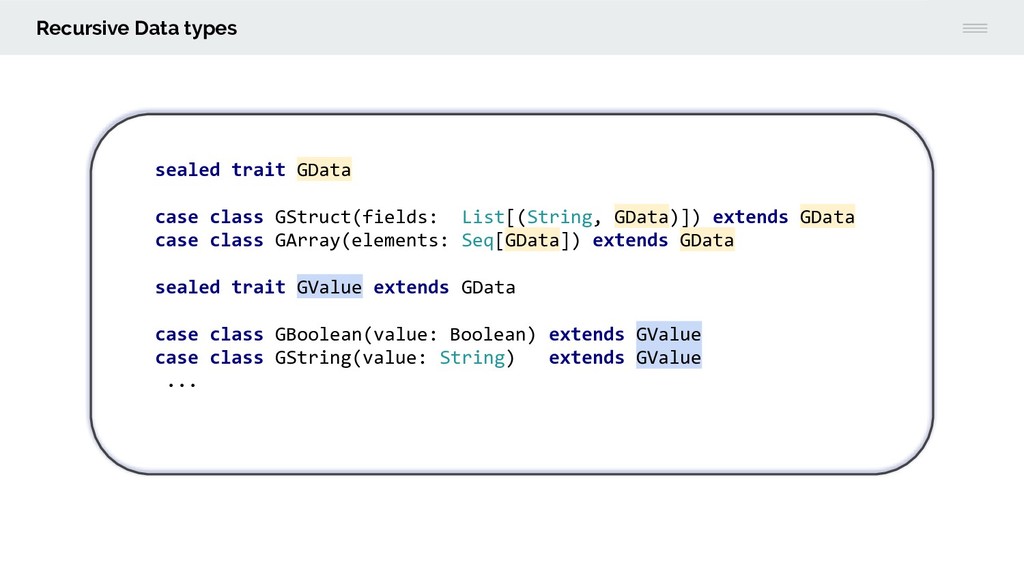
Recursive Data types sealed trait GData case class GStruct(fields: List[(String,
GData)]) extends GData case class GArray(elements: Seq[GData]) extends GData sealed trait GValue extends GData case class GBoolean(value: Boolean) extends GValue case class GString(value: String) extends GValue ... -
Same thing in Spark : Schema DataType DateType IntegerType BooleanType
ArrayType StructType StringType DoubleType Value Type -
Recursive functions - Think of how to traverse a recursive
structure and what to do with each layer - Complex code -
Recursive functions - Think of how to traverse a recursive
structure and what to do with each layer - Complex code -
Recursion Schemes + Separate how to traverse a recursive structure
and what to do with each layer + Maintainable code Functional Programming with Bananas, Lenses, Envelopes and Barbed Wire -
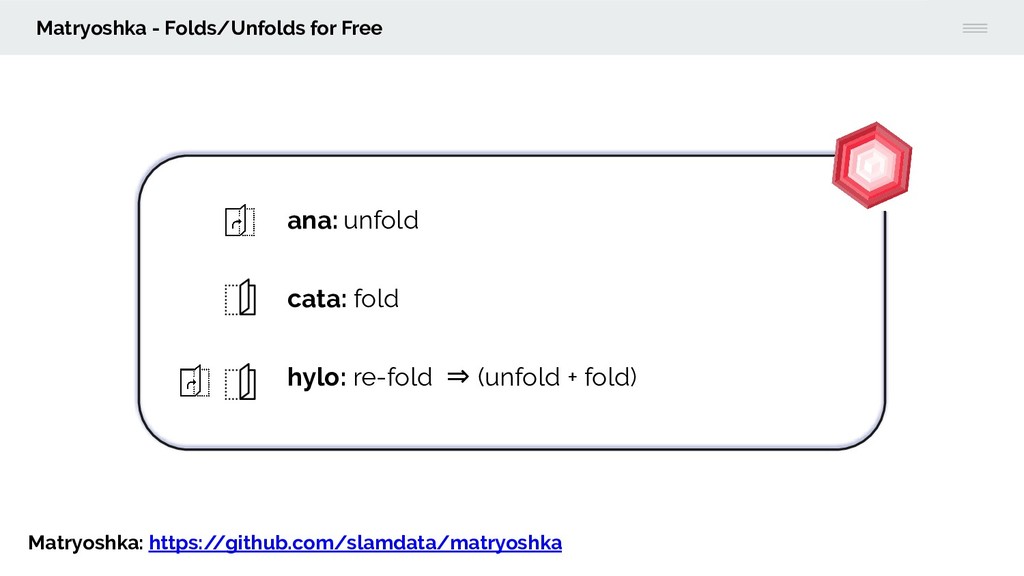
Matryoshka - Folds/Unfolds for Free ana: unfold cata: fold hylo:
re-fold ⇒ (unfold + fold) Matryoshka: https:/ /github.com/slamdata/matryoshka -
Remove Recursion sealed trait TSchema case class TStruct(fields: List[(String, TSchema)],
metadata: ColumnMetadata) extends TSchema case class TArray(elementType: TSchema, metadata: ColumnMetadata) extends TSchema sealed trait TValue extends TSchema case class TBoolean(metadata: ColumnMetadata) extends TSchema case class TString(metadata: ColumnMetadata) extends TSchema ... -
Remove Recursion sealed trait TSchema case class TStruct(fields: List[(String, TSchema)],
metadata: ColumnMetadata) extends TSchema case class TArray(elementType: TSchema, metadata: ColumnMetadata) extends TSchema sealed trait TValue extends TSchema case class TBoolean(metadata: ColumnMetadata) extends TSchema case class TString(metadata: ColumnMetadata) extends TSchema ... sealed trait SchemaF[A] case class StructF[A] (fields: List[(String, A)], metadata: ColumnMetadata) extends SchemaF[A] case class ArrayF[A](elementType: A, metadata: ColumnMetadata) extends SchemaF[A] sealed trait ValueF[A] extends SchemaF[A] case class BooleanF[A](metadata: ColumnMetadata) extends ValueF[A] case class StringF[A](metadata: ColumnMetadata) extends ValueF[A] … -
Remove Recursion sealed trait TSchema case class TStruct(fields: List[(String, TSchema)],
metadata: ColumnMetadata) extends TSchema case class TArray(elementType: TSchema, metadata: ColumnMetadata) extends TSchema sealed trait TValue extends TSchema case class TBoolean(metadata: ColumnMetadata) extends TSchema case class TString(metadata: ColumnMetadata) extends TSchema ... sealed trait SchemaF[A] case class StructF[A] (fields: List[(String, A)], metadata: ColumnMetadata) extends SchemaF[A] case class ArrayF[A](elementType: A, metadata: ColumnMetadata) extends SchemaF[A] sealed trait ValueF[A] extends SchemaF[A] case class BooleanF[A](metadata: ColumnMetadata) extends ValueF[A] case class StringF[A](metadata: ColumnMetadata) extends ValueF[A] … -
Remove Recursion case class StructF[A] (fields: List[(String, A)], metadata: ColumnMetadata)
extends SchemaF[A] case class ArrayF[A](elementType: A, metadata: ColumnMetadata) extends SchemaF[A] What if A is another SchemaF[A]? -
Remove Recursion Schema with Different shape val schema: SchemaF[SchemaF[ ]]
= StructF(List("adresses" -> ArrayF(StringF[Nothing](m1), m2), m3), m4) -
Remove Recursion Schema with Different shape val schema: SchemaF[SchemaF[ ]]
= StructF(List("adresses" -> ArrayF(StringF[Nothing](m1), m2), m3), m4) We need something like this: val schema:Type[SchemaF] -
Recapture Recursion case class Fix[F[_]](unFix: F[Fix[F]]) val schema: Fix[SchemaF] =
Fix(StructF(List("isAvailable" -> Fix(BooleanF(???)), "date" -> Fix(DataF(???)), "person" -> Fix(StructF(List("name" -> Fix(StringF(???)), "array" -> Fix(ArrayF(Fix(DoubleF(???)), ???))), ???))), ???)) -
Define Functor implicit val schemaFunctor: Functor[SchemaF] = new Functor[SchemaF] {
def map[A, B](fa: SchemaF[A])(f: A => B): SchemaF[B] = fa match { case StructF(fields, m) => StructF(fields.map{ case (name, value) => name -> f(value) }), m) case ArrayF(elem, m) => ArrayF(f(elem), m) case BooleanF(m) => BooleanF(m) case StringF(m) => StringF(m) case IntegerF(m) => IntegerF(m) ... } } -
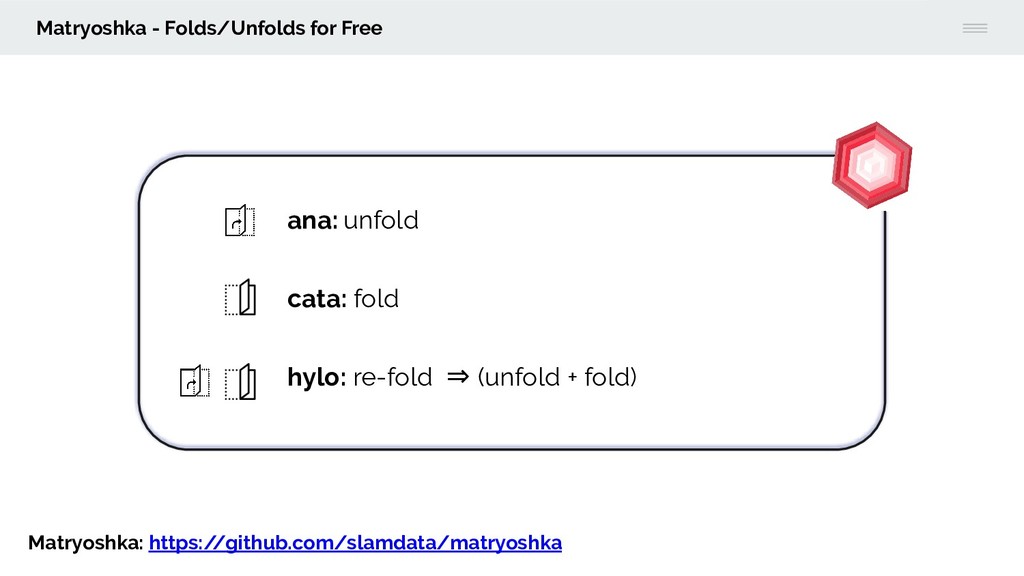
Matryoshka - Folds/Unfolds for Free ana: unfold cata: fold hylo:
re-fold ⇒ (unfold + fold) Matryoshka: https:/ /github.com/slamdata/matryoshka -
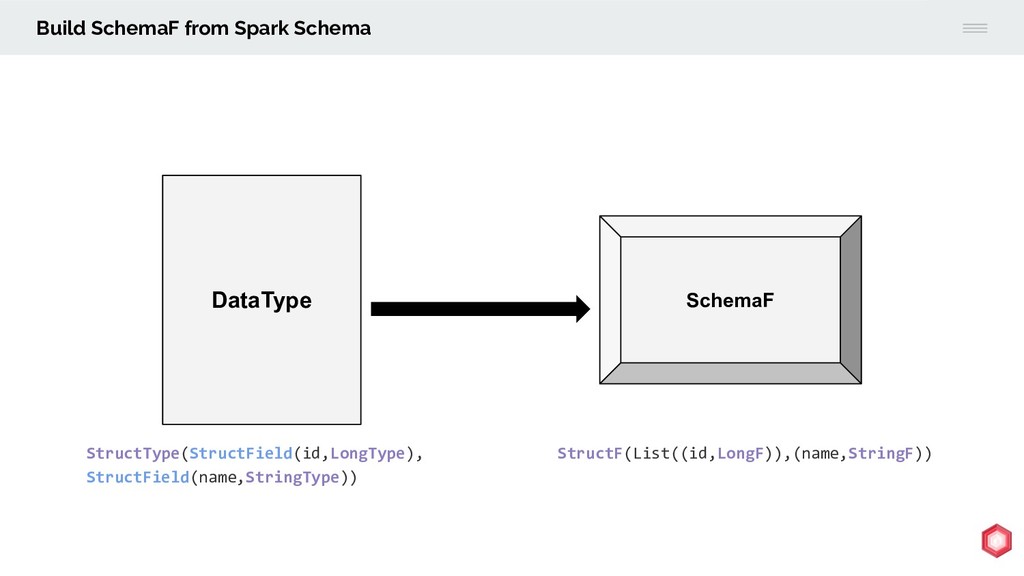
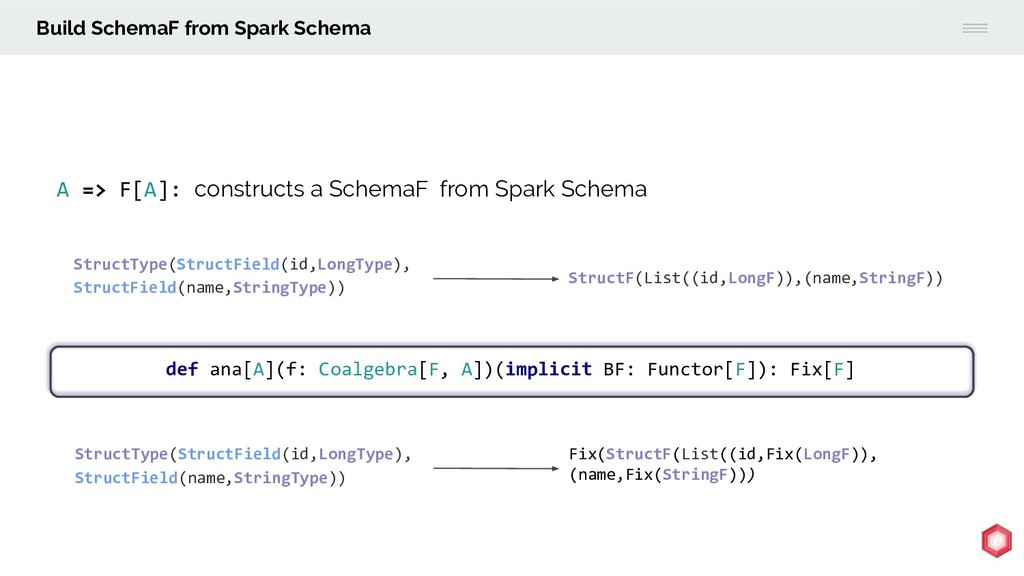
StructType(StructField(id,LongType), StructField(name,StringType)) StructF(List((id,LongF)),(name,StringF)) Build SchemaF from Spark Schema A =>
F[A]: constructs a SchemaF from Spark Schema -
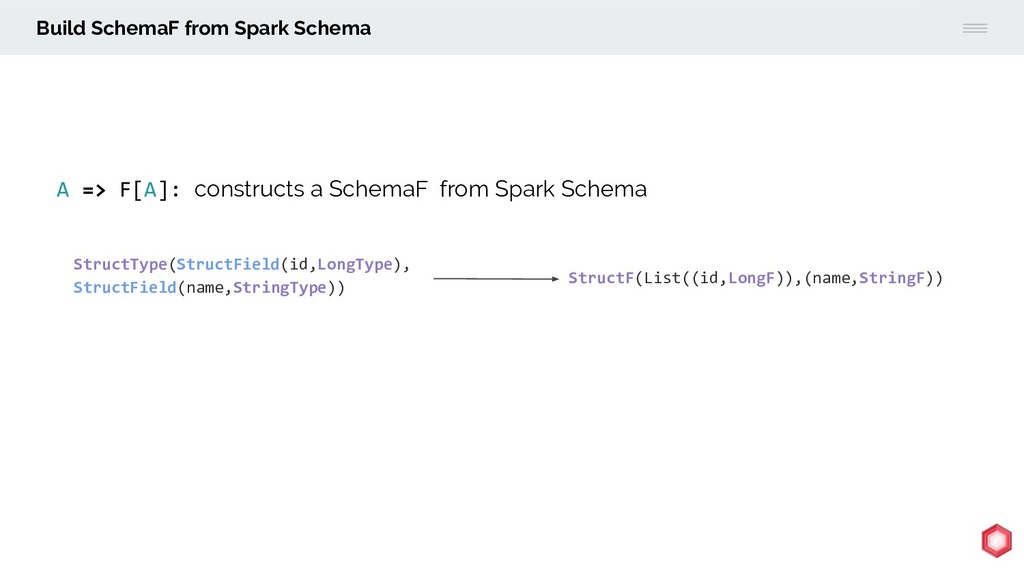
A => F[A]: constructs a SchemaF from Spark Schema StructType(StructField(id,LongType),
StructField(name,StringType)) StructF(List((id,LongF)),(name,StringF)) Build SchemaF from Spark Schema def ana[A](f: Coalgebra[F, A])(implicit BF: Functor[F]): Fix[F] -
StructType(StructField(id,LongType), StructField(name,StringType)) StructF(List((id,LongF)),(name,StringF)) StructType(StructField(id,LongType), StructField(name,StringType)) Fix(StructF(List((id,Fix(LongF)), (name,Fix(StringF))) Build SchemaF from
Spark Schema def ana[A](f: Coalgebra[F, A])(implicit BF: Functor[F]): Fix[F] A => F[A]: constructs a SchemaF from Spark Schema -
Matryoshka - ana StructType(StructField(id,LongType), StructField(name,StringType)) StructF LongType def ana[A](f: Coalgebra[F,
A])(implicit BF: Functor[F]): Fix[F] -
Matryoshka - ana StructType(StructField(id,LongType), StructField(name,StringType)) StructF LongF def ana[A](f: Coalgebra[F,
A])(implicit BF: Functor[F]): Fix[F] -
Matryoshka - ana StructType(StructField(id,LongType), StructField(name,StringType)) StructF LongF StringType def ana[A](f:
Coalgebra[F, A])(implicit BF: Functor[F]): Fix[F] -
Matryoshka - ana StructType(StructField(id,LongType), StructField(name,StringType)) StructF LongF StringF def ana[A](f:
Coalgebra[F, A])(implicit BF: Functor[F]): Fix[F] -
Matryoshka - ana StructType(StructField(id,LongType), StructField(name,StringType)) StructF LongF StringF def ana[A](f:
Coalgebra[F, A])(implicit BF: Functor[F]): Fix[F] -
Matryoshka - ana Coalgebra[F, A] = A => F[A] Coalgebra[SchemaF,
DataType] = DataType => SchemaF[DataType] def ana[A](f: Coalgebra[F, A])(implicit BF: Functor[F]): Fix[F] -
Matryoshka val dataTypeToSchemaF: Coalgebra[SchemaF, DataType] = { case StructType(fields) =>
StructF(fields.map(f => f.name -> f.dataType)), ColumnMetadata.empty) case ArrayType(elem, _) => ArrayF(elem, ColumnMetadata.empty) case BooleanType => BooleanF(ColumnMetadata.empty) case DateType => DateF(ColumnMetadata.empty) case DoubleType => DoubleF(ColumnMetadata.empty) case FloatType => FloatF(ColumnMetadata.empty) case IntegerType => IntegerF(ColumnMetadata.empty) case LongType => LongF(ColumnMetadata.empty) case StringType => StringF(ColumnMetadata.empty) } -
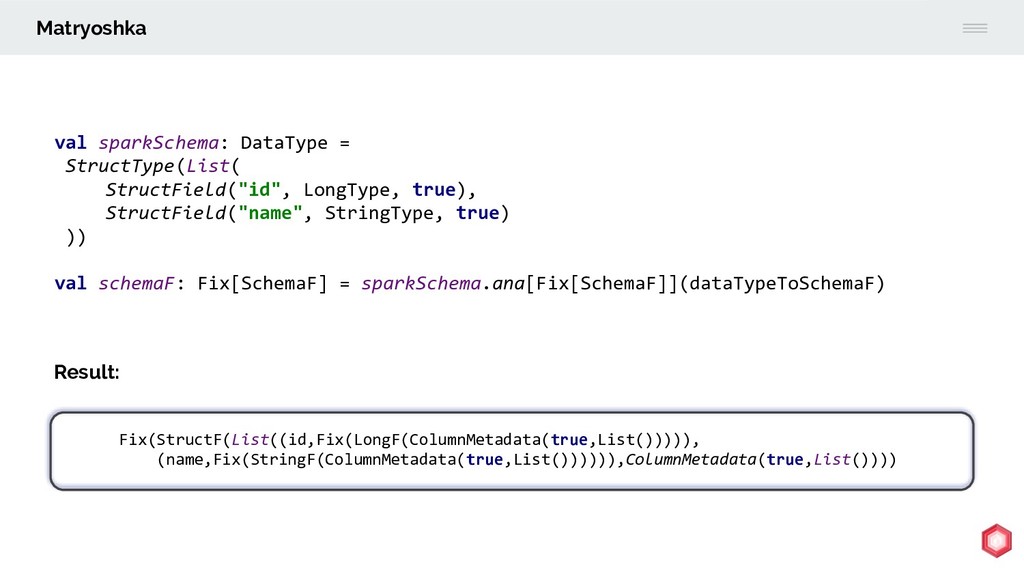
Matryoshka val sparkSchema: DataType = StructType(List( StructField("id", LongType, true), StructField("name",
StringType, true) )) val schemaF: Fix[SchemaF] = sparkSchema.ana[Fix[SchemaF]](dataTypeToSchemaF) Fix(StructF(List((id,Fix(LongF(ColumnMetadata(true,List())))), (name,Fix(StringF(ColumnMetadata(true,List()))))),ColumnMetadata(true,List()))) Result: -
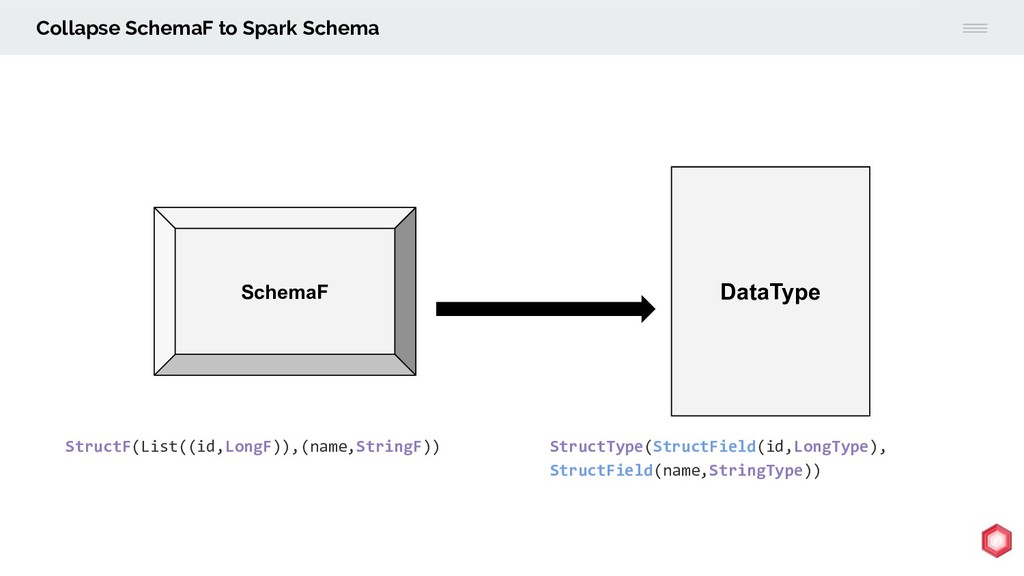
F[A] => A: folds a SchemaF to Spark Schema StructType(StructField(id,LongType),
StructField(name,StringType)) StructF(List((id,LongF)),(name,StringF)) Collapse SchemaF to Spark Schema -
Collapse SchemaF to Spark Schema F[A] => A: folds a
SchemaF to Spark Schema StructType(StructField(id,LongType), StructField(name,StringType)) StructF(List((id,LongF)),(name,StringF)) def cata[A](f: Algebra[F, A])(implicit BF: Functor[F]): A -
Matryoshka - cata StructF(List((id,LongF)),(name,StringF)) LongType StringType StructF def cata[A](f: Algebra[F,
A])(implicit BF: Functor[F]): A -
Matryoshka - cata StructF(List((id,LongF)),(name,StringF)) LongType StringType StructType def cata[A](f: Algebra[F,
A])(implicit BF: Functor[F]): A -
Matryoshka - cata StructF(List((id,LongF)),(name,StringF)) StructType LongType StringType def cata[A](f: Algebra[F,
A])(implicit BF: Functor[F]): A -
Matryoshka - cata def cata[A](f: Algebra[F, A])(implicit BF: Functor[F]): A
Algebra[F, A] = F[A] => A Algebra[SchemaF, DataType] = SchemaF[DataType] => DataType -
Matryoshka - cata def cata[A](f: Algebra[F, A])(implicit BF: Functor[F]): A
Algebra[F, A] = F[A] => A Algebra[SchemaF, DataType] = SchemaF[DataType] => DataType -
Matryoshka - cata def schemaFToDataType: Algebra[SchemaF, DataType] = { case
StructF(fields, _) => StructType(fields.map { case (name, value) => StructField(name, value) }.toArray) case ArrayF(elem, m) => ArrayType(elem, containsNull = false) case BooleanF(_) => BooleanType case DateF(_) => DateType case DoubleF(_) => DoubleType case FloatF(_) => FloatType case IntegerF(_) => IntegerType case LongF(_) => LongType case StringF(_) => StringType } -
Matryoshka - cata val schemaF: Fix[SchemaF] = Fix(StructF(List(id,Fix(LongF(ColumnMetadata.empty)), (name, Fix(StringF(ColumnMetadata.empty)))))
val dataType: DataType = schemaF.cata[DataType](schemaFToDataType) Result: StructType(List(StructField("id", LongType, true), StructField("name", org.apache.spark.sql.types.StringType, true))) -
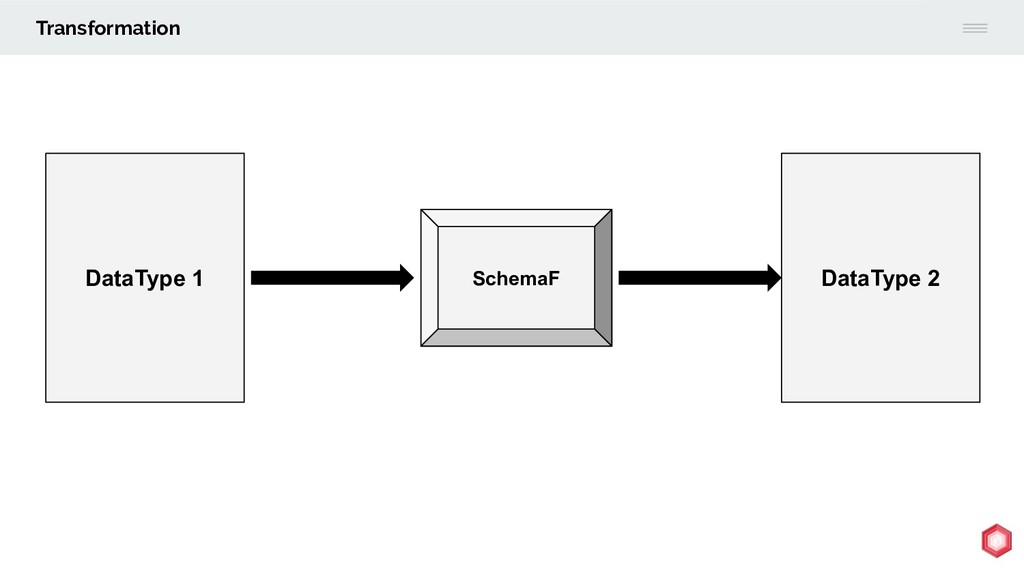
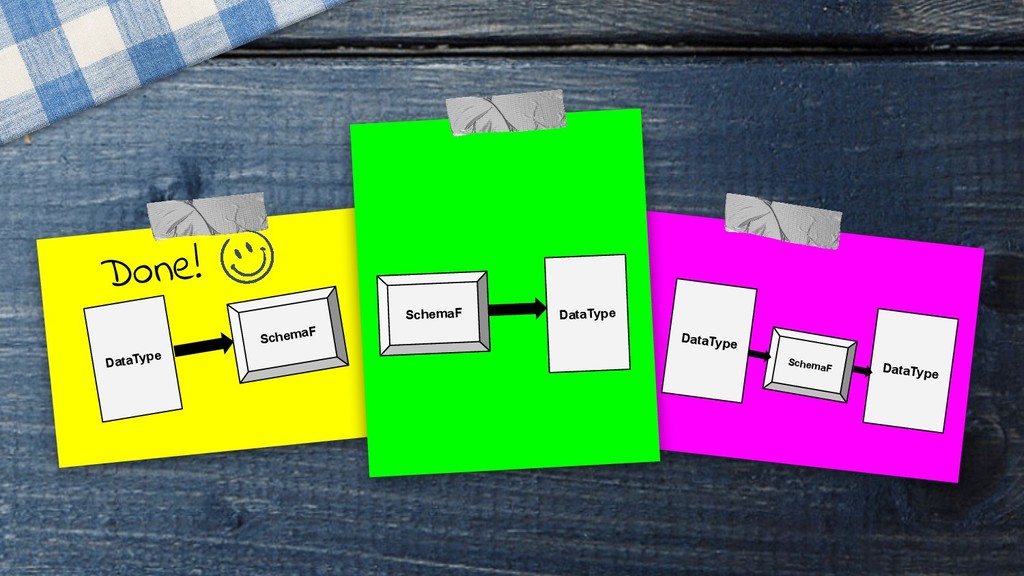
SchemaF DataType 1 DataType 2 F[A] => A A =>
F[A] ana cata Transformation -
SchemaF DataType 1 DataType 2 F[A] => A A =>
F[A] ana cata Coalgebra Algebra ana cata Transformation -
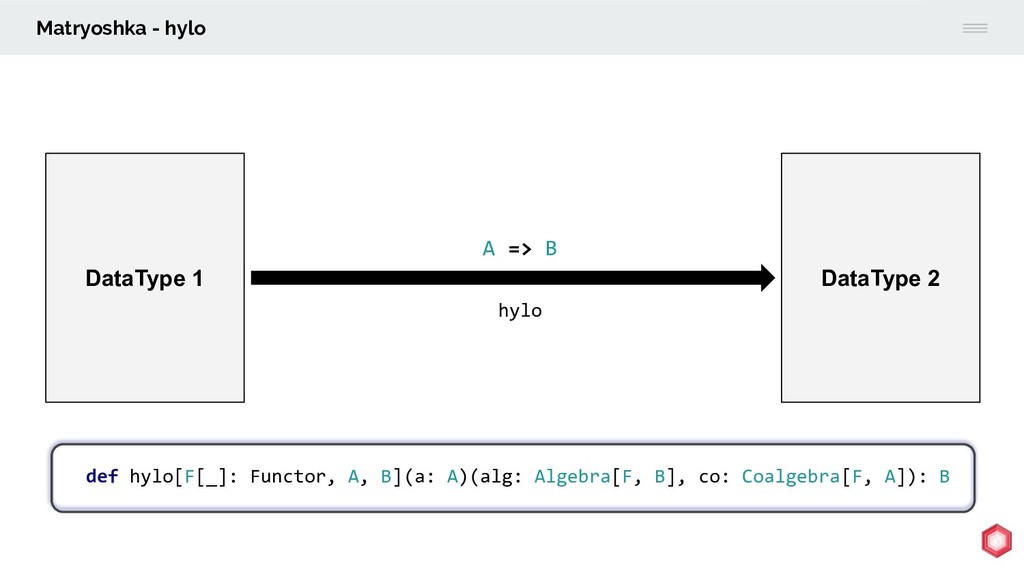
Matryoshka - hylo DataType 1 DataType 2 A => B
hylo def hylo[F[_]: Functor, A, B](a: A)(alg: Algebra[F, B], co: Coalgebra[F, A]): B -
Apply privacy - changeSchema def changeSchema(privacyStrategies: PrivacyStrategies, schemaF: Fix[SchemaF]): Fix[SchemaF]
= { val s = schemaF.unFix privacyStrategies .find { case (tags, _) => tags == s.metadata.tags } .fold(schemaF) { case (_, strategy) => Fix(strategy.schema(s)) } } def alg: Algebra[SchemaF, Fix[SchemaF]] = s => changeSchema(privacyStrategies, Fix(s)) schema.cata(alg) -
Privacy engine type PrivacyStrategies = Map[Seq[String], PrivacyStrategy] “address” “name” “email”
“id” “pw” ... encryptStrategy changeSchema Tags -
Privacy engine type PrivacyStrategies = Map[Seq[String], PrivacyStrategy] “address” “name” “email”
“id” “pw” ... encryptStrategy changeSchema Tags Goal: encrypt Data only if the tags within its Schema matches those of Privacy Strategy -
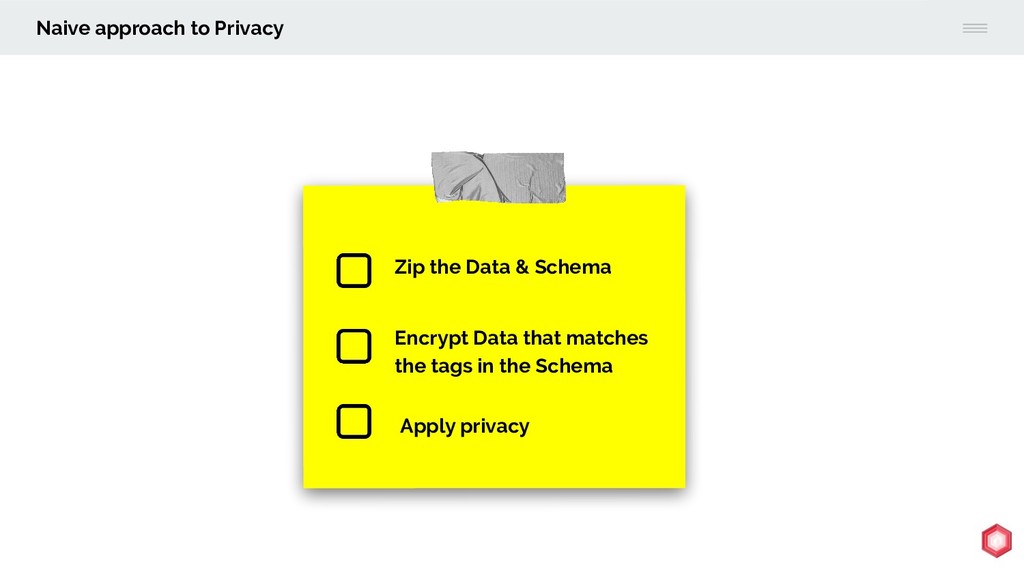
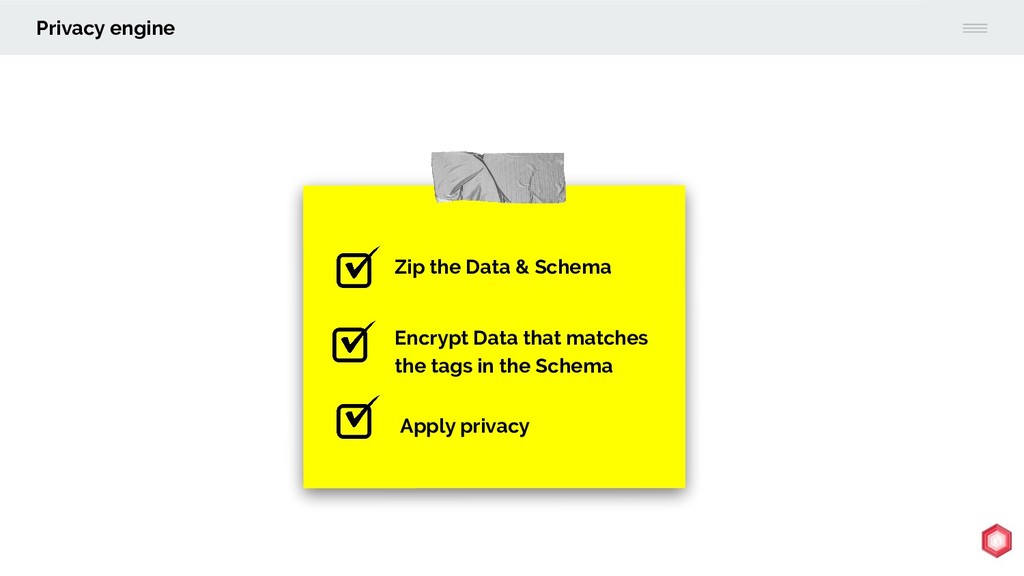
Naive approach to Privacy Zip the Data & Schema Encrypt
Data that matches the tags in the Schema Apply privacy -
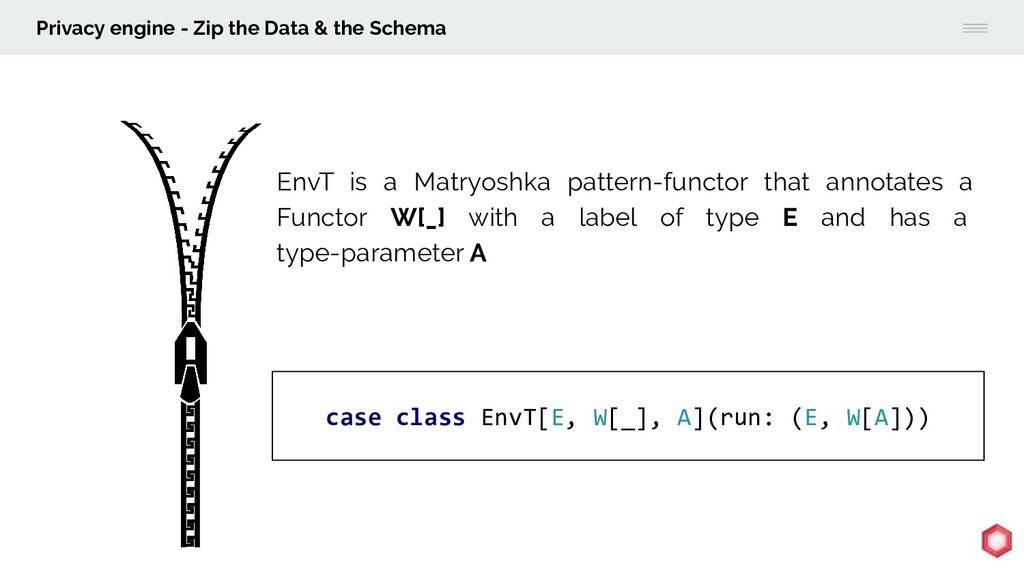
Privacy engine - Zip the Data & the Schema case
class EnvT[E, W[_], A](run: (E, W[A])) EnvT is a Matryoshka pattern-functor that annotates a Functor W[_] with a label of type E and has a type-parameter A -
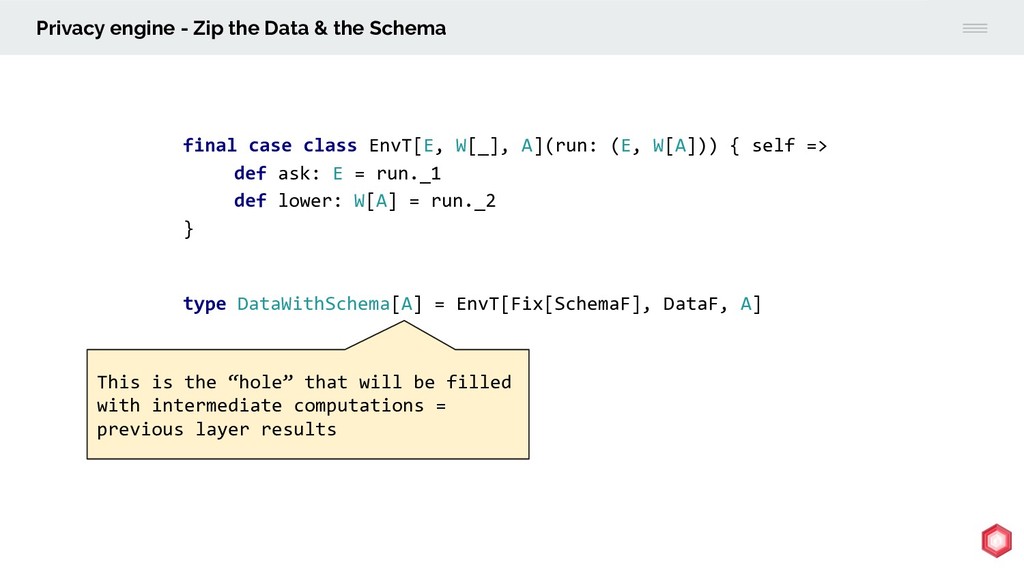
Privacy engine - Zip the Data & the Schema type
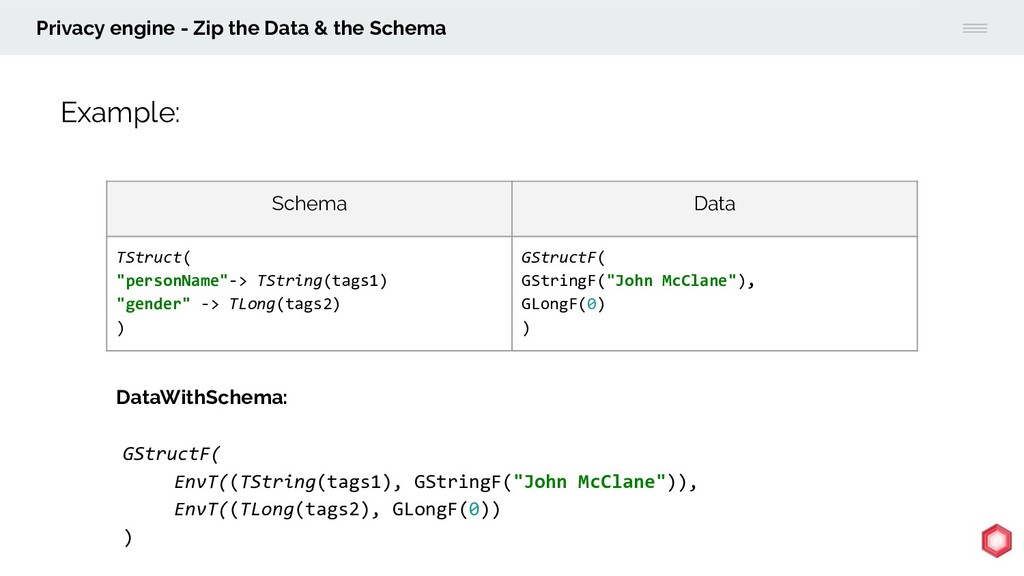
DataWithSchema[A] = EnvT[Fix[SchemaF], DataF, A] final case class EnvT[E, W[_], A](run: (E, W[A])) { self => def ask: E = run._1 def lower: W[A] = run._2 } This is the “hole” that will be filled with intermediate computations = previous layer results -
GStructF( EnvT((TString(tags1), GStringF("John McClane")), EnvT((TLong(tags2), GLongF(0)) ) Schema Data TStruct(
"personName"-> TString(tags1) "gender" -> TLong(tags2) ) GStructF( GStringF("John McClane"), GLongF(0) ) Privacy engine - Zip the Data & the Schema Example: DataWithSchema: -
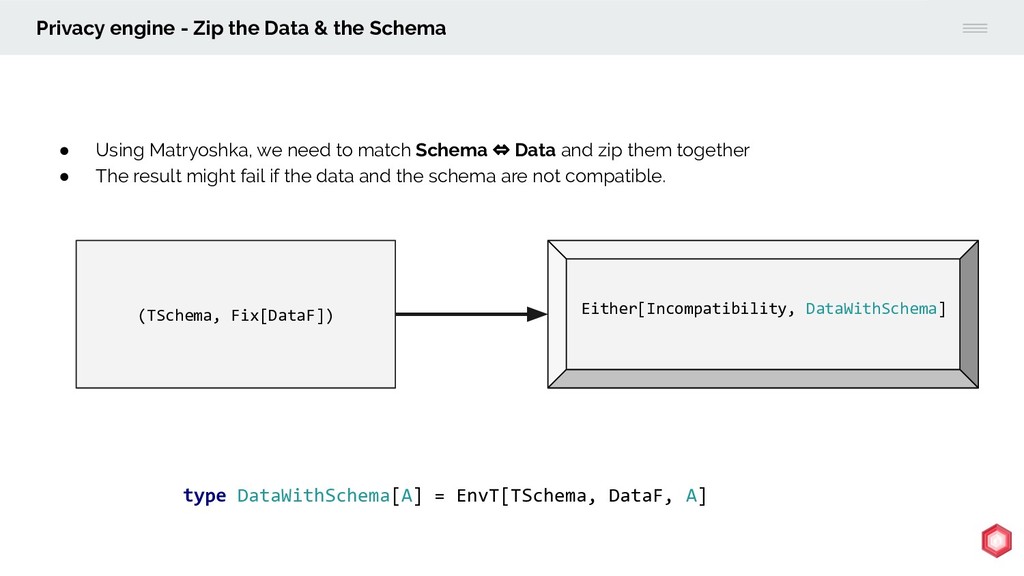
• Using Matryoshka, we need to match Schema ⇔ Data
and zip them together • The result might fail if the data and the schema are not compatible. Privacy engine - Zip the Data & the Schema (TSchema, Fix[DataF]) Either[Incompatibility, DataWithSchema] type DataWithSchema[A] = EnvT[TSchema, DataF, A] -
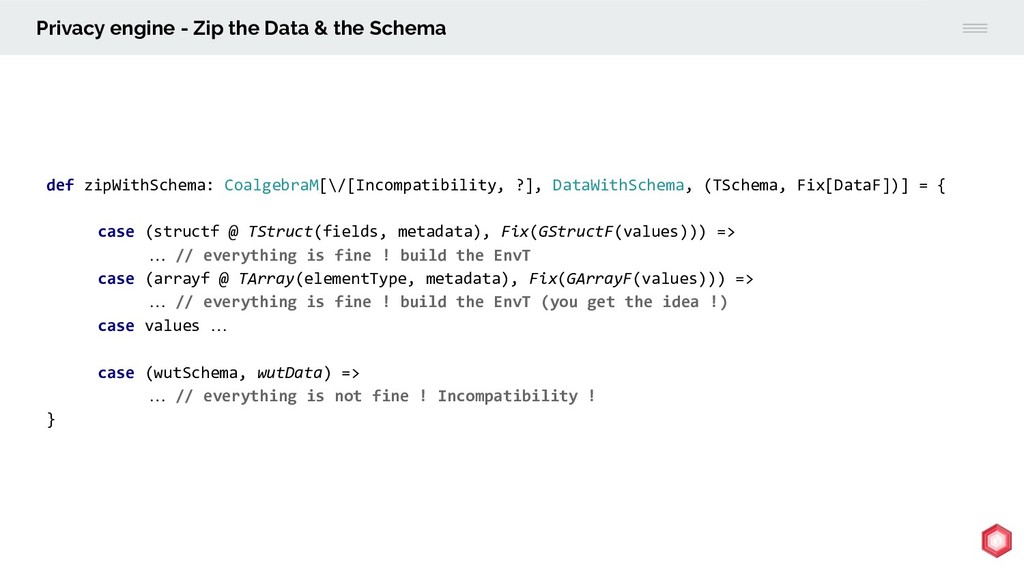
Privacy engine - Zip the Data & the Schema def
zipWithSchema: CoalgebraM[\/[Incompatibility, ?], DataWithSchema, (TSchema, Fix[DataF])] = { case (structf @ TStruct(fields, metadata), Fix(GStructF(values))) => … // everything is fine ! build the EnvT case (arrayf @ TArray(elementType, metadata), Fix(GArrayF(values))) => … // everything is fine ! build the EnvT (you get the idea !) case values … case (wutSchema, wutData) => … // everything is not fine ! Incompatibility ! } -
Privacy engine Zip the Data & Schema Encrypt Data that
matches the tags in the Schema Apply privacy -
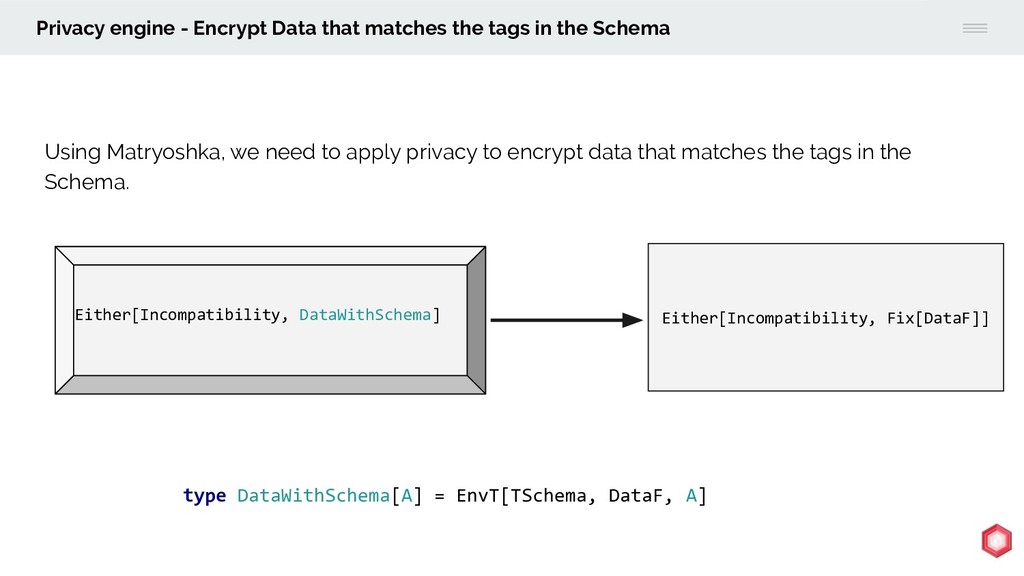
Using Matryoshka, we need to apply privacy to encrypt data
that matches the tags in the Schema. Privacy engine - Encrypt Data that matches the tags in the Schema Either[Incompatibility, Fix[DataF]] type DataWithSchema[A] = EnvT[TSchema, DataF, A] Either[Incompatibility, DataWithSchema] -
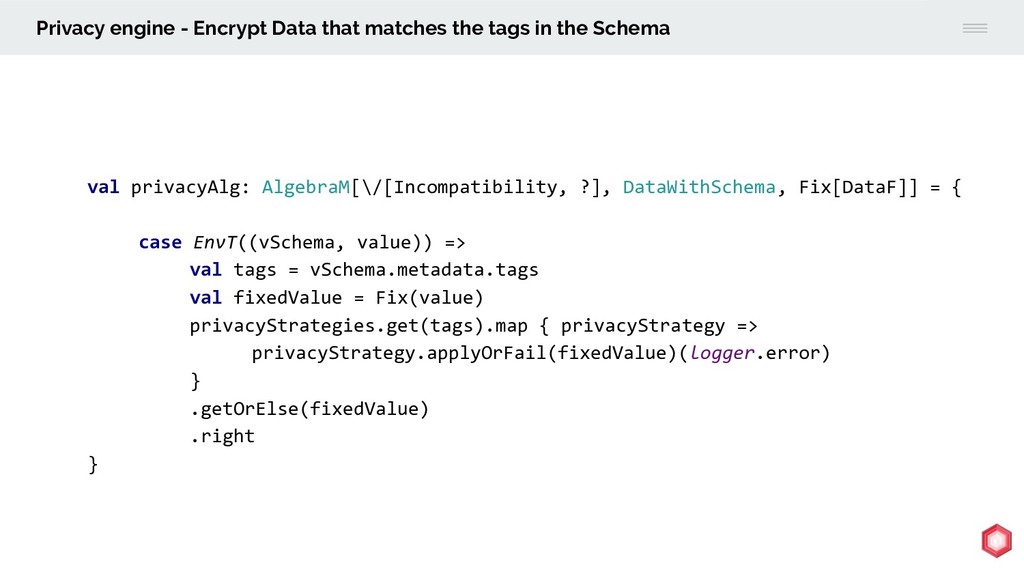
Privacy engine - Encrypt Data that matches the tags in
the Schema val privacyAlg: AlgebraM[\/[Incompatibility, ?], DataWithSchema, Fix[DataF]] = { case EnvT((vSchema, value)) => val tags = vSchema.metadata.tags val fixedValue = Fix(value) privacyStrategies.get(tags).map { privacyStrategy => privacyStrategy.applyOrFail(fixedValue)(logger.error) } .getOrElse(fixedValue) .right } -
Privacy engine Zip the Data & Schema Encrypt Data that
matches the tags in the Schema Apply privacy -
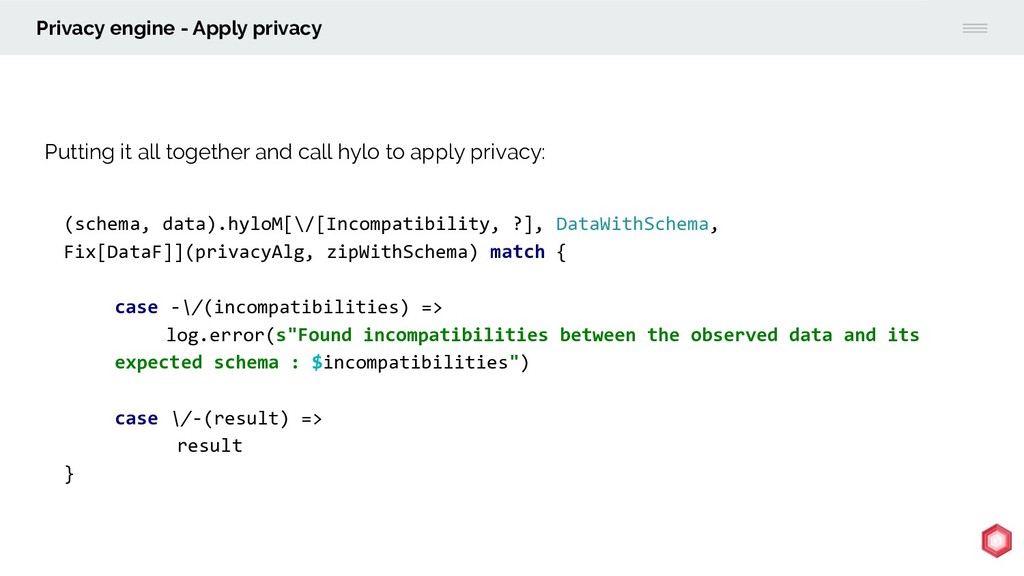
Putting it all together and call hylo to apply privacy:
Privacy engine - Apply privacy (schema, data).hyloM[\/[Incompatibility, ?], DataWithSchema, Fix[DataF]](privacyAlg, zipWithSchema) match { case -\/(incompatibilities) => log.error(s"Found incompatibilities between the observed data and its expected schema : $incompatibilities") case \/-(result) => result } -
Privacy engine Zip the Data & Schema Encrypt Data that
matches the tags in the Schema Apply privacy -
We now have our most : • versatile • generic
• efficient privacy engine ! Privacy engine - Victory \o/ -
The previous engine is perfect BUT : - For every
piece of data we need to zip it with its schema. - For 1,000 rows of the same table, we will duplicate the same schema. Is it possible to just “prepare” the mutation ? Lambda -
Lambda How? Let’s build a “Lambda” that will go down
into the data according to a schema and it will be applied only if there’s something to cypher -
Lambda / Mutations classes MutationOp NoOp GoDownOp apply(gdata: Fix[DataF]): Fix[DataF]
andThen(f: Fix[DataF] => Fix[DataF]) -
Lambda - prepare transformation def prepareTransform(schema: Fix[SchemaF], privacyStrategies: PrivacyStrategies): MutationOp
= { val privacyAlg: Algebra[SchemaF, MutationOp] = ??? schema.cata[MutationOp](privacyAlg) } -
Lambda - prepare transformation val privacyAlg: Algebra[SchemaF, MutationOp] = {
… case value: ValueF[MutationOp] => val tags = value.metadata.tags privacyStrategies.get(tags).map { privacyStrategy => GoDownOp(fx => privacyStrategy.applyOrFail(fx)(logger.error)) } .getOrElse(NoOp) } -
Lambda - prepare transformation val privacyAlg: Algebra[SchemaF, MutationOp] = {
… case ArrayF(previousOp, metadata) => previousOp match { case NoOp => NoOp case op => GoDownOp { case Fix(GArrayF(elems)) => val result = elems.map(previousOp.apply) Fix(GArrayF(result)) } ... } -
Lambda - prepare transformation val privacyAlg: Algebra[SchemaF, MutationOp] = {
case StructF(fields, metadata) => if (fields.forall(_ == NoOp)) { // all fields are not to be touched NoOp } else { // at least one field need work done GoDownOp { case Fix(GStructF(dataFields)) => Fix(GStructF(fields.zip(dataFields).map { case ((fieldName, innerOp), (_, data)) => if (innerOp == NoOp) { (fieldName, data) } else { (fieldName, innerOp(data)) } } )) } ... } -
Lambda According to any given Schema, we can now build
only once a lambda that : - will zoom into our recursive data - But only go into what it needs to > data.get(0).get(1).get(0) <=== There it is ! - And can be Serialized & applied many times -
Lambda - Victory \o/ We now have our most :
• versatile • generic • efficient privacy engine ! At least… managed by the GC -
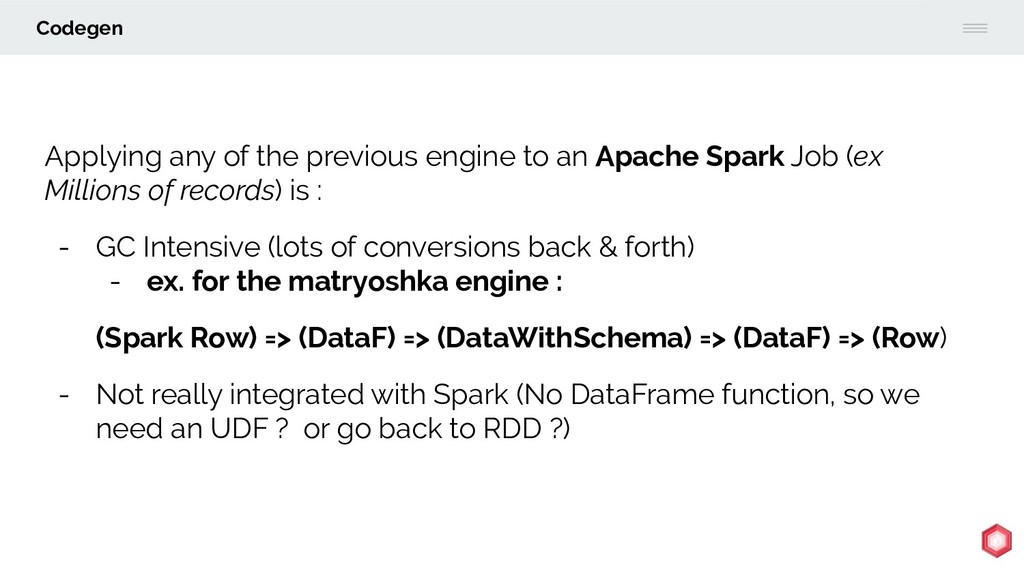
Codegen Applying any of the previous engine to an Apache
Spark Job (ex Millions of records) is : - GC Intensive (lots of conversions back & forth) - ex. for the matryoshka engine : (Spark Row) => (DataF) => (DataWithSchema) => (DataF) => (Row) - Not really integrated with Spark (No DataFrame function, so we need an UDF ? or go back to RDD ?) -
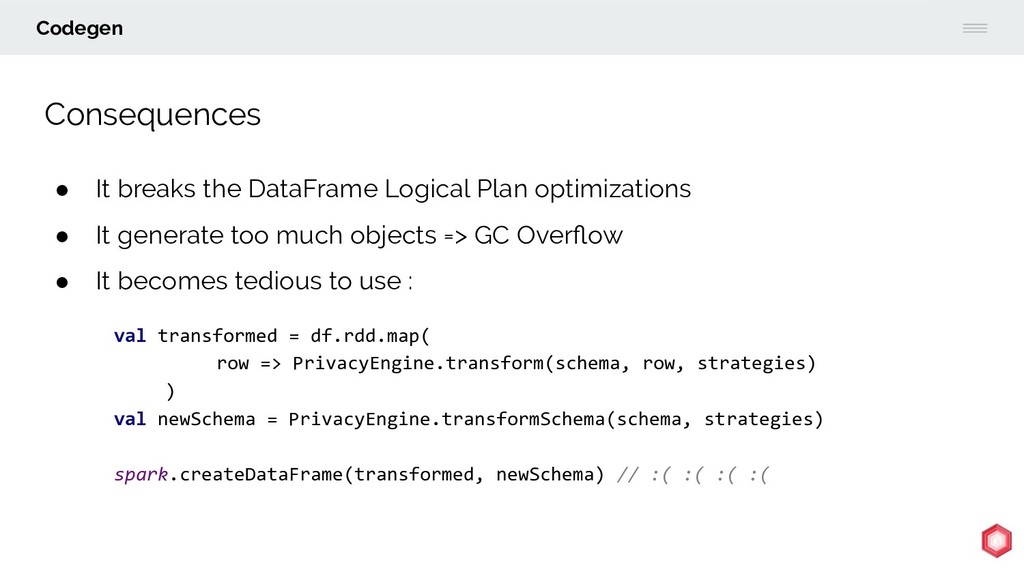
Codegen • It breaks the DataFrame Logical Plan optimizations •
It generate too much objects => GC Overflow • It becomes tedious to use : Consequences val transformed = df.rdd.map( row => PrivacyEngine.transform(schema, row, strategies) ) val newSchema = PrivacyEngine.transformSchema(schema, strategies) spark.createDataFrame(transformed, newSchema) // :( :( :( :( -
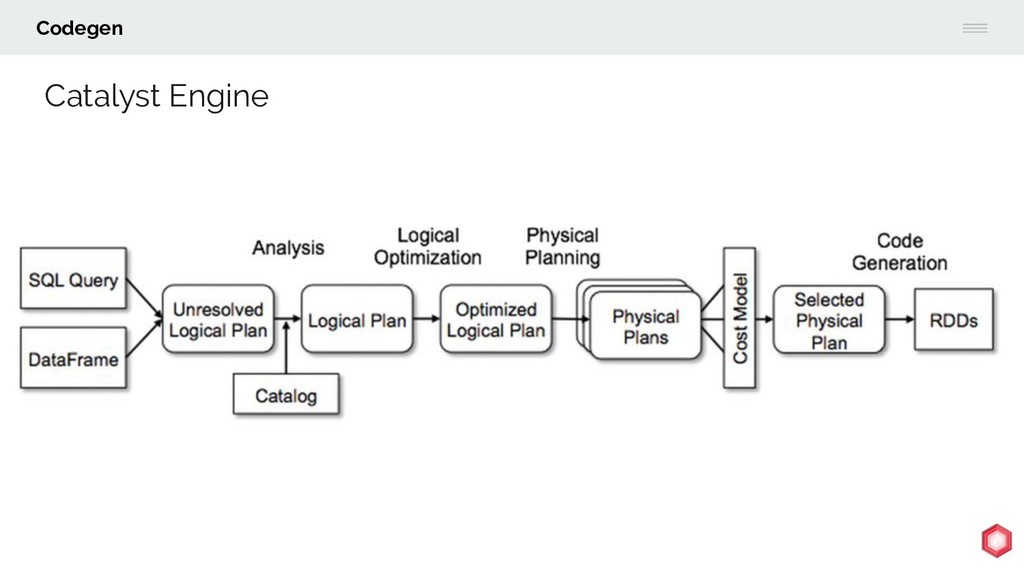
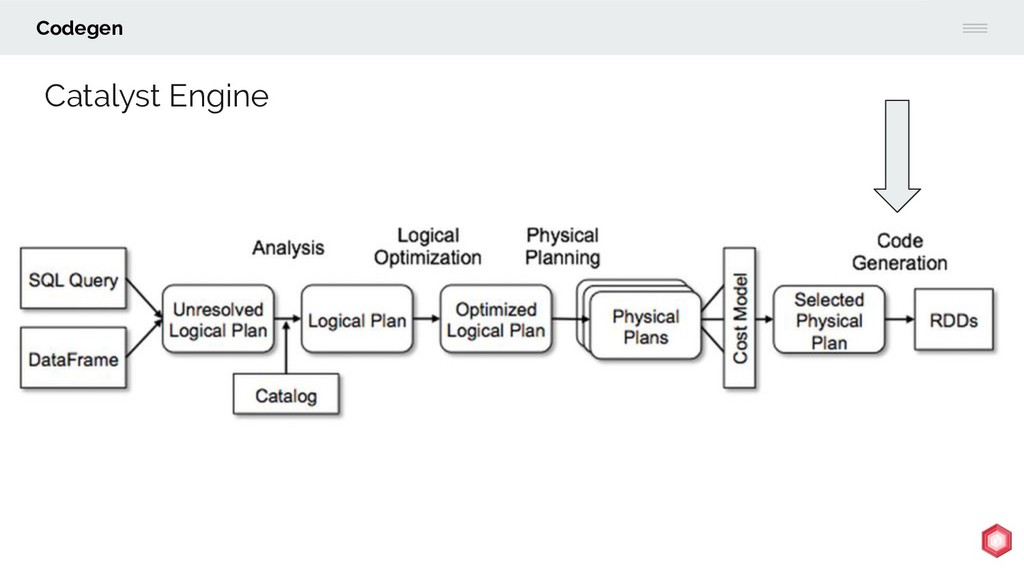
Codegen Use Spark Catalyst engine to generate ad-hoc optimized “Java
Code” to - go down into the data according to a schema - mutate it according to privacy - stay “off-heap” using sun.misc.unsafe as much as possible How? -
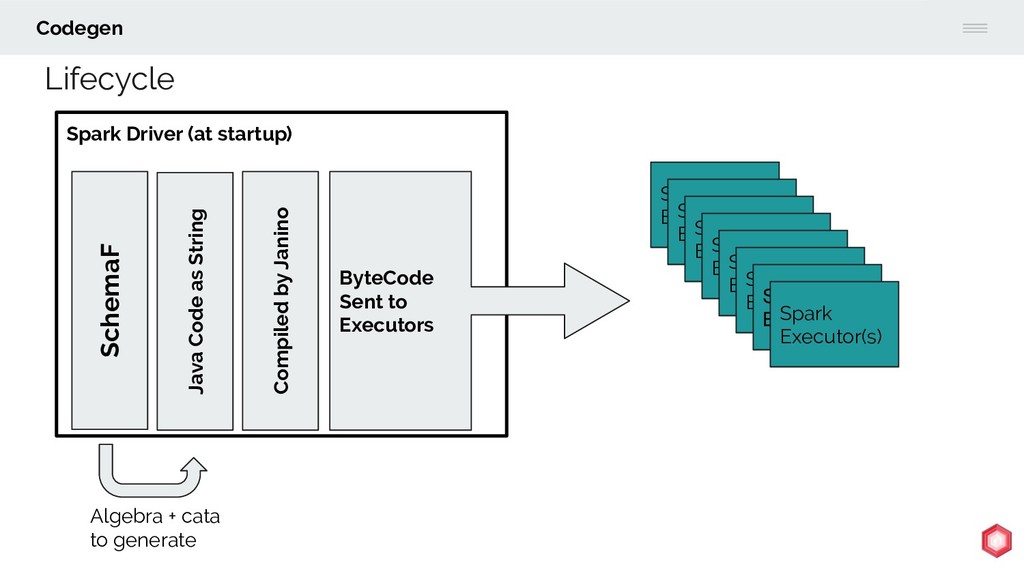
Codegen Spark Driver (at startup) Lifecycle SchemaF Algebra + cata
to generate Java Code as String Compiled by Janino Spark Executor Spark Executor Spark Executor Spark Executor Spark Executor Spark Executor Spark Executor Spark Executor(s) ByteCode Sent to Executors -
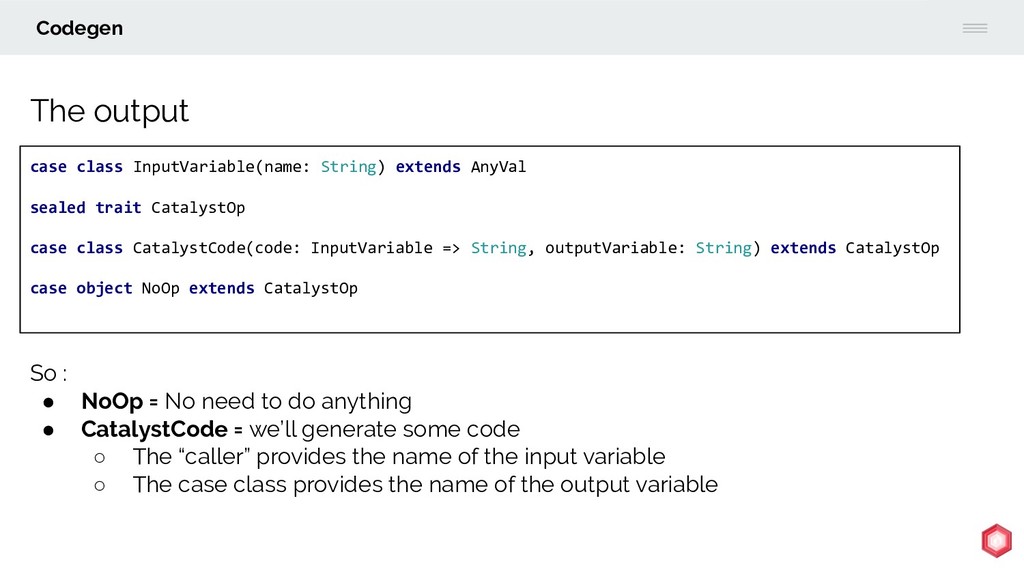
Codegen The output So : • NoOp = No need
to do anything • CatalystCode = we’ll generate some code ◦ The “caller” provides the name of the input variable ◦ The case class provides the name of the output variable case class InputVariable(name: String) extends AnyVal sealed trait CatalystOp case class CatalystCode(code: InputVariable => String, outputVariable: String) extends CatalystOp case object NoOp extends CatalystOp -
Codegen Create a new expression case class ApplyPrivacyExpression(schema: Fix[SchemaF], //
Our schema privacyStrategies: PrivacyStrategies, // The strategies to apply children: Seq[Expression] // The top columns of our dataframe ) extends Expression { // can your expression output a null ? override def nullable: Boolean = ??? // How does your expression transform the original schema of your data override def dataType: DataType = ??? // What spark will call to evaluate your expression without codegen override def eval(input: InternalRow) = ??? // here’s the code generation part ! override protected def doGenCode(ctx: CodegenContext, ev: ExprCode): ExprCode = ??? } -
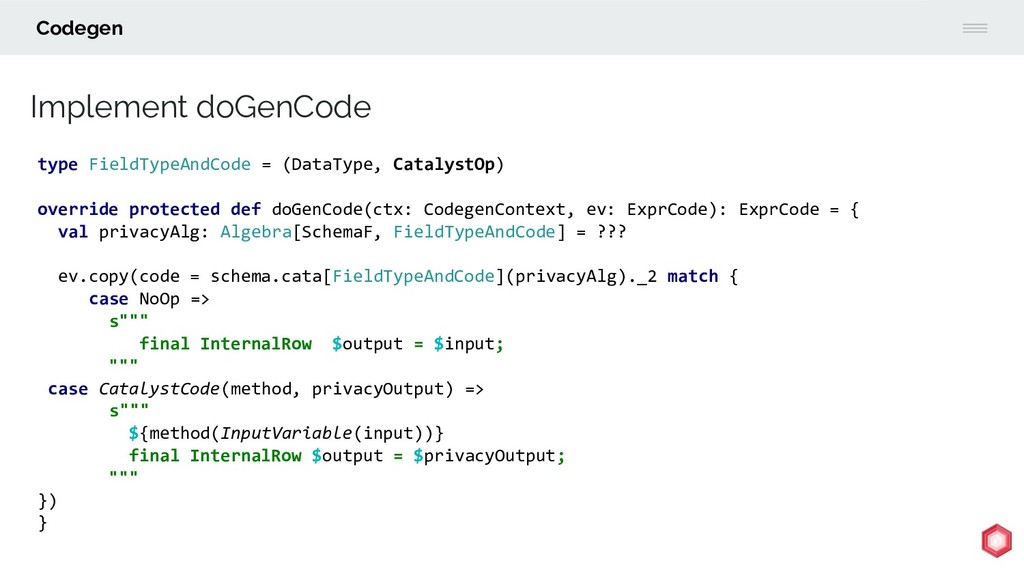
Codegen Implement doGenCode type FieldTypeAndCode = (DataType, CatalystOp) override protected
def doGenCode(ctx: CodegenContext, ev: ExprCode): ExprCode = { val privacyAlg: Algebra[SchemaF, FieldTypeAndCode] = ??? ev.copy(code = schema.cata[FieldTypeAndCode](privacyAlg)._2 match { case NoOp => s""" final InternalRow $output = $input; """ case CatalystCode(method, privacyOutput) => s""" ${method(InputVariable(input))} final InternalRow $output = $privacyOutput; """ }) } -
Codegen Create the CataListCode val privacyAlg: Algebra[SchemaF, FieldTypeAndCode] = {
case StructF(fieldsWithDataTypes, metadata) => // create the code to destroy / re-create the struct // & call the code previously computed for each field case ArrayF(elementType, metadata) => // create the code to destroy / re-create the array // & call the code previously computed for the “elementType” case v: ValueF[FieldTypeAndCode] if valueColumnSchema.metadata.tags.nonEmpty => // create the code to mutate the field (or NoOp) case v: ValueF[FieldTypeAndCode] if value.metadata.tags.isEmpty => // \o/ NoOp FTW ! } -
Codegen Case ValueF case valueCol: ValueF[FieldTypeAndCode] if valueCol.metadata.tags.nonEmpty => val
valueCode = privacyStrategies.get(tags).map { val cypherInSpark = ctx.addReferenceObj("cypherLambda", cypherLambda) val code = (inputVariable: InputVariable) => s""" $javaType $output = ($javaType) $cypherInSpark.apply(${inputVariable.name}); """ CatalystCode(code, output) }.getOrElse(NoOp) (valueCol.dataType, valueCode) -
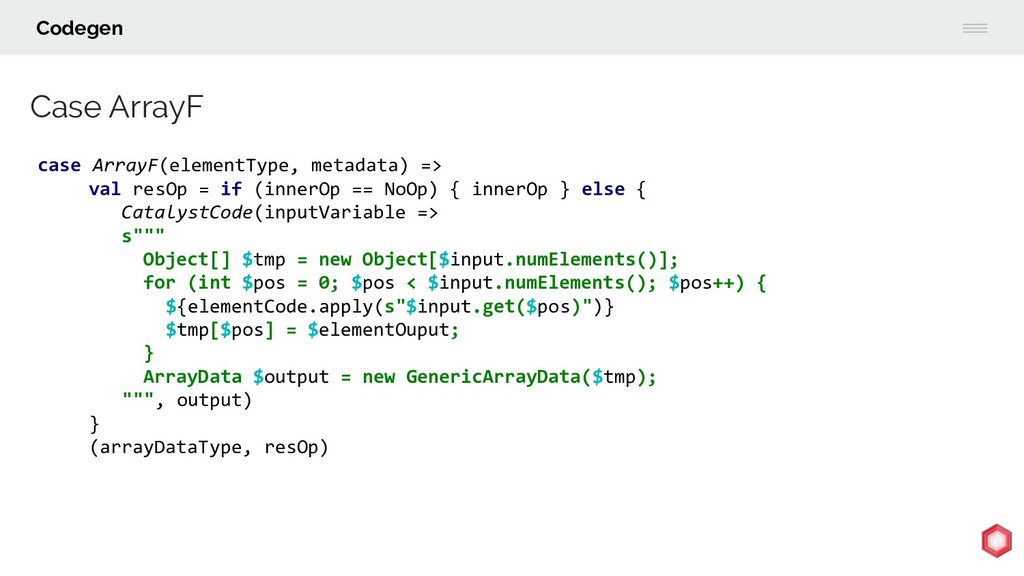
Codegen Case ArrayF case ArrayF(elementType, metadata) => val resOp =
if (innerOp == NoOp) { innerOp } else { CatalystCode(inputVariable => s""" Object[] $tmp = new Object[$input.numElements()]; for (int $pos = 0; $pos < $input.numElements(); $pos++) { ${elementCode.apply(s"$input.get($pos)")} $tmp[$pos] = $elementOuput; } ArrayData $output = new GenericArrayData($tmp); """, output) } (arrayDataType, resOp) -
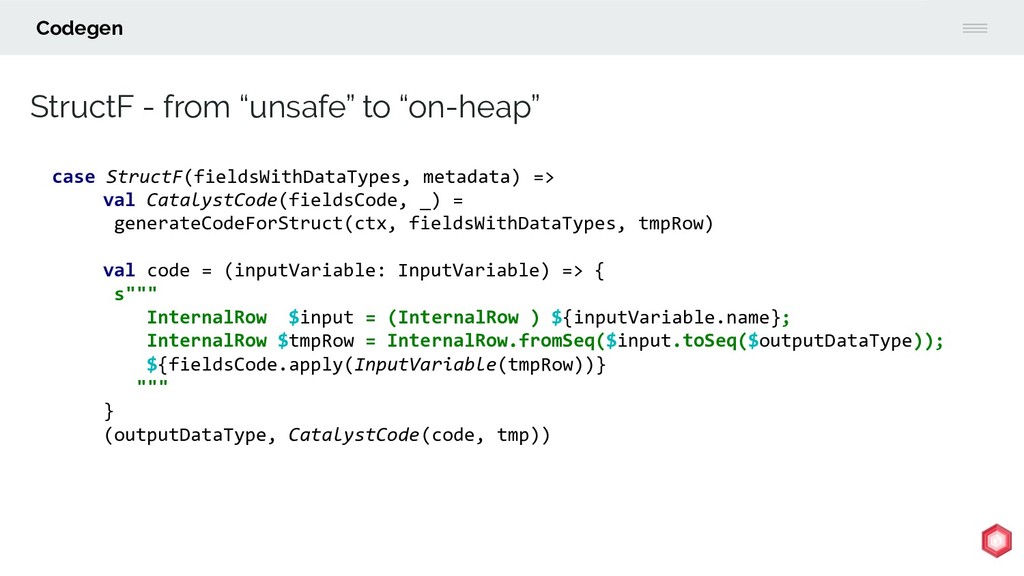
Codegen StructF - from “unsafe” to “on-heap” case StructF(fieldsWithDataTypes, metadata)
=> val CatalystCode(fieldsCode, _) = generateCodeForStruct(ctx, fieldsWithDataTypes, tmpRow) val code = (inputVariable: InputVariable) => { s""" InternalRow $input = (InternalRow ) ${inputVariable.name}; InternalRow $tmpRow = InternalRow.fromSeq($input.toSeq($outputDataType)); ${fieldsCode.apply(InputVariable(tmpRow))} """ } (outputDataType, CatalystCode(code, tmp)) -
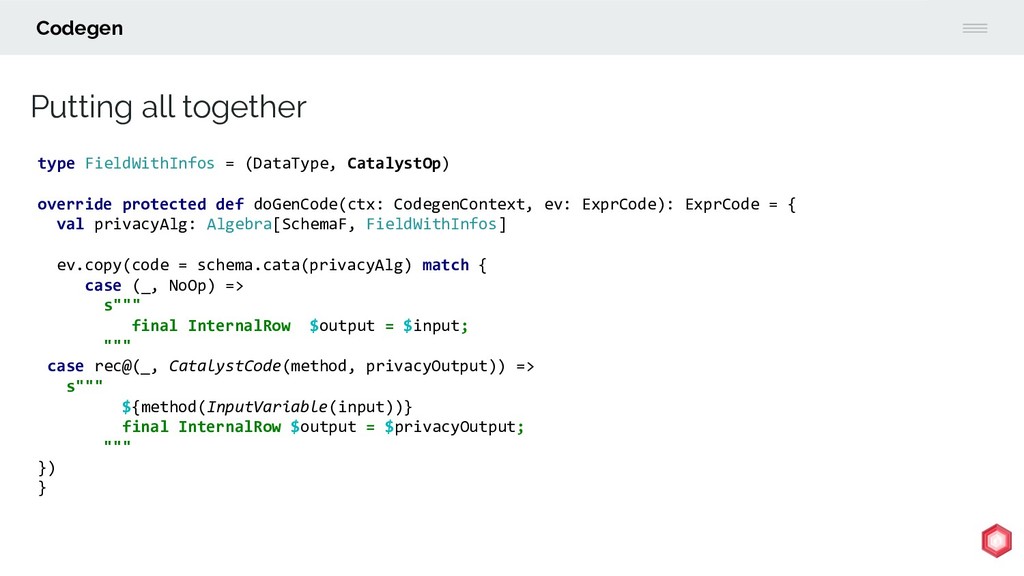
Codegen Putting all together type FieldWithInfos = (DataType, CatalystOp) override
protected def doGenCode(ctx: CodegenContext, ev: ExprCode): ExprCode = { val privacyAlg: Algebra[SchemaF, FieldWithInfos] ev.copy(code = schema.cata(privacyAlg) match { case (_, NoOp) => s""" final InternalRow $output = $input; """ case rec@(_, CatalystCode(method, privacyOutput)) => s""" ${method(InputVariable(input))} final InternalRow $output = $privacyOutput; """ }) } -
Codegen - Victory \o/ Putting all together It was tough
! But now : - The data stays “off”-heap if it’s not needed - It can even stays in the Tungsten format for Long,Int,etc… while being mutated - It is deeply integrated with Spark in a non-hacky way ! -
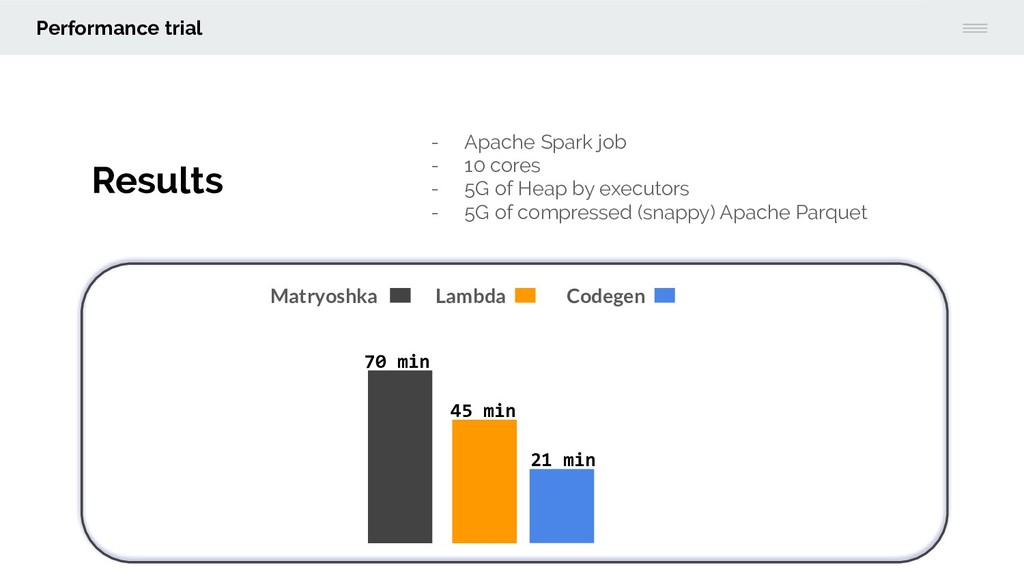
Results - Apache Spark job - 10 cores - 5G
of Heap by executors - 5G of compressed (snappy) Apache Parquet Matryoshka Lambda Codegen 70 min 45 min 21 min Performance trial -
Wrap up Using FP we managed to : • create
a generic privacy framework • create 3 engines with different point of views : ◦ Matryoshka Engine for the most complicated cases ◦ Lambda Engine well suited for streaming app ◦ Codegen Engine well suited for simple low-overhead Batch processing • All of that in a testable, (type-)safe, efficient and maintainable way ! -
To go further All the code and slides are available
here - https:/ /github.com/wi101/high-perf-privacy-scalaDays Matryoshka: - https:/ /github.com/slamdata/matryoshka Functional Programming with Bananas, Lenses, Envelopes and Barbed Wire - https:/ /maartenfokkinga.github.io/utwente/mmf91m.pdf Wrap up -
Voilà! Special thanks to the people that made it possible
: - Amine Sagaama (@sagaama) - Ghazy Ben Ahmed (@ghazy17) And Valentin Kasas for the foundations (@ValentinKasas) Wrap up
 ogirardot
 nokonoko1203
 l2hyunwoo
 yosuke_furukawa
 inariku
 ktombow
 jsoizo
 vivion
 yuuu
 youto
 nnaka2992
 yahir0
 dalinaum
 rmw
 techseoconnect
 madoxten
 mkilby
 mayatellez
 jdejongh
 elsirapls
 soudai
 skoyamalab
 mclloyd
 chikuwait







![Recapture Recursion case class Fix[F[_]](unFix: F[Fix[F]])](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_37.jpg)
![Recapture Recursion case class Fix[F[_]](unFix: F[Fix[F]]) val schema: Fix[SchemaF] =](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_38.jpg)



(implicit BF: Functor[F]): Fix[F]](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_48.jpg)
(implicit BF:](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_49.jpg)
(implicit](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_50.jpg)
(implicit](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_51.jpg)




(implicit BF: Functor[F]): A](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_65.jpg)
(implicit BF: Functor[F]):](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_66.jpg)
(implicit BF:](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_67.jpg)
(implicit BF:](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_68.jpg)
(implicit](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_69.jpg)
(implicit](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_70.jpg)


(implicit BF: Functor[F]): A](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_74.jpg)
(implicit BF: Functor[F]): A](https://files.speakerdeck.com/presentations/4cfe748eaba249e1b1c57e8af09b1745/slide_75.jpg)