Share
Embed
Downsampling, Time Series, and PostgreSQL
Preetam Jinka
March 28, 2019
Transcript
14 slides
-
Two ways to speed up time series queries Speeding up
queries means doing less work at query time. 1. Filter out data early TimescaleDB: time and column based partitioning Open-source PostgreSQL extension 2. Precompute some work Downsampling — What this talk is about! -
Time series are immutable • Observations don’t change. • Written
once, queried rarely in aggregate, never updated -
Downsampling Downsampling takes high resolution data and aggregates it into
low resolution data. e.g. 1s points to 1m points Downsampling takes advantage of immutability to precompute. -
Two ways to downsample • Streaming • Raw events ->
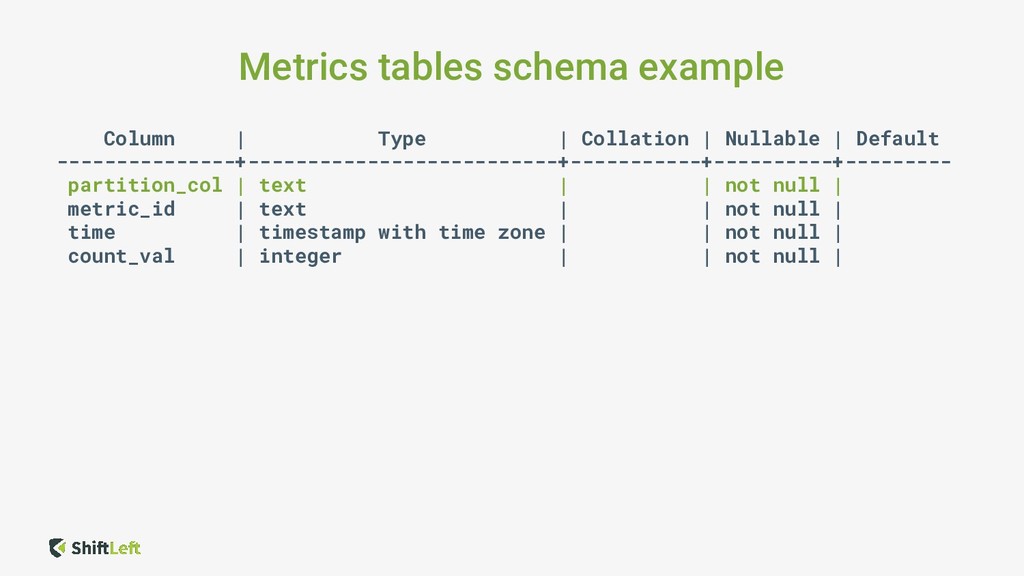
2s, 1m, 5m • Batch • 5m -> 1h, 1d Each granularity gets its own table: metrics_raw, metrics_1m, metrics_5m, ... PostgreSQL Downsample Downsample -
Metrics tables schema example Column | Type | Collation |
Nullable | Default ---------------+--------------------------+-----------+----------+--------- partition_col | text | | not null | metric_id | text | | not null | time | timestamp with time zone | | not null | count_val | integer | | not null | -
Keeping track of what to downsample Downsampling status table: -[
RECORD 1 ]-----------------+------------------------------ granularity | 1h time_bucket | 2018-08-17 14:00:00+00 last_processed_time | 2018-08-17 18:16:20.939407+00 last_processed_duration | 00:00:00.398403 data_last_added_to_time_range | 2018-08-17 14:40:30.188875+00 PostgreSQL Downsample -
Example of a query SELECT sp_id, occurrence_id, Sum(occ_count) AS occ_count
FROM ( ( SELECT sp_id, occurrence_id, Sum(occ_count) AS occ_count FROM metrics_5m WHERE (( sp_id = $1 AND occurrence_id IN (...))) AND time >= $244 AND time < $245 GROUP BY sp_id, occurrence_id) UNION ( SELECT sp_id, occurrence_id, sum(occ_count) AS occ_count FROM metrics_1h WHERE (( sp_id = $246 AND occurrence_id IN (...))) AND time >= $489 AND time < $490 GROUP BY sp_id, occurrence_id) UNION ( SELECT sp_id, occurrence_id, sum(occ_count) AS occ_count FROM metrics_1d WHERE (( sp_id = $491 AND occurrence_id IN (...))) AND time >= $734 AND time < $735 GROUP BY sp_id, occurrence_id) UNION ( SELECT sp_id, occurrence_id, sum(occ_count) AS occ_count FROM metrics_1h WHERE (( sp_id = $736 AND occurrence_id IN (...))) AND time >= $979 AND time < $980 GROUP BY sp_id, occurrence_id) UNION ( SELECT sp_id, occurrence_id, sum(occ_count) AS occ_count FROM metrics_5m WHERE (( sp_id = $981 AND occurrence_id IN (...))) AND time >= $1224 AND time < $1225 GROUP BY sp_id, occurrence_id) UNION ( SELECT sp_id, occurrence_id, sum(occ_count) AS occ_count FROM metrics_1m WHERE (( sp_id = $1226 AND occurrence_id IN (...))) AND time >= $1469 AND time < $1470 GROUP BY sp_id, occurrence_id)) -
Scalability • Writes: everything is aggregated before reaching the DB
• Reads: multiple granularities, read replicas PostgreSQL Downsample Downsample -
What this means in practice • Not too difficult to
implement • Keep queries fast, storage costs low • Scales easily -
Questions? Read more on “Time Series at ShiftLeft” https://blog.shiftleft.io/time-series-at-shiftleft-e1f98196909b Reach
out via Twitter: @PreetamJinka