Share
Embed
Time Series Storage @ Data Hackers
Slides presented during the Data Hackers meetup in Richmond, VA.
Preetam Jinka
May 20, 2015
Transcript
60 slides
-
Time Series Storage Designing and implementing a time series storage
engine Preetam Jinka (@PreetamJinka) May 2015 Data Hackers (Richmond, VA) -
Me • Undergrad math student at UVA ◦ I study
time series anomaly detection • Engineer at VividCortex ◦ Lots of backend stuff GitHub: PreetamJinka Twitter: @PreetamJinka 2 -
This will get technical. • This is about a storage
engine. • Not about using databases, but designing databases ◦ Byte-by-byte, file-by-file • Please feel free to ask questions in the middle! 3 -
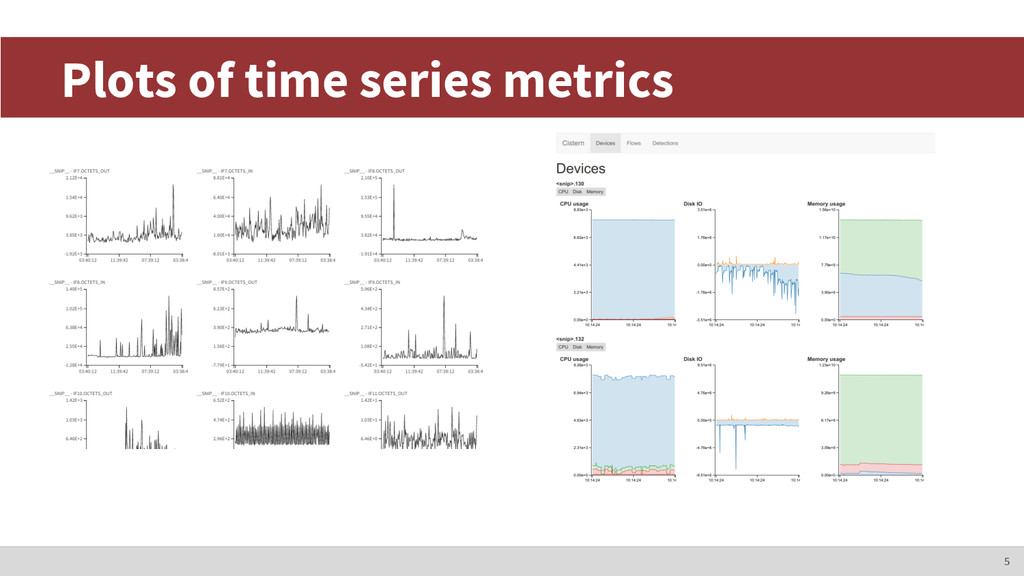
• Network flow collector ◦ It monitors enterprise routers, switches,
servers • Network Behavior Anomaly Detection ◦ DDoS attacks, SYN floods, MAC spoofing, etc. • Monitoring implies time series ◦ Lots of useful metrics. Data transfer rates, counters, system gauges, etc. 4 Personal project: Cistern -
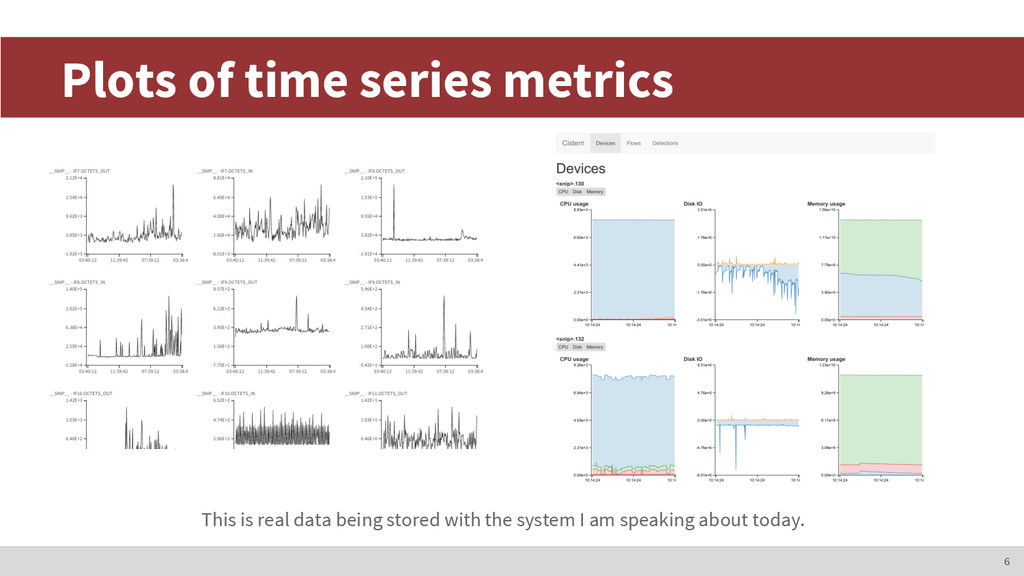
6 Plots of time series metrics This is real data
being stored with the system I am speaking about today. -
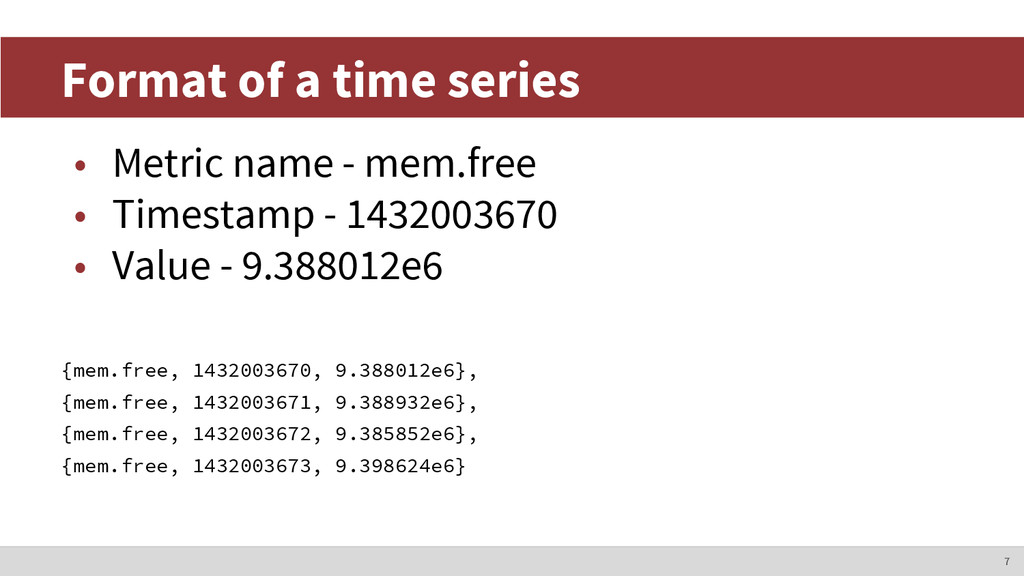
Format of a time series 7 • Metric name -
mem.free • Timestamp - 1432003670 • Value - 9.388012e6 {mem.free, 1432003670, 9.388012e6}, {mem.free, 1432003671, 9.388932e6}, {mem.free, 1432003672, 9.385852e6}, {mem.free, 1432003673, 9.398624e6} -
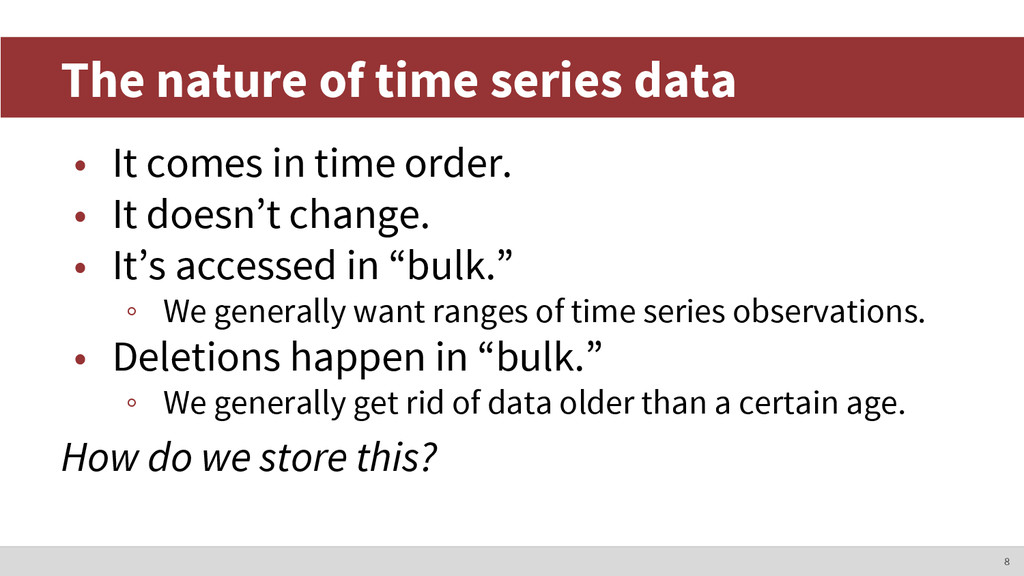
• It comes in time order. • It doesn’t change.
• It’s accessed in “bulk.” ◦ We generally want ranges of time series observations. • Deletions happen in “bulk.” ◦ We generally get rid of data older than a certain age. How do we store this? The nature of time series data 8 -
Storage hardware in a nutshell Caveat: These are extreme generalizations!
• Sequential reads and writes are fastest • Seeking (i.e. jumping around a file) is relatively slow • Writing to the end of a file is optimal Remember, writing to the beginning of a file and maintaining order means you have to rewrite the entire file. You have to shift everything over. 9 -
Indexes in a nutshell • Database indexes store things in
order • Make searching faster • Usually require fancy data structures (e.g. B- trees) ◦ Trade-off: faster reads can mean slower writes • We’re going to talk about indexing time series. 10 -
Storing time series: isn’t this simple? • Time series is
already indexed in time order. • Just use a file per metric! • Writing to the end of a file is fast and efficient. • Data points do not change, so you only have to write once. • Reading data is fast because it’s already indexed. 11 -
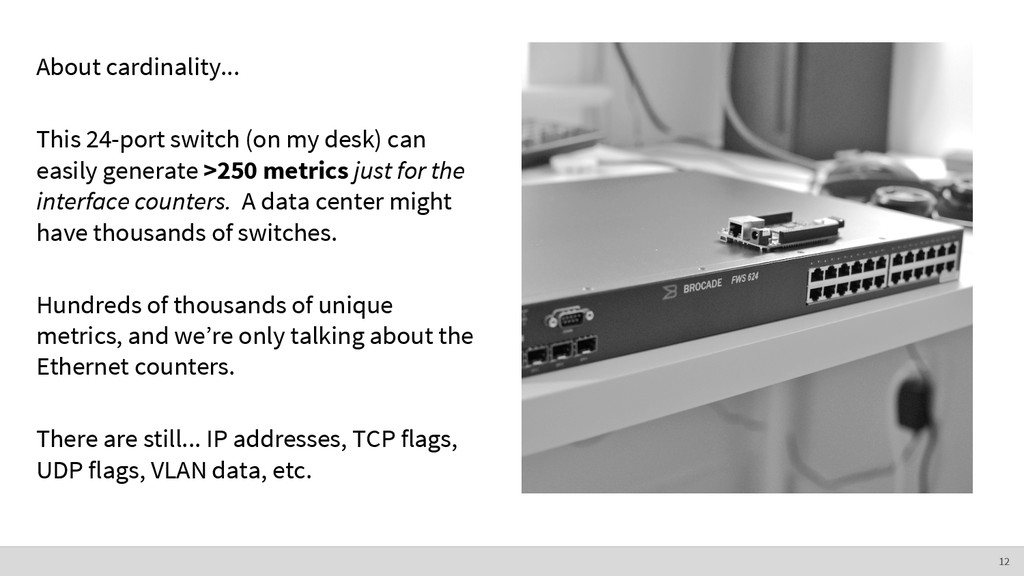
About cardinality... This 24-port switch (on my desk) can easily
generate >250 metrics just for the interface counters. A data center might have thousands of switches. Hundreds of thousands of unique metrics, and we’re only talking about the Ethernet counters. There are still... IP addresses, TCP flags, UDP flags, VLAN data, etc. 12 -
Adding these characteristics changes everything: • High cardinality ◦ You
can’t have a file per metric. Operational nightmare. • Potentially sparse ◦ You can’t preallocate space. These rule out solutions like RRDTool or Whisper (Graphite’s storage engine). What else can we do? The nature of time series data 13 -
• Data storage and retrieval • Resource management • Powerful
primitives? Role of a storage engine 14 -
Why not use... • ...RRDTool? • ...Graphite? • ...{RDBMS}? •
...Elastic(search)? • ...LevelDB? • ...B-trees? 15 -
So, no, you shouldn’t reinvent the wheel. Unless you plan
on learning more about wheels, that is. — http://blog.codinghorror.com/dont-reinvent-the-wheel-unless-you-plan-on-learning-more-about-wheels/ 16 -
17 That said... • There are always elements of prior
work that we can take advantage of -
18 Ordered key-value storage engines Two big categories • B-trees
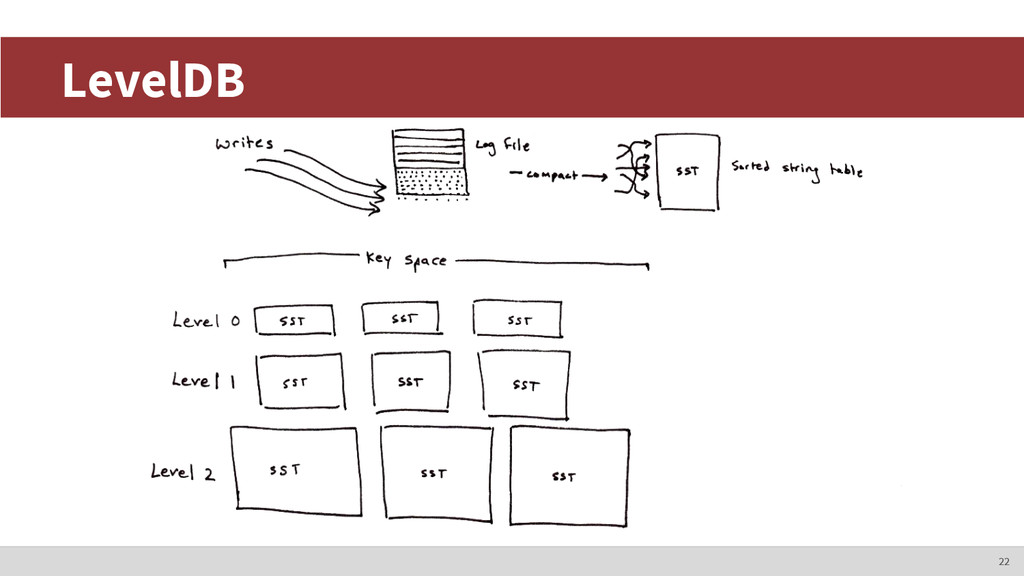
◦ Generally read optimized ◦ Most RDBMSs use B-trees for ordered indexes ◦ MySQL’s InnoDB, LMDB, Bolt, etc. • Log-structured merge (LSM) ◦ Write optimized ◦ Cassandra’s storage engine, LevelDB, RocksDB, etc. -
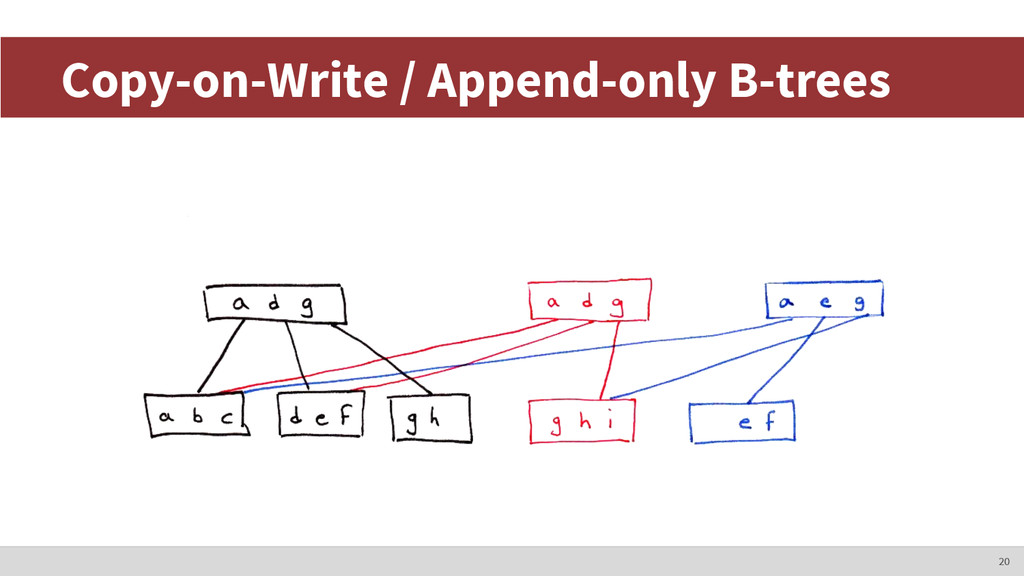
B-Trees • There are lots of types. • Different implementation
choices, etc. • We’ll stick with copy-on-write B+trees ◦ LMDB is based on this ◦ Simple, reliable, efficient ◦ Copy-on-write has interesting advantages 19 -
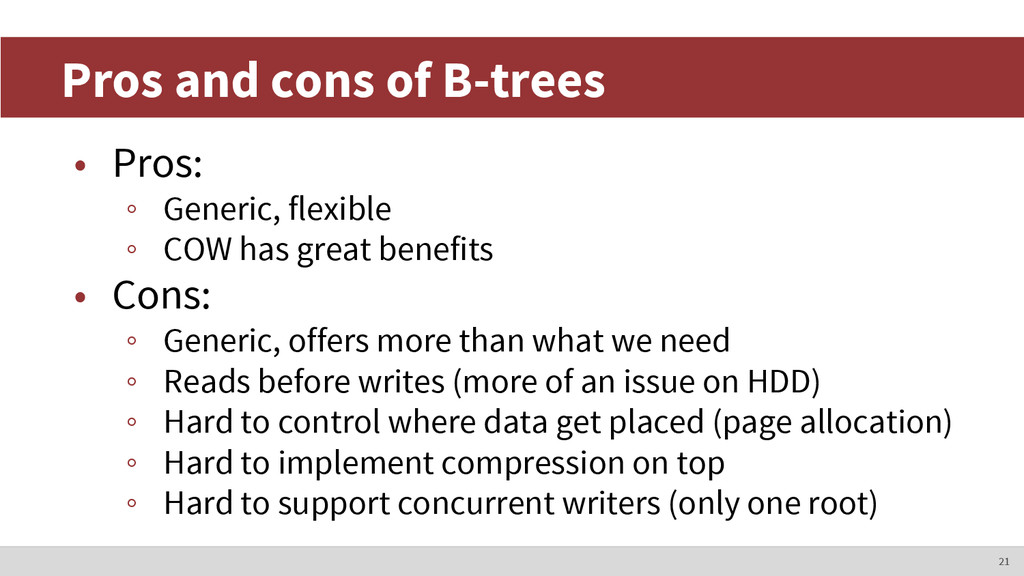
Pros and cons of B-trees • Pros: ◦ Generic, flexible
◦ COW has great benefits • Cons: ◦ Generic, offers more than what we need ◦ Reads before writes (more of an issue on HDD) ◦ Hard to control where data get placed (page allocation) ◦ Hard to implement compression on top ◦ Hard to support concurrent writers (only one root) 21 -
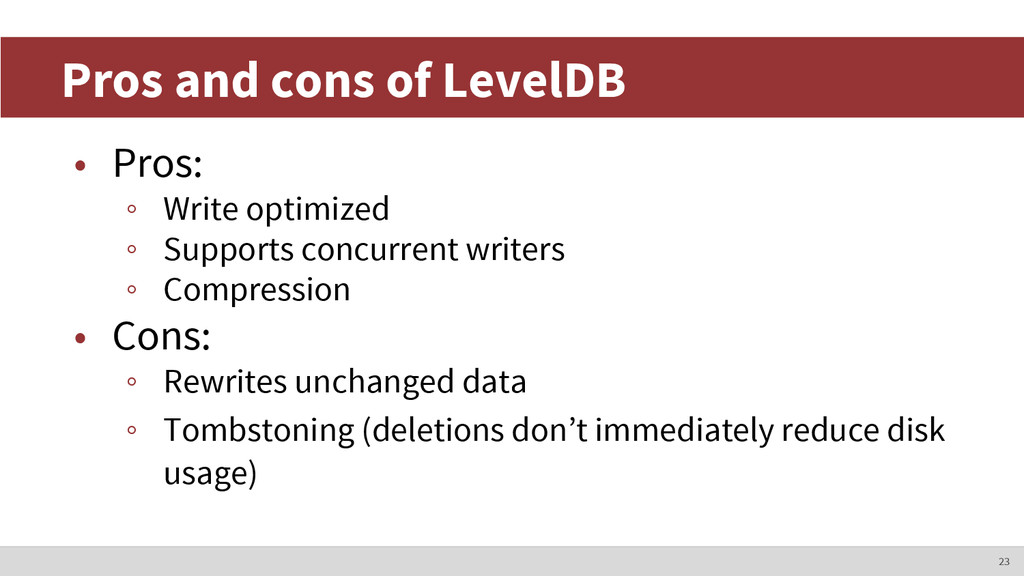
Pros and cons of LevelDB • Pros: ◦ Write optimized
◦ Supports concurrent writers ◦ Compression • Cons: ◦ Rewrites unchanged data ◦ Tombstoning (deletions don’t immediately reduce disk usage) 23 -
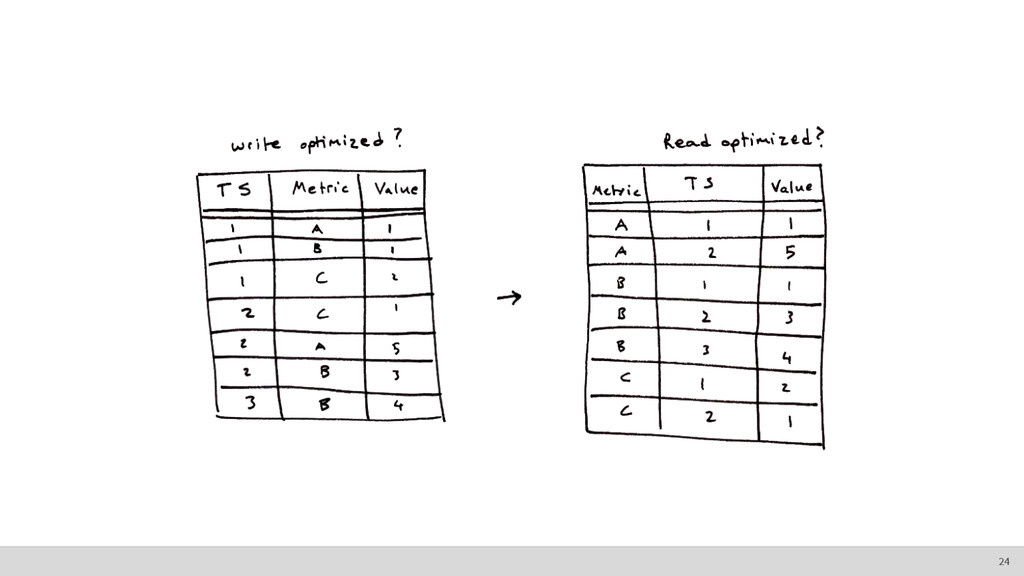
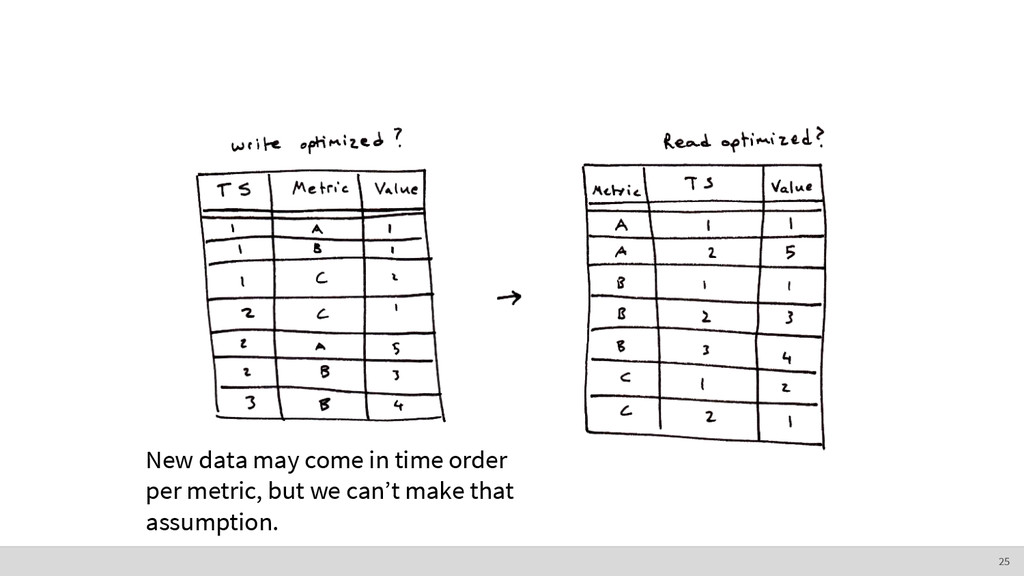
25 New data may come in time order per metric,
but we can’t make that assumption. -
Read optimization The fastest way to read from disk is
sequentially. We want to minimize expensive seeks. We want to only read what we have to. 26 -
Write optimization The fastest way to write to disk is
sequentially. It’s better to write without reading (blind writes). We want to avoid rewriting data that do not change. Write amplification is bad for SSDs. They wear out quicker. But doing more work in general is not preferred. 27 -
Write-ahead logging • Append updates to the end of a
file (a write- ahead log, WAL) • Provides durability • Basically a “redo” log during recovery 28 -
You can have sequential reads without amplification, sequential writes without
amplification, or an immutable write-once design—pick any two. — Baron Schwartz (http://www.xaprb.com/blog/2015/04/02/state-of-the-storage-engine/) 29 -
Compression • Time series data compresses really well • Fixed,
compact structure • Imagine a metric that has 0s for every timestamp 30 -
Putting everything together... • There are fast generic key-value stores
• There are time series storage engines, but they’ re not good for this use case Can we design something that is both fast, and designed for time series? Of course. 31 -
Catena n. A closely linked series. • Write optimized for
fast, concurrent writes ◦ Sequential writes like LSM • Read optimized for indexed reads ◦ Uses something similar to a B-tree with extents • Implemented in Go ◦ Still young. ~2 weeks of writing and coding 32 -
Basic API db := catena.NewDB(...) db.InsertRows([...]) i := db.NewIterator(“source”, “metric”)
i.Seek(1234) i.Next() p := i.Point() 33 -
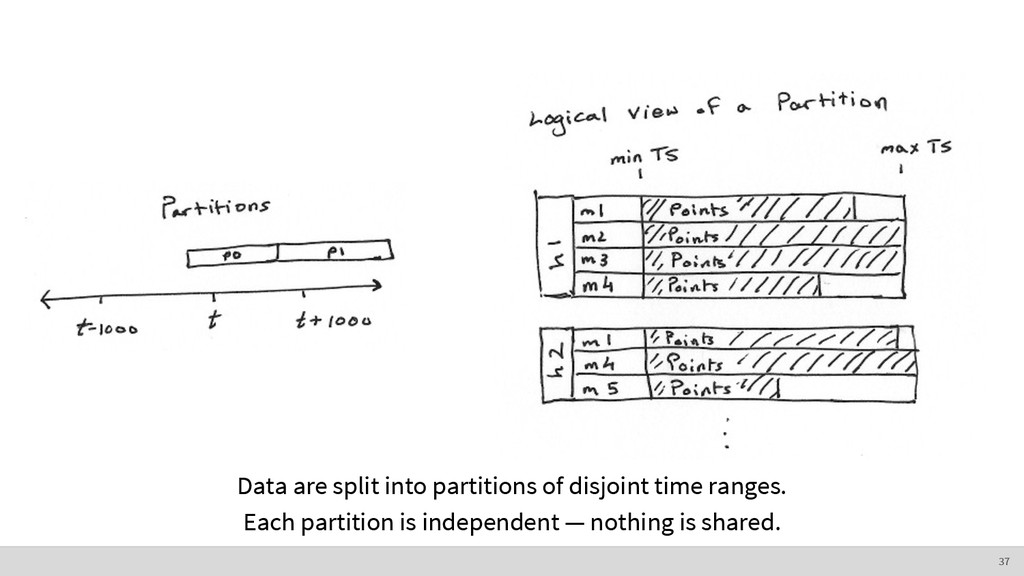
Data are split into partitions of disjoint time ranges. Each
partition is independent — nothing is shared. 37 -
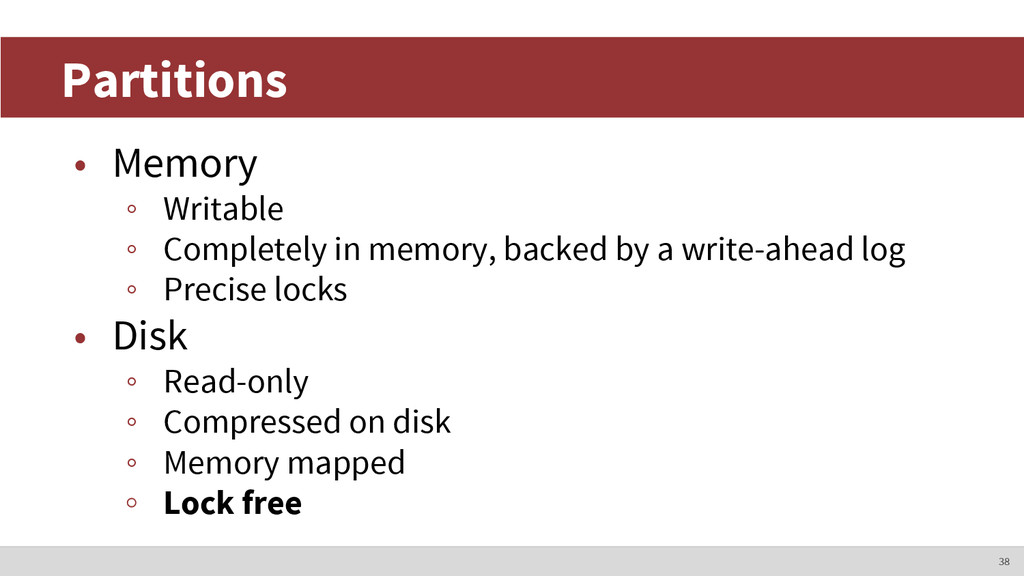
• Memory ◦ Writable ◦ Completely in memory, backed by
a write-ahead log ◦ Precise locks • Disk ◦ Read-only ◦ Compressed on disk ◦ Memory mapped ◦ Lock free 38 Partitions -
• Operational benefits ◦ Dropping old partitions is simple ◦
Each partition is a separate file ◦ Configurable size (1 hour, 1 day, whatever) ◦ Configurable retention 39 Partitions -
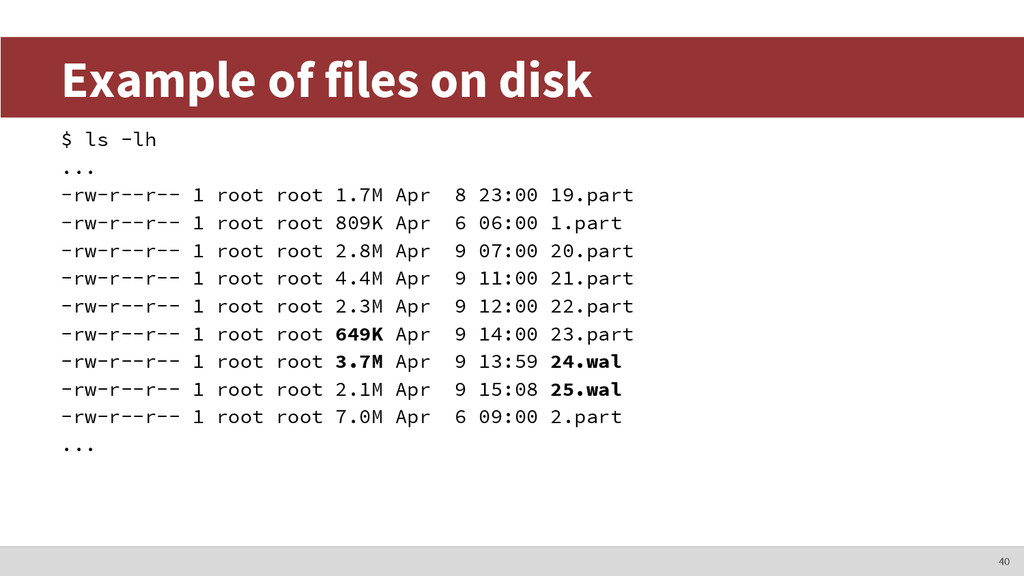
Example of files on disk $ ls -lh ... -rw-r--r--
1 root root 1.7M Apr 8 23:00 19.part -rw-r--r-- 1 root root 809K Apr 6 06:00 1.part -rw-r--r-- 1 root root 2.8M Apr 9 07:00 20.part -rw-r--r-- 1 root root 4.4M Apr 9 11:00 21.part -rw-r--r-- 1 root root 2.3M Apr 9 12:00 22.part -rw-r--r-- 1 root root 649K Apr 9 14:00 23.part -rw-r--r-- 1 root root 3.7M Apr 9 13:59 24.wal -rw-r--r-- 1 root root 2.1M Apr 9 15:08 25.wal -rw-r--r-- 1 root root 7.0M Apr 6 09:00 2.part ... 40 -
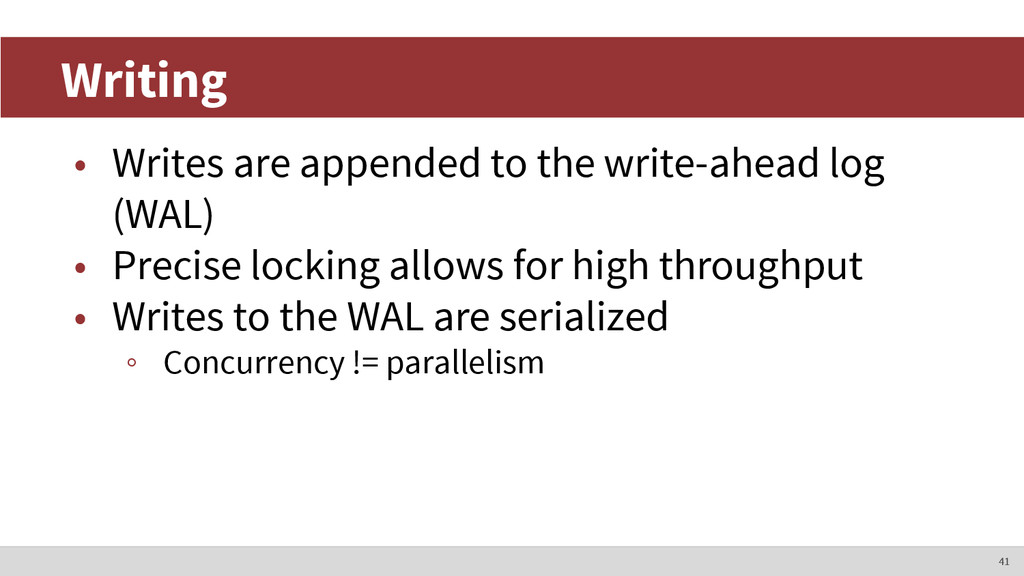
Writing • Writes are appended to the write-ahead log (WAL)
• Precise locking allows for high throughput • Writes to the WAL are serialized ◦ Concurrency != parallelism 41 -
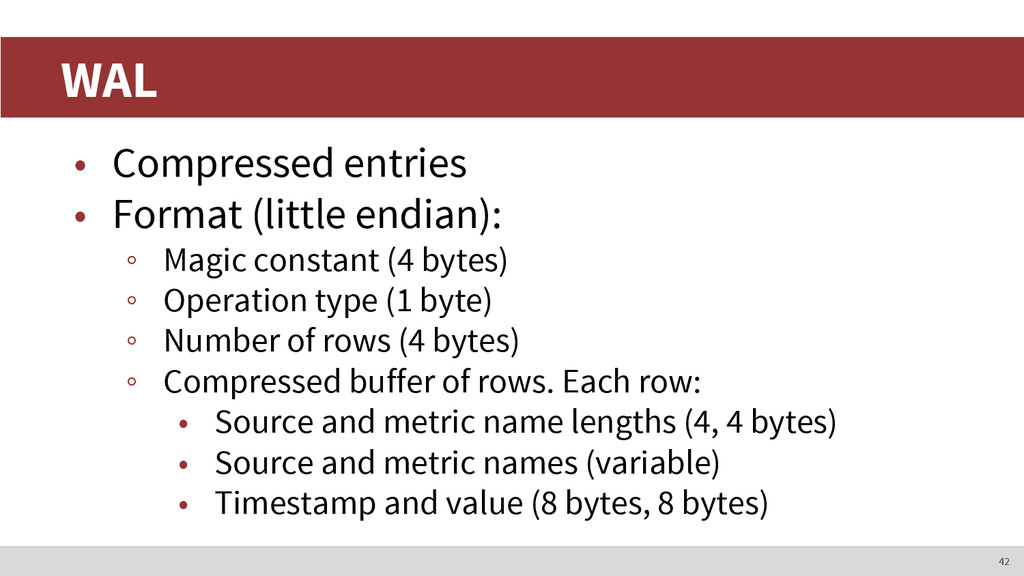
WAL • Compressed entries • Format (little endian): ◦ Magic
constant (4 bytes) ◦ Operation type (1 byte) ◦ Number of rows (4 bytes) ◦ Compressed buffer of rows. Each row: • Source and metric name lengths (4, 4 bytes) • Source and metric names (variable) • Timestamp and value (8 bytes, 8 bytes) 42 -
WAL • WAL writes are buffered until written to disk
◦ Single write() call at the end ◦ WAL mutex is locked and unlocked around the write() • Not fsync’d after each append 43 -
WAL recovery • Create a new memory partition • Read
as many records from the WAL as possible • Truncate after the last good record • Start to accept writes and append to the end 44 -
Reading Iterators • Created using a source and metric pair
• Great abstraction ◦ Seek to timestamps ◦ Do not block writers ◦ Stream off a disk ◦ Transition across partitions 45 -
More iterator benefits • Composable • Low-overhead reads • Offer
high reader concurrency 46 -
Concurrency • This is what Go is great for, right?
• Catena only launches one goroutine: the compactor • All operations are thread-safe. 47 -
Compactor • Runs in a single goroutine (for now) •
Drops old partitions ◦ Only when there are no readers using that partition • Compacts partitions 48 -
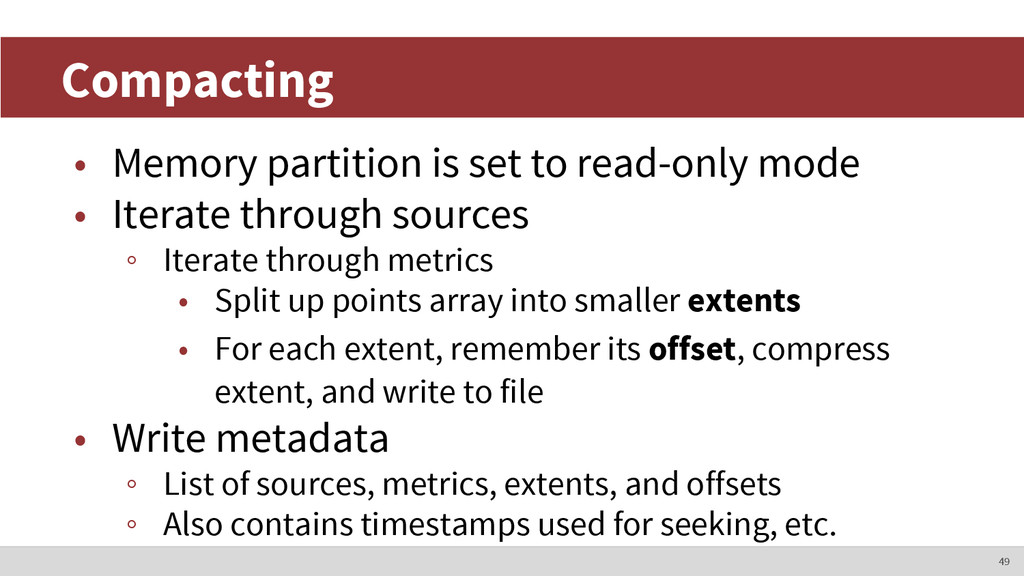
Compacting • Memory partition is set to read-only mode •
Iterate through sources ◦ Iterate through metrics • Split up points array into smaller extents • For each extent, remember its offset, compress extent, and write to file • Write metadata ◦ List of sources, metrics, extents, and offsets ◦ Also contains timestamps used for seeking, etc. 49 -
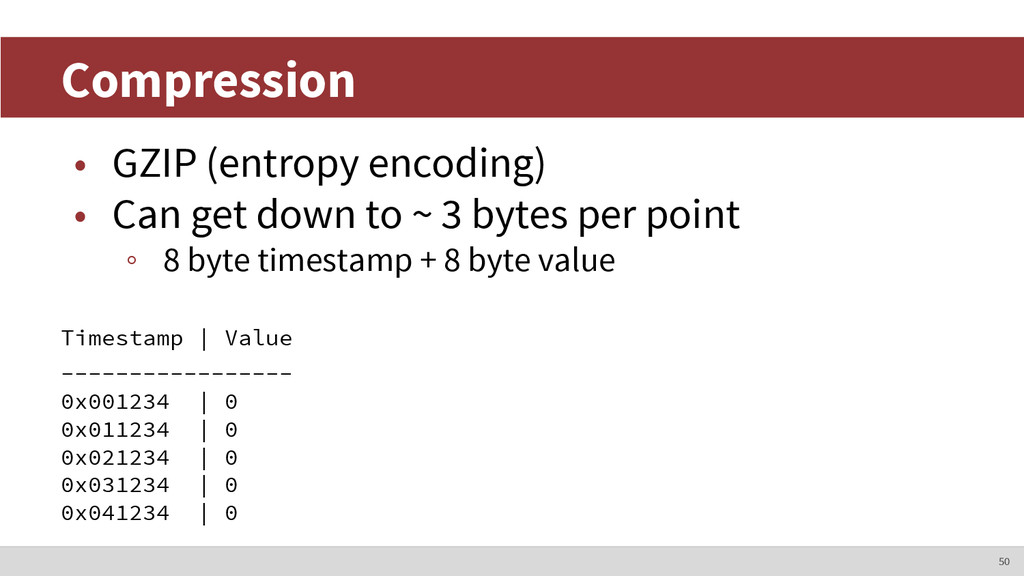
Compression • GZIP (entropy encoding) • Can get down to
~ 3 bytes per point ◦ 8 byte timestamp + 8 byte value Timestamp | Value ----------------- 0x001234 | 0 0x011234 | 0 0x021234 | 0 0x031234 | 0 0x041234 | 0 50 -
Compacting • Compacting happens in the background. • After compacted,
a memory partition gets replaced with its newly created disk partition ◦ This is an atomic swap in the partition list 51 -
Partition list • It’s an ordered, lock-free linked list. •
Newest partition is first. • Threads don’t wait. • The compactor can safely and quickly swap references to partitions. 52 -
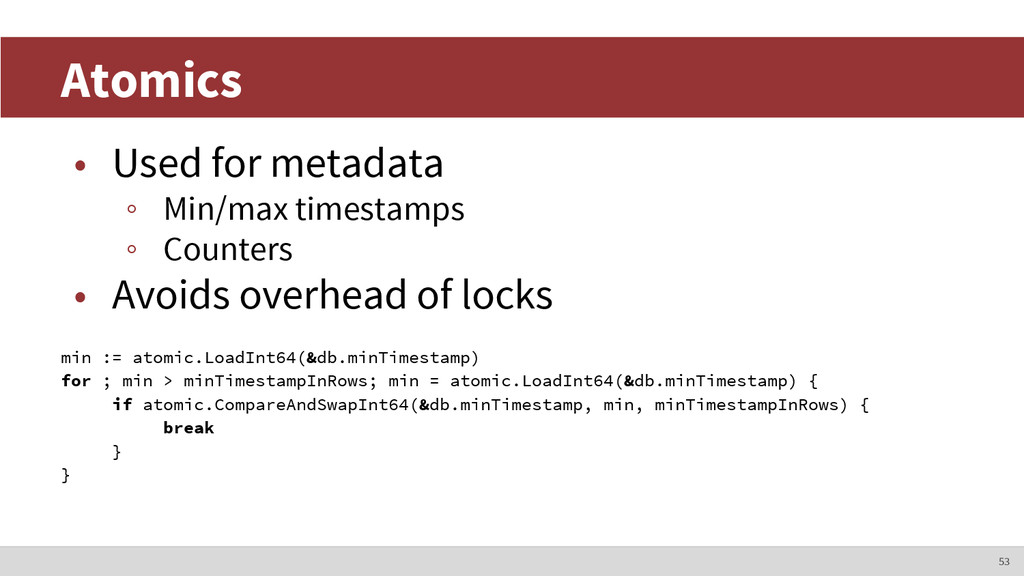
Atomics • Used for metadata ◦ Min/max timestamps ◦ Counters
• Avoids overhead of locks min := atomic.LoadInt64(&db.minTimestamp) for ; min > minTimestampInRows; min = atomic.LoadInt64(&db.minTimestamp) { if atomic.CompareAndSwapInt64(&db.minTimestamp, min, minTimestampInRows) { break } } 53 -
Locks • They’re everywhere. • Mutexes ◦ Used for slices
• RWMutexes ◦ Multiple readers or a single writer ◦ Used for partitions: shared “holds” and exclusive “holds” ◦ Also used for maps in memory partitions to avoid readers blocking each other 54 -
Reducing overhead for writes • Batching writes ◦ Optimal batch
size? Not sure yet. 55 -
Lagging writes • Need to keep more than one writable
partition ◦ Can’t write to compacted partitions 56 -
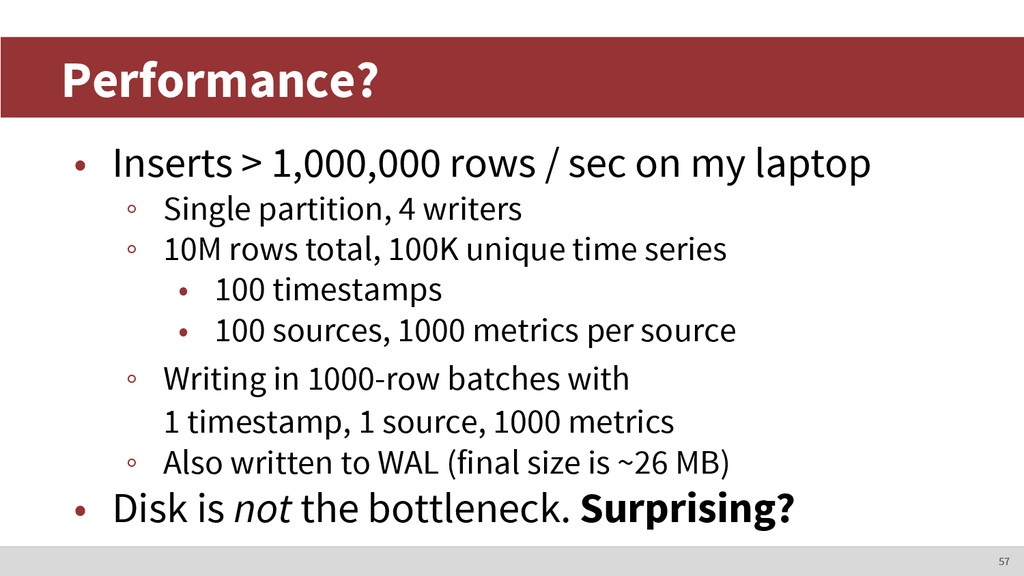
Performance? • Inserts > 1,000,000 rows / sec on my
laptop ◦ Single partition, 4 writers ◦ 10M rows total, 100K unique time series • 100 timestamps • 100 sources, 1000 metrics per source ◦ Writing in 1000-row batches with 1 timestamp, 1 source, 1000 metrics ◦ Also written to WAL (final size is ~26 MB) • Disk is not the bottleneck. Surprising? 57 -
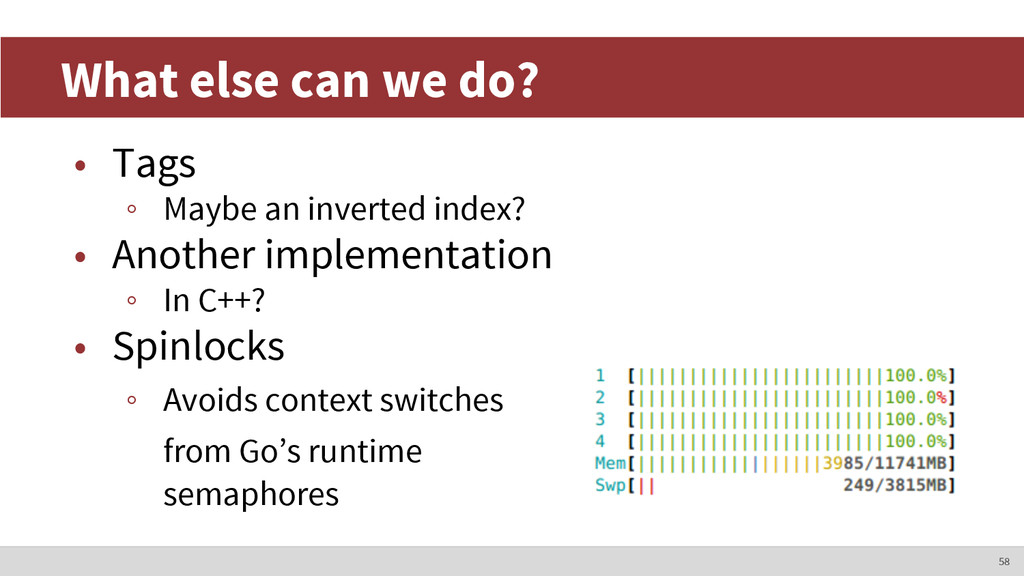
What else can we do? • Tags ◦ Maybe an
inverted index? • Another implementation ◦ In C++? • Spinlocks ◦ Avoids context switches from Go’s runtime semaphores 58 -
Helpful resources The Right Read Optimization is Actually Write Optimization
[video] Building a Time Series Database on MySQL [video] Lock-Free Programming (or, Juggling Razor Blades) [video] LevelDB and Node: What is LevelDB Anyway? [article] 60