Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
ML Productivity
Search
Beomjun Shin
January 17, 2018
Research
93
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
ML Productivity
short talks on productivity of machine learning
Beomjun Shin
January 17, 2018
Transcript
22 slides
ML Productivity Ben (Beomjun Shin) 2018-01-17 (Wed) © Beomjun Shin
Productivity is about not waiting © Beomjun Shin
Time Scales © Beomjun Shin
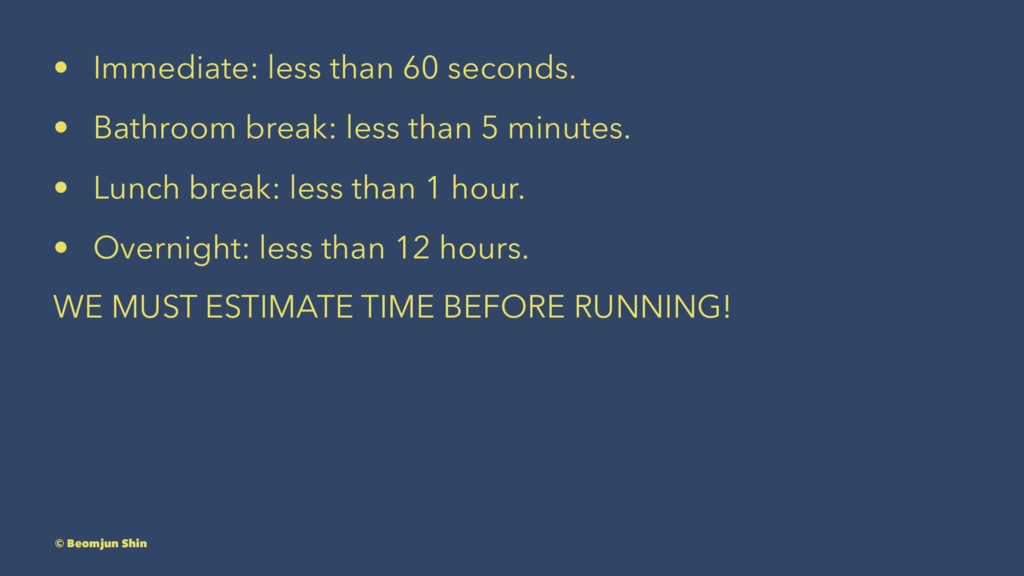
• Immediate: less than 60 seconds. • Bathroom break: less
than 5 minutes. • Lunch break: less than 1 hour. • Overnight: less than 12 hours. WE MUST ESTIMATE TIME BEFORE RUNNING! © Beomjun Shin
Productivity == Iteration © Beomjun Shin
© Beomjun Shin
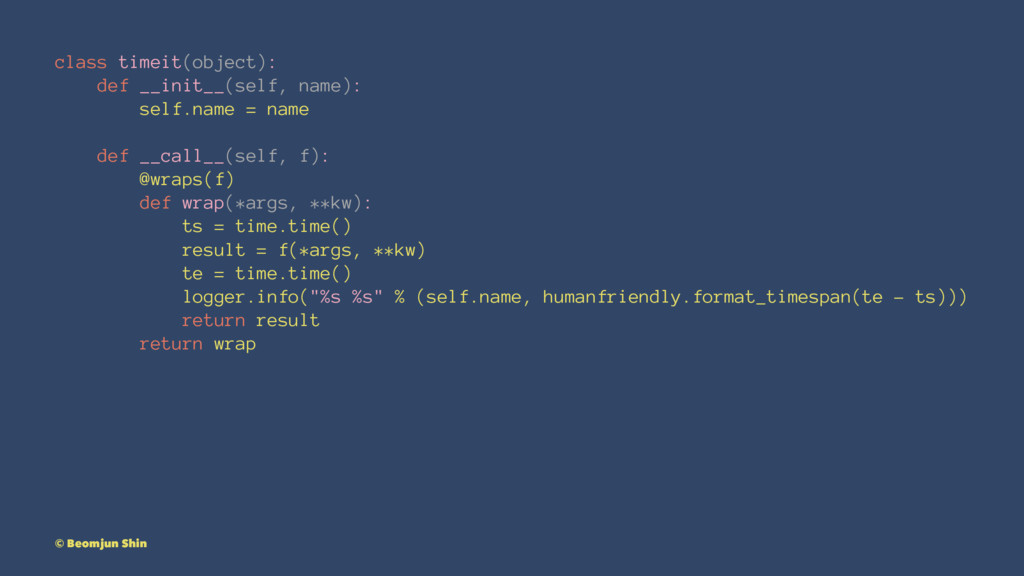
class timeit(object): def __init__(self, name): self.name = name def __call__(self,
f): @wraps(f) def wrap(*args, **kw): ts = time.time() result = f(*args, **kw) te = time.time() logger.info("%s %s" % (self.name, humanfriendly.format_timespan(te - ts))) return result return wrap © Beomjun Shin
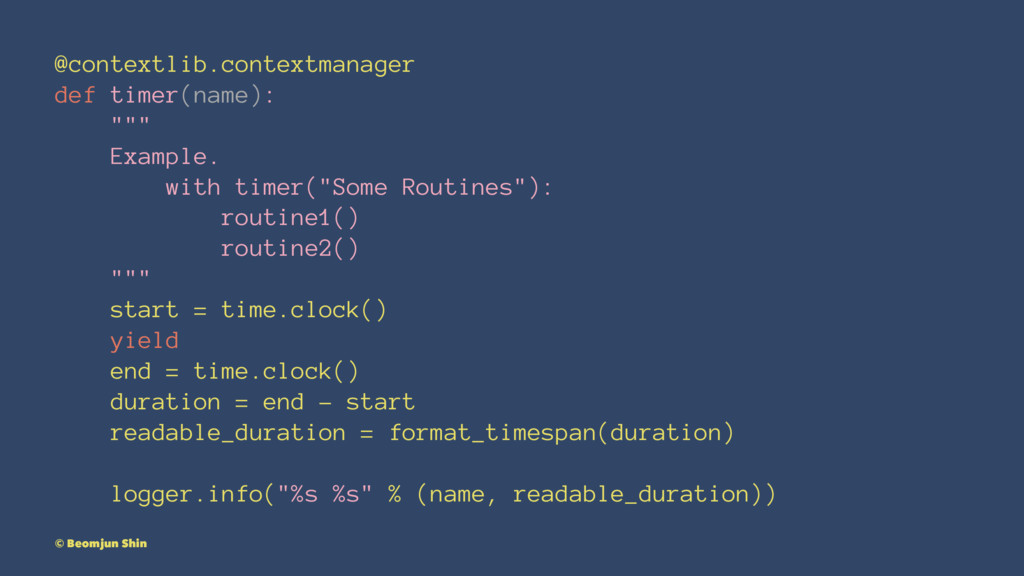
@contextlib.contextmanager def timer(name): """ Example. with timer("Some Routines"): routine1() routine2()
""" start = time.clock() yield end = time.clock() duration = end - start readable_duration = format_timespan(duration) logger.info("%s %s" % (name, readable_duration)) © Beomjun Shin
Use Less Data • Sampled data • Various data •
Synthesis data to validate hypothesis © Beomjun Shin
Sublinear Debugging • Prefer pre-trained model to training from scratch
• Prefer "proven(open-sourced)" code to coding from scratch • Prefer "SGD" to "complex" optimization algorithm © Beomjun Shin
Sublinear Debugging • Logging as many as possible: • First
N step BatchNorm Mean/Variance tracking • Scale of Logit, Activation • Rigorous validation of data quality, preprocessing, augmentation • 2 days of validation is worth enough • Insert assertions as many as possible © Beomjun Shin
Linear Feature Engineering engineering features for a linear model and
then switching to a more complicated model on the same representation © Beomjun Shin
Flexible Code • We can sacrifice "Code Efficiency" for "Flexibility"
• Exchange "raw" data between models and preprocessing by code • Unlike API server, in machine learning task so many assumption can be changed • We should always be prepare to build whole pipeline from scratch © Beomjun Shin
Reproducible preprocessing • Every data preprocessing will be fail in
first iteration • let's fall in love with shell © Beomjun Shin
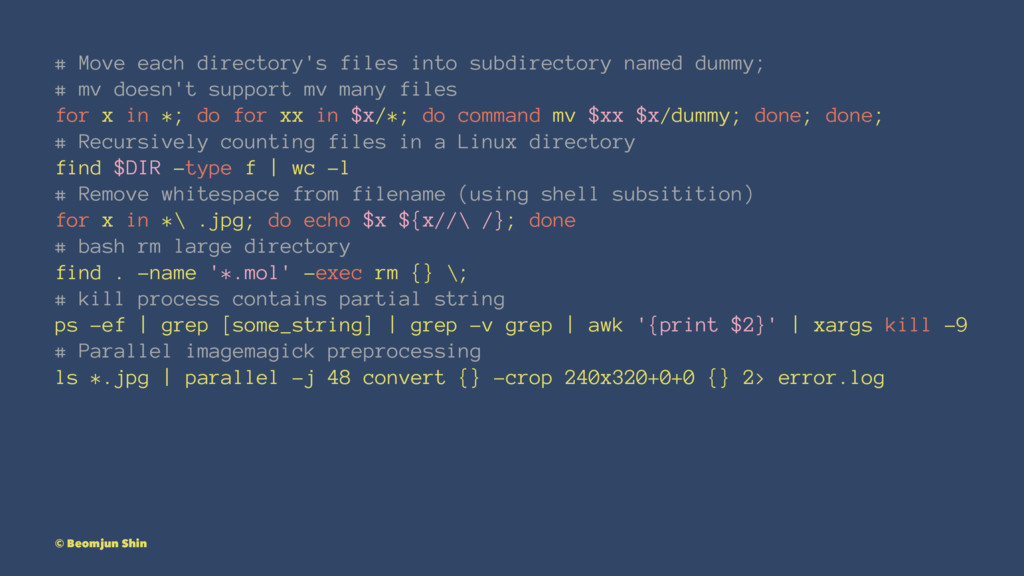
Shell commands © Beomjun Shin
# Move each directory's files into subdirectory named dummy; #
mv doesn't support mv many files for x in *; do for xx in $x/*; do command mv $xx $x/dummy; done; done; # Recursively counting files in a Linux directory find $DIR -type f | wc -l # Remove whitespace from filename (using shell subsitition) for x in *\ .jpg; do echo $x ${x//\ /}; done # bash rm large directory find . -name '*.mol' -exec rm {} \; # kill process contains partial string ps -ef | grep [some_string] | grep -v grep | awk '{print $2}' | xargs kill -9 # Parallel imagemagick preprocessing ls *.jpg | parallel -j 48 convert {} -crop 240x320+0+0 {} 2> error.log © Beomjun Shin
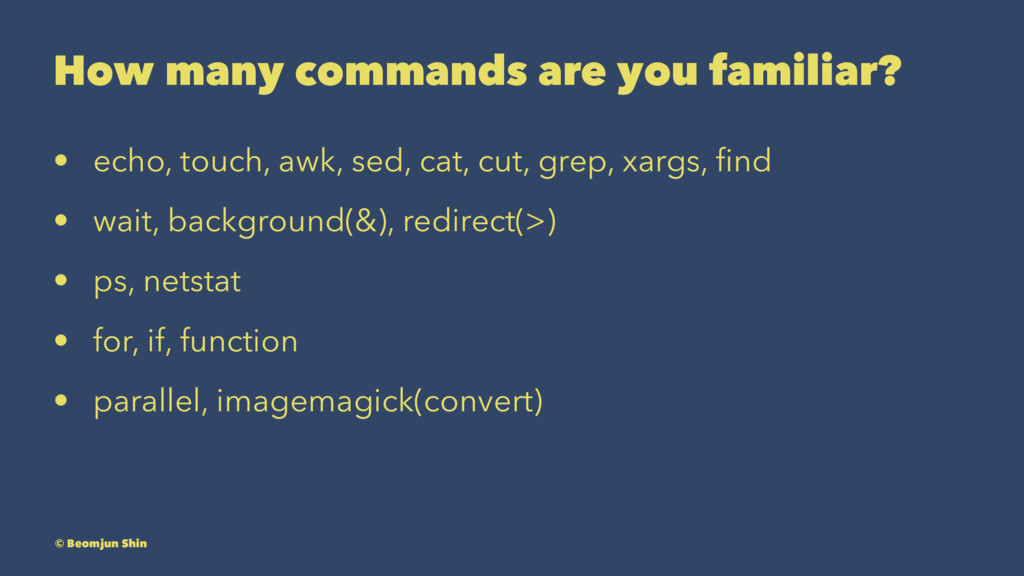
How many commands are you familiar? • echo, touch, awk,
sed, cat, cut, grep, xargs, find • wait, background(&), redirect(>) • ps, netstat • for, if, function • parallel, imagemagick(convert) © Beomjun Shin
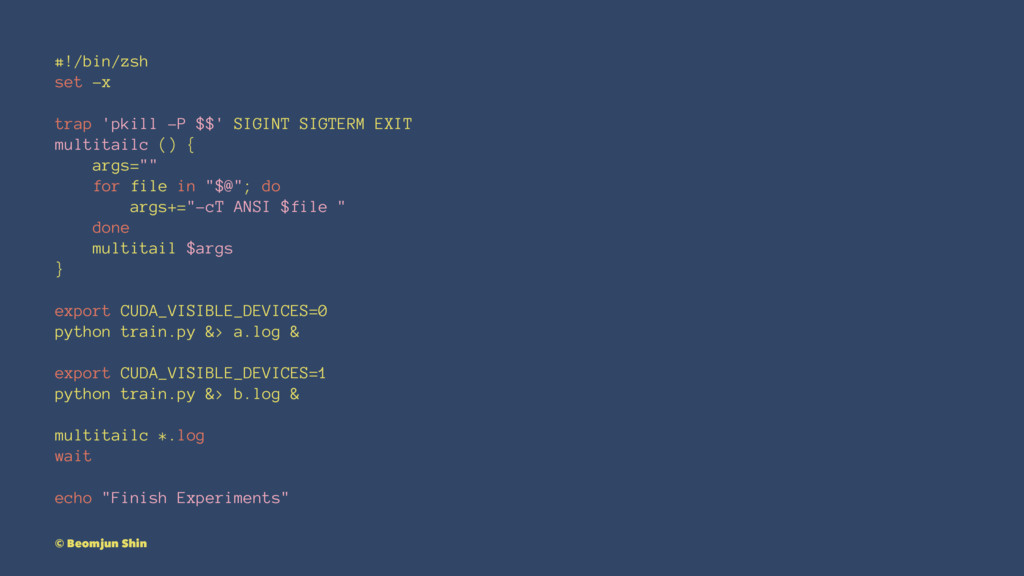
#!/bin/zsh set -x trap 'pkill -P $$' SIGINT SIGTERM EXIT
multitailc () { args="" for file in "$@"; do args+="-cT ANSI $file " done multitail $args } export CUDA_VISIBLE_DEVICES=0 python train.py &> a.log & export CUDA_VISIBLE_DEVICES=1 python train.py &> b.log & multitailc *.log wait echo "Finish Experiments" © Beomjun Shin
Working Process 1. Prepare "proven" data, model or idea 2.
Data validation 3. Setup evaluation metrics (at least two) • one is for model comparison, the other is for human 4. Code and test whether it is "well" trained or not 5. Model improvement (iteration) © Beomjun Shin
Build our best practice • datawrapper - model - trainer
• data/ folder in project root • experiment management © Beomjun Shin
Be aware of ML's technical debt • Recommend to read
Machine Learning: The High- Interest Credit Card of Technical Debt from Google © Beomjun Shin
References • Productivity is about not waiting • Machine Learning:
The High-Interest Credit Card of Technical Debt • Patterns for Research in Machine Learning • Development workflows for Data Scientists © Beomjun Shin
More Decks by Beomjun Shin
See All by Beomjun Shin
Convolution Transpose by yourself
shastakr
0
97
스마트폰 위의 딥러닝
shastakr
0
290
Design your CNN: historical inspirations
shastakr
0
55
"진짜 되는" 투자 전략 찾기: 금융전략과 통계적 검정
shastakr
0
93
Other Decks in Research
See All in Research
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
350
[webinaire du Ciirpo] Agnelages plein air : des éleveurs partagent leurs pratiques
institutdelelevage
PRO
0
340
横浜市長(山中氏)の言動にかかる第三者による調査報告書
sishi2026
0
680
[最先端NLP勉強会2026] Agentic Rubrics as Contextual Verifiers for SWE Agents
rfujii
1
420
Model Predictive Control for Uncertain Systems: Robust & Data-Driven Designs
kohlerjohannes
0
230
モデル評価を効率的にする方法
ftakahashi
0
250
Adapter les bergeries aux fortes chaleurs
institutdelelevage
PRO
0
190
[IEICE-Soceity-Conf2026] セマンティック通信を見据えたマルチスケールセンシングと 学習の融合によるデジタルツイン基盤 / Digital Twin Infrastructure via the Fusion of Multi-Scale Sensing and Learning toward Semantic Communications
pman0214
0
150
ThermoGS (ECCV2026)解説 — 4D Gaussian Splatting × Thermodynamics CVと物理の統合モデルとして
godel
PRO
0
120
Top 4セキュリティ会議に一通り論文が採択されるまでの道のりと展望 / Top 4 Security Grand Slam
takaomurakami
0
1.1k
[SNLP2026] Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach
wataruuuuu
0
370
Evaluating LLM Reliability Across Facts, Evidence, and Cultures
yukiar
0
250
Featured
See All Featured
Unlocking the hidden potential of vector embeddings in international SEO
frankvandijk
0
1k
Sharpening the Axe: The Primacy of Toolmaking
bcantrill
46
3.1k
Six Lessons from altMBA
skipperchong
29
4.6k
Ten Tips & Tricks for a 🌱 transition
stuffmc
1
290
Everyday Curiosity
cassininazir
0
400
Self-Hosted WebAssembly Runtime for Runtime-Neutral Checkpoint/Restore in Edge–Cloud Continuum
chikuwait
0
960
10 Git Anti Patterns You Should be Aware of
lemiorhan
PRO
659
62k
Abbi's Birthday
coloredviolet
5
11k
B2B Lead Gen: Tactics, Traps & Triumph
marketingsoph
1
300
More Than Pixels: Becoming A User Experience Designer
marktimemedia
3
630
The Language of Interfaces
destraynor
162
27k
The Psychology of Web Performance [Beyond Tellerrand 2023]
tammyeverts
49
3.6k


 shastakr
 s_mizuki_nlp
 institutdelelevage
 sishi2026
 rfujii
 kohlerjohannes
 ftakahashi
 pman0214
 godel
 takaomurakami
 wataruuuuu
 yukiar
 frankvandijk
 bcantrill
 skipperchong
 stuffmc
 cassininazir
 chikuwait
 lemiorhan
 coloredviolet
 marketingsoph
 marktimemedia
 destraynor
 tammyeverts