Share
Embed
Behind the Yahoo! JAPAN Top Page: Trial and Error of the Article Recommendation System and Future Challenges
Shumpei Okura (Yahoo! JAPAN / Development Division 2, Media Services Group, Media Group / Engineer)
https://tech-verse.me/ja/sessions/166
https://tech-verse.me/en/sessions/166
https://tech-verse.me/ko/sessions/166
Tech-Verse2022
November 17, 2022
Transcript
60 slides
-
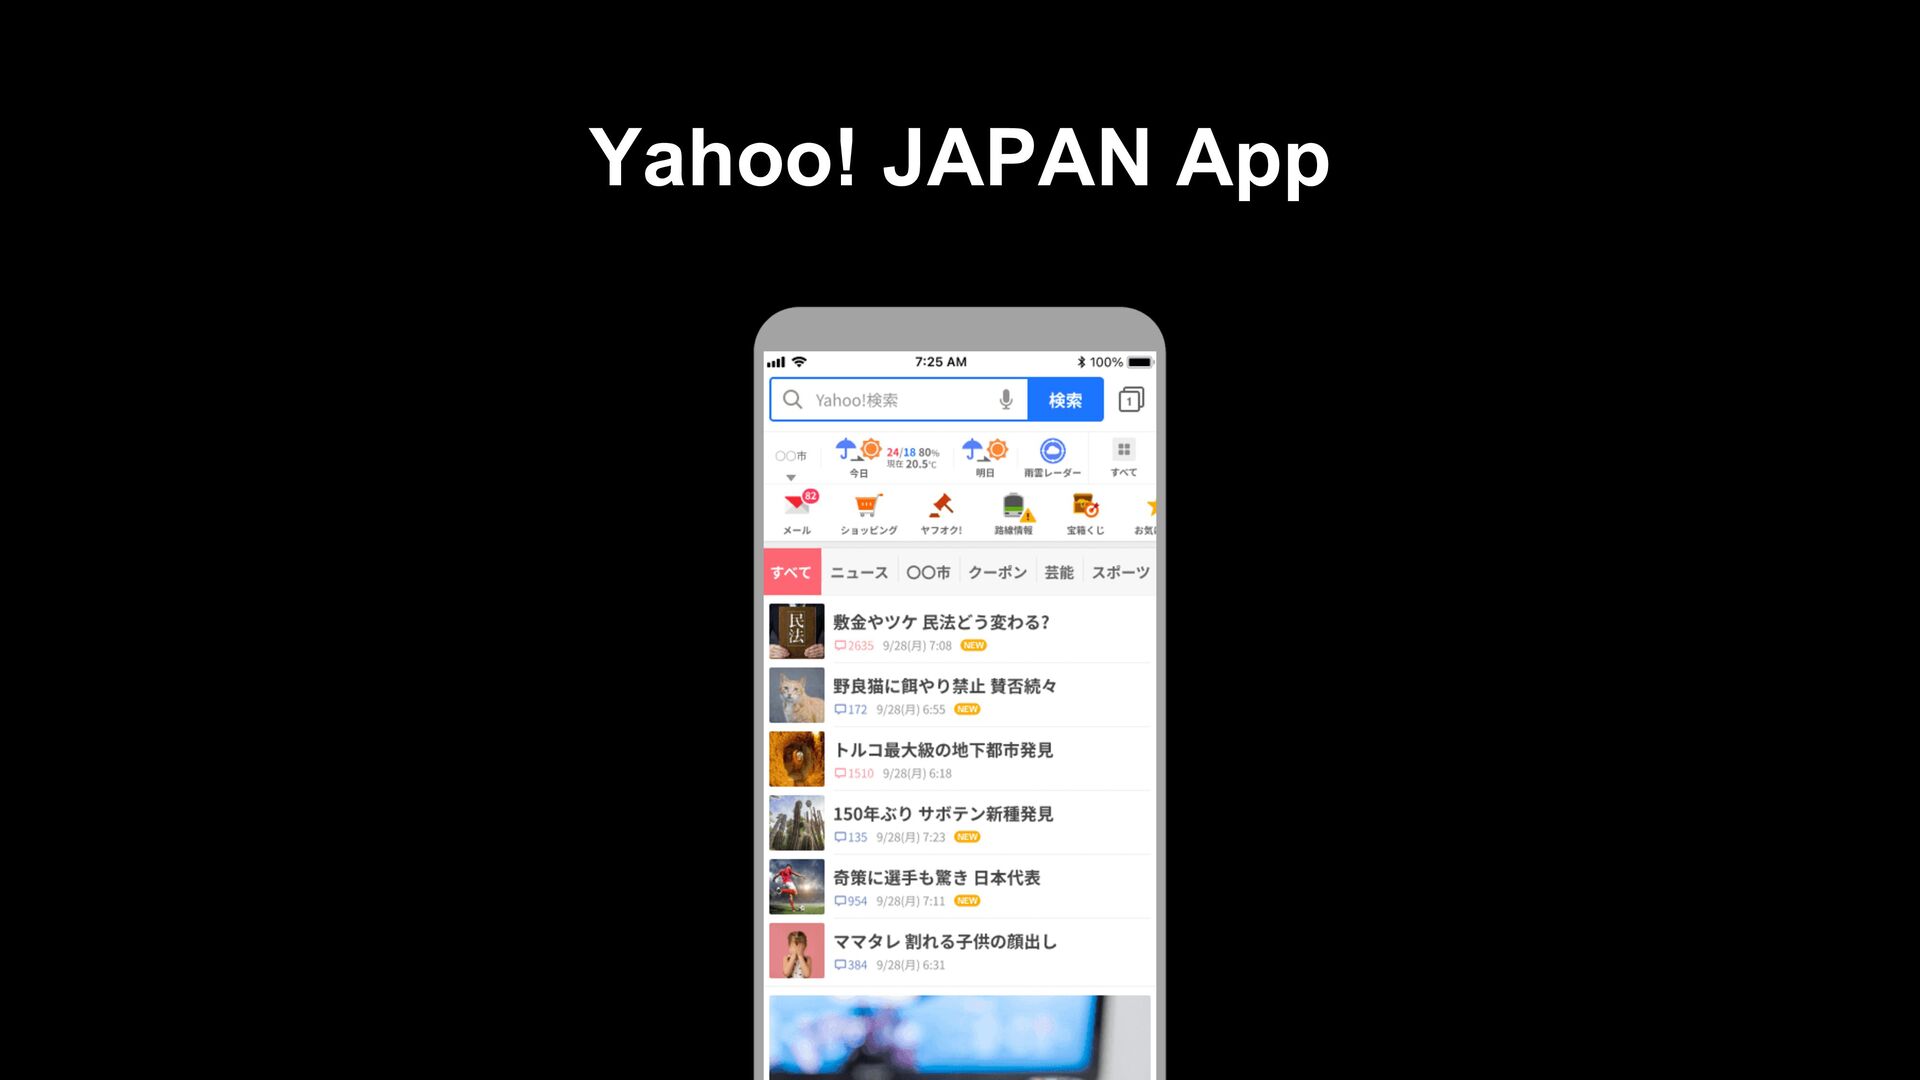
Behind the Yahoo! JAPAN Top Page: Trial and Error of
the Article Recommendation System and Future Challenges Shumpei Okura / Yahoo! JAPAN -
Speaker 12th Machine Learning Black Belt (the technical expert title
at Yahoo! JAPAN). 2012~ Advertising background engineer 2015~ Researcher and developer of news recommendations In 2016, We introduced the first deep learning model for news recommendation to Yahoo Japan top page. And since then, we have continued to improve the model in parallel with user analysis. Shumpei Okura (Yahoo Japan Corp.) -
Agenda - Introduction - Overview our recommendation systems - How
to train the recommendation model - Recent Issues and workarounds • Diversity of contents • Dislike signals • Accuracy blur per learning -
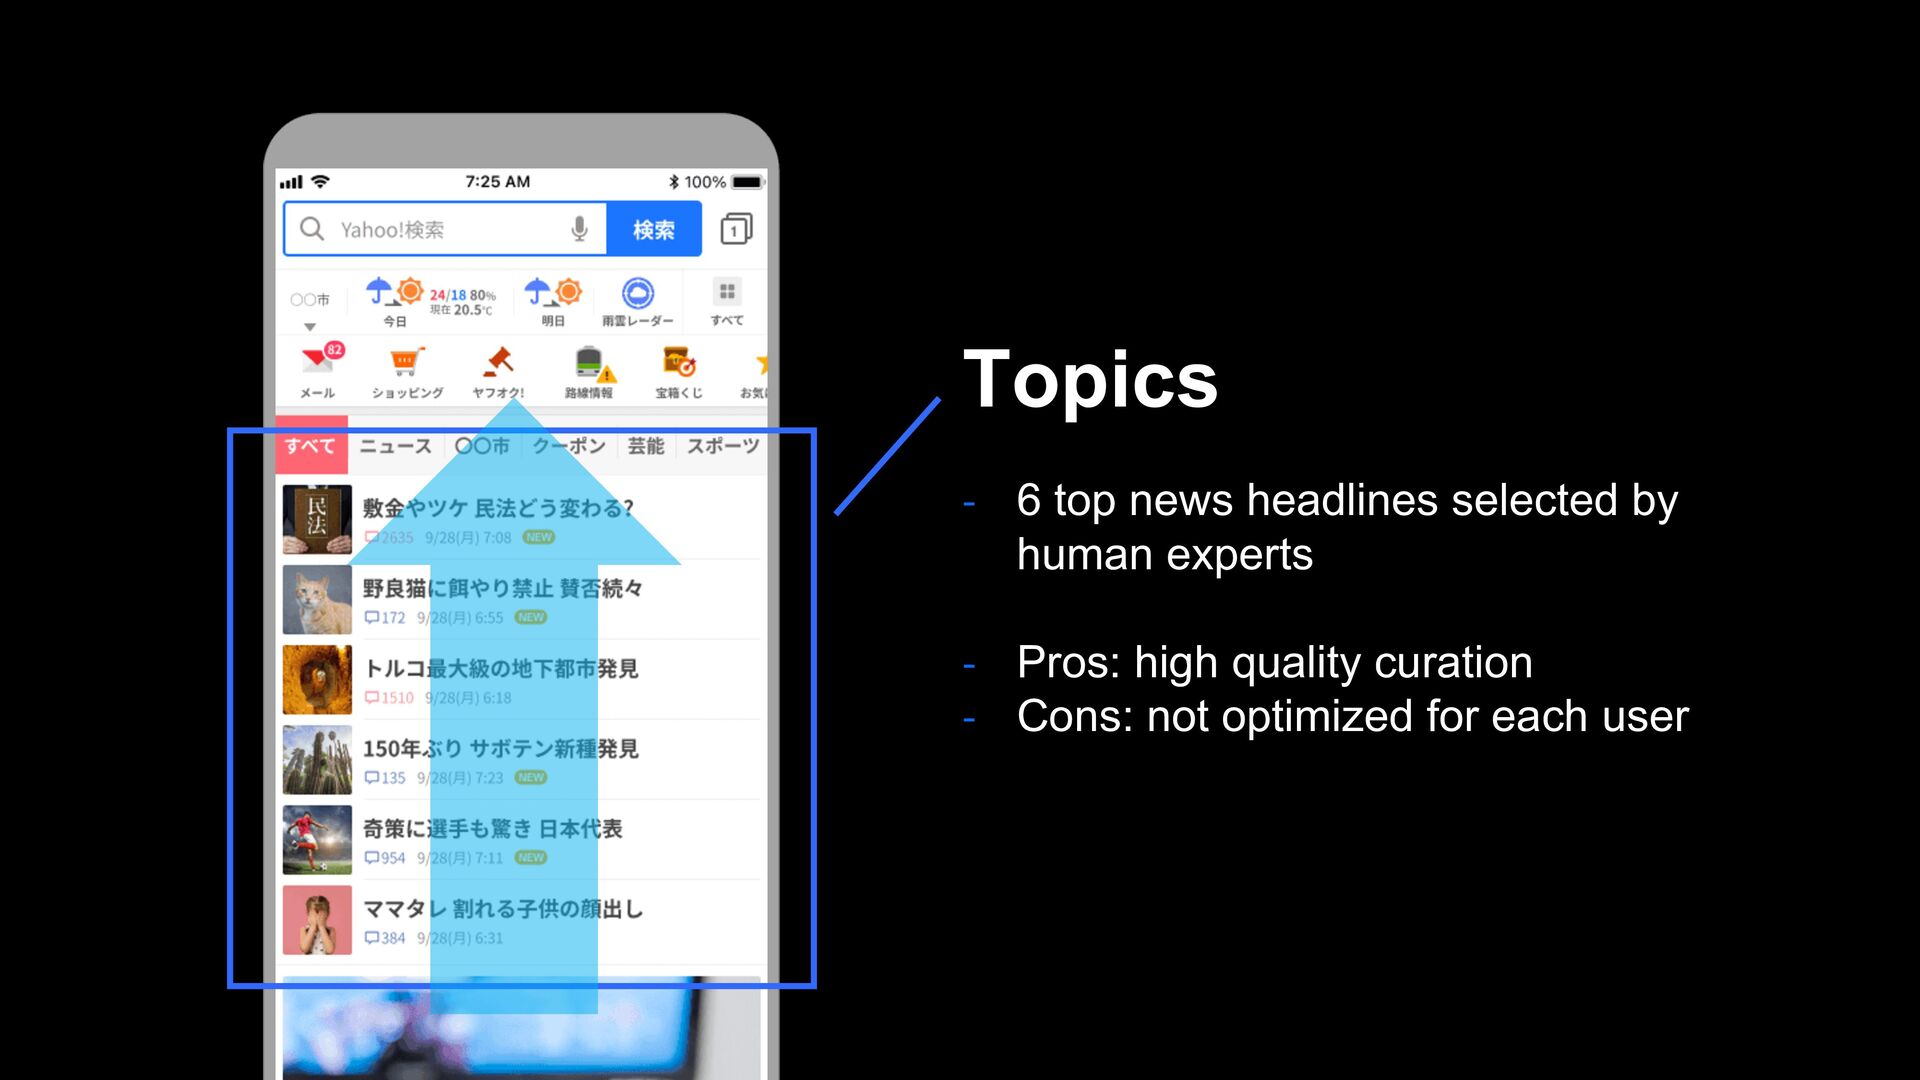
- 6 top news headlines selected by human experts -
Pros: high quality curation - Cons: not optimized for each user Topics -
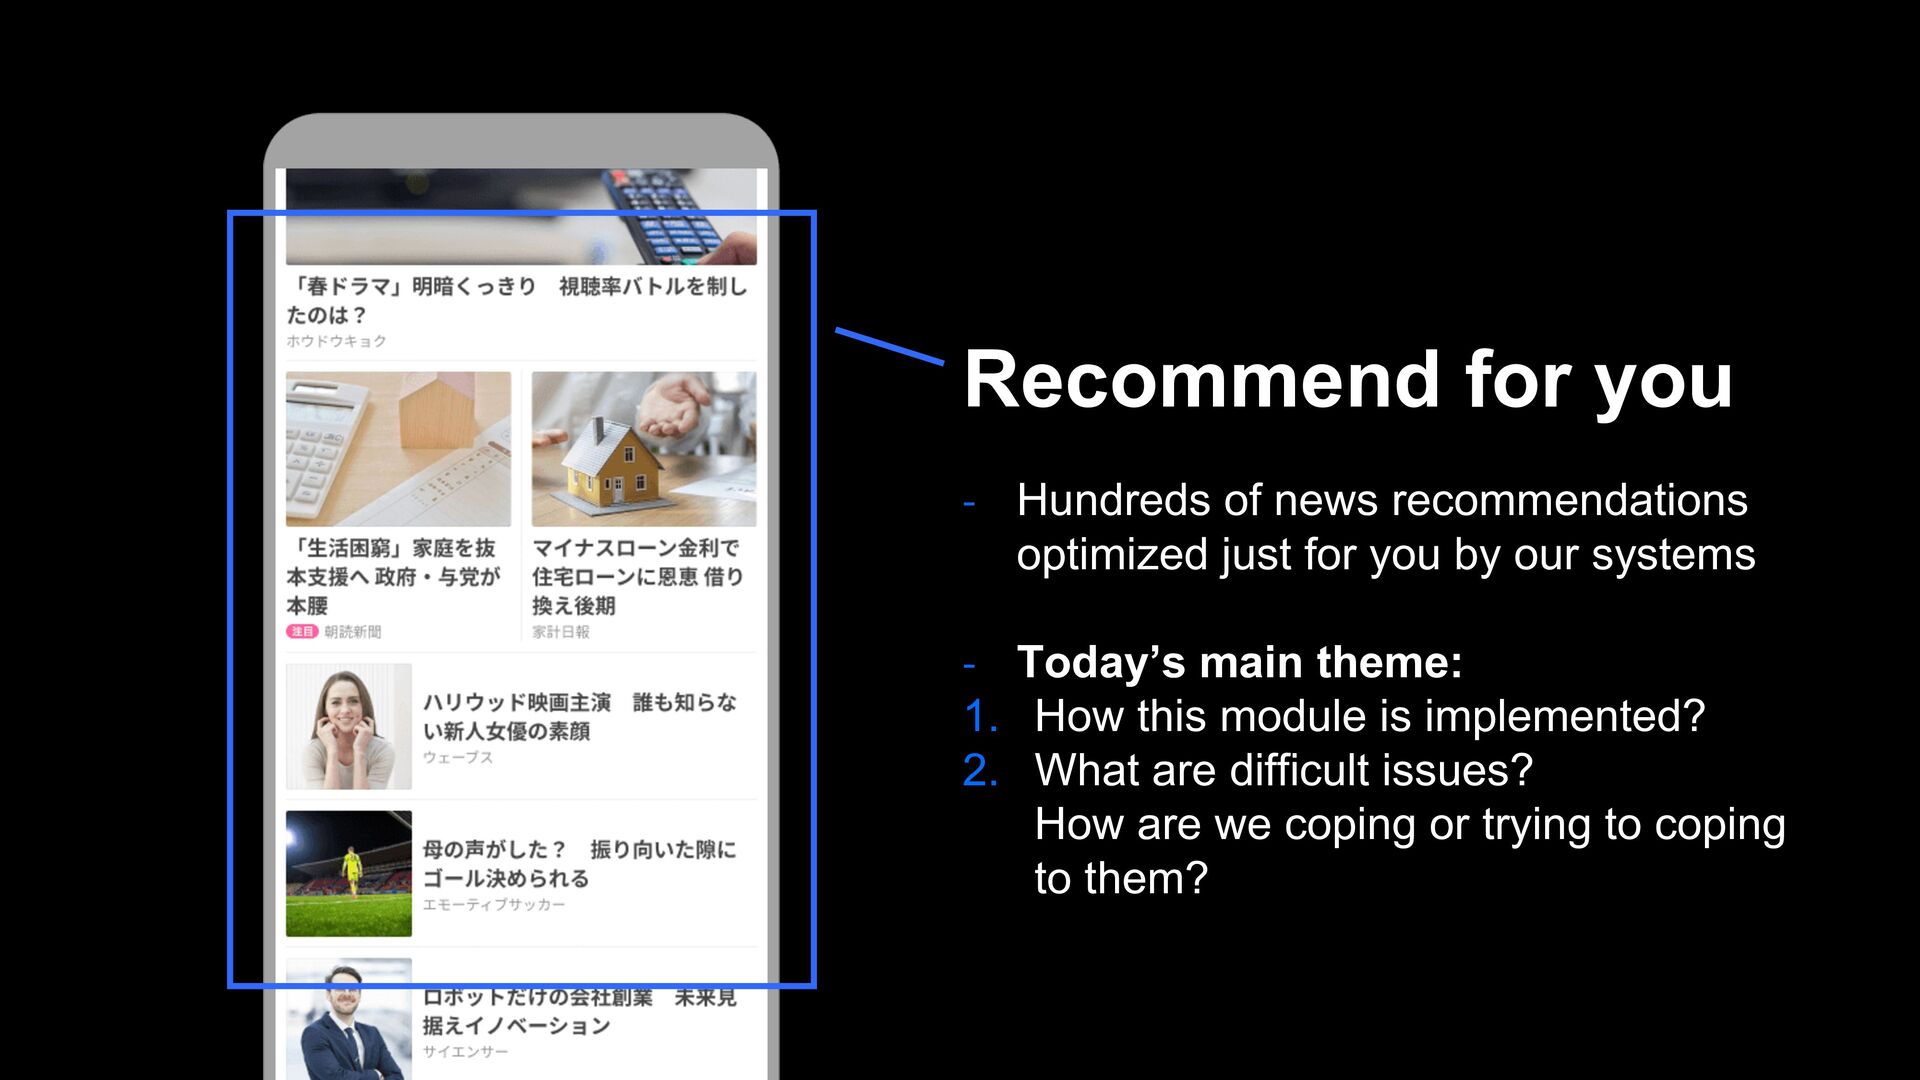
- Hundreds of news recommendations optimized just for you by
our systems - Today’s main theme: 1. How this module is implemented? 2. What are difficult issues? How are we coping or trying to coping to them? Recommend for you -
Concept of recommendations - Immediacy is especially important for news
articles. - When updated information arrives, old information is no longer useful, and the next day it will be no longer interesting to users. Posted new articles immediately appear in the recommendation list. -
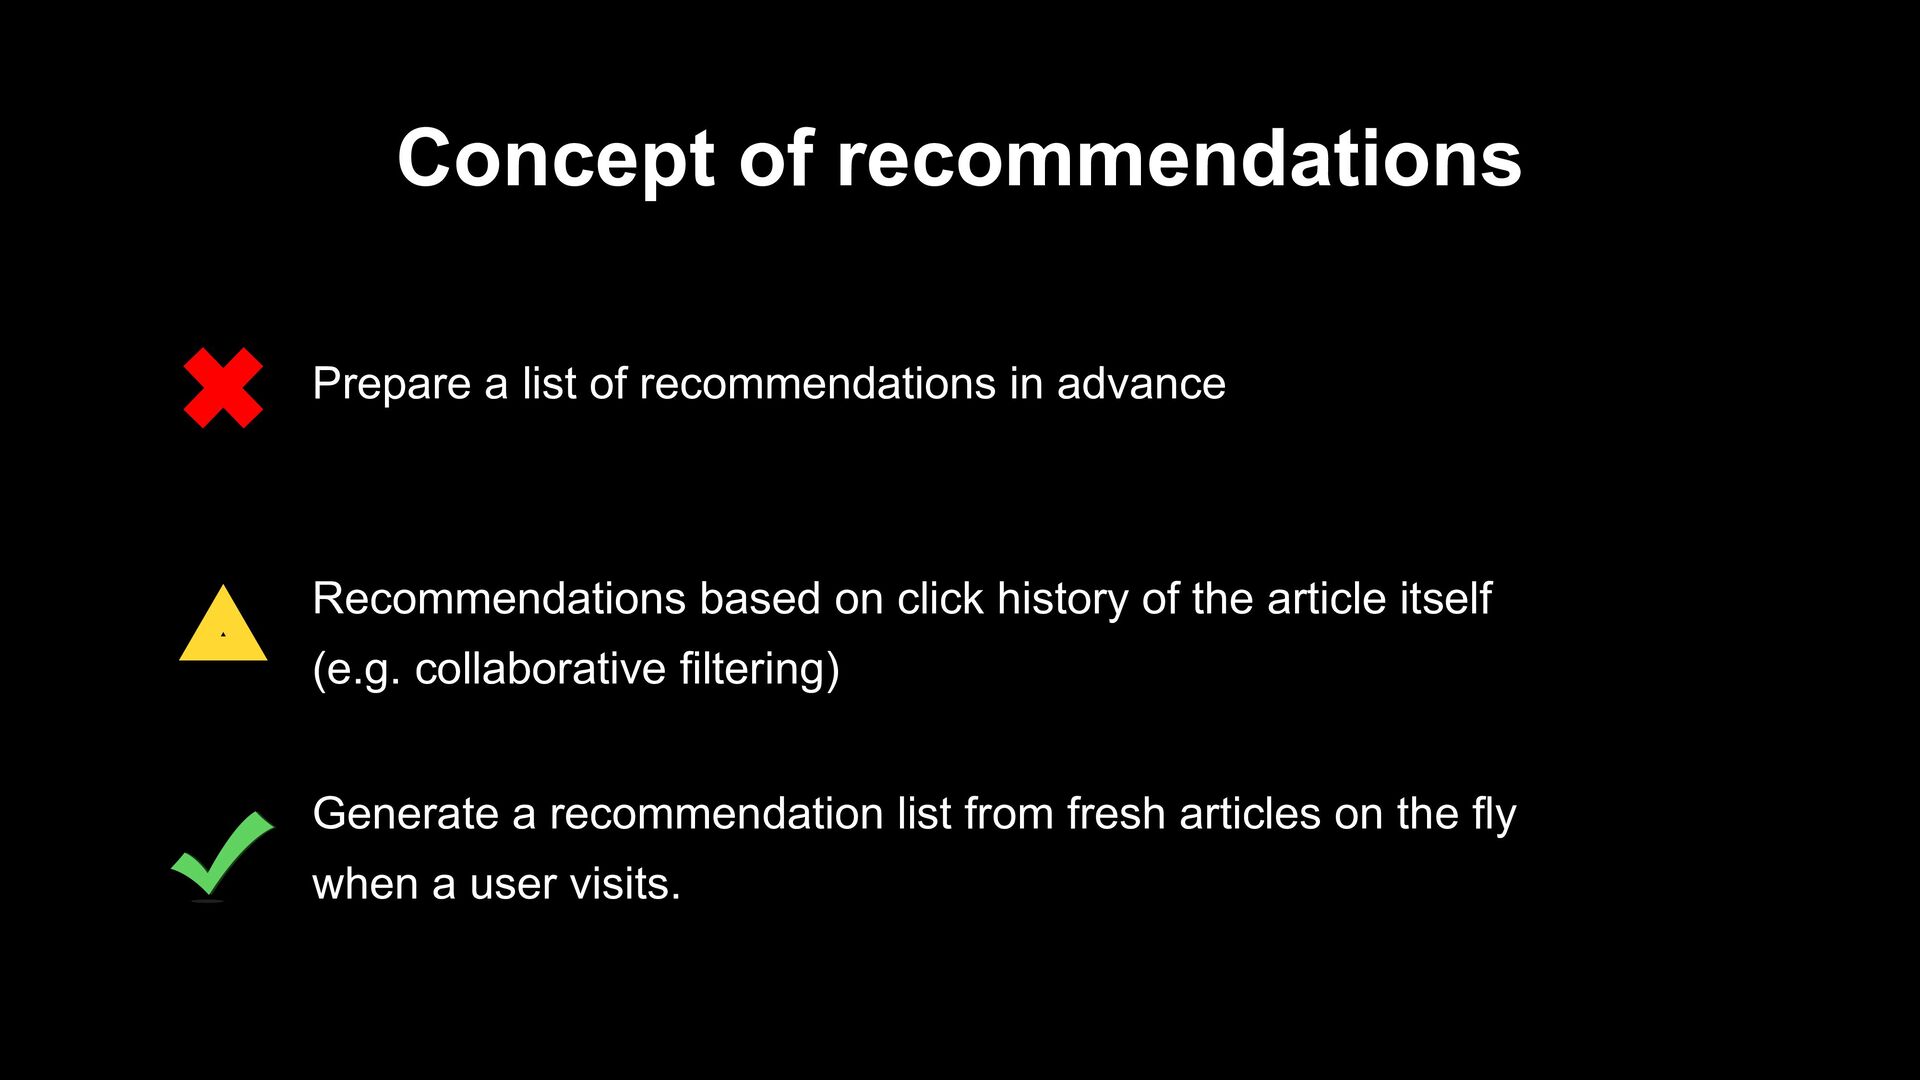
Concept of recommendations Recommendations based on click history of the
article itself (e.g. collaborative filtering) Generate a recommendation list from fresh articles on the fly when a user visits. Prepare a list of recommendations in advance -
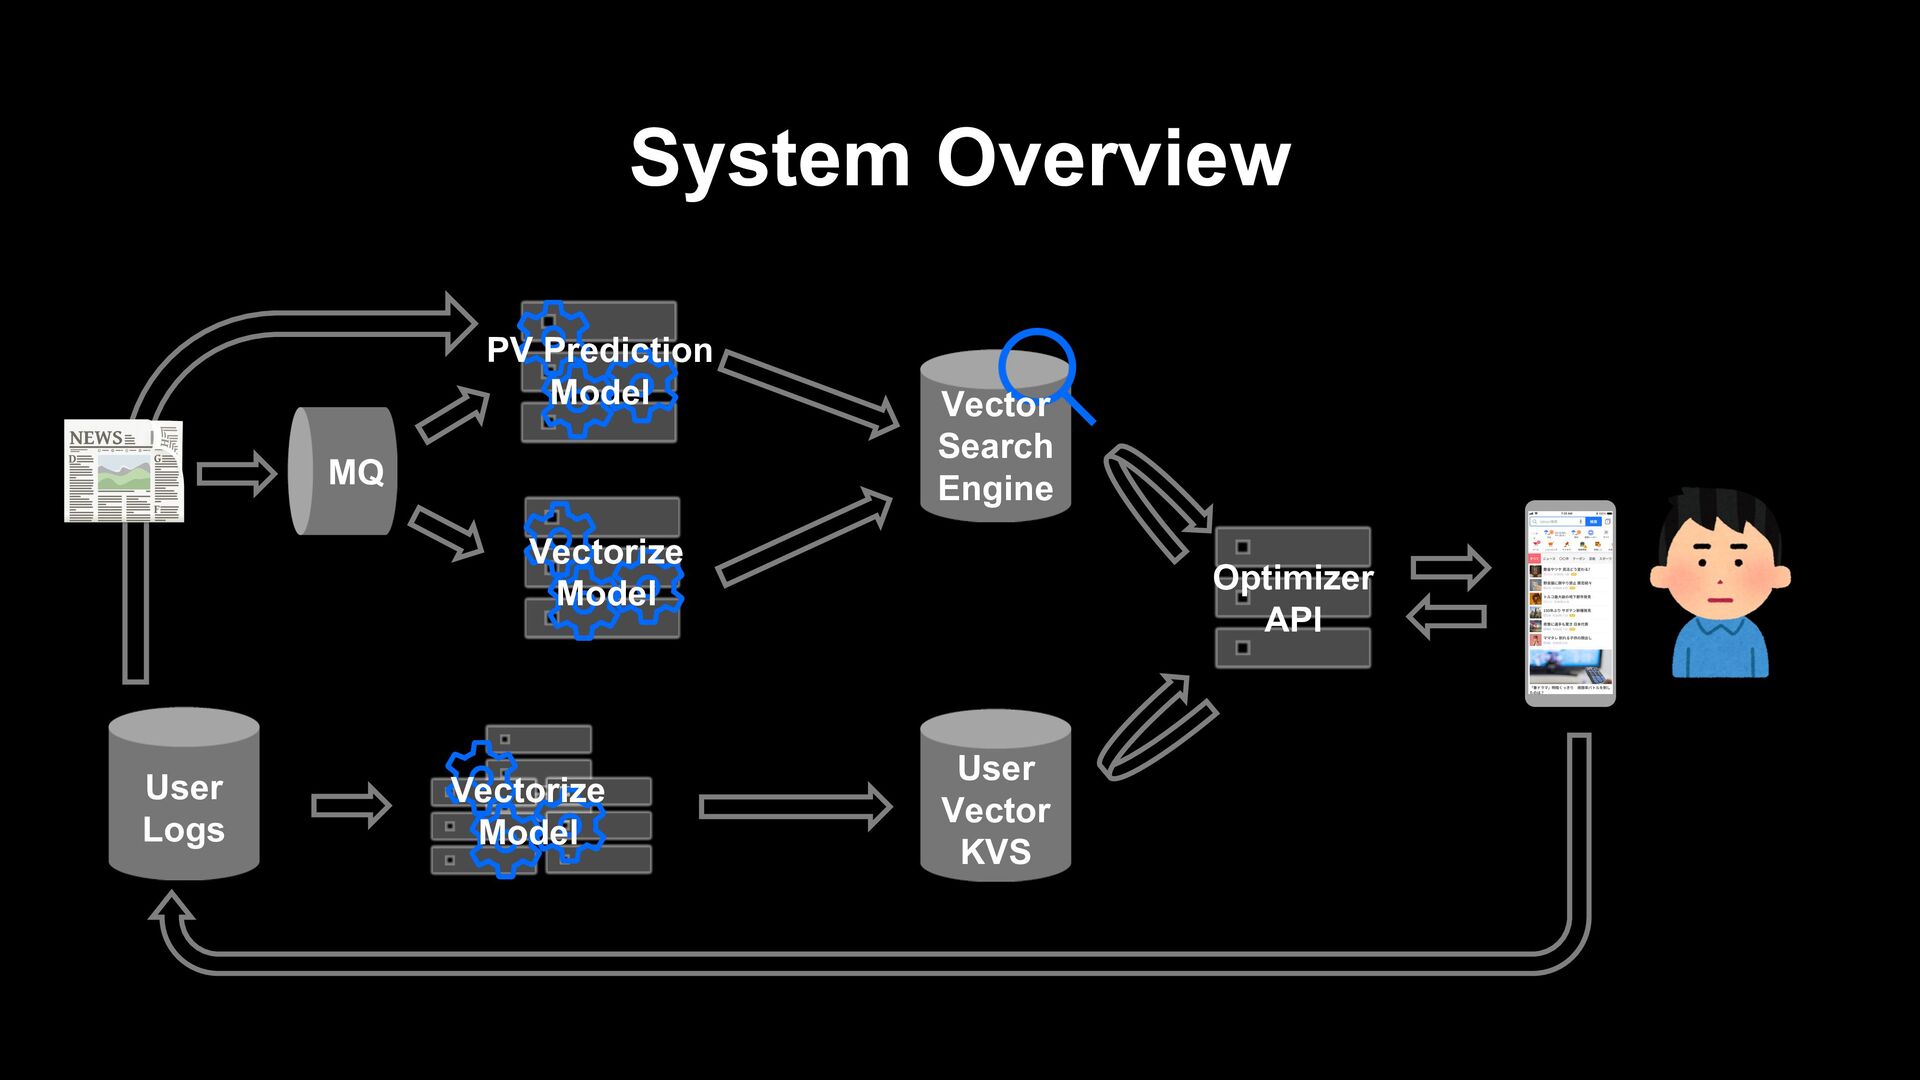
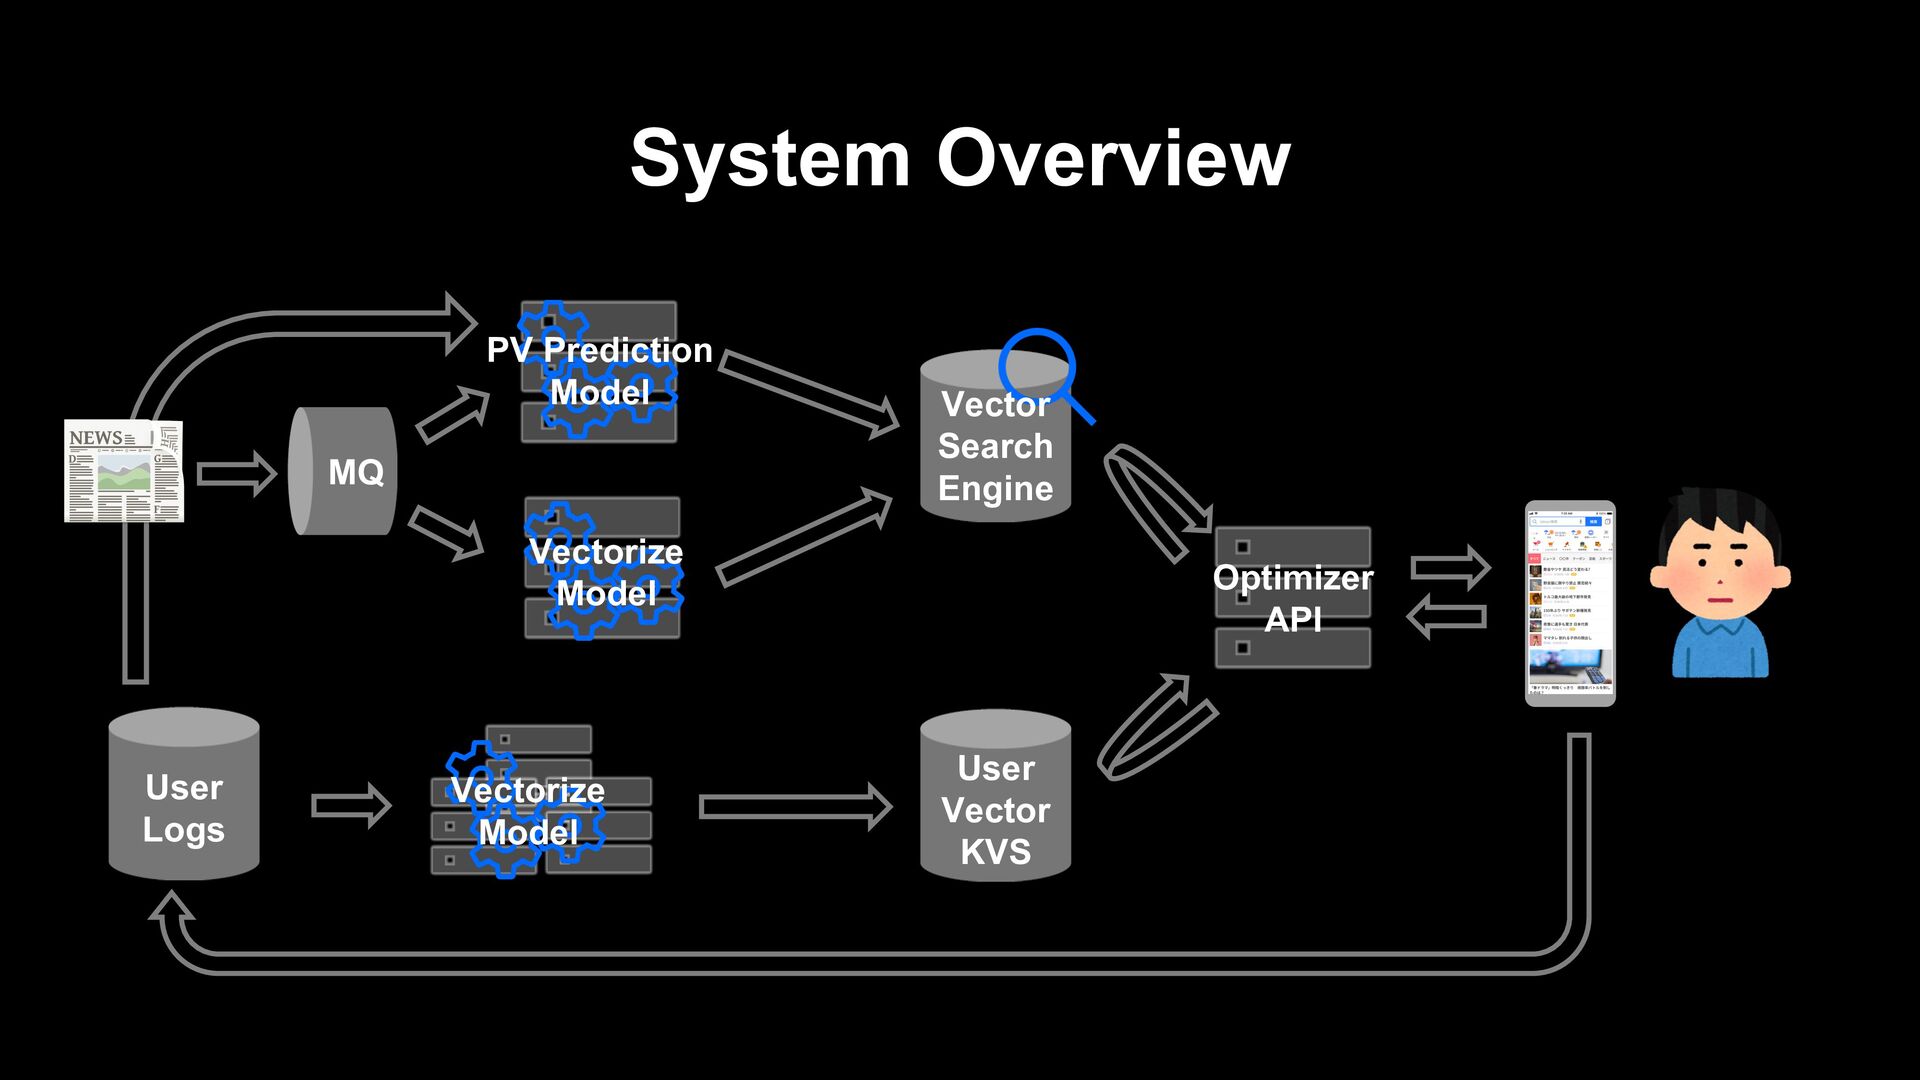
System Overview MQ Vector Search Engine User Vector KVS Optimizer
API User Logs Vectorize Model PV Prediction Model Vectorize Model -
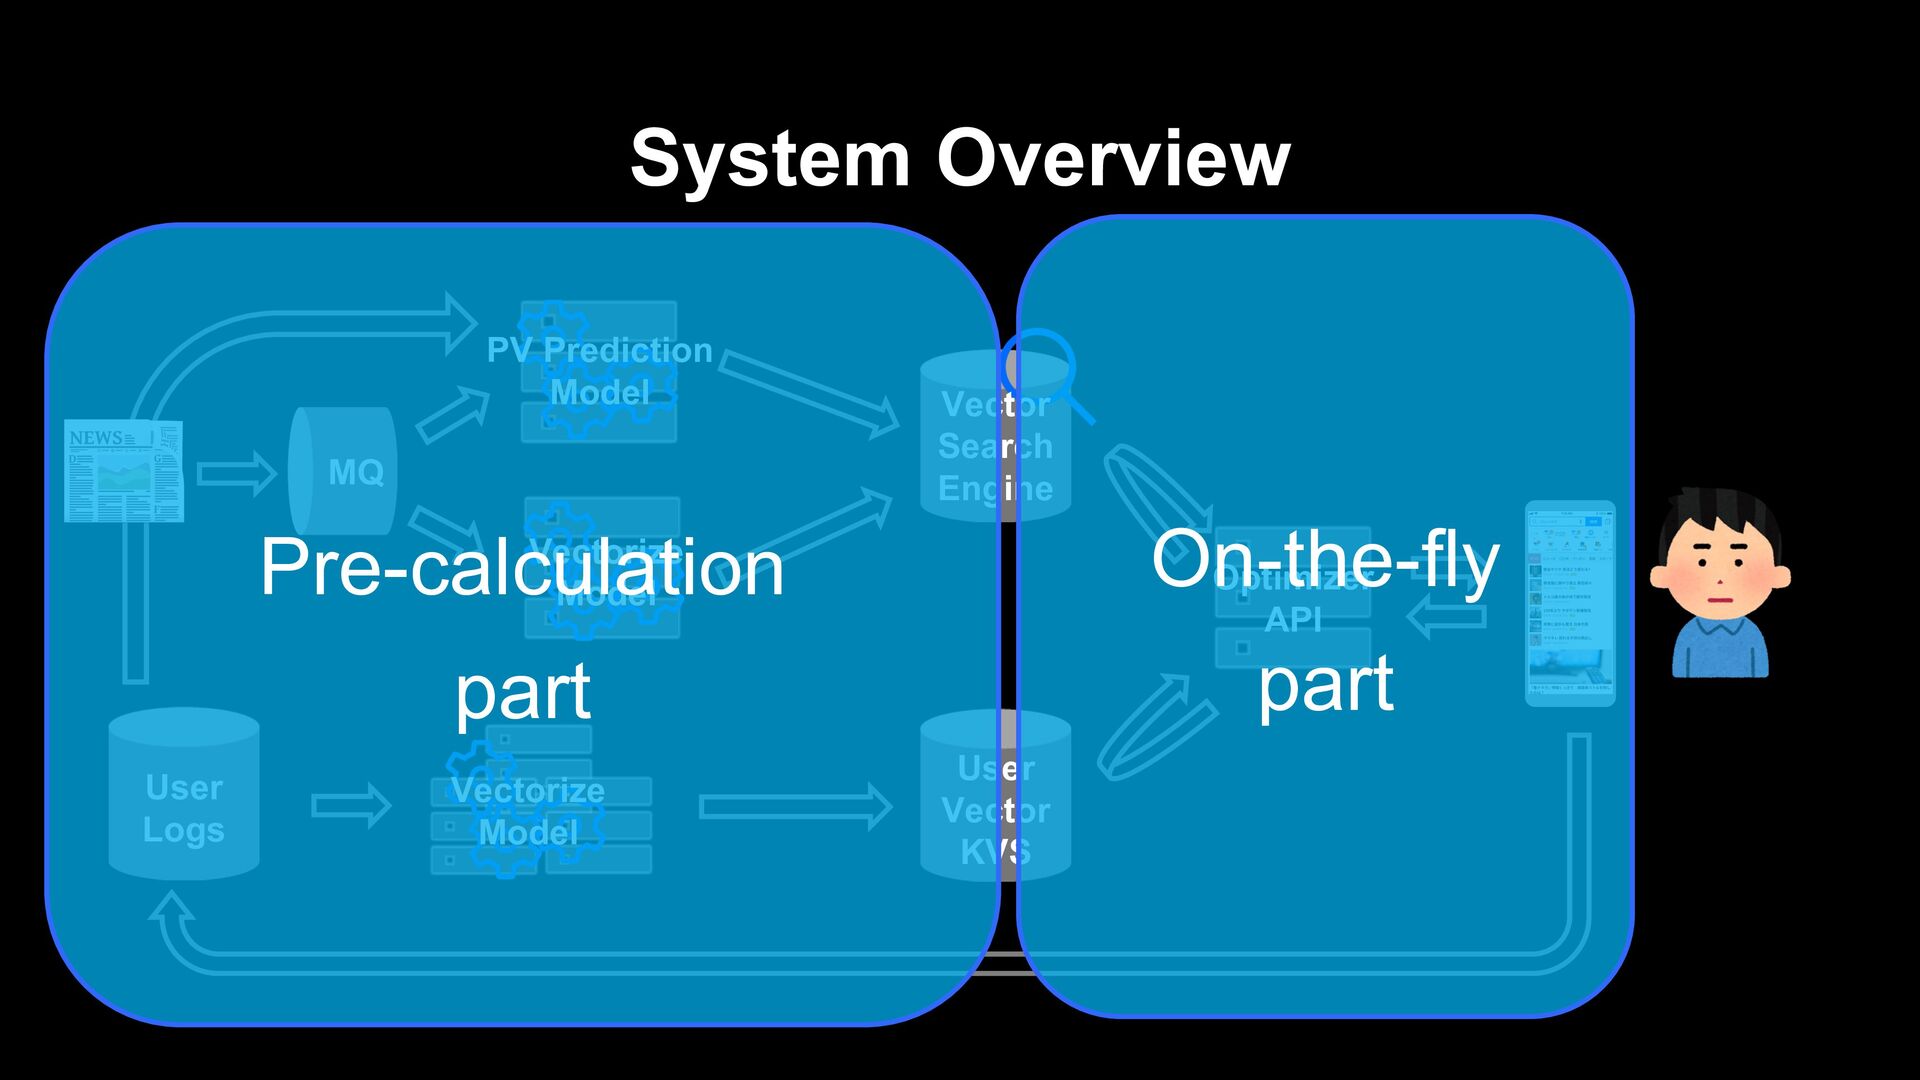
System Overview MQ Vector Search Engine User Vector KVS Optimizer
API User Logs Vectorize Model PV Prediction Model Vectorize Model Pre-calculation part On-the-fly part -
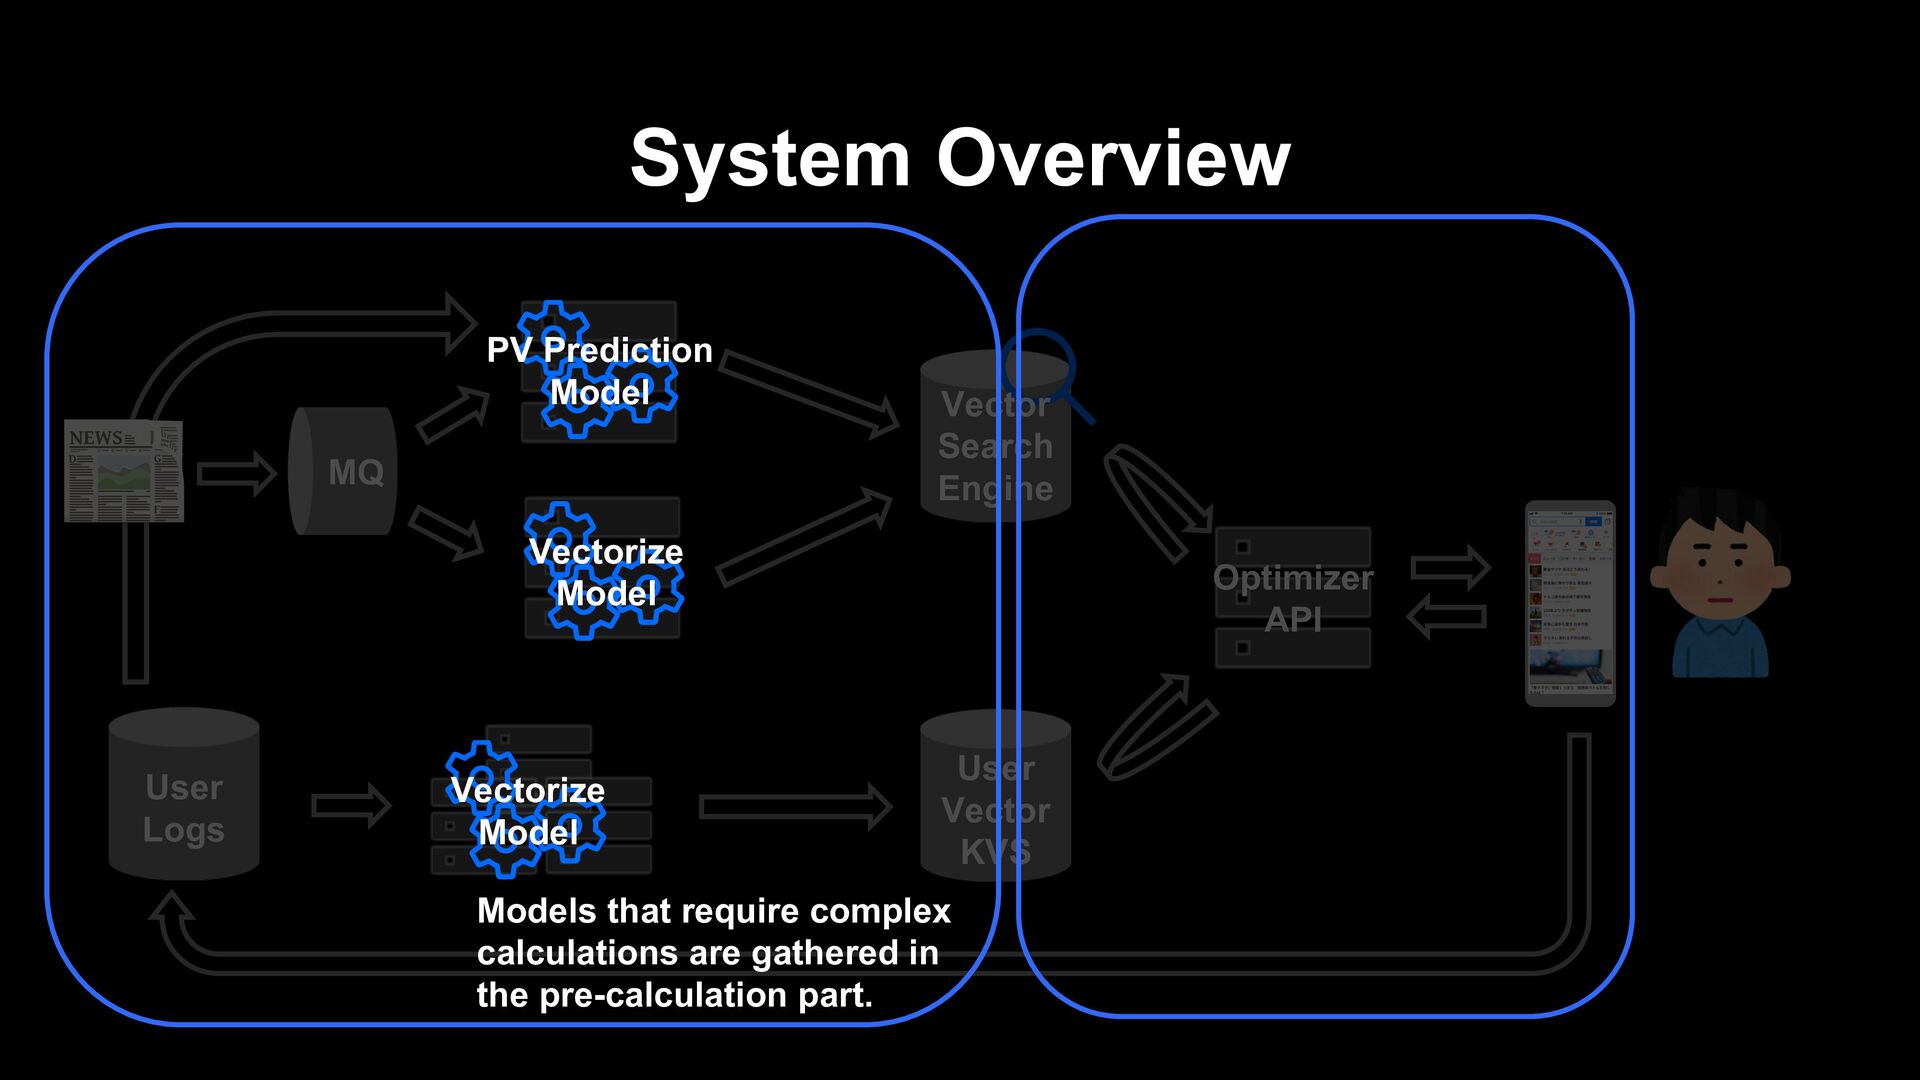
System Overview MQ Vector Search Engine User Vector KVS Optimizer
API User Logs Vectorize Model PV Prediction Model Vectorize Model Models that require complex calculations are gathered in the pre-calculation part. -
System Overview MQ Vector Search Engine User Vector KVS Optimizer
API User Logs Vectorize Model PV Prediction Model Vectorize Model -
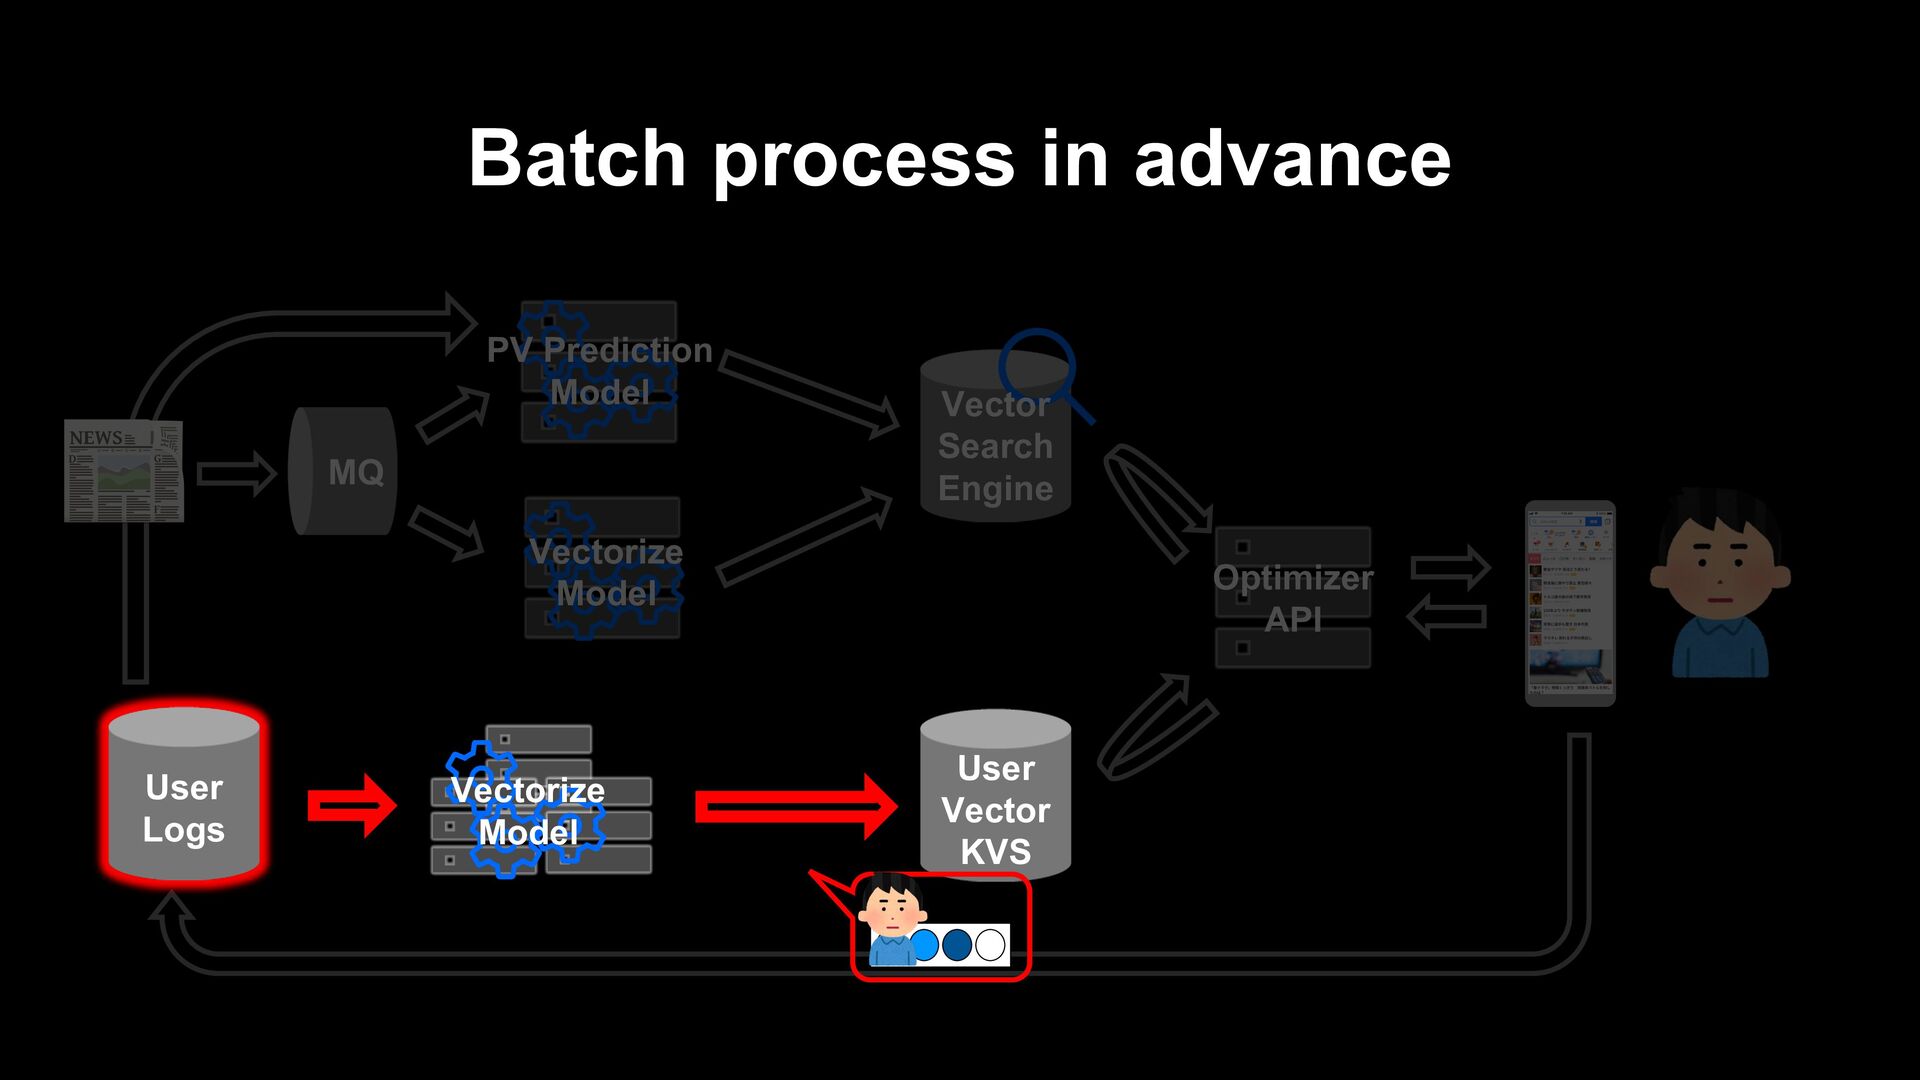
Batch process in advance MQ Vector Search Engine Optimizer API
Vectorize Model PV Prediction Model User Vector KVS User Logs Vectorize Model -
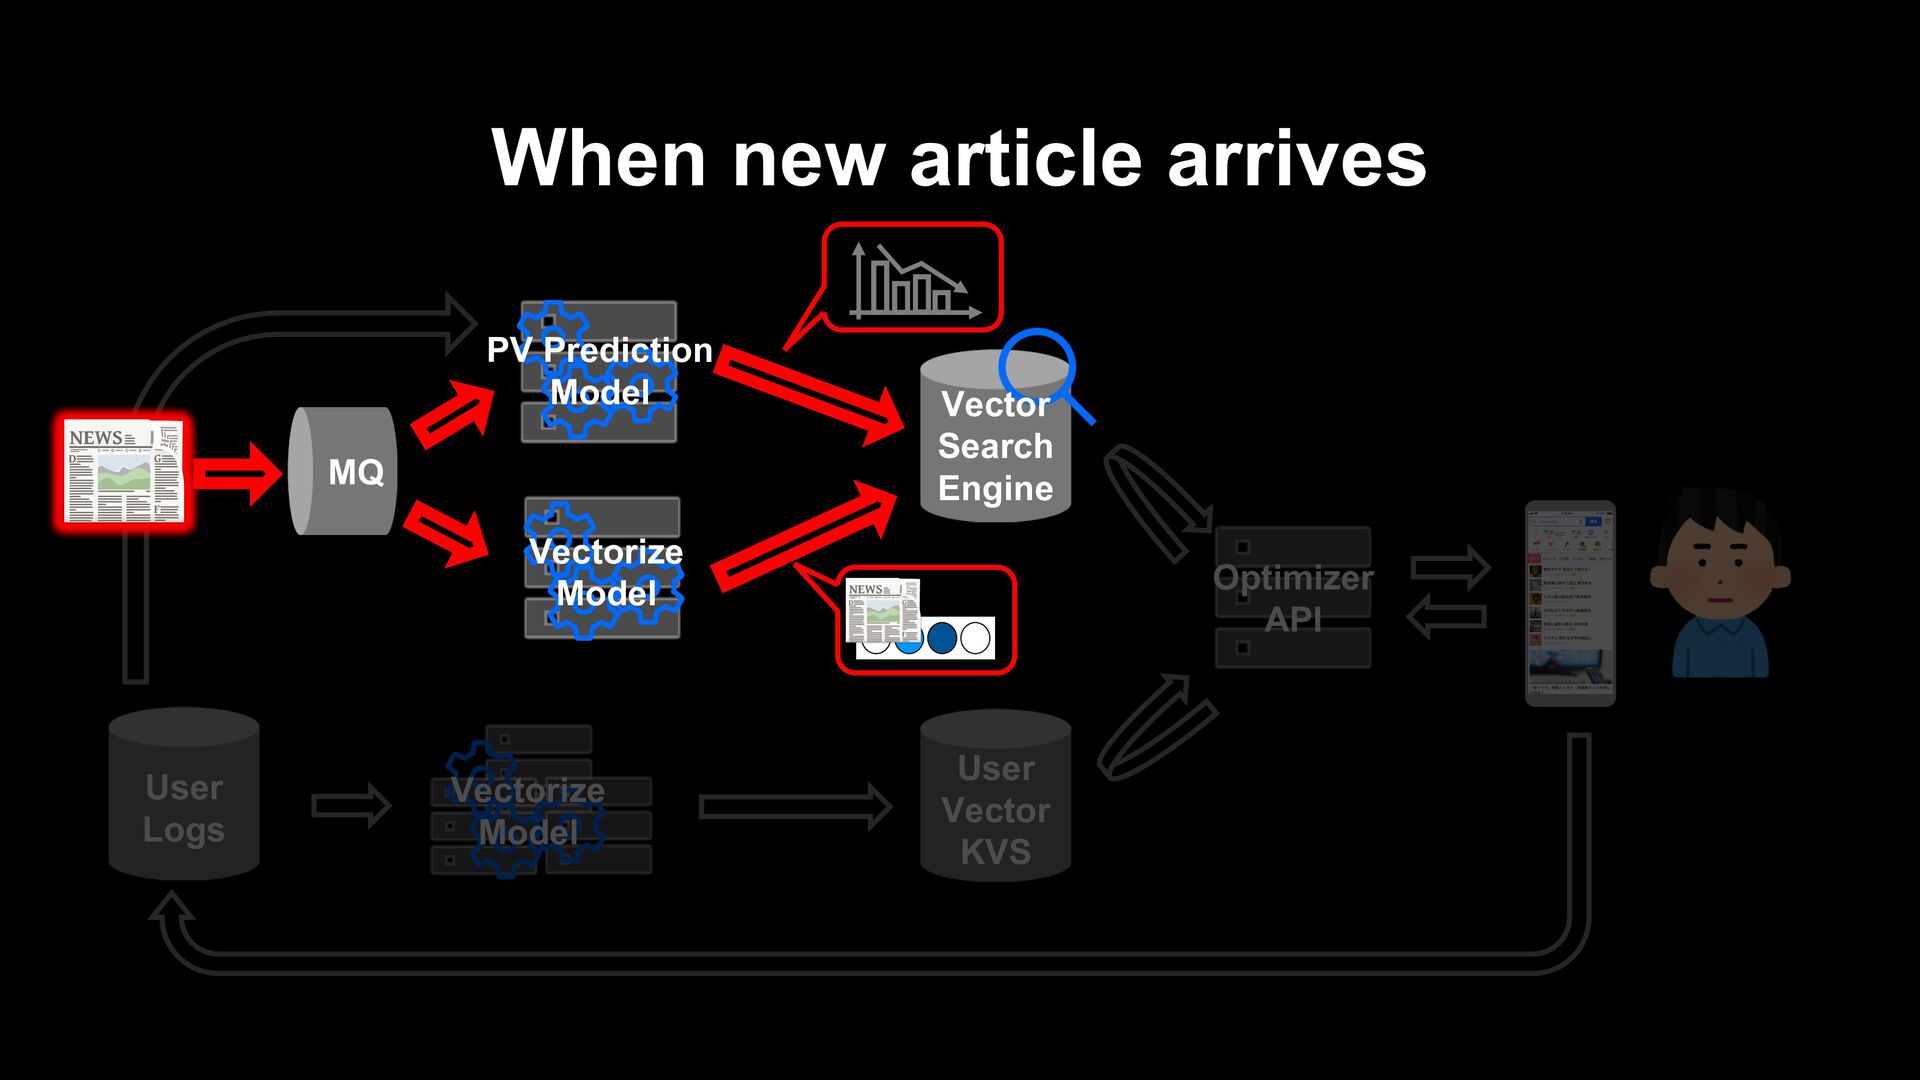
When new article arrives User Vector KVS Optimizer API User
Logs Vectorize Model MQ Vector Search Engine Vectorize Model PV Prediction Model -
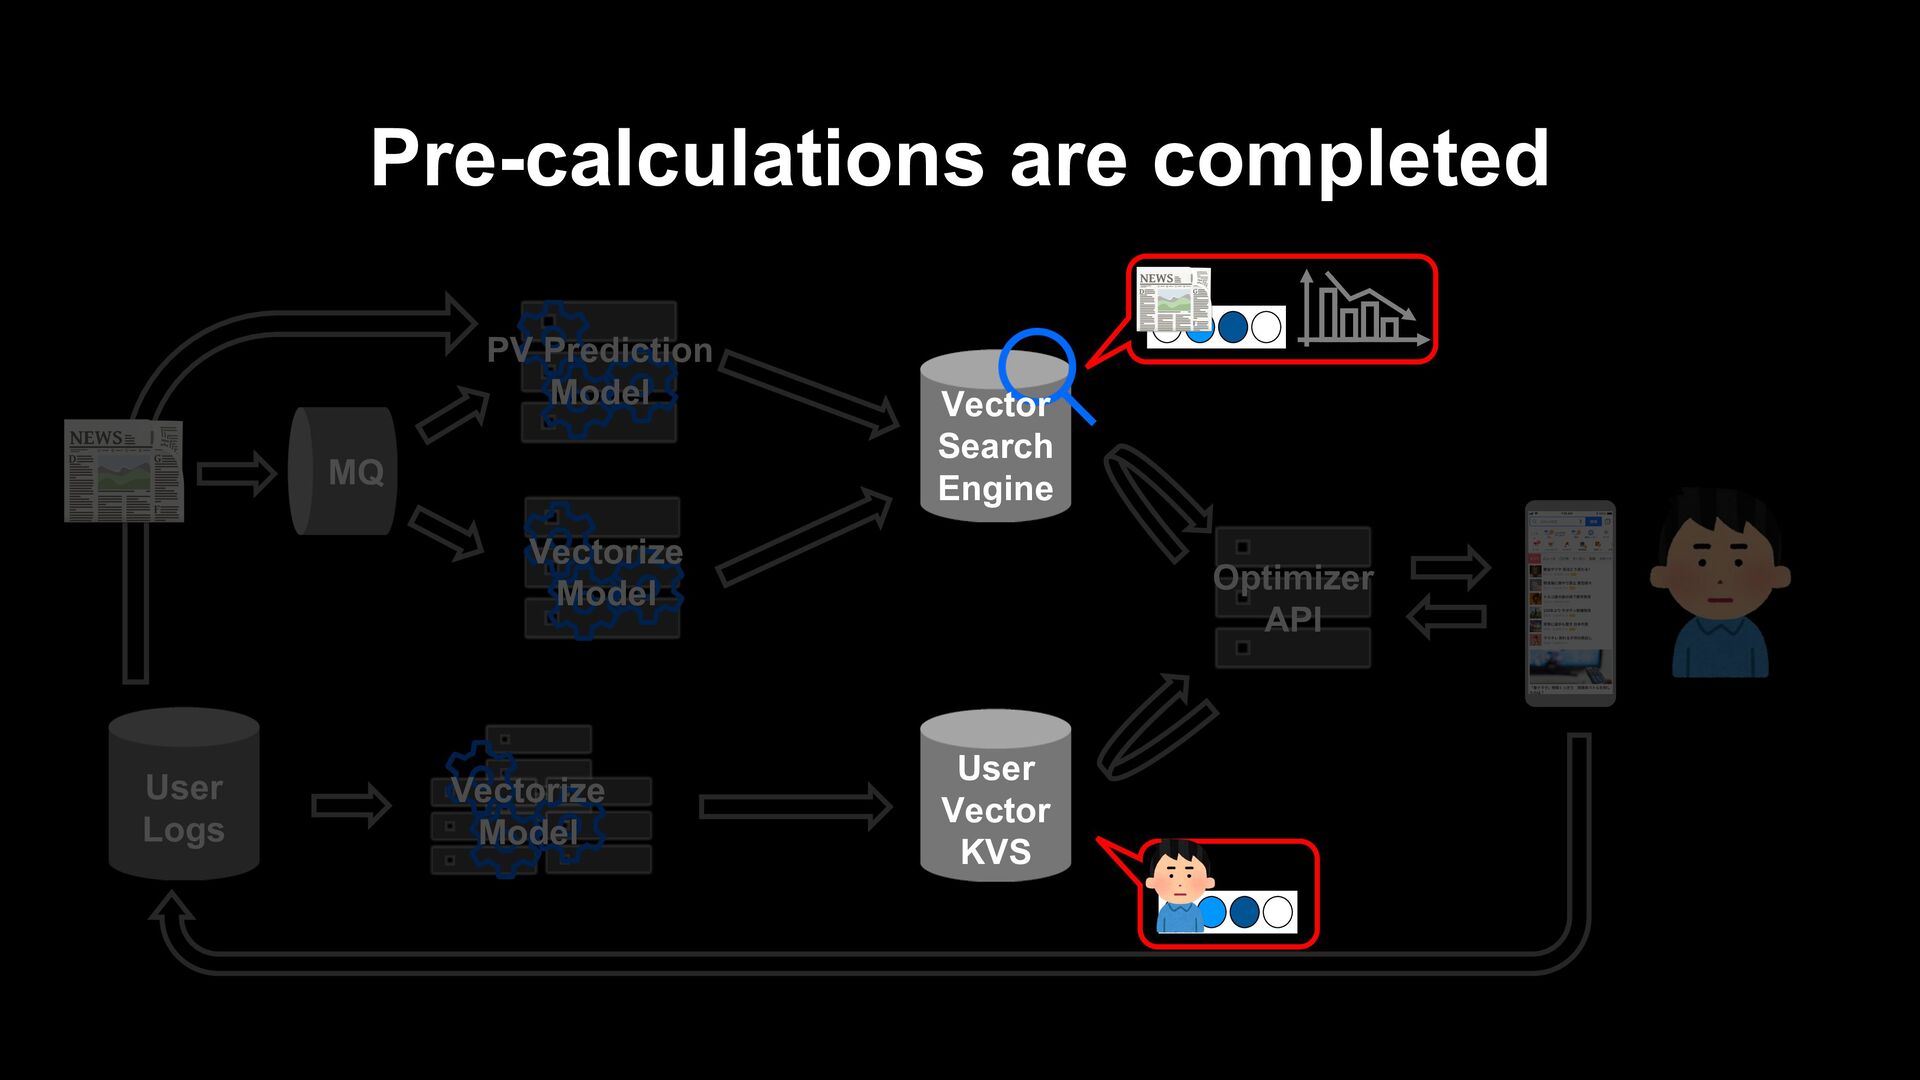
Pre-calculations are completed MQ Optimizer API User Logs Vectorize Model
PV Prediction Model Vectorize Model User Vector KVS Vector Search Engine -
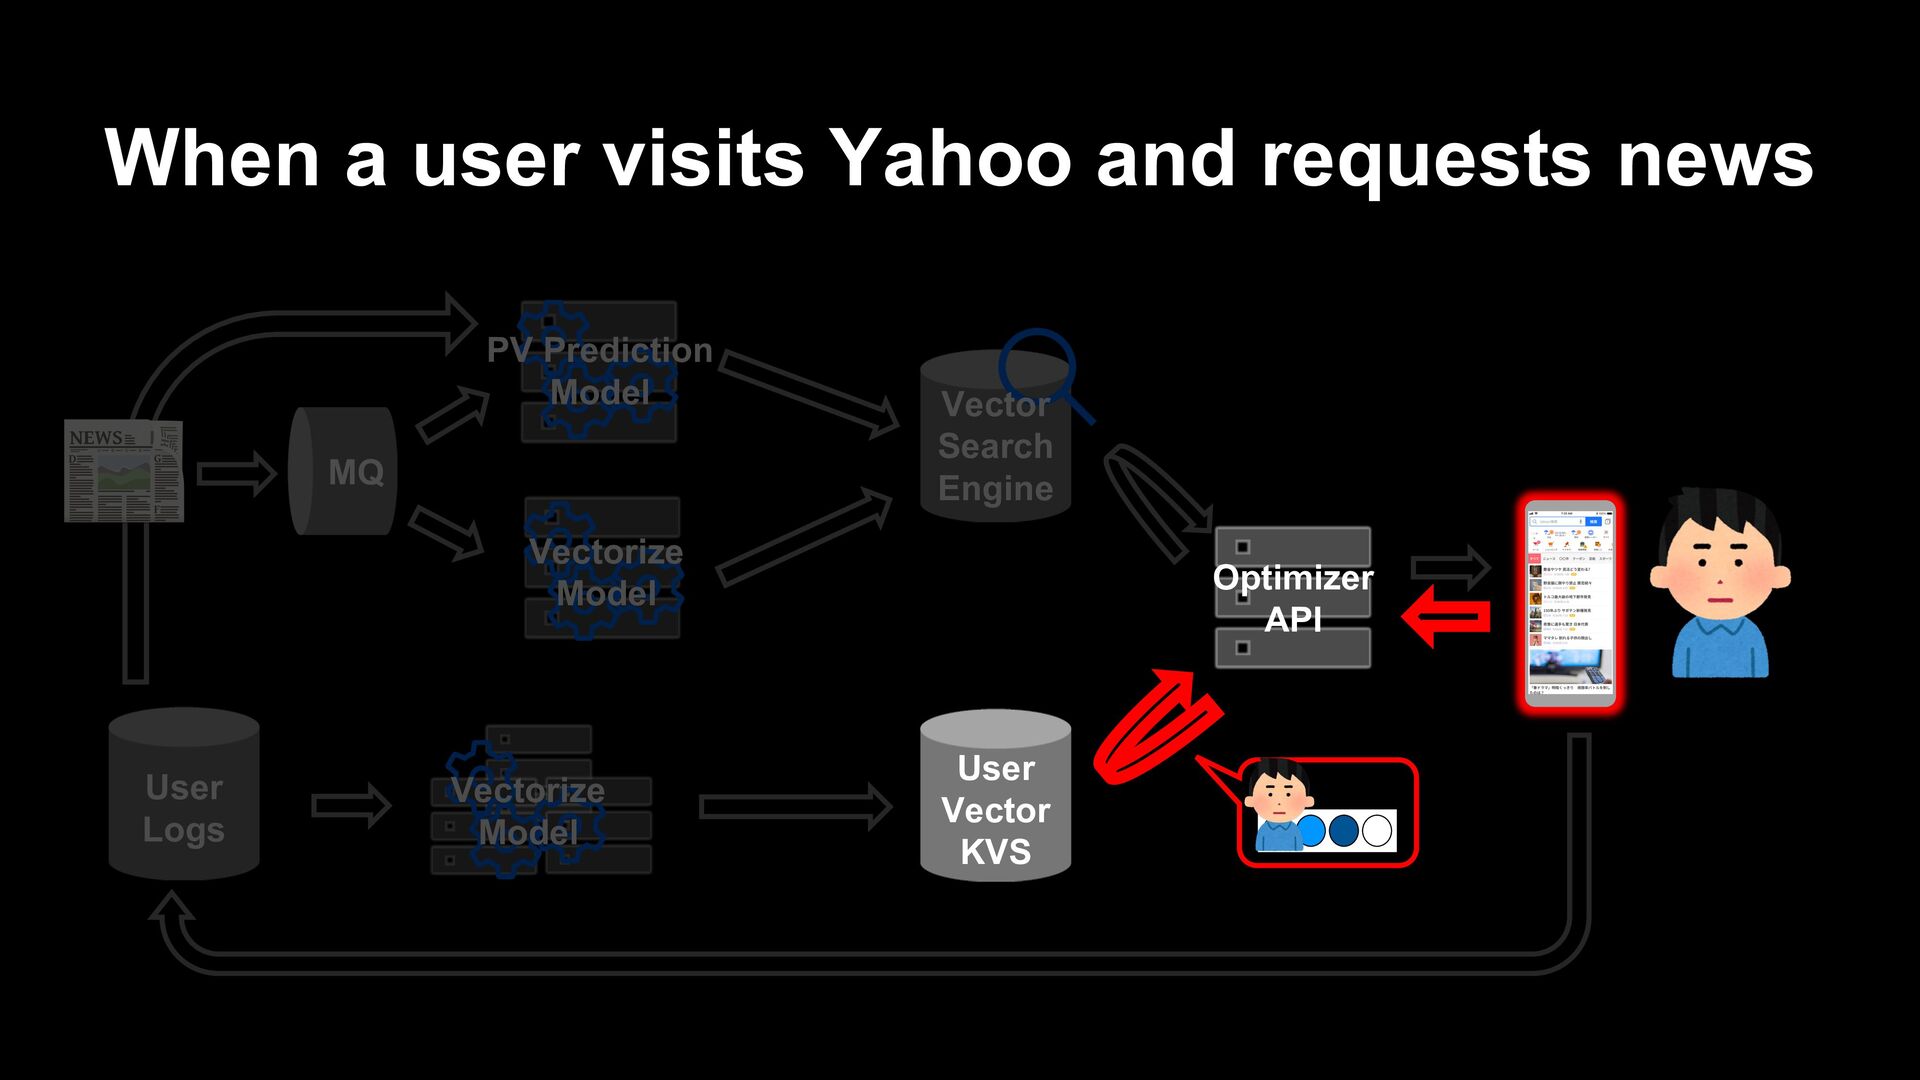
When a user visits Yahoo and requests news MQ Vector
Search Engine User Logs Vectorize Model PV Prediction Model Vectorize Model User Vector KVS Optimizer API -
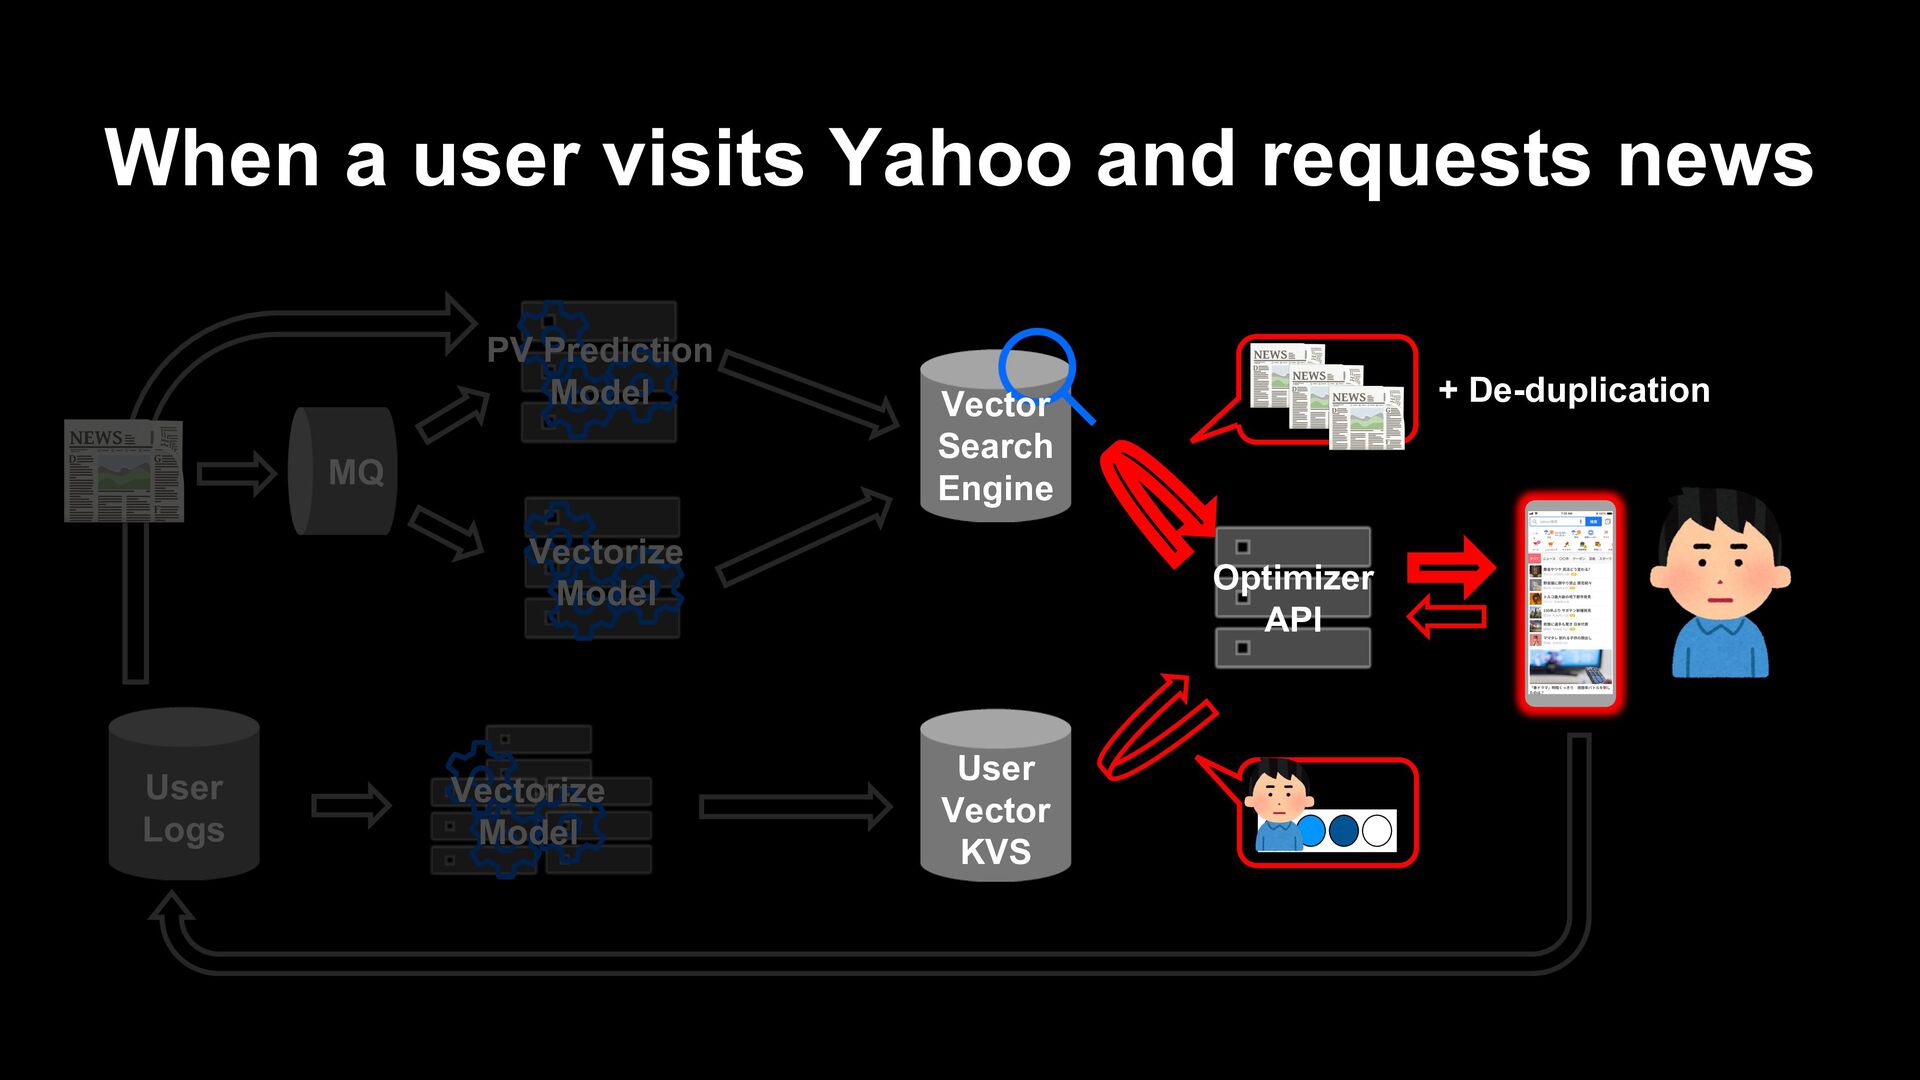
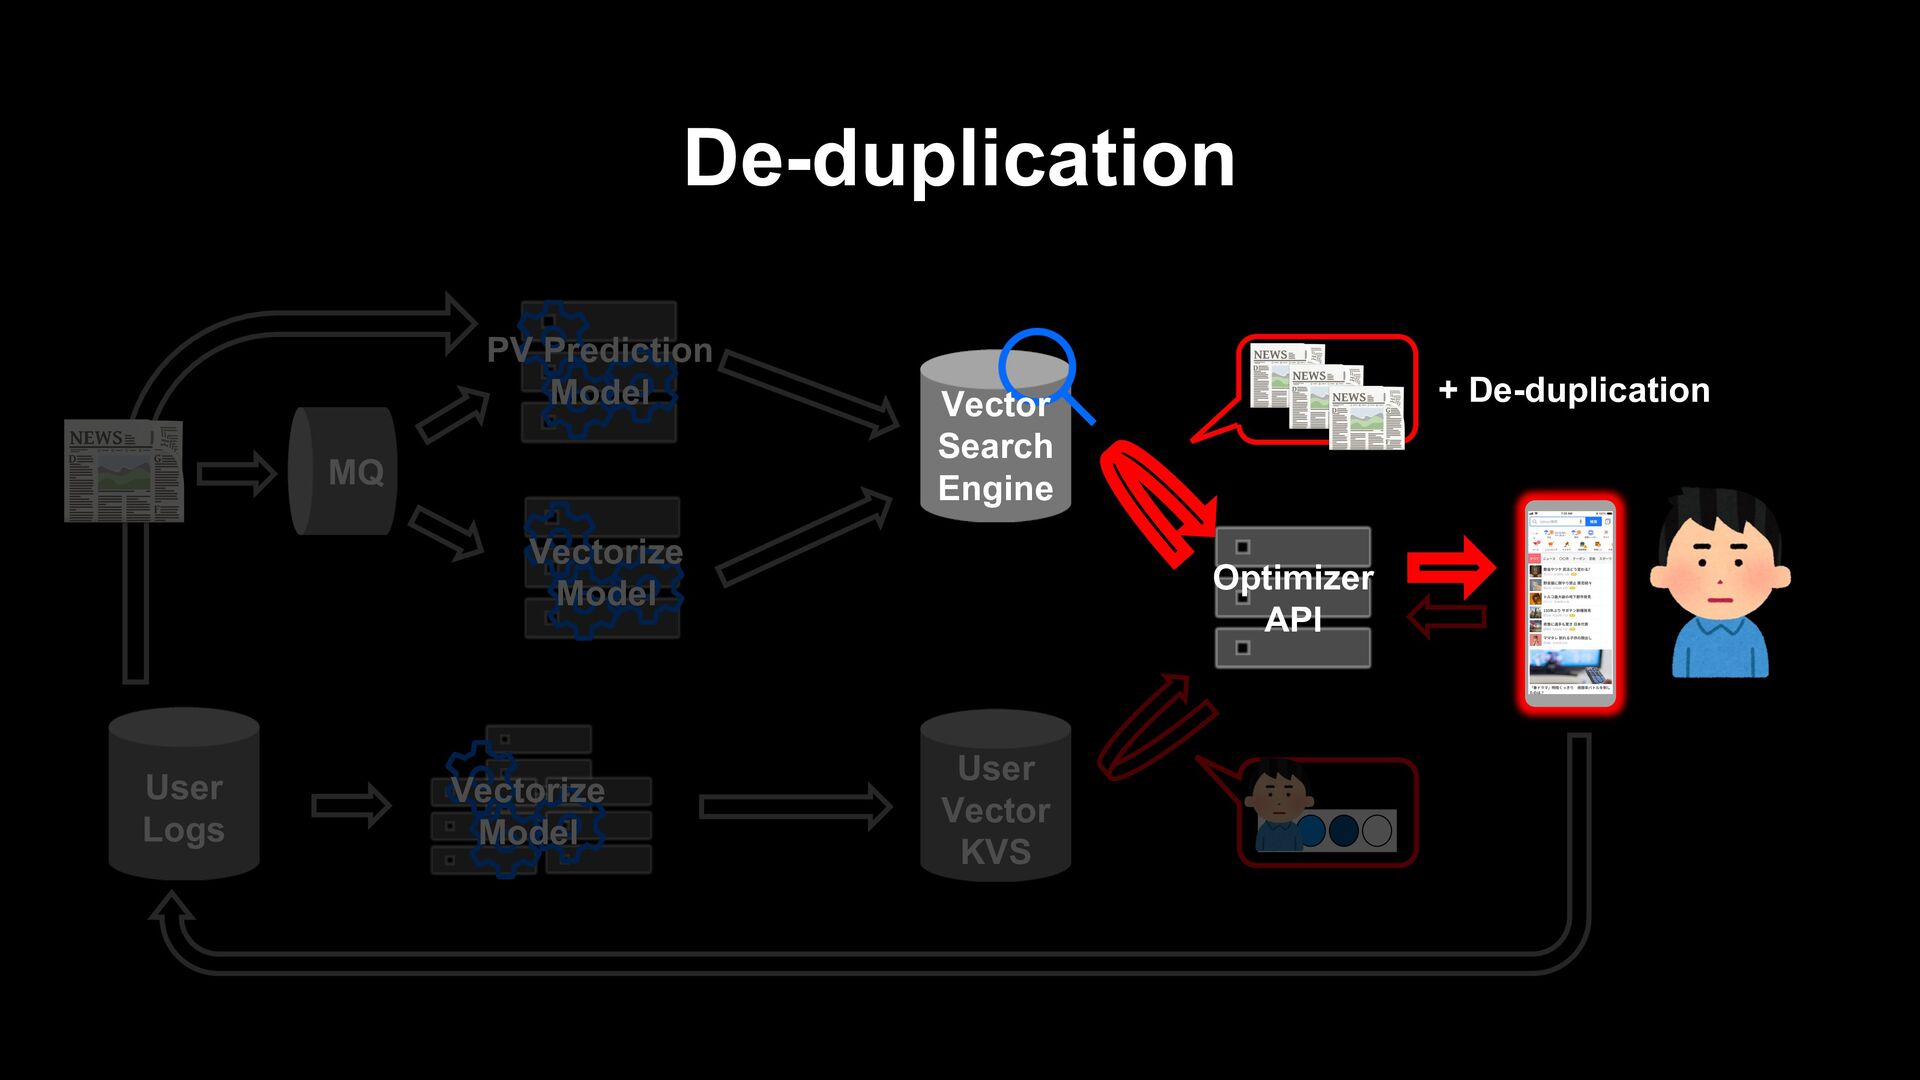
When a user visits Yahoo and requests news MQ User
Logs Vectorize Model PV Prediction Model Vectorize Model Vector Search Engine User Vector KVS Optimizer API + De-duplication -
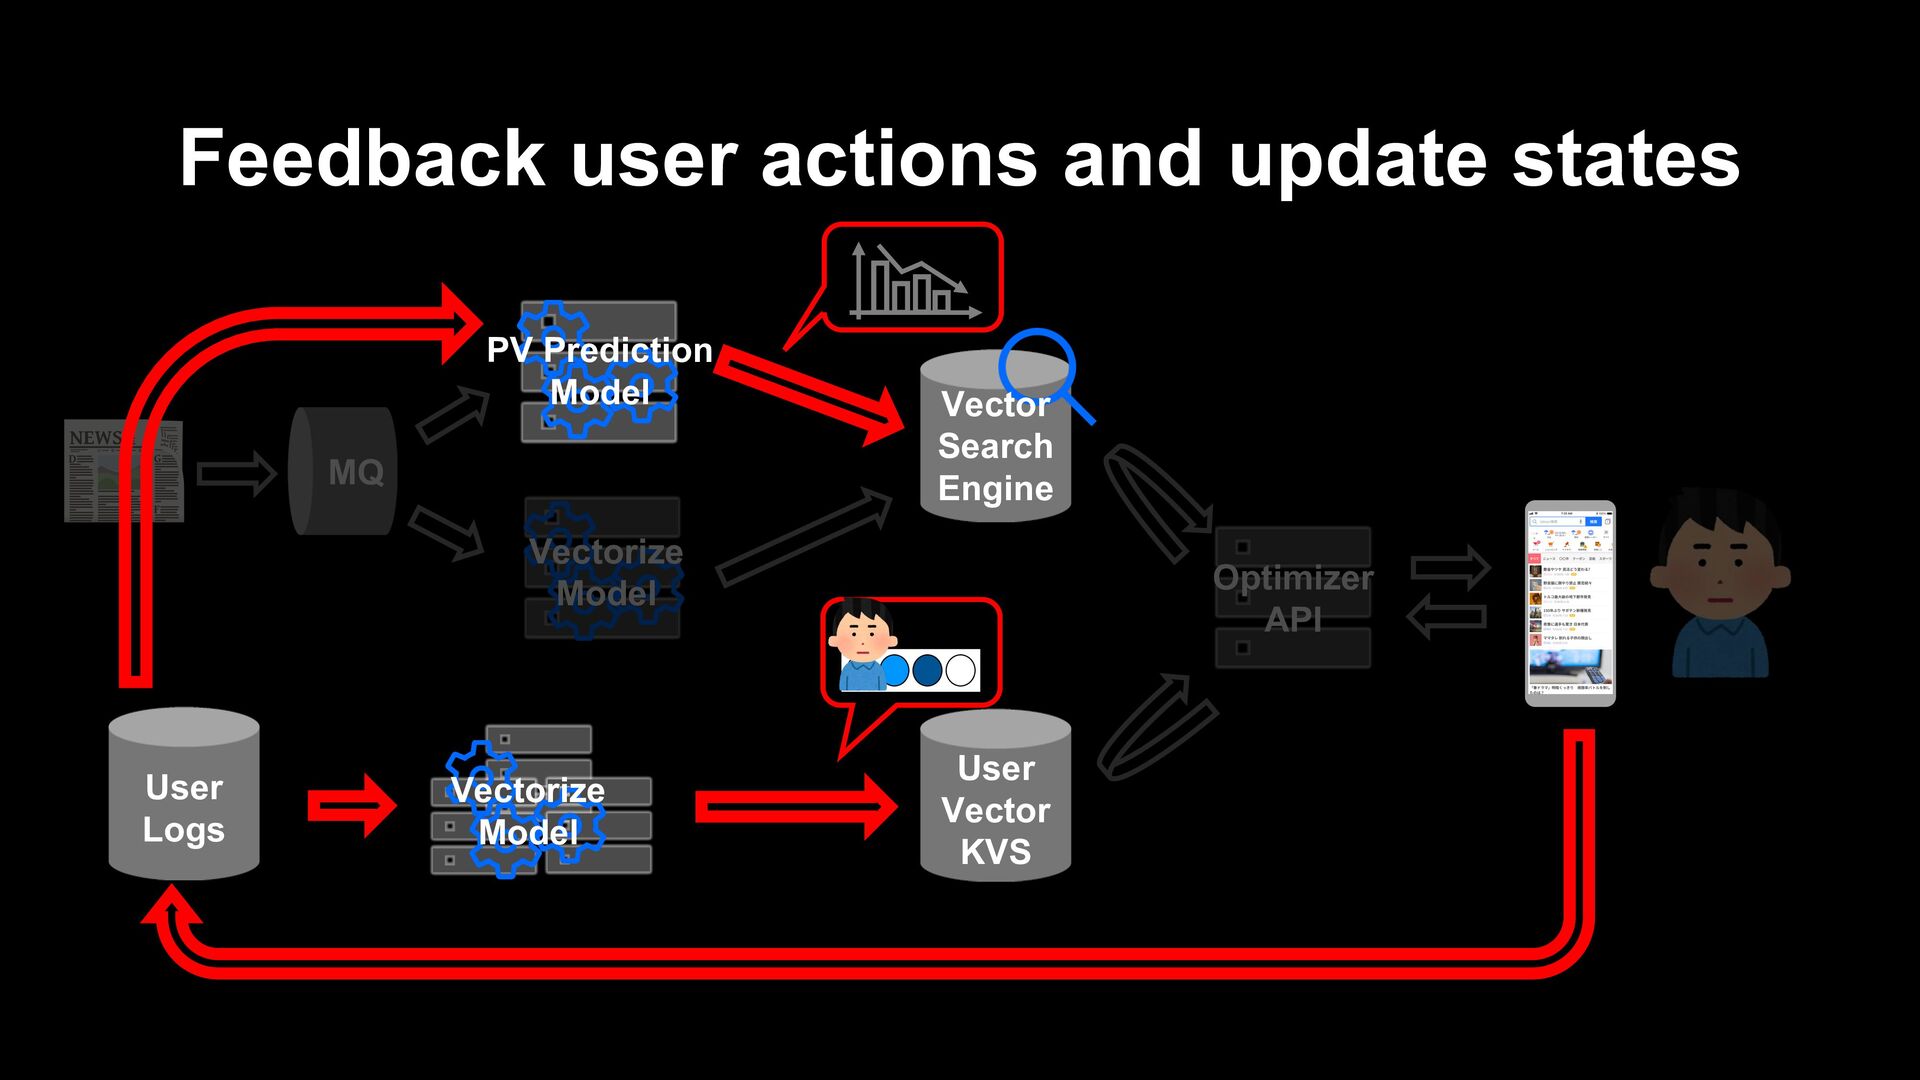
Feedback user actions and update states MQ Optimizer API Vectorize
Model Vector Search Engine User Vector KVS User Logs PV Prediction Model Vectorize Model -
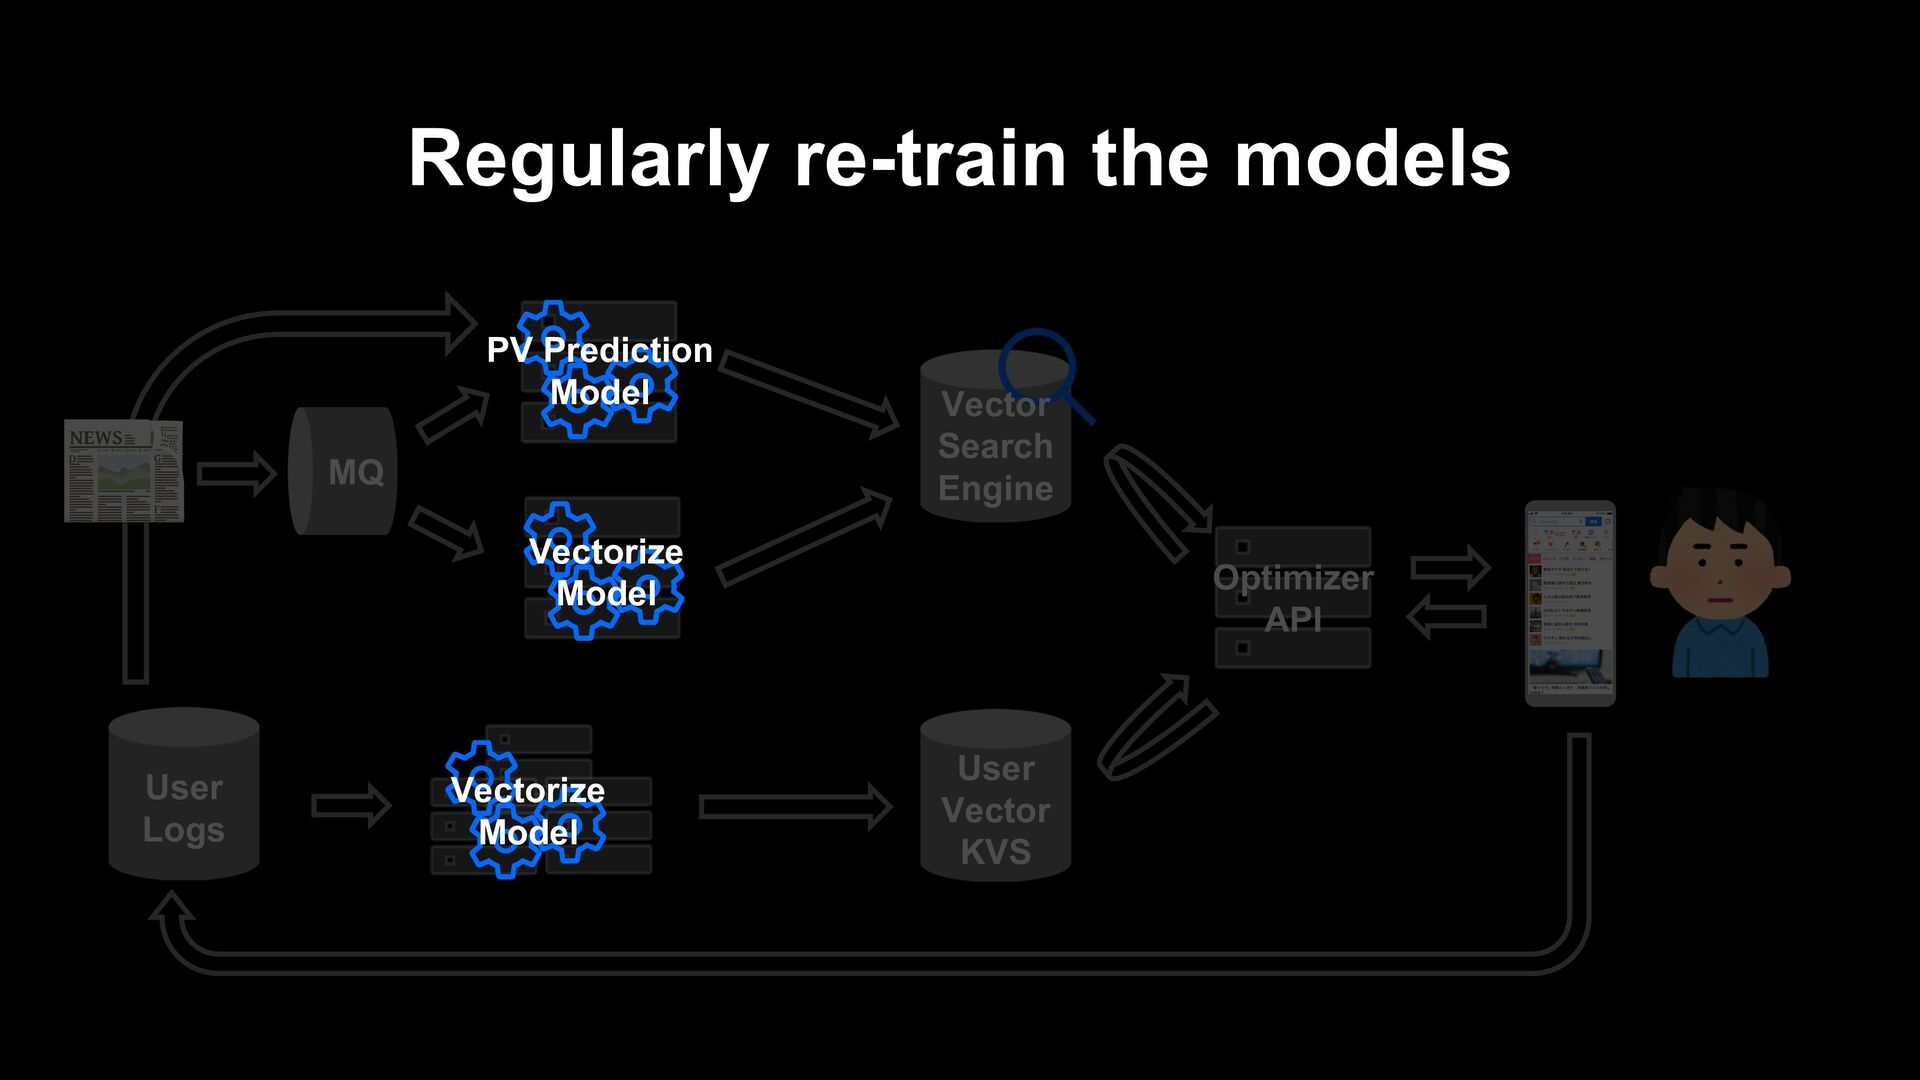
Regularly re-train the models MQ Vector Search Engine User Vector
KVS Optimizer API User Logs Vectorize Model PV Prediction Model Vectorize Model -
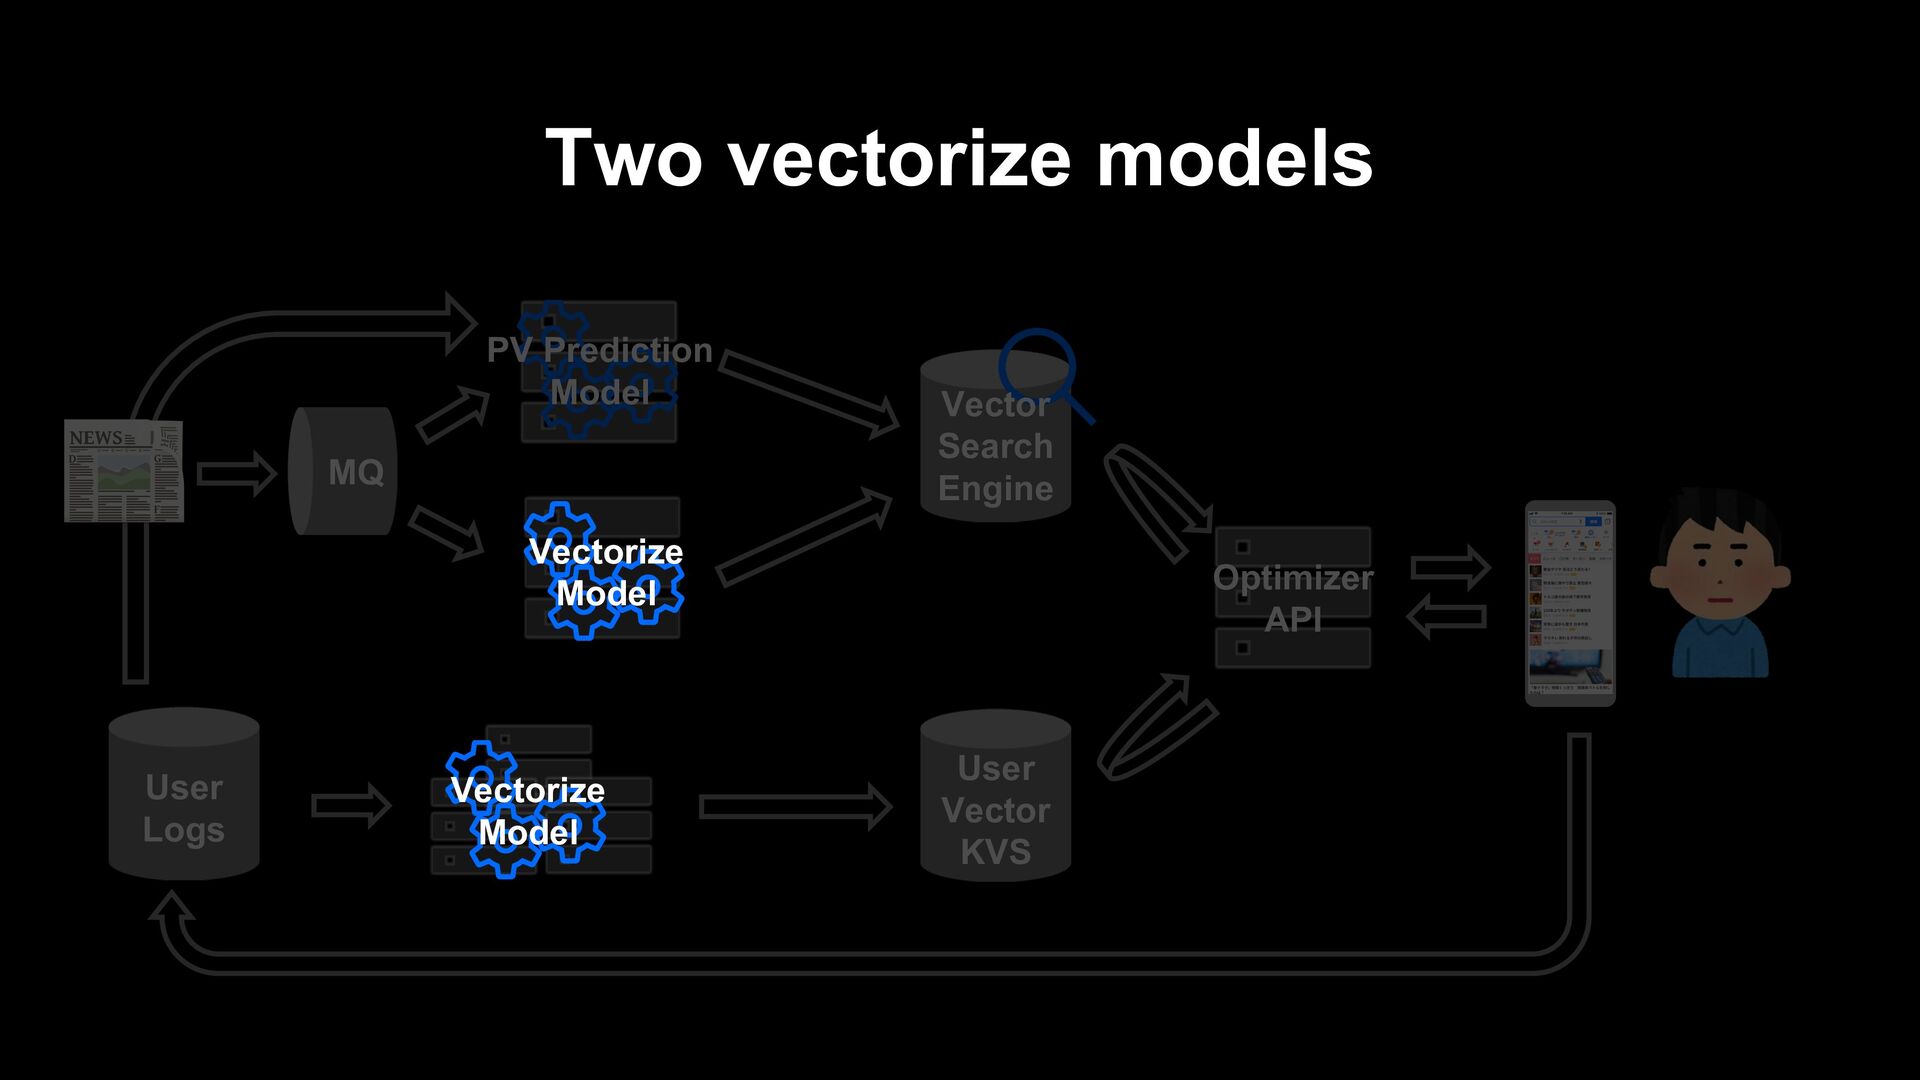
Two vectorize models MQ Vector Search Engine User Vector KVS
Optimizer API User Logs PV Prediction Model Vectorize Model Vectorize Model -
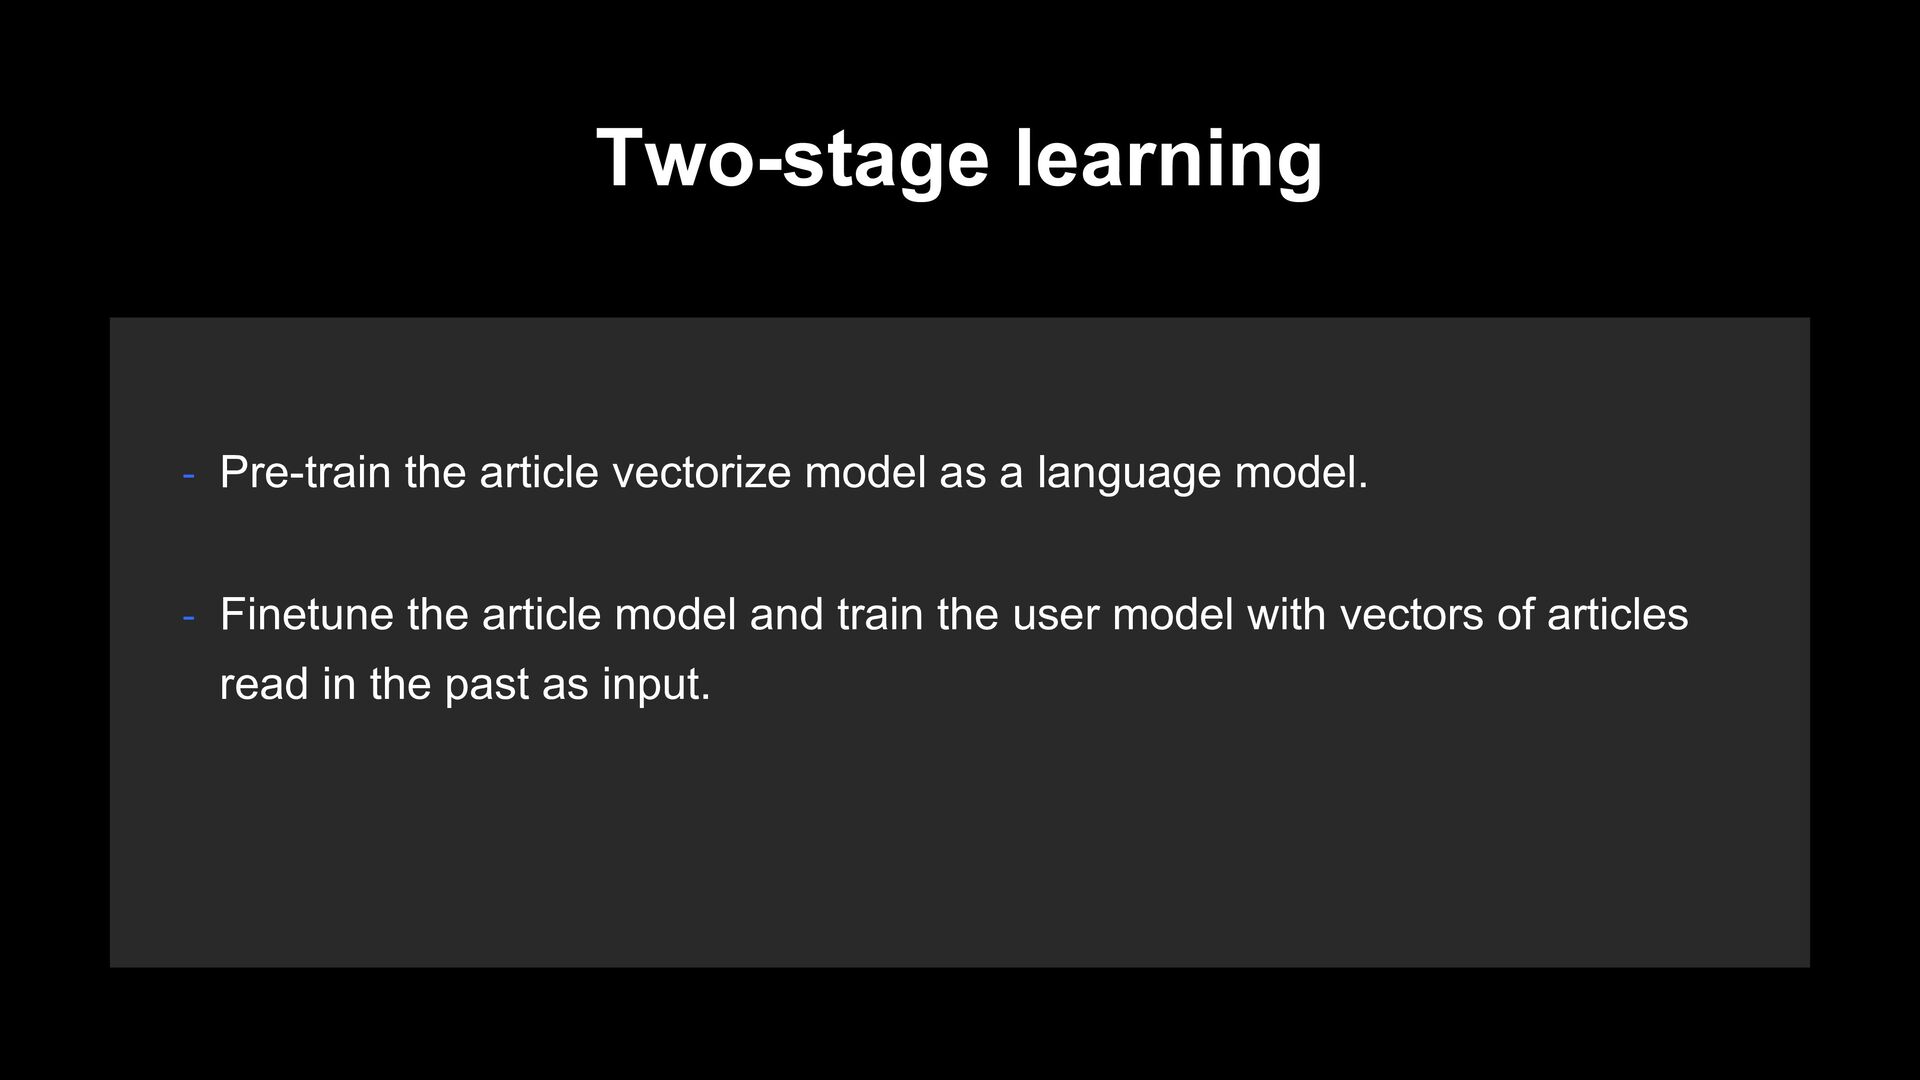
Two-stage learning - Finetune the article model and train the
user model with vectors of articles read in the past as input. - Pre-train the article vectorize model as a language model. -
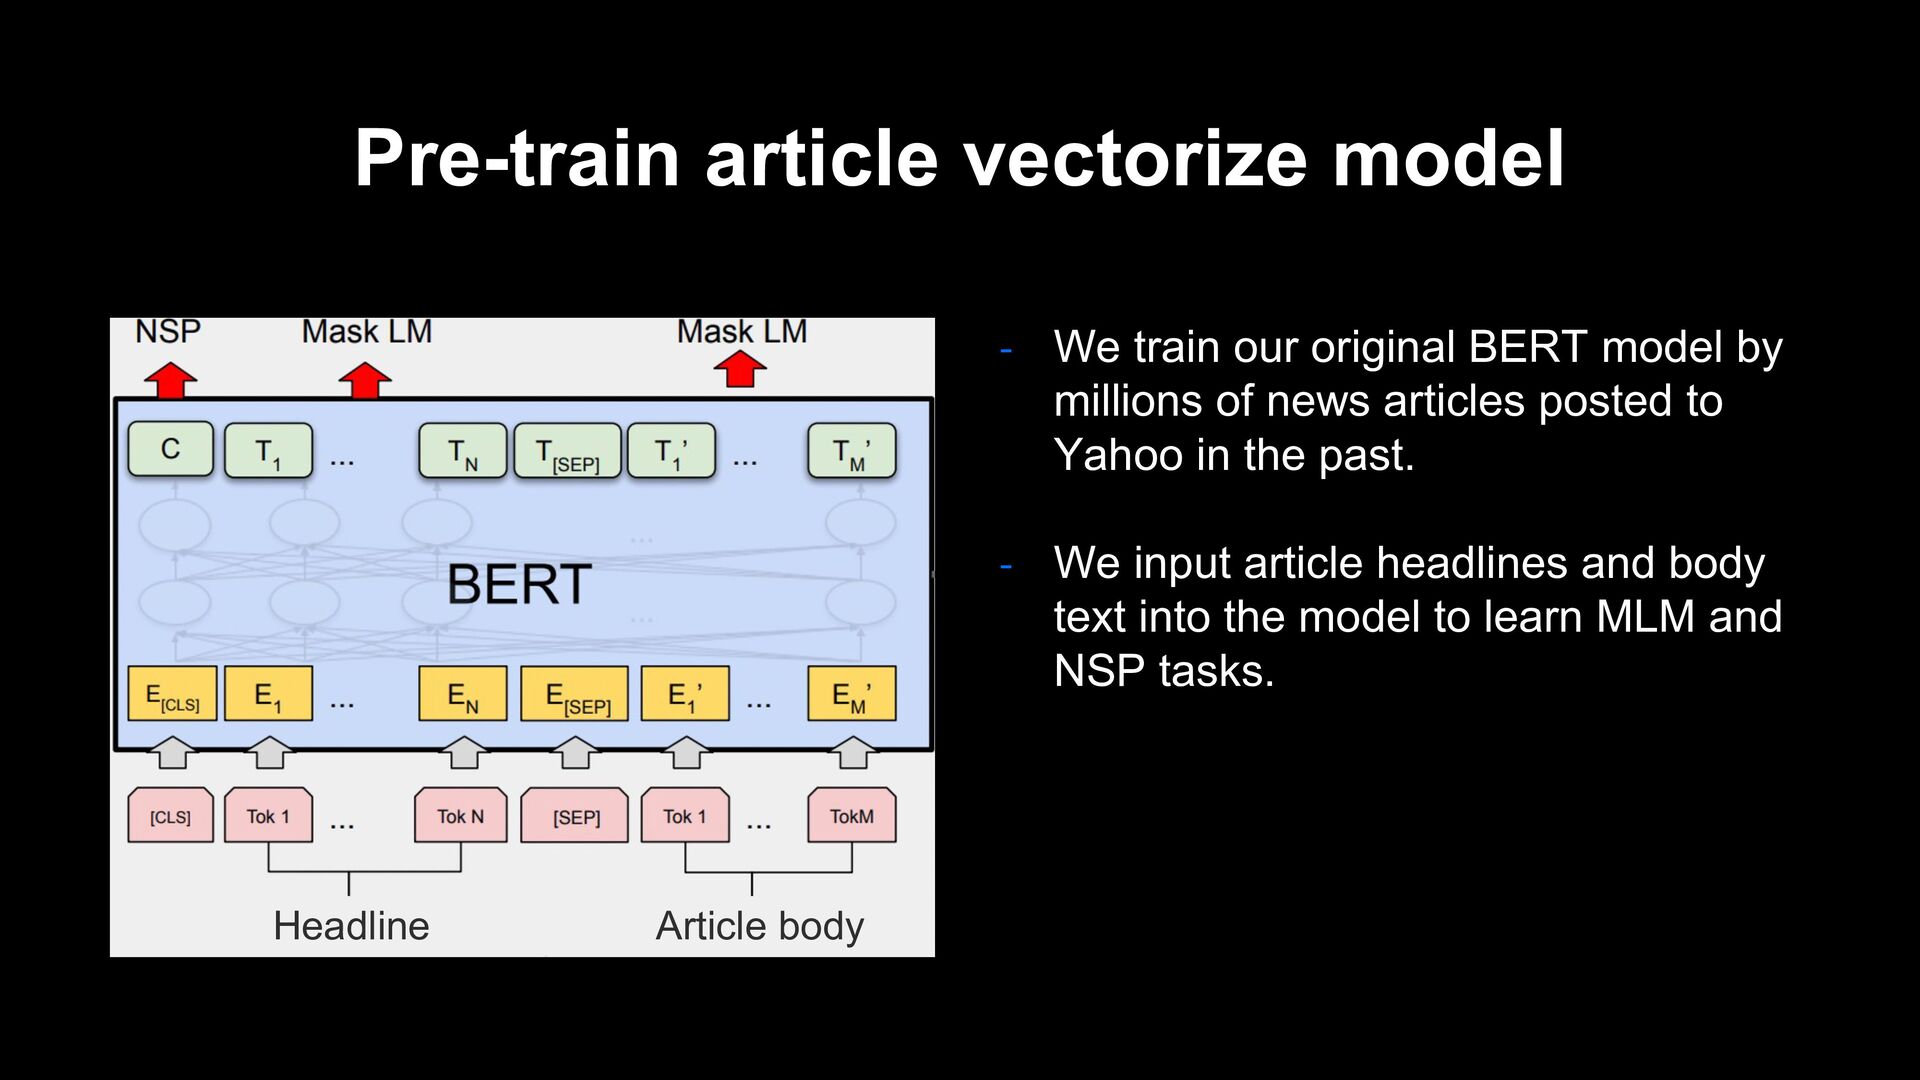
Pre-train article vectorize model - We train our original BERT
model by millions of news articles posted to Yahoo in the past. - We input article headlines and body text into the model to learn MLM and NSP tasks. Headline Article body -
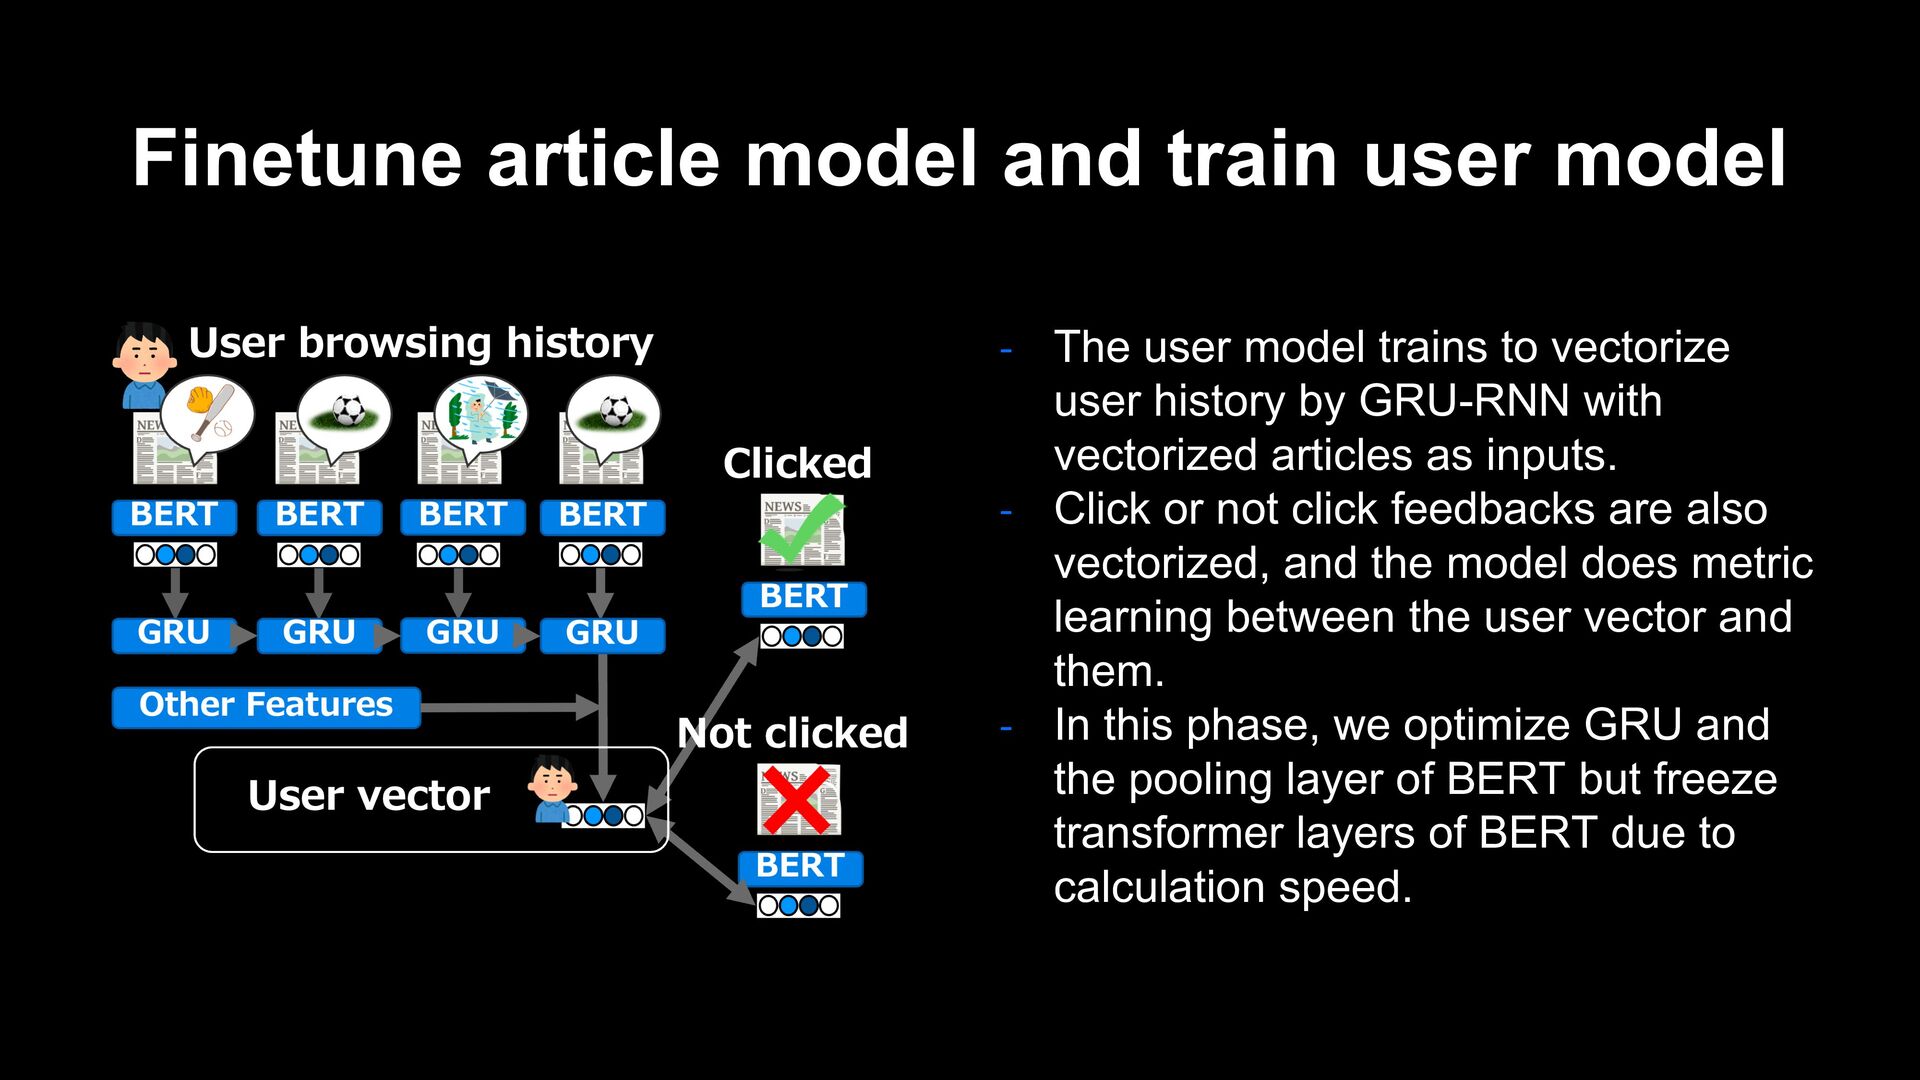
Finetune article model and train user model - The user
model trains to vectorize user history by GRU-RNN with vectorized articles as inputs. - Click or not click feedbacks are also vectorized, and the model does metric learning between the user vector and them. - In this phase, we optimize GRU and the pooling layer of BERT but freeze transformer layers of BERT due to calculation speed. -
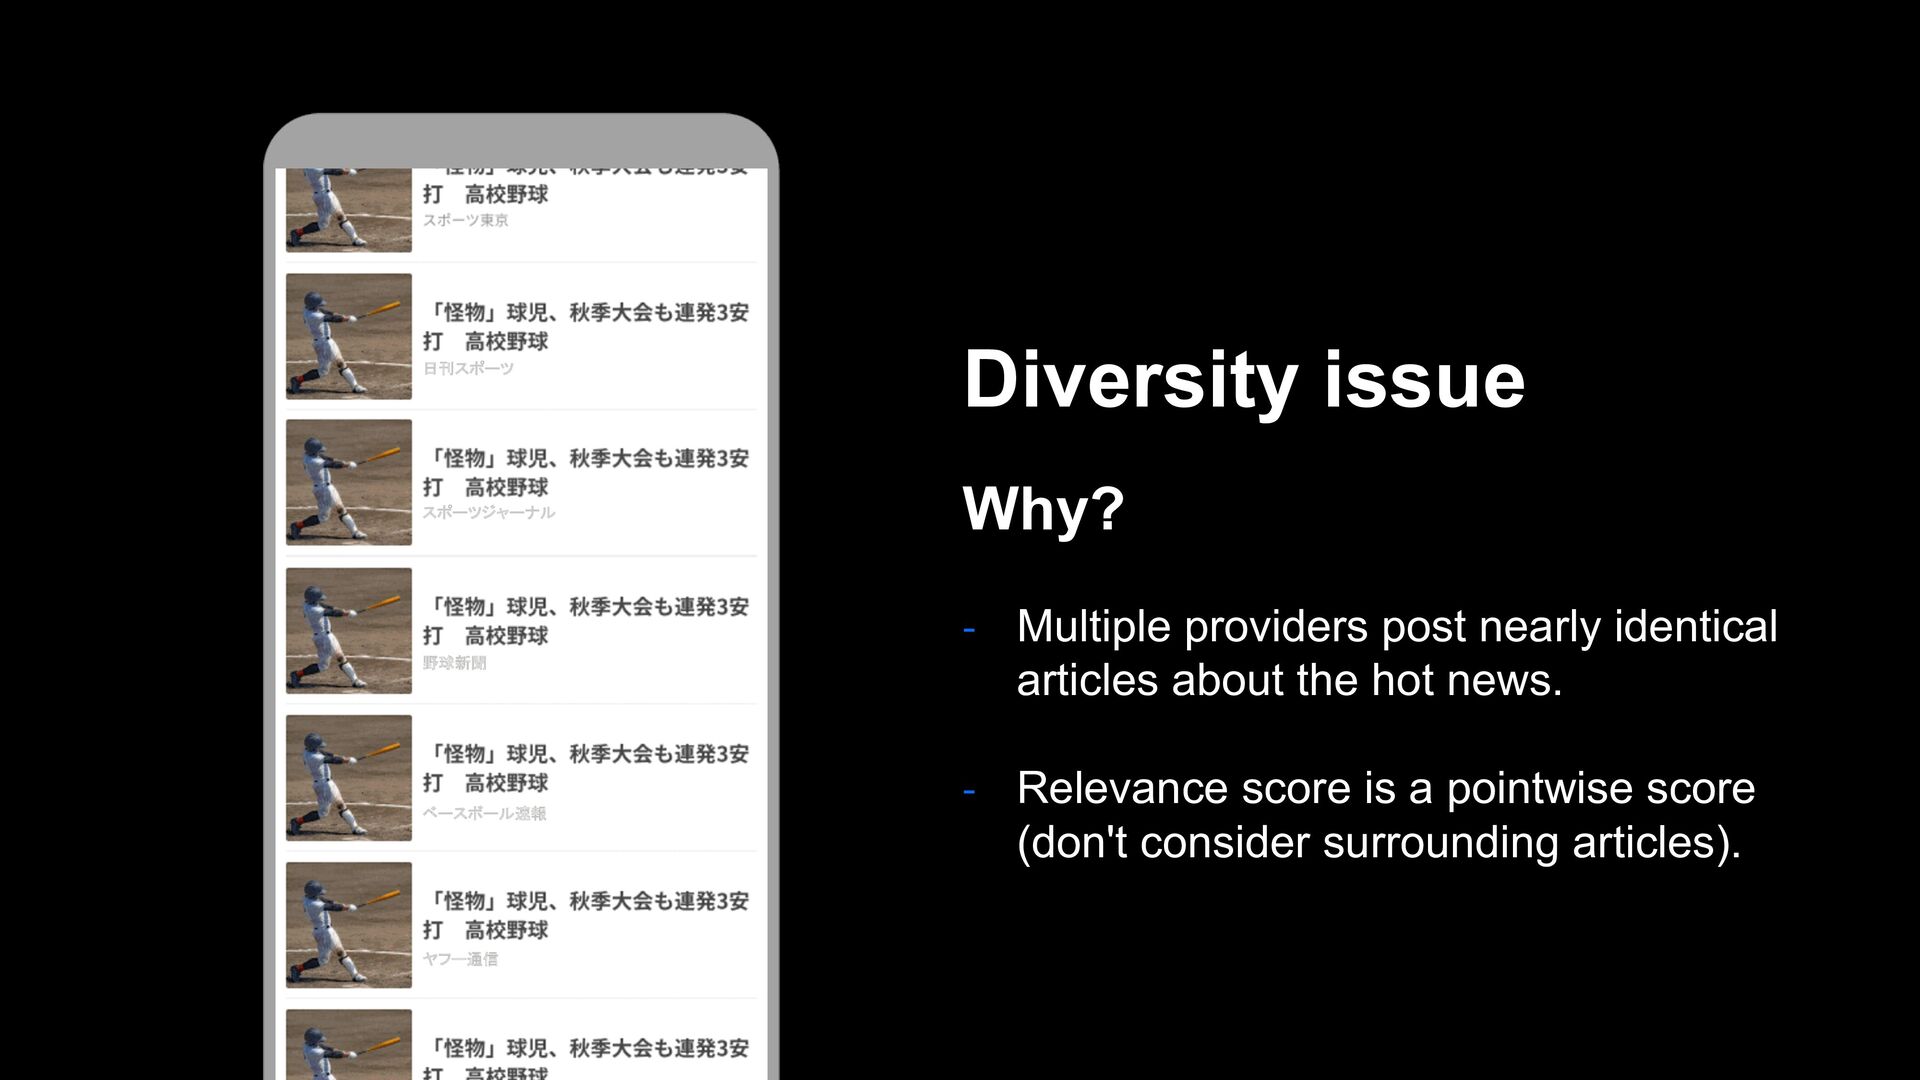
Why? - Multiple providers post nearly identical articles about the
hot news. - Relevance score is a pointwise score (don't consider surrounding articles). Diversity issue 日刊スポーツ スポーツジャーナル 野球新聞 ベースボール速報 ヤフー通信 -
De-duplication MQ User Logs Vectorize Model PV Prediction Model Vectorize
Model User Vector KVS Vector Search Engine Optimizer API + De-duplication -
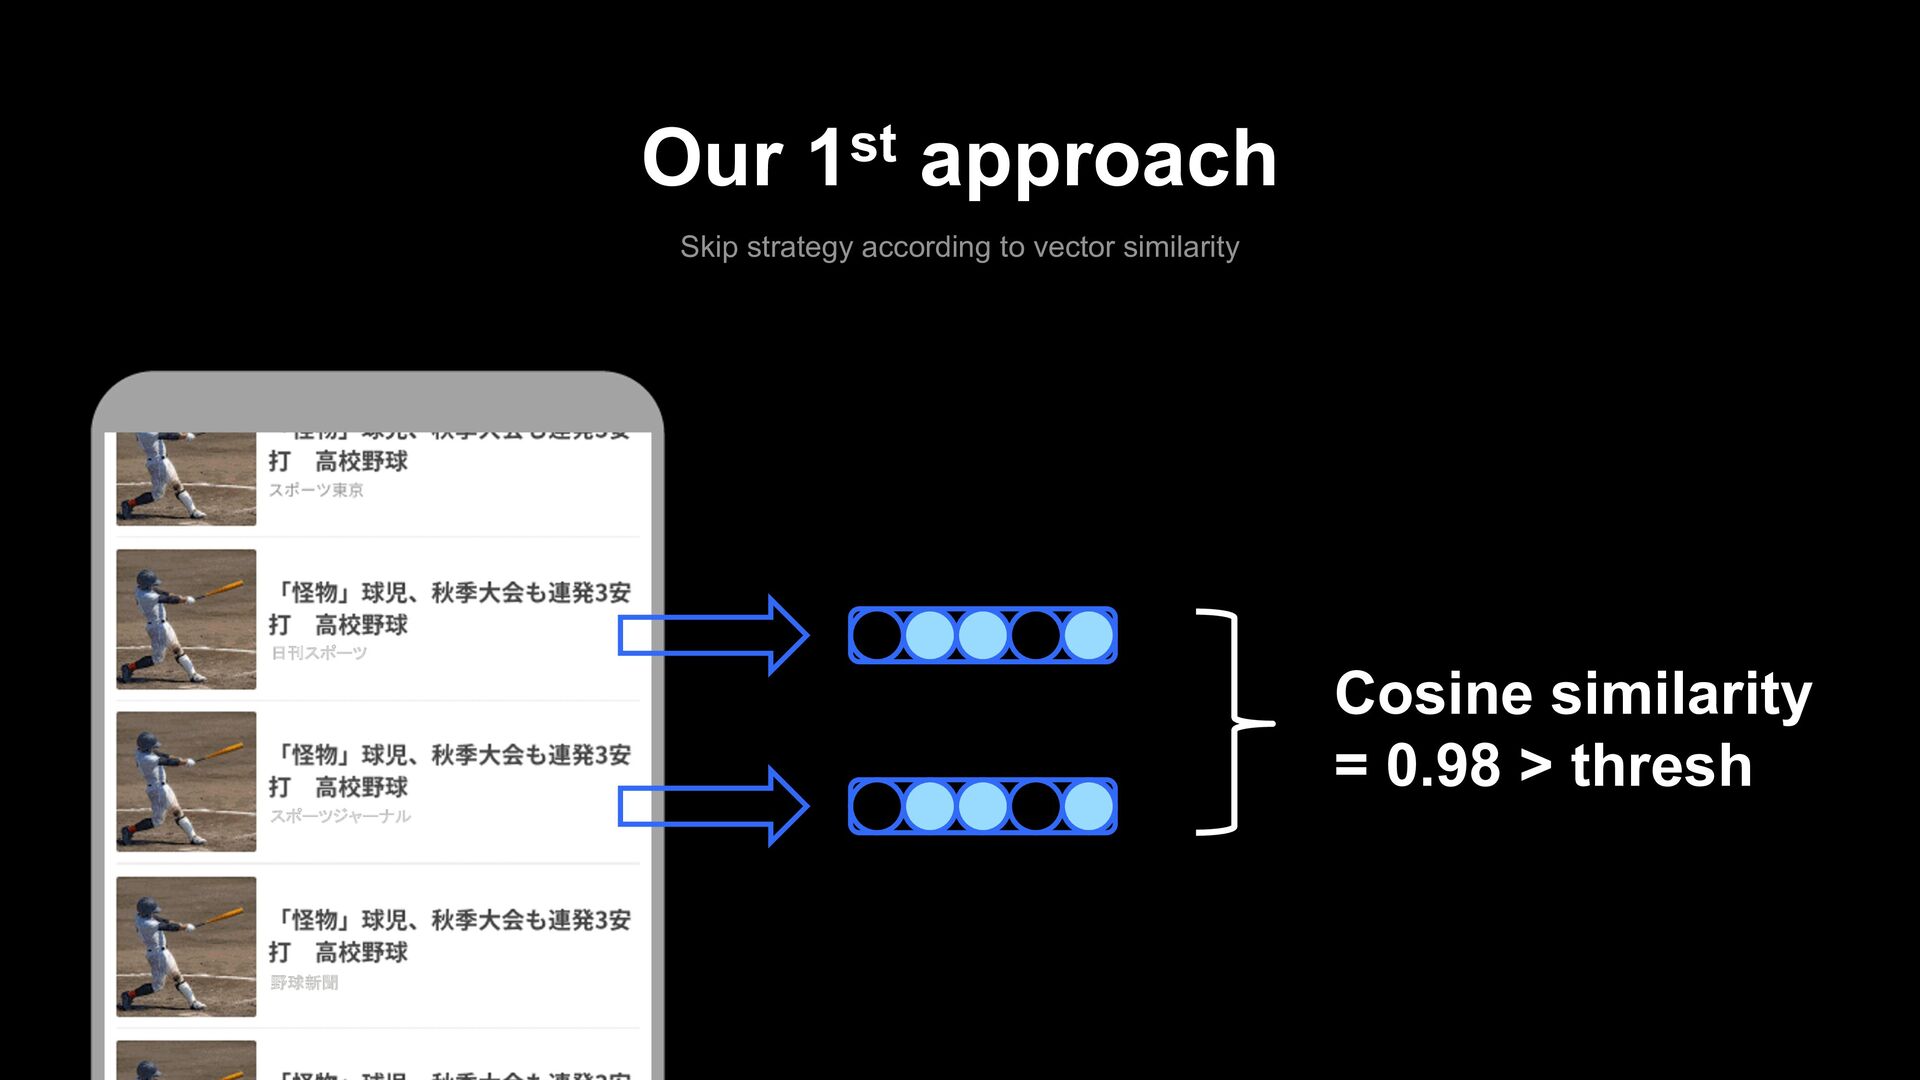
Our 1st approach Skip strategy according to vector similarity Cosine
similarity = 0.98 > thresh 日刊スポーツ スポーツジャーナル 野球新聞 -
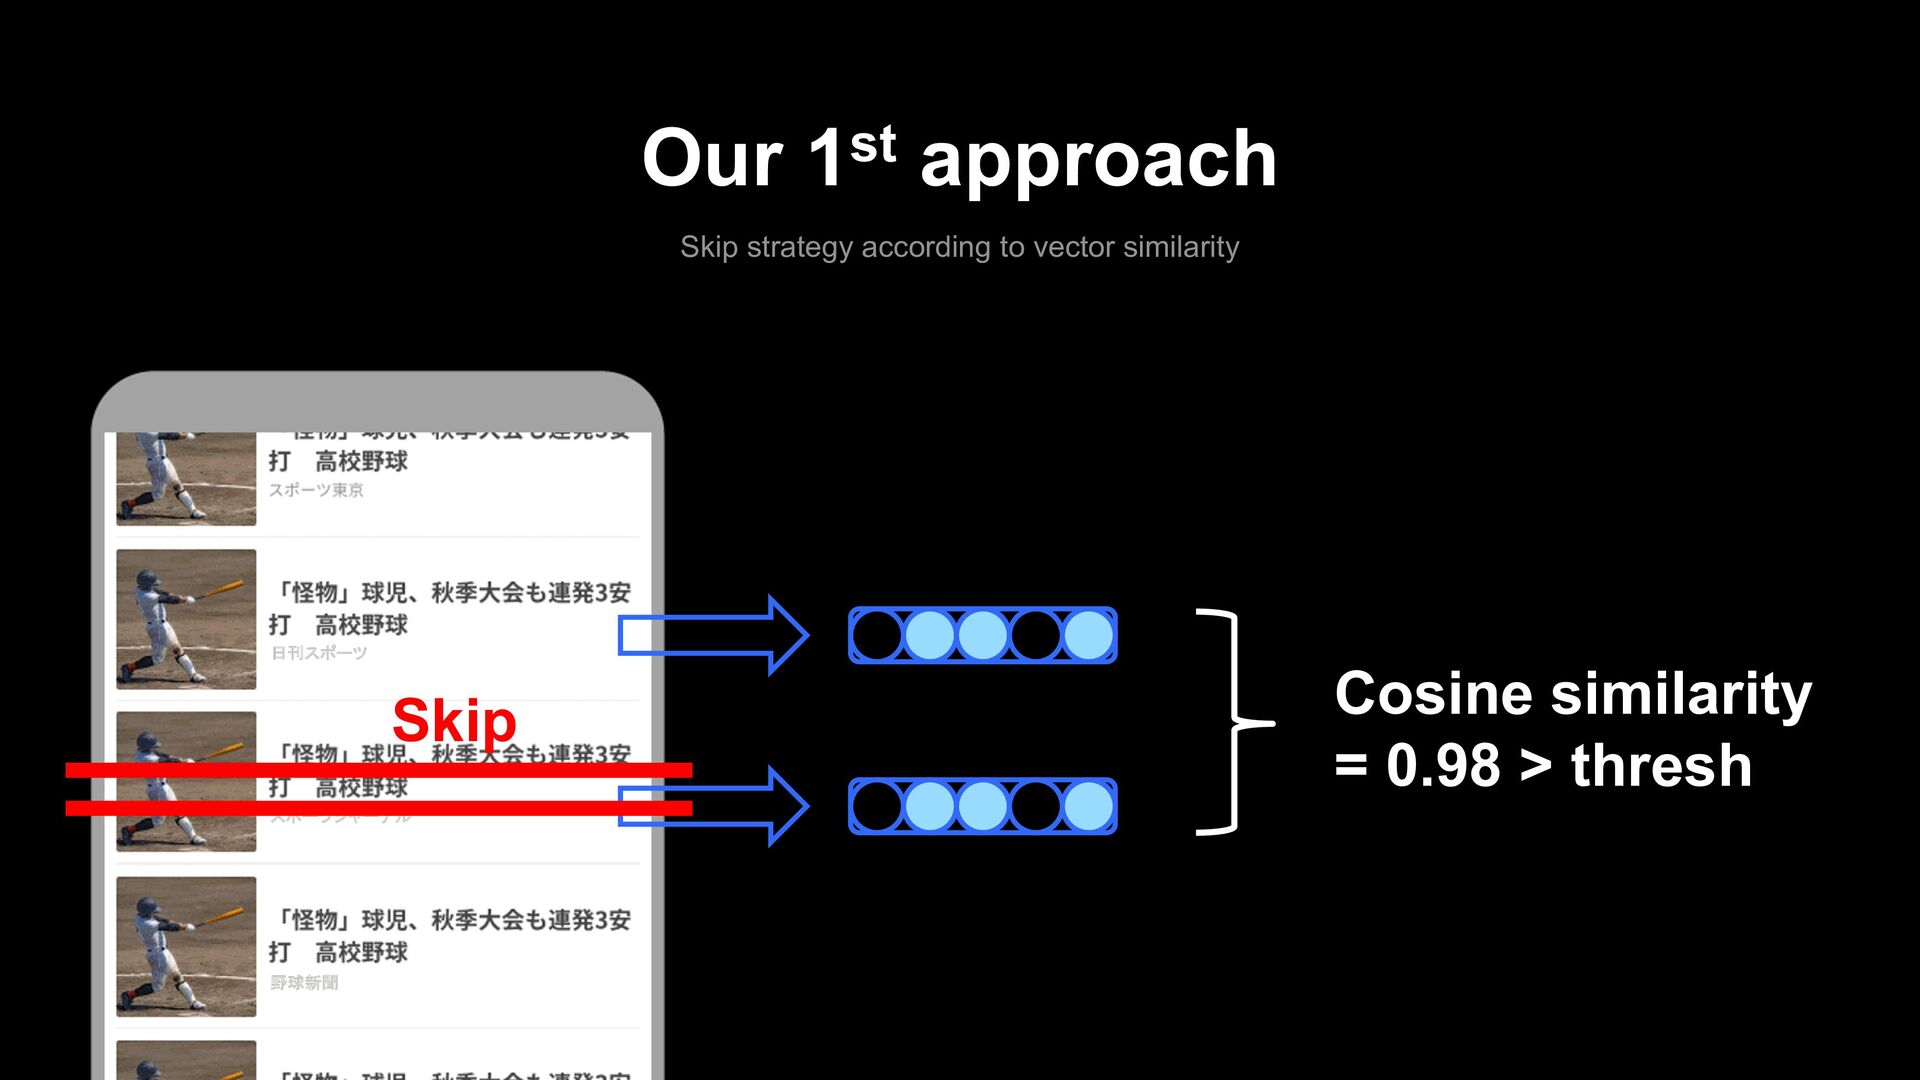
Our 1st approach Skip strategy according to vector similarity Cosine
similarity = 0.98 > thresh Skip 日刊スポーツ スポーツジャーナル 野球新聞 -
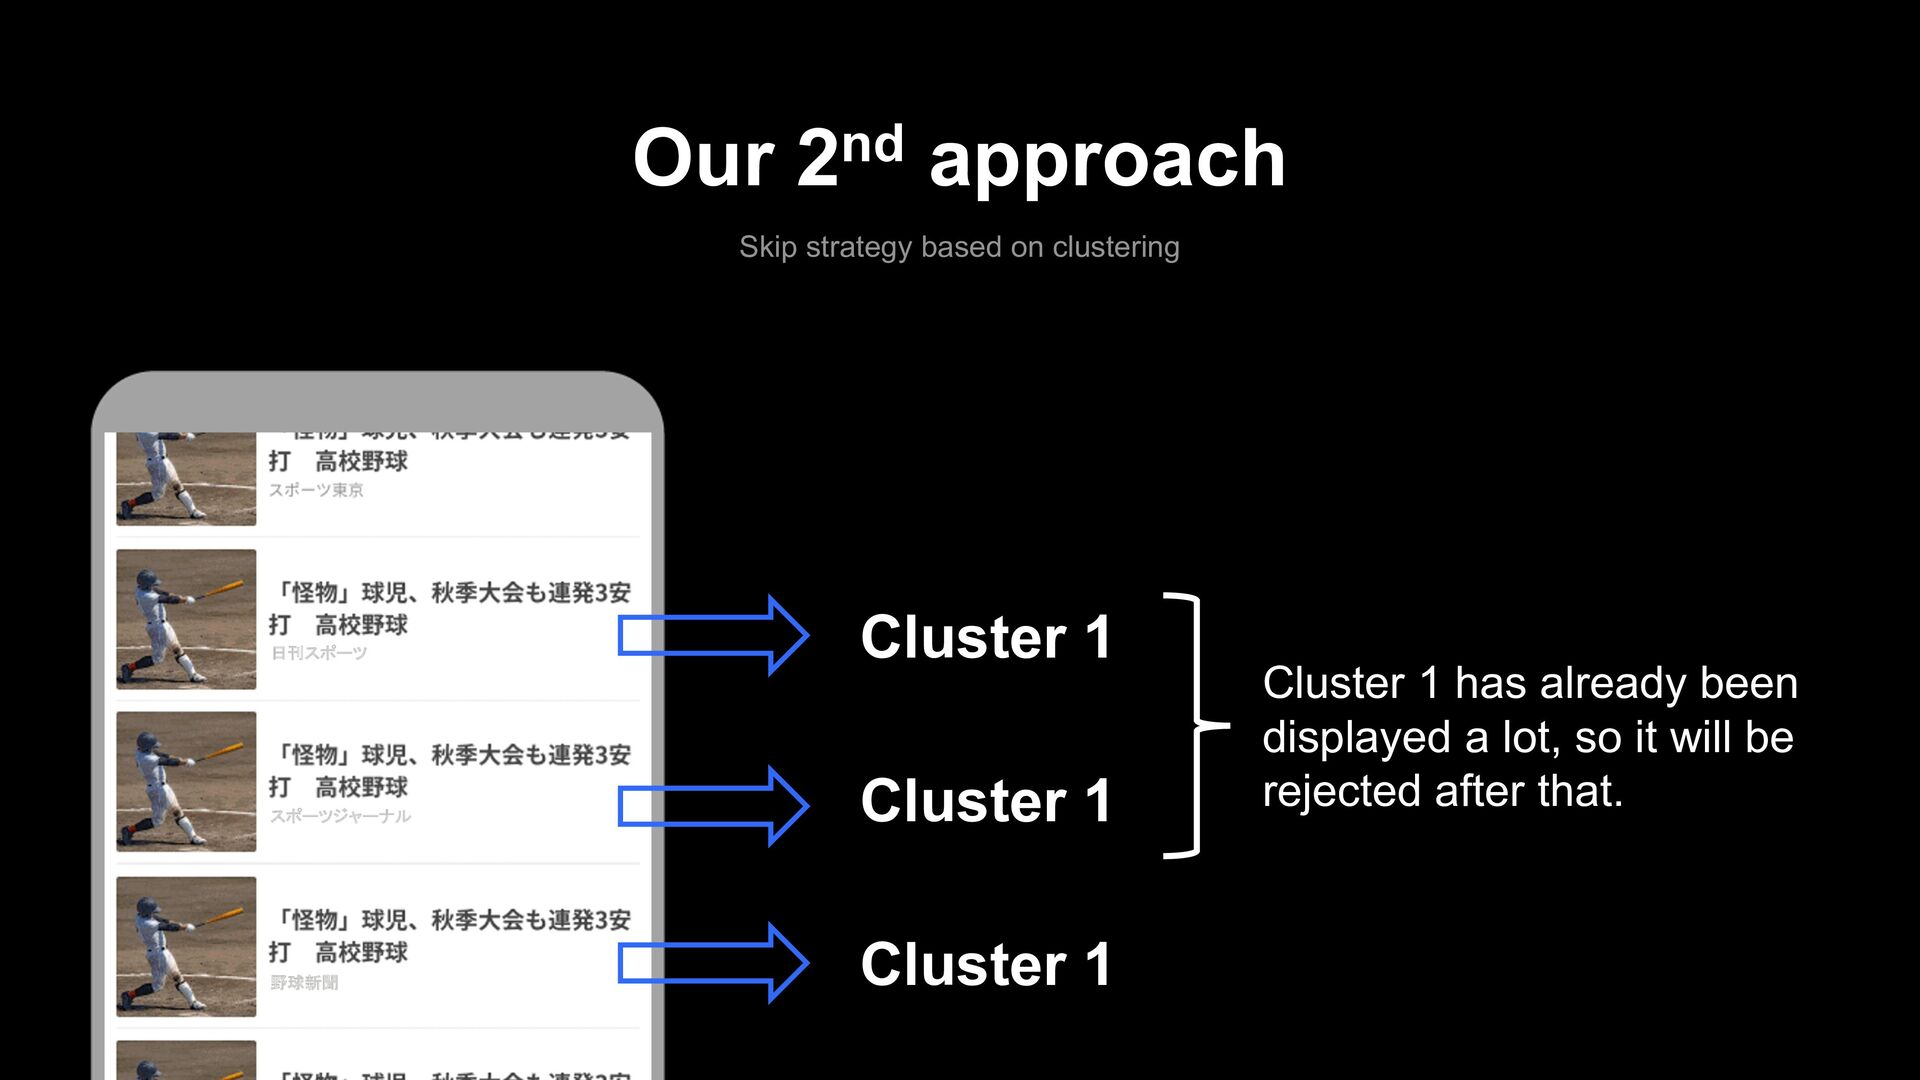
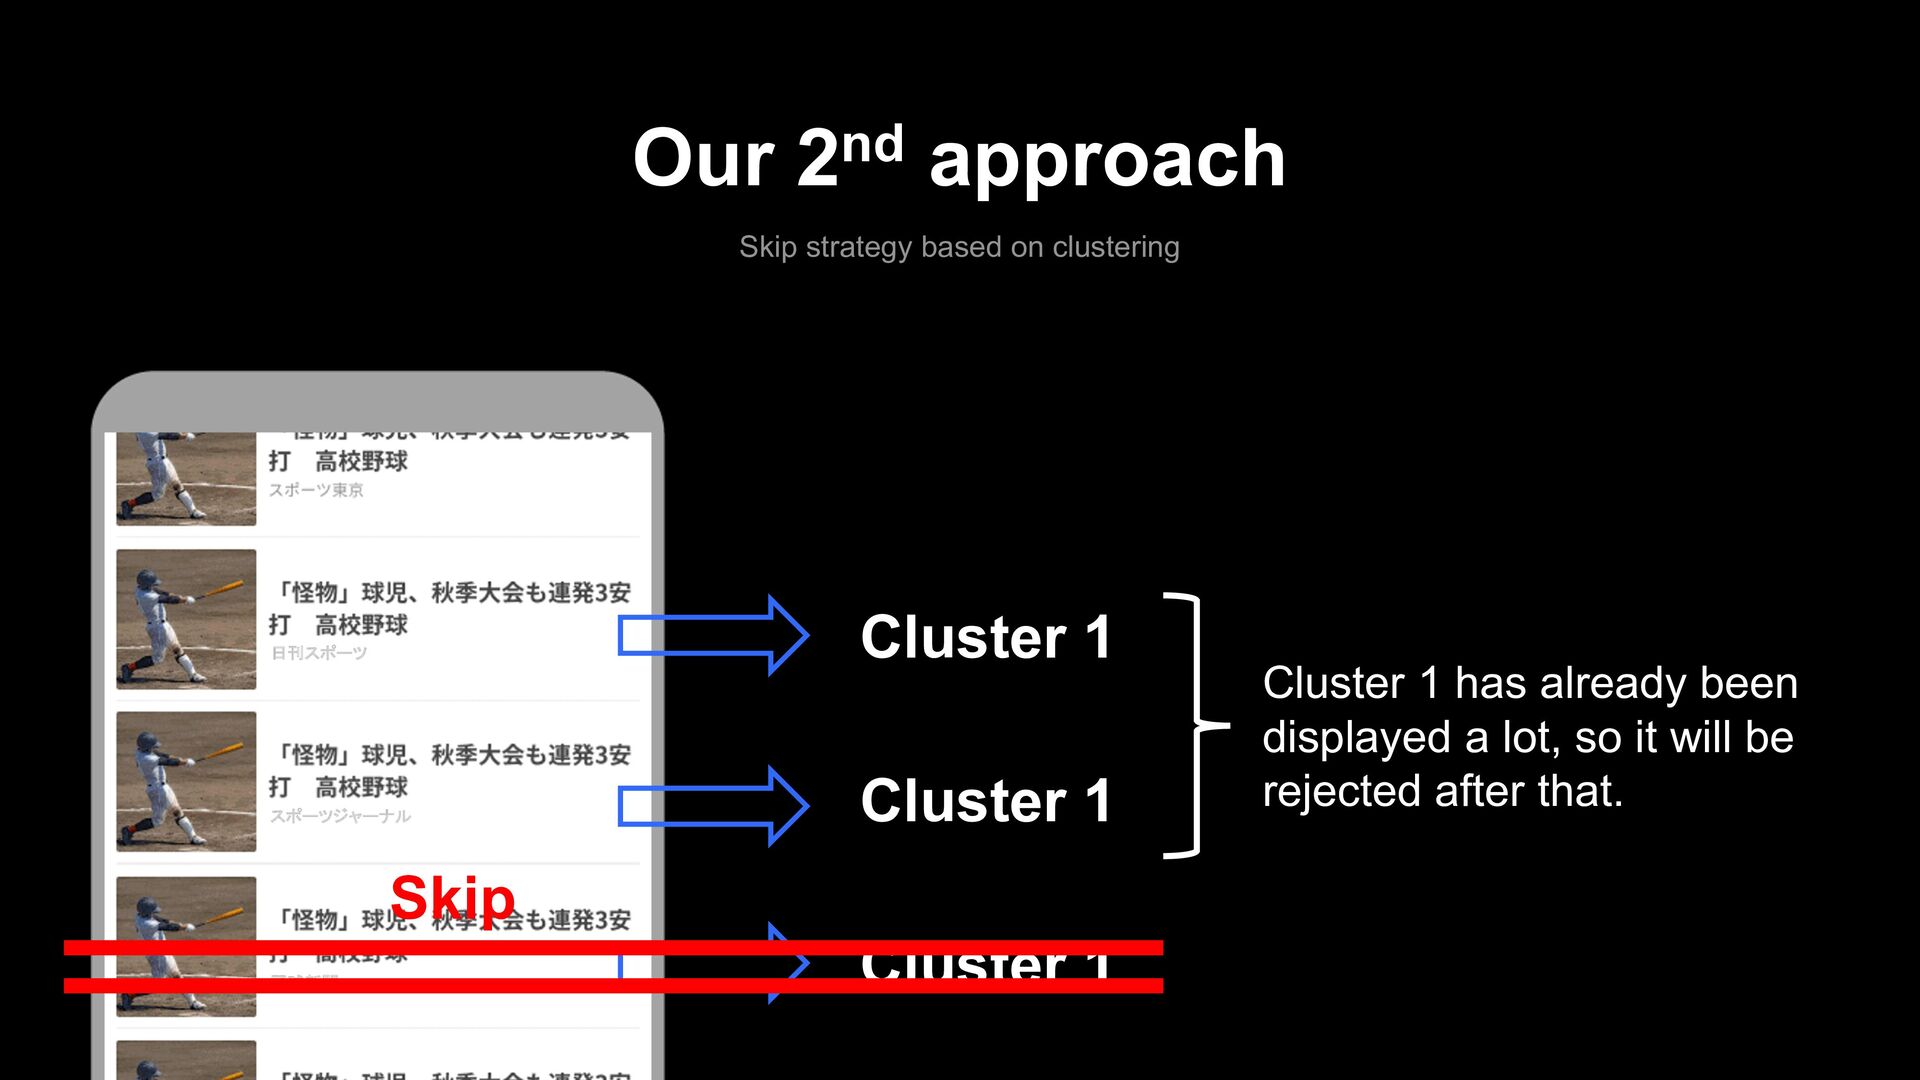
Our 2nd approach Skip strategy based on clustering Cluster 1
Cluster 1 Cluster 1 Cluster 1 has already been displayed a lot, so it will be rejected after that. 日刊スポーツ スポーツジャーナル 野球新聞 -
Our 2nd approach Skip strategy based on clustering Cluster 1
Cluster 1 Cluster 1 Cluster 1 has already been displayed a lot, so it will be rejected after that. Skip 日刊スポーツ スポーツジャーナル 野球新聞 -
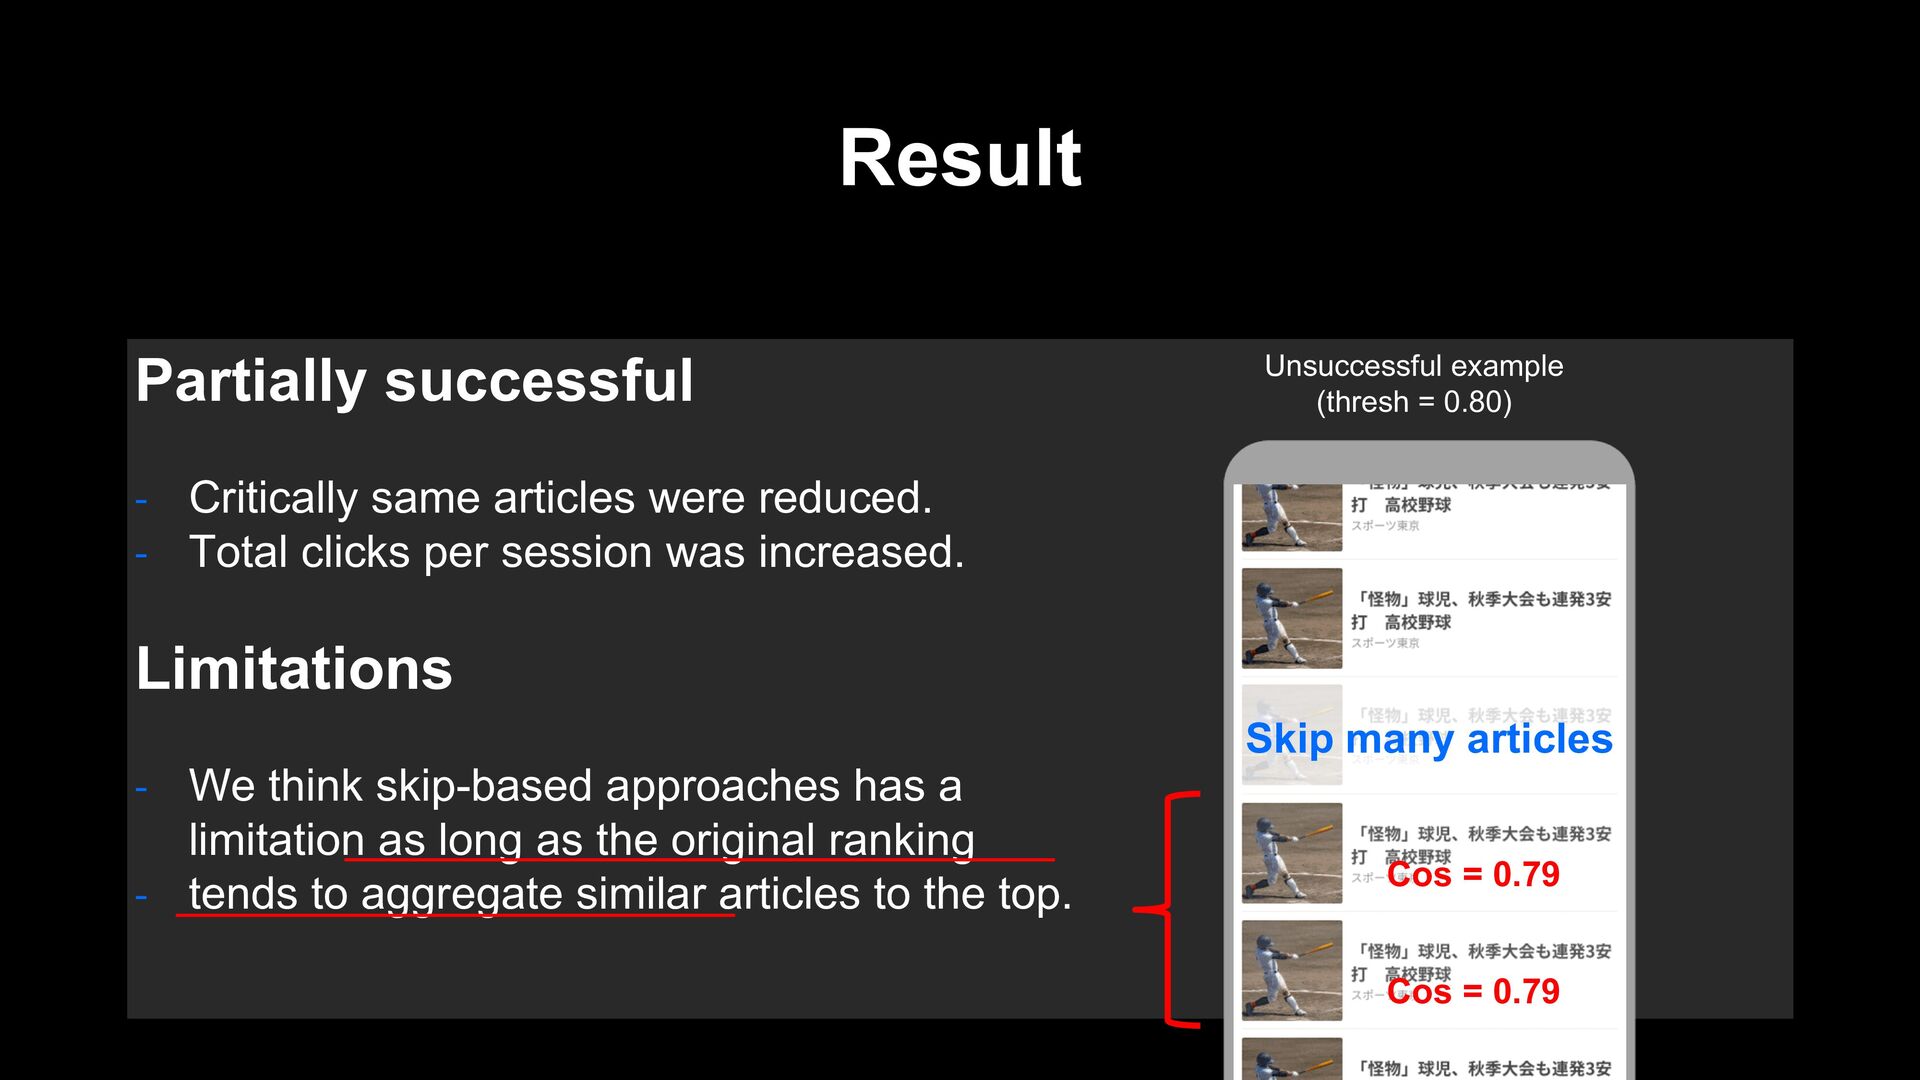
Result Partially successful - Critically same articles were reduced. -
Total clicks per session was increased. Limitations - We think skip-based approaches has a limitation as long as the original ranking - tends to aggregate similar articles to the top. Unsuccessful example (thresh = 0.80) Skip many articles Cos = 0.79 Cos = 0.79 -
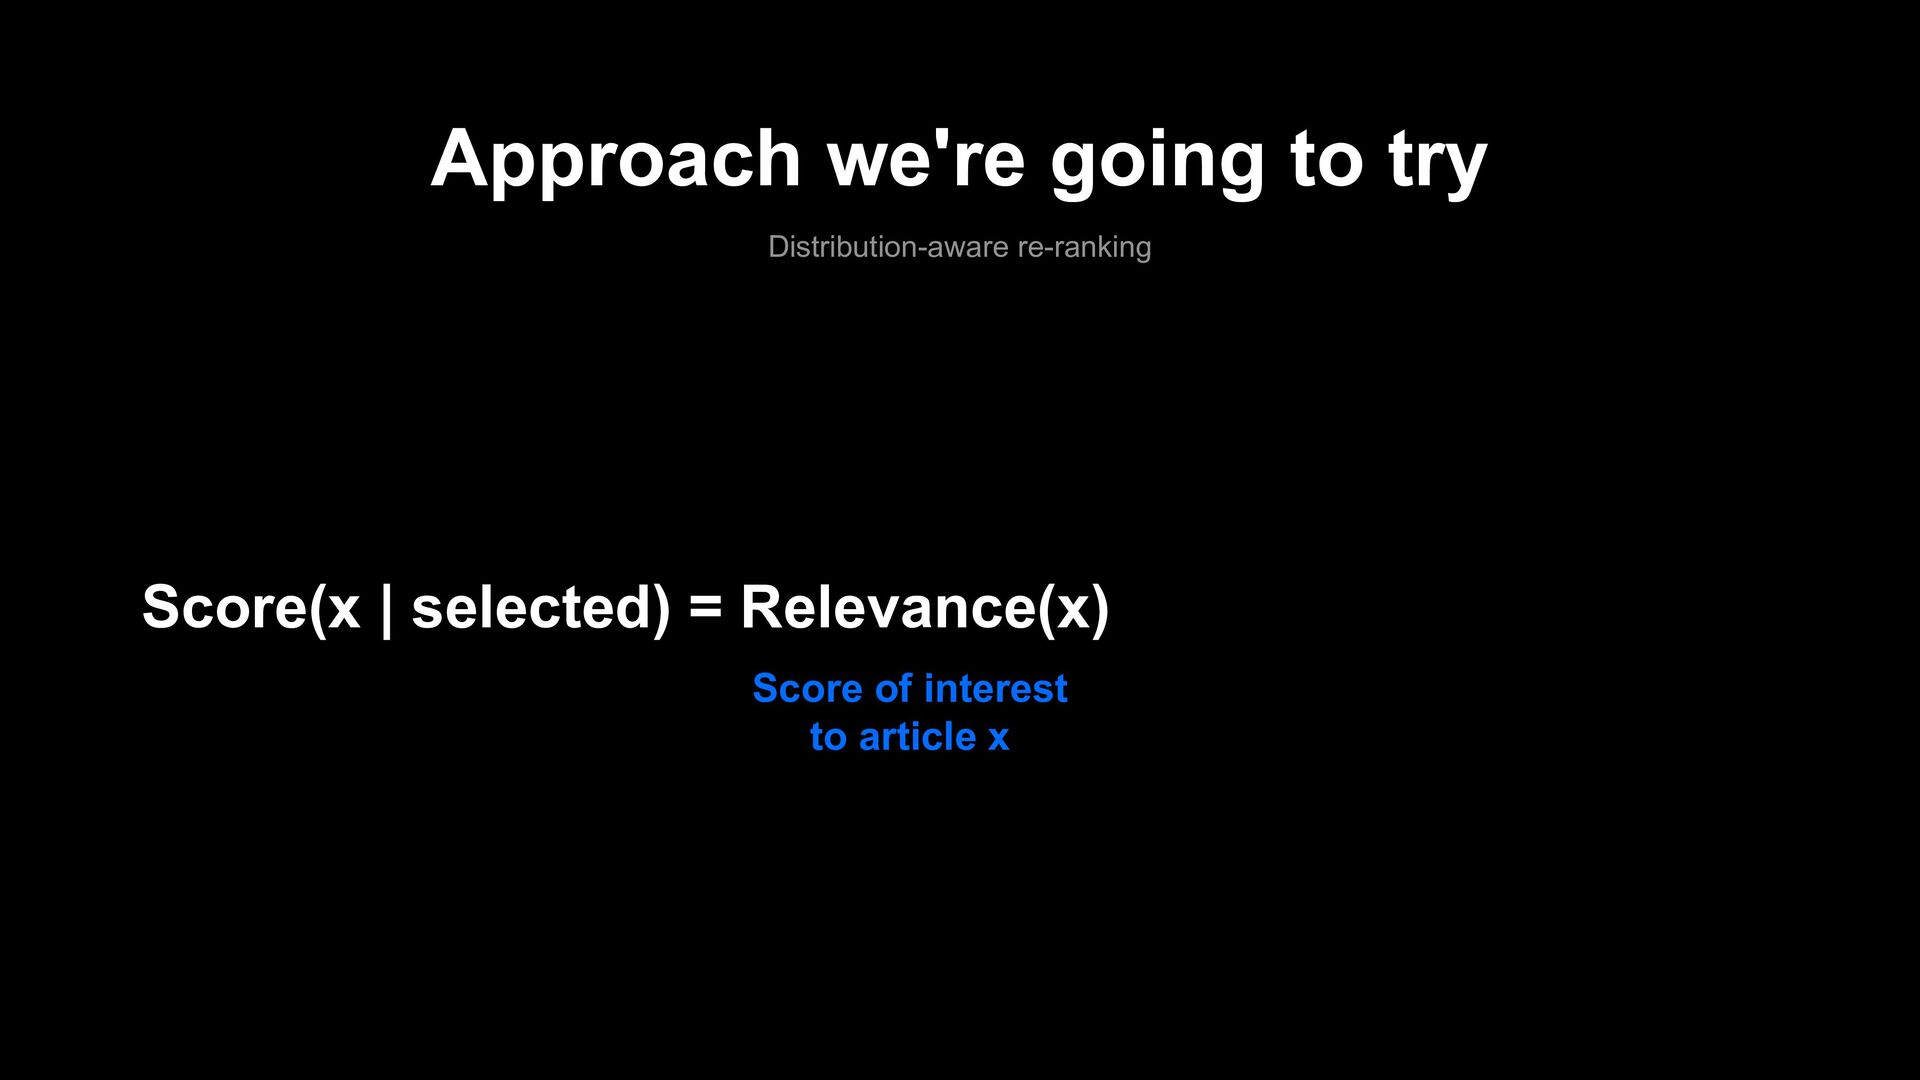
Approach we're going to try Distribution-aware re-ranking Score(x | selected)
= Relevance(x) – λ KL(p, selected + x) Score of interest to article x -
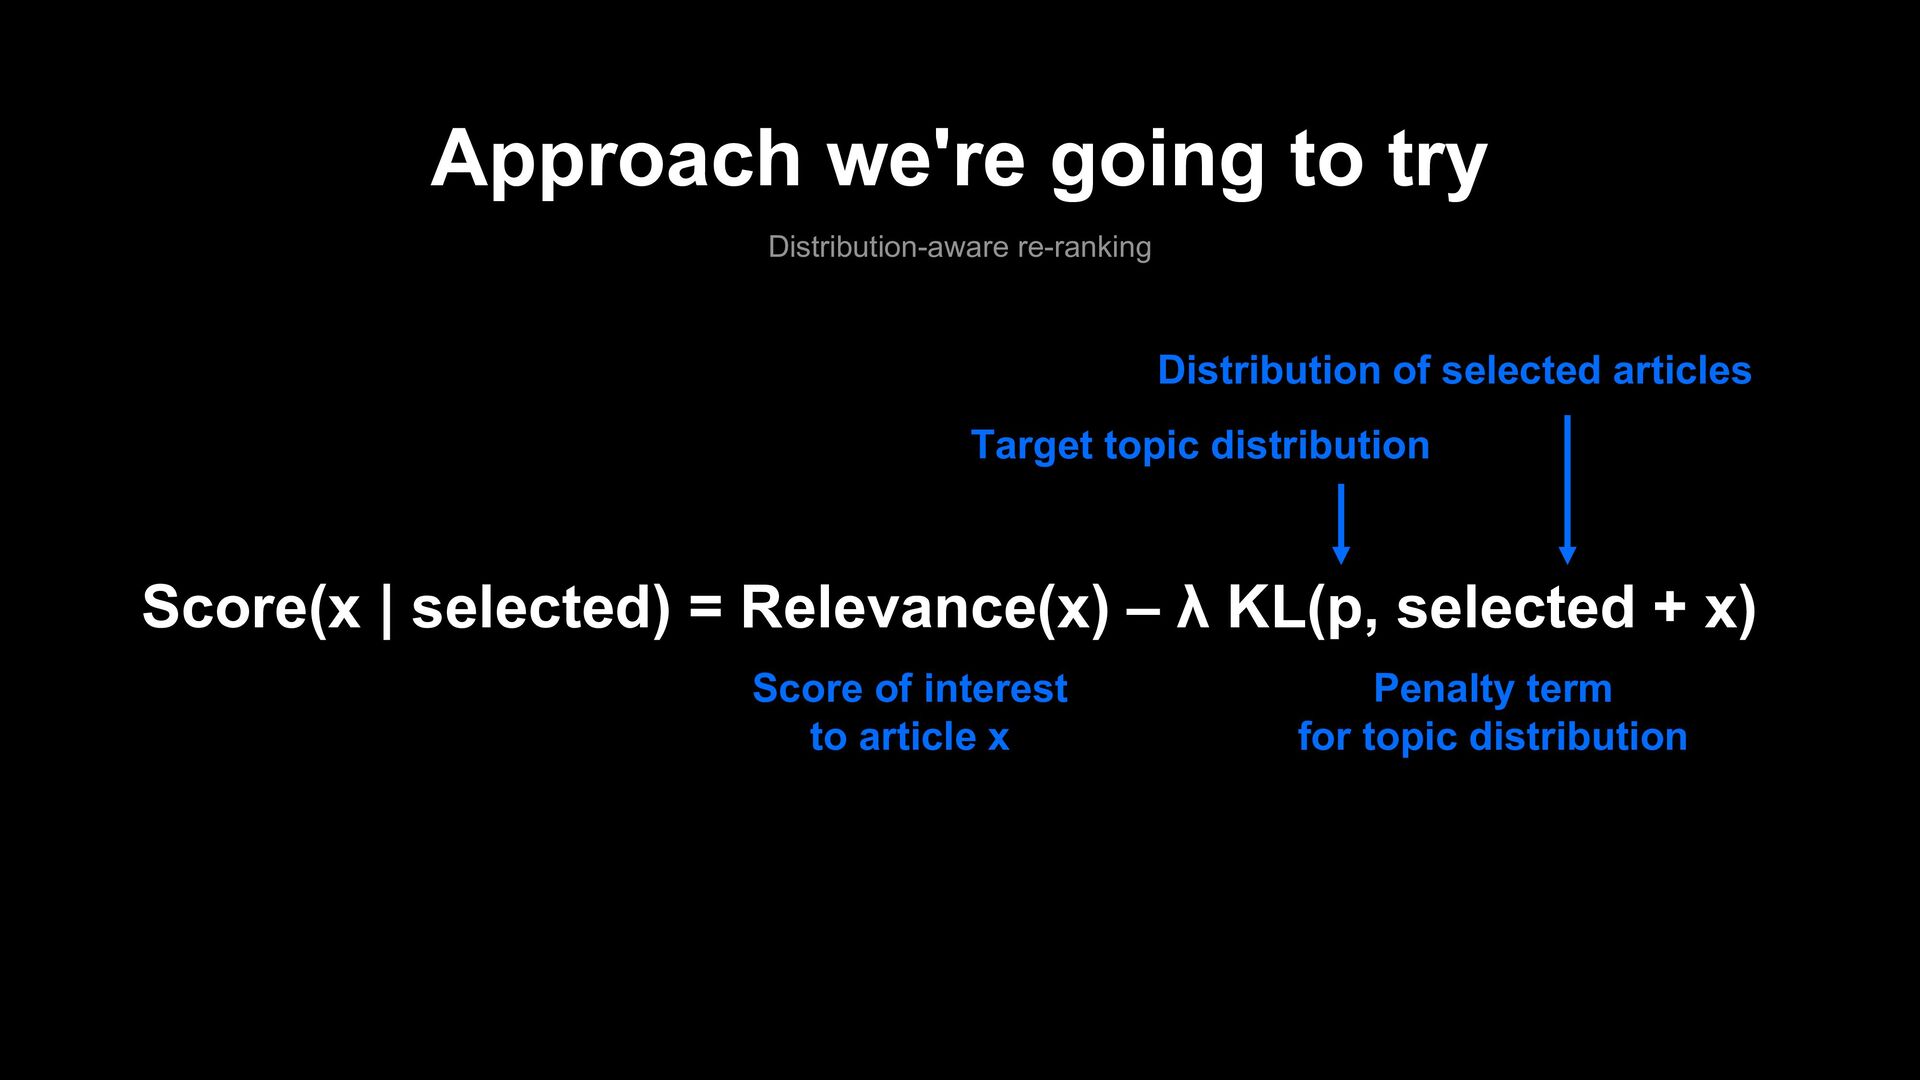
Approach we're going to try Distribution-aware re-ranking Score(x | selected)
= Relevance(x) – λ KL(p, selected + x) Target topic distribution Distribution of selected articles Penalty term for topic distribution Score of interest to article x -
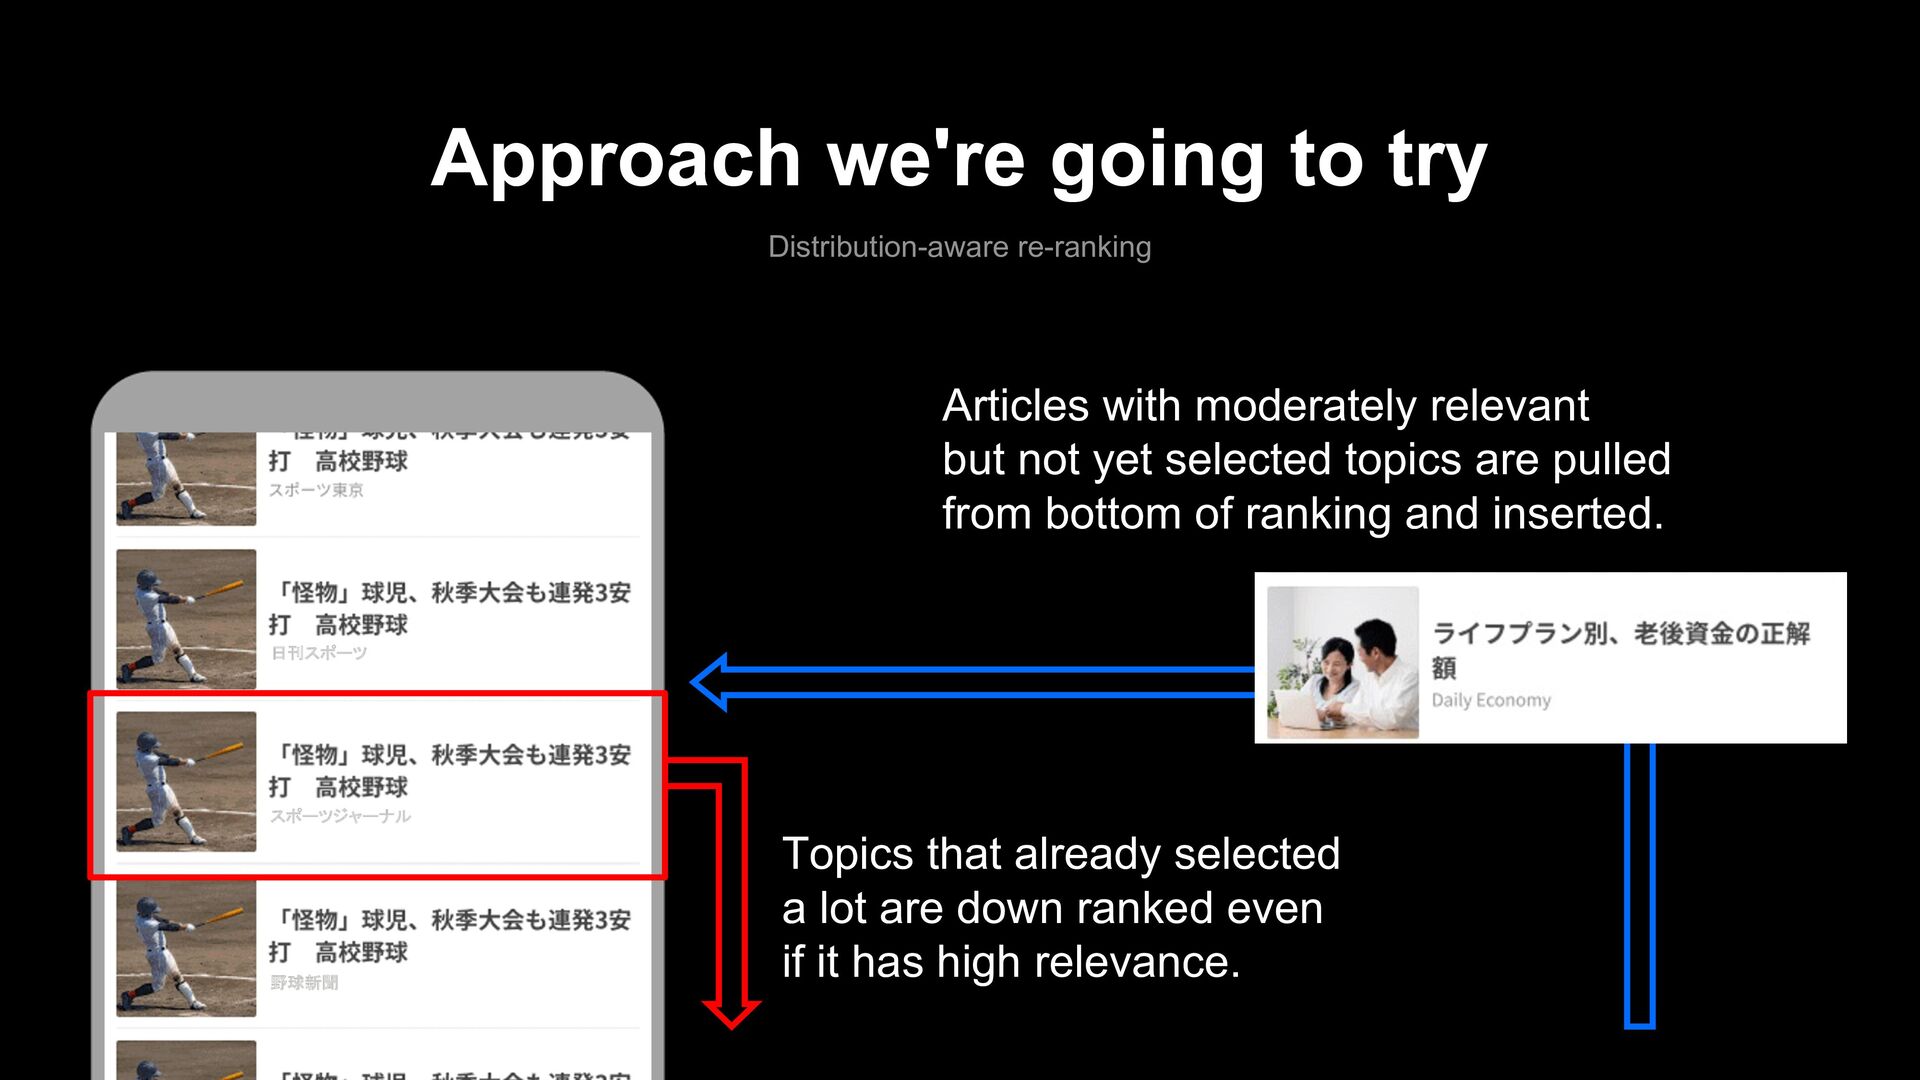
Approach we're going to try Distribution-aware re-ranking Topics that already
selected a lot are down ranked even if it has high relevance. Articles with moderately relevant but not yet selected topics are pulled from bottom of ranking and inserted. 日刊スポーツ スポーツジャーナル 野球新聞 -
Approach we're going to try Distribution-aware re-ranking Challenges to deploy
- It requires a lot of computation. - Skip-based approaches require calculating the score only once for each article. - The re-ranking approach requires re-calculating each article's score and sorting them each time one article is selected. -
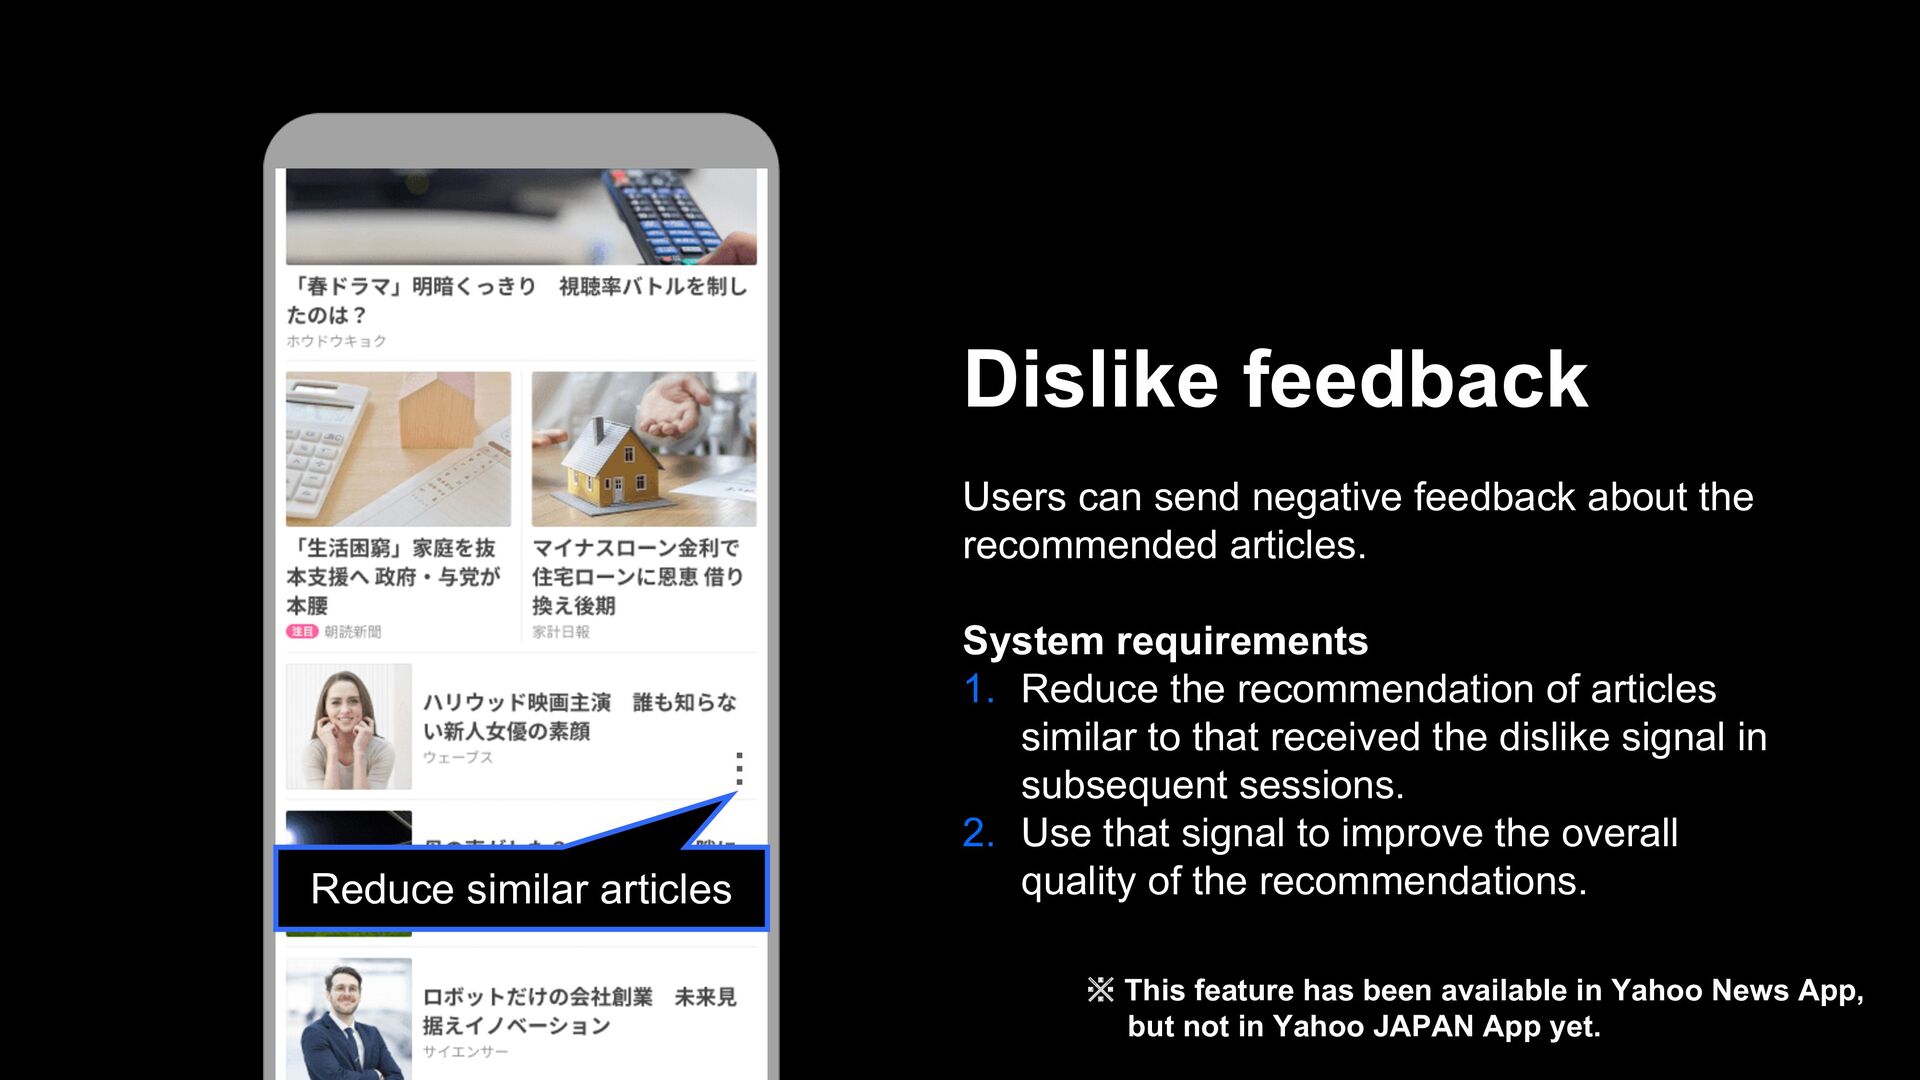
Users can send negative feedback about the recommended articles. System
requirements 1. Reduce the recommendation of articles similar to that received the dislike signal in subsequent sessions. 2. Use that signal to improve the overall quality of the recommendations. Dislike feedback … Reduce similar articles ※ This feature has been available in Yahoo News App, but not in Yahoo JAPAN App yet. -
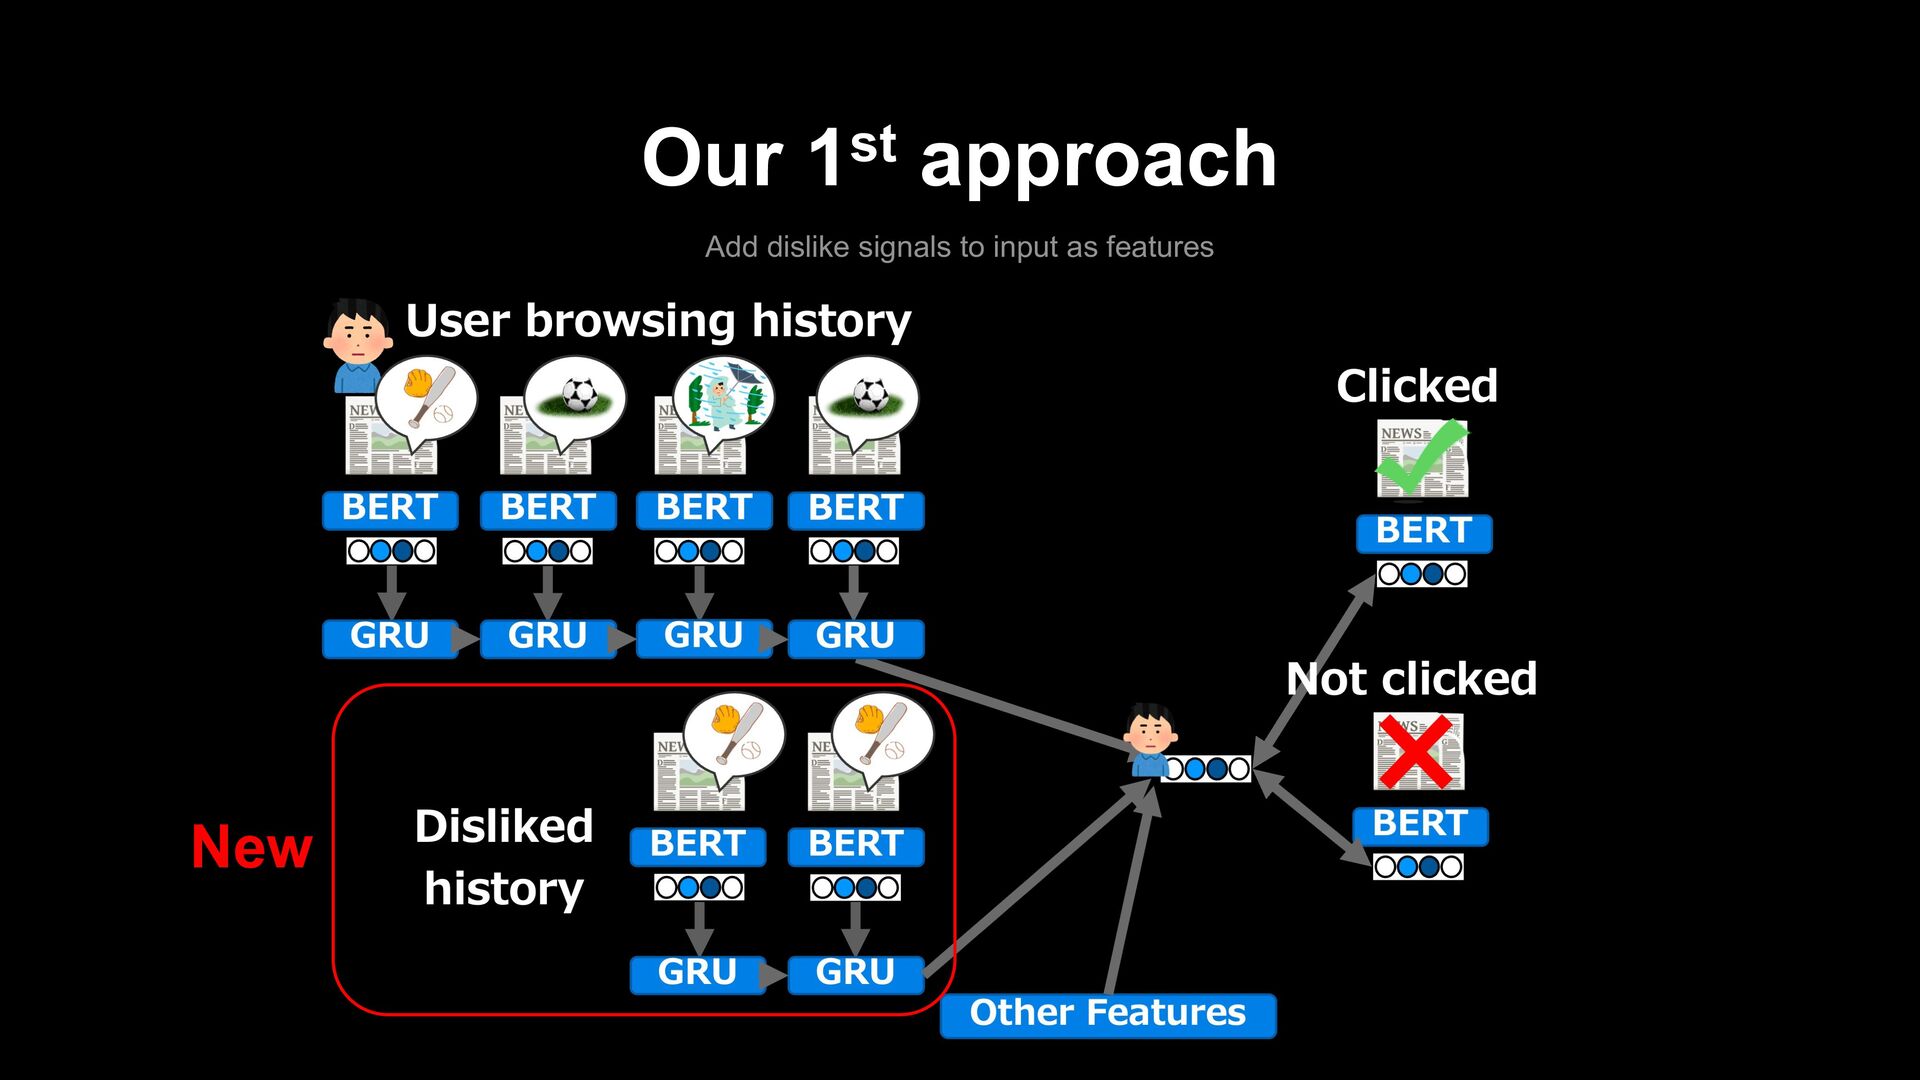
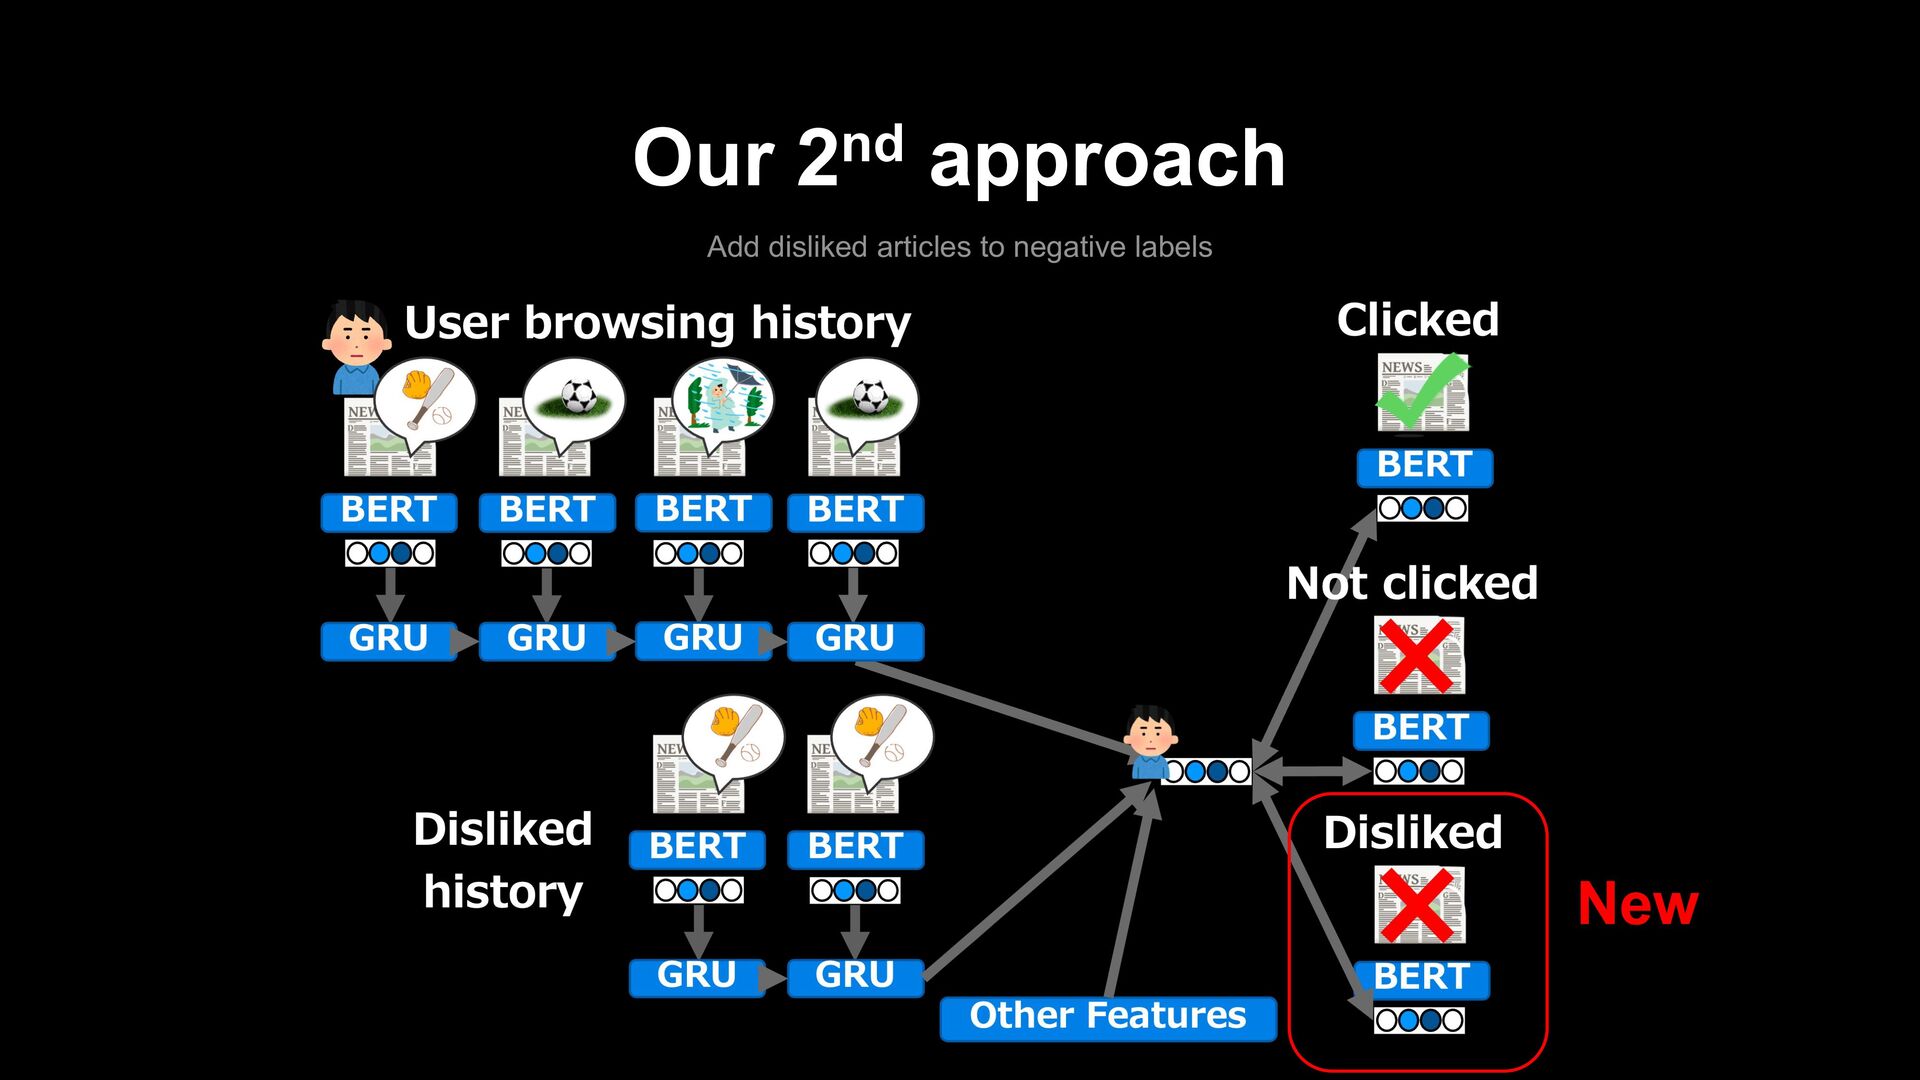
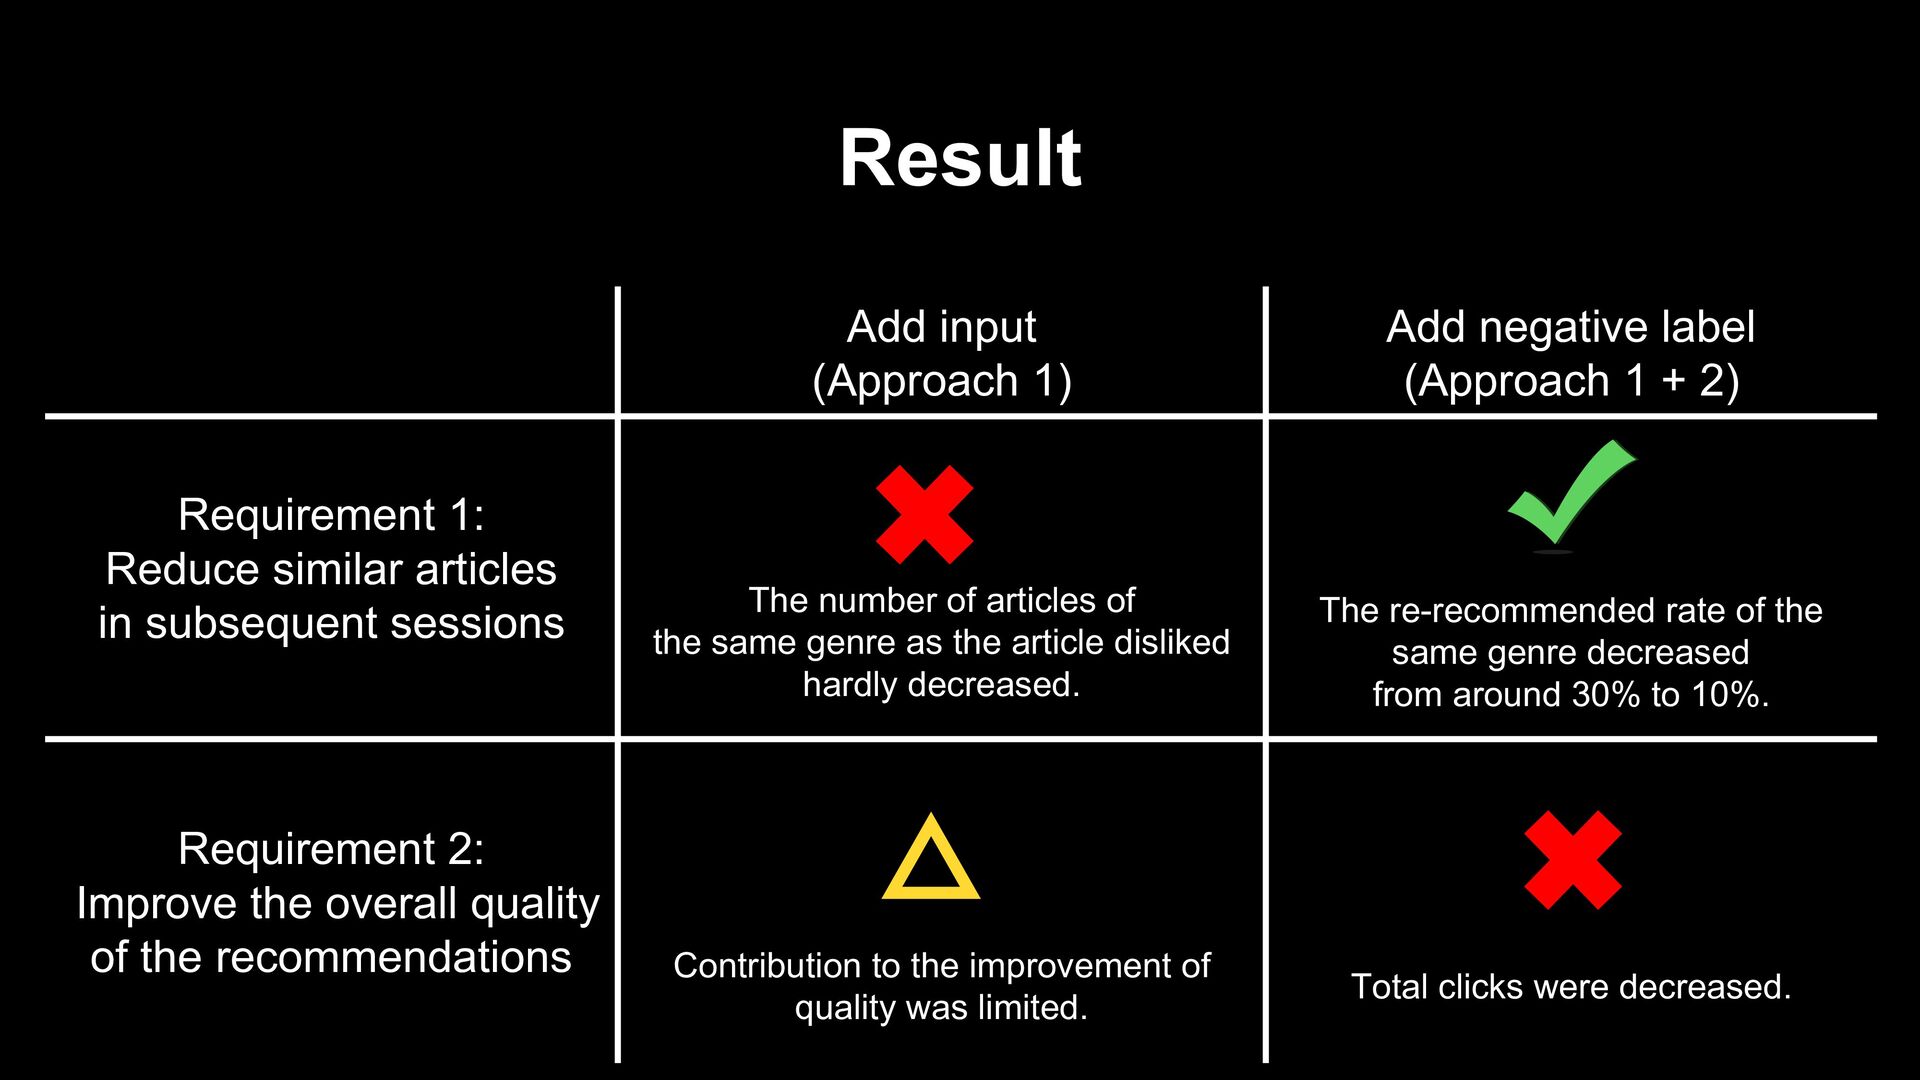
Result Add input (Approach 1) Add negative label (Approach 1
+ 2) Requirement 1: Reduce similar articles in subsequent sessions The number of articles of the same genre as the article disliked hardly decreased. The re-recommended rate of the same genre decreased from around 30% to 10%. Requirement 2: Improve the overall quality of the recommendations Contribution to the improvement of quality was limited. Total clicks were decreased. -
What was not good and what to do next (1/2)
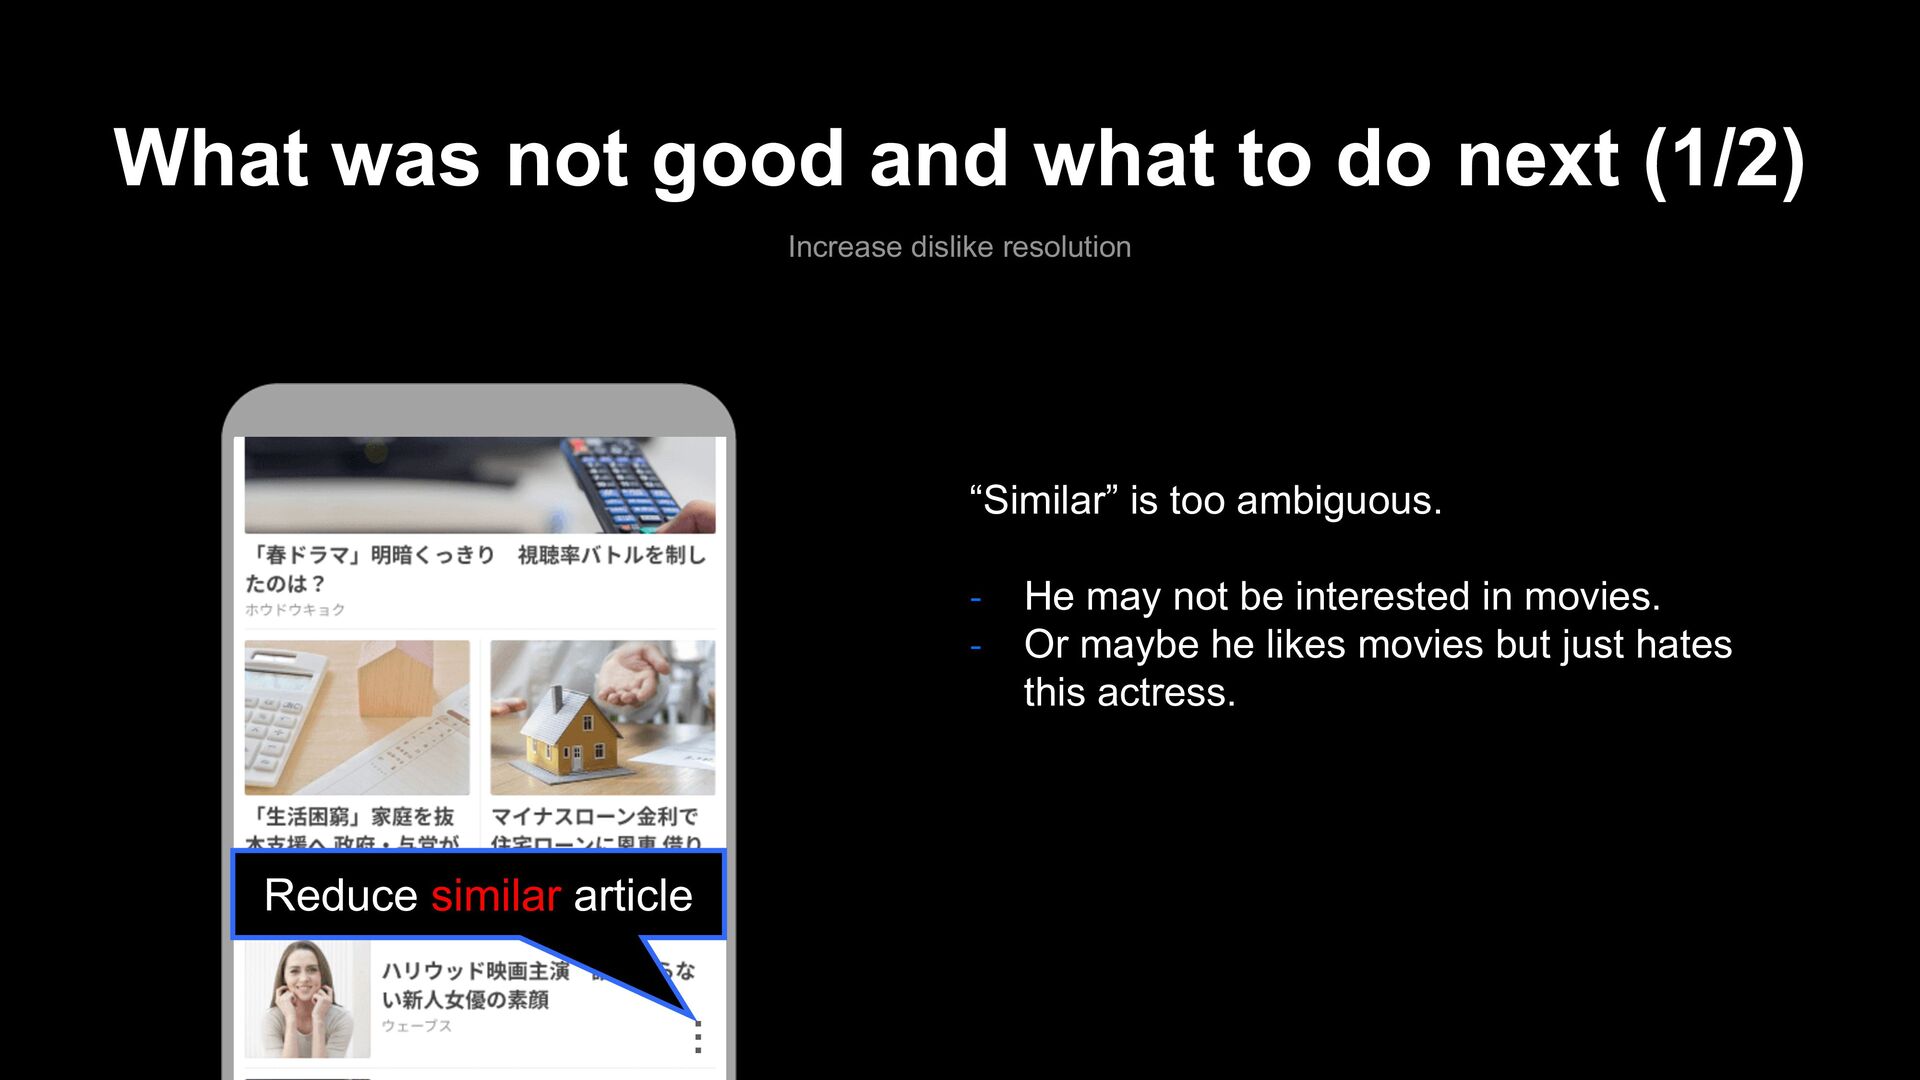
Increase dislike resolution … Reduce similar article “Similar” is too ambiguous. - He may not be interested in movies. - Or maybe he likes movies but just hates this actress. -
What was not good and what to do next (1/2)
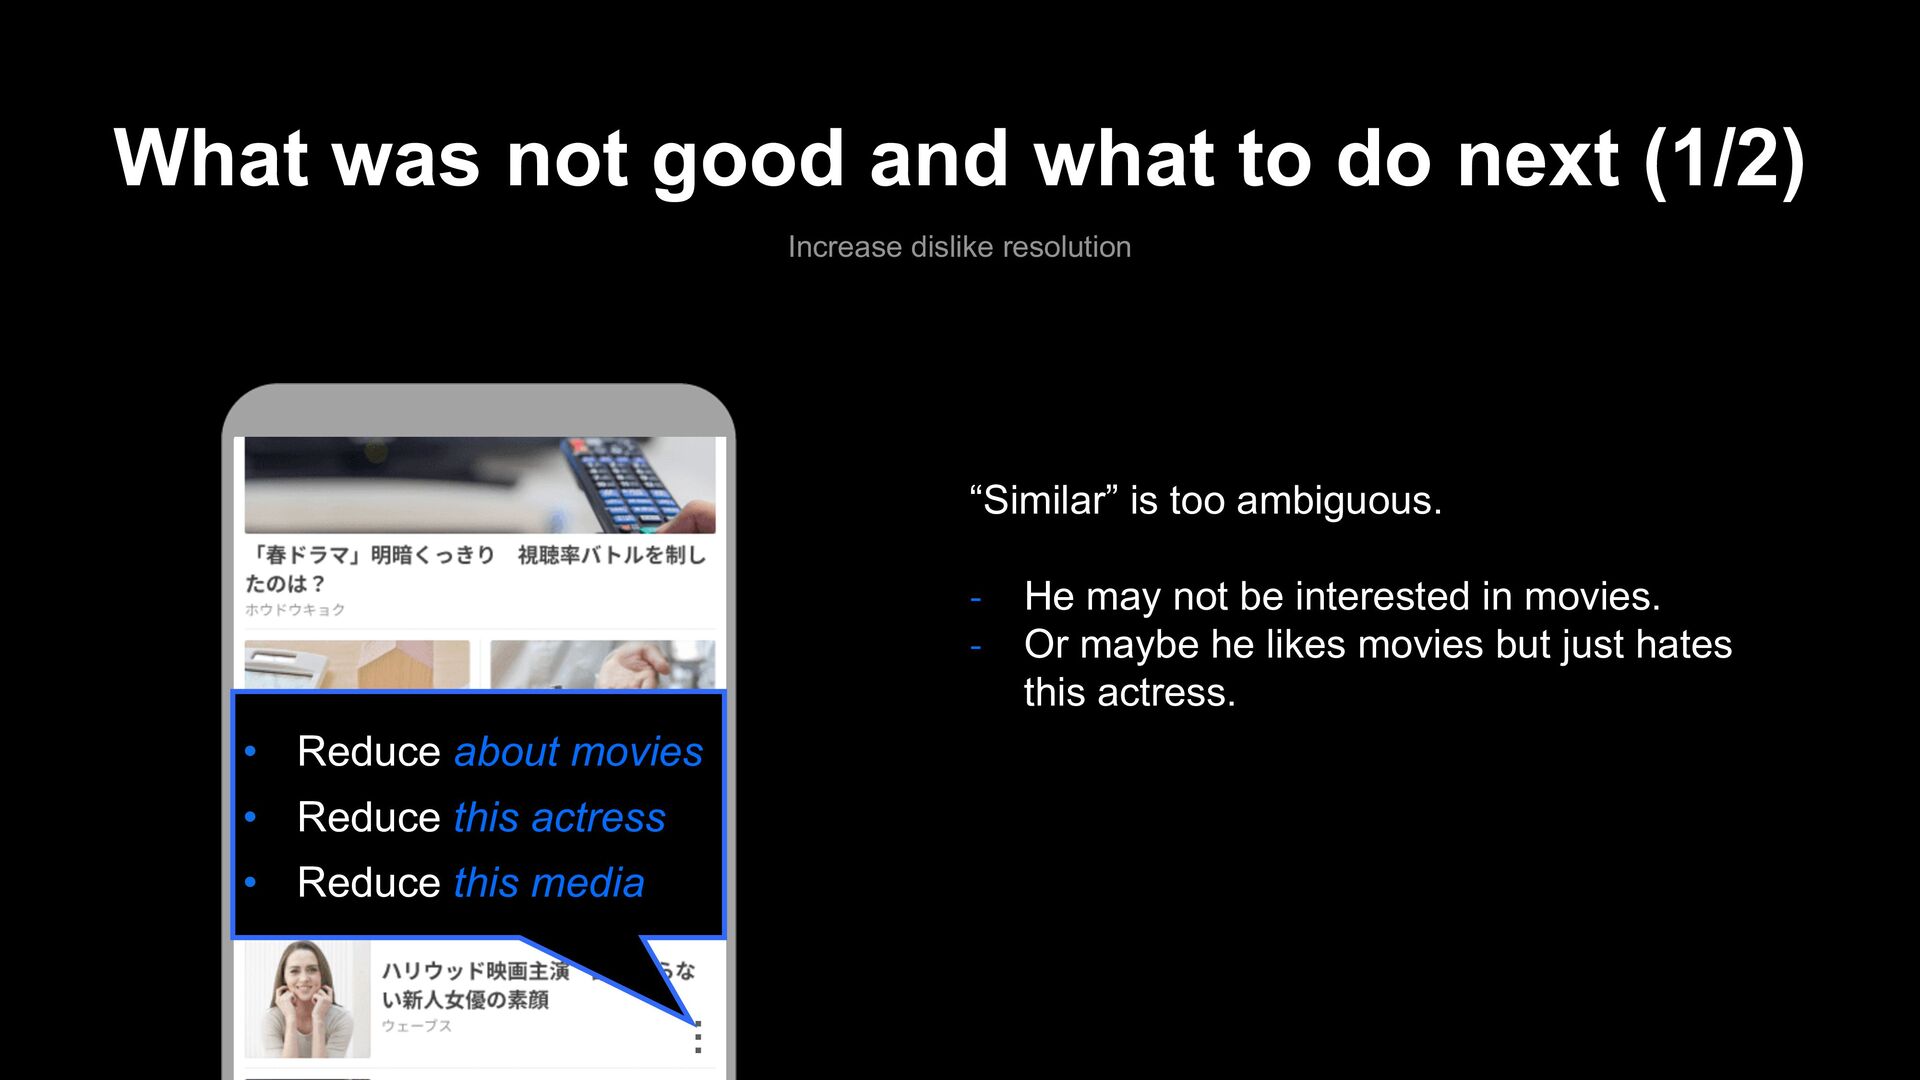
Increase dislike resolution … • Reduce about movies • Reduce this actress • Reduce this media “Similar” is too ambiguous. - He may not be interested in movies. - Or maybe he likes movies but just hates this actress. -
What was not good and what to do next (2/2)
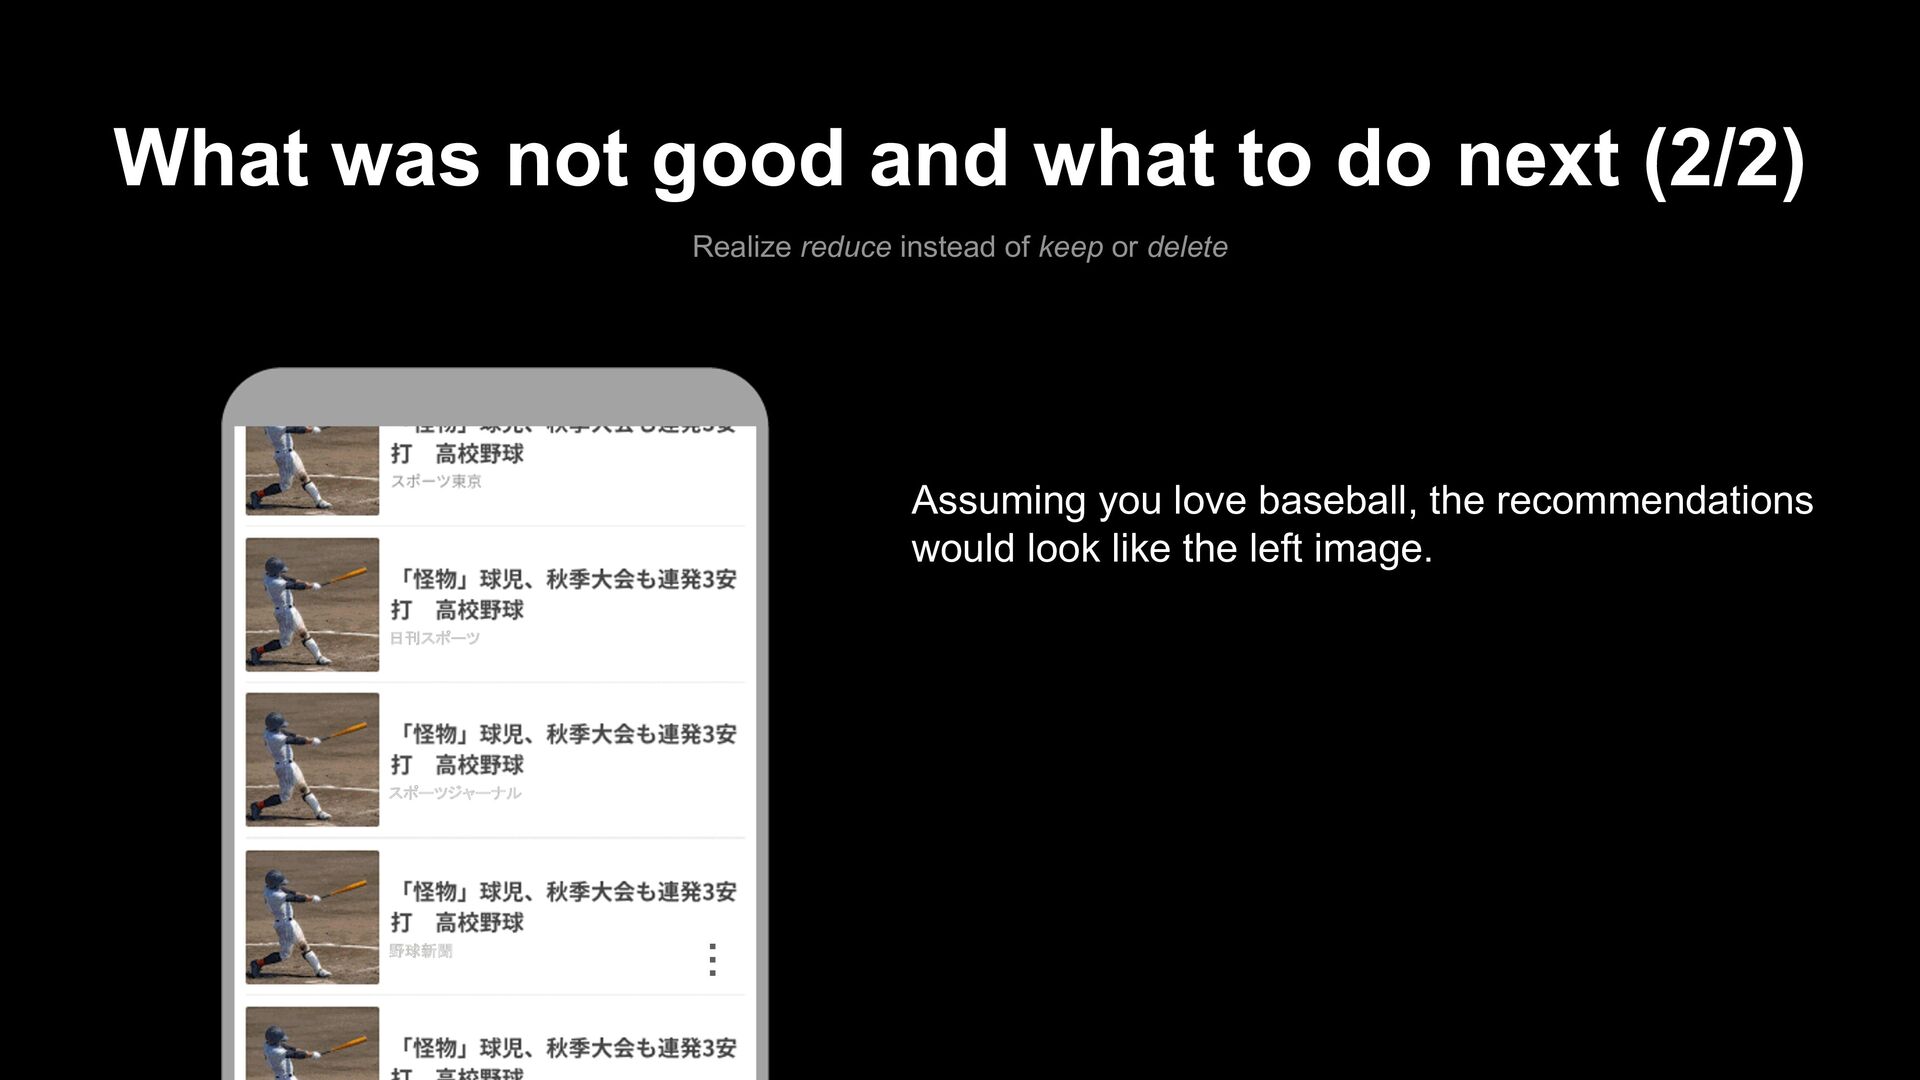
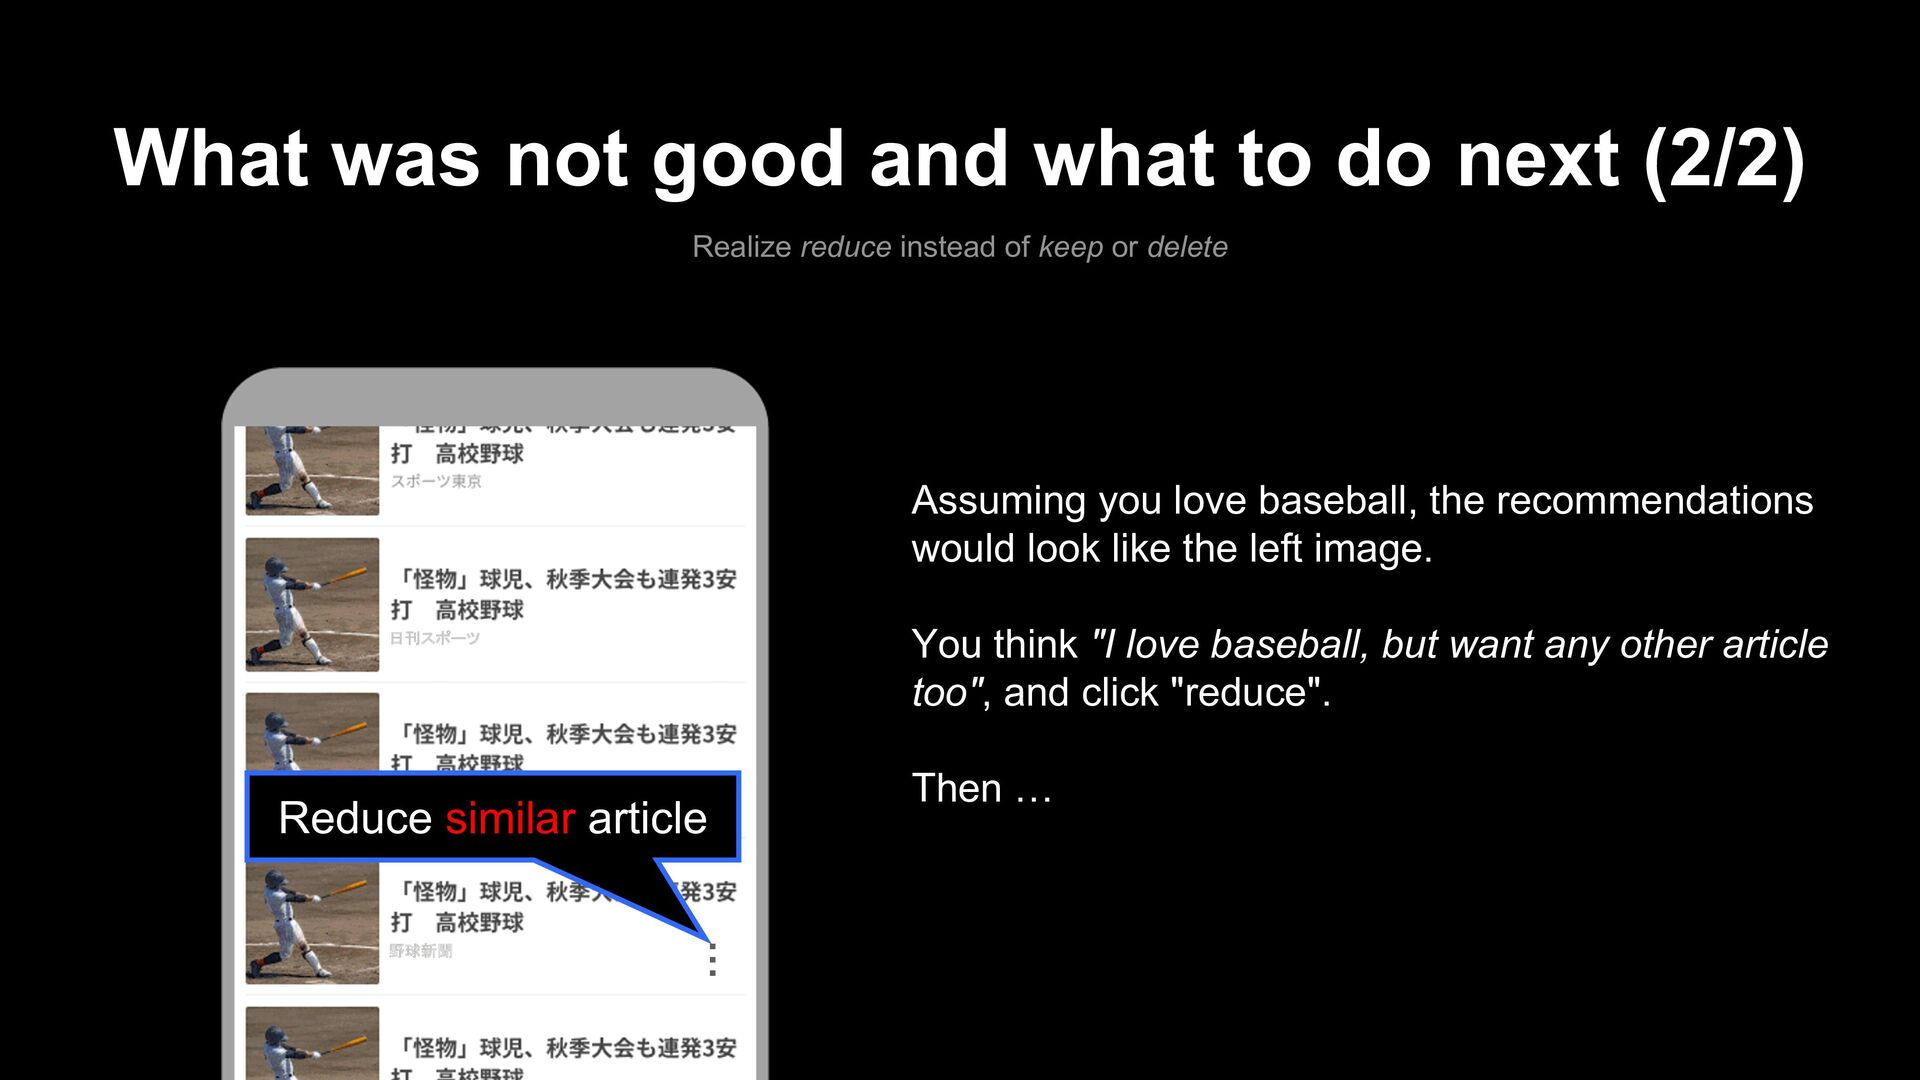
Realize reduce instead of keep or delete … Assuming you love baseball, the recommendations would look like the left image. … 日刊スポーツ スポーツジャーナル 野球新聞 -
What was not good and what to do next (2/2)
Realize reduce instead of keep or delete … Assuming you love baseball, the recommendations would look like the left image. You think "I love baseball, but want any other article too", and click "reduce". Then … … 日刊スポーツ スポーツジャーナル 野球新聞 Reduce similar article -
What was not good and what to do next (2/2)
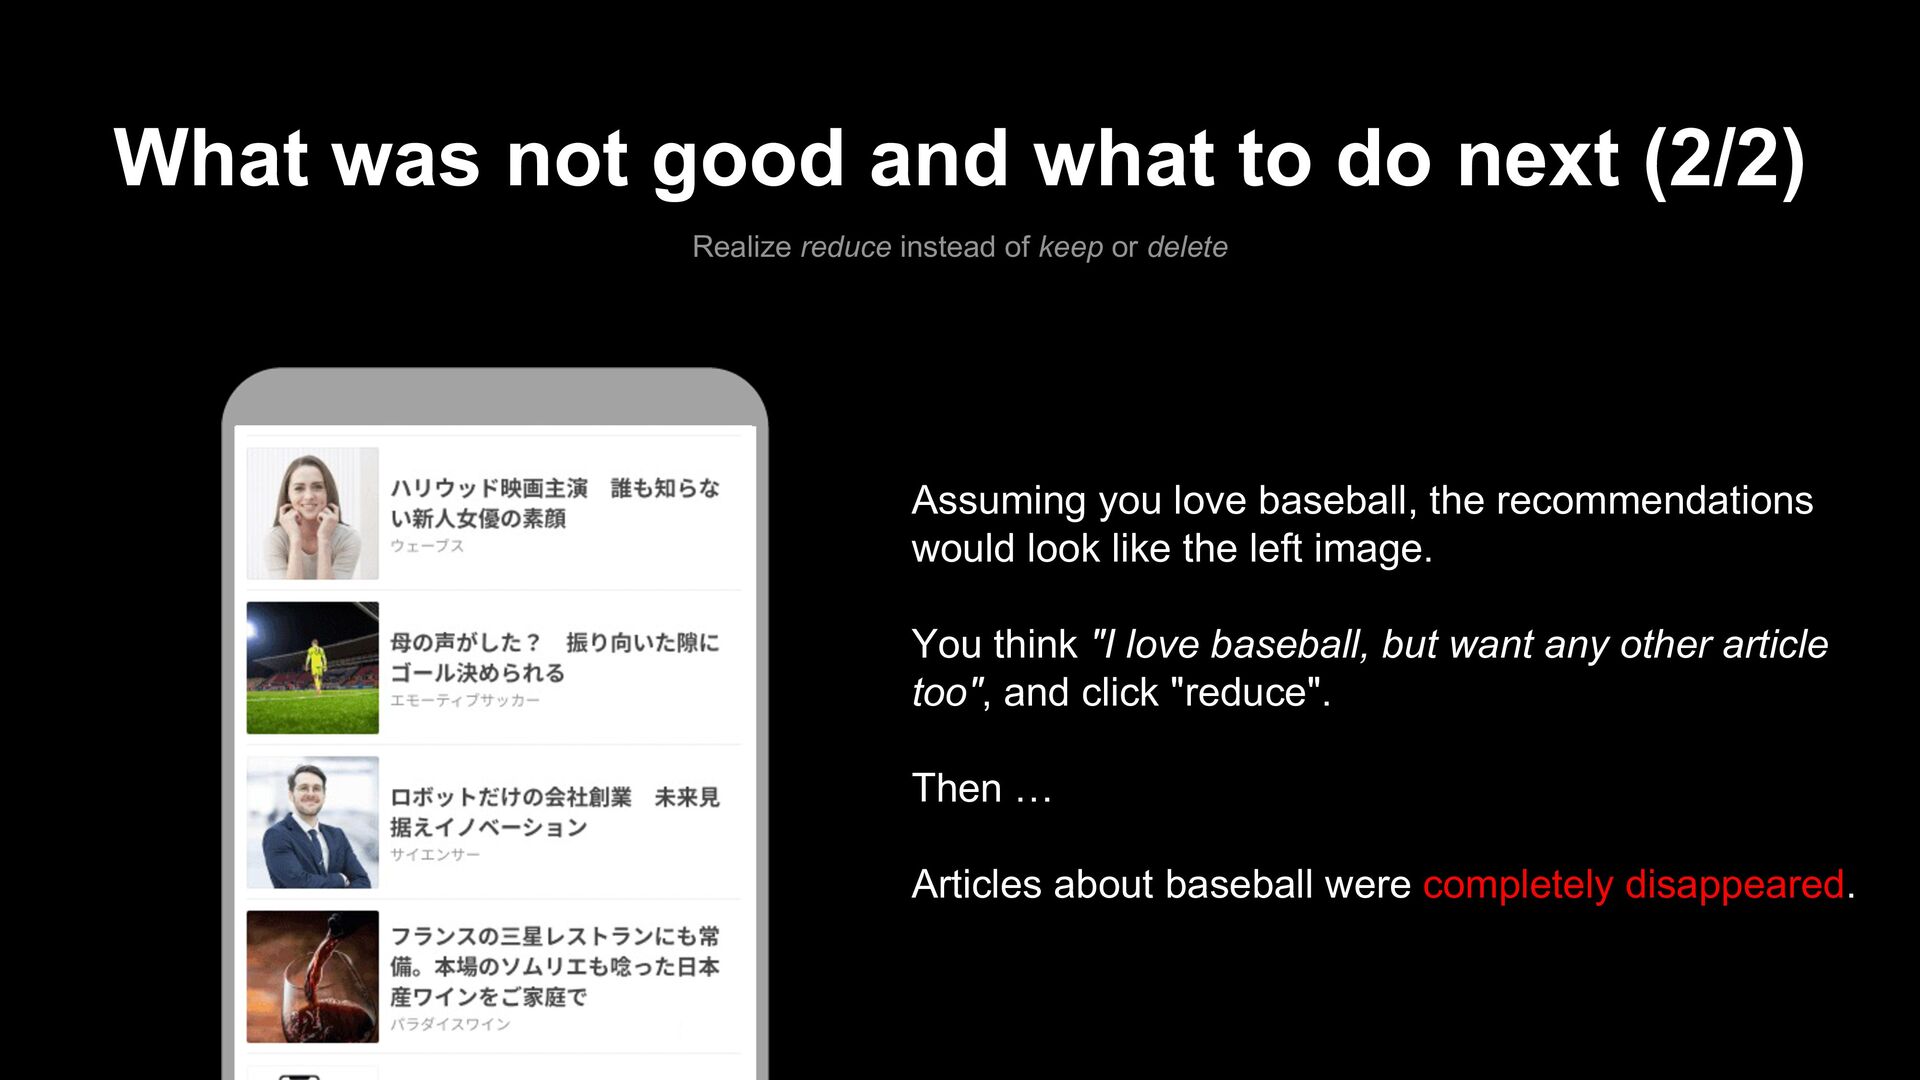
Realize reduce instead of keep or delete … Assuming you love baseball, the recommendations would look like the left image. You think "I love baseball, but want any other article too", and click "reduce". Then … Articles about baseball were completely disappeared. … -
What was not good and what to do next (2/2)
Realize reduce instead of keep or delete Ranking by interest score does not allow to reduce the frequency of a particular genre without lowering the rank of all articles of that genre. Therefore, we believe that the distribution-aware re-ranking mentioned in the previous section will be necessary also to solve this issue. Reduce 日刊スポーツ スポーツジャーナル 野球新聞 -
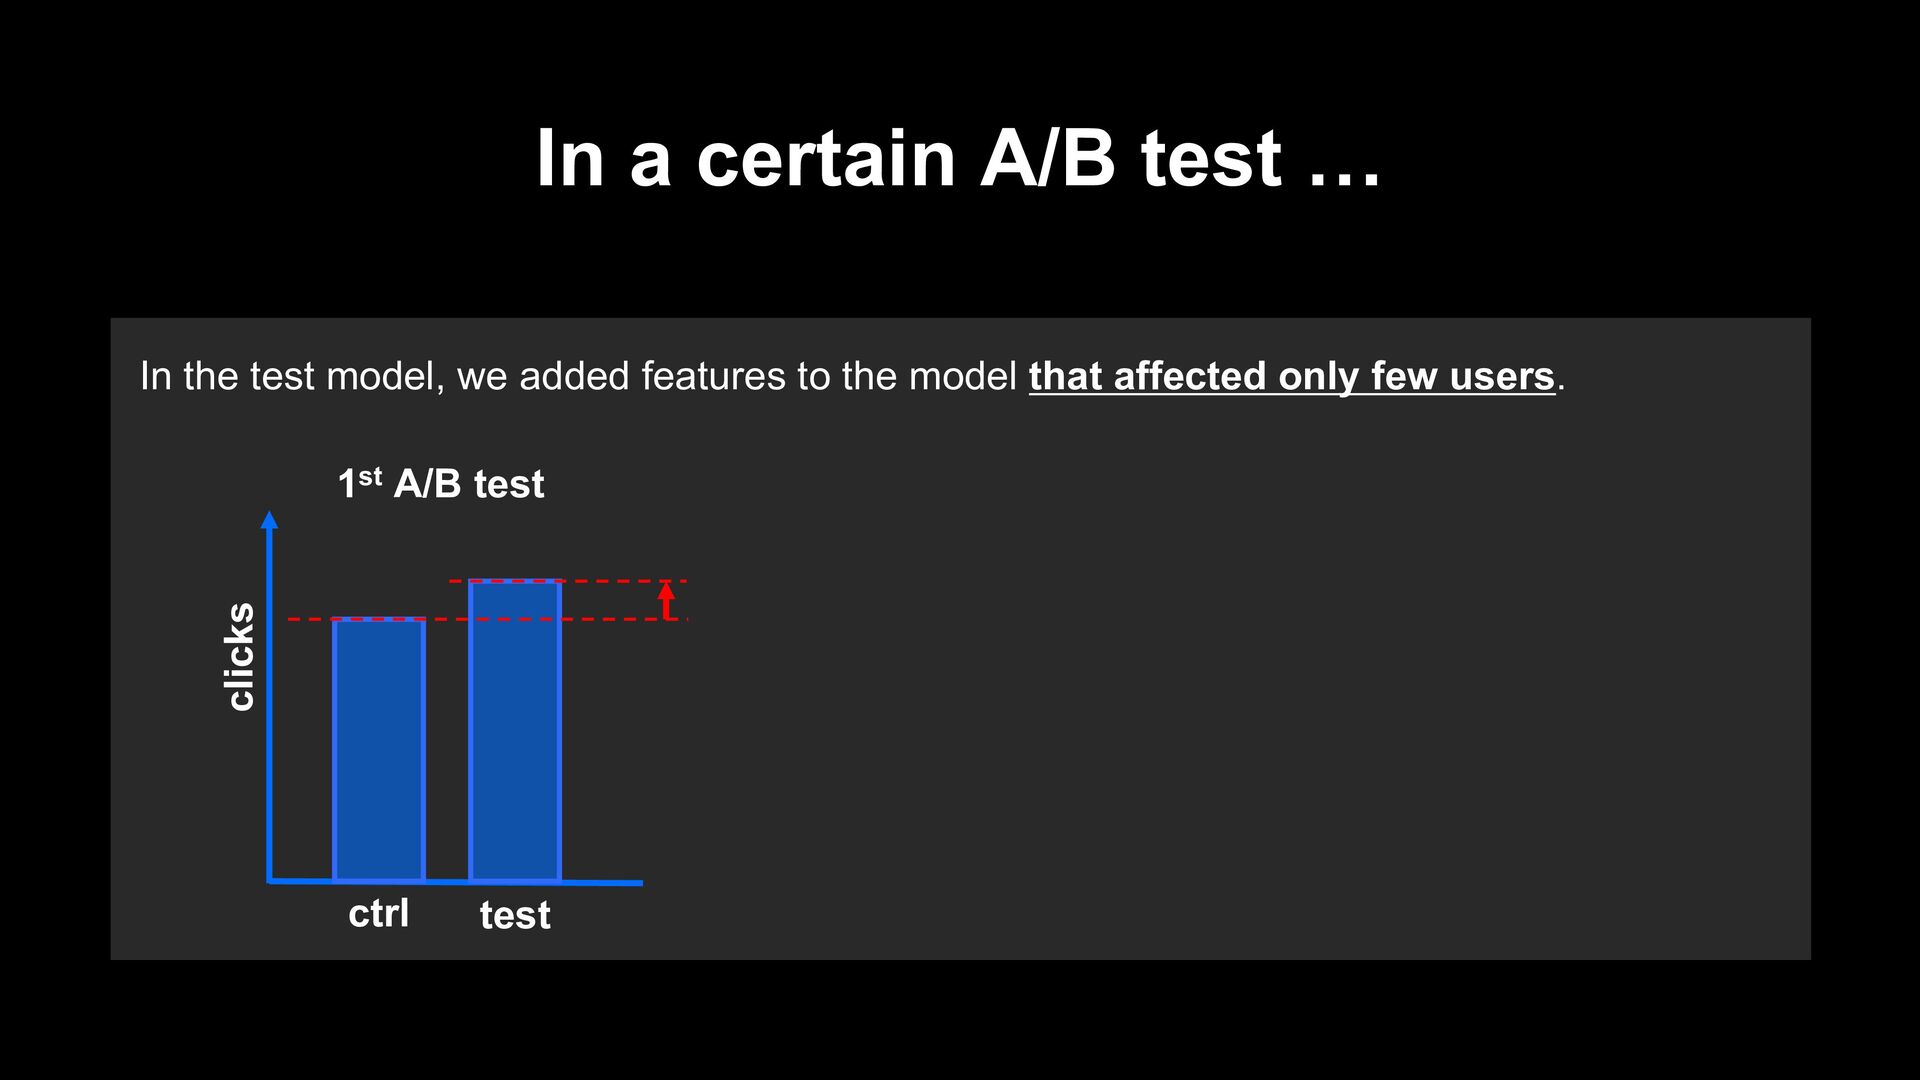
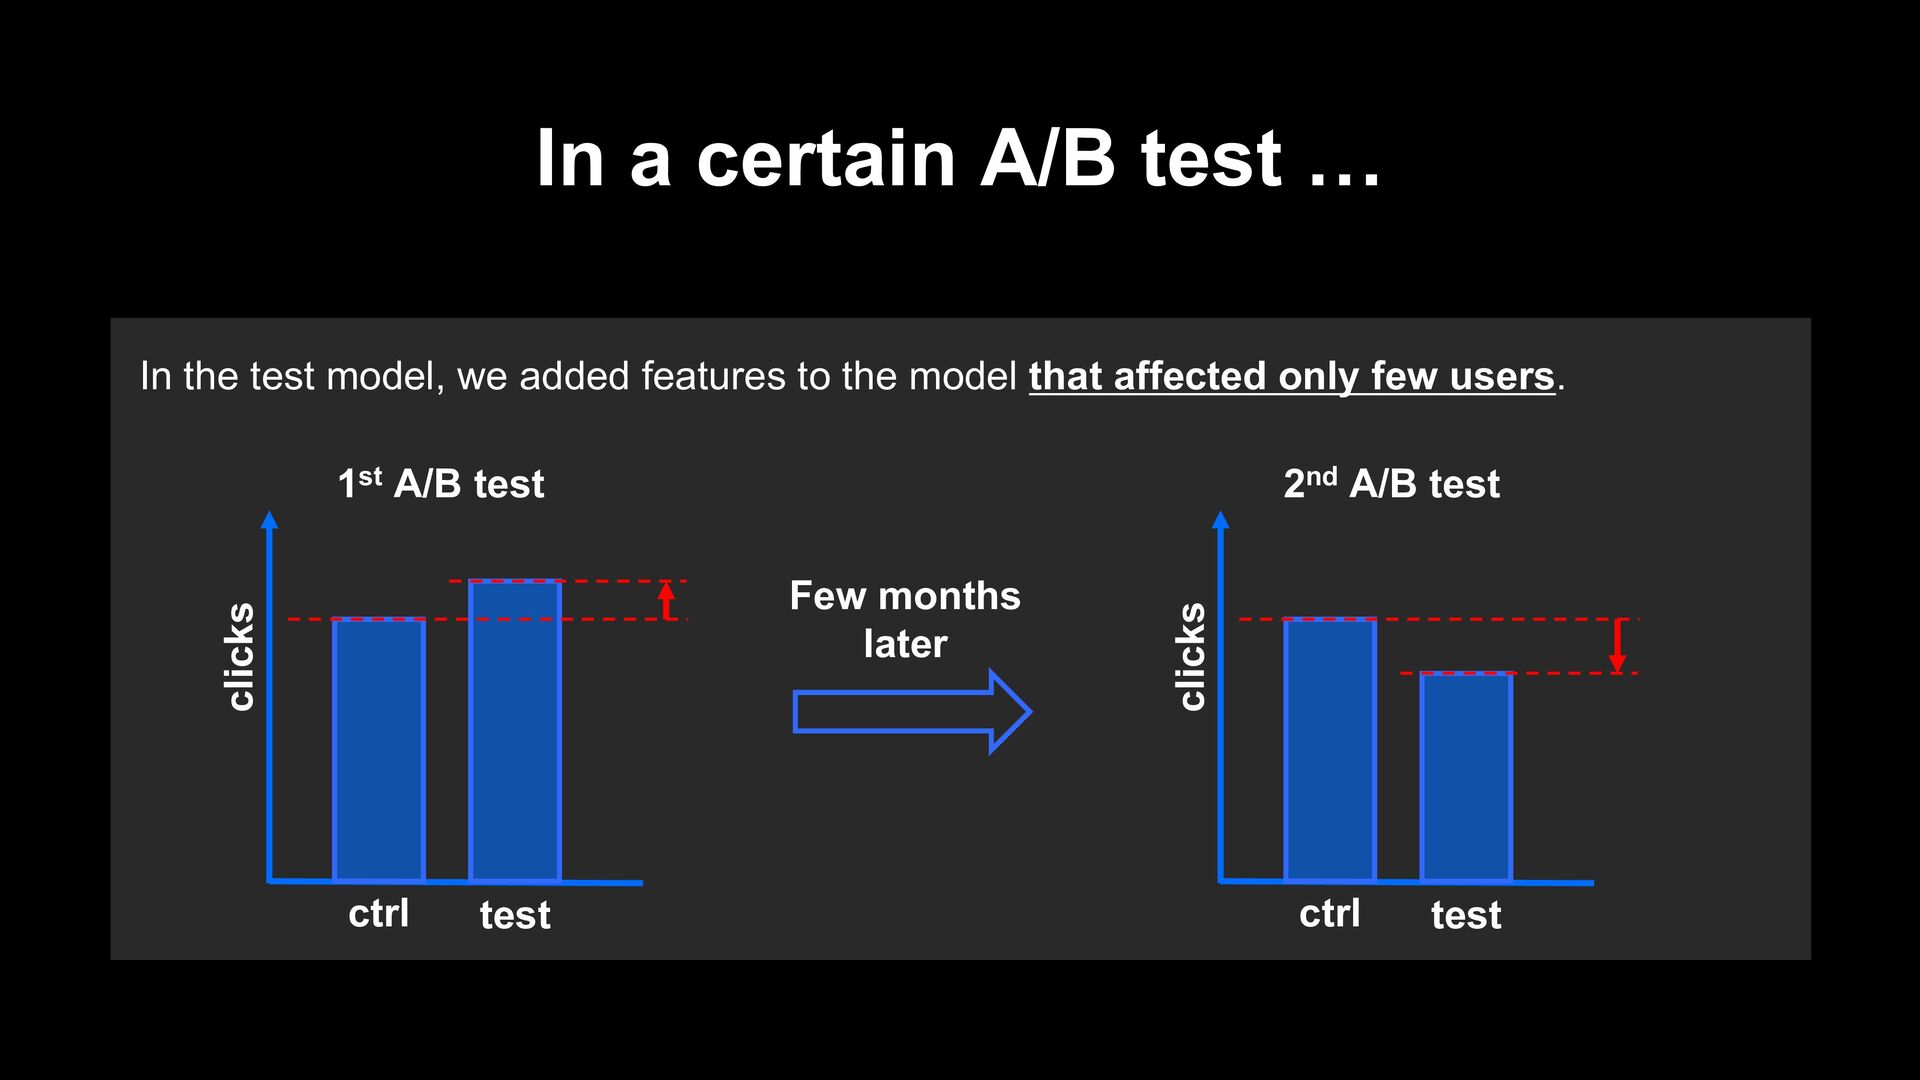
In a certain A/B test … In the test model,
we added features to the model that affected only few users. ctrl test clicks 1st A/B test -
In a certain A/B test … In the test model,
we added features to the model that affected only few users. ctrl test clicks 1st A/B test ctrl test clicks 2nd A/B test Few months later -
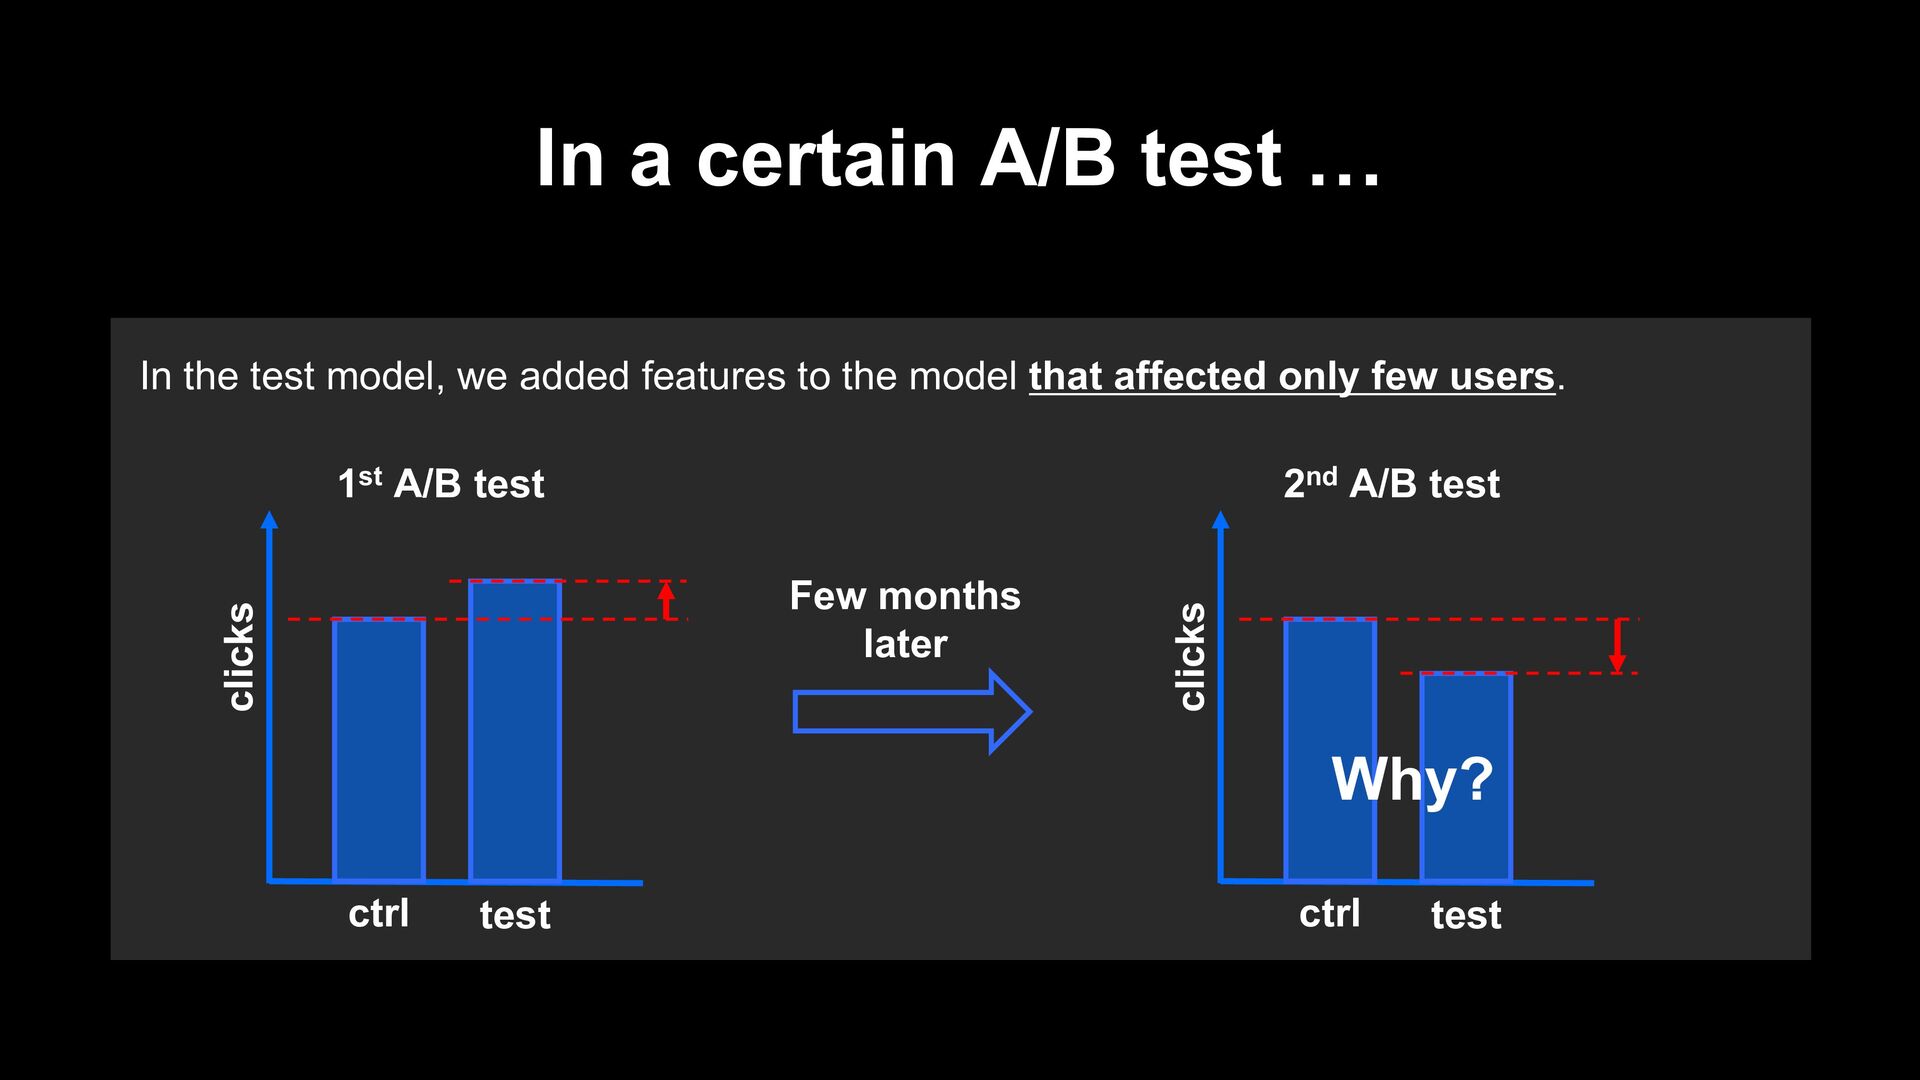
In a certain A/B test … In the test model,
we added features to the model that affected only few users. ctrl test clicks 1st A/B test ctrl test clicks 2nd A/B test Few months later Why? -
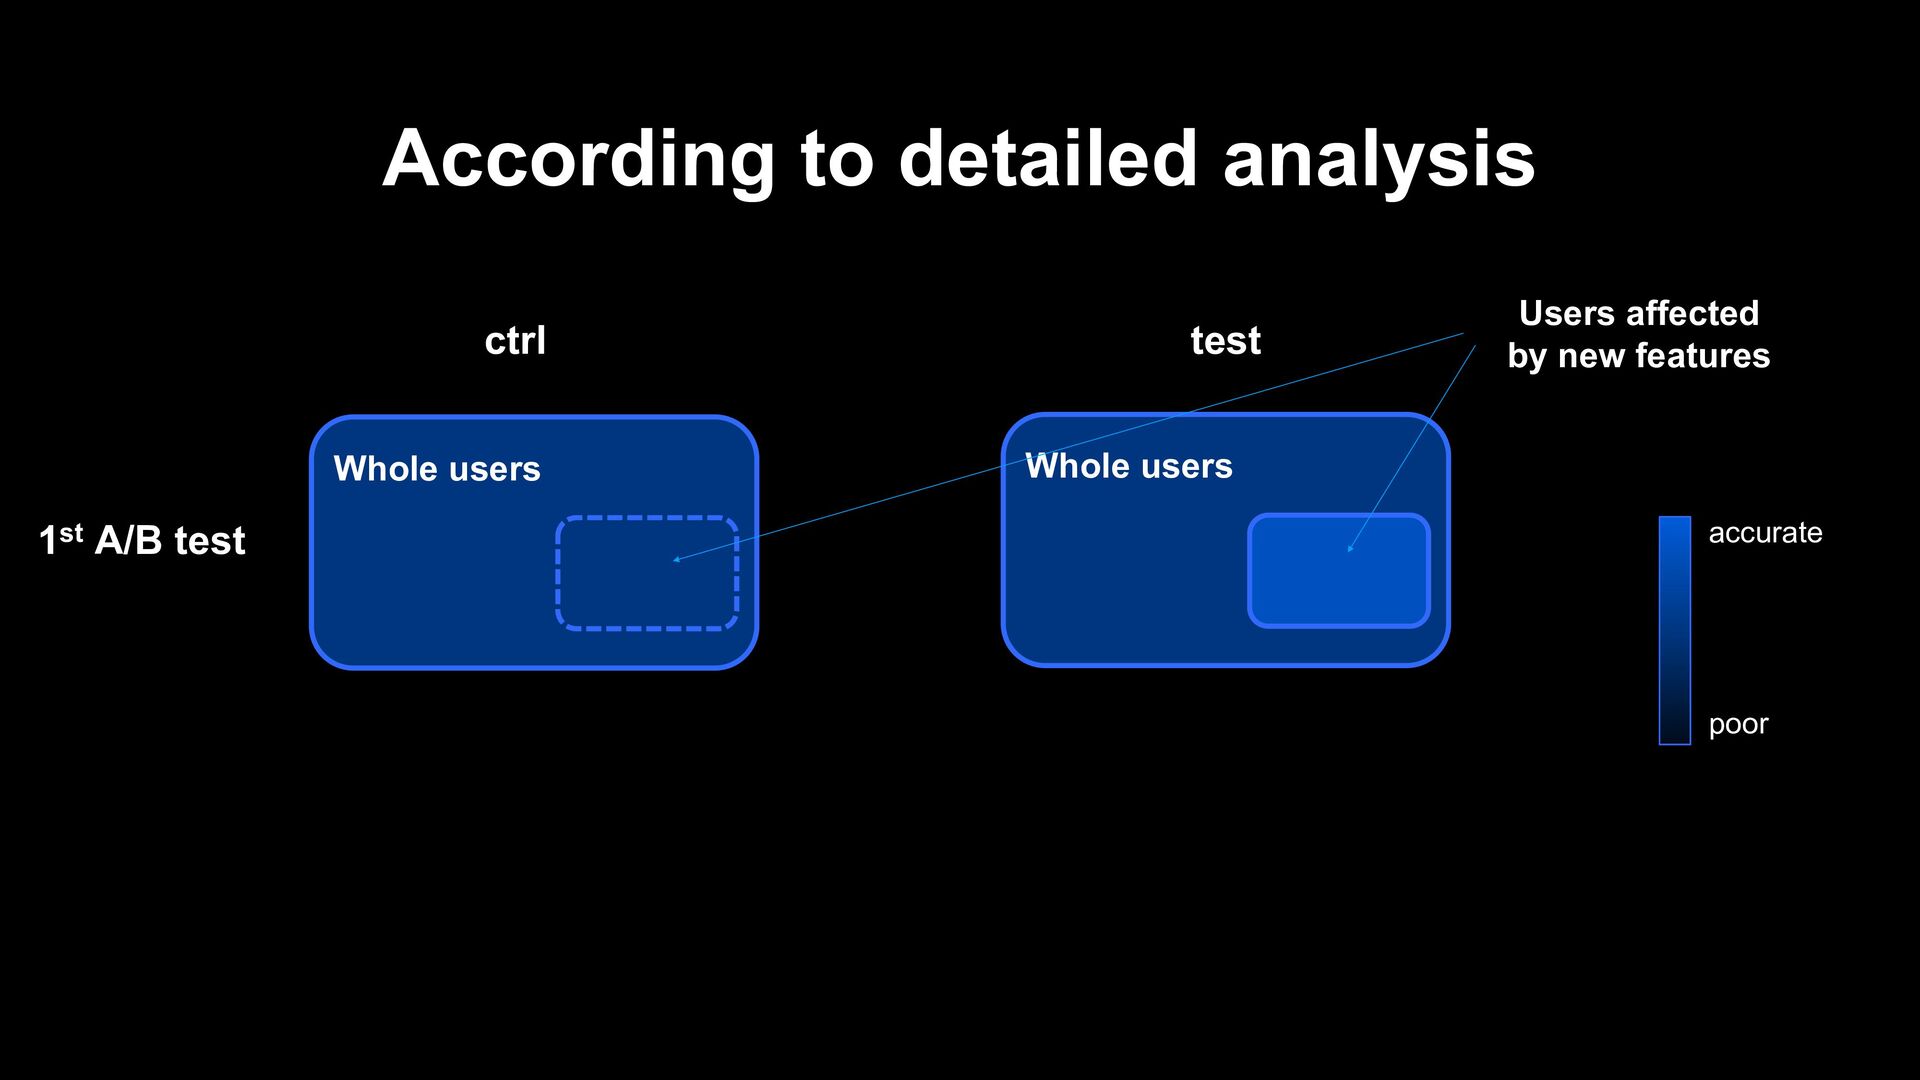
According to detailed analysis Whole users Whole users Users affected
by new features 1st A/B test ctrl test accurate poor -
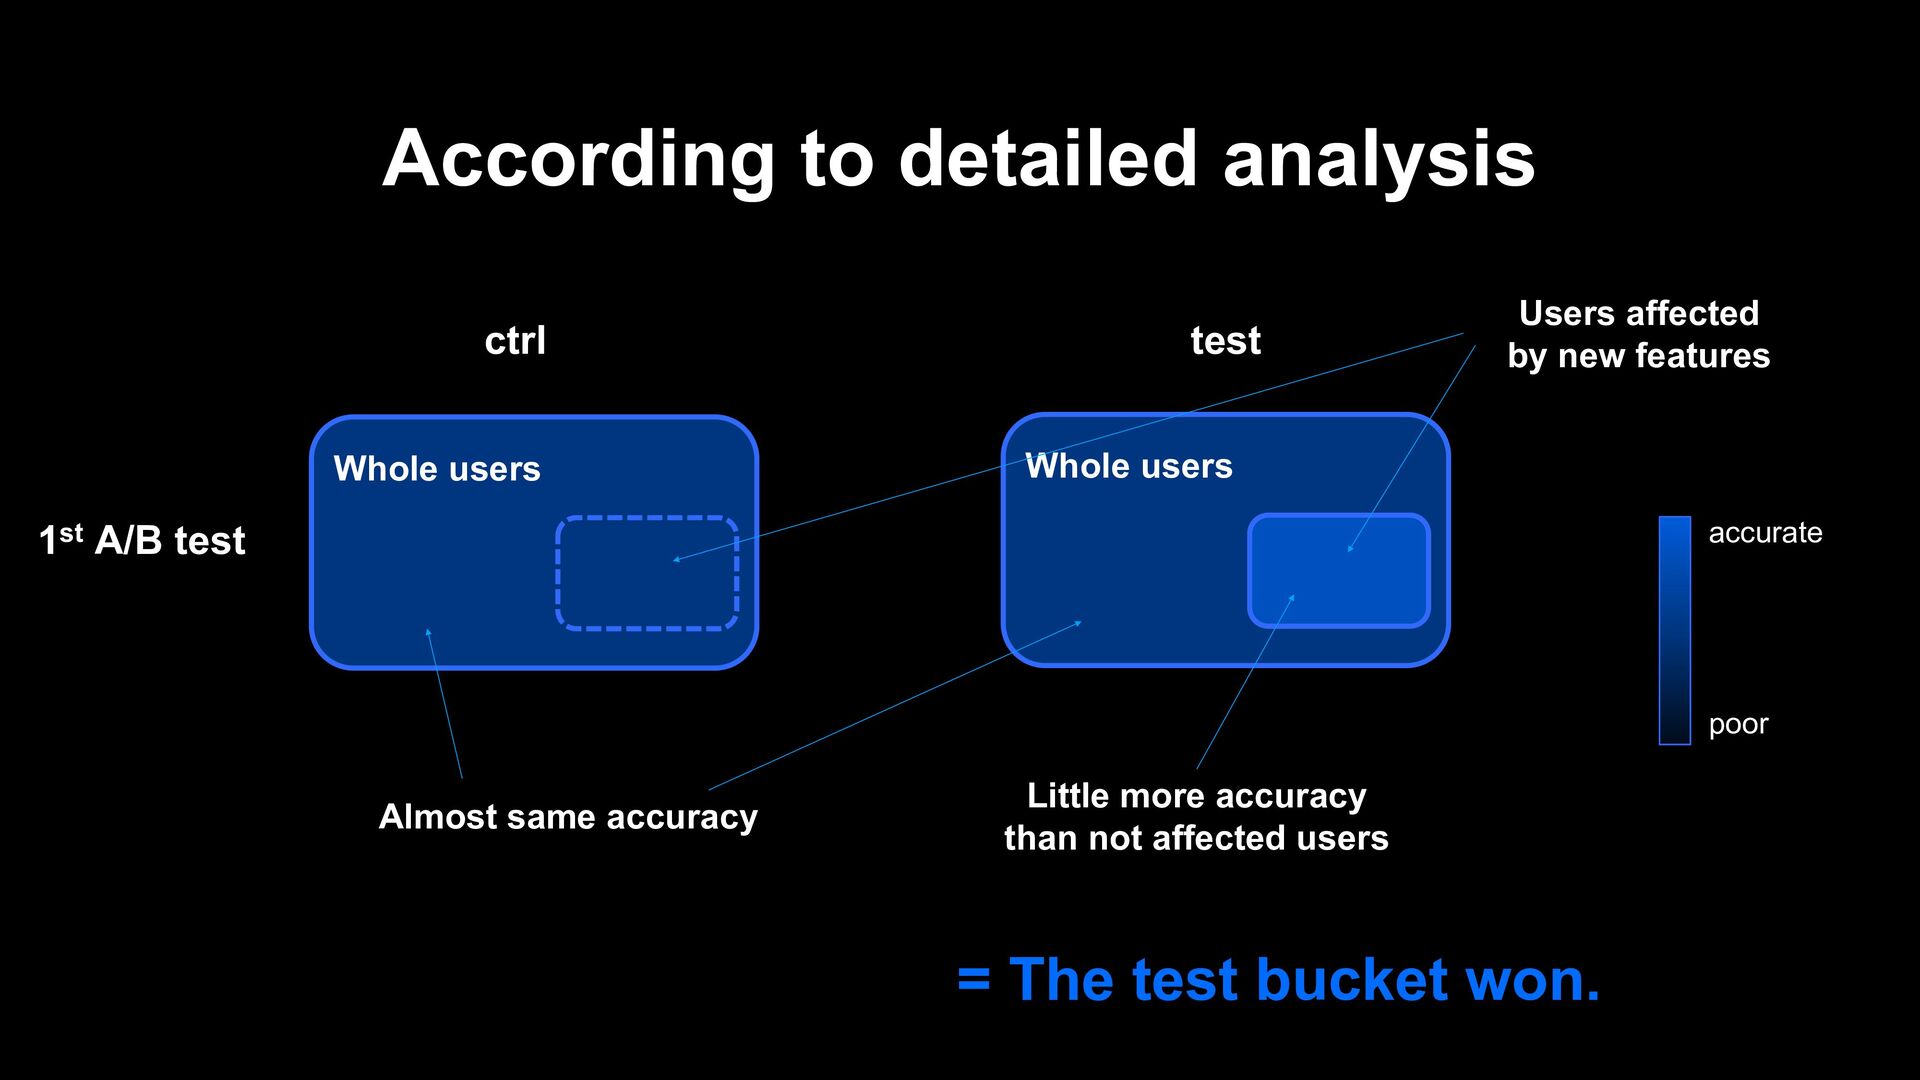
According to detailed analysis Whole users Whole users Users affected
by new features 1st A/B test ctrl test Almost same accuracy Little more accuracy than not affected users = The test bucket won. accurate poor -
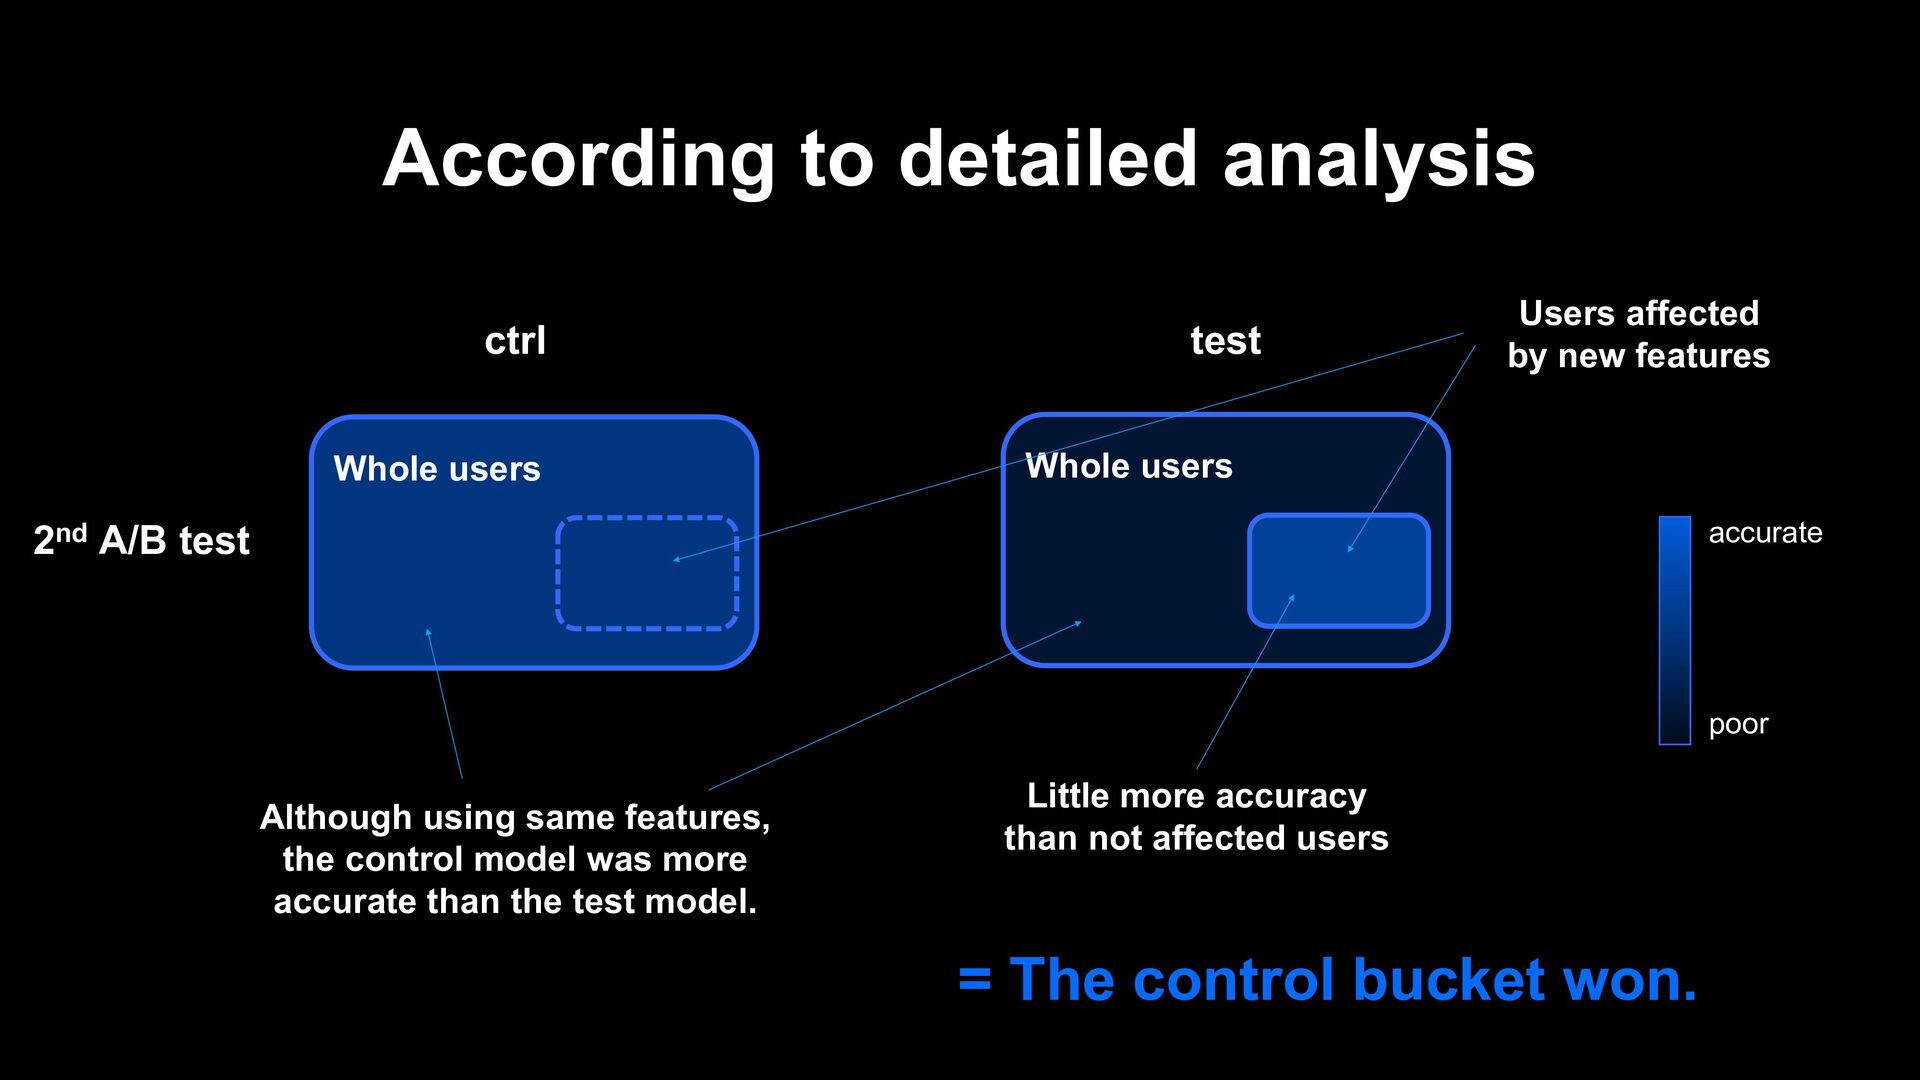
According to detailed analysis Whole users Whole users Users affected
by new features 2nd A/B test ctrl test Although using same features, the control model was more accurate than the test model. Little more accuracy than not affected users = The control bucket won. accurate poor -
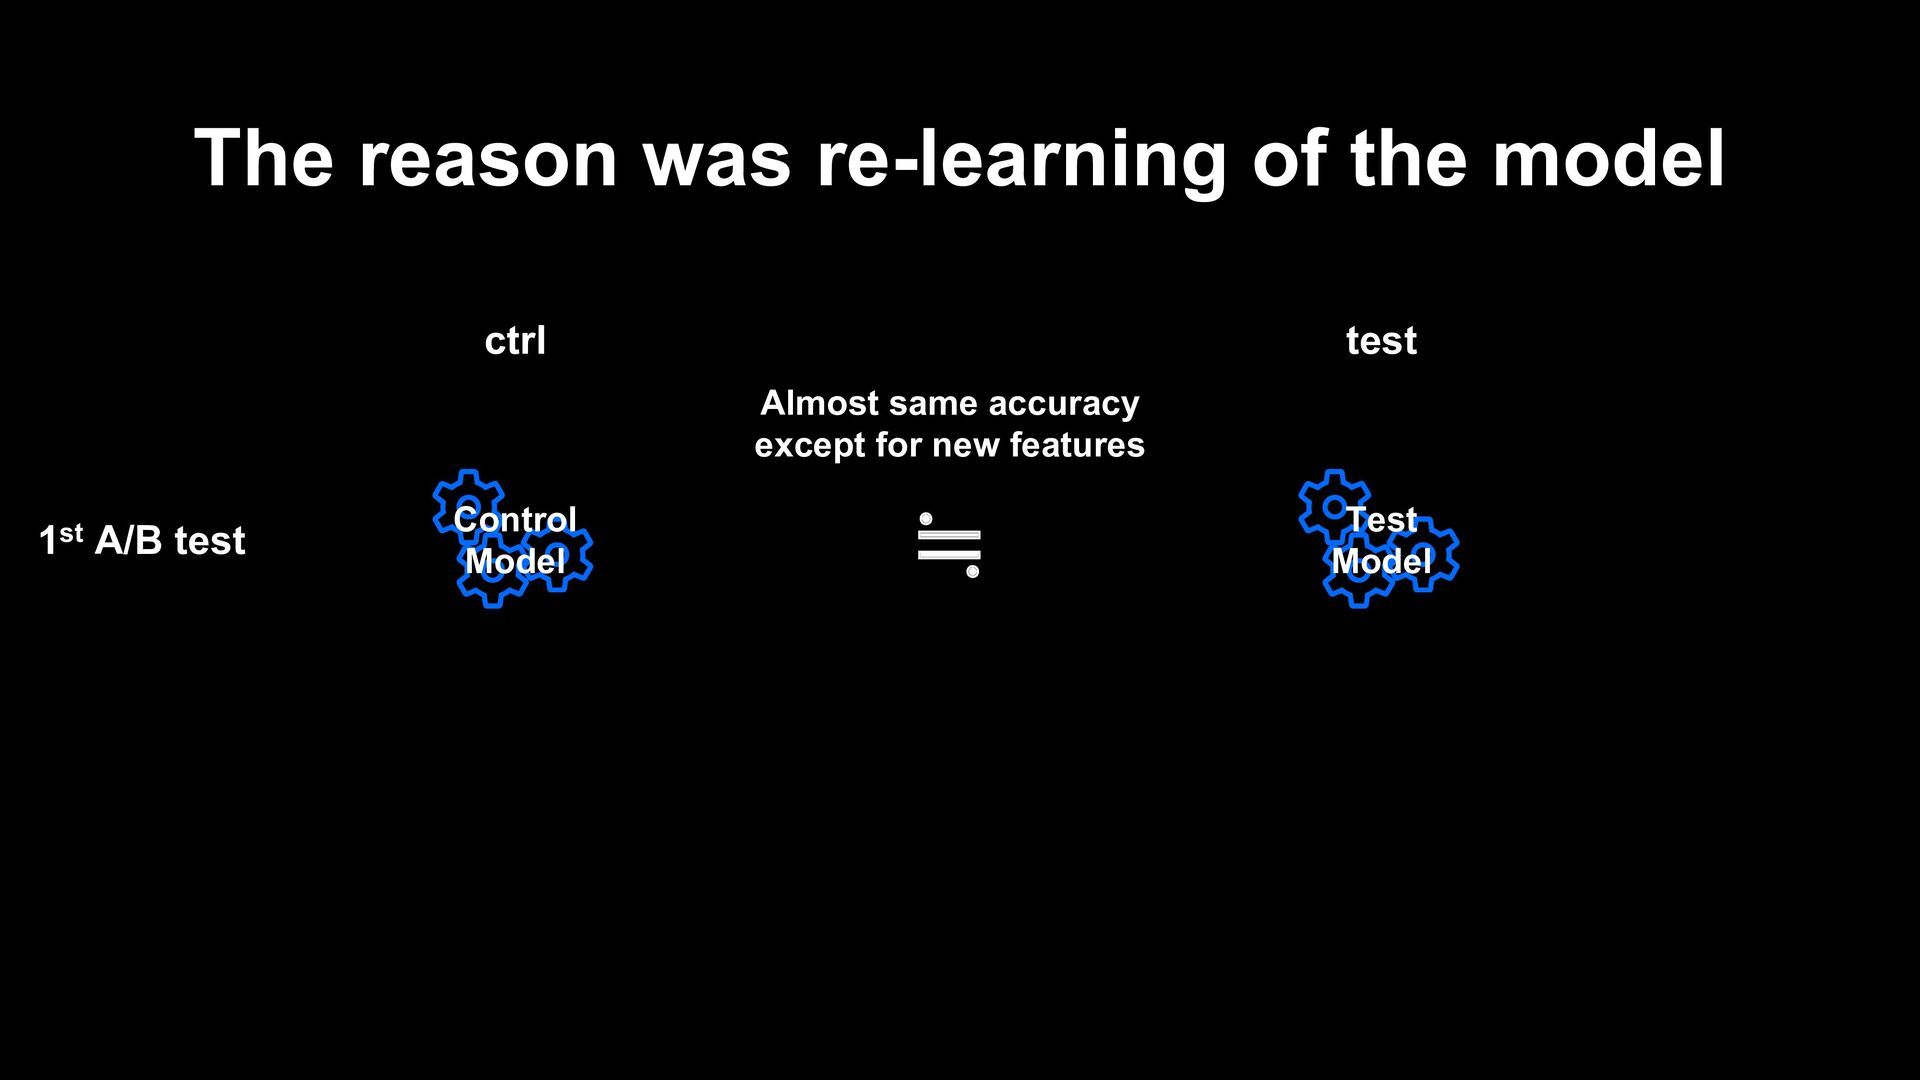
The reason was re-learning of the model 1st A/B test
ctrl test Control Model Test Model ≒ Almost same accuracy except for new features -
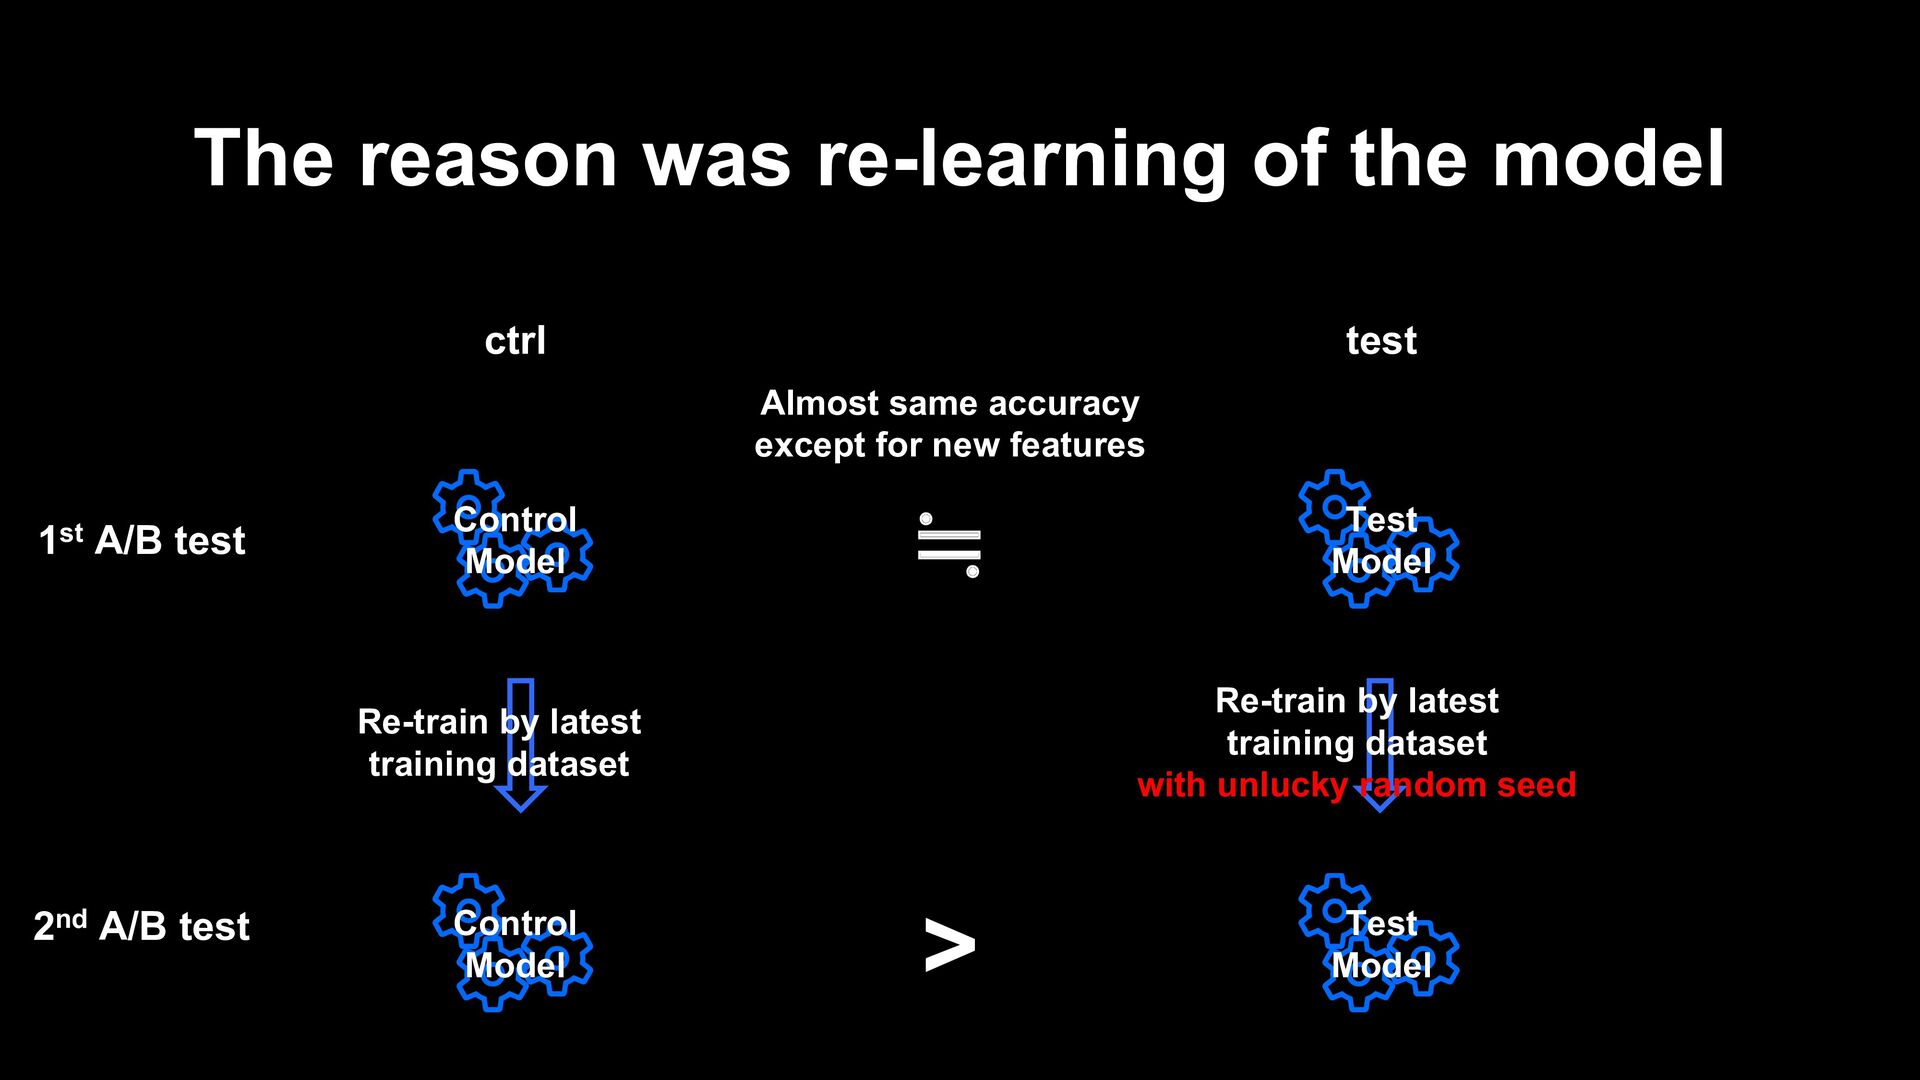
The reason was re-learning of the model 1st A/B test
ctrl test Control Model Test Model ≒ Almost same accuracy except for new features Control Model Test Model 2nd A/B test Re-train by latest training dataset Re-train by latest training dataset with unlucky random seed > -
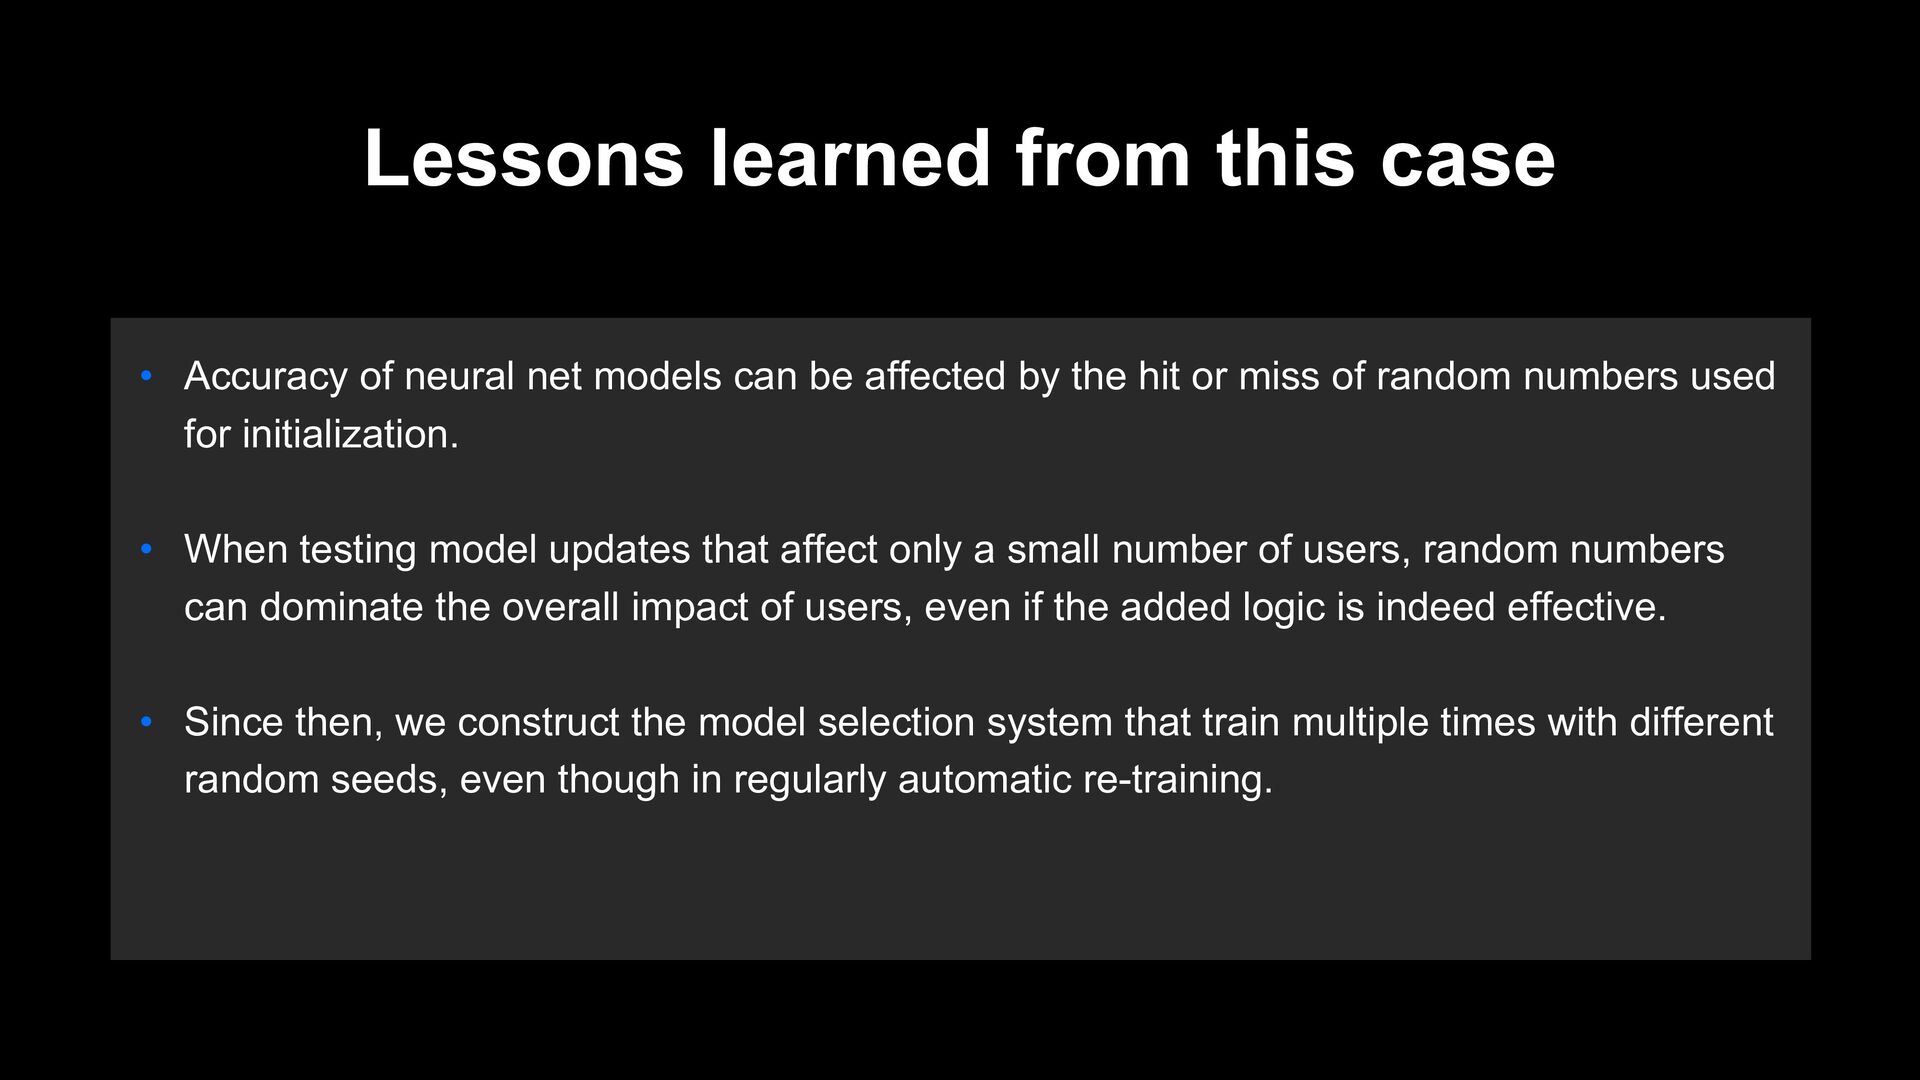
Lessons learned from this case • Accuracy of neural net
models can be affected by the hit or miss of random numbers used for initialization. • When testing model updates that affect only a small number of users, random numbers can dominate the overall impact of users, even if the added logic is indeed effective. • Since then, we construct the model selection system that train multiple times with different random seeds, even though in regularly automatic re-training. -
Summary of this session • I introduced the concept and
overview of our news recommendation system. • I explained how to learn our models. • I introduced some recent issues in our systems and how to deal with them. Thanks for listening