Share
Embed
Machine Learning 101 - CUTI & Tryolabs
Machine Learning 101 meetup presentation. Date: 10/20/2016.
Presented by Martín Alcalá Rubí and Alan Descoins from Tryolabs.
Tryolabs
October 20, 2016
Transcript
40 slides
-
Agenda 1. What is Machine Learning 2. In practice: Python
& its benefits 3. Types of Machine Learning problems 4. Steps needed to solve them 5. How two classification algorithms work a. K-Nearest Neighbors b. Support Vector Machines 6. Evaluating an algorithm a. Overfitting 7. Demo 8. (Very) basic intro to Deep Learning & what follows 7 -
What is Machine Learning? The subfield of computer science that
"gives computers the ability to learn without being explicitly programmed" (Arthur Samuel, 1959). A computer program is said to learn from experience E with respect to some class of tasks T and performance measure P if its performance at tasks in T, as measured by P, improves with experience E” (Tom Mitchell, 1997) • Machine Learning vs AI? 8 -
Why Python? • Simple & powerful • Fast prototyping ◦
Batteries included • Lots of libraries ◦ For everything, not just Machine Learning ◦ Bindings to integrate with other languages • Community ◦ Very active scientific community ◦ Used in academia & industry 10 -
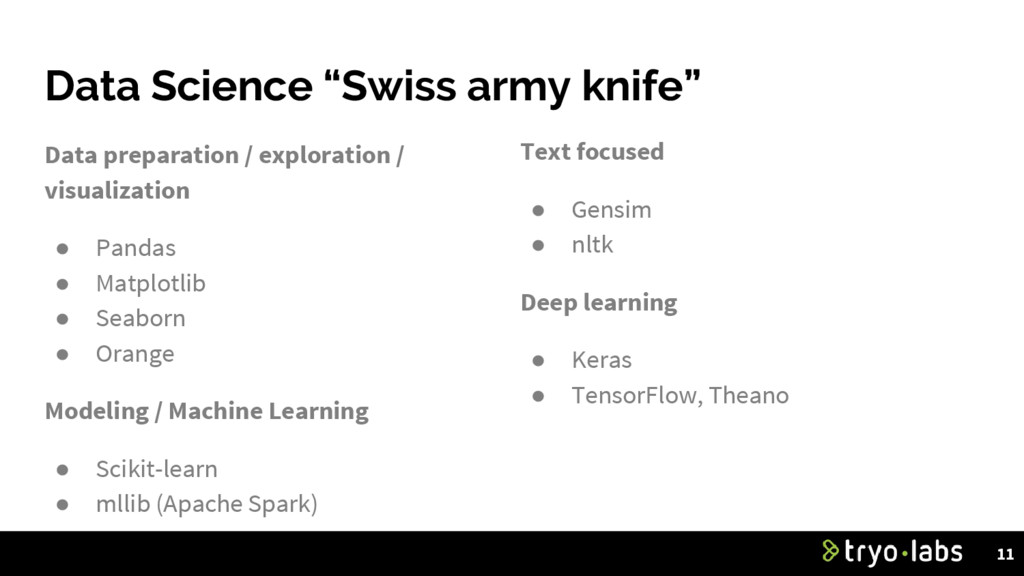
Data Science “Swiss army knife” Data preparation / exploration /
visualization • Pandas • Matplotlib • Seaborn • Orange Modeling / Machine Learning • Scikit-learn • mllib (Apache Spark) Text focused • Gensim • nltk Deep learning • Keras • TensorFlow, Theano 11 -
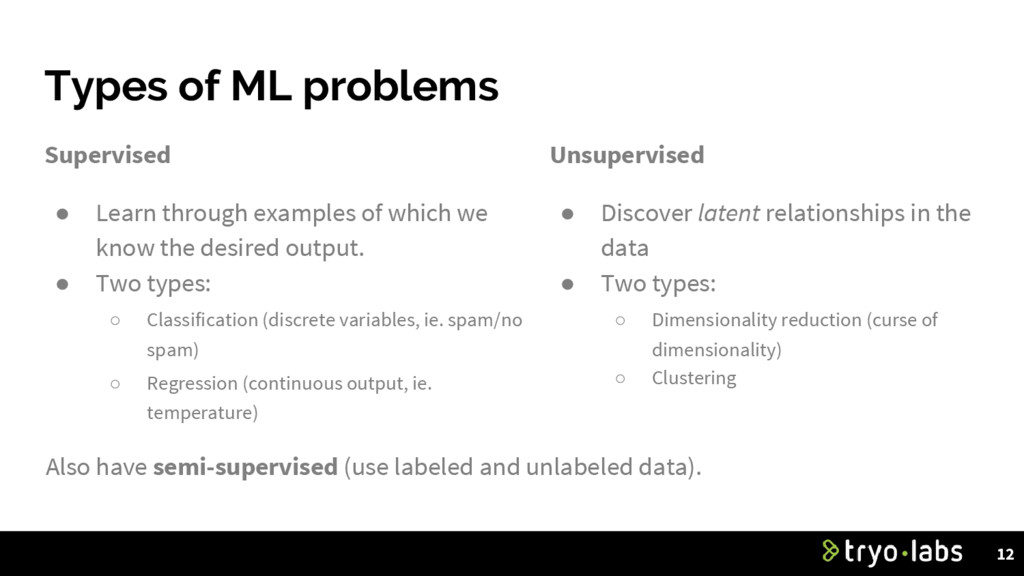
Types of ML problems Supervised • Learn through examples of
which we know the desired output. • Two types: ◦ Classification (discrete variables, ie. spam/no spam) ◦ Regression (continuous output, ie. temperature) 12 Unsupervised • Discover latent relationships in the data • Two types: ◦ Dimensionality reduction (curse of dimensionality) ◦ Clustering Also have semi-supervised (use labeled and unlabeled data). -
Steps in every Machine Learning problem To solve any ML
task, need to go through: 1. Data gathering 2. Data processing & feature engineering 3. Algorithm & training 4. Applying model to make predictions (evaluate, improve) 13 -
Data gathering • Depends on the specific task • Might
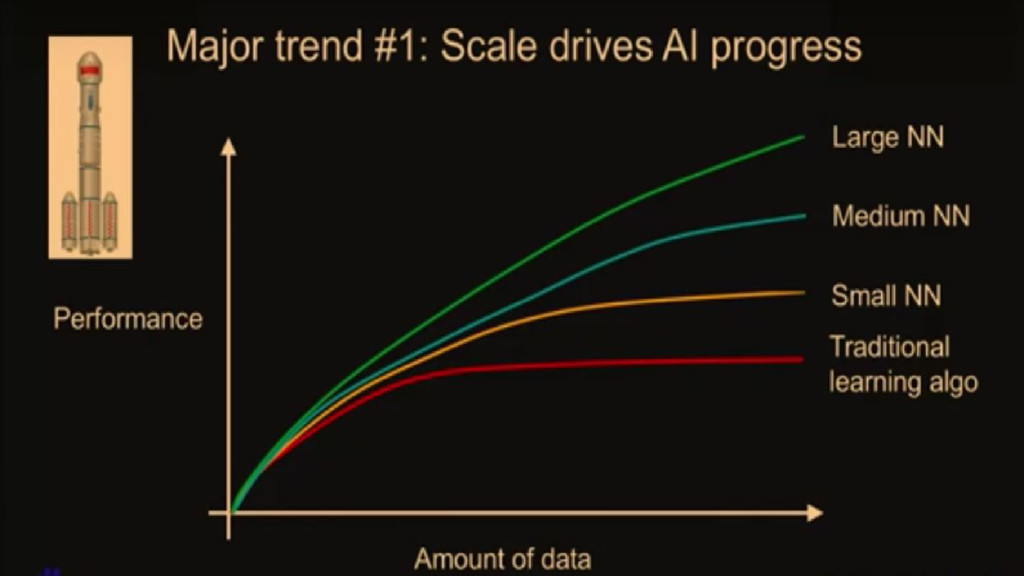
need to put humans to work :( ◦ Ie. Manual labelling for supervised learning ◦ Domain knowledge. Maybe even experts. ◦ Can leverage Mechanical Turk / CrowdFlower. • May come for free, or “sort of” ◦ Ie. Machine Translation. ◦ Categorized articles in Amazon, etc. • The more the better ◦ Some algorithms need large amounts of data to be useful (ie. neural networks). 14 -
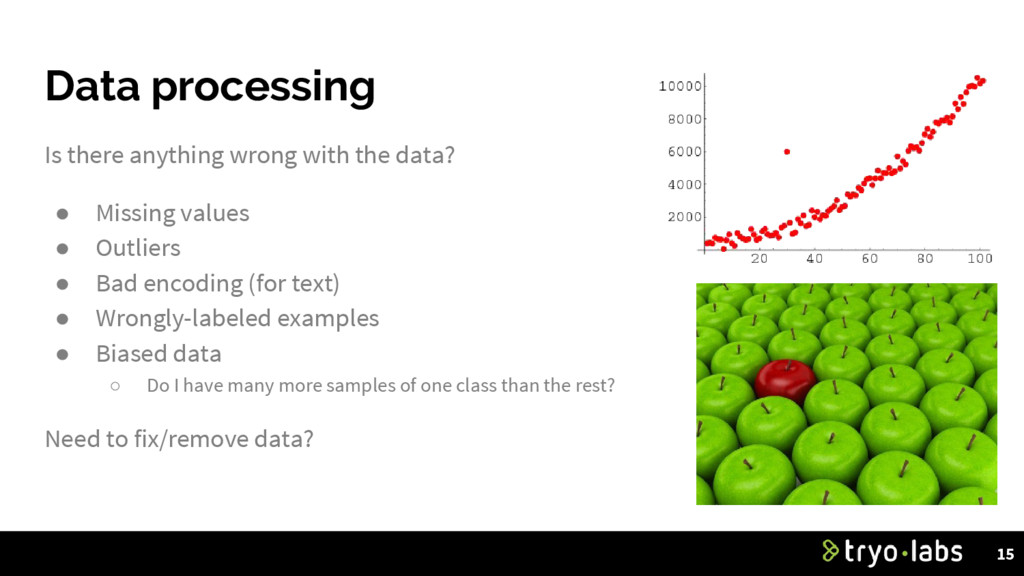
Data processing Is there anything wrong with the data? •
Missing values • Outliers • Bad encoding (for text) • Wrongly-labeled examples • Biased data ◦ Do I have many more samples of one class than the rest? Need to fix/remove data? 15 -
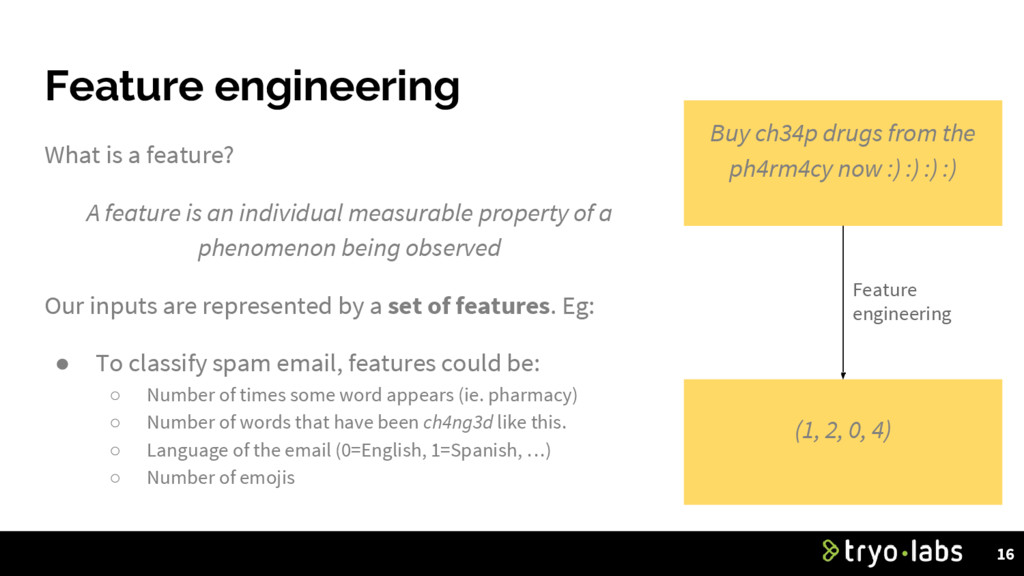
Feature engineering What is a feature? A feature is an
individual measurable property of a phenomenon being observed Our inputs are represented by a set of features. Eg: • To classify spam email, features could be: ◦ Number of times some word appears (ie. pharmacy) ◦ Number of words that have been ch4ng3d like this. ◦ Language of the email (0=English, 1=Spanish, …) ◦ Number of emojis 16 Buy ch34p drugs from the ph4rm4cy now :) :) :) :) (1, 2, 0, 4) Feature engineering -
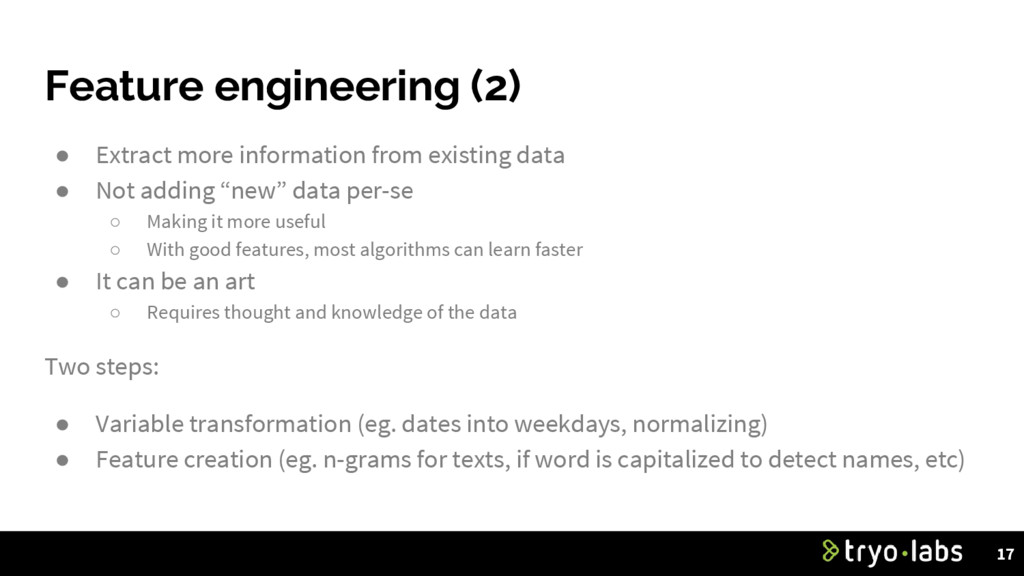
Feature engineering (2) • Extract more information from existing data
• Not adding “new” data per-se ◦ Making it more useful ◦ With good features, most algorithms can learn faster • It can be an art ◦ Requires thought and knowledge of the data Two steps: • Variable transformation (eg. dates into weekdays, normalizing) • Feature creation (eg. n-grams for texts, if word is capitalized to detect names, etc) 17 -
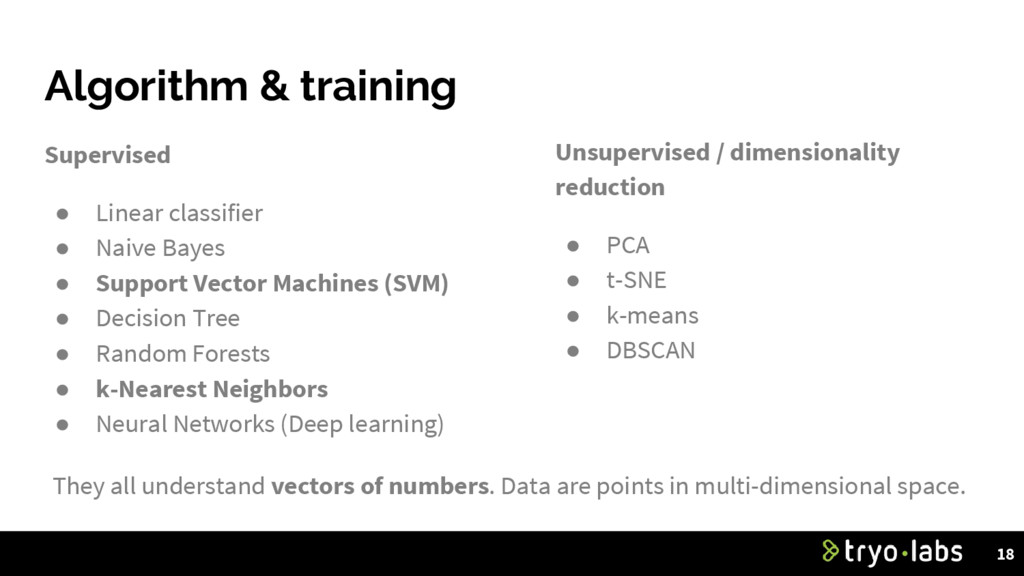
Algorithm & training Supervised • Linear classifier • Naive Bayes
• Support Vector Machines (SVM) • Decision Tree • Random Forests • k-Nearest Neighbors • Neural Networks (Deep learning) Unsupervised / dimensionality reduction • PCA • t-SNE • k-means • DBSCAN They all understand vectors of numbers. Data are points in multi-dimensional space. 18 -
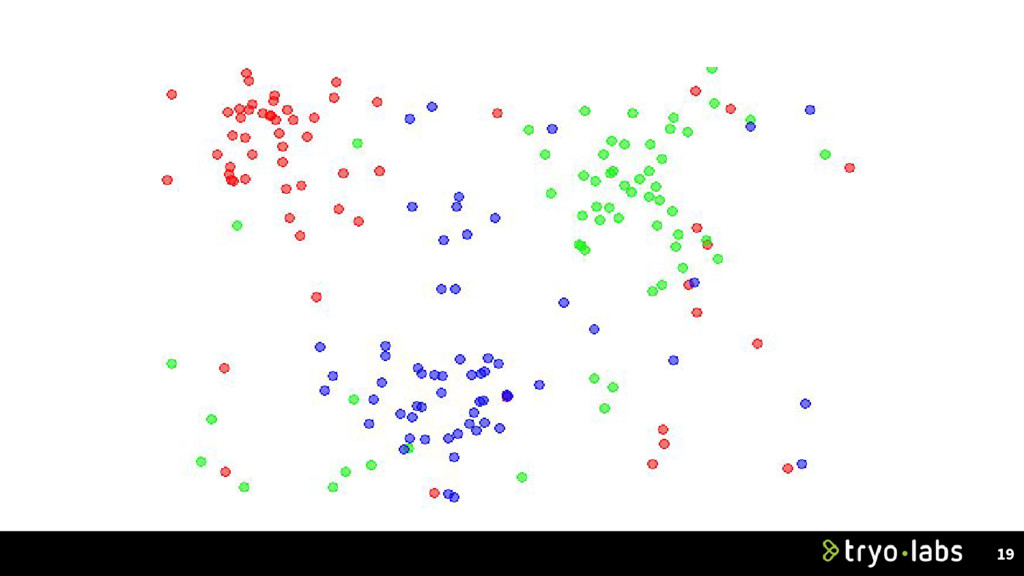
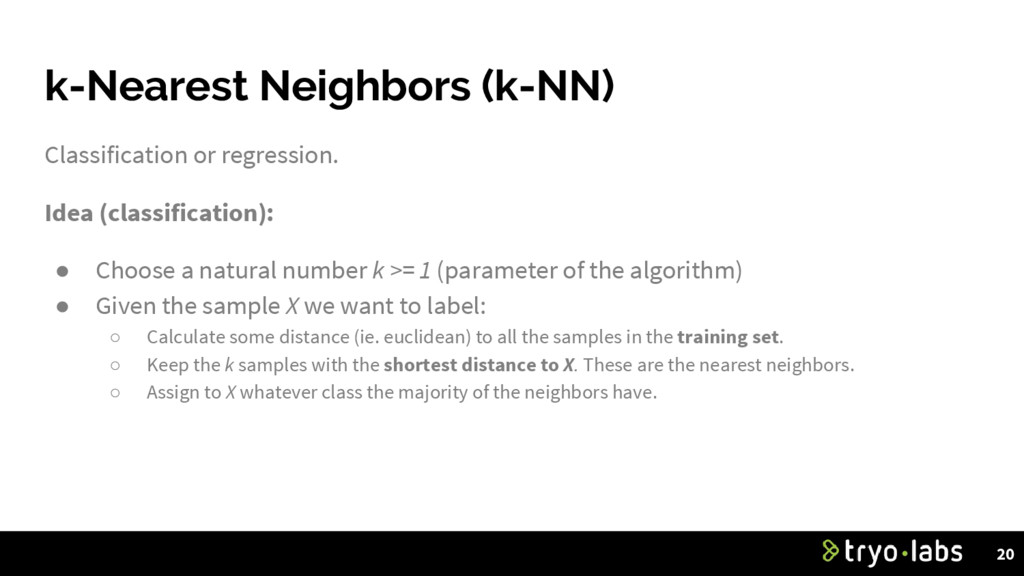
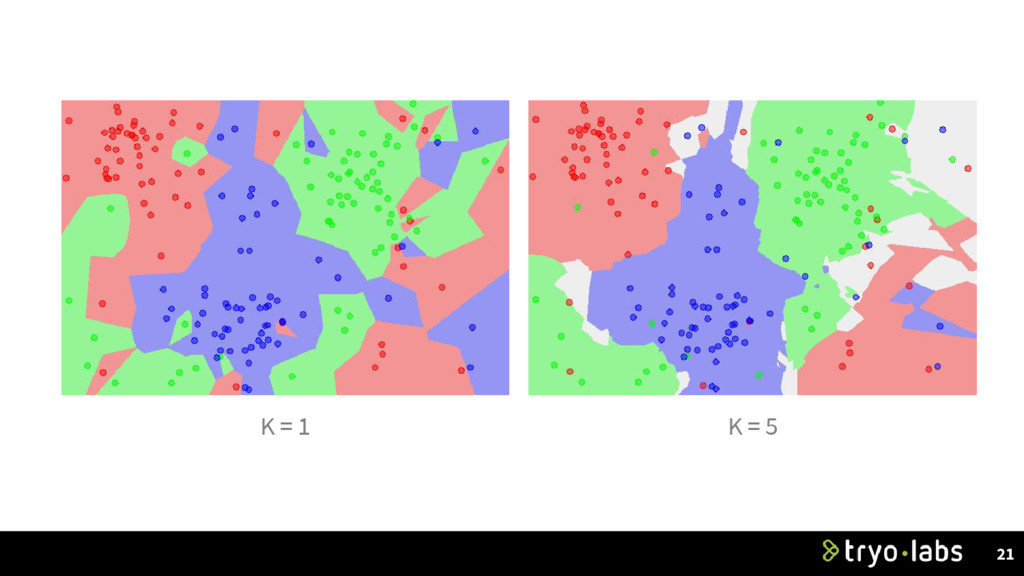
k-Nearest Neighbors (k-NN) Classification or regression. Idea (classification): • Choose
a natural number k >= 1 (parameter of the algorithm) • Given the sample X we want to label: ◦ Calculate some distance (ie. euclidean) to all the samples in the training set. ◦ Keep the k samples with the shortest distance to X. These are the nearest neighbors. ◦ Assign to X whatever class the majority of the neighbors have. 20 -
k-Nearest Neighbors (k-NN) (2) • Fast computation of nearest neighbors
is an active area of research. • Naive brute-force approach computes distance to all points, need to keep entire dataset in memory at classification time (no offline training). • Need to experiment to get the right k. There are other algorithms that use approximations to deal with these inefficiencies. 22 -
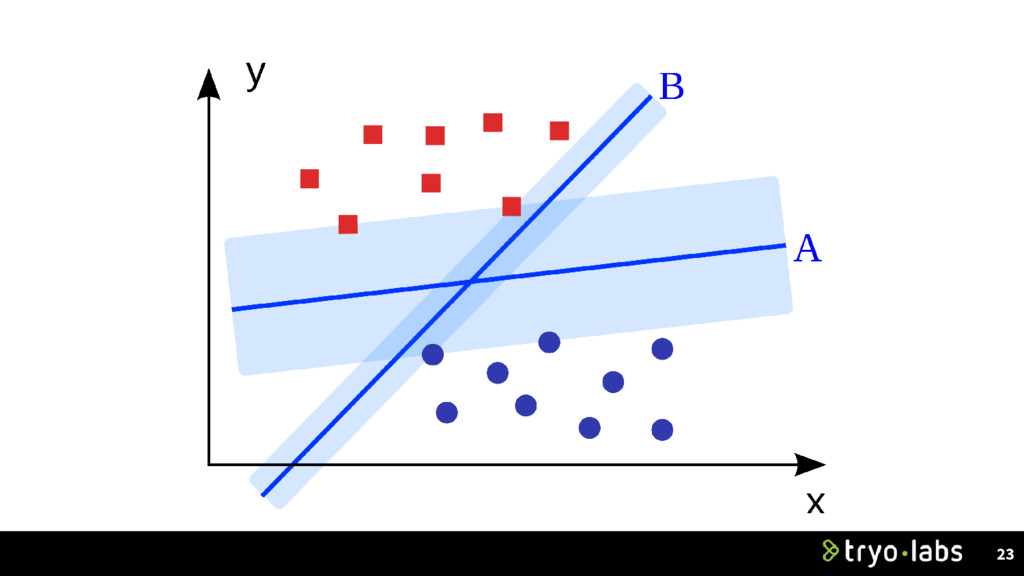
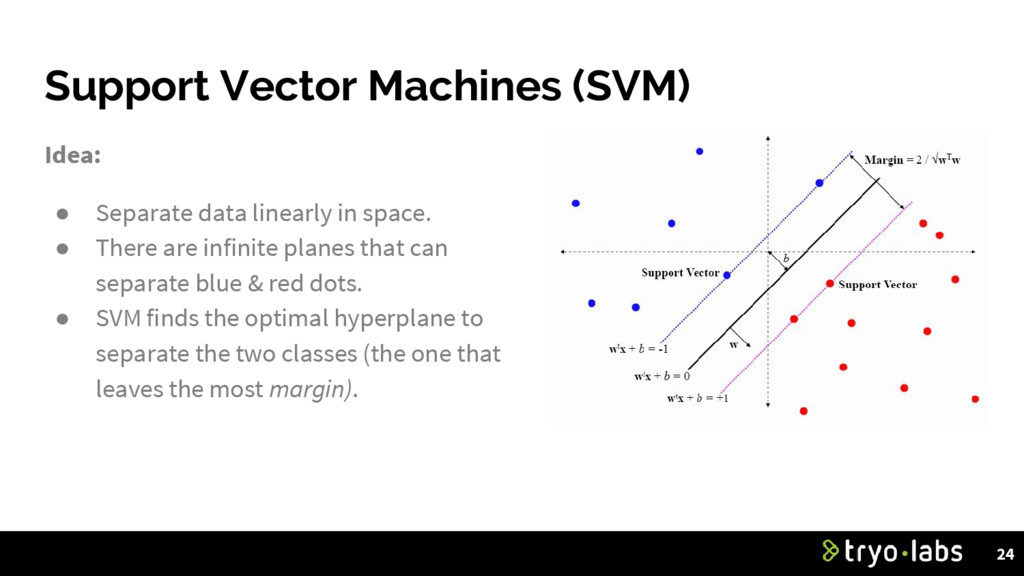
Support Vector Machines (SVM) Idea: • Separate data linearly in
space. • There are infinite planes that can separate blue & red dots. • SVM finds the optimal hyperplane to separate the two classes (the one that leaves the most margin). 24 -
Support Vector Machines (SVM) (2) • SVMs focus only on
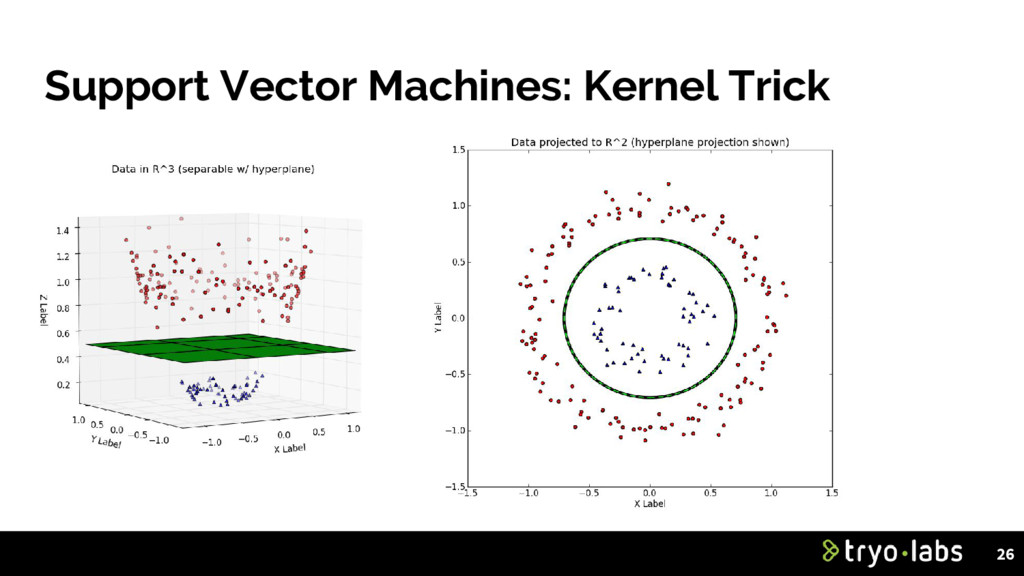
the points that are the most difficult to tell apart (other classifiers pay attention to all the points). • We call them the support vectors. • Decision boundary doesn’t change if we add more samples that are outside the margin. • Can achieve good accuracy with fewer training samples compared to other algorithms. Only works if data is linearly separable. • If not, can use a kernel to transform it to a higher dimension. 25 -
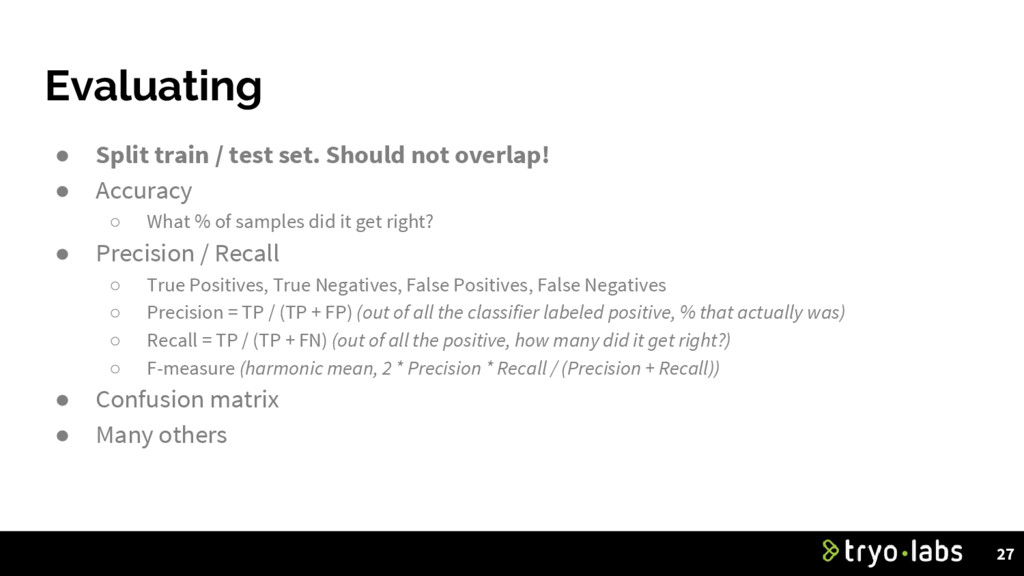
Evaluating • Split train / test set. Should not overlap!
• Accuracy ◦ What % of samples did it get right? • Precision / Recall ◦ True Positives, True Negatives, False Positives, False Negatives ◦ Precision = TP / (TP + FP) (out of all the classifier labeled positive, % that actually was) ◦ Recall = TP / (TP + FN) (out of all the positive, how many did it get right?) ◦ F-measure (harmonic mean, 2 * Precision * Recall / (Precision + Recall)) • Confusion matrix • Many others 27 -
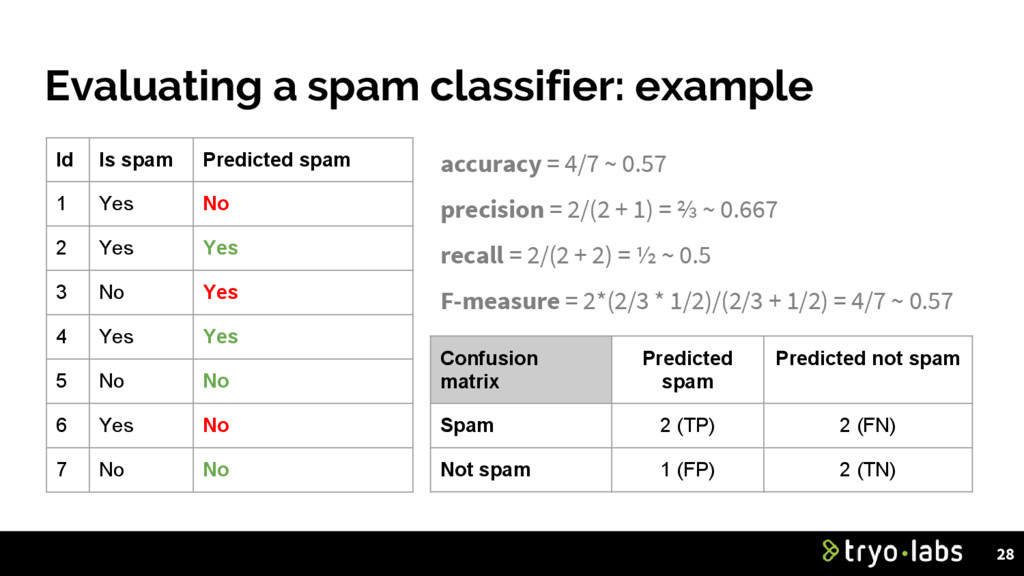
Evaluating a spam classifier: example 28 Id Is spam Predicted
spam 1 Yes No 2 Yes Yes 3 No Yes 4 Yes Yes 5 No No 6 Yes No 7 No No accuracy = 4/7 ~ 0.57 precision = 2/(2 + 1) = ⅔ ~ 0.667 recall = 2/(2 + 2) = ½ ~ 0.5 F-measure = 2*(2/3 * 1/2)/(2/3 + 1/2) = 4/7 ~ 0.57 Confusion matrix Predicted spam Predicted not spam Spam 2 (TP) 2 (FN) Not spam 1 (FP) 2 (TN) -
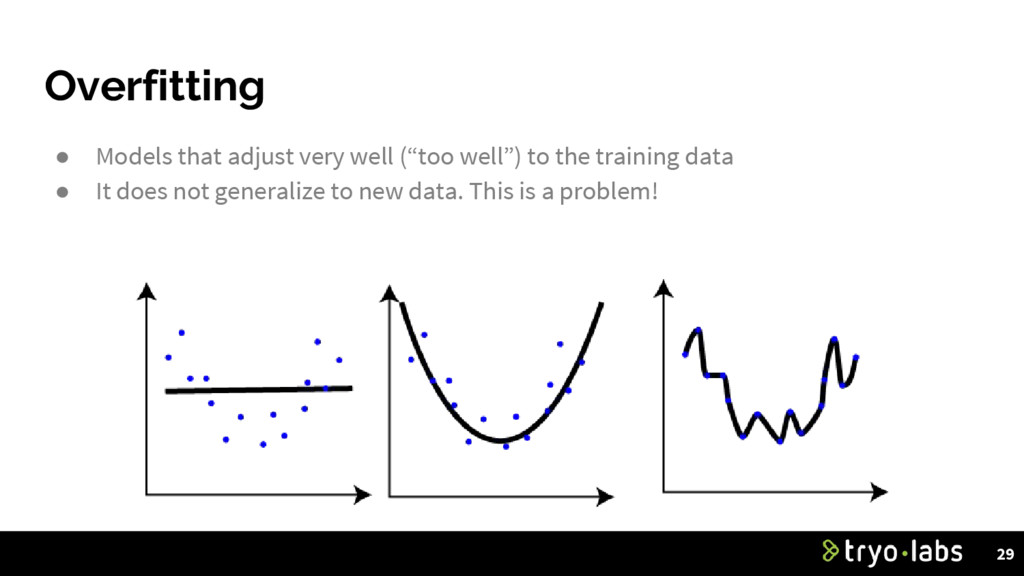
Overfitting • Models that adjust very well (“too well”) to
the training data • It does not generalize to new data. This is a problem! 29 -
Preventing overfitting • Detect outliers in the data • Simple
is better than complex ◦ Fewer parameters to tune can bring better performance. ◦ Eliminate degrees of freedom. Eg. polynomial. ◦ Regularization (penalize complexity). • K-fold cross validation (different train/test partitions) • Get more training data! 30 -
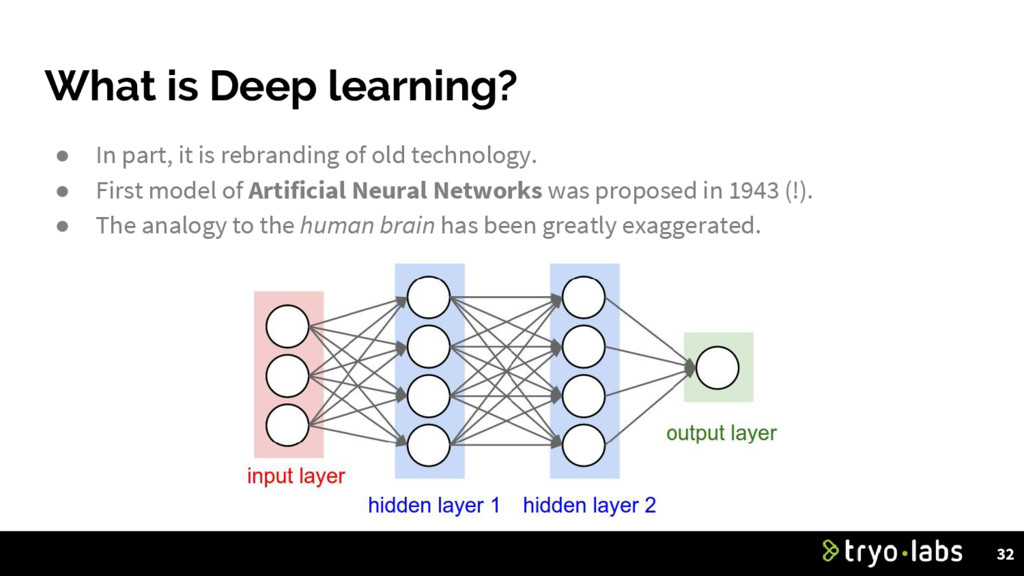
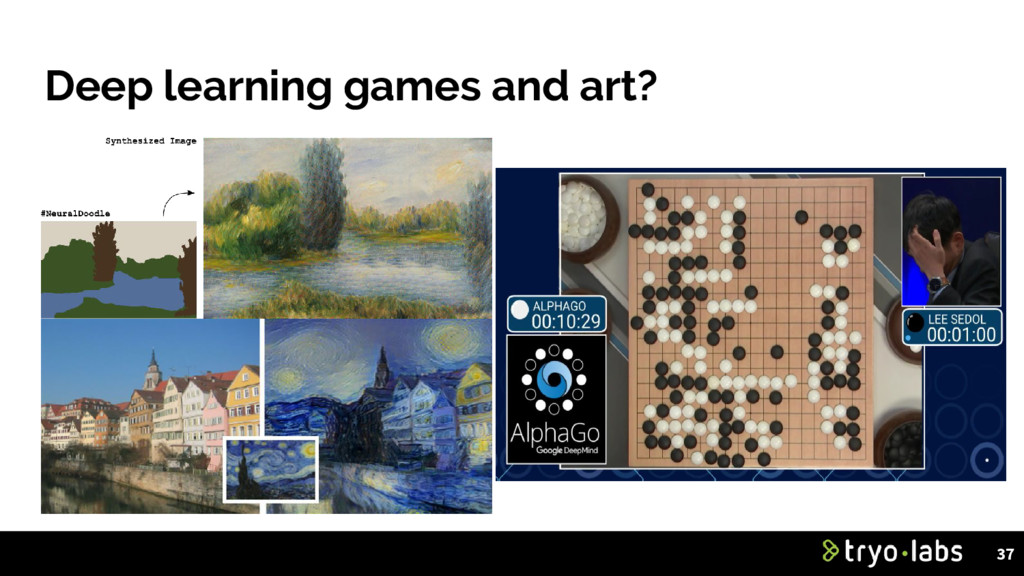
What is Deep learning? • In part, it is rebranding
of old technology. • First model of Artificial Neural Networks was proposed in 1943 (!). • The analogy to the human brain has been greatly exaggerated. 32 -
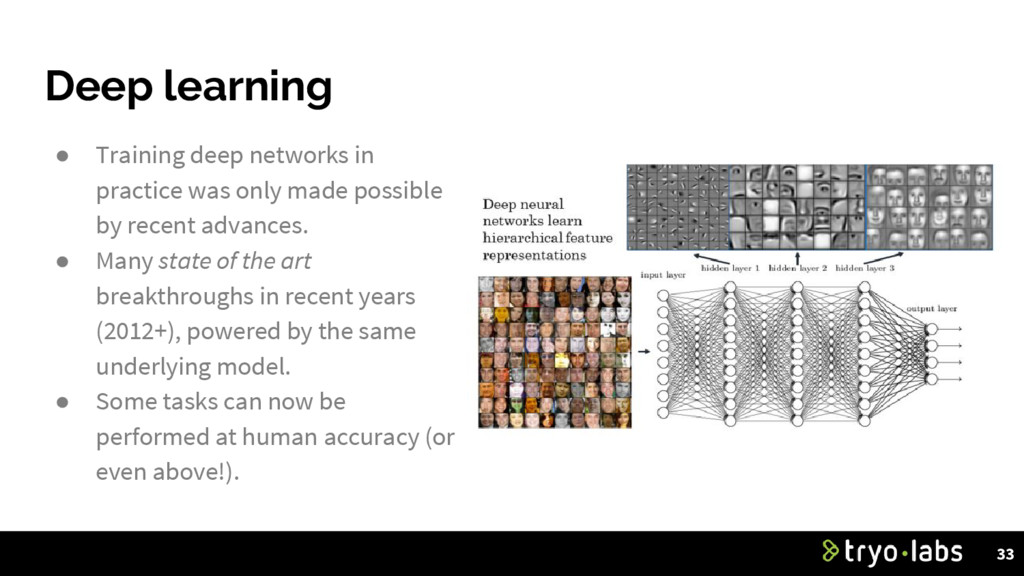
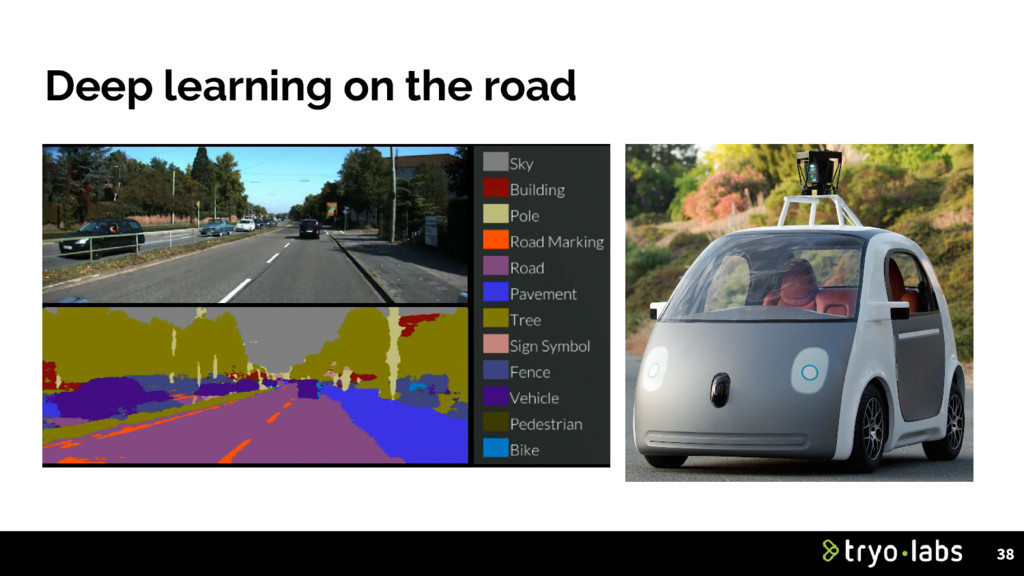
Deep learning • Training deep networks in practice was only
made possible by recent advances. • Many state of the art breakthroughs in recent years (2012+), powered by the same underlying model. • Some tasks can now be performed at human accuracy (or even above!). 33 -
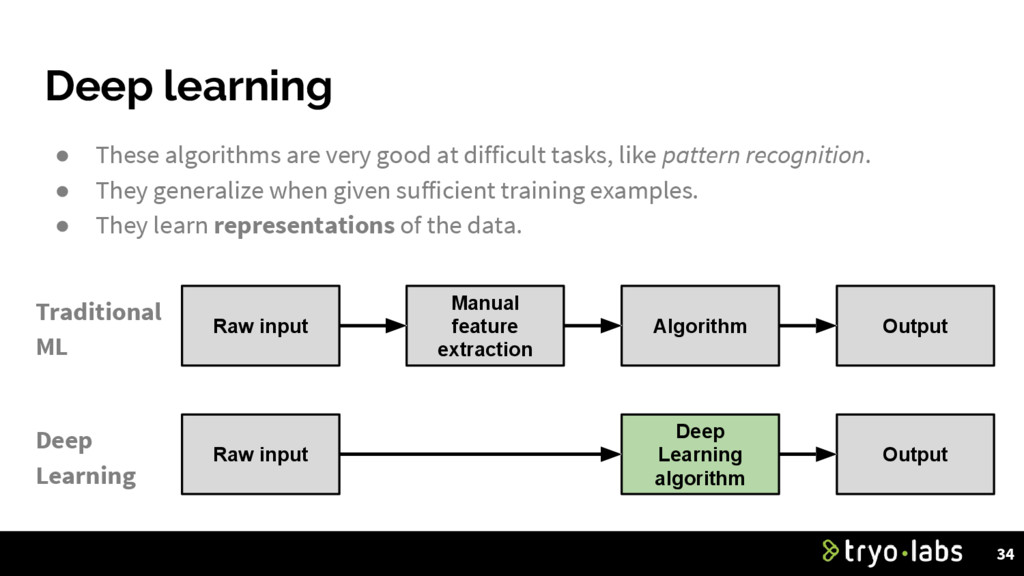
Deep learning 34 Raw input Manual feature extraction Algorithm Output
• These algorithms are very good at difficult tasks, like pattern recognition. • They generalize when given sufficient training examples. • They learn representations of the data. Raw input Deep Learning algorithm Output Traditional ML Deep Learning -
What follows There is A LOT to learn! Many active
research areas and infinite applications. We are living a revolution. • Rapid progress, need to keep up ;) • Entry barrier for using these technologies is lower than ever. • Processing power keeps increasing, models keep getting better. • What is the limit? 39