Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
金研究室 勉強会 『もう一度理解する Transformer(前編)』
Search
winnie279
July 12, 2022
Science
150
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
金研究室 勉強会 『もう一度理解する Transformer(前編)』
もう一度理解するTransformer(前編), 中村勇士, 2022
winnie279
July 12, 2022
More Decks by winnie279
See All by winnie279
NowWay:訪⽇外国⼈旅⾏者向けの災害⽀援サービス
yjn279
0
46
「みえるーむ」(都知事杯Open Data Hackathon 2024 Final Stage)
yjn279
0
120
「みえるーむ」(都知事杯オープンデータ・ハッカソン 2024)
yjn279
0
100
5分で学ぶOpenAI APIハンズオン
yjn279
0
260
『確率思考の戦略論』
yjn279
0
170
Amazonまでのレコメンド入門
yjn279
1
210
もう一度理解するTransformer(後編)
yjn279
0
100
金研究室 勉強会 『U-Netとそのバリエーションについて』
yjn279
0
1.1k
金研究室 勉強会 『Seismic Data Augmentation Based on Conditional Generative Adversarial Networks』
yjn279
0
140
Other Decks in Science
See All in Science
1. CPC理論の展開と集合的知能モデル(JSAI2026 KS-27 集合的予測符号化と新たな知性の時代)
hayashiyus884
1
410
20260410_SystemsThinking
takusamar
1
160
生成AI時代のインタラクションサイエンス(招待講演)/interaction-science
okana2ki
0
110
データベース04: SQL (1/3) 単純質問 & 集約演算
trycycle
PRO
0
1.8k
サンプル対応のない複数遺伝子発現プロファイルに対するテンソル分解型統合解析の要約
tagtag
PRO
0
270
How a camera trap data standard enabled an ecosystem of interoperable tools
peterdesmet
0
140
機械学習 - 決定木からはじめる機械学習
trycycle
PRO
0
1.7k
Massey Ratings for Match Outcome Prediction in Table Tennis: Evidence of Greater Stability than the ITTF World Ranking
konakalab
0
160
Leitner Inauguration Lecture Chalmers University of Technology
xleitix
0
380
Build your own LLM, Live, with MicroGPT
ianozsvald
0
160
HOLO: Homography-Guided Pose Estimator Network for Fine-Grained Visual Localization on SD Maps
tomoaki0705
0
170
[第67回 CV勉強会@関東] CV × Scientific Figures / kantoCV 67th CVPR 2026
lychee1223
0
250
Featured
See All Featured
Designing Experiences People Love
moore
143
24k
Making the Leap to Tech Lead
cromwellryan
135
10k
Unlocking the hidden potential of vector embeddings in international SEO
frankvandijk
0
980
技術選定の審美眼(2025年版) / Understanding the Spiral of Technologies 2025 edition
twada
PRO
120
120k
How to Build an AI Search Optimization Roadmap - Criteria and Steps to Take #SEOIRL
aleyda
1
2.2k
What's in a price? How to price your products and services
michaelherold
247
13k
Balancing Empowerment & Direction
lara
6
1.3k
Fireside Chat
paigeccino
43
4.1k
Leadership Guide Workshop - DevTernity 2021
reverentgeek
1
400
DBのスキルで生き残る技術 - AI時代におけるテーブル設計の勘所
soudai
PRO
68
58k
Designing for humans not robots
tammielis
254
26k
Measuring Dark Social's Impact On Conversion and Attribution
stephenakadiri
2
310
Transcript
もう一度理解する Transformer(前編) 金研 機械学習勉強会 2022/07/12 中村勇士
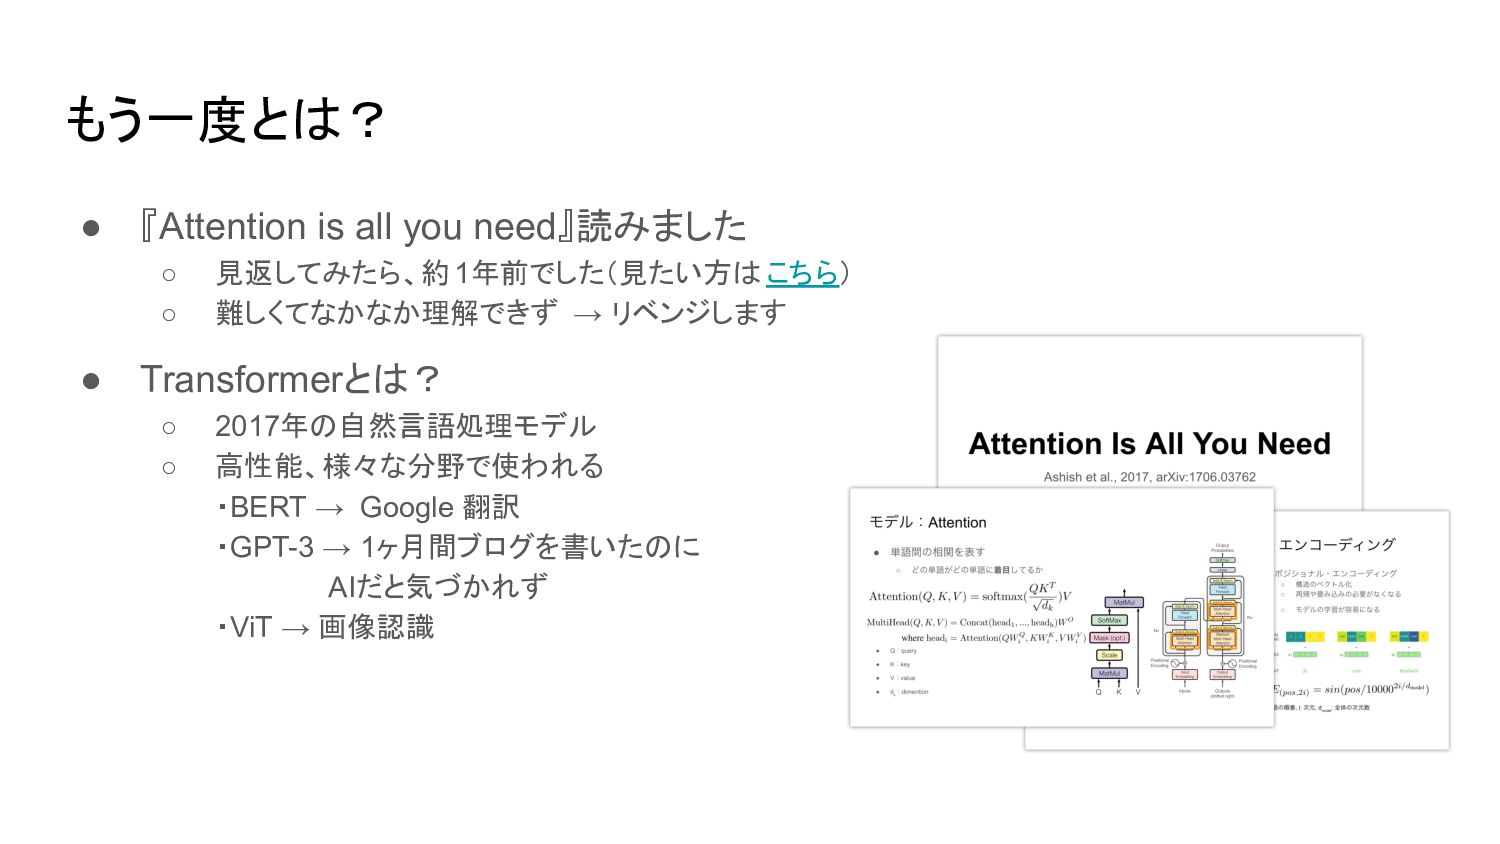
もう一度とは? • 『Attention is all you need』読みました ◦ 見返してみたら、約1年前でした(見たい方は こちら)
◦ 難しくてなかなか理解できず → リベンジします • Transformerとは? ◦ 2017年の自然言語処理モデル ◦ 高性能、様々な分野で使われる ・BERT → Google 翻訳 ・GPT-3 → 1ヶ月間ブログを書いたのに AIだと気づかれず ・ViT → 画像認識
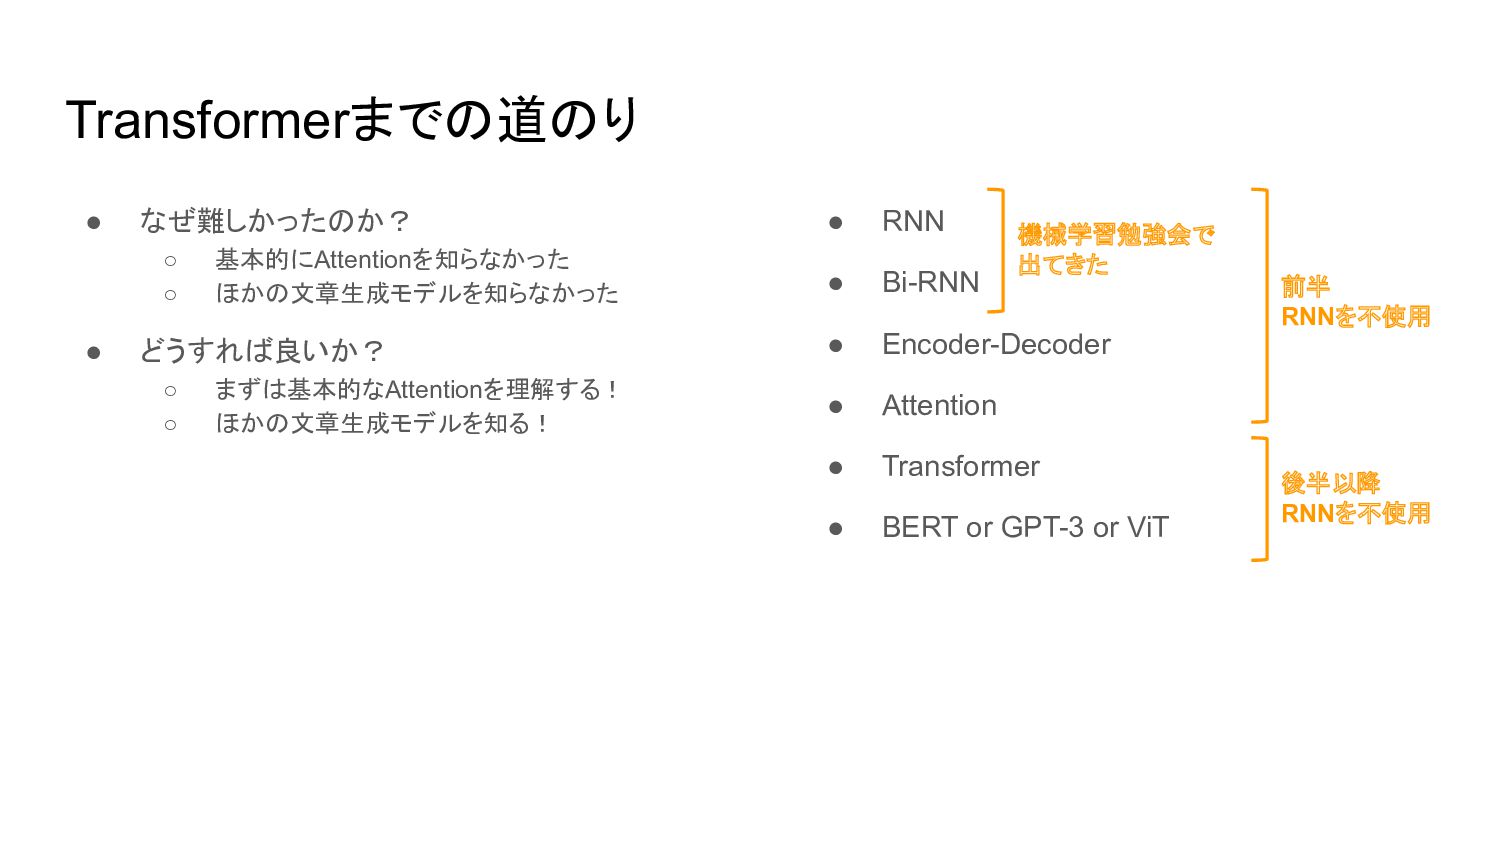
Transformerまでの道のり • なぜ難しかったのか? ◦ 基本的にAttentionを知らなかった ◦ ほかの文章生成モデルを知らなかった • どうすれば良いか? ◦
まずは基本的なAttentionを理解する! ◦ ほかの文章生成モデルを知る! • RNN • Bi-RNN • Encoder-Decoder • Attention • Transformer • BERT or GPT-3 or ViT 機械学習勉強会で 出てきた 前半 RNNを不使用 後半以降 RNNを不使用
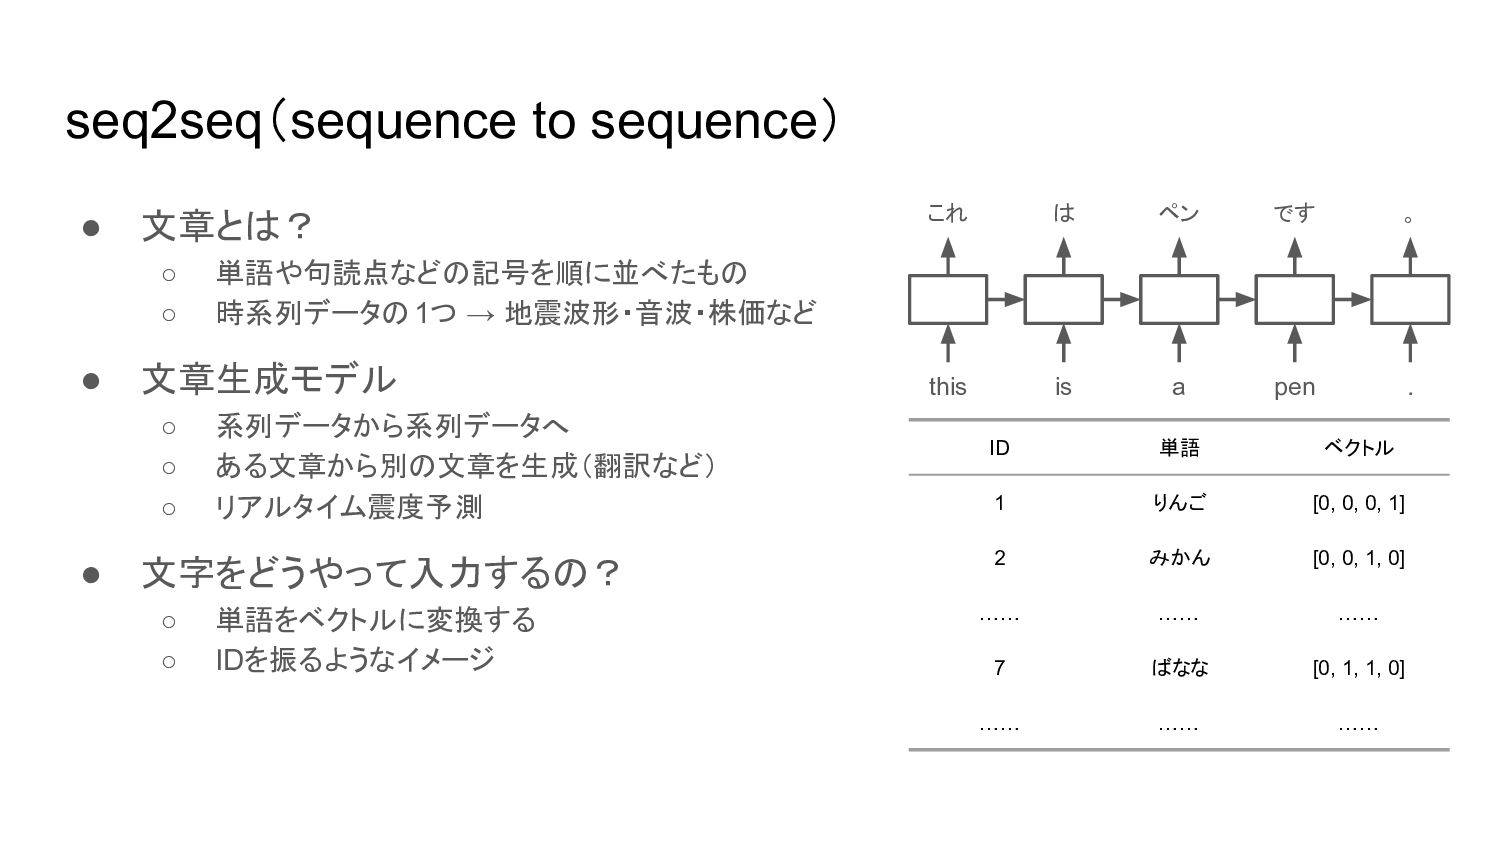
seq2seq(sequence to sequence) • 文章とは? ◦ 単語や句読点などの記号を順に並べたもの ◦ 時系列データの1つ →
地震波形・音波・株価など • 文章生成モデル ◦ 系列データから系列データへ ◦ ある文章から別の文章を生成(翻訳など) ◦ リアルタイム震度予測 • 文字をどうやって入力するの? ◦ 単語をベクトルに変換する ◦ IDを振るようなイメージ this is . a pen これ は ペン です 。 ID 単語 ベクトル 1 りんご [0, 0, 0, 1] 2 みかん [0, 0, 1, 0] …… …… …… 7 ばなな [0, 1, 1, 0] …… …… ……
• 前後の情報を持てる • 文字の説明 ◦ x:入力データ ◦ h:隠れ状態 ◦ W,
U:重み ◦ b:バイアス Bi-RNN(Bidirectional RNN) this h s is . a pen これ は ペン です 。 結合 以降の情報
• 文脈ベクトル(context vector)をもつ • 入力と出力を異なる長さにできる • 文字の説明 ◦ h:隠れ状態 ◦
y:出力 ◦ c:文脈ベクトル Encoder-Decoder this h t is . a pen <bos> これ は は これ 文脈ベクトル 1つ前の出力 隠れ状態
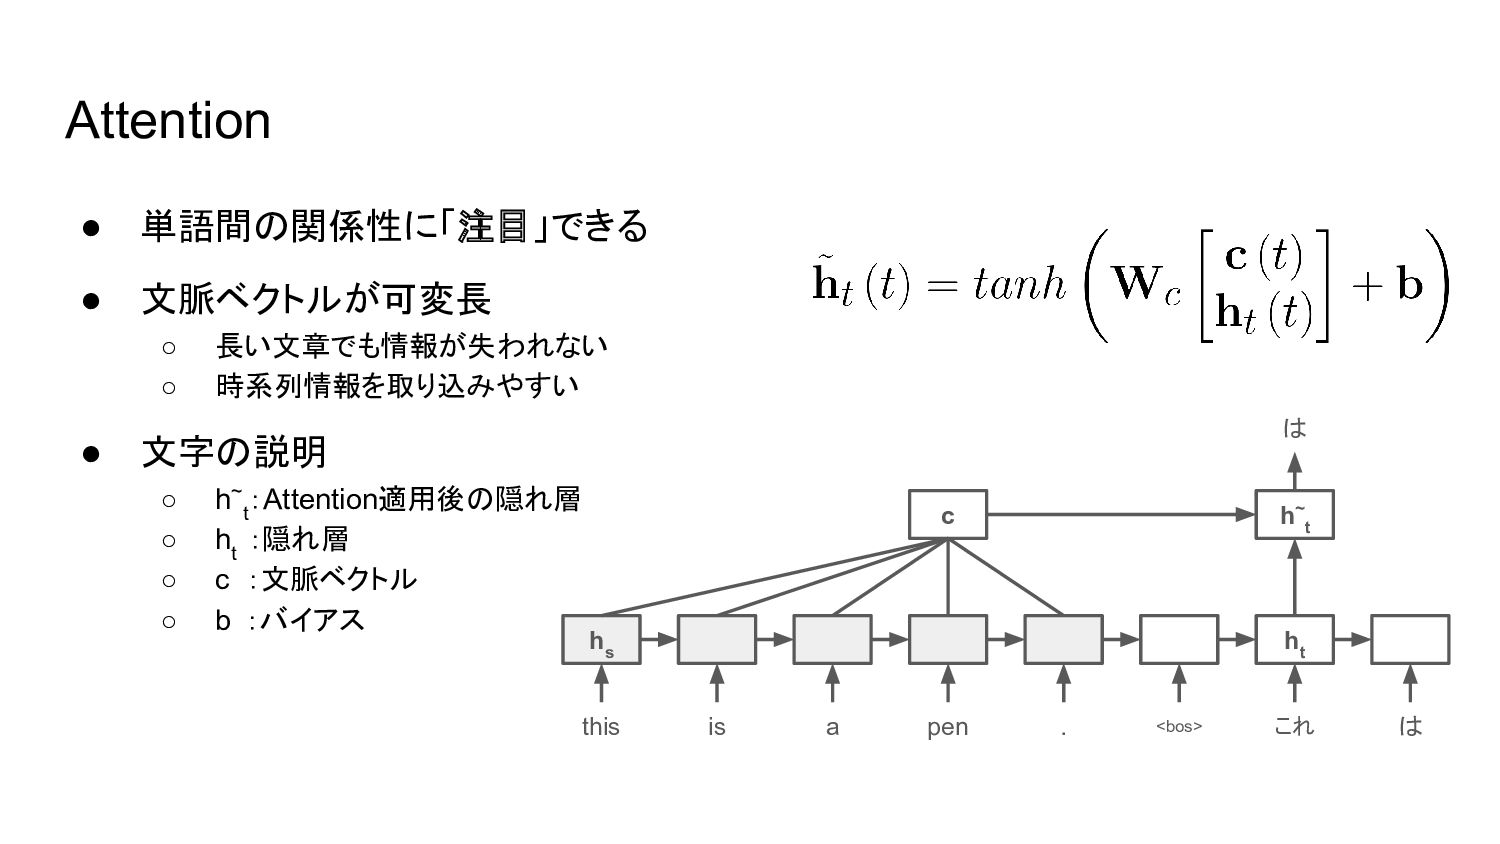
• 単語間の関係性に「注目」できる • 文脈ベクトルが可変長 ◦ 長い文章でも情報が失われない ◦ 時系列情報を取り込みやすい • 文字の説明
◦ h~ t :Attention適用後の隠れ層 ◦ h t :隠れ層 ◦ c :文脈ベクトル ◦ b :バイアス Attention this h s h t h~ t c is . a pen <bos> これ は は
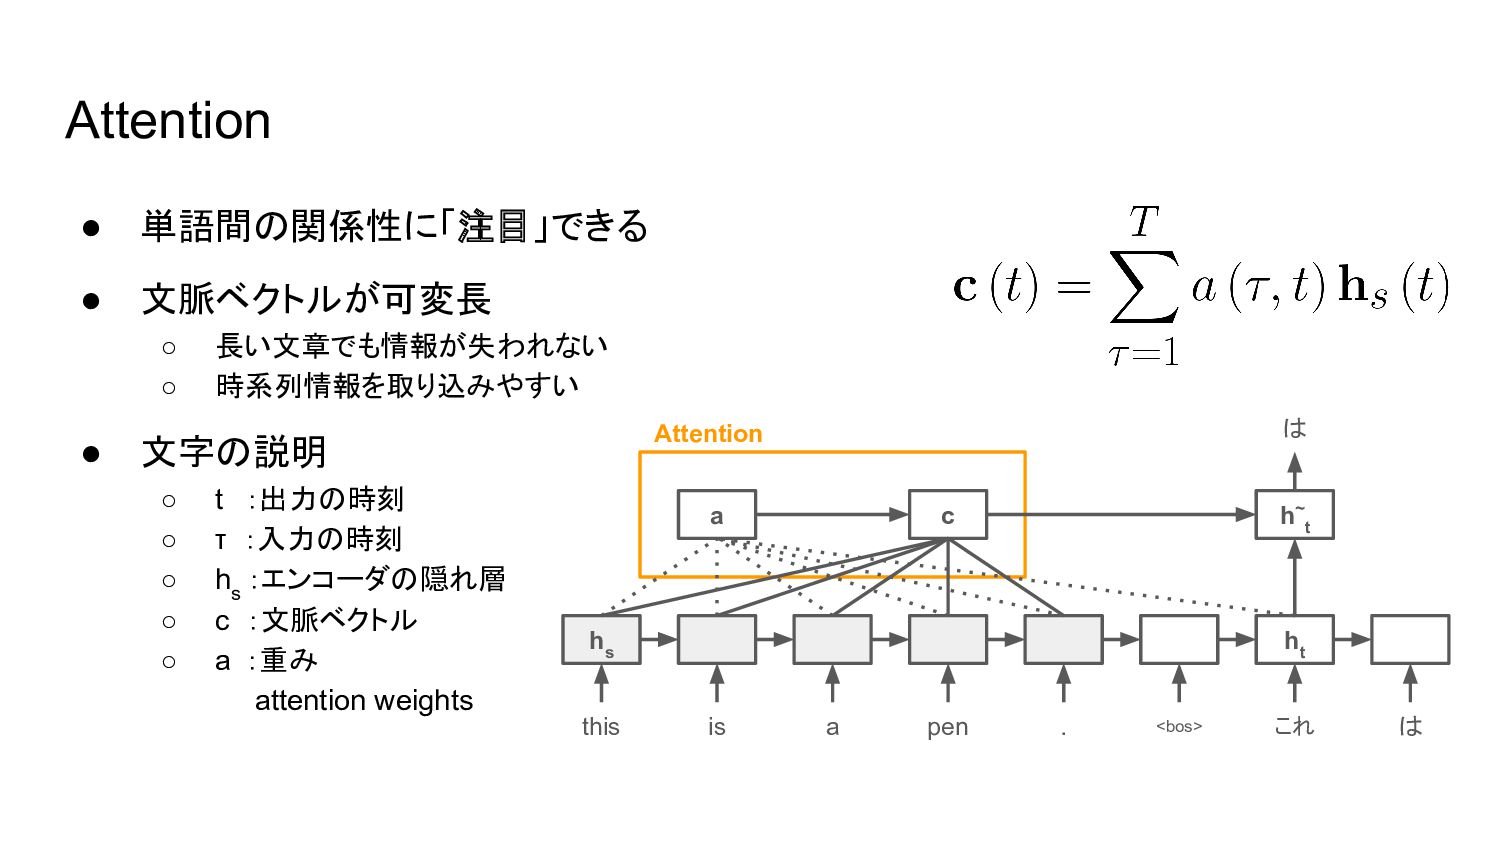
• 単語間の関係性に「注目」できる • 文脈ベクトルが可変長 ◦ 長い文章でも情報が失われない ◦ 時系列情報を取り込みやすい • 文字の説明
◦ t :出力の時刻 ◦ τ :入力の時刻 ◦ h s :エンコーダの隠れ層 ◦ c :文脈ベクトル ◦ a :重み attention weights Attention this h s h t h~ t c a is . a pen <bos> これ は は Attention
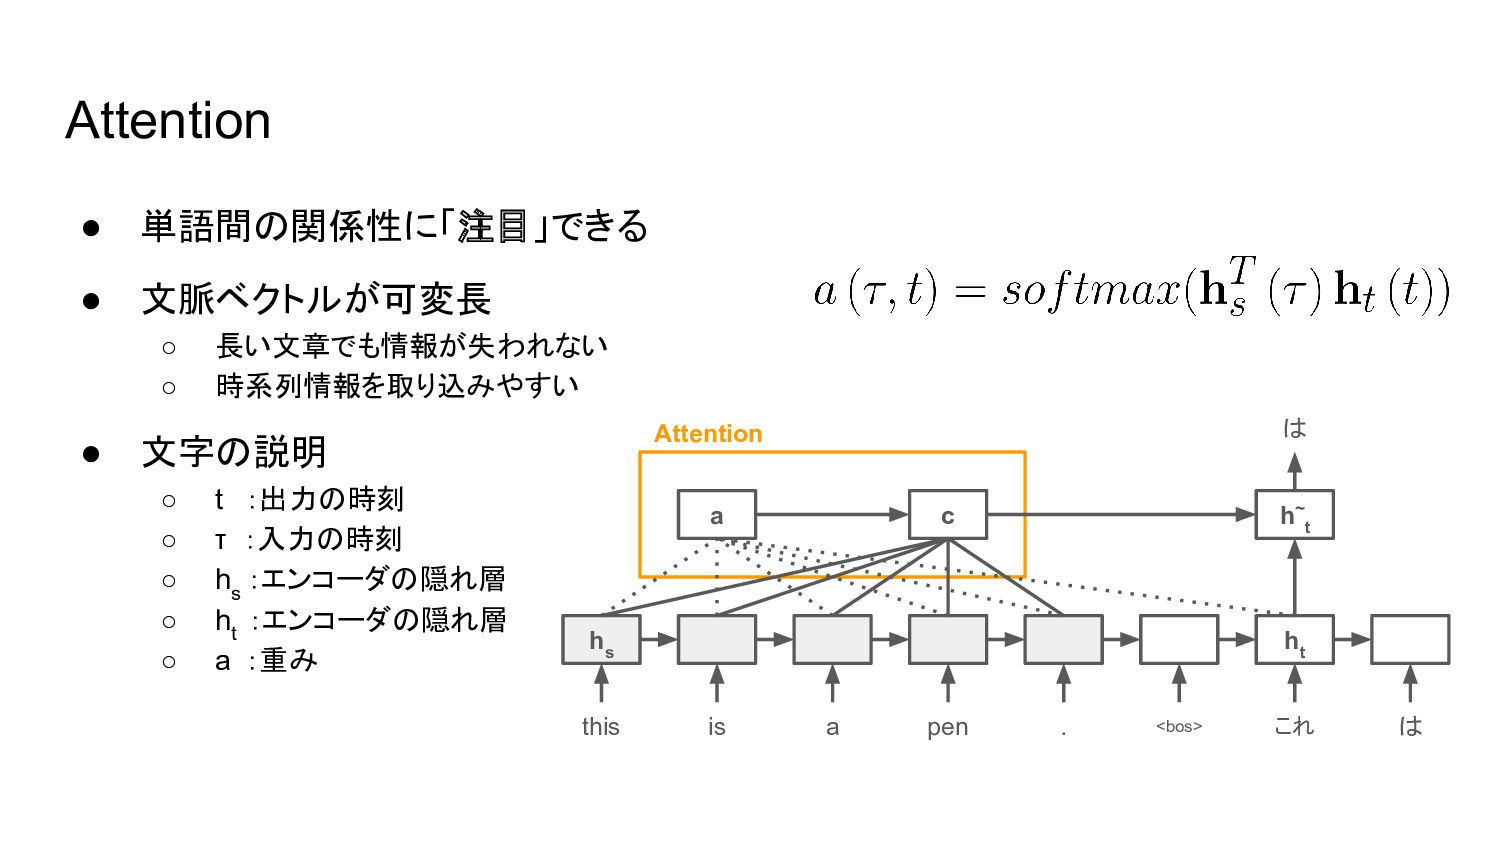
• 単語間の関係性に「注目」できる • 文脈ベクトルが可変長 ◦ 長い文章でも情報が失われない ◦ 時系列情報を取り込みやすい • 文字の説明
◦ t :出力の時刻 ◦ τ :入力の時刻 ◦ h s :エンコーダの隠れ層 ◦ h t :エンコーダの隠れ層 ◦ a :重み Attention this h s h t h~ t c a is . a pen <bos> これ は は Attention
• 単語間の関係性に「注目」できる • 文脈ベクトルが可変長 ◦ 長い文章でも情報が失われない ◦ 時系列情報を取り込みやすい • まとめ
◦ AttentionはEncoder-Decoderに c(t)を加えたもの ◦ cは単語と単語の関係性から 文脈ベクトルを合成する Attention this h s h t h~ t c a is . a pen <bos> これ は は Attention
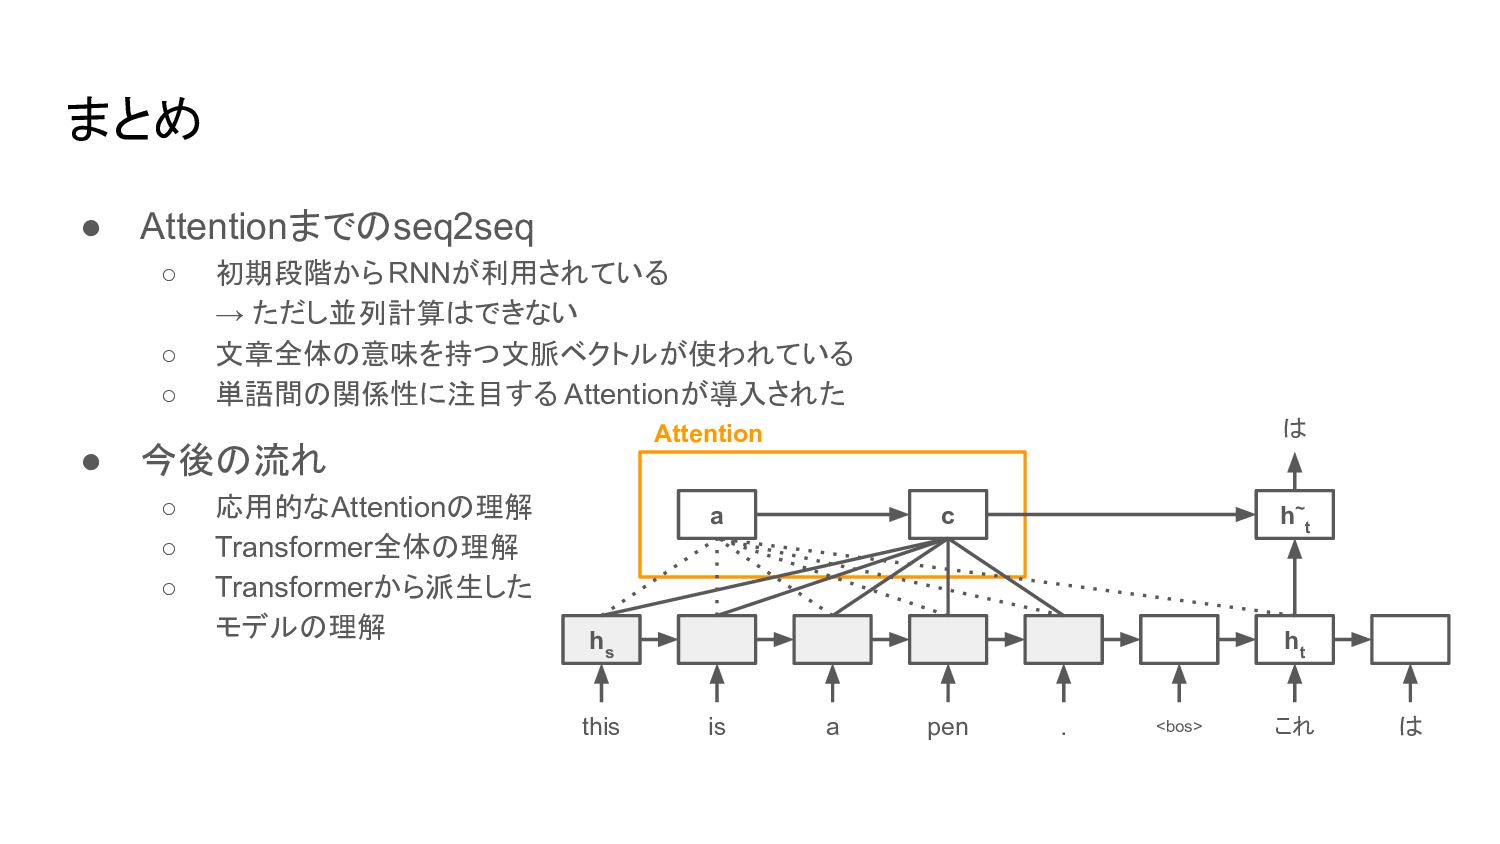
まとめ • Attentionまでのseq2seq ◦ 初期段階からRNNが利用されている → ただし並列計算はできない ◦ 文章全体の意味を持つ文脈ベクトルが使われている ◦
単語間の関係性に注目する Attentionが導入された • 今後の流れ ◦ 応用的なAttentionの理解 ◦ Transformer全体の理解 ◦ Transformerから派生した モデルの理解 this h s h t h~ t c a is . a pen <bos> これ は は Attention


 yjn279
 hayashiyus884
 takusamar
 okana2ki
 trycycle
 tagtag
 peterdesmet
 konakalab
 xleitix
 ianozsvald
 tomoaki0705
 lychee1223
 moore
 cromwellryan
 frankvandijk
 twada
 aleyda
 michaelherold
 lara
 paigeccino
 reverentgeek
 soudai
 tammielis
 stephenakadiri