Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
論文紹介:What In-Context Learning “Learns” In-Conte...
Search
yuri
August 21, 2023
Research
670
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
論文紹介:What In-Context Learning “Learns” In-Context: Disentangling Task Recognition and Task Learning
yuri
August 21, 2023
More Decks by yuri
See All by yuri
データ指向モデリング「テキストマイニングの基礎」
yuri00
0
50
論文紹介:∞-former: Infinite Memory Transformer
yuri00
0
460
論文紹介:Learning Dependency-Based Compositional Semantics
yuri00
0
170
論文紹介:What Context Features Can Transformer Language Models Use?
yuri00
0
490
Other Decks in Research
See All in Research
SAM3を用いたコマ・吹き出しの 領域検出と分割構造からの読み順推定
kzmssk
0
210
OWASP AISVS - C7
shiell
2
860
VLMの推論を高速化する視覚トークン削減の仕組み
tattaka
2
410
Vector Map as Language: Toward Unified Remote Sensing Vector Mapping
satai
3
340
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
330
横浜市長(山中氏)の言動にかかる第三者による調査報告書
sishi2026
0
670
SigLIP2 Explanation
auranightsky
0
100
Détecter les vulnérabilités dans un environnement souverain
hellosct1
0
120
Les émissions de méthane entérique en élevage laitier : Enjeux et travaux menés en Afrique de l’Ouest et en France
institutdelelevage
PRO
0
150
Kunai: Toward a Verifier-Safe Layered DSL for Nested Encapsulation Packet Filtering on eBPF
takehaya
1
190
オンライン凸最適化の基礎とゲーム理論への応用 (IBIS 2026 チュートリアル)
taira_tsuchiya
2
1.3k
マニアックセッション 〜次世代のメールプロトコルの斜め読み(2026年版)
hirachan
0
200
Featured
See All Featured
New Earth Scene 8
popppiees
4
2.8k
How to Align SEO within the Product Triangle To Get Buy-In & Support - #RIMC
aleyda
2
1.9k
"I'm Feeling Lucky" - Building Great Search Experiences for Today's Users (#IAC19)
danielanewman
230
23k
The Illustrated Children's Guide to Kubernetes
chrisshort
51
53k
The #1 spot is gone: here's how to win anyway
tamaranovitovic
4
1.2k
The Myth of the Modular Monolith - Day 2 Keynote - Rails World 2024
eileencodes
28
3.7k
How GitHub (no longer) Works
holman
316
150k
The Invisible Side of Design
smashingmag
301
52k
Effective software design: The role of men in debugging patriarchy in IT @ Voxxed Days AMS
baasie
1
600
Breaking role norms: Why Content Design is so much more than writing copy - Taylor Woolridge
uxyall
1
500
Easily Structure & Communicate Ideas using Wireframe
afnizarnur
194
17k
Understanding Cognitive Biases in Performance Measurement
bluesmoon
32
3.1k
Transcript
What In-Context Learning “Learns” In-Context: Disentangling Task Recognition and Task
Learning Jane Pan, Tianyu Gao, Howard Chen, Danqi Chen ACL2023 Findings 村山 友理 東大和泉研 2023/08/27 第15回最先端NLP勉強会
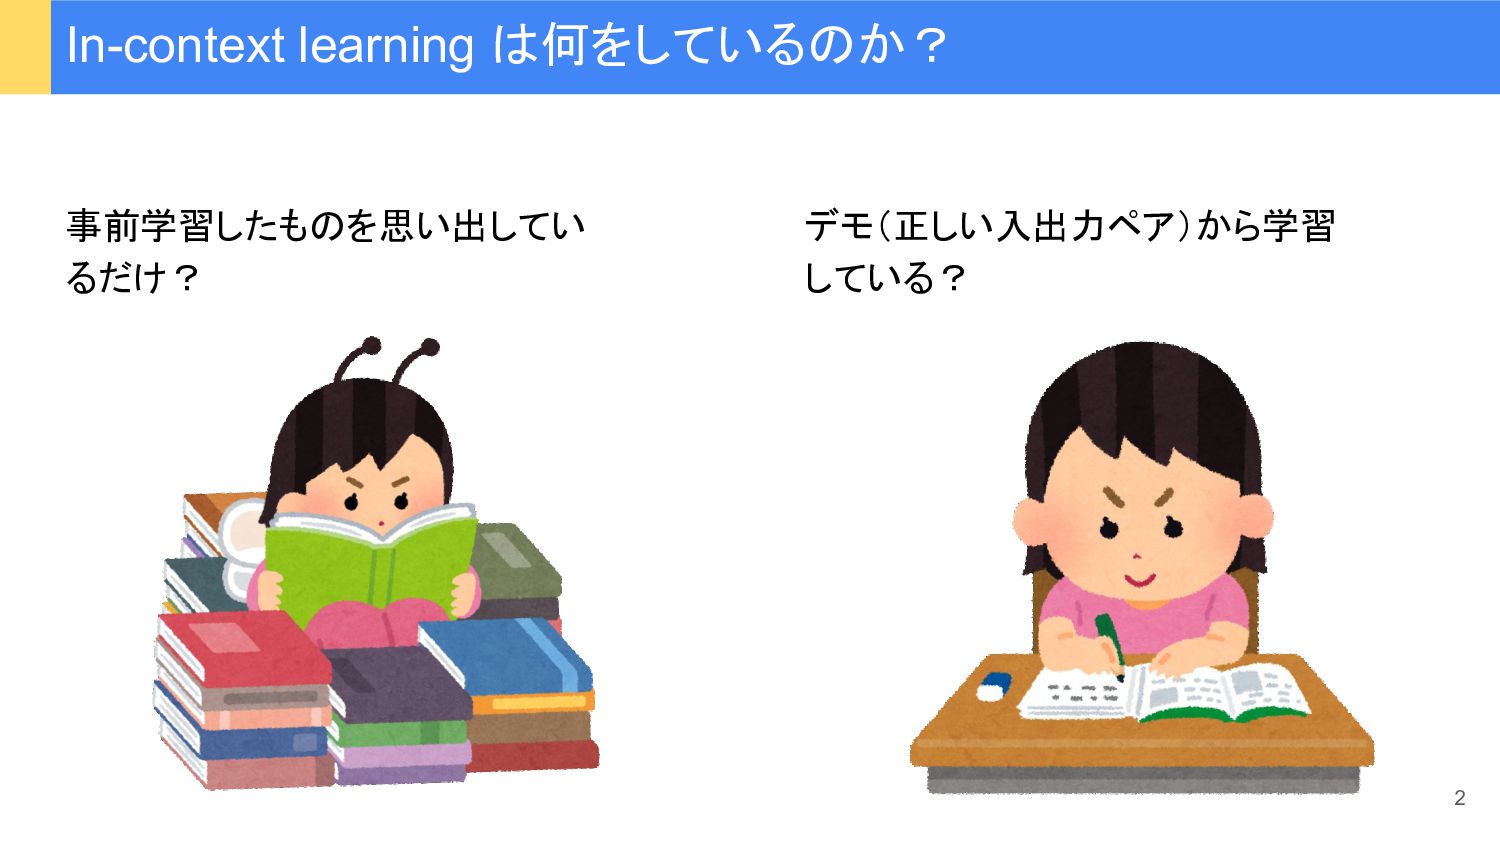
事前学習したものを思い出してい るだけ? In-context learning は何をしているのか? 2 デモ(正しい入出力ペア)から学習 している?
• 事前学習時にダウンストリームで必要なタスクを暗黙的に学習していて、in-context のデモはどのタスクを解くべきかモデルに認識させるための情報を与えるだけ (Xie+ 22) • ICL性能は正解ラベルの使用に対してinsensitive (Min+ 22) 事前学習したものを思い出しているだけ?
3
• Transformer-based モデルは「内部モデル」を更新するために暗黙的に勾配降下 法を行っている可能性 (Akyürek+ 23), (vonOswald+ 22) • 実データセットの指標を用いると、ICLとファインチューニングには類似点がある
(Dai+ 23) デモから学習している? 4
ICLの能力を「タスク認識」と「タスク学習」に分解 5 事前学習したものを思い出してい るだけ? タスク認識 デモ(正しい入出力ペア)から学習 している? タスク学習 • それぞれの能力を評価するために、プロンプトのラベルを操作
• いろいろなモデルサイズとデモ数で実験
Random (= タスク認識) • ラベルは一様にランダムにサンプリングされる ラベル操作 1. Random 6
Abstract (=タスク学習) • プロンプトからタスク指示文を取り除き、ラベルを抽象的な記号に置換 ◦ 数字 (0, 1, 2,...) /
文字 (A, B, C,...) / 記号 (@, #, $, %, *, ∧,...) • 抽象的なラベルであっても事前学習のバイアスがある可能性 ◦ 例えば、“0”は負例っぽい ◦ バイアスを避けるために、プロンプト毎にラベルから抽象記号にランダムに写像 ラベル操作 2. Abstract 7
Gold (= タスク認識 + タスク学習) • 正解の入力・ラベルペアが与えられる従来のプロンプト ラベル操作 3. Gold
8
• データセット ◦ 4タイプのタスクに関する16の分類データセットを使用: ▪ 感情分析 ▪ 毒性検出 ▪ 自然言語推論
/ 言い換え検出 ▪ トピック / スタンス分類 • モデル ◦ GPT-3 (Brown+ 20) ▪ ada (350M), babbage (1.3B), curie (6.7B), davinci (175B) (OpenAI API) ◦ LLaMA (Touvron+ 23) ▪ 7B, 13B, 33B, 65B ◦ OPT (Zhang+ 22) ▪ 350M, 2.7B, 6.7B, 13B, 30B, 66B (Transformers library) 実験設定 9
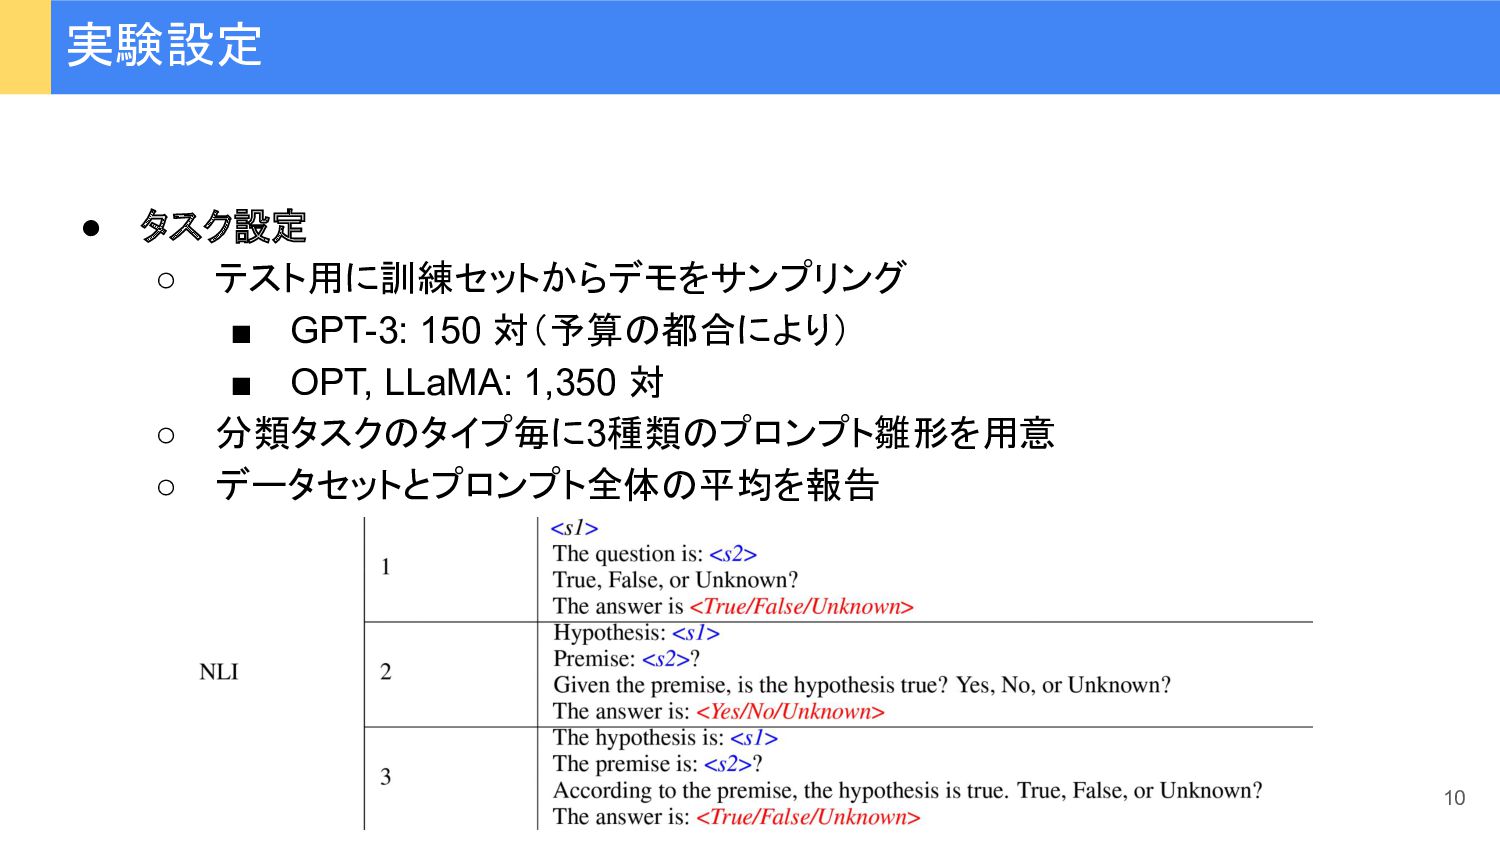
• タスク設定 ◦ テスト用に訓練セットからデモをサンプリング ▪ GPT-3: 150 対(予算の都合により) ▪ OPT,
LLaMA: 1,350 対 ◦ 分類タスクのタイプ毎に3種類のプロンプト雛形を用意 ◦ データセットとプロンプト全体の平均を報告 実験設定 10
• Gold (= タスク認識 + タスク学習) ◦ 全体的に一番良い • Random
(= タスク認識) ◦ 性能はスケールに依らずほぼ 横ばい • Abstract (= タスク学習) ◦ モデルサイズとデモ数に応じて 増加 ◦ 小さなモデル、少ないデモ数で はRandomより低いが、パラ メータ数・デモ数が増えると逆転 ◦ LLaMA-65B以外のOPT-66Bと davinciはGOLDに匹敵 結果 11 ※ Abstractについては数字ラベルの結果
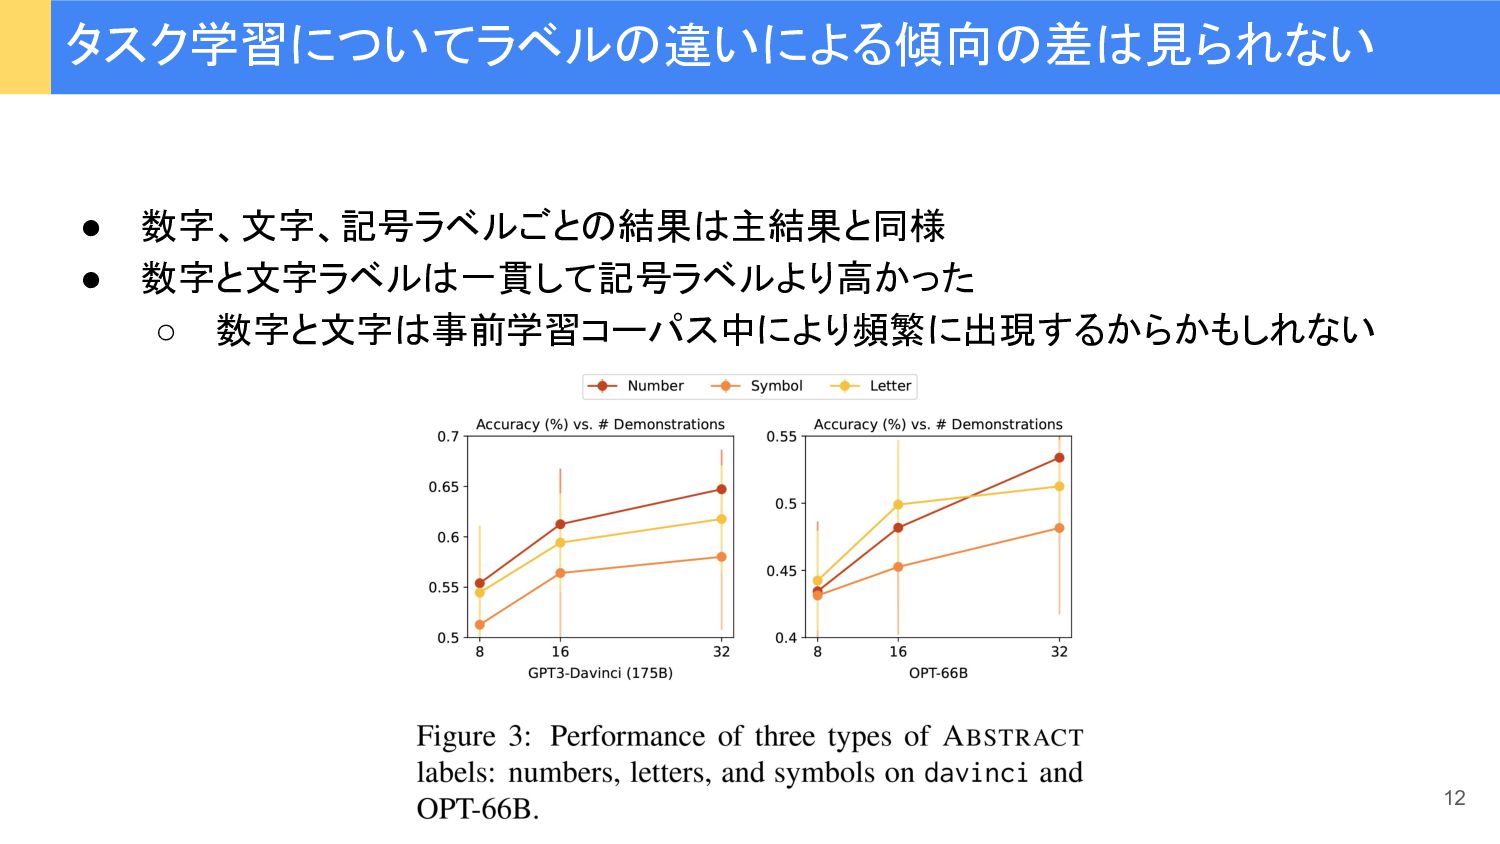
• 数字、文字、記号ラベルごとの結果は主結果と同様 • 数字と文字ラベルは一貫して記号ラベルより高かった ◦ 数字と文字は事前学習コーパス中により頻繁に出現するからかもしれない タスク学習についてラベルの違いによる傾向の差は見られない 12
• 感情分析とNLIを比較 • NLIのAbstract曲線がより平らなので、プロンプトと事前学習の質が重要 タスク学習ではタスクが単純な方がサイズとデモ数にスケールする 13
タスクのタイプ別の結果 14 感情分析 トピック / スタンス分類 毒性検出 NLI / 言い換え検出
GPT-3 LLaMA OPT
• ICLを2つの能力「タスク認識」と「タスク学習」に分解し、それぞれ異なる条件下で 発現することを示した • 小さなモデルでもタスク認識の能力はあるが、スケールしない • タスク学習の能力は大きなモデルで現れる ◦ 小さなモデルではデモを増やしても性能が上がらない ◦
大きなモデルはデモが増えると性能も向上 • Limitations ◦ 「タスク認識」と「タスク学習」に分けたが、タスク学習がデモで示されたパター ンを事前学習で学習した概念に代替しているとすれば、タスク認識の進化形と 捉えることもできるかもしれない まとめ 15


 yuri00
 kzmssk
 shiell
 tattaka
 satai
 s_mizuki_nlp
 sishi2026
 auranightsky
 hellosct1
 institutdelelevage
 takehaya
 taira_tsuchiya
 hirachan
 popppiees
 aleyda
 danielanewman
 chrisshort
 tamaranovitovic
 eileencodes
 holman
 smashingmag
 baasie
 uxyall
 afnizarnur
 bluesmoon