Patterns for Continuous Delivery, Reactive, Hig...

Share
Embed
Patterns for Continuous Delivery, Reactive, High Availability, DevOps & Cloud Native Open Source with NetflixOSS
Yow Australia 2013 Workshop Slides yowconference.com #yow13

Adrian Cockcroft
December 04, 2013
Transcript
175 slides
-
Pa#erns for Con,nuous Delivery, Reac,ve, High Availability, DevOps &
Cloud Na,ve Open Source with NeClixOSS YOW! Workshop December 2013 Adrian CockcroN + Ben Christensen @adrianco @NeClixOSS @benjchristensen -
Presenta,on vs. Workshop • Presenta,on – Short dura,on, focused
subject – One presenter to many anonymous audience – A few ques,ons at the end • Workshop – Time to explore in and around the subject – Tutor gets to know the audience – Discussion, rat-‐holes, “bring out your dead” -
Presenters Adrian Cockcro, Cloud Architecture Pa3erns Etc.
Ben Christensen Func9onal Reac9ve Pa3erns Etc. -
A#endee Introduc,ons • Who are you, where do you
work • Why are you here today, what do you need • “Bring out your dead” – Do you have a specific problem or ques,on? – One sentence elevator pitch • What instrument do you play? -
Content Adrian: Cloud at Scale with Ne@lix Adrian:
Cloud Na9ve Ne@lixOSS Ben: Resilient Developer Pa3erns Adrian: Availability and Efficiency Ques9ons and Discussion -
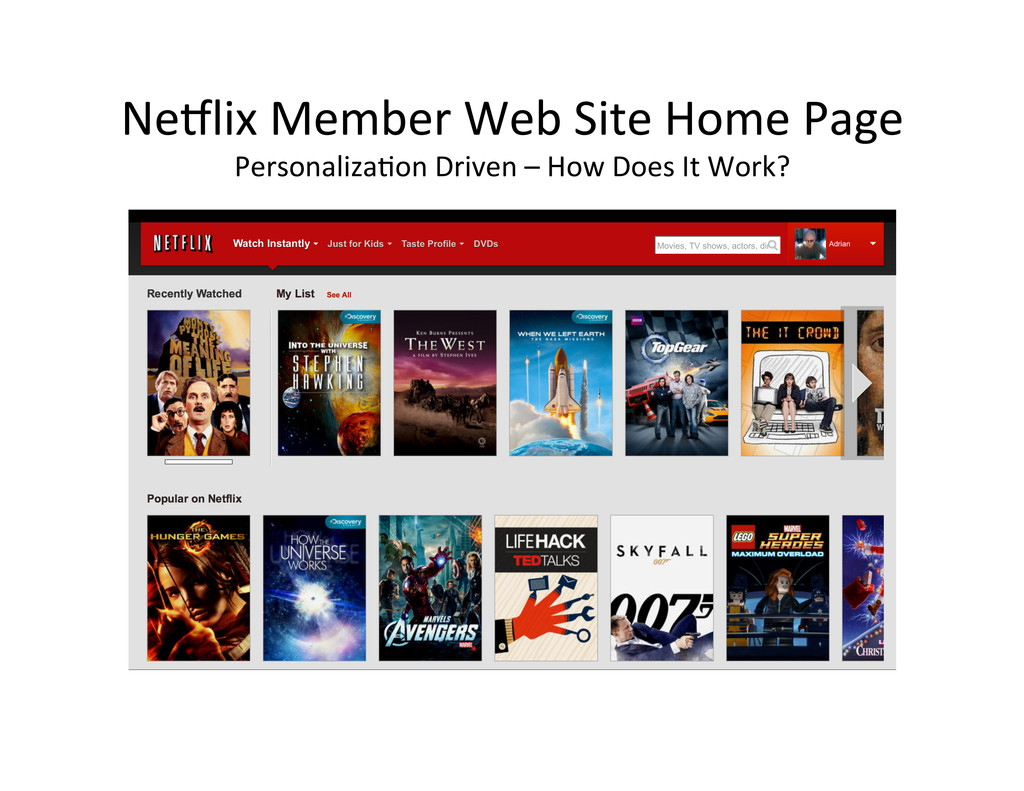
NeClix Member Web Site Home Page Personaliza,on Driven –
How Does It Work? -
How NeClix Used to Work Customer Device (PC,
PS3, TV…) Monolithic Web App Oracle MySQL Monolithic Streaming App Oracle MySQL Limelight/Level 3 Akamai CDNs Content Management Content Encoding Consumer Electronics AWS Cloud Services CDN Edge Loca,ons Datacenter -
How NeClix Streaming Works Today Customer Device (PC,
PS3, TV…) Web Site or Discovery API User Data Personaliza,on Streaming API DRM QoS Logging OpenConnect CDN Boxes CDN Management and Steering Content Encoding Consumer Electronics AWS Cloud Services CDN Edge Loca,ons Datacenter -
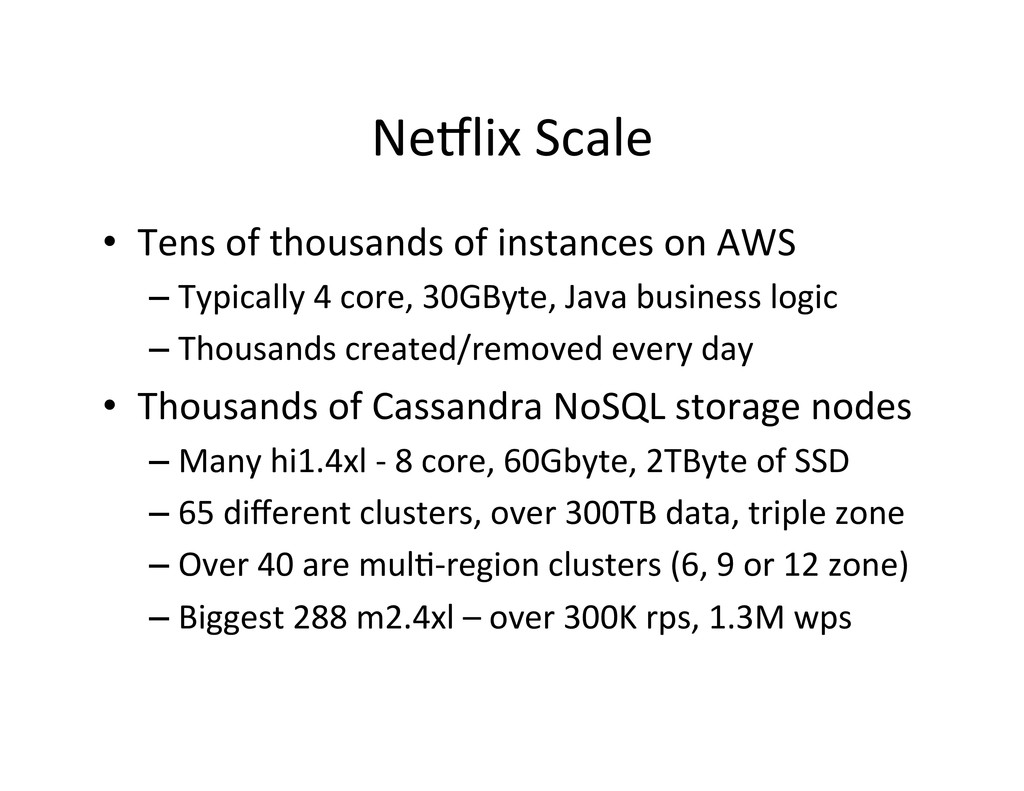
NeClix Scale • Tens of thousands of instances on
AWS – Typically 4 core, 30GByte, Java business logic – Thousands created/removed every day • Thousands of Cassandra NoSQL storage nodes – Many hi1.4xl -‐ 8 core, 60Gbyte, 2TByte of SSD – 65 different clusters, over 300TB data, triple zone – Over 40 are mul,-‐region clusters (6, 9 or 12 zone) – Biggest 288 m2.4xl – over 300K rps, 1.3M wps -
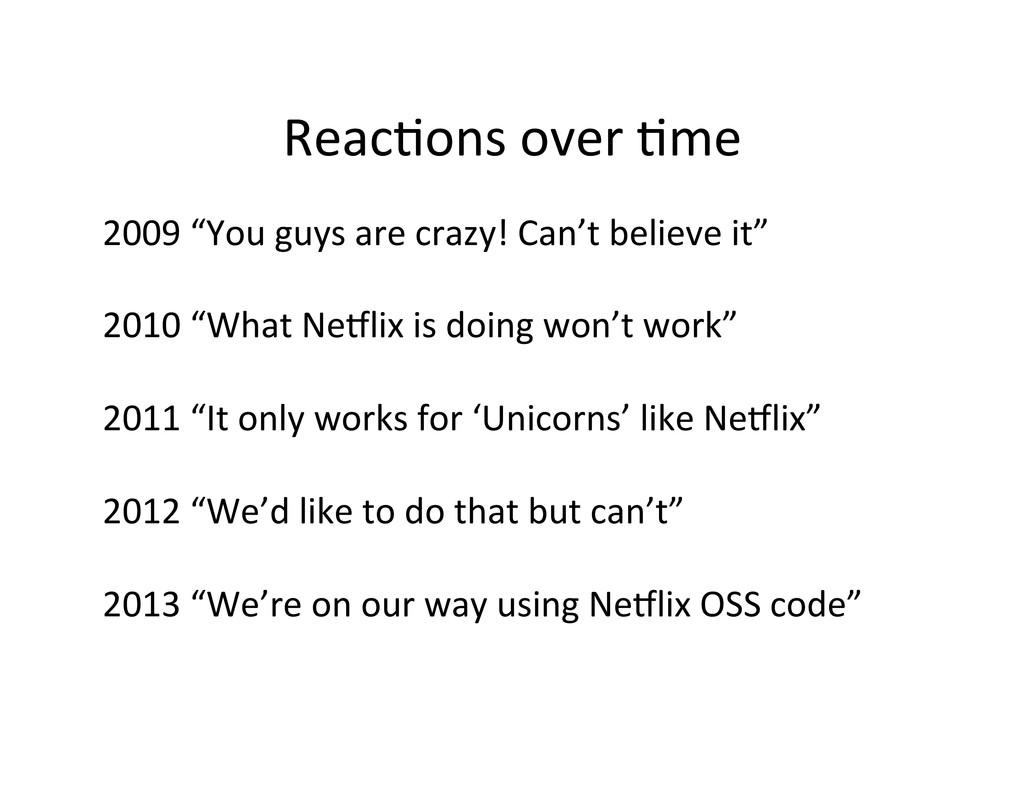
Reac,ons over ,me 2009 “You guys are crazy! Can’t
believe it” 2010 “What NeClix is doing won’t work” 2011 “It only works for ‘Unicorns’ like NeClix” 2012 “We’d like to do that but can’t” 2013 “We’re on our way using NeClix OSS code” -
Strive for perfec,on Perfect code Perfect hardware
Perfectly operated -
But perfec,on takes too long… Compromises… Time to
market vs. Quality Utopia remains out of reach -
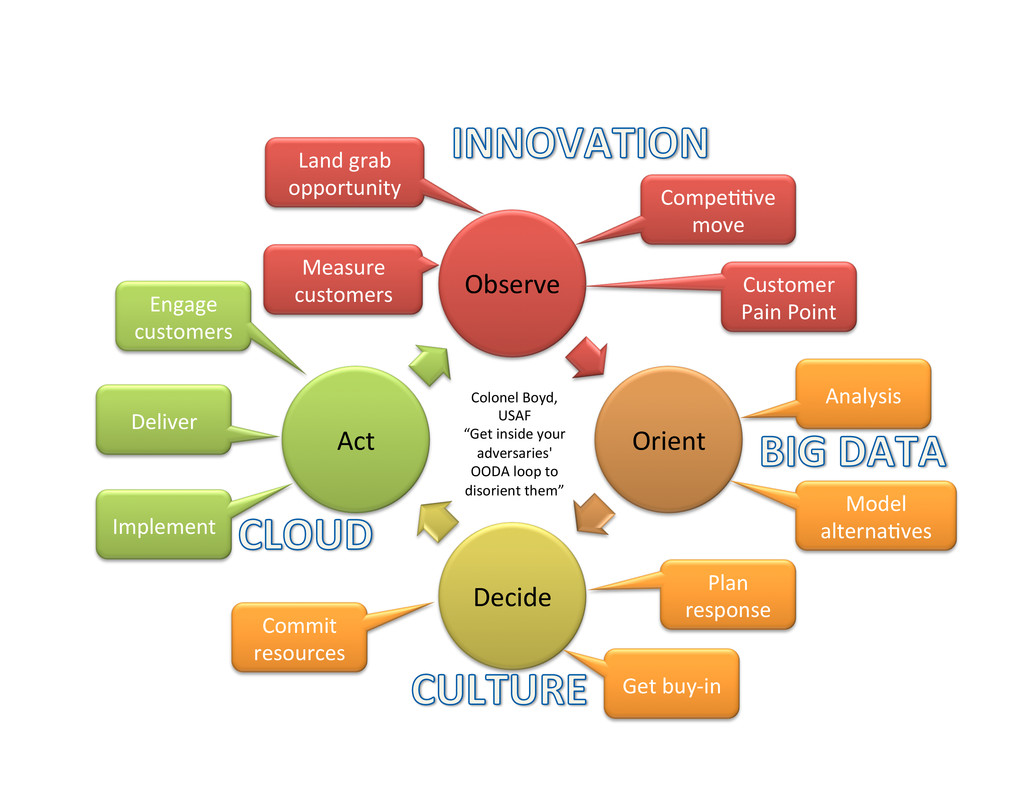
Where ,me to market wins big Making a land-‐grab
Disrup,ng compe,tors (OODA) Anything delivered as web services -
Observe Orient Decide Act Land grab
opportunity Compe,,ve move Customer Pain Point Analysis Get buy-‐in Plan response Commit resources Implement Deliver Engage customers Model alterna,ves Measure customers Colonel Boyd, USAF “Get inside your adversaries' OODA loop to disorient them” -
How Soon? Product features in days instead of months
Deployment in minutes instead of weeks Incident response in seconds instead of hours -
Cloud Na,ve A new engineering challenge Construct a
highly agile and highly available service from ephemeral and assumed broken components -
How to get to Cloud Na,ve Freedom and Responsibility
for Developers Decentralize and Automate Ops Ac,vi,es Integrate DevOps into the Business Organiza,on -
Four Transi,ons • Management: Integrated Roles in a Single
Organiza,on – Business, Development, Opera,ons -‐> BusDevOps • Developers: Denormalized Data – NoSQL – Decentralized, scalable, available, polyglot • Responsibility from Ops to Dev: Con,nuous Delivery – Decentralized small daily produc,on updates • Responsibility from Ops to Dev: Agile Infrastructure -‐ Cloud – Hardware in minutes, provisioned directly by developers -
The DIY Ques,on Why doesn’t NeClix build and run
its own cloud? -
Fiwng Into Public Scale Public Grey Area
Private 1,000 Instances 100,000 Instances NeClix Facebook Startups -
How big is Public? AWS upper bound es,mate based
on the number of public IP Addresses Every provisioned instance gets a public IP by default (some VPC don’t) AWS Maximum Possible Instance Count 5.1 Million – Sept 2013 Growth >10x in Three Years, >2x Per Annum -‐ h#p://bit.ly/awsiprange -
The Alterna,ve Supplier Ques,on What if there is
no clear leader for a feature, or AWS doesn’t have what we need? -
Things We Don’t Use AWS For SaaS Applica,ons –
Pagerduty, Onelogin etc. Content Delivery Service DNS Service -
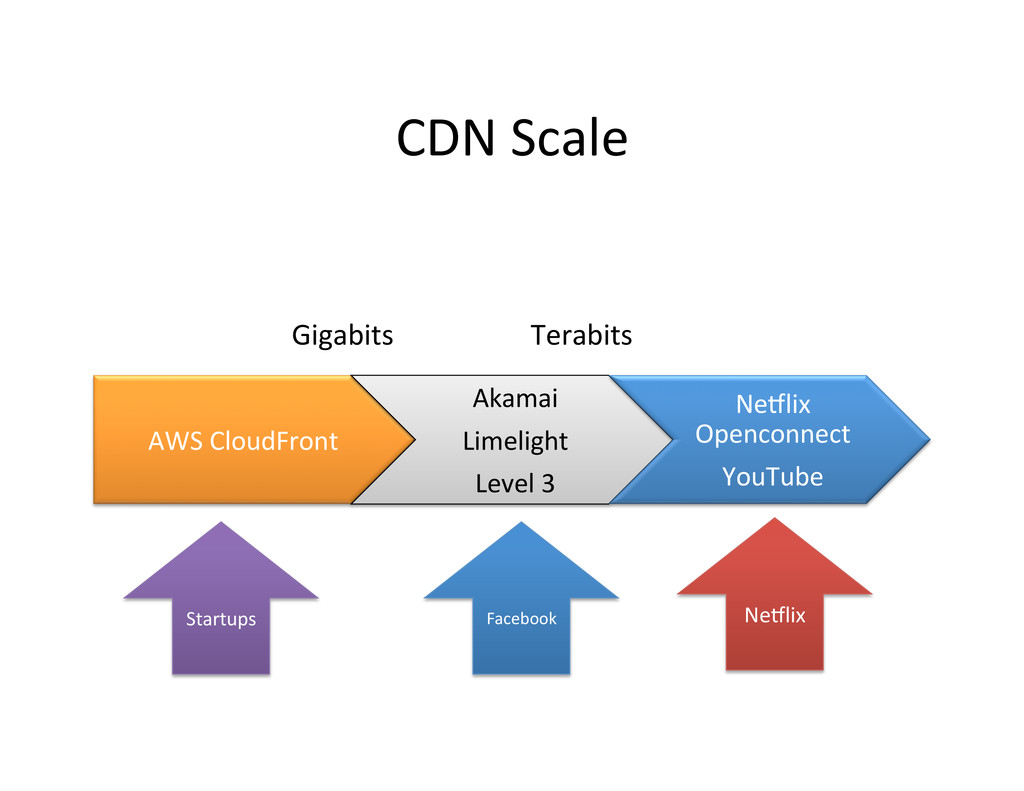
CDN Scale AWS CloudFront Akamai Limelight
Level 3 NeClix Openconnect YouTube Gigabits Terabits NeClix Facebook Startups -
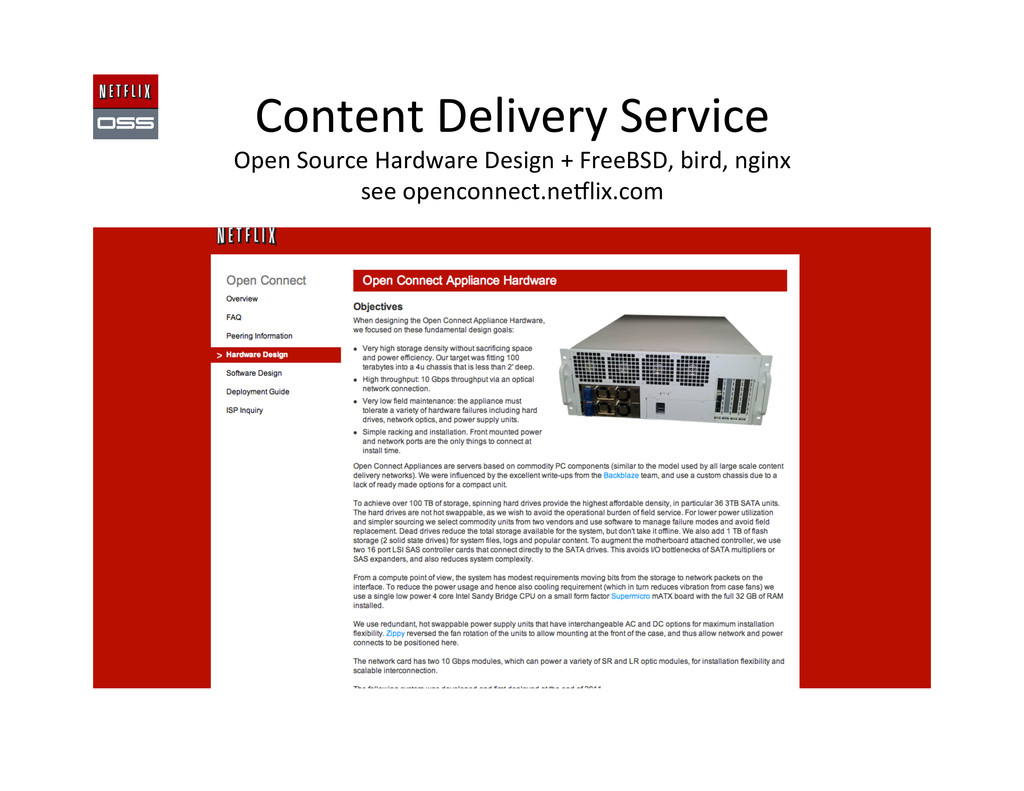
Content Delivery Service Open Source Hardware Design + FreeBSD,
bird, nginx see openconnect.neClix.com -
DNS Service AWS Route53 is missing too many features
(for now) Mul,ple vendor strategy Dyn, Ultra, Route53 Abstracted (broken) DNS APIs with Denominator -
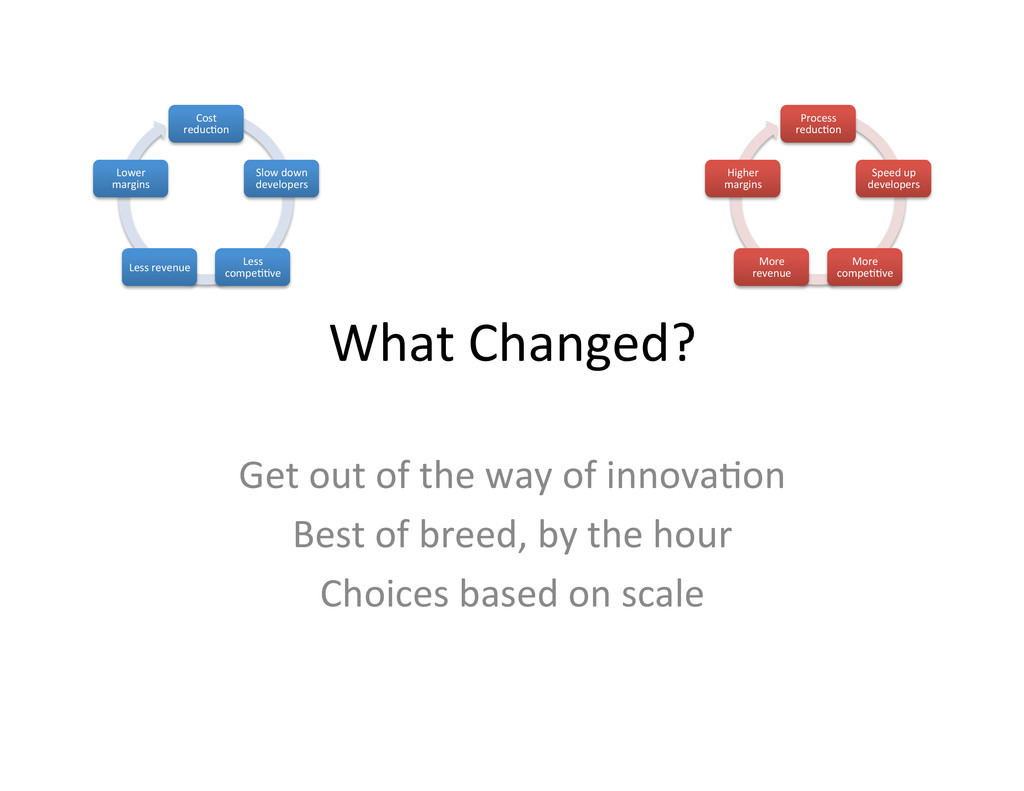
What Changed? Get out of the way of innova,on
Best of breed, by the hour Choices based on scale Cost reduc,on Slow down developers Less compe,,ve Less revenue Lower margins Process reduc,on Speed up developers More compe,,ve More revenue Higher margins -
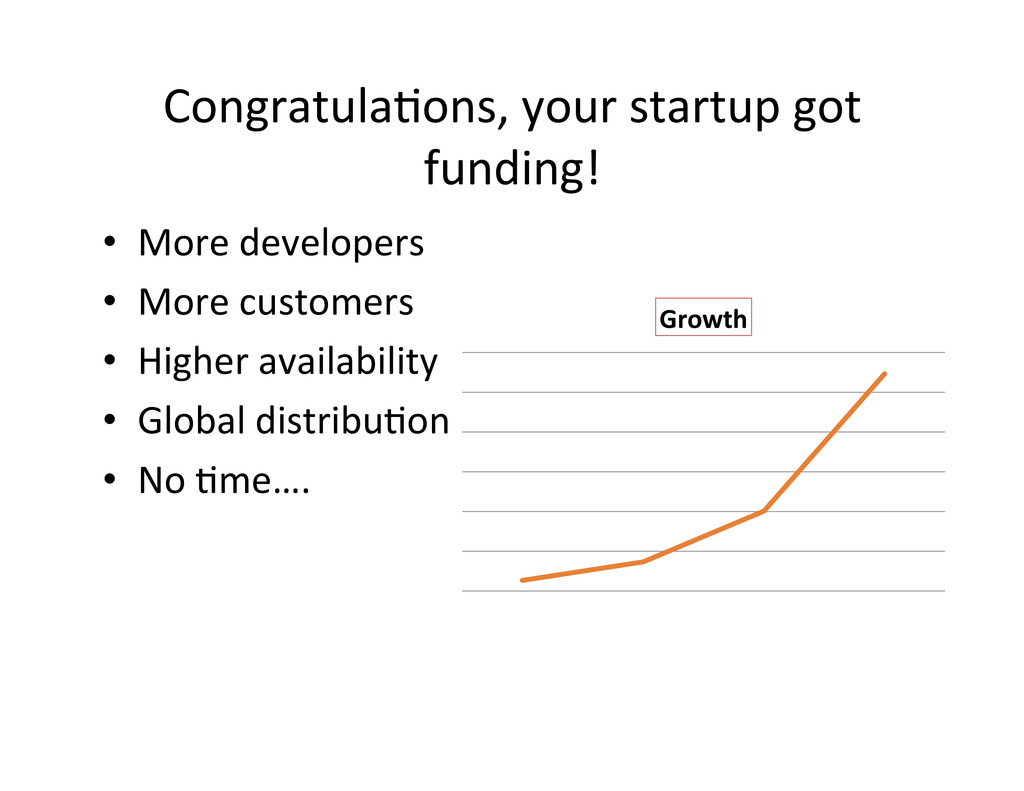
Congratula,ons, your startup got funding! • More developers
• More customers • Higher availability • Global distribu,on • No ,me…. Growth -
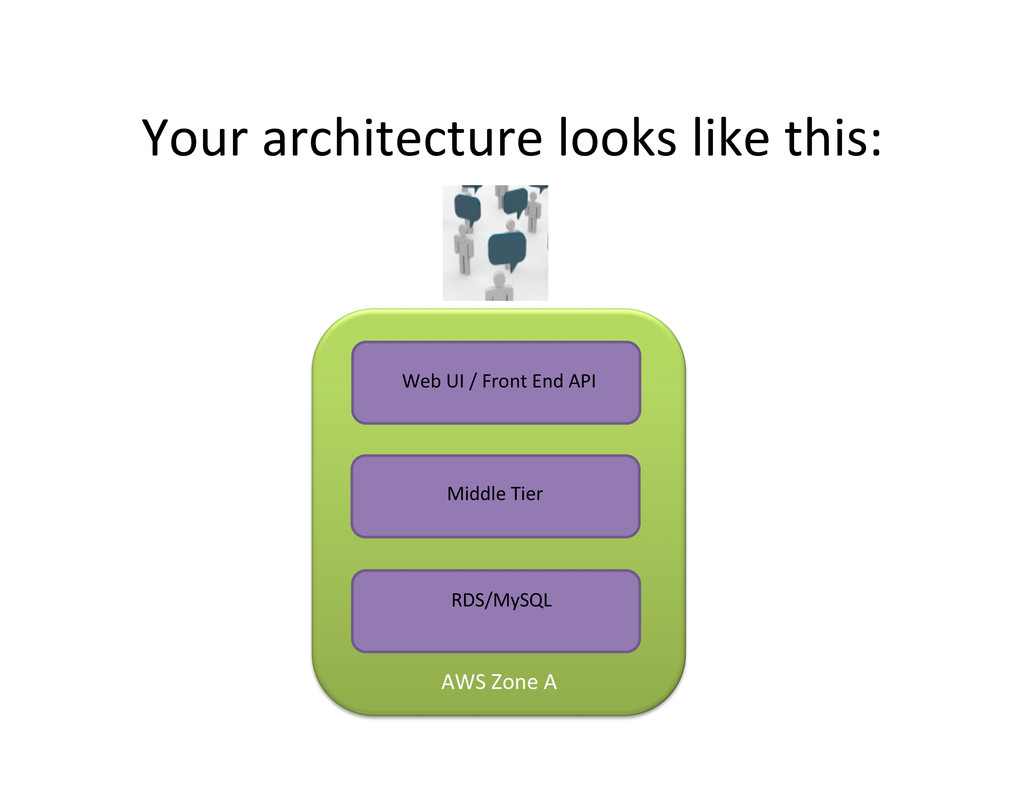
And it needs to look more like this…
Cassandra Replicas Zone A Cassandra Replicas Zone B Cassandra Replicas Zone C Regional Load Balancers Cassandra Replicas Zone A Cassandra Replicas Zone B Cassandra Replicas Zone C Regional Load Balancers -
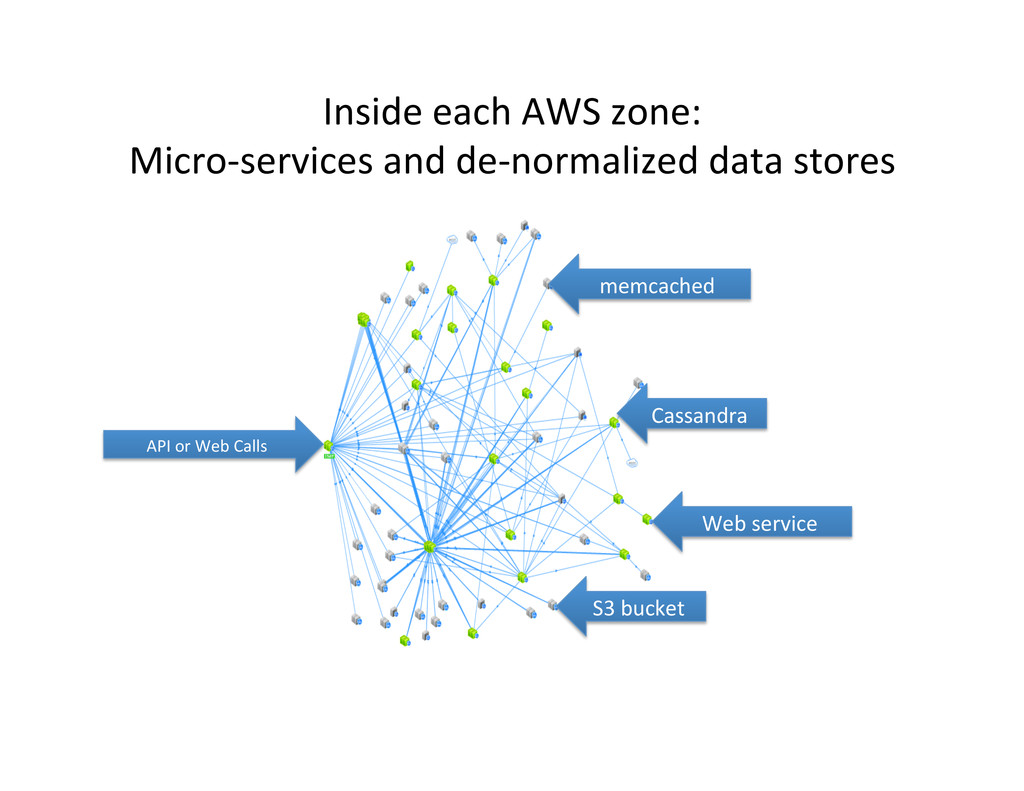
Inside each AWS zone: Micro-‐services and de-‐normalized data stores
API or Web Calls memcached Cassandra Web service S3 bucket -
We’re here to help you get to global scale…
Apache Licensed Cloud Na,ve OSS PlaCorm h#p://neClix.github.com -
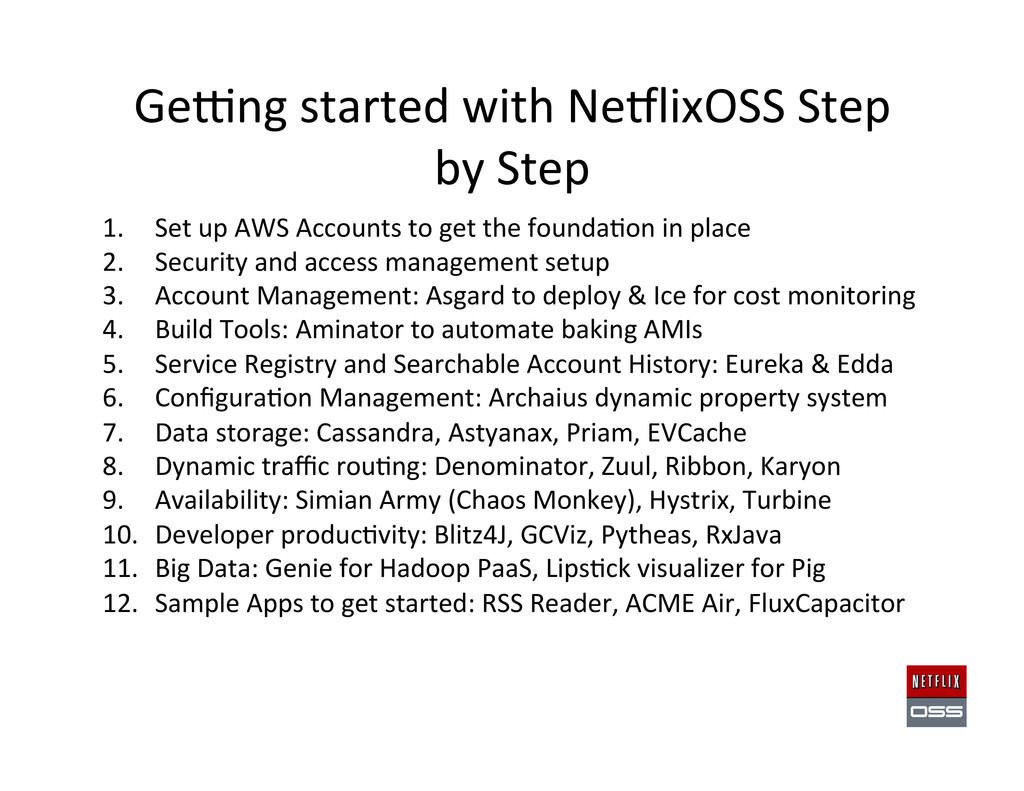
Gewng started with NeClixOSS Step by Step 1.
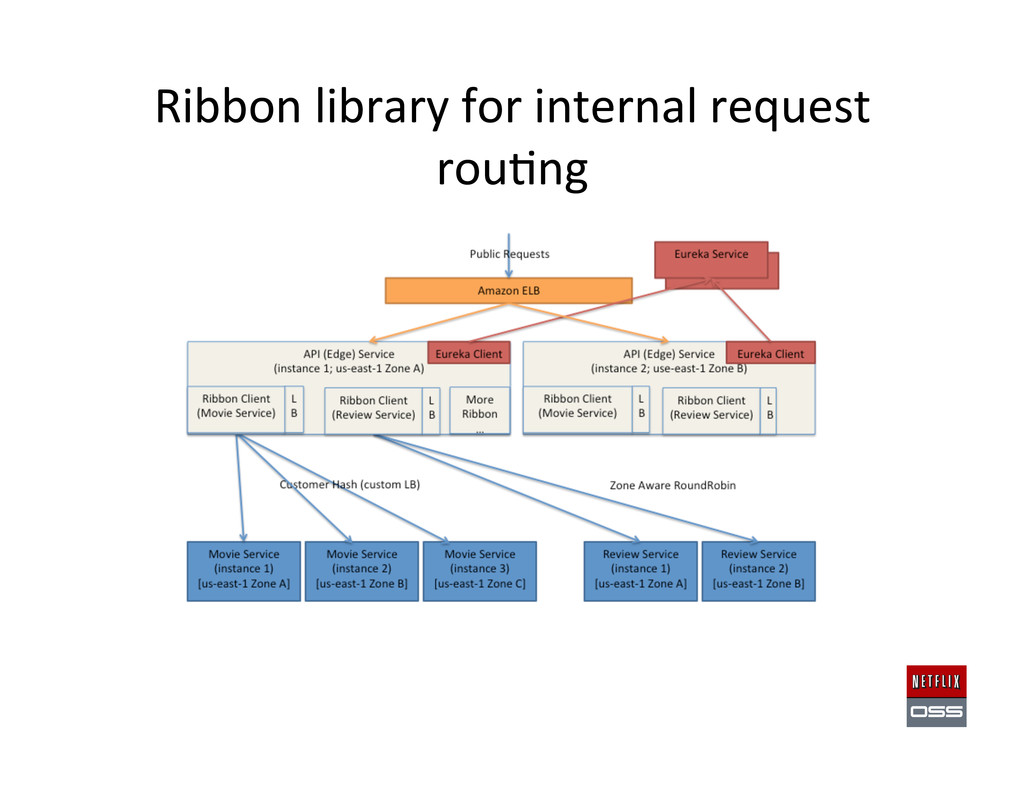
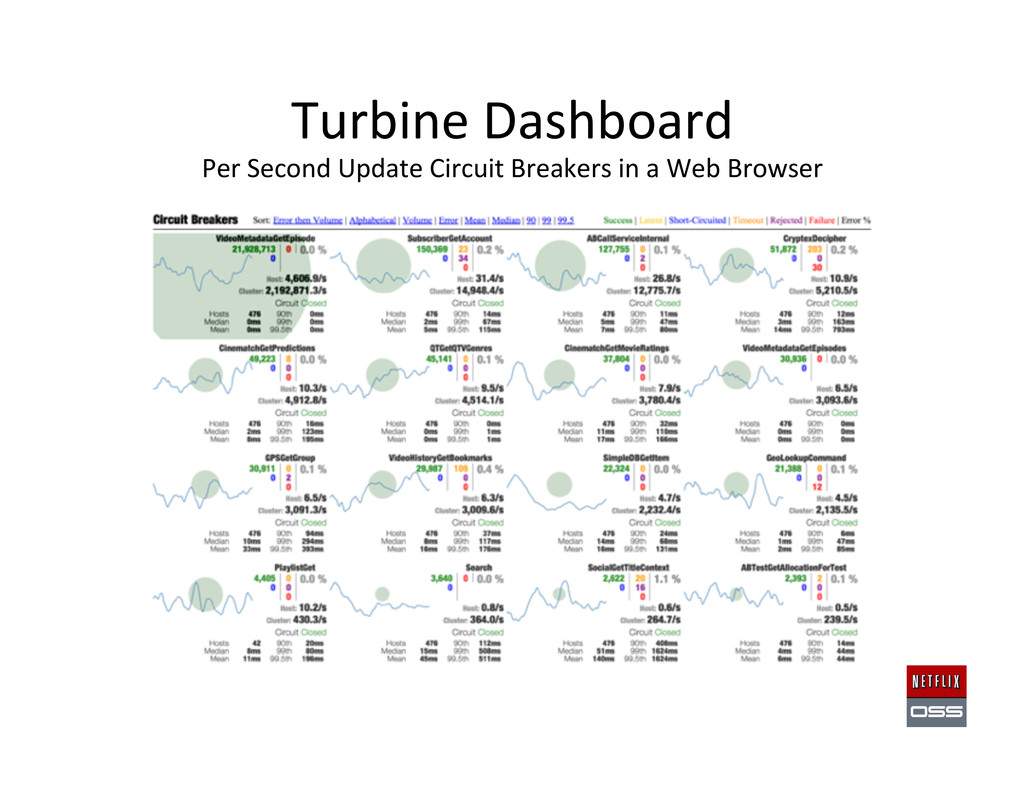
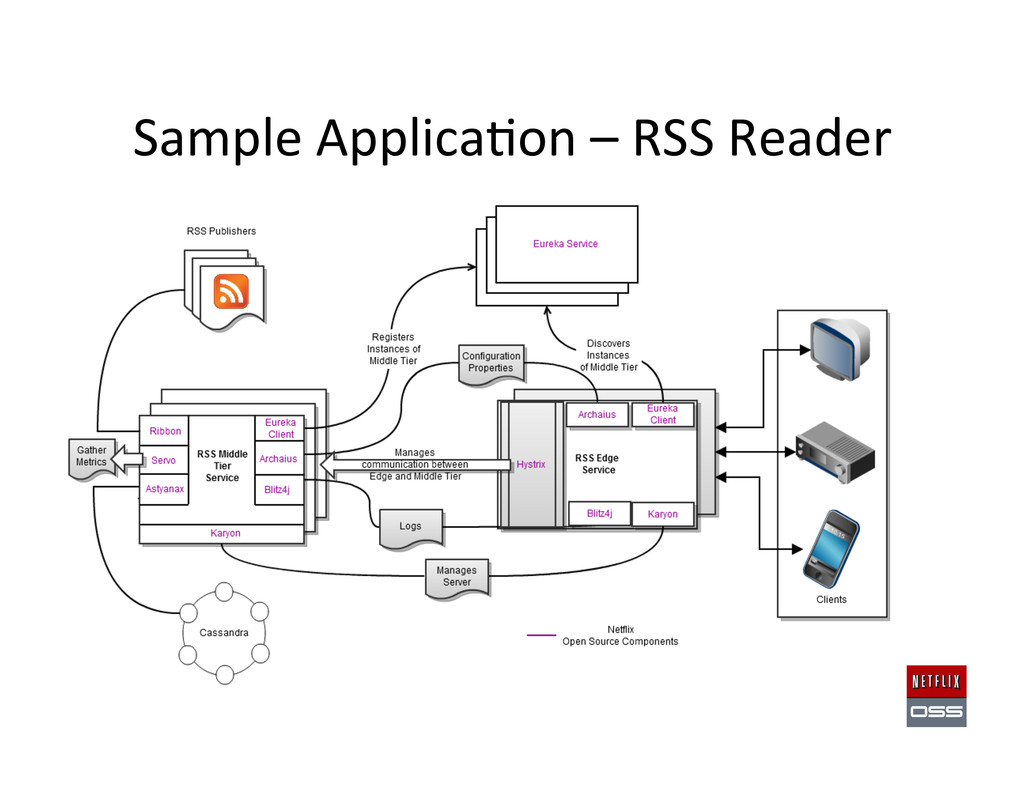
Set up AWS Accounts to get the founda,on in place 2. Security and access management setup 3. Account Management: Asgard to deploy & Ice for cost monitoring 4. Build Tools: Aminator to automate baking AMIs 5. Service Registry and Searchable Account History: Eureka & Edda 6. Configura,on Management: Archaius dynamic property system 7. Data storage: Cassandra, Astyanax, Priam, EVCache 8. Dynamic traffic rou,ng: Denominator, Zuul, Ribbon, Karyon 9. Availability: Simian Army (Chaos Monkey), Hystrix, Turbine 10. Developer produc,vity: Blitz4J, GCViz, Pytheas, RxJava 11. Big Data: Genie for Hadoop PaaS, Lips,ck visualizer for Pig 12. Sample Apps to get started: RSS Reader, ACME Air, FluxCapacitor -
Flow of Code and Data Between AWS Accounts
Produc,on Account Archive Account Auditable Account Dev Test Build Account AMI AMI Backup Data to S3 Weekend S3 restore New Code Backup Data to S3 -
Account Security • Protect Accounts – Two factor authen,ca,on
for primary login • Delegated Minimum Privilege – Create IAM roles for everything • Security Groups – Control who can call your services -
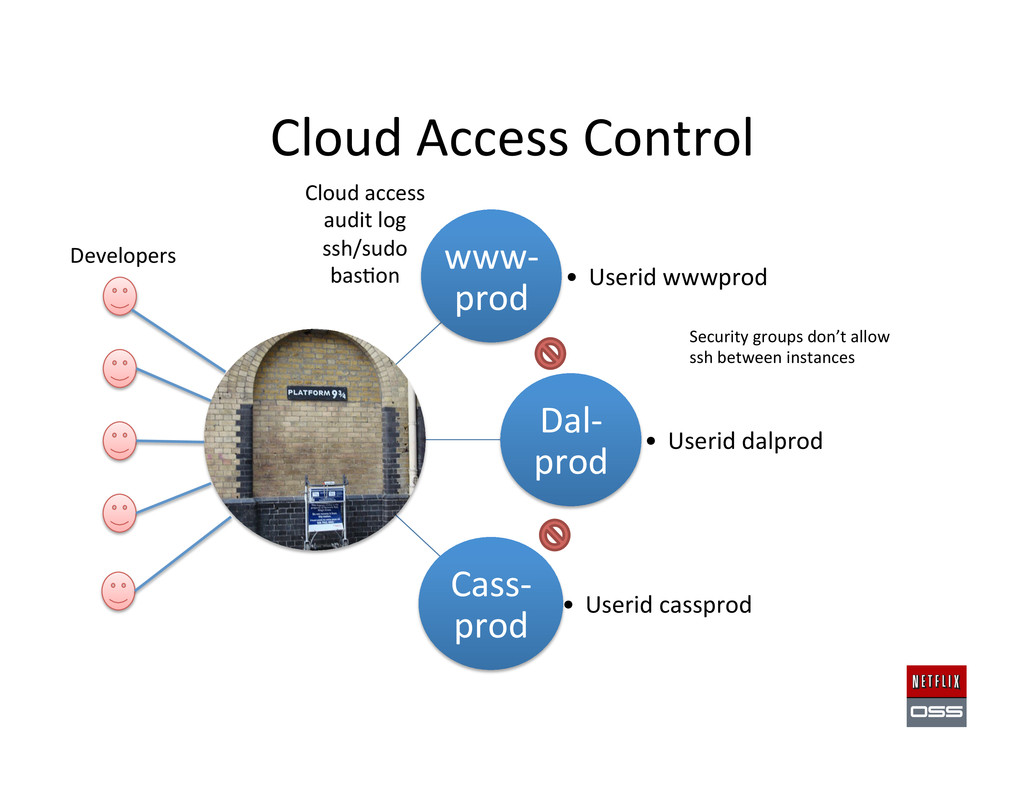
Cloud Access Control www-‐ prod • Userid wwwprod
Dal-‐ prod • Userid dalprod Cass-‐ prod • Userid cassprod Cloud access audit log ssh/sudo bas,on Security groups don’t allow ssh between instances Developers -
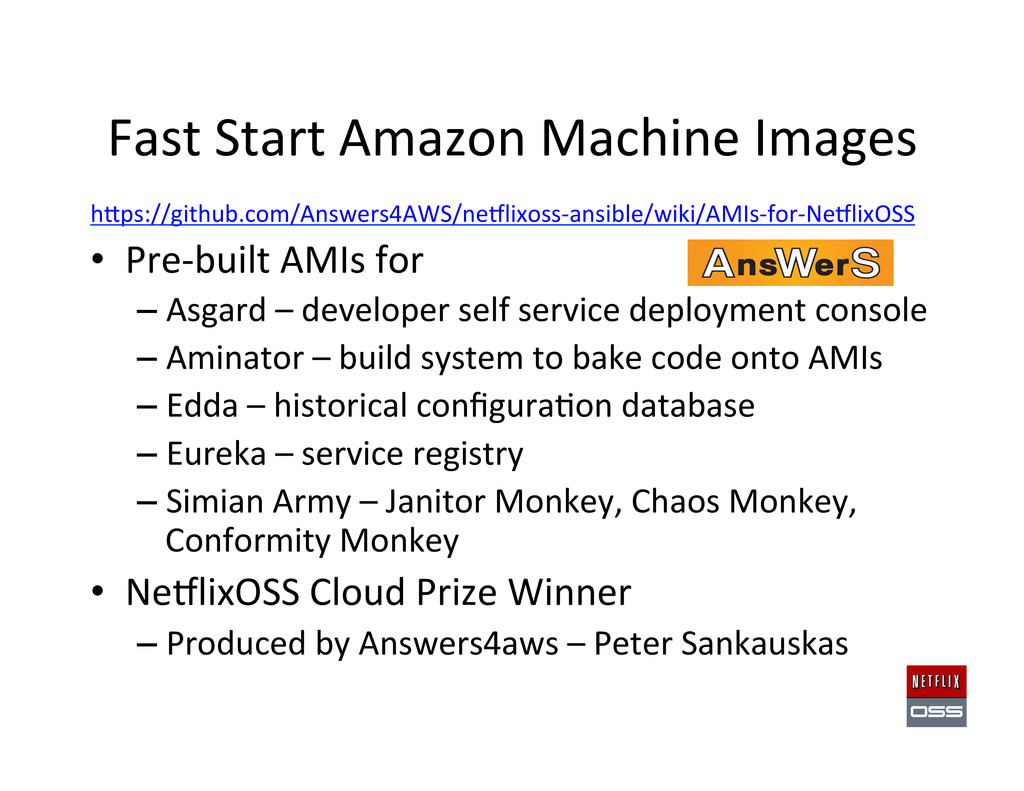
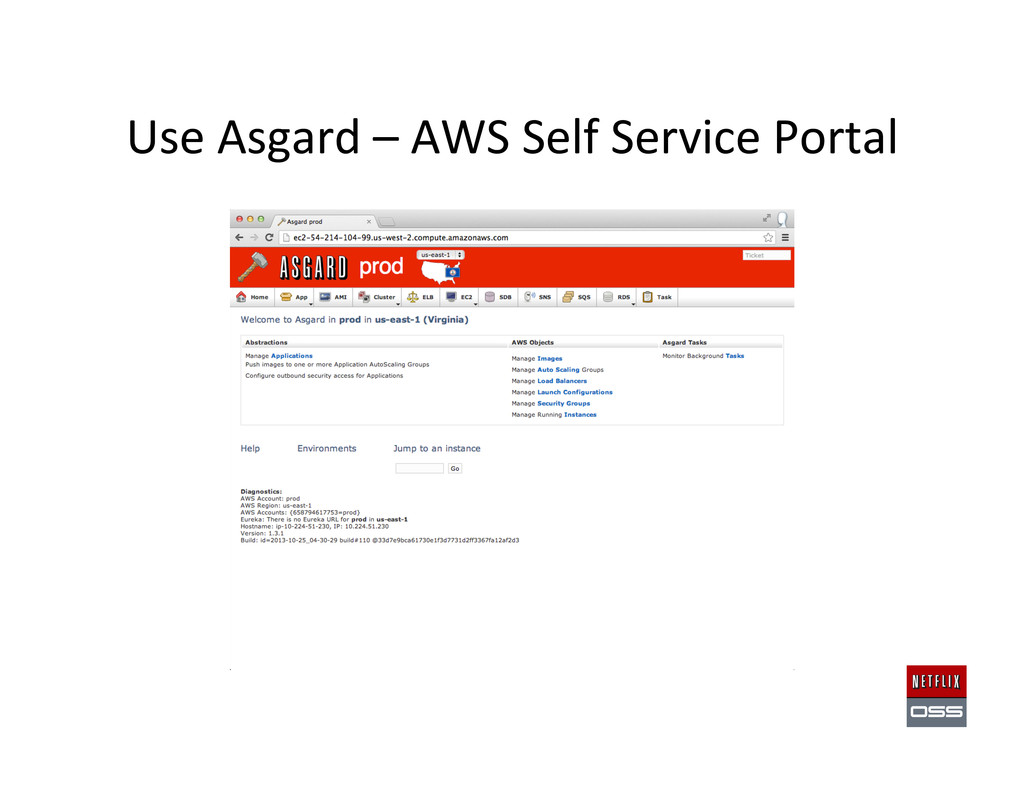
Fast Start Amazon Machine Images h#ps://github.com/Answers4AWS/neClixoss-‐ansible/wiki/AMIs-‐for-‐NeClixOSS • Pre-‐built
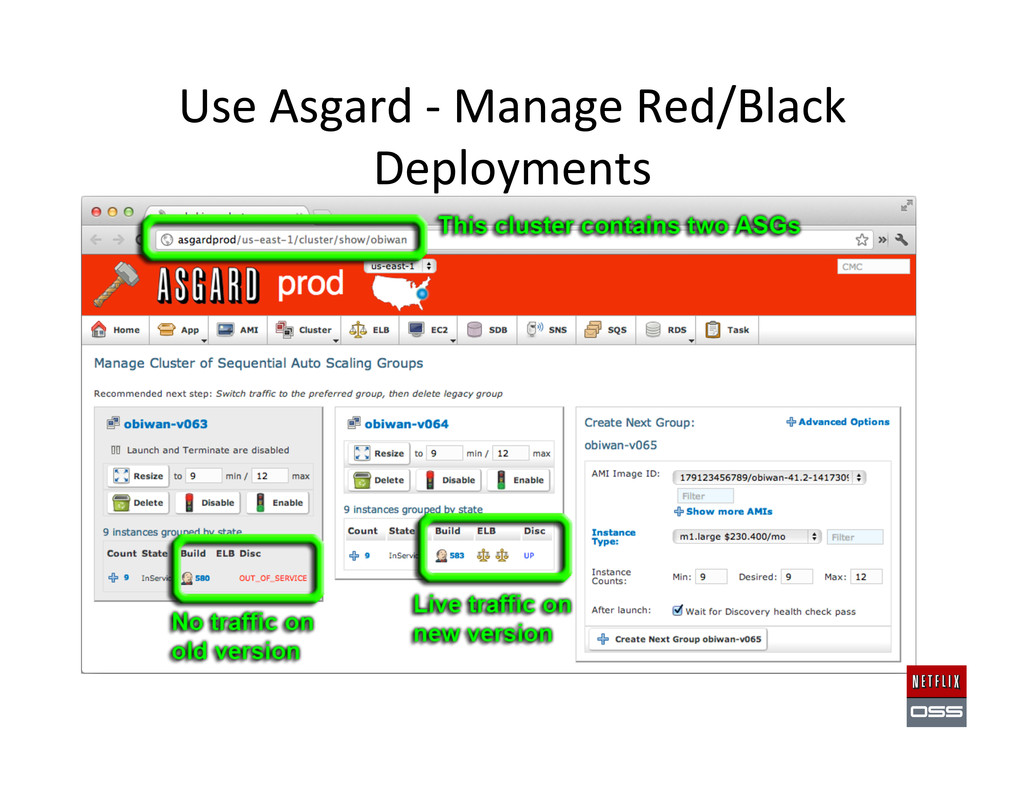
AMIs for – Asgard – developer self service deployment console – Aminator – build system to bake code onto AMIs – Edda – historical configura,on database – Eureka – service registry – Simian Army – Janitor Monkey, Chaos Monkey, Conformity Monkey • NeClixOSS Cloud Prize Winner – Produced by Answers4aws – Peter Sankauskas -
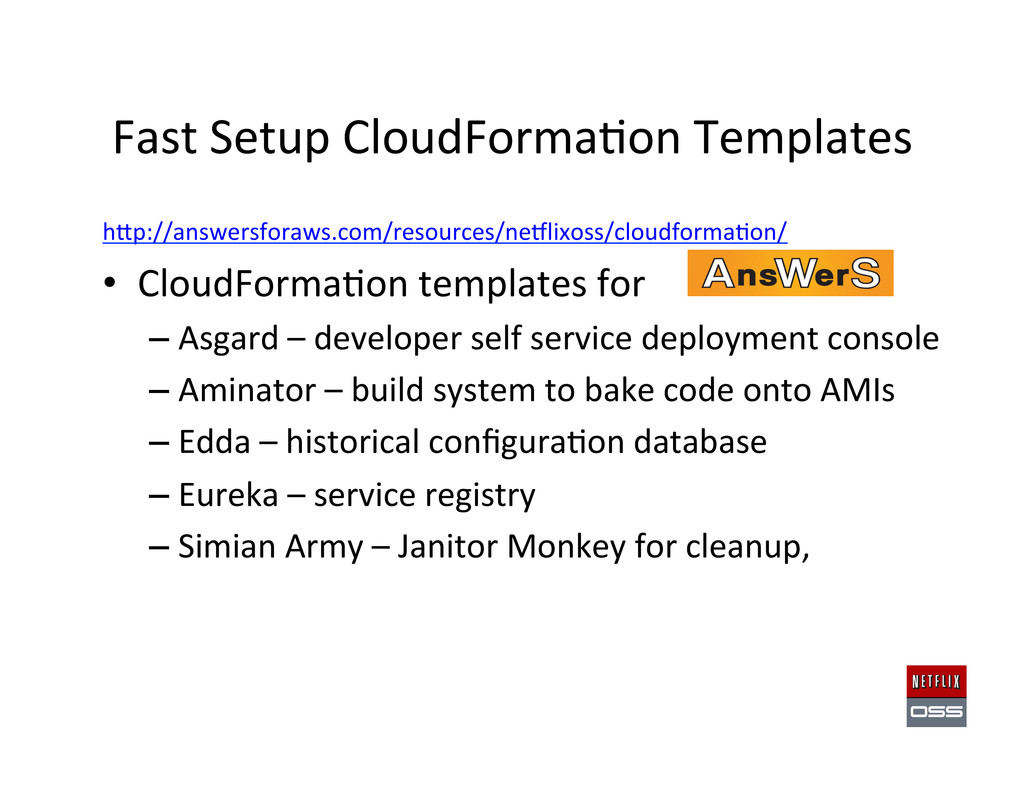
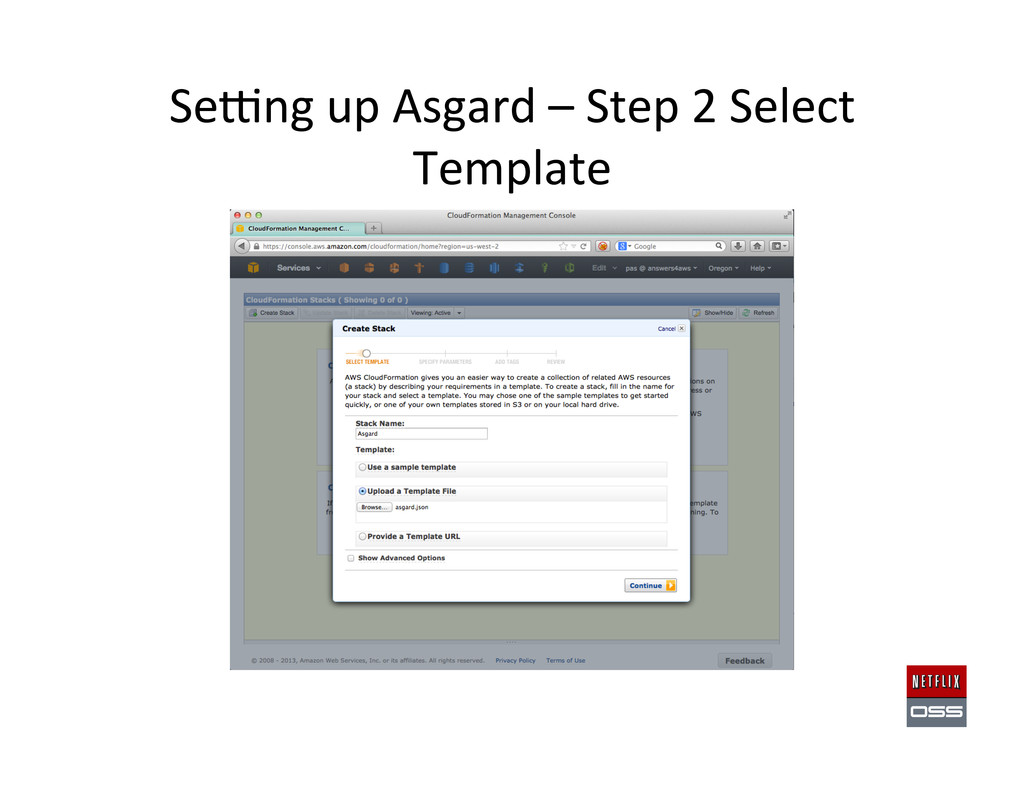
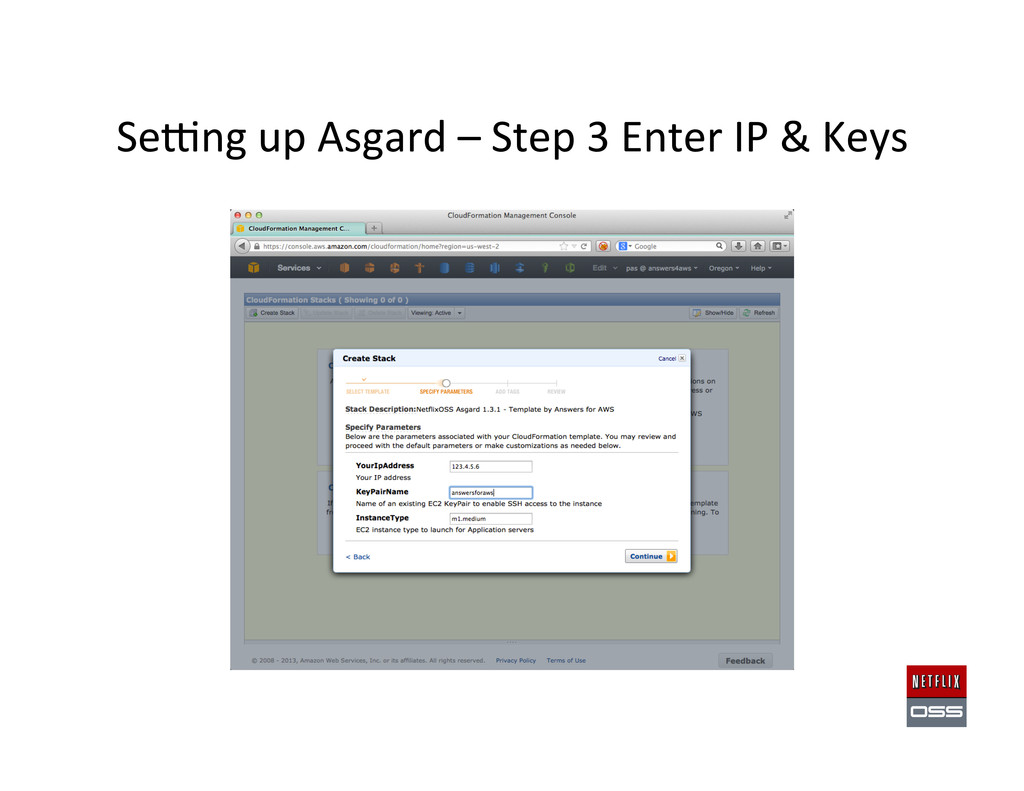
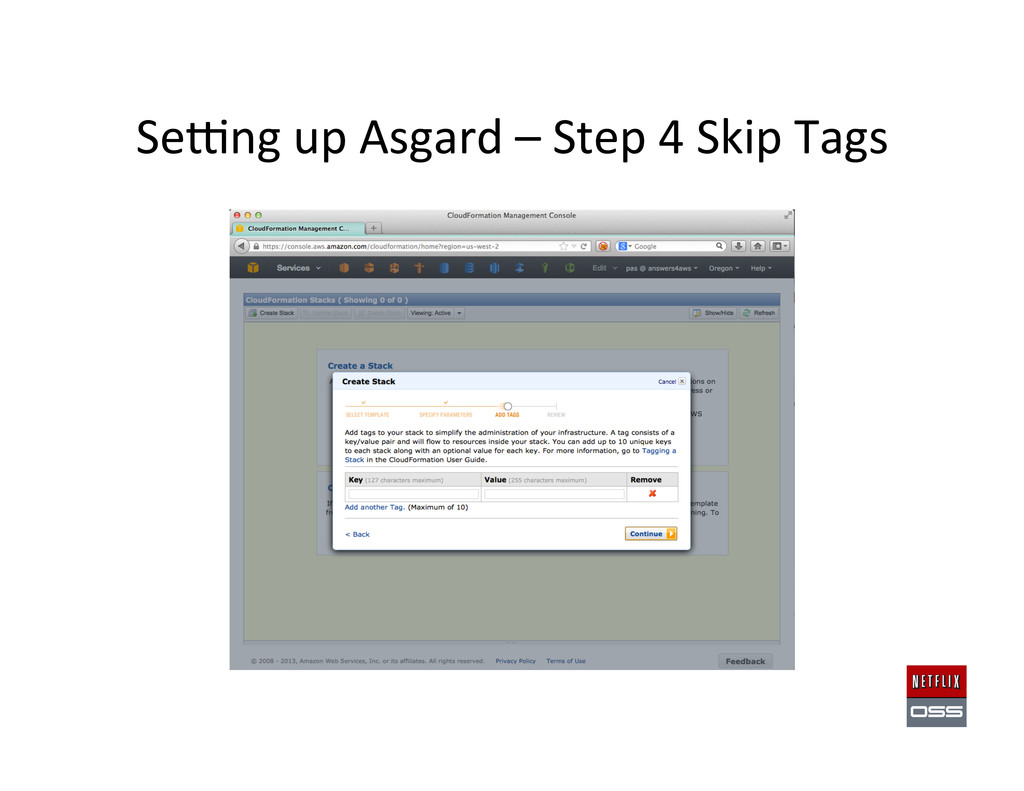
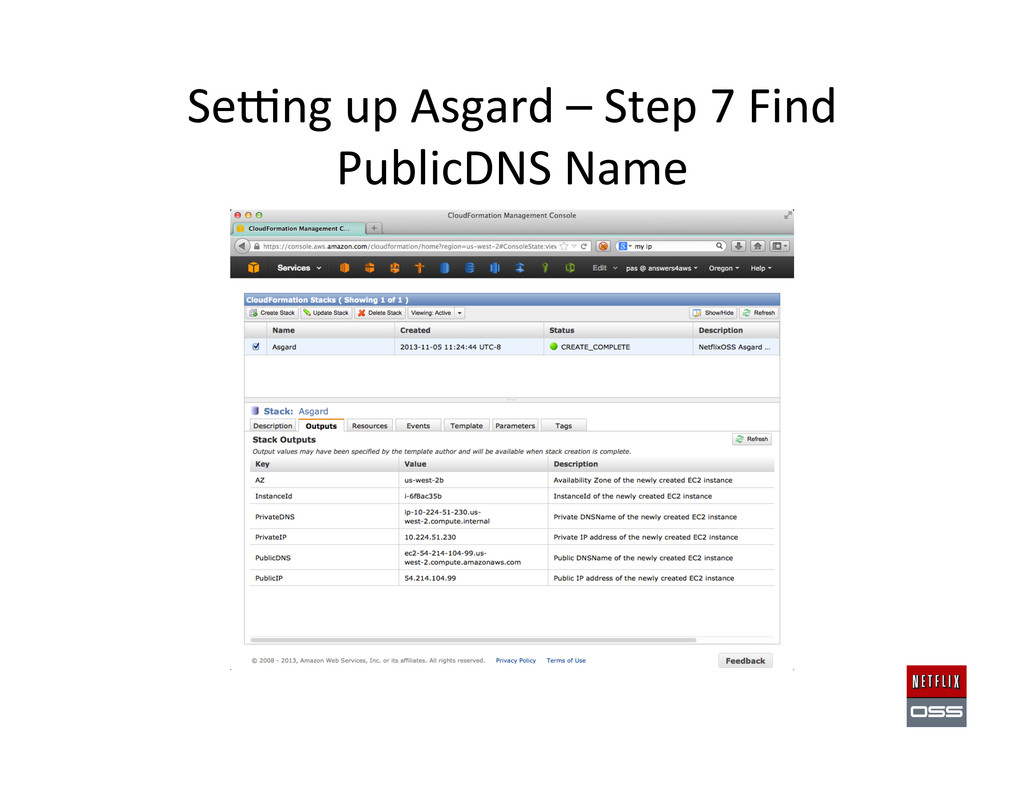
Fast Setup CloudForma,on Templates h#p://answersforaws.com/resources/neClixoss/cloudforma,on/ • CloudForma,on templates
for – Asgard – developer self service deployment console – Aminator – build system to bake code onto AMIs – Edda – historical configura,on database – Eureka – service registry – Simian Army – Janitor Monkey for cleanup, -
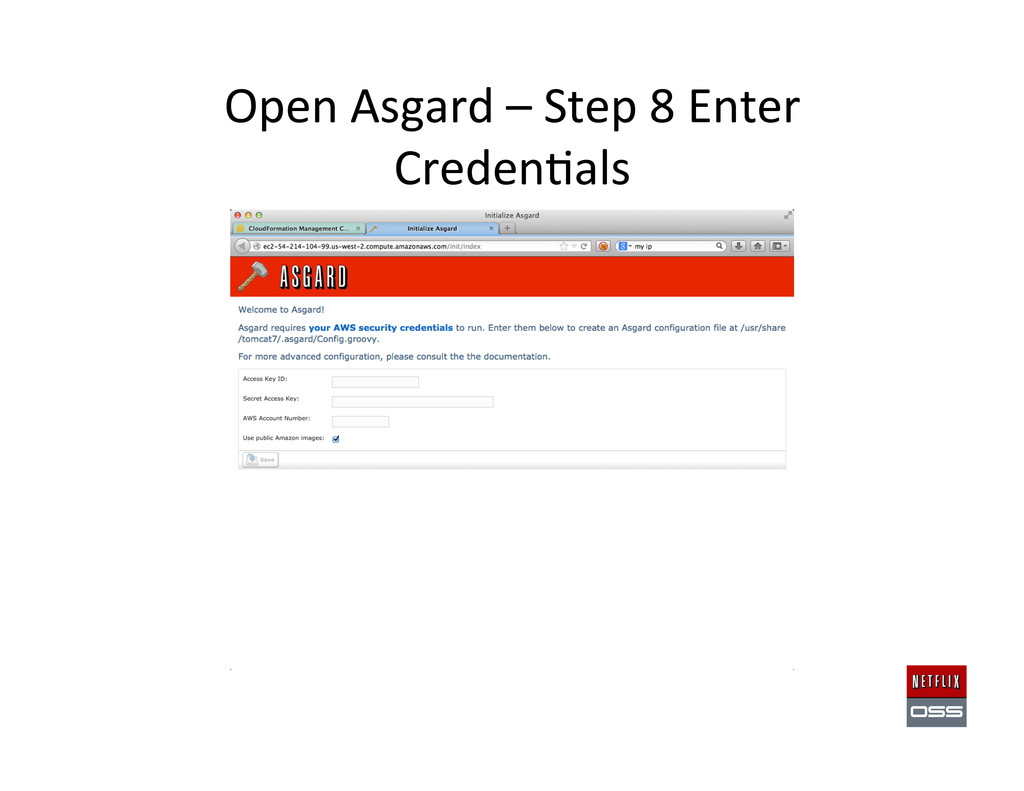
CloudForma,on Walk-‐Through for Asgard (Repeat for Prod,
Test and Audit Accounts) -
Sewng up ICE • Visit github site for instruc,ons
• Currently depends on HiCharts – Non-‐open source package license – Free for non-‐commercial use – Download and license your own copy – We can’t provide a pre-‐built AMI – sorry! • Long term plan to make ICE fully OSS – Anyone want to help? -
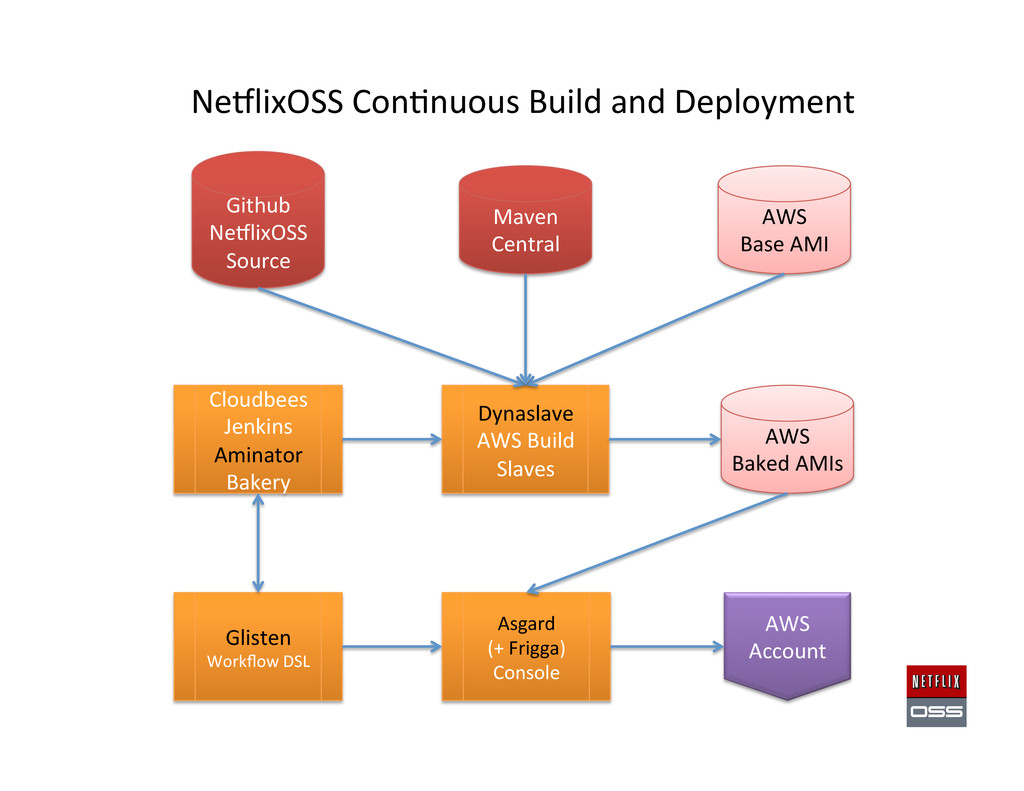
Build Pipeline Automa,on Jenkins in the Cloud auto-‐builds NeClixOSS
Pull Requests h#p://www.cloudbees.com/jenkins -
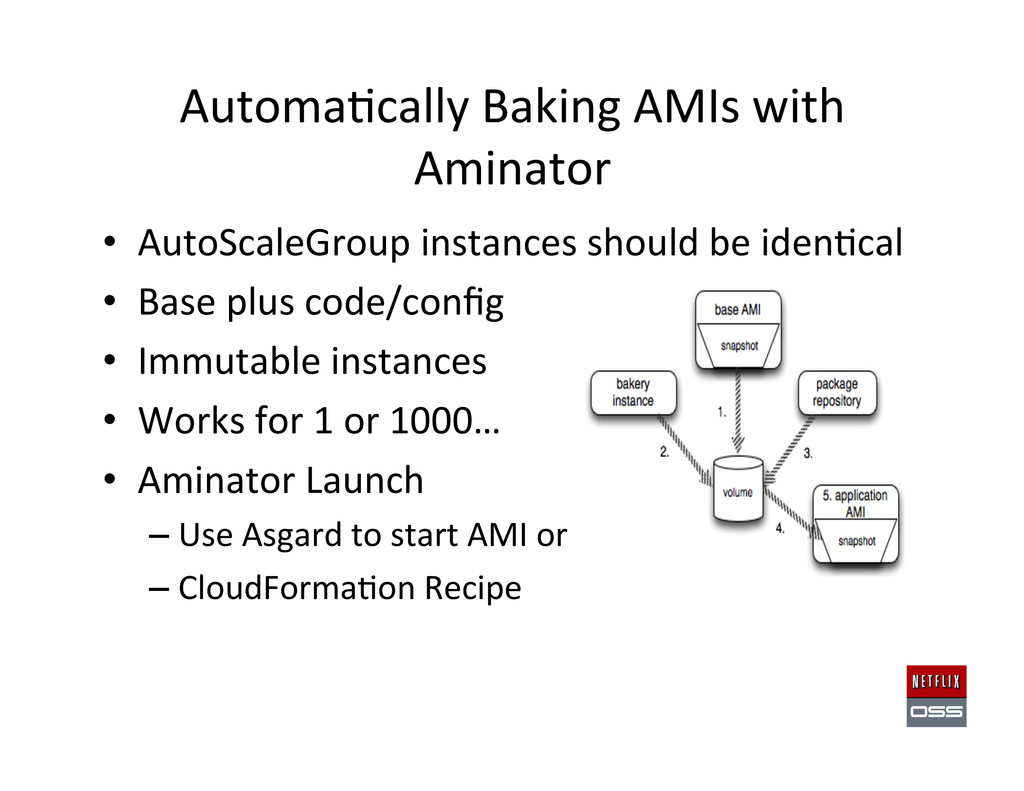
Automa,cally Baking AMIs with Aminator • AutoScaleGroup instances
should be iden,cal • Base plus code/config • Immutable instances • Works for 1 or 1000… • Aminator Launch – Use Asgard to start AMI or – CloudForma,on Recipe -
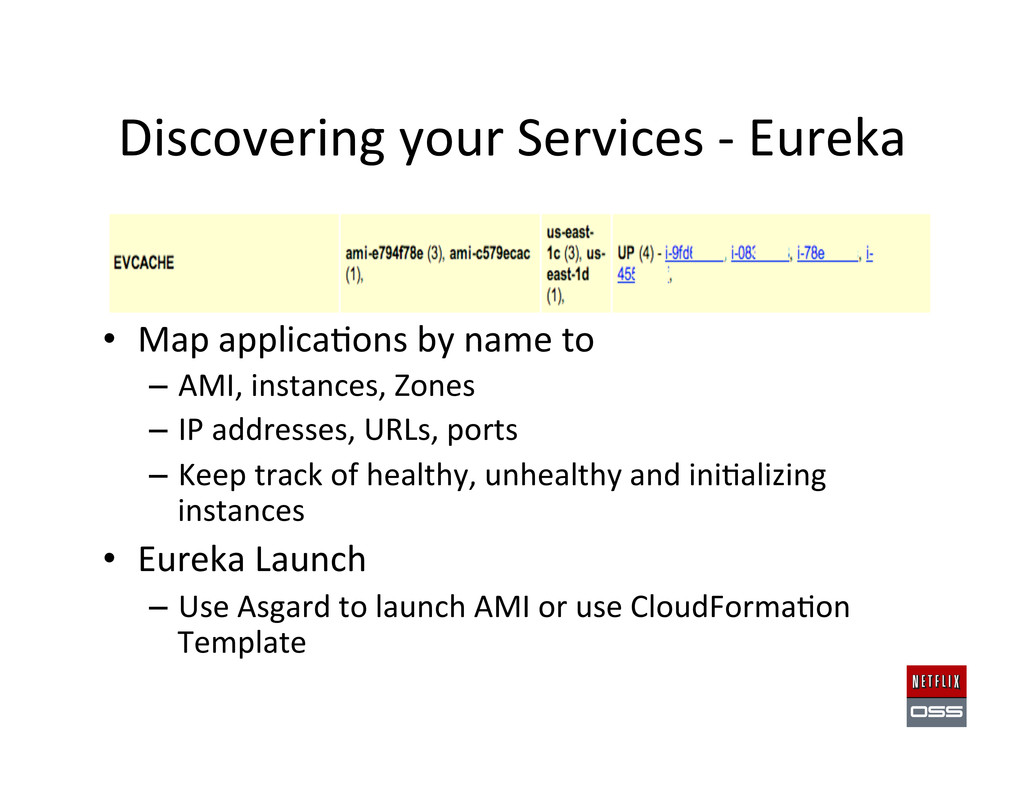
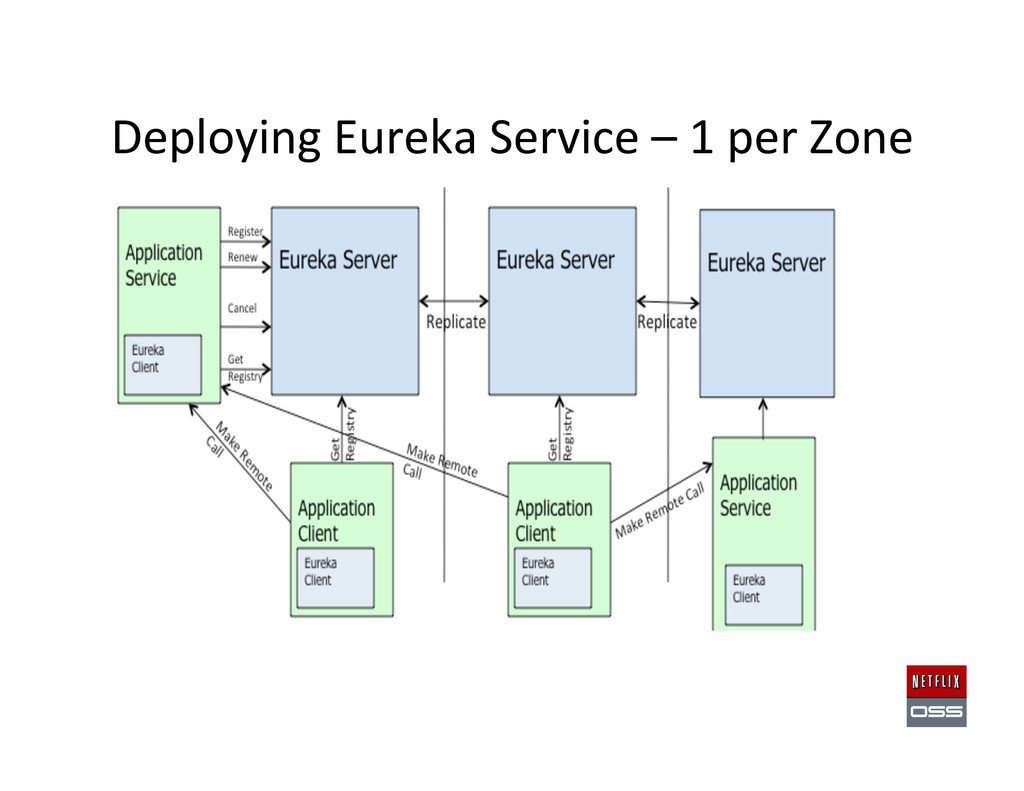
Discovering your Services -‐ Eureka • Map applica,ons by
name to – AMI, instances, Zones – IP addresses, URLs, ports – Keep track of healthy, unhealthy and ini,alizing instances • Eureka Launch – Use Asgard to launch AMI or use CloudForma,on Template -
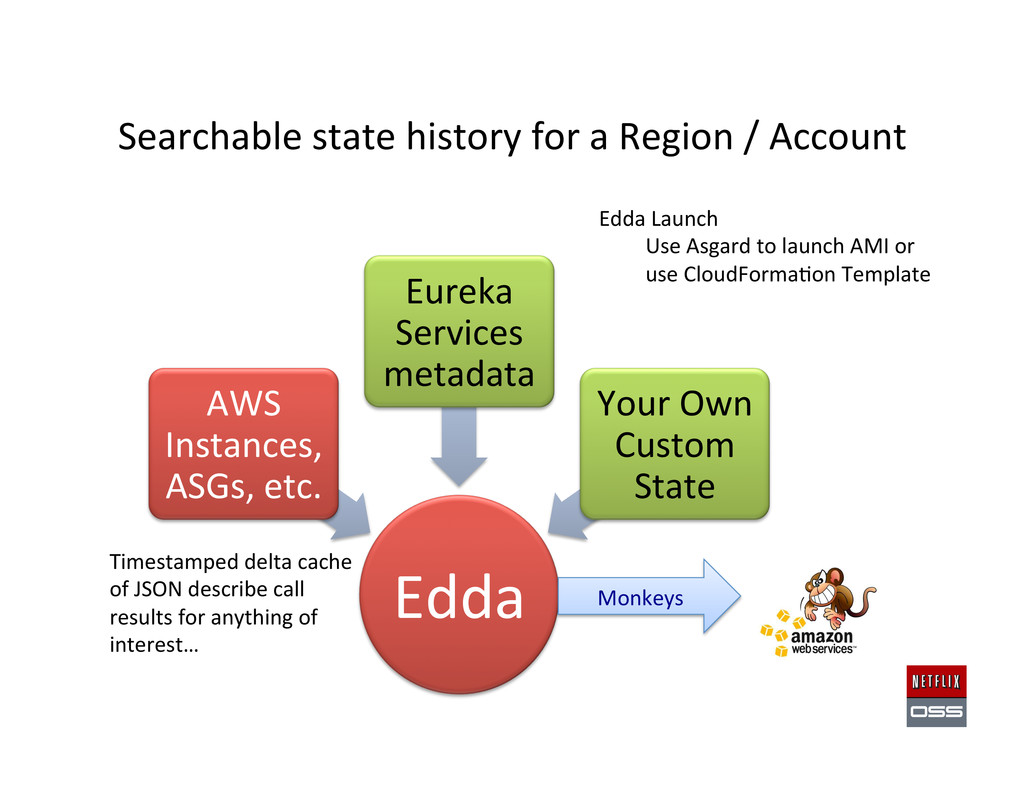
Edda AWS Instances, ASGs, etc. Eureka
Services metadata Your Own Custom State Searchable state history for a Region / Account Monkeys Timestamped delta cache of JSON describe call results for anything of interest… Edda Launch Use Asgard to launch AMI or use CloudForma,on Template -
Edda Query Examples Find any instances that have ever
had a specific public IP address! $ curl "http://edda/api/v2/view/instances;publicIpAddress=1.2.3.4;_since=0"! ["i-0123456789","i-012345678a","i-012345678b”]! ! Show the most recent change to a security group! $ curl "http://edda/api/v2/aws/securityGroups/sg-0123456789;_diff;_all;_limit=2"! --- /api/v2/aws.securityGroups/sg-0123456789;_pp;_at=1351040779810! +++ /api/v2/aws.securityGroups/sg-0123456789;_pp;_at=1351044093504! @@ -1,33 +1,33 @@! {! …! "ipRanges" : [! "10.10.1.1/32",! "10.10.1.2/32",! + "10.10.1.3/32",! - "10.10.1.4/32"! …! }! -
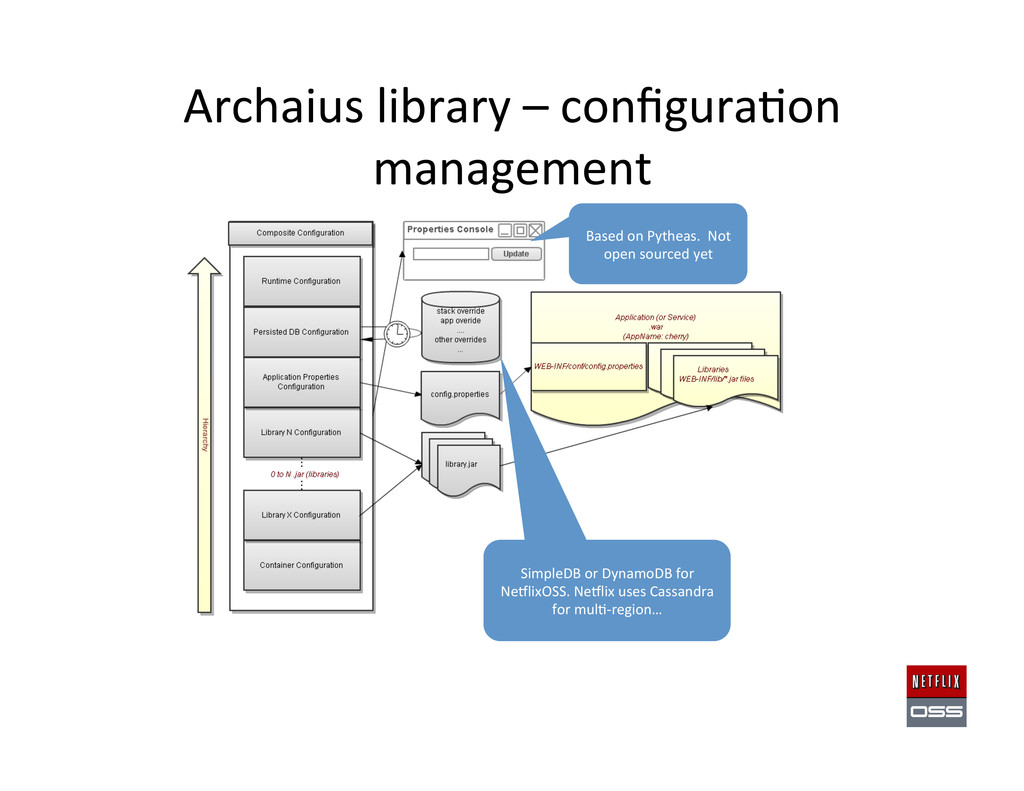
Archaius library – configura,on management SimpleDB or DynamoDB
for NeClixOSS. NeClix uses Cassandra for mul,-‐region… Based on Pytheas. Not open sourced yet -
Data Storage Op,ons • RDS for MySQL –
Deploy using Asgard • DynamoDB – Fast, easy to setup and scales up from a very low cost base • Cassandra – Provides portability, mul,-‐region support, very large scale – Storage model supports incremental/immutable backups – Priam: easy deploy automa,on for Cassandra on AWS -
Priam – Cassandra co-‐process • Runs alongside Cassandra on
each instance • Fully distributed, no central master coordina,on • S3 Based backup and recovery automa,on • Bootstrapping and automated token assignment. • Centralized configura,on management • RESTful monitoring and metrics • Underlying config in SimpleDB – NeClix uses Cassandra “turtle” for Mul,-‐region -
Astyanax Cassandra Client for Java • Features – Abstrac,on
of connec,on pool from RPC protocol – Fluent Style API – Opera,on retry with backoff – Token aware – Batch manager – Many useful recipes – En,ty Mapper based on JPA annota,ons -
Cassandra Astyanax Recipes • Distributed row lock (without needing
zookeeper) • Mul,-‐region row lock • Uniqueness constraint • Mul,-‐row uniqueness constraint • Chunked and mul,-‐threaded large file storage • Reverse index search • All rows query • Durable message queue • Contributed: High cardinality reverse index -
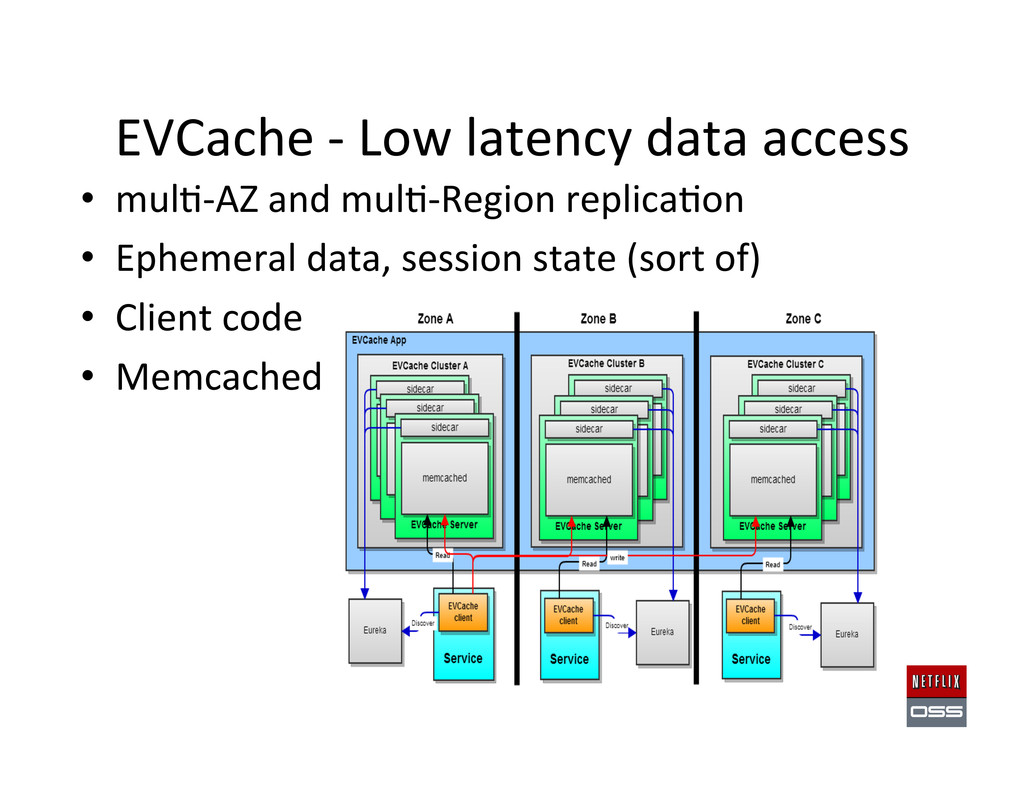
EVCache -‐ Low latency data access • mul,-‐AZ and
mul,-‐Region replica,on • Ephemeral data, session state (sort of) • Client code • Memcached -
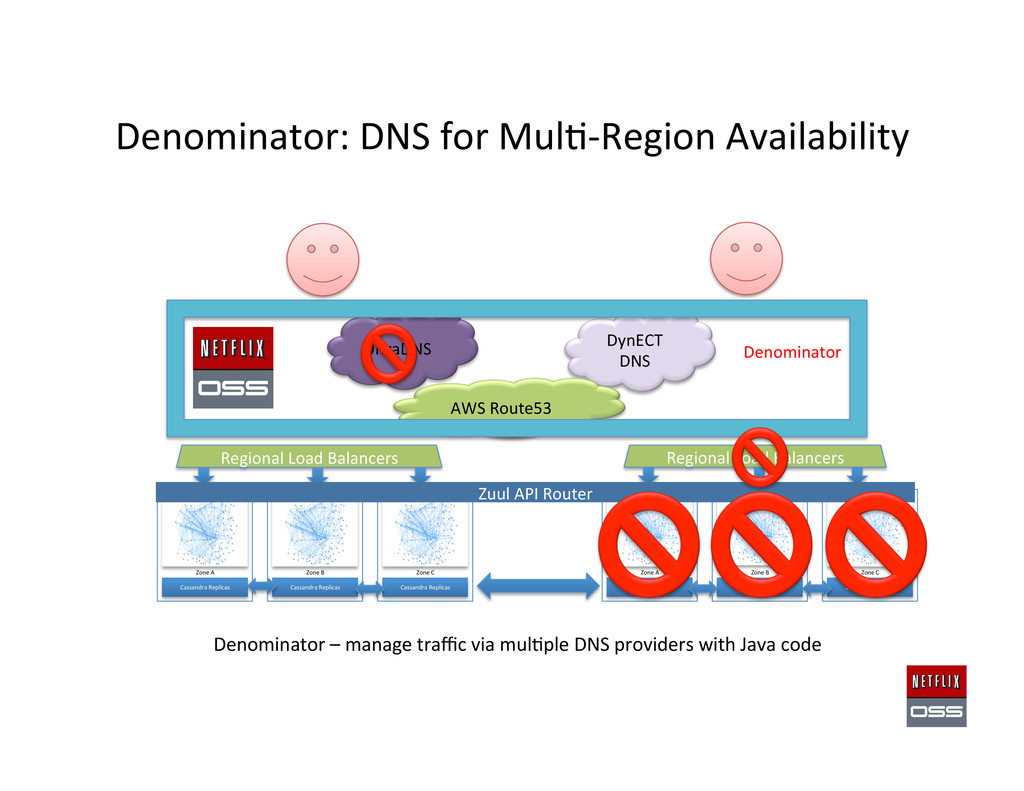
Denominator: DNS for Mul,-‐Region Availability Cassandra Replicas Zone
A Cassandra Replicas Zone B Cassandra Replicas Zone C Cassandra Replicas Zone A Cassandra Replicas Zone B Cassandra Replicas Zone C Denominator – manage traffic via mul,ple DNS providers with Java code Regional Load Balancers Regional Load Balancers UltraDNS DynECT DNS AWS Route53 Denominator Zuul API Router -
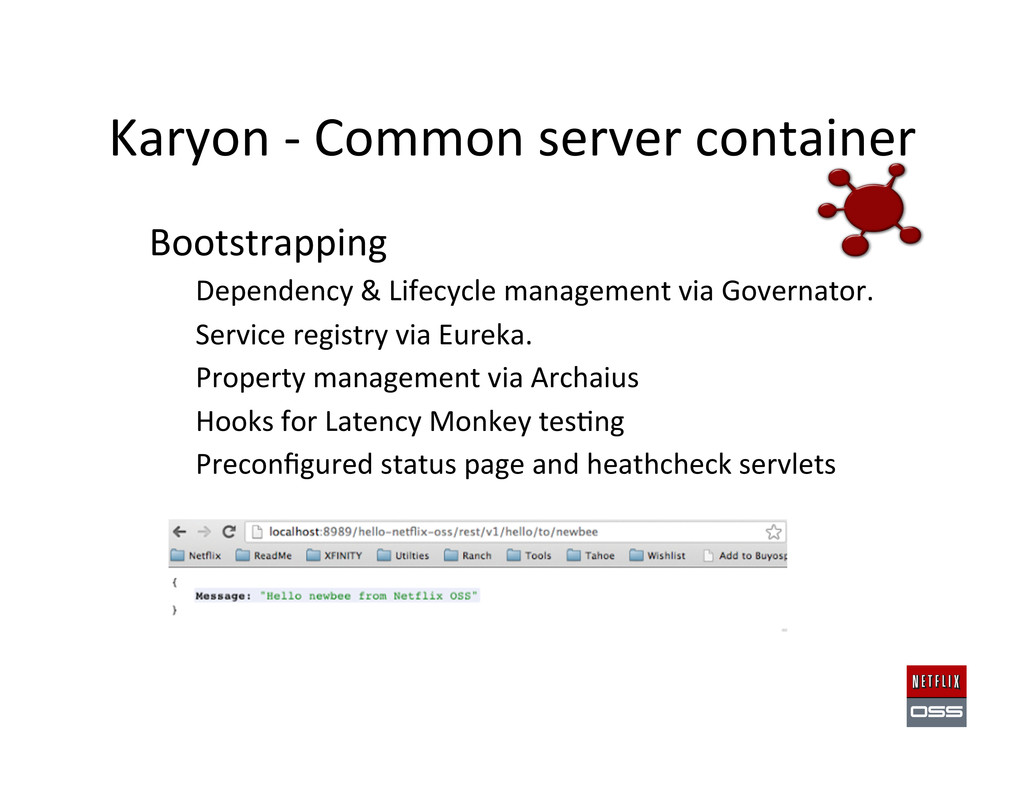
Karyon -‐ Common server container • Bootstrapping o Dependency
& Lifecycle management via Governator. o Service registry via Eureka. o Property management via Archaius o Hooks for Latency Monkey tes,ng o Preconfigured status page and heathcheck servlets -
• Embedded Status Page Console o Environment o
Eureka o JMX Karyon -
Clean up your room! – Janitor Monkey Works with
Edda history to clean up aNer Asgard -
Conformity Monkey Track and alert for old code versions
and known issues Walks Karyon status pages found via Edda -
Blitz4J – Non-‐blocking Logging • Be#er handling of log
messages during storms • Replace sync with concurrent data structures. • Extreme configurability • Isola,on of app threads from logging threads -
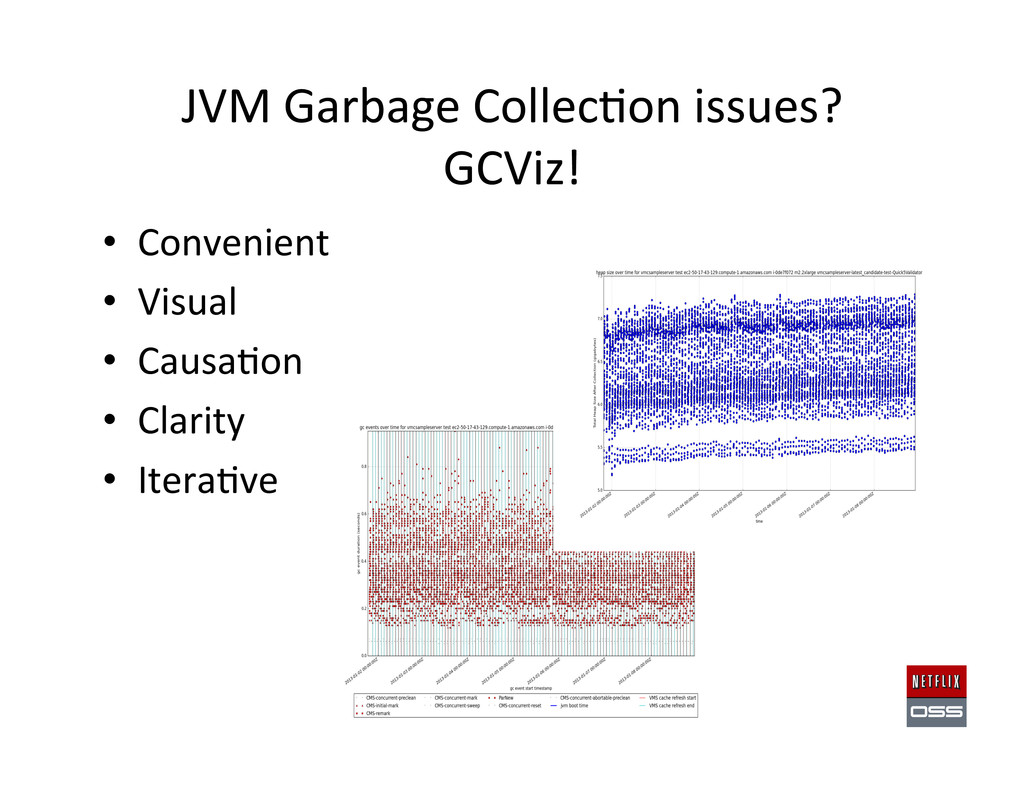
JVM Garbage Collec,on issues? GCViz! • Convenient
• Visual • Causa,on • Clarity • Itera,ve -
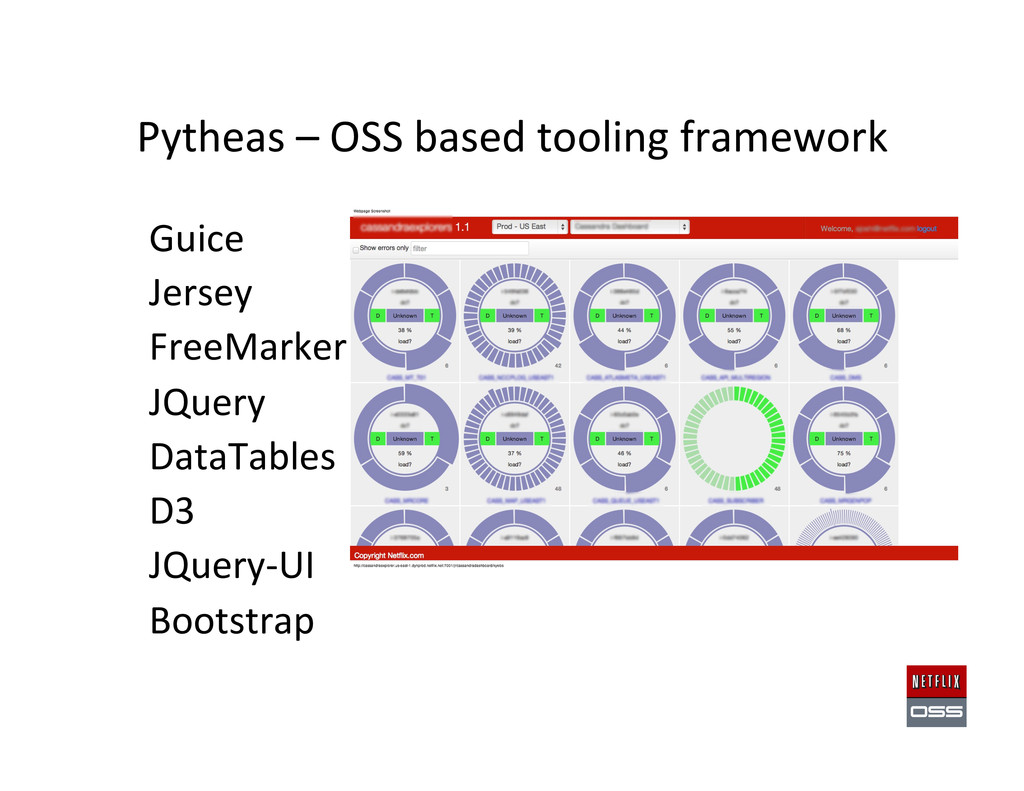
Pytheas – OSS based tooling framework • Guice • Jersey
• FreeMarker • JQuery • DataTables • D3 • JQuery-‐UI • Bootstrap -
RxJava -‐ Func,onal Reac,ve Programming • A Simpler Approach
to Concurrency – Use Observable as a simple stable composable abstrac,on • Observable Service Layer enables any of – condi,onally return immediately from a cache – block instead of using threads if resources are constrained – use mul,ple threads – use non-‐blocking IO – migrate an underlying implementa,on from network based to in-‐memory cache -
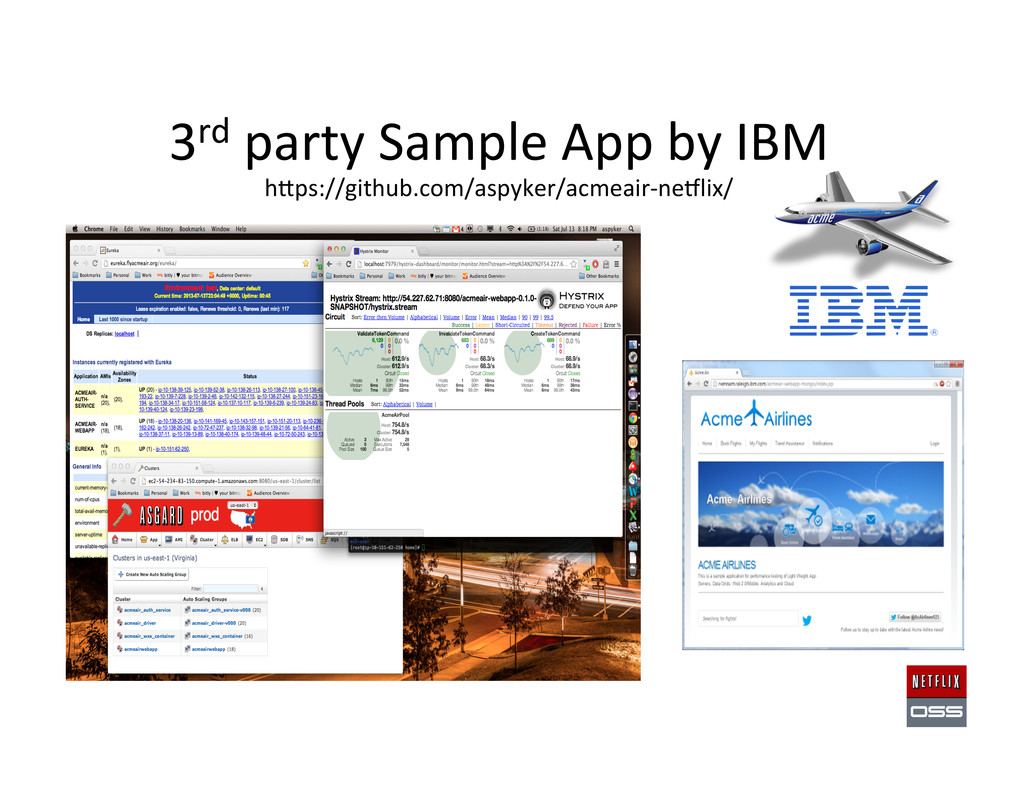
3rd Party Sample App by Chris Fregly fluxcapacitor.com
Flux Capacitor is a Java-‐based reference app using: archaius (zookeeper-‐based dynamic configura,on) astyanax (cassandra client) blitz4j (asynchronous logging) curator (zookeeper client) eureka (discovery service) exhibitor (zookeeper administra,on) governator (guice-‐based DI extensions) hystrix (circuit breaker) karyon (common base web service) ribbon (eureka-‐based REST client) servo (metrics client) turbine (metrics aggrega,on) Flux also integrates popular open source tools such as Graphite, Jersey, Je#y, Ne#y, and Tomcat. -
Github NeClixOSS Source AWS Base AMI
Maven Central Cloudbees Jenkins Aminator Bakery Dynaslave AWS Build Slaves Asgard (+ Frigga) Console AWS Baked AMIs Glisten Workflow DSL AWS Account NeClixOSS Con,nuous Build and Deployment -
AWS Account Asgard Console Archaius Config
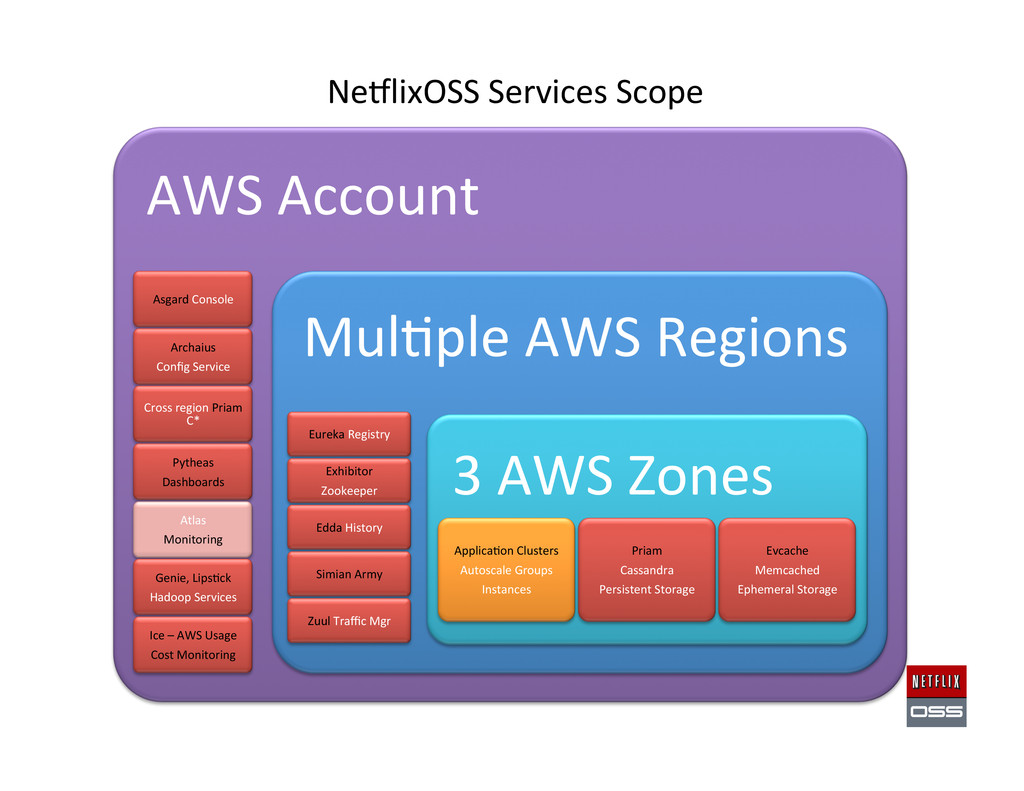
Service Cross region Priam C* Pytheas Dashboards Atlas Monitoring Genie, Lips,ck Hadoop Services Ice – AWS Usage Cost Monitoring Mul,ple AWS Regions Eureka Registry Exhibitor Zookeeper Edda History Simian Army Zuul Traffic Mgr 3 AWS Zones Applica,on Clusters Autoscale Groups Instances Priam Cassandra Persistent Storage Evcache Memcached Ephemeral Storage NeClixOSS Services Scope -
• Baked AMI – Tomcat, Apache, your code • Governator –
Guice based dependency injec,on • Archaius – dynamic configura,on proper,es client • Eureka -‐ service registra,on client Ini,aliza,on • Karyon -‐ Base Server for inbound requests • RxJava – Reac,ve pa#ern • Hystrix/Turbine – dependencies and real-‐,me status • Ribbon and Feign -‐ REST Clients for outbound calls Service Requests • Astyanax – Cassandra client and pa#ern library • Evcache – Zone aware Memcached client • Curator – Zookeeper pa#erns • Denominator – DNS rou,ng abstrac,on Data Access • Blitz4j – non-‐blocking logging • Servo – metrics export for autoscaling • Atlas – high volume instrumenta,on Logging NeClixOSS Instance Libraries -
• CassJmeter – Load tes,ng for Cassandra • Circus Monkey –
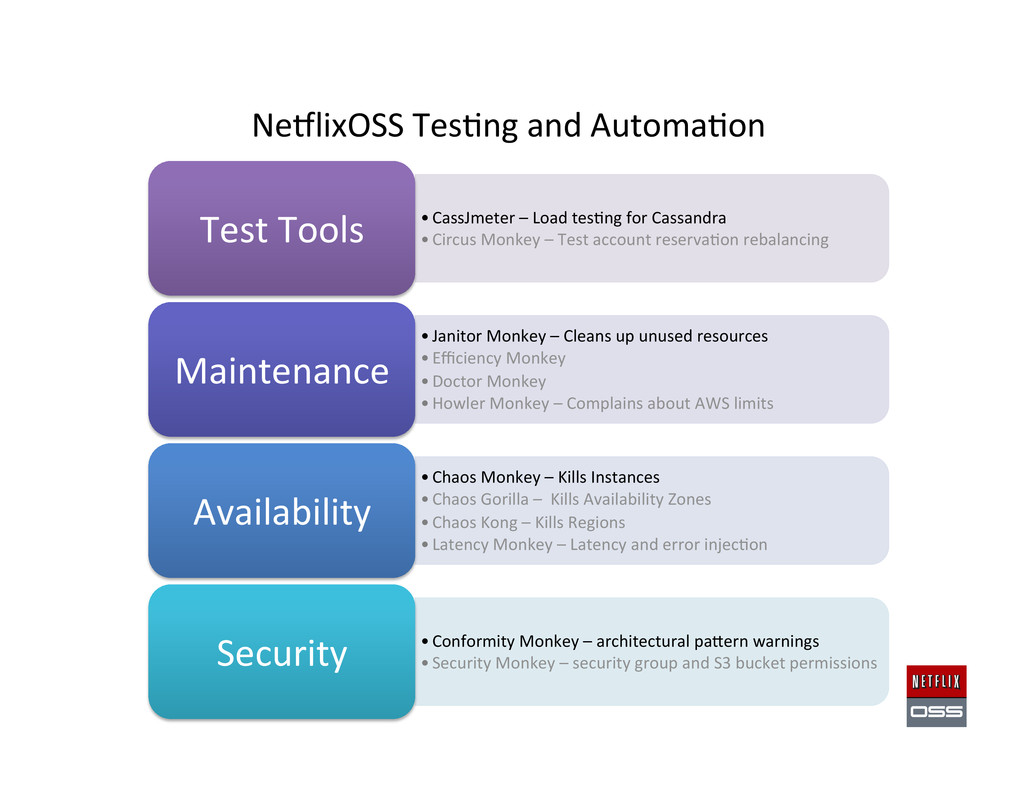
Test account reserva,on rebalancing Test Tools • Janitor Monkey – Cleans up unused resources • Efficiency Monkey • Doctor Monkey • Howler Monkey – Complains about AWS limits Maintenance • Chaos Monkey – Kills Instances • Chaos Gorilla – Kills Availability Zones • Chaos Kong – Kills Regions • Latency Monkey – Latency and error injec,on Availability • Conformity Monkey – architectural pa#ern warnings • Security Monkey – security group and S3 bucket permissions Security NeClixOSS Tes,ng and Automa,on -
Vendor Driven Portability Interest in using NeClixOSS for Enterprise
Private Clouds “It’s done when it runs Asgard” Func,onally complete Demonstrated March 2013 Released June 2013 in V3.3 Vendor and end user interest Openstack “Heat” gewng there Paypal C3 Console based on Asgard IBM Example applica,on “Acme Air” Based on NeClixOSS running on AWS Ported to IBM SoNlayer with Rightscale -
Some of the companies using NeClixOSS (There are
many more, please send us your logo!) -
Use NeClixOSS to scale your startup or enterprise
Contribute to exis,ng github projects and add your own -
Availability Is it running yet? How many places
is it running in? How far apart are those places? -
NeClix Outages • Running very fast with scissors
– Mostly self inflicted – bugs, mistakes from pace of change – Some caused by AWS bugs and mistakes • Incident Life-‐cycle Management by PlaCorm Team – No runbooks, no opera,onal changes by the SREs – Tools to iden,fy what broke and call the right developer • Next step is mul,-‐region ac,ve/ac,ve – Inves,ga,ng and building in stages during 2013 – Could have prevented some of our 2012 outages -
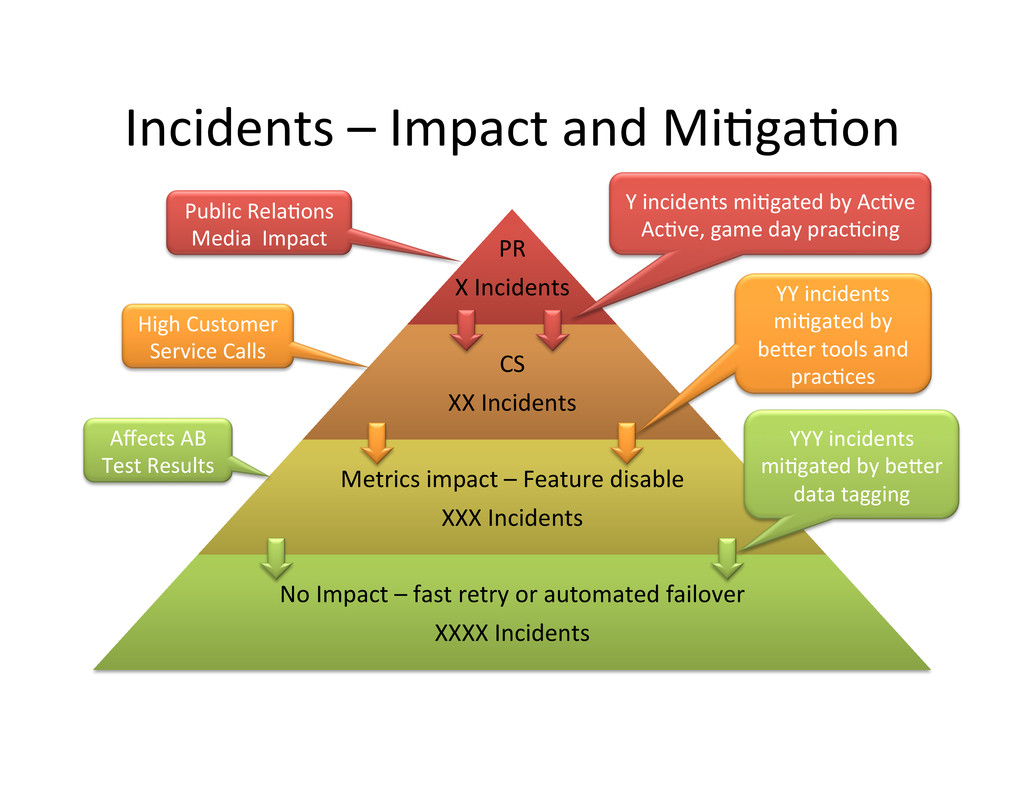
Incidents – Impact and Mi,ga,on PR X Incidents
CS XX Incidents Metrics impact – Feature disable XXX Incidents No Impact – fast retry or automated failover XXXX Incidents Public Rela,ons Media Impact High Customer Service Calls Affects AB Test Results Y incidents mi,gated by Ac,ve Ac,ve, game day prac,cing YY incidents mi,gated by be#er tools and prac,ces YYY incidents mi,gated by be#er data tagging -
Real Web Server Dependencies Flow (NeClix Home page business
transac,on as seen by AppDynamics) Start Here memcached Cassandra Web service S3 bucket Personaliza,on movie group choosers (for US, Canada and Latam) Each icon is three to a few hundred instances across three AWS zones -
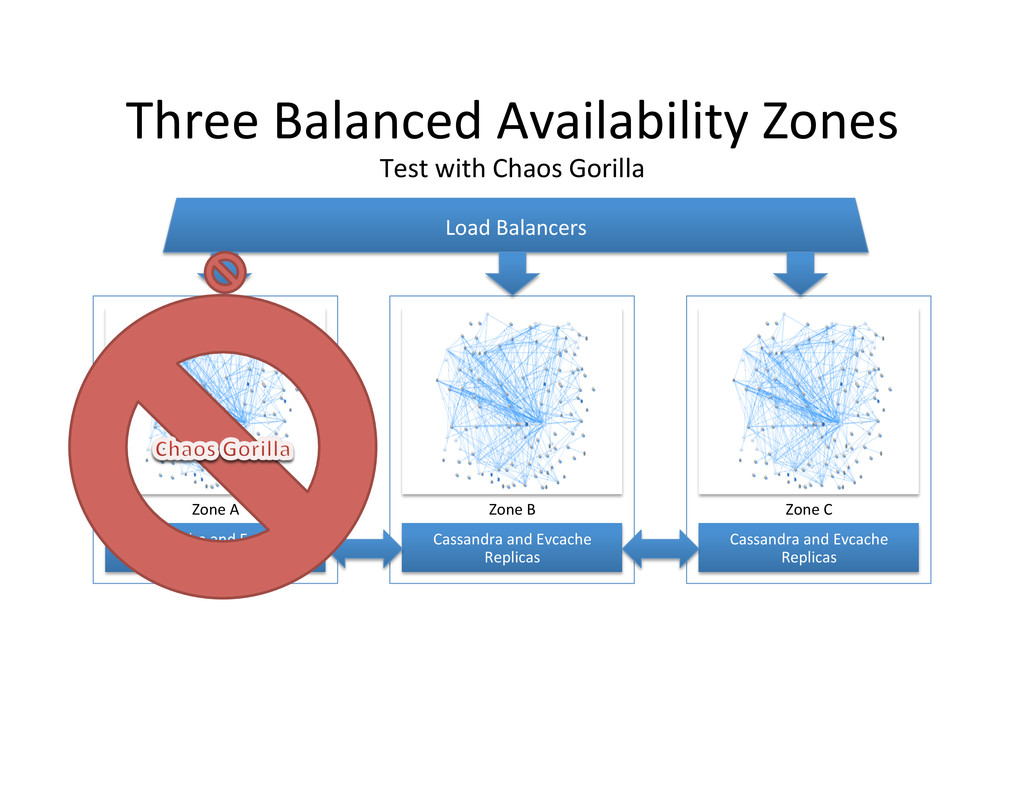
Three Balanced Availability Zones Test with Chaos Gorilla
Cassandra and Evcache Replicas Zone A Cassandra and Evcache Replicas Zone B Cassandra and Evcache Replicas Zone C Load Balancers -
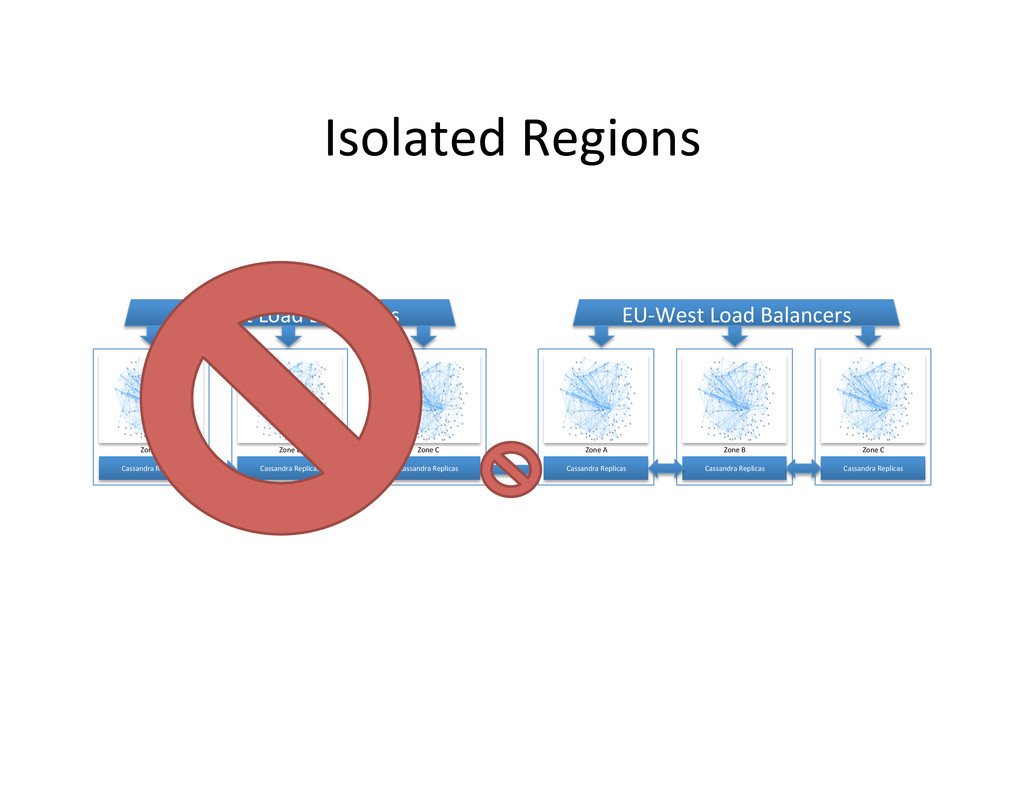
Isolated Regions Cassandra Replicas Zone A Cassandra
Replicas Zone B Cassandra Replicas Zone C US-‐East Load Balancers Cassandra Replicas Zone A Cassandra Replicas Zone B Cassandra Replicas Zone C EU-‐West Load Balancers -
Highly Available NoSQL Storage A highly scalable, available and
durable deployment pa#ern based on Apache Cassandra -
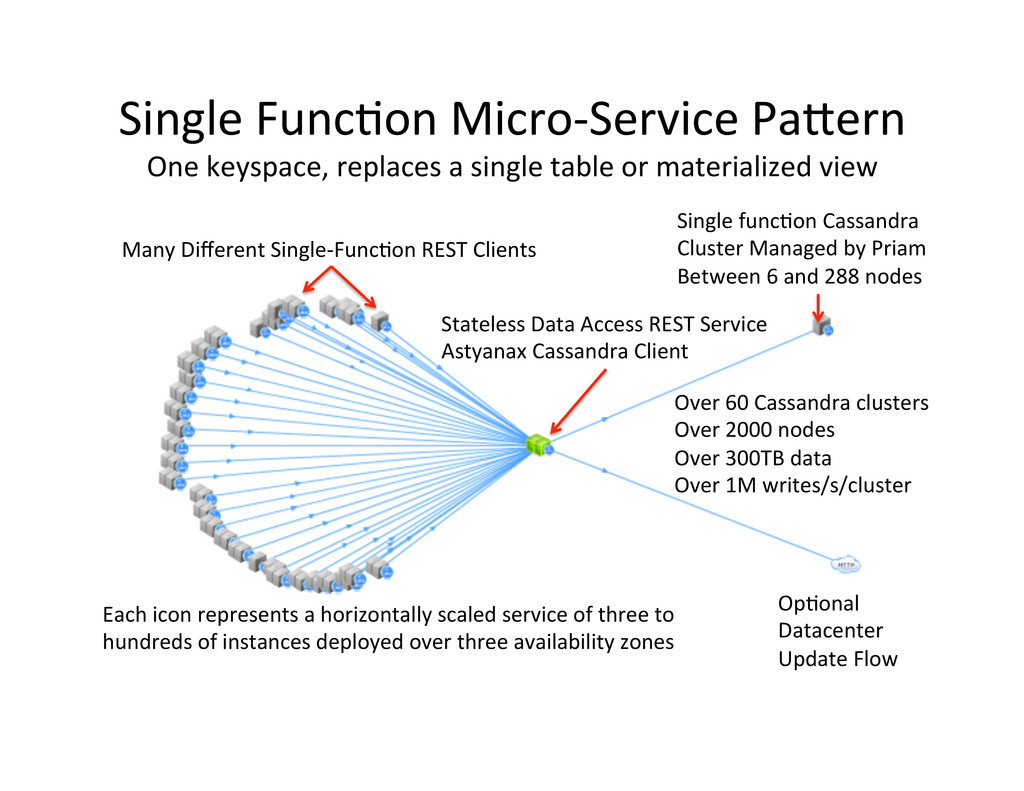
Single Func,on Micro-‐Service Pa#ern One keyspace, replaces a single
table or materialized view Single func,on Cassandra Cluster Managed by Priam Between 6 and 288 nodes Stateless Data Access REST Service Astyanax Cassandra Client Op,onal Datacenter Update Flow Many Different Single-‐Func,on REST Clients Each icon represents a horizontally scaled service of three to hundreds of instances deployed over three availability zones Over 60 Cassandra clusters Over 2000 nodes Over 300TB data Over 1M writes/s/cluster -
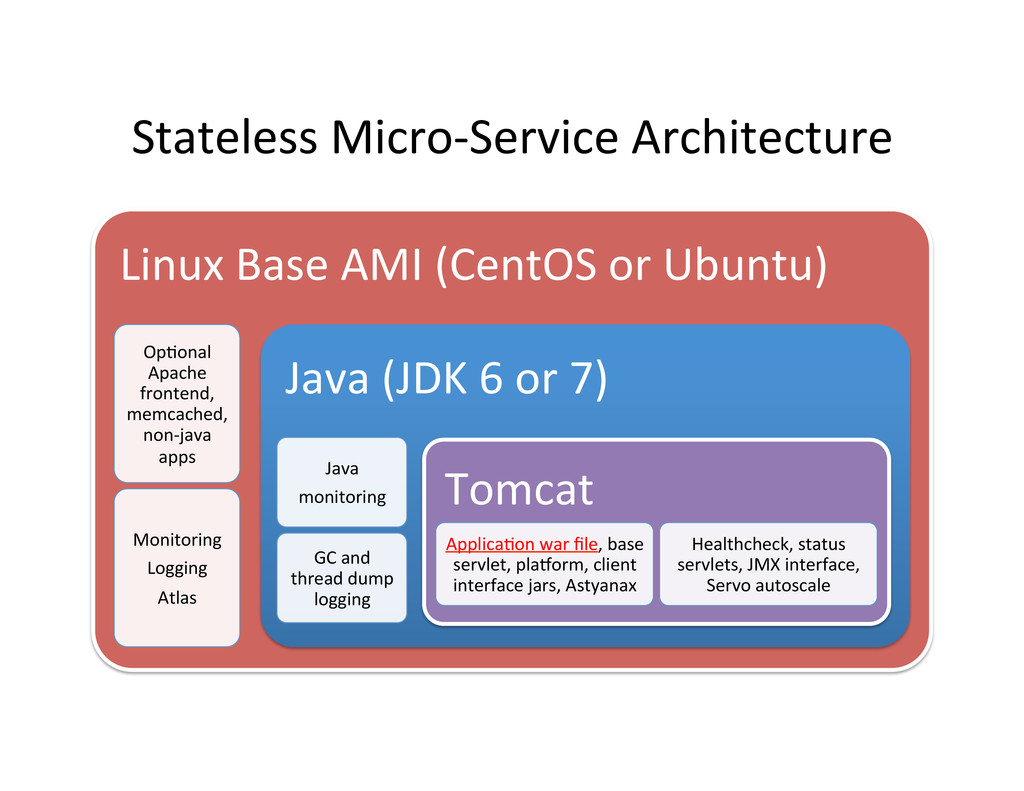
Stateless Micro-‐Service Architecture Linux Base AMI (CentOS or Ubuntu)
Op,onal Apache frontend, memcached, non-‐java apps Monitoring Logging Atlas Java (JDK 6 or 7) Java monitoring GC and thread dump logging Tomcat Applica,on war file, base servlet, plaCorm, client interface jars, Astyanax Healthcheck, status servlets, JMX interface, Servo autoscale -
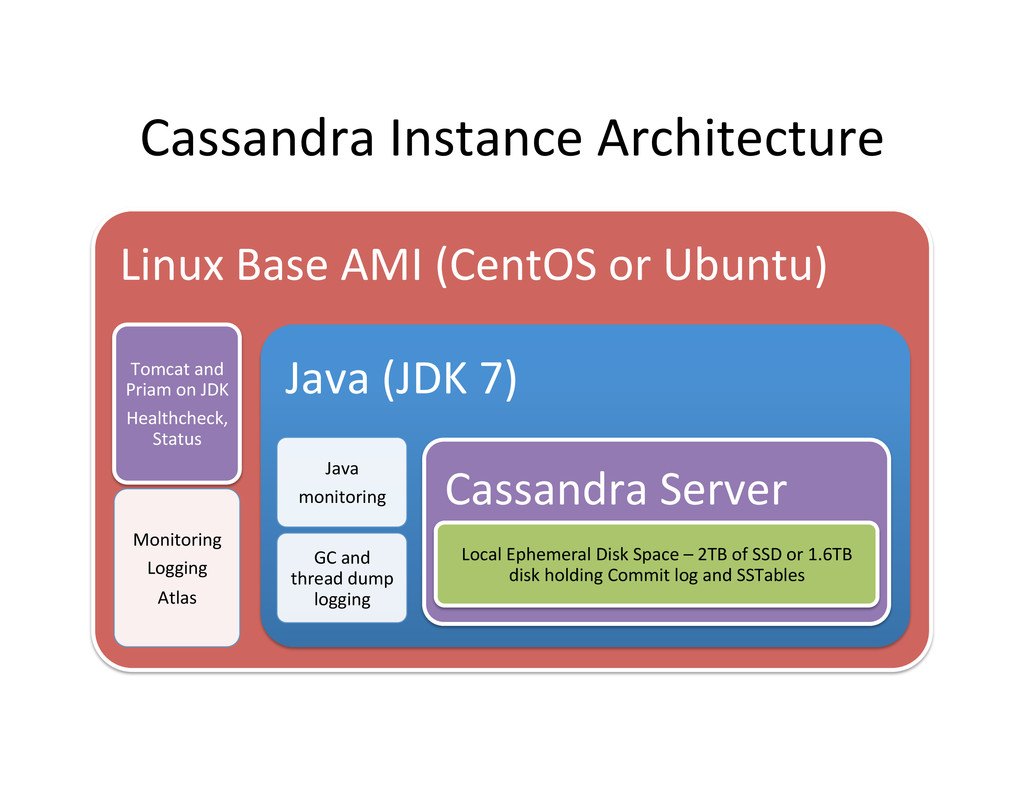
Cassandra Instance Architecture Linux Base AMI (CentOS or Ubuntu)
Tomcat and Priam on JDK Healthcheck, Status Monitoring Logging Atlas Java (JDK 7) Java monitoring GC and thread dump logging Cassandra Server Local Ephemeral Disk Space – 2TB of SSD or 1.6TB disk holding Commit log and SSTables -
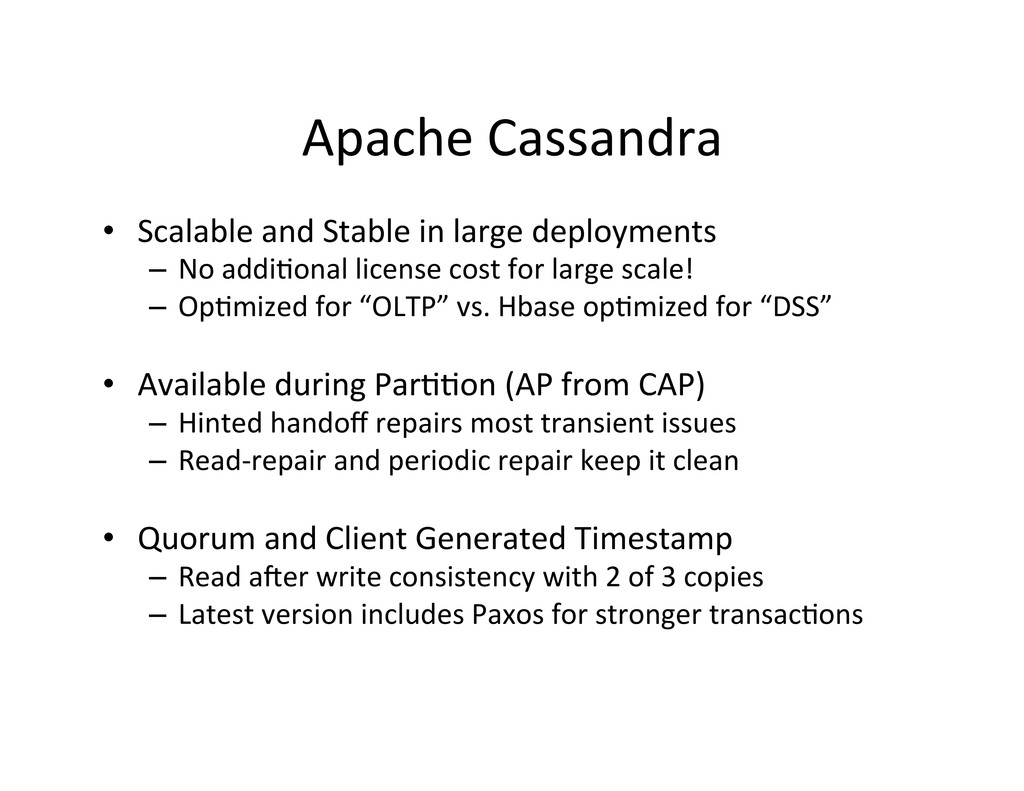
Apache Cassandra • Scalable and Stable in large deployments
– No addi,onal license cost for large scale! – Op,mized for “OLTP” vs. Hbase op,mized for “DSS” • Available during Par,,on (AP from CAP) – Hinted handoff repairs most transient issues – Read-‐repair and periodic repair keep it clean • Quorum and Client Generated Timestamp – Read aNer write consistency with 2 of 3 copies – Latest version includes Paxos for stronger transac,ons -
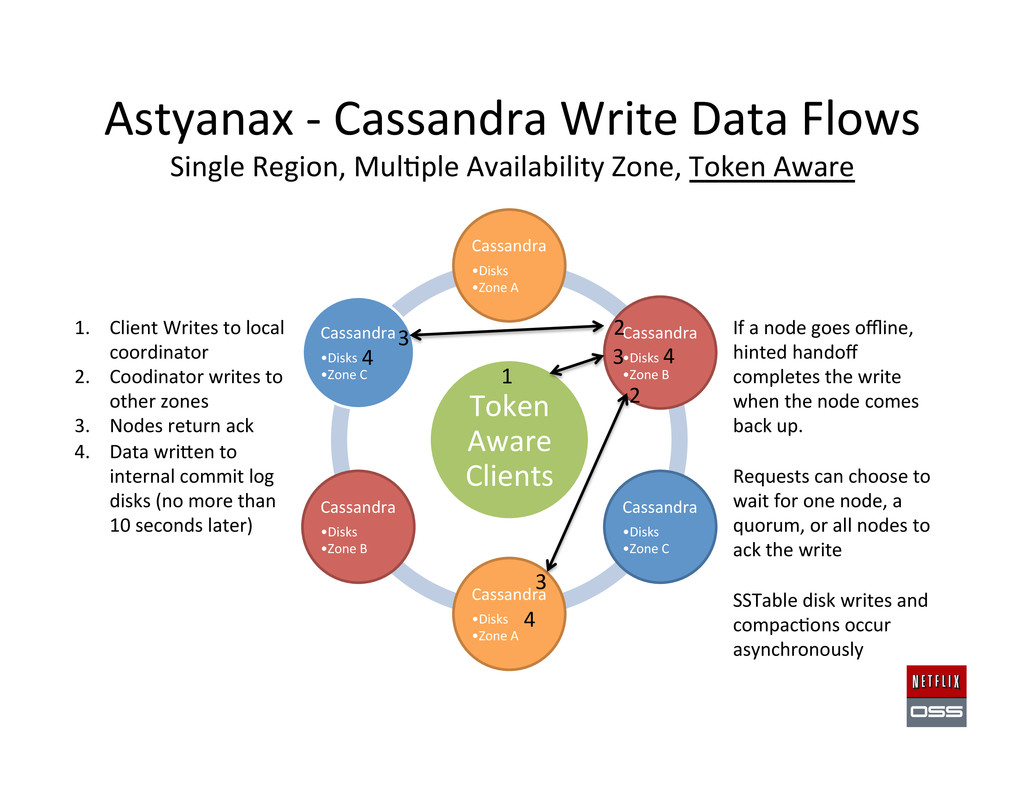
Astyanax -‐ Cassandra Write Data Flows Single Region, Mul,ple
Availability Zone, Token Aware Token Aware Clients Cassandra • Disks • Zone A Cassandra • Disks • Zone B Cassandra • Disks • Zone C Cassandra • Disks • Zone A Cassandra • Disks • Zone B Cassandra • Disks • Zone C 1. Client Writes to local coordinator 2. Coodinator writes to other zones 3. Nodes return ack 4. Data wri#en to internal commit log disks (no more than 10 seconds later) If a node goes offline, hinted handoff completes the write when the node comes back up. Requests can choose to wait for one node, a quorum, or all nodes to ack the write SSTable disk writes and compac,ons occur asynchronously 1 4 4 4 2 3 3 3 2 -
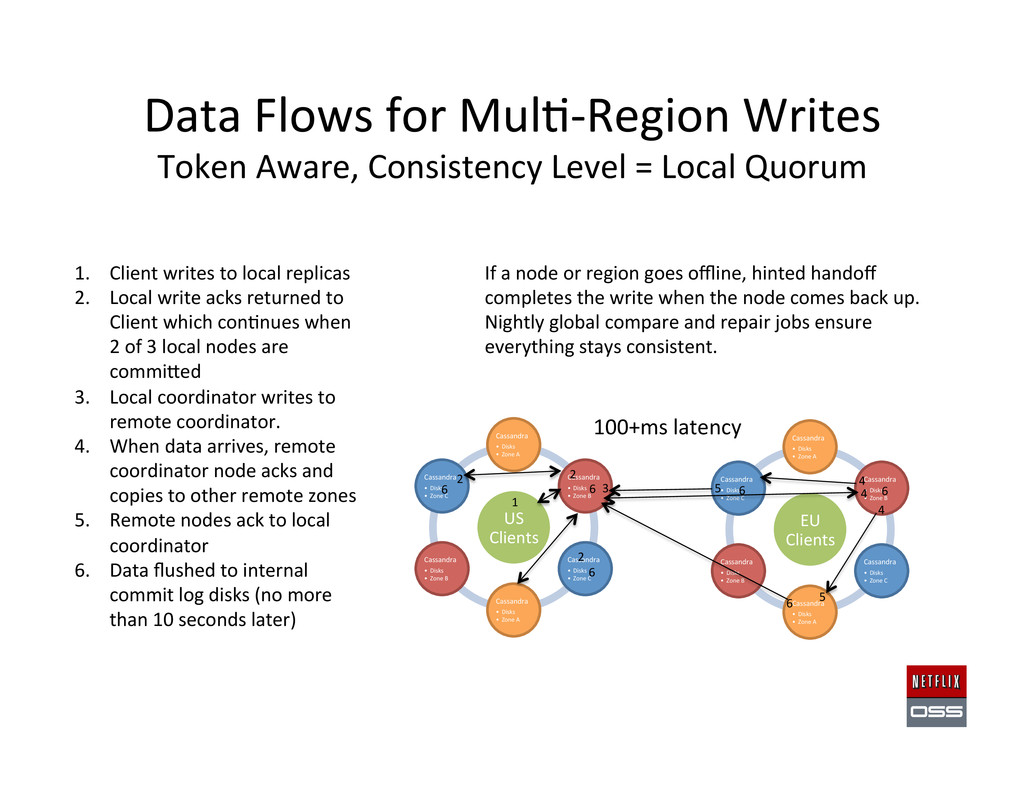
Data Flows for Mul,-‐Region Writes Token Aware, Consistency Level
= Local Quorum US Clients Cassandra • Disks • Zone A Cassandra • Disks • Zone B Cassandra • Disks • Zone C Cassandra • Disks • Zone A Cassandra • Disks • Zone B Cassandra • Disks • Zone C 1. Client writes to local replicas 2. Local write acks returned to Client which con,nues when 2 of 3 local nodes are commi#ed 3. Local coordinator writes to remote coordinator. 4. When data arrives, remote coordinator node acks and copies to other remote zones 5. Remote nodes ack to local coordinator 6. Data flushed to internal commit log disks (no more than 10 seconds later) If a node or region goes offline, hinted handoff completes the write when the node comes back up. Nightly global compare and repair jobs ensure everything stays consistent. EU Clients Cassandra • Disks • Zone A Cassandra • Disks • Zone B Cassandra • Disks • Zone C Cassandra • Disks • Zone A Cassandra • Disks • Zone B Cassandra • Disks • Zone C 6 5 5 6 6 4 4 4 1 6 6 6 2 2 2 3 100+ms latency -
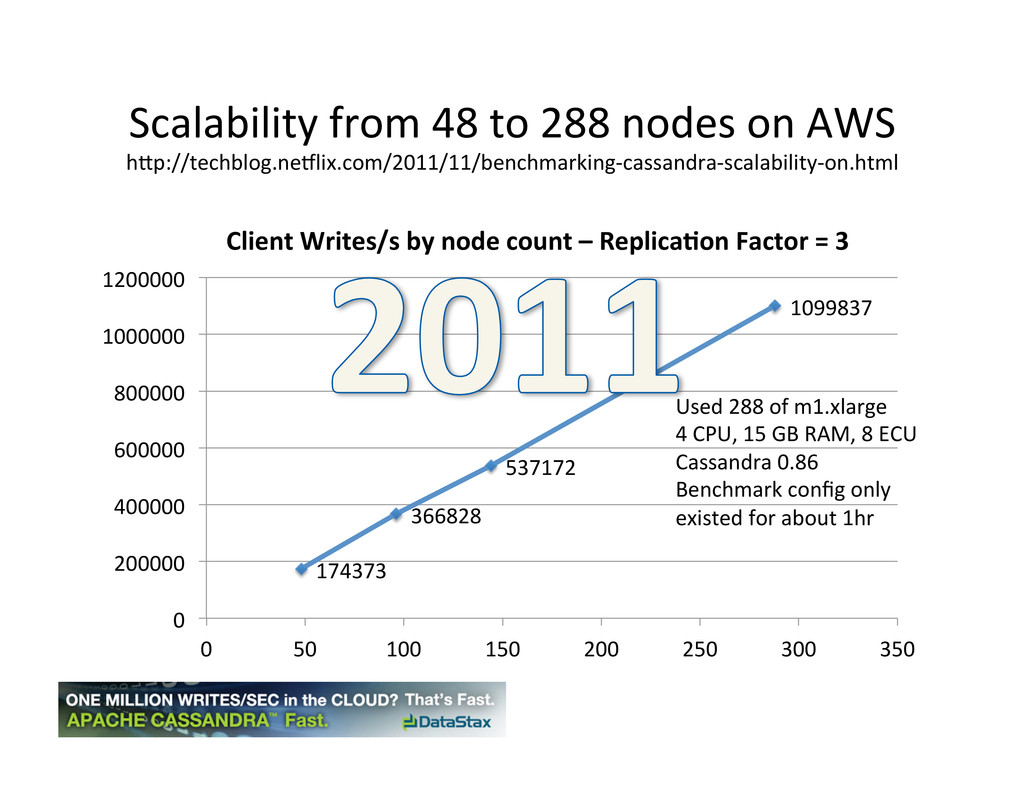
Scalability from 48 to 288 nodes on AWS h#p://techblog.neClix.com/2011/11/benchmarking-‐cassandra-‐scalability-‐on.html
174373 366828 537172 1099837 0 200000 400000 600000 800000 1000000 1200000 0 50 100 150 200 250 300 350 Client Writes/s by node count – Replica9on Factor = 3 Used 288 of m1.xlarge 4 CPU, 15 GB RAM, 8 ECU Cassandra 0.86 Benchmark config only existed for about 1hr -
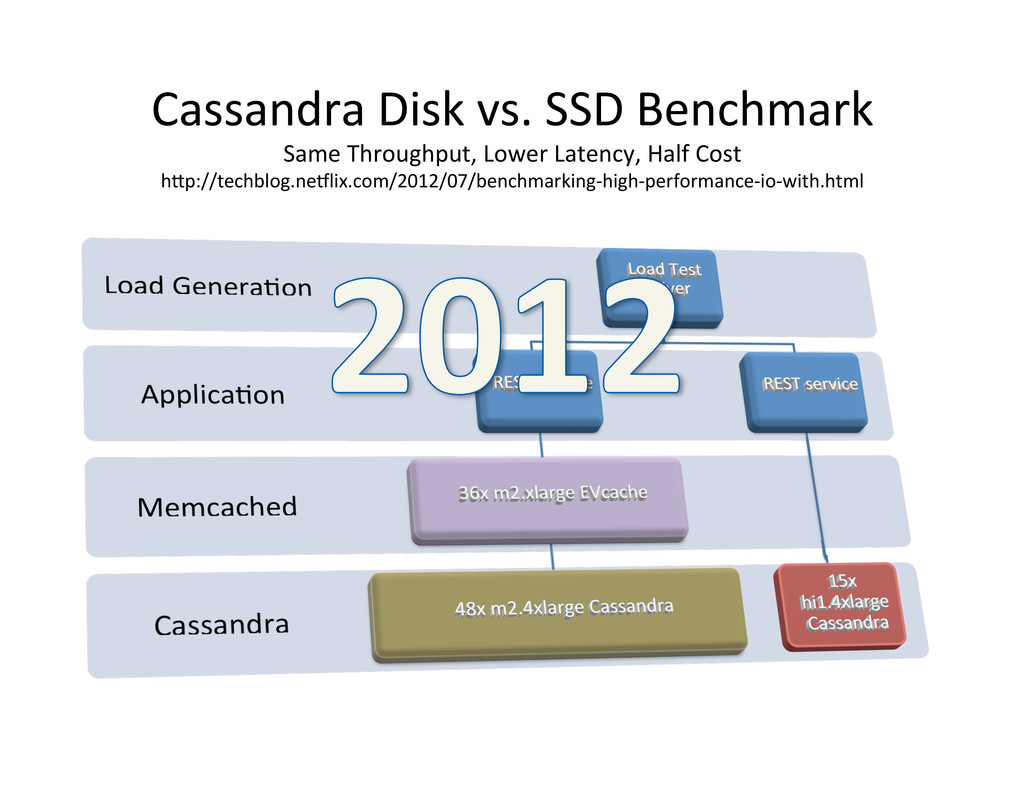
Cassandra Disk vs. SSD Benchmark Same Throughput, Lower Latency,
Half Cost h#p://techblog.neClix.com/2012/07/benchmarking-‐high-‐performance-‐io-‐with.html -
2013 -‐ Cross Region Use Cases • Geographic Isola,on
– US to Europe replica,on of subscriber data – Read intensive, low update rate – Produc,on use since late 2011 • Redundancy for regional failover – US East to US West replica,on of everything – Includes write intensive data, high update rate – Tes,ng now -
Benchmarking Global Cassandra Write intensive test of cross region
replica,on capacity 16 x hi1.4xlarge SSD nodes per zone = 96 total 192 TB of SSD in six loca,ons up and running Cassandra in 20 minutes Cassandra Replicas Zone A Cassandra Replicas Zone B Cassandra Replicas Zone C US-‐West-‐2 Region -‐ Oregon Cassandra Replicas Zone A Cassandra Replicas Zone B Cassandra Replicas Zone C US-‐East-‐1 Region -‐ Virginia Test Load Test Load Valida,on Load Inter-‐Zone Traffic 1 Million writes CL.ONE (wait for one replica to ack) 1 Million reads ANer 500ms CL.ONE with no Data loss Inter-‐Region Traffic Up to 9Gbits/s, 83ms 18TB backups from S3 -
Copying 18TB from East to West Cassandra bootstrap 9.3
Gbit/s single threaded 48 nodes to 48 nodes Thanks to boundary.com for these network analysis plots -
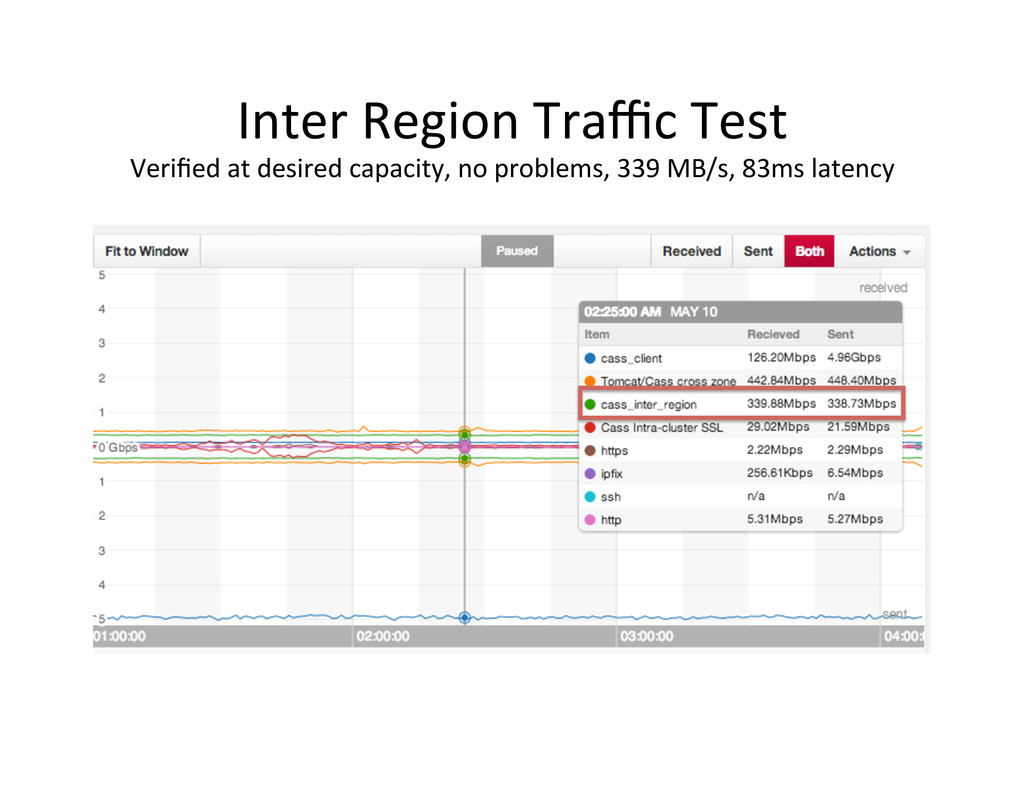
Inter Region Traffic Test Verified at desired capacity, no
problems, 339 MB/s, 83ms latency -
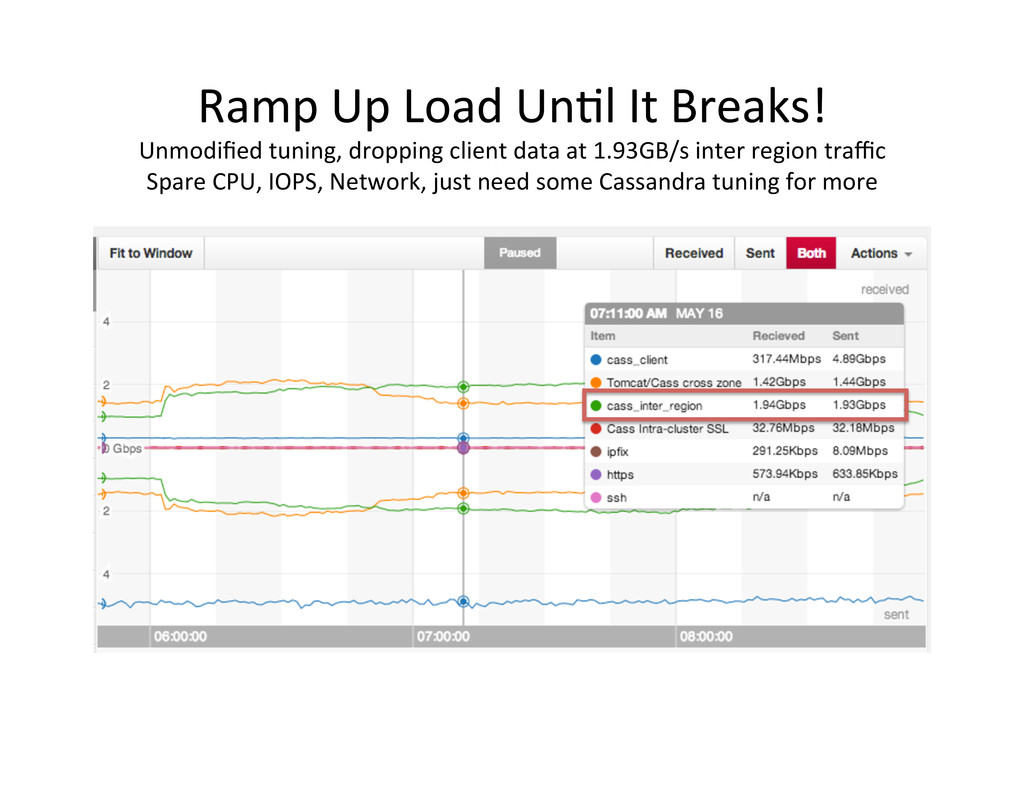
Ramp Up Load Un,l It Breaks! Unmodified tuning, dropping
client data at 1.93GB/s inter region traffic Spare CPU, IOPS, Network, just need some Cassandra tuning for more -
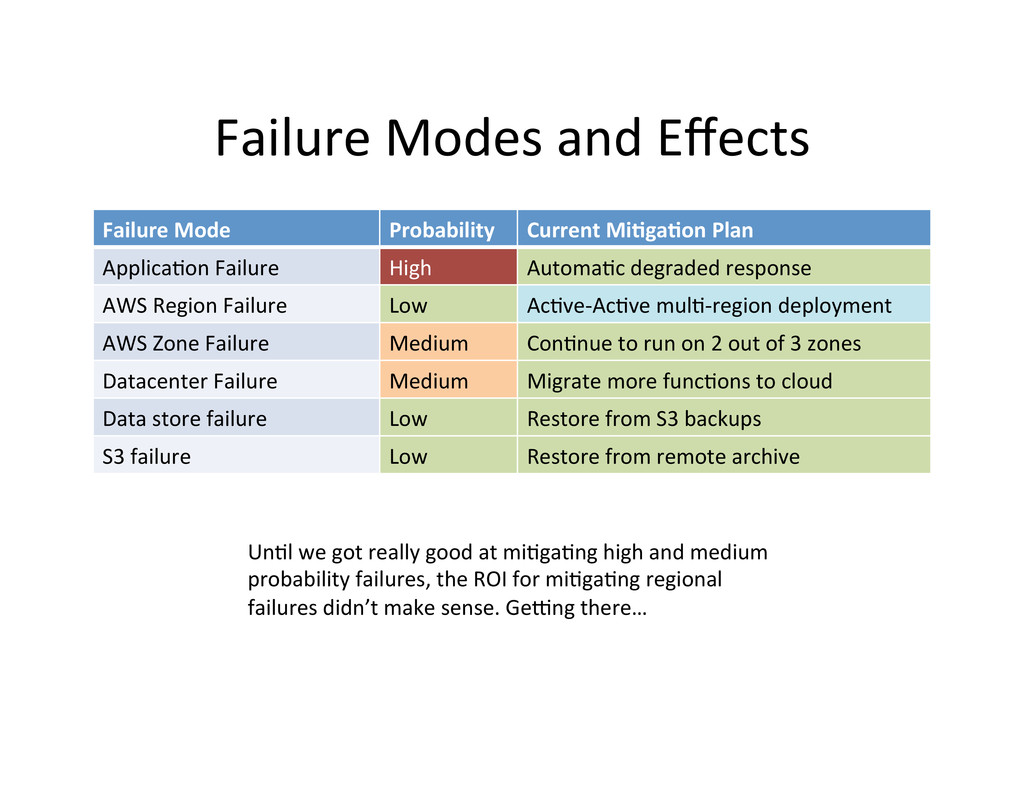
Failure Modes and Effects Failure Mode Probability
Current Mi9ga9on Plan Applica,on Failure High Automa,c degraded response AWS Region Failure Low Ac,ve-‐Ac,ve mul,-‐region deployment AWS Zone Failure Medium Con,nue to run on 2 out of 3 zones Datacenter Failure Medium Migrate more func,ons to cloud Data store failure Low Restore from S3 backups S3 failure Low Restore from remote archive Un,l we got really good at mi,ga,ng high and medium probability failures, the ROI for mi,ga,ng regional failures didn’t make sense. Gewng there… -
Cloud Security Fine grain security rather than perimeter
Leveraging AWS Scale to resist DDOS a#acks Automated a#ack surface monitoring and tes,ng h#p://www.slideshare.net/jason_chan/resilience-‐and-‐security-‐scale-‐lessons-‐learned -
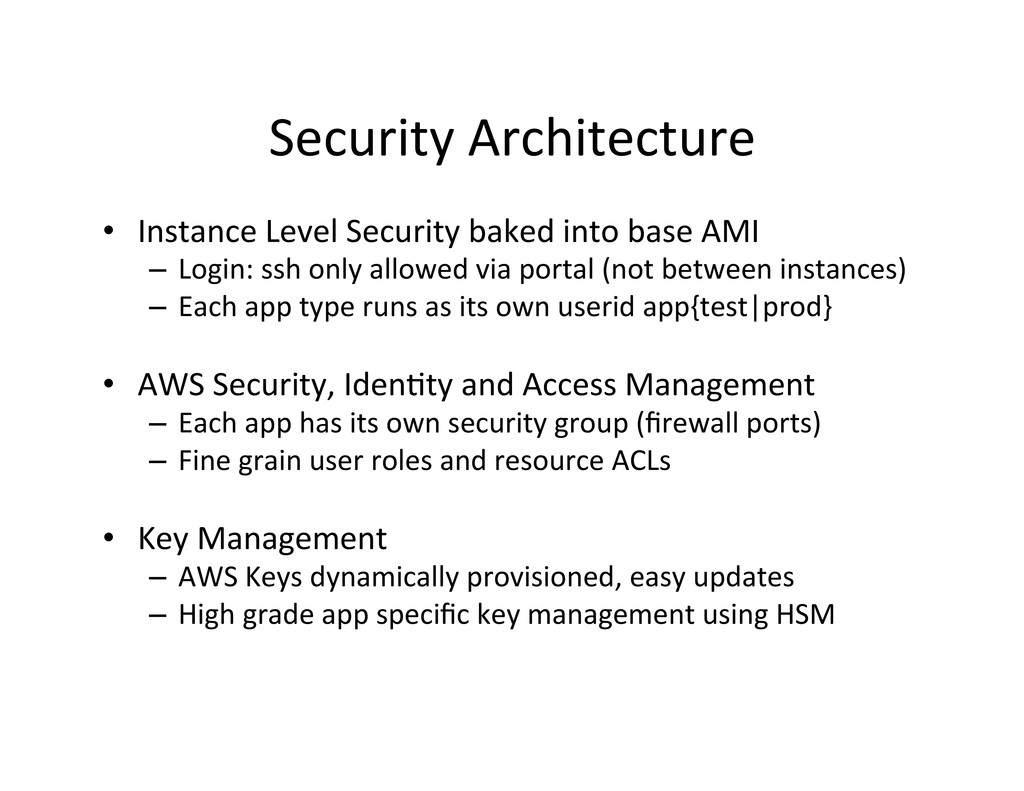
Security Architecture • Instance Level Security baked into base
AMI – Login: ssh only allowed via portal (not between instances) – Each app type runs as its own userid app{test|prod} • AWS Security, Iden,ty and Access Management – Each app has its own security group (firewall ports) – Fine grain user roles and resource ACLs • Key Management – AWS Keys dynamically provisioned, easy updates – High grade app specific key management using HSM -
Cost-‐Aware Cloud Architectures Based on slides jointly developed
with Jinesh Varia @jinman Technology Evangelist -
« Want to increase innova,on? Lower the cost of
failure » Joi Ito -
NeClix Examples • European Launch using AWS Ireland
– No employees in Ireland, no provisioning delay, everything worked – No need to do detailed capacity planning – Over-‐provisioned on day 1, shrunk to fit aNer a few days – Capacity grows as needed for addi,onal country launches • Brazilian Proxy Experiment – No employees in Brazil, no “mee,ngs with IT” – Deployed instances into two zones in AWS Brazil – Experimented with network proxy op,miza,on – Decided that gain wasn’t enough, shut everything down -
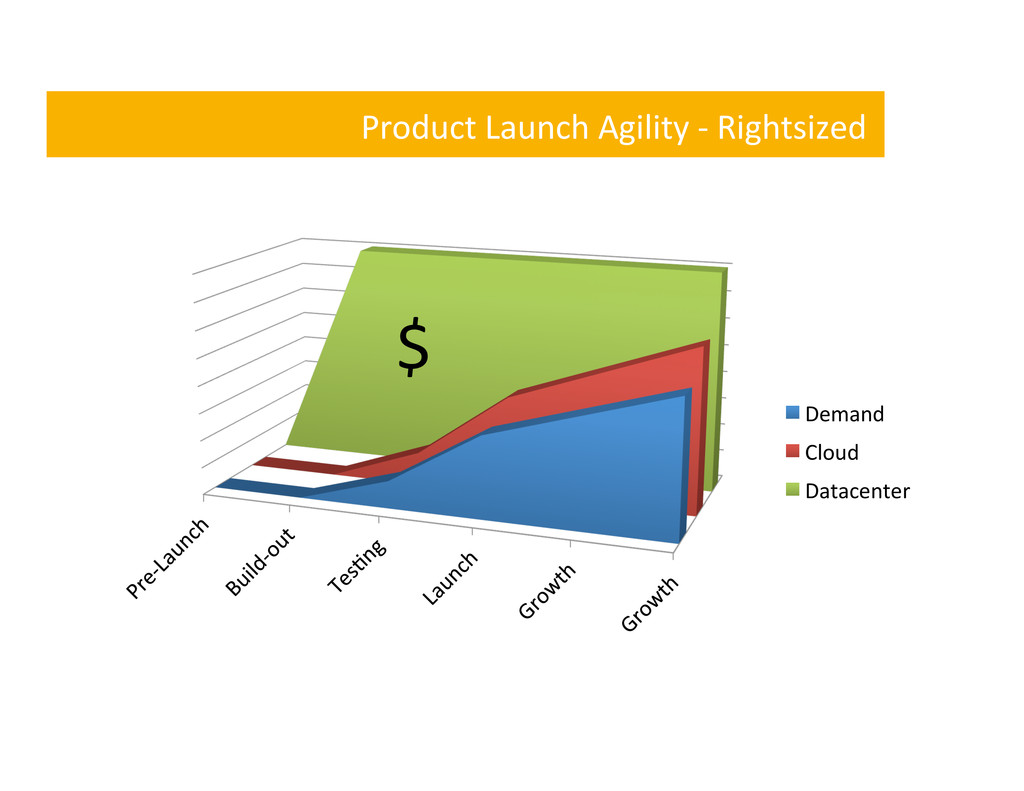
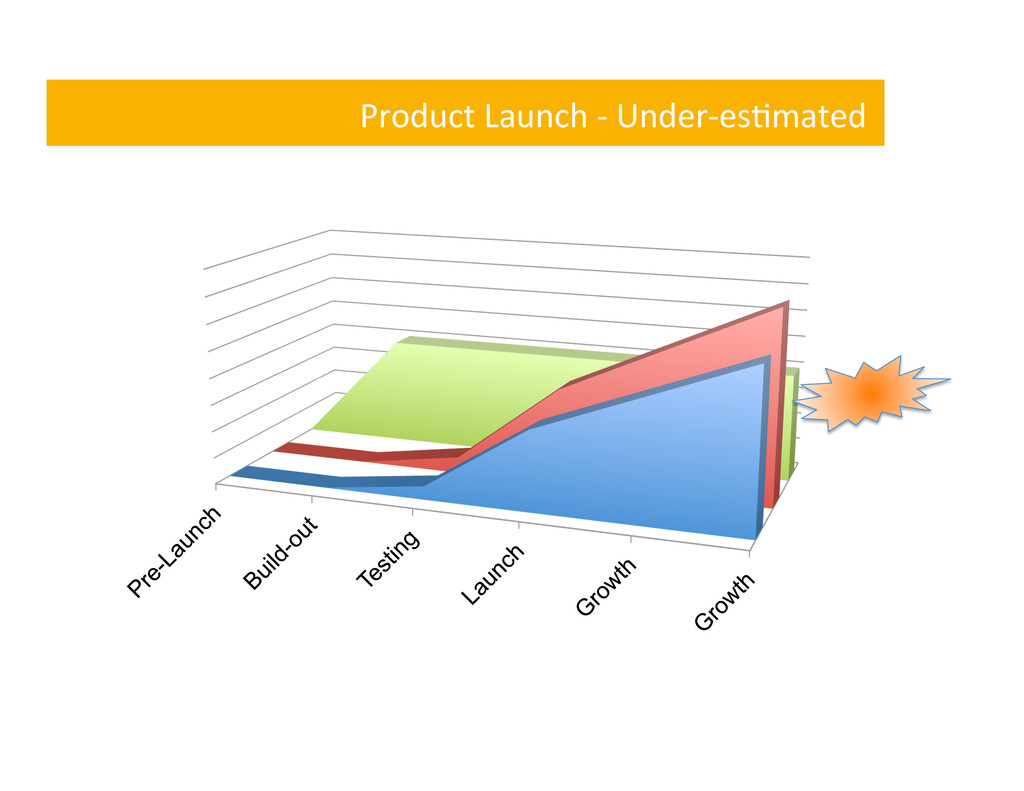
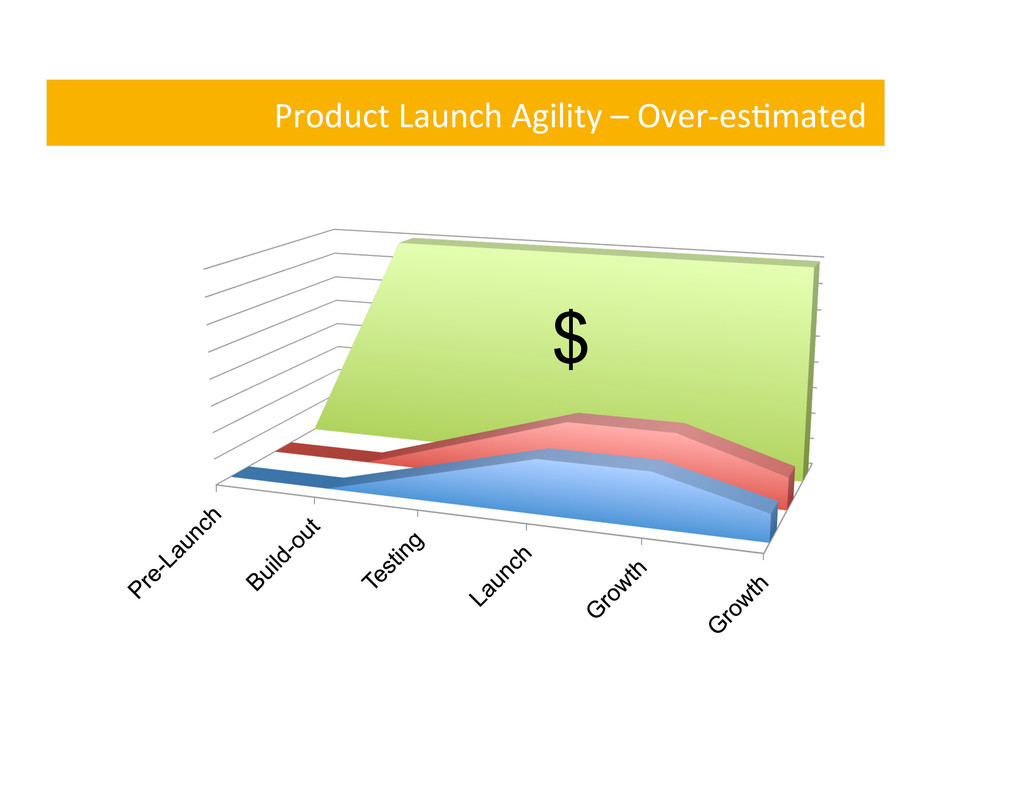
Product Launch Agility -‐ Rightsized Demand Cloud
Datacenter $ -
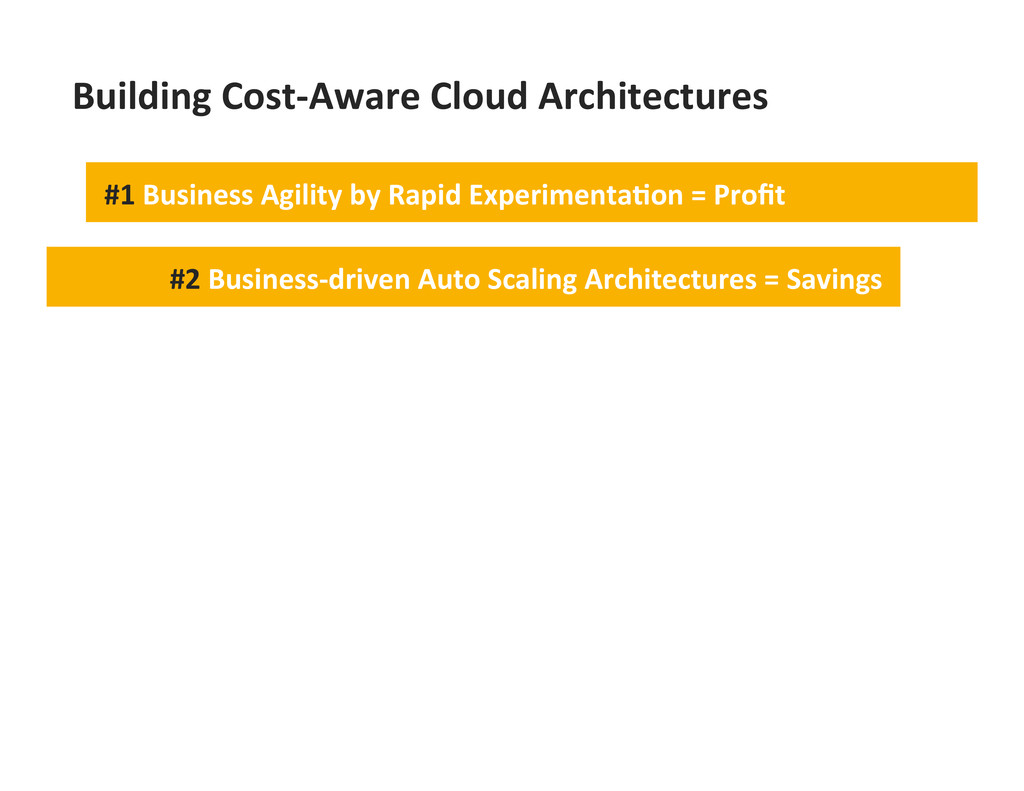
#1 Business Agility by Rapid Experimenta9on = Profit Key
Takeaways on Cost-‐Aware Architectures…. -
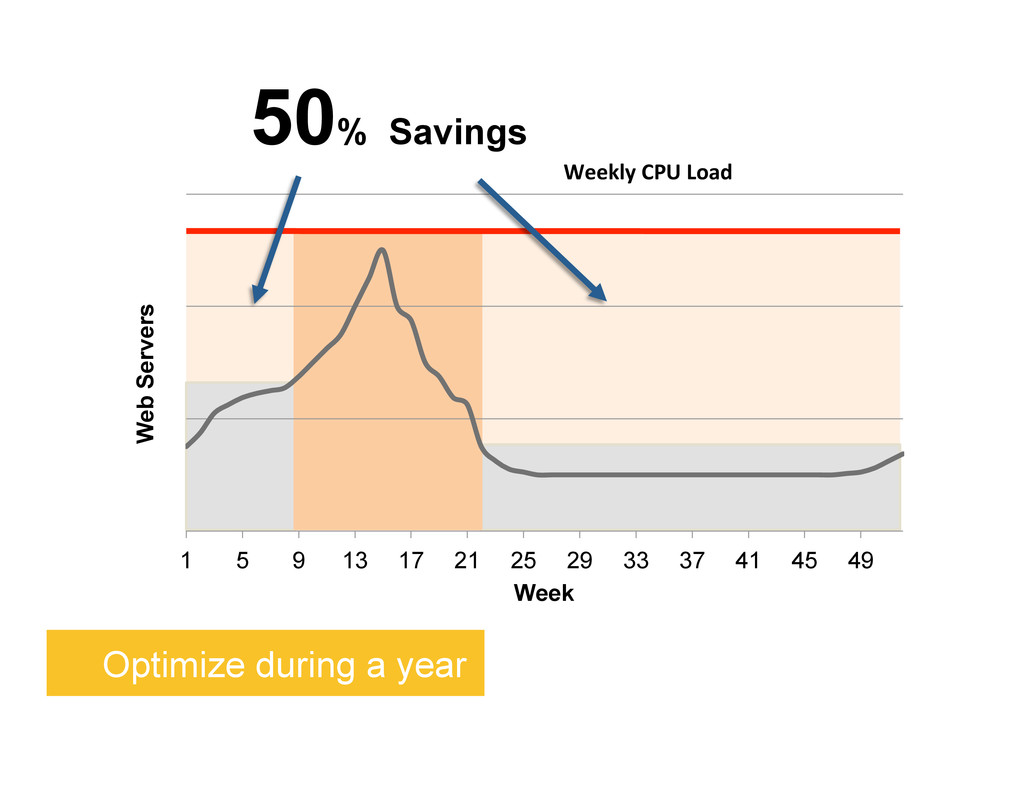
When you turn off your cloud resources, you actually
stop paying for them -
1 5 9 13 17 21 25 29 33 37
41 45 49 Web Servers Week Optimize during a year 50% Savings Weekly CPU Load -
50%+ Cost Saving Scale up/down by 70%+
Move to Load-‐Based Scaling -
Other simple op,miza,on ,ps • Don’t forget to…
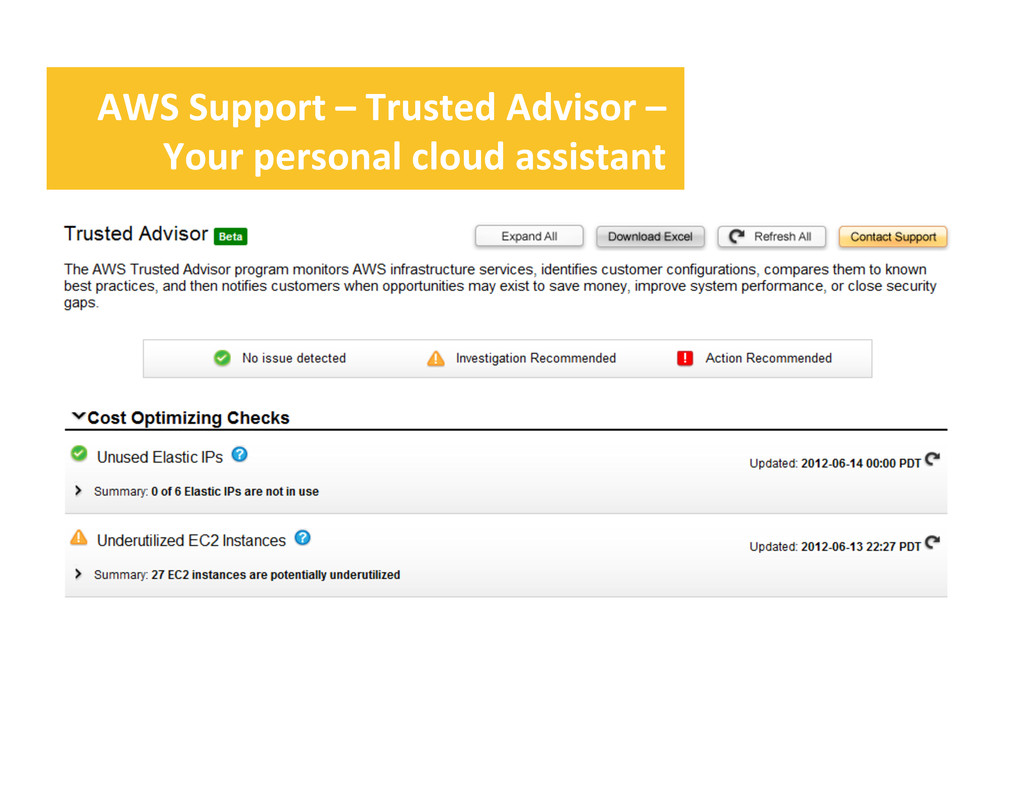
– Disassociate unused EIPs – Delete unassociated Amazon EBS volumes – Delete older Amazon EBS snapshots – Leverage Amazon S3 Object Expira,on Janitor Monkey cleans up unused resources -
#1 Business Agility by Rapid Experimenta9on = Profit #2
Business-‐driven Auto Scaling Architectures = Savings Building Cost-‐Aware Cloud Architectures -
When Comparing TCO… Make sure that you are
including all the cost factors into considera,on Place Power Pipes People Pa3erns -
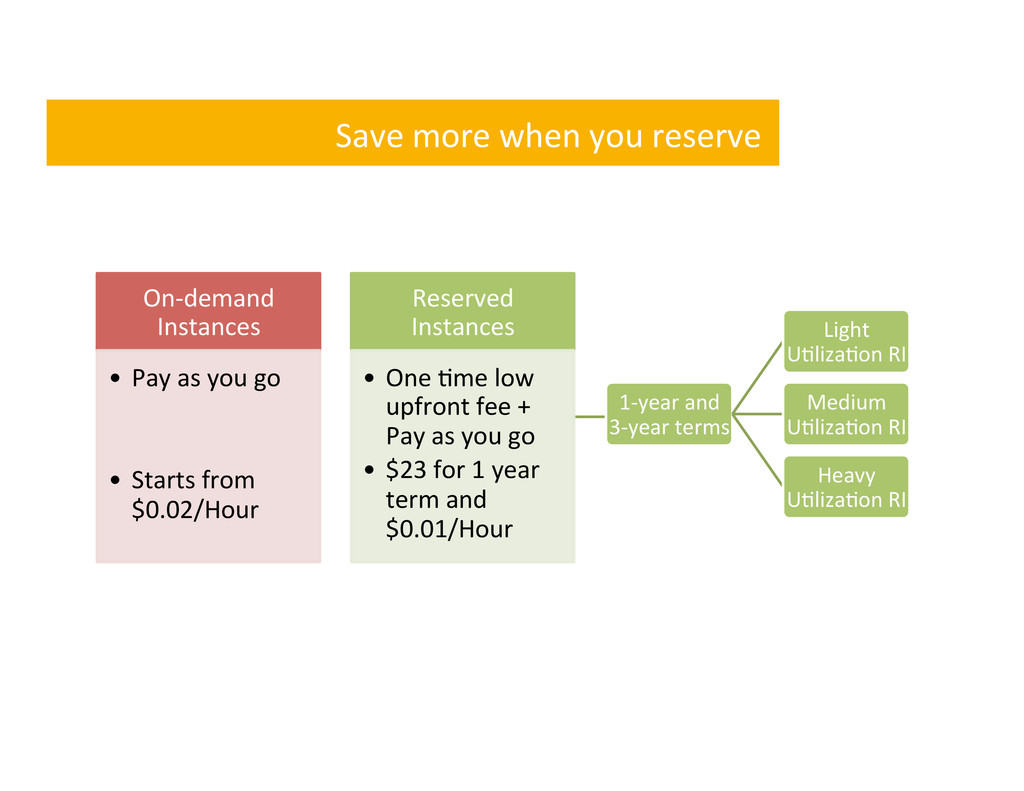
Save more when you reserve On-‐demand Instances
• Pay as you go • Starts from $0.02/Hour Reserved Instances • One ,me low upfront fee + Pay as you go • $23 for 1 year term and $0.01/Hour 1-‐year and 3-‐year terms Light U,liza,on RI Medium U,liza,on RI Heavy U,liza,on RI -
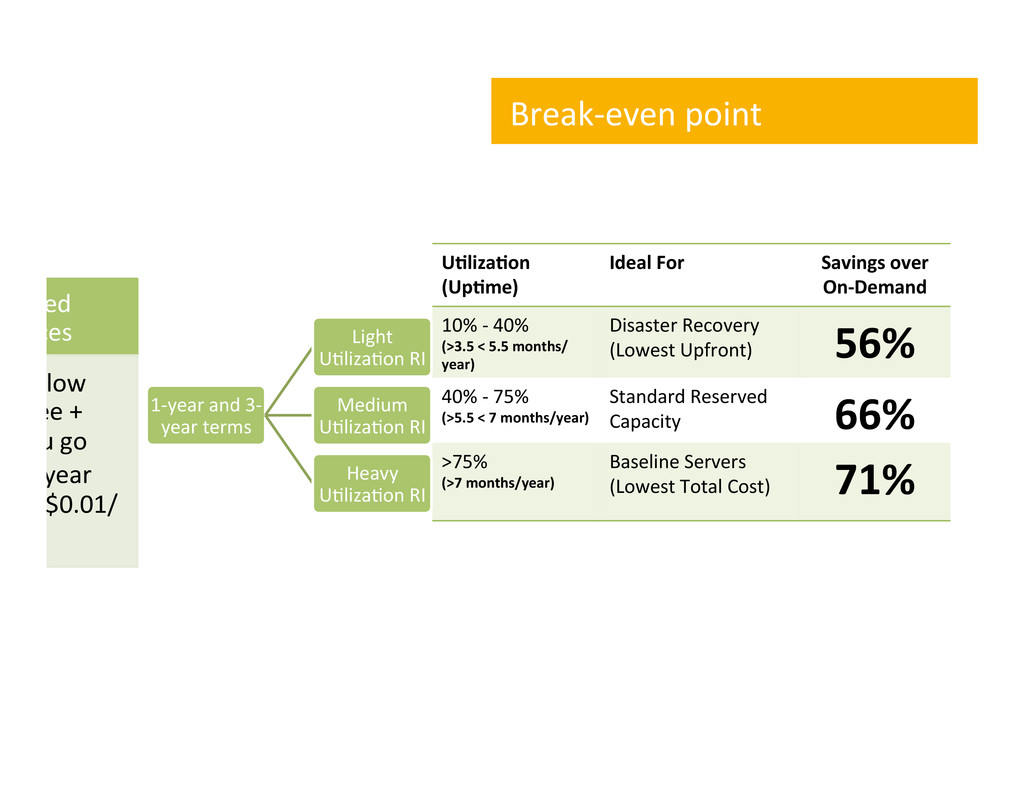
U9liza9on (Up9me) Ideal For Savings over
On-‐Demand 10% -‐ 40% (>3.5 < 5.5 months/ year) Disaster Recovery (Lowest Upfront) 56% 40% -‐ 75% (>5.5 < 7 months/year) Standard Reserved Capacity 66% >75% (>7 months/year) Baseline Servers (Lowest Total Cost) 71% Break-‐even point served stances ,me low nt fee + s you go or 1 year and $0.01/ 1-‐year and 3-‐ year terms Light U,liza,on RI Medium U,liza,on RI Heavy U,liza,on RI -
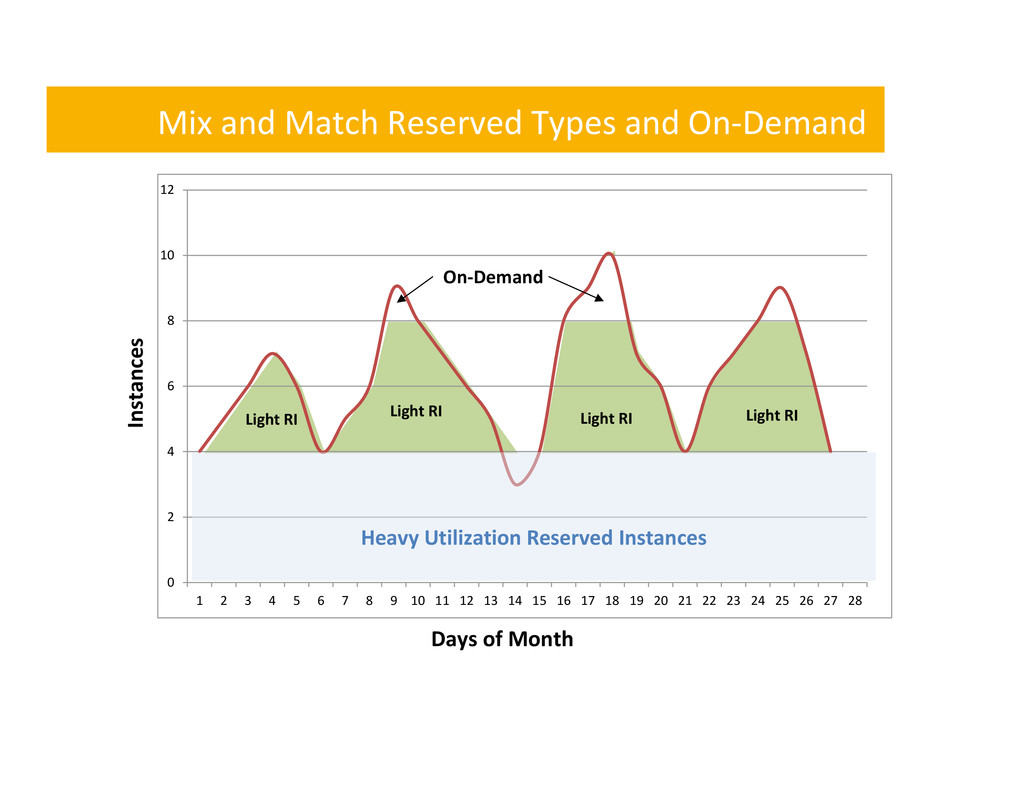
Mix and Match Reserved Types and On-‐Demand Instances
Days of Month 0 2 4 6 8 10 12 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 Heavy Utilization Reserved Instances Light RI Light RI Light RI Light RI On-‐Demand -
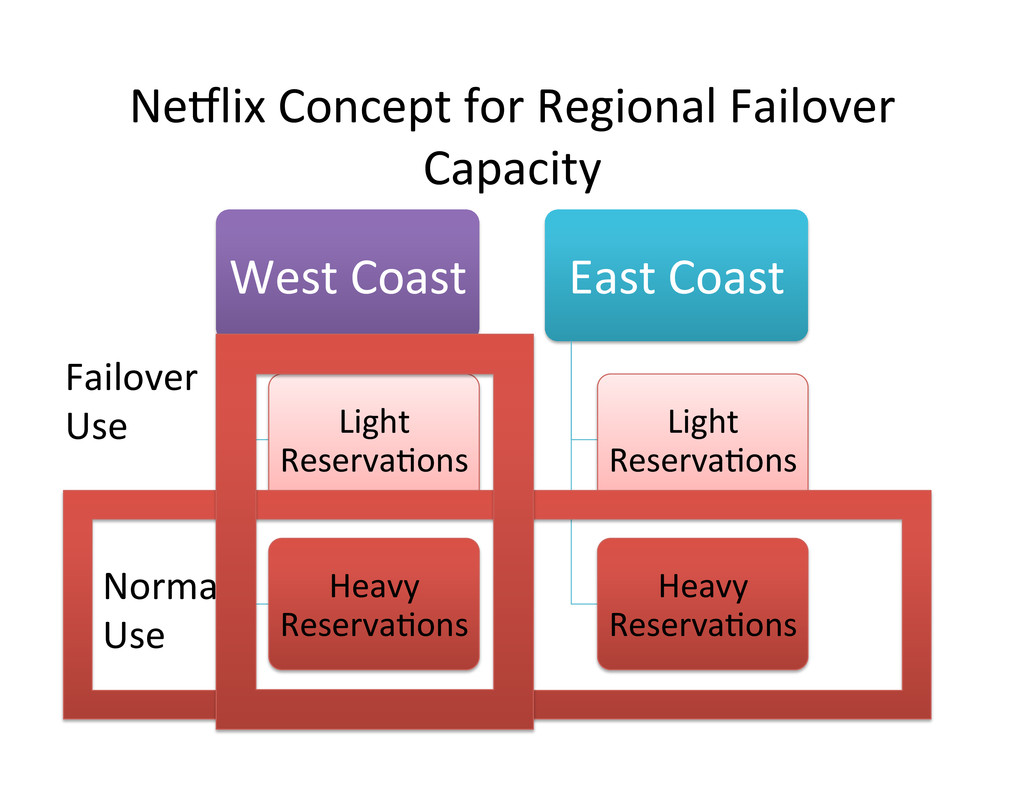
NeClix Concept for Regional Failover Capacity West Coast
Light Reserva,ons Heavy Reserva,ons East Coast Light Reserva,ons Heavy Reserva,ons Normal Use Failover Use -
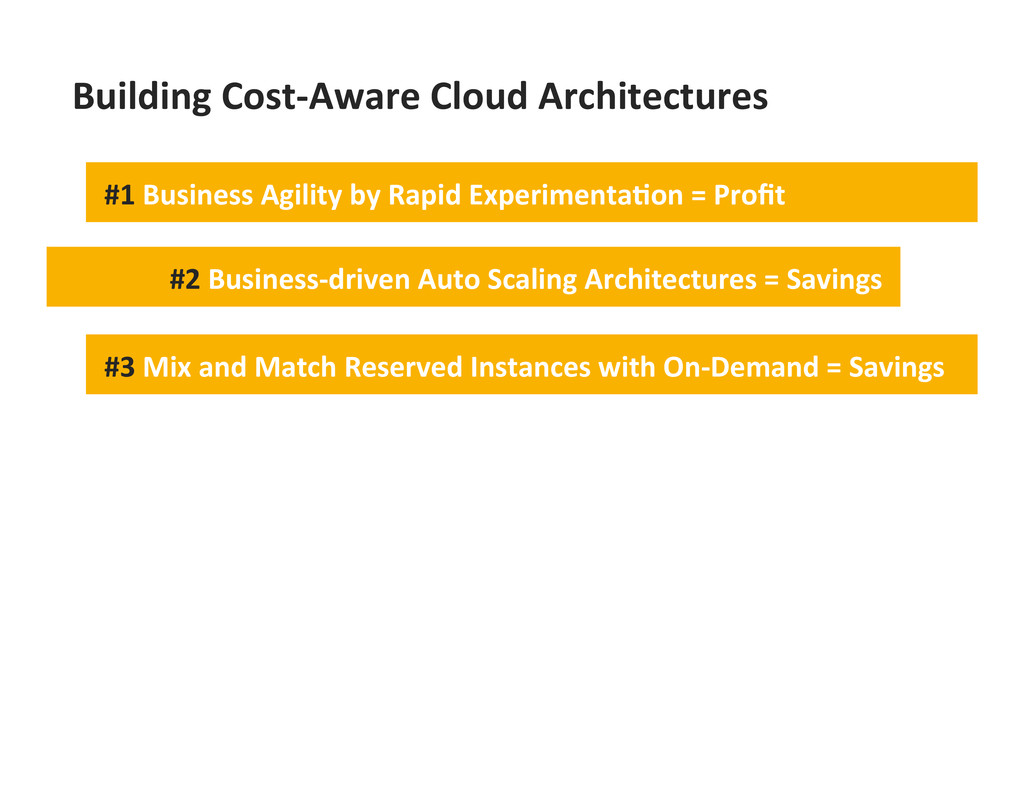
#1 Business Agility by Rapid Experimenta9on = Profit #2
Business-‐driven Auto Scaling Architectures = Savings #3 Mix and Match Reserved Instances with On-‐Demand = Savings Building Cost-‐Aware Cloud Architectures -
Variety of Applica,ons and Environments Produc9on Fleet Dev
Fleet Test Fleet Staging/QA Perf Fleet DR Site Every Applica9on has…. Every Company has…. Business App Fleet Marke9ng Site Intranet Site BI App Mul9ple Products Analy9cs -
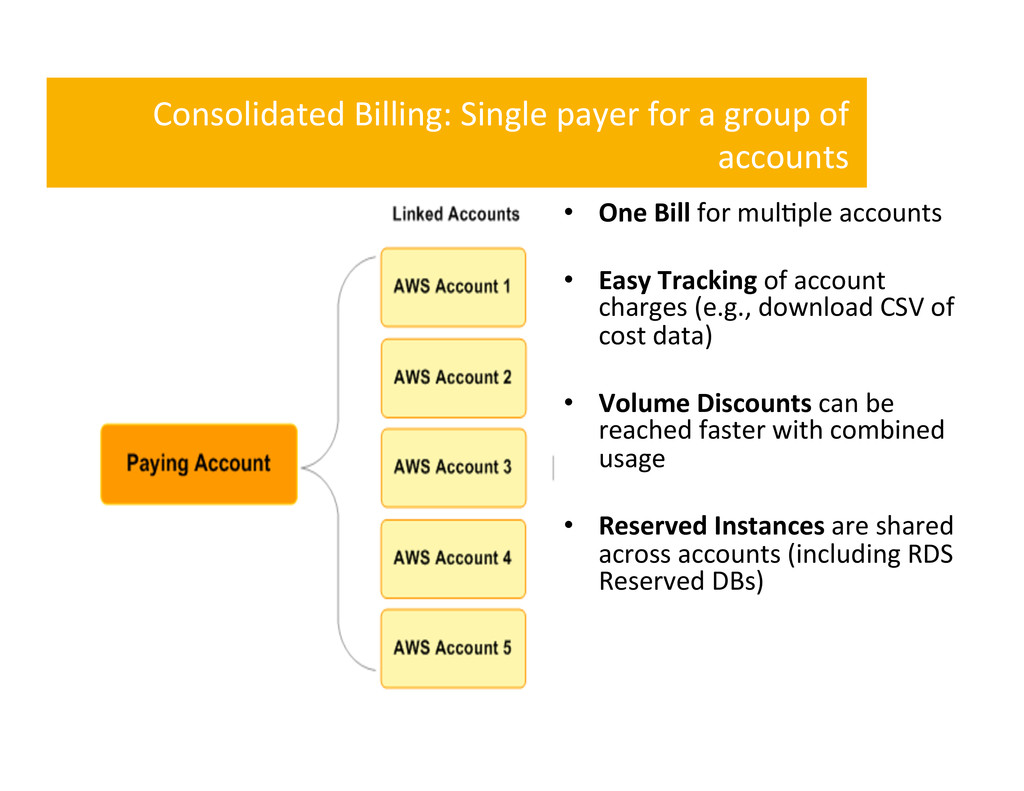
Consolidated Billing: Single payer for a group of accounts
• One Bill for mul,ple accounts • Easy Tracking of account charges (e.g., download CSV of cost data) • Volume Discounts can be reached faster with combined usage • Reserved Instances are shared across accounts (including RDS Reserved DBs) -
Over-‐Reserve the Produc,on Environment Produc,on Env. Account
100 Reserved QA/Staging Env. Account 0 Reserved Perf Tes,ng Env. Account 0 Reserved Development Env. Account 0 Reserved Storage Account 0 Reserved Total Capacity -
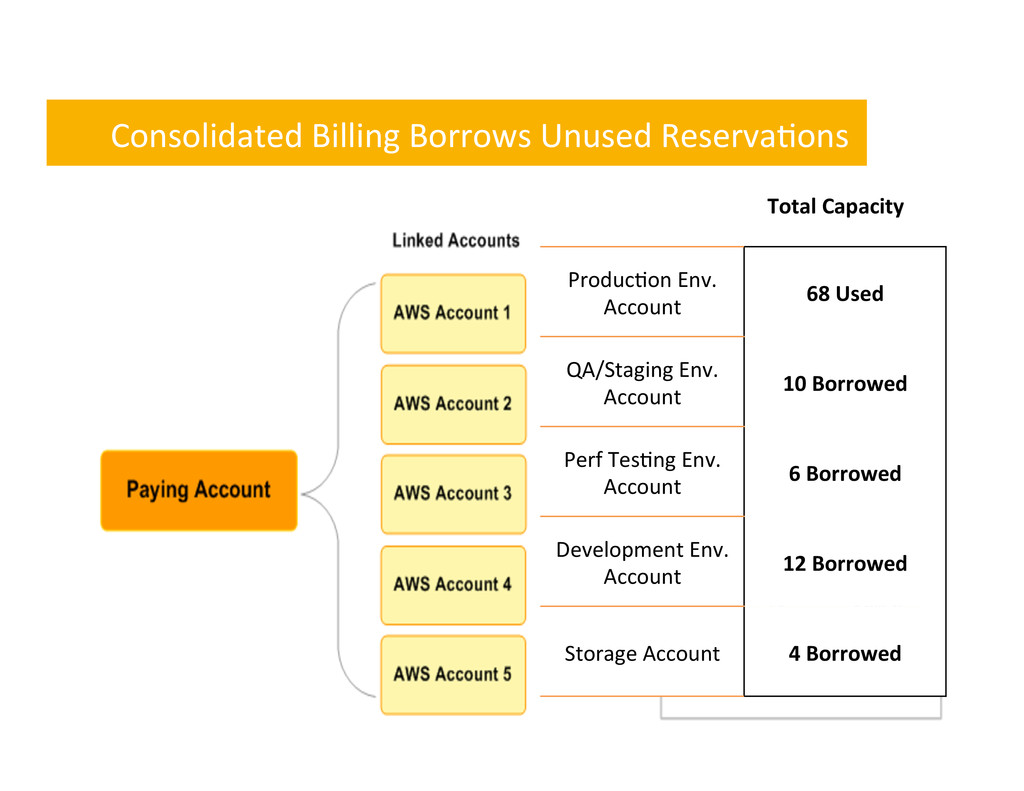
Consolidated Billing Borrows Unused Reserva,ons Produc,on Env. Account
68 Used QA/Staging Env. Account 10 Borrowed Perf Tes,ng Env. Account 6 Borrowed Development Env. Account 12 Borrowed Storage Account 4 Borrowed Total Capacity -
Consolidated Billing Advantages • Produc,on account is guaranteed to
get burst capacity – Reserva,on is higher than normal usage level – Requests for more capacity always work up to reserved limit – Higher availability for handling unexpected peak demands • No addi,onal cost – Other lower priority accounts soak up unused reserva,ons – Totals roll up in the monthly billing cycle -
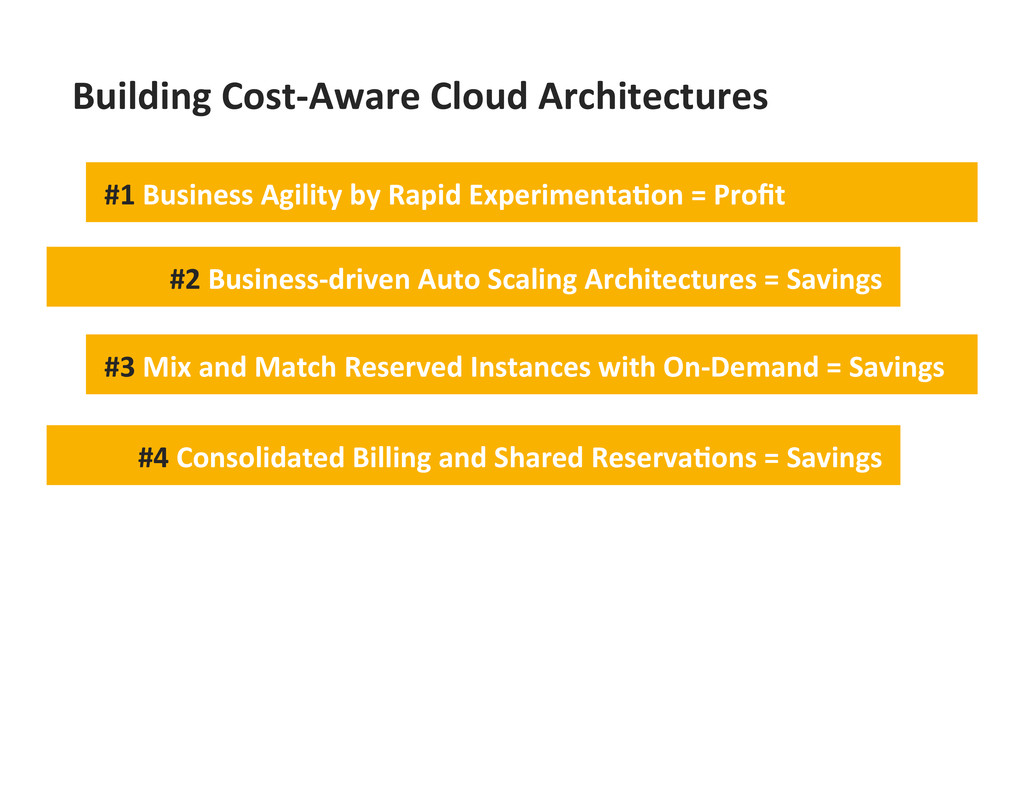
#1 Business Agility by Rapid Experimenta9on = Profit #2
Business-‐driven Auto Scaling Architectures = Savings #3 Mix and Match Reserved Instances with On-‐Demand = Savings #4 Consolidated Billing and Shared Reserva9ons = Savings Building Cost-‐Aware Cloud Architectures -
Con,nuous op,miza,on in your architecture results in
recurring savings as early as your next month’s bill -
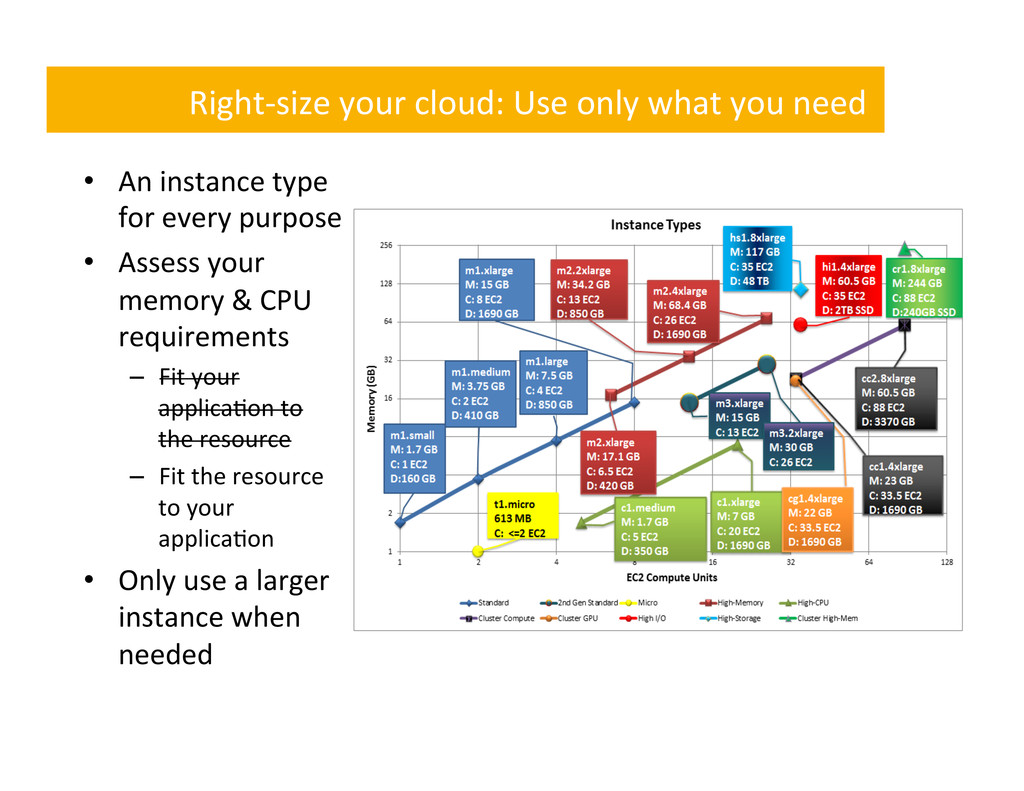
Right-‐size your cloud: Use only what you need •
An instance type for every purpose • Assess your memory & CPU requirements – Fit your applica,on to the resource – Fit the resource to your applica,on • Only use a larger instance when needed -
Reserved Instance Marketplace Buy a smaller term instance
Buy instance with different OS or type Buy a Reserved instance in different region Sell your unused Reserved Instance Sell unwanted or over-‐bought capacity Further reduce costs by op9mizing -
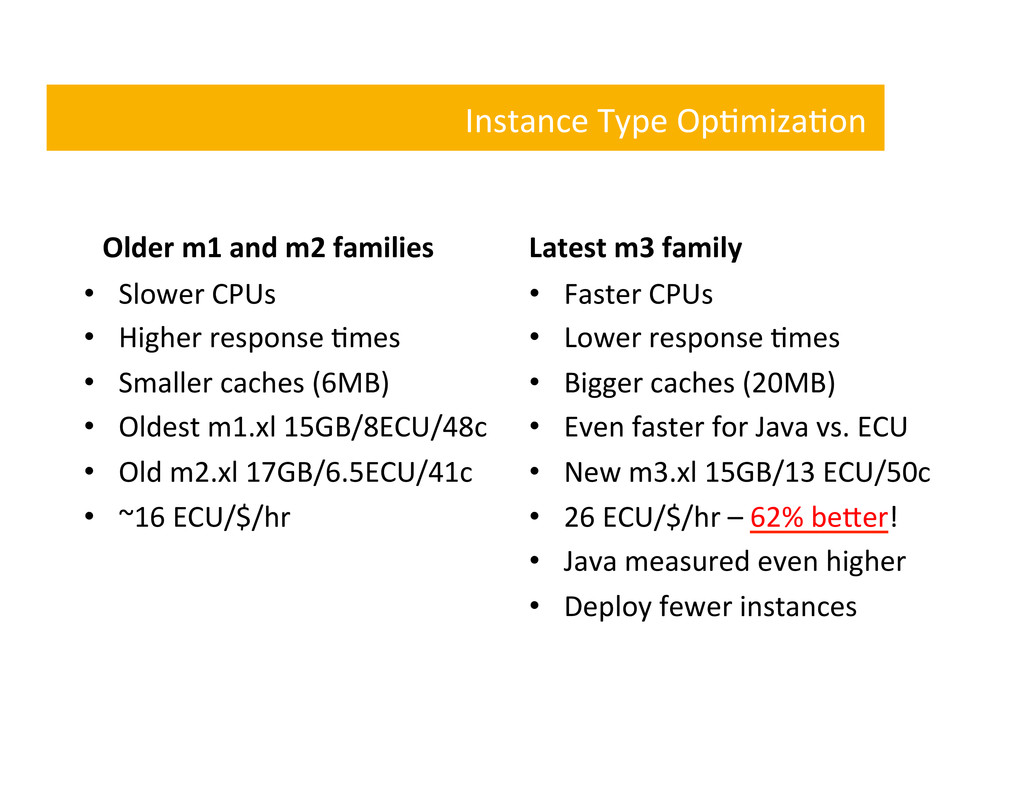
Instance Type Op,miza,on Older m1 and m2 families
• Slower CPUs • Higher response ,mes • Smaller caches (6MB) • Oldest m1.xl 15GB/8ECU/48c • Old m2.xl 17GB/6.5ECU/41c • ~16 ECU/$/hr Latest m3 family • Faster CPUs • Lower response ,mes • Bigger caches (20MB) • Even faster for Java vs. ECU • New m3.xl 15GB/13 ECU/50c • 26 ECU/$/hr – 62% be#er! • Java measured even higher • Deploy fewer instances -
#1 Business Agility by Rapid Experimenta9on = Profit #2
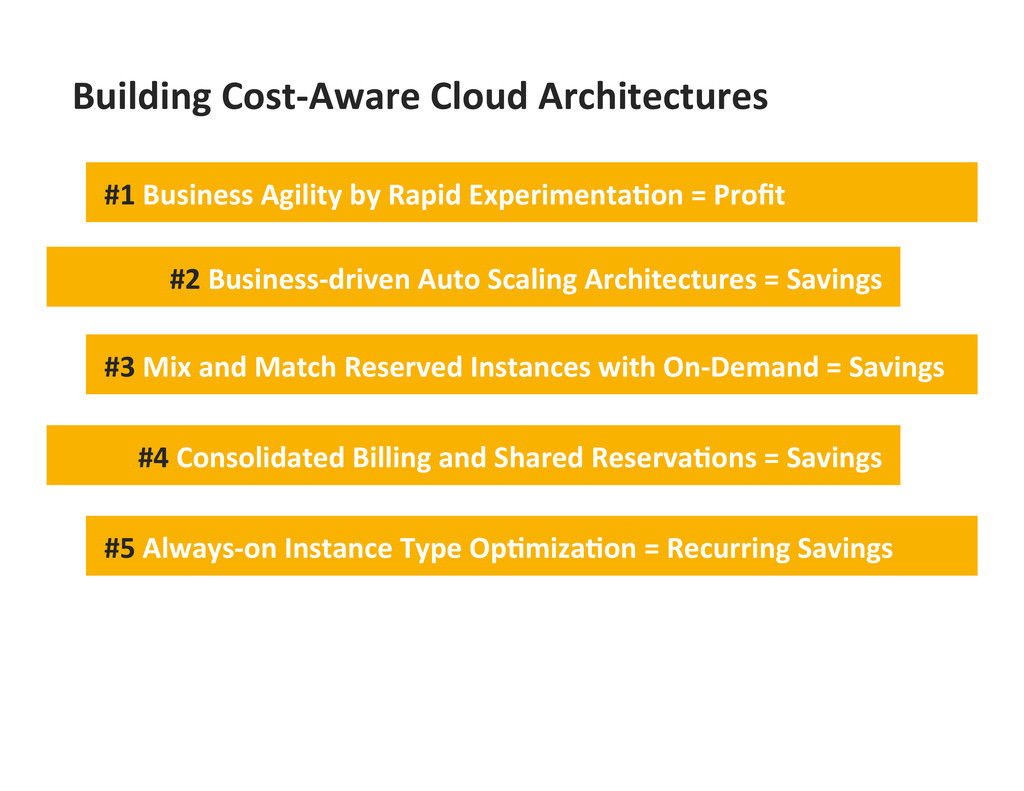
Business-‐driven Auto Scaling Architectures = Savings #3 Mix and Match Reserved Instances with On-‐Demand = Savings #4 Consolidated Billing and Shared Reserva9ons = Savings #5 Always-‐on Instance Type Op9miza9on = Recurring Savings Building Cost-‐Aware Cloud Architectures -
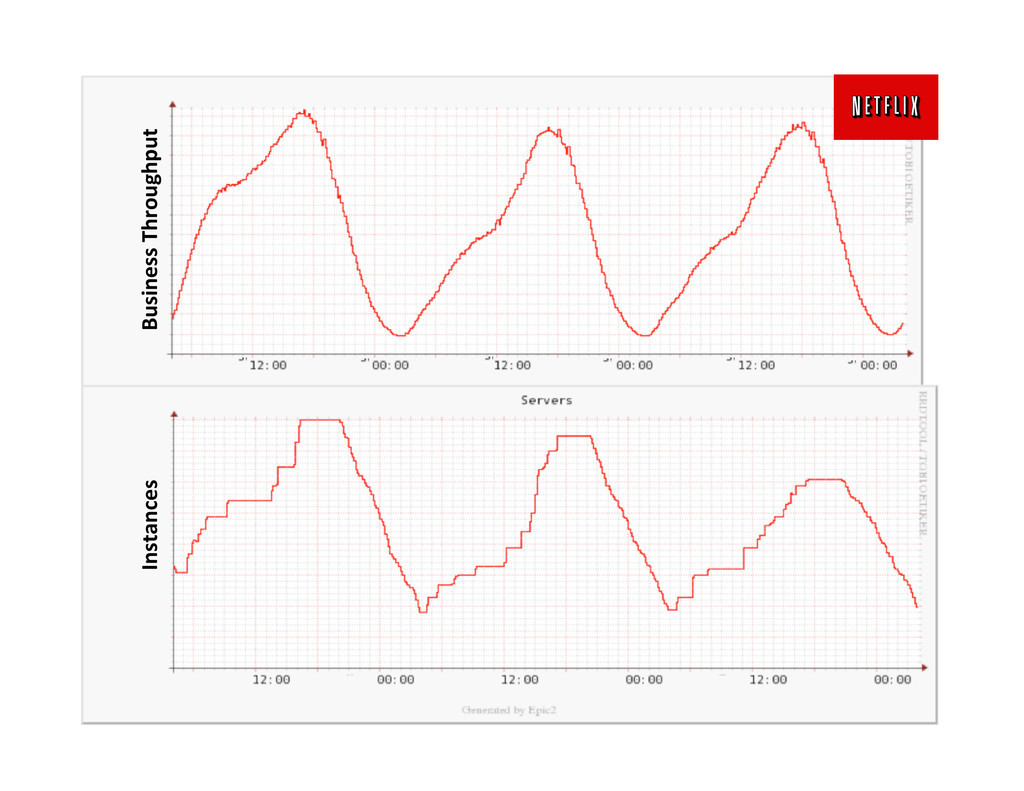
Follow the Customer (Run web servers) during the day
Follow the Money (Run Hadoop clusters) at night 0 2 4 6 8 10 12 14 16 Mon Tue Wed Thur Fri Sat Sun No of Instances Running Week Auto Scaling Servers Hadoop Servers No. of Reserved Instances -
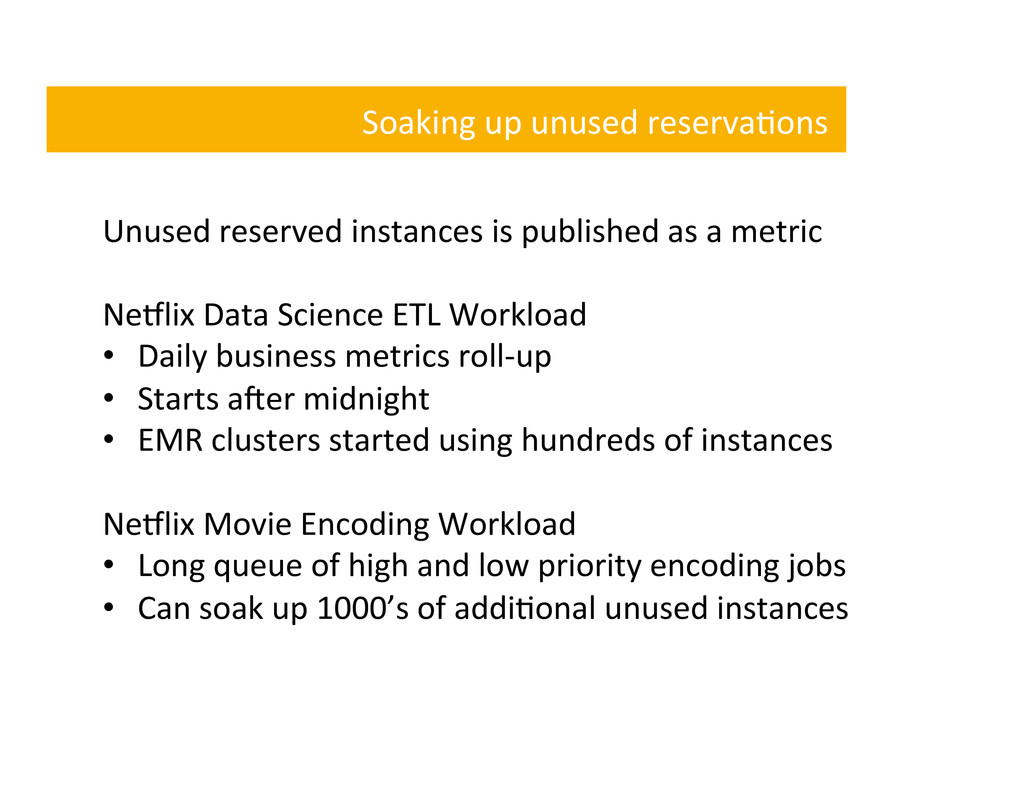
Soaking up unused reserva,ons Unused reserved instances is published
as a metric NeClix Data Science ETL Workload • Daily business metrics roll-‐up • Starts aNer midnight • EMR clusters started using hundreds of instances NeClix Movie Encoding Workload • Long queue of high and low priority encoding jobs • Can soak up 1000’s of addi,onal unused instances -
#1 Business Agility by Rapid Experimenta9on = Profit #2
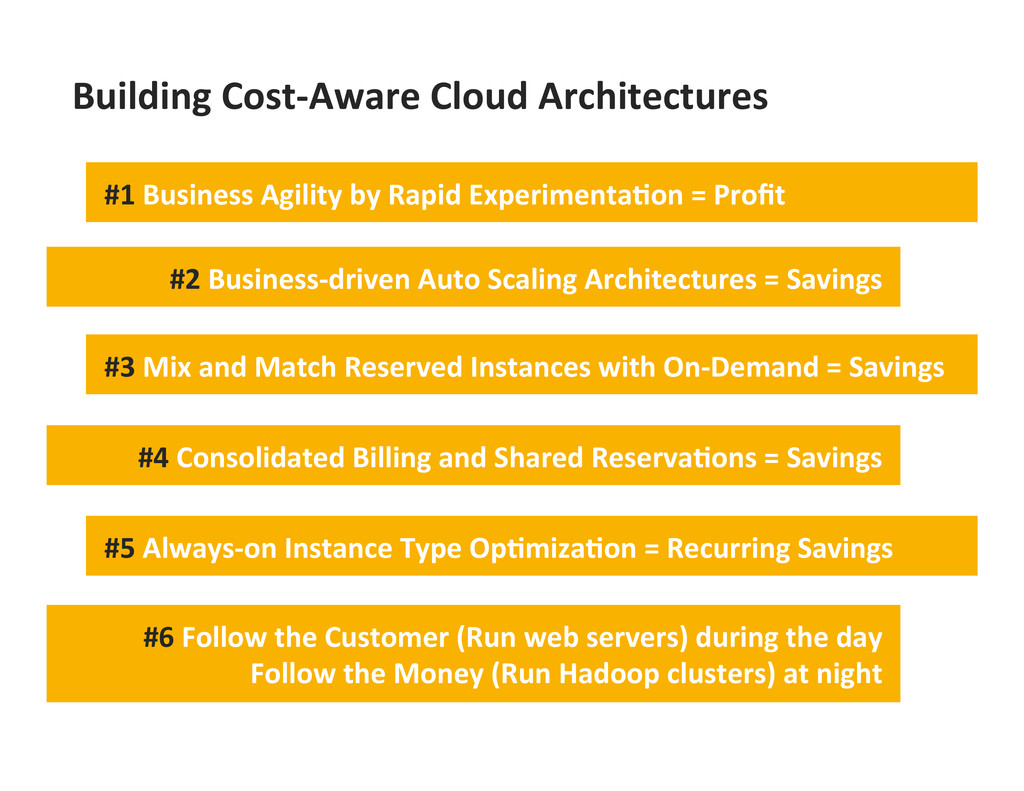
Business-‐driven Auto Scaling Architectures = Savings #3 Mix and Match Reserved Instances with On-‐Demand = Savings #4 Consolidated Billing and Shared Reserva9ons = Savings #5 Always-‐on Instance Type Op9miza9on = Recurring Savings Building Cost-‐Aware Cloud Architectures #6 Follow the Customer (Run web servers) during the day Follow the Money (Run Hadoop clusters) at night -
Takeaways Cloud Na1ve Manages Scale and Complexity at Speed
Ne9lixOSS makes it easier for everyone to become Cloud Na1ve Rethink deployments and turn things off to save money! h#p://neClix.github.com h#p://techblog.neClix.com h#p://slideshare.net/NeClix h#p://www.linkedin.com/in/adriancockcroN @adrianco @NeClixOSS @benjchristensen
 adrianco
 goyoki
 yama3133
 wind111
 yosukeyoshida
 kobayashiyorimitsu
 munenick
 minorun365
 carta_engineering
 kota2and3kan
 kentosuzuki
 orimanabu
 takano0131
 rocio
 gr2m
 tammyeverts
 inesmontani
 gurzu
 baasie
 codingconduct
 signer
 reverentgeek
 axbom
 mongodb
 mfonobong