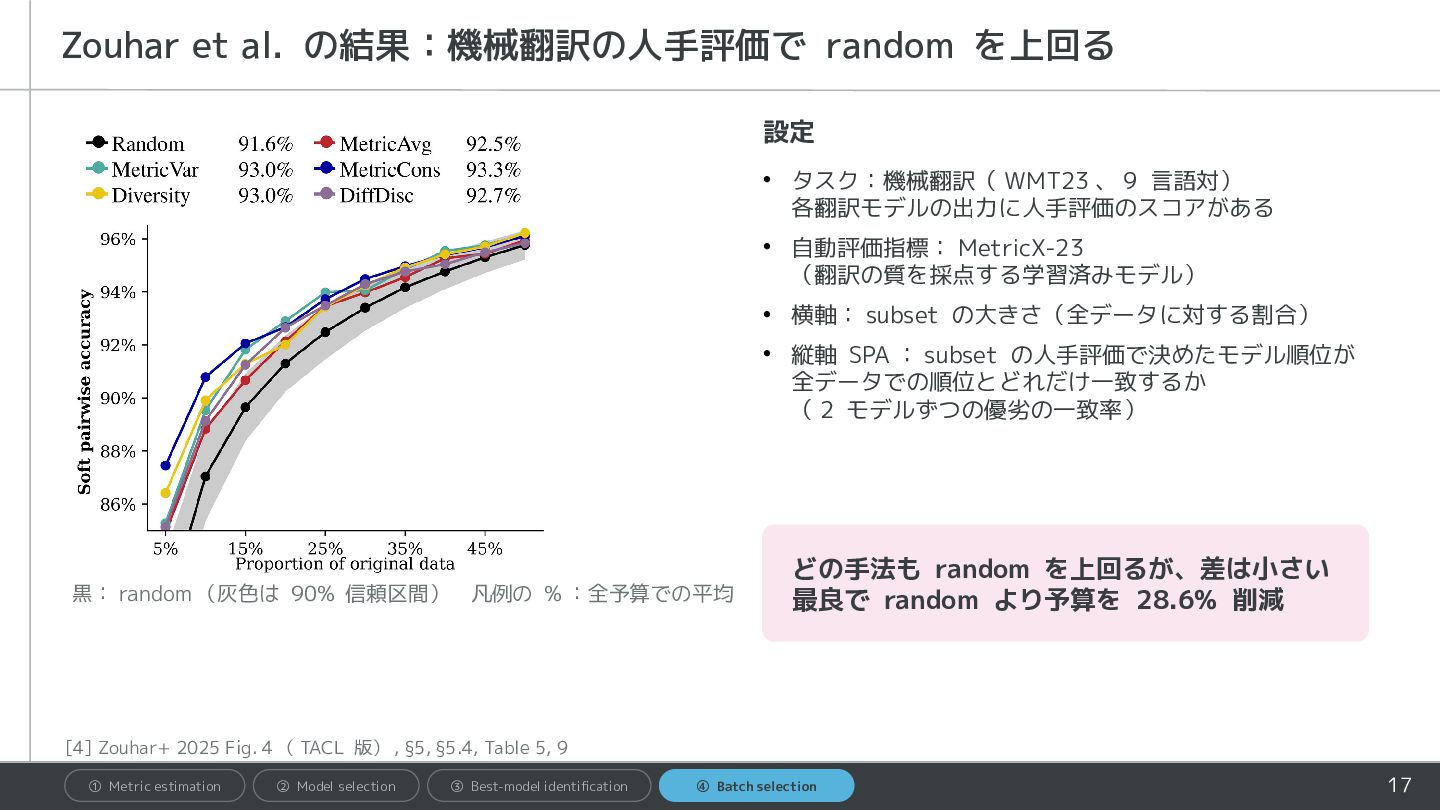
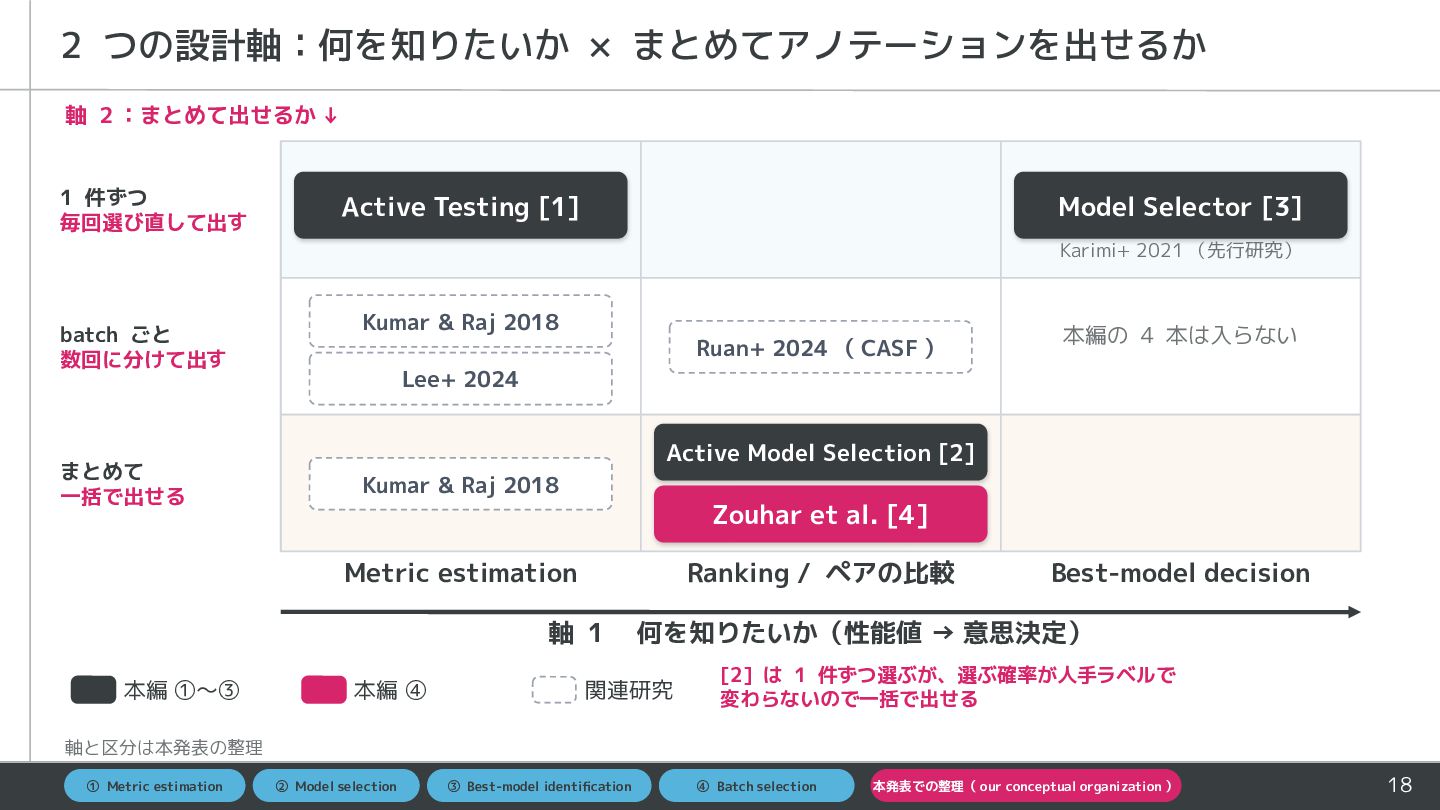
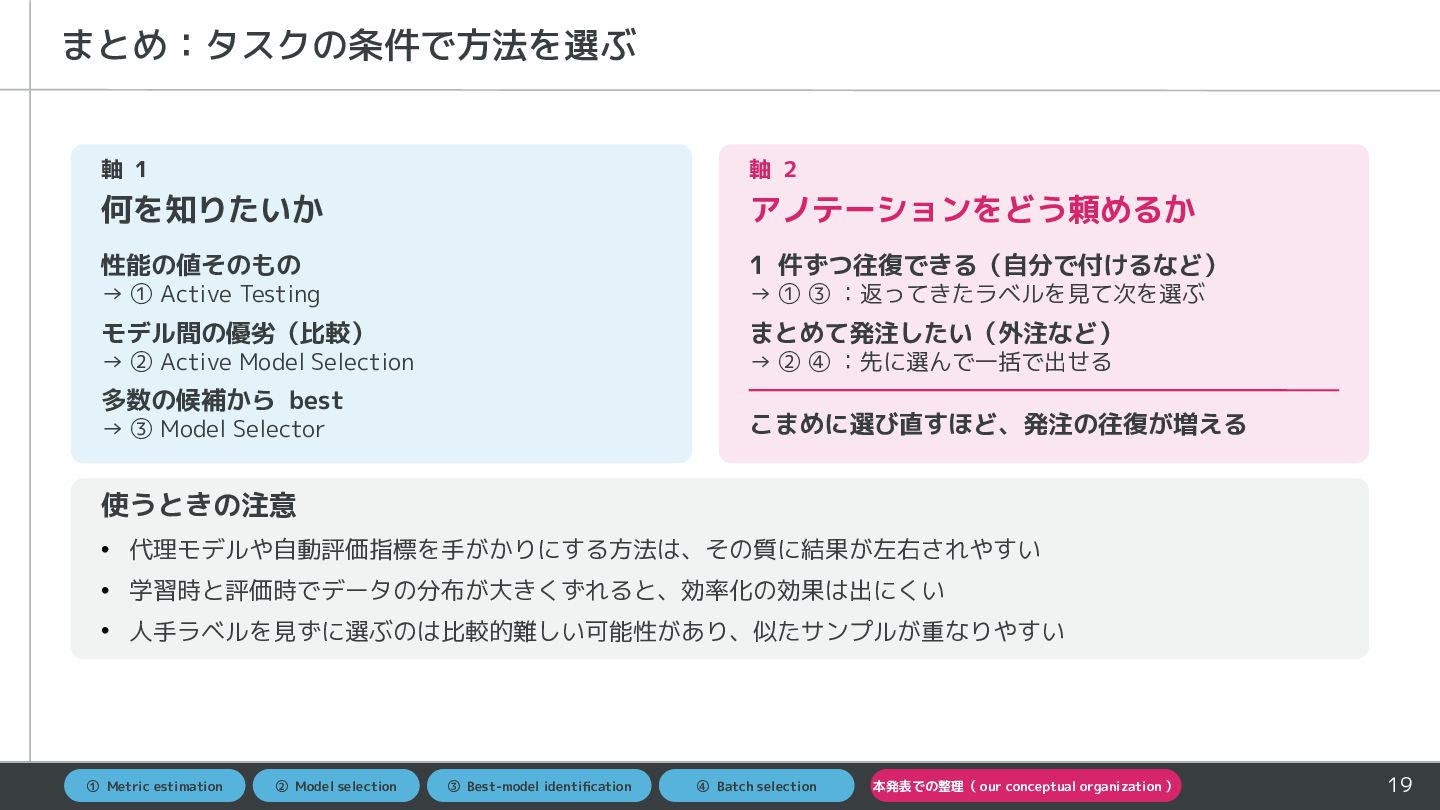
Rainforth. Active Testing: Sample-Efficient Model Evaluation. ICML 2021, PMLR 139, pp. 5753–5763. [2] S. Hara, M. Matsuura, J. Honda, S. Ito. Active model selection: A variance minimization approach. Machine Learning 113, pp. 8327–8345, 2024. [3] P. Okanovic, A. Kirsch, J. Kasper, T. Hoefler, A. Krause, N. M. Gürel. All models are wrong, some are useful: Model Selection with Limited Labels. AISTATS 2025, PMLR 258, pp. 2035–2043. [4] V. Zouhar, P. Cui, M. Sachan. How to Select Datapoints for Efficient Human Evaluation of NLG Models? TACL 13, pp. 1789 –1811, 2025. 2 つの設計軸の地図( Slide 18 )の関連研究 M. R. Karimi, N. M. Gürel, B. Karlaš, J. Rausch, C. Zhang, A. Krause. Online Active Model Selection for Pre-trained Classifiers. AISTATS 2021, PMLR 130, pp. 307 –315. A. Kumar, B. Raj. Classifier Risk Estimation under Limited Labeling Resources. PAKDD 2018, pp. 3–15. J. Lee, S. Kolla, Y. Chen. Towards optimal model evaluation: enhancing active testing with actively improved estimators. Scientific Reports 14, 10690, 2024. J. Ruan, X. Pu, M. Gao, X. Wan, Y. Zhu. Better than Random: Reliable NLG Human Evaluation with Constrained Active Sampling. arXiv:2406.07967, 2024. その他 S. Farquhar, Y. Gal, T. Rainforth. On Statistical Bias in Active Learning: How and When to Fix It. ICLR 2021. ( LURE ) C. Sawade, N. Landwehr, T. Scheffer. Active Comparison of Prediction Models. NeurIPS 2012. ( Slide 11 の比較手法 Sawade ) Y. Chen, S. H. Hassani, A. Karbasi, A. Krause. Sequential Information Maximization: When is Greedy Near-optimal? COLT 2015. A. Kirsch, J. van Amersfoort, Y. Gal. BatchBALD: Efficient and Diverse Batch Acquisition for Deep Bayesian Active Learning. NeurIPS 2019. B. Recht, R. Roelofs, L. Schmidt, V. Shankar. Do ImageNet Classifiers Generalize to ImageNet? ICML 2019. ( ImageNetV2 ) J. Juraska et al. MetricX-23: The Google Submission to the WMT 2023 Metrics Shared Task. WMT 2023. K. Papineni, S. Roukos, T. Ward, W.-J. Zhu. BLEU: a Method for Automatic Evaluation of Machine Translation. ACL 2002. B. Thompson, N. Mathur, D. Deutsch, H. Khayrallah. Improving Statistical Significance in Human Evaluation of Automatic Metrics via Soft Pairwise Accuracy. WMT 2024. ( SPA ) 20


 ftakahashi
 rikkabotan7
 kzmssk
 koide3
 wataruuuuu
 mikimhk
 fkske
 shunk031
 datascientistsociety
 signer
 yuukit
 matsumooon
 kobayashi31
 jonrohan
 honnibal
 techseoconnect
 lfama
 eileencodes
 aemeredith
 samtorres
 gr2m
 sergeychernyshev
 szymonslowik
 marcelosomers
 samlambert