


Share
Embed
[arXiv'23] SCOPE-RL: A Python Library for Offline RL and Off-Policy Evaluation
arXiv: https://arxiv.org/abs/2311.18206
package: https://github.com/hakuhodo-technologies/scope-rl
documentation: https://scope-rl.readthedocs.io/en/latest/
日本語スライド:https://speakerdeck.com/aiueola/scope-rl-ja

Haruka Kiyohara
November 30, 2023
Transcript
107 slides
-
SCOPE-RL: A Python package for offline RL, off-policy evaluation and
selection (OPE/OPS) Haruka Kiyohara, Ren Kishimoto, Kosuke Kawakami, Ken Kobayashi, Kazuhide Nakata, Yuta Saito May 2024 SCOPE-RL package description 1 -
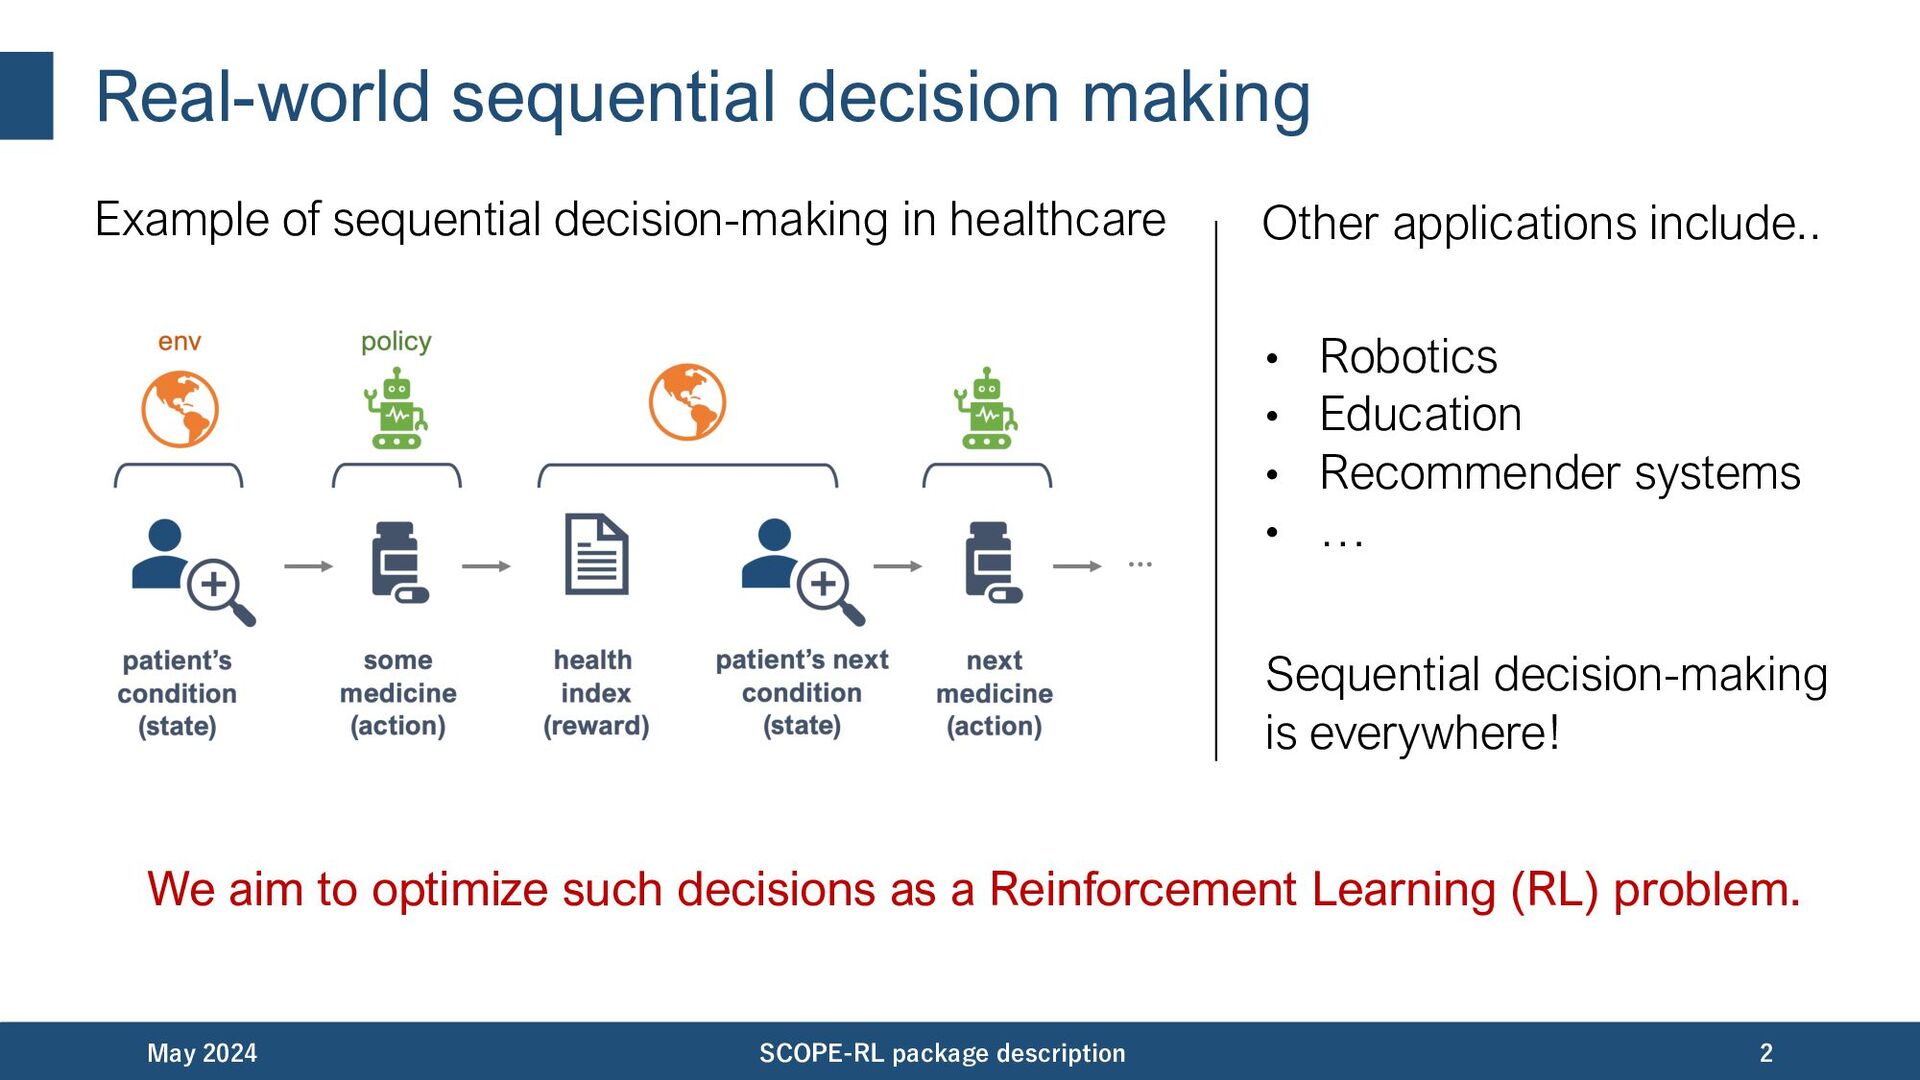
Real-world sequential decision making Example of sequential decision-making in healthcare
We aim to optimize such decisions as a Reinforcement Learning (RL) problem. May 2024 SCOPE-RL package description 2 Other applications include.. • Robotics • Education • Recommender systems • … Sequential decision-making is everywhere! -
Online and Offline Reinforcement Learning (RL) • Online RL –
• learns a policy through interaction • may harm the real system with bad action choices • Offline RL – • learns and evaluate a policy solely from offline data • can be a safe alternative for online RL May 2024 SCOPE-RL package description 3 We talk about a library for offline RL and policy evaluation. -
Content • Motivation • Key features of SCOPE-RL • End-to-end
implementation of offline RL and off-policy evaluation (OPE) • Various OPE estimators • Assessment protocols for OPE • User-friendly APIs • Appendix • Quick demo on the usage • Implemented OPE estimators and assessment protocols May 2024 SCOPE-RL package description 4 -
Motivation May 2024 SCOPE-RL package description 5 Why do we
need a new offline RL platform? -
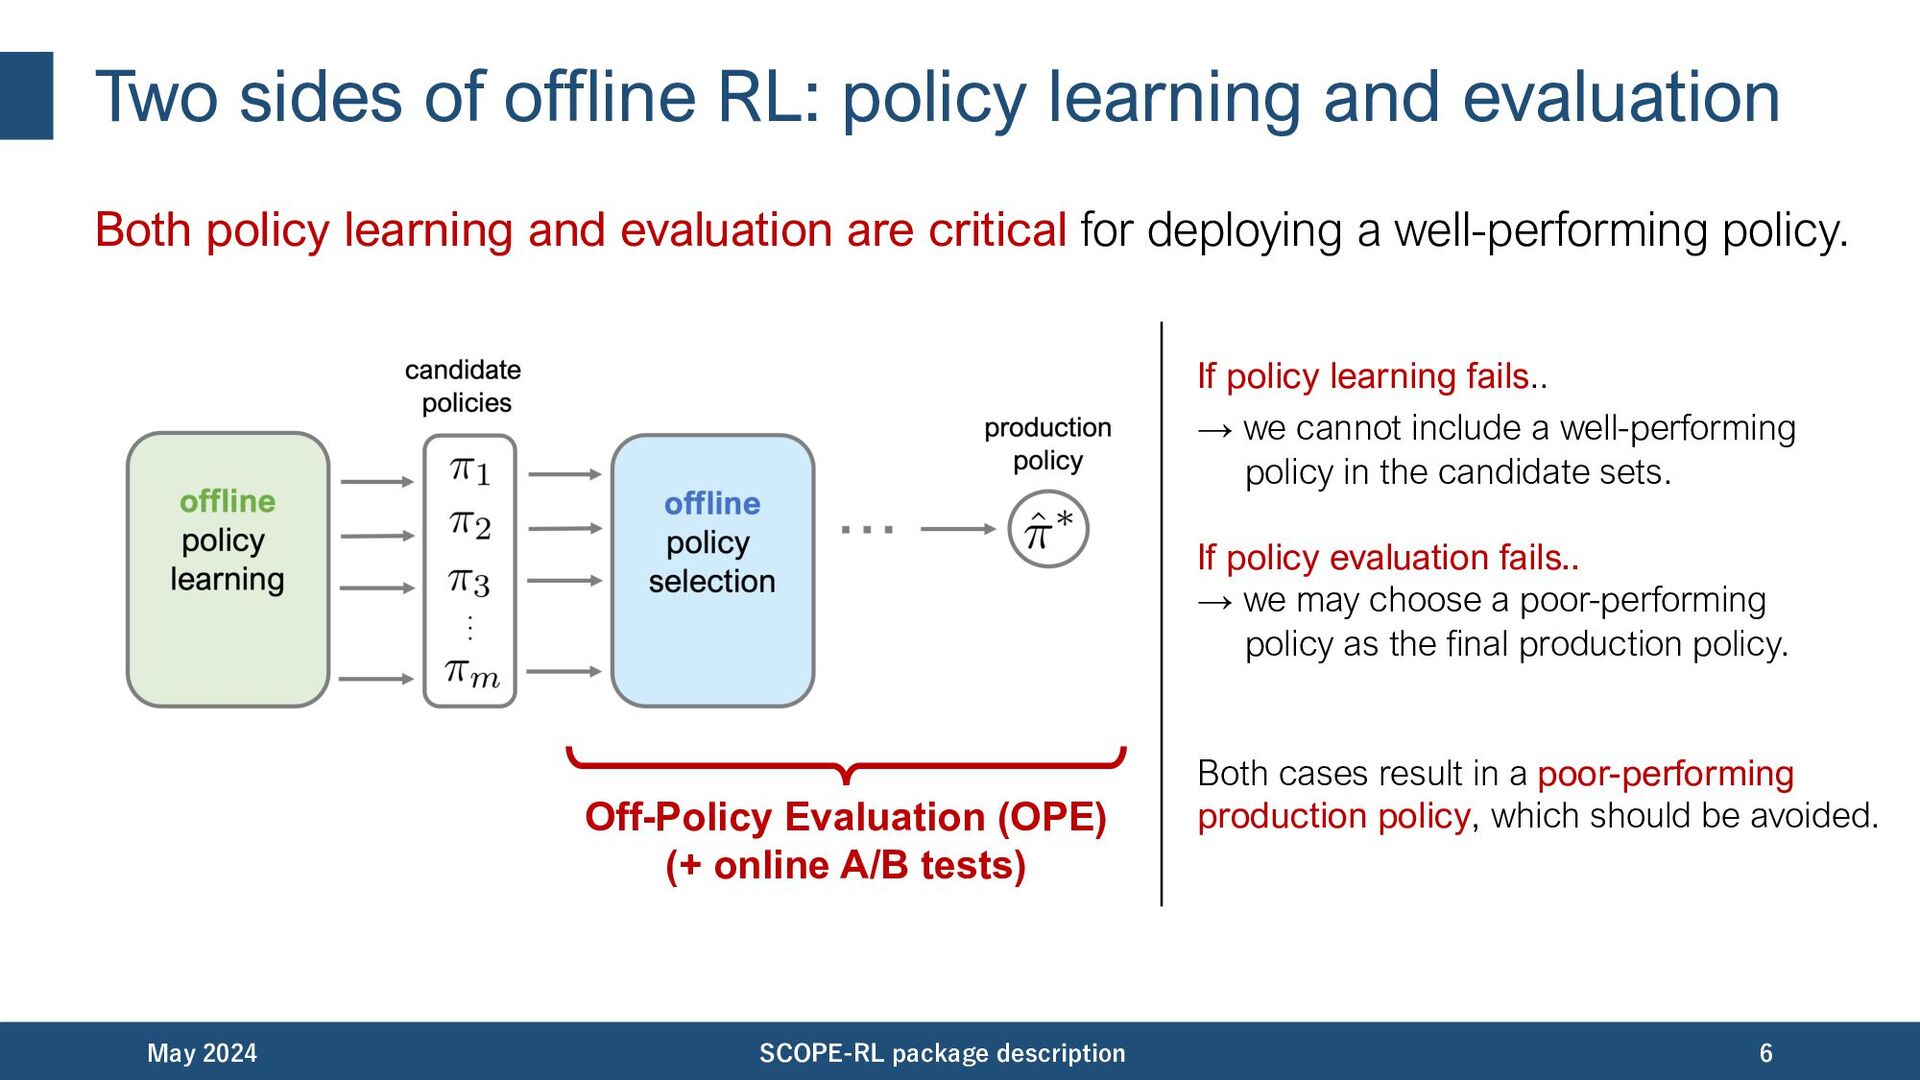
Two sides of offline RL: policy learning and evaluation Both
policy learning and evaluation are critical for deploying a well-performing policy. May 2024 SCOPE-RL package description 6 Off-Policy Evaluation (OPE) (+ online A/B tests) If policy learning fails.. → we cannot include a well-performing policy in the candidate sets. If policy evaluation fails.. → we may choose a poor-performing policy as the final production policy. Both cases result in a poor-performing production policy, which should be avoided. -
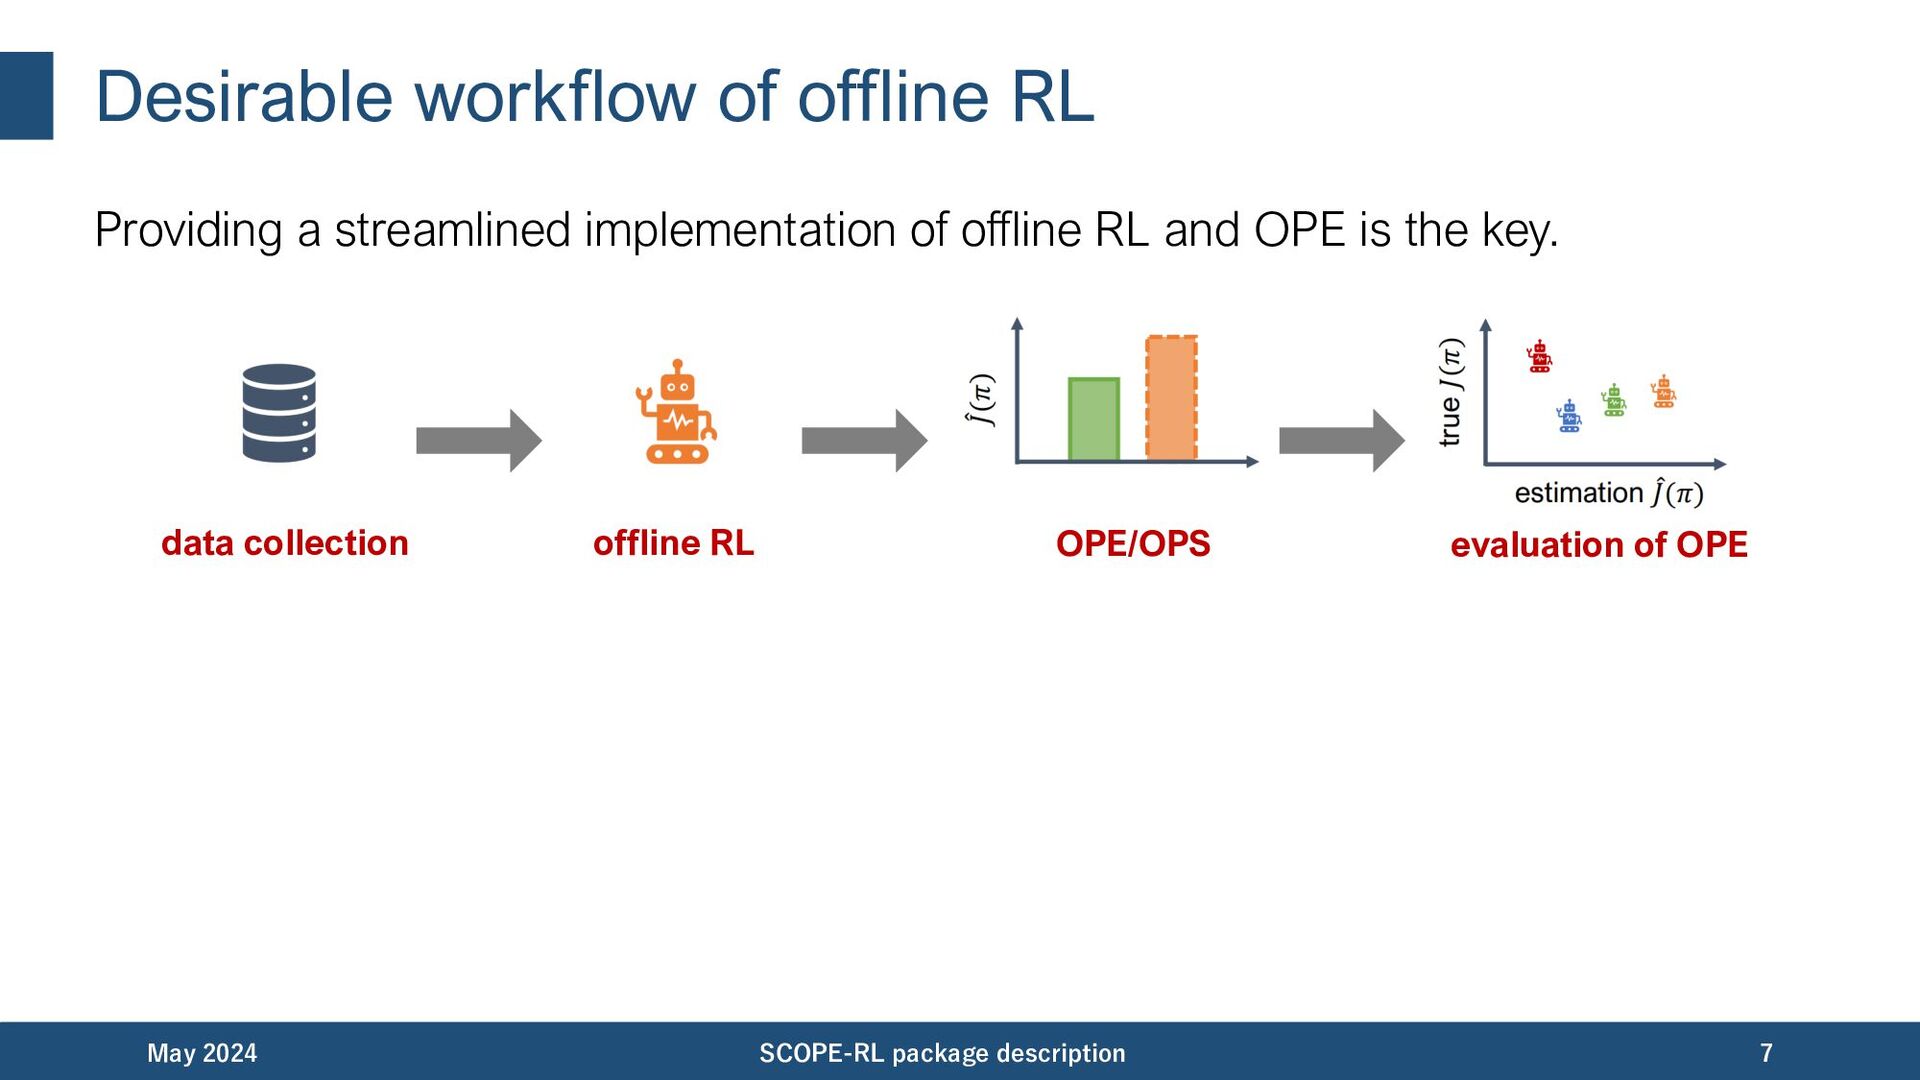
Desirable workflow of offline RL Providing a streamlined implementation of
offline RL and OPE is the key. May 2024 SCOPE-RL package description 7 data collection offline RL OPE/OPS evaluation of OPE -
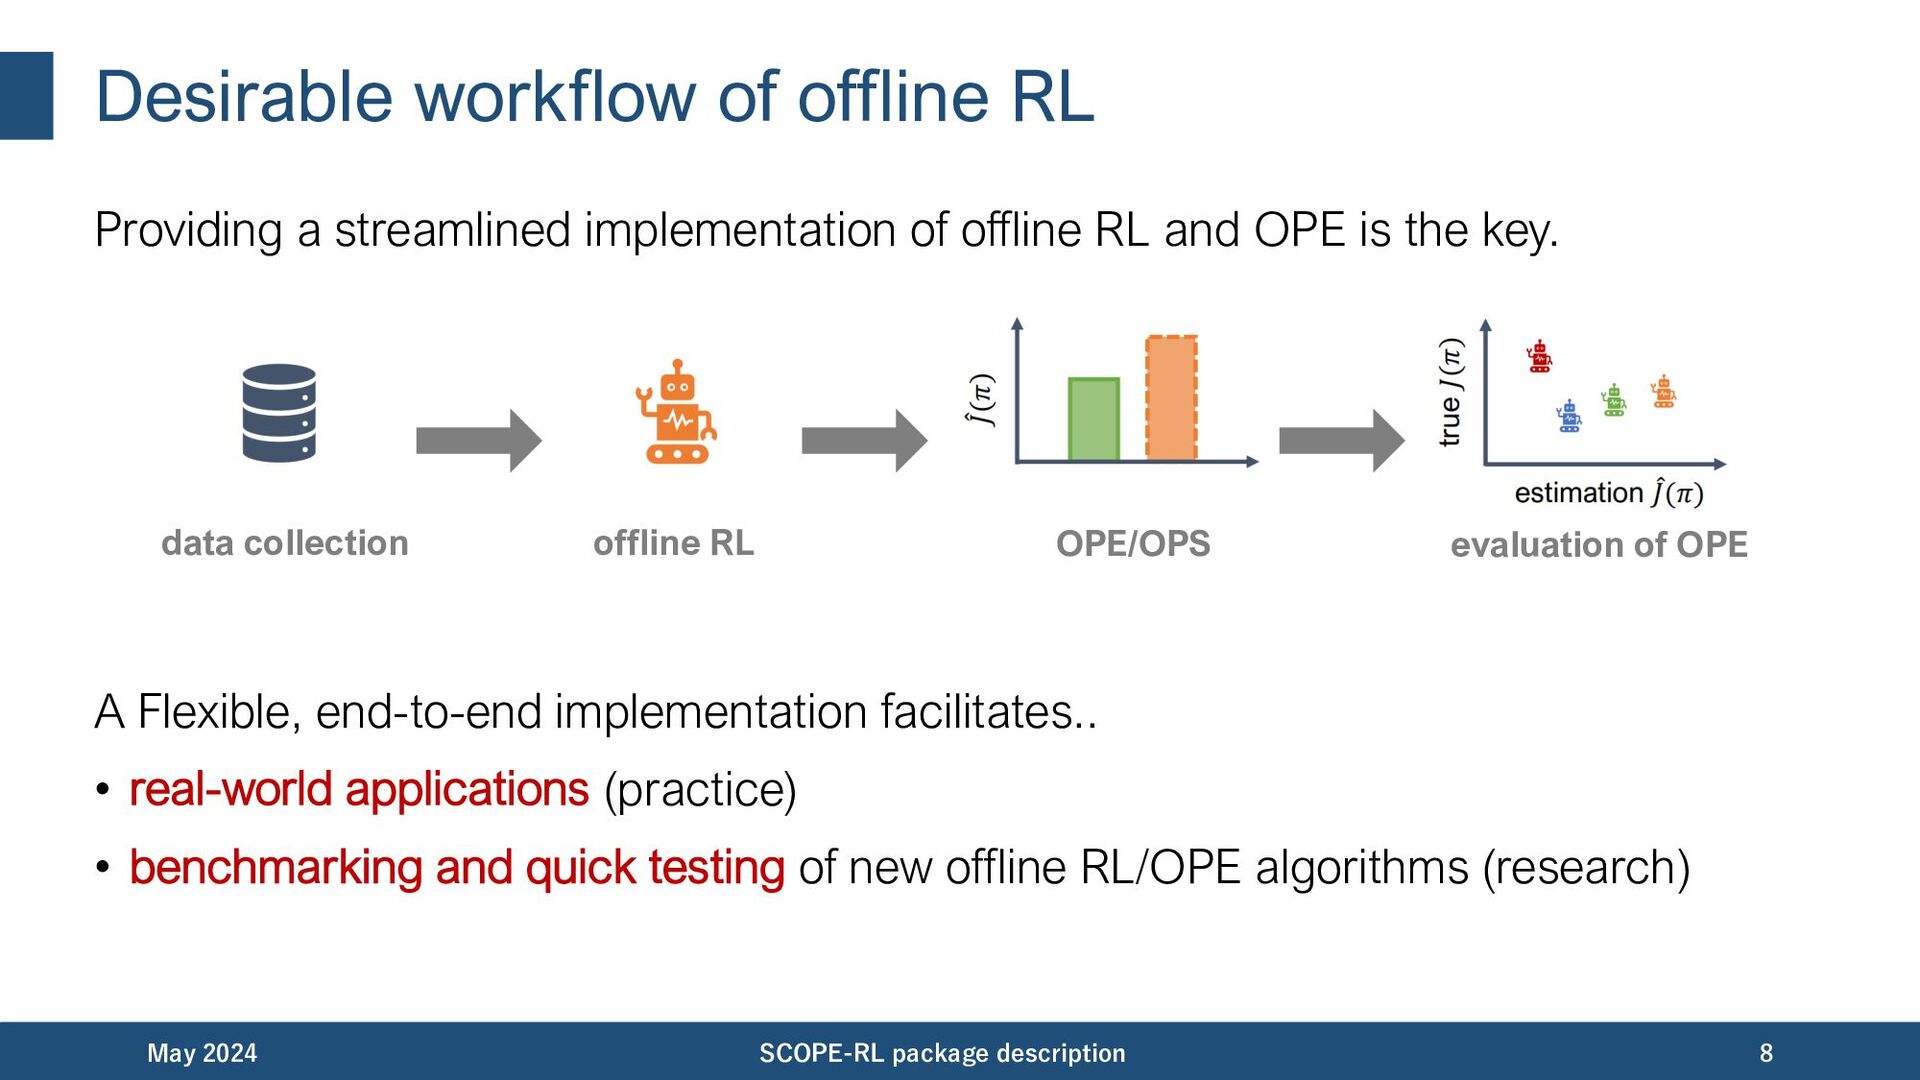
Desirable workflow of offline RL Providing a streamlined implementation of
offline RL and OPE is the key. A Flexible, end-to-end implementation facilitates.. • real-world applications (practice) • benchmarking and quick testing of new offline RL/OPE algorithms (research) May 2024 SCOPE-RL package description 8 data collection offline RL OPE/OPS evaluation of OPE -
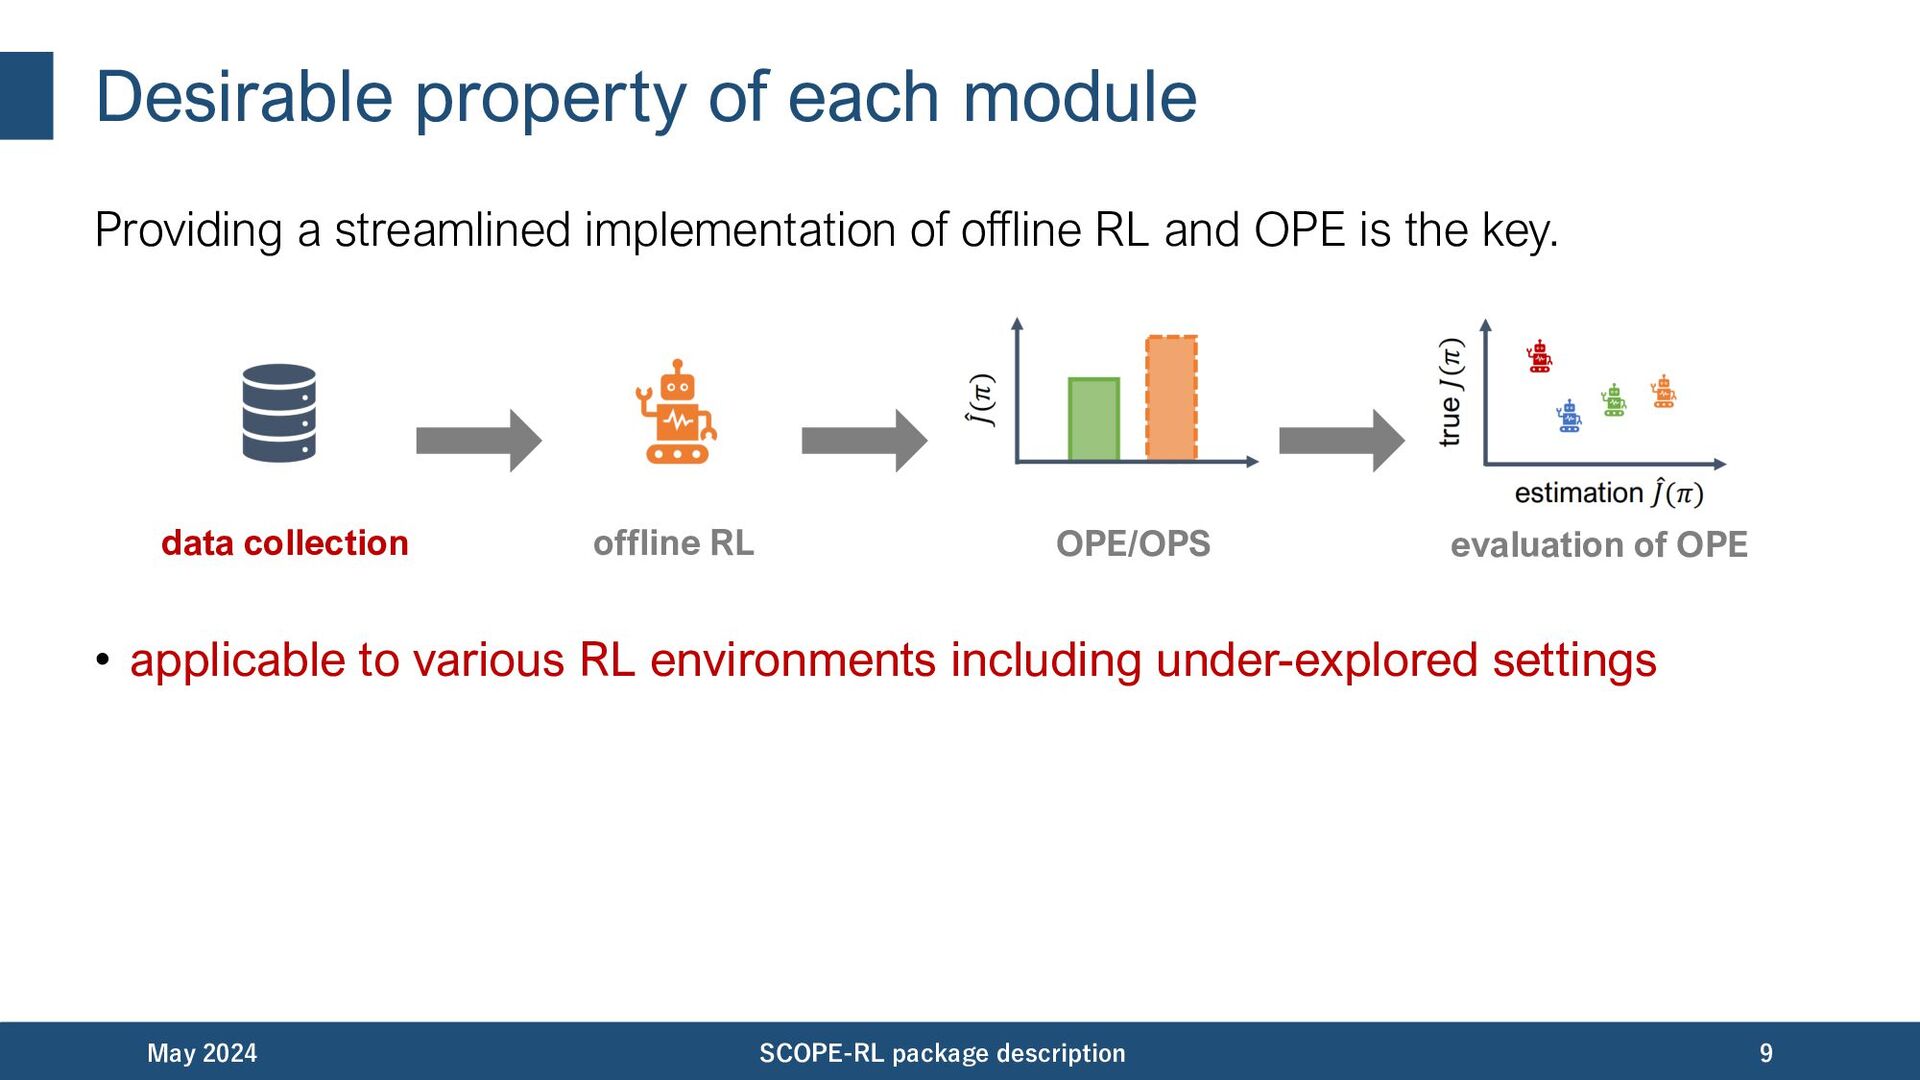
Desirable property of each module Providing a streamlined implementation of
offline RL and OPE is the key. • applicable to various RL environments including under-explored settings May 2024 SCOPE-RL package description 9 data collection offline RL OPE/OPS evaluation of OPE -
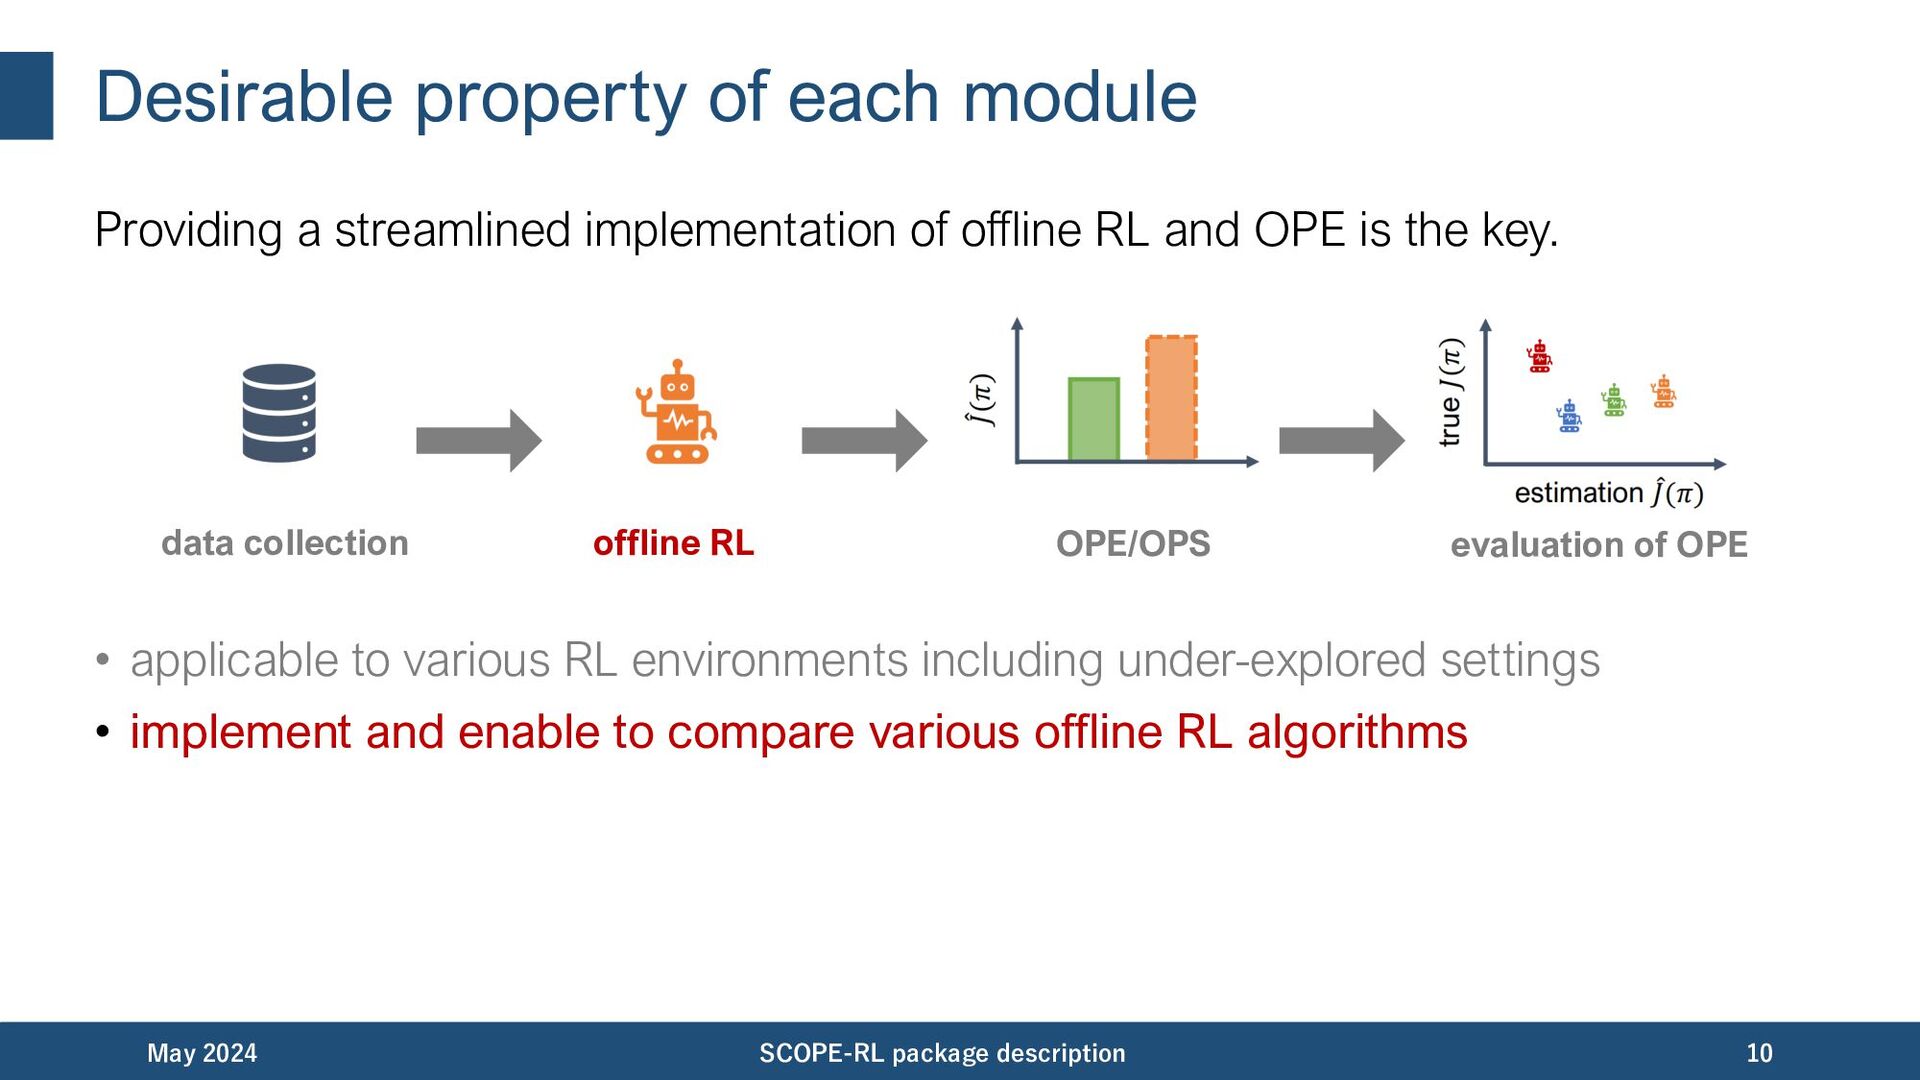
Desirable property of each module Providing a streamlined implementation of
offline RL and OPE is the key. • applicable to various RL environments including under-explored settings • implement and enable to compare various offline RL algorithms May 2024 SCOPE-RL package description 10 data collection offline RL OPE/OPS evaluation of OPE -
Desirable property of each module Providing a streamlined implementation of
offline RL and OPE is the key. • applicable to various RL environments including under-explored settings • implement and enable to compare various offline RL algorithms • able to evaluate various policies with various OPE estimators May 2024 SCOPE-RL package description 11 data collection offline RL OPE/OPS evaluation of OPE -
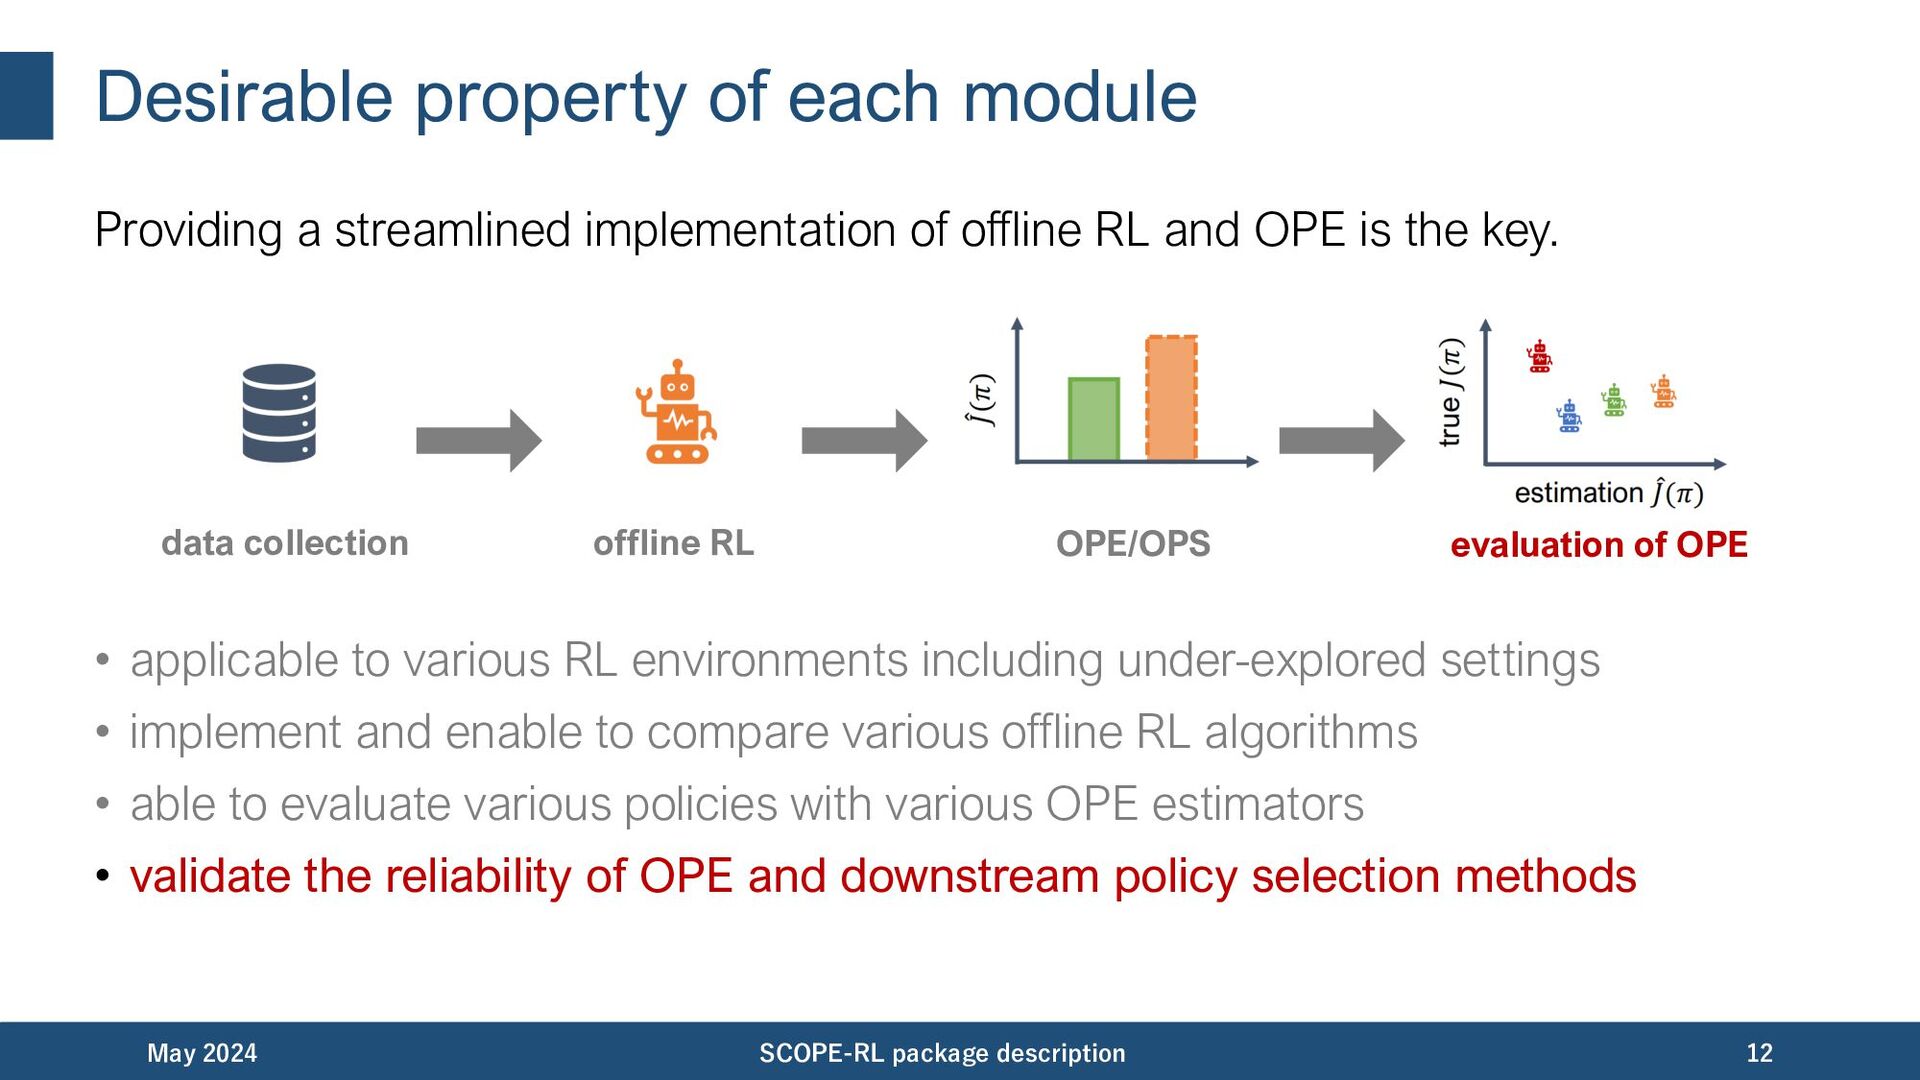
Desirable property of each module Providing a streamlined implementation of
offline RL and OPE is the key. • applicable to various RL environments including under-explored settings • implement and enable to compare various offline RL algorithms • able to evaluate various policies with various OPE estimators • validate the reliability of OPE and downstream policy selection methods May 2024 SCOPE-RL package description 12 data collection offline RL OPE/OPS evaluation of OPE -
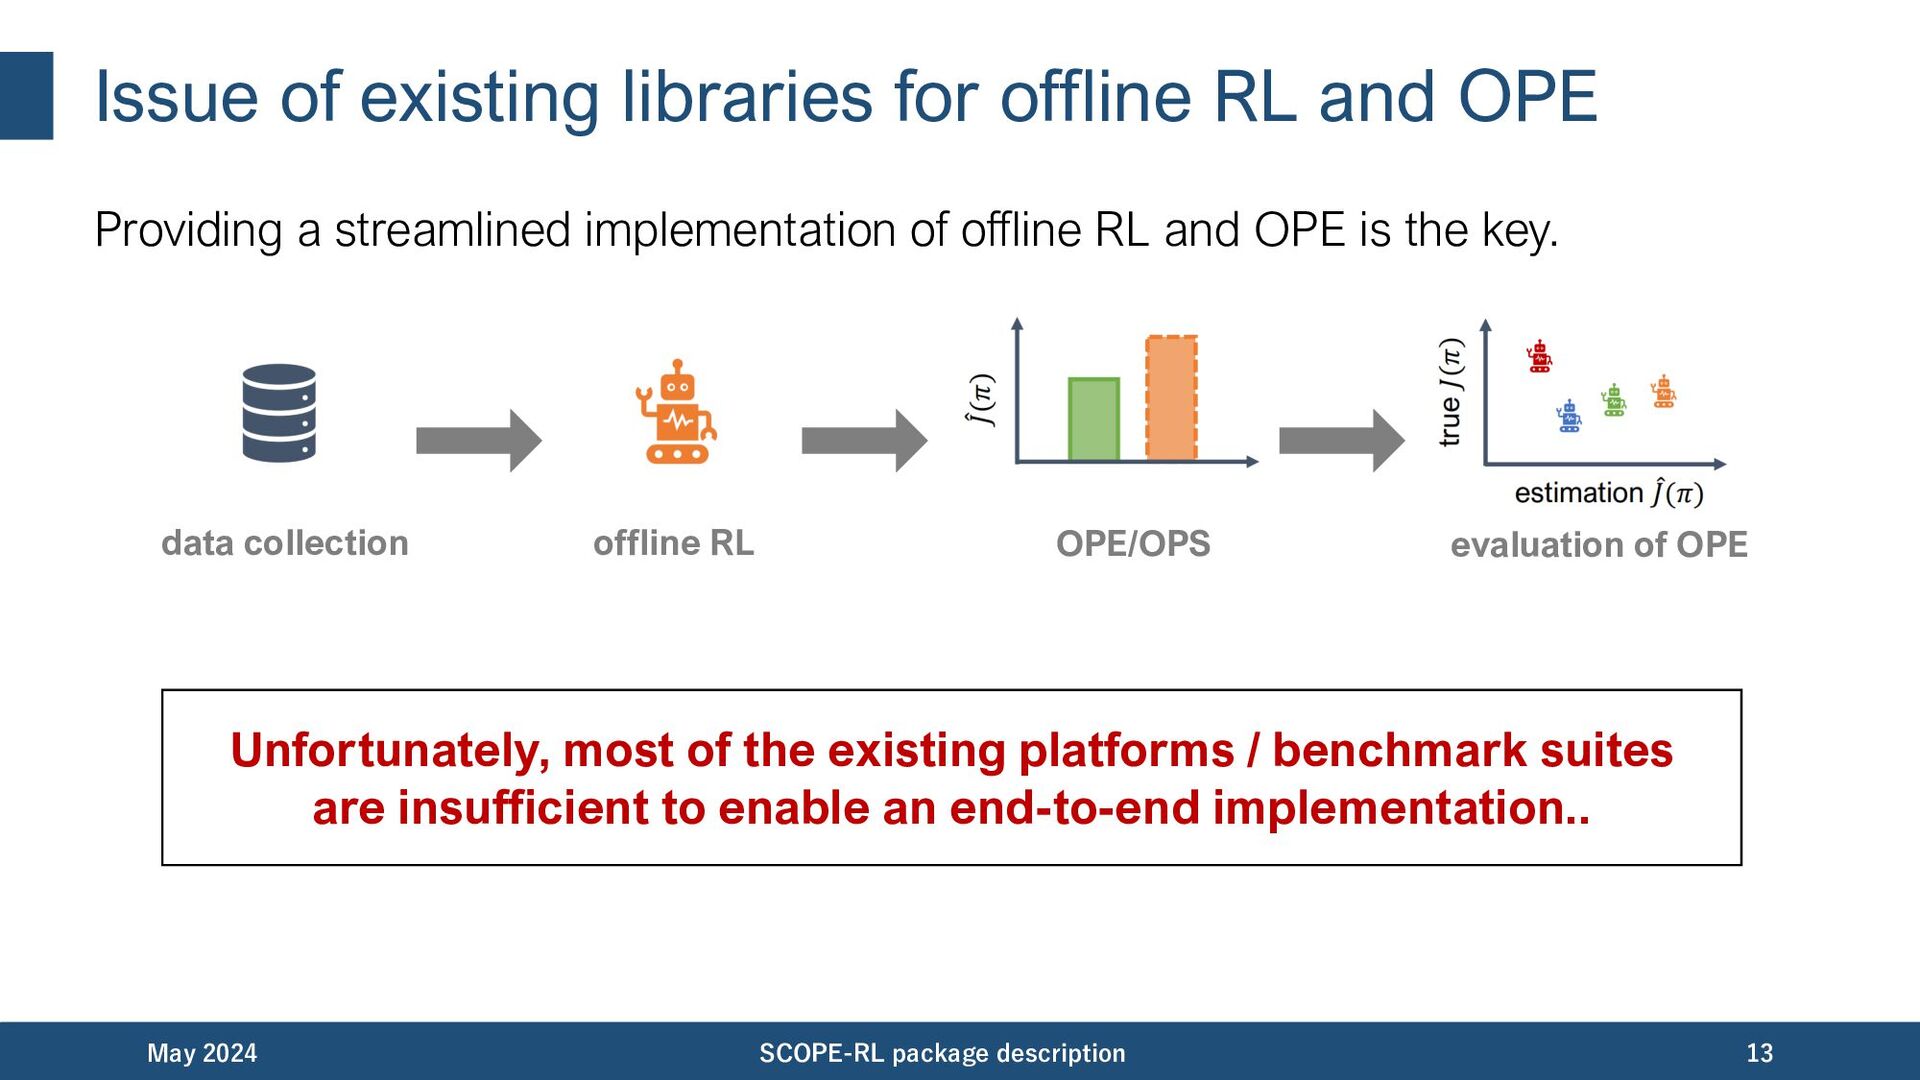
Issue of existing libraries for offline RL and OPE Providing
a streamlined implementation of offline RL and OPE is the key. May 2024 SCOPE-RL package description 13 data collection offline RL OPE/OPS evaluation of OPE Unfortunately, most of the existing platforms / benchmark suites are insufficient to enable an end-to-end implementation.. -
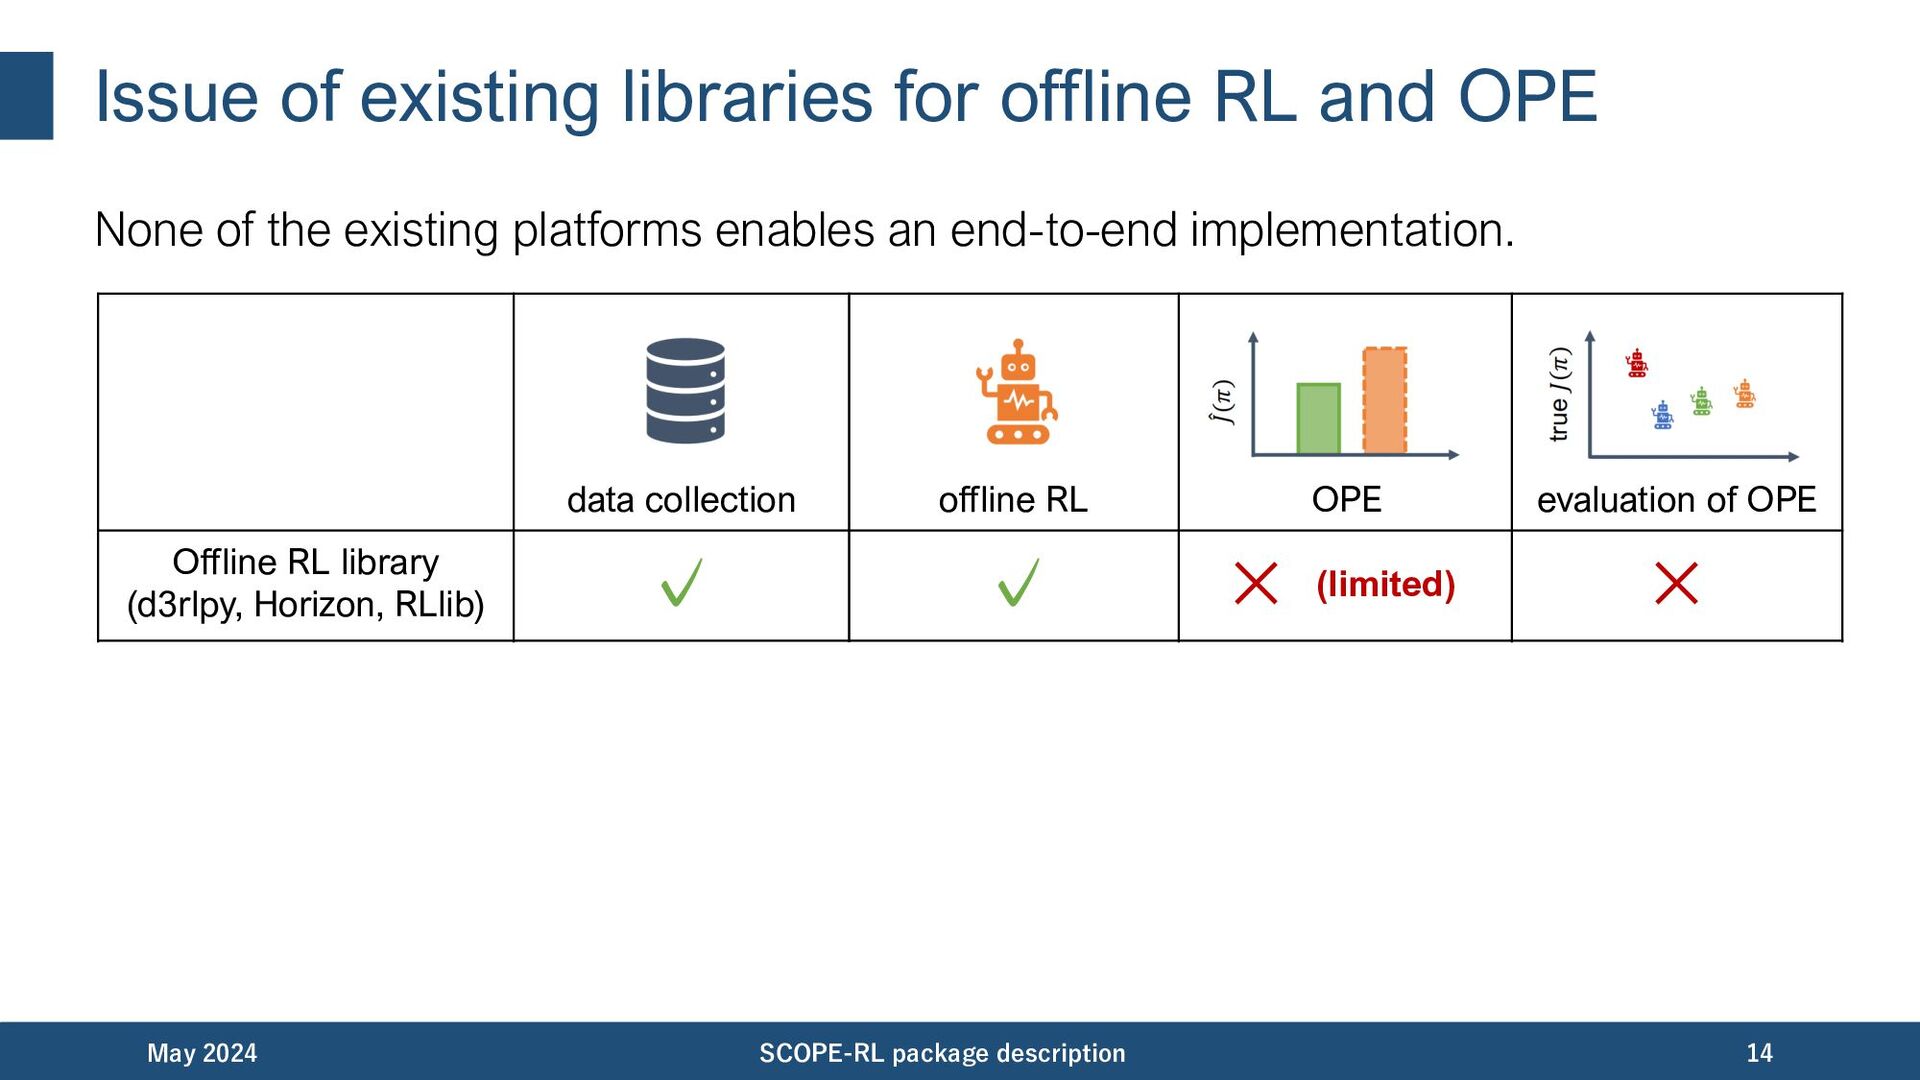
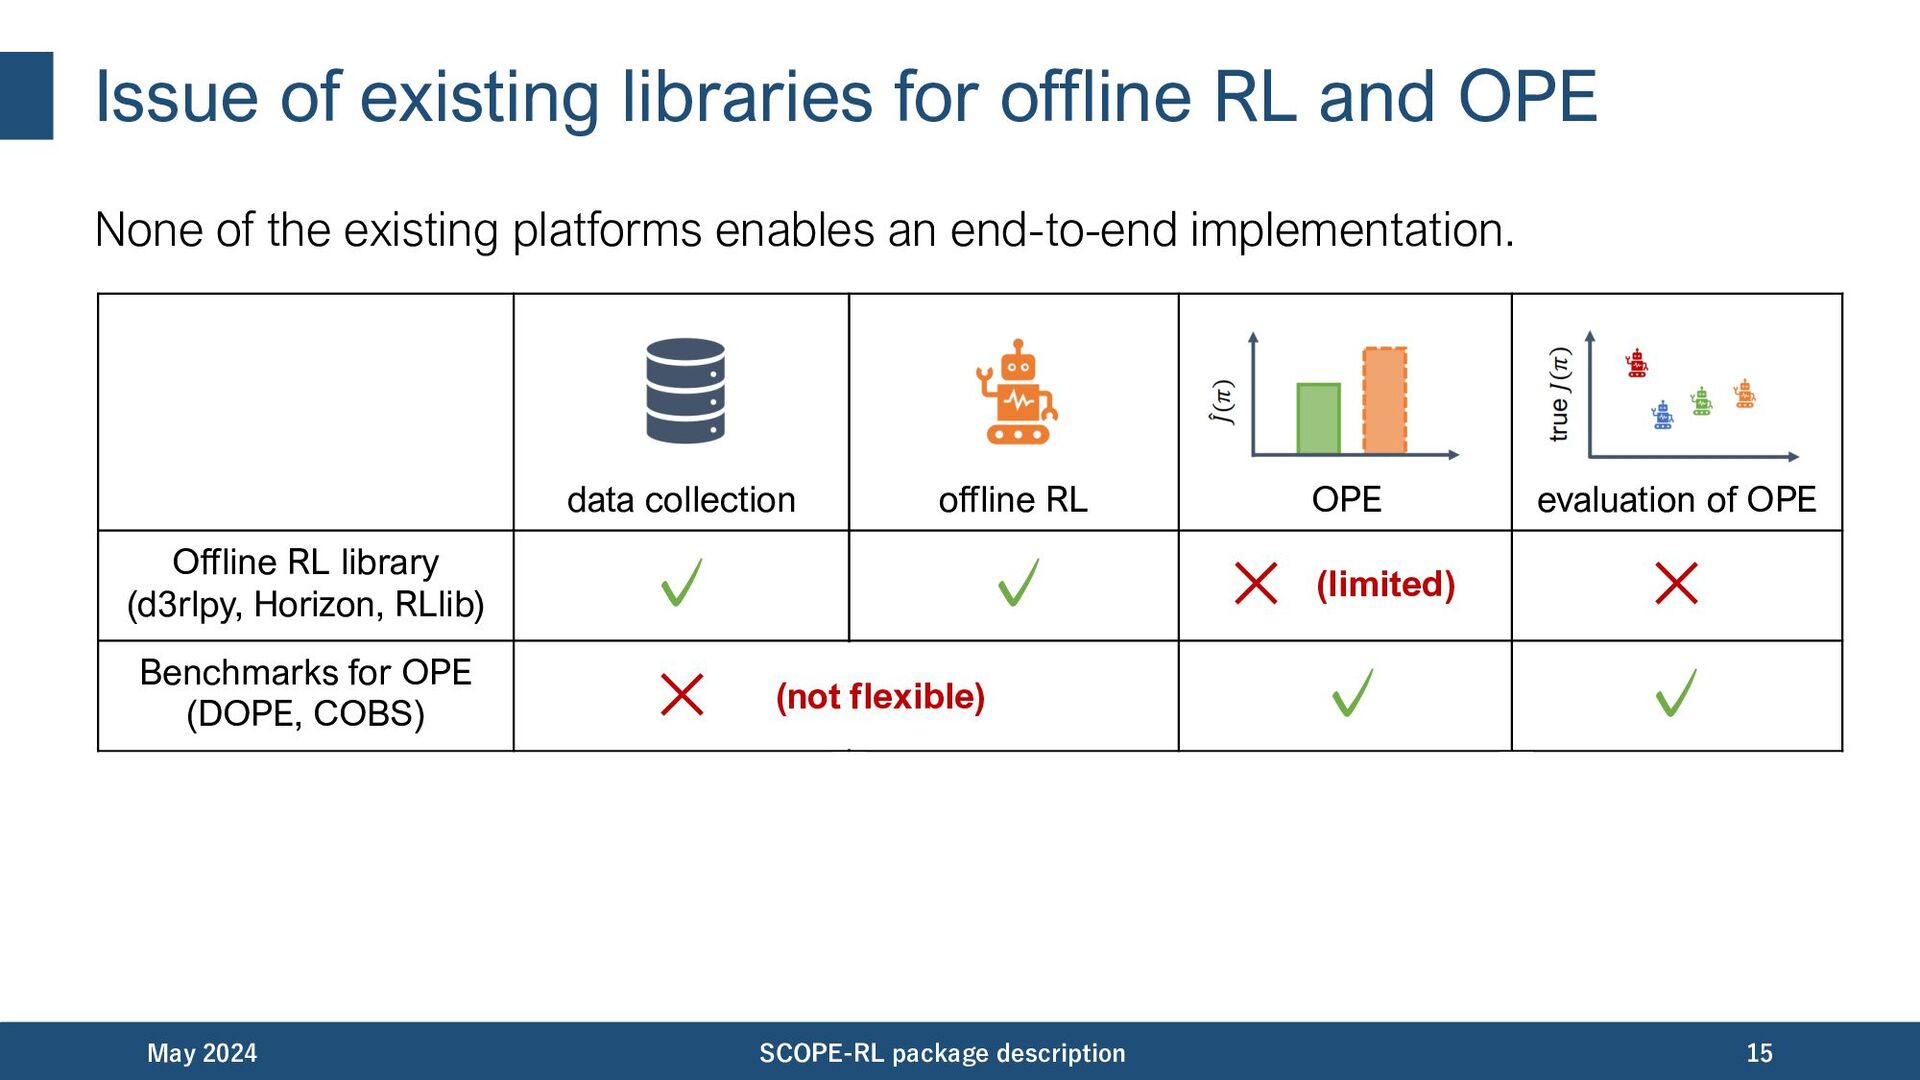
Issue of existing libraries for offline RL and OPE None
of the existing platforms enables an end-to-end implementation. May 2024 SCOPE-RL package description 14 Offline RL library (d3rlpy, Horizon, RLlib) Benchmark for OPE (DOPE, COBS) (OBP) (RecoGym, RL4RS) evaluation of OPE OPE offline RL data collection ✓ ✓ × (limited) × × (not flexible) ✓ ✓ × (implements whole procedures, but is not applicable to RL) × (specific) ✓ × (limited) × -
Issue of existing libraries for offline RL and OPE None
of the existing platforms enables an end-to-end implementation. May 2024 SCOPE-RL package description 15 Offline RL library (d3rlpy, Horizon, RLlib) Benchmarks for OPE (DOPE, COBS) (OBP) (RecoGym, RL4RS) evaluation of OPE OPE offline RL data collection ✓ ✓ × (limited) × × (not flexible) ✓ ✓ × (implements whole procedures, but is not applicable to RL) × (specific) ✓ × (limited) × -
Issue of existing libraries for offline RL and OPE None
of the existing platforms enables an end-to-end implementation. May 2024 SCOPE-RL package description 16 Offline RL library (d3rlpy, Horizon, RLlib) Benchmarks for OPE (DOPE, COBS) OPE platform (OBP) (RecoGym, RL4RS) evaluation of OPE OPE offline RL data collection ✓ ✓ × (limited) × × (not flexible) ✓ ✓ × (specific) ✓ × (limited) × ✓? ✓? ✓? ✓? -
Issue of existing libraries for offline RL and OPE None
of the existing platforms enables an end-to-end implementation. May 2024 SCOPE-RL package description 17 Offline RL library (d3rlpy, Horizon, RLlib) Benchmarks for OPE (DOPE, COBS) OPE platform (OBP) (RecoGym, RL4RS) evaluation of OPE OPE offline RL data collection ✓ ✓ × (limited) × × ✓ ✓ × (specific) ✓ × (limited) × × (not flexible) (not applicable to RL) -
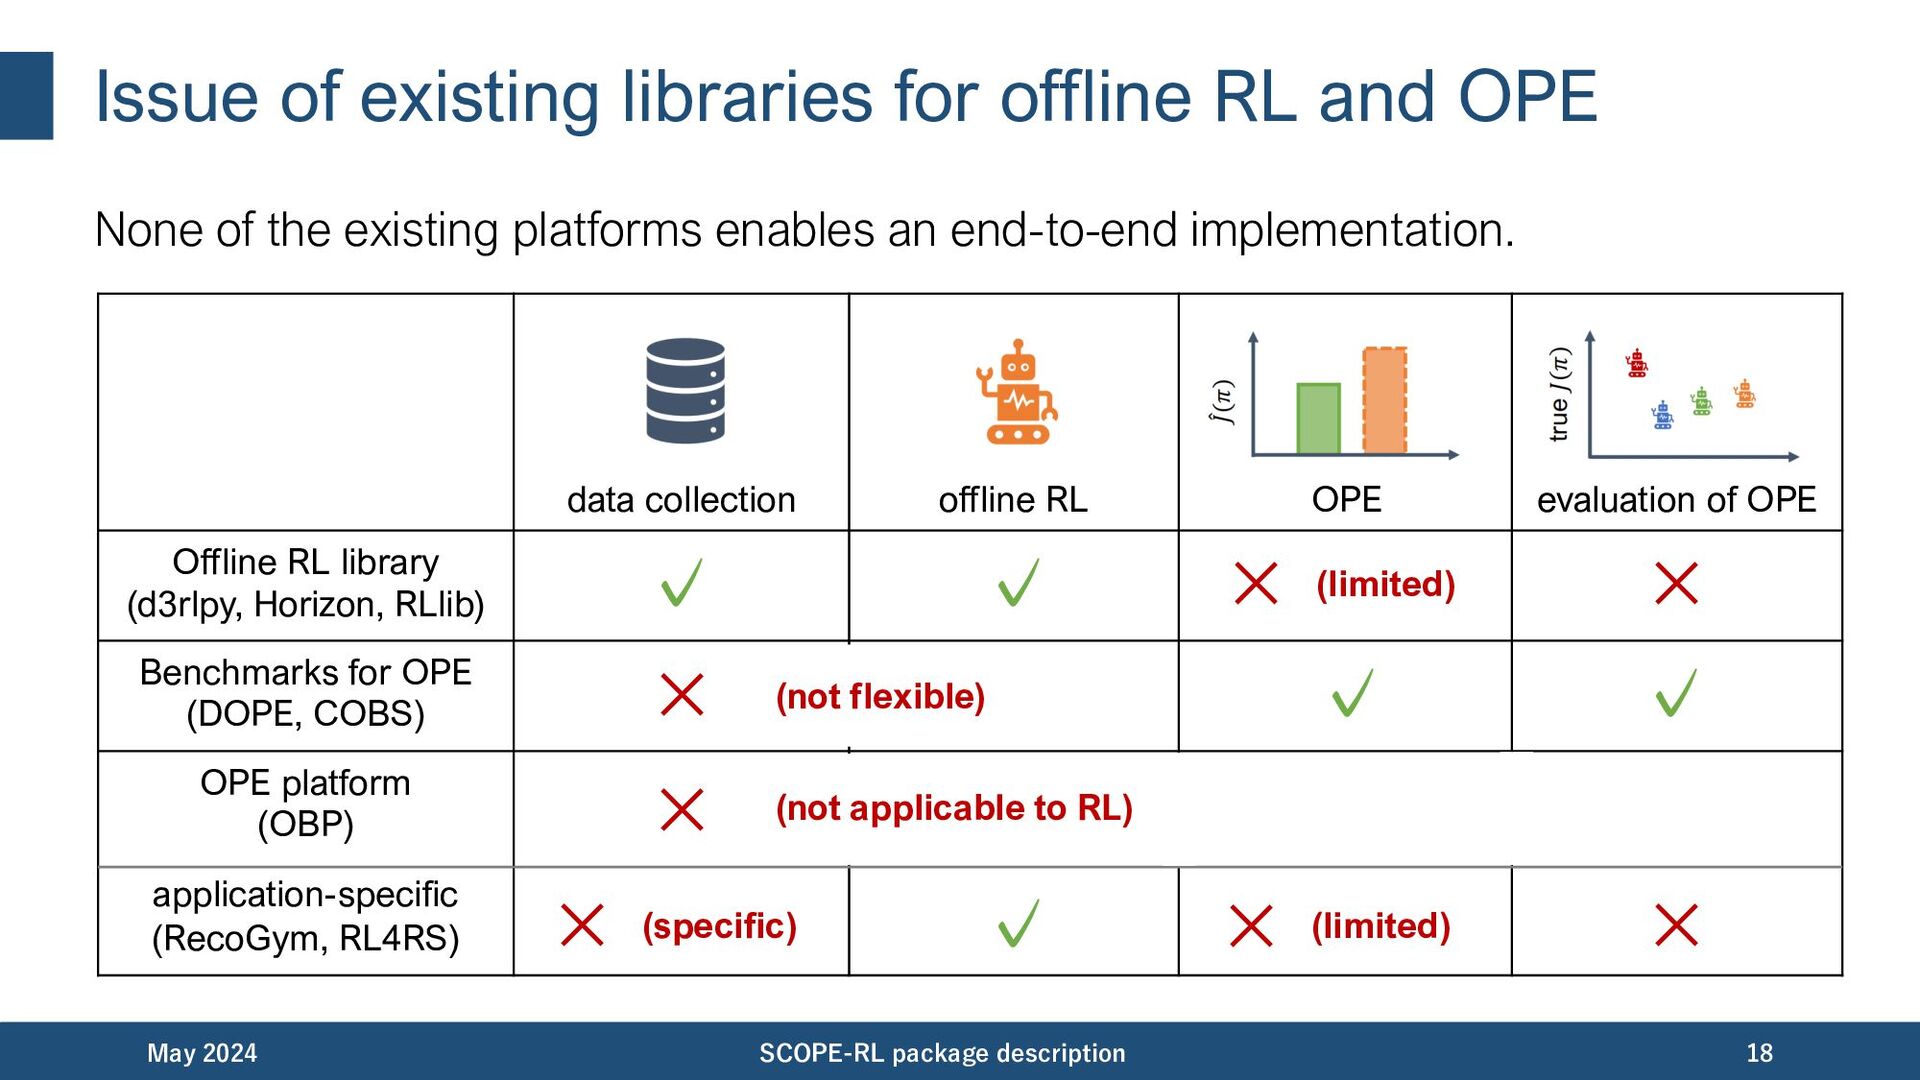
Issue of existing libraries for offline RL and OPE None
of the existing platforms enables an end-to-end implementation. May 2024 SCOPE-RL package description 18 Offline RL library (d3rlpy, Horizon, RLlib) Benchmarks for OPE (DOPE, COBS) OPE platform (OBP) application-specific (RecoGym, RL4RS) evaluation of OPE OPE offline RL data collection ✓ ✓ × (limited) × × ✓ ✓ × × (specific) ✓ × (limited) × (not flexible) (not applicable to RL) -
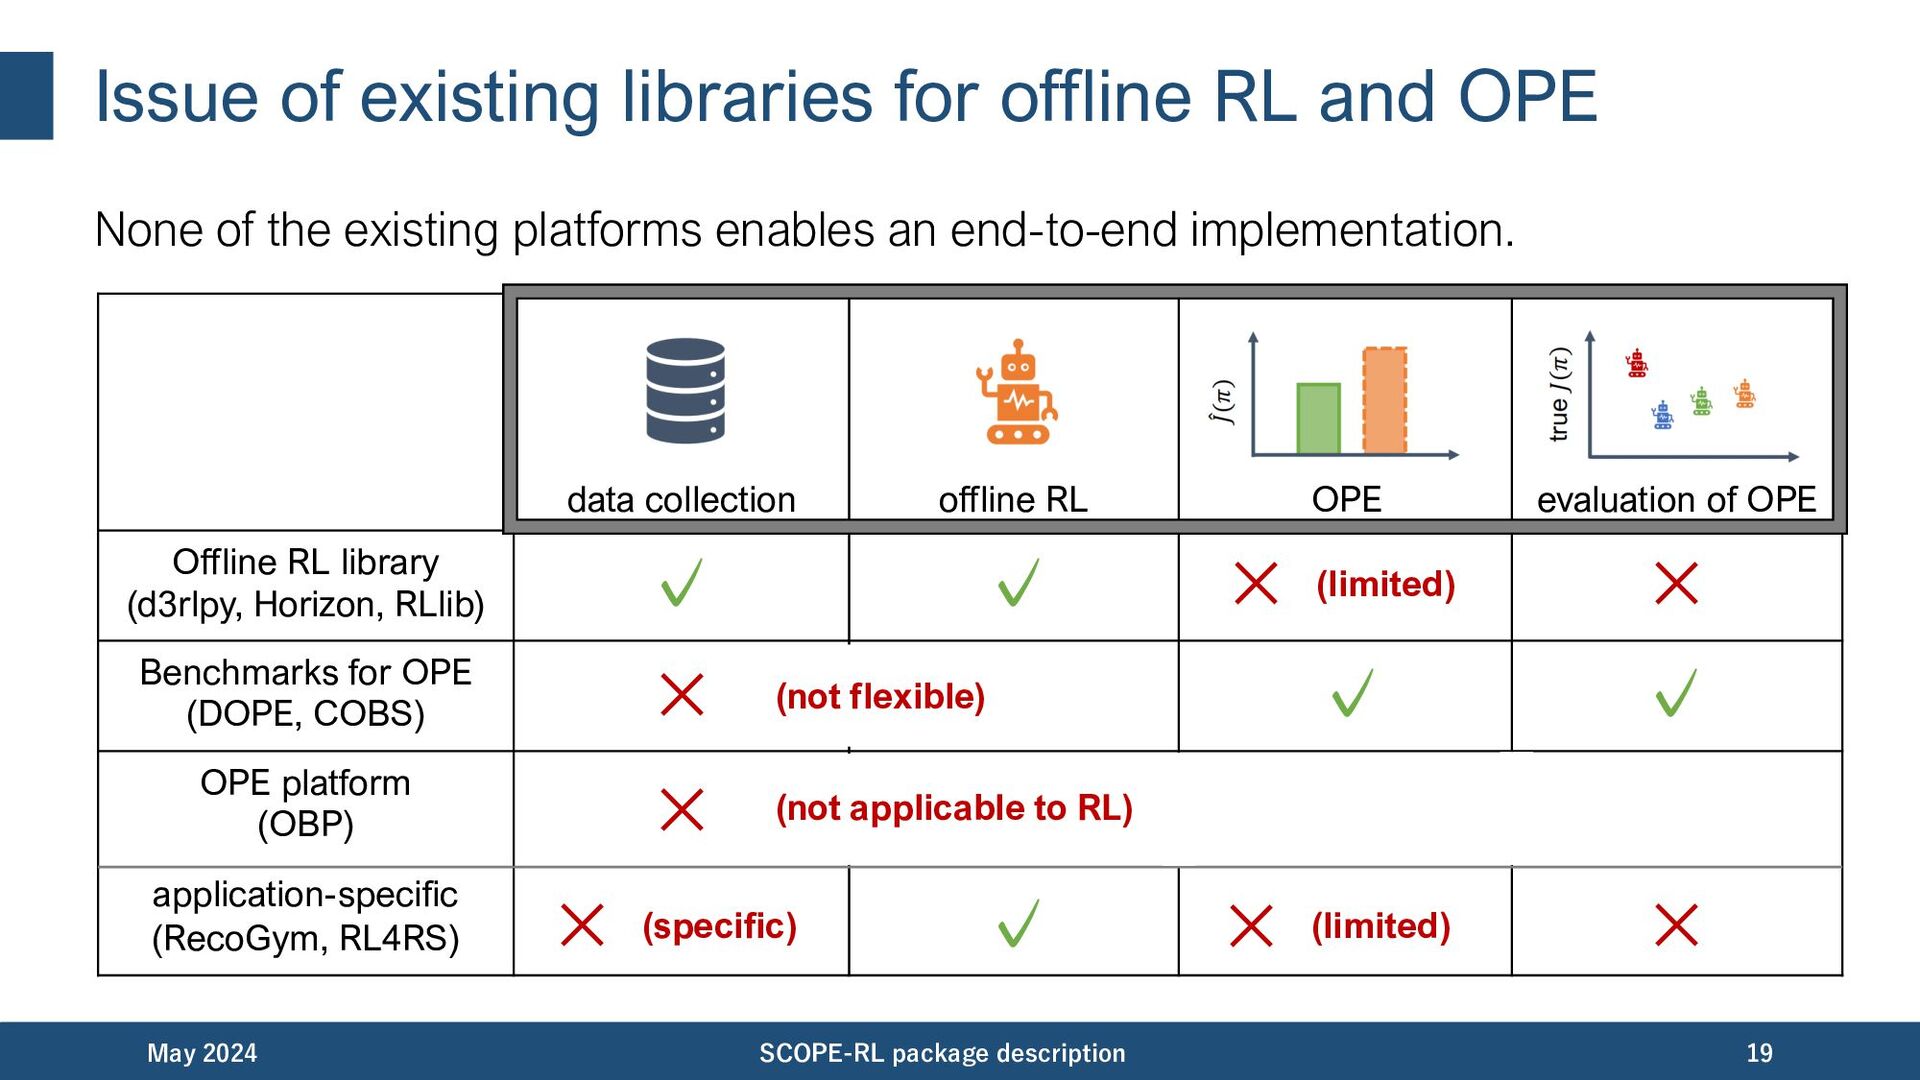
Issue of existing libraries for offline RL and OPE None
of the existing platforms enables an end-to-end implementation. May 2024 SCOPE-RL package description 19 Offline RL library (d3rlpy, Horizon, RLlib) Benchmarks for OPE (DOPE, COBS) OPE platform (OBP) application-specific (RecoGym, RL4RS) evaluation of OPE OPE offline RL data collection ✓ ✓ × (limited) × × ✓ ✓ × × (specific) ✓ × (limited) × (not flexible) (not applicable to RL) -
Issue of existing libraries for offline RL and OPE Particularly,
only a few libraries support OPE implementations. May 2024 SCOPE-RL package description 20 Offline RL library (d3rlpy, Horizon, RLlib) Benchmarks for OPE (DOPE, COBS) OPE platform (OBP) application-specific (RecoGym, RL4RS) evaluation of OPE OPE offline RL data collection ✓ ✓ × (limited) × × ✓ ✓ × × (specific) ✓ × (limited) × × (not flexible) (not applicable to RL) -
Key features of SCOPE-RL May 2024 SCOPE-RL package description 21
What is distinctive about SCOPE-RL? -
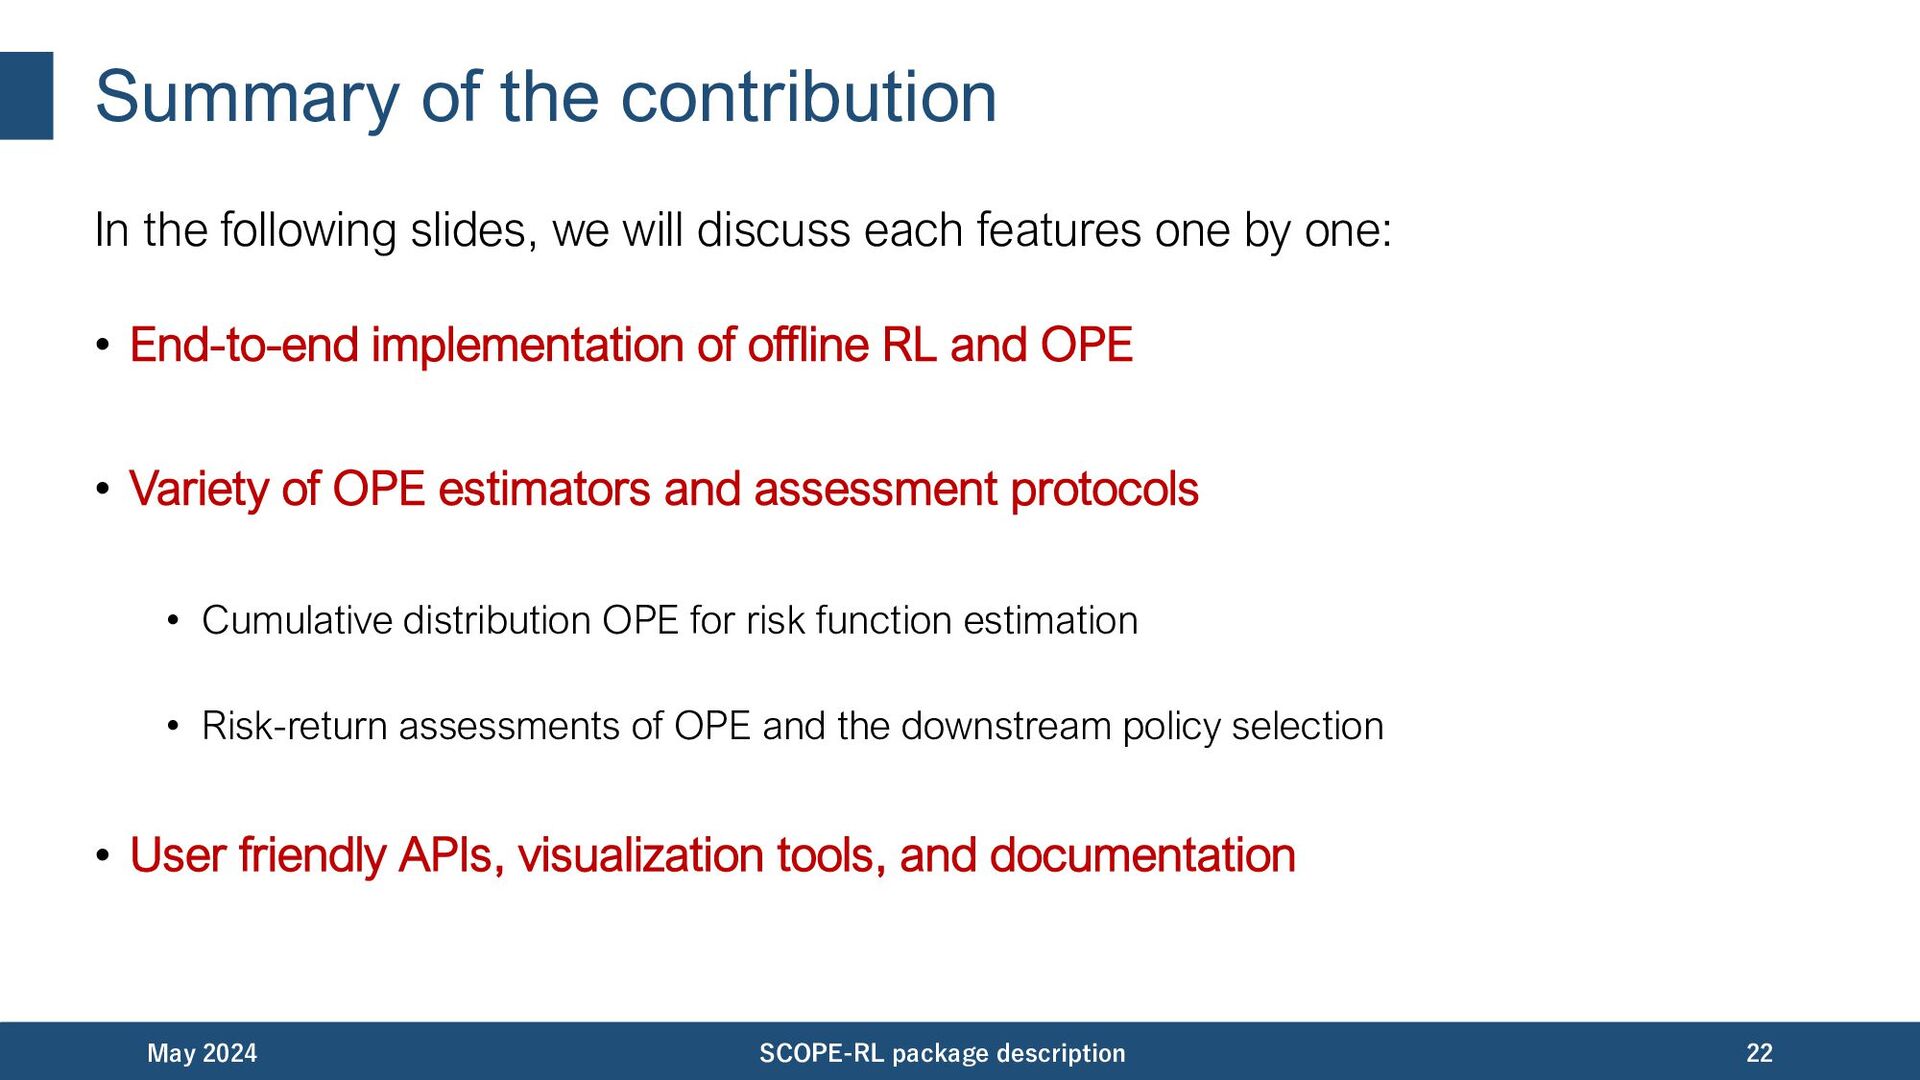
Summary of the contribution In the following slides, we will
discuss each features one by one: • End-to-end implementation of offline RL and OPE • Variety of OPE estimators and assessment protocols • Cumulative distribution OPE for risk function estimation • Risk-return assessments of OPE and the downstream policy selection • User friendly APIs, visualization tools, and documentation May 2024 SCOPE-RL package description 22 -
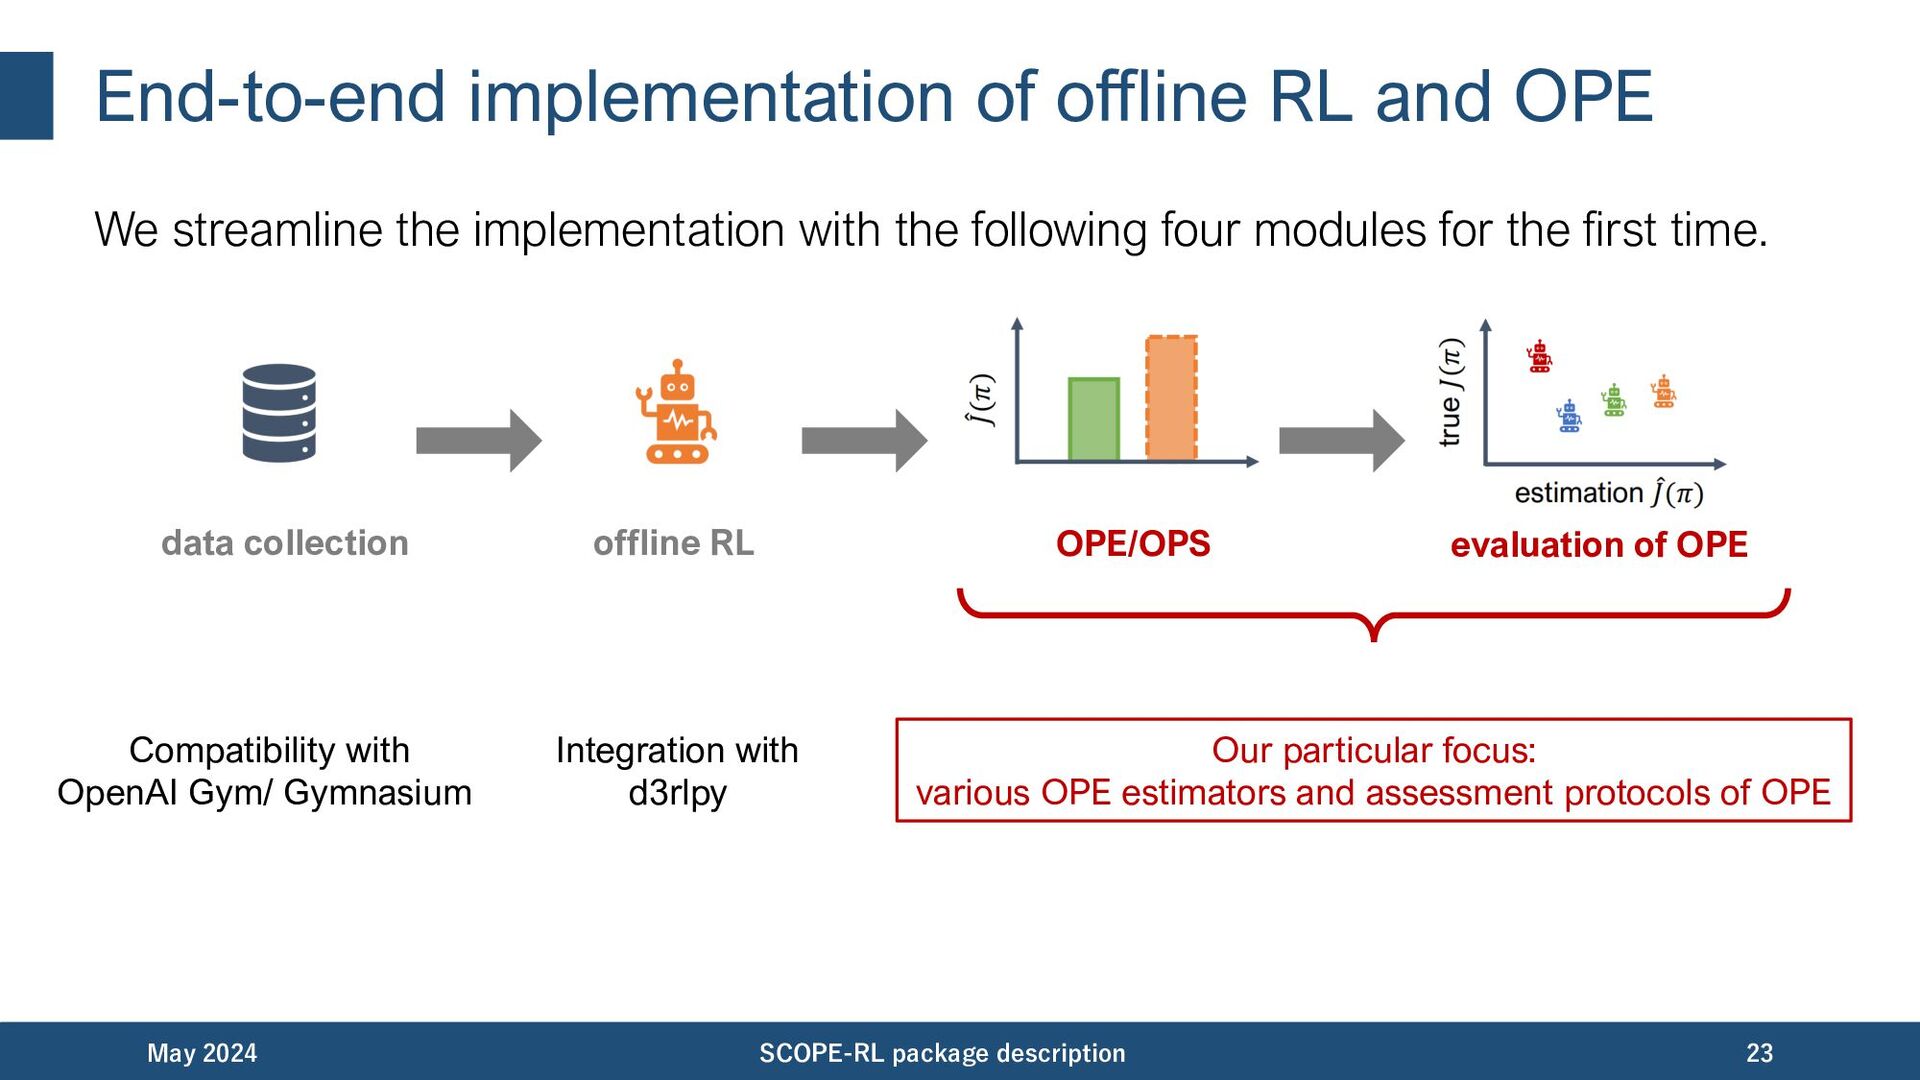
End-to-end implementation of offline RL and OPE We streamline the
implementation with the following four modules for the first time. May 2024 SCOPE-RL package description 23 data collection offline RL OPE/OPS evaluation of OPE Compatibility with OpenAI Gym/ Gymnasium Integration with d3rlpy Our particular focus: various OPE estimators and assessment protocols of OPE -
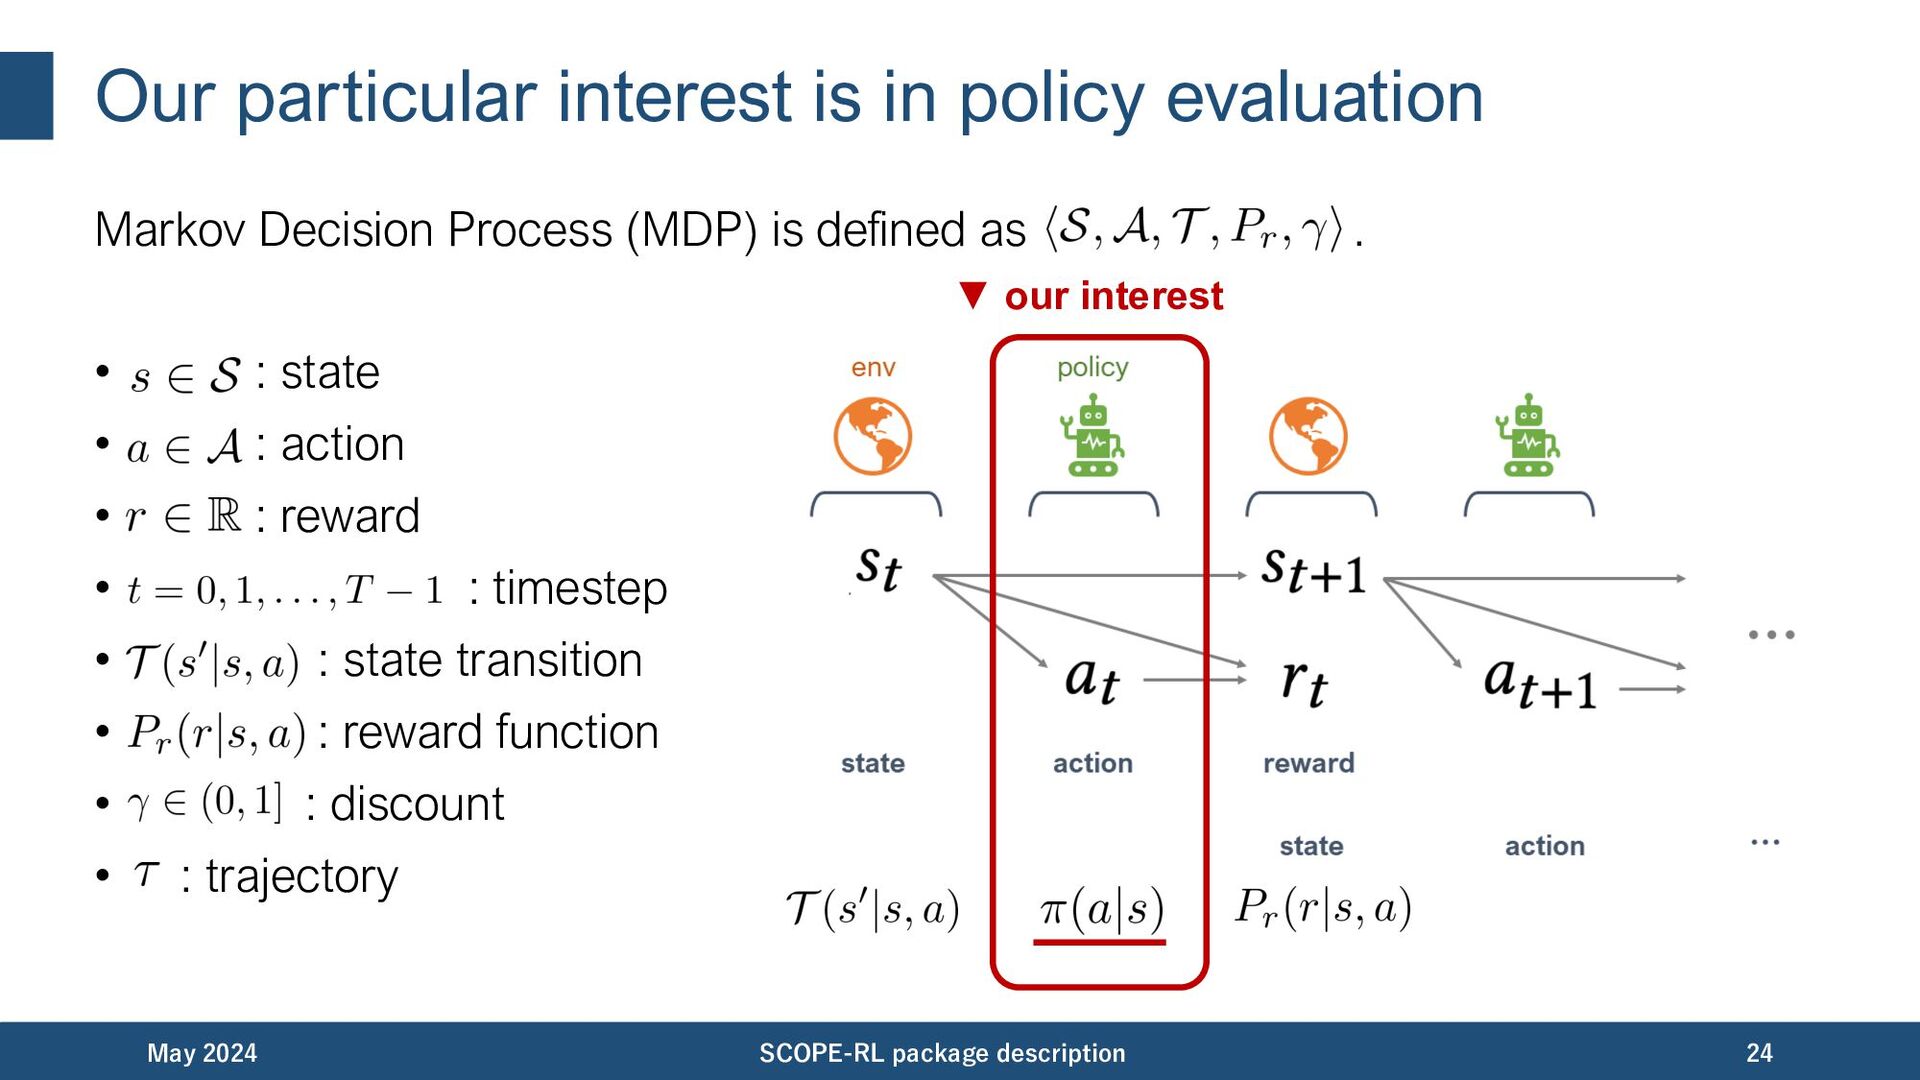
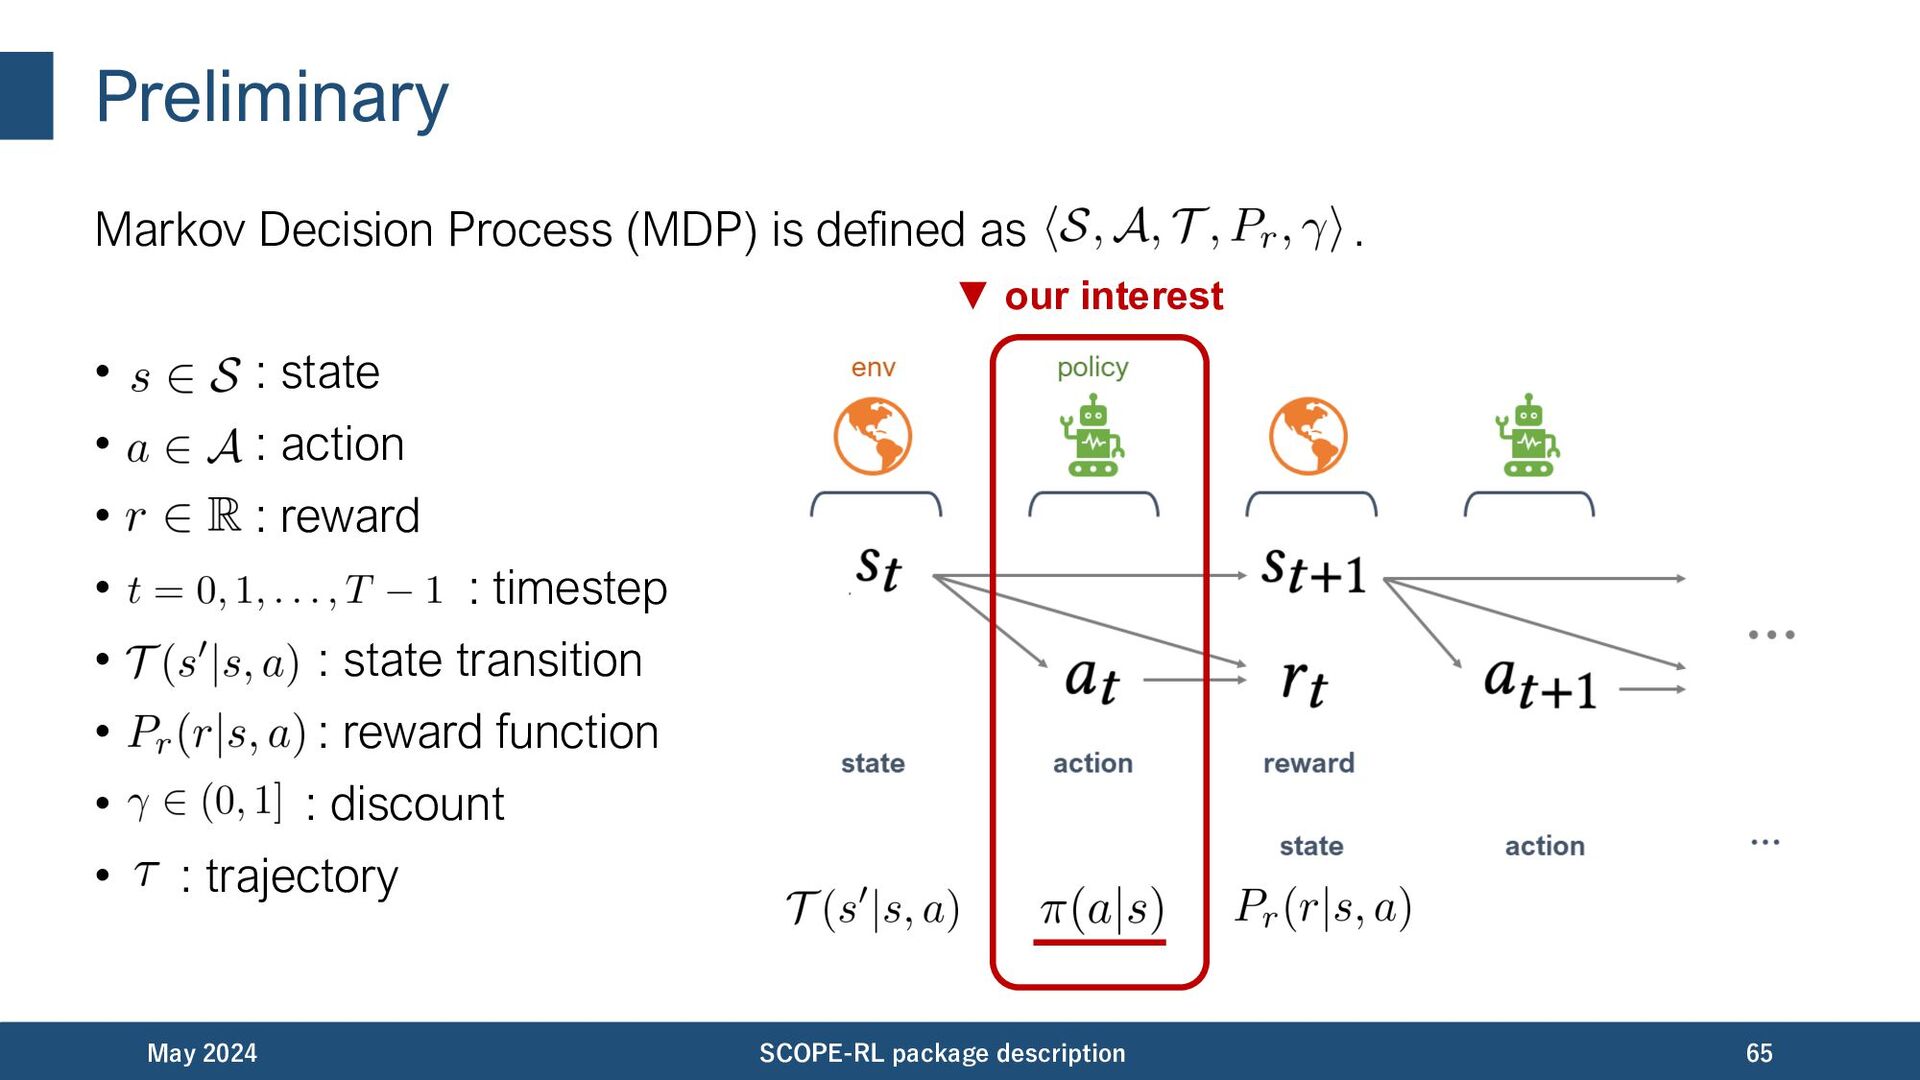
Our particular interest is in policy evaluation May 2024 SCOPE-RL
package description 24 Markov Decision Process (MDP) is defined as . • : state • : action • : reward • : timestep • : state transition • : reward function • : discount • : trajectory ▼ our interest -
Variety of OPE estimators and assessment protocols SCOPE-RL implements various
OPE estimators to estimate the expected rewards. • (Basic) Direct Method (DM) / Per-Decision Importance Sampling (PDIS) / Doubly Robust (DR) • (Advanced) State(-action) Marginal Importance Sampling (S(A)MIS) and Doubly Robust (S(A)MDR) / Double Reinforcement Learning (DRL) • (Options) Self-normalized estimators / Spectrum of OPE (SOPE) / kernel-based estimators for continuous actions May 2024 SCOPE-RL package description 25 See Appendix for the details. -
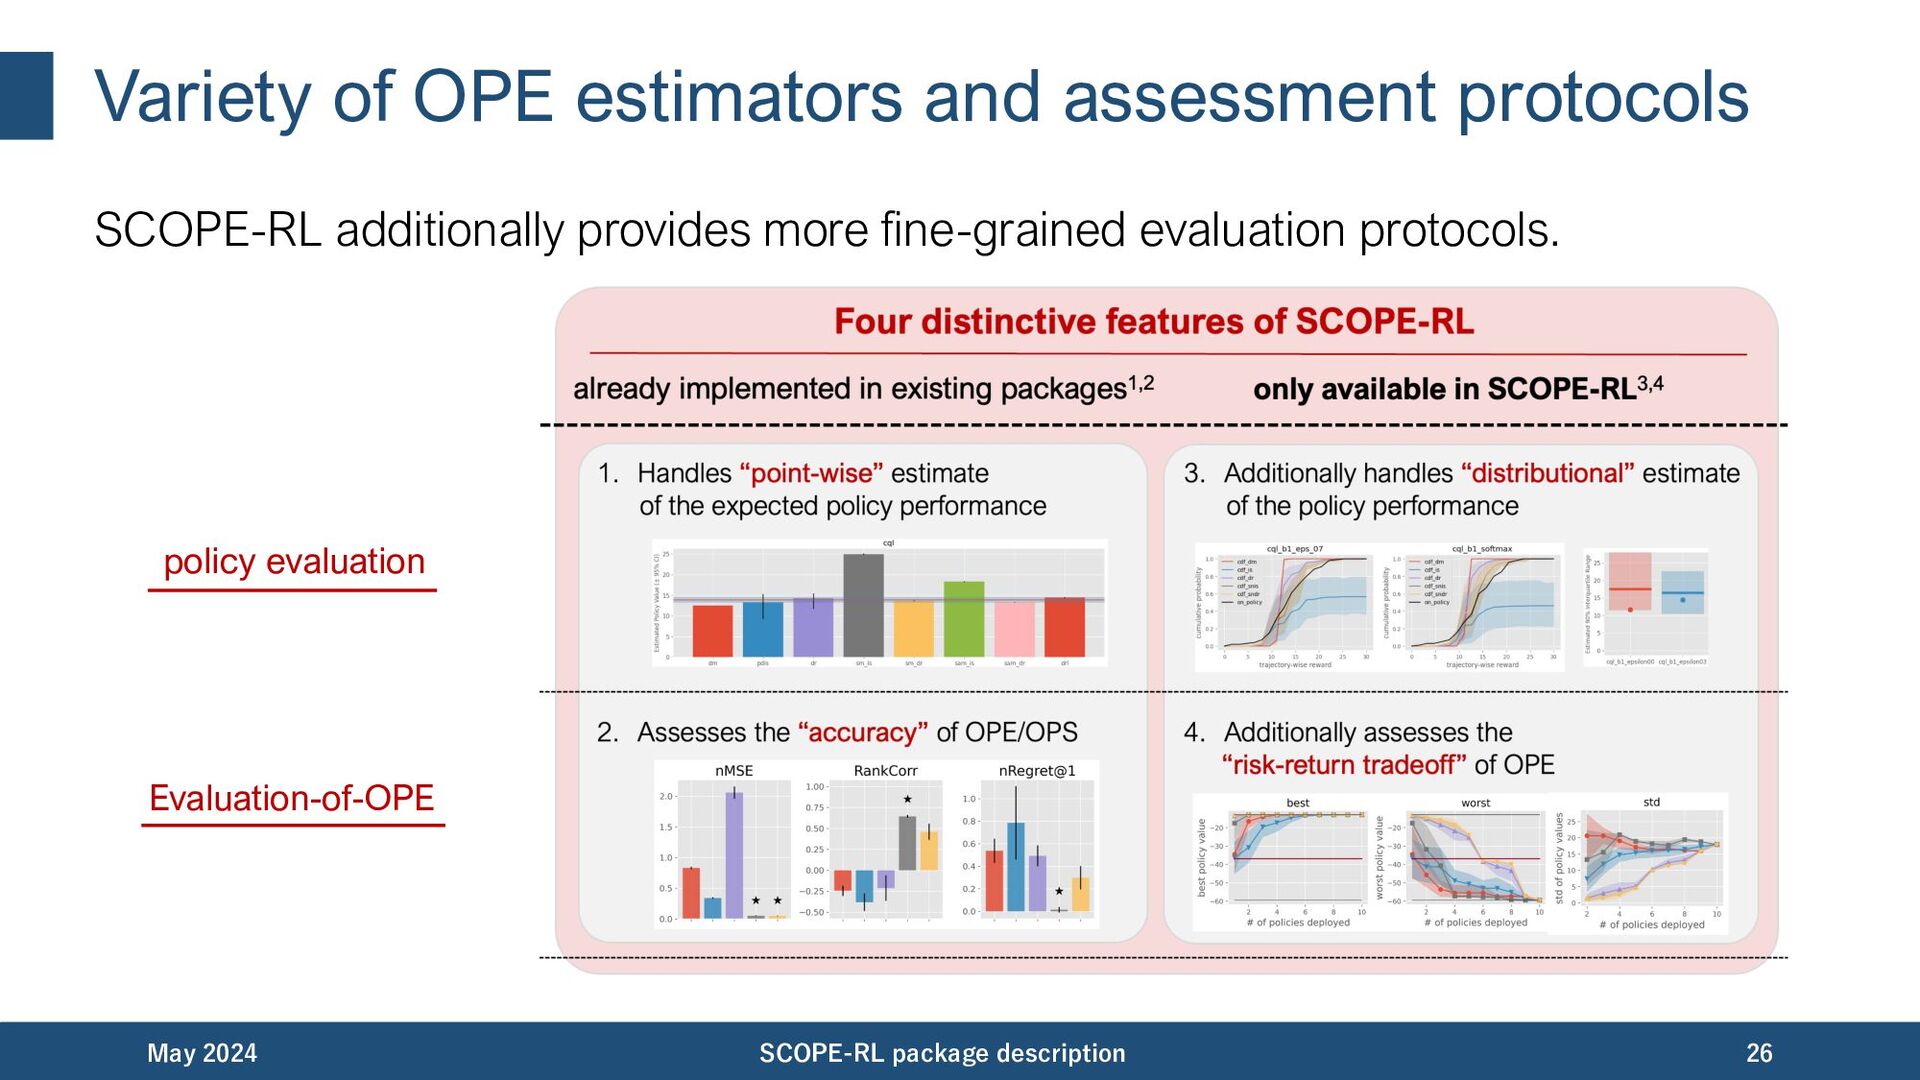
Variety of OPE estimators and assessment protocols SCOPE-RL additionally provides
more fine-grained evaluation protocols. May 2024 SCOPE-RL package description 26 policy evaluation Evaluation-of-OPE -
(1) Cumulative distribution OPE for risk function estim. Cumlative distribution
OPE (CD-OPE) estimates the whole performance distribution. May 2024 SCOPE-RL package description 27 𝐹(𝜋) reward threshold -
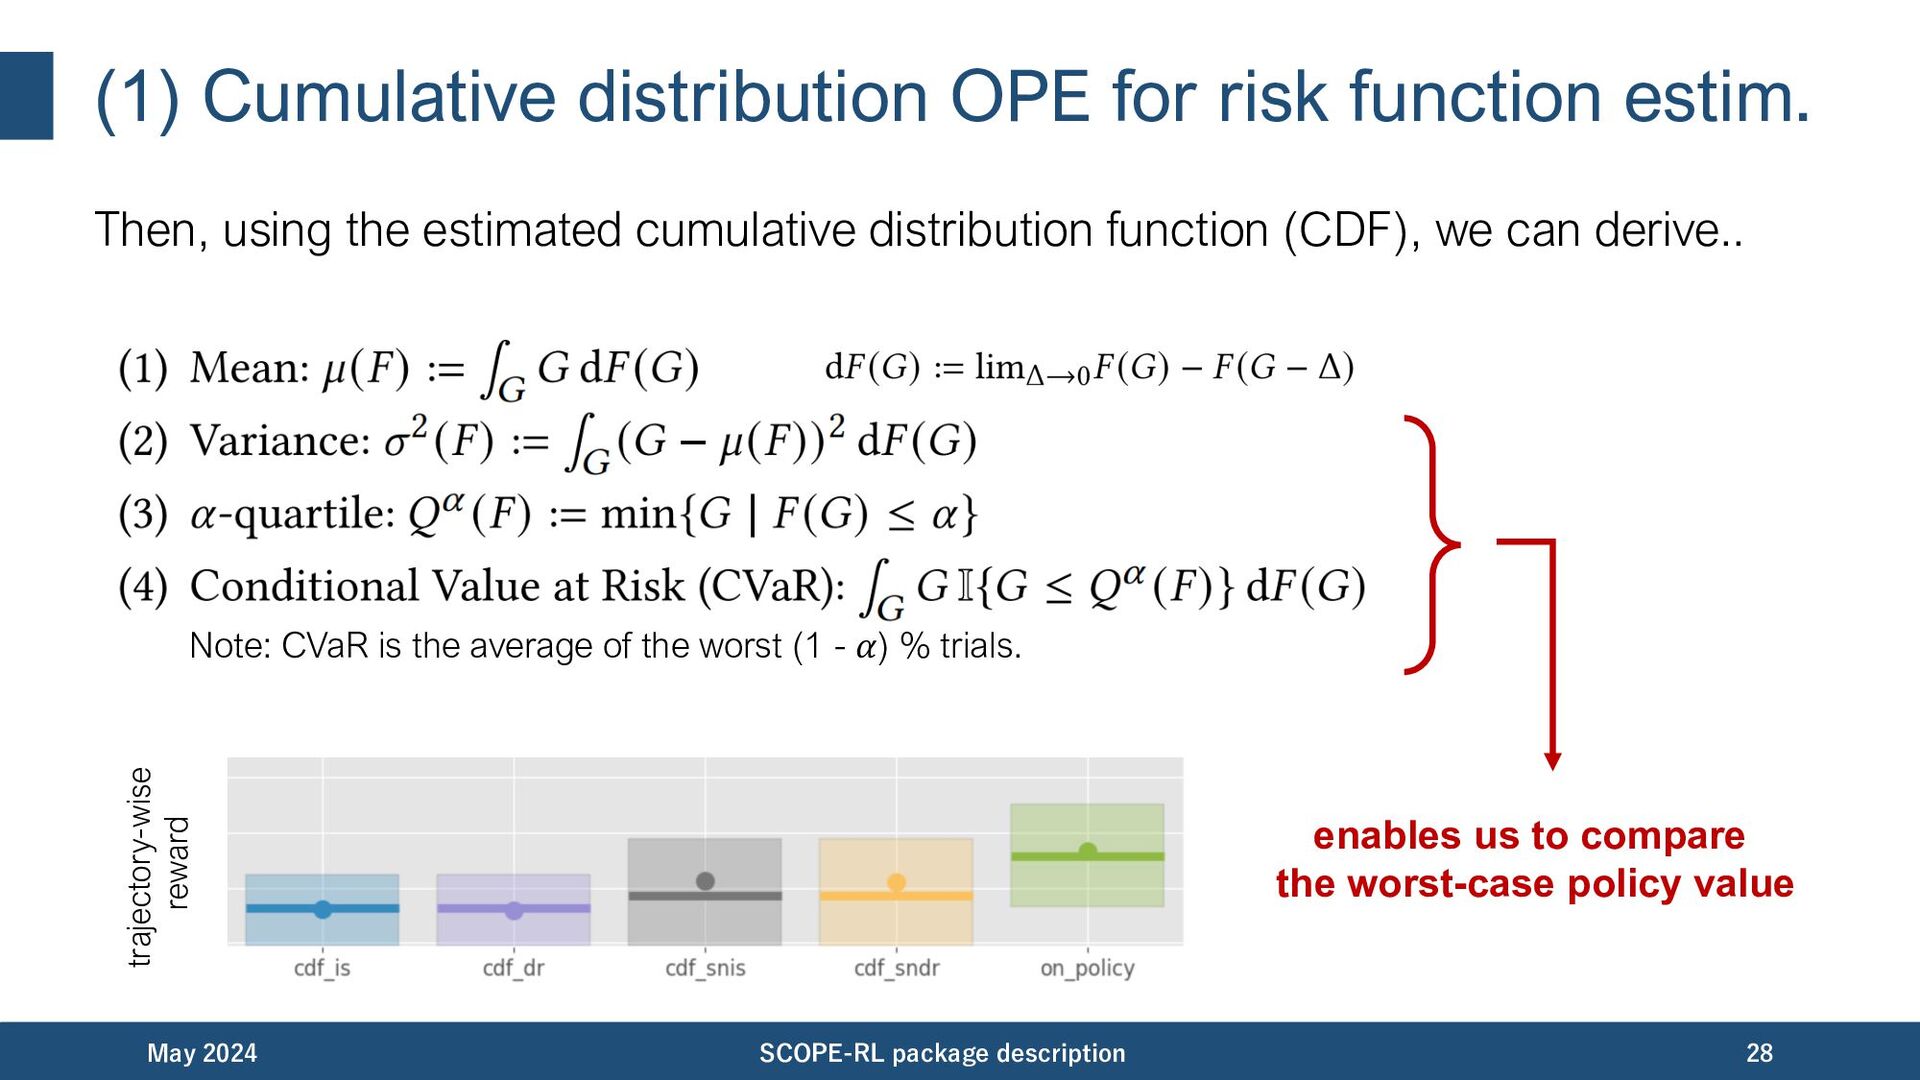
(1) Cumulative distribution OPE for risk function estim. Then, using
the estimated cumulative distribution function (CDF), we can derive.. May 2024 SCOPE-RL package description 28 enables us to compare the worst-case policy value trajectory-wise reward Note: CVaR is the average of the worst (1 - 𝛼) % trials. -
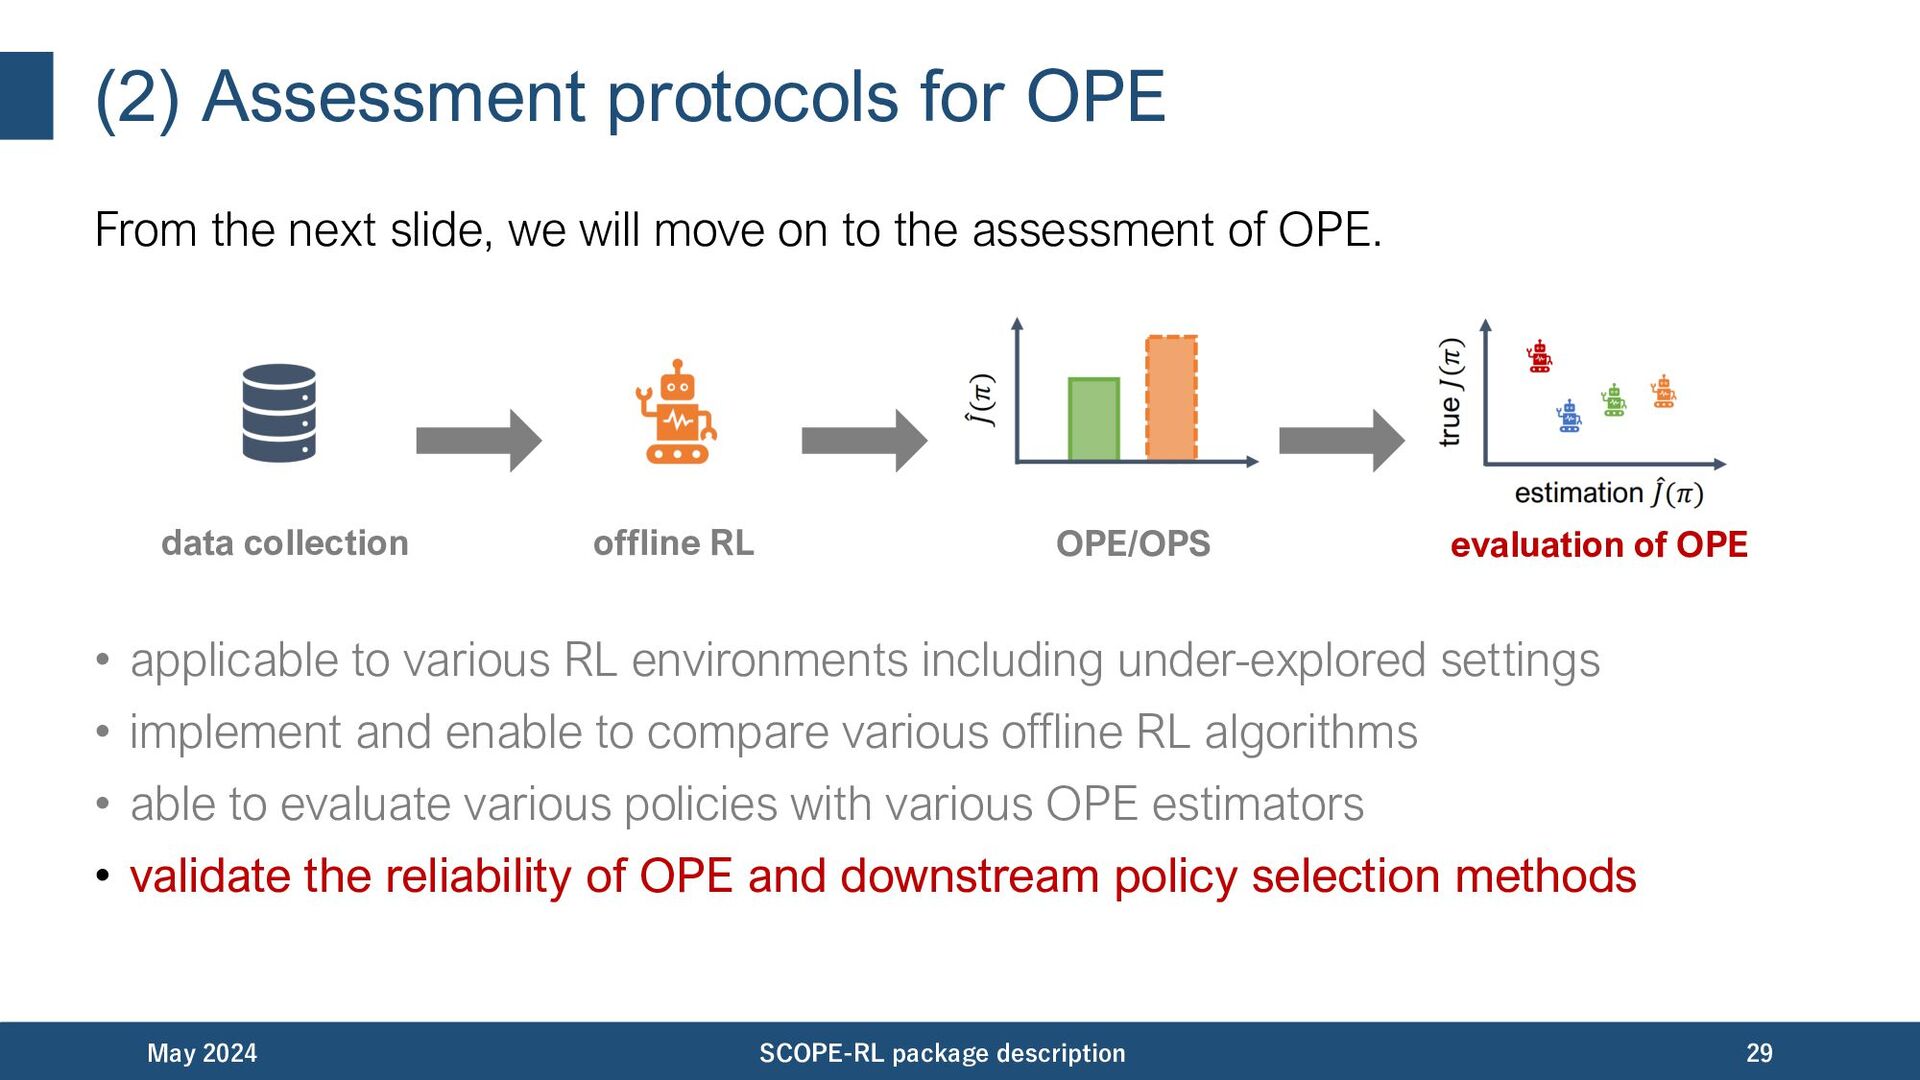
(2) Assessment protocols for OPE From the next slide, we
will move on to the assessment of OPE. • applicable to various RL environments including under-explored settings • implement and enable to compare various offline RL algorithms • able to evaluate various policies with various OPE estimators • validate the reliability of OPE and downstream policy selection methods May 2024 SCOPE-RL package description 29 data collection offline RL OPE/OPS evaluation of OPE -
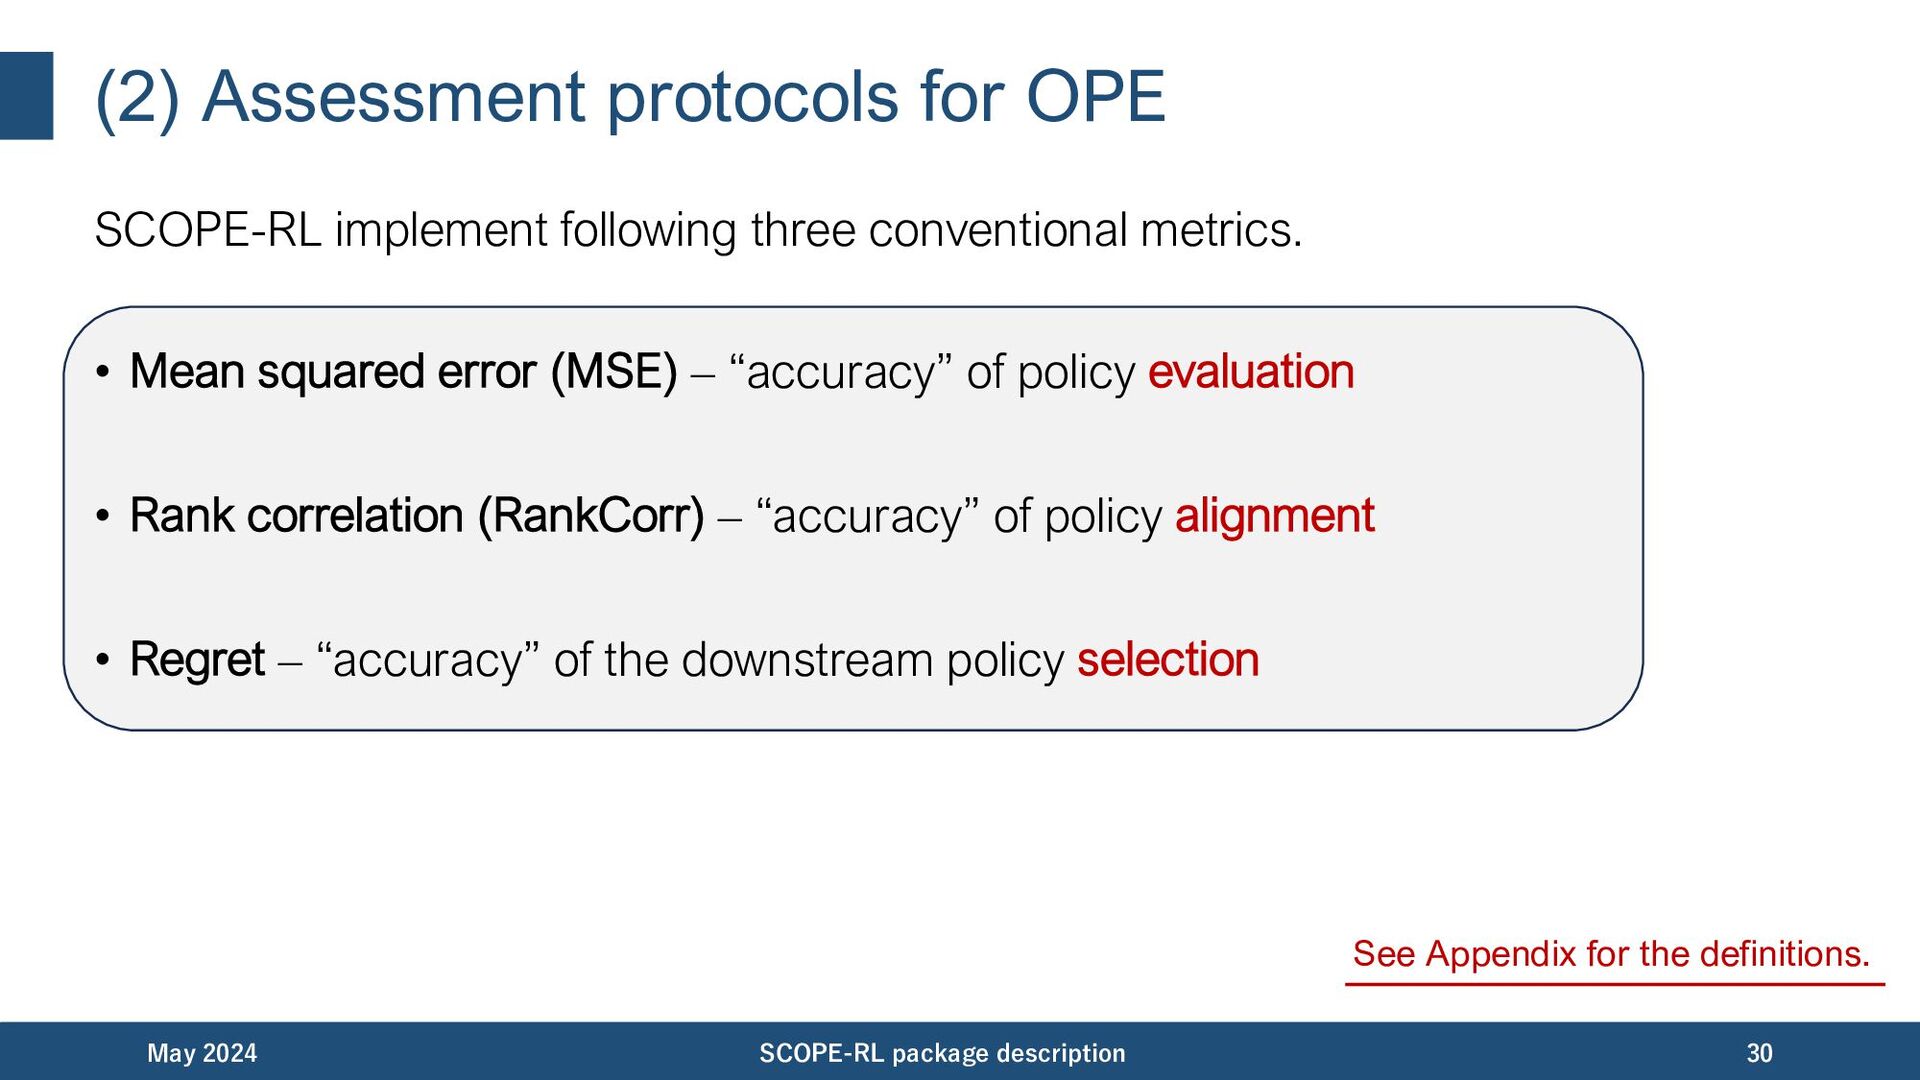
(2) Assessment protocols for OPE SCOPE-RL implement following three conventional
metrics. • Mean squared error (MSE) – “accuracy” of policy evaluation • Rank correlation (RankCorr) – “accuracy” of policy alignment • Regret – “accuracy” of the downstream policy selection May 2024 SCOPE-RL package description 30 See Appendix for the definitions. -
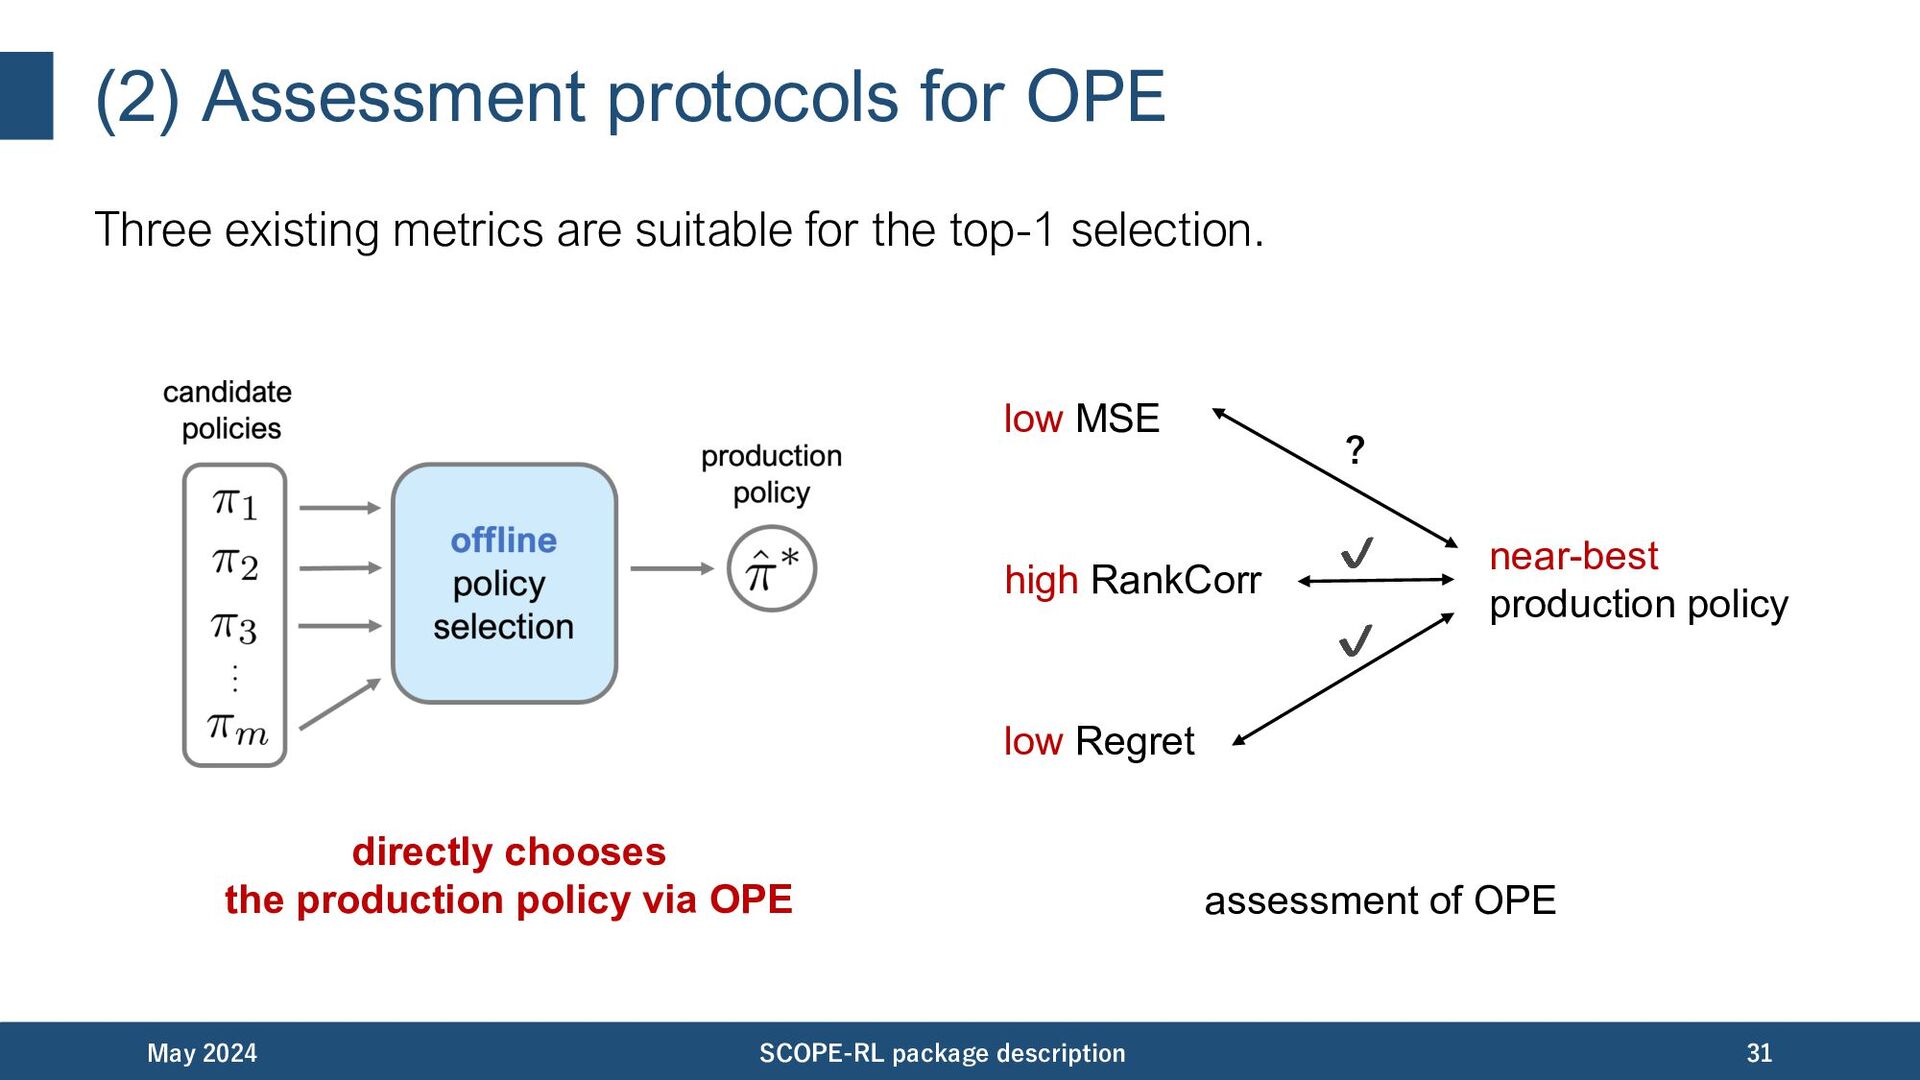
(2) Assessment protocols for OPE Three existing metrics are suitable
for the top-1 selection. May 2024 SCOPE-RL package description 31 directly chooses the production policy via OPE low MSE high RankCorr low Regret near-best production policy ? ✔ ✔ assessment of OPE -
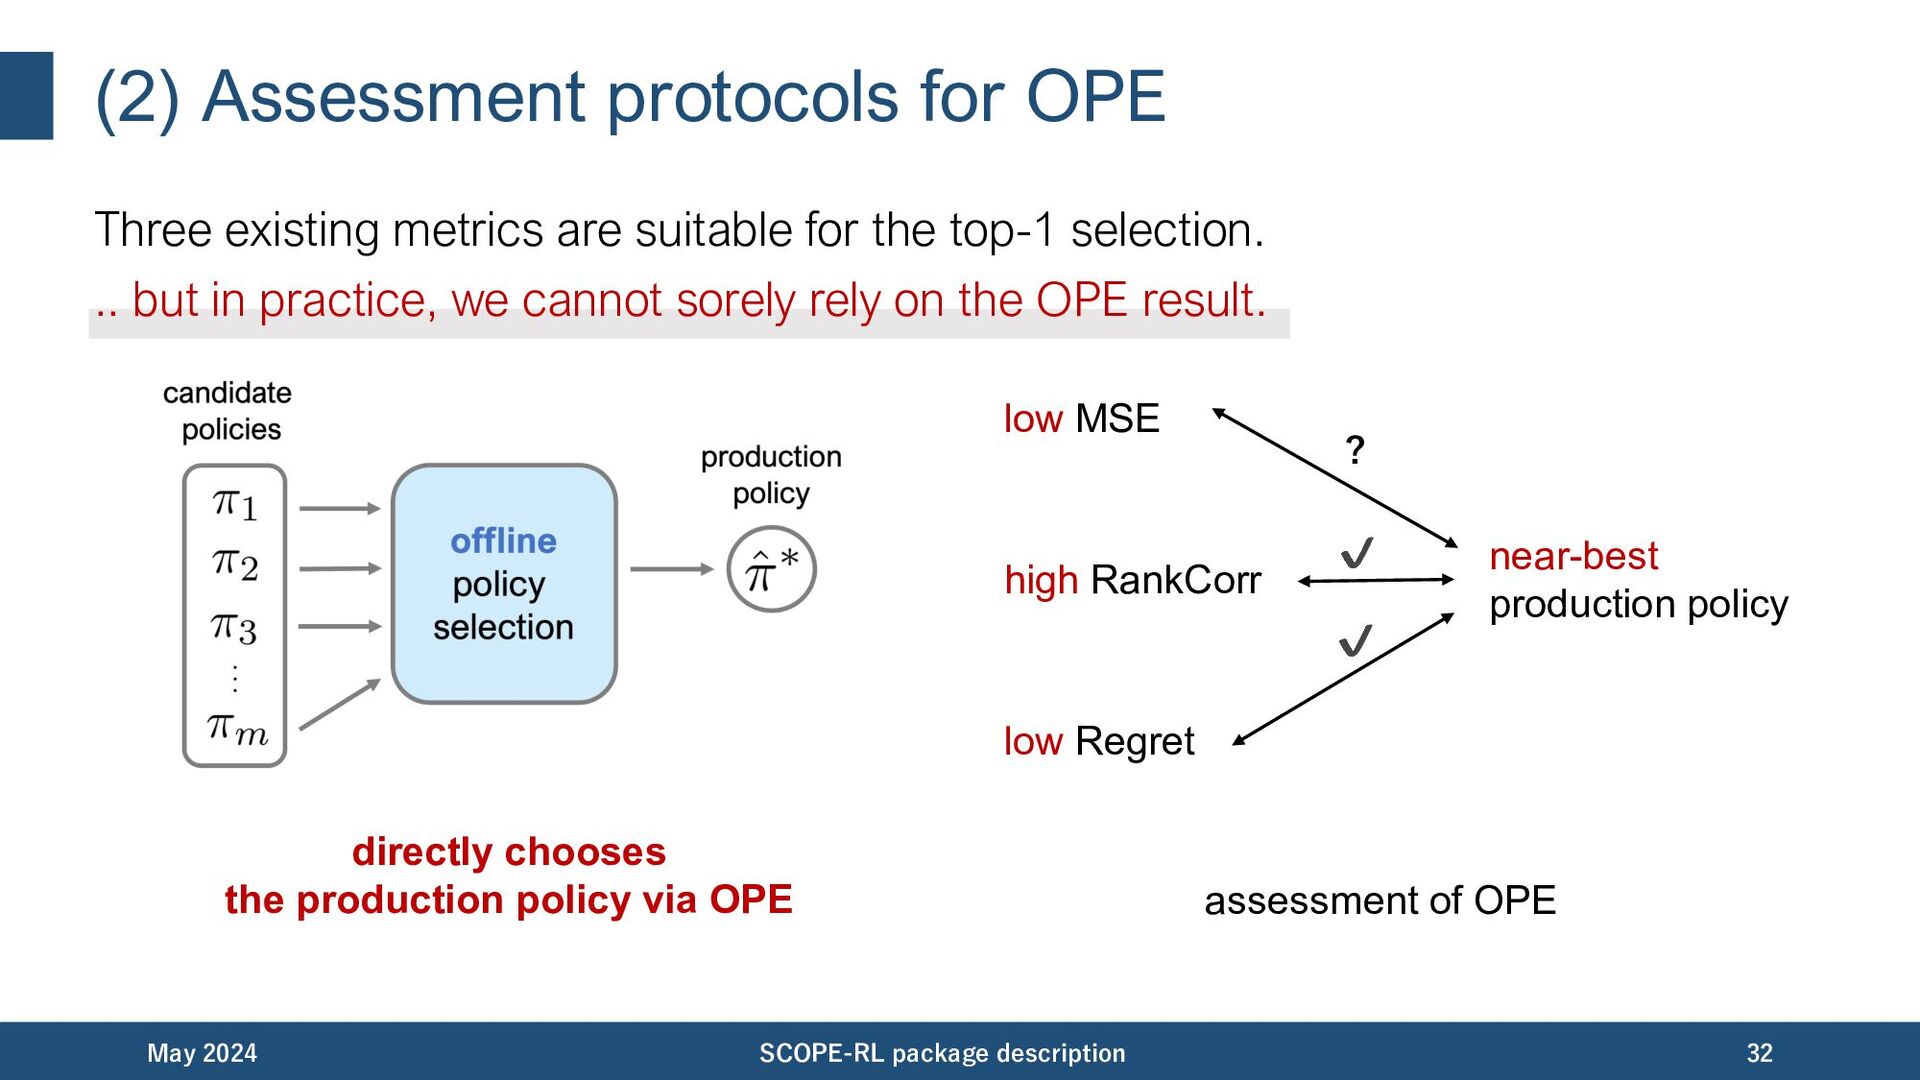
(2) Assessment protocols for OPE Three existing metrics are suitable
for the top-1 selection. .. but in practice, we cannot sorely rely on the OPE result. May 2024 SCOPE-RL package description 32 directly chooses the production policy via OPE low MSE high RankCorr low Regret near-best production policy ? ✔ ✔ assessment of OPE -
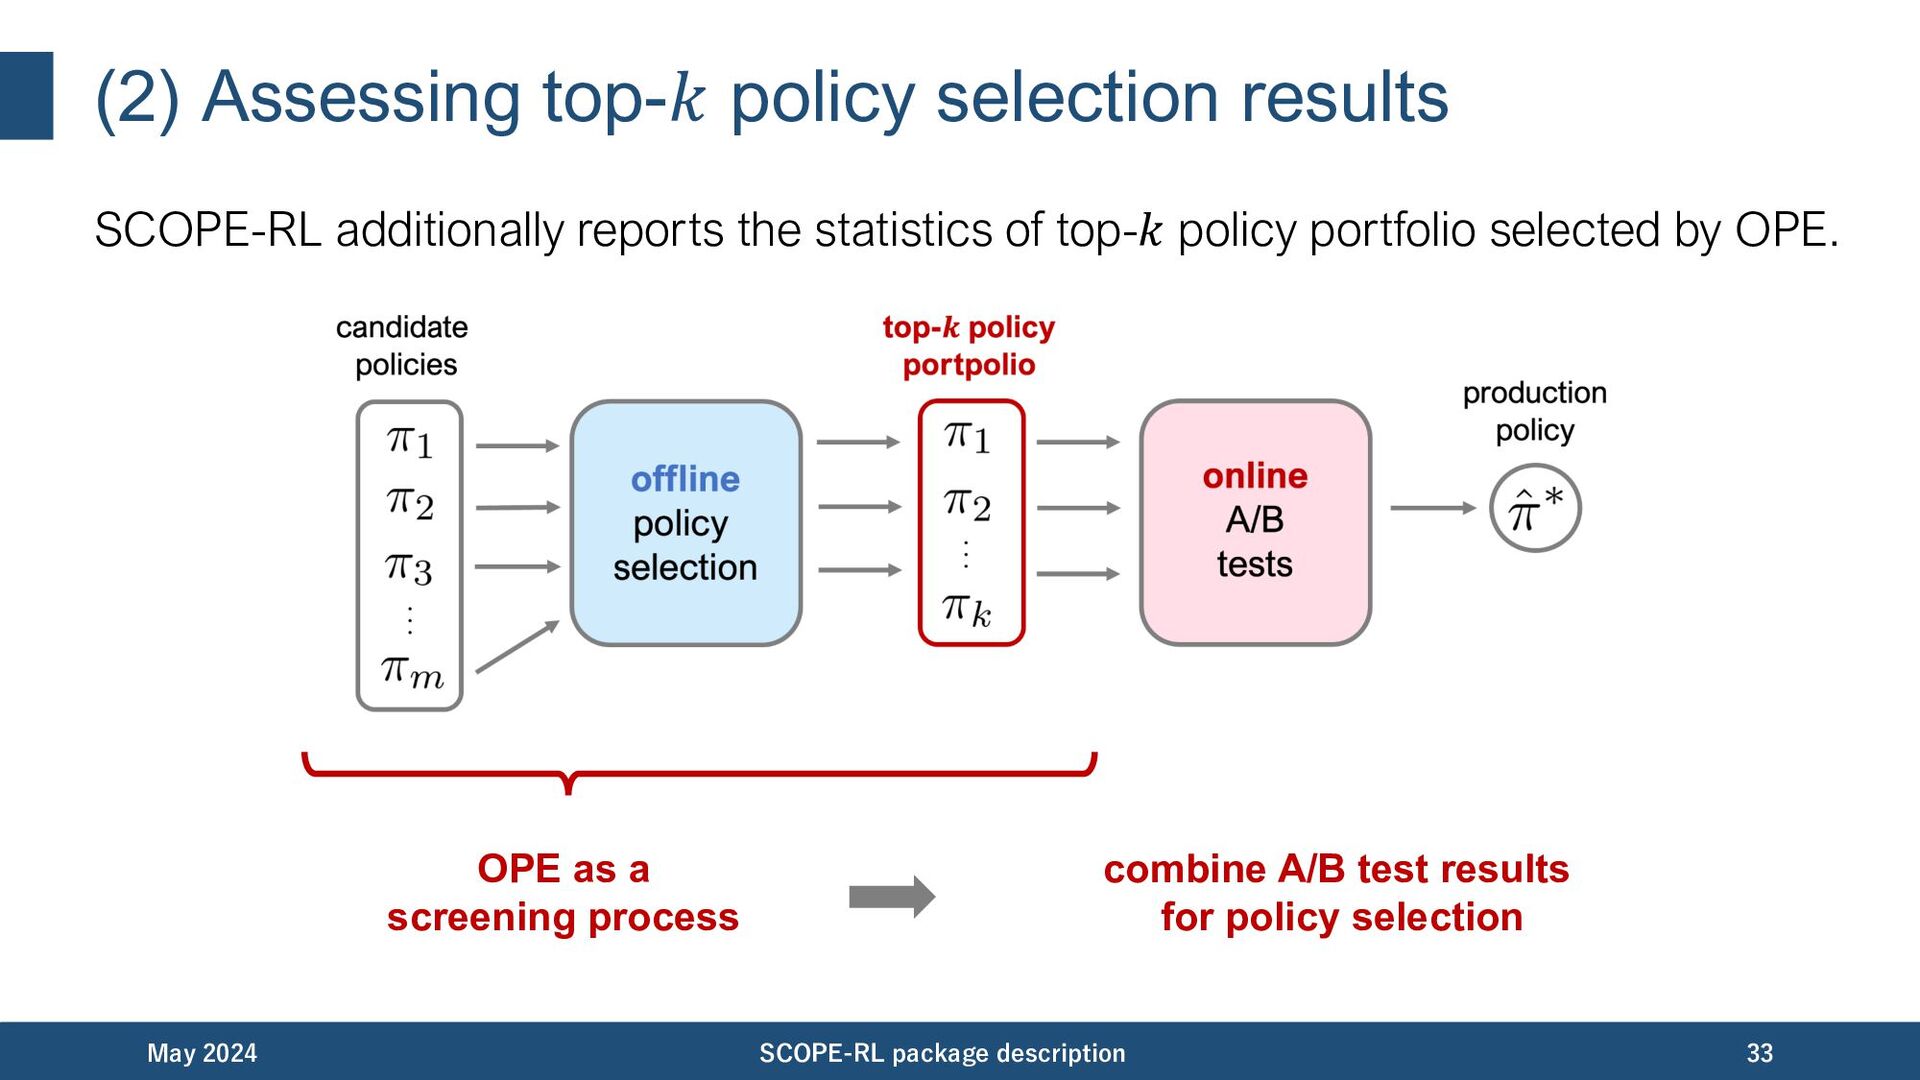
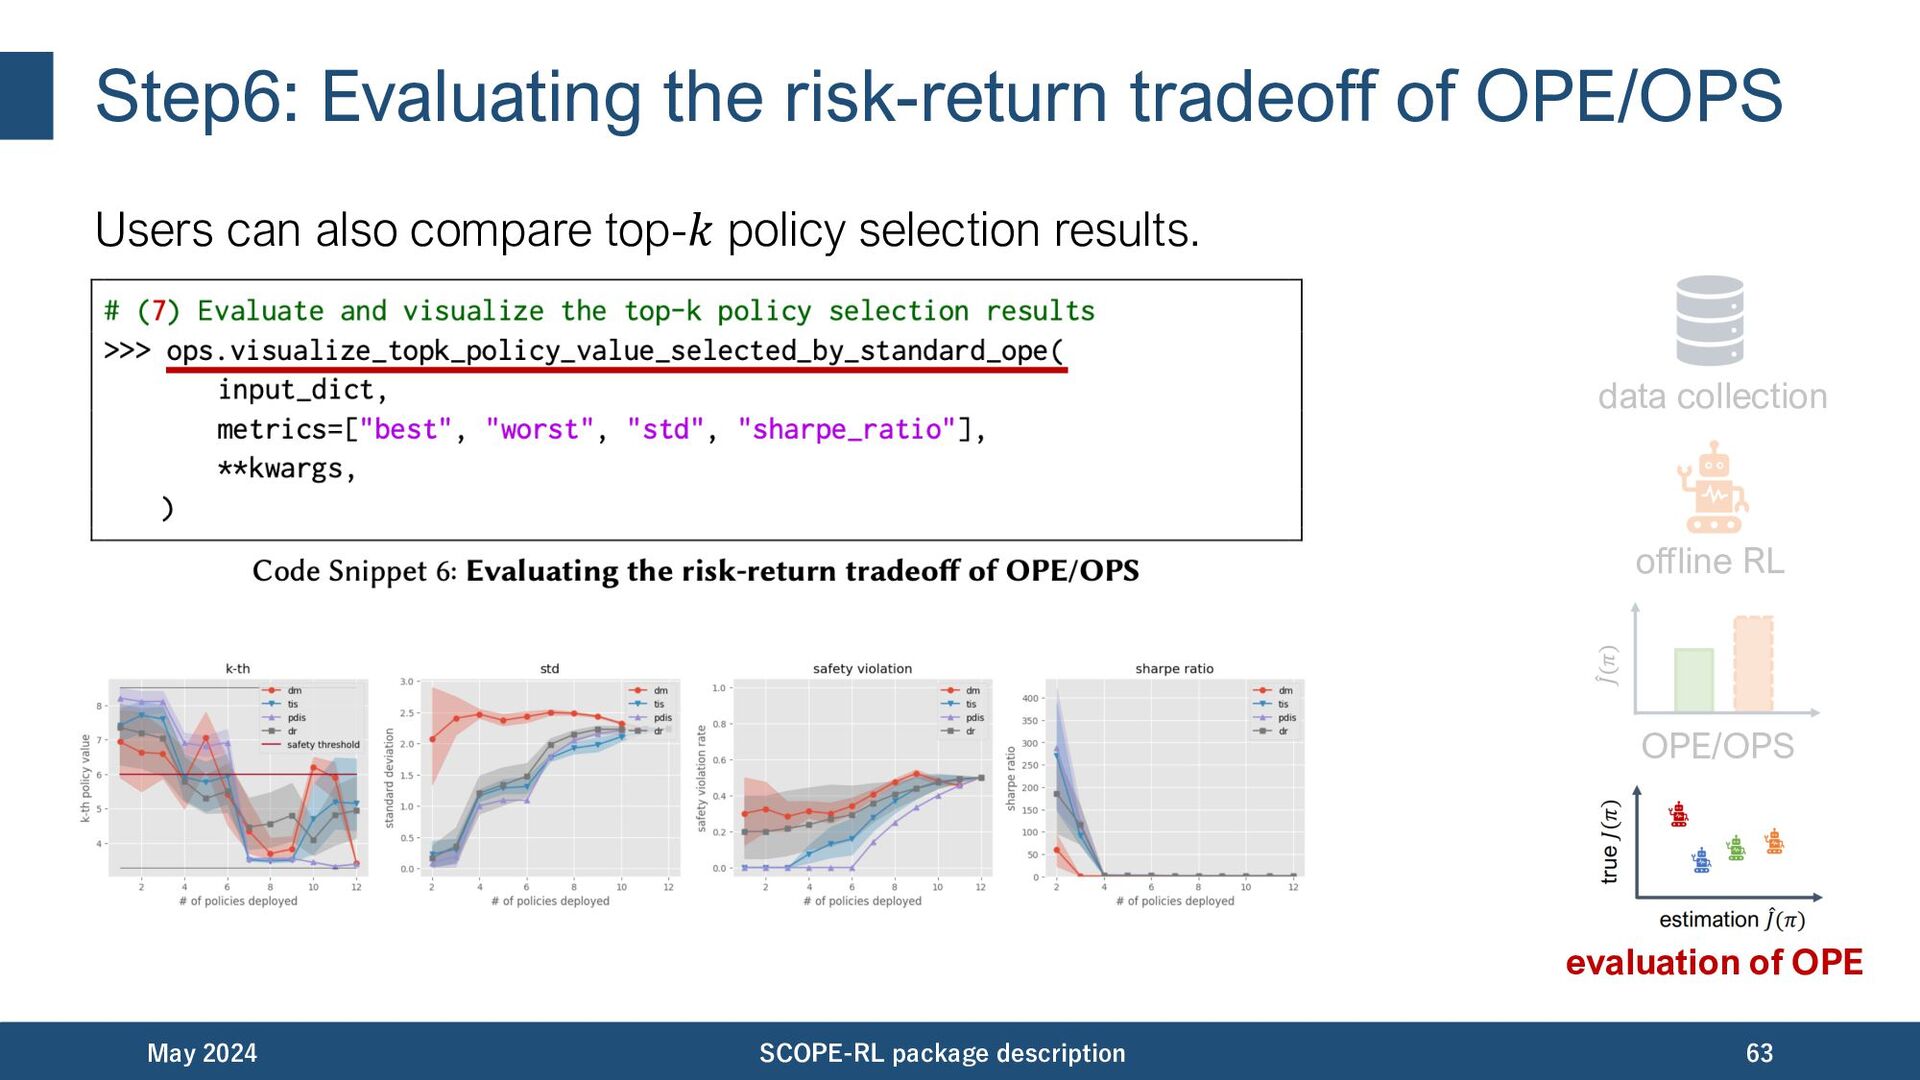
(2) Assessing top-𝑘 policy selection results SCOPE-RL additionally reports the
statistics of top-𝑘 policy portfolio selected by OPE. May 2024 SCOPE-RL package description 33 OPE as a screening process combine A/B test results for policy selection -
(2) Assessing top-𝑘 policy selection results SCOPE-RL additionally reports the
statistics of top-𝑘 policy portfolio selected by OPE. May 2024 SCOPE-RL package description 34 OPE as a screening process Assess risk-returns of online A/B tests via statistics of policy portfolio -
(2) Assessing top-𝑘 policy selection results SCOPE-RL additionally reports the
statistics of top-𝑘 policy portfolio selected by OPE. • best@𝑘 (return): measures the performance of the Lnal production policy. • worst@𝑘, mean@𝑘, std@𝑘, safety violation rate@𝑘 (risk): measures the risk of deploying poor-performing policies in online A/B tests. • SharpeRatio@k (ef]ciency): measures the return (best@𝑘) over the risk-free baseline (𝐽(𝜋𝑏 )), discounted by the risk of deploying poor policies (std@𝑘). May 2024 SCOPE-RL package description 35 See Appendix for the definitions. -
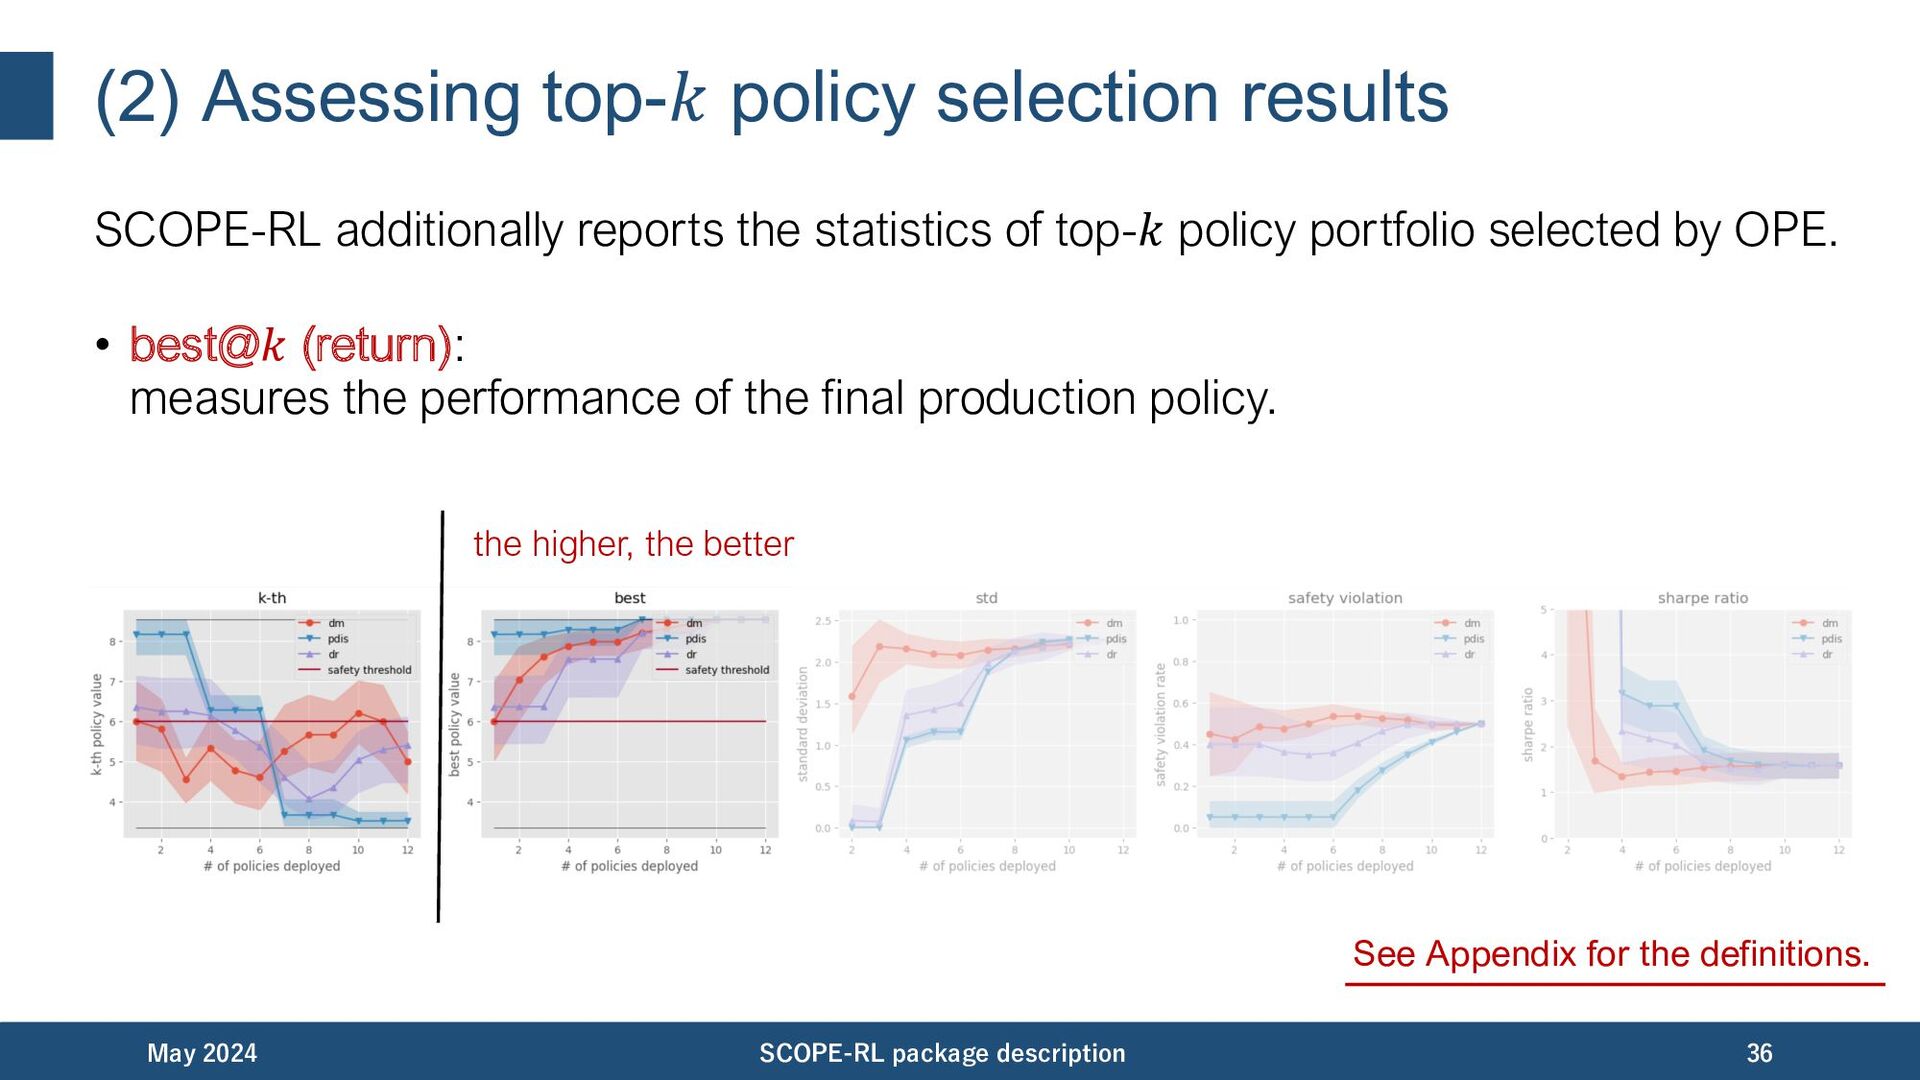
(2) Assessing top-𝑘 policy selection results SCOPE-RL additionally reports the
statistics of top-𝑘 policy portfolio selected by OPE. • best@𝑘 (return): measures the performance of the ]nal production policy. May 2024 SCOPE-RL package description 36 See Appendix for the definitions. the higher, the better -
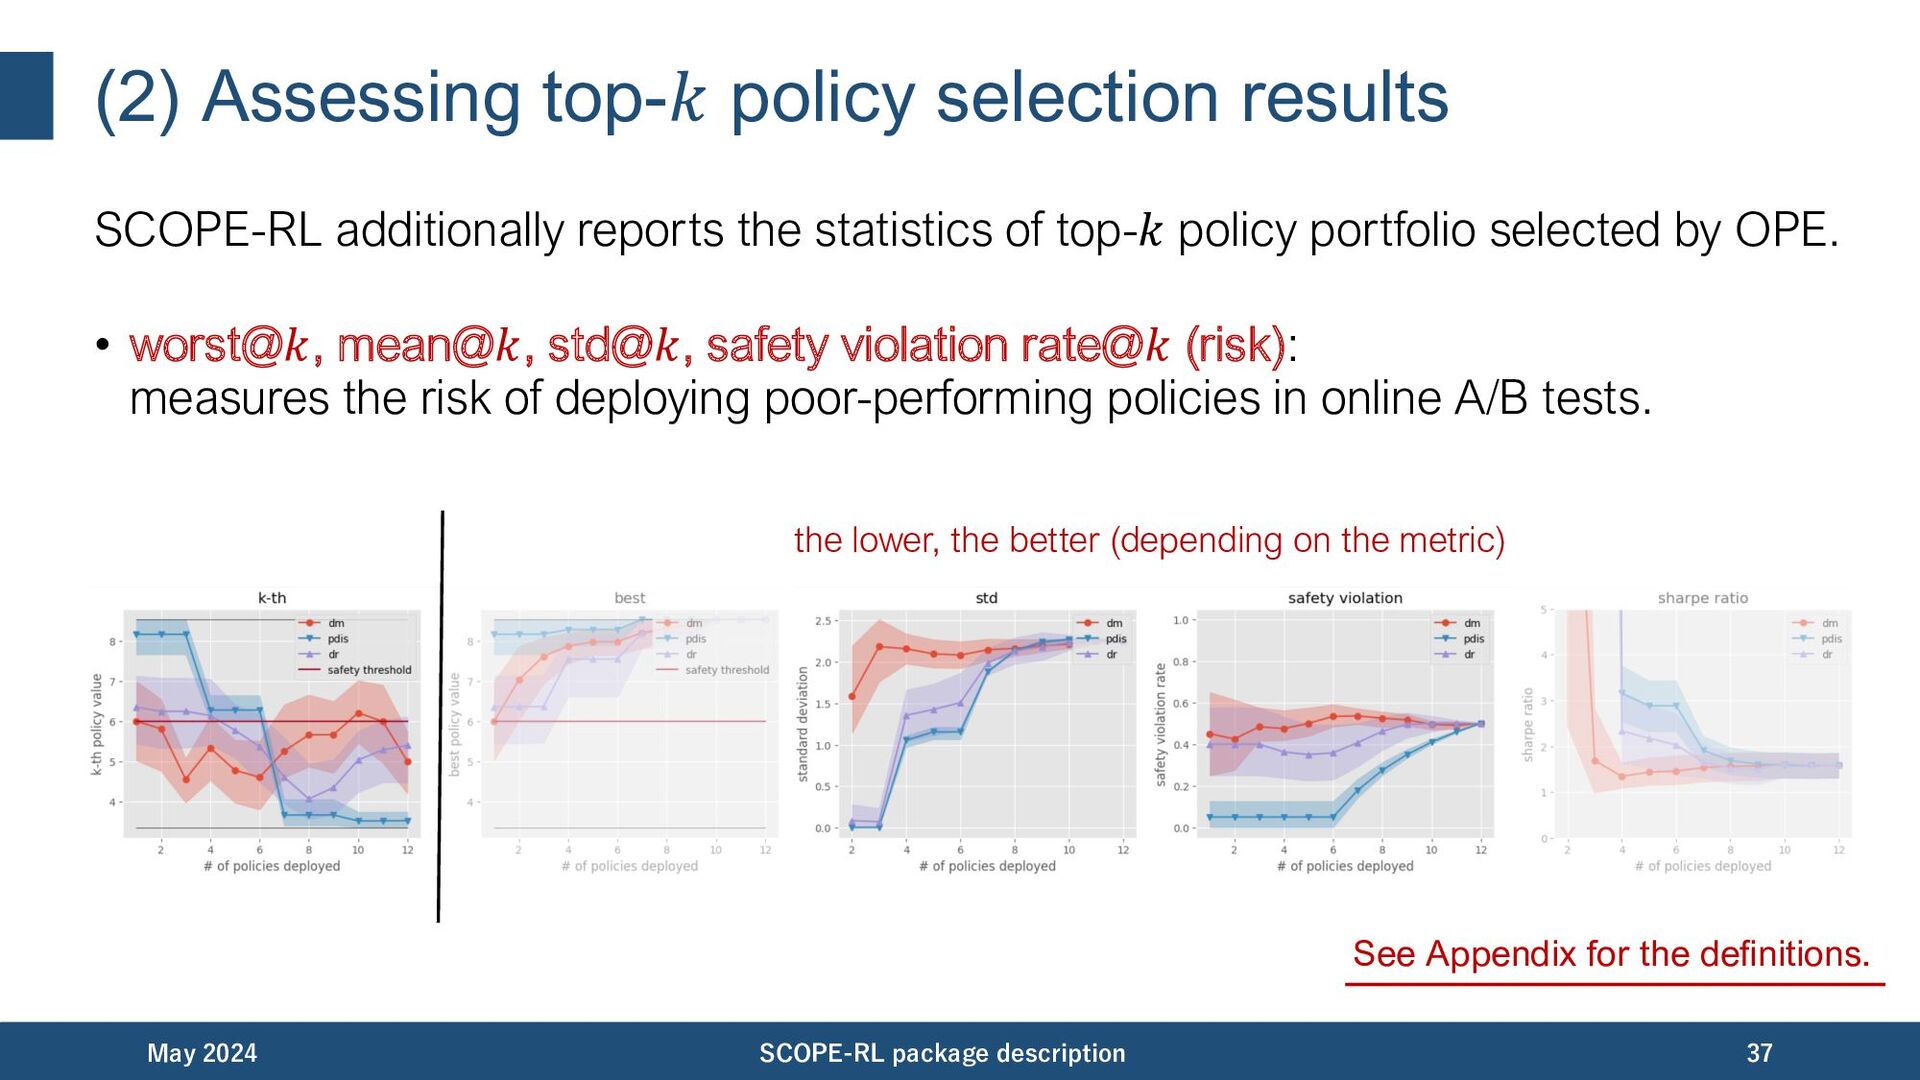
(2) Assessing top-𝑘 policy selection results SCOPE-RL additionally reports the
statistics of top-𝑘 policy portfolio selected by OPE. • worst@𝑘, mean@𝑘, std@𝑘, safety violation rate@𝑘 (risk): measures the risk of deploying poor-performing policies in online A/B tests. May 2024 SCOPE-RL package description 37 See Appendix for the dePnitions. the lower, the better (depending on the metric) -
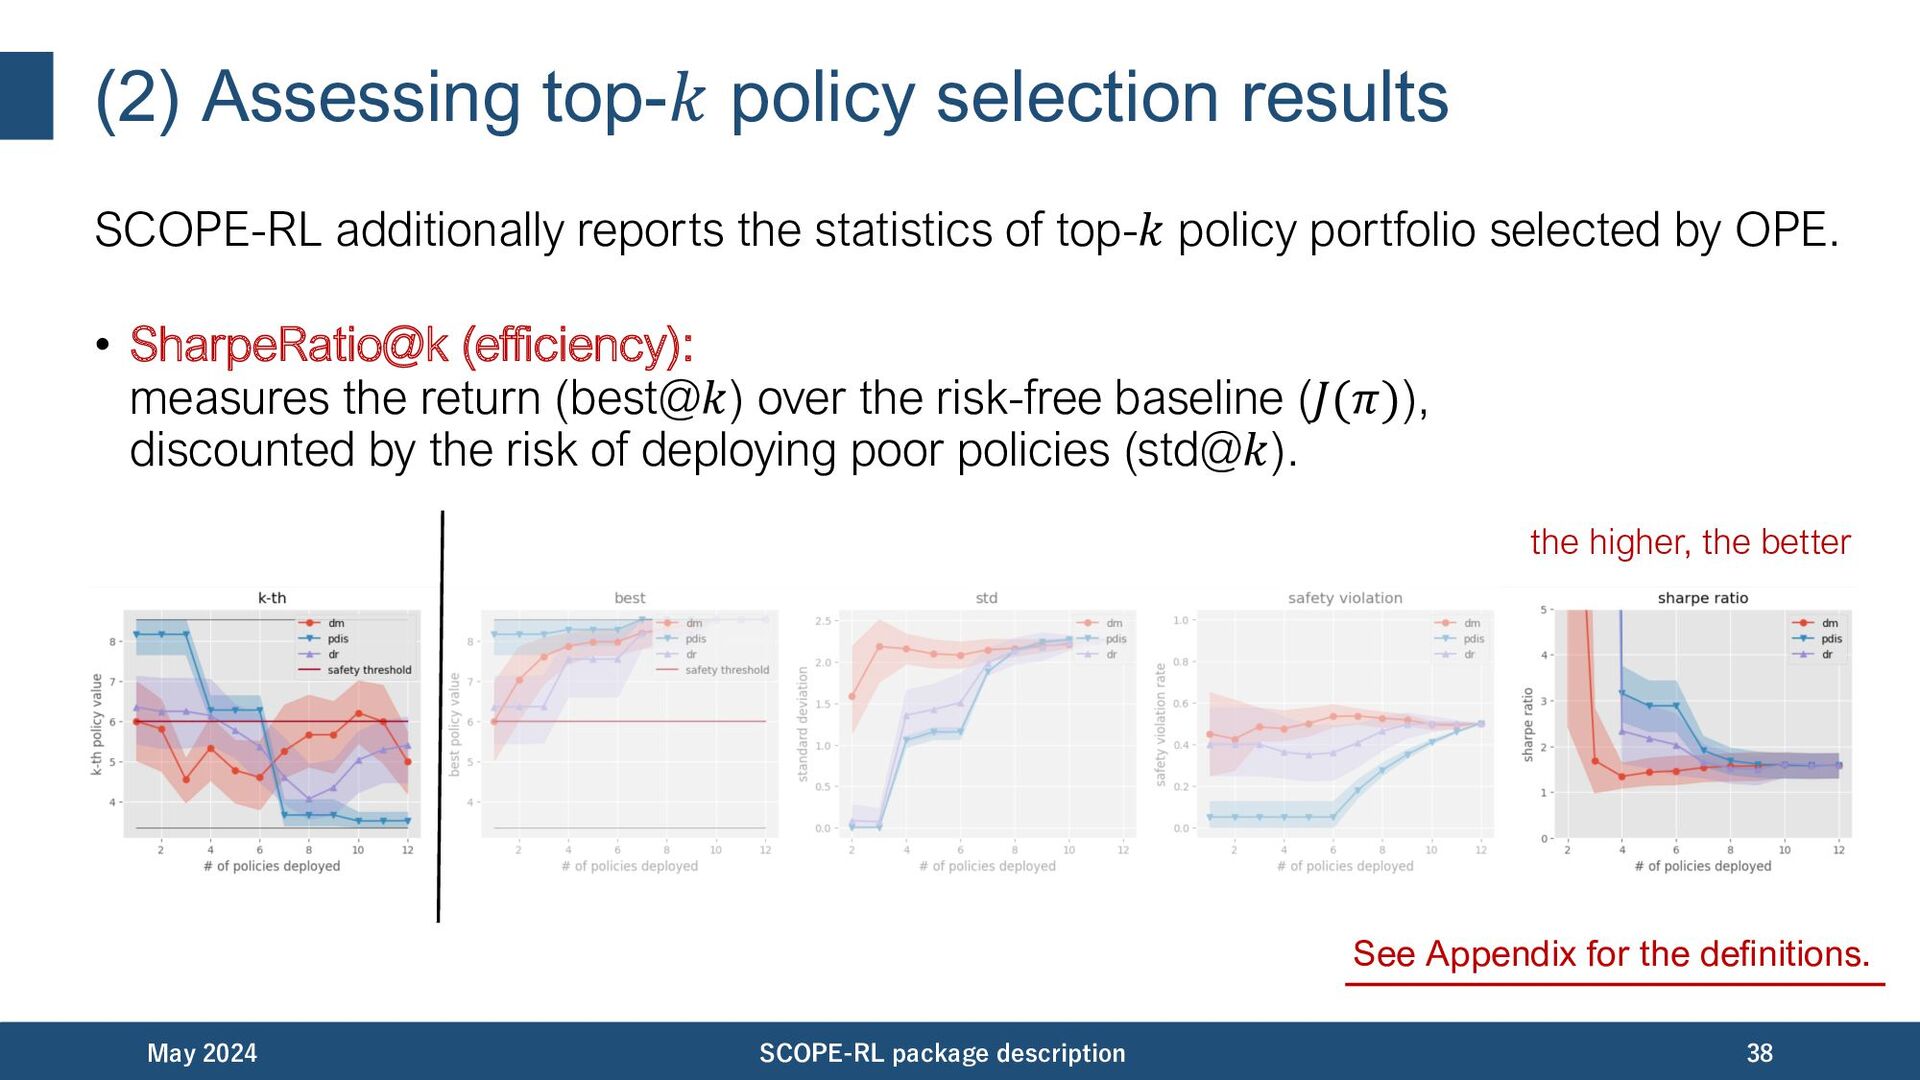
(2) Assessing top-𝑘 policy selection results SCOPE-RL additionally reports the
statistics of top-𝑘 policy portfolio selected by OPE. • SharpeRatio@k (efficiency): measures the return (best@𝑘) over the risk-free baseline (𝐽(𝜋)), discounted by the risk of deploying poor policies (std@𝑘). May 2024 SCOPE-RL package description 38 See Appendix for the dePnitions. the higher, the better -
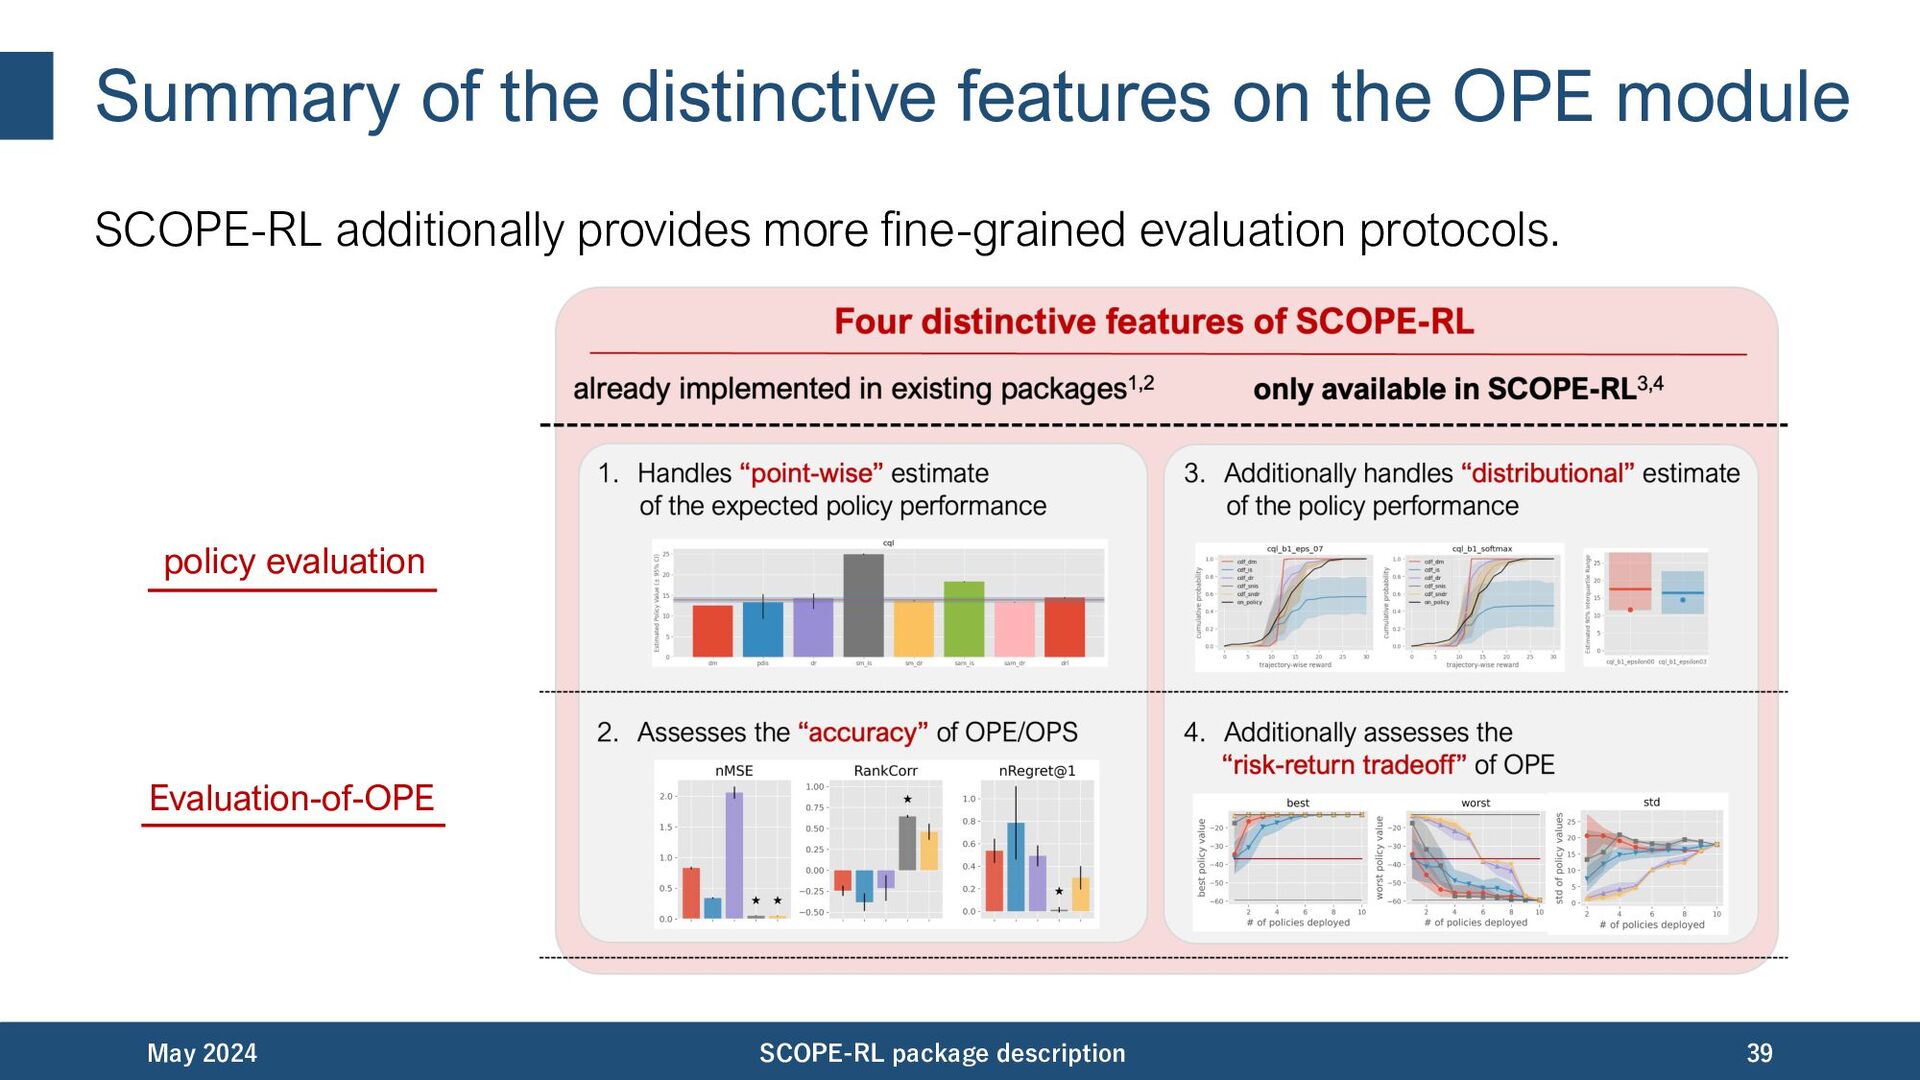
Summary of the distinctive features on the OPE module SCOPE-RL
additionally provides more fine-grained evaluation protocols. May 2024 SCOPE-RL package description 39 policy evaluation Evaluation-of-OPE -
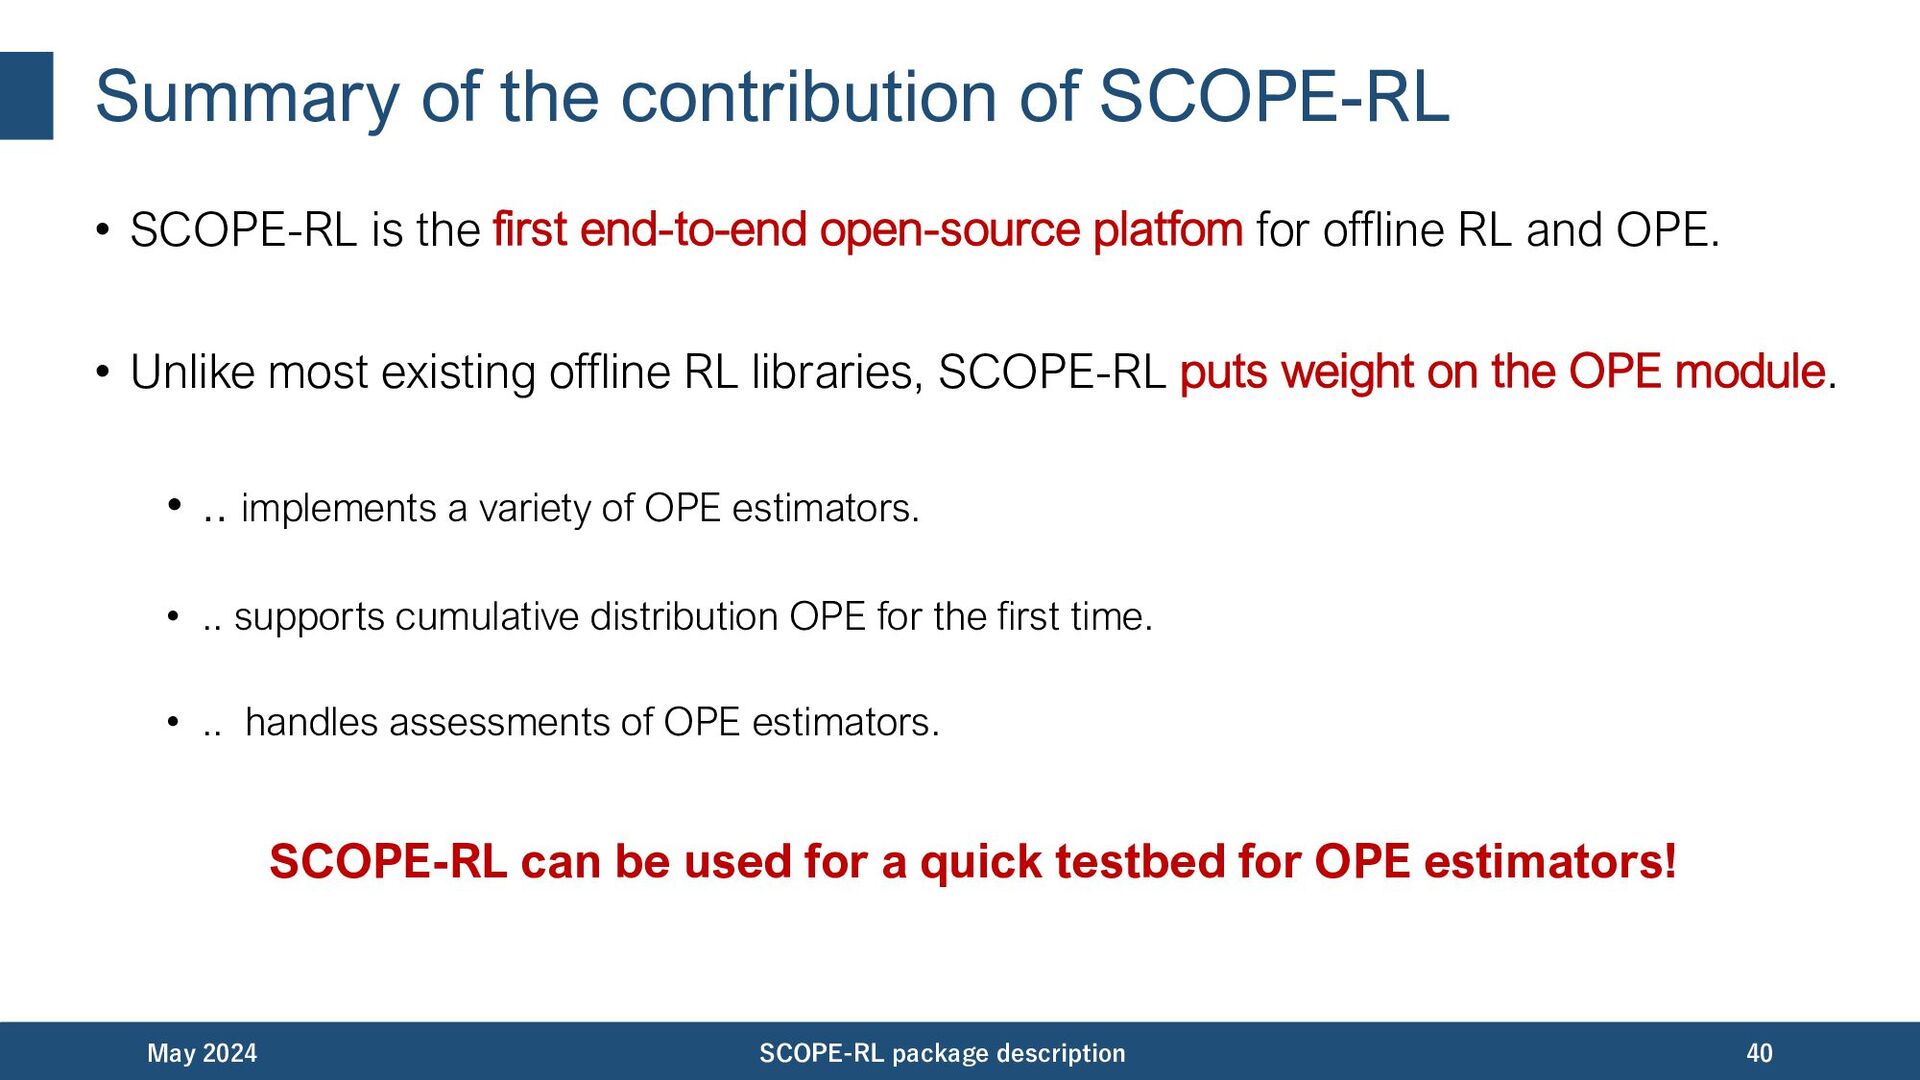
Summary of the contribution of SCOPE-RL • SCOPE-RL is the
first end-to-end open-source platfom for offline RL and OPE. • Unlike most existing offline RL libraries, SCOPE-RL puts weight on the OPE module. • .. implements a variety of OPE estimators. • .. supports cumulative distribution OPE for the first time. • .. handles assessments of OPE estimators. SCOPE-RL can be used for a quick testbed for OPE estimators! May 2024 SCOPE-RL package description 40 -
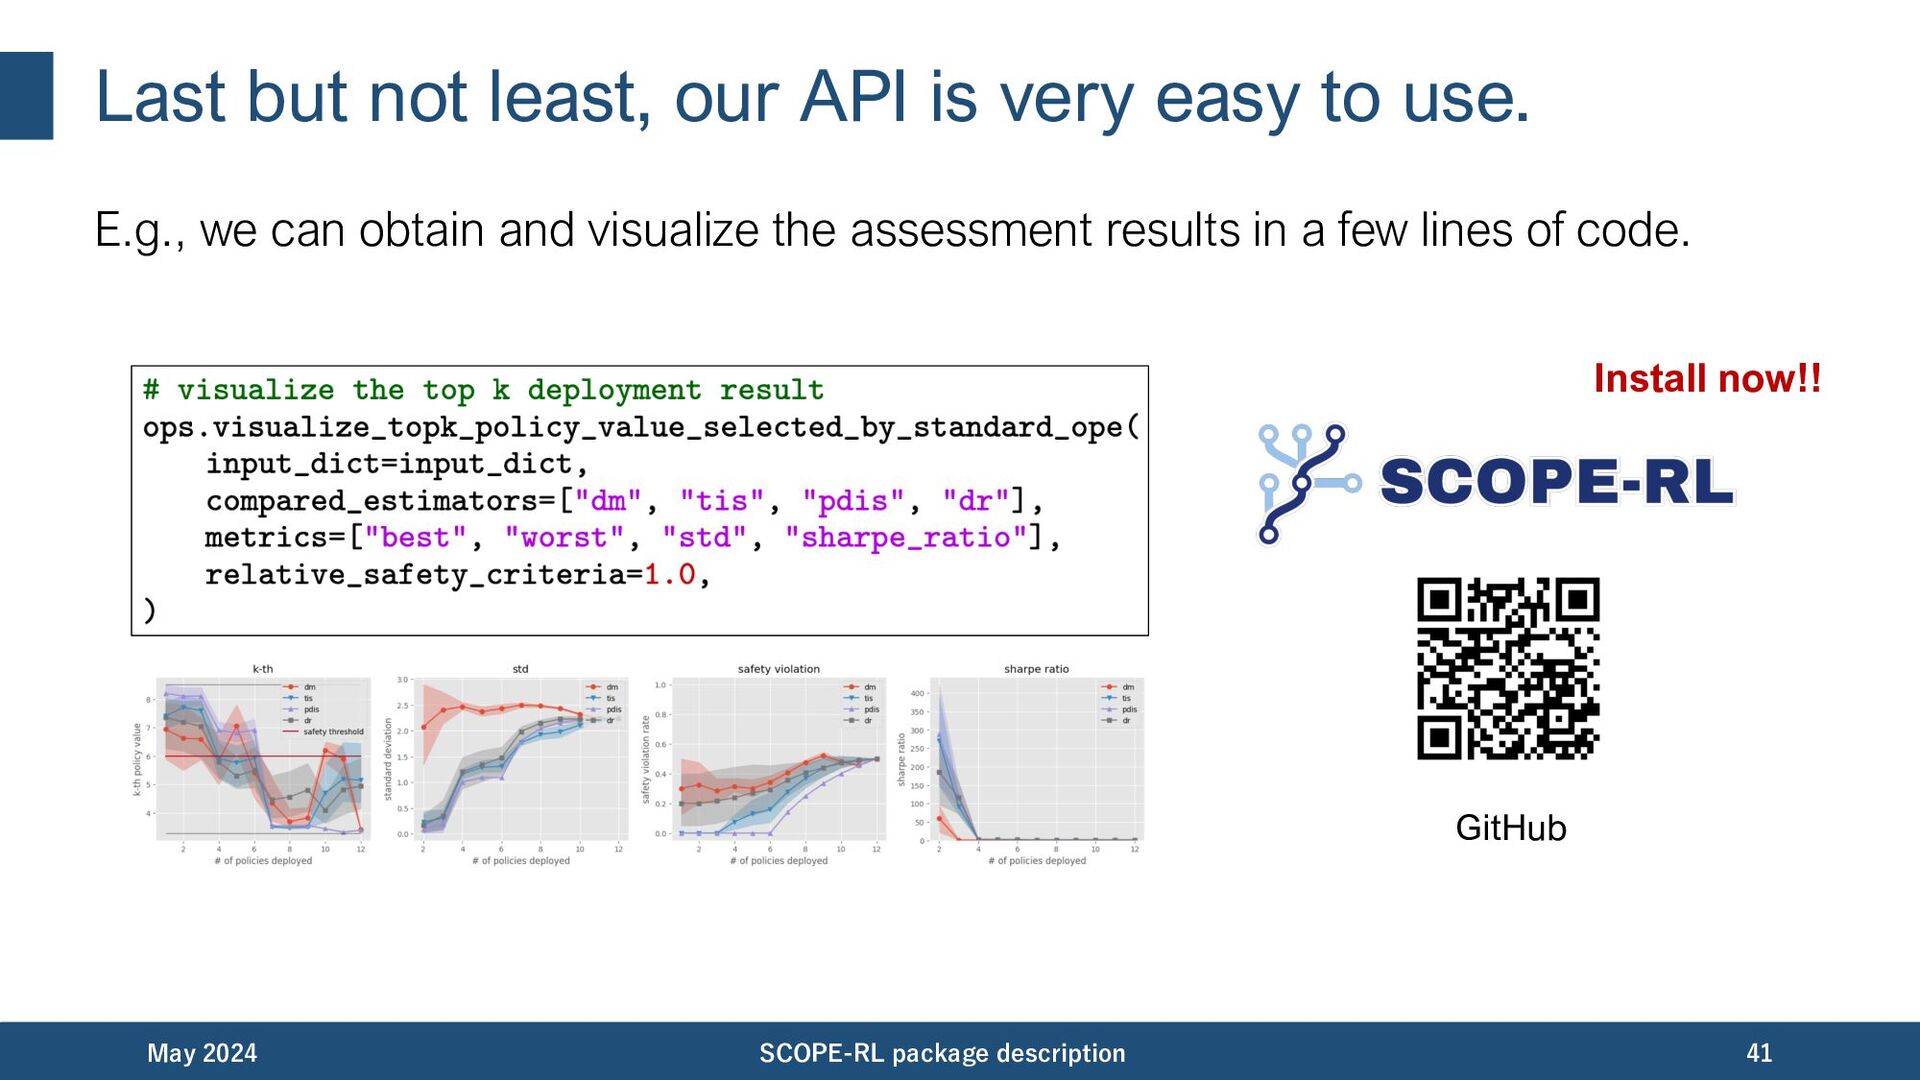
Last but not least, our API is very easy to
use. E.g., we can obtain and visualize the assessment results in a few lines of code. May 2024 SCOPE-RL package description 41 GitHub Install now!! -
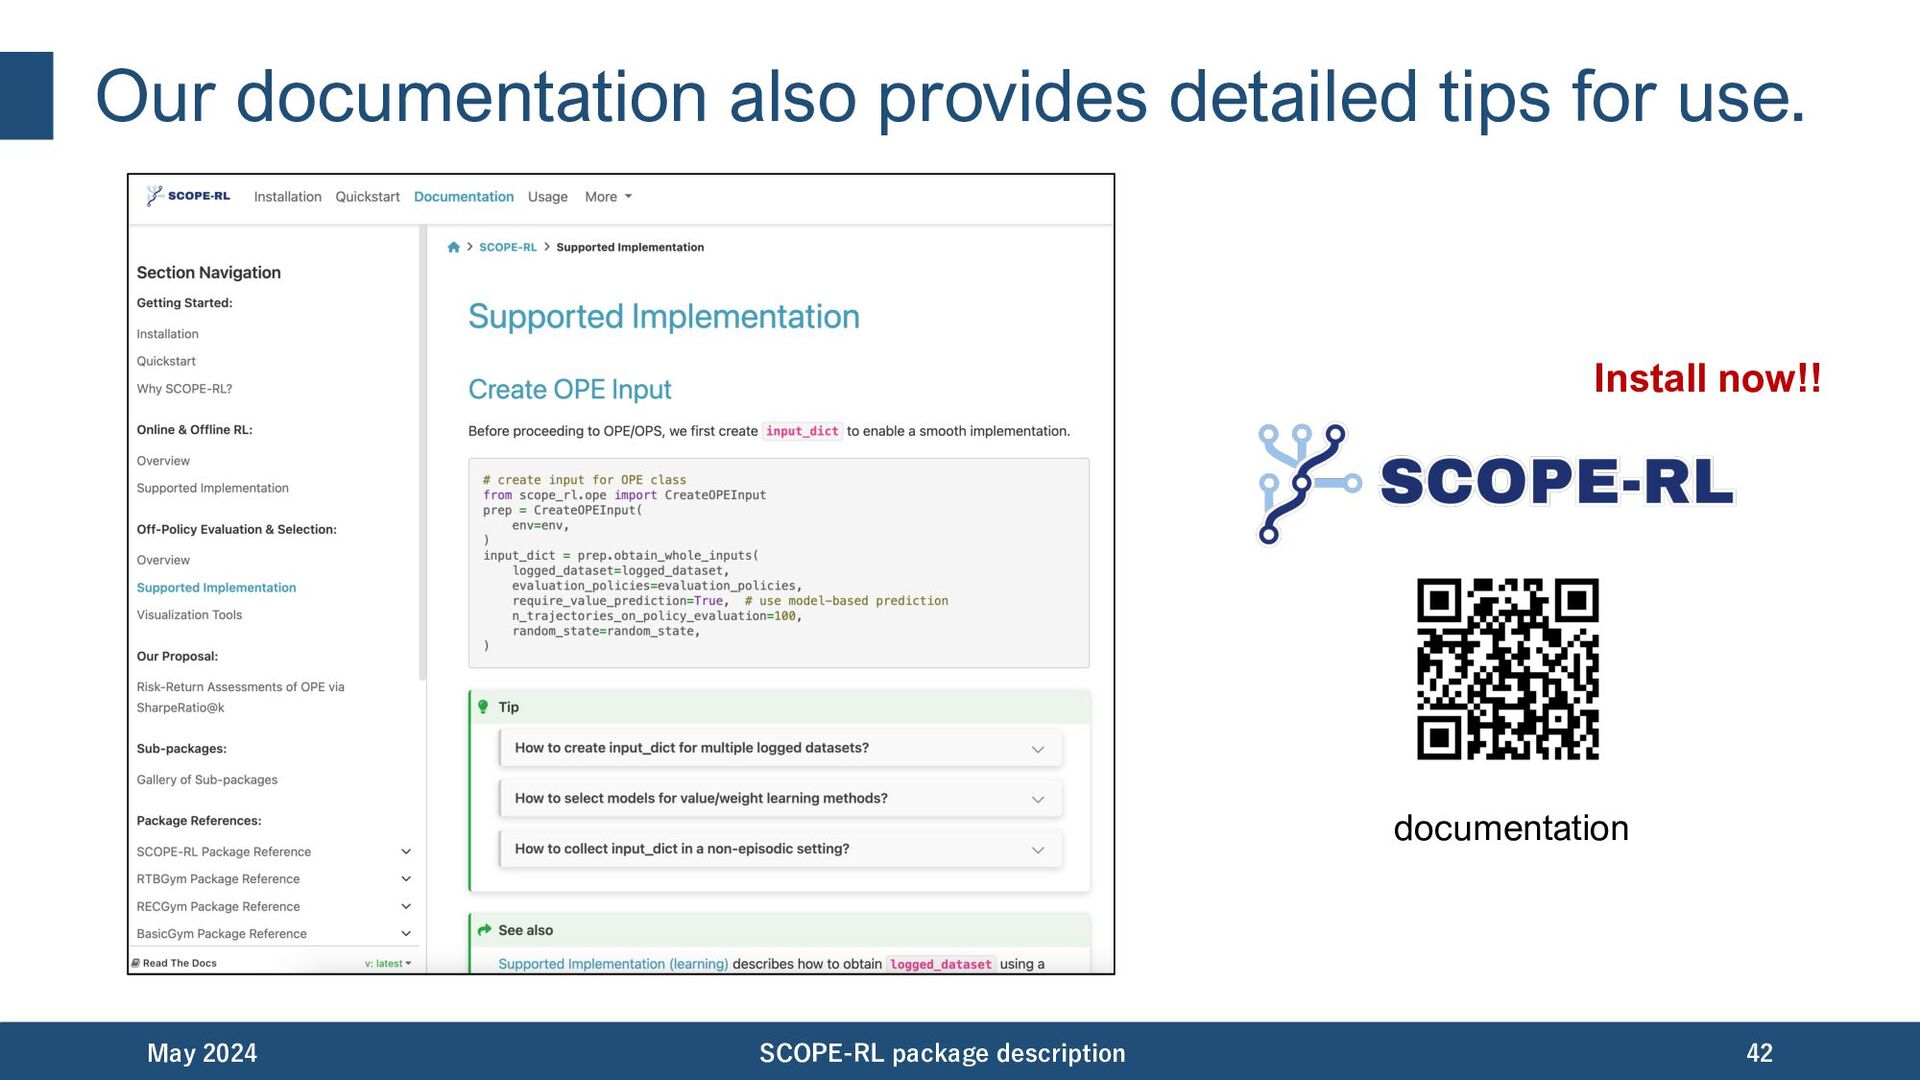
Our documentation also provides detailed tips for use. May 2024
SCOPE-RL package description 42 documentation Install now!! -
Find more in the SCOPE-RL reference pages! • Webpage (documentation):
https://scope-rl.readthedocs.io/en/latest/ • Package reference: https://scope-rl.readthedocs.io/en/latest/ documentation/scope_rl_api.html • GitHub: https://github.com/hakuhodo-technologies/scope-rl • PyPI: https://pypi.org/project/scope-rl/ • Google Group: https://groups.google.com/g/scope-rl May 2024 SCOPE-RL package description 43 documentation GitHub PyPI -
Example Usage A quick demo for streamlining offline RL and
OPE May 2024 SCOPE-RL package description 45 -
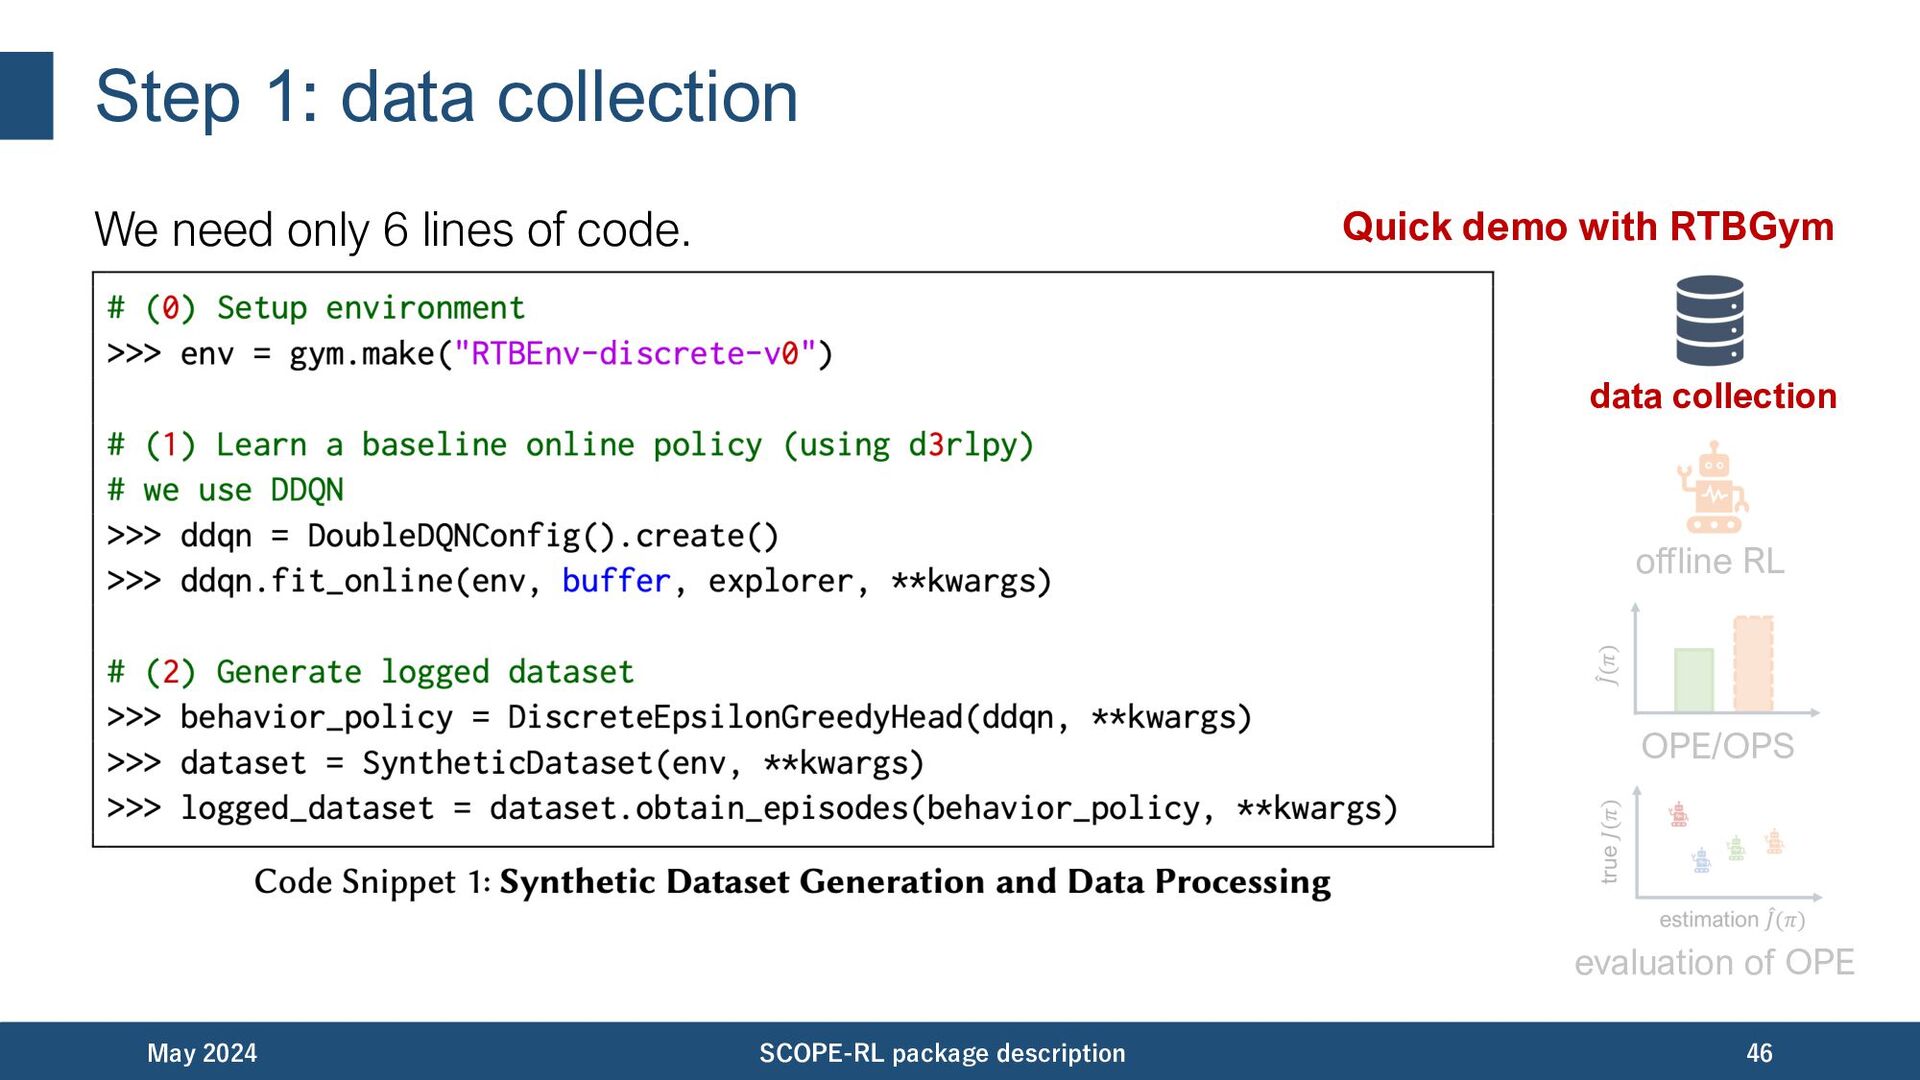
Step 1: data collection We need only 6 lines of
code. May 2024 SCOPE-RL package description 46 Quick demo with RTBGym offline RL OPE/OPS evaluation of OPE data collection -
Step 1: data collection We need only 6 lines of
code. May 2024 SCOPE-RL package description 47 Quick demo with RTBGym offline RL OPE/OPS evaluation of OPE data collection -
Step 1: data collection We need only 6 lines of
code. May 2024 SCOPE-RL package description 48 Quick demo with RTBGym offline RL OPE/OPS evaluation of OPE data collection -
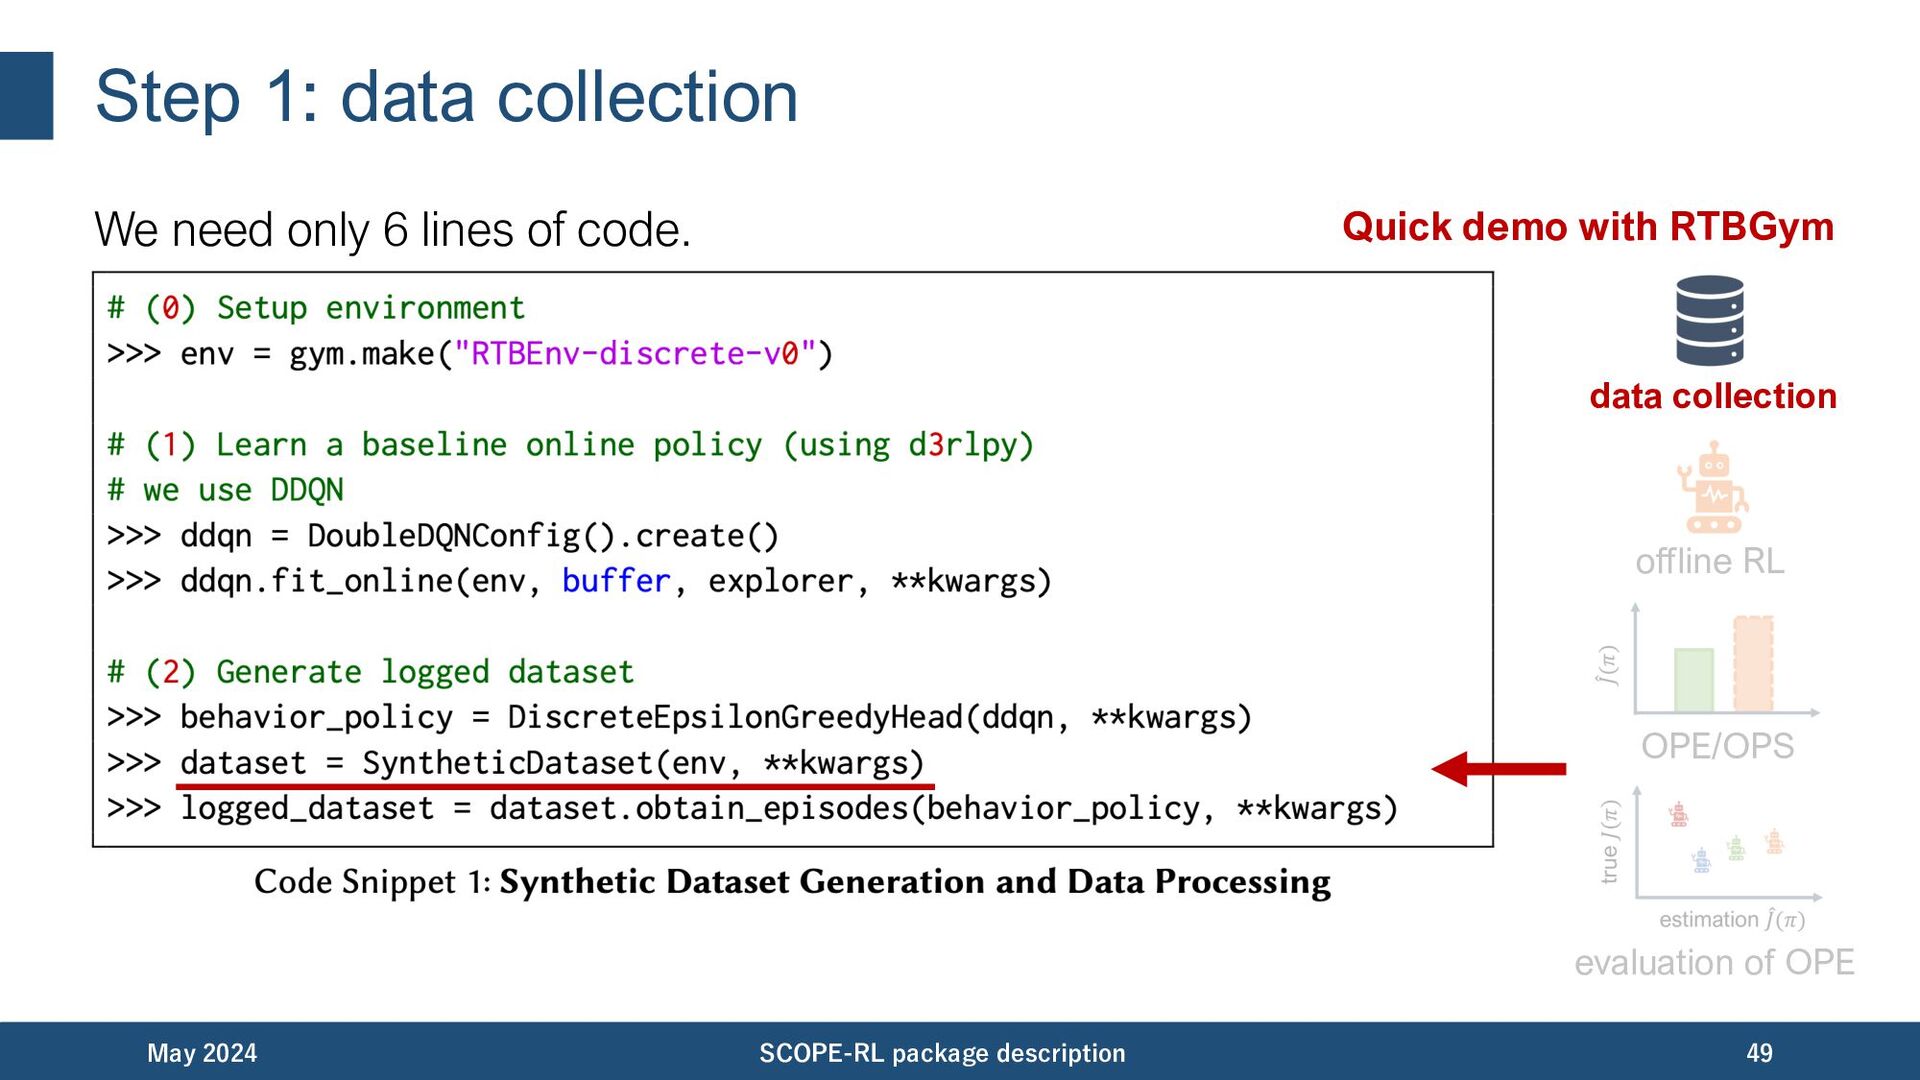
Step 1: data collection We need only 6 lines of
code. May 2024 SCOPE-RL package description 49 Quick demo with RTBGym data collection offline RL OPE/OPS evaluation of OPE -
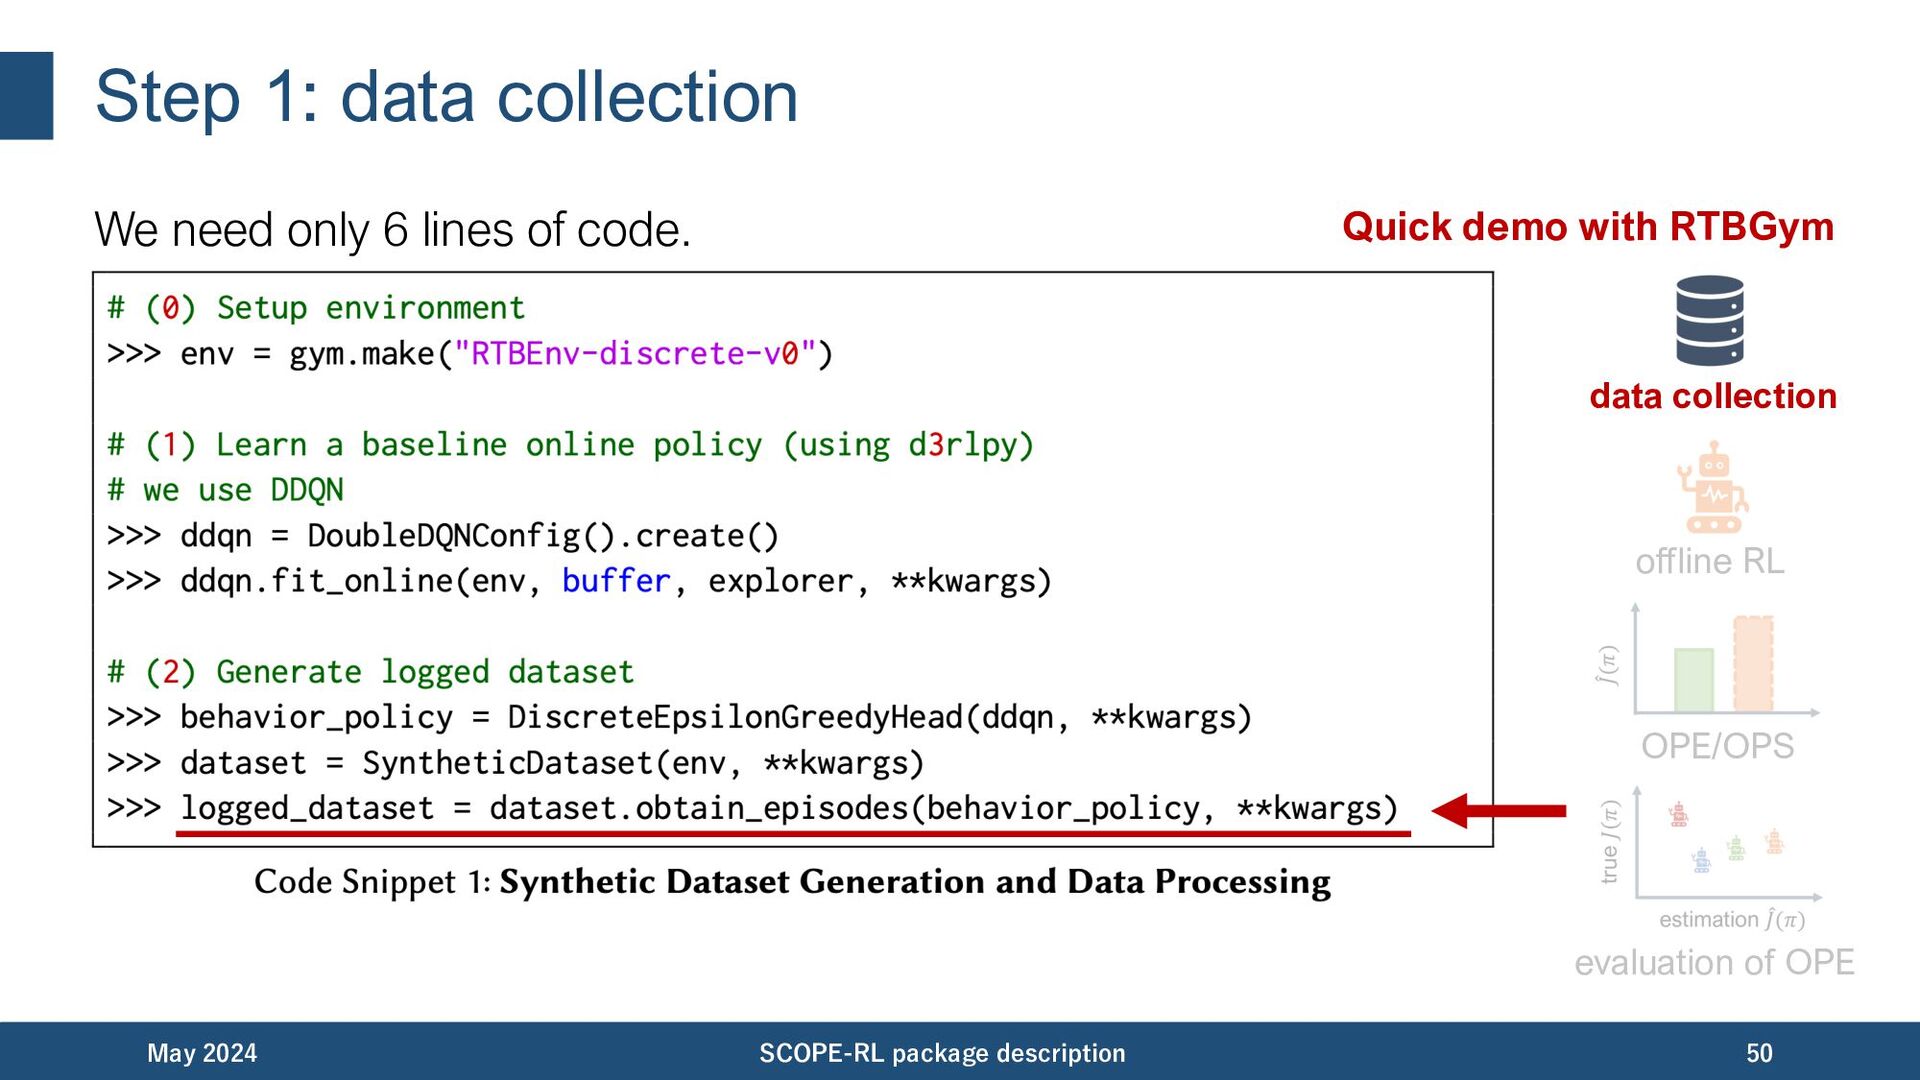
Step 1: data collection We need only 6 lines of
code. May 2024 SCOPE-RL package description 50 Quick demo with RTBGym offline RL OPE/OPS evaluation of OPE data collection -
Step2: learning a new policy offline (offline RL) We use
d3rlpy for the offline RL part. May 2024 SCOPE-RL package description 51 data collection offline RL OPE/OPS evaluation of OPE -
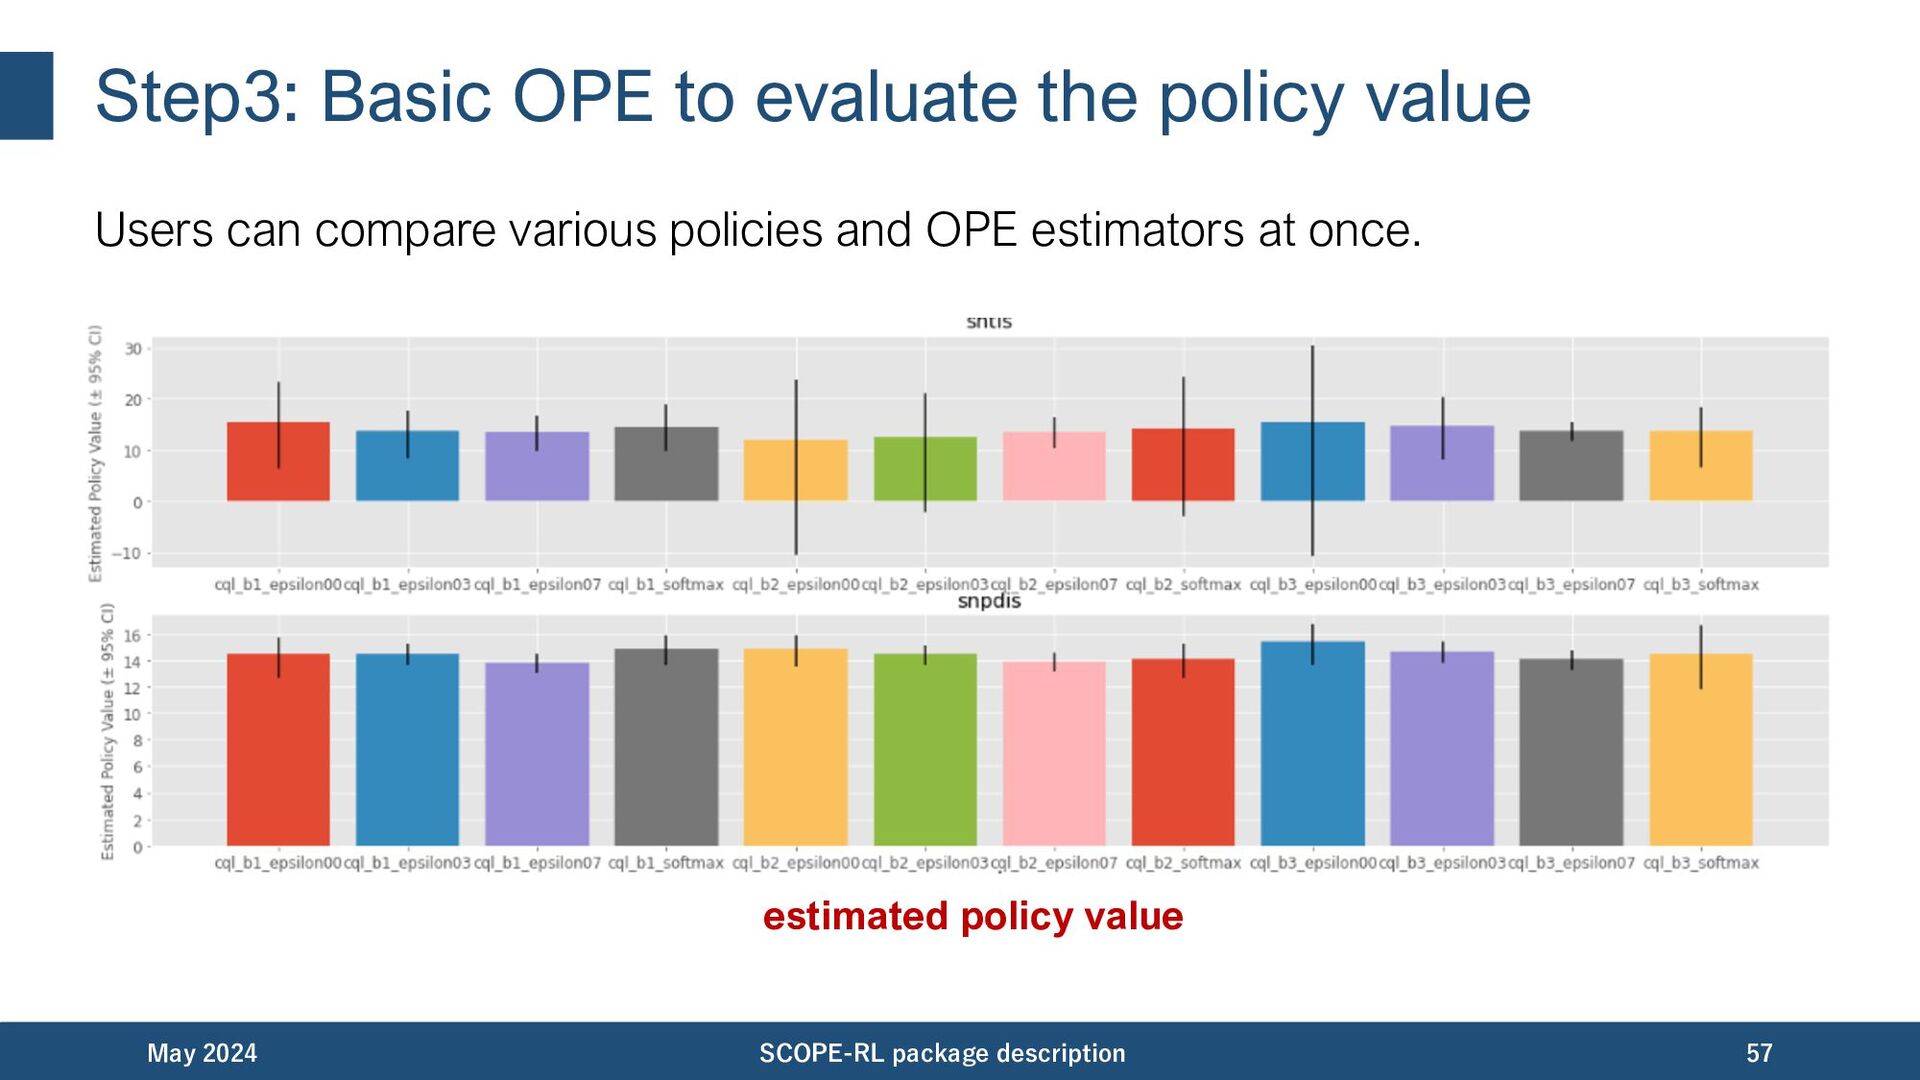
Step3: Basic OPE to evaluate the policy value Users can
compare various policies and OPE estimators at once. May 2024 SCOPE-RL package description 52 data collection offline RL OPE/OPS evaluation of OPE -
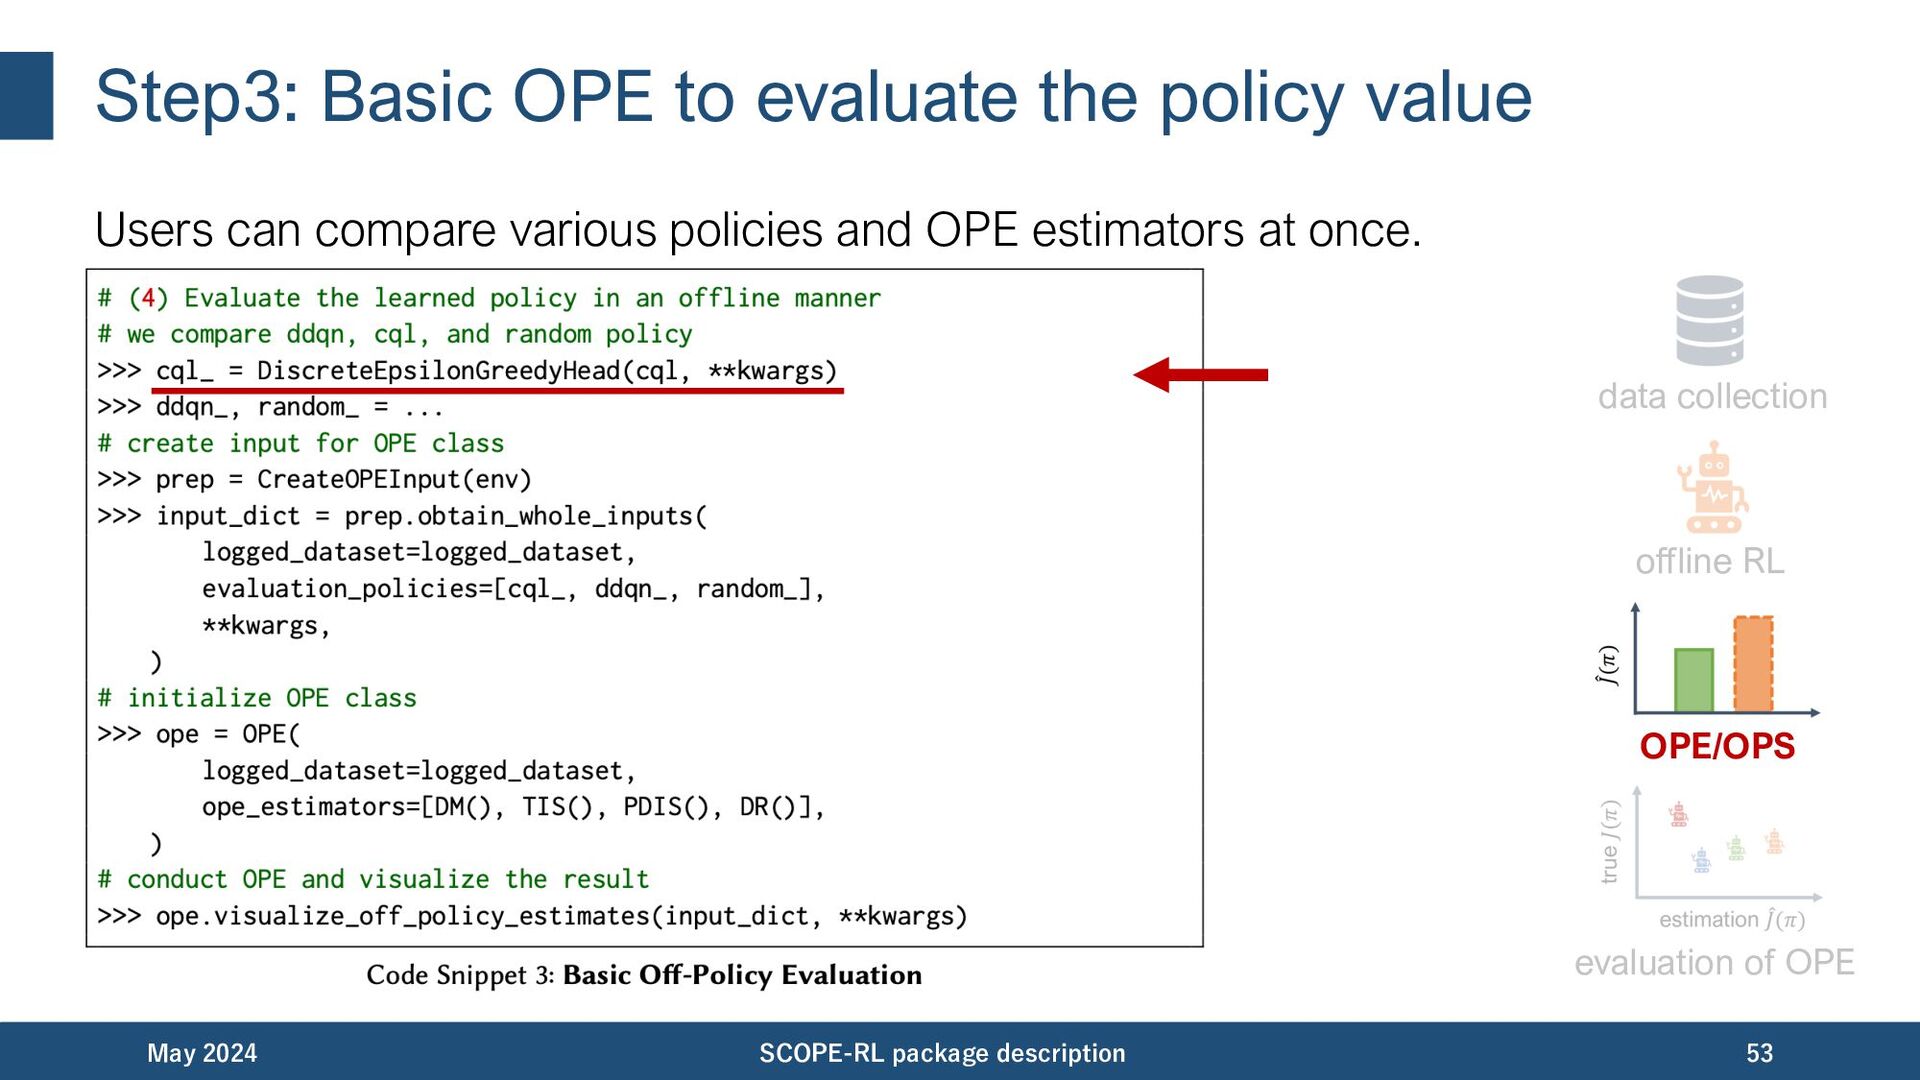
Step3: Basic OPE to evaluate the policy value Users can
compare various policies and OPE estimators at once. May 2024 SCOPE-RL package description 53 data collection offline RL OPE/OPS evaluation of OPE -
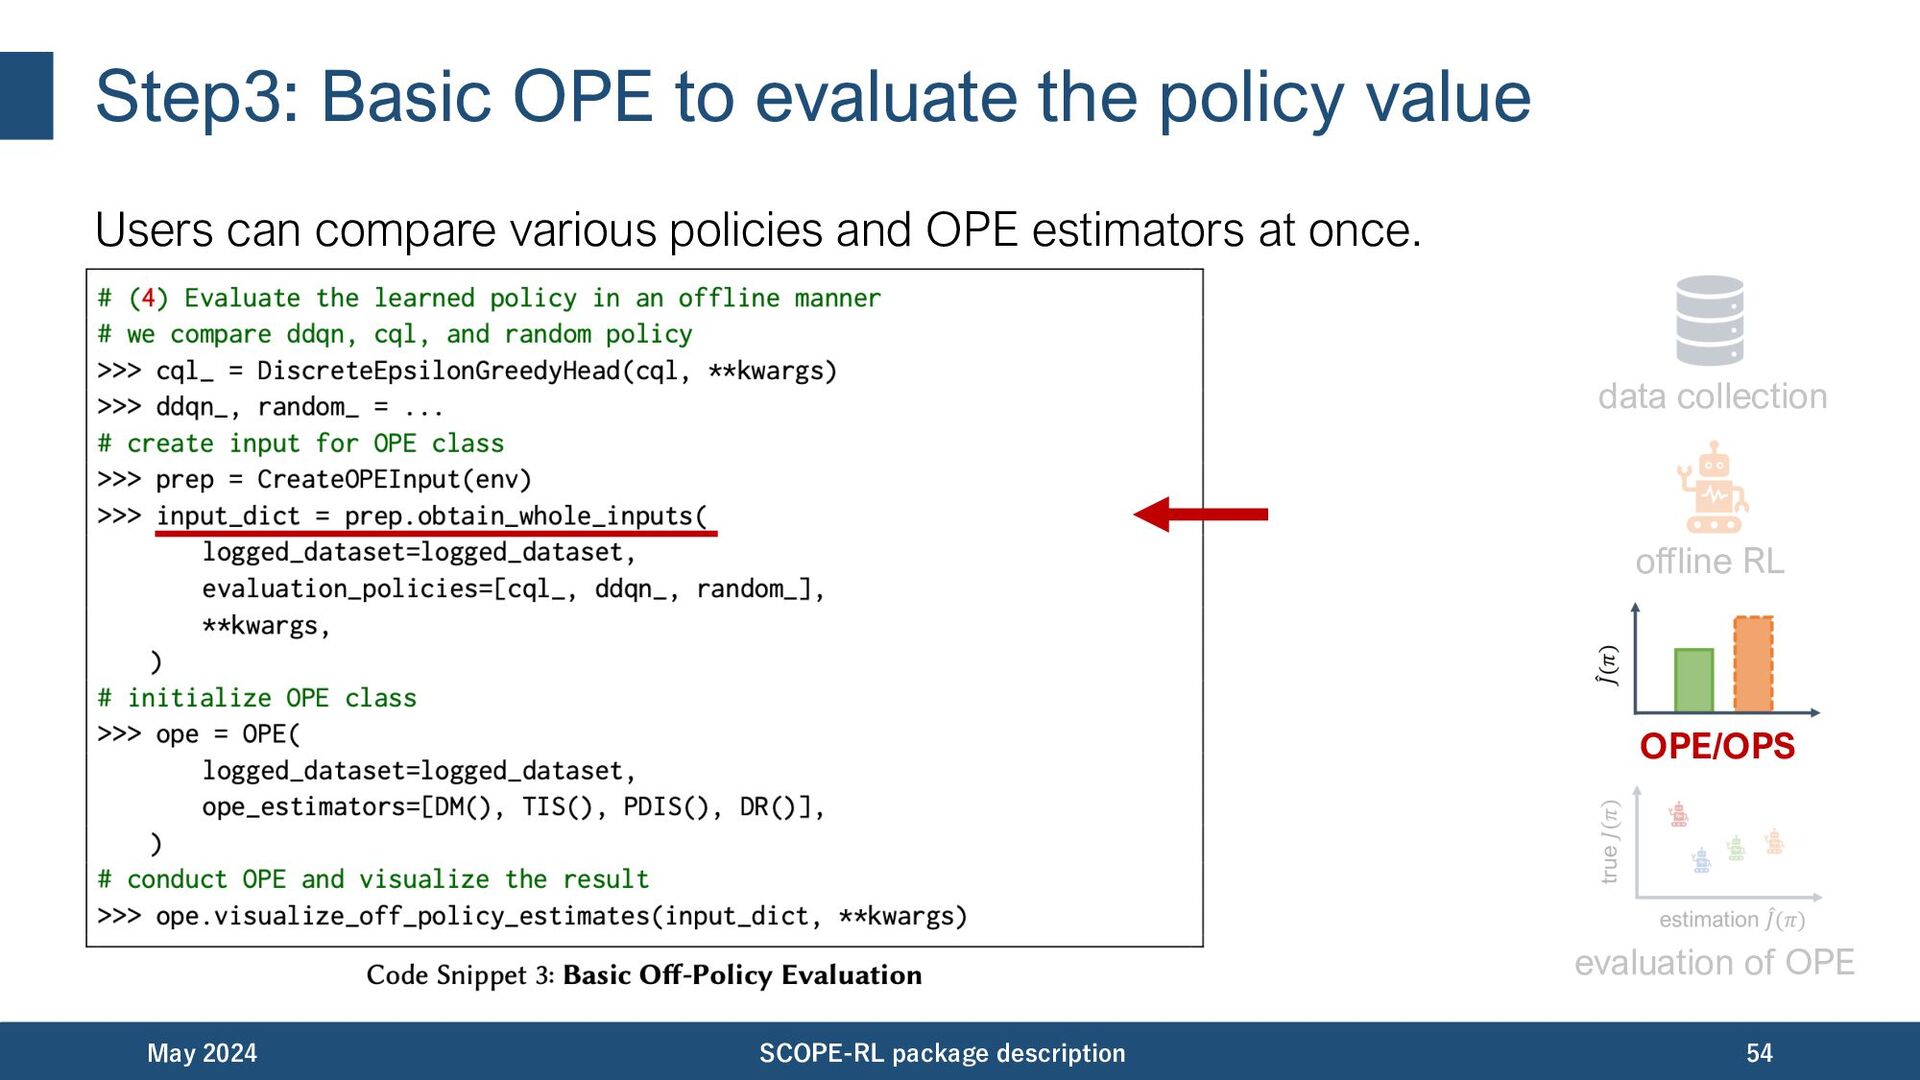
Step3: Basic OPE to evaluate the policy value Users can
compare various policies and OPE estimators at once. May 2024 SCOPE-RL package description 54 data collection offline RL OPE/OPS evaluation of OPE -
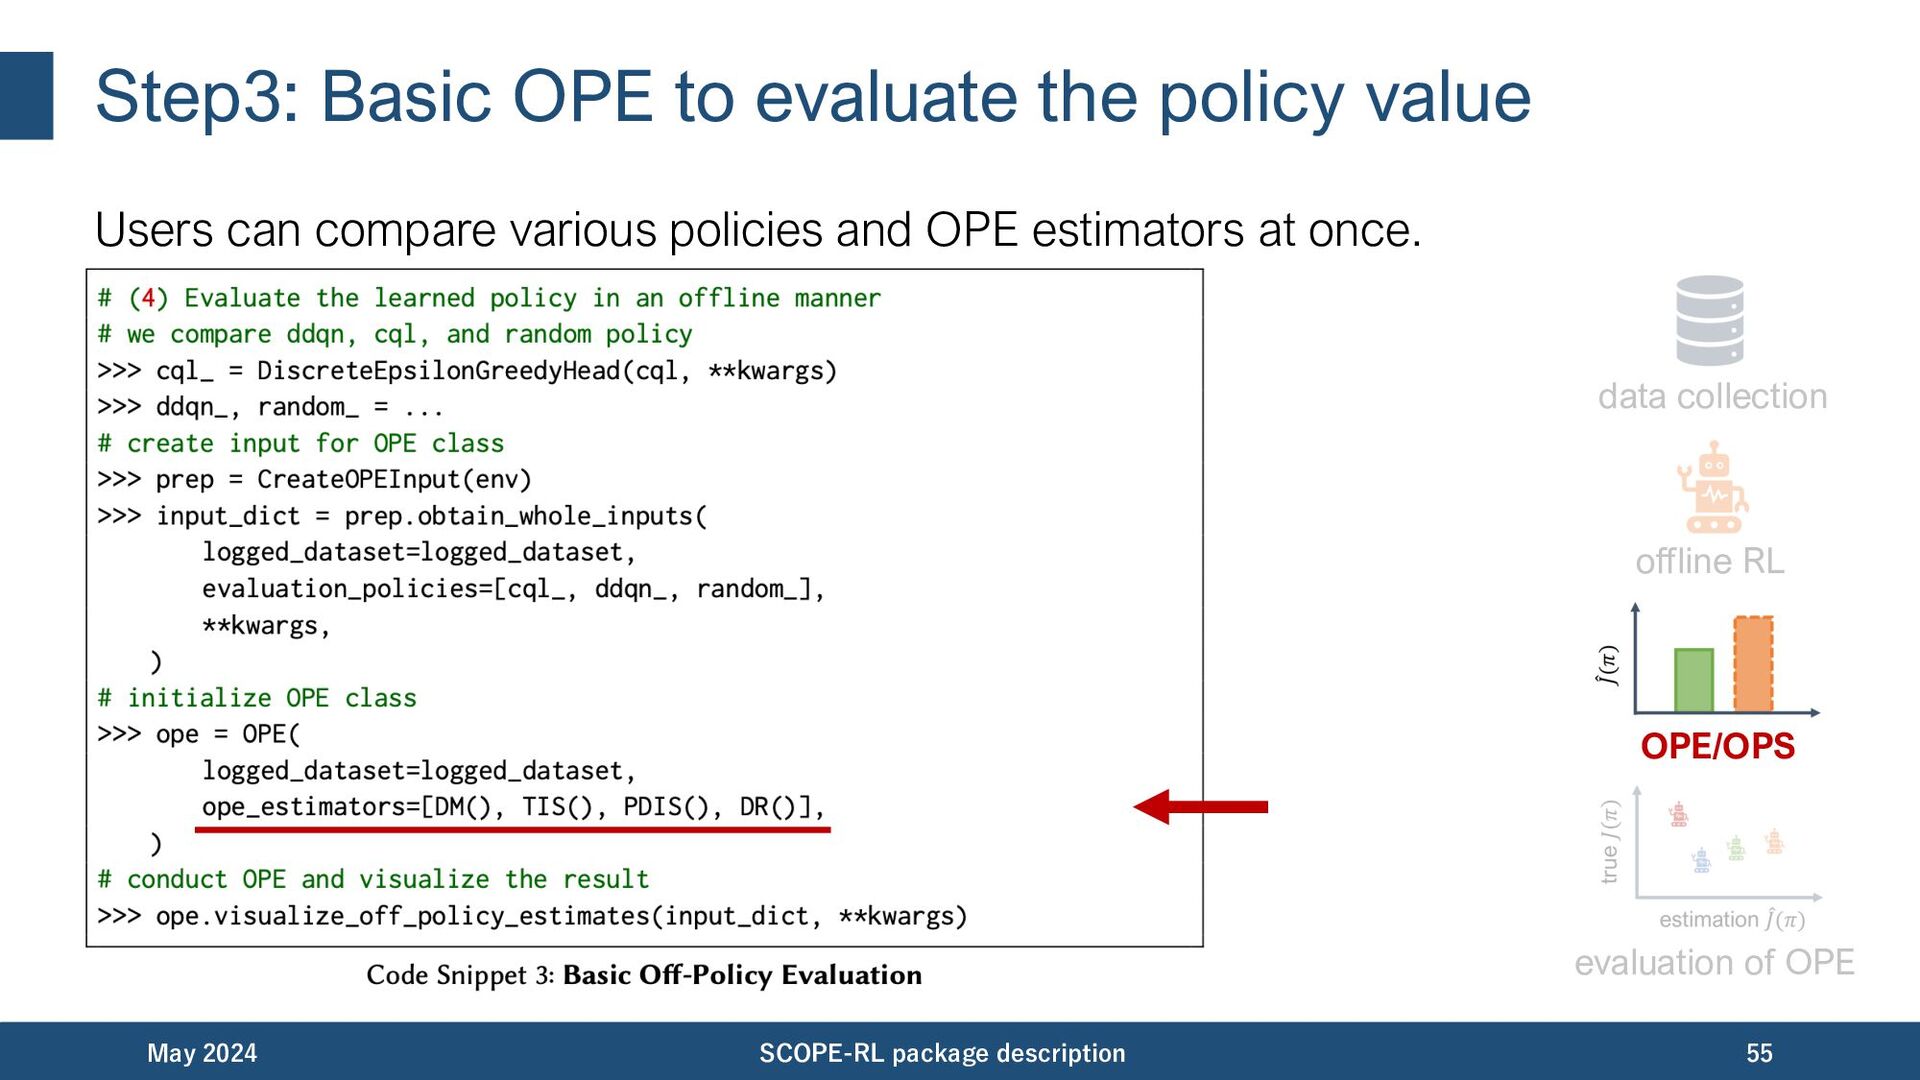
Step3: Basic OPE to evaluate the policy value Users can
compare various policies and OPE estimators at once. May 2024 SCOPE-RL package description 55 data collection offline RL OPE/OPS evaluation of OPE -
Step3: Basic OPE to evaluate the policy value Users can
compare various policies and OPE estimators at once. May 2024 SCOPE-RL package description 56 data collection offline RL OPE/OPS evaluation of OPE -
Step3: Basic OPE to evaluate the policy value Users can
compare various policies and OPE estimators at once. May 2024 SCOPE-RL package description 57 estimated policy value -
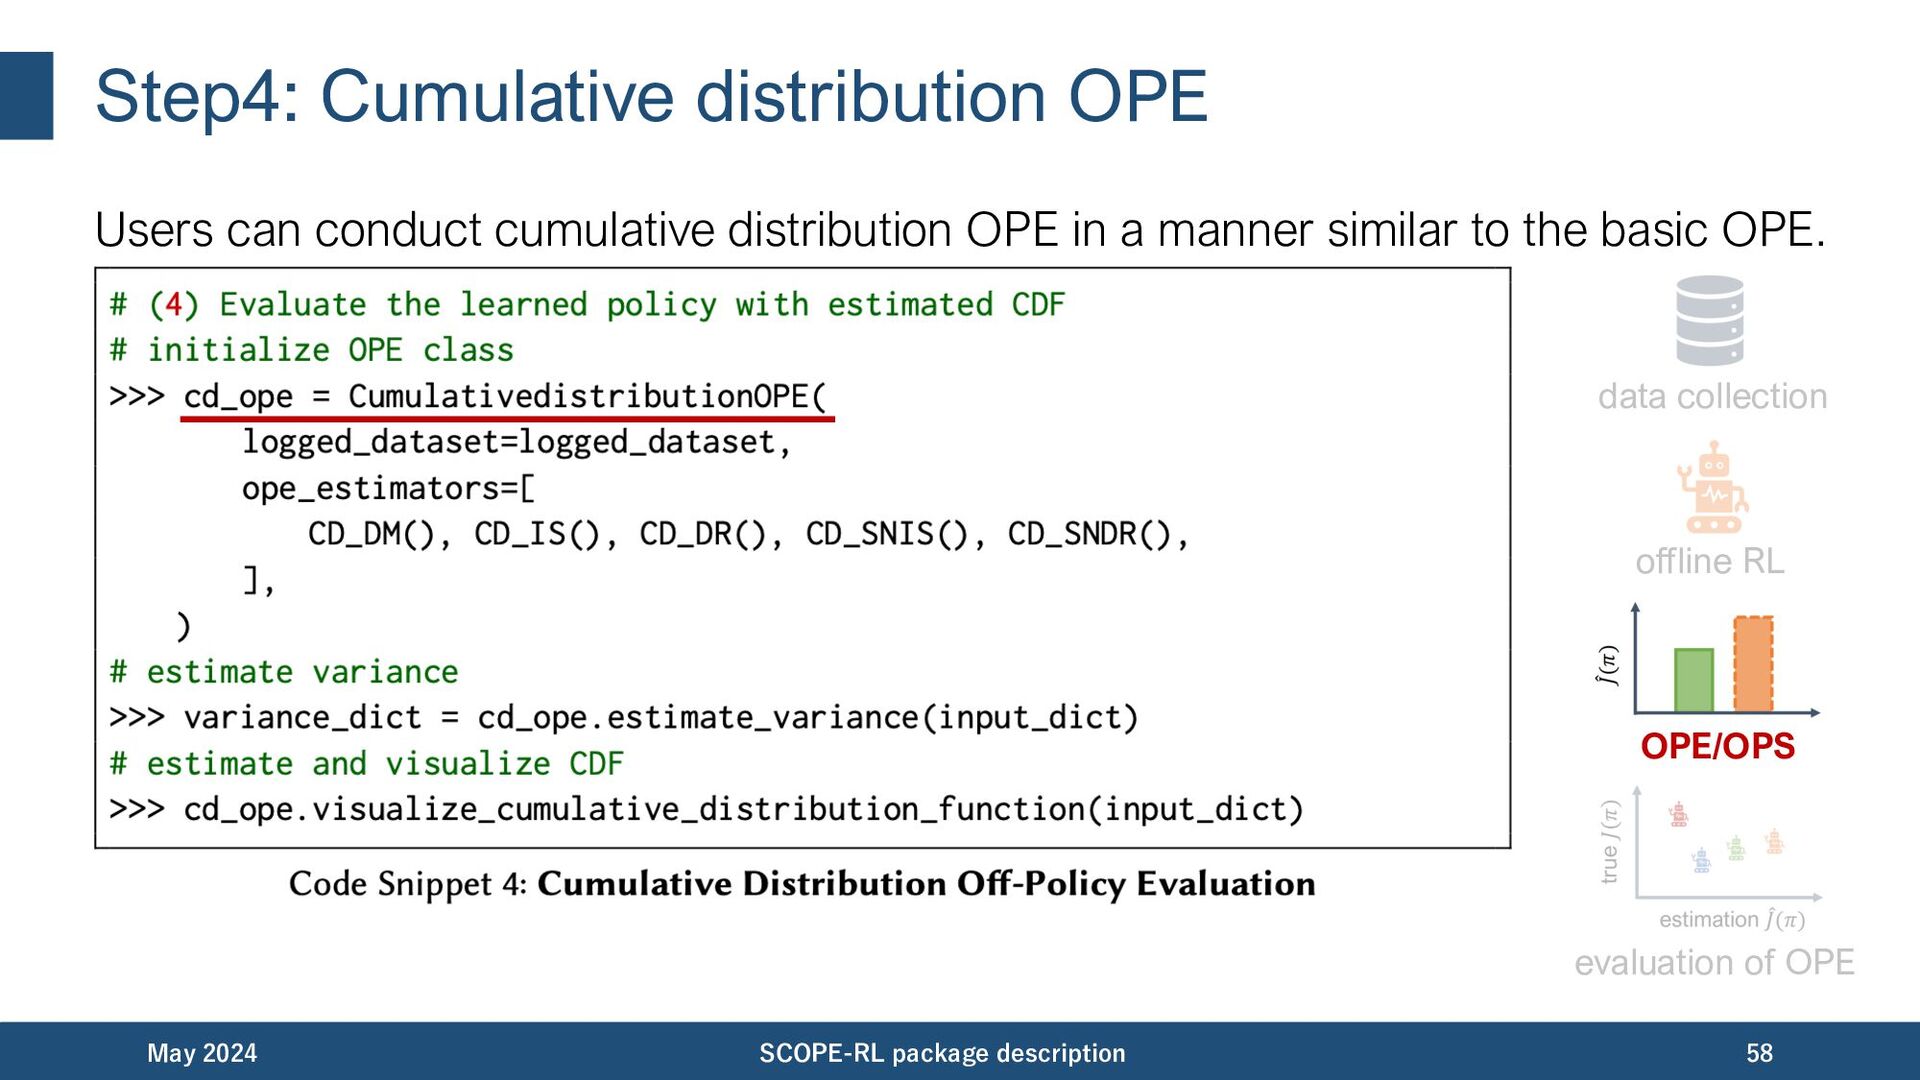
Step4: Cumulative distribution OPE May 2024 SCOPE-RL package description 58
Users can conduct cumulative distribution OPE in a manner similar to the basic OPE. data collection offline RL OPE/OPS evaluation of OPE -
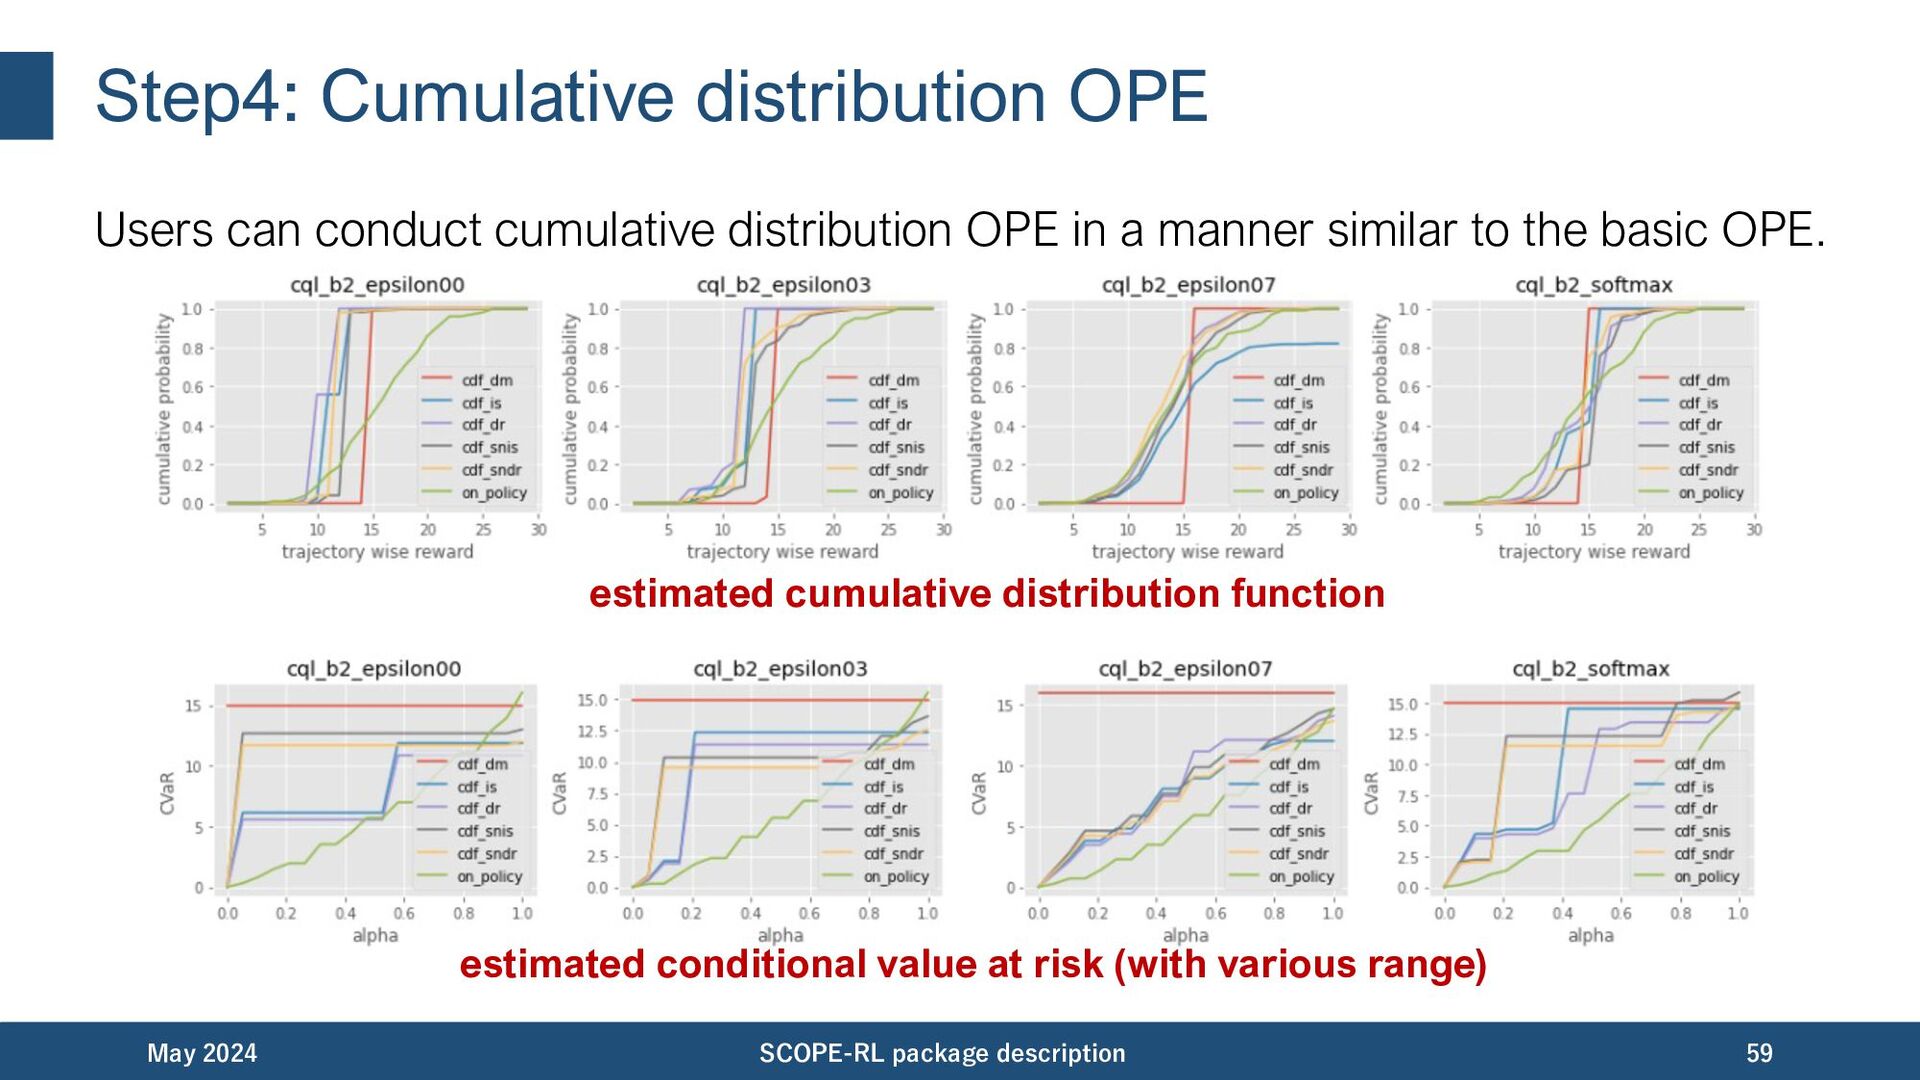
Step4: Cumulative distribution OPE Users can conduct cumulative distribution OPE
in a manner similar to the basic OPE. May 2024 SCOPE-RL package description 59 estimated cumulative distribution function estimated conditional value at risk (with various range) -
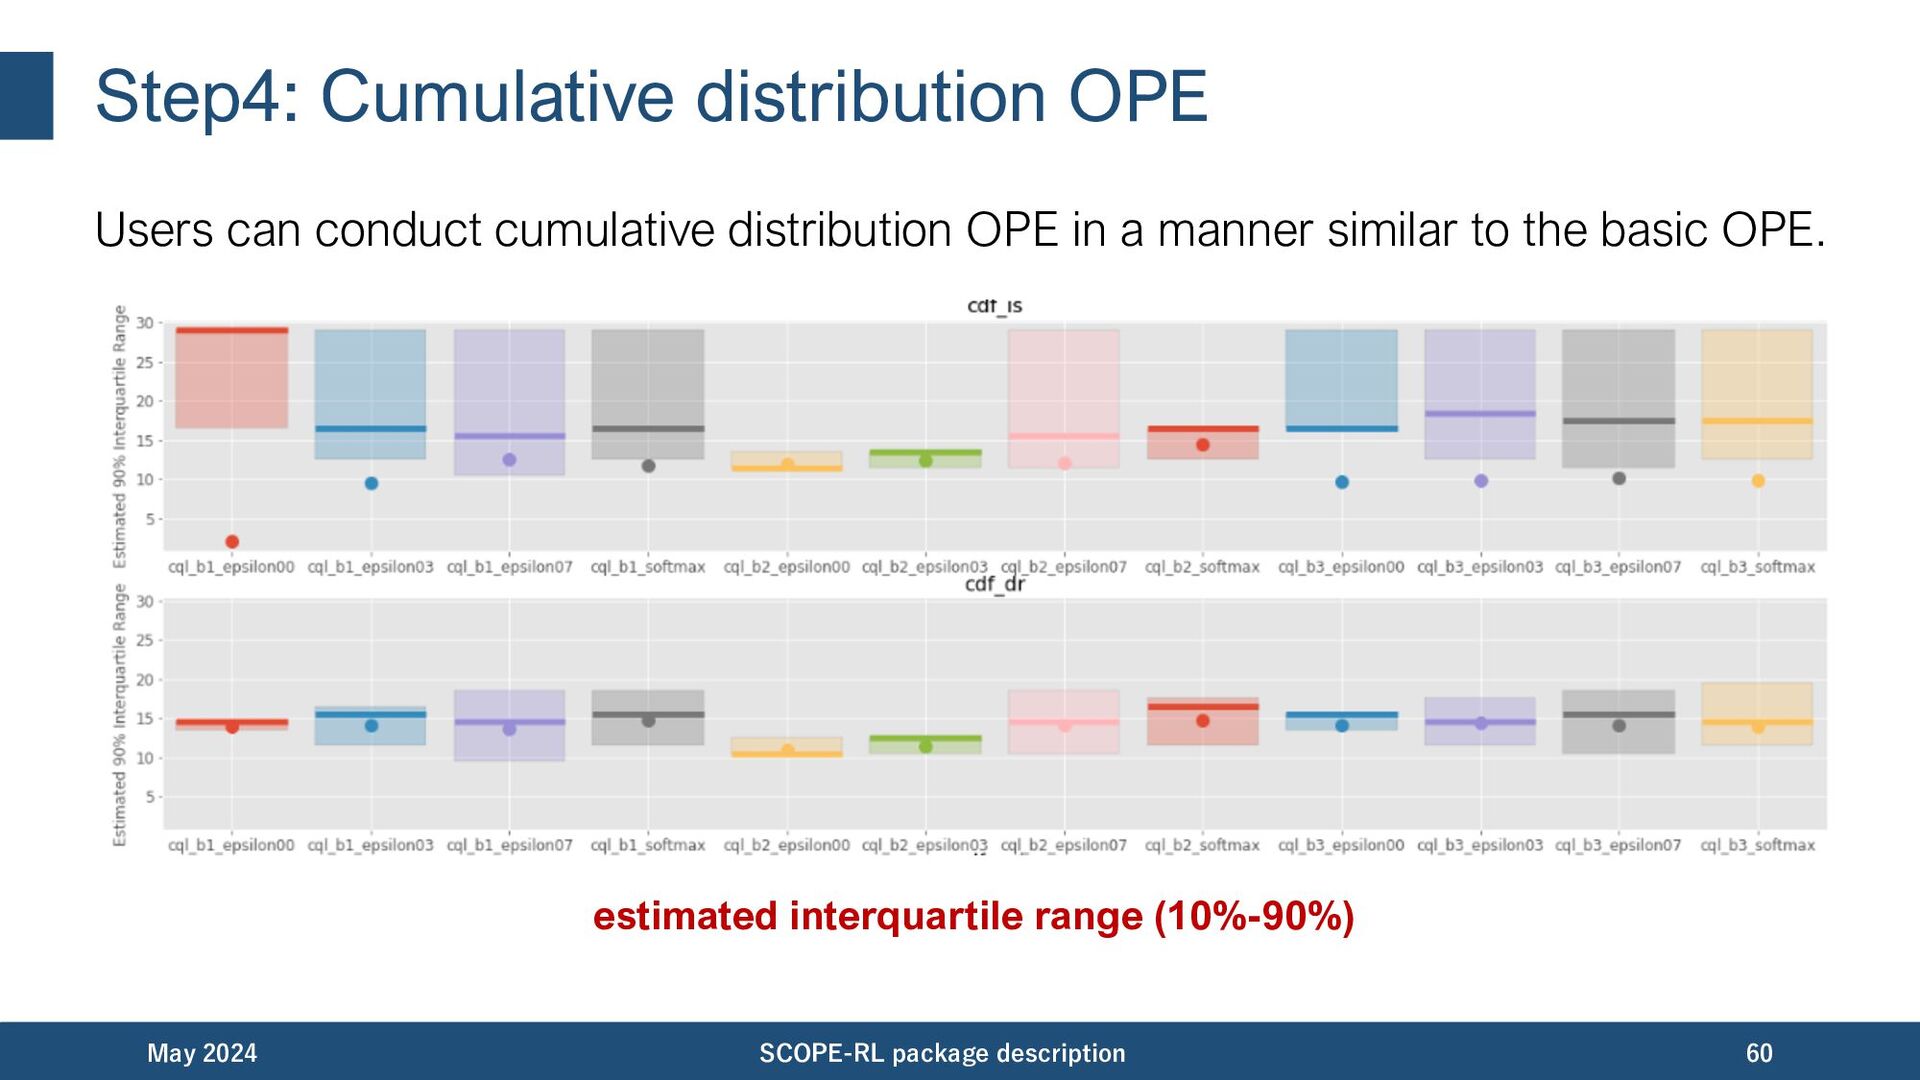
Step4: Cumulative distribution OPE Users can conduct cumulative distribution OPE
in a manner similar to the basic OPE. May 2024 SCOPE-RL package description 60 estimated interquartile range (10%-90%) -
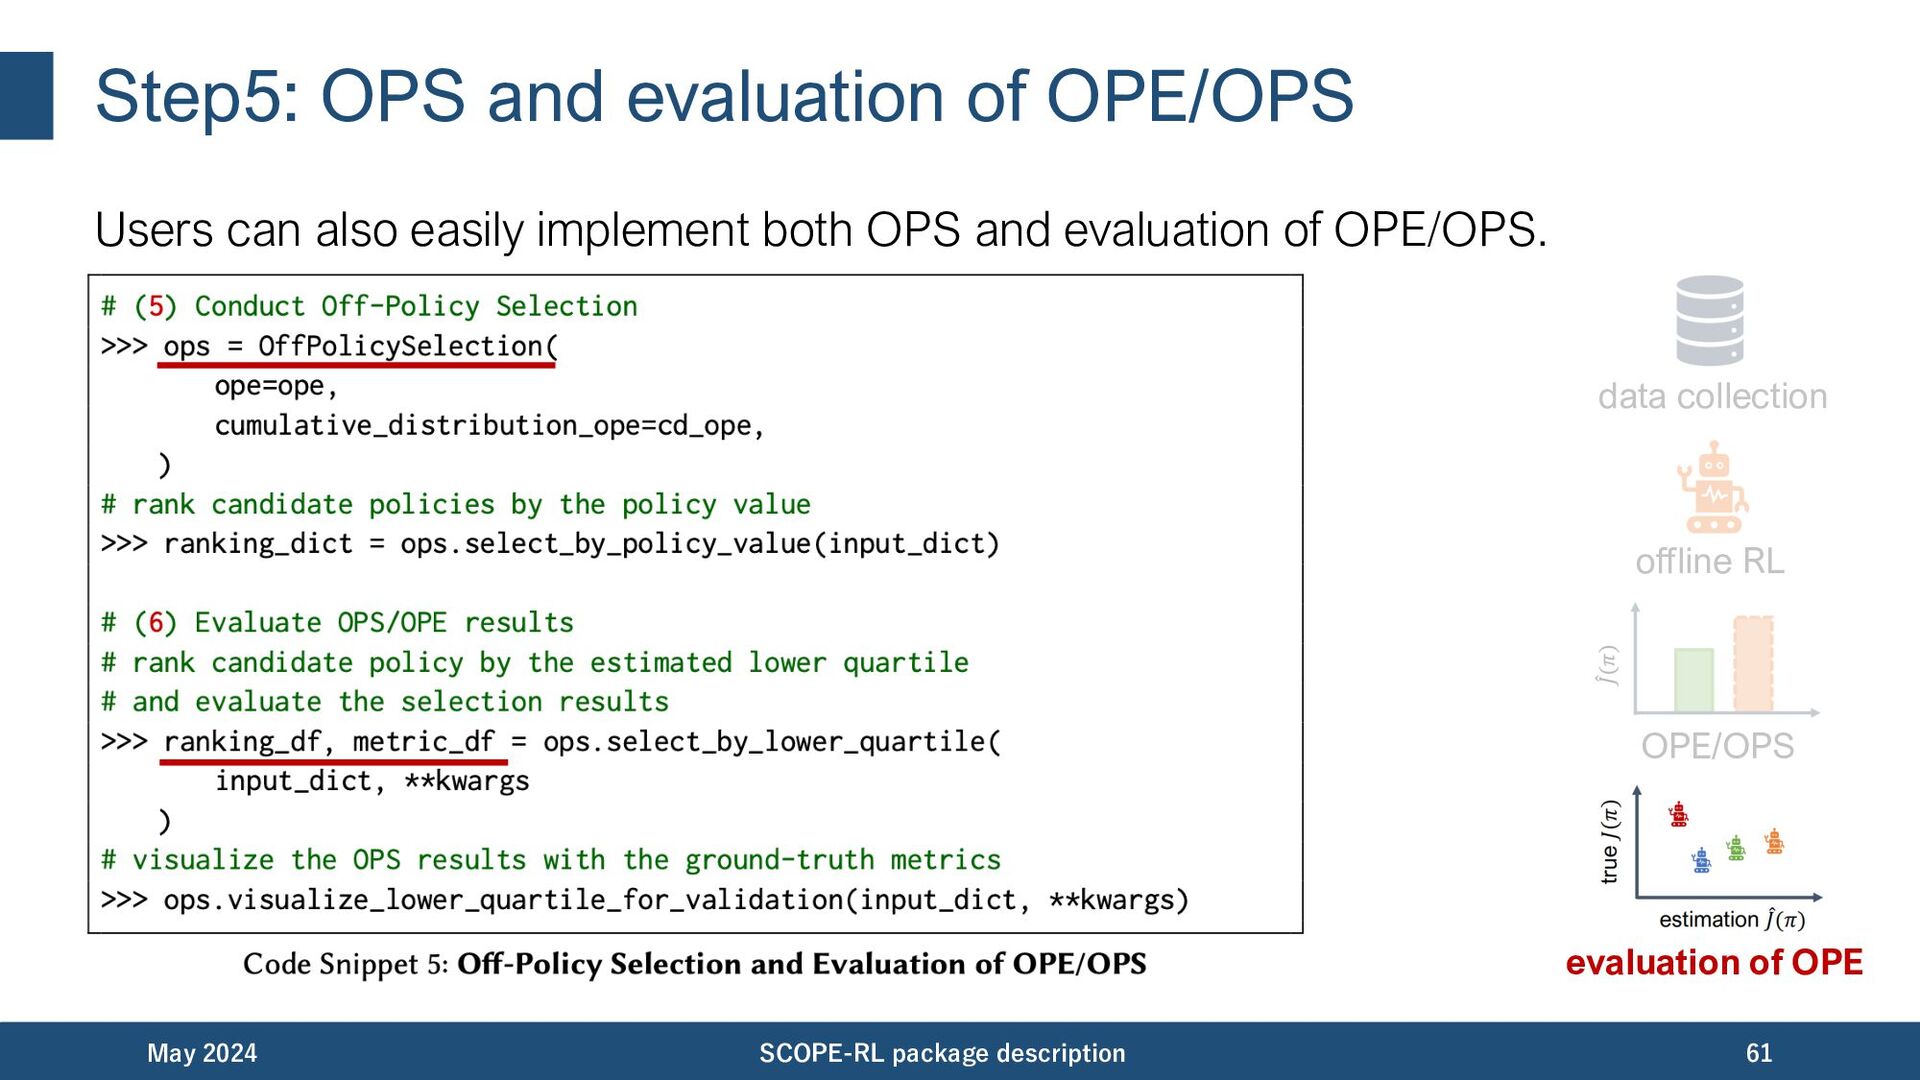
Step5: OPS and evaluation of OPE/OPS Users can also easily
implement both OPS and evaluation of OPE/OPS. May 2024 SCOPE-RL package description 61 data collection offline RL OPE/OPS evaluation of OPE -
Step5: OPS and evaluation of OPE/OPS Users can also easily
implement both OPS and evaluation of OPE/OPS. May 2024 SCOPE-RL package description 62 comparing the true (x) and estimated (y) variance evaluating the quality of OPS results -
Step6: Evaluating the risk-return tradeoff of OPE/OPS Users can also
compare top-𝑘 policy selection results. May 2024 SCOPE-RL package description 63 data collection offline RL OPE/OPS evaluation of OPE -
Implemented OPE estimators and metrics May 2024 SCOPE-RL package description
64 p65-79: standard OPE p80-85: cumulative distribution OPE P86-96: assessment protocols of OPE -
Preliminary May 2024 SCOPE-RL package description 65 Markov Decision Process
(MDP) is defined as . • : state • : action • : reward • : timestep • : state transition • : reward function • : discount • : trajectory ▼ our interest -
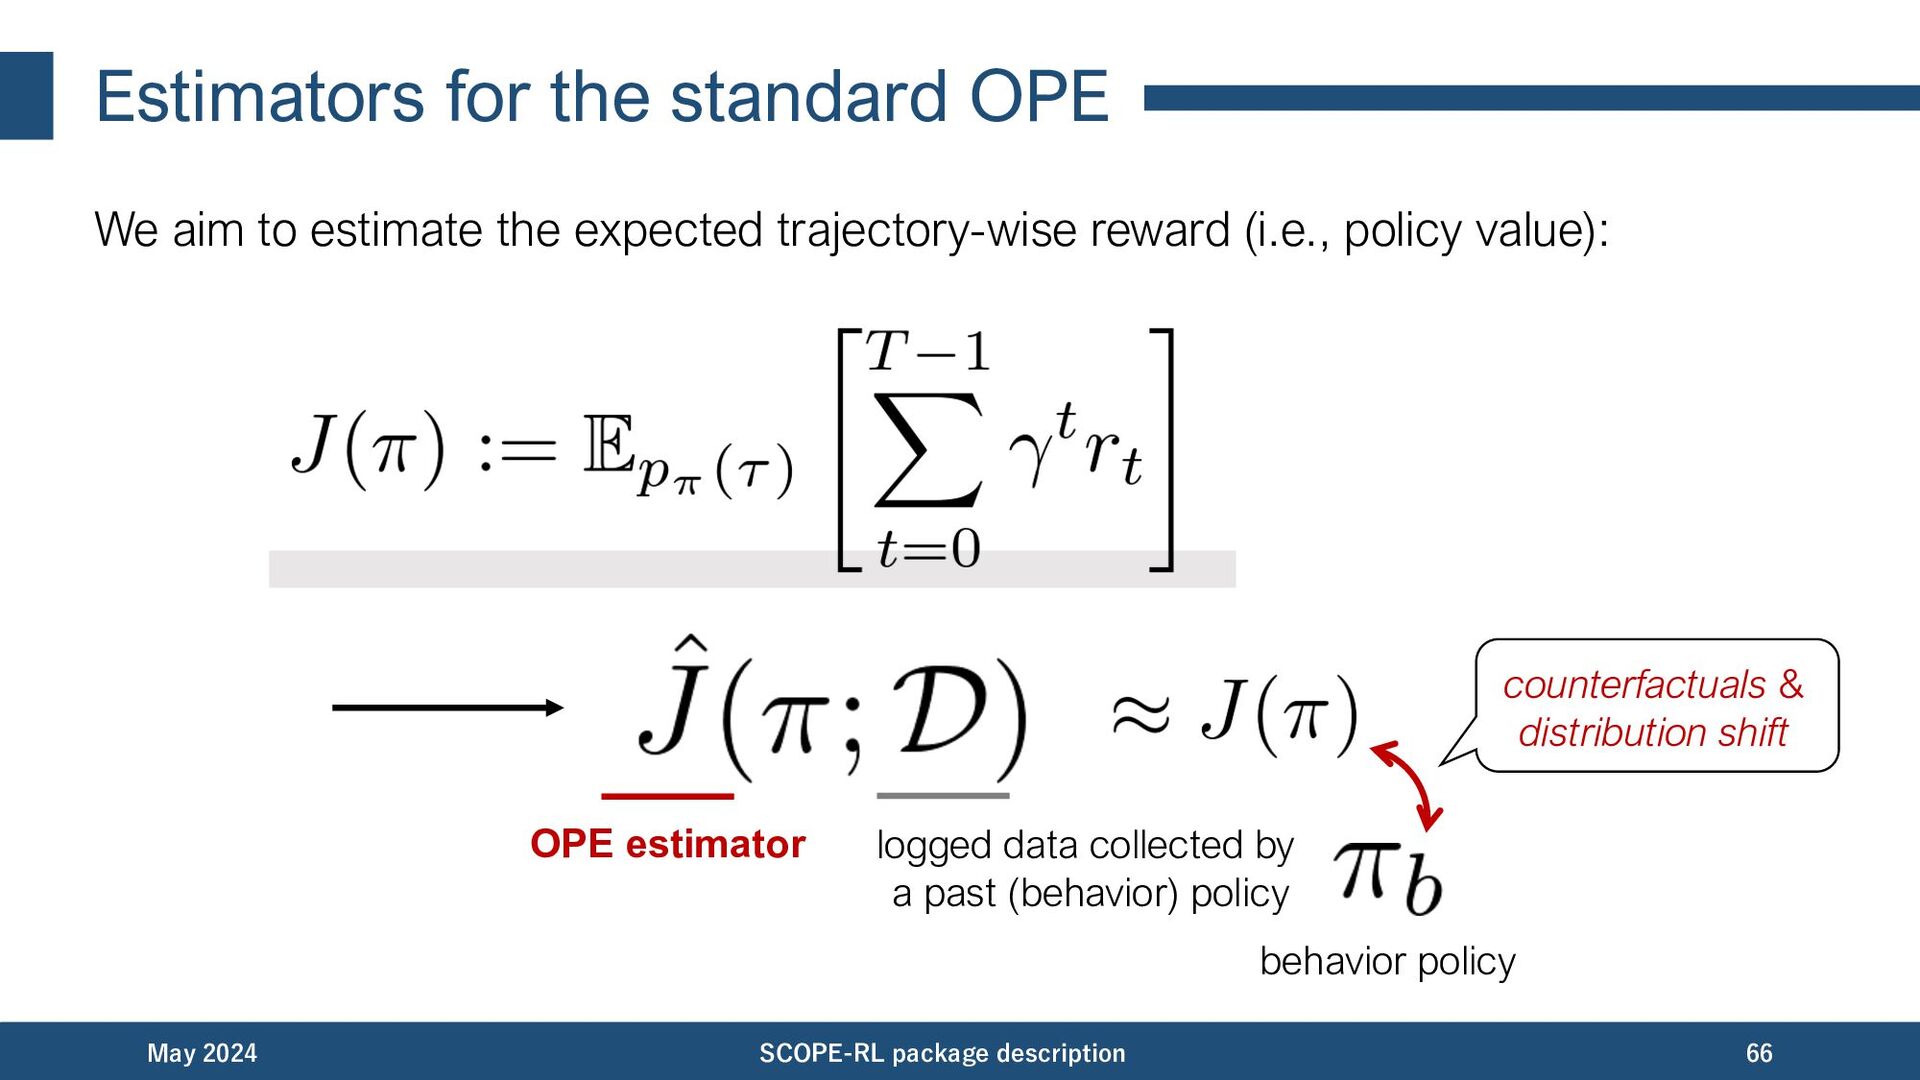
Estimators for the standard OPE We aim to estimate the
expected trajectory-wise reward (i.e., policy value): May 2024 SCOPE-RL package description 66 OPE estimator logged data collected by a past (behavior) policy counterfactuals & distribution shift behavior policy -
Direct Method (DM) [Le+,19] DM trains a value predictor and
estimates the policy value from the prediction. Pros: variance is small. Cons: bias can be large when & 𝑄 is inaccurate. May 2024 SCOPE-RL package description 67 value prediction estimating expected reward at future timesteps empirical average (𝑛 is the data size and 𝑖 is the index) -
Per-Decision Importance Sampling (PDIS) [Precup+,00] PDIS applies importance sampling to
correct the distribution shift. Pros: unbiased (under the common support assumption: ). Cons: variance can be exponentially large as 𝑡 grows. May 2024 SCOPE-RL package description 68 importance weight = product of step-wise iimportance weights -
Doubly Robust (DR) [Jiang&Li,16] [Thomas&Brunskill,16] DR is a hydrid of
DM and IPS, which apply importance sampling only on the residual. May 2024 SCOPE-RL package description 69 (recursive form) importance weight is multiplied on the residual value after timestep 𝒕 -
Doubly Robust (DR) [Jiang&Li,16] [Thomas&Brunskill,16] DR is a hydrid of
DM and IPS, which apply importance sampling only on the residual. Pros: unbiased and often reduce variance compared to PDIS. Cons: can still suffer from high variance when 𝑡 is large. May 2024 SCOPE-RL package description 70 -
State-action Marginal IS (SAM-IS) [Uehara+,20] To alleviate variance, SAM-IS considers
IS on the (state-action) marginal distribution. Pros: unbiased when ) 𝜌 is correct and reduces variance compared to PDIS. Cons: accurate estimation of ) 𝜌 is often challenging, resulting in some bias. May 2024 SCOPE-RL package description 71 (estimated) marginal importance weight state-action visitation probability -
State-action Marginal DR (SAM-DR) [Uehara+,20] SAM-DR is a DR variant
that leverages the (state-action) marginal distribution. Pros: unbiased when ) 𝜌 or & 𝑄 is accurate and reduces variance compared to DR. Cons: accurate estimation of ) 𝜌 is often challenging, resulting in some bias. May 2024 SCOPE-RL package description 72 marginal importance weight is multiplied on the residual -
State Marginal estimators (SM-IS/DR) [Liu+,18] Likewise, state marginal estimators uses
the (state) marginal importance weights. where is the (estimated) state marginal importance weight. is the step-wise importance weight at timestep 𝑡. May 2024 SCOPE-RL package description 73 -
Spectrum of Off-Policy Evaluation (SOPE) [Yuan+,21] SOPE interpolates between marginal
IS and per-decision IS to balance bias-variance. May 2024 SCOPE-RL package description 74 -
Spectrum of Off-Policy Evaluation (SOPE) [Yuan+,21] For example, SAM-IS/DR w/
SOPE are defined as follows. May 2024 SCOPE-RL package description 75 -
Double Reinforcement Learning (DRL) [Kallus&Uehara,20] DRL achieves the lowerest variance
among unbiased estimators. DRL also uses cross-]tting, which estimate ) 𝜌 and & 𝑄 on 𝐷\𝐷𝑘 and estimate - 𝐽 on 𝐷𝑘 (i.e., different subsets of data), to alleviate potential bias in estimation. May 2024 SCOPE-RL package description 76 (reference) cross-fitting -
Self-normalized estimators [Kallus&Uehara,19] Self-normalized estimators alleviate variance by modifying the
importance weight. Self-normalized estimators are no longer unbiased, but remains consistent. May 2024 SCOPE-RL package description 77 -
Self-normalized estimators [Kallus&Uehara,19] Self-normalized estimators alleviate variance by modifying the
importance weight. May 2024 SCOPE-RL package description 78 -
Extension to continuous action spaces [Kallus&Zhou,18] As the naive importance
weight rejects almost all actions , we exploit similarity between actions using a kernel. May 2024 SCOPE-RL package description 79 kernel function (e.g., Gaussian kernel) -
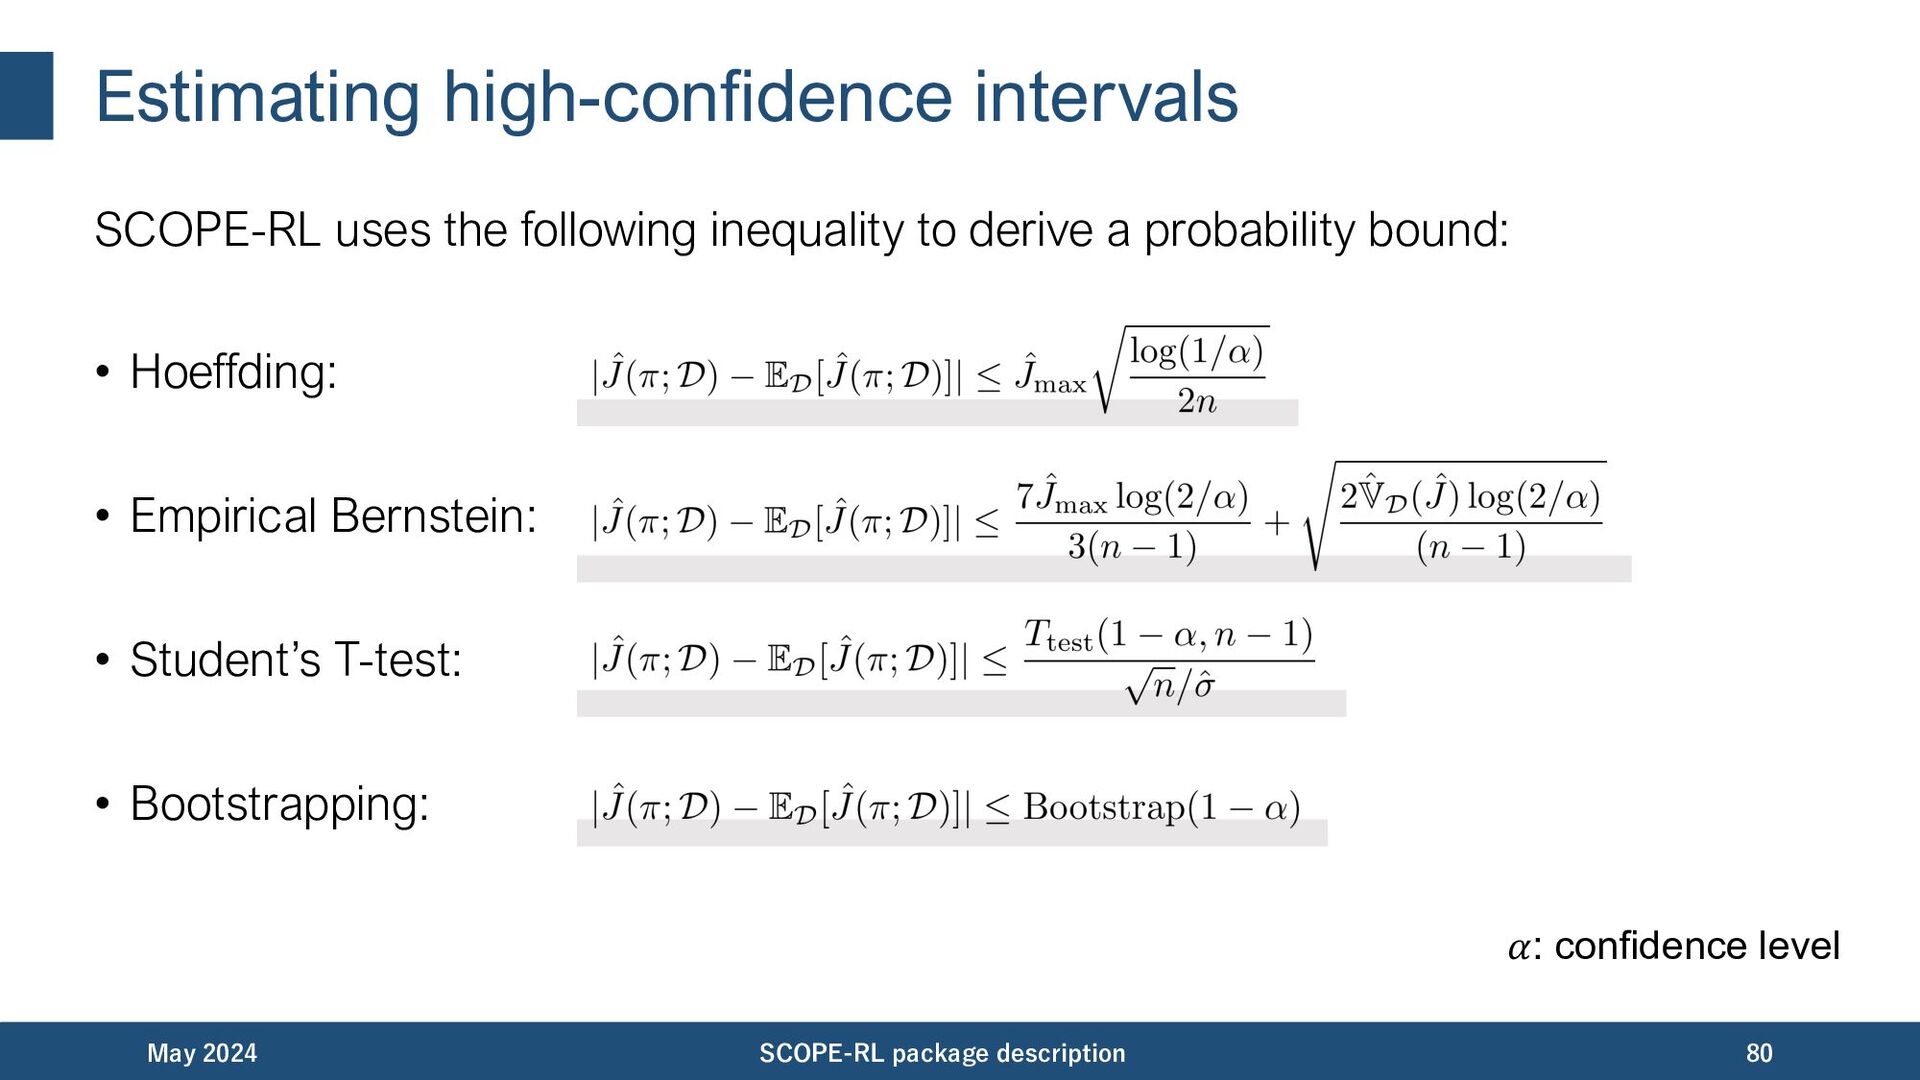
Estimating high-conXdence intervals SCOPE-RL uses the following inequality to derive
a probability bound: • Hoeffding: • Empirical Bernstein: • Student’s T-test: • Bootstrapping: May 2024 SCOPE-RL package description 80 𝛼: confidence level -
Estimators for the cumulative distribution OPE Cumlative distribution OPE (CD-OPE)
estimates the whole performance distribution. May 2024 SCOPE-RL package description 81 𝐹(𝜋) enable us to compare the worst-case policy value reward threshold -
Estimators for the cumulative distribution OPE Cumlative distribution OPE (CD-OPE)
estimates the whole performance distribution. May 2024 SCOPE-RL package description 82 OPE estimator 𝐹(𝜋) [Chandak+,21] [Huang+,21,22] reward threshold -
DM for CD-OPE DM is a model-based approach, which uses
predicted reward. May 2024 SCOPE-RL package description 83 reward prediction -
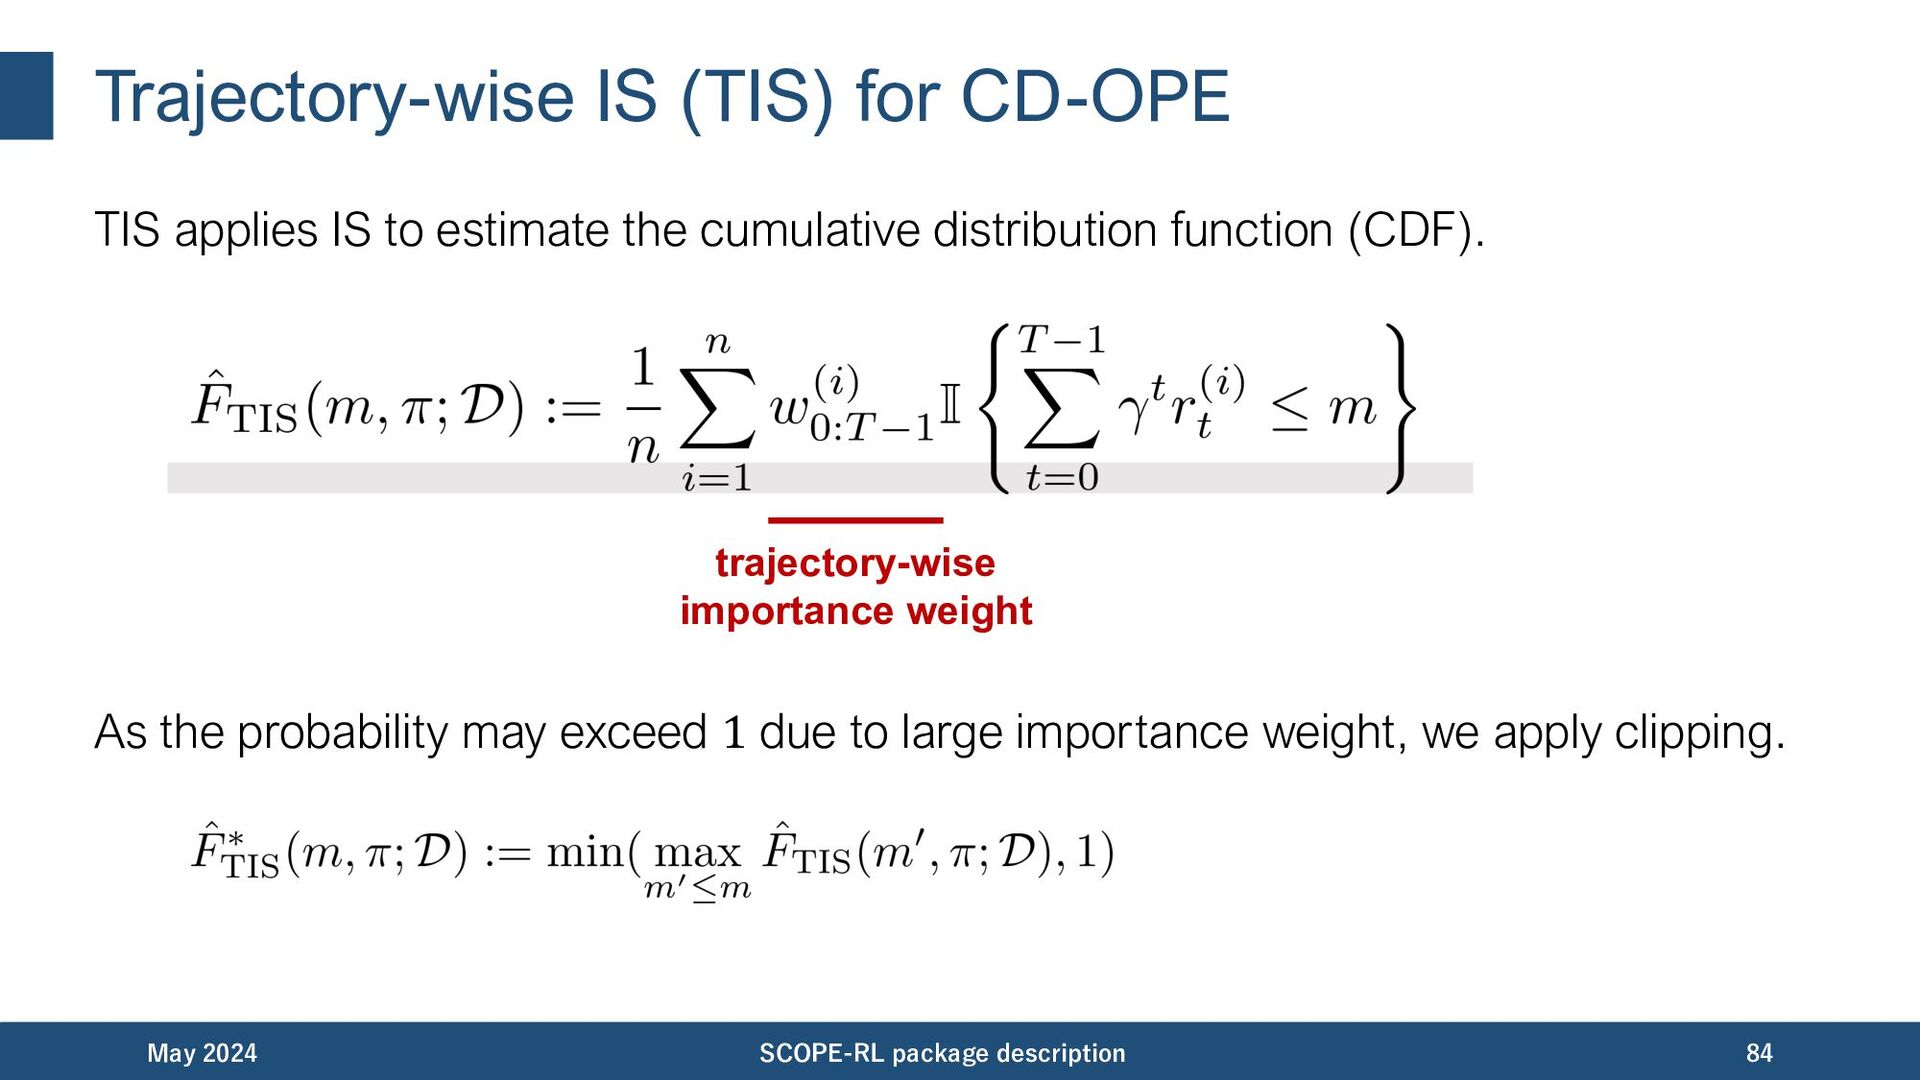
Trajectory-wise IS (TIS) for CD-OPE TIS applies IS to estimate
the cumulative distribution function (CDF). As the probability may exceed 1 due to large importance weight, we apply clipping. May 2024 SCOPE-RL package description 84 trajectory-wise importance weight -
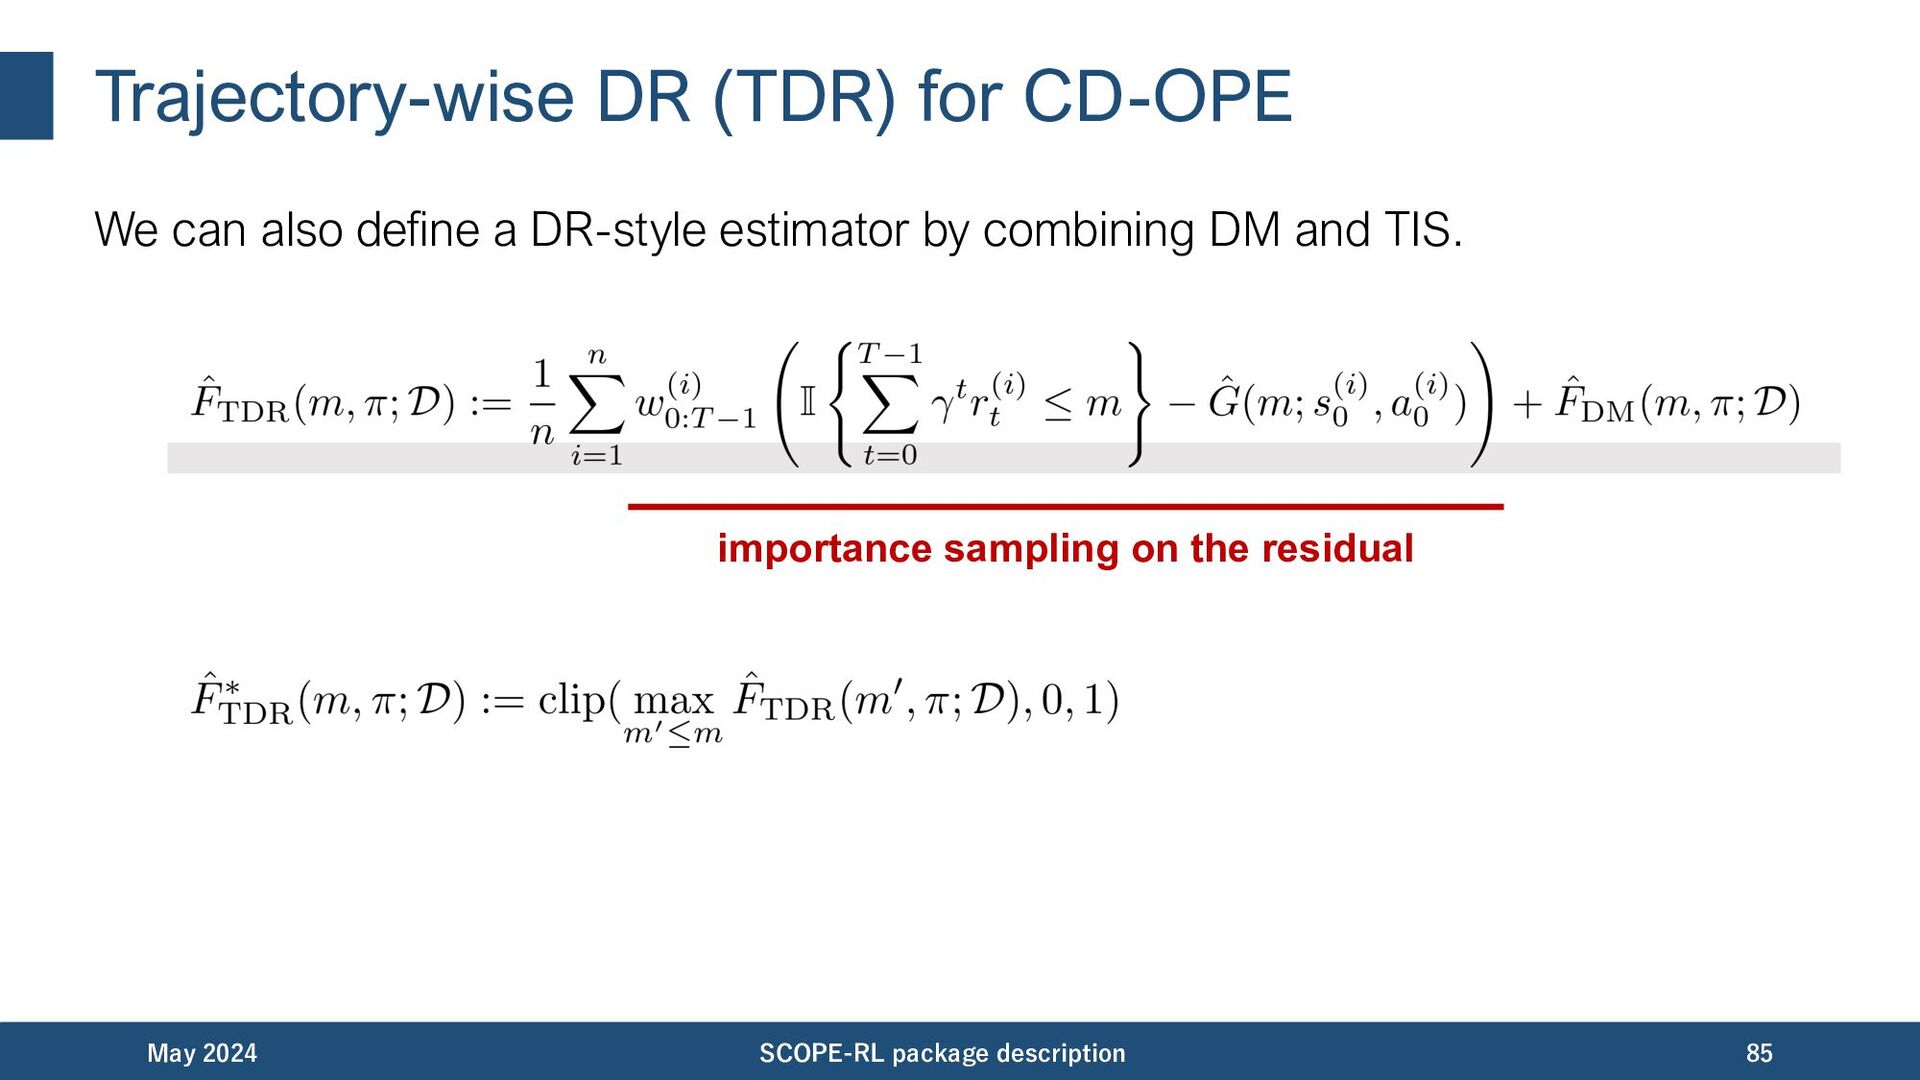
Trajectory-wise DR (TDR) for CD-OPE We can also define a
DR-style estimator by combining DM and TIS. May 2024 SCOPE-RL package description 85 importance sampling on the residual -
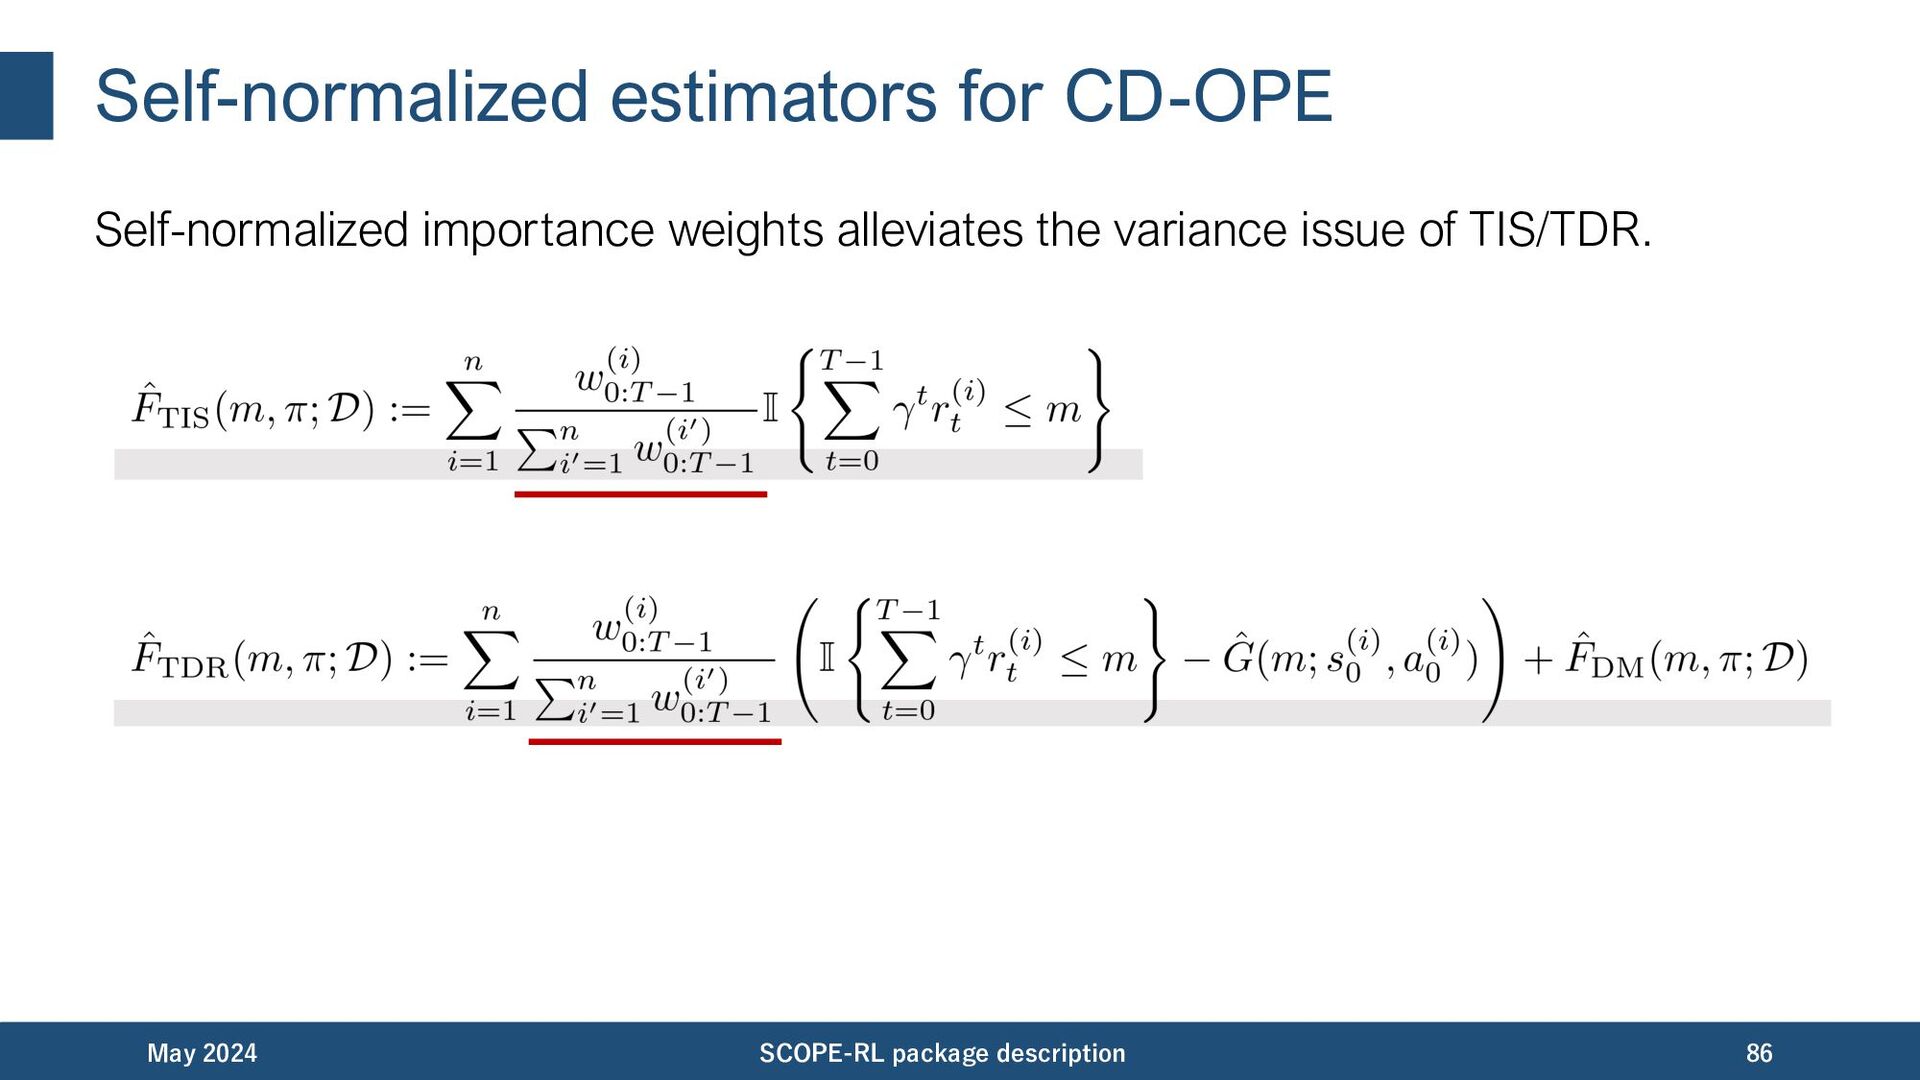
Self-normalized estimators for CD-OPE Self-normalized importance weights alleviates the variance
issue of TIS/TDR. May 2024 SCOPE-RL package description 86 -
Implemented conventional assessment metrics There are four metrics used to
assess the accuracy of OPE. • Mean squared error (MSE) – “accuracy” of policy evaluation • Rank correlation (RankCorr) – “accuracy” of policy alignment • Regret – “accuracy” of policy selection • Type I and Type II error rates – “accuracy” of safety validation May 2024 SCOPE-RL package description 87 -
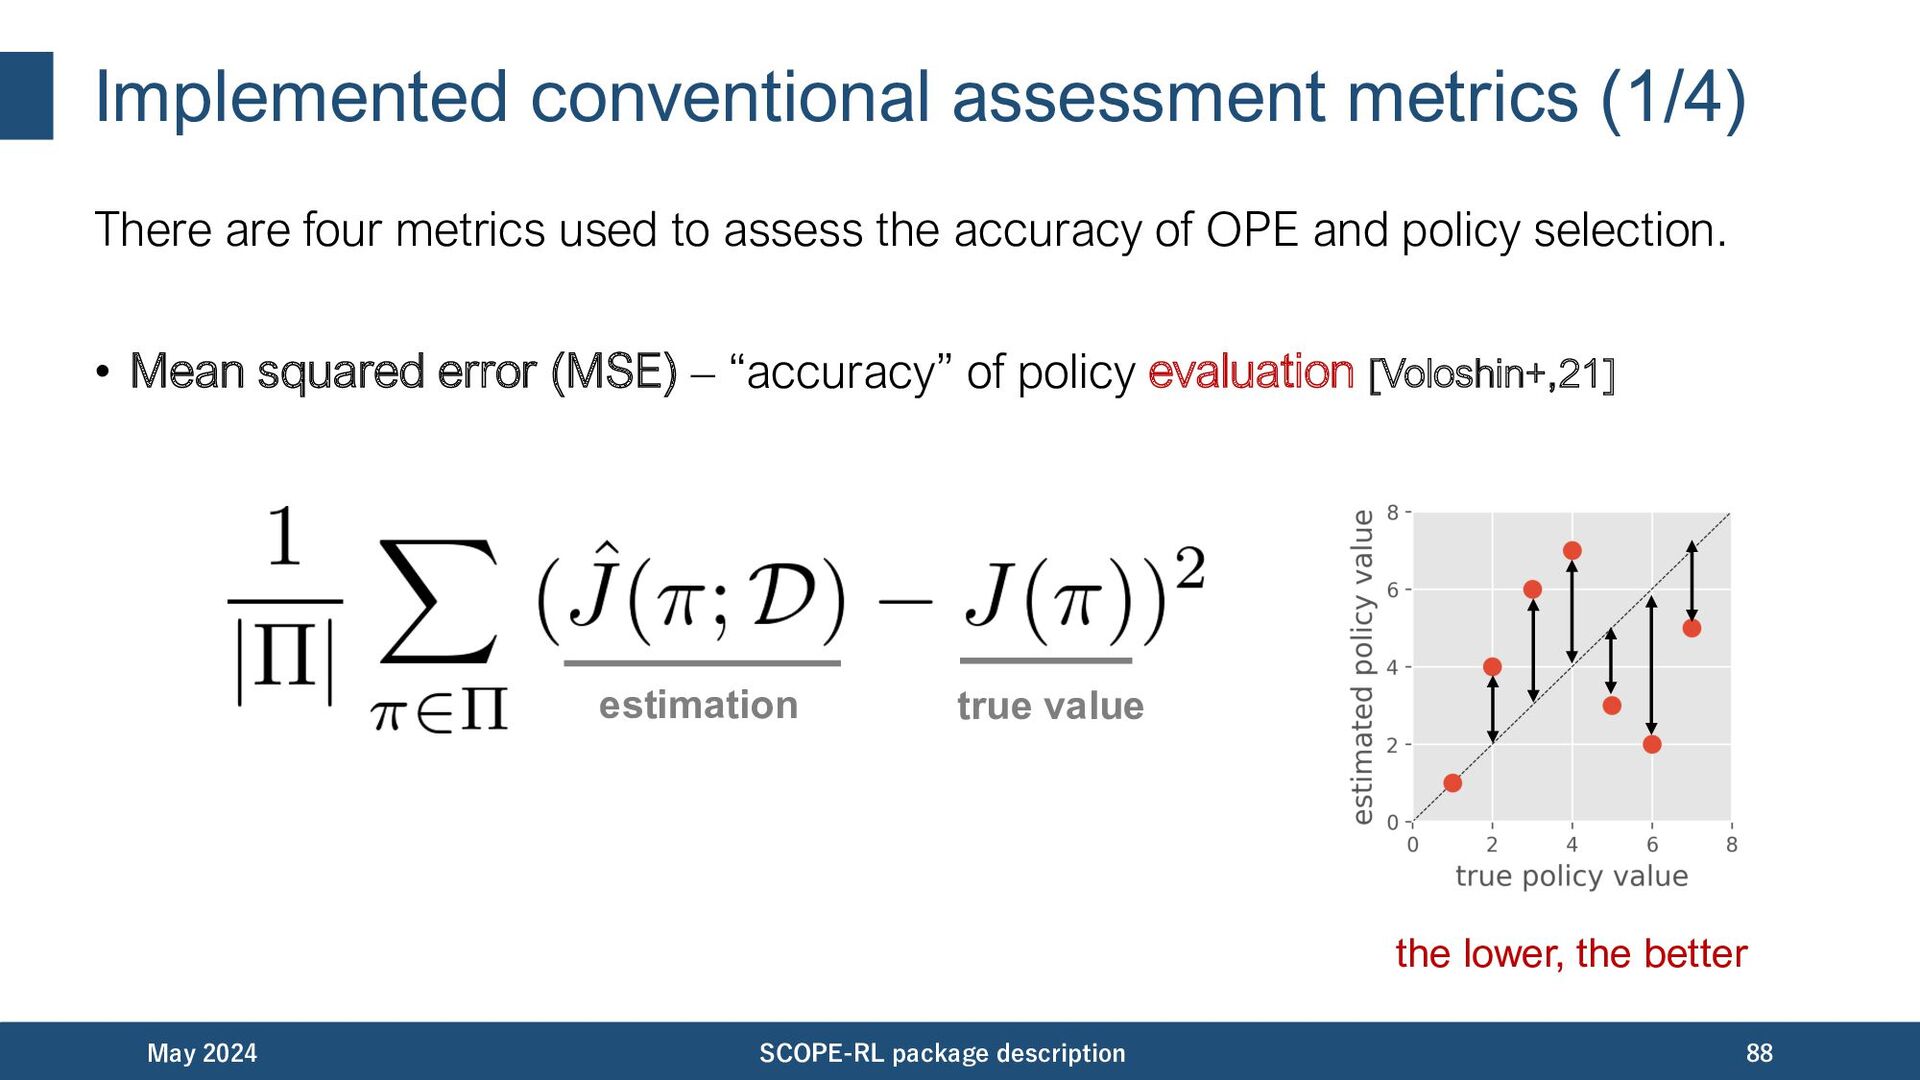
Implemented conventional assessment metrics (1/4) There are four metrics used
to assess the accuracy of OPE and policy selection. • Mean squared error (MSE) – “accuracy” of policy evaluation [Voloshin+,21] May 2024 SCOPE-RL package description 88 estimation true value the lower, the better -
Implemented conventional assessment metrics (2/4) There are four metrics used
to assess the accuracy of OPE/OPS. • Rank correlation (RankCorr) – “accuracy” of policy alignment [Fu+,21] May 2024 SCOPE-RL package description 89 1 2 3 4 5 6 7 estimation true ranking the higher, the better -
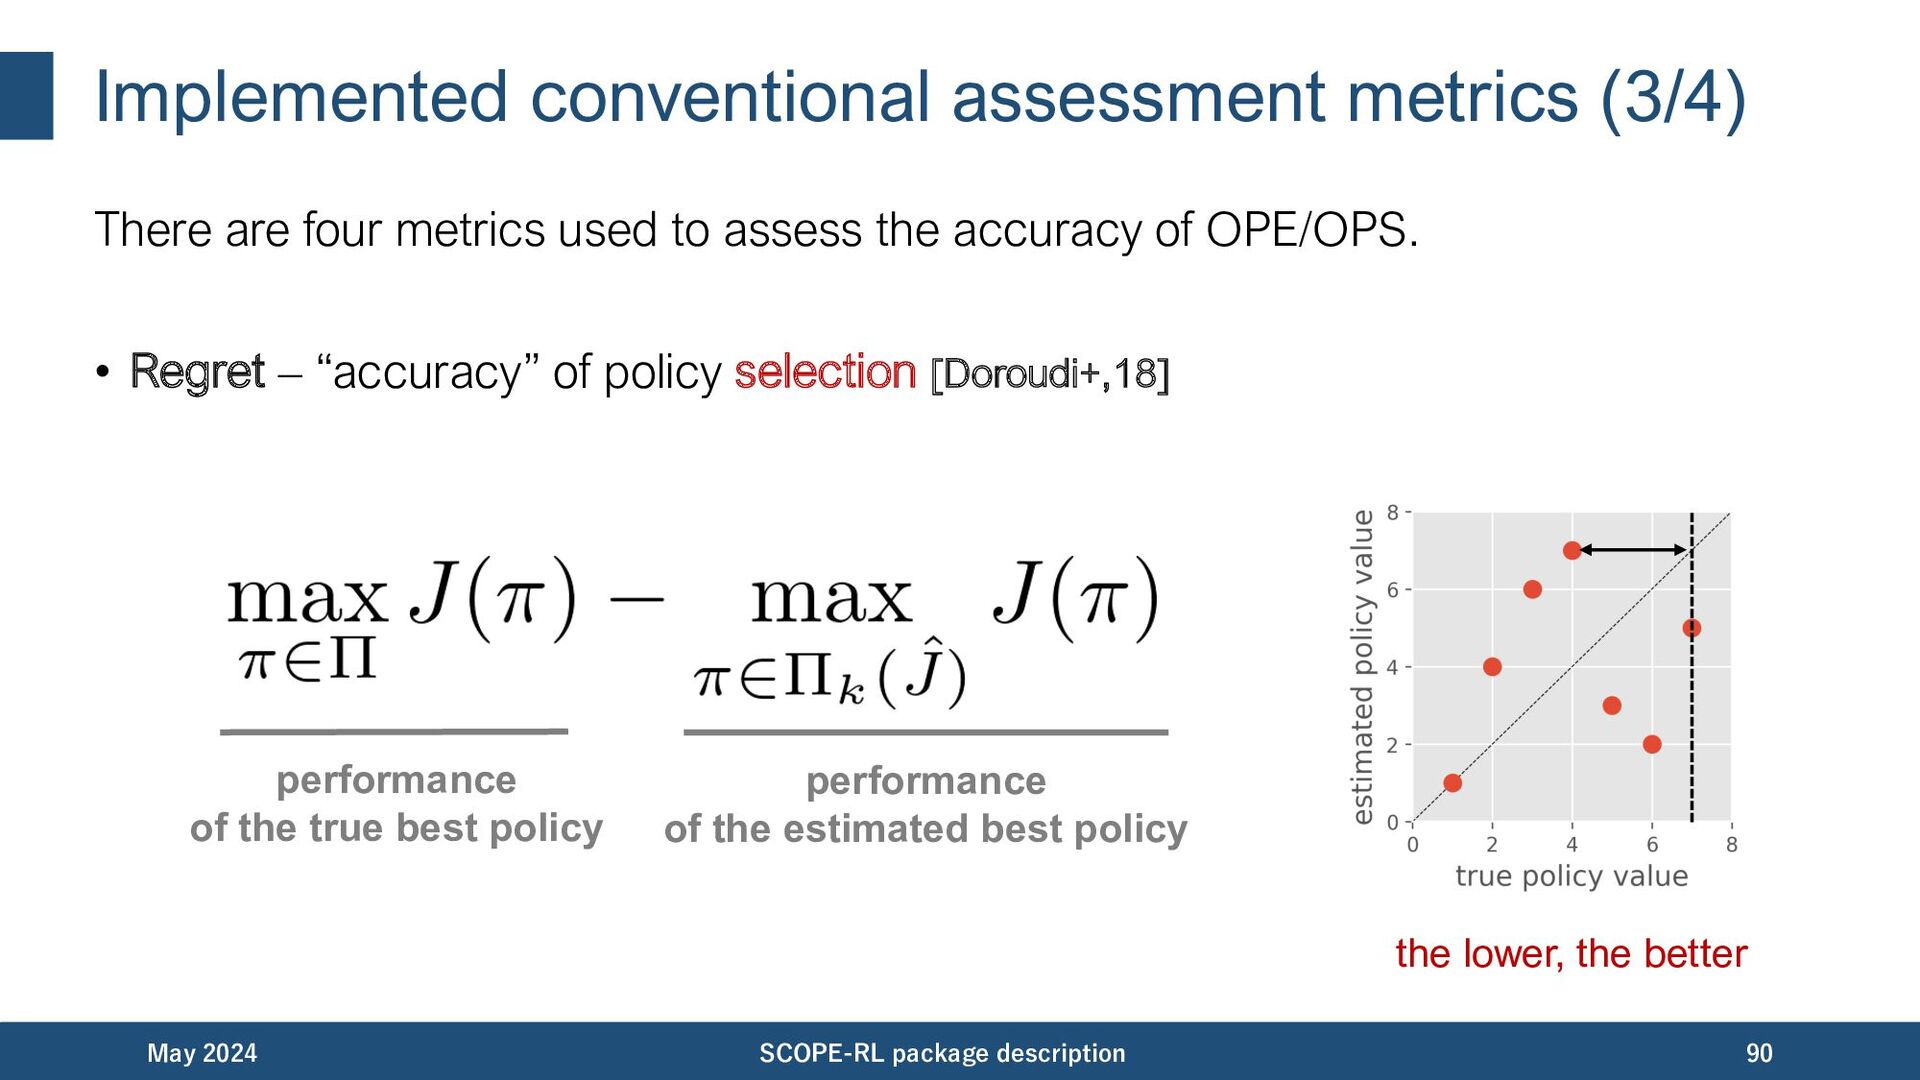
Implemented conventional assessment metrics (3/4) There are four metrics used
to assess the accuracy of OPE/OPS. • Regret – “accuracy” of policy selection [Doroudi+,18] May 2024 SCOPE-RL package description 90 performance of the true best policy performance of the estimated best policy the lower, the better -
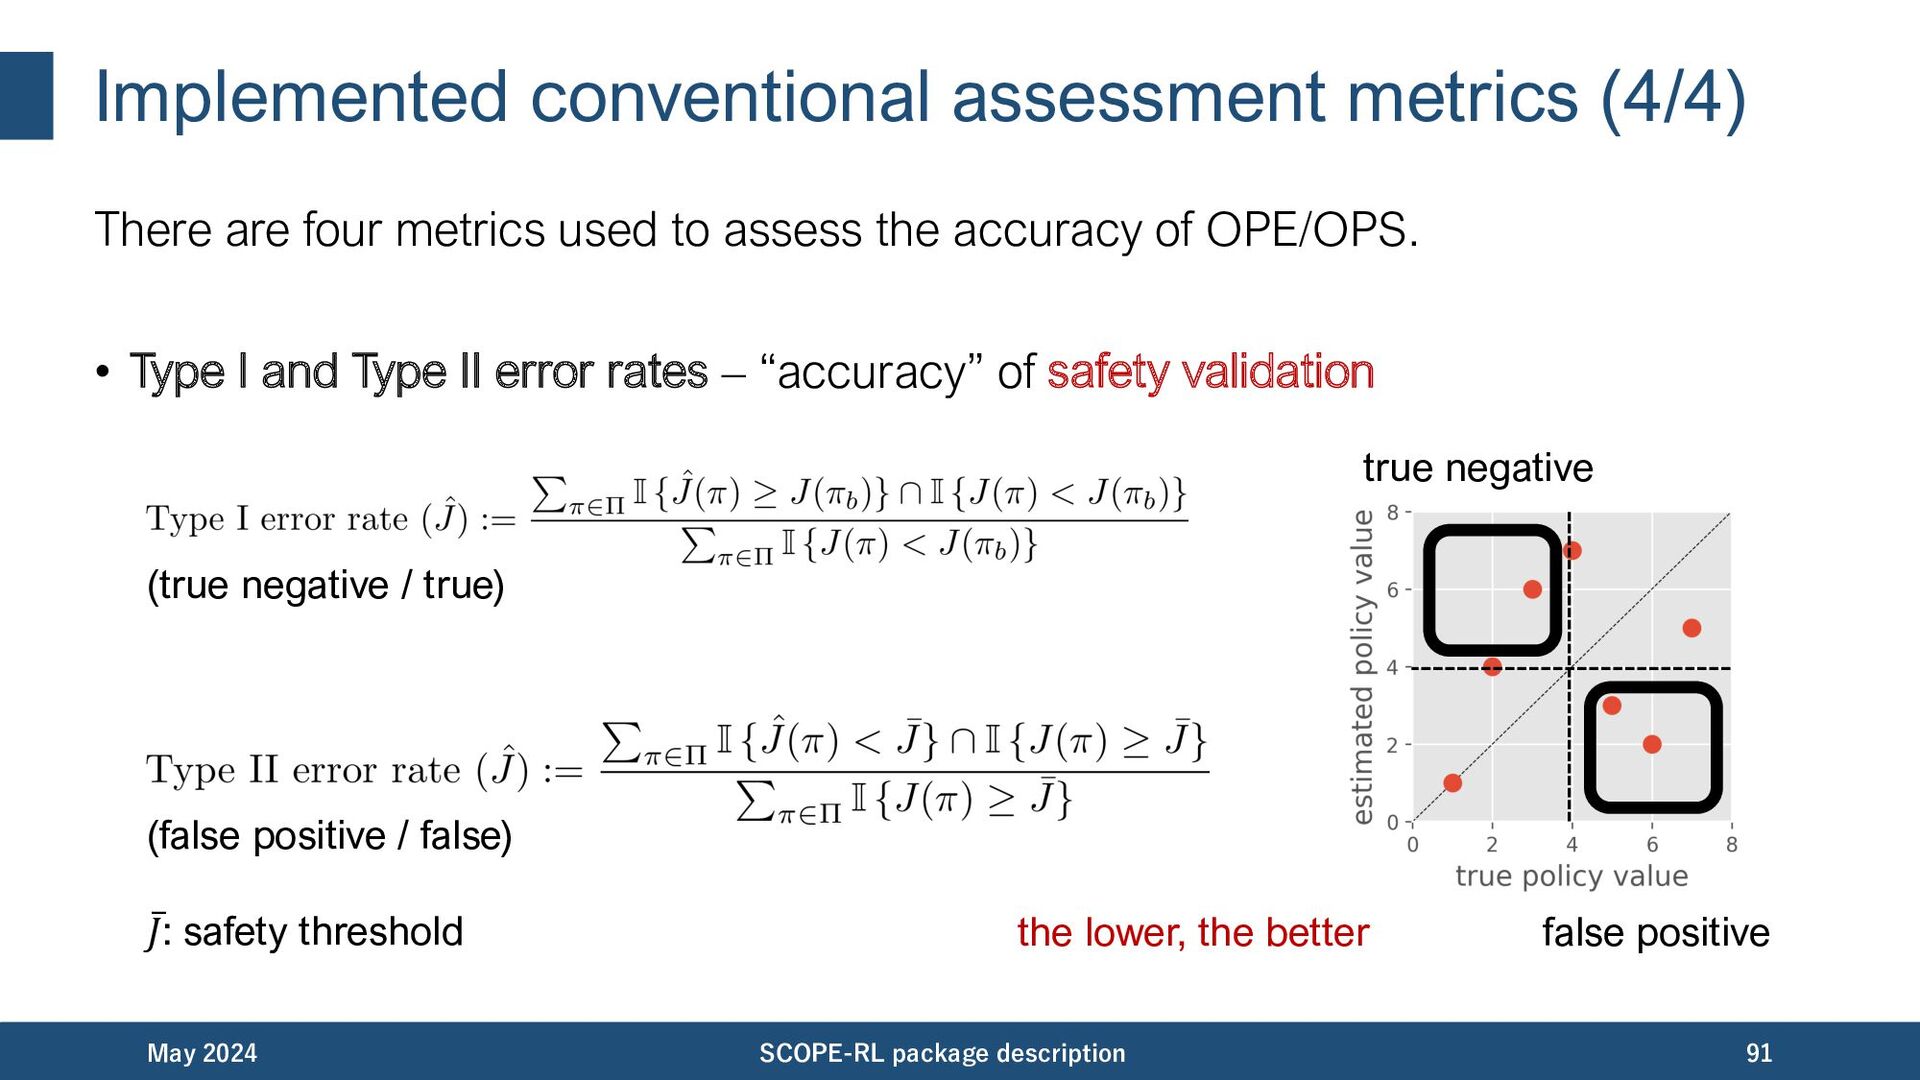
Implemented conventional assessment metrics (4/4) There are four metrics used
to assess the accuracy of OPE/OPS. • Type I and Type II error rates – “accuracy” of safety validation May 2024 SCOPE-RL package description 91 false positive true negative ̅ 𝐽: safety threshold (true negative / true) (false positive / false) the lower, the better -
Top-𝑘 risk-return tradeoff metrics SCOPE-RL additionally reports the statistics of
top-𝑘 policy portfolio selected by OPE. • best@𝑘 (return): measures the performance of the final production policy. • worst@𝑘, mean@𝑘, std@𝑘, safety violation rate@𝑘 (risk): measures the risk of deploying poor-performing policies in online A/B tests. • SharpeRatio@k (efficiency): measures the return (best@𝑘) over the risk-free baseline (𝐽(𝜋)), discounted by the risk of deploying poor policies (std@𝑘). May 2024 SCOPE-RL package description 92 -
Top-𝑘 risk-return tradeoff metrics SCOPE-RL additionally reports the statistics of
top-𝑘 policy portfolio selected by OPE. • best@𝑘 (return; the higher, the better): measures the performance of the ]nal production policy. May 2024 SCOPE-RL package description 93 -
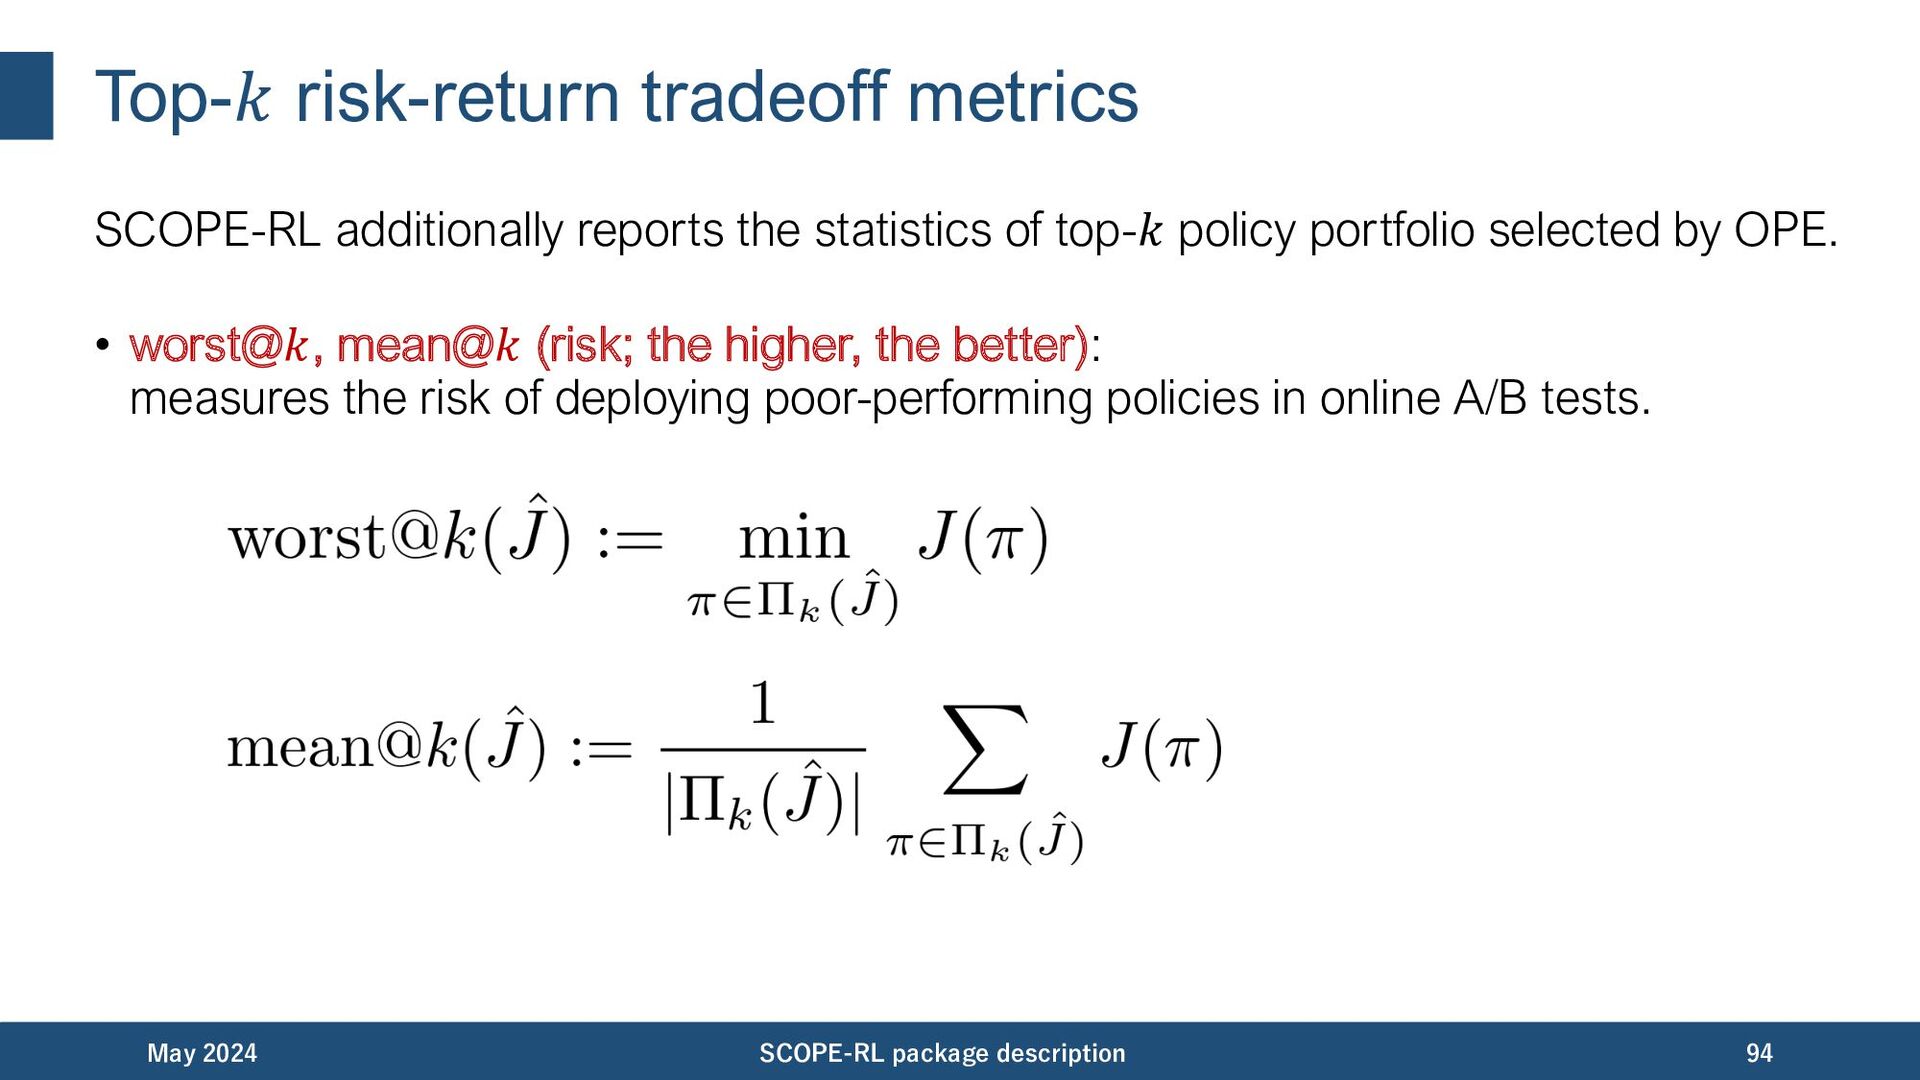
Top-𝑘 risk-return tradeoff metrics SCOPE-RL additionally reports the statistics of
top-𝑘 policy portfolio selected by OPE. • worst@𝑘, mean@𝑘 (risk; the higher, the better): measures the risk of deploying poor-performing policies in online A/B tests. May 2024 SCOPE-RL package description 94 -
Top-𝑘 risk-return tradeoff metrics SCOPE-RL additionally reports the statistics of
top-𝑘 policy portfolio selected by OPE. • std@𝑘 (risk; the lower, the better): measures the risk of deploying poor-performing policies in online A/B tests. May 2024 SCOPE-RL package description 95 -
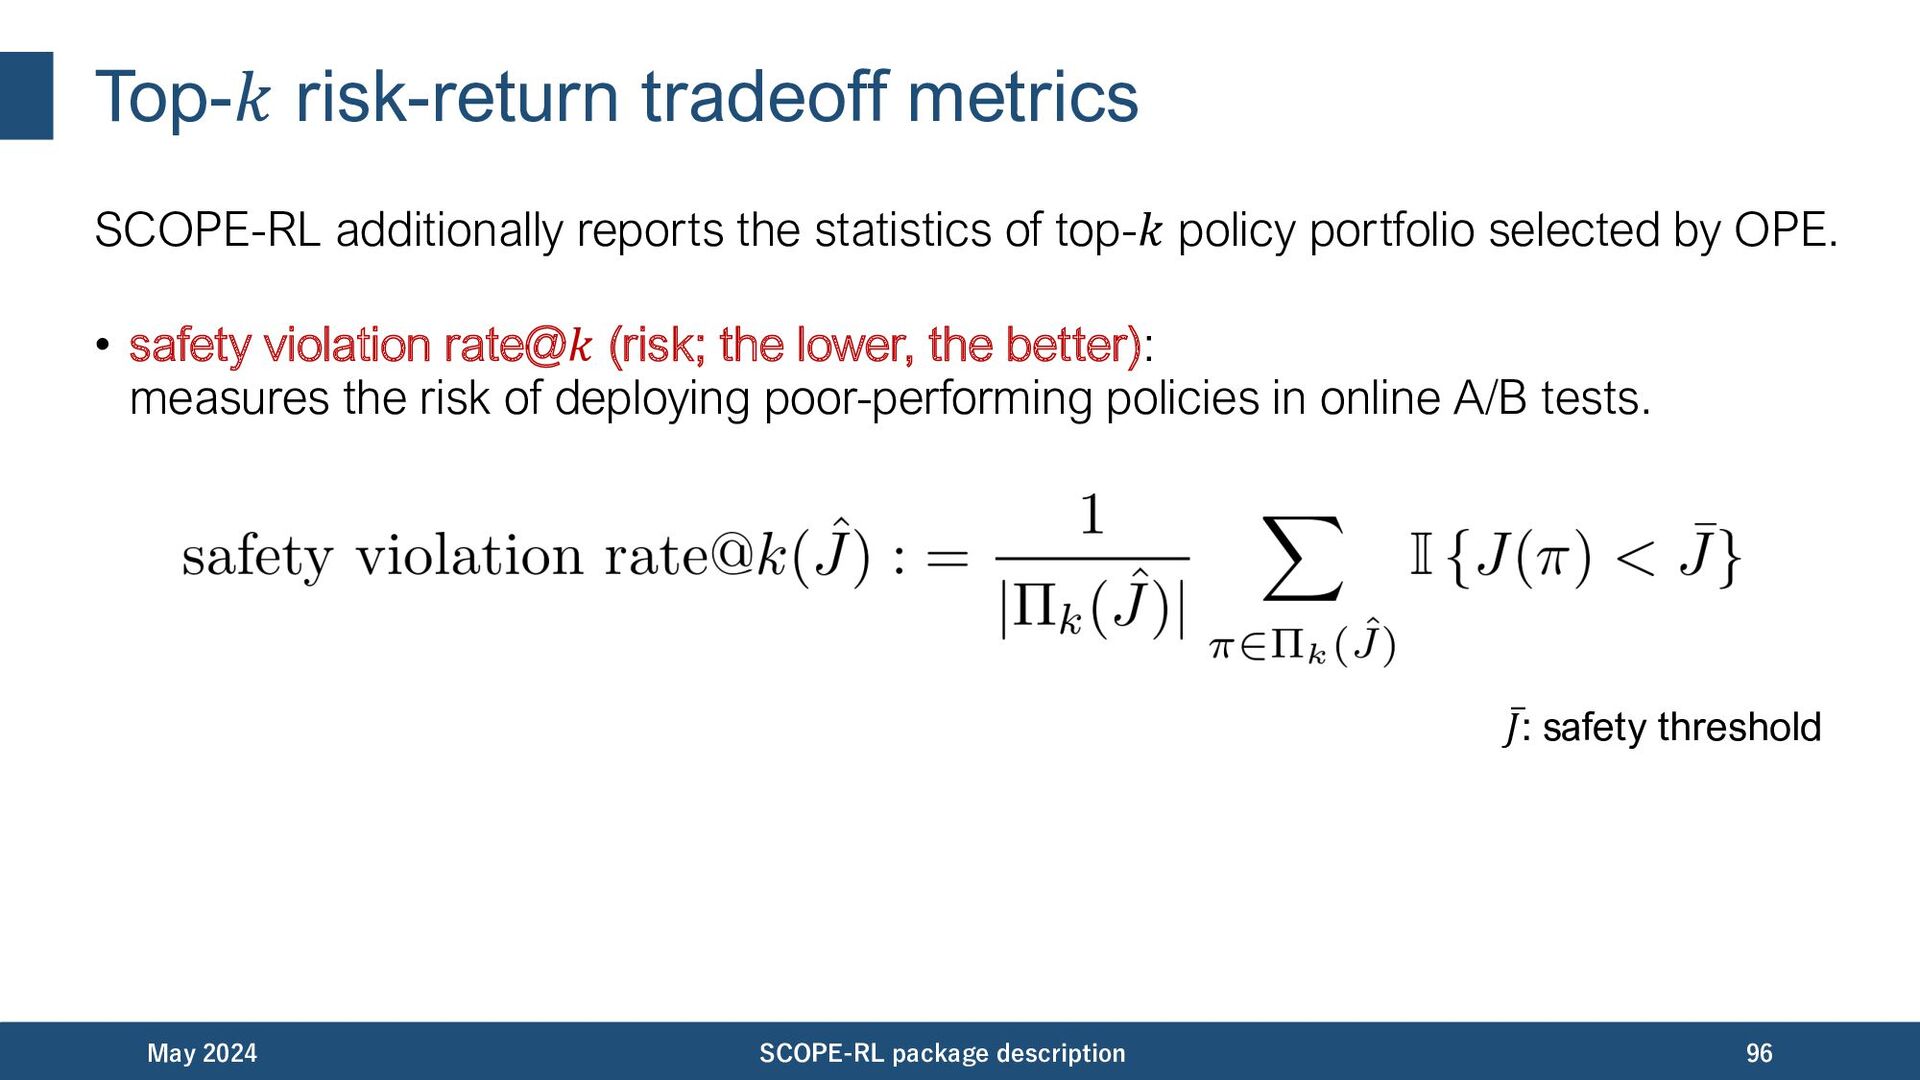
Top-𝑘 risk-return tradeoff metrics SCOPE-RL additionally reports the statistics of
top-𝑘 policy portfolio selected by OPE. • safety violation rate@𝑘 (risk; the lower, the better): measures the risk of deploying poor-performing policies in online A/B tests. May 2024 SCOPE-RL package description 96 ̅ 𝐽: safety threshold -
Top-𝑘 risk-return tradeoff metrics SCOPE-RL additionally reports the statistics of
top-𝑘 policy portfolio selected by OPE. • SharpeRatio@k (ef]ciency; the higher, the better): [Kiyohara+,23] measures the return (best@𝑘) over the risk-free baseline (𝐽(𝜋)), discounted by the risk of deploying poor policies (std@𝑘). May 2024 SCOPE-RL package description 97 -
References (1/9) [Seno&Imai,22 (d3rlpy)] Takuma Seno and Michita Imai. “d3rlpy:
An Offline Deep Reinforcement Learning Library.” JMLR, 2022. https://arxiv.org/abs/2111.03788 [Gauci+,18 (Horizon)] Jason Gauci, Edoardo Conti, Yitao Liang, Kittipat Virochsiri, Yuchen He, Zachary Kaden, Vivek Narayanan, Xiaohui Ye, Zhengxing Chen, and Scott Fujimoto. “Horizon: Facebook's Open Source Applied Reinforcement Learning Platform.” 2018. https://arxiv.org/abs/1811.00260 [Liang+,18 (RLlib)] Eric Liang, Richard Liaw, Philipp Moritz, Robert Nishihara, Roy Fox, Ken Goldberg, Joseph E. Gonzalez, Michael I. Jordan, and Ion Stoica. “RLlib: Abstractions for Distributed Reinforcement Learning.” ICML, 2018. https://arxiv.org/abs/1712.09381 May 2024 SCOPE-RL package description 99 -
References (2/9) [Fu+,21 (DOPE)] Justin Fu, Mohammad Norouzi, Ofir Nachum,
George Tucker, Ziyu Wang, Alexander Novikov, Mengjiao Yang, Michael R. Zhang, Yutian Chen, Aviral Kumar, Cosmin Paduraru, Sergey Levine, and Tom Le Paine. “Benchmarks for Deep Off-Policy Evaluation.” ICLR, 2021. https://arxiv.org/abs/2103.16596 [Voloshin+,21 (COBS)] Cameron Voloshin, Hoang M. Le, Nan Jiang, and Yisong Yue. “Empirical Study of Off-Policy Policy Evaluation for Reinforcement Learning.” NeurIPS dataset&benchmark, 2021. https://arxiv.org/abs/1911.06854 [Rohde+,18 (RecoGym)] David Rohde, Stephen Bonner, Travis Dunlop, Flavian Vasile, and Alexandros Karatzoglou “RecoGym: A Reinforcement Learning Environment for the problem of Product Recommendation in Online Advertising.” 2018. https://arxiv.org/abs/1808.00720 May 2024 SCOPE-RL package description 100 -
References (3/9) [Wang+,21 (RL4RS)] Kai Wang, Zhene Zou, Yue Shang,
Qilin Deng, Minghao Zhao, Yile Liang, Runze Wu, Jianrong Tao, Xudong Shen, Tangjie Lyu, and Changjie Fan. “RL4RS: A Real-World Benchmark for Reinforcement Learning based Recommender System.” 2021. https://arxiv.org/abs/2110.11073 [Saito+,21 (OBP)] Yuta Saito, Shunsuke Aihara, Megumi Matsutani, and Yusuke Narita. “Open Bandit Dataset and Pipeline: Towards Realistic and Reproducible Off- Policy Evaluation.” NeurIPS dataset&benchmark, 2021. https://arxiv.org/abs/2008.07146 [Brockman+,16 (OpenAI Gym)] Greg Brockman, Vicki Cheung, Ludwig Pettersson, Jonas Schneider, John Schulman, Jie Tang, and Wojciech Zaremba. “OpenAI Gym.” 2016. https://arxiv.org/abs/1606.01540 May 2024 SCOPE-RL package description 101 -
References (4/9) [Kiyohara+,21 (RTBGym)] Haruka Kiyohara, Kosuke Kawakami, and Yuta
Saito. “Accelerating Offline Reinforcement Learning Application in Real-Time Bidding and Recommendation: Potential Use of Simulation.” 2021. https://arxiv.org/abs/2109.08331 [Chandak+,21 (CD-OPE)] Yash Chandak, Scott Niekum, Bruno Castro da Silva, Erik Learned-Miller, Emma Brunskill, and Philip S. Thomas. “Universal Off-Policy Evaluation.” NeurIPS, 2021. https://arxiv.org/abs/2104.12820 [Huang+,21 (CD-OPE)] Audrey Huang, Liu Leqi, Zachary C. Lipton, and Kamyar Azizzadenesheli. “Off-Policy Risk Assessment in Contextual Bandits.” NeurIPS, 2021. https://arxiv.org/abs/2104.12820 May 2024 SCOPE-RL package description 102 -
References (5/9) [Huang+,22 (CD-OPE)] Audrey Huang, Liu Leqi, Zachary C.
Lipton, and Kamyar Azizzadenesheli. “Off-Policy Risk Assessment for Markov Decision Processes.” AISTATS, 2022. https://proceedings.mlr.press/v151/huang22b.html [Hasselt+,16 (DDQN)] Hado van Hasselt, Arthur Guez, and David Silver. “Deep Reinforcement Learning with Double Q-learning.” AAAI, 2016. https://arxiv.org/abs/1509.06461 [Kumar+,20 (CQL)] Aviral Kumar, Aurick Zhou, George Tucker, and Sergey Levine. “Conservative Q-Learning for Offline Reinforcement Learning.” NeurIPS, 2020. https://arxiv.org/abs/2006.04779 [Le+,19 (DM)] Hoang M. Le, Cameron Voloshin, and Yisong Yue. “Batch Policy Learning under Constraints.” ICML, 2019. https://arxiv.org/abs/1903.08738 May 2024 SCOPE-RL package description 103 -
References (6/9) [Precup+,00 (IPS)] Doina Precup, Richard S. Sutton, and
Satinder P. Singh. “Eligibility Traces for Off-Policy Policy Evaluation.” ICML, 2000. https://scholarworks.umass.edu/cgi/viewcontent.cgi?article=1079&context=cs_facult y_pubs [Jiang&Li,16 (DR)] Nan Jiang and Lihong Li. “Doubly Robust Off-policy Value Evaluation for Reinforcement Learning.” ICML, 2016. https://arxiv.org/abs/1511.03722 [Thomas&Brunskill,16 (DR)] Philip S. Thomas and Emma Brunskill. “Data-Ef]cient Off-Policy Policy Evaluation for Reinforcement Learning.” ICML, 2016. https://arxiv.org/abs/1604.00923 [Uehara+,20 (SAM-IS/DR)] Masatoshi Uehara, Jiawei Huang, Nan Jiang. “Minimax Weight and Q-Function Learning for Off-Policy Evaluation.” ICML, 2020. https://arxiv.org/abs/1910.12809 May 2024 SCOPE-RL package description 104 -
References (7/9) [Liu+,18 (SM-IS/DR)] Qiang Liu, Lihong Li, Ziyang Tang,
Dengyong Zhou. “Breaking the Curse of Horizon: Infinite-Horizon Off-Policy Estimation.” NeurIPS, 2018. https://arxiv.org/abs/1810.12429 [Yuan+,21 (SOPE)] Christina J. Yuan, Yash Chandak, Stephen Giguere, Philip S. Thomas, Scott Niekum. “SOPE: Spectrum of Off-Policy Estimators.” NeurIPS, 2021. https://arxiv.org/abs/2111.03936 [Kallus&Uehara,20 (DRL)] Nathan Kallus, Masatoshi Uehara. “Double Reinforcement Learning for Efficient Off-Policy Evaluation in Markov Decision Processes.” JMLR, 2020. https://arxiv.org/abs/1908.08526 [Kallus&Uehara,19 (Self-normalized estimators)] Nathan Kallus, Masatoshi Uehara. “Intrinsically Efficient, Stable, and Bounded Off-Policy Evaluation for Reinforcement Learning.” NeurIPS, 2019. https://arxiv.org/abs/1906.03735 May 2024 SCOPE-RL package description 105 -
References (8/9) [Kallus&Zhou,18 (extension to continuous actions)] Nathan Kallus, Angela
Zhou. “Policy Evaluation and Optimization with Continuous Treatments.” AISTATS, 2018. https://arxiv.org/abs/1802.06037 [Thomas+,15 (high-confidence OPE)] Philip S. Thomas, Georgios Theocharous, Mohammad Ghavamzadeh. “High Confidence Off-Policy Evaluation.” AAAI, 2015. https://people.cs.umass.edu/~pthomas/papers/Thomas2015.pdf [Thomas+,15 (high-confidence OPE)] Philip S. Thomas, Georgios Theocharous, Mohammad Ghavamzadeh. “High Confidence Policy Improvement.” ICML, 2015. https://people.cs.umass.edu/~pthomas/papers/Thomas2015b.pdf [Voloshin+,21 (MSE)] Cameron Voloshin, Hoang M. Le, Nan Jiang, Yisong Yue. “Empirical Study of Off-Policy Policy Evaluation for Reinforcement Learning.” NeurIPS datasets&benchmarks, 2021. https://arxiv.org/abs/1911.06854 May 2024 SCOPE-RL package description 106 -
References (9/9) [Fu+,21 (RankCorr)] Justin Fu, Mohammad Norouzi, O]r Nachum,
George Tucker, Ziyu Wang, Alexander Novikov, Mengjiao Yang, Michael R. Zhang, Yutian Chen, Aviral Kumar, Cosmin Paduraru, Sergey Levine, Tom Le Paine. “Benchmarks for Deep Off- Policy Evaluation.” ICLR, 2021. https://arxiv.org/abs/2103.16596 [Doroudi+,18 (Regret)] Shayan Doroudi, Philip S. Thomas, Emma Brunskill. “Importance Sampling for Fair Policy Selection.” IJCAI, 2018. https://people.cs.umass.edu/~pthomas/papers/Daroudi2017.pdf [Kiyohara+,23 (SharpeRatio@k)] Haruka Kiyohara, Ren Kishimoto, Kosuke Kawakami, Ken Kobayashi, Kazuhide Nakata, Yuta Saito. “Towards Assessing and Benchmarking Risk-Return Tradeoff of Off-Policy Evaluation in Reinforcement Learning.” 2023. May 2024 SCOPE-RL package description 107
 harukakiyohara_
 rfujii
 takasehideki
 eumesy
 youten622
 shiell
 kohlerjohannes
 junkashihara
 ktanishima
 institutdelelevage
 pomcho555
 analokmaus
 ishiirikie
 uxyall
 marketingsoph
 garrettdimon
 codingconduct
 aleyda
 axbom
 minecr
 ipullrank
 livdayseo
 moore
 sarafernandez




























![References (9/9) [Fu+,21 (RankCorr)] Justin Fu, Mohammad Norouzi, O]r Nachum,](https://files.speakerdeck.com/presentations/850efe7156b742678e050aeb65058281/slide_106.jpg)