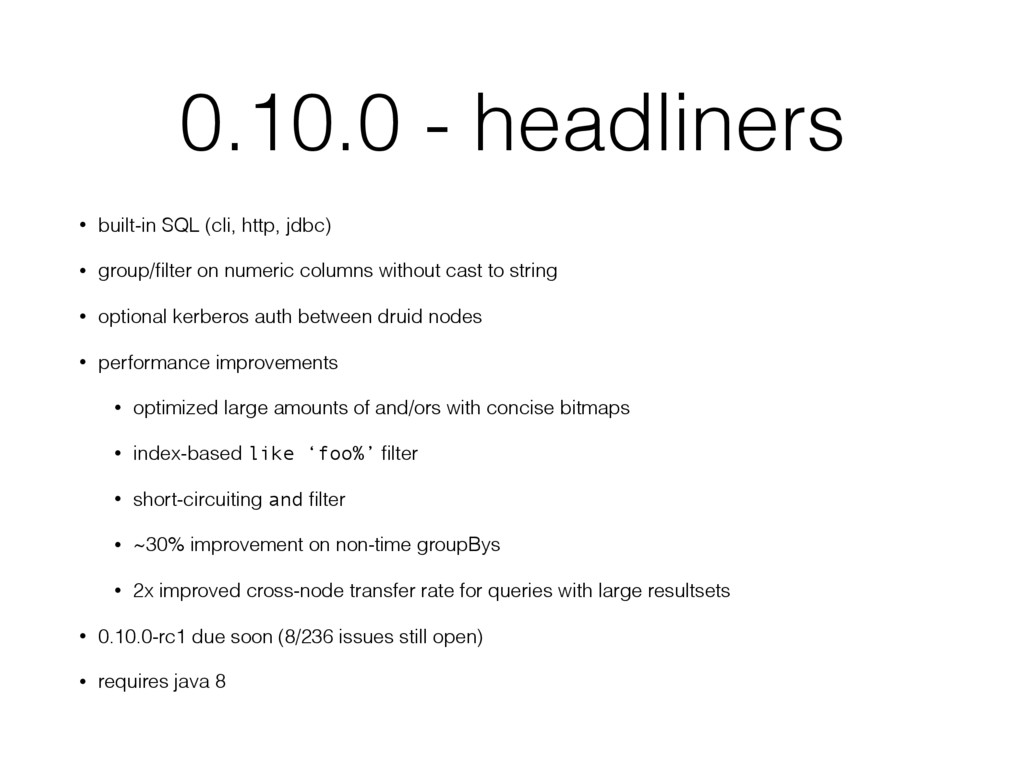
group/filter on numeric columns without cast to string • optional kerberos auth between druid nodes • performance improvements • optimized large amounts of and/ors with concise bitmaps • index-based like ‘foo%’ filter • short-circuiting and filter • ~30% improvement on non-time groupBys • 2x improved cross-node transfer rate for queries with large resultsets • 0.10.0-rc1 due soon (8/236 issues still open) • requires java 8
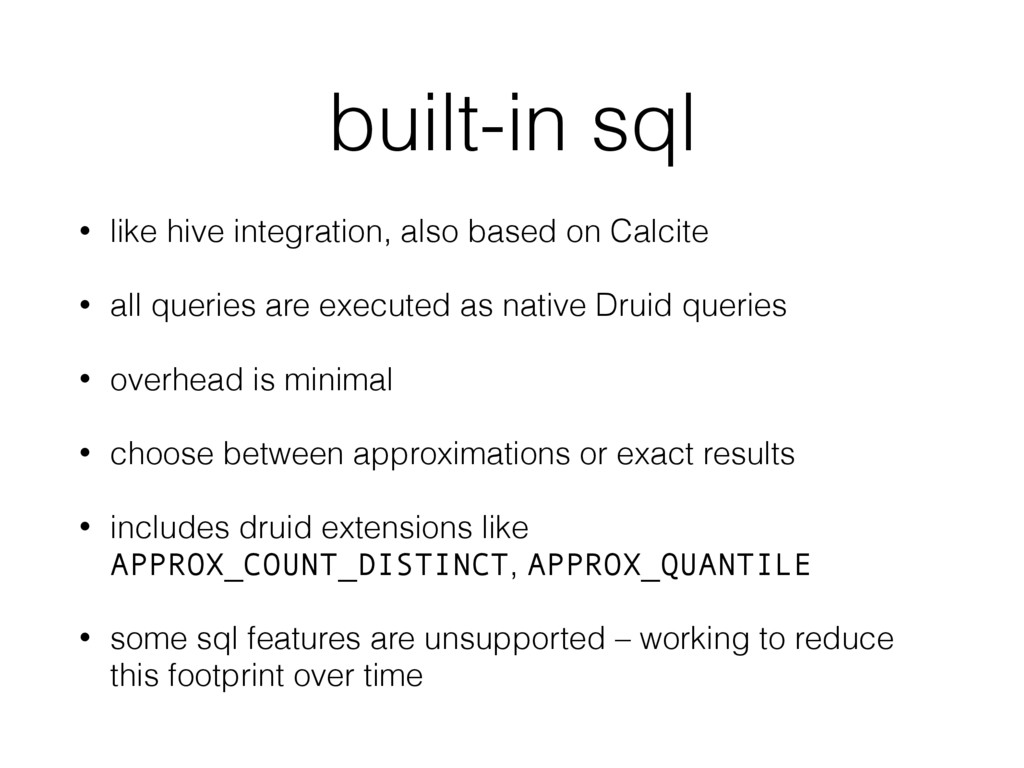
• all queries are executed as native Druid queries • overhead is minimal • choose between approximations or exact results • includes druid extensions like APPROX_COUNT_DISTINCT, APPROX_QUANTILE • some sql features are unsupported – working to reduce this footprint over time


 implydatainc
 miu_crescent
 carta_engineering
 harutiro
 chmikata
 takuyay0ne
 ymotongpoo
 nealle
 jcabot
 kaminashi
 minorun365
 azukiazusa1
 _kotobuki_
 retrage
 reverentgeek
 lara
 smashingmag
 jnunemaker
 cassininazir
 chriscoyier
 eileencodes
 sergeychernyshev
 helenjbeal
 tammielis