Share
Embed
Clustered Global Phrase Reordering Model for Statistical Machine Translation
Masaaki Nagata, Kuniko Saito, Kazuhide Yamamoto and Kazuteru Ohashi. Clustered Global Phrase Reordering Model for Statistical Machine Translation. Proceedings of 21st International Conference on Computational Linguistics and 44th Annual Meeting of the Association for Computational Linguistics (COLING-ACL 2006), pp.713-720 (2006.7)
自然言語処理研究室
July 31, 2006
Transcript
22 slides
-
1 A Clustered Global Phrase Reordering Model for Statistical Machine
Translation Masaaki Nagata, Kuniko Saito NTT Corporation Kazuhide Yamamoto, Kazuteru Ohashi Nagaoka University of Technology -
2 Introduction (1/3) Global reordering is essential to translation
of languages with different word orders Japanese verb at the end of the sentence must be moved at the beginning after subject in English Standard phrase-based translation systems use a word distance-based reordering model (Koehn et al., 2003) (Och and Ney, 2004) Penalize non-monotonic alignment exponentially Ignore orientation of the alignment and the identities of the source and target phrases -
3 Introduction (2/3) Block orientation bigram (Tillmann-Zhang05)
Block: a pair of source and target phrases that are translations of each other Local reordering of adjacent blocks are expressed as a three-valued orientation Right (monotone), Left (swapped), or Neutral Global reordering is not explicitly modeled. Neutral: the block is less strongly linked to its predecessor block -
4 Introduction (3/3) We present a global reordering model
Explicitly models long distance reordering Predicts four type of reordering patterns Monotone (adjacent | gap), reverse (adjacent | gap) Considers identities of source and target phrases Parameters are estimated from the N-best phrase alignment of training sentences It significantly outperformed the baseline IWSLT-2005 Japanese-English translation task -
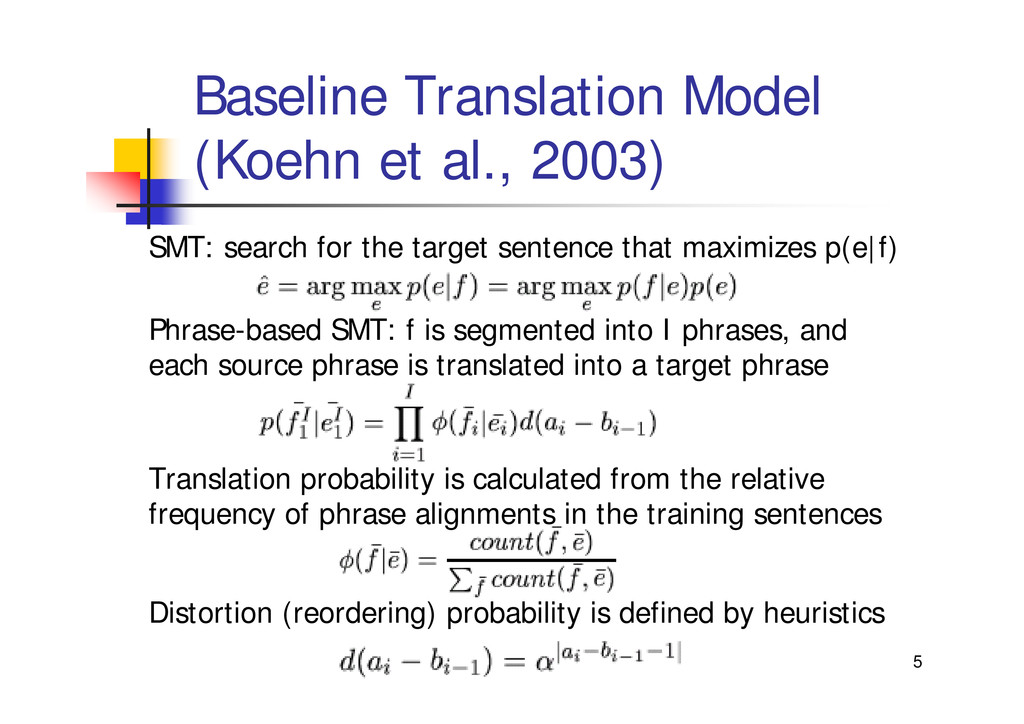
5 Baseline Translation Model (Koehn et al., 2003) SMT: search
for the target sentence that maximizes p(e|f) Phrase-based SMT: f is segmented into I phrases, and each source phrase is translated into a target phrase Distortion (reordering) probability is defined by heuristics Translation probability is calculated from the relative frequency of phrase alignments in the training sentences -
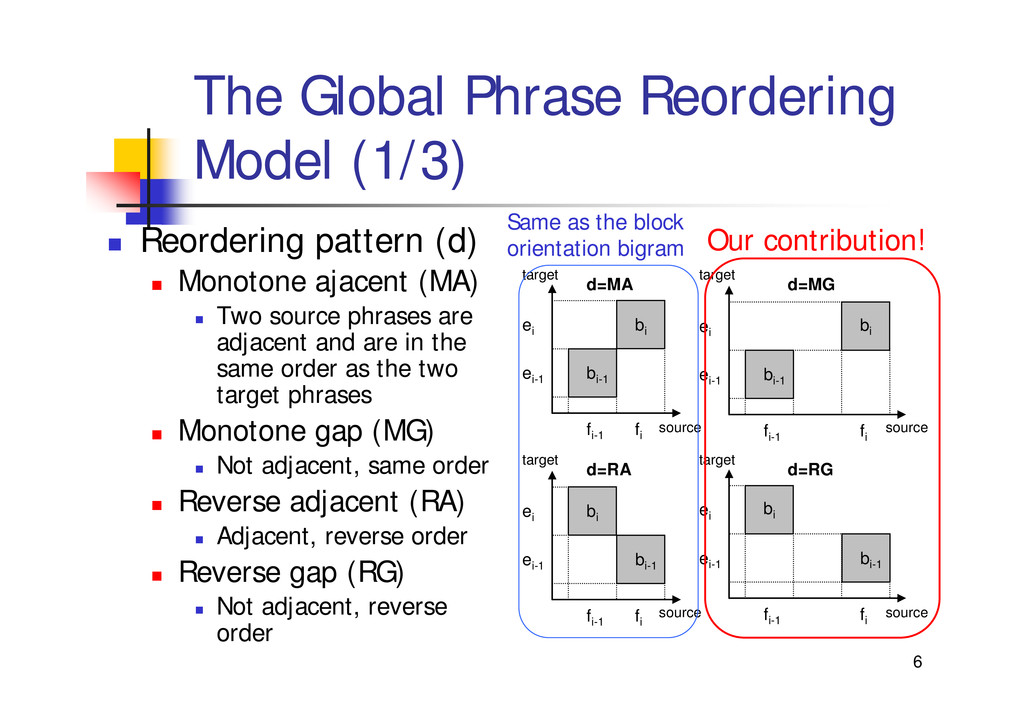
6 The Global Phrase Reordering Model (1/3) Reordering pattern
(d) Monotone ajacent (MA) Two source phrases are adjacent and are in the same order as the two target phrases Monotone gap (MG) Not adjacent, same order Reverse adjacent (RA) Adjacent, reverse order Reverse gap (RG) Not adjacent, reverse order bi-1 bi fi-1 fi ei-1 ei bi-1 bi fi-1 fi ei-1 ei bi-1 bi fi-1 fi ei-1 ei bi-1 bi fi-1 fi ei-1 ei source target target source target target source source d=MA d=MG d=RA d=RG Our contribution! Same as the block orientation bigram -
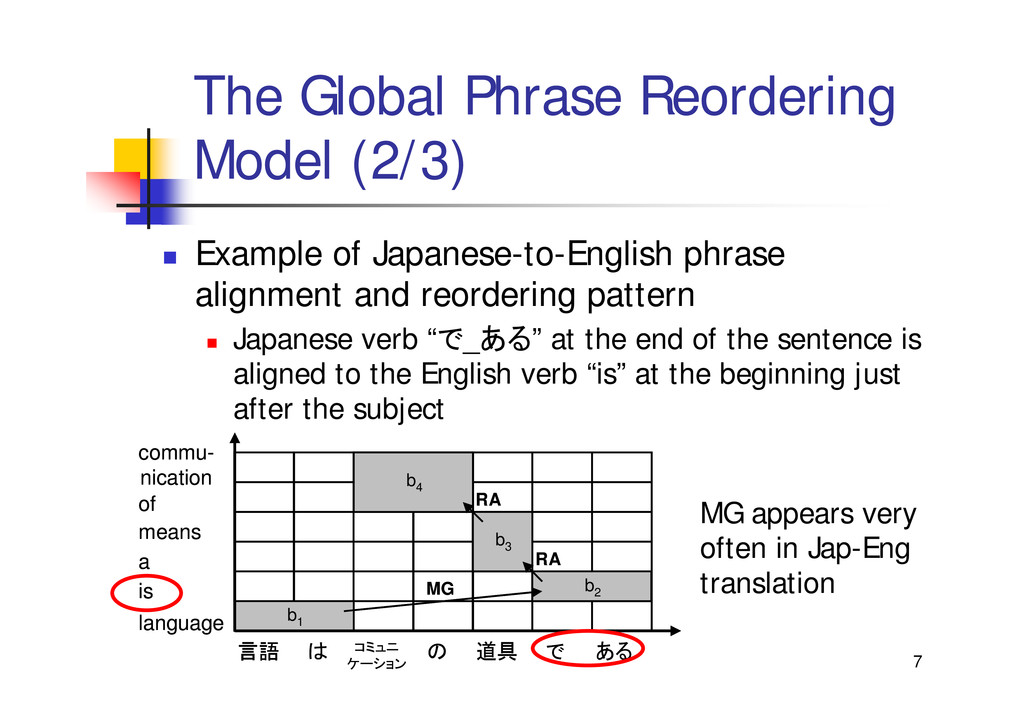
7 The Global Phrase Reordering Model (2/3) Example of
Japanese-to-English phrase alignment and reordering pattern Japanese verb “で_ある” at the end of the sentence is aligned to the English verb “is” at the beginning just after the subject 言語 は コミュニ ケーション の 道具 で ある language is a means commu- nication of MG RA RA b 1 b 2 b 3 b 4 言語 は コミュニ ケーション の 道具 で ある language is a means commu- nication of MG RA RA b 1 b 2 b 3 b 4 MG appears very often in Jap-Eng translation -
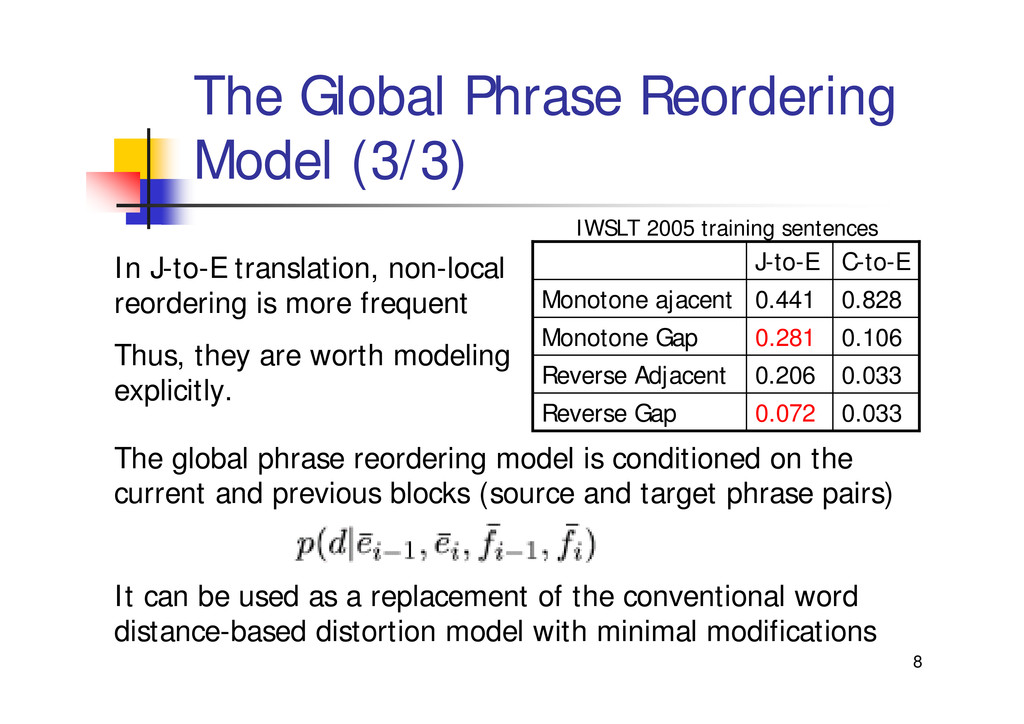
8 The Global Phrase Reordering Model (3/3) J-to-E C-to-E Monotone
ajacent 0.441 0.828 Monotone Gap 0.281 0.106 Reverse Adjacent 0.206 0.033 Reverse Gap 0.072 0.033 In J-to-E translation, non-local reordering is more frequent Thus, they are worth modeling explicitly. The global phrase reordering model is conditioned on the current and previous blocks (source and target phrase pairs) It can be used as a replacement of the conventional word distance-based distortion model with minimal modifications IWSLT 2005 training sentences -
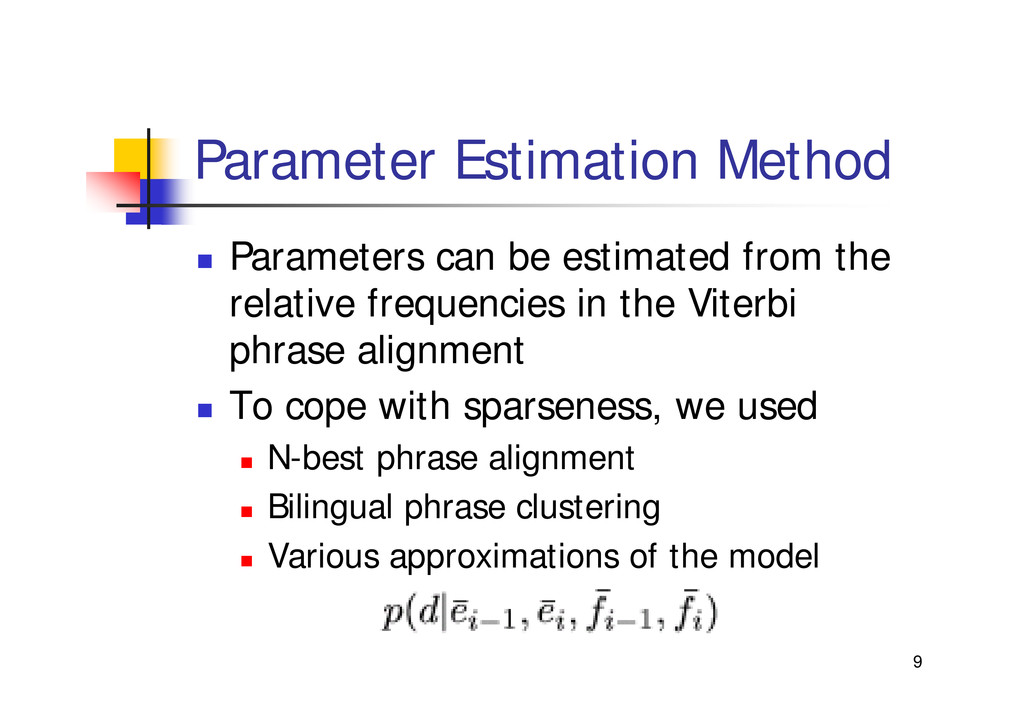
9 Parameter Estimation Method Parameters can be estimated from
the relative frequencies in the Viterbi phrase alignment To cope with sparseness, we used N-best phrase alignment Bilingual phrase clustering Various approximations of the model -
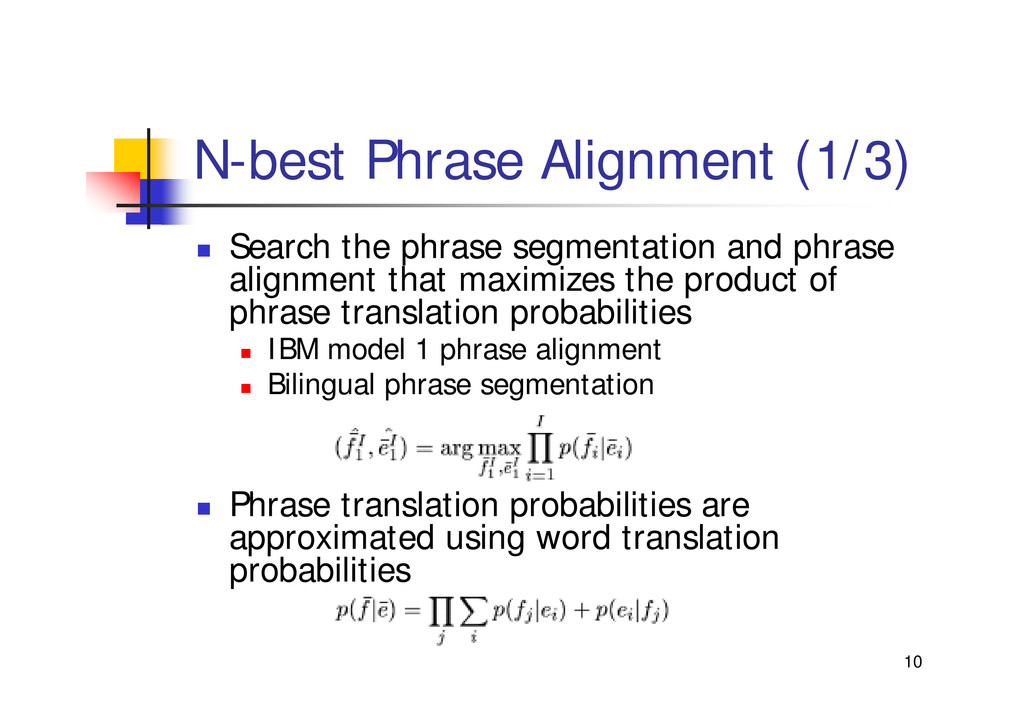
10 N-best Phrase Alignment (1/3) Search the phrase segmentation
and phrase alignment that maximizes the product of phrase translation probabilities IBM model 1 phrase alignment Bilingual phrase segmentation Phrase translation probabilities are approximated using word translation probabilities -
11 N-best Phrase Alignment (2/3) The search for N-best
phrase alignment is implemented as followings: All source word and target word pairs are considered to be initial phrase pairs If the phrase translation probability of the phrase pair is less than the threshold, it is deleted Each phrase pair is expanded toward the eight neighboring directions (see next slides) If the phrase translation probability of the expanded phrase pair is less than the threshold, it is deleted. The process of expansion and deletion is repeated until no further expansion is possible. The consistent N-best phrase alignment are searched from all combinations of the above phrase pairs -
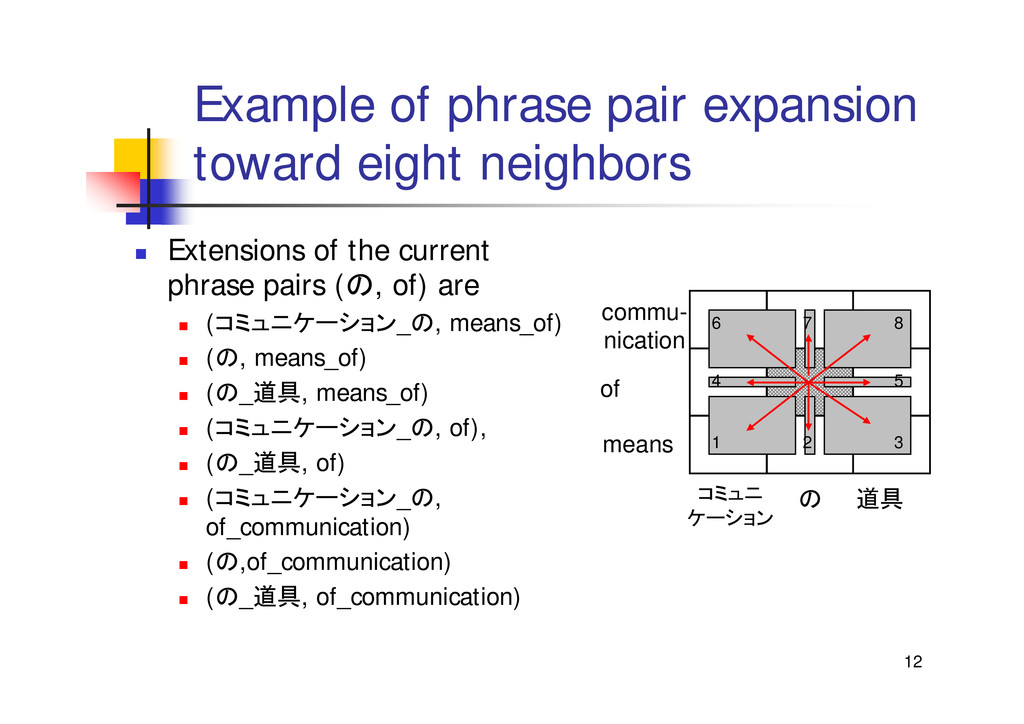
12 Example of phrase pair expansion toward eight neighbors
Extensions of the current phrase pairs (の, of) are (コミュニケーション_の, means_of) (の, means_of) (の_道具, means_of) (コミュニケーション_の, of), (の_道具, of) (コミュニケーション_の, of_communication) (の,of_communication) (の_道具, of_communication) の 道具 コミュニ ケーション means commu- nication of 1 2 3 4 5 6 7 8 -
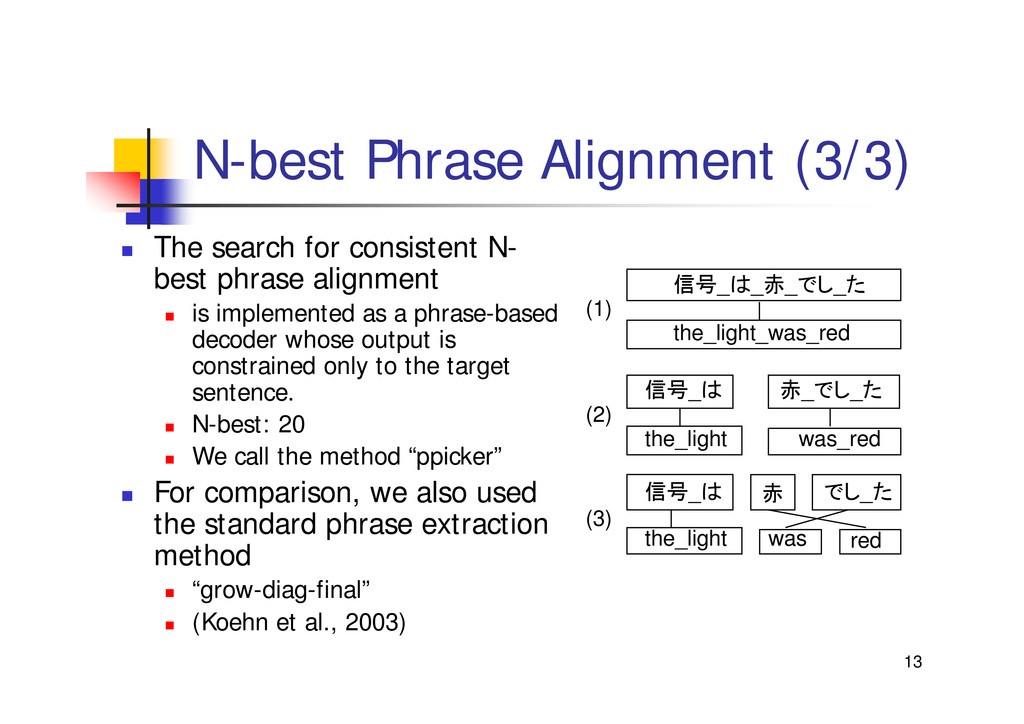
13 N-best Phrase Alignment (3/3) The search for consistent
N- best phrase alignment is implemented as a phrase-based decoder whose output is constrained only to the target sentence. N-best: 20 We call the method “ppicker” For comparison, we also used the standard phrase extraction method “grow-diag-final” (Koehn et al., 2003) 信号_は_赤_でし_た the_light_was_red 信号_は 赤_でし_た the_light was_red 信号_は でし_た the_light was 赤 red (1) (2) (3) -
14 Bilingual Phrase Clustering We used a bilingual word
clustering tool “mkcls” (Och et al., 1999) It makes partitions of the phrases that maximize the joint probability of the training bilingual corpus All words in a phrase are concatenated by an underscore '_' to form a pseudo word All N-best phrase alignments are treated equally # of classes: 20 For comparison, two different phrase classification “1pos”: POS of the first word in English phrase and that of the last word in Japanese Phrase “2pos”: POS of the first and last words of each phrase -
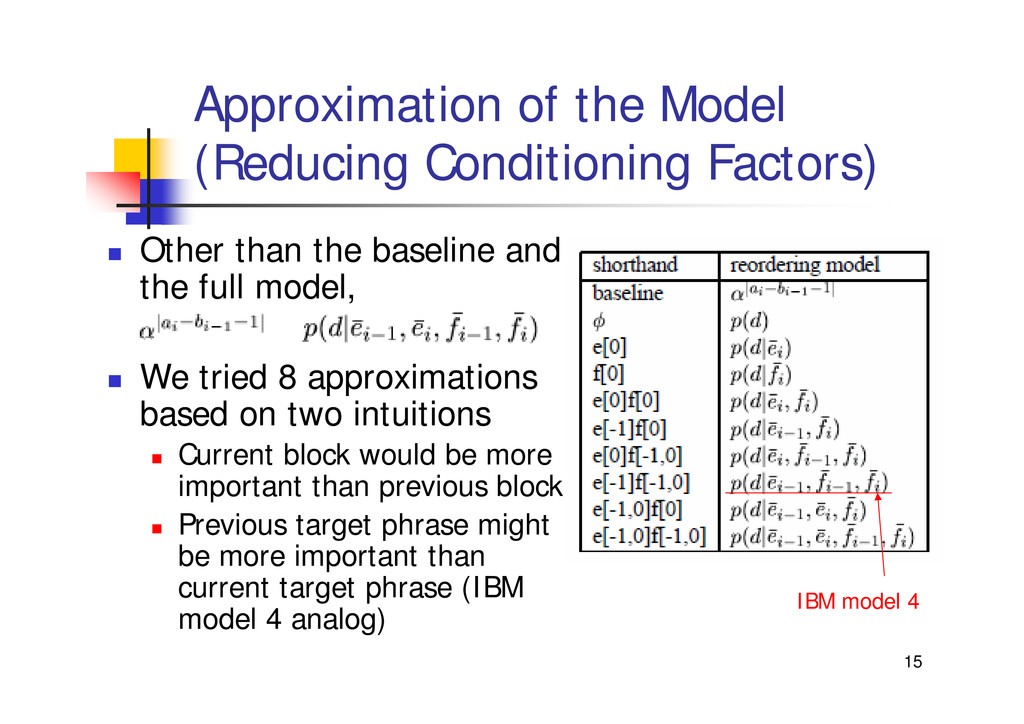
15 Approximation of the Model (Reducing Conditioning Factors) Other
than the baseline and the full model, We tried 8 approximations based on two intuitions Current block would be more important than previous block Previous target phrase might be more important than current target phrase (IBM model 4 analog) IBM model 4 -
16 Experiments Corpus IWSLT-2005 Japanese-English translation task
Basic travel conversations 20,000 training sentences Average sentence lengths (J: 9.9 words, E: 9.2 words) Two development sets, each contains 500 sentences with 16 reference translations We used ‘devset2’ (IWSLT-2004) for the experiment Tools Japanese morphological analysis: ChaSen English POS tagging: MXPOST -
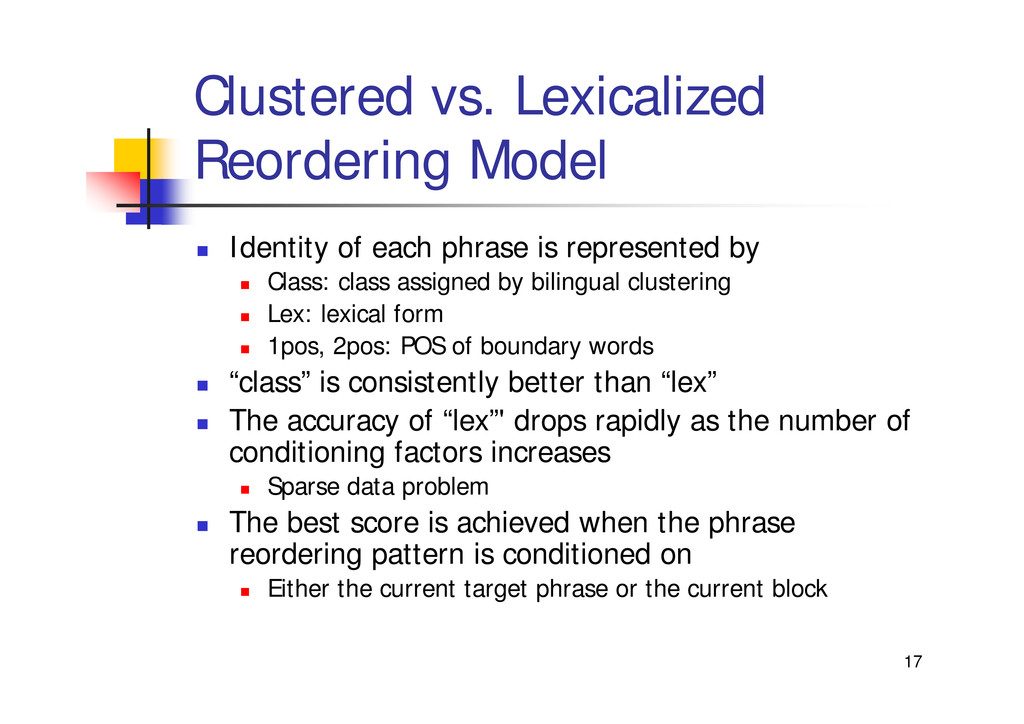
17 Clustered vs. Lexicalized Reordering Model Identity of each
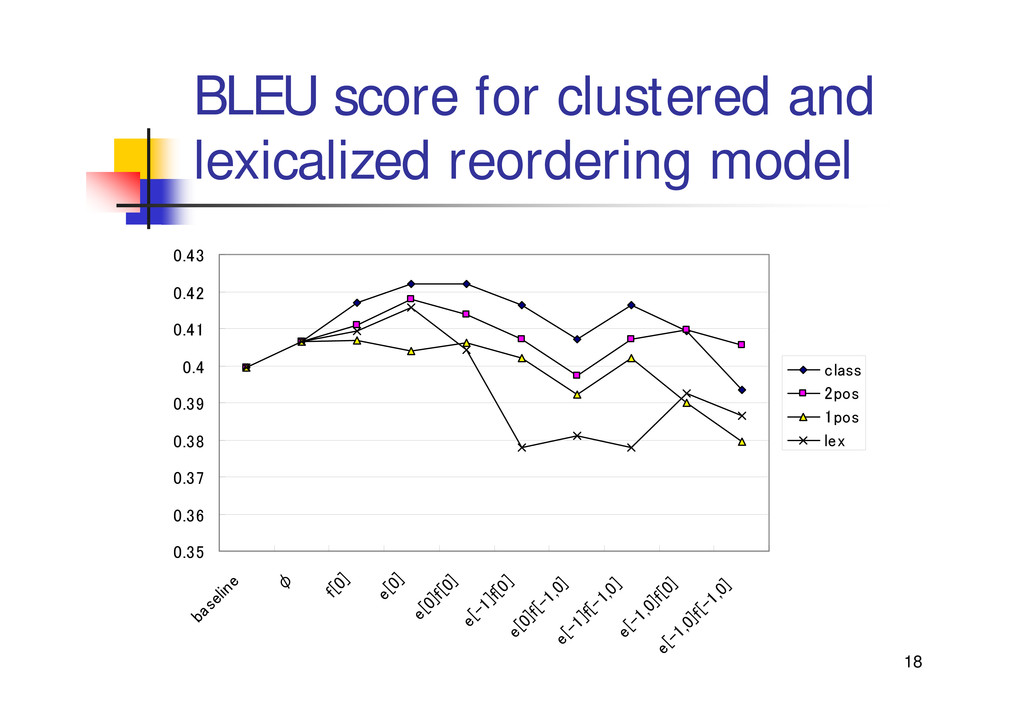
phrase is represented by Class: class assigned by bilingual clustering Lex: lexical form 1pos, 2pos: POS of boundary words “class” is consistently better than “lex” The accuracy of “lex”' drops rapidly as the number of conditioning factors increases Sparse data problem The best score is achieved when the phrase reordering pattern is conditioned on Either the current target phrase or the current block -
18 BLEU score for clustered and lexicalized reordering model 0.35
0.36 0.37 0.38 0.39 0.4 0.41 0.42 0.43 baseline φ f[0] e[0] e[0]f[0] e[-1]f[0] e[0]f[-1,0] e[-1]f[-1,0] e[-1,0]f[0] e[-1,0]f[-1,0] class 2pos 1pos lex -
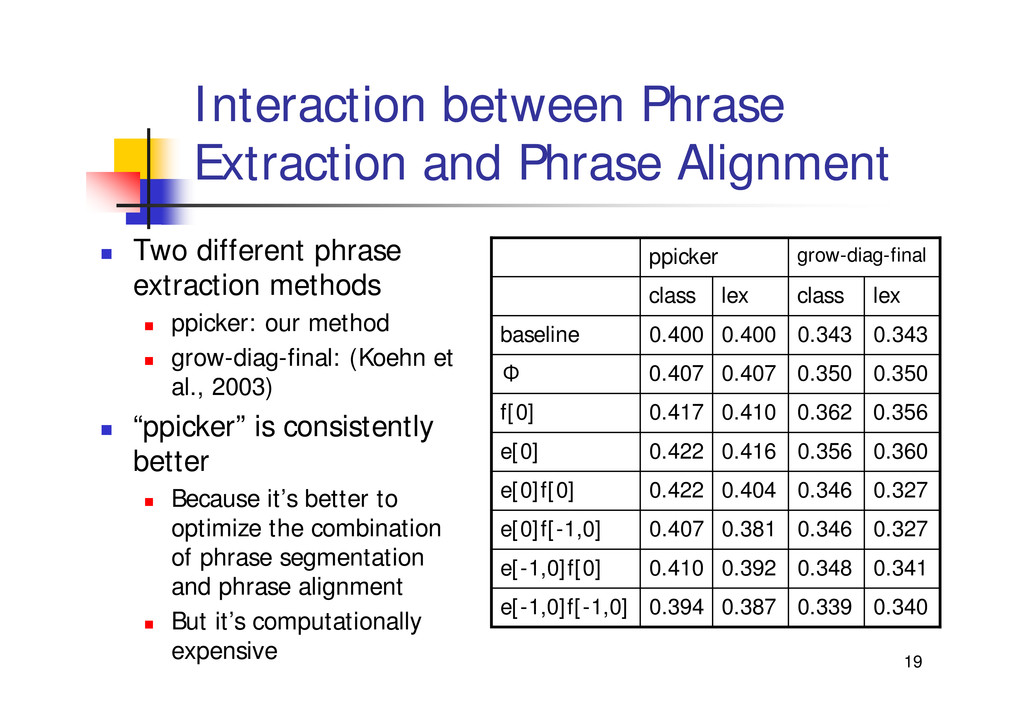
19 Interaction between Phrase Extraction and Phrase Alignment Two
different phrase extraction methods ppicker: our method grow-diag-final: (Koehn et al., 2003) “ppicker” is consistently better Because it’s better to optimize the combination of phrase segmentation and phrase alignment But it’s computationally expensive ppicker grow-diag-final class lex class lex baseline 0.400 0.400 0.343 0.343 Φ 0.407 0.407 0.350 0.350 f[0] 0.417 0.410 0.362 0.356 e[0] 0.422 0.416 0.356 0.360 e[0]f[0] 0.422 0.404 0.346 0.327 e[0]f[-1,0] 0.407 0.381 0.346 0.327 e[-1,0]f[0] 0.410 0.392 0.348 0.341 e[-1,0]f[-1,0] 0.394 0.387 0.339 0.340 -
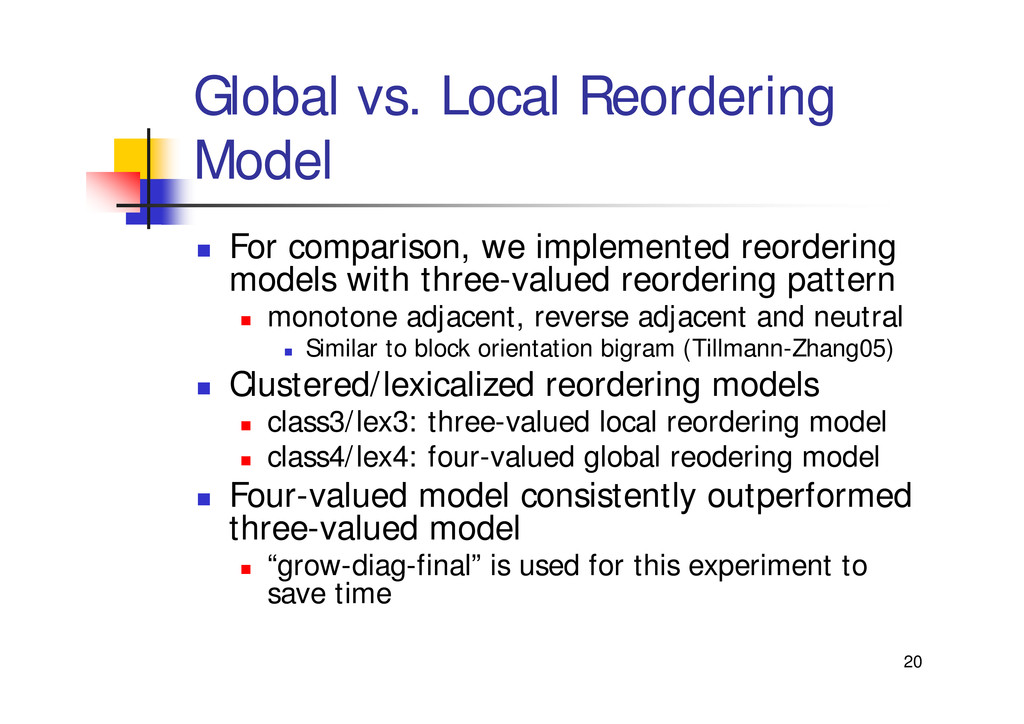
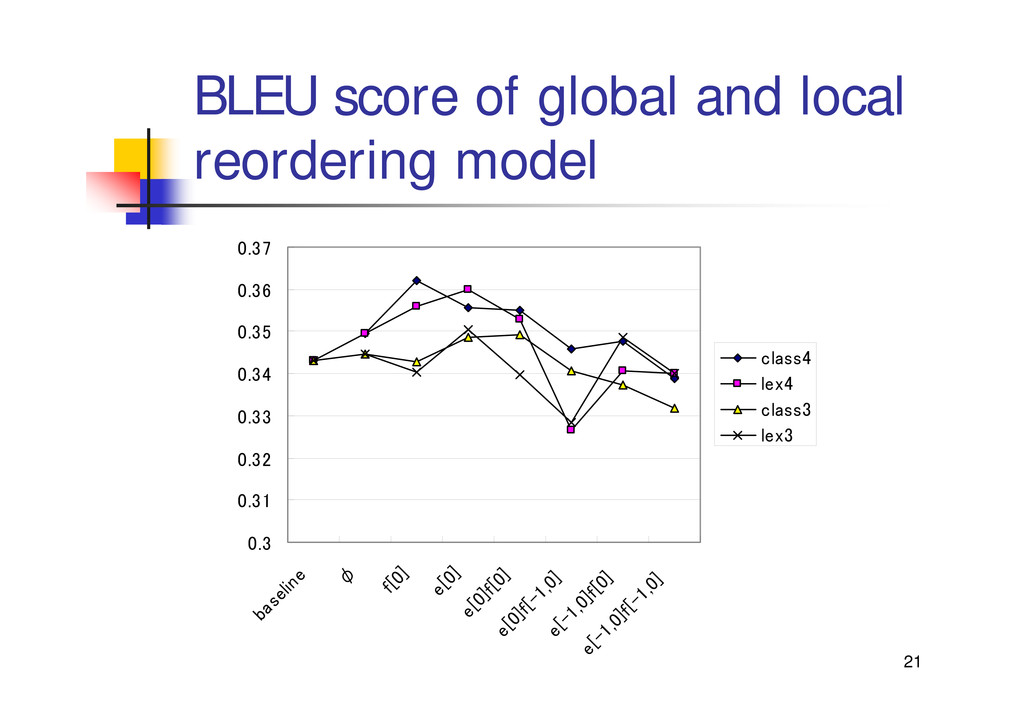
20 Global vs. Local Reordering Model For comparison, we
implemented reordering models with three-valued reordering pattern monotone adjacent, reverse adjacent and neutral Similar to block orientation bigram (Tillmann-Zhang05) Clustered/lexicalized reordering models class3/lex3: three-valued local reordering model class4/lex4: four-valued global reodering model Four-valued model consistently outperformed three-valued model “grow-diag-final” is used for this experiment to save time -
21 BLEU score of global and local reordering model 0.3
0.31 0.32 0.33 0.34 0.35 0.36 0.37 baseline φ f[0] e[0] e[0]f[0] e[0]f[-1,0] e[-1,0]f[0] e[-1,0]f[-1,0] class4 lex4 class3 lex3 -
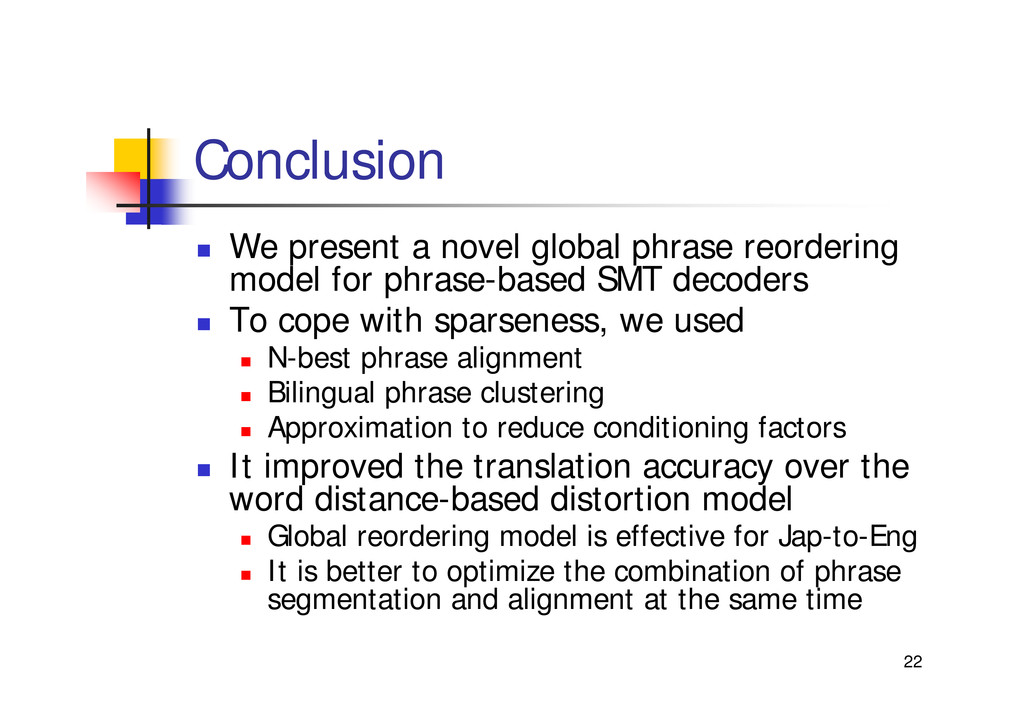
22 Conclusion We present a novel global phrase reordering
model for phrase-based SMT decoders To cope with sparseness, we used N-best phrase alignment Bilingual phrase clustering Approximation to reduce conditioning factors It improved the translation accuracy over the word distance-based distortion model Global reordering model is effective for Jap-to-Eng It is better to optimize the combination of phrase segmentation and alignment at the same time