Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
個人適応による英日翻訳での訳語候補の順位付け
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
自然言語処理研究室
March 31, 2006
Research
180
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
個人適応による英日翻訳での訳語候補の順位付け
青木 優、山本 和英. 個人適応による英日翻訳での訳語候補の順位付け. 言語処理学会第12回年次大会, pp.260-263 (2006.3)
自然言語処理研究室
March 31, 2006
More Decks by 自然言語処理研究室
See All by 自然言語処理研究室
データサイエンス14_システム.pdf
jnlp
0
420
データサイエンス13_解析.pdf
jnlp
0
550
データサイエンス12_分類.pdf
jnlp
0
380
データサイエンス11_前処理.pdf
jnlp
0
510
Recurrent neural network based language model
jnlp
0
190
自然言語処理研究室 研究概要(2012年)
jnlp
0
170
自然言語処理研究室 研究概要(2013年)
jnlp
0
130
自然言語処理研究室 研究概要(2014年)
jnlp
0
160
自然言語処理研究室 研究概要(2015年)
jnlp
0
240
Other Decks in Research
See All in Research
多様なデータを許容し学習し続ける模倣学習 / Advanced Imitation Learning for VLA
prinlab
0
330
秋葉原ウォーカブル基礎調査報告書
izumiyama_lab
1
120
最先端NLP 2026 論文紹介: Wait, Wait, Wait... Why Do Reasoning Models Loop? / SNLP Paper Review: Wait, Wait, Wait... Why Do Reasoning Models Loop?
tkng
0
240
論文紹介: Understanding Epistemic Language with a Language-augmented Bayesian Theory of Mind
hisaokatsumi
0
170
CVPR2026論文紹介_VLMにとって良いvision encoderとは何か?Rethinking Model Selection in VLM Through the Lens of Gromov-Wasserstein Distance
kobayashi31
1
220
超効率化への挑戦:1bit LLMの現状と展望
yumaichikawa
0
730
2025年度秋葉原ウォーカブルプロジェクト調査報告 「アキバらしいウォーカブル」とは何か
izumiyama_lab
1
220
ros2-perf-multihost: Automated Coordination Framework for Objective Architecture Evaluation in Distributed Systems
takasehideki
0
110
プレイス・ワークショップ秋葉原
izumiyama_lab
1
100
【ローカルAIに向き合う展示会vol.2】液体時間定数型モジュールを用いた オリジナルの双方向エンコーダーモデルNexteraBERT 推論速度向上検討並びにダウンストリーム評価
rikkabotan7
0
200
Karkada さんの論文 × 2 の紹介: (1) Closed-Form Training Dynamics Reveal Learned Features and Linear Structure in Word2Vec-like Models, (2) Symmetry in language statistics shapes the geometry of model representations
eumesy
PRO
1
750
ふとした出会いで生まれたSkillが、 社内利用1位になるまで
mikimhk
21
24k
Featured
See All Featured
Efficient Content Optimization with Google Search Console & Apps Script
katarinadahlin
PRO
1
870
Making the Leap to Tech Lead
cromwellryan
135
10k
Bridging the Design Gap: How Collaborative Modelling removes blockers to flow between stakeholders and teams @FastFlow conf
baasie
0
700
Building a A Zero-Code AI SEO Workflow
portentint
PRO
0
730
Introduction to Domain-Driven Design and Collaborative software design
baasie
1
990
The Anti-SEO Checklist Checklist. Pubcon Cyber Week
ryanjones
0
250
How Fast Is Fast Enough? [PerfNow 2025]
tammyeverts
3
900
Bootstrapping a Software Product
garrettdimon
PRO
306
120k
Chasing Engaging Ingredients in Design
codingconduct
0
320
Leading Effective Engineering Teams in the AI Era
addyosmani
9
2.6k
Winning Ecommerce Organic Search in an AI Era - #searchnstuff2025
aleyda
2
2.1k
Reality Check: Gamification 10 Years Later
codingconduct
0
2.3k
Transcript
個人適応による英日翻訳での 訳語候補の順位付け 長岡技術科学大学 電気系 青木 優 山本 和英
はじめに 背景 個人の興味や知識を学習する個人適応 システムは、ユーザが大量の情報を選 別するタスクに有効である。 問題設定
複数の選択肢が提示されたとき、ユー ザにとって必要な情報の取捨選択。 →英日翻訳における訳語選択
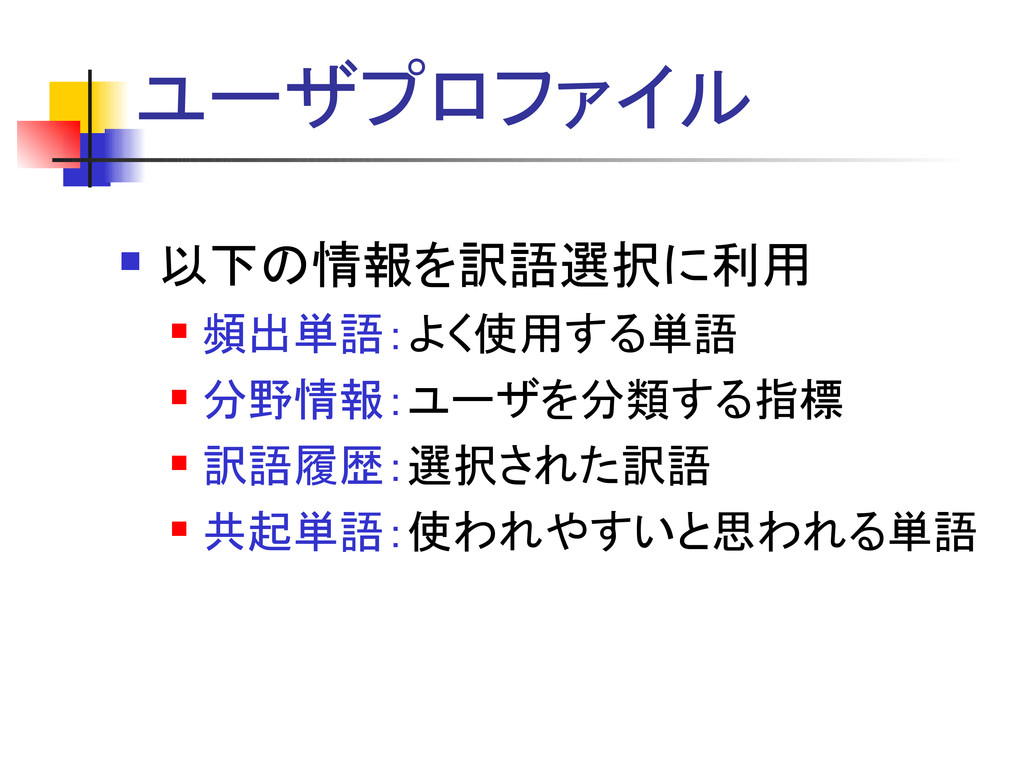
ユーザプロファイル 以下の情報を訳語選択に利用 頻出単語:よく使用する単語 分野情報:ユーザを分類する指標 訳語履歴:選択された訳語
共起単語:使われやすいと思われる単語
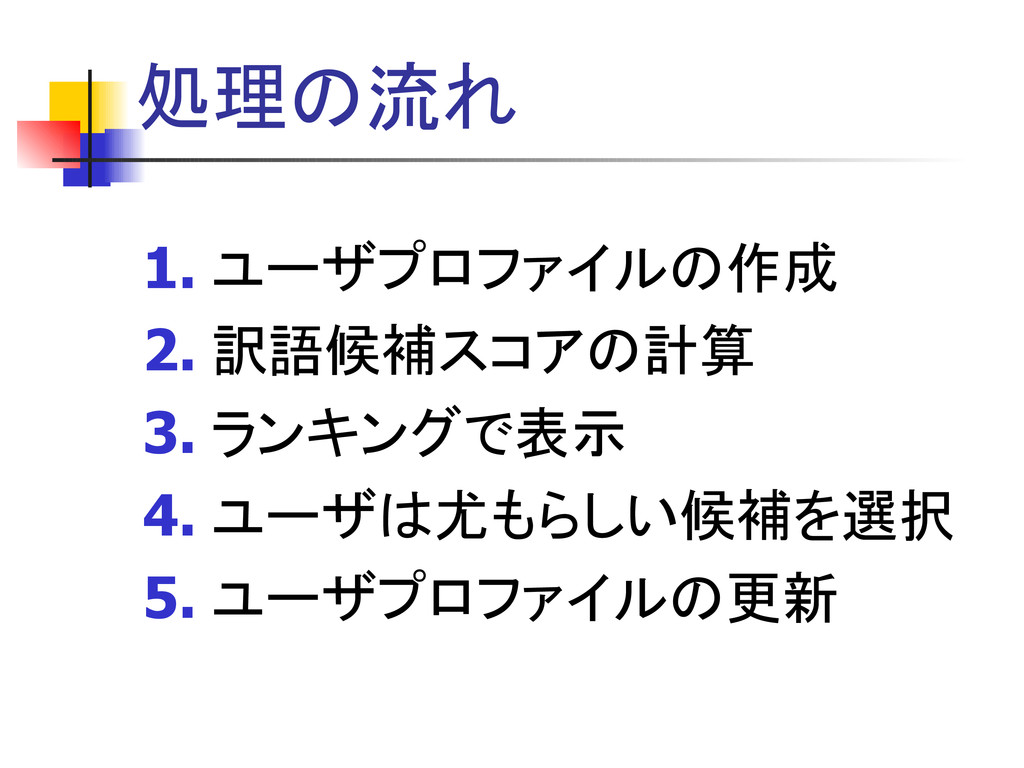
処理の流れ 1. ユーザプロファイルの作成 2. 訳語候補スコアの計算 3. ランキングで表示 4. ユーザは尤もらしい候補を選択 5.
ユーザプロファイルの更新
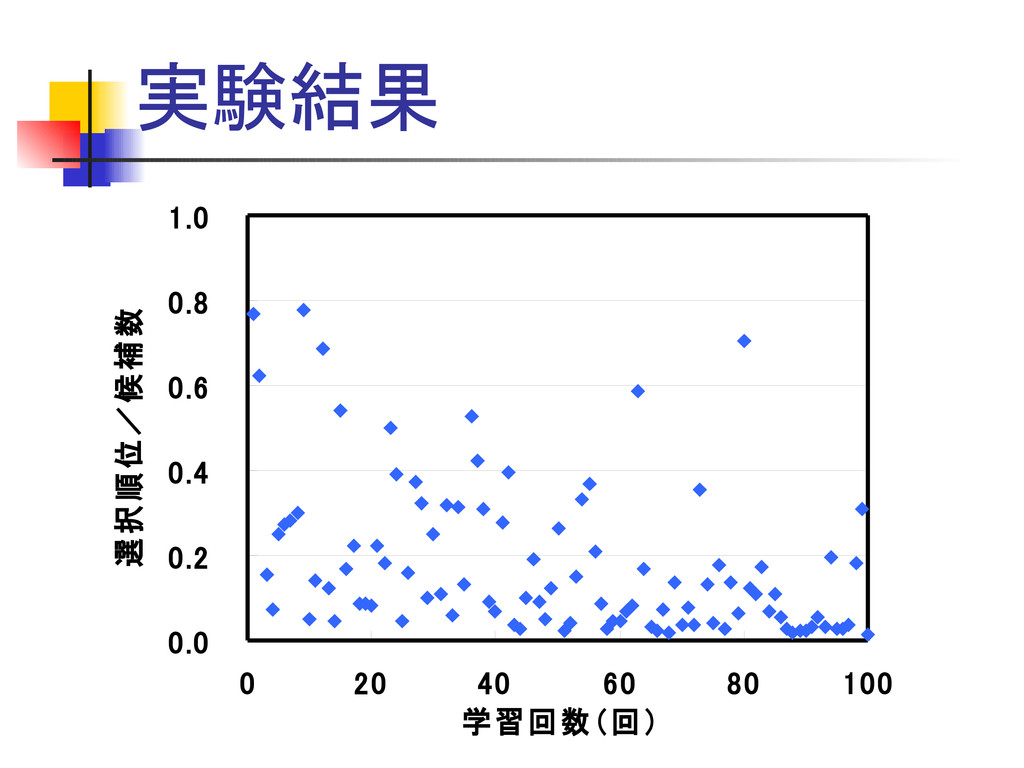
まとめ ユーザプロファイルを作成、利用 訳語候補をランキングで提示 ユーザの個人性を学習させた その結果、学習回数の増加に伴い、 選択された訳語の順位が上位である 割合が高くなくなる傾向が見られた。
辞書の作成 属性付き対訳辞書 クロスランゲージ専門語辞書を使用 共起単語辞書 一文中で共起する2語の共起頻度
毎日新聞2000年版を使用 [circuit:回路:電気・電子]
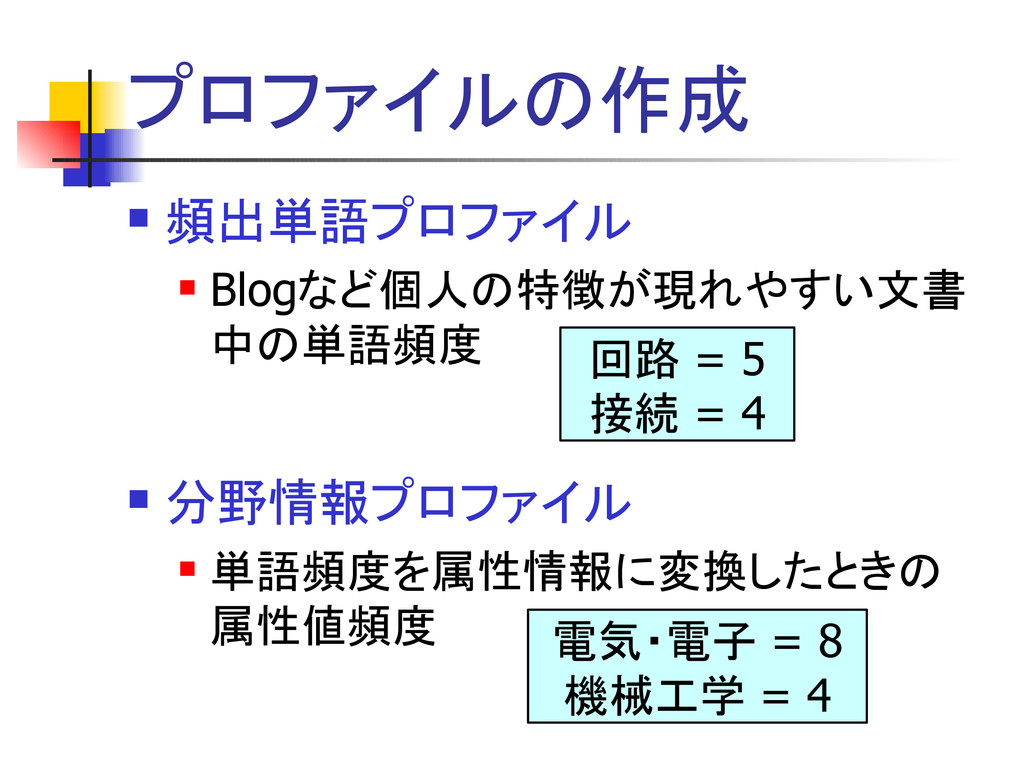
プロファイルの作成 頻出単語プロファイル Blogなど個人の特徴が現れやすい文書 中の単語頻度 分野情報プロファイル 単語頻度を属性情報に変換したときの
属性値頻度 回路 = 5 接続 = 4 電気・電子 = 8 機械工学 = 4
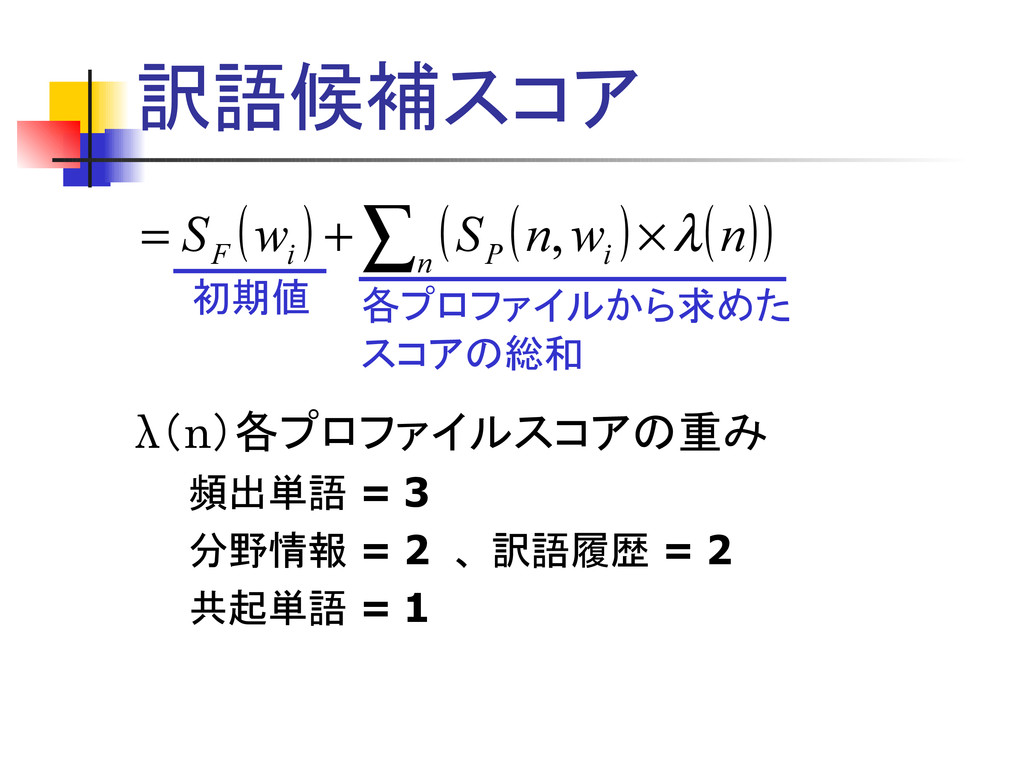
訳語候補スコア λ(n)各プロファイルスコアの重み 頻出単語 = 3 分野情報 = 2 、 訳語履歴
= 2 共起単語 = 1 ( ) ( ) ( ) ( ) ∑ × + = n i P i F n w n S w S λ , 初期値 各プロファイルから求めた スコアの総和
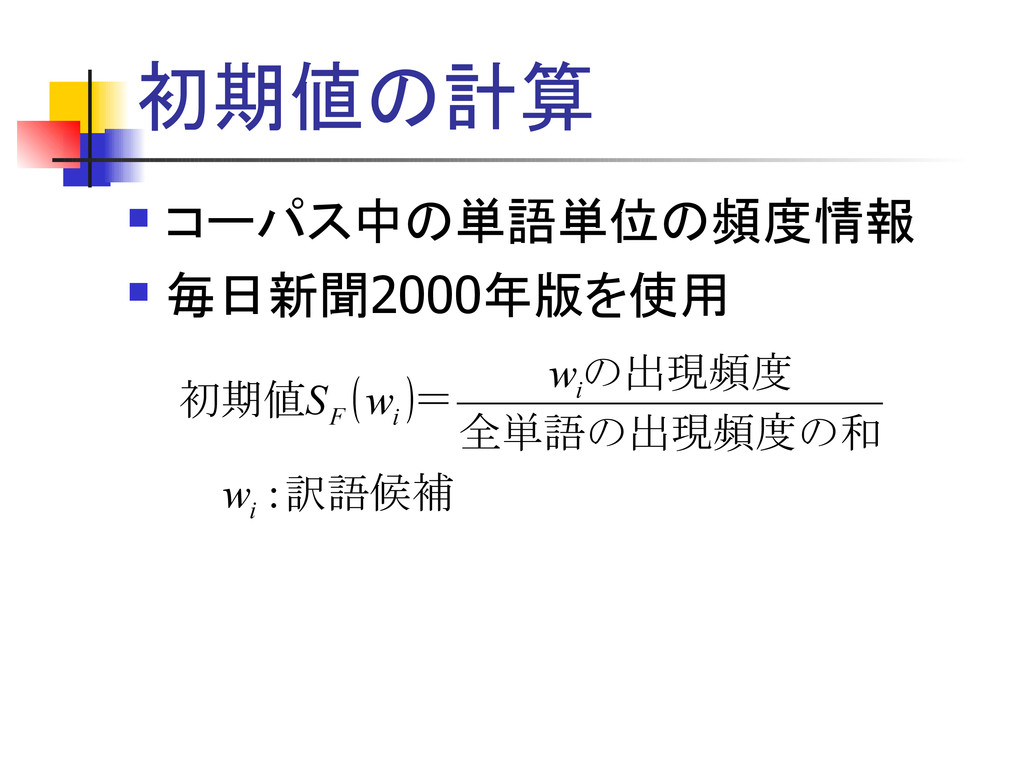
初期値の計算 コーパス中の単語単位の頻度情報 毎日新聞2000年版を使用 ( ) 訳語候補 全単語の出現頻度の和
の出現頻度 = 初期値 : i i i F w w w S
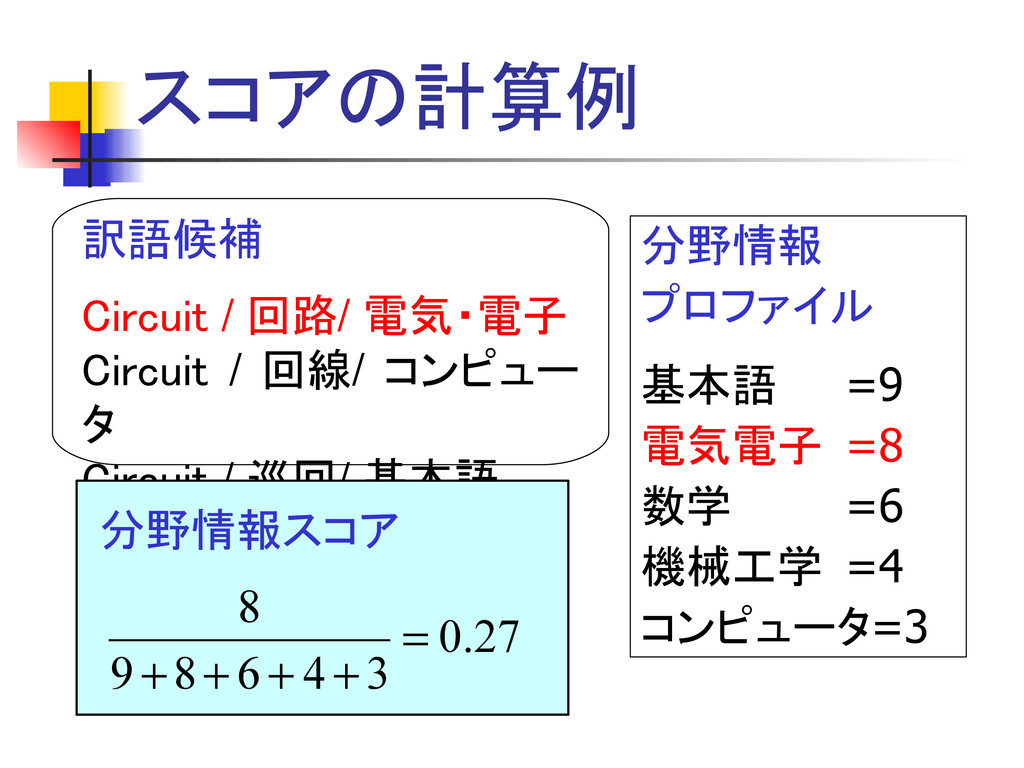
スコアの計算例 分野情報 プロファイル 基本語 =9 電気電子 =8 数学 =6 機械工学
=4 コンピュータ=3 訳語候補 Circuit / 回路/ 電気・電子 Circuit / 回線/ コンピュー タ Circuit / 巡回/ 基本語 27 . 0 3 4 6 8 9 8 = + + + + 分野情報スコア
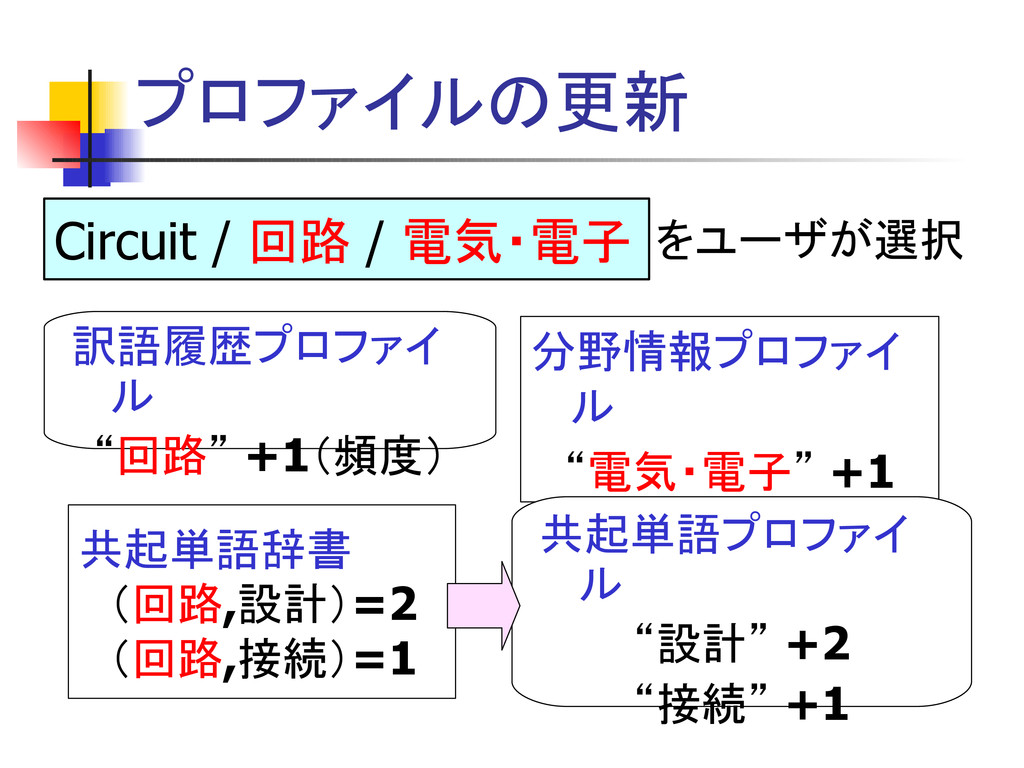
プロファイルの更新 Circuit / 回路 / 電気・電子 分野情報プロファイ ル “電気・電子” +1
訳語履歴プロファイ ル “回路” +1(頻度) 共起単語プロファイ ル “設計” +2 “接続” +1 共起単語辞書 (回路,設計)=2 (回路,接続)=1 をユーザが選択
評価実験 ランダムで選んだ英単語100語を入力 ユーザは尤もらしいと思う訳語を選択 システムに学習させる 選ばれた訳語の順位の推移を評価 プロファイルを更新し、システムに学習さ
せることで、ユーザに選ばれる訳語候補 が上位に出力されることを確認する。
実験結果 0.0 0.2 0.4 0.6 0.8 1.0 0 20 40
60 80 100 学習回数(回) 選択順位/候補数
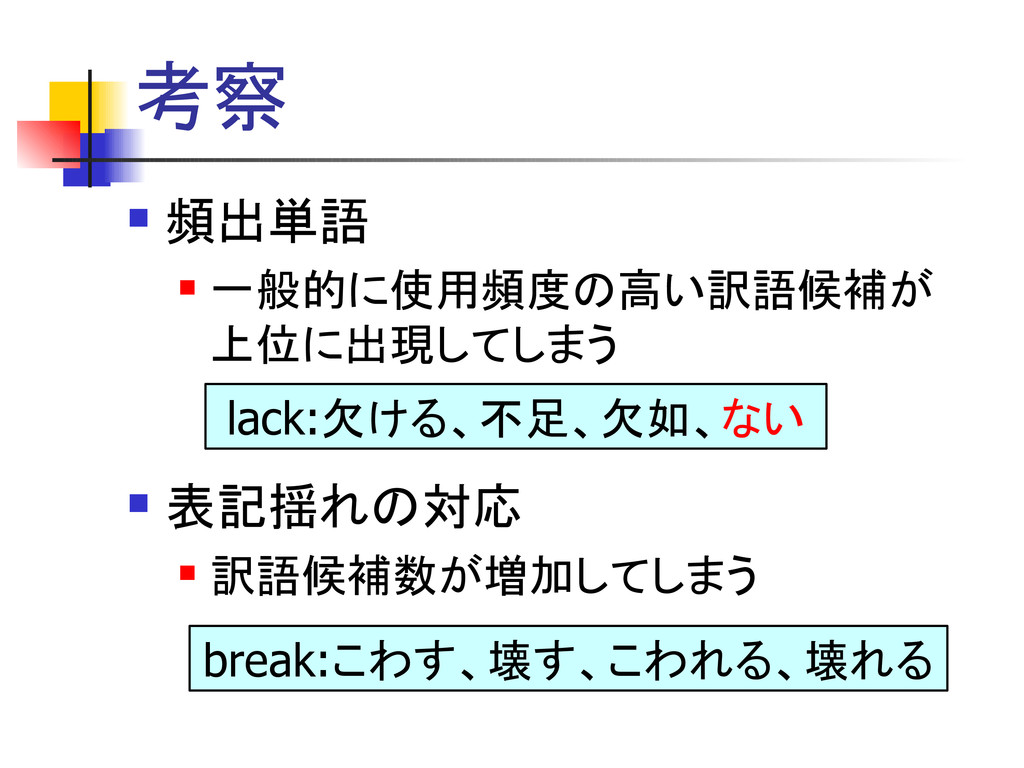
考察 頻出単語 一般的に使用頻度の高い訳語候補が 上位に出現してしまう 表記揺れの対応 訳語候補数が増加してしまう
lack:欠ける、不足、欠如、ない break:こわす、壊す、こわれる、壊れる
課題 ユーザプロファイルの作成 個人の特徴が現れるような文書の 収集方法の検討 初期でのプロファイルの作成 効率的な学習
重み付け方法の検討

 Your Podcast. Everywhere. Effortlessly.


 jnlp
 prinlab
 izumiyama_lab
 tkng
 hisaokatsumi
 kobayashi31
 yumaichikawa
 takasehideki
 rikkabotan7
 eumesy
 mikimhk
 katarinadahlin
 cromwellryan
 baasie
 portentint
 ryanjones
 tammyeverts
 garrettdimon
 codingconduct
 addyosmani
 aleyda